
DeepFakeX: A Comprehensive Multimodal Deepfake Dataset for Research and Analysis


Abstract
1. Summary
2. Data Description
2.1. Dataset Overview
- Identity replacement through facial manipulation.
- Audio track substitution while preserving the original visuals.
- Artificially generated speech imitating the original speaker.
- Simultaneous manipulation of both facial identity and audio content.
2.2. Directory Organization and File Naming Convention
- deepfake_face_swapped/—facial identity altered while preserving the original audio track.
- deepfake_audio_swapped/—audio content modified while retaining the original visual stream.
- deepfake_voice_cloned/—synthetic voice generation applied to the original visual content.
- deepfake_combined_face_audio_swapped/—facial identity and audio content are both synthetically altered.
2.3. Modal Diversity
- Ethnicities: South Asian, African, East Asian, and Caucasian.
- Gender Identity: Male, female, and transgender individuals are represented.
- Age groups: Young, middle-aged, and older adults.
- Languages: Videos are primarily in English, with a subset in Urdu.
- Contexts: Video contexts include speeches, informational videos, interviews, news coverage, vlogs, and film excerpts.
2.4. Data Specifications and Availability
- Video format: All files are provided in .mp4.
- Audio configuration: Mono or stereo tracks with normalized volume levels.
- Spatial resolution: Videos are available in 720p or 1080p formats.
- Video duration: Each video ranges between 4 and 12 s.
- Repository link: https://doi.org/10.5281/zenodo.14202454
- Usage License: Distributed under the Creative Commons Attribution-NonCommercial 4.0 International (CC BY-NC 4.0) license.
3. Methods
3.1. Deepfake Video Generation and Processing Pipeline
- (1)
- Source content selection;
- (2)
- Use of deepfake creation applications;
- (3)
- Post-processing operations for uniformity;
- (4)
- Dataset organization and file structuring.
3.2. Deepfake Generation Tools and Software Platforms
3.3. Post-Processing and Dataset Curation
- Format Standardization: The videos were encoded in MP4 format by utilizing the H.264 codec.
- Resolution Adjustment: The video files were scaled to either 720p or 1080p resolution.
- Frame Rate Normalization: The frame rate was standardized to 25 or 30 frames per second to ensure temporal consistency.
- Audio Level Normalization: Audio levels were calibrated to achieve balanced and uniform audio output across the dataset.
- File Naming Protocol: Each file was assigned a standardized prefix (e.g., ff_, fa_, vc_, ffa_) identifying its deepfake category.
3.4. Dataset Validation and Quality Assessment
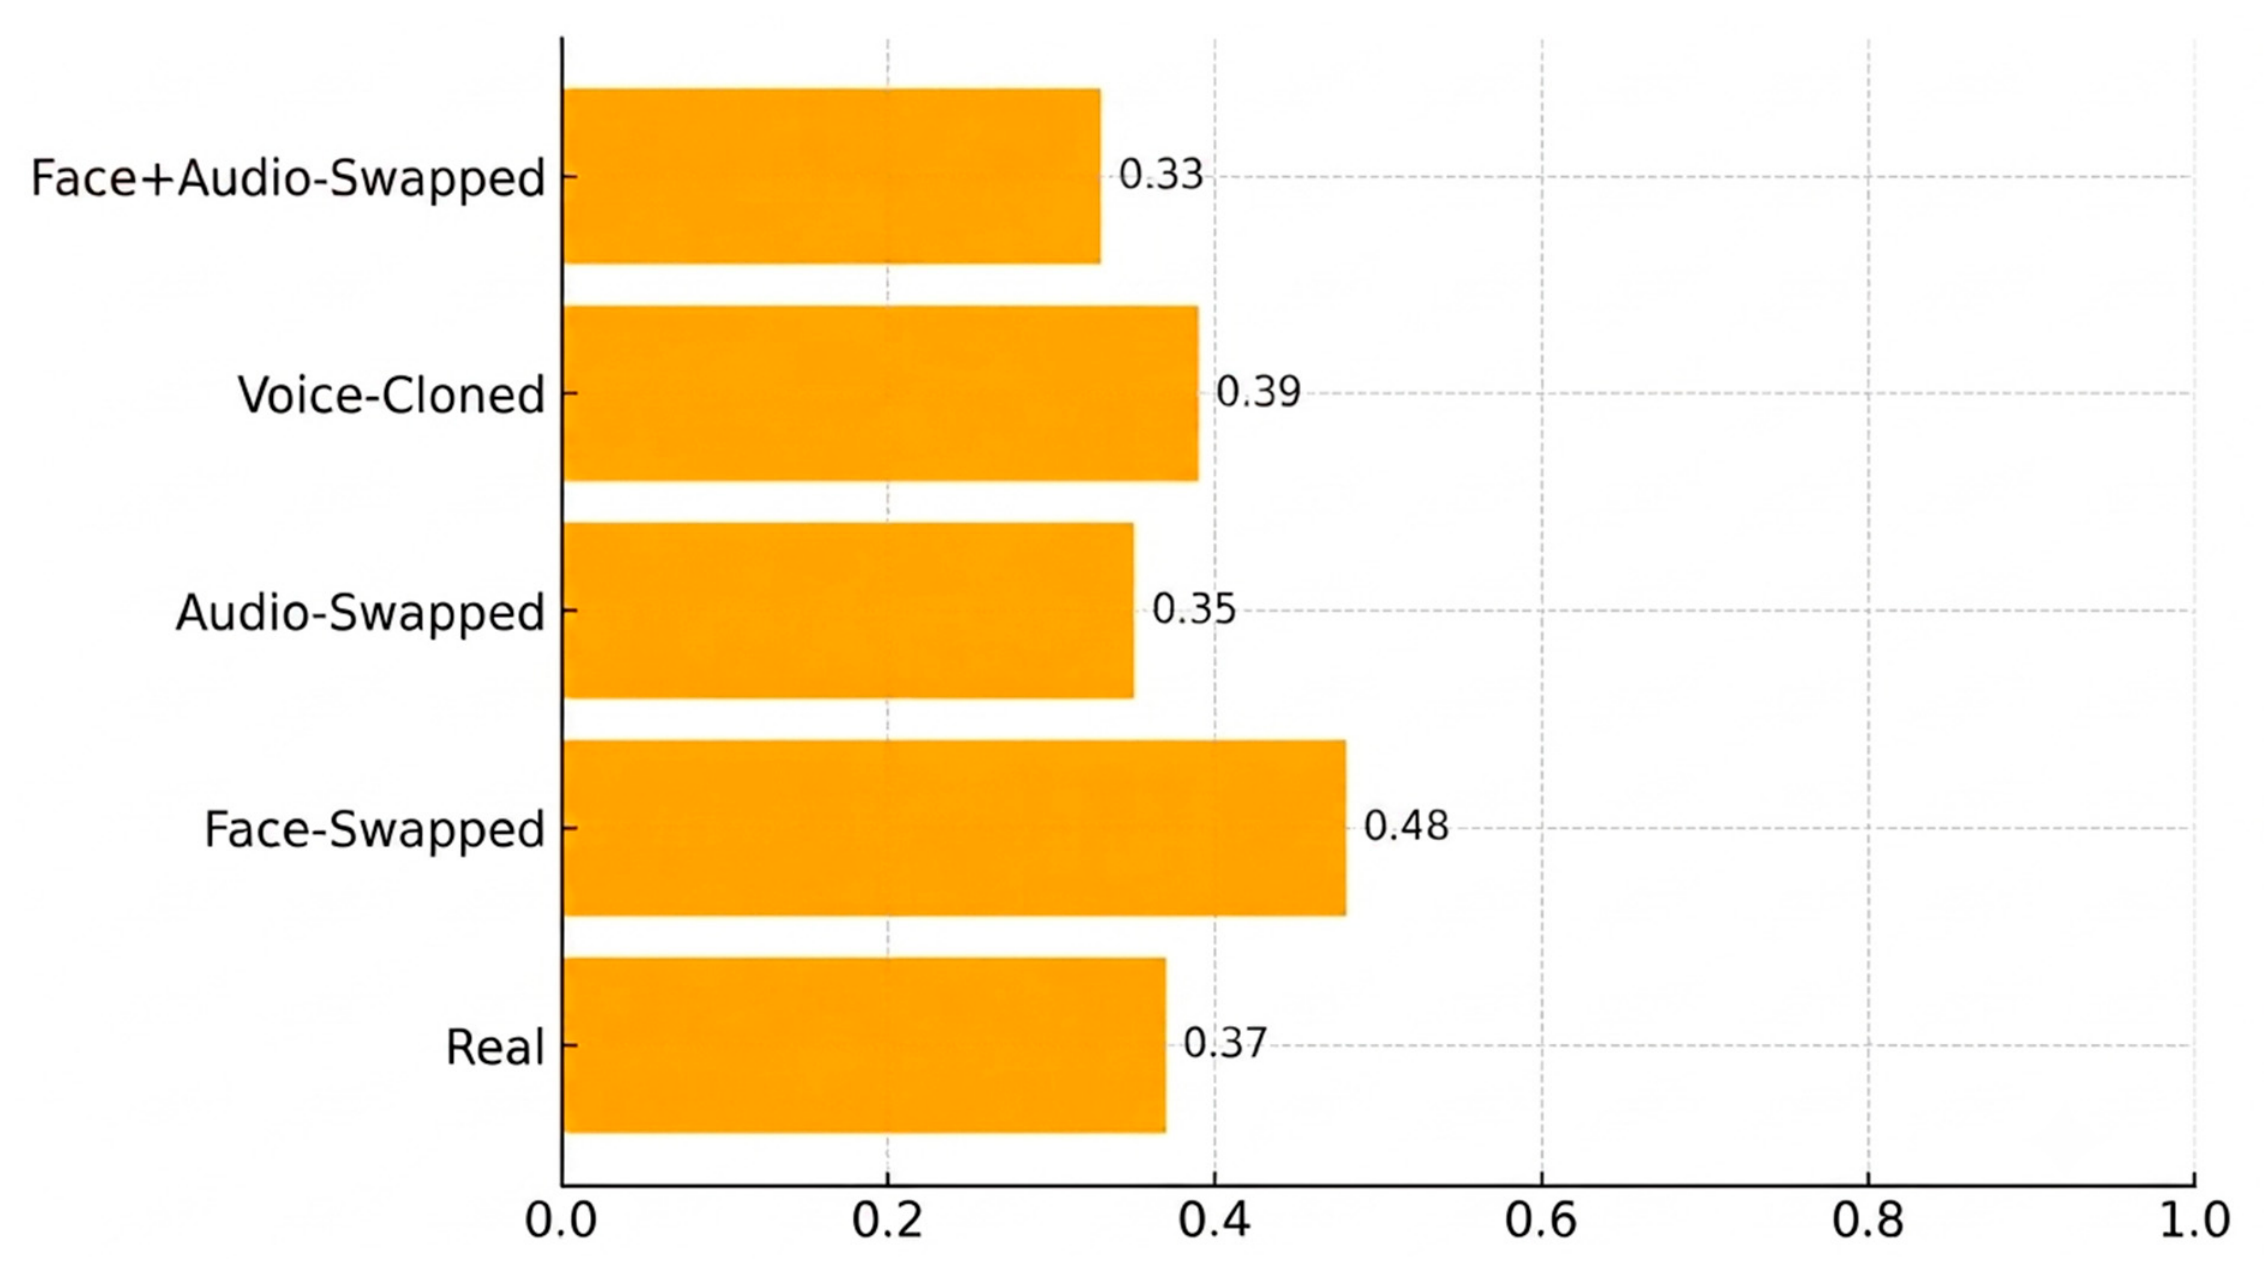
3.4.1. Visual Integrity Evaluation by Structural Similarity Index Measure (SSIM)
- -
- Real: 0.37 (range 0.15–0.61).
- -
- Face-swapped: 0.32 (range 0.16–0.66).
- -
- Audio-swapped: 0.35 (range 0.04–0.63).
- -
- Voice-cloned: 0.36 (range 0.19–0.98).
- -
- Face-and-audio-swapped: 0.44 (range 0.33–0.77).
3.4.2. Audio Feature Analysis
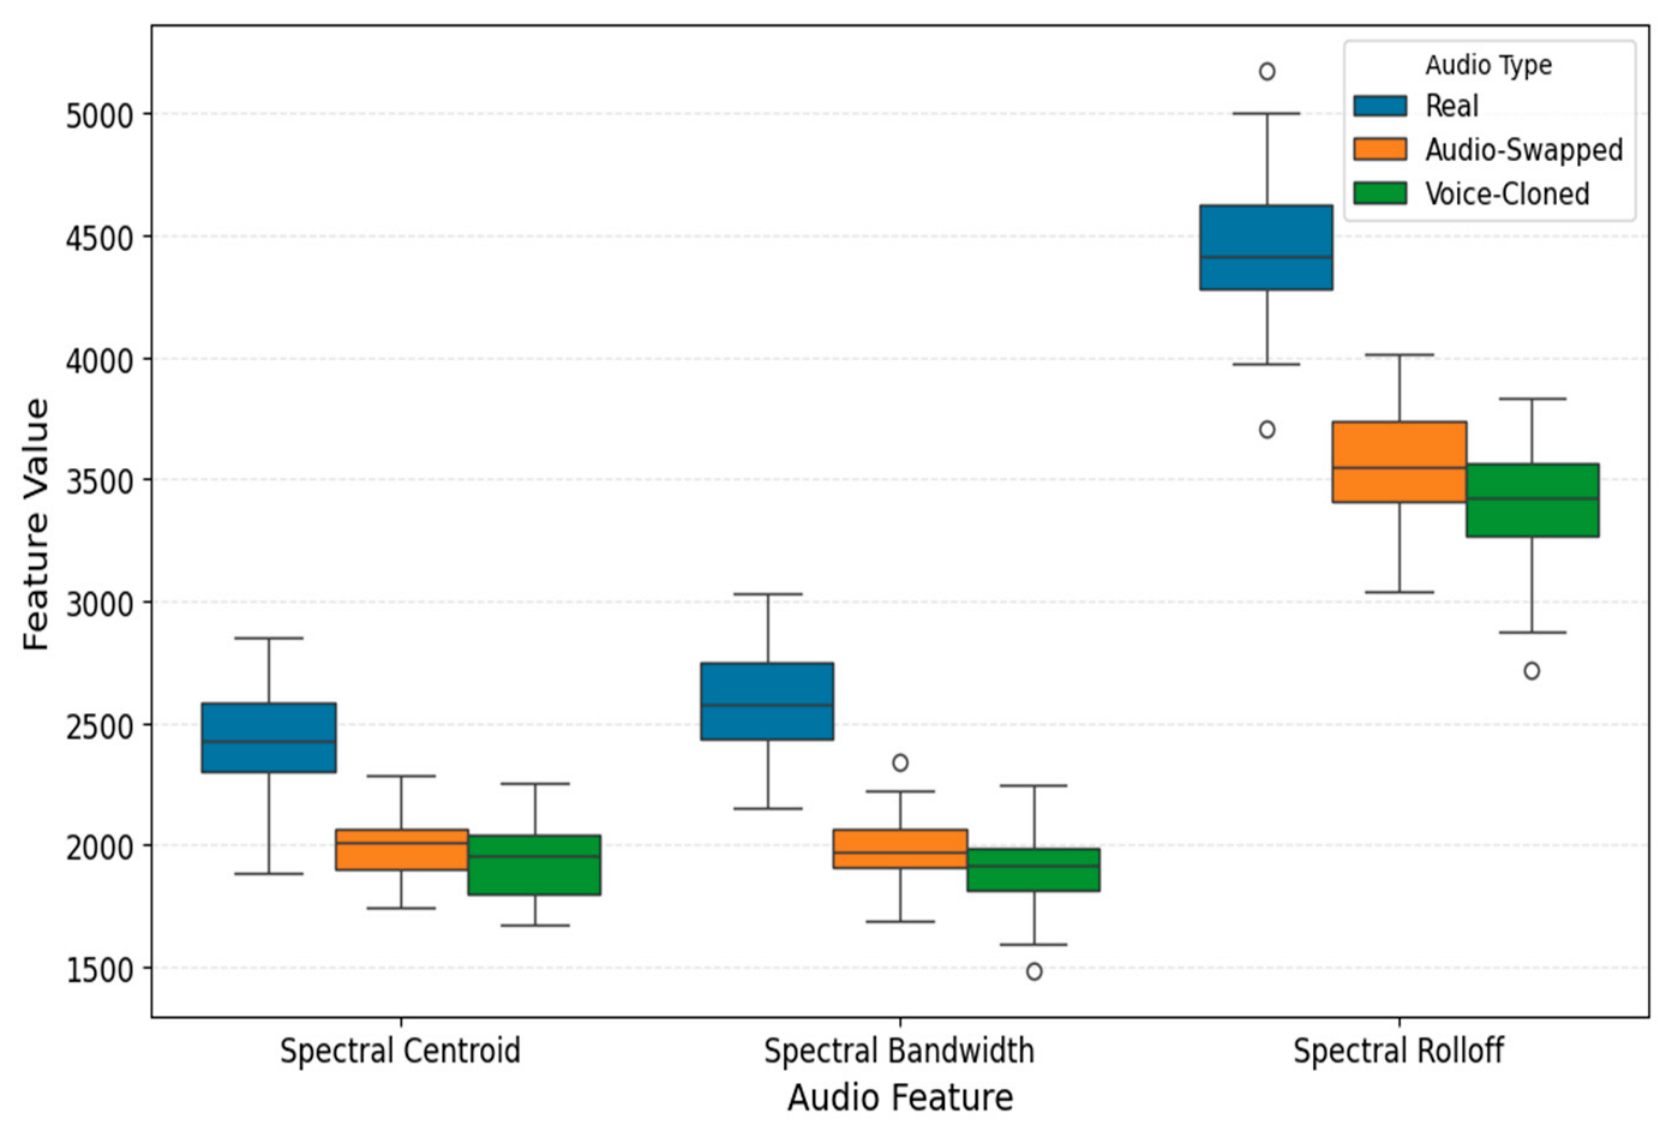
- Spectral centroid and Spectral Rolloff [17] capture spectral brightness distribution and overall energy concentration.
- Zero-crossing rate (ZCR) [5] measures waveform complexity and the rate of signal sign changes, reflecting transient characteristics.
- Mel-Frequency Cepstral Coefficients (MFCCs) [5] encode phonetic patterns and vocal-tract properties, and are widely used in speech and speaker recognition tasks.
- Audio generated through audio-swapping and voice-cloning techniques exhibited reduced spectral centroid and zero-crossing rate values, indicating more uniform and less complex waveform characteristics.
- The MFCCs extracted from synthetic clips were more uniform compared to real audio; however, inter-class differences remained sufficiently distinct to support effective classification.
- Real audio recordings exhibited a wider range of feature values, reflecting natural variation in pitch, timbre, and articulation.
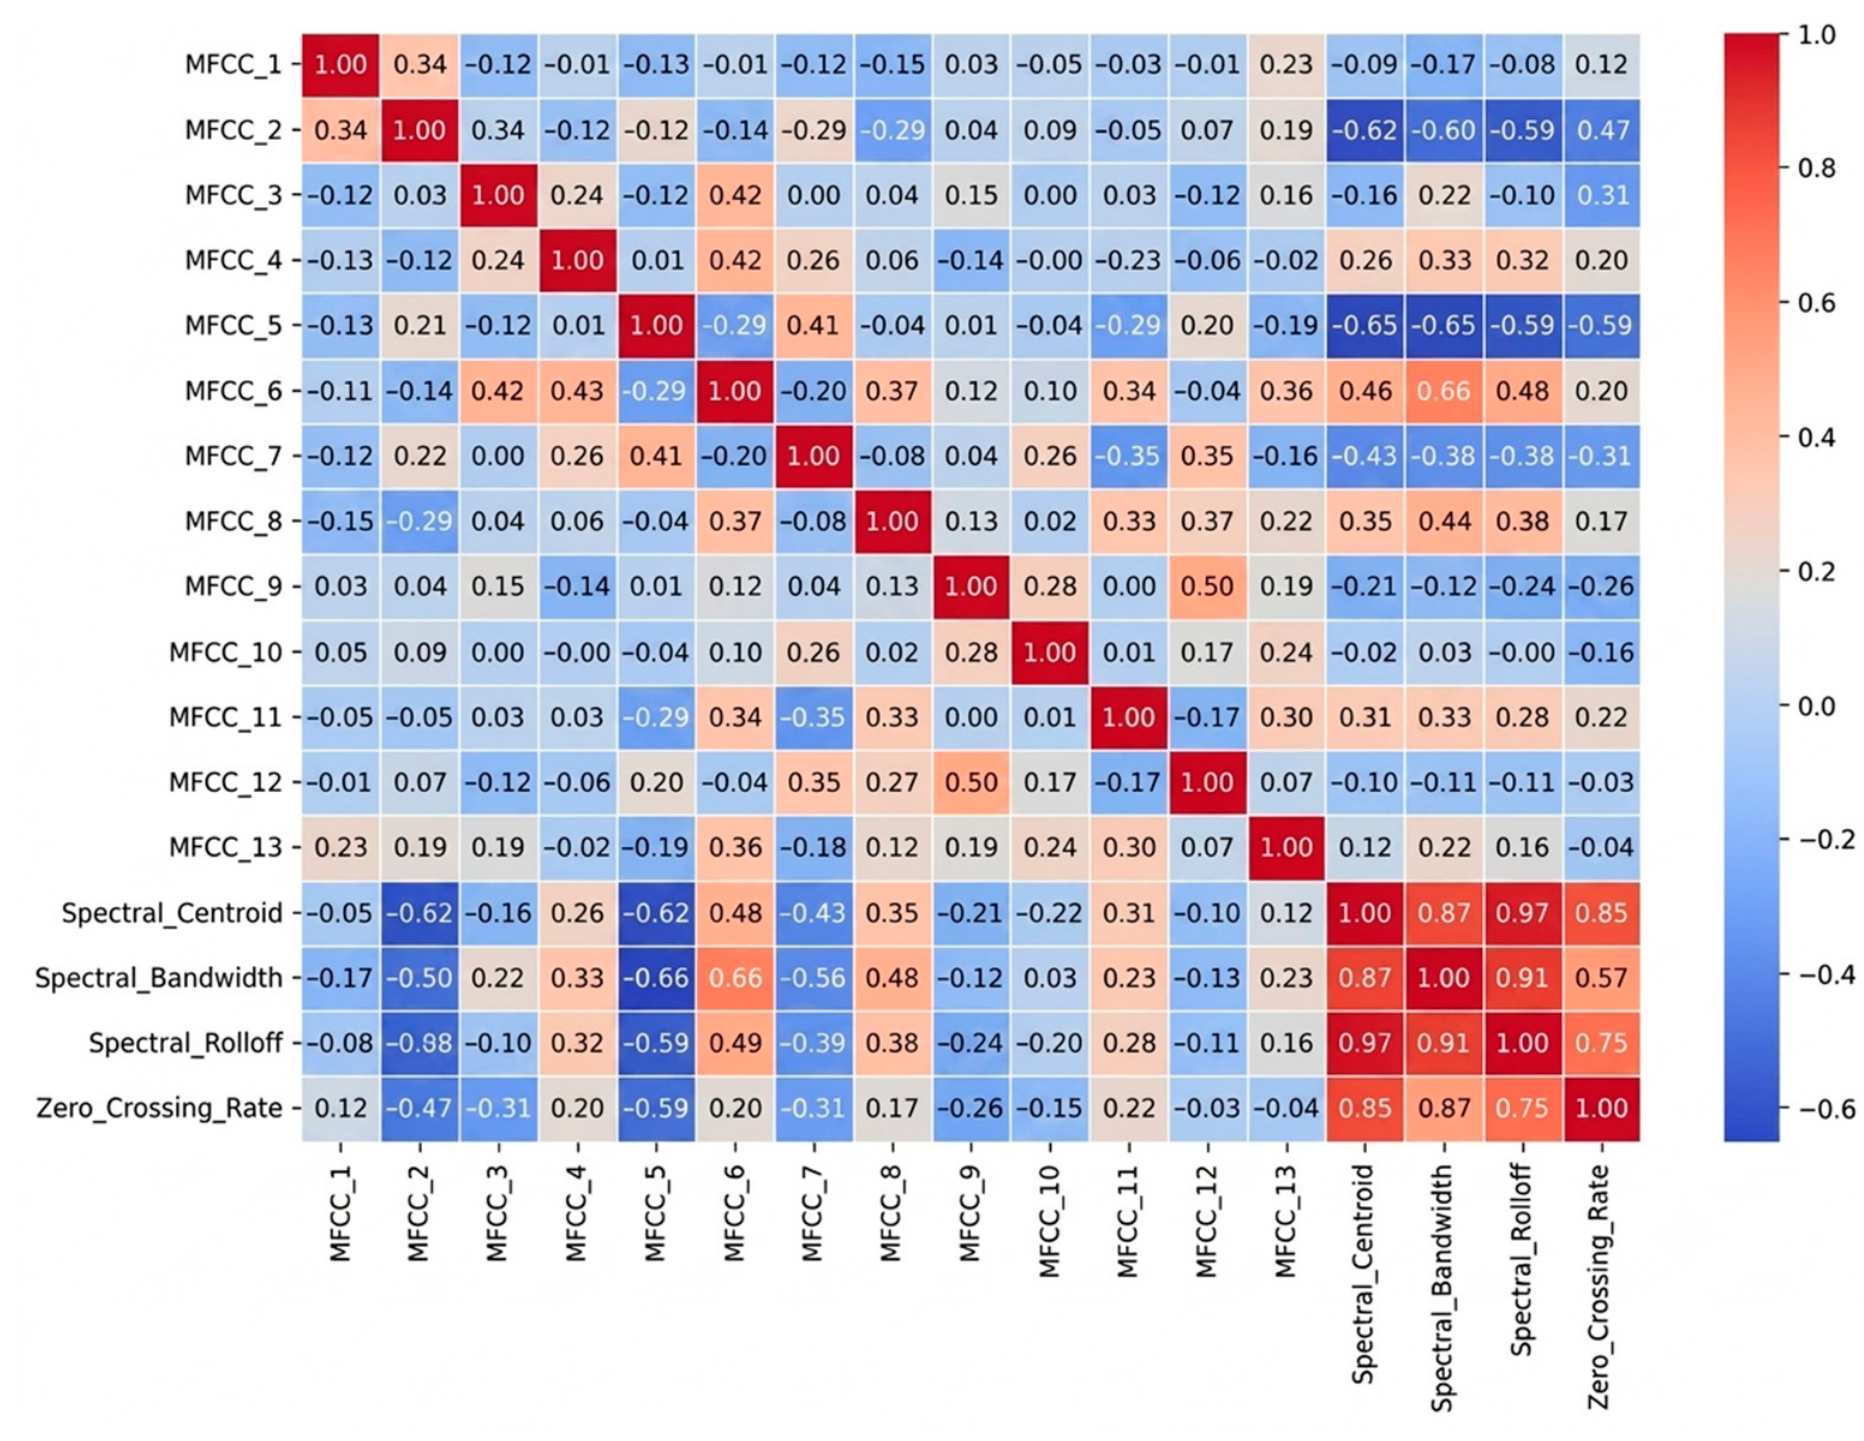
3.4.3. Audio Feature Correlation Heatmap
- Strong correlations among the spectral attributes of synthetic audio reflect the structured, algorithm-driven nature of the generation pipeline.
- Real audio exhibited weaker and more diffuse inter-feature correlations, consistent with the natural variability inherent in human speech.
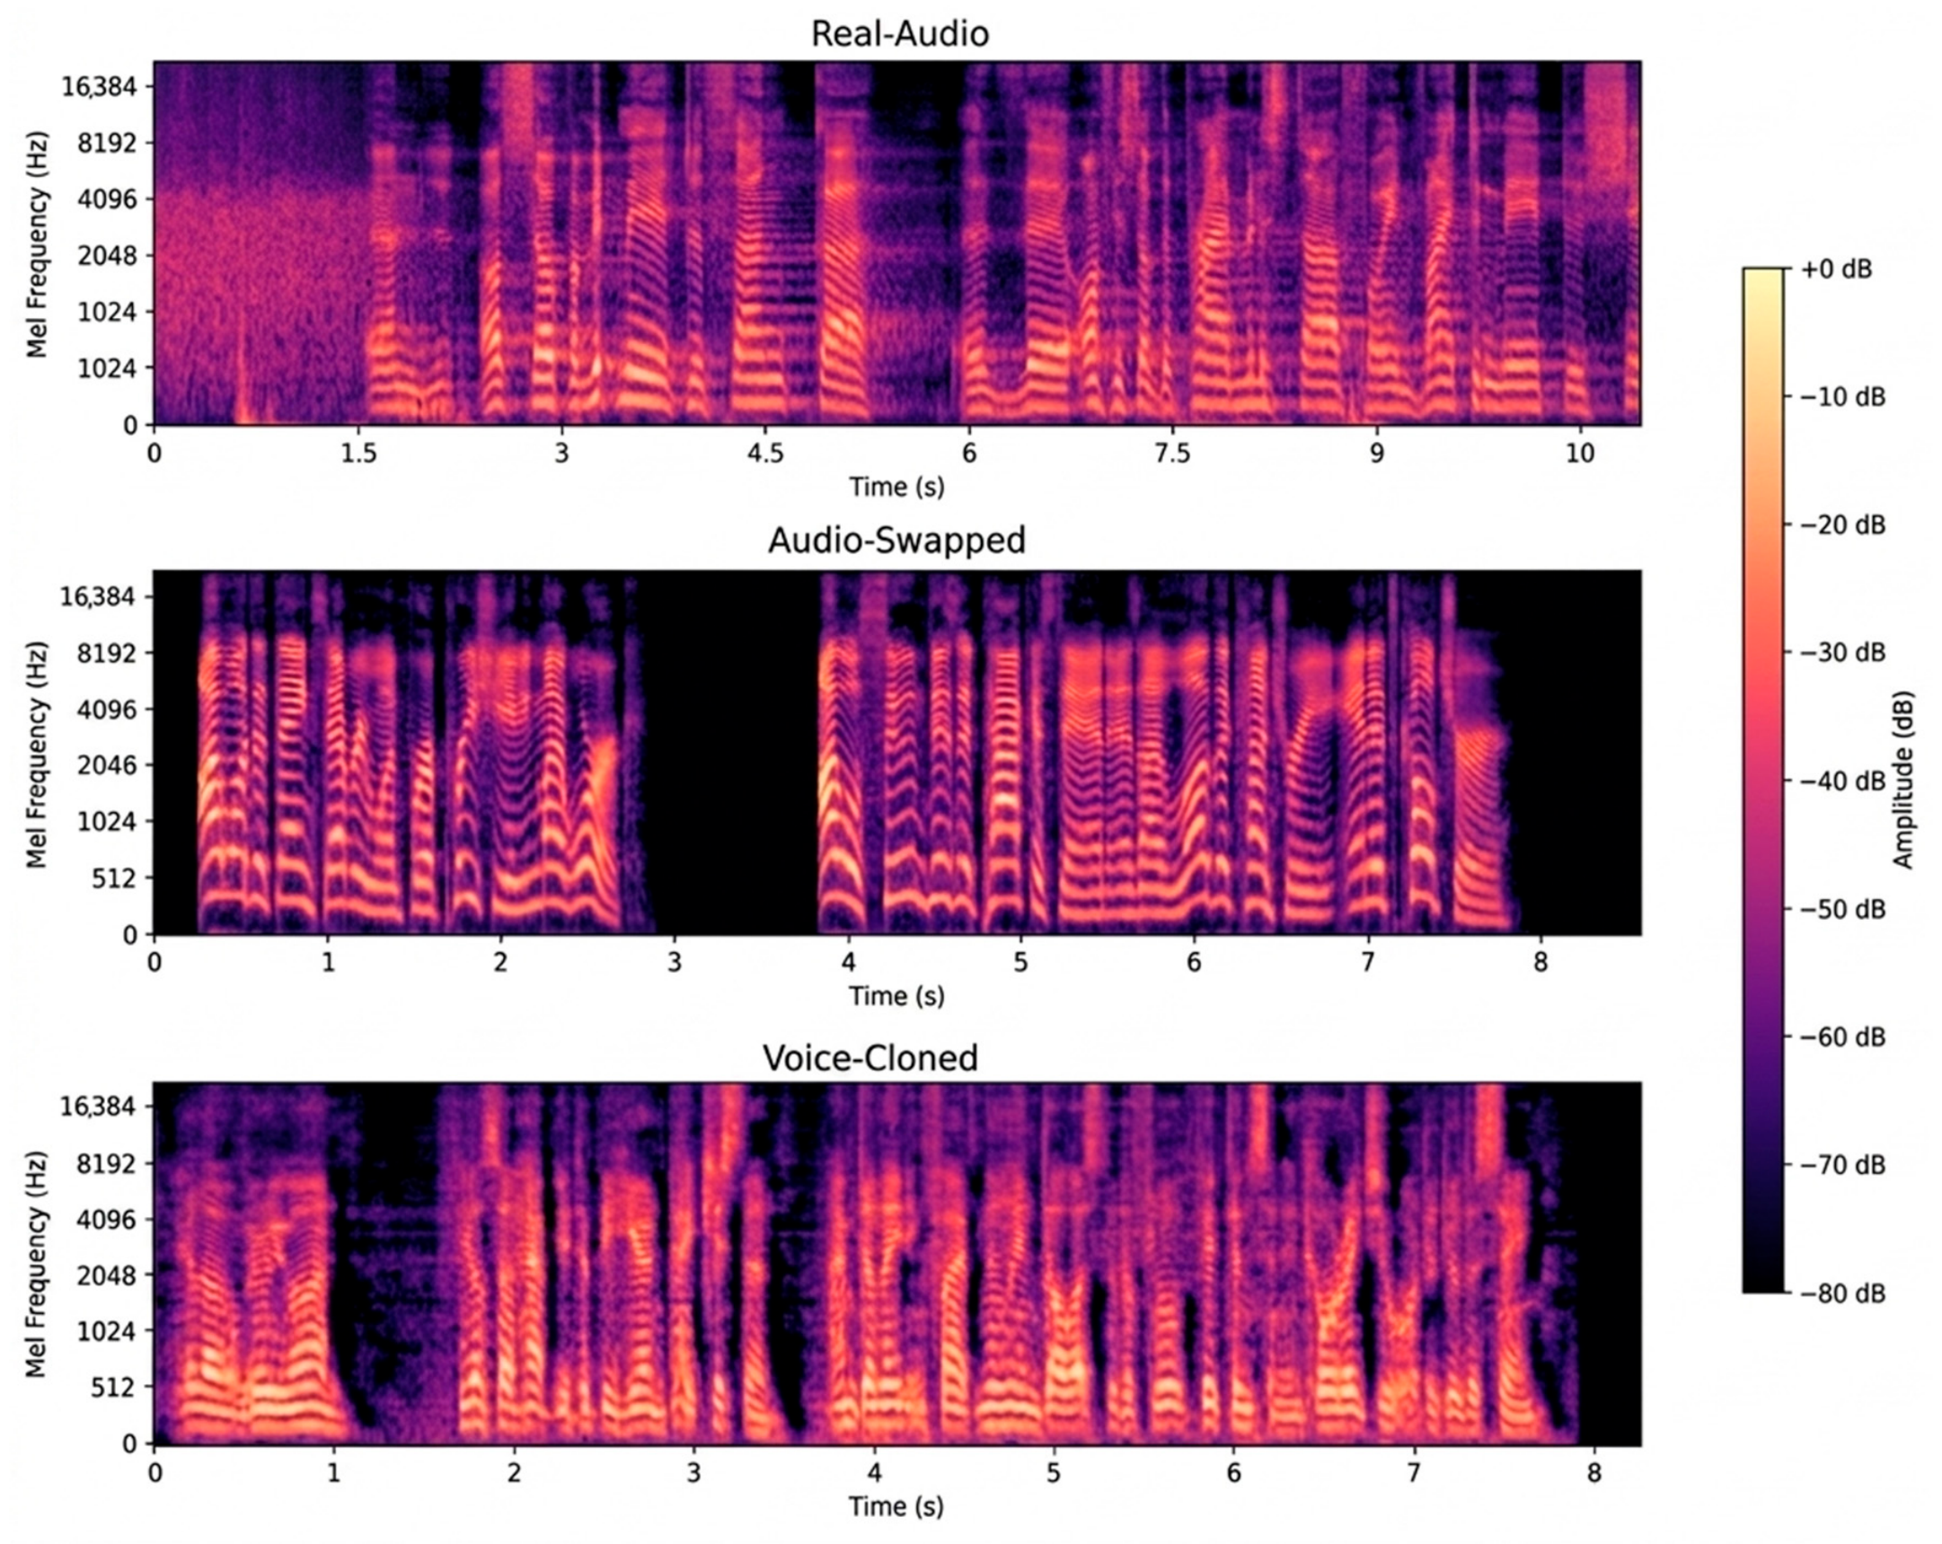
3.4.4. Spectrogram Comparison
- Real speech exhibited complex harmonic transitions and greater diversity in energy distribution across the time-frequency domain.
- Synthetic audio displayed flatter spectral profiles, characterized by smoother frequency bands and reduced temporal variation, consistent with the constrained output of generative synthesis pipelines.
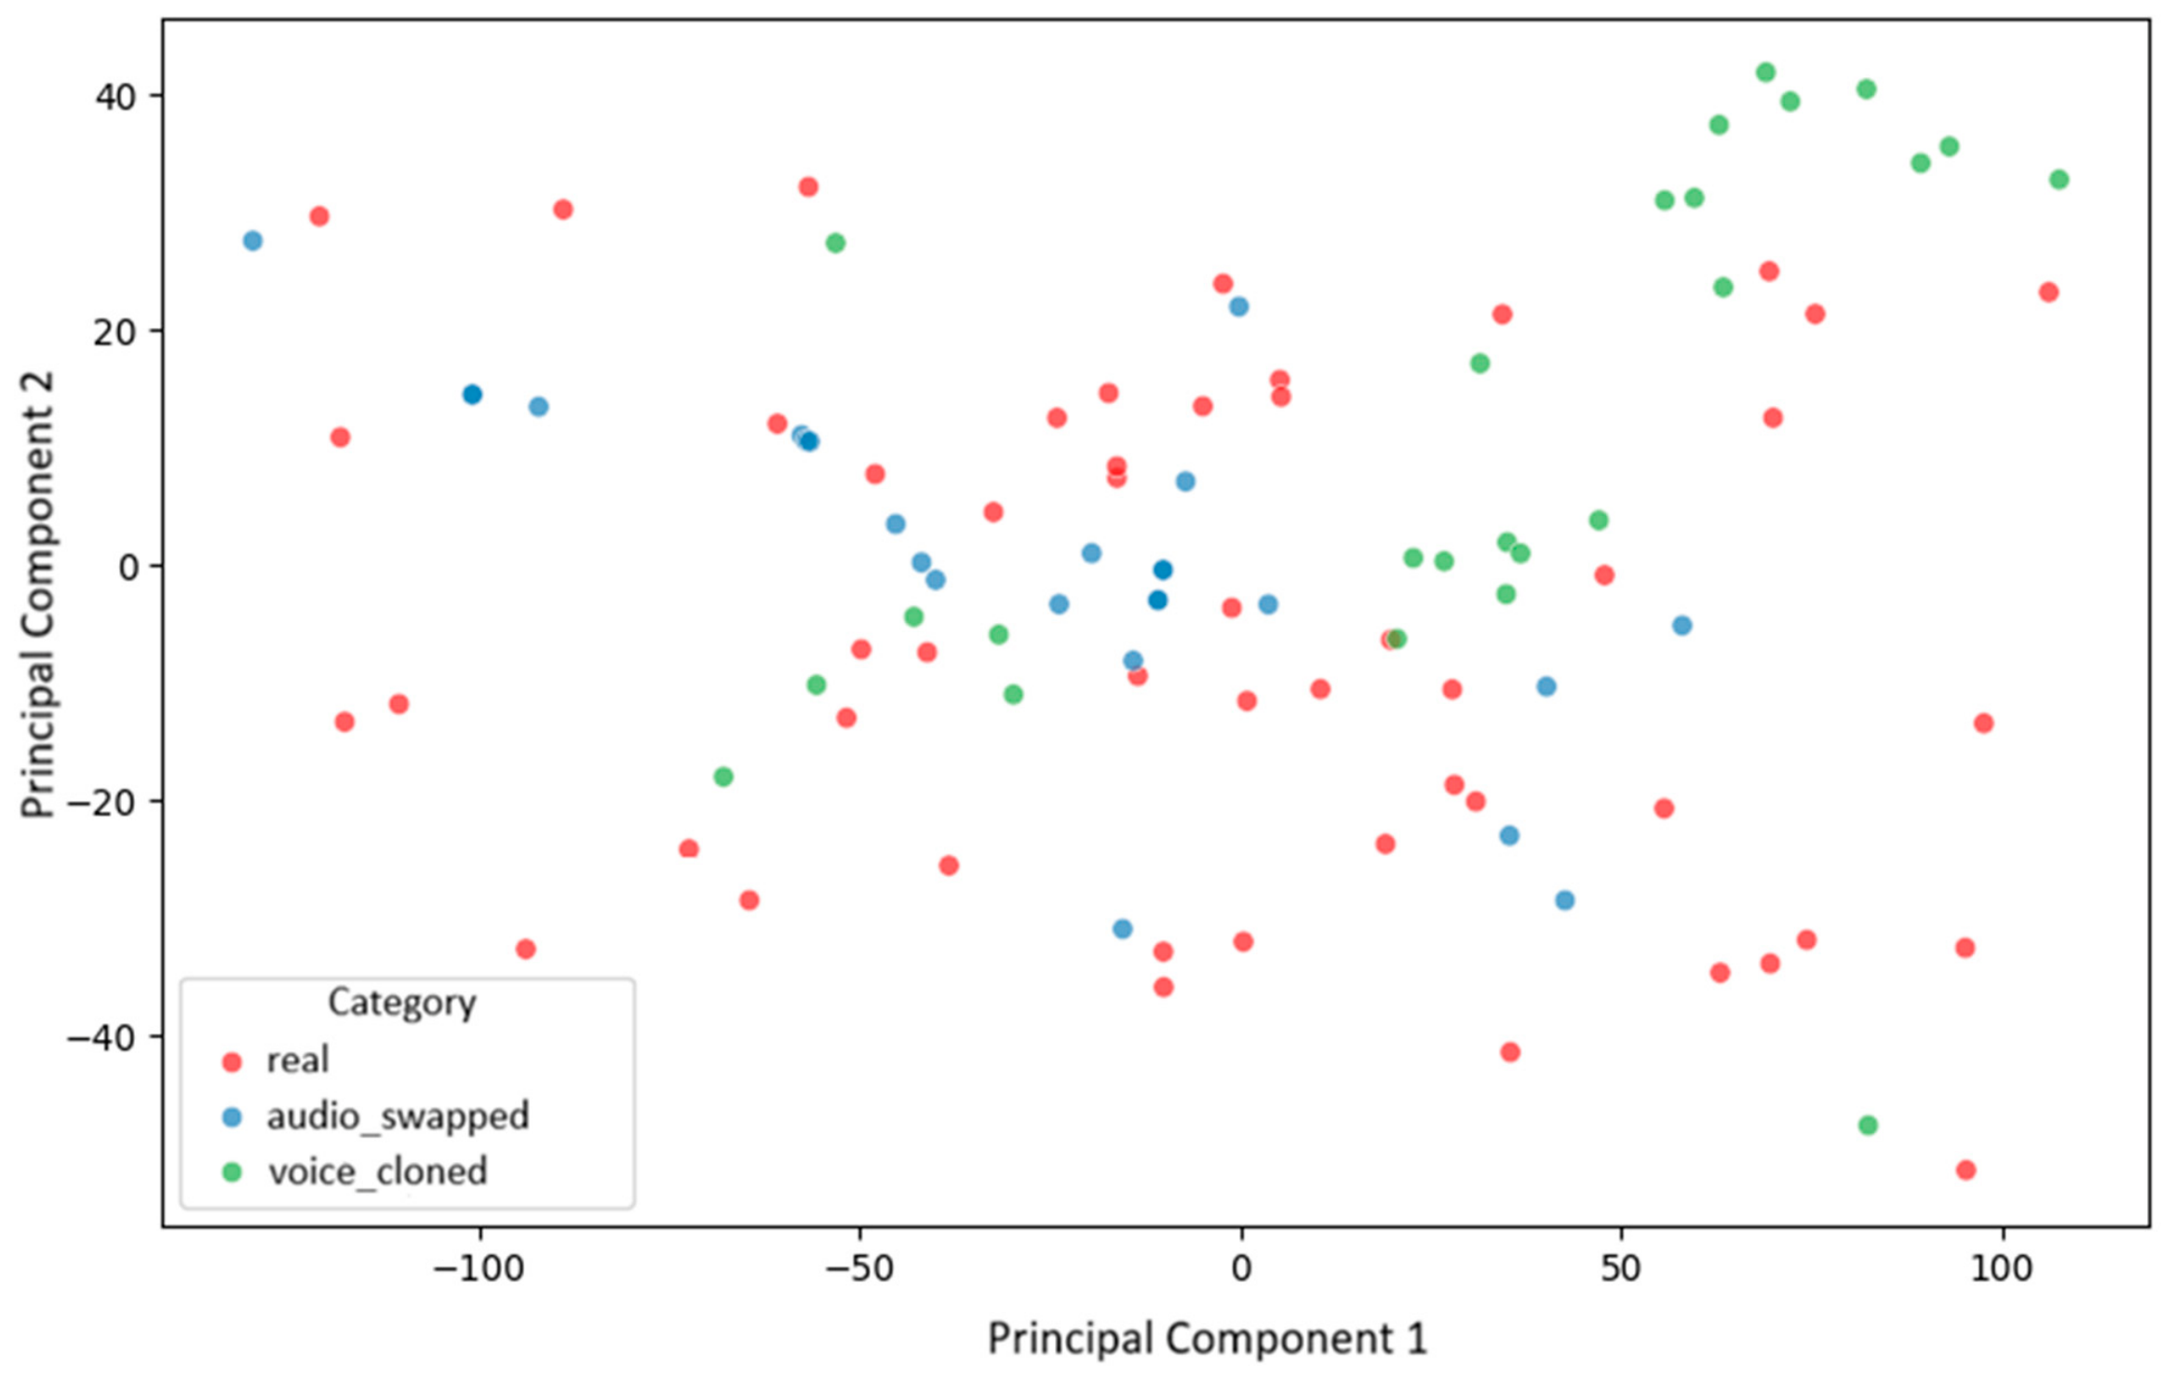
3.4.5. Principal Component Analysis of MFCC Features
- Synthetic samples exhibited tight clustering, suggesting relative homogeneity introduced by the synthesis pipeline.
- Real samples were more dispersed, reflecting the natural variability present in human speech.
3.4.6. Data Quality Assurance and Noise Mitigation
- Visible artifacts such as facial distortions and lip-synchronization mismatches.
- Misalignment between vocal and facial expressions.
- High levels of background noise or extended silent segments.
3.4.7. Benchmark Evaluation Using State-of-the-Art Detection Models
- -
- Visual-only detectors targeting face-swap manipulations (MesoNet, GenConViT, AltFreezing, FreqNet, CNN-based Ensemble) were evaluated on the 500 face-swapped videos plus the 200 real reference videos.
- -
- Audio-only detectors (Synthetic Speech Detection, FakeSound, RawNet2Vocoder) were evaluated on the 100 audio-swapped or 100 voice-cloned videos (as appropriate to each model’s published scope) plus the 200 real reference videos.
- -
- Audiovisual and lip-synchronization detectors (SyncNet, SyncNet with Frequency, LIPINC) were evaluated on the audio-swapped, voice-cloned, and combined face-and-audio-swapped subsets plus the 200 real reference videos.
- -
- Multimodal detectors (FakeAVCeleb Ensemble, REFEREE, AVT2-DWF, Not Made for Each Other) were evaluated on all 800 synthetic videos plus the 200 real reference videos.
3.5. Ethical Considerations
4. Dataset Novelty and Research Relevance
- Evaluation of deepfake detection performance across many modalities (visual, audio, and multimodal).
- Generalization testing across diverse languages, demographic groups, and real-world scenarios.
- Development of bias-aware and explainable deepfake detection models.
- Enhancement of audiovisual coherence analysis for digital forensic investigation.

| Dataset | Face Swap | Audio Swap | Voice Cloning | Multimodal | Demographic Diversity | Language Diversity | Realistic Scenarios |
|---|---|---|---|---|---|---|---|
| FaceForensics++ [35] | ✓ | X | X | X | Medium | Low | Partial |
| Celeb-DF v2 [37] | ✓ | X | X | X | Medium | Low | Partial |
| DFDC [36] | ✓ | Δ | Δ | ✓ | High | Low | Partial |
| DeepFake-TIMIT [38] | ✓ | X | X | X | Low | Low | No |
| FakeAVCeleb [19] | ✓ | X | ✓ | ✓ | High | Medium | Partial |
| DeepFakeX (Proposed) | ✓ | ✓ | ✓ | ✓ | High | Medium | Full |
5. Limitations
6. User Notes
- Train and evaluate deepfake detection systems across visual, audio, and multimodal frameworks.
- Examine model robustness and generalization across diverse synthesis techniques.
- Conduct research in digital media forensics, synthetic media detection, and content authenticity verification.
Author Contributions
Funding
Institutional Review Board Statement
Informed Consent Statement
Data Availability Statement
Acknowledgments
Conflicts of Interest
Abbreviations
| MFCC | Mel-Frequency Cepstral Coefficients |
| SSIM | Structural Similarity Index Measure |
| ZCR | Zero Crossing Rate |
| PCA | Principal Component Analysis |
| H.264 | Advanced Video Coding Standard |
| CC BY-NC | Creative Commons Attribution NonCommercial License |
References
- Salman, S.; Shamsi, J.A. Comparison of Deepfakes Detection Techniques. In Proceedings of the 2023 3rd International Conference on Artificial Intelligence (ICAI), Islamabad, Pakistan, 22 February 2023; pp. 227–232. [Google Scholar]
- Salman, S.; Shamsi, J.A.; Qureshi, R. Deep Fake Generation and Detection: Issues, Challenges, and Solutions. IT Prof. 2023, 25, 52–59. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.; Bovik, A.C.; Sheikh, H.R.; Simoncelli, E.P. Image Quality Assessment: From Error Visibility to Structural Similarity. IEEE Trans. Image Process. 2004, 13, 600–612. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zafar, F.; Khan, T.A.; Akbar, S.; Ubaid, M.T.; Javaid, S.; Kadir, K.A. A Hybrid Deep Learning Framework for Deepfake Detection Using Temporal and Spatial Features. IEEE Access 2025, 13, 79560–79570. [Google Scholar] [CrossRef] [Scilit]
- Hamza, A.; Javed, A.R.R.; Iqbal, F.; Kryvinska, N.; Almadhor, A.S.; Jalil, Z.; Borghol, R. Deepfake Audio Detection via MFCC Features Using Machine Learning. IEEE Access 2022, 10, 134018–134028. [Google Scholar] [CrossRef] [Scilit]
- Perov, I.; Gao, D.; Chervoniy, N.; Liu, K.; Marangonda, S.; Umé, C.; Dpfks; Facenheim, C.S.; RP, L.; Jiang, J.; et al. DeepFaceLab: Integrated, Flexible and Extensible Face-Swapping Framework. arXiv 2021, arXiv:2005.05535. [Google Scholar]
- Chen, R.; Chen, X.; Ni, B.; Ge, Y. SimSwap: An Efficient Framework for High Fidelity Face Swapping. In Proceedings of the Proceedings of the 28th ACM International Conference on Multimedia, Seattle, WA, USA, 12–16 October 2020; pp. 2003–2011. [Google Scholar]
- Siarohin, A.; Lathuilière, S.; Tulyakov, S.; Ricci, E.; Sebe, N. First Order Motion Model for Image Animation. In Proceedings of the 33rd International Conference on Neural Information Processing Systems; Curran Associates Inc.: Red Hook, NY, USA, 2020. [Google Scholar]
- Swapface. Available online: https://www.swapface.org/#/home (accessed on 20 August 2024).
- Reface—AI Face Swap App & Video Face Swaps. Available online: https://reface.ai/ (accessed on 20 August 2024).
- Prajwal, K.R.; Mukhopadhyay, R.; Namboodiri, V.P.; Jawahar, C.V. A Lip Sync Expert Is All You Need for Speech to Lip Generation In the Wild. In Proceedings of the 28th ACM International Conference on Multimedia, Seattle, WA, USA, 12–16 October 2020; pp. 484–492. [Google Scholar]
- Pika. Available online: https://pika.art/ (accessed on 30 May 2024).
- Lalamu Studio. Available online: https://www.canva.com/your-apps/AAF5prtvncA/lalamu-studio?q=Lalamu+Studio (accessed on 20 August 2024).
- Free Text to Speech & AI Voice Generator|ElevenLabs. Available online: https://elevenlabs.io/ (accessed on 15 April 2025).
- PlayHT. Available online: https://playhtai.com/ (accessed on 15 April 2025).
- Gooey.AI—The Best of Private & Open Source AI. Available online: https://gooey.ai/ (accessed on 15 April 2025).
- Kumar, V.; Kapoor, A.; Chaudhary, R.R.; Gupta, L.; Khokhar, D. Preserving Integrity: A Binary Classification Approach to Unmasking Artificially Generated Voices in the Age of Deepkakes. In Proceedings of the 2024 11th International Conference on Computing for Sustainable Global Development (INDIACom), New Delhi, India, 28 February–1 March 2024; pp. 1449–1454. [Google Scholar]
- Amerini, I.; Barni, M.; Battiato, S.; Bestagini, P.; Boato, G.; Bruni, V.; Caldelli, R.; De Natale, F.; De Nicola, R.; Guarnera, L.; et al. Deepfake Media Forensics: Status and Future Challenges. J. Imaging 2025, 11, 73. [Google Scholar] [CrossRef] [Scilit]
- Khalid, H.; Tariq, S.; Kim, M.; Woo, S.S. FakeAVCeleb: A Novel Audio-Video Multimodal Deepfake Dataset. arXiv 2022, arXiv:2108.05080. [Google Scholar]
- Xie, Z.; Li, B.; Xu, X.; Liang, Z.; Yu, K.; Wu, M. FakeSound: Deepfake General Audio Detection. arXiv 2024, arXiv:2406.08052. [Google Scholar] [CrossRef] [Scilit]
- Boo, H.; Lee, E.; Lee, J. Referee: Reference-Aware Audiovisual Deepfake Detection. arXiv 2025, arXiv:2510.27475. [Google Scholar]
- Tak, H.; Patino, J.; Todisco, M.; Nautsch, A.; Evans, N.; Larcher, A. End-to-End Anti-Spoofing with RawNet2. In Proceedings of the ICASSP 2021—2021 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Toronto, ON, Canada, 6–11 June 2021; pp. 6369–6373. [Google Scholar]
- Datta, S.K.; Jia, S.; Lyu, S. Exposing Lip-Syncing Deepfakes from Mouth Inconsistencies. In Proceedings of the 2024 IEEE International Conference on Multimedia and Expo (ICME), Niagara Falls, ON, Canada, 15–19 July 2024. [Google Scholar]
- Wang, Z.; Bao, J.; Zhou, W.; Wang, W.; Li, H. AltFreezing for More General Video Face Forgery Detection. In Proceedings of the 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, BC, Canada, 17–24 June 2023; pp. 4129–4138. [Google Scholar]
- Wang, R.; Ye, D.; Tang, L.; Zhang, Y.; Deng, J. AVT2-DWF: Improving Deepfake Detection with Audio-Visual Fusion and Dynamic Weighting Strategies. IEEE Signal Process. Lett. 2024, 31, 1960–1964. [Google Scholar] [CrossRef] [Scilit]
- Tan, C.; Zhao, Y.; Wei, S.; Gu, G.; Liu, P.; Wei, Y. Frequency-Aware Deepfake Detection: Improving Generalizability through Frequency Space Domain Learning. Proc. AAAI Conf. Artif. Intell. 2024, 38, 5052–5060. [Google Scholar] [CrossRef] [Scilit]
- Afchar, D.; Nozick, V.; Yamagishi, J.; Echizen, I. MesoNet: A Compact Facial Video Forgery Detection Network. In Proceedings of the 2018 IEEE International Workshop on Information Forensics and Security (WIFS), Hong Kong, China, 11–13 December 2018; pp. 1–7. [Google Scholar]
- Bonettini, N.; Cannas, E.D.; Mandelli, S.; Bondi, L.; Bestagini, P.; Tubaro, S. Video Face Manipulation Detection Through Ensemble of CNNs. In Proceedings of the 2020 25th International Conference on Pattern Recognition (ICPR), Milan, Italy, 10–15 January 2021. [Google Scholar]
- Chugh, K.; Gupta, P.; Dhall, A.; Subramanian, R. Not Made for Each Other- Audio-Visual Dissonance-Based Deepfake Detection and Localization. In Proceedings of the 28th ACM International Conference on Multimedia, Seattle, WA, USA, 12–16 October 2020; pp. 439–447. [Google Scholar]
- Towards End-to-End Synthetic Speech Detection|IEEE Journals & Magazine|IEEE Xplore. Available online: https://ieeexplore.ieee.org/document/9456037 (accessed on 31 May 2024).
- Deressa, D.W.; Mareen, H.; Lambert, P.; Atnafu, S.; Akhtar, Z.; Van Wallendael, G. Deepfake Video Detection Using Generative Convolutional Vision Transformer. arXiv 2023, arXiv:2307.07036. [Google Scholar] [CrossRef] [Scilit]
- European Parliament; Council of the European Union. Regulation (EU) 2016/679 of the European Parliament and of the Council of 27 April 2016 on the Protection of Natural Persons with Regard to the Processing of Personal Data and on the Free Movement of Such Data (General Data Protection Regulation). Off. J. Eur. Union 2016, L119, 1–88. [Google Scholar]
- IEEE. IEEE Code of Ethics; IEEE: Piscataway, NJ, USA, 2024. [Google Scholar]
- Association for Computing Machinery. ACM Code of Ethics and Professional Conduct; ACM: New York, NY, USA, 2018. [Google Scholar]
- Rossler, A.; Cozzolino, D.; Verdoliva, L.; Riess, C.; Thies, J.; Niessner, M. FaceForensics++: Learning to Detect Manipulated Facial Images. In Proceedings of the 2019 IEEE/CVF International Conference on Computer Vision (ICCV), Seoul, Republic of Korea, 27 October–2 November 2019; pp. 1–11. [Google Scholar]
- Dolhansky, B.; Bitton, J.; Pflaum, B.; Lu, J.; Howes, R.; Wang, M.; Ferrer, C.C. The DeepFake Detection Challenge (DFDC) Dataset. arXiv 2020, arXiv:2006.07397. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Yang, X.; Sun, P.; Qi, H.; Lyu, S. Celeb-DF: A Large-Scale Challenging Dataset for DeepFake Forensics. In Proceedings of the 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 3204–3213. [Google Scholar]
- Korshunov, P.; Marcel, S. DeepFakes: A New Threat to Face Recognition? Assessment and Detection. arXiv 2018, arXiv:1812.08685. [Google Scholar] [CrossRef] [Scilit]


| Prefix | Type of Deepfake |
|---|---|
| ff_ | Face-swapped |
| fa_ | Audio-swapped |
| vc_ | Voice-cloned |
| ffa_ | Face- + audio-swapped |
| Attribute | Demographic Category | Proportion (%) |
|---|---|---|
| Ethnicity | South Asian | 37.8 |
| Caucasian | 32.7 | |
| East Asian | 15.3 | |
| African | 14.3 | |
| Gender Identity | Male | 51.0 |
| Female | 47.0 | |
| Transgender | 2.0 | |
| Age Group | Young-aged | 19.2 |
| Middle-aged | 60.6 | |
| Older Adults | 20.2 | |
| Video Context | News segments | 12.7 |
| Speeches | 22.4 | |
| Informational/Video clips | 34.7 | |
| Interviews | 23.5 | |
| Film Excerpts | 7.1 |
| Deepfake Category | Generation Tools/Platforms | Number of Videos |
|---|---|---|
| Face-swapped | DeepFaceLab [6], SimSwap [7], First Order Motion Model [8], SwapFace [9], Reface [10] | 500 |
| Audio-swapped | Wav2Lip [11], Pika Labs [12], Lalamu Studio [13] | 100 |
| Voice-cloned | ElevenLabs [14], Play.ht [15], Gooey.ai [16], Lalamu Studio [13] | 100 |
| Combined (Face + Audio) swapped | Combination of face-swap and audio-swap tools listed above | 100 |
| Model | Detection Modality | Applied Deepfake Types | F1-Score |
|---|---|---|---|
| FakeAVCeleb Ensemble [19] | Audio–Visual | All deepfake types | 0.81 |
| FakeSound [20] | Audio-only | Audio-swapped, voice-cloned | 0.69 |
| REFEREE [21] | Audio–Visual | All deepfake types | 0.64 |
| RawNet2Vocoder [22] | Audio-only | Voice-cloned | 0.76 |
| LIPINC [23] | Visual-only | Audio-swapped | 0.75 |
| AltFreezing [24] | Visual-only | Face-swapped | 0.75 |
| AVT2-DWF [25] | Audio–Visual | All deepfake types | 0.80 |
| FreqNet [26] | Visual-only | Face-swapped | 0.70 |
| SyncNet [11] | Audio–Visual | Audio-swapped | 0.20 |
| SyncNet with Frequency [2] | Audio–Visual | All deepfake types | 0.69 |
| MesoNet [27] | Visual-only | Face-swapped | 0.54 |
| CNN-based Ensemble (Face Manipulation) [28] | Visual-only | Face-swapped | 0.35 |
| Not Made for Each Other [29] | Audio–Visual | All deepfake types | 0.62 |
| Synthetic Speech Detection [30] | Audio-only | Audio-swapped | 0.54 |
| GenConViT (Hybrid CNN-Transformer) [31] | Visual-only | Face-swapped | 0.68 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Salman, S.; Shamsi, J.A.; Qureshi, R. DeepFakeX: A Comprehensive Multimodal Deepfake Dataset for Research and Analysis. Data 2026, 11, 141. https://doi.org/10.3390/data11060141
Salman S, Shamsi JA, Qureshi R. DeepFakeX: A Comprehensive Multimodal Deepfake Dataset for Research and Analysis. Data. 2026; 11(6):141. https://doi.org/10.3390/data11060141
Chicago/Turabian StyleSalman, Sonia, Jawwad Ahmed Shamsi, and Rizwan Qureshi. 2026. "DeepFakeX: A Comprehensive Multimodal Deepfake Dataset for Research and Analysis" Data 11, no. 6: 141. https://doi.org/10.3390/data11060141
APA StyleSalman, S., Shamsi, J. A., & Qureshi, R. (2026). DeepFakeX: A Comprehensive Multimodal Deepfake Dataset for Research and Analysis. Data, 11(6), 141. https://doi.org/10.3390/data11060141