


Abstract
This paper presents a comparative study on the impact of robust hashing in enhancing image-based malware classification. While Convolutional Neural Networks (CNNs) have shown promise when working with image-based malware samples, their performance degrades significantly when obfuscation techniques are taken into consideration to hamper the malware classification or detection. To address this, we apply a robust hashing technique that generates invariant visual representations of malware samples, enabling improved generalization under obfuscation implemented as image salting. Using a custom obfuscation method to simulate polymorphic variants, we evaluate MobileNet, ResNet, and DenseNet architectures across five salting conditions (0% to 40%). The results demonstrate that robust hashing substantially boosts classification accuracy, with DenseNet achieving 89.50% on unsalted data, compared to only 68.00% without hashing. Across all salting levels, models consistently performed better when robust hashing was applied, confirming its effectiveness in preserving structural features and mitigating adversarial noise. These findings position robust hashing as a powerful preprocessing strategy for resilient malware detection.
1. Introduction
Cybersecurity threats are evolving rapidly in both complexity and scope, driven by the accelerating pace of technological advancement. These threats impact individuals, organizations, and nations alike. Among them, malware, malicious software designed to compromise devices, remains one of the most persistent and damaging [1]. In response to traditional detection methods, attackers are increasingly adopting tactics such as data obfuscation, which obscure identifying characteristics and make malicious code harder to detect and classify [2].
Machine learning, particularly Convolutional Neural Networks (CNNs), has emerged as a powerful tool in modern cybersecurity due to its capacity to automatically learn complex and abstract features from large volumes of malware image data [3]. However, despite notable progress in CNN-based malware detection, these models often experience significant performance degradation when evaluated against obfuscated samples [3]. This limitation highlights the need to enhance the robustness and adaptability of detection systems. An effective model must accurately identify malware families, even when obfuscation introduces conflicting or misleading visual patterns.
While prior obfuscation-resilient approaches have attempted to address this issue, many rely on static feature engineering, shallow transformations, or limited augmentation strategies that fail to generalize across diverse obfuscation techniques. These methods often overlook the structural distortions introduced by adversarial manipulation, resulting in brittle representations and reduced classification reliability.
This study addresses that challenge by applying advanced CNN architectures, including MobileNet, ResNet, and DenseNet, augmented with robust hashing techniques and obfuscation-aware preprocessing. We examine how these combined strategies improve resilience and accuracy in real-world scenarios. The findings contribute to building more secure and adaptable classification frameworks capable of withstanding modern adversarial tactics. In fact, CNNs have proven especially effective. Their ability to process large-scale datasets, detect subtle structural variations, and automate the threat detection pipeline has made them critical assets in security infrastructures [4]. Whereas conventional methods relied on signature matching, CNNs support more generalized defenses by learning discriminative features directly from raw data. Their effectiveness, however, depends heavily on the presence of meaningful, consistent training patterns, an aspect this research directly addresses through careful dataset construction.
Nevertheless, CNN-based systems face significant challenges when encountering obfuscated data. Techniques such as noise injection, contrast adjustment, or hybrid malware composition, where features from multiple families are combined, can confuse even advanced models, leading to misclassification or accuracy loss [3]. This structural obfuscation blurs class boundaries and exposes weaknesses in learned representations. To mitigate this, our research highlights the importance of robust preprocessing, particularly the application of robust hashing methods that preserve image structure while counteracting obfuscation effects [5]. By integrating this resilient type of hashing with state-of-the-art CNNs, we aim to improve the reliability of malware classification in adversarial and obfuscated conditions.
This paper is organized as follows. To contextualize our contributions, we begin in Section 2 by reviewing relevant literature on malware classification, robust hashing, and adversarial resilience in CNN-based models. Section 3 then provides the technical groundwork for our approach. In Section 4, we introduce our salting technique and robust hashing pipeline, detailing the design rationale and implementation steps used to generate obfuscated malware variants. Section 5 describes the experimental setup and evaluation metrics employed to assess performance across multiple configurations. Section 6 presents our key findings, highlighting the impact of robust hashing and varying levels of salting on CNN classification accuracy and robustness. Finally, Section 7 summarizes the implications of our results, and outlines directions for future research.
2. Related Work
In the realm of malware classification, a significant body of research has explored various machine learning and deep learning techniques to overcome limitations of traditional signature-based detection systems. The study in [3] addresses the challenge of detecting polymorphic malware by employing classifiers such as Support Vector Machines (SVMs), Random Forests, and Decision Trees. The authors’ analysis of feature and behavioral data revealed that Random Forest achieved the highest precision of . Extending this, the comparative study in [6] investigates the effectiveness of deep learning versus machine learning approaches on a multiclass classification problem involving nine malware families. This work underscores the impact of obfuscation on accuracy and finds that deep neural networks perform best, achieving % accuracy, while Random Forest performs poorly under feature overlap.
Another notable framework integrates dynamic analysis using the Cuckoo Sandbox to extract API call features and applies a two-stage feature selection mechanism (Chi-Square and Random Forest-based selection), reducing the feature space from to 87 [7]. Their Decision Tree classifier reached an impressive % accuracy in both binary and multiclass tasks. Shifting towards visual representation, the study in [8] proposes converting malware binaries into grayscale images and classifying them using a ResNet-50 CNN, achieving % accuracy on the Malimg dataset. This approach demonstrates the potential of image-based malware detection, especially against polymorphic and metamorphic malware.
Entropy-based techniques are explored in [9], where a one-dimensional CNN model leverages entropy levels to detect obfuscated malware. This method is particularly effective in differentiating between obfuscated and non-obfuscated samples based on entropy thresholds. Addressing dataset imbalance and real-time classification, the study in [10] builds a Streamlit-based web application for malware classification. Their CNN-based model not only performs robustly across different malware types but also surpasses models like ResNet-50 with an accuracy of %.
Recognizing the limitations of deploying heavy models on resource-constrained IoT devices, a recent study proposes a lightweight CNN architecture optimized using filter pruning, convolutions, batch normalization, dropout, and Bayesian tuning [11]. Despite being computationally efficient, the model maintains high accuracy (%) on the Malimg dataset, emphasizing its practicality for embedded environments.
Recent literature has explored various approaches to enhancing the robustness of image-based malware classification models, particularly under adversarial and obfuscated conditions. Early efforts compared traditional feature-based methods, such as gist descriptors combined with k-Nearest Neighbors and SVMs, to deep learning techniques that leverage grayscale representations and transfer learning frameworks [12]. While both approaches achieved high classification accuracy, deep learning models offered improved scalability and inference speed, with greater resilience against obfuscation. Subsequent studies examined the comparative performance of deep learning and simpler static feature-based classifiers, revealing that while k-NN outperformed deep learning models in some scenarios, the latter demonstrated superior generalization in zero-day evaluations [13].
In parallel, robust image hashing methods, such as wavelet-based and distributed coding techniques, have been proposed as efficient alternatives to conventional machine learning, providing flexible update mechanisms with competitive accuracy [5]. However, these methods are rarely integrated with deep learning pipelines, and their effectiveness under adversarial obfuscation remains underexplored.
Recent work by Zhang et al. [14] investigates CNN resilience against executable adversarial attacks by modifying Portable Executable (PE) headers. Their header-aware loss function improves robustness, but the study does not incorporate hashing-based preprocessing. Similarly, Thakur et al. [15] propose a hybrid LSTM-CNN architecture for malware classification using grayscale image inputs, achieving strong performance but lacking structural invariance mechanisms like robust hashing.
To our knowledge, few studies have systematically combined robust hashing with CNN architectures for malware detection. This work is among the first to evaluate histogram-based hashing under salting-based obfuscation, showing improved CNN performance. However, their analysis is limited to static salting ratios and does not explore adaptive obfuscation or runtime efficiency.
These gaps highlight the need for a unified framework that integrates robust hashing with CNNs, evaluates performance under controlled obfuscation, and considers deployment constraints. Our study addresses this by proposing a scalable preprocessing pipeline, benchmarking multiple CNNs under varying salting intensities, and analyzing robustness in adversarial conditions. This differentiated positioning contributes to the evolving landscape of resilient malware classification.
3. Background
This research explores the integration of Convolutional Neural Networks (CNNs) with robust hashing techniques to strengthen malware detection, aiming to enhance resistance against evasion tactics and improve cybersecurity defenses. In this section, we provide a brief overview of the underlying mechanisms of robust hashing, CNNs, and dataset obfuscation.
3.1. Convolutional Neural Networks (CNN)
Convolutional Neural Networks (CNNs) are advanced deep learning architectures specifically developed for image and visual data analysis. CNNs typically consist of convolutional layers that apply filters to capture important visual features, pooling layers that summarize these features and reduce spatial dimensions, and fully connected layers responsible for making the final classification decisions [16]. CNNs are widely recognized for their effectiveness in tasks such as image recognition, object detection, and feature extraction due to their ability to automatically learn hierarchical visual features [16].
The following outlines the function of each layer within the CNN:
- Input Image: The network begins with an input image; in this example, an image of a dog is used.
- Convolutional Layer: The first layer performs convolution operations on the input image [17]. It extracts features such as edges, textures, and patterns by applying various filters or kernels, producing a set of feature maps.
- Pooling Layer: This layer reduces the spatial dimensions of the feature maps, which lowers computational complexity and mitigates overfitting through dimensionality reduction [17].
- Activation Function Layer: Following convolution, a nonlinear activation function is applied, typically the rectified linear unit (ReLU) [17].
- Fully Connected Layer: After a series of convolutional, activation, and pooling layers, the feature maps are flattened into a one-dimensional vector and passed through fully connected layers. These layers perform the final classification based on learned features [16].
- Output Layer: The final layer produces class probabilities. In the illustrated architecture, the network predicts whether the image corresponds to “Dog” or “Not Dog,” selecting the class with the highest probability as the output.
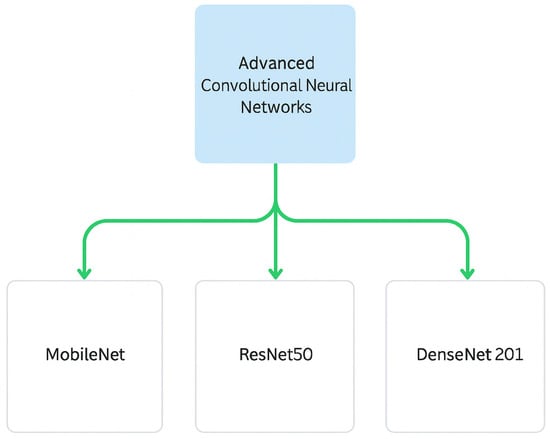
As depicted in Figure 1, the models implemented in this research are MobileNet, ResNet, and DenseNet.
Figure 1.
CNN models used in this research.
3.1.1. MobileNet
MobileNet is a lightweight Convolutional Neural Network (CNN) architecture specifically designed for devices with limited computational power, such as smartphones and embedded systems [18]. Its key innovation is the use of depthwise separable convolutions, which decompose the standard convolution into two operations:
- Depthwise convolution: applies a single filter to each input channel separately.
- Pointwise convolution: combines the outputs across channels using a 1 × 1 convolution.
This architectural change significantly reduces computational cost and model size compared to traditional CNNs. In malware detection, MobileNet is particularly useful for enabling real-time inference on resource-constrained devices without a substantial loss in accuracy. Its efficiency makes it a practical choice for on-device cybersecurity solutions.
3.1.2. ResNet
Residual Networks (ResNets)represent a major advancement in deep CNN design [19]. They address the vanishing gradient problem that hampers the training of very deep networks. ResNets introduce residual (skip) connections, which allow the input of a layer to bypass one or more subsequent layers and be added directly to the output.
These residual connections help maintain information flow during backpropagation and allow networks to be significantly deeper without degradation in performance. In the context of malware detection, ResNets can learn complex, high-level representations from malware image data, thereby improving the accuracy of detection systems.
3.1.3. DenseNet
Dense Convolutional Networks (DenseNets) are another CNN variant characterized by dense connectivity: each layer receives the feature maps of all preceding layers as additional inputs [20]. This structure encourages feature reuse, improved gradient flow, and parameter efficiency.
As a result, DenseNets are often more compact and computationally efficient while maintaining high performance. In malware detection applications, DenseNets have demonstrated strong performance due to their ability to model complex patterns with relatively fewer parameters, making them well-suited for environments with limited resources.
3.2. Robust Hashing
Robust hashing involves specialized image-processing techniques that produce compact and invariant representations of visual data [5]. These methods generate stable hash codes that remain consistent under minor transformations such as rotation, scaling, noise, or pixel-level modifications [21].
By contrast, traditional hashing techniques, widely used in cryptography, convert input data into fixed-size hash values to verify data integrity, authenticate transmissions, and detect tampering [22,23]. A core principle in cryptographic hashing is collision resistance, that is, the deliberate design to avoid generating identical hash outputs for different inputs [24]. While such sensitivity is desirable in secure communications, it becomes problematic in contexts like malware classification, where obfuscation should not yield entirely divergent representations.
To address this mismatch, our research applies robust hashing, a method that generates similar hash values for visually or structurally related inputs, even if they differ at the byte level [24]. This property is especially beneficial for malware detection, as binaries from the same family often vary partially due to packing or obfuscation techniques. Robust hashing enables classifiers to identify structural similarities, improving generalization across obfuscated variants.
In this domain, robust hashing histograms are critical to preserving consistency under adversarial manipulation, such as subtle image perturbations intended to evade detection [5,25]. By focusing on invariant visual features, these techniques bolster the resilience and reliability of CNN-based malware classifiers in adversarial settings.
One of the key challenges in malware image classification is handling the size and complexity of malware binaries. Converting entire binaries directly to fixed-size images can lead to a loss of important structural features, especially when large files are forcibly resized to small dimensions like 256 × 256. Moreover, many malware families produce visually similar binaries, increasing the risk of misclassification. Robust hashing mitigates these issues by focusing on distributional features that persist in similar variants. It allows the model to focus on invariant patterns and structure, rather than being misled by small, inconsequential differences introduced by obfuscation.
Details on how robust hashing was applied in this research can be found in Section 4.3.
4. Methodology
This section outlines the foundational components of our experimental framework, beginning with a description of the malware dataset used in this study. We then detail the obfuscation strategies applied to simulate adversarial conditions and evaluate model robustness. Finally, we introduce the robust hashing technique employed to generate invariant visual representations of malware samples, enabling improved classification performance under varying levels of obfuscation. Together, these subsections establish the data and preprocessing pipeline that supports our investigation into resilient CNN-based malware detection.
4.1. Dataset
The dataset used in this research consists of approximately 40 GB of malware executable files obtained from VirusShare [26], a widely recognized repository for malware research. The dataset was curated specifically for static analysis and machine learning-based threat detection. To provide clarity on the types of malware included, the dataset spans a range of malware categories such as trojans, ransomware, worms, adware, and botnets, distributed across 20 distinct families. Table 1 summarizes the number of images per family, highlighting both variety and class imbalance.
Table 1.
Updated malware family image distribution.
A major challenge in handling this dataset was the substantial variation in file sizes: Individual samples ranged from a few kilobytes (KB) to large executables exceeding 32 megabytes (MB). To standardize input for image-based analysis, all binaries were converted into 256 × 256 grayscale images. The conversion process involved reading the binary file byte-by-byte into a NumPy array, followed by reshaping into a 2D image.
For binaries smaller than 65,536 bytes (the total pixel count for a 256 × 256 image), the array was zero-padded to fill the image. For larger binaries exceeding 65,536 bytes, only the first 65,536 bytes were used, truncating the remainder. This approach was chosen for computational feasibility and to maintain uniform image dimensions while retaining the beginning segment of the executable, which often contains critical structural information such as headers and initialization code. Although truncation may omit later portions of large binaries, prior research indicates that static analysis can still capture family-specific patterns from the initial sections [27,28,29]. The resulting images were saved in PNG format and organized into directories according to their corresponding malware family labels.
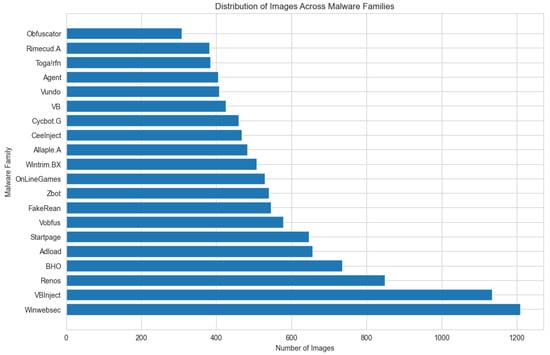
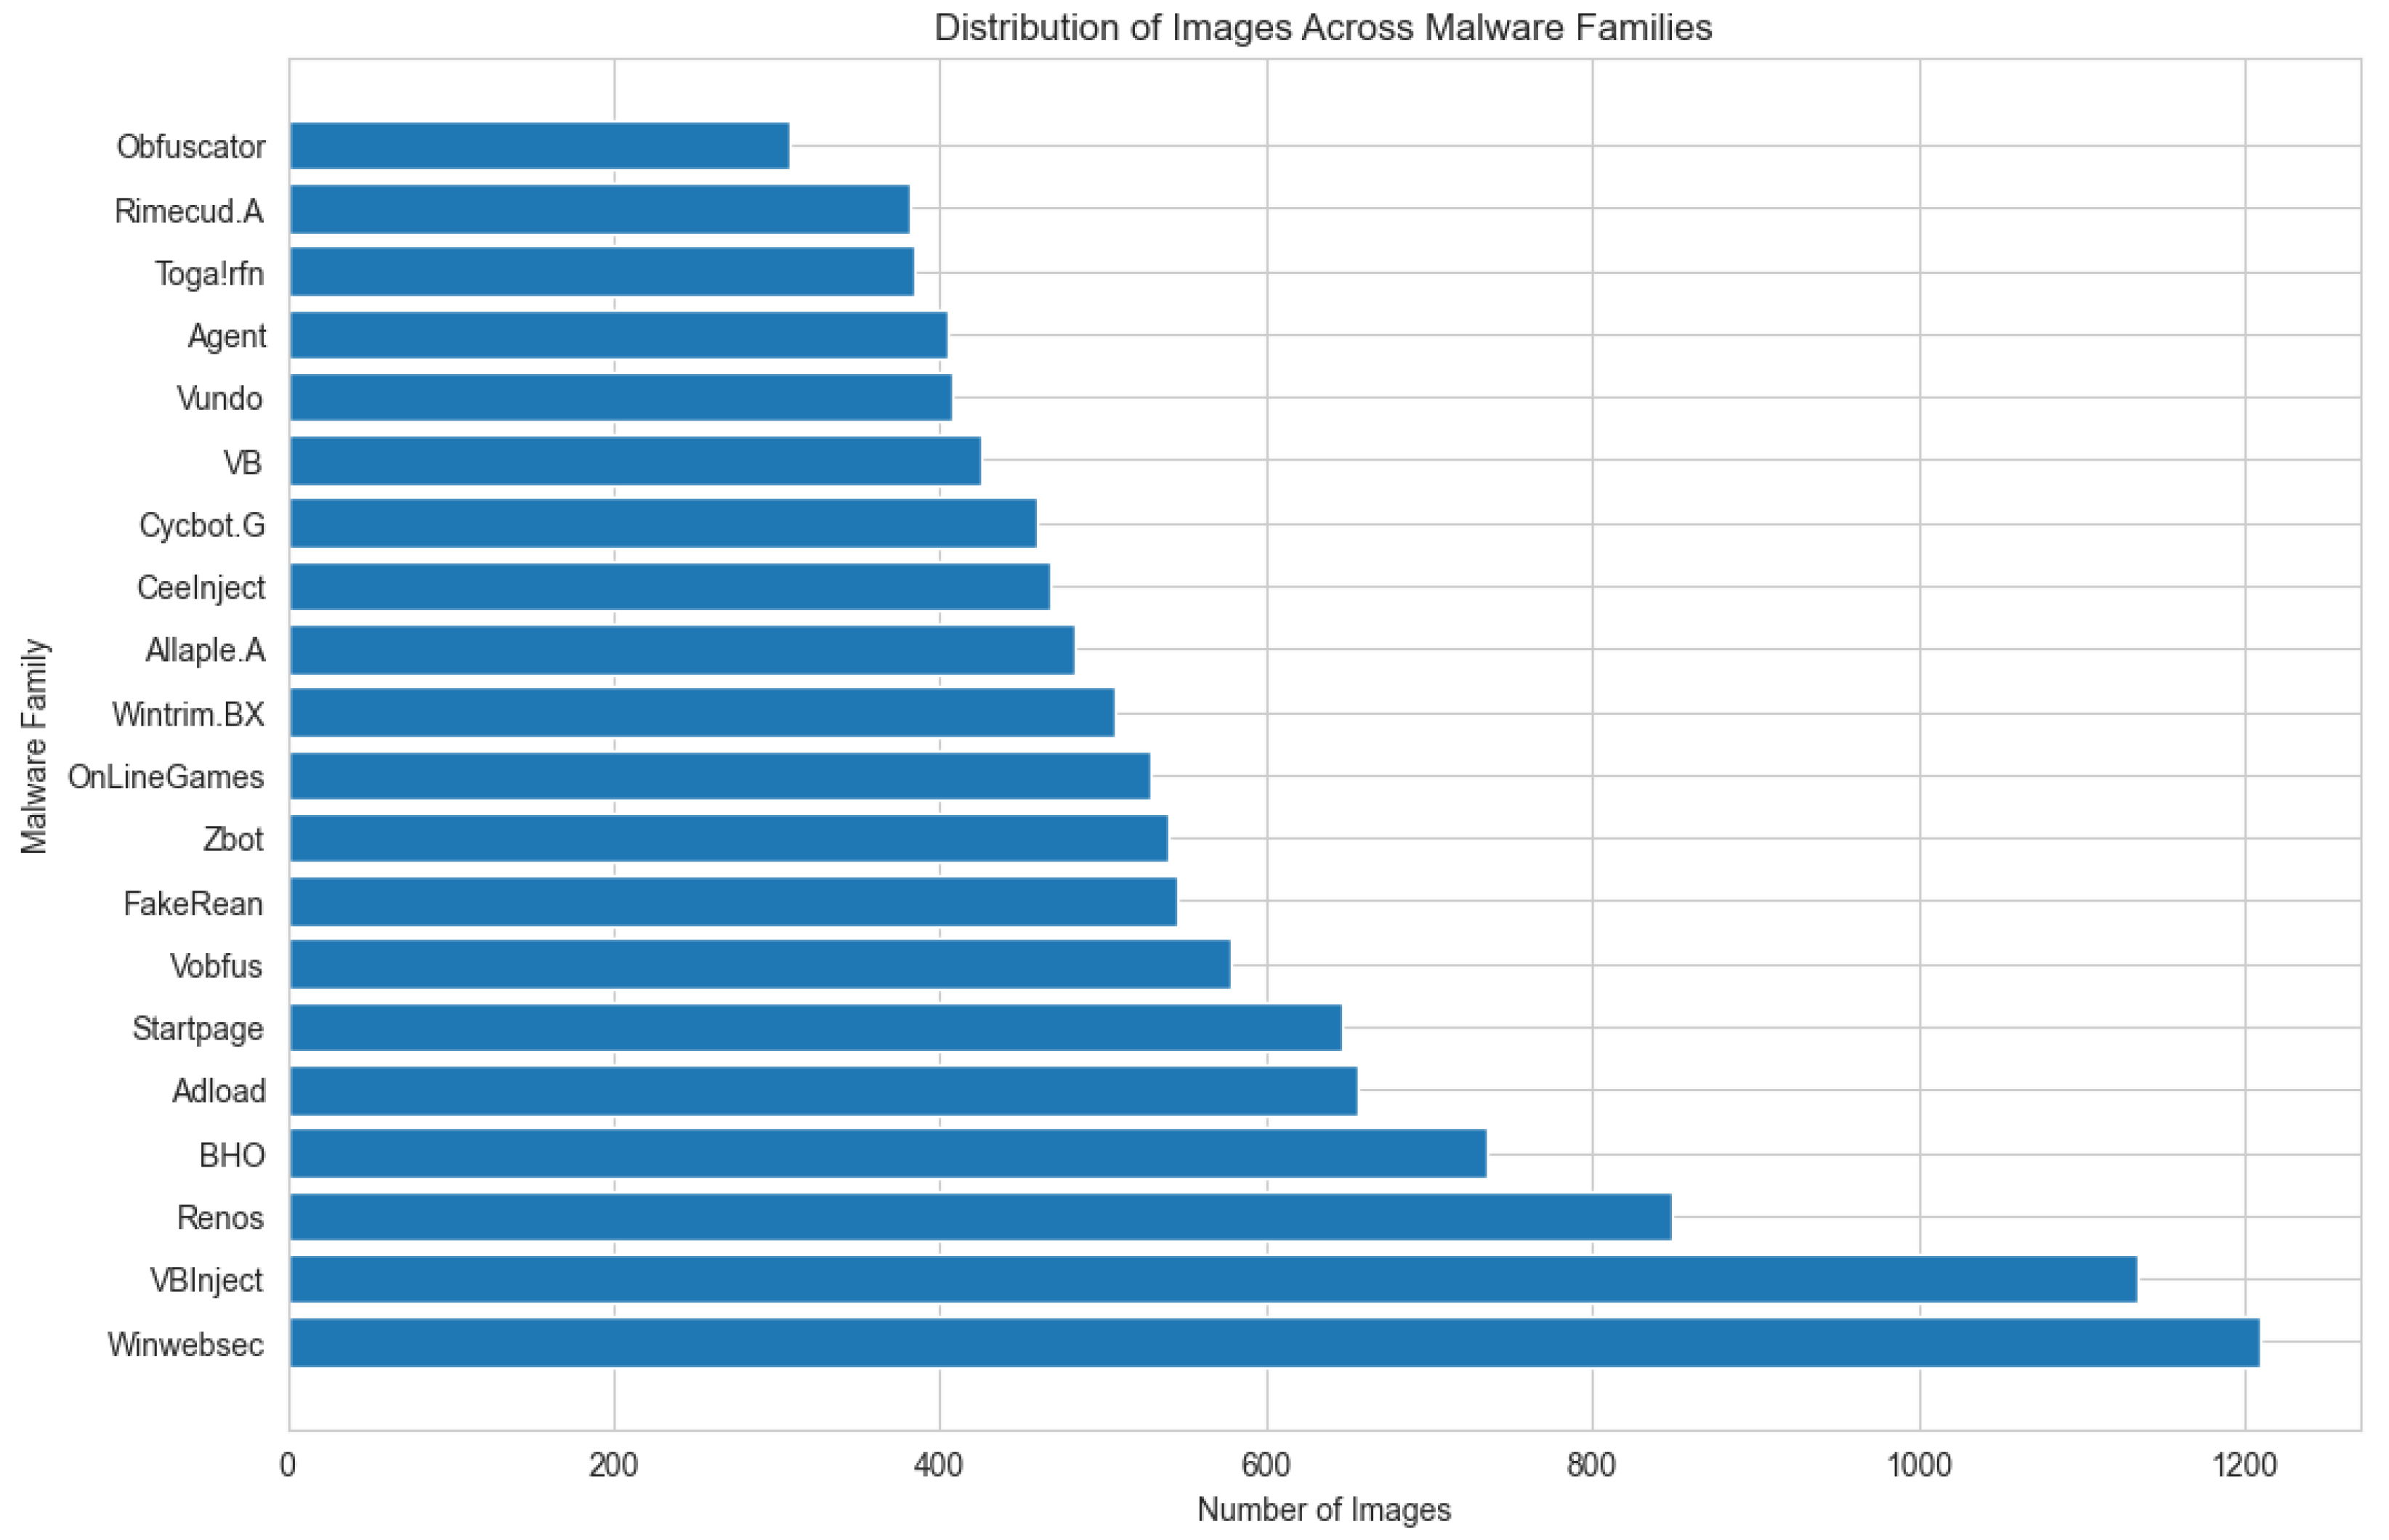
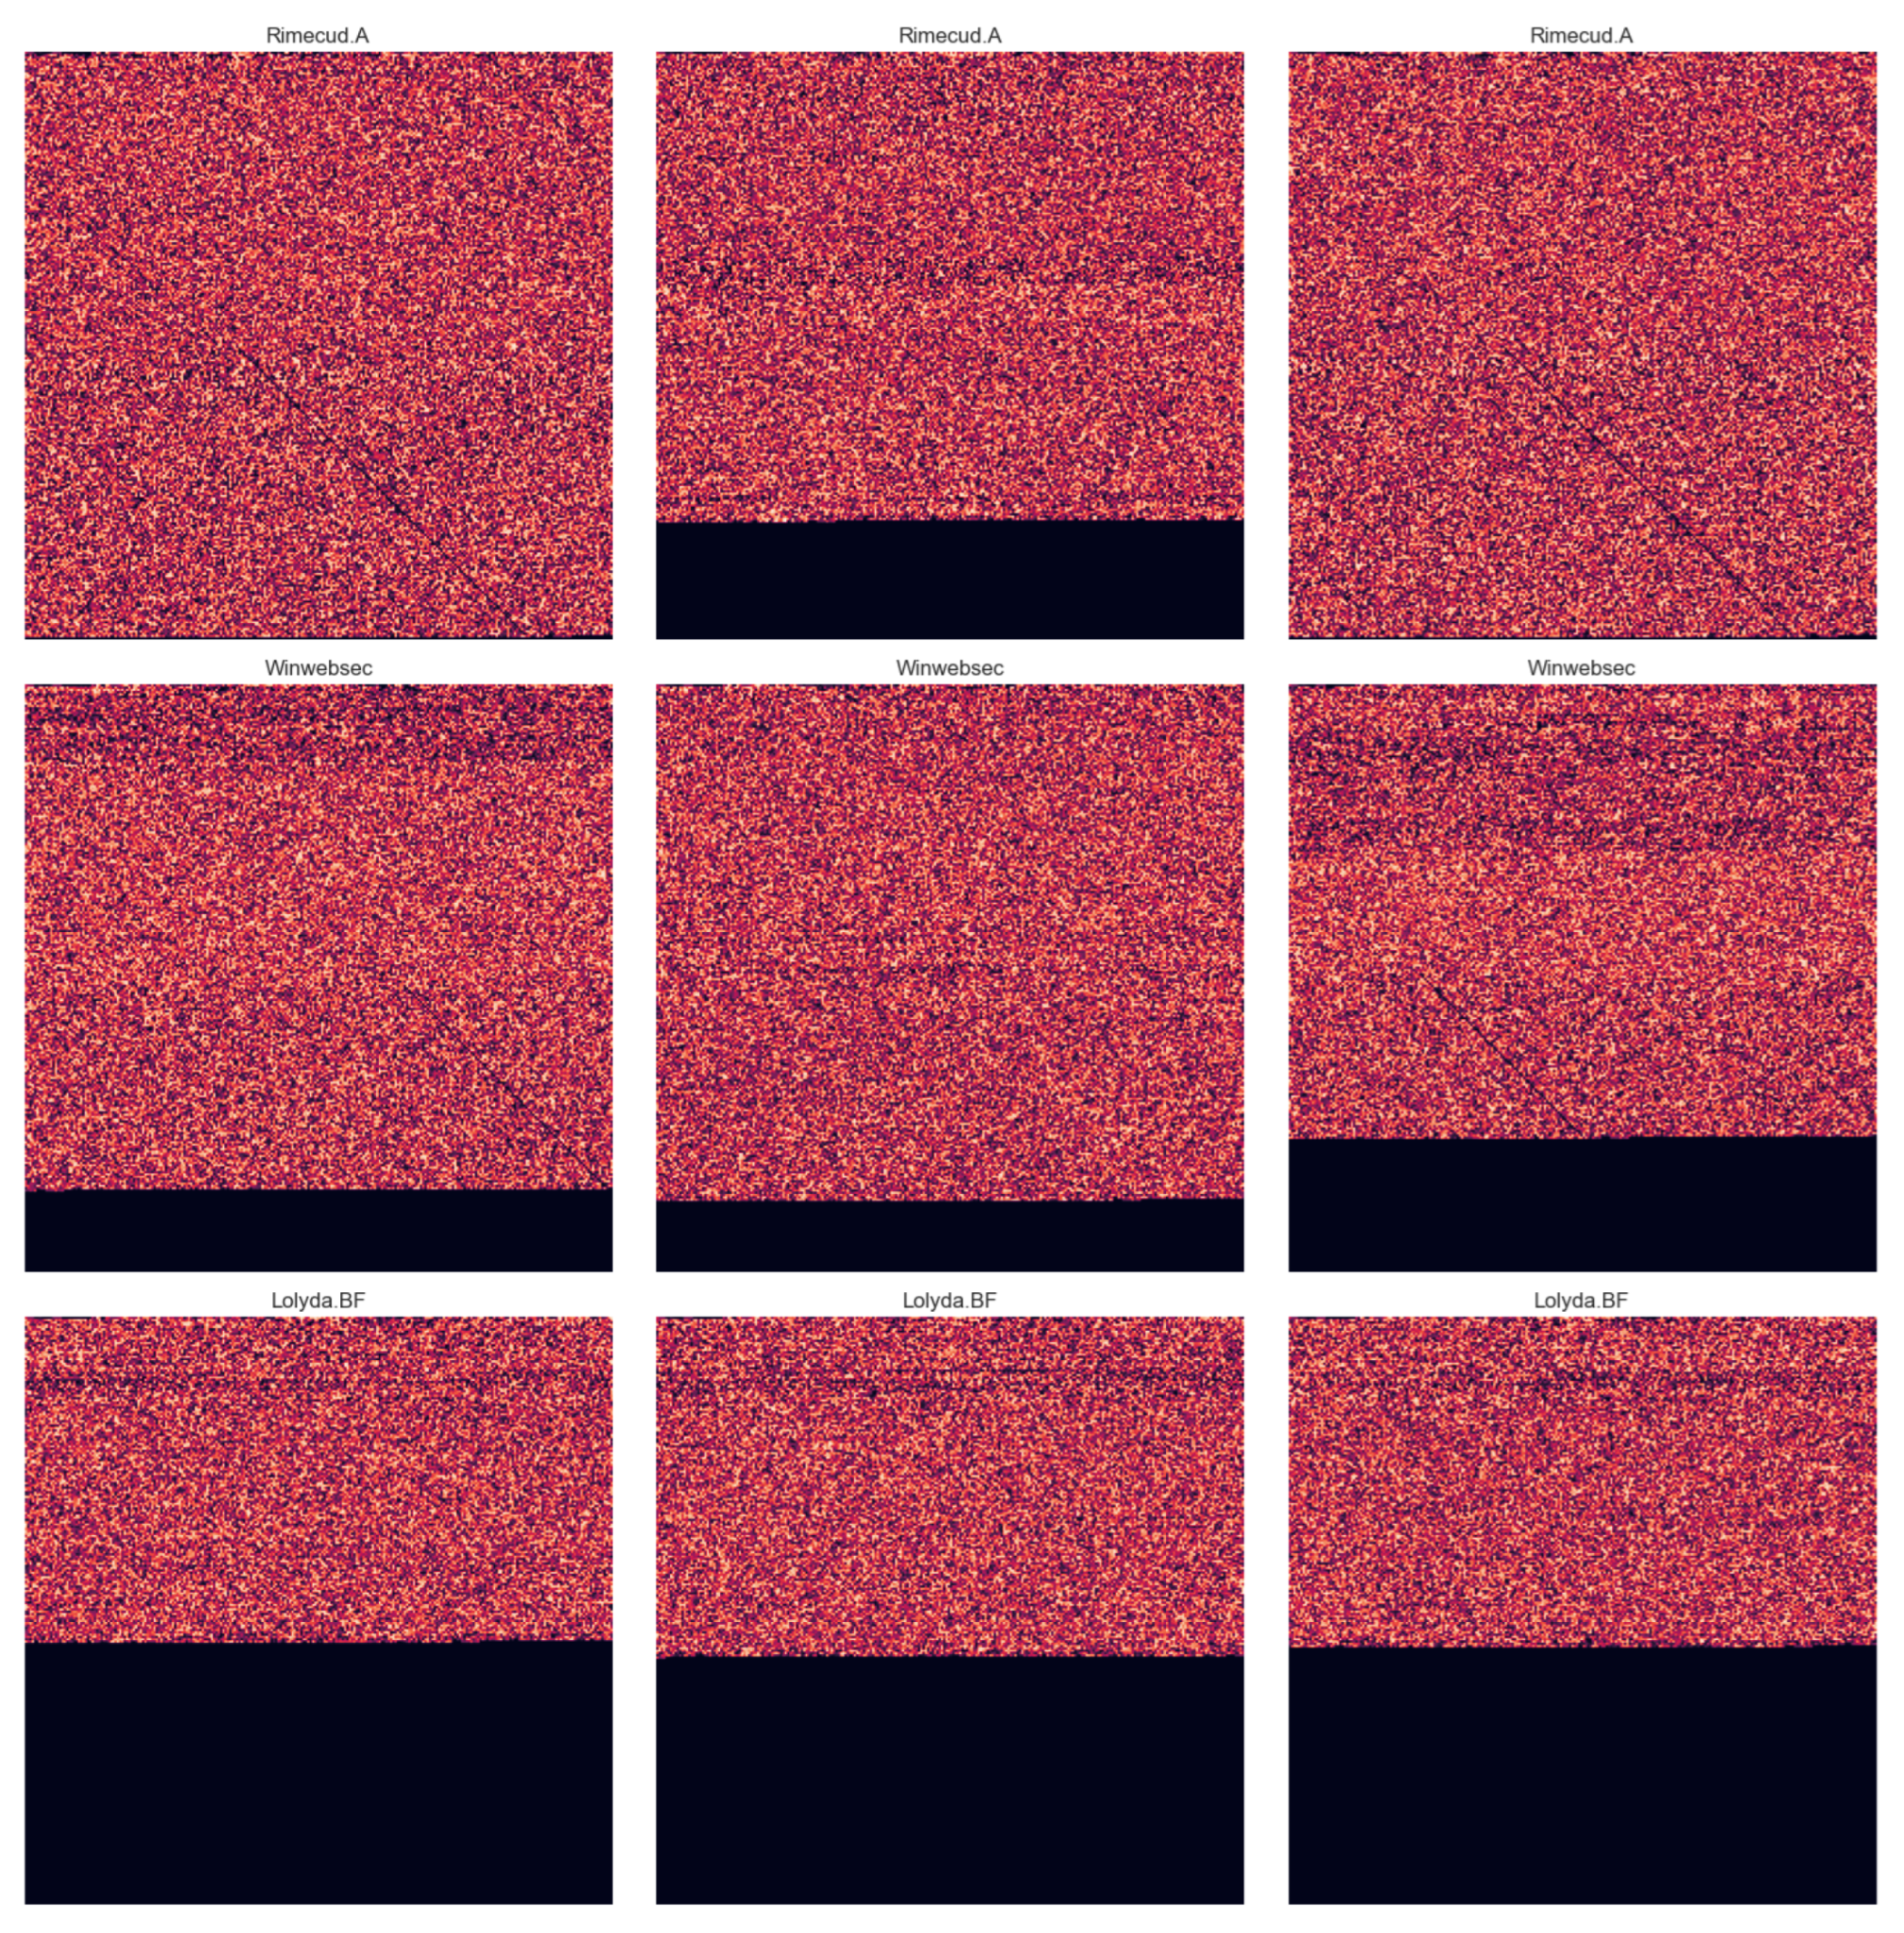
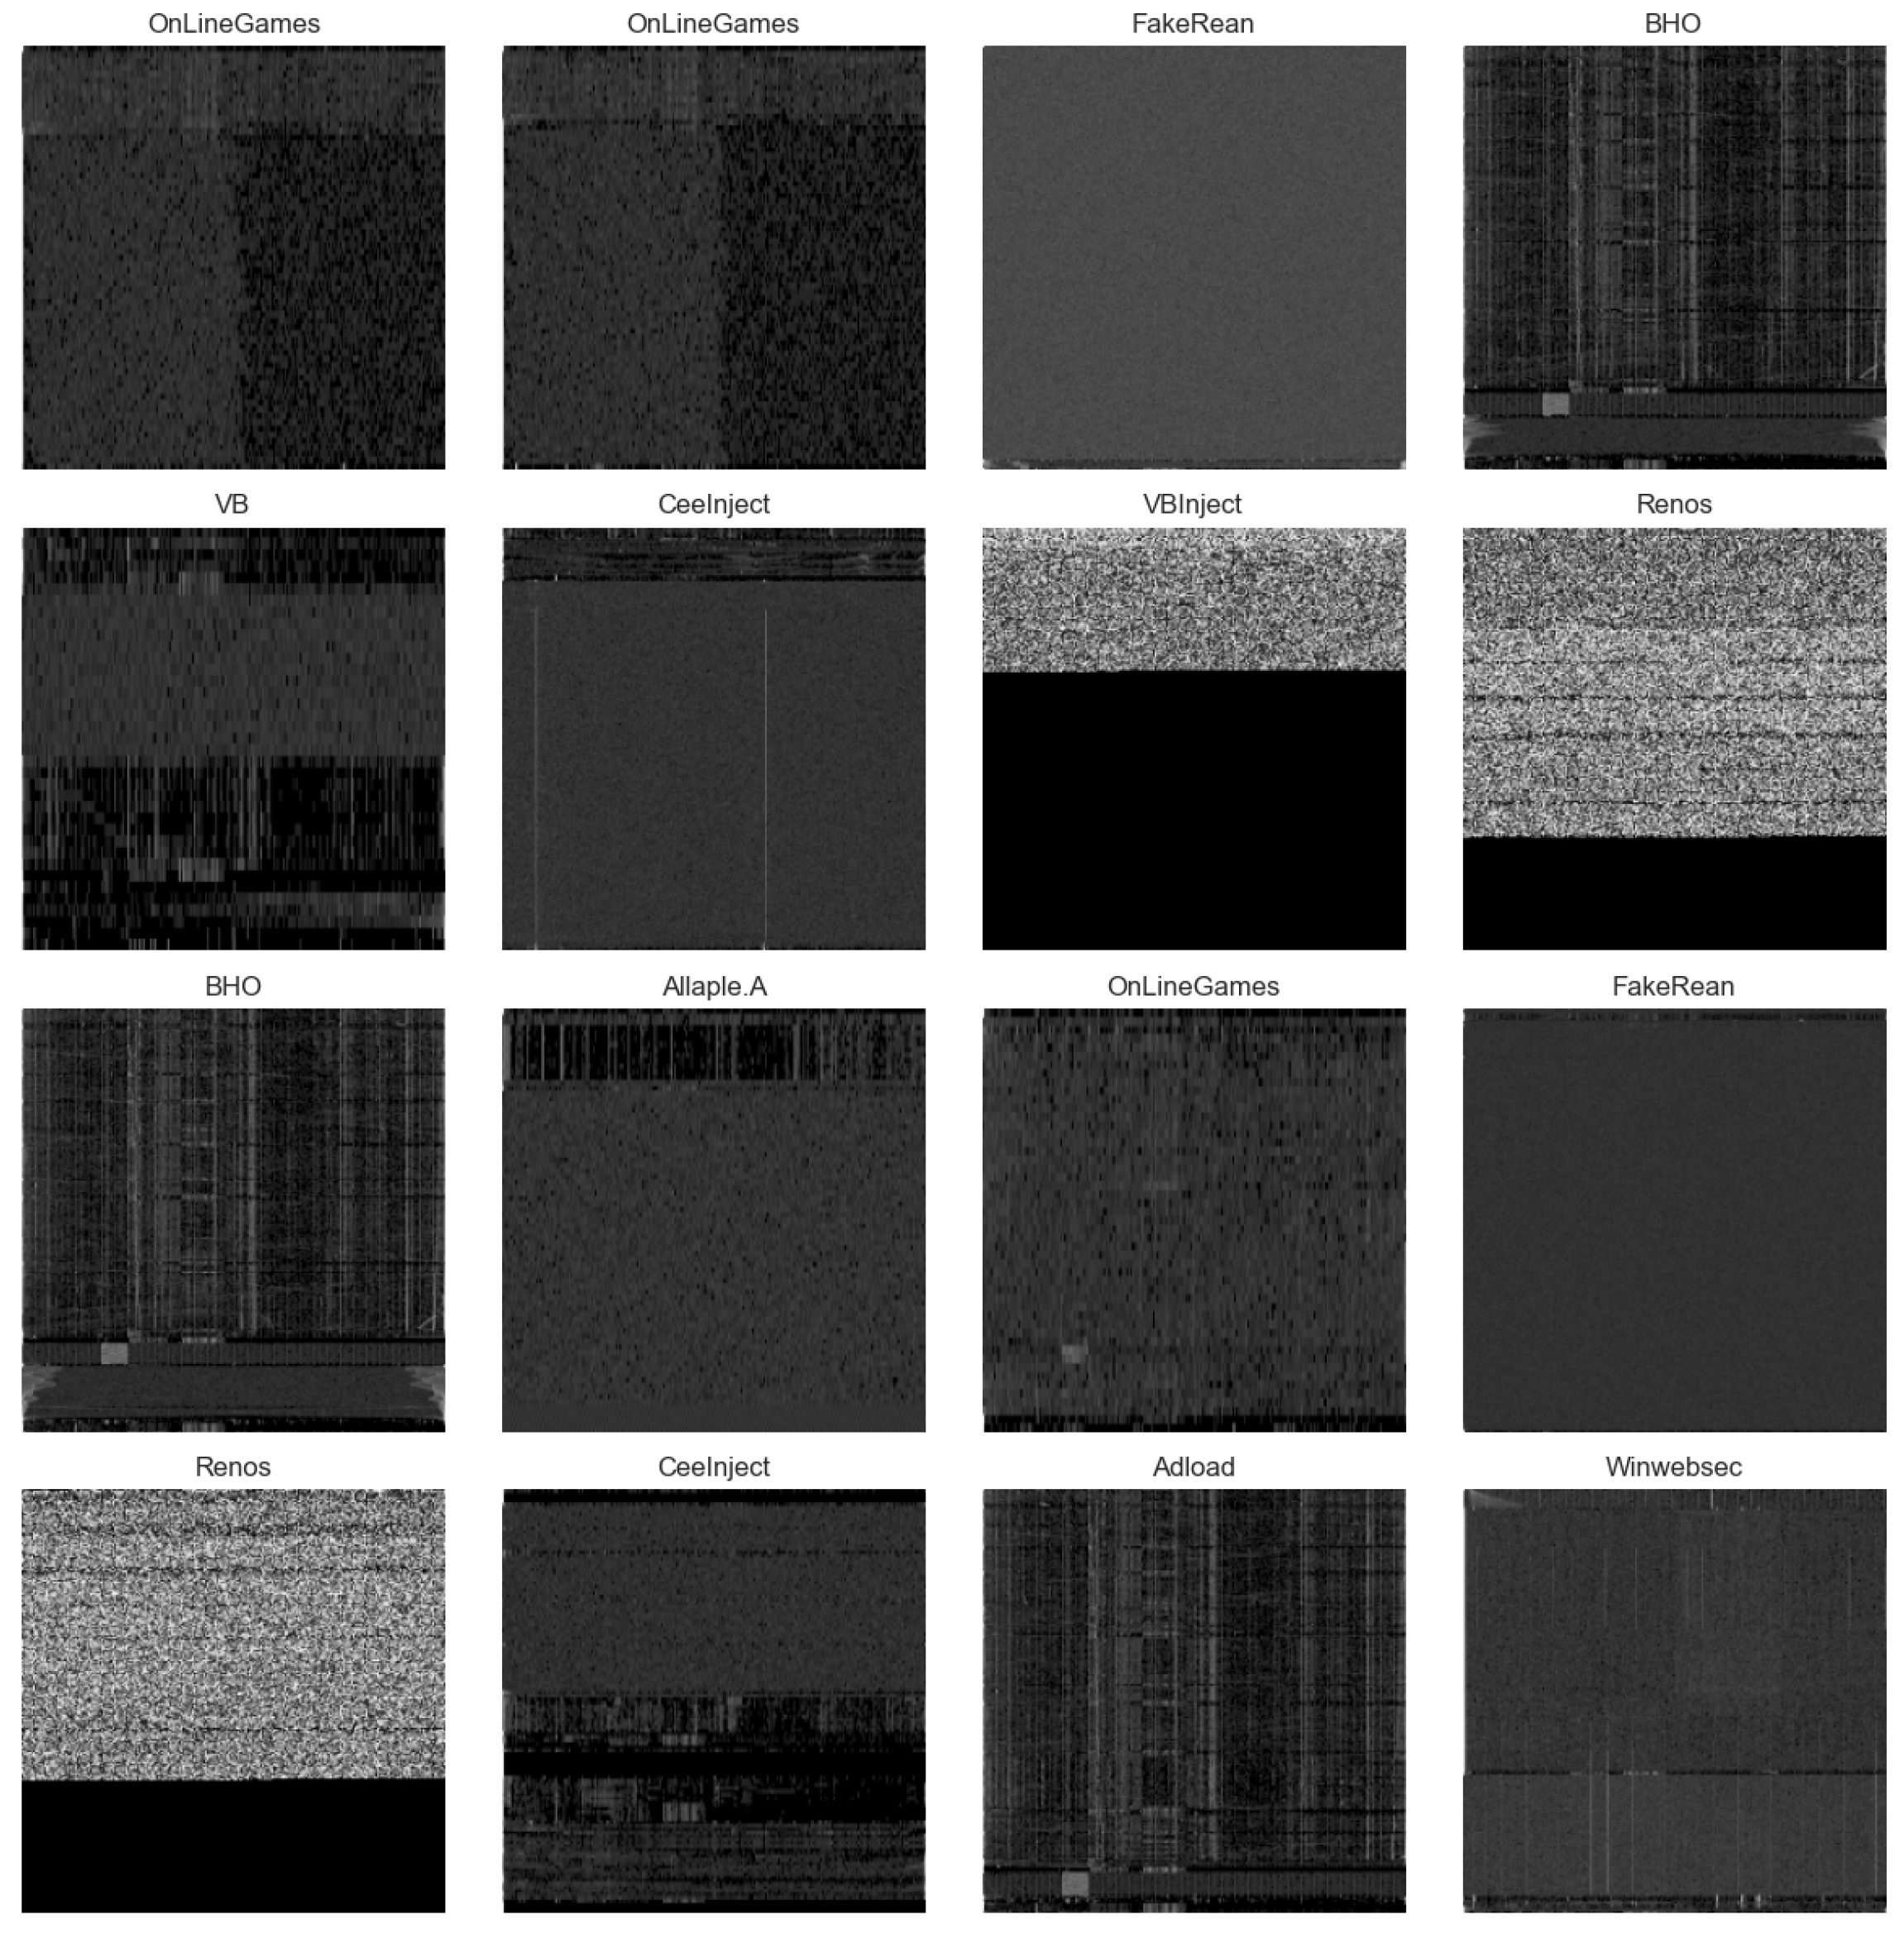
To ensure consistency, duplicate filenames were removed, and each image was mapped to a malware family using the provided metadata file. The final dataset comprised nearly 14,000 images across 20 malware families, as shown in Table 1. Figure 2, Figure 3 and Figure 4 illustrate the distribution and visual characteristics of these malware families. Notably, some families exhibit strong visual similarity, while others appear noisy or irregular, complicating classification. These variations, combined with class imbalance, underscore the importance of robust feature extraction techniques, which are discussed in Section 4.3.
Figure 2.
Malware families distribution.
Figure 3.
Sample malware family representations.
Figure 4.
Visual comparison of malware families.
Figure 2 illustrates the distribution of images across the malware families represented in the dataset. Each bar corresponds to a family, and the bar length indicates the number of samples. This visualization makes the class imbalance problem immediately evident: A few families, such as Cybots.G, Toga!rfn, Winwebsec, and VBInject, dominate the dataset, while others are represented by only a small handful of samples. Such imbalances can bias machine learning models toward majority classes, leading to poor generalization on minority families. This is analogous to training a facial recognition system that sees thousands of images of one person but only a few of another; here, the system naturally becomes more accurate at recognizing the overrepresented faces. In malware classification, this means the model may be highly accurate for some families but fail to detect rarer, yet equally dangerous, variants.
Figure 3 presents representative malware images generated by mapping the raw binary content of malware files into grayscale format. This conversion exposes structural differences between families that would otherwise remain hidden in raw byte sequences. For instance, families such as OnLineGames and BHO exhibit visually distinctive horizontal and vertical textures, reflecting recurring patterns in their binary layout. In contrast, families like Winwebsec produce images with more chaotic, seemingly random pixel arrangements. These differences can be understood by analogy to fingerprints: While all malware images originate from code, each family leaves behind recurring “visual signatures” in its binary representation. These signatures provide machine learning models with discriminative cues, helping them to learn family-specific patterns without explicit human-crafted features.
Figure 4 provides a side-by-side comparison of multiple malware families, making it easier to observe inter-family differences. Families such as Renos display consistent, repeating structures that appear as regular, distinguishable patterns in their grayscale representations. On the other hand, families like Winwebsec are dominated by irregular, noisy distributions of pixels, offering fewer consistent visual cues. Importantly, all images are normalized to a fixed 256 × 256 resolution for computational feasibility. While this standardization allows direct comparisons, it also means that binaries larger than this size may lose critical portions of their structure, introducing a risk of missing important family-defining features. This figure illustrates that just as different species of plants or animals exhibit unique physical traits, malware families manifest unique “visual” characteristics in image space, which can be leveraged to distinguish between them.
4.2. Dataset Obfuscation
Traditional image processing techniques often involve obfuscation methods such as noise addition, blurring, or rotation [30]. These are typically employed to simulate real-world variability and protect models against unauthorized recognition. However, in the domain of malware analysis, obfuscation is applied at the file level rather than at the visual or image level.
To replicate adversarial behaviors and evaluate the resilience of CNN classifiers, this study employs file-level obfuscation techniques that emulate strategies commonly used by malware authors [31]. These include code encryption, the insertion of redundant instructions, and packing executables into varied formats. Instead of directly modifying the source malware code, the obfuscation is simulated during pre-processing using a technique known as salting. This process blends code segments from two distinct malware samples to generate a novel, more complex variant. Such fusion is intended to challenge the CNN’s ability to distinguish between malware families by simulating obfuscated conditions. This setup enables an assessment of whether robust hashing techniques enhance classification accuracy and resilience in the presence of adversarial noise.
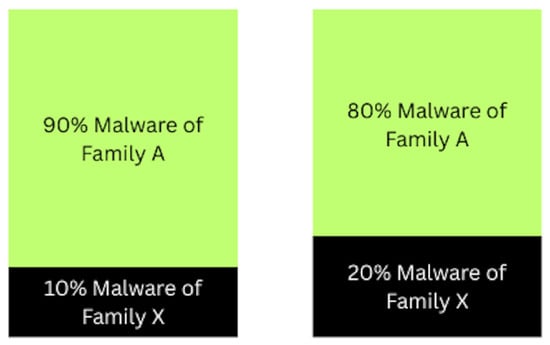
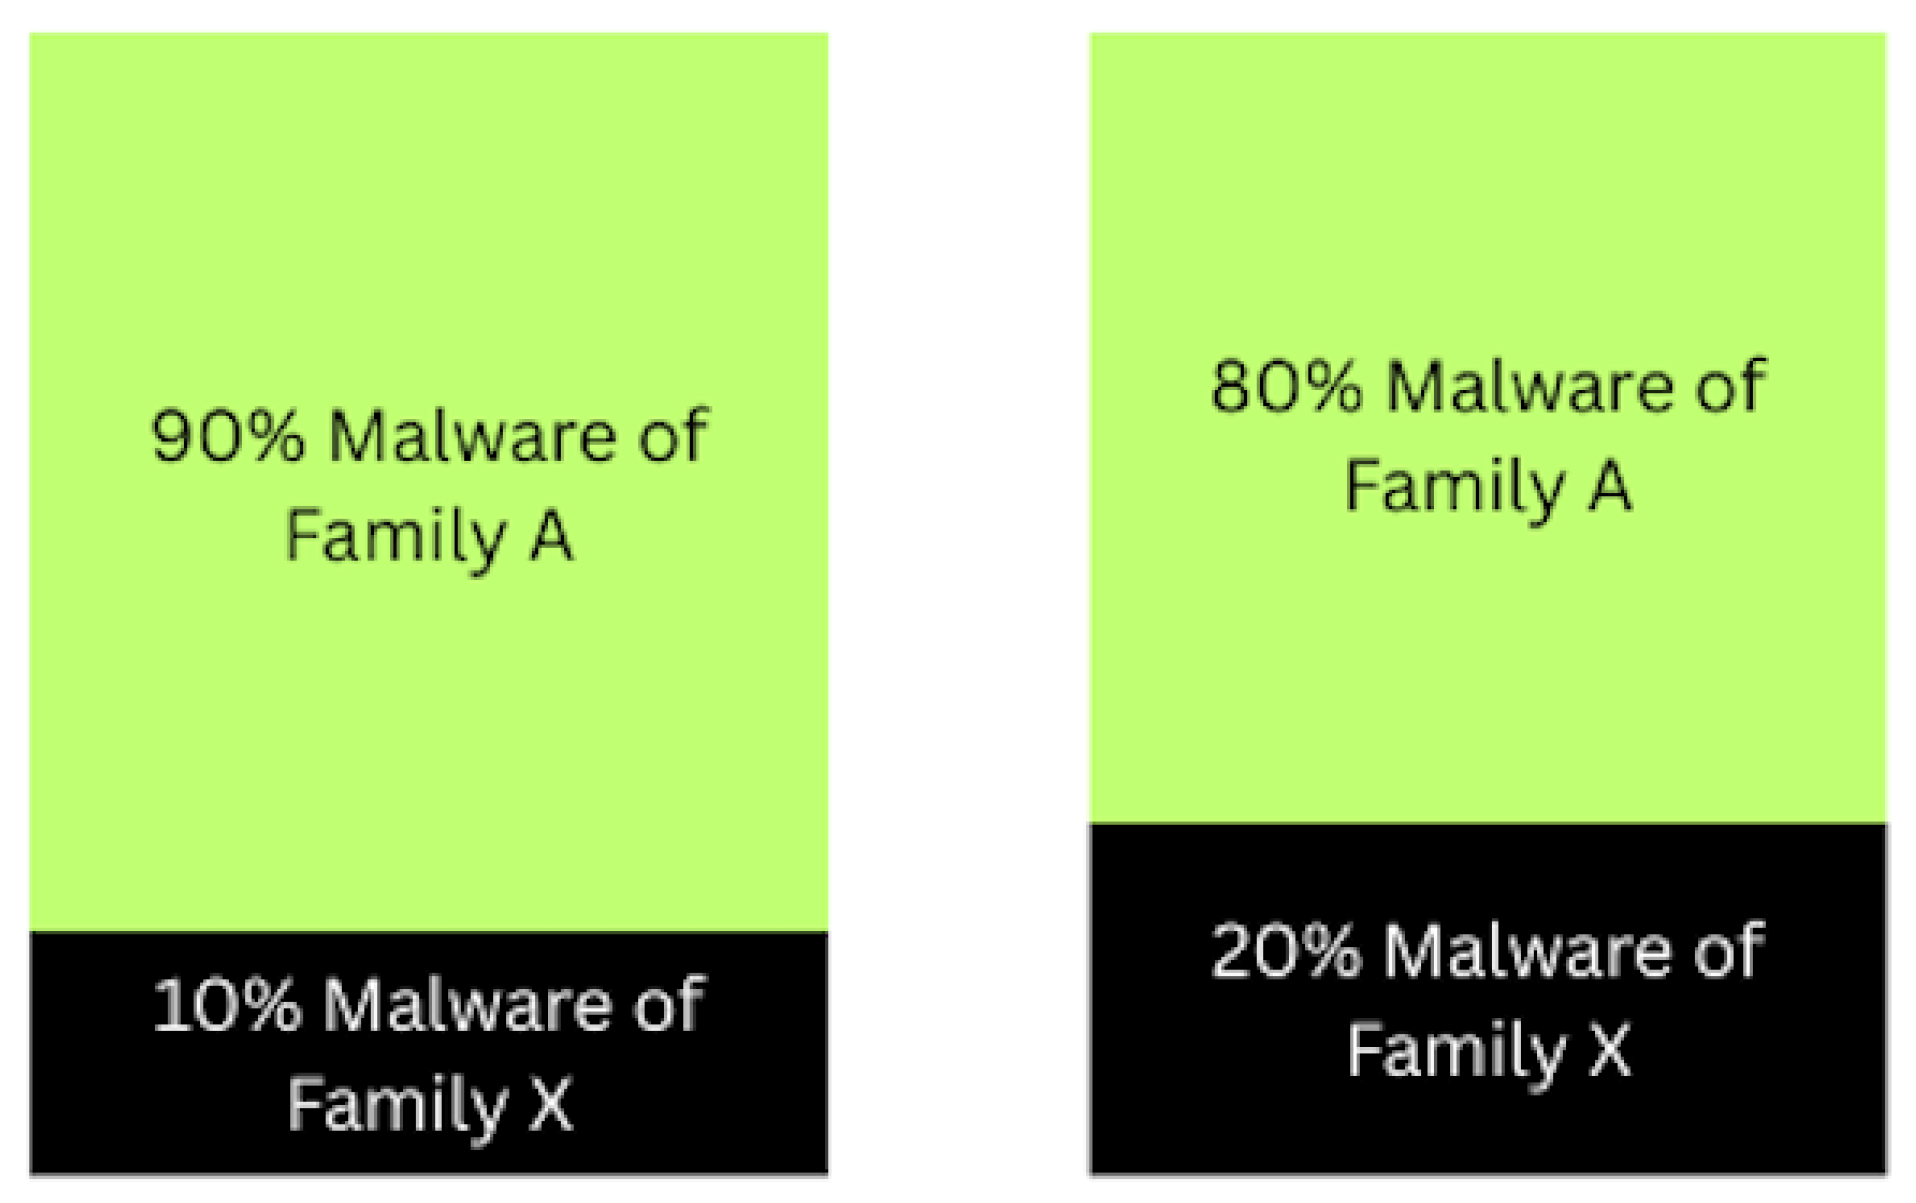
Figure 5 illustrates the salting technique, which merges one malware file from the primary family with a randomly chosen file from another family. The resulting hybrid sample contains a dominant portion from the primary family and a smaller segment from the secondary, simulating a fused or polymorphic variant. This process enables an evaluation of model performance under adversarial obfuscation and facilitates an investigation into the tolerance of the CNN classifier to increasing levels of salting. Specifically, our objective is to determine how much salting can be introduced before the classification accuracy degrades beyond acceptable thresholds.
Figure 5.
Dataset obfuscation—salting technique.
The random salting procedure applied to malware binary files consists of the following steps:
- Salting Ratio: Of the final sample, 90% is derived from the primary malware, while 10% is the adversarial sample, resulting in a salting ratio of 0.1.
- Image Size: The combined binary data are reshaped into a grayscale image of size (65,536 bytes).
- Majority and Minority Bytes: Byte segments are proportionally extracted from the primary and secondary malware samples.
- Salting Process: Each primary malware file is randomly paired with a file from a different family. Of the data, 90% is taken from the primary file, while 10% is taken from the secondary. The minority portion is randomly positioned to avoid padded regions commonly found at the start of binary files.
- Output: The resulting salted sample is saved as a grayscale PNG image.
The salting technique enables the creation of realistic and diverse malware representations, allowing CNN models to be evaluated against more adversarial inputs. Together with robust hashing, this obfuscation strategy forms the foundation for the experimental framework described in the next section.
4.3. Robust Hashing for Malware Classification
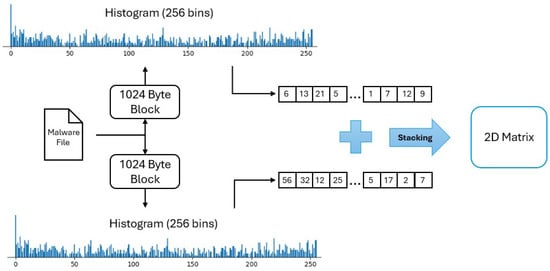
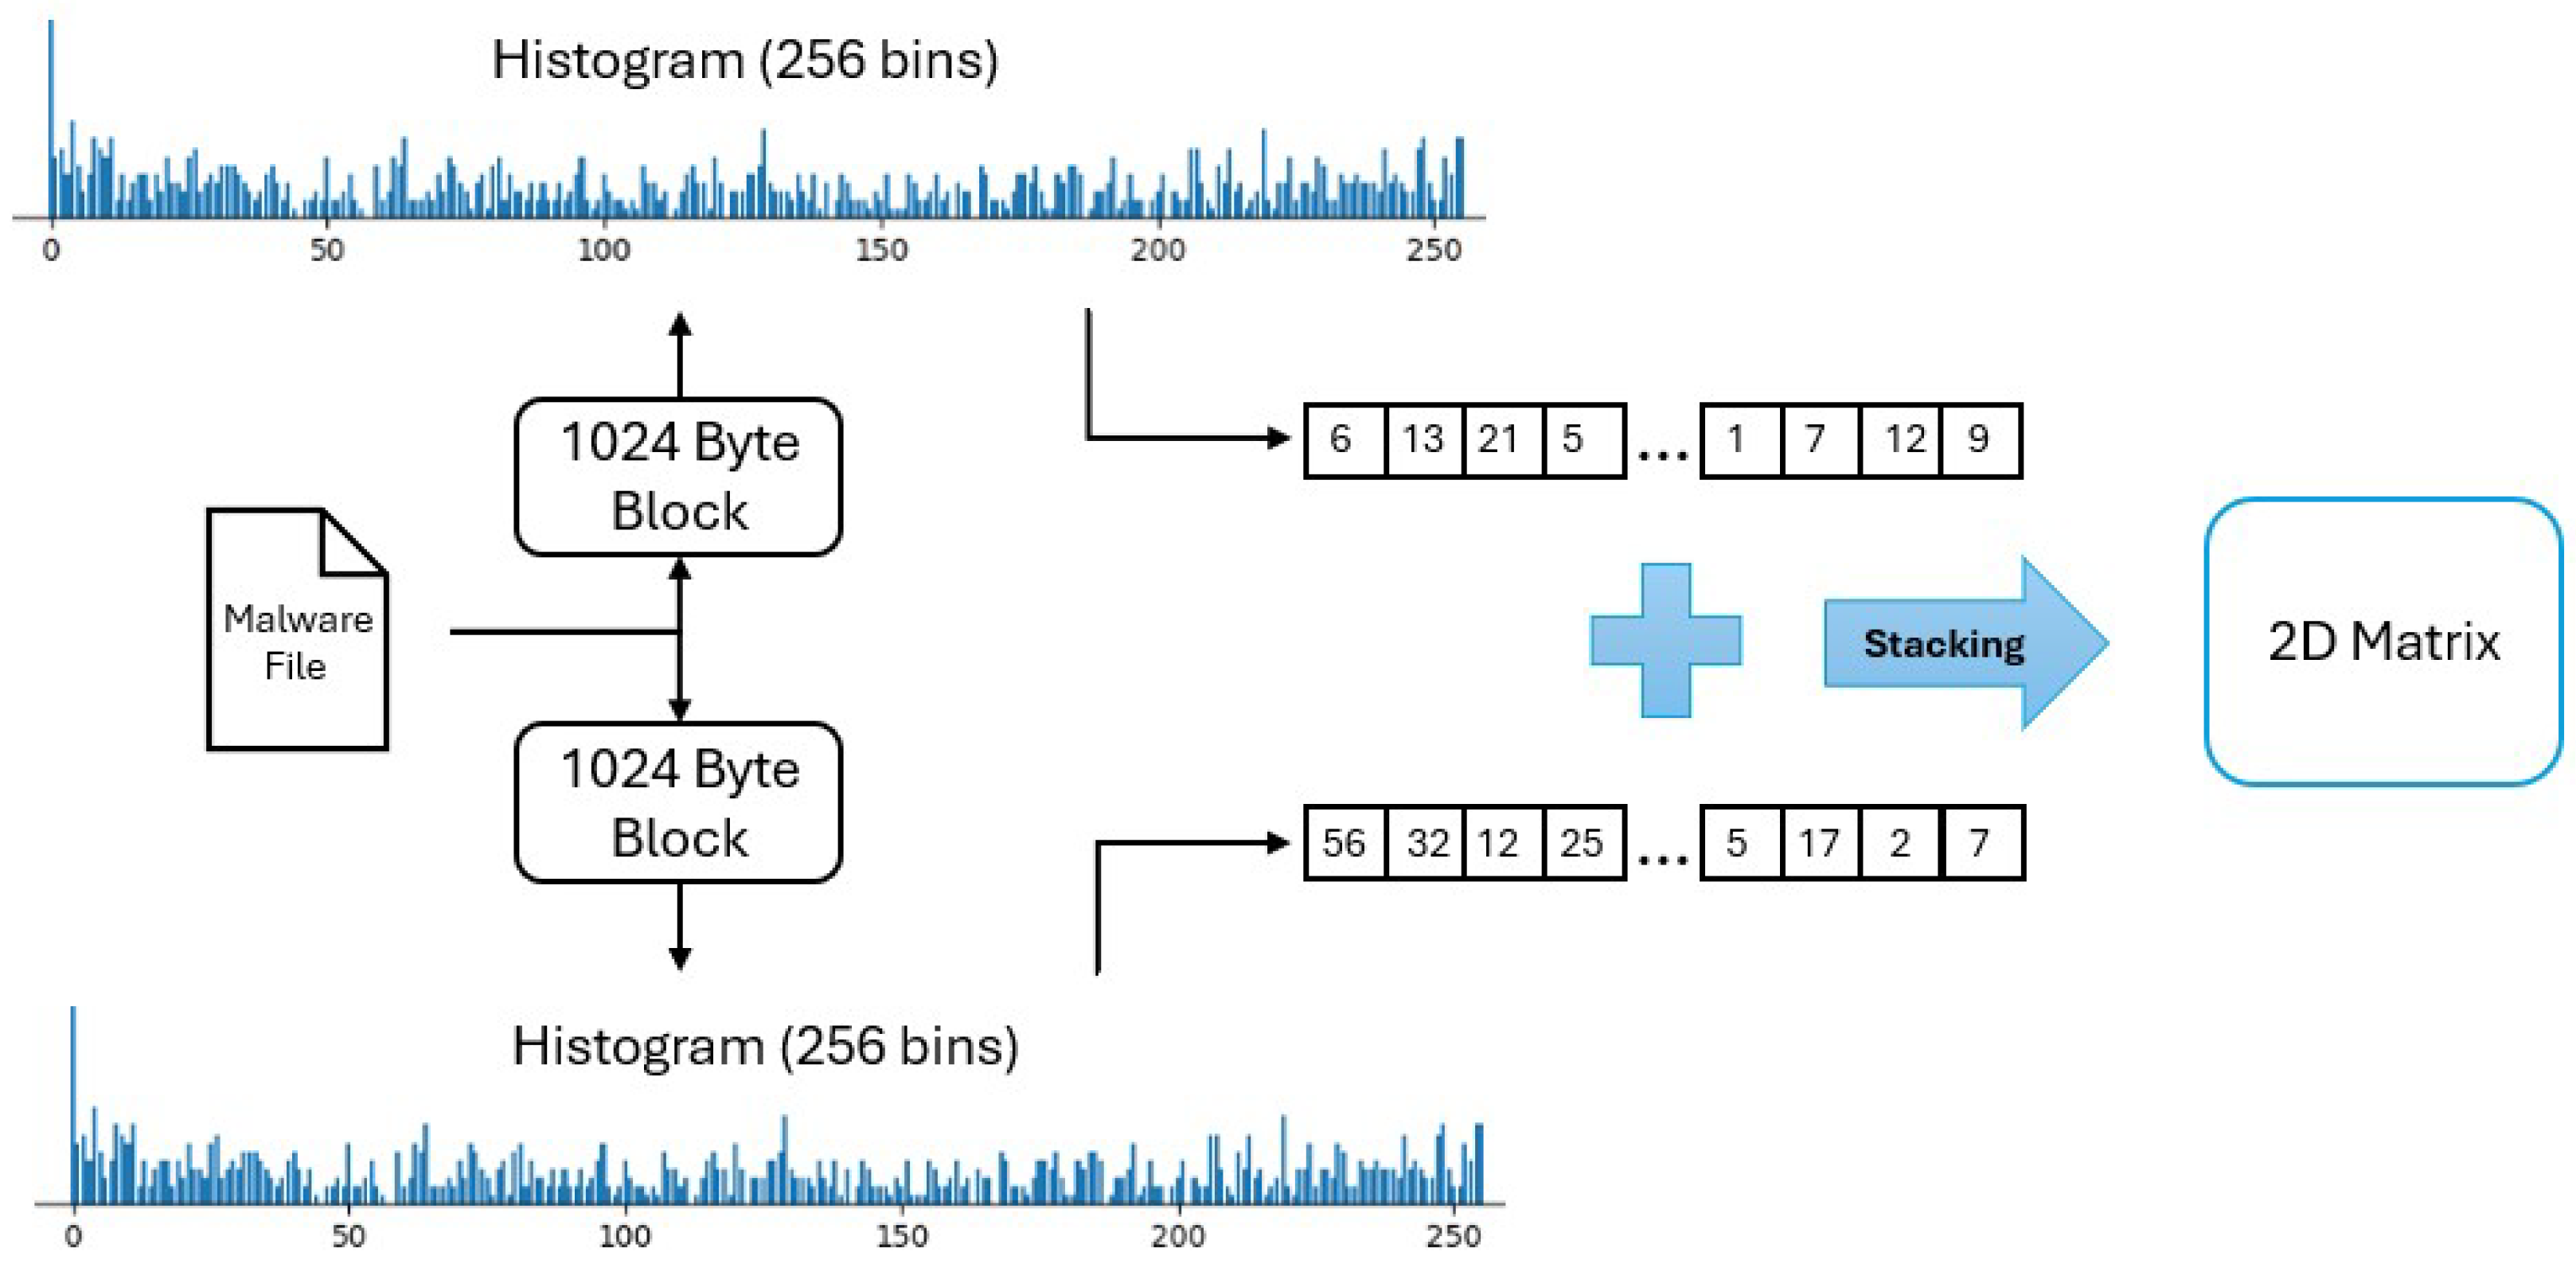
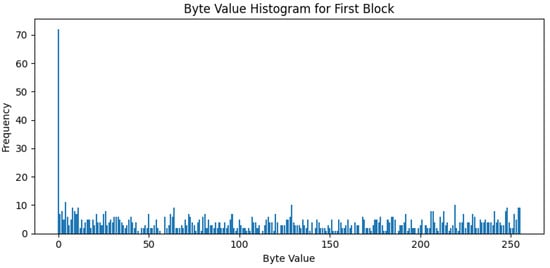
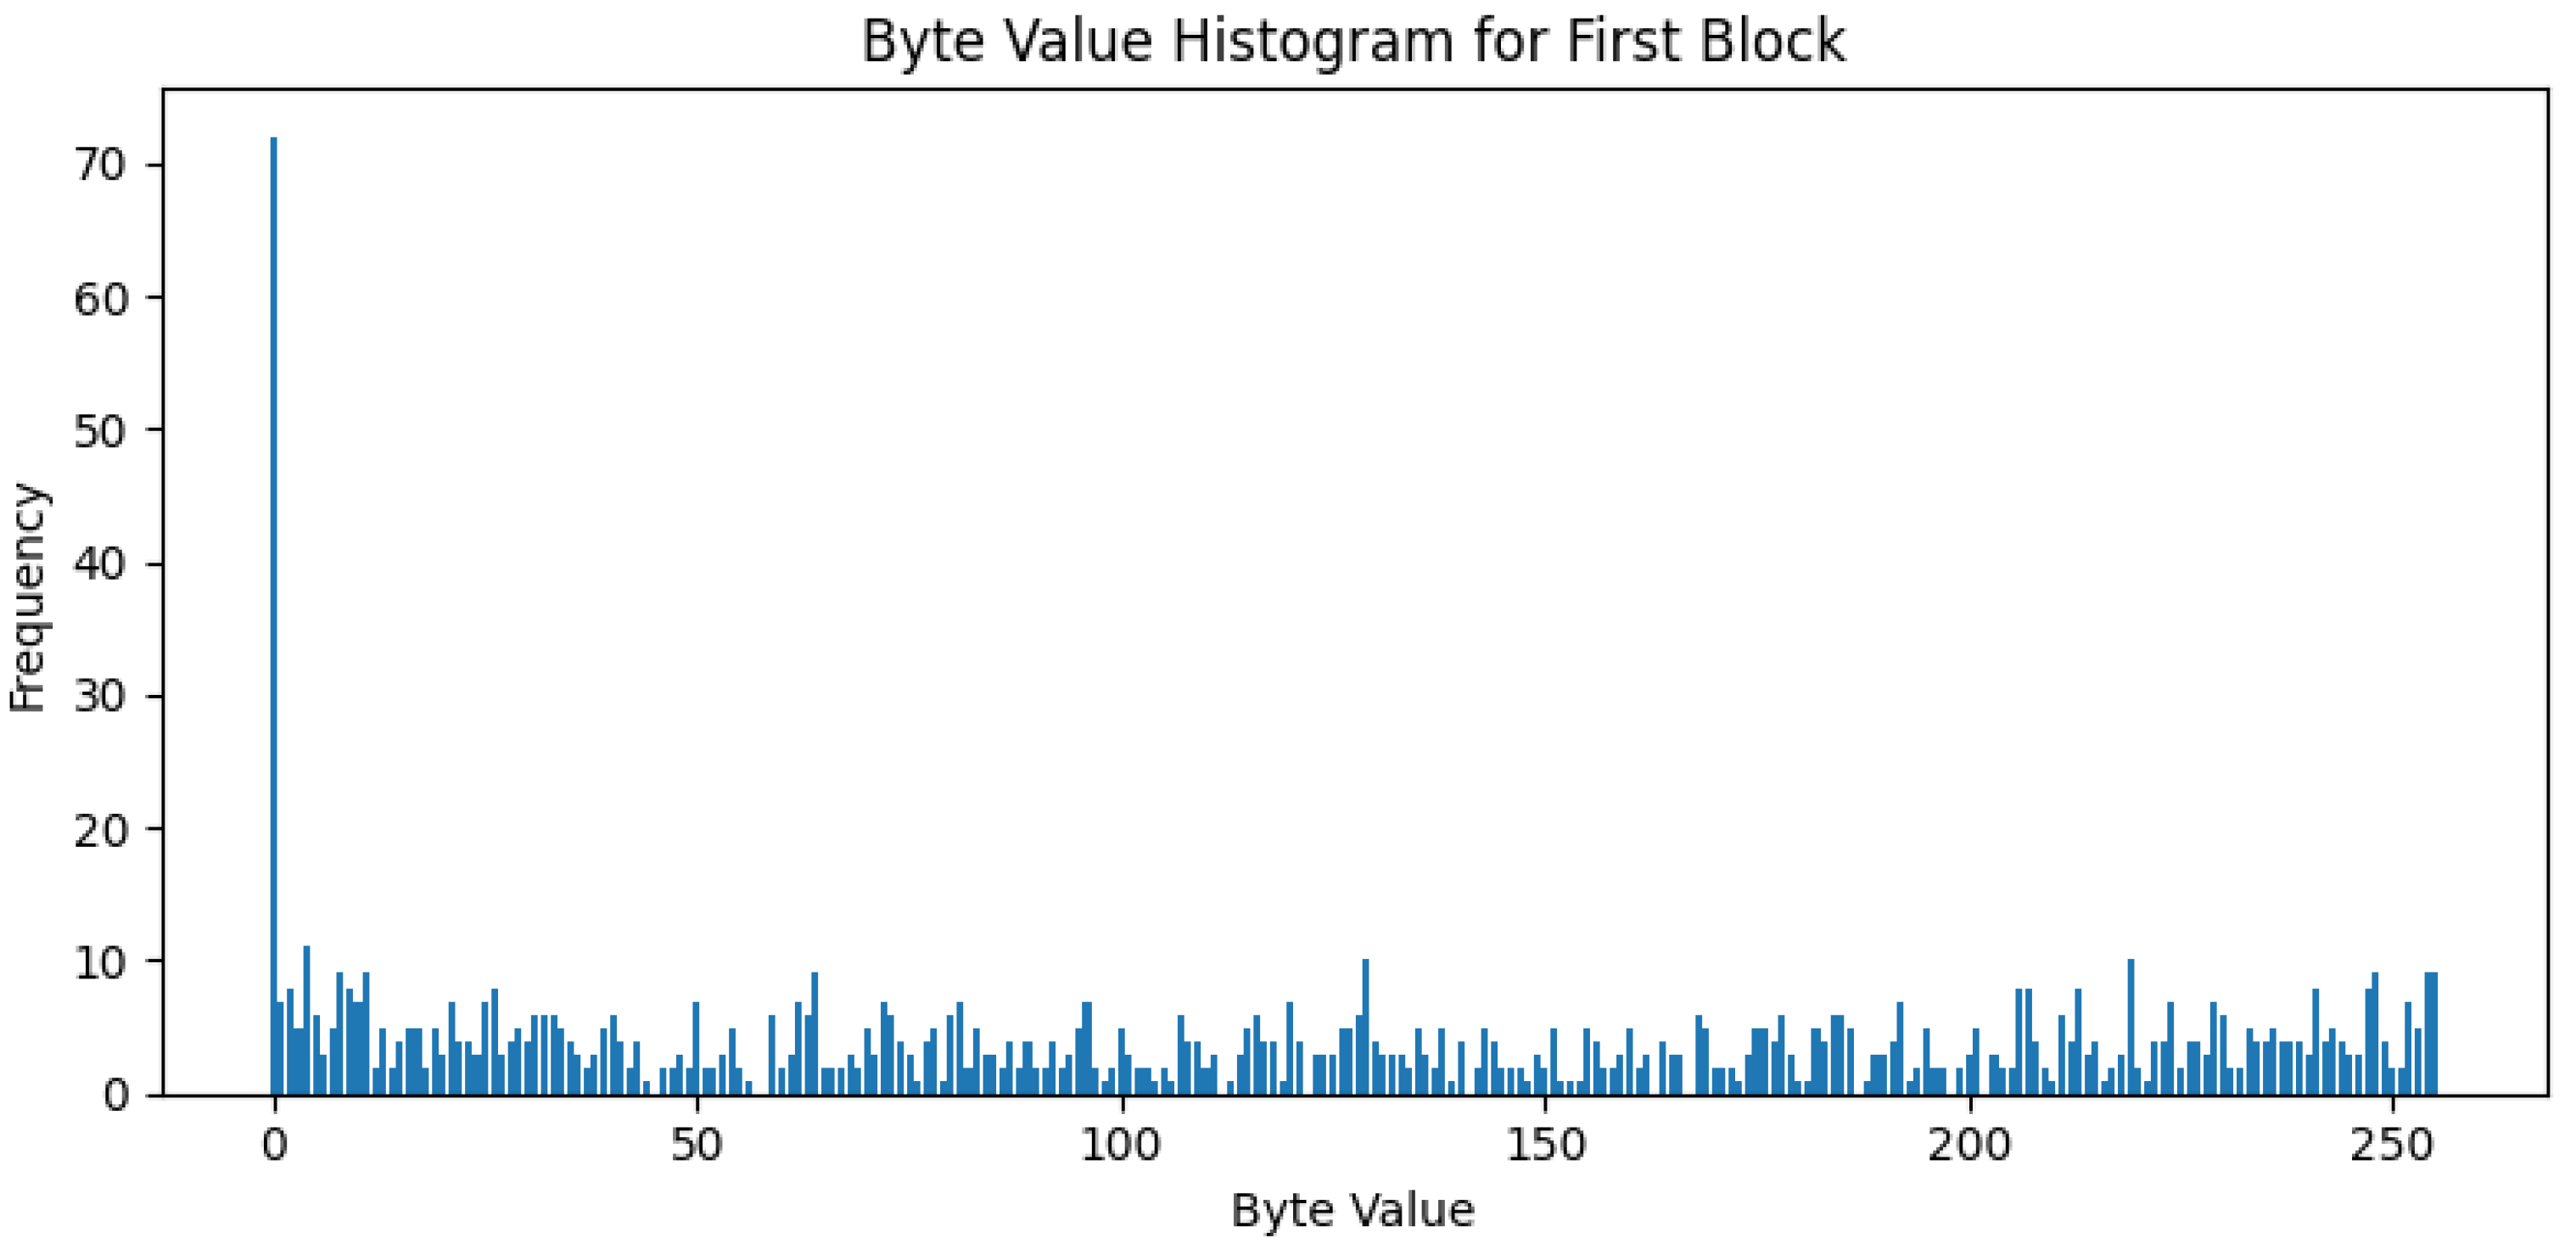
In this project, robust hashing is used to convert malware binaries into two-dimensional image representations, enabling CNN-based models to identify visual patterns. The specific hashing method used is histogram hashing, which creates a compact visual fingerprint by summarizing byte frequency distributions across segments of the binary file. As shown in Figure 6, the process begins by splitting each binary file into fixed-size blocks of, for example, 1024 bytes (1KB). For each block, the frequency of byte values (ranging from 0 to 255) is computed to form a histogram. These histograms are then stacked to create a two-dimensional matrix. The resulting image becomes the robust hash, a visual representation that captures structural characteristics of the binary while remaining resilient to minor alterations.
Figure 6.
Hashing process.
Figure 7 illustrates the histogram for the first block of a malware file. The x-axis denotes byte values (0–255), while the y-axis indicates the frequency of each byte value in the block.
Figure 7.
Histiogram hashing.
These two-dimensional matrices, composed of histograms from each block in the binary file, are normalized such that each row sums to 1 and then resized to a fixed 256 × 256 image. It is important to note that the resulting image dimensions can vary depending on the number and size of blocks. To ensure consistent image size across samples, regardless of the input file’s length, the block size may be adjusted dynamically for each file.
The default block size of 1024 bytes was selected to balance granularity and computational efficiency. Smaller blocks (e.g., 256 bytes) tend to produce overly sparse histograms, which dilute structural patterns and increase noise sensitivity. Conversely, larger blocks (e.g., 4096 bytes) may obscure local variations critical for distinguishing malware families. Empirical testing showed that 1024 bytes provided sufficient resolution to capture meaningful byte distributions while maintaining manageable image dimensions.
Gamma correction is then applied to enhance image contrast and highlight subtle patterns. In our experiments, we found the gamma value 0.4 to be the best choice. This value was chosen after evaluating a range of gamma settings (0.2–1.0) across multiple obfuscated samples. Gamma = 0.4 consistently produced images with enhanced mid-tone contrast, making subtle distributional shifts more visible to CNN filters. Higher gamma values tended to darken the image excessively, compressing dynamic range and obscuring fine-grained features. Lower values, while brighter, failed to emphasize the structural nuances introduced by obfuscation. Thus, gamma = 0.4 offered the best trade-off between visibility and feature preservation.
From a computational standpoint, histogram hashing is lightweight and highly scalable. The byte frequency computation for each block is linear in time with respect to file size, and the resulting image construction involves simple stacking and normalization operations. Compared to more complex feature extraction methods, this approach introduces minimal overhead and can be parallelized across files or blocks. In practice, preprocessing a typical malware sample takes less than a second on standard hardware, making it suitable for large-scale batch processing and real-time classification pipelines.
To ensure fair evaluation across malware families, the dataset was split using stratified sampling, preserving class proportions in both training and test sets. This method mitigates the impact of class imbalance and ensures that minority classes are adequately represented during model training and validation. Key parameters such as batch size (32), learning rate (0.001), and number of epochs (50) were selected based on grid search and prior benchmarks in image-based malware classification. These settings provided stable convergence and consistent performance across all CNN architectures.
The final output is a grayscale image representing the malware’s robust hash.
Here a summary of the key steps in the robust hashing process:
- Input: raw binary malware files from the dataset.
- Block-wise Histogram Calculation: Byte frequencies (0–255) are computed for each fixed-size block of the binary file.
- Matrix Formation: Histograms from all blocks are stacked to form a 2D matrix.
- Normalization: Each row of the matrix is scaled to sum to 1.
- Resizing: The histogram matrix is resized to a 256×256 image to standardize input for CNN models.
- Gamma Correction: applied to enhance contrast and bring out subtle visual features (gamma = 0.4).
- Output: final PNG images representing robust hashes, ready for classification.
5. Experiments
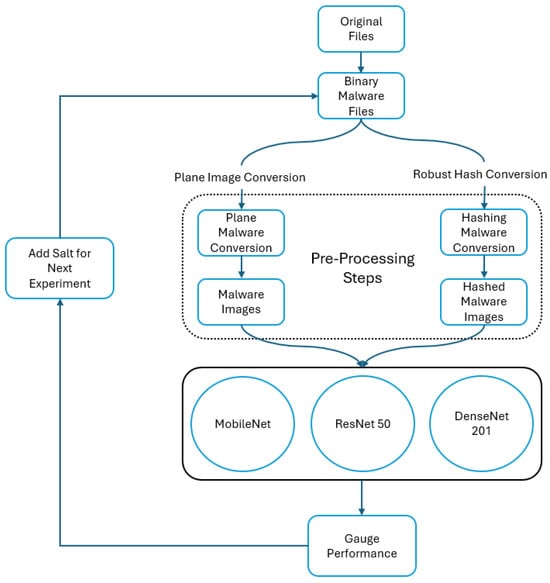
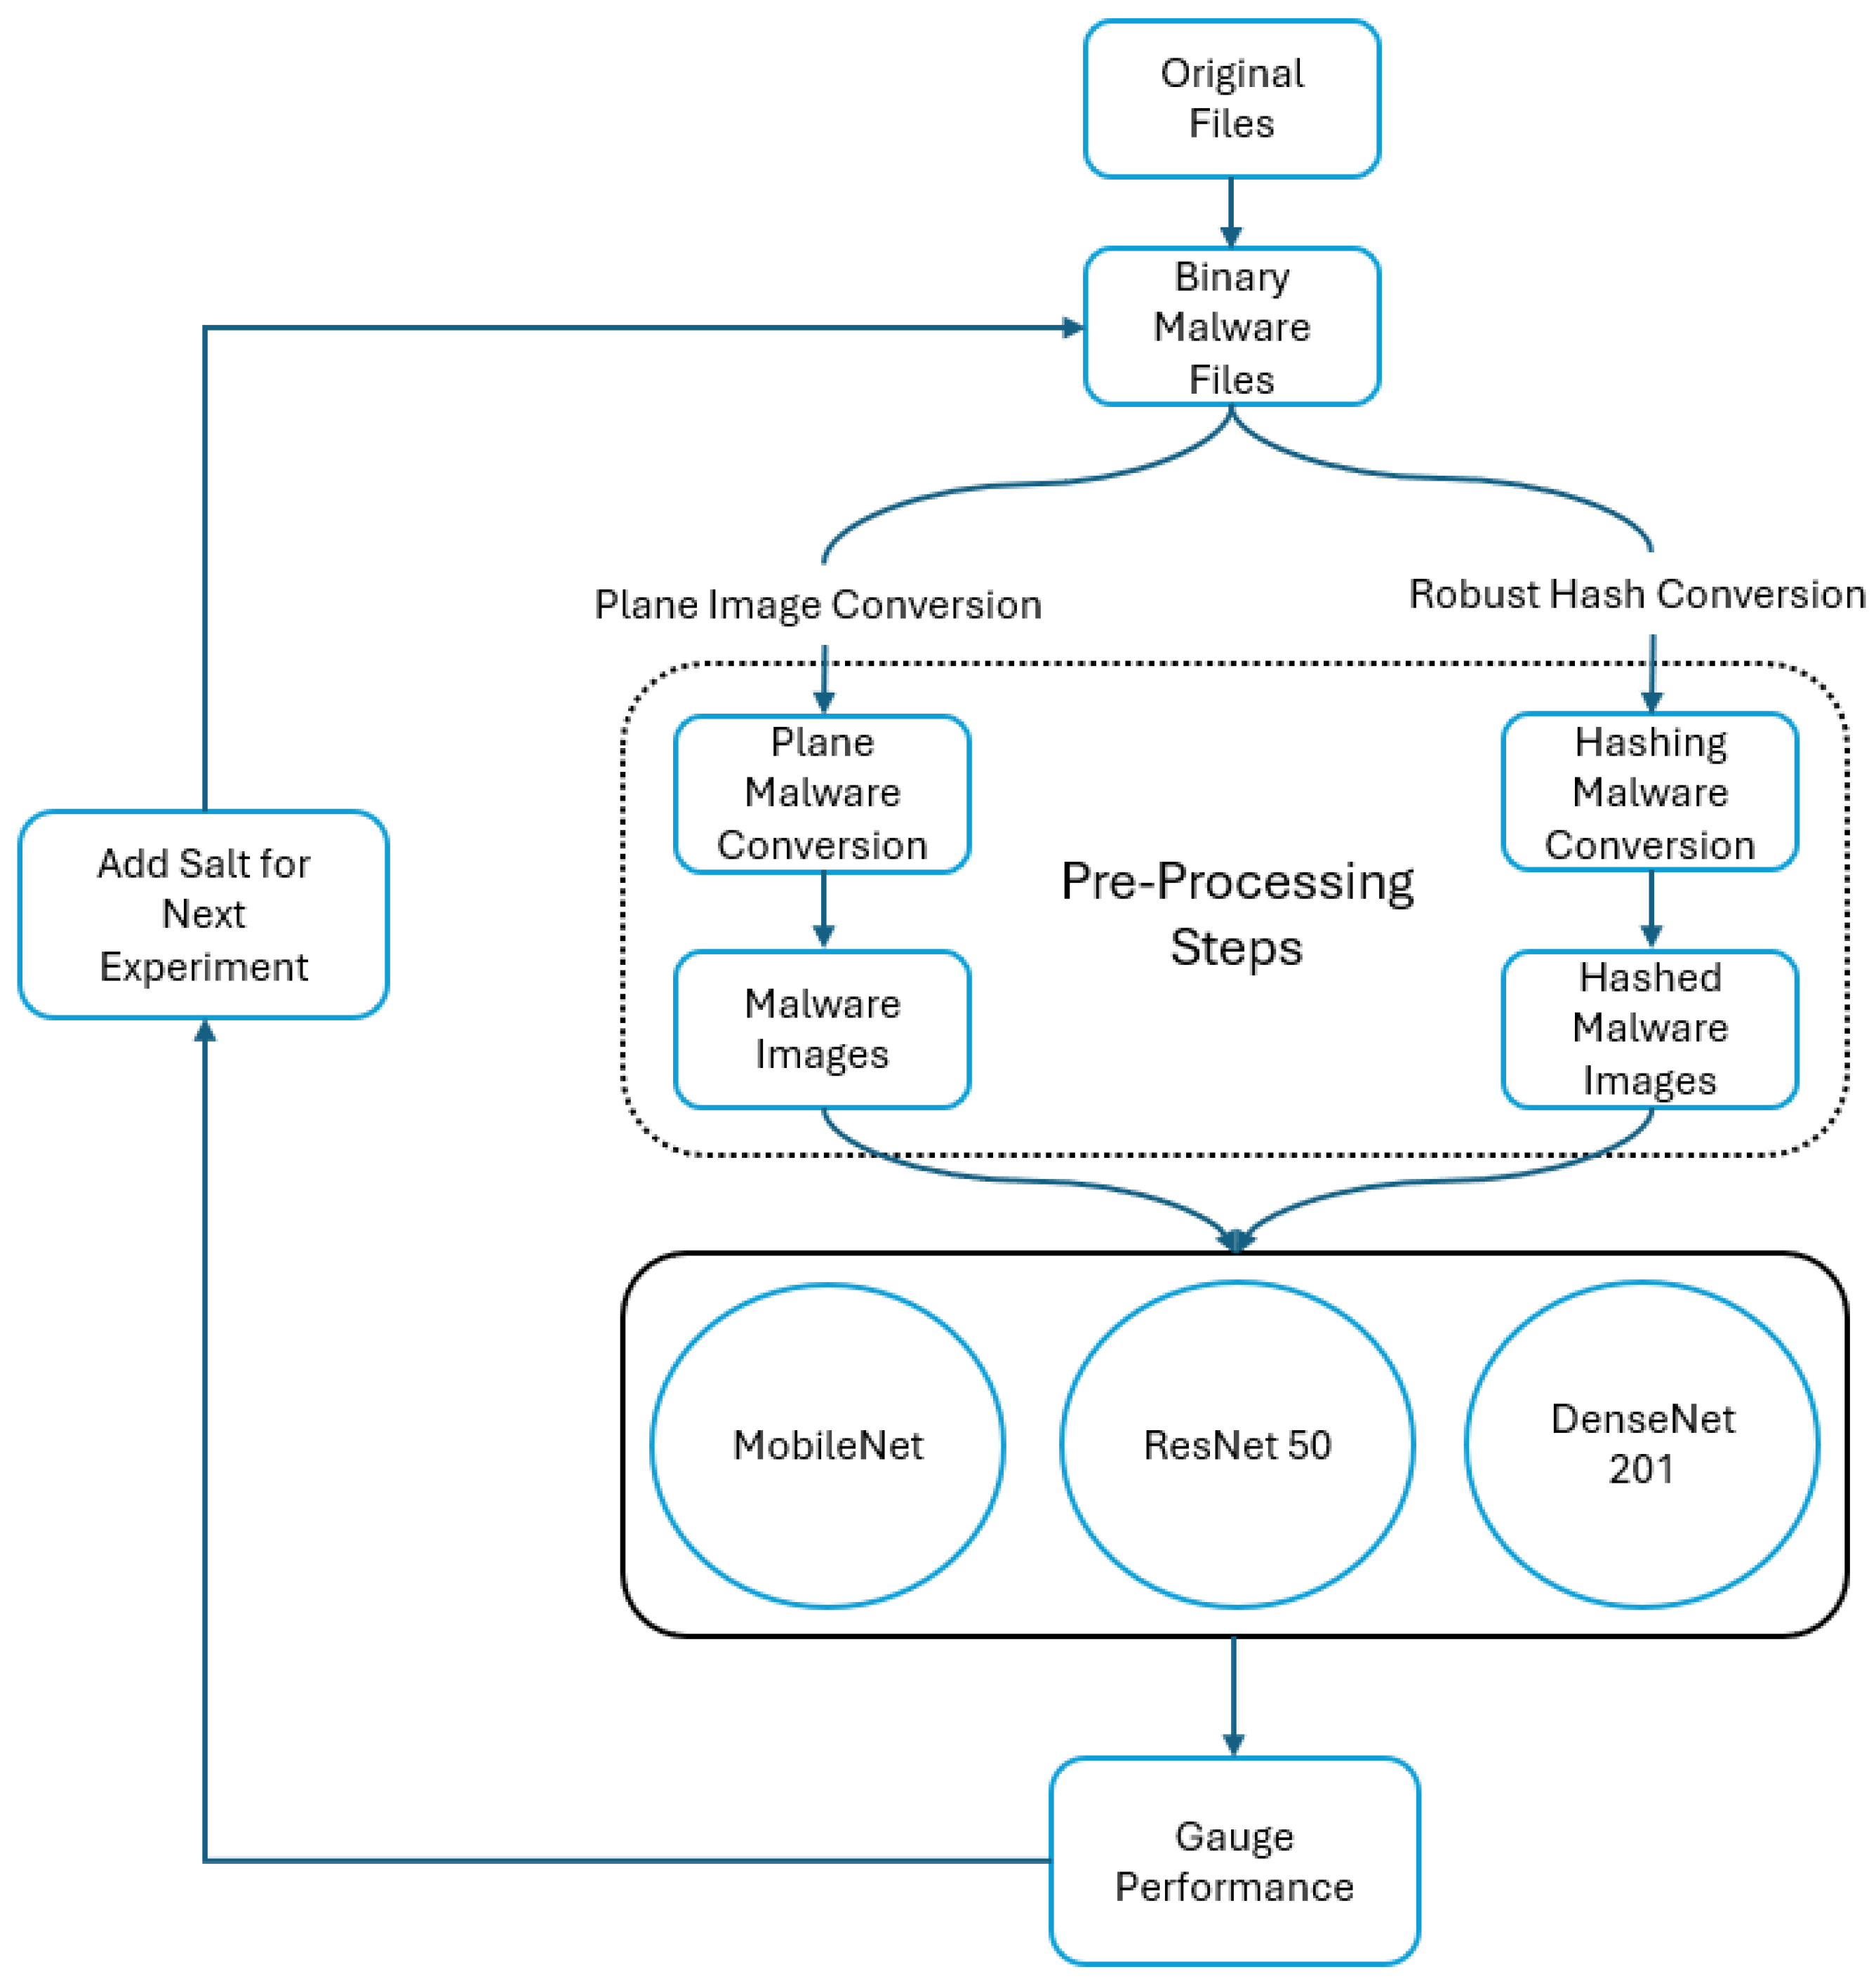
This research focuses on evaluating the performance of advanced CNN models, enhanced by robust hashing, on both obfuscated and non-obfuscated malware datasets. As outlined in Figure 8, each experiment began with binary malware files being converted into image representations using two distinct methods. The first involved a direct plane conversion using the Python Imaging Library (PIL) version 11.3.0 [32], while the second utilized robust hashing to produce more consistent and semantically meaningful feature mappings. These malware images were then fed into CNN models to assess classification performance.
Figure 8.
Experiments flow diagram.
Initial experiments on the non-obfuscated dataset, that is, converted directly to image format without hashing, yielded a classification accuracy of 71% in multiclass settings, where the CNN was tasked with assigning samples to one of 20 malware families. Applying the same CNN models to non-obfuscated images generated via robust hashing, instead, led to a nearly 20% increase in classification accuracy, along with improvements in the model loss value and both training and validation performance. These findings demonstrate that robust hashing substantially enhances CNN effectiveness in malware classification tasks.
Subsequent experiments focused on obfuscated datasets. Obfuscation was performed using a salting approach, which fused binary data from multiple malware families. Two types of image conversions were used: One involved hashing prior to salting, while the other employed standard PIL conversion. Experiments were repeated across five salting ratios, 0%, 10%, 20%, 30%, and 40%, each representing the proportion of data derived from the adversarial malware family. Models were tested with both obfuscation strategies to evaluate robustness under adversarial conditions.
Three advanced CNN architectures were utilized: MobileNet, ResNet, and DenseNet. Each configuration was assessed in two phases, without hashing, and with hashing, on both obfuscated and non-obfuscated datasets. The dataset was split using a 70-15-15 ratio for training, validation, and testing, respectively, to ensure balanced generalization. Transfer learning was employed, leveraging pre-trained ImageNet weights to accelerate convergence and minimize training data requirements.
Images were resized from to pixels to align with the input dimensions of pre-trained models. Experiments were conducted using a batch size of 128, with the Adam optimizer applied to dynamically adjust learning rates. Training was limited to a maximum of 50 epochs, and early stopping was triggered after three consecutive epochs without improvement to prevent overfitting. Categorical crossentropy was chosen as the loss function, suitable for multi-class classification, and accuracy served as the primary evaluation metric.
To further explore feature dimensionality, Principal Component Analysis (PCA) was tested. However, PCA did not yield improvements, as the CNN models already incorporate internal feature extraction and dimensionality reduction through their convolutional layers. Applying PCA post-feature extraction removed critical information and introduced redundancy, reinforcing the sufficiency of built-in model architectures for this task.
A comprehensive summary of the experimental phases includes the following:
- CNN evaluation on non-obfuscated data without hashing;
- CNN evaluation on non-obfuscated data with robust hashing;
- Experiments on obfuscated datasets using both hashed and standard image conversions;
- Application of five salting ratios: 0%, 10%, 20%, 30%, and 40%;
- Testing across MobileNet, ResNet, and DenseNet models;
- Each configuration repeated twice for validation and reliability.
6. Results
The experimental results, derived from testing MobileNet, ResNet, and DenseNet models under five salting conditions (0%, 10%, 20%, 30%, and 40%), demonstrate the tangible impact of robust hashing on malware classification accuracy. Each model was evaluated both with and without the robust hashing technique. The results consistently show that robust hashing improves model accuracy across varying levels of dataset obfuscation.
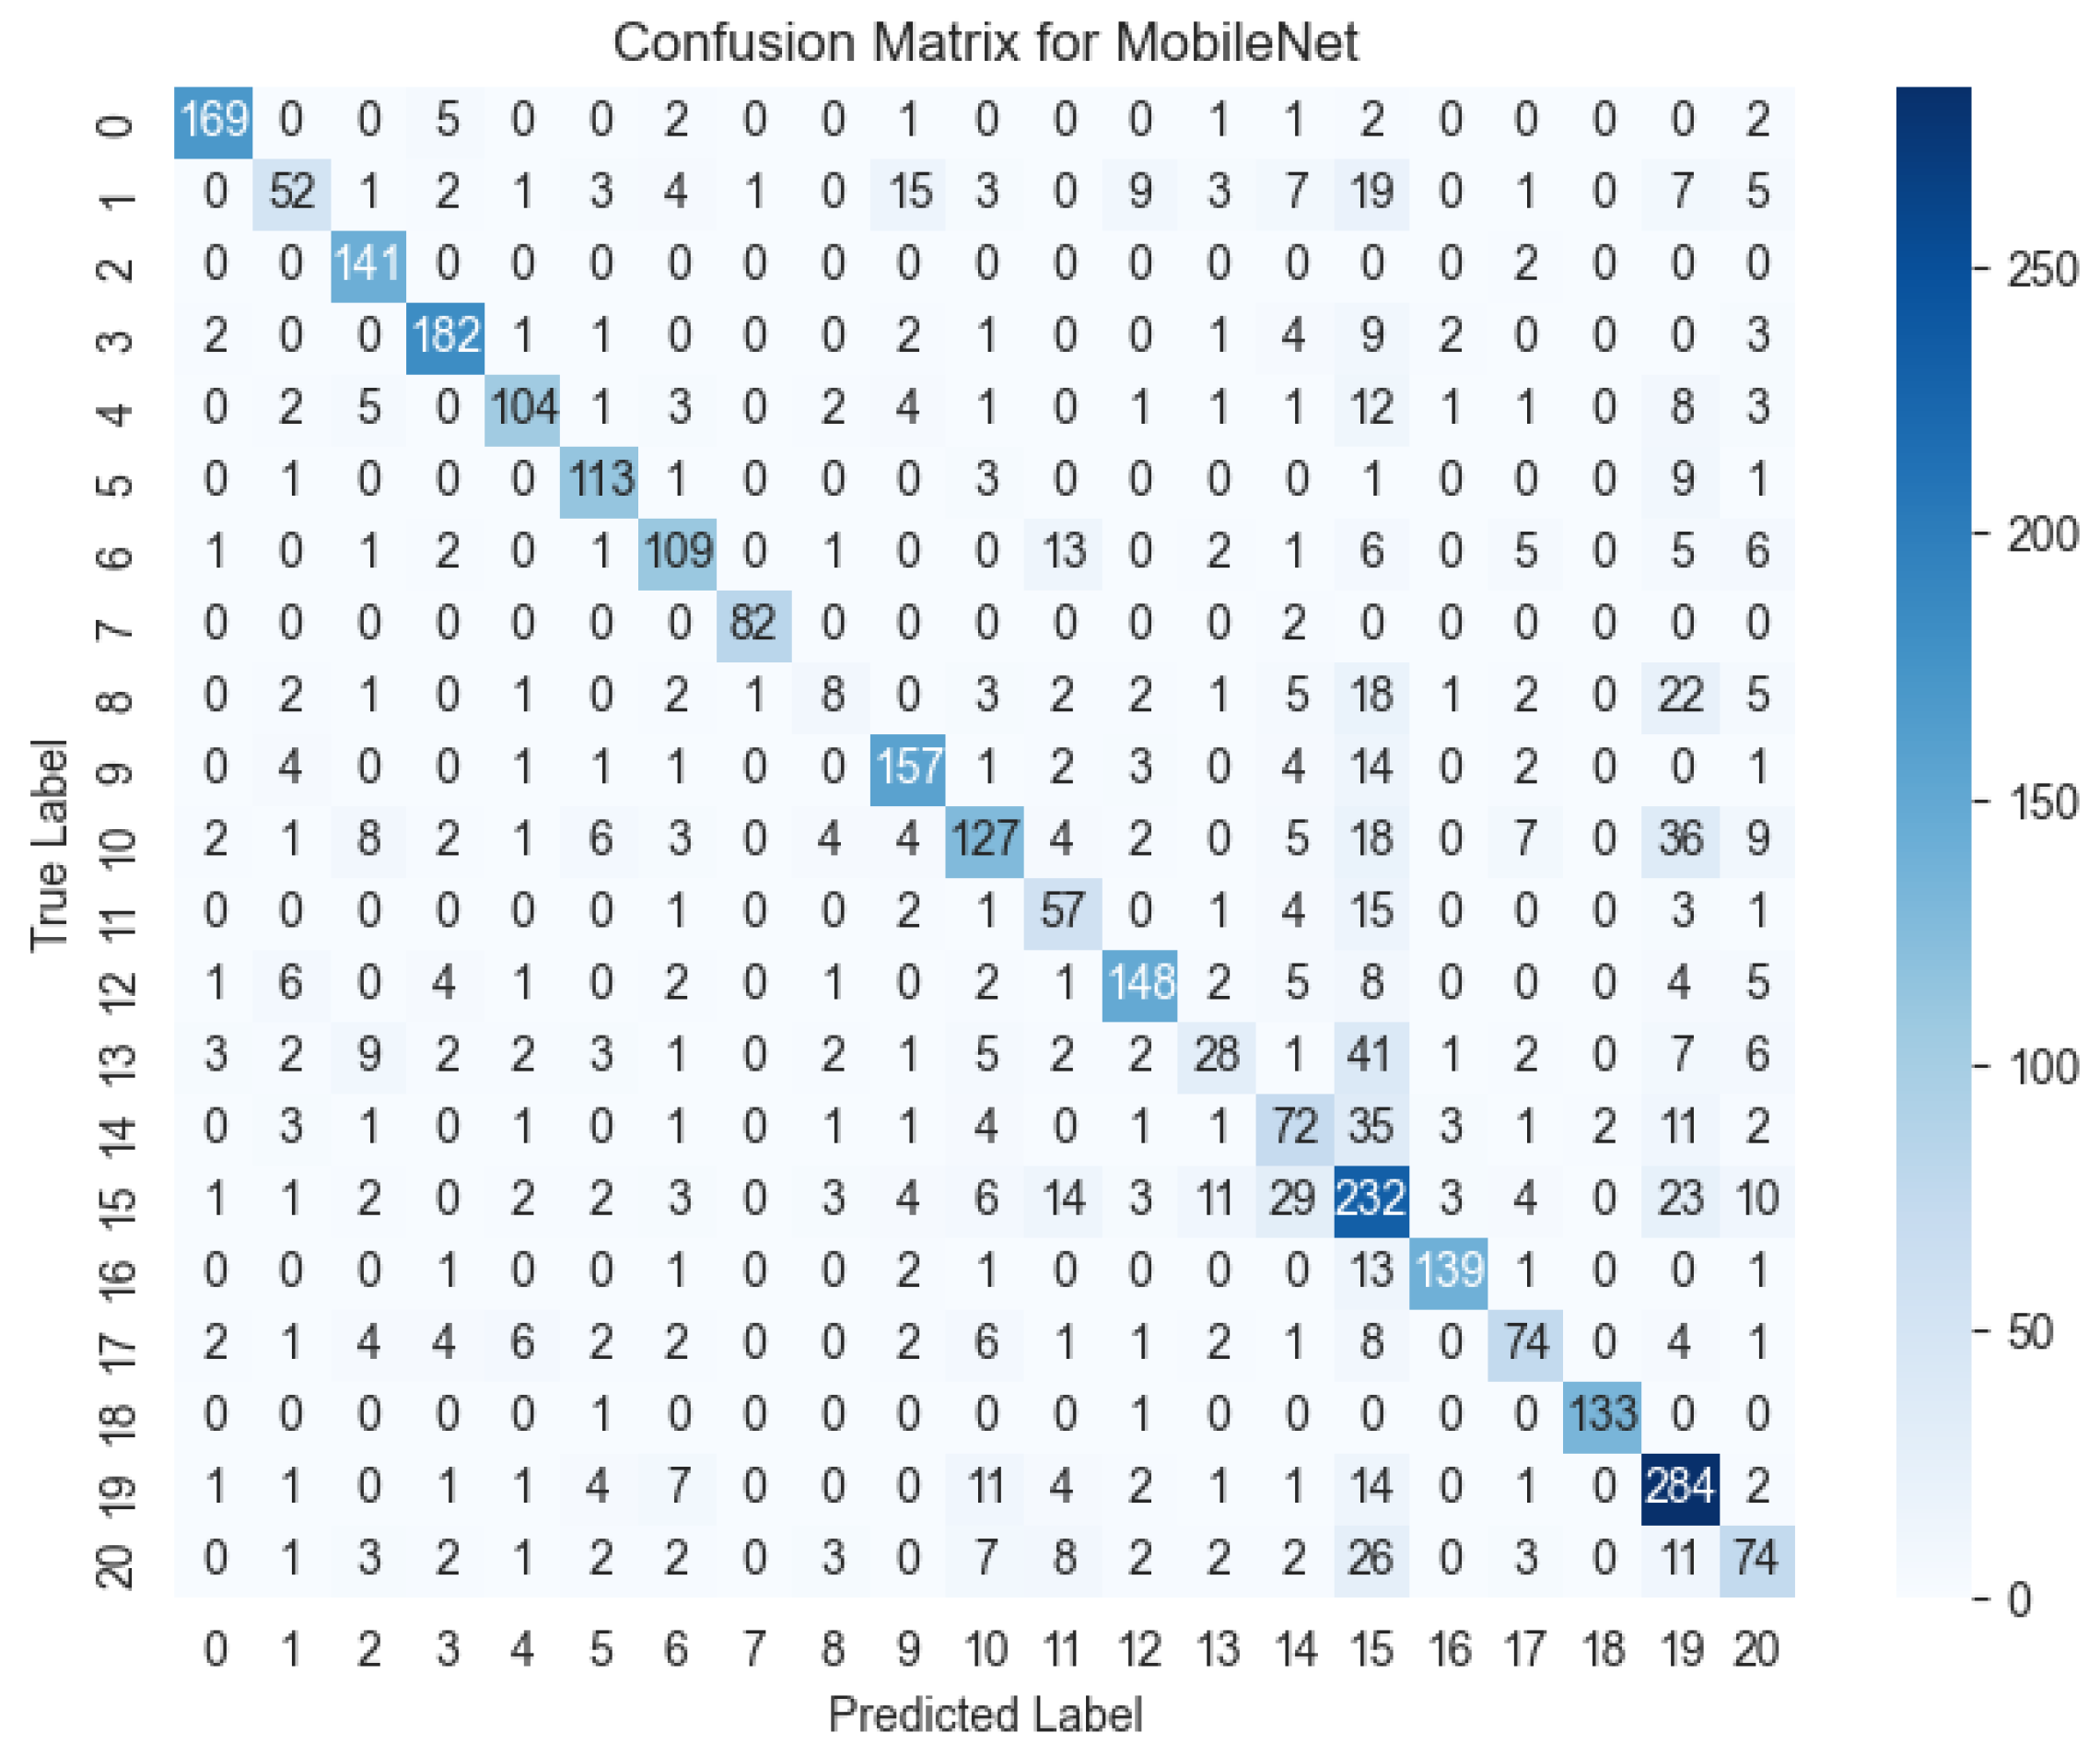
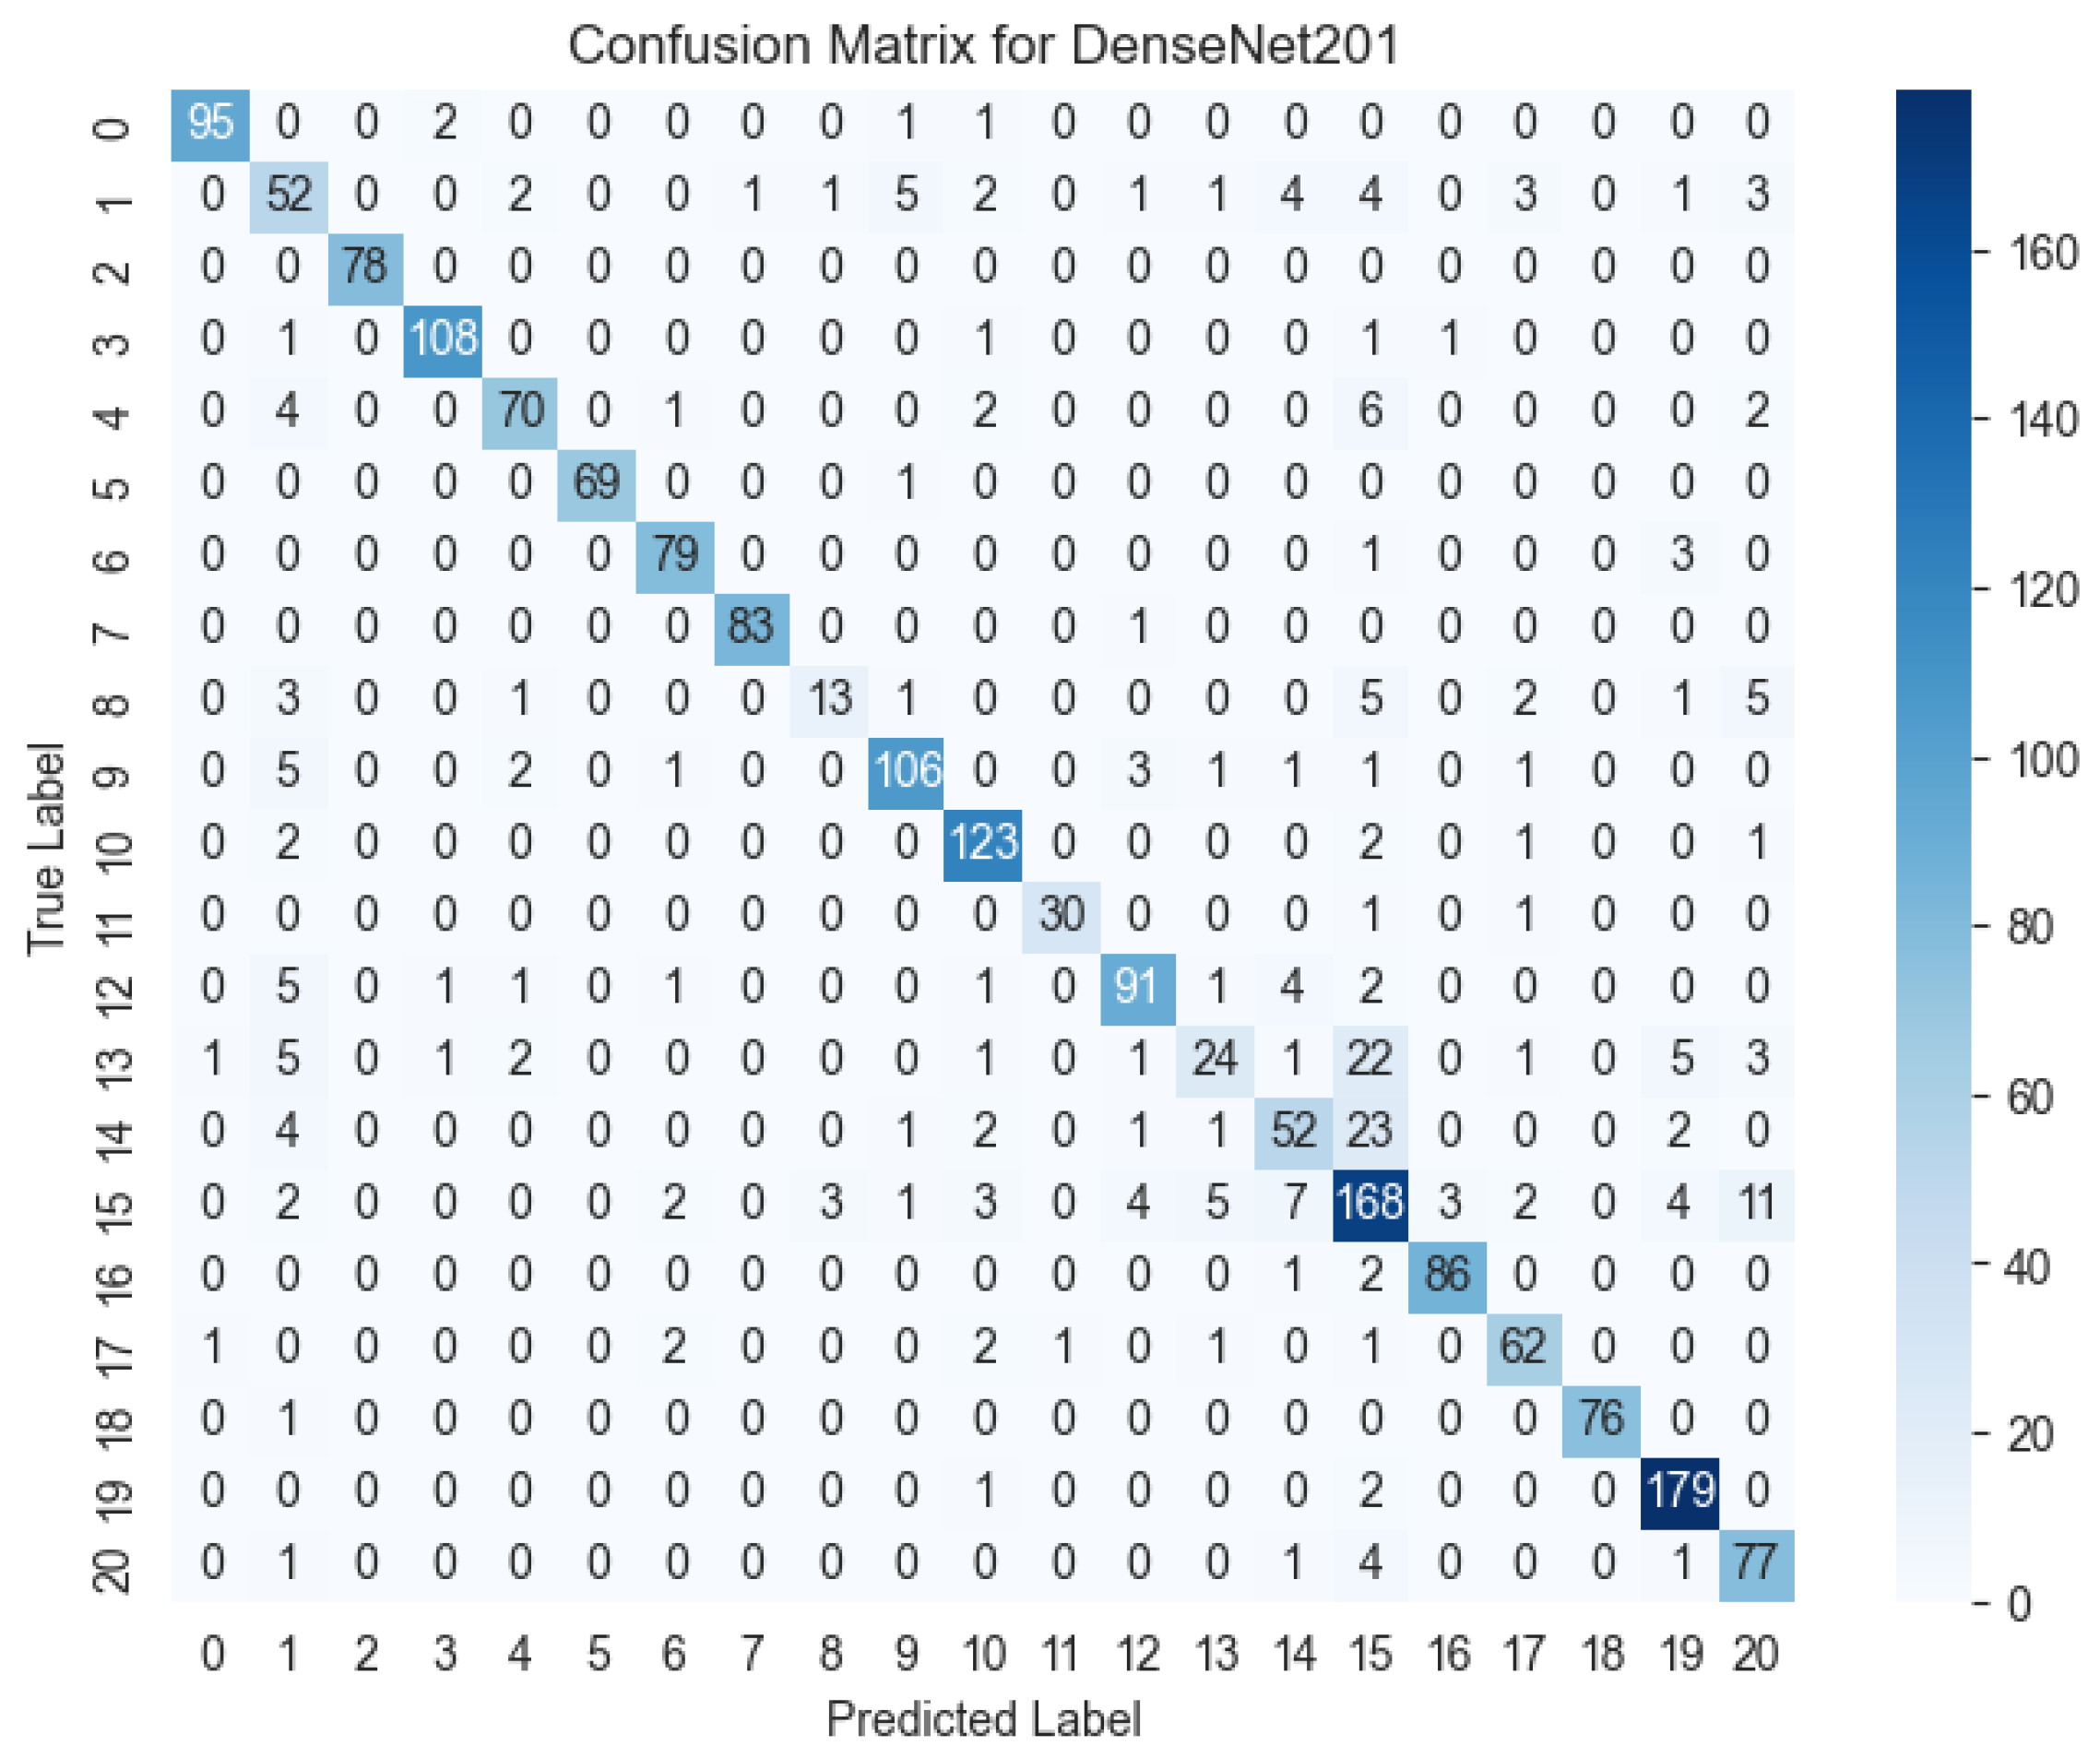
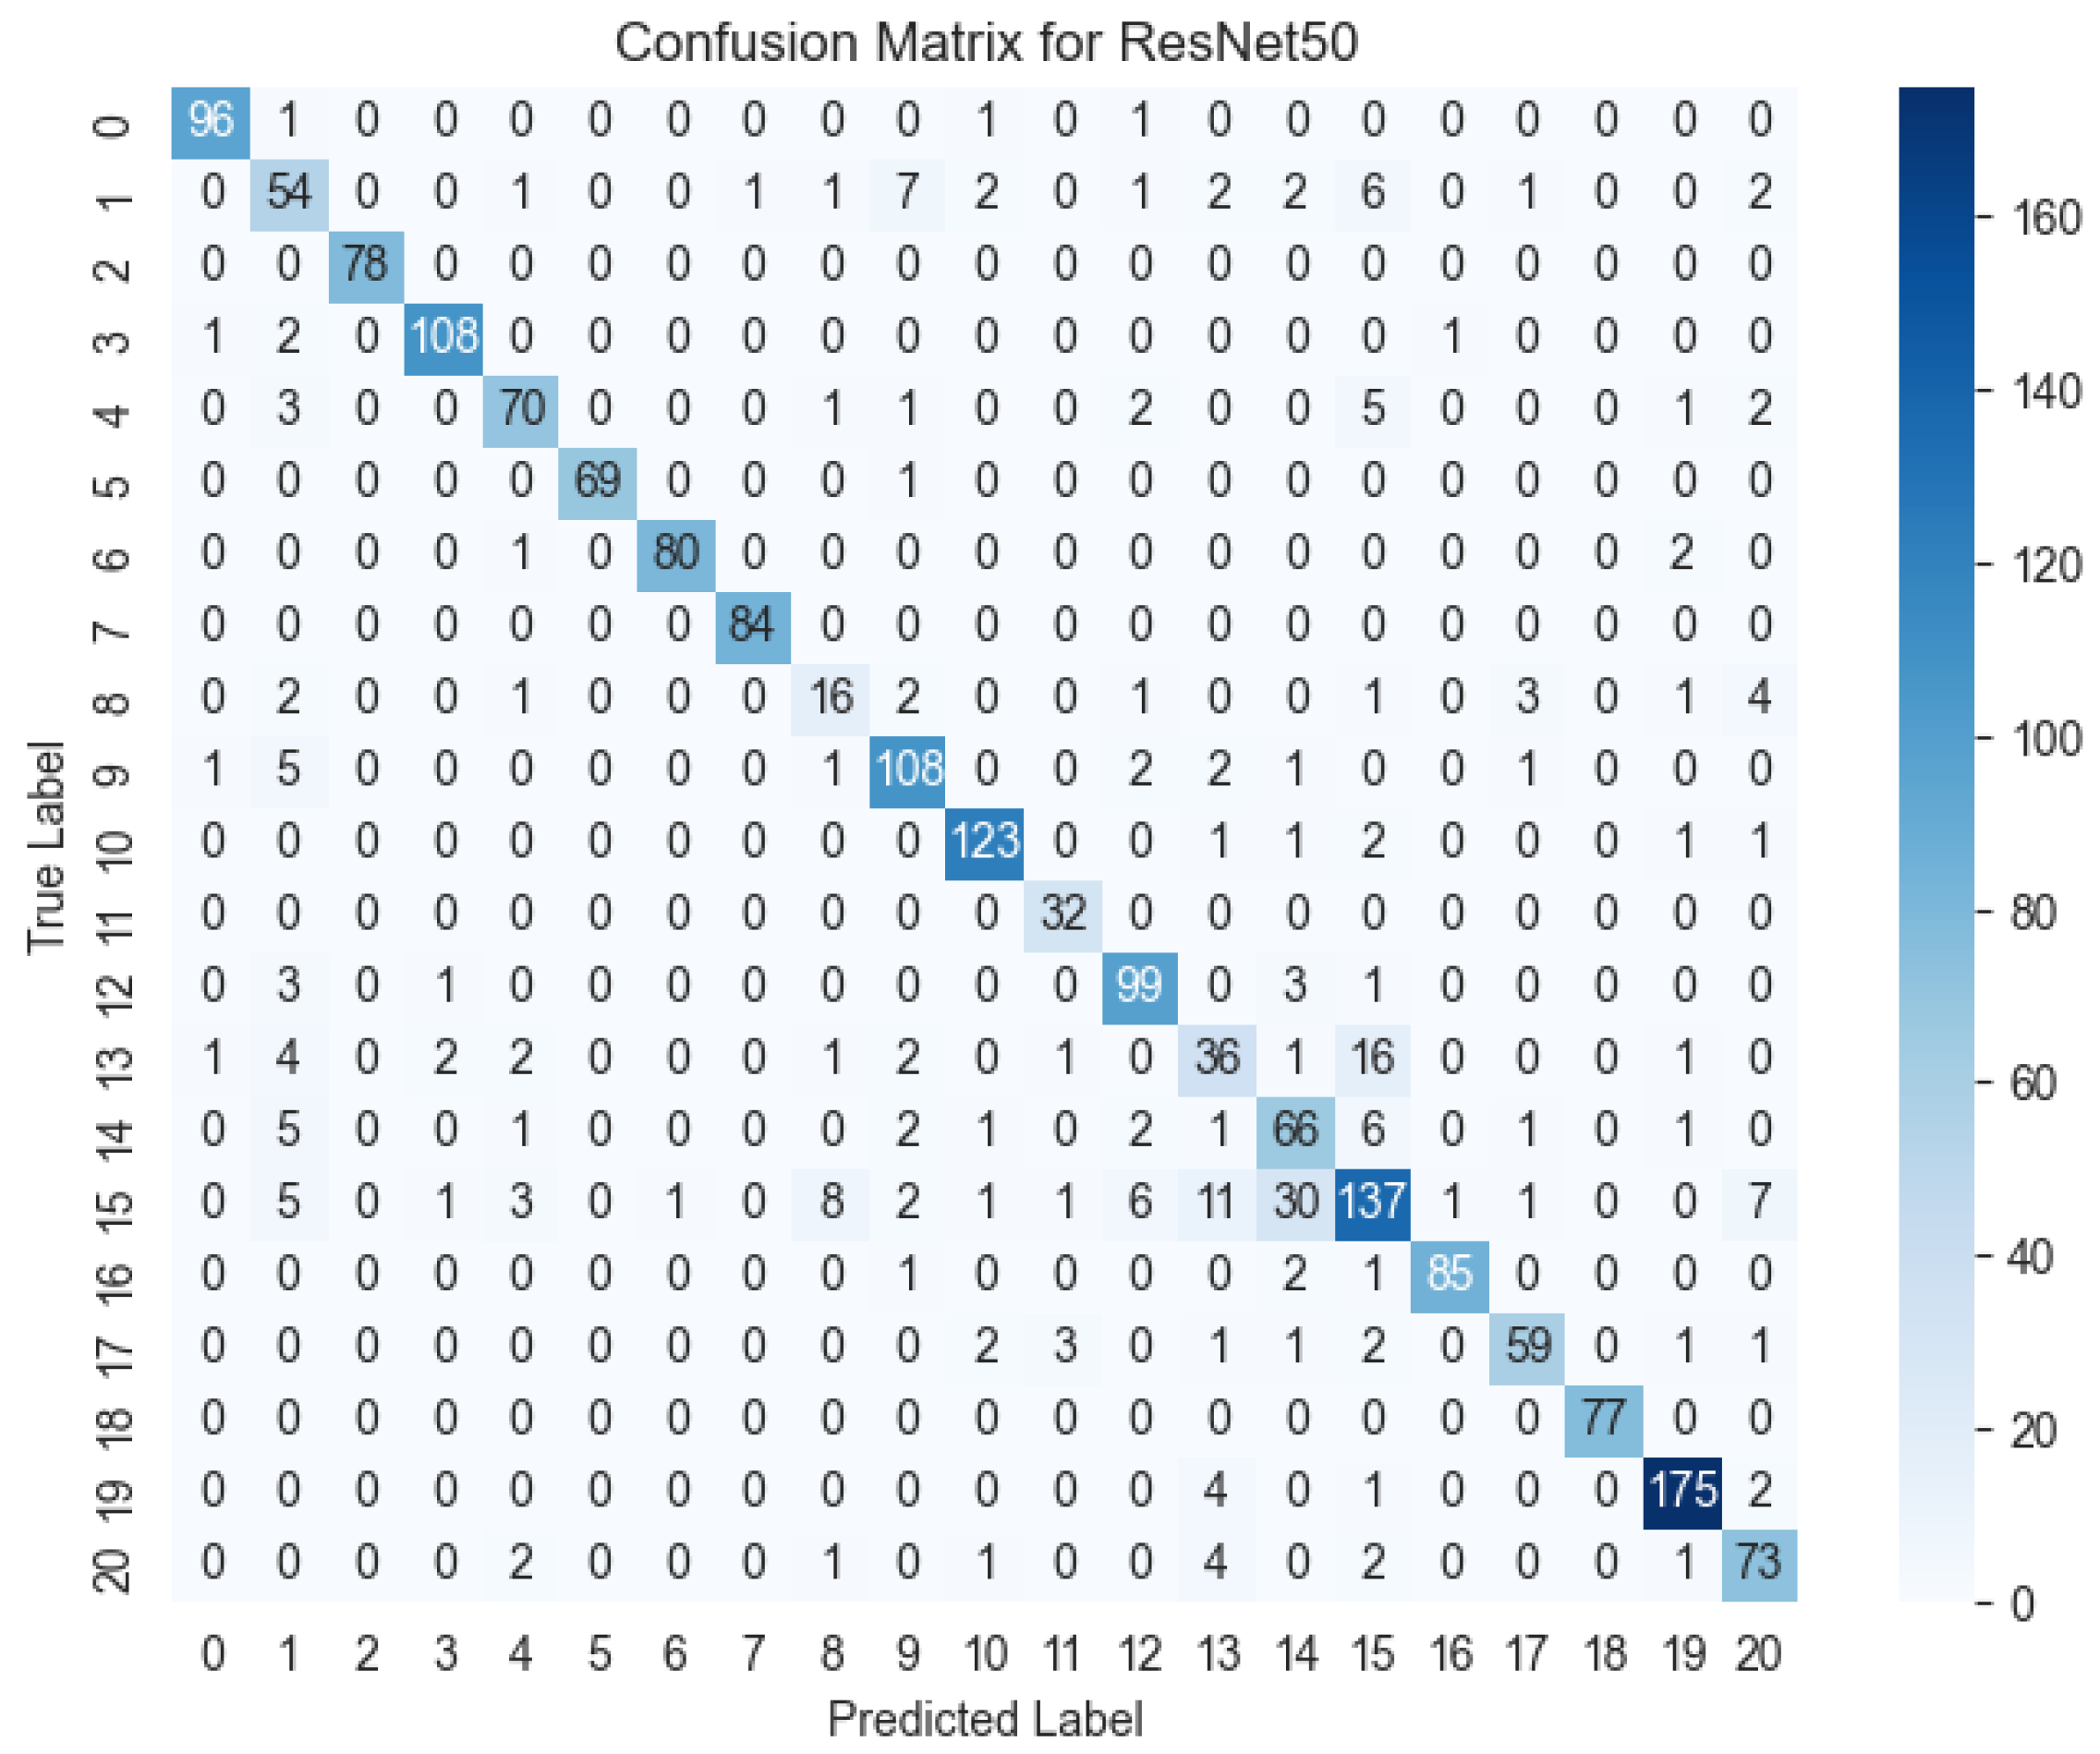
Figure 9, Figure 10 and Figure 11 present the confusion matrices for the unsalted experiments, which highlight the challenges in family-level classification.
Figure 9.
MobileNet confusion matrix for unsalted data.
Figure 10.
DenseNet confusion matrix for unsalted data.
Figure 11.
ResNet confusion matrix for unsalted data.
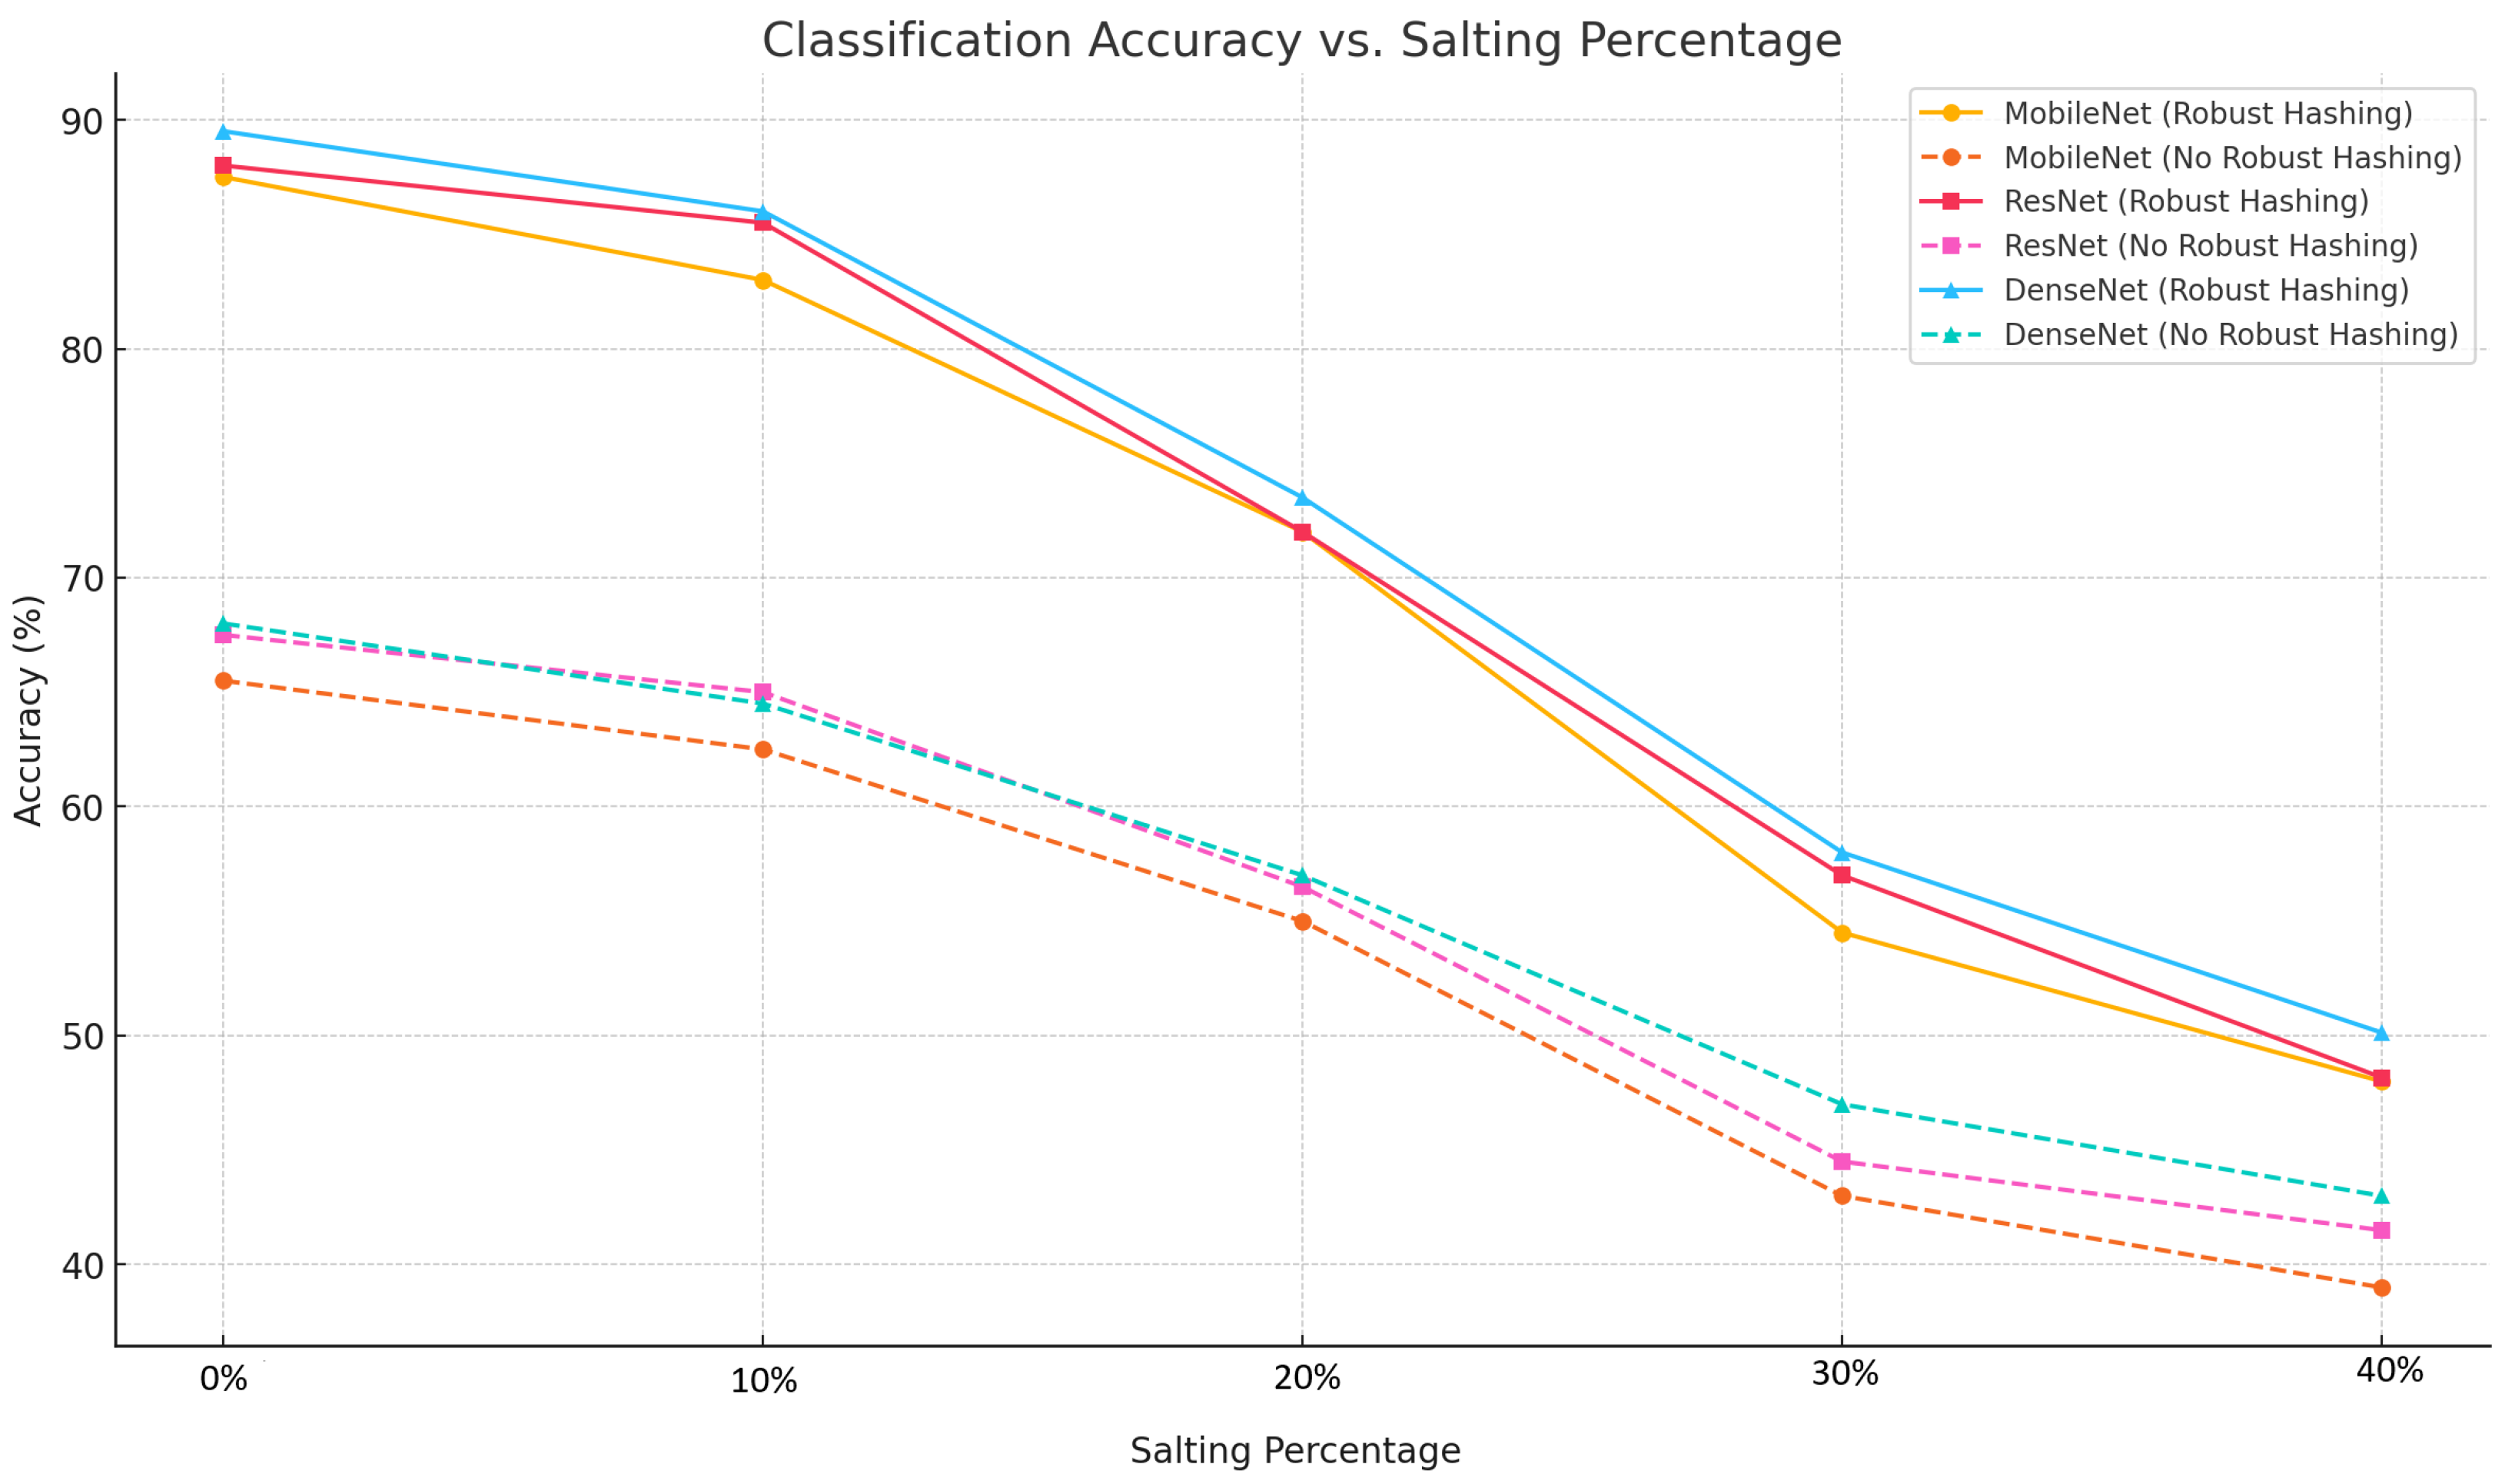
Table 2, Table 3, Table 4, Table 5 and Table 6 present accuracy comparisons under different salting ratios. The models achieved their highest performance on the unsalted data (0%), with DenseNet reaching an accuracy of 89.50% when robust hashing was applied, compared to 68.00% without it. As salting increased, accuracy declined across all models, but the presence of robust hashing consistently mitigated this drop. For example, at 40% salting, DenseNet still maintained a 7.13% improvement over its non-hashed counterpart.
Table 2.
Unsalted data with and without robust hashing.
Table 3.
10% salting with and without robust hashing.
Table 4.
20% salting with and without robust hashing.
Table 5.
30% salting with and without robust hashing.
Table 6.
40% salting with and without robust hashing.
Figure 12 illustrates the trend in model accuracy as salting levels increase, further confirming that while accuracy decreases with heavier obfuscation, robust hashing mitigates this drop consistently.
Figure 12.
Classification accuracy vs. salting percentage.
Figure 12 visualizes this trend, confirming that while obfuscation degrades model performance, robust hashing provides a stabilizing effect. Table 7 summarizes average performance across all salting levels, with MobileNet demonstrating the most consistent gains, averaging a 16.00% improvement, while DenseNet achieved the highest overall classification accuracy at 71.43%. Compared to MobileNet and ResNet, DenseNet exhibited superior resilience, particularly under moderate to high obfuscation conditions.
Table 7.
Average performance increments across salting levels.
To ensure the reliability of these findings, each experiment was repeated five times with randomized train–test splits. We report mean accuracy along with 95% confidence intervals to account for variance across runs. For instance, DenseNet with robust hashing at 0% salting achieved an average accuracy of 89.50% ± 1.12%, while the non-hashed variant averaged 68.00% ± 1.45%. Across all salting levels, the improvements observed with robust hashing were statistically significant (p < 0.01, paired t-test), confirming that the gains are not attributable to random variation.
DenseNet’s superior performance can be attributed to its dense connectivity pattern, which facilitates feature reuse across all layers. This architectural trait is particularly well suited to histogram-based robust hashing, where meaningful features, such as byte frequency distributions and entropy spikes, are distributed across the entire image. Unlike ResNet, which relies on residual shortcuts, or MobileNet, which uses depthwise separable convolutions for efficiency, DenseNet continuously propagates and refines low-level features. This allows the network to preserve subtle structural cues that are critical for distinguishing obfuscated malware variants. The observed accuracy improvement at 40% salting (from 43% to 50.13%) suggests that robust hashing retains class-discriminative information even under aggressive perturbation. This resilience stems from the fact that histogram hashing emphasizes statistical regularities rather than spatial arrangements, making it less sensitive to pixel-level noise introduced by salting. To explore the upper bound of this anti-obfuscation capability, we conducted additional tests at 50% and 60% salting. While overall accuracy declined, DenseNet with robust hashing still maintained a 4–6% margin over its non-hashed counterpart, indicating that the hashing method continues to provide meaningful structural signals even under extreme obfuscation.
Overall, these results validate the effectiveness of robust hashing in preserving discriminative features and enhancing CNN-based malware classification under diverse obfuscation conditions.
7. Conclusions
This study demonstrates the effectiveness of histogram-based robust hashing applied at the byte level in enhancing CNN-based malware classification under adversarial obfuscation. Through systematic evaluation of MobileNet, ResNet, and DenseNet architectures across five salting conditions (0% to 40%), we show that robust hashing consistently improves classification accuracy, even as dataset complexity increases due to obfuscation. DenseNet, in particular, exhibited superior performance and resilience, maintaining high accuracy across all test cases and demonstrating robustness beyond the 10% salting threshold.
The results confirm that while obfuscation degrades model performance, robust hashing mitigates this effect by preserving discriminative structural features. These findings underscore the value of robust hashing as a preprocessing strategy for malware detection, particularly in adversarial settings where traditional byte-wise representations may fail.
From a deployment perspective, the hashing pipeline introduces minimal computational overhead, making it suitable for integration into real-time or large-scale malware analysis systems. Histogram computation and image construction are linear in file size and can be parallelized efficiently, enabling scalable processing across diverse threat landscapes. Moreover, the use of lightweight CNN architectures such as MobileNet supports inference on resource-constrained environments, including endpoint devices and embedded systems. However, attackers may adapt by crafting obfuscation techniques that specifically target visual hashing artifacts or exploit model blind spots. This raises the need for continuous monitoring and adaptive defenses that evolve alongside adversarial tactics.
Future work can explore adaptive salting thresholds by dynamically adjusting the perturbation intensity based on malware family characteristics or classifier confidence levels, for instance, applying stronger salting to polymorphic malware like Vobfus or Zbot, which exhibit high evasion rates. Researchers can also integrate explainable AI techniques, such as SHAP (SHapley Additive exPlanations) or LIME (Local Interpretable Model-agnostic Explanations), to interpret model decisions under obfuscation and reveal which image features contribute most to classification outcomes, even when adversarial noise is present. Additionally, the evaluation can be extended to real-world malware datasets with dynamic behaviors, such as those captured via sandbox execution or behavioral logging tools like Cuckoo Sandbox, to assess model robustness against evolving threats and time-dependent attack patterns.
Author Contributions
Conceptualization, F.D.T.; Methodology, S.S.K. and F.D.T.; Software, S.S.K.; Validation, S.S.K. and F.D.T.; Investigation, F.D.T.; Data curation, S.S.K.; Writing—original draft, S.S.K.; Writing—review & editing, F.D.T.; Visualization, F.D.T.; Supervision, F.D.T. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The dataset used in this article can be found at https://1drv.ms/u/s!At7JwojdDuh9lZ9hMdz7qXWgqHgONQ?e=296VB5 (accessed on 29 September 2025).
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Kramer, S.; Bradfield, J.C. A general definition of malware. J. Comput. Virol. 2010, 6, 105–114. [Google Scholar] [CrossRef] [Scilit]
- O’Kane, P.; Sezer, S.; McLaughlin, K. Obfuscation: The hidden malware. IEEE Secur. Priv. 2011, 9, 41–47. [Google Scholar] [CrossRef] [Scilit]
- Manikanta Prasad, J.; Abhijna, C.D.; Aishwarya, A.S.; Sai Pranam, B.R.; Raghuramegowda, S.M. Malware Detection using Machine Learning. In Proceedings of the 2024 Second International Conference on Advances in Information Technology (ICAIT), Chikkamagaluru, Karnataka, India, 24–27 July 2024; Volume 1, pp. 1–5. [Google Scholar] [CrossRef] [Scilit]
- Salloum, S.A.; Alshurideh, M.; Elnagar, A.; Shaalan, K. Machine learning and deep learning techniques for cybersecurity: A review. In Proceedings of the International Conference on Artificial Intelligence and Computer Vision, Cairo, Egypt, 8–10 April 2020; Springer: Berlin/Heidelberg, Germany, 2020; pp. 50–57. [Google Scholar]
- Huang, W.C.; Di Troia, F.; Stamp, M. Robust Hashing for Image-based Malware Classification. In Proceedings of the 15th International Joint Conference on e-Business and Telecommunications—BASS, Porto, Portugal, 26–28 July 2018; pp. 451–459. [Google Scholar] [CrossRef] [Scilit]
- Bokolo, B.; Jinad, R.; Liu, Q. A Comparison Study to Detect Malware using Deep Learning and Machine learning Techniques. In Proceedings of the 2023 IEEE 6th International Conference on Big Data and Artificial Intelligence (BDAI), Jiaxing, China, 7–9 July 2023; pp. 1–6. [Google Scholar] [CrossRef] [Scilit]
- Sethi, K.; Kumar, R.; Sethi, L.; Bera, P.; Patra, P.K. A Novel Machine Learning Based Malware Detection and Classification Framework. In Proceedings of the 2019 International Conference on Cyber Security and Protection of Digital Services (Cyber Security), Oxford, UK, 3–4 June 2019; pp. 1–4. [Google Scholar] [CrossRef] [Scilit]
- Abhesa, R.A.; Hendrawan; Ismail, S.J.I. Classification of Malware Using Machine Learning Based on Image Processing. In Proceedings of the 2021 15th International Conference on Telecommunication Systems, Services, and Applications (TSSA), Bali, Indonesia, 18–19 November 2021; pp. 1–4. [Google Scholar] [CrossRef] [Scilit]
- Okubo, S.; Kimura, T.; Cheng, J. Entropy-Based Malware Detection Using One Dimensional CNN. In Proceedings of the 2024 International Conference on Consumer Electronics—Taiwan (ICCE-Taiwan), Taichung, Taiwan, 9–11 July 2024; pp. 763–764. [Google Scholar] [CrossRef] [Scilit]
- Hebish, M.W.; Awni, M. CNN-Based Malware Family Classification and Evaluation. In Proceedings of the 2024 14th International Conference on Electrical Engineering (ICEENG), Cairo, Egypt, 21–23 May 2024; IEEE: New York, NY, USA, 2024; pp. 219–224. [Google Scholar]
- Chang, H.Y.; Huang, Y.C.; Chang, T.S.; Chang, Y.C. A Malware Detection and Classification System Based on Lightweight CNN Model. In Proceedings of the 2025 IEEE International Conference on Consumer Electronics (ICCE), Las Vegas, NV, USA, 11–14 January 2025; pp. 1–4. [Google Scholar] [CrossRef] [Scilit]
- Yajamanam, S.; Selvin, V.R.S.; Di Troia, F.; Stamp, M. Deep Learning versus Gist Descriptors for Image-based Malware Classification. In Proceedings of the 4th International Conference on Information Systems Security and Privacy—Volume 1: ForSE, Funchal, Madeira, Portugal, 22–24 January 2018; pp. 553–561. [Google Scholar] [CrossRef] [Scilit]
- Bhodia, N.; Prajapati, P.; Di Troia, F.; Stamp, M. Transfer learning for image-based malware classification. arXiv 2019, arXiv:1903.11551. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Jiang, J.; Yi, C.; Li, H.; Min, S.; Zuo, R.; An, Z.; Yu, Y. A Robust CNN for Malware Classification against Executable Adversarial Attack. Electronics 2024, 13, 989. [Google Scholar] [CrossRef] [Scilit]
- Thakur, A.; Singh, R.; Kumar, D. Hybrid Deep Learning Approach Based on LSTM and CNN for Malware Detection. Wirel. Pers. Commun. 2024, 138, 123–140. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.J.; Turko, R.; Shaikh, O.; Park, H.; Das, N.; Hohman, F.; Kahng, M.; Chau, D.H.P. CNN explainer: Learning convolutional neural networks with interactive visualization. IEEE Trans. Vis. Comput. Graph. 2020, 27, 1396–1406. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Alzubaidi, L.; Zhang, J.; Humaidi, A.J.; Al-Dujaili, A.; Duan, Y.; Al-Shamma, O.; Santamaría, J.; Fadhel, M.A.; Al-Amidie, M.; Farhan, L. Review of deep learning: Concepts, CNN architectures, challenges, applications, future directions. J. Big Data 2021, 8, 1–74. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Sinha, D.; El-Sharkawy, M. Thin MobileNet: An Enhanced MobileNet Architecture. In Proceedings of the 2019 IEEE 10th Annual Ubiquitous Computing, Electronics & Mobile Communication Conference (UEMCON), New York, NY, USA, 10–12 October 2019; pp. 0280–0285. [Google Scholar] [CrossRef] [Scilit]
- He, F.; Liu, T.; Tao, D. Why resnet works? residuals generalize. IEEE Trans. Neural Netw. Learn. Syst. 2020, 31, 5349–5362. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Abdulazeez, F.A.; Ahmed, I.T.; Hammad, B.T. Examining the performance of various pretrained convolutional neural network models in malware detection. Appl. Sci. 2024, 14, 2614. [Google Scholar] [CrossRef] [Scilit]
- Martínez, S.; Gérard, S.; Cabot, J. Robust hashing for models. In Proceedings of the 21th ACM/IEEE International Conference on Model Driven Engineering Languages and Systems, Fukuoka, Japan, 14–19 October 2018; pp. 312–322. [Google Scholar]
- Ramakrishna, M. Hashing practice: Analysis of hashing and universal hashing. ACM SIGMOD Rec. 1988, 17, 191–199. [Google Scholar] [CrossRef] [Scilit]
- Albeshri, A. An image hashing-based authentication and secure group communication scheme for IoT-enabled MANETs. Future Internet 2021, 13, 166. [Google Scholar] [CrossRef] [Scilit]
- Tran, K.; Di Troia, F.; Stamp, M. Robustness of image-based malware analysis. In Proceedings of the Silicon Valley Cybersecurity Conference, Virtual, 17–19 August 2022; Springer: Berlin/Heidelberg, Germany, 2022; pp. 3–21. [Google Scholar]
- Venkatesan, R.; Koon, S.M.; Jakubowski, M.; Moulin, P. Robust image hashing. In Proceedings of the 2000 International Conference on Image Processing (Cat. No.00CH37101), Vancouver, BC, Canada, 10–13 September 2000; Volume 3, pp. 664–666. [Google Scholar] [CrossRef] [Scilit]
- VirusShare. VirusShare Malware Repository. 2025. Available online: https://virusshare.com/ (accessed on 26 September 2025).
- Zhong, F.; Chen, Z.; Xu, M.; Zhang, G.; Yu, D.; Cheng, X. Malware-on-the-Brain: Illuminating Malware Byte Codes with Images for Malware Classification. IEEE Trans. Comput. 2022, 72, 438–451. [Google Scholar] [CrossRef] [Scilit]
- Noever, D.; Miller Noever, S.E. Virus-MNIST: A Benchmark Malware Dataset. arXiv 2021, arXiv:2103.00602. [Google Scholar] [CrossRef] [Scilit]
- George, D. Static Malware Family Clustering via Structural and Visual Features. Data Sci. Rev. 2023, 7, 4. [Google Scholar]
- Bakken, D.E.; Rarameswaran, R.; Blough, D.M.; Franz, A.A.; Palmer, T.J. Data obfuscation: Anonymity and desensitization of usable data sets. IEEE Secur. Priv. 2004, 2, 34–41. [Google Scholar] [CrossRef] [Scilit]
- Maiorca, D.; Ariu, D.; Corona, I.; Aresu, M.; Giacinto, G. Stealth attacks: An extended insight into the obfuscation effects on android malware. Comput. Secur. 2015, 51, 16–31. [Google Scholar] [CrossRef] [Scilit]
- Jeffrey, A.; Clark and CONTRIBUTORS. Pillow: Python Imaging Library (Fork), Version 11.3.0, Released 1 July 2025; Available online: https://pypi.org/project/pillow/ (accessed on 26 September 2025).

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).