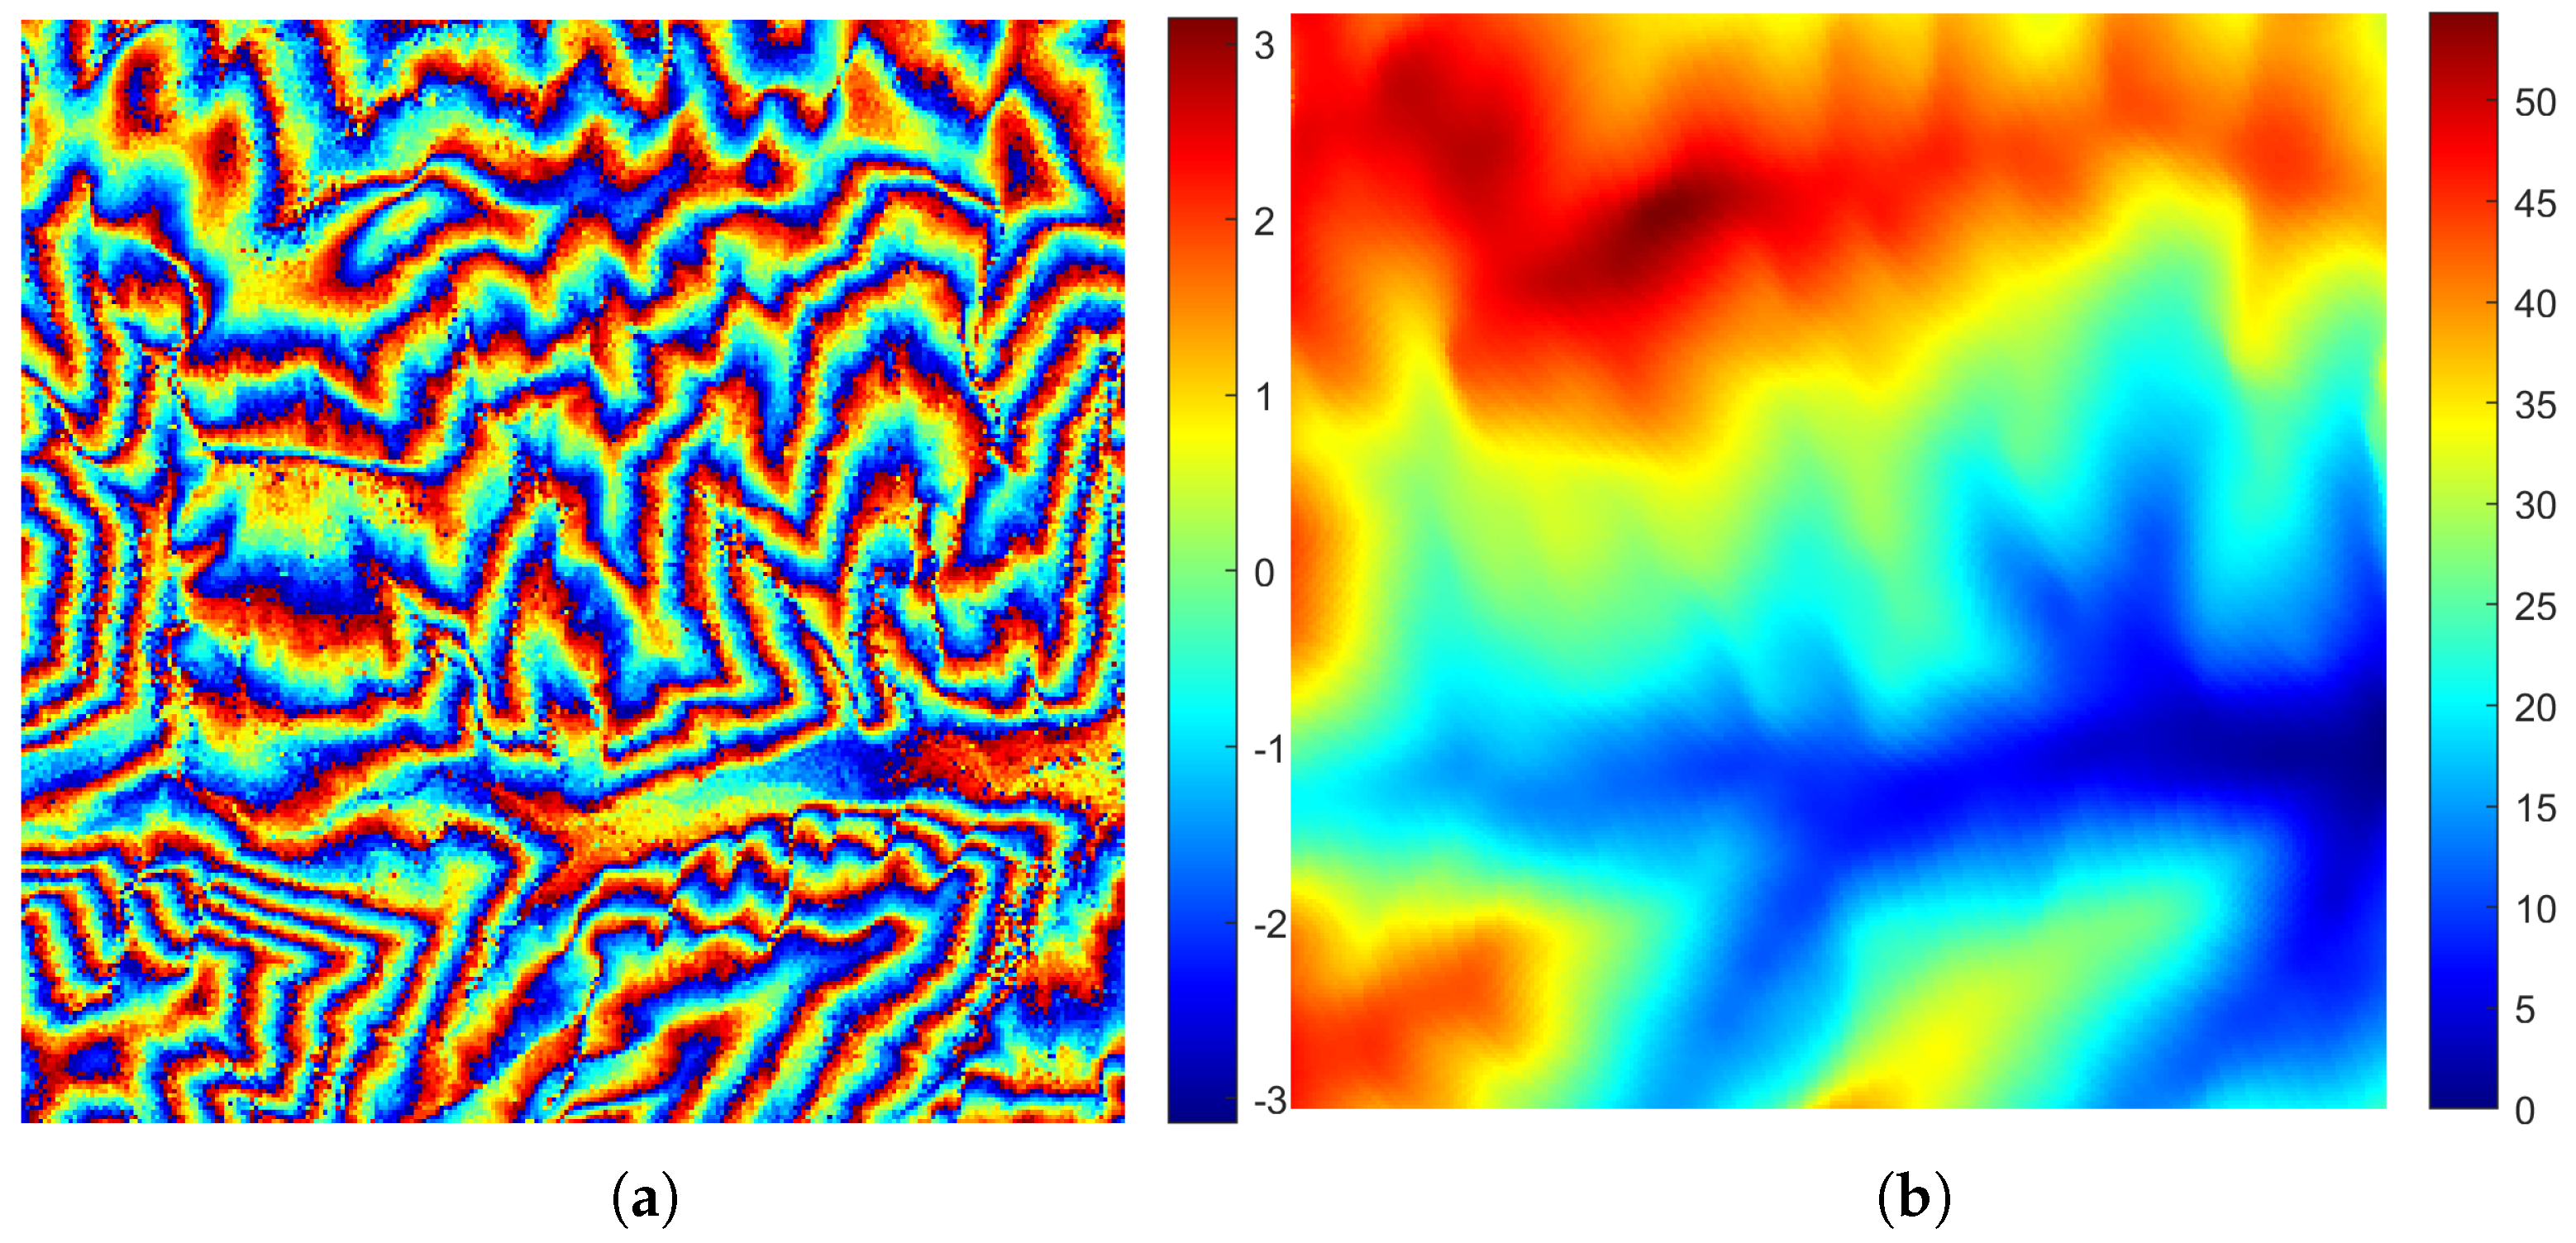
1. Introduction
Interferometric synthetic aperture radar (InSAR) has become an essential remote-sensing technique for deriving high-precision digital elevation models (DEMs) and monitoring subtle surface deformation over large spatial scales. It is particularly valuable for geological hazard assessment, volcanic activity monitoring, and urban infrastructure stability analysis due to its ability to operate independently of weather conditions and illumination variations [
1,
2,
3]. However, the recorded interferometric phase is inherently wrapped into the interval
, where discontinuities occur once the true phase difference exceeds
. Phase unwrapping aims to recover these missing integer multiples of
, converting the wrapped phase into a continuous absolute phase field. By reconstructing the correct 2
jumps, phase unwrapping ensures the accuracy and reliability of subsequent topographic mapping and deformation inversion.
Traditional phase unwrapping methods often rely on Itoh phase continuity condition [
4]. Phase unwrapping algorithms can be broadly grouped into three families, including path-tracking methods, optimal-estimation methods, and minimum-norm methods. Path-tracking approaches, such as the branch-cut method proposed by Goldstein et al. [
5] and various quality-guided techniques developed in subsequent studies [
6,
7], resolve phase discontinuities by constructing unwrapping paths according to pixel reliability. Optimal-estimation methods, represented by Costantini’s minimum-cost flow (MCF) framework [
8], formulate phase unwrapping as a global optimization problem over residue pairs. Minimum-norm approaches, including the minimum-norm optimization method of Ghiglia et al. [
9] and the least-squares formulations systematically summarized by Ghiglia and Pritt [
3]. These methods recover the unwrapped surface by minimizing global phase inconsistencies in the L2 sense. The classical techniques perform well in regions with high coherence and smoothly varying phase. However, they are highly susceptible to noise, dense phase residues, and sharp terrain gradients. Such conditions often lead to error propagation, phase discontinuities, and fringe artifacts, ultimately degrading the accuracy of derived DEMs and surface deformation measurements [
10].
In recent years, the rapid progress of deep learning has led researchers to explore data-driven models to address the phase unwrapping problem [
11]. The existing deep learning-based approaches can be broadly divided into two categories. The end-to-end methods directly estimate the absolute phase from the wrapped input, including regression-based models such as DLPU [
12], PhUN [
13], Unwrap-Net [
14], and Res_UNet [
11], as well as segmentation-based frameworks such as PhaseNet [
15] and BCNet [
16]. The DL-assisted methods predict residue points or discontinuity boundaries instead of output the absolute phase directly. They integrate deep priors into traditional optimization pipelines to enhance robustness, such as DENet [
17], MoDL-PU [
18], PIPNet [
19], and PGENet-LS [
20]. These learning-based approaches have demonstrated strong robustness and generalization in challenging scenarios that involve complex fringes, severe noise, and low coherence.
Although U_Net and its variants have achieved promising performance in phase unwrapping tasks, their skip connections typically fuse encoder and decoder features at the same scale through simple concatenation. In the InSAR context, deep encoder features in U_Net and its variants (Res_UNet [
11]) tend to capture global phase continuity, noise suppression patterns, and long-range gradient correlations. In contrast, shallow decoder features focus more on local fringe details and high-frequency gradient responses. Due to the significant differences in semantic abstraction levels and information emphasis between these two types of features, direct concatenation may lead to semantic mismatch during feature fusion. This issue becomes particularly pronounced in low-coherence or high-noise regions. Simple linear concatenation is insufficient to effectively bridge the semantic gap between global consistency modeling and local detail restoration.
Therefore, when extending the U_Net architecture, two key issues must be addressed: First, how may we select and organize encoder features at different hierarchical levels to achieve effective multi-scale information aggregation and enhance global contextual modeling. Second, how may we mitigate semantic discrepancies between features of different abstraction levels during feature fusion, rather than relying solely on straightforward concatenation. To tackle these challenges, various improvement strategies have been proposed in the field of medical image segmentation. One line of work replaces conventional skip connections with nested dense skip pathways. For example, UNet++ [
21] introduces a series of densely connected convolutional layers to progressively reduce the semantic gap between encoder and decoder subnetworks, thereby improving feature fusion. This design overcomes the restrictive nature of the original U_Net, which only fuses feature maps at the same scale. Another approach enhances skip connections by introducing additional nonlinear transformations or refinement modules along the encoder pathway to strengthen feature representation. This partially alleviates the semantic gap problem [
22]. Although these methods have achieved favorable performance, they still fail to sufficiently exploit information across all scales. Therefore, more effective skip connection mechanisms are required to better bridge the semantic discrepancy between encoder and decoder features [
23,
24].
Recent advances of transformer architectures in computer vision has provided new opportunities for addressing the challenges of InSAR phase unwrapping. The vision transformer (ViT) demonstrated the global modeling capability of self-attention for image classification tasks [
25]. Then, numerous transformer-based medical image segmentation approaches have emerged. TransUNet [
26] represents the first transformer framework for medical segmentation, and Swin-Unet [
27] replaces convolutional blocks with swin transformer modules to construct a fully transformer-based u-shaped architecture. In parallel, the classic U_Net model and its enhanced variants (UNet++ [
21], Attention U_Net [
28], DenseUNet [
29], and MultiResUNet [
22]) have continually improved skip connections and multi-scale feature fusion. These developments provide valuable insights for mitigating the semantic gap between encoder and decoder representations, which is critical for robust and accurate phase unwrapping.
Medical image segmentation and InSAR phase unwrapping exhibit strong similarities in terms of noise interference, multi-scale feature dependency, and edge-detail preservation. This similarity stems from their high consistency at the problem-modeling level. Both tasks require the recovery of sparse, thin, and topologically constrained critical structures from gradient fields under severe noise conditions. Cell membranes or vascular boundaries in medical images share notable similarities with phase discontinuities and residues in interferograms in terms of geometric morphology, statistical distribution, and error propagation mechanisms. Previous studies have explicitly formulated phase residue detection and phase unwrapping as pixel-level classification or segmentation problems (e.g., Res_UNet [
11], DLPU [
12], PhUn [
13], VURNet [
30]). This provides a theoretical foundation for adopting deep learning architectures and attention mechanisms originally developed for medical image segmentation.
Recently, transformer has been introduced into phase unwrapping tasks across a wide range of applications, including fiber-optic sensing, digital holography, fringe projection, and InSAR. For example, Duan et al. proposed the PARFT network [
31], Zhu et al. developed Hformer [
32] for holographic phase recovery. In the context of InSAR, Liu et al. introduced PIPNet [
19]. These studies collectively indicate the strong potential of transformers in phase unwrapping, and they provide the methodological foundation for incorporating a channel transformer (CTrans) in our work.
In the InSAR phase unwrapping task, critical semantic information is more strongly reflected in the phase gradients, noise suppression patterns, and global consistency features encoded across different feature channels, rather than in fixed spatially salient regions. Directly introducing attention mechanisms along the spatial dimension may amplify local noise responses, which is detrimental to modeling global phase consistency. Therefore, it is essential to explore how multi-scale channel-wise information fusion can be leveraged to effectively capture non-local semantic correlations. This approach can fully bridge the semantic gap between the encoder and decoder. To this end, this study proposes ResUCTransNet that integrates residual structures with transformer mechanisms. Built upon a multi-scale residual Res_UNet backbone, the network leverages multi-branch residual modules to extract robust deep features. More importantly, a CTrans module is introduced to replace traditional skip connections. Channel-wise cross fusion transformer (CCT) and channel-wise cross attention (CCA) enable effective multi-scale feature fusion and semantic alignment between encoder–decoder pathways. Through this design, ResUCTransNet combines the strong local representation capability of CNNs with the global contextual modeling strength of transformers. Therefore, it achieves enhanced robustness and generalization in challenging interferograms characterized by dense fringes, noise contamination, and low-coherence regions.
Zhou and Yu et al. [
33]. introduced the InSAR-DLPU dataset, which provides the first large-scale public benchmark specifically designed for deep-learning-based phase unwrapping. Accordingly, this work conducts a comparison in the proposed method, multiple state-of-the-art deep learning approaches and representative classical algorithms on the publicly available InSAR-DLPU dataset. The experimental results demonstrate that ResUCTransNet effectively reduces model complexity. At the same time, it achieves significantly better performance than existing methods in terms of root mean square error (RMSE) and structural similarity index (SSIM). This confirms its superiority in both phase reconstruction accuracy and structural fidelity. The proposed model benefits from the joint design of residual learning, multi-branch feature extraction, and the CTrans module to exhibit notably enhanced robustness under complex terrain conditions and high-noise scenarios.
The remainder of this paper is organized as follows.
Section 2 describes the principles and methodology, including the theoretical background, the overall architecture of ResUCTransNet, and its key modules.
Section 3 presents experimental results based on simulated and real-world data, provides quantitative comparisons with mainstream methods, and reports ablation studies. Finally,
Section 5 concludes the paper and discusses potential directions for future research.
2. Principles and Methods
In this section, we first introduce the principle of phase unwrapping. The structure of the ResUCTransNet is then described in detail.
2.1. The Principle of Phase Unwrapping
In InSAR interferometry, the corresponding pixels of the master and slave images can be expressed as
, where
and
are the echo phases acquired by the radar during the two observations. By performing pixel-wise multiplication of the two images and taking the complex conjugate, the interferometric complex signal
is obtained. The interferometric phase is then computed from the trigonometric form
of the complex quantity. The phase is constrained to a wrapped form due to the principal value range of arctan satisfies
.
If the true phase difference exceeds
, the measured value will exhibit a discontinuity, which causes the phase field to become noncontinuous and unusable for terrain inversion or deformation analysis. Therefore, the main task of phase unwrapping is to recover the missing information and convert the wrapped phase into a continuous absolute phase [
3]:
In this expression, k is an unknown integer. DL–based phase-unwrapping methods take a data-driven perspective and directly learn the nonlinear mapping between the wrapped phase and the absolute phase [
12]. They no longer explicitly rely on traditional theories such as Itoh continuity or minimum-cost flow. The core idea can be summarized as follows: under a supervised learning framework, the deep learning model takes the wrapped phase
as input and the unwrapped absolute phase
as the supervisory label and learning the mapping relationship from a large number of paired samples. That is
where
denotes the trainable parameters of the network. The training objective can be written as:
where
is the loss function. The DL-based PU methods usually use L2-norm (also known as mean squared error) [
34] or L1-norm (also known as mean absolute error) [
35] as whole or main components of the loss function.
2.2. ResUCTransNet
In this study, we propose ResUCTransNet, a deep learning framework designed for phase unwrapping in InSAR. By integrating residual learning with attention mechanisms, the network effectively addresses key challenges in complex interferograms, including dense phase fringes, noise interference, and spatial discontinuities.
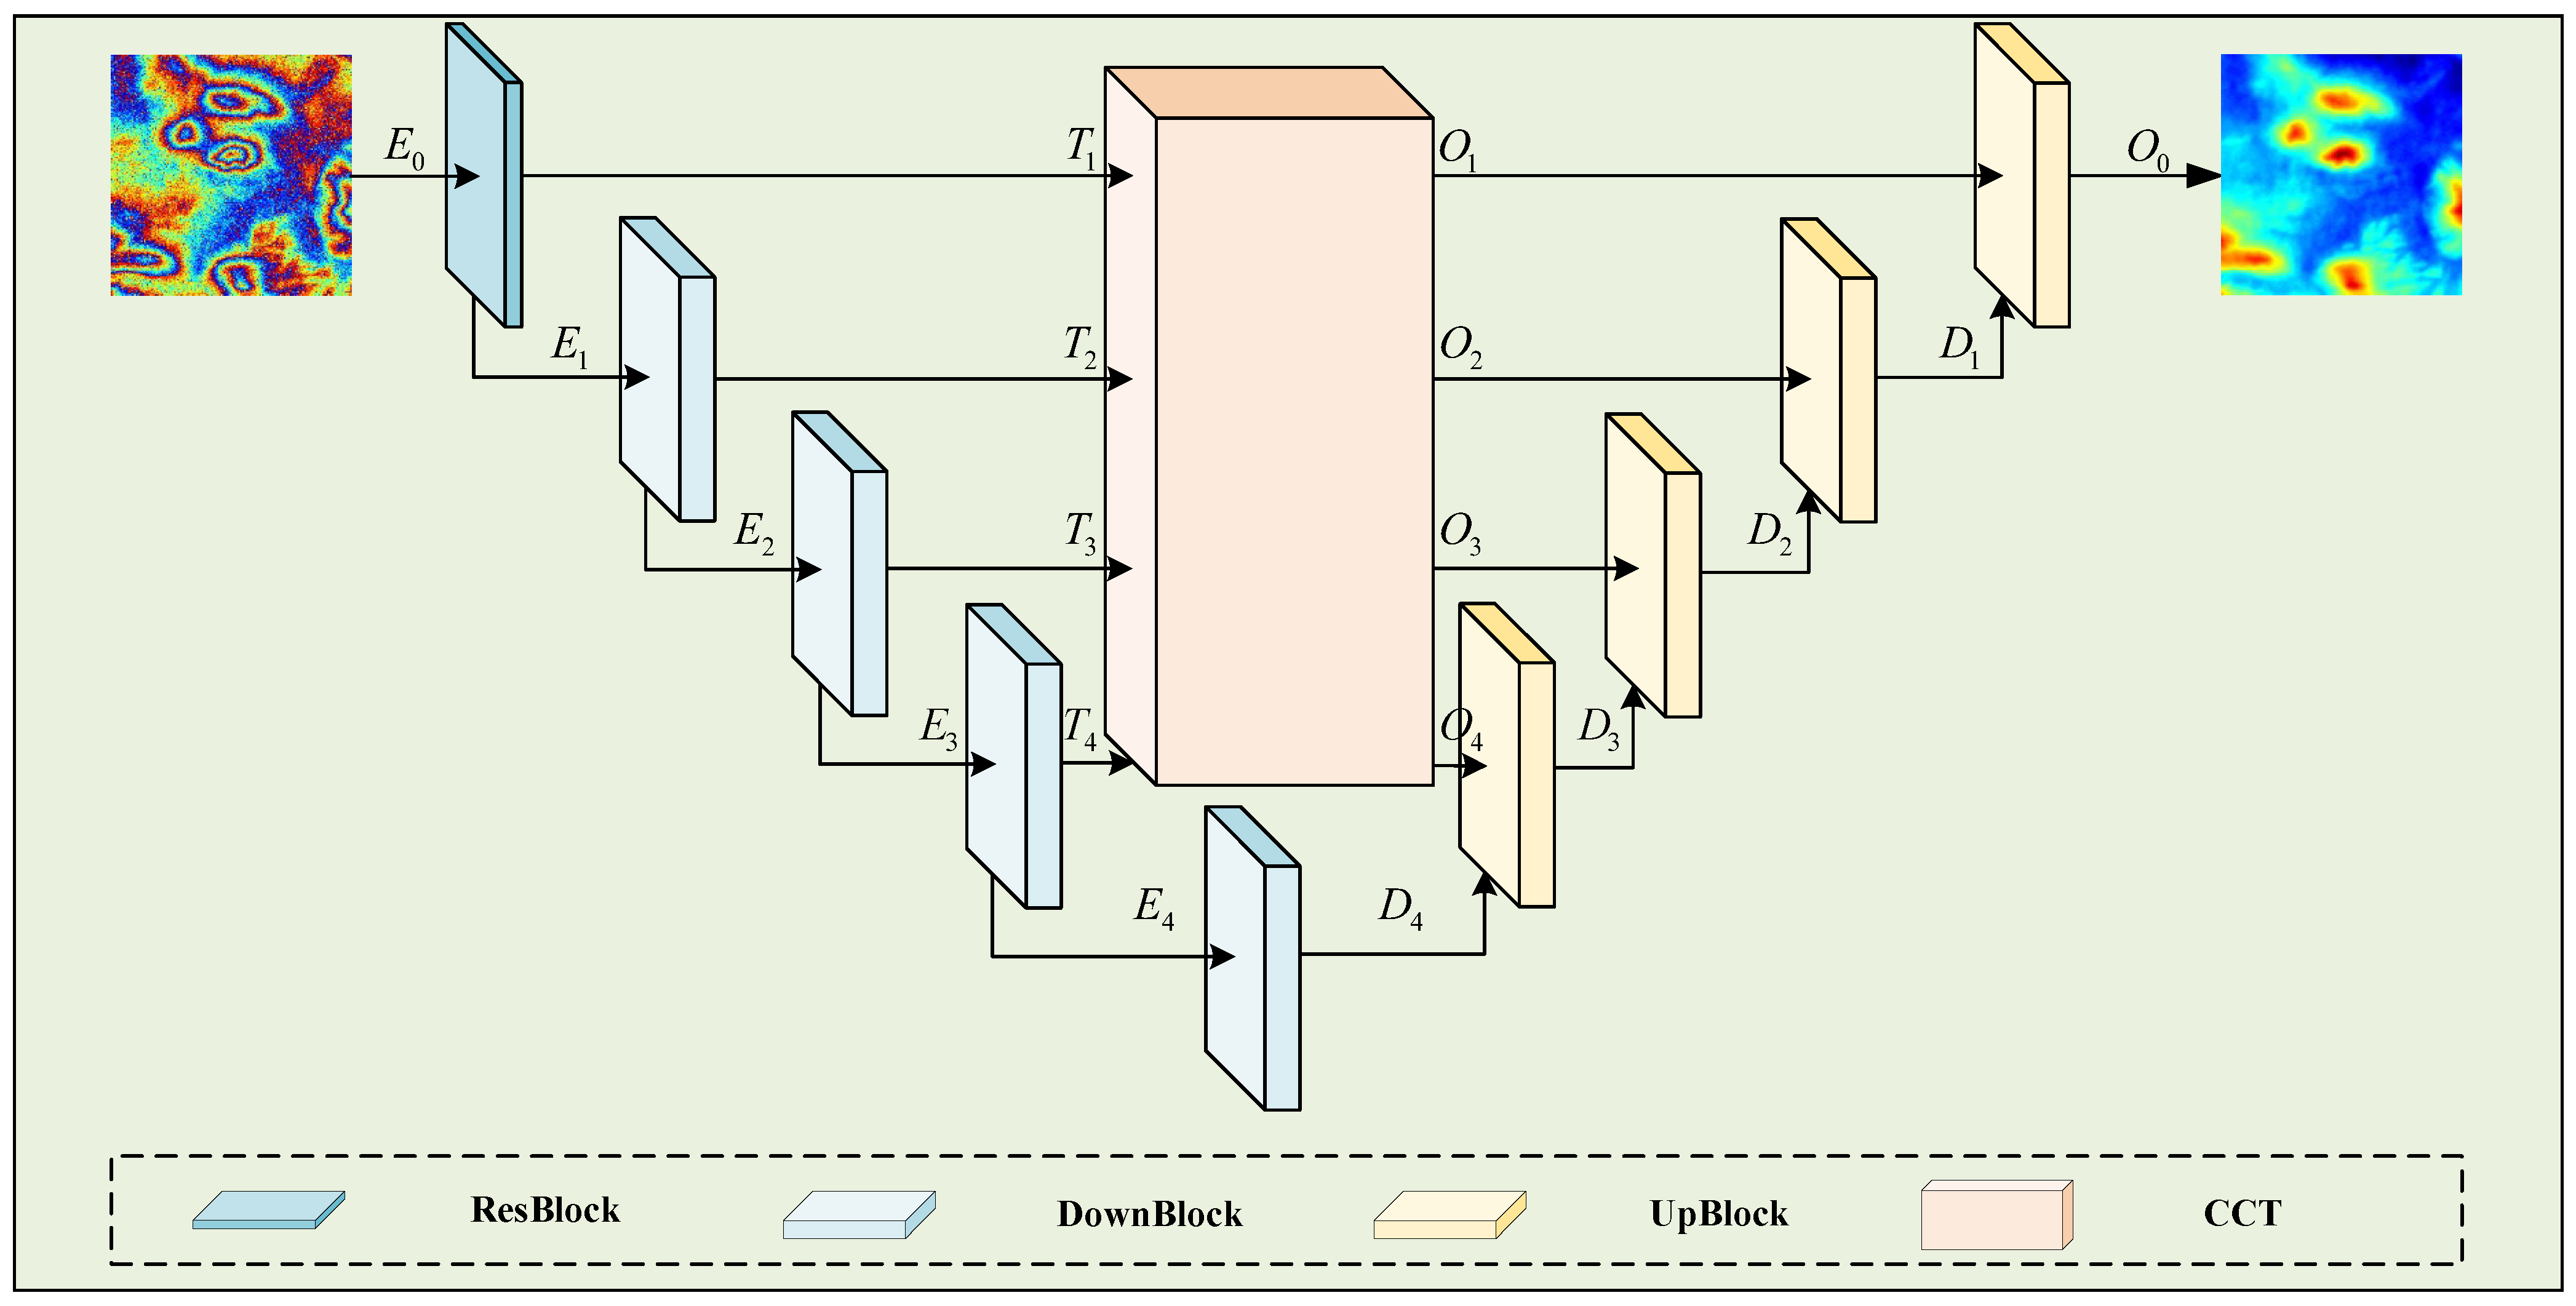
The overall network architecture consists of an encoder (for feature extraction and downsampling), a CTrans module (for enhanced skip connections), and a decoder (for feature restoration and upsampling), as illustrated in
Figure 1. The main parameters of ResUCTransNet are shown in
Table 1.
Assuming the size of each interferogram in the dataset is 256 × 256, the input first passes through an initial residual Inception block (ResBlock) in the encoder, where the multi-branch convolutional structure extracts rich local features. Subsequently, four consecutive downsampling blocks (DownBlock) progressively reduce the spatial resolution via MaxPooling (128 × 128, 64 × 64, 32 × 32, and 16 × 16), simultaneously strengthening the abstraction level and high-level semantic representation of the encoded features.
The multi-scale feature maps produced by the encoder are first processed through the CCT-based skip connections. The CCT module leverages a transformer-based architecture to perform channel-wise self-attention, which enables the model to capture global dependencies in different scales and channels. In addition, its skip-connection design further strengthens multi-level feature aggregation, which allows the decoder to more effectively exploit both deep semantic features and shallow spatial details. CCT facilitates collaborative learning of cross-scale channel interactions instead of relying on independent concatenation that offer an adaptive solution to bridge the potential semantic gaps between feature scales. Moreover, a CCA module is introduced to fuse the multi-scale encoder features with the decoder-stage features, aiming to alleviate the semantic inconsistency caused by differences in representation levels. These two cross-attention mechanisms are jointly referred to as CTrans, which establishes effective associations between the encoder and decoder by exploring multi-scale global contextual information. By replacing the conventional skip connections, CTrans mitigates the semantic gap between deep and shallow features and, consequently, enhances the overall performance of the network.
In the decoder, four attention-guided upsampling modules (UpBlock-attention) progressively recover the feature-map resolution (16 × 16 → 32 × 32 → 64 × 64 → 128 × 128 → 256 × 256). Each module combines an upsampling operation with a CCA mechanism. The enhanced skip-connection features from the CCT module are fused in each stage. This design improves spatial localization and strengthens attention to important regions.
Finally, a 1 × 1 convolution maps the decoder output to a single-channel 256 × 256 continuous absolute phase map, completing the phase-unwrapping prediction. In summary, ResUCTransNet integrates CNN-based local perception, the global channel-level attention of CCT, and skip-connection structures. This combination significantly enhances phase unwrapping performance for complex interferograms and provides strong applicability in real scenarios with rugged terrain and heavy noise interference.
2.2.1. DownBlock
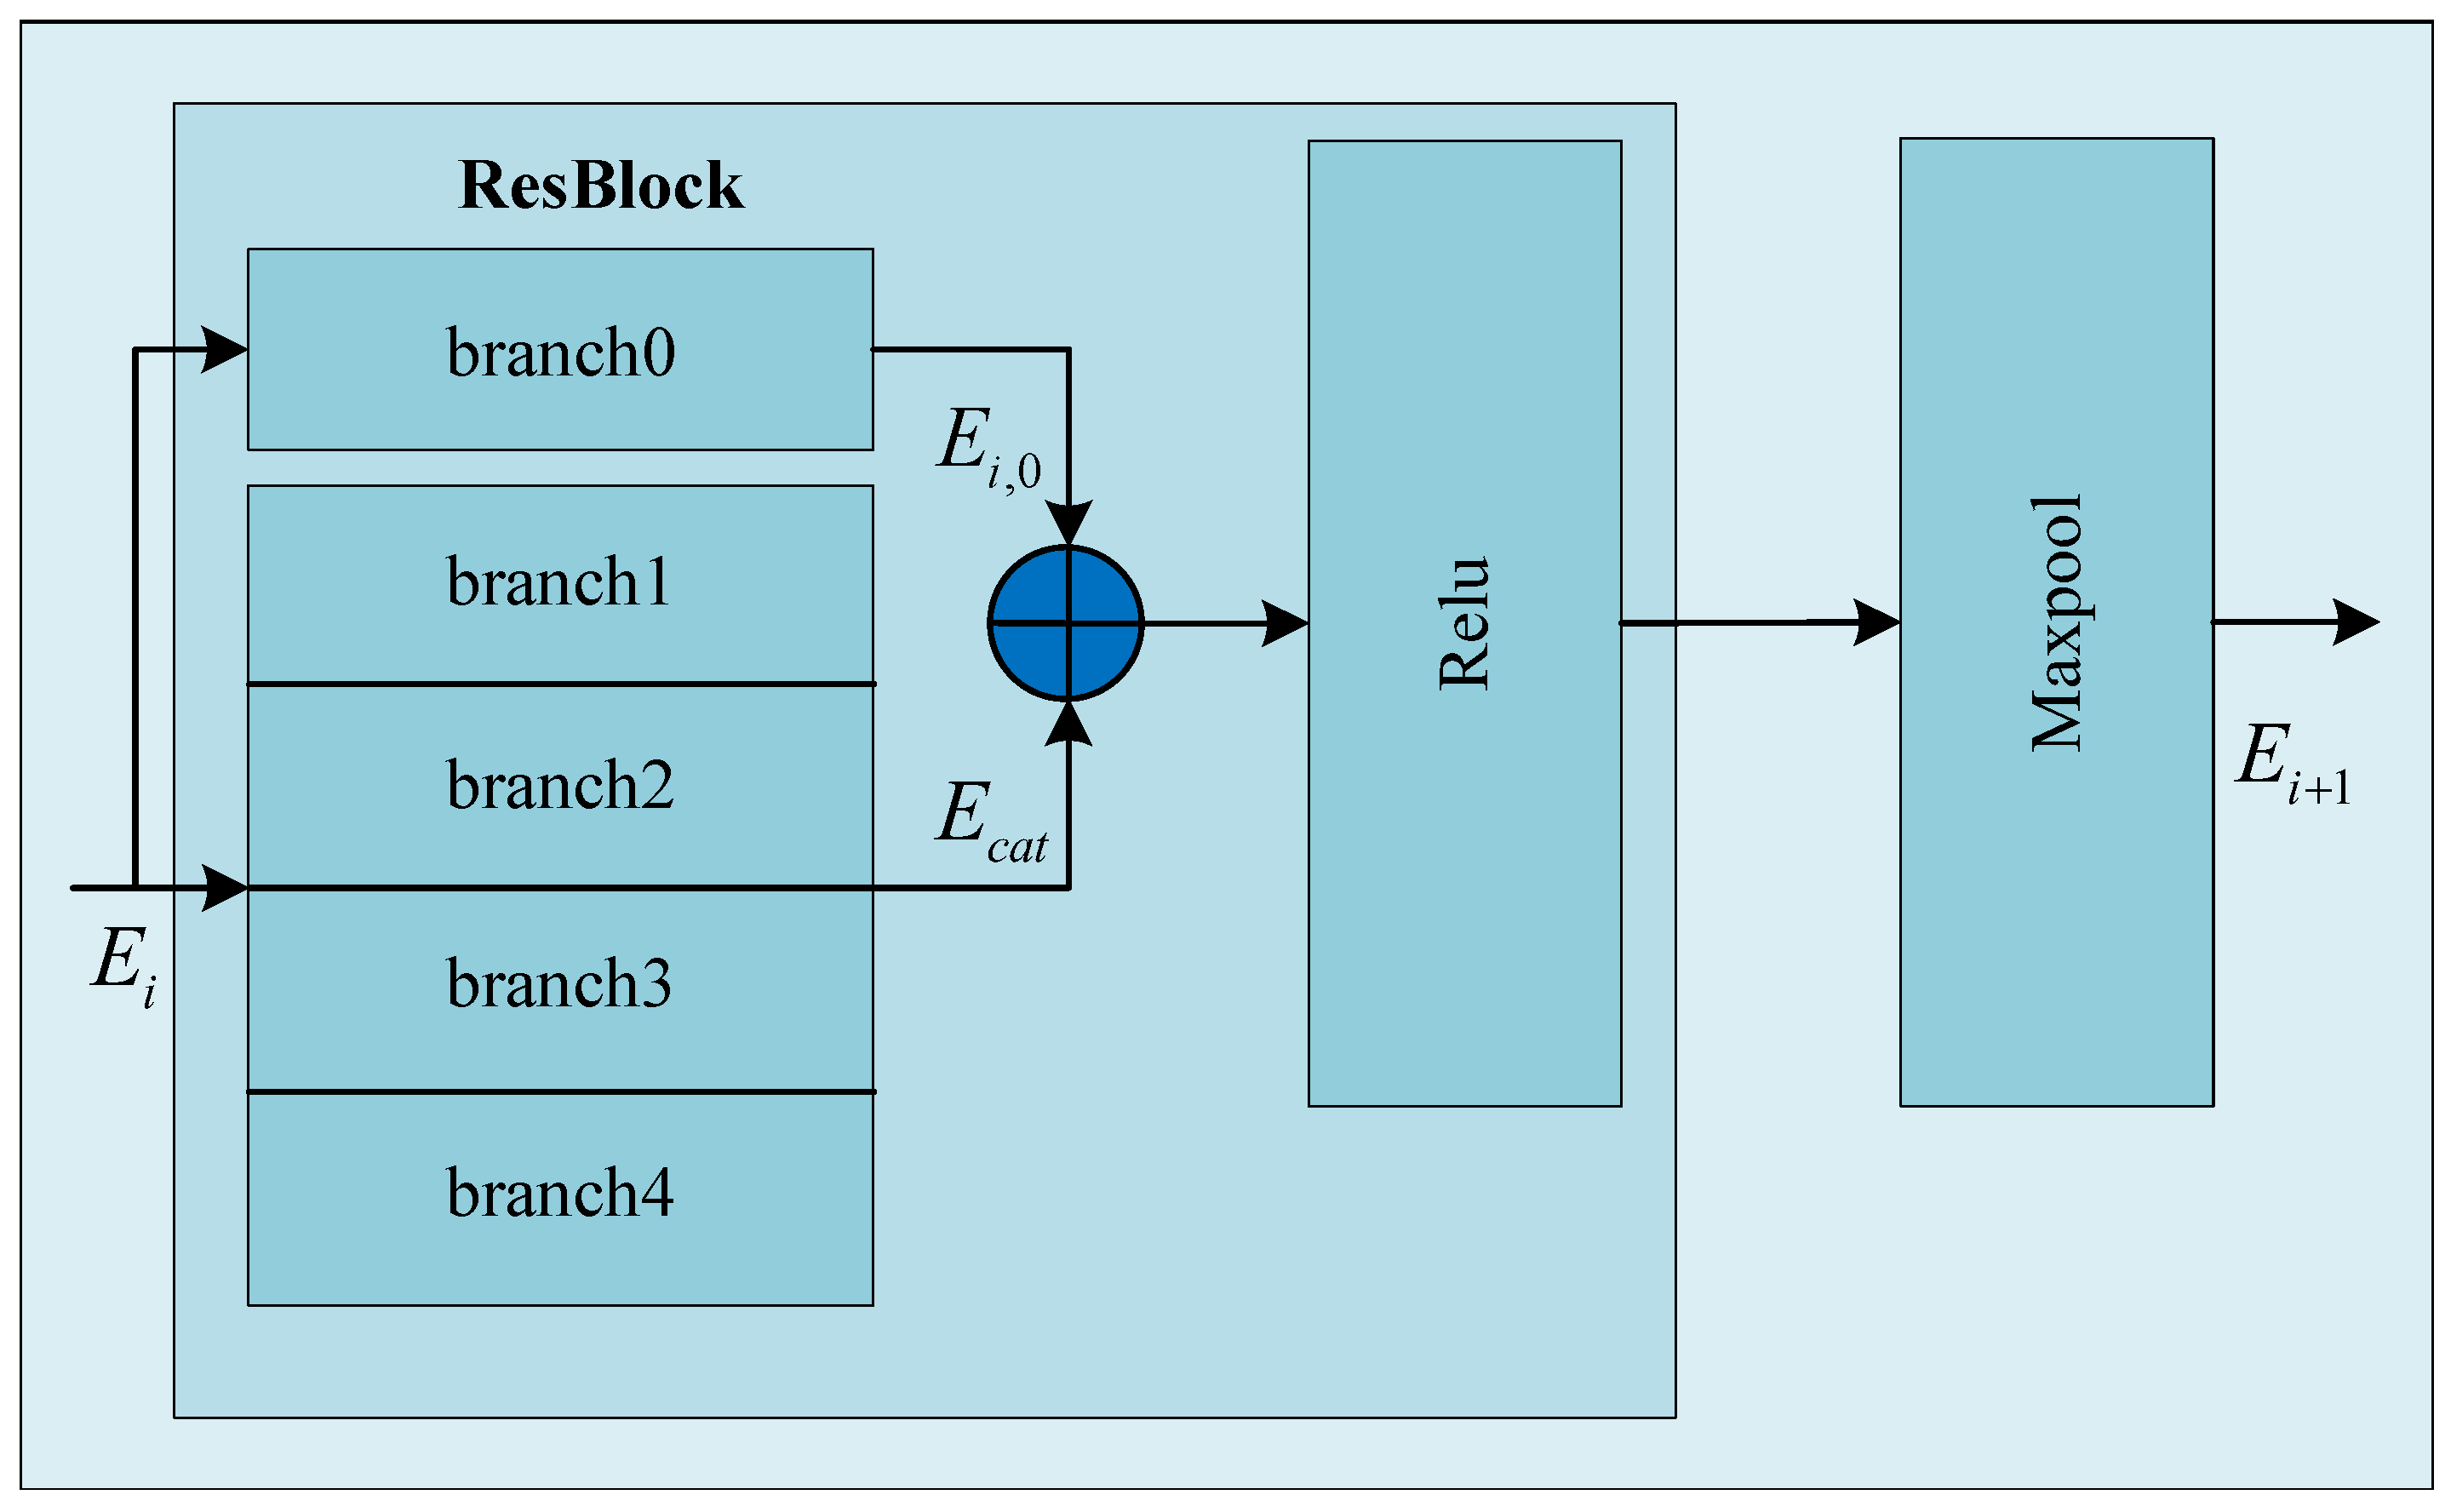
To better accommodate the pronounced local discontinuities, high-frequency disturbances, and multi-scale structural variations inherent in InSAR interferograms, the DownBlock is built upon a multi-scale residual backbone (Res_UNet), which enables the extraction of stable and high-quality deep feature representations. Res_UNet extends the standard U_Net by integrating a ResBlock that contains five parallel convolutional paths with different depths, as illustrated in
Figure 2. Branch0: A 1 × 1 convolution that rapidly adjusts channel dimensionality and preserves global information flow. Branch1: A single 3 × 3 convolution for capturing fundamental texture features. Branch2: A two-layer cascade of 3 × 3 convolutions for modeling mid-scale structural cues. Branch3: A three-layer cascade of 3 × 3 convolutions to strengthen local semantic representation. Branch4: A four-layer deep convolutional pathway designed to construct features with a large receptive field. The outputs of 1–4 branches are concatenated along the channel dimension and fused with the residual projection from the Branch0 path to form the final multi-scale feature representation. Given an input feature map
and output
, the operation can be formulated as:
where
denotes the leakyrelu activation function, and BN represents the batch normalization. The output is followed by a MaxPooling layer.
Through this operation, global contextual information and local structural details are effectively fused, thereby significantly enhancing the network’s ability to perceive and represent wrapped-phase discontinuities and boundary details.
2.2.2. CTrans Module
To address the semantic inconsistency between the encoder and decoder and to enhance cross-scale feature fusion, this study replaces the skip connections in Res_UNet with a CTrans module. CTrans consists of two key components, CCT for fusing multi-scale encoder features, and CCA for integrating decoder features with the enhanced CCT representation [
36].
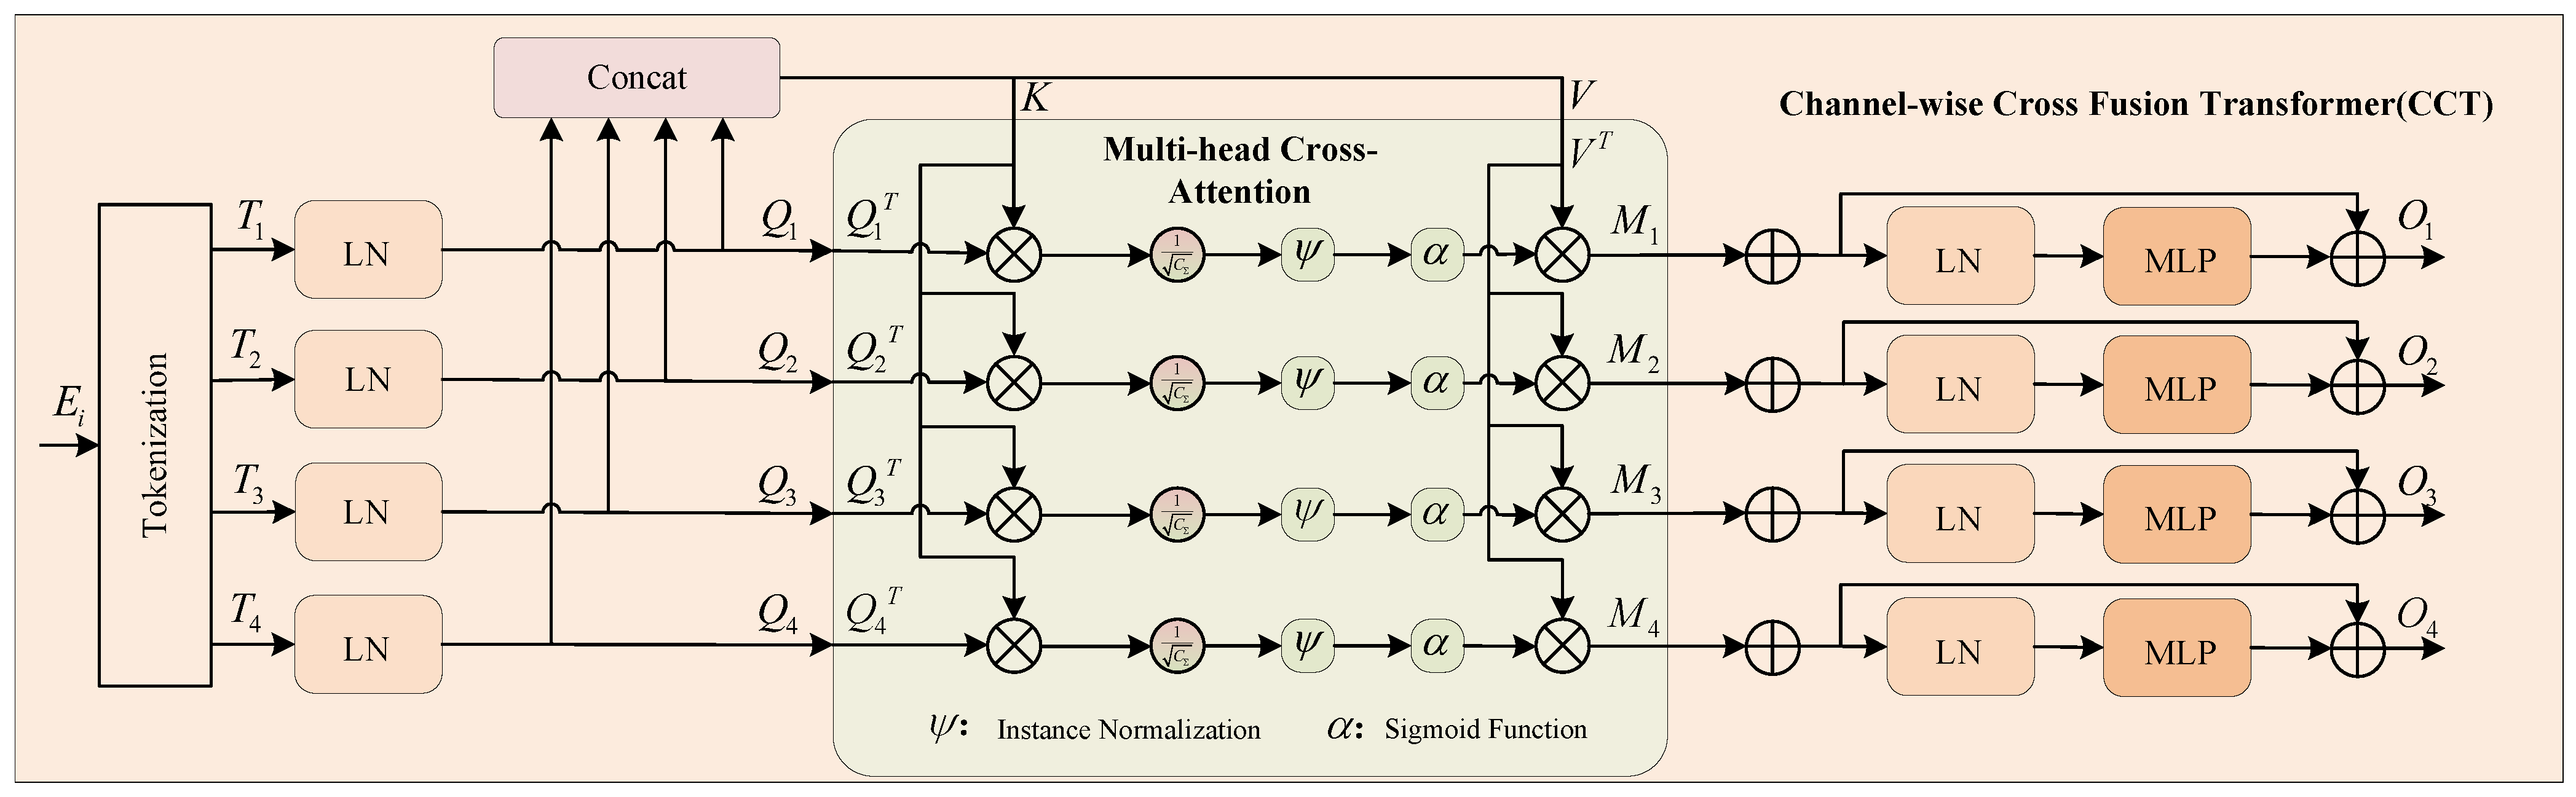
The CCT applies a cross-scale attention mechanism along the channel dimension to fuse multi-resolution features from different depths of the Res_UNet encoder. This extracts globally informative representations that are beneficial for phase unwrapping. The CCT structure includes three stages, multi-scale feature embedding, multi-head channel-wise cross-attention, and multi-layer perceptron (MLP), as illustrated in
Figure 3.
Multi-scale feature embedding: Given the outputs of four skip-connection layers
. The features are converted into sequences of flattened 2D patches with predefined patch sizes
, respectively, to perform tokenization so that the patches correspond to the same spatial regions across all scales. Each channel is treated as an individual token, while the original channel dimensions are preserved. The tokens from the four layers,
, are then concatenated to form the Key and Value:
which are subsequently used as inputs to the channel-wise cross-attention module.
Multi-head channel-wise cross-attention: Features at different scales
are first processed by layer normalization (LN) and, subsequently, used as query vectors, whereas the concatenated features of all scales
are used as the keys and values, expressed as follows:
Among them, the weight matrix has the dimension
, where d denotes the size of the attention dimension.
represents the sum of the channel sizes of the four skip-connection layers. The attention weights are normalized along the channel dimension using instance normalization [
37]
, followed by a softmax to yield the similarity matrix
:
Based on this weight, the fused feature representation is:
. Under the multi-head mechanism, the results of all attention heads are averaged:
where N is the number of heads.
MLP: The fused features are first normalized by LN, followed by further processing through a multi-layer perceptron (MLP) and a residual operator. The output is obtained as follows:
Among them, the output
represents the fused features of the i-th layer.
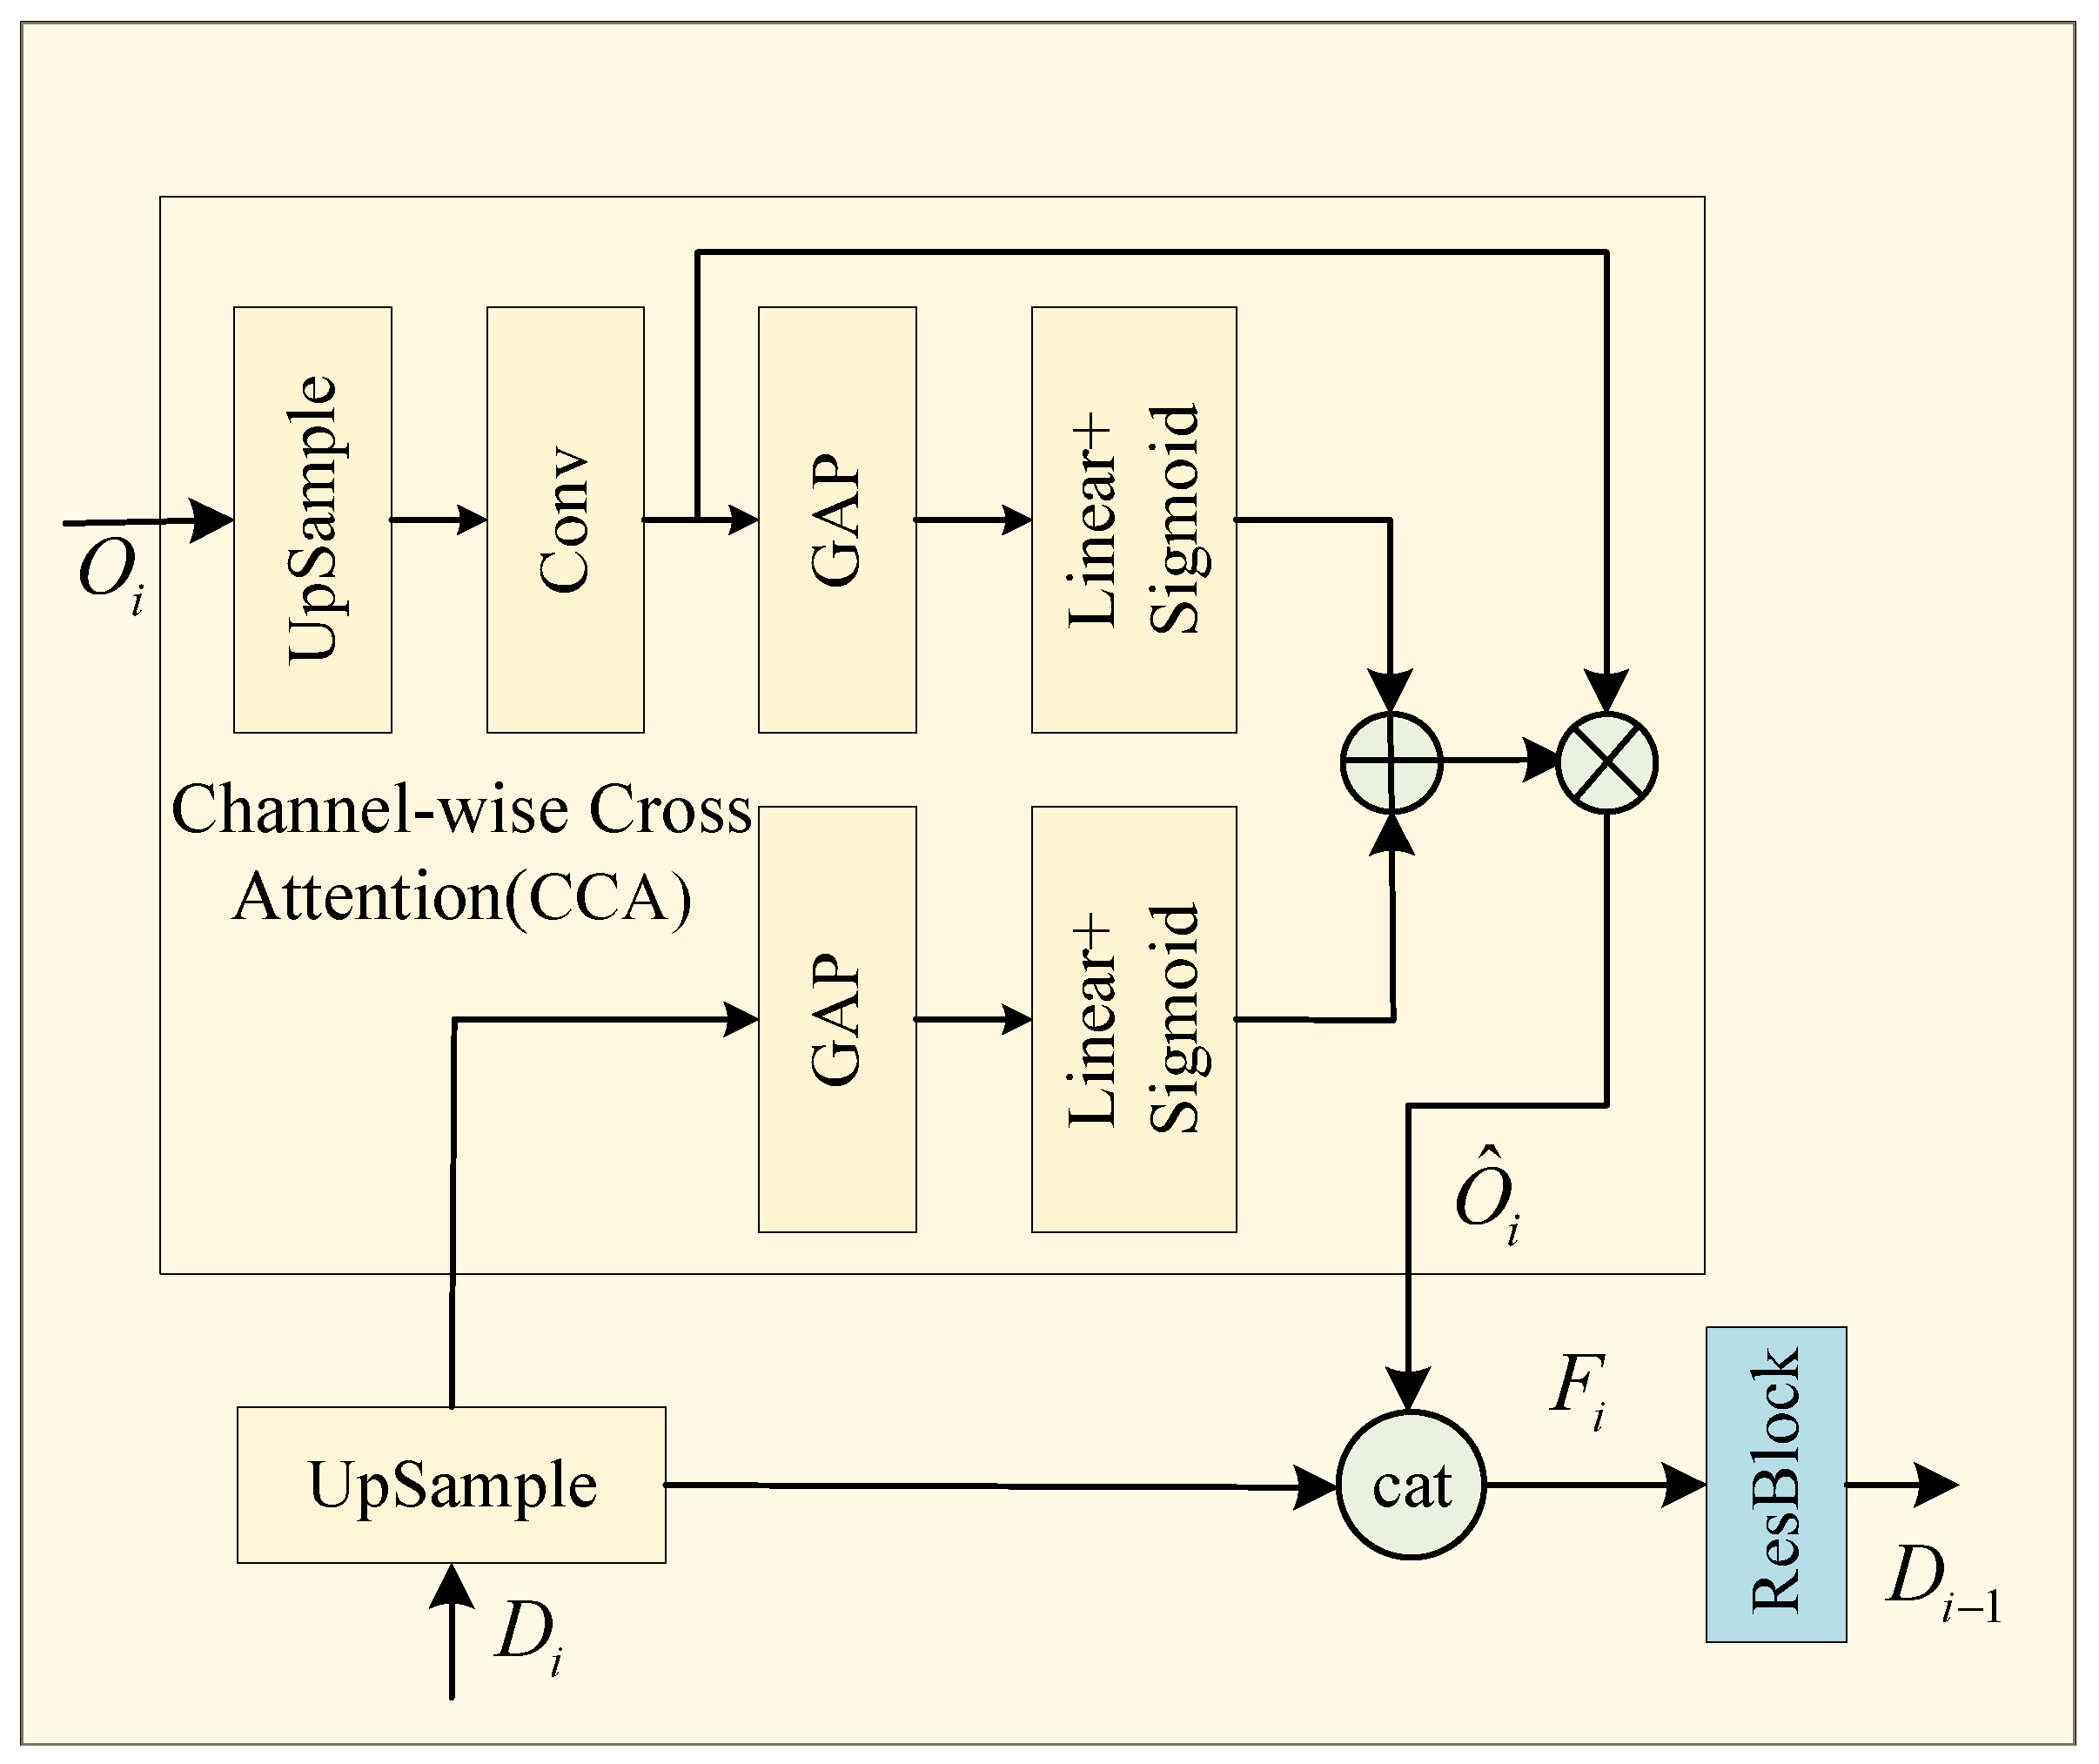
To further align the CCT outputs with the decoder unwrapped features Di, the CCA is introduced. The CCA module performs semantic mapping through a channel-selective mechanism and is used to fuse multi-scale features with the features in the decoder stage to address the issue of semantic-level inconsistency. As shown in
Figure 4, for each group of feature maps
, the feature maps are upsampled to double their height and width with unchanged channel dimensions via the upsample layer in PyTorch (Version: 1.8.1+cu111). A channel descriptor vector is extracted through global average pooling (GAP)
. The pooled results are then fed into linear layers and fused with learned weights to generate the channel attention mask.
where
denotes the linear transformation matrix, and
represents the ReLU activation function. The attention mask is processed by a linear layer, activated via a sigmoid function, and then applied to
, yielding the weighted features
. These are then concatenated with the decoder features to form the final fused features.
where
denotes the sigmoid function, and
is the fused features are fed into the output head.
2.3. LOSS Function
The training samples is assumed that consist of wrapped absolute phase pairs, where is the input wrapped phase and is the corresponding absolute phase ground truth. The backbone network outputs , and each layer of the decoder produces K multiscale auxiliary predictions . Let denote the bilinear upsampling operator that resizes to the same spatial resolution as , . Let be the set of pixels, and be the total number of pixels.
To measure the discrepancy between the absolute phase map predicted by the neural network and the ground-truth phase map, the proposed method adopts the L1 loss function (Mean Absolute Error, MAE) as the primary supervised training loss. The L1 loss is robust and insensitive to outliers, which helps mitigate the adverse effects of local phase anomalies (such as residue points or local fringe breakages) on backpropagation. Meanwhile, MAE provides more stable gradients, which promotes the overall convergence of the unwrapping network. The mathematical formulation is as follows:
To enhance the “top-down” supervision of deep features for phase unwrapping, the proposed method applies smooth-L1 (also known as the Huber loss) to the auxiliary predictions
at all scales and computes their weighted sum. For small residuals, the loss adopts quadratic penalization to encourage fine refinement. For large residuals, it degenerates into L1 to improve robustness against outliers. The pixel-wise Huber loss for a single scale is defined as:
where
denotes the residues and
denotes the branch points.
is upsampled to full resolution and denote it as
. Then, the average Smooth-L1 of the
K-th auxiliary branch is:
Considering that the low-resolution branches contribute little to the final fine details and the necessity of stable gradients, a coarse-to-fine decreasing weight
is adopted. The multi-scale auxiliary loss is written as:
The total objective function is combines the above main loss and auxiliary losses:
4. Discussion
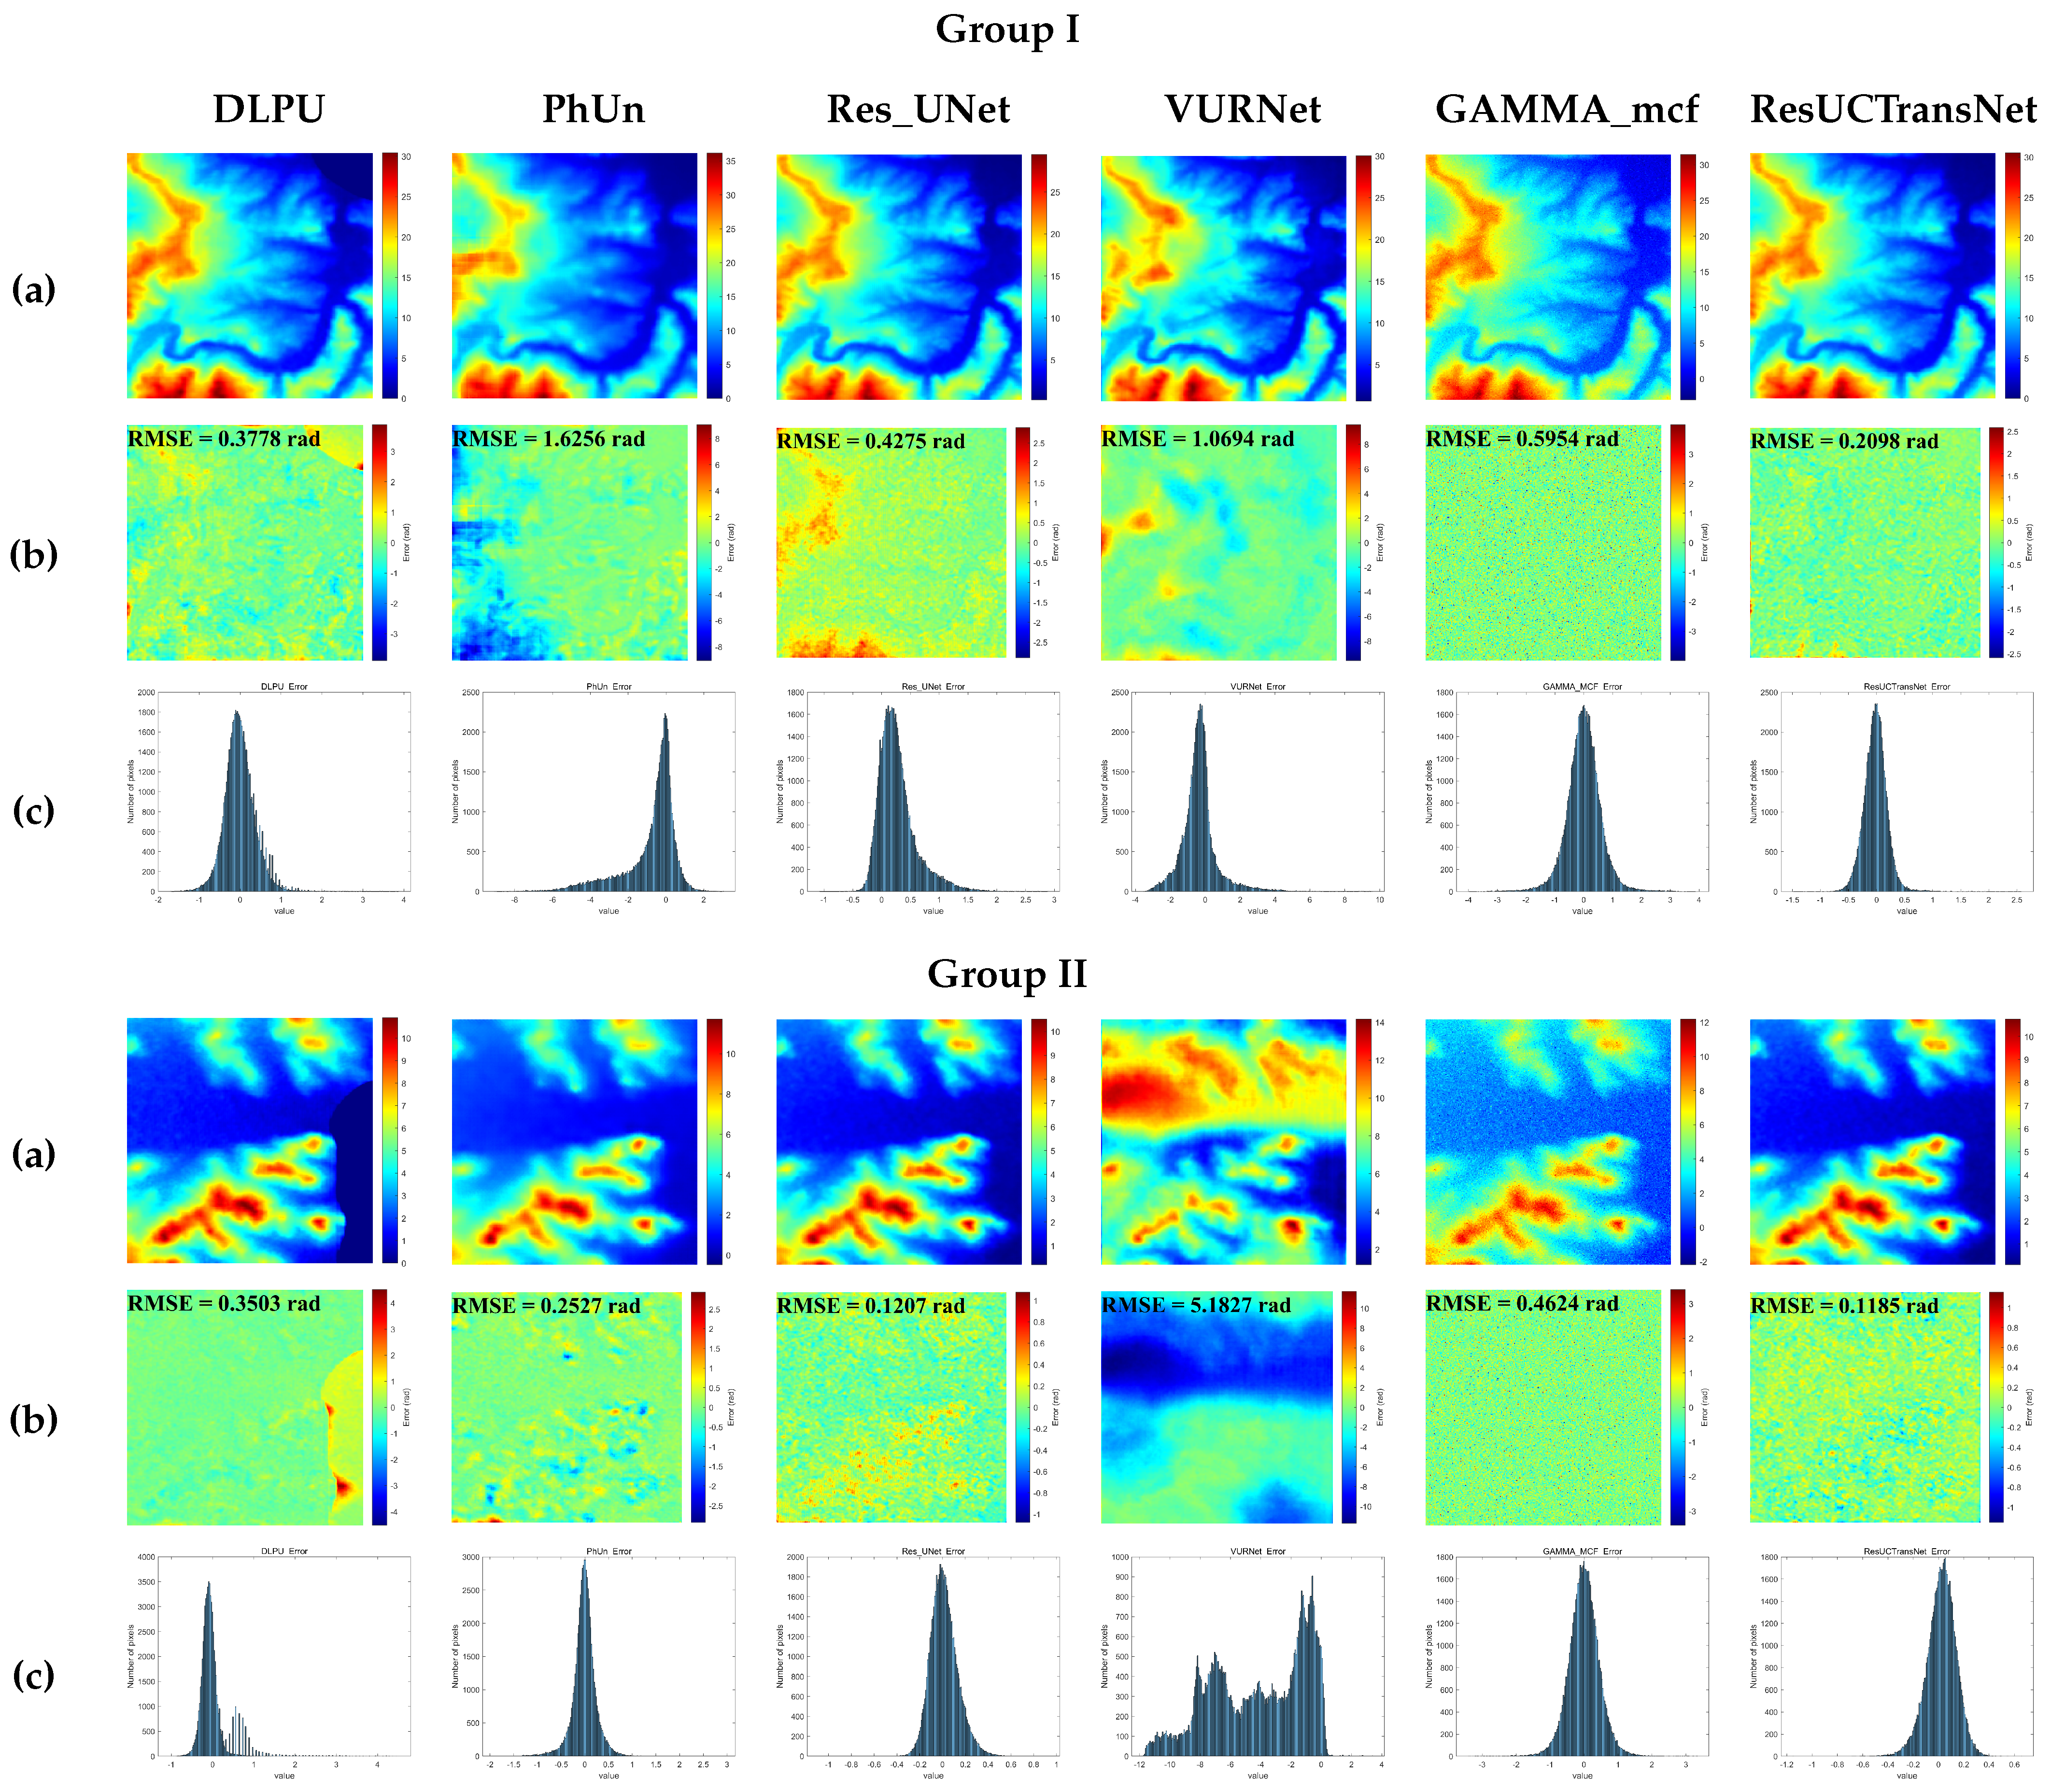
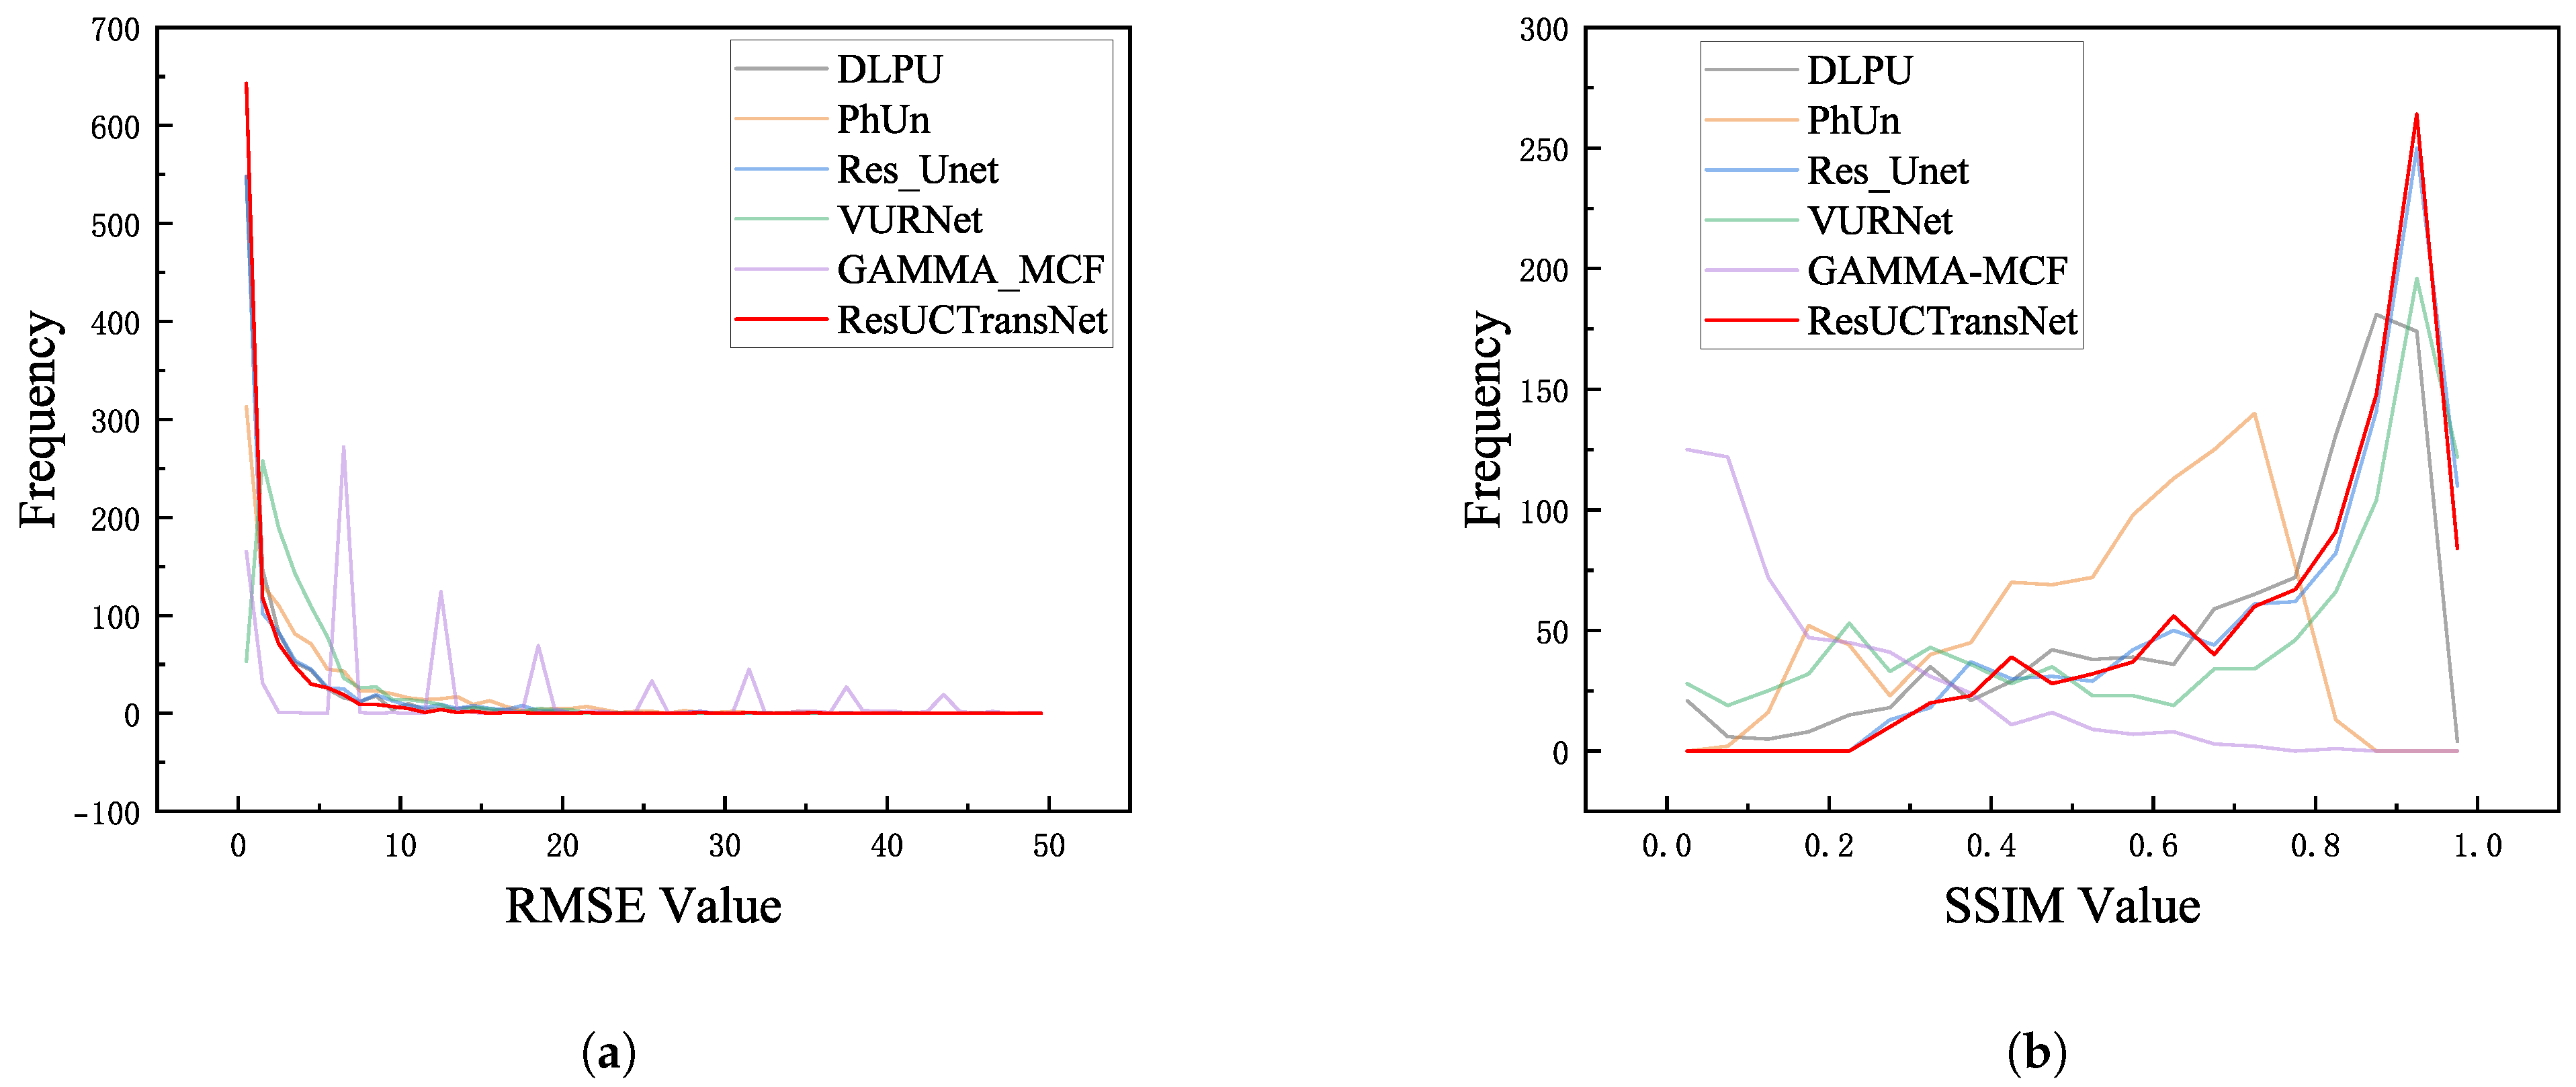
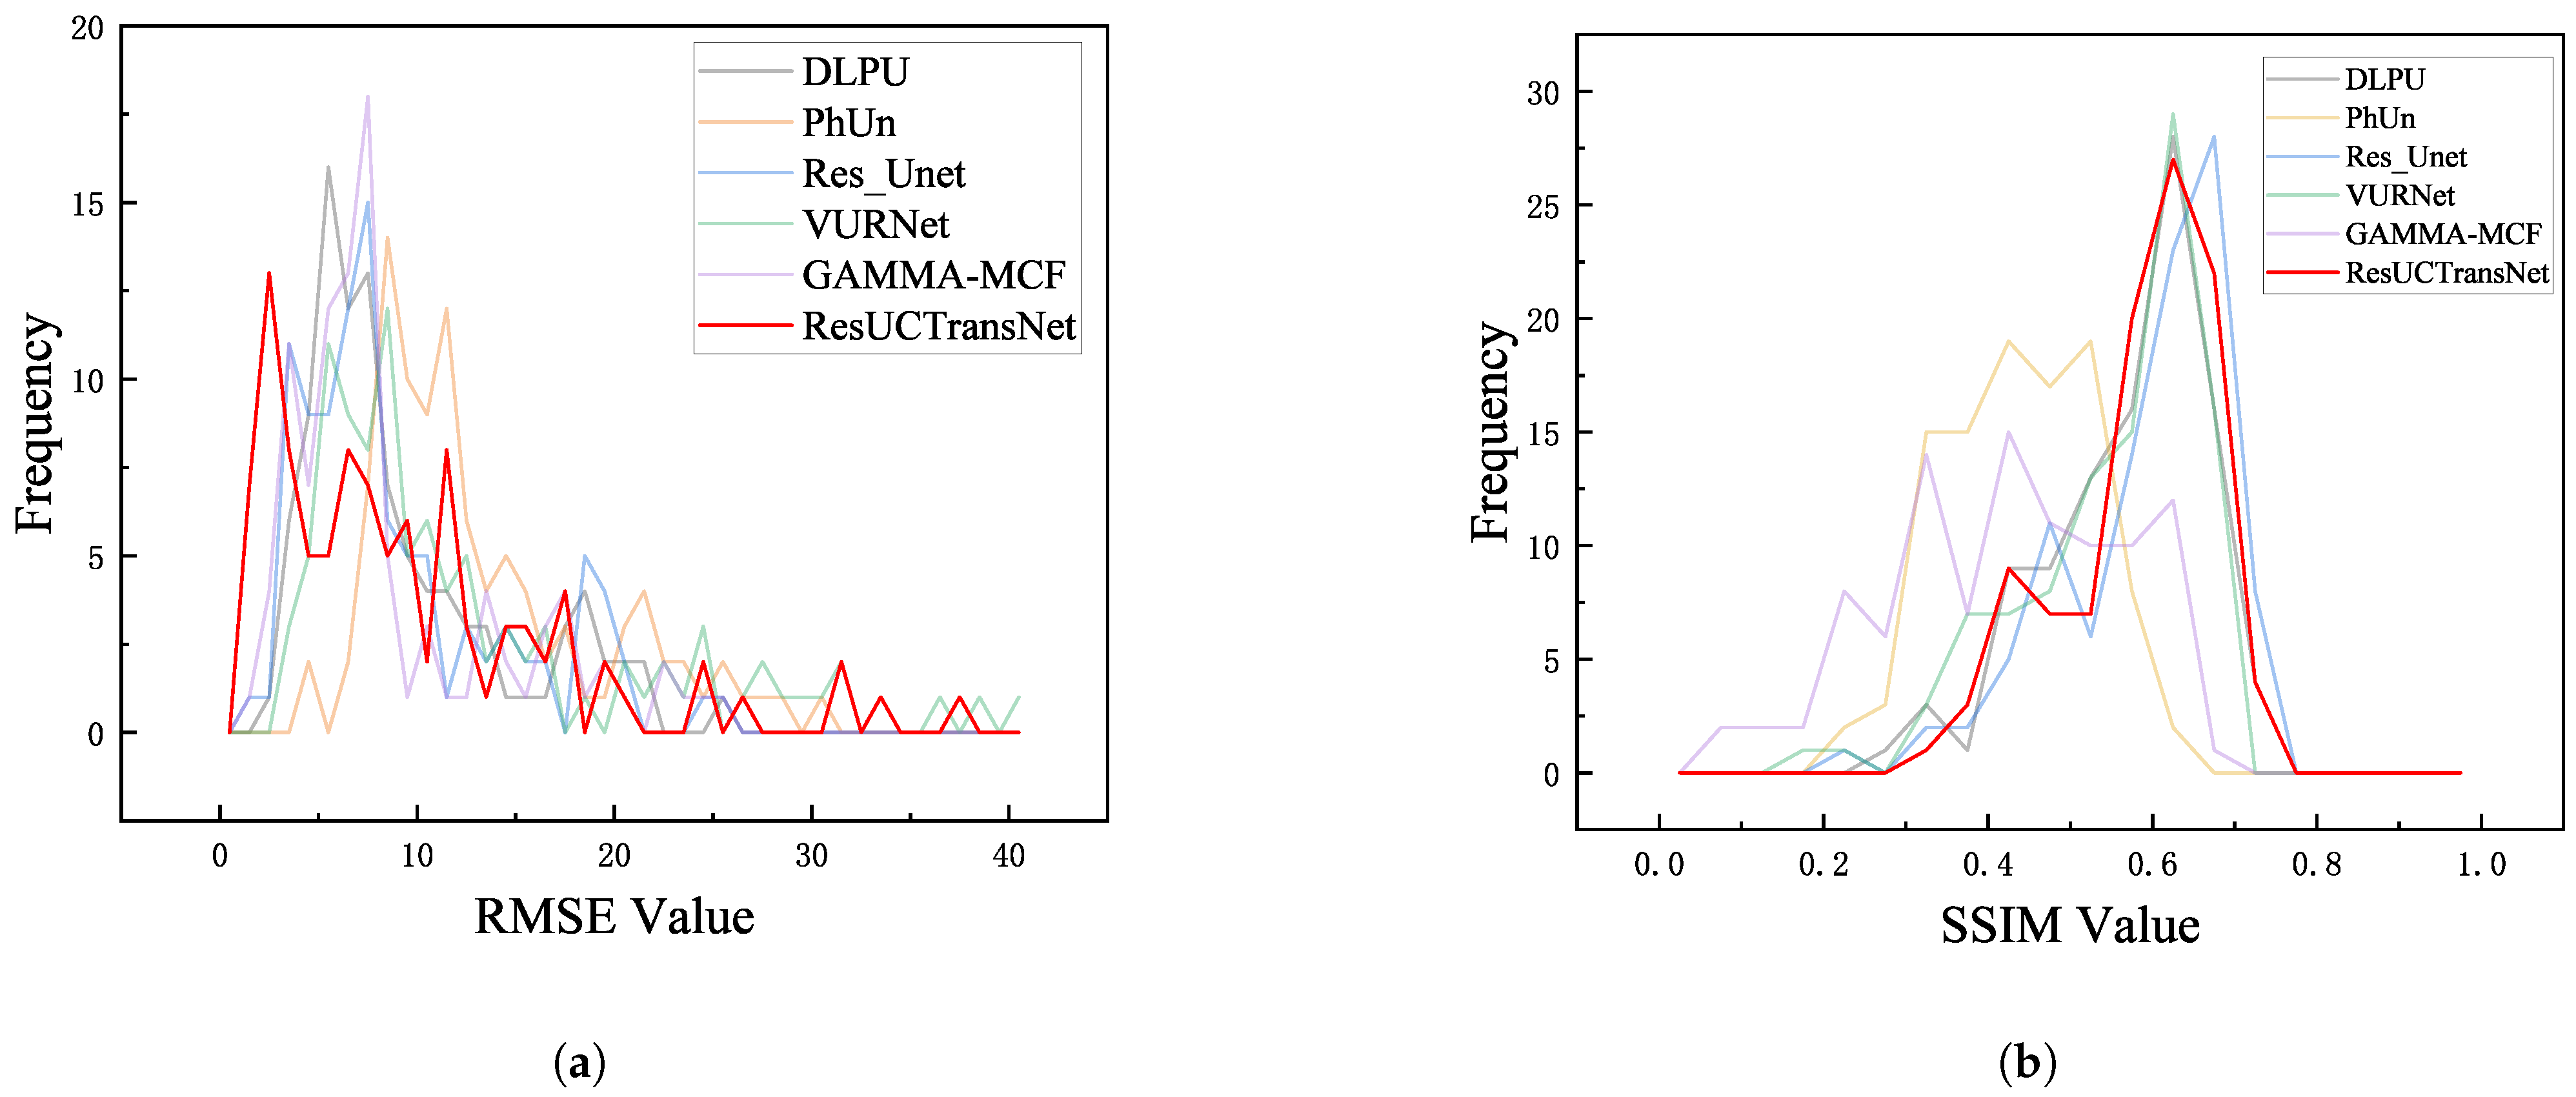
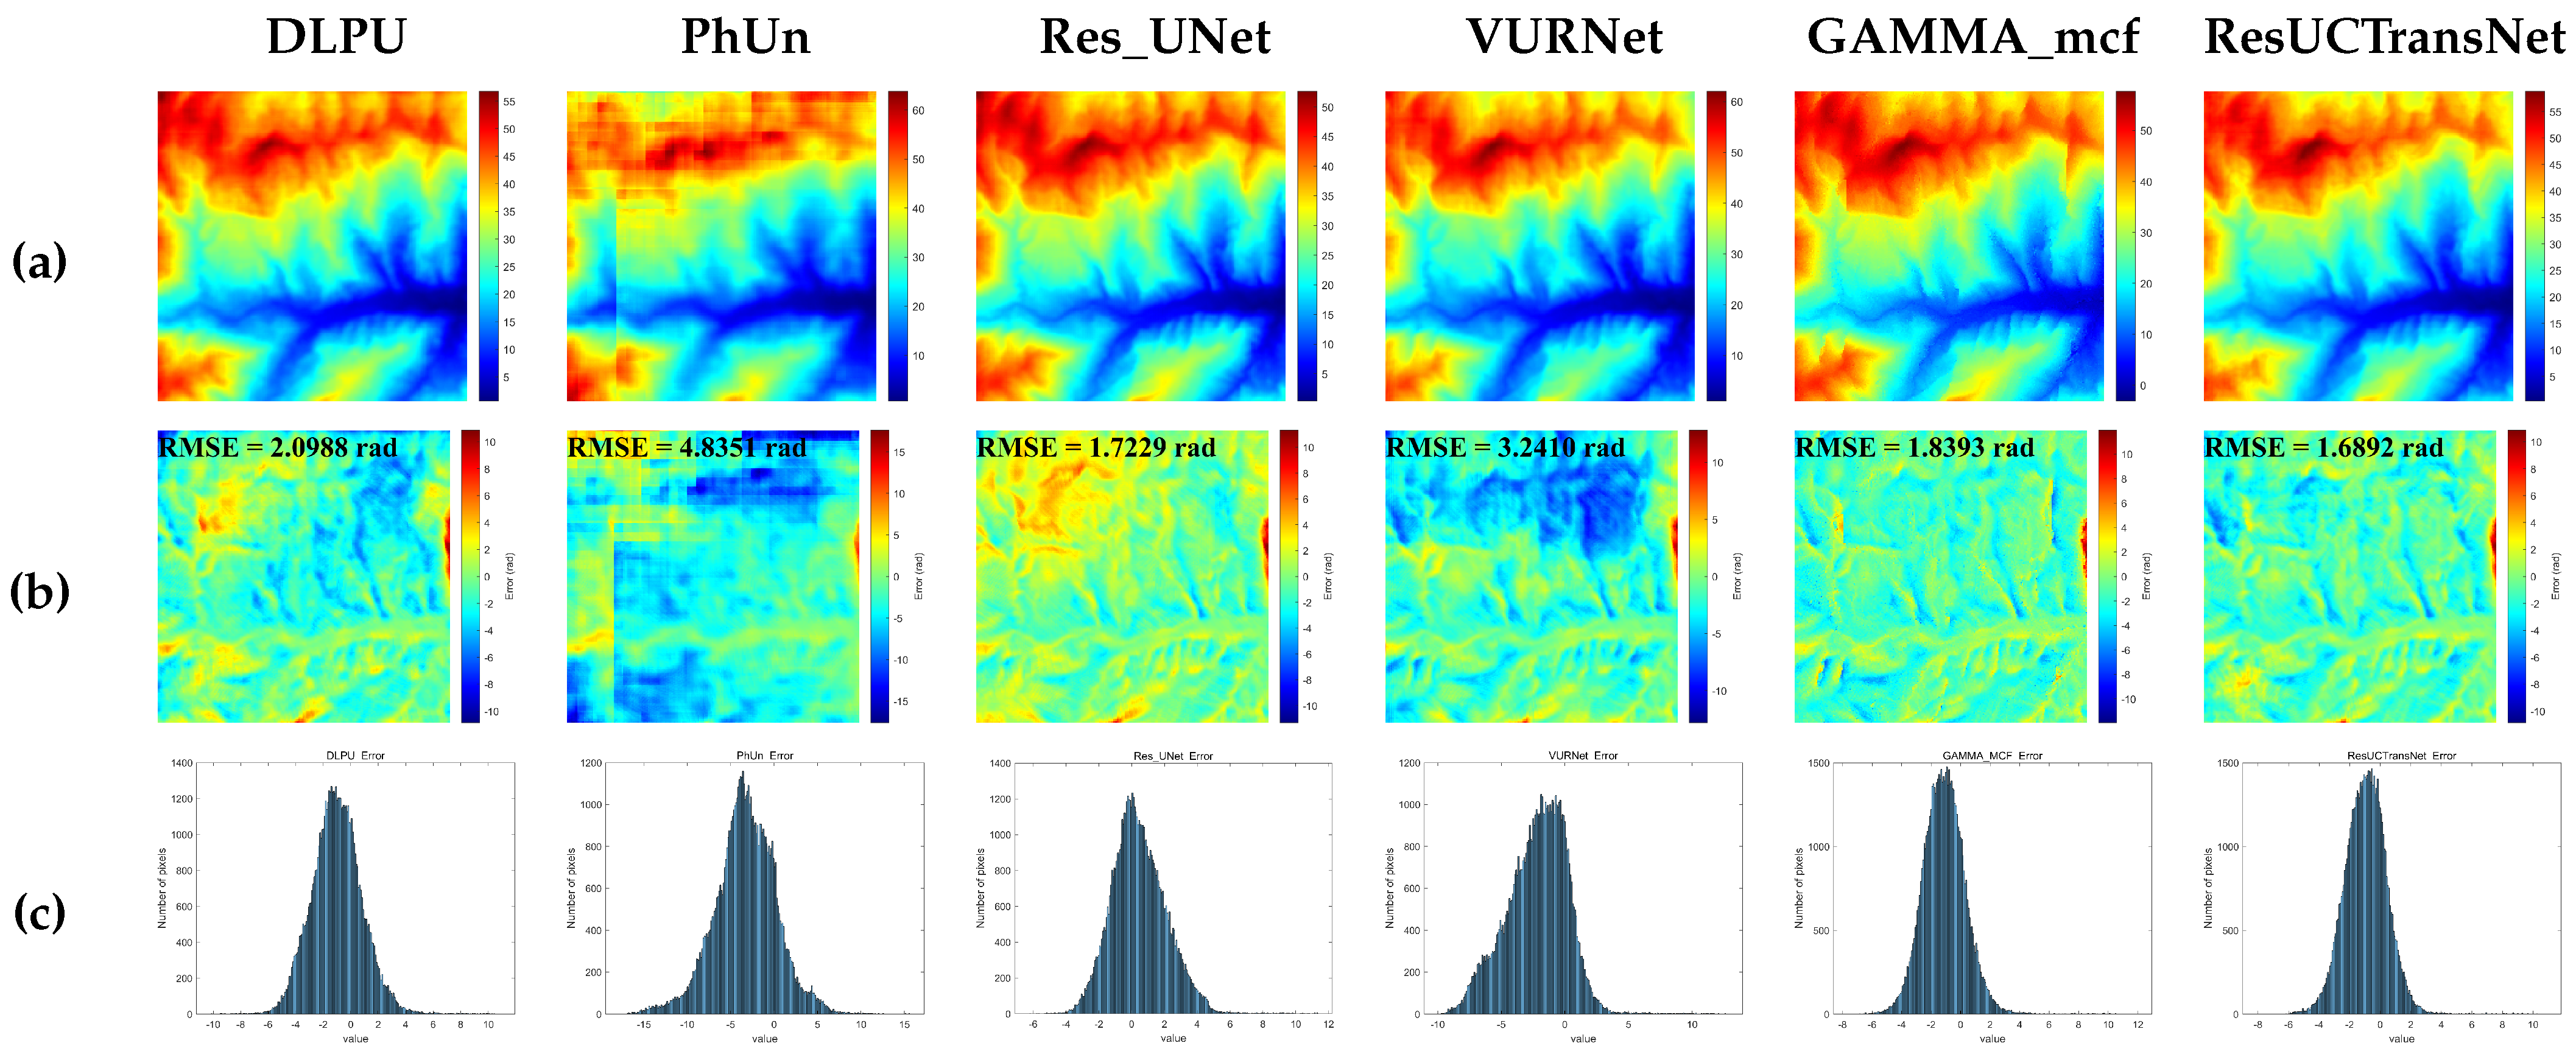
The proposed network achieves lower RMSE and more stable structural fidelity on both data. This includes simulated data and real TanDEM-X external validation. The error histograms exhibit a near-zero-centered distribution with a suppressed long tail. This indicates strong robustness against local unwrapping failures. Fringe continuity and boundary transitions are noticeably improved. There are significantly fewer discontinuities and tearing artifacts in high-gradient and low-coherence regions. These enhancements primarily stem from the introduced CCT and CCA modules. They strengthen cross-scale dependency modeling and cross-stage semantic alignment. This improves the model’s ability to interpret complex phase fringes and noise perturbations. Furthermore, the combination of L1 supervision in the main branch and multi-scale Smooth-L1 deep supervision provides stable gradient propagation. This ensures balanced optimization between numerical accuracy and structural preservation through a coarse-to-fine approach.
Compared with the deep-learning baseline Res_UNet, the proposed method achieves a substantial RMSE reduction. It maintains or slightly improves SSIM. This demonstrates better preservation of spatial relationships and phase continuity along complex terrain edges. Relative to traditional optimization-based unwrapping techniques, the method exhibits reduced dependence on manually designed quality maps and path-following strategies. It offers a more direct inference pipeline with improved engineering applicability and deployment flexibility.
Nevertheless, the model may still encounter challenges under extreme conditions. In ultra-dense fringe regions where phase gradients change rapidly within a few pixels, the local ambiguity of phase continuity increases significantly. Although cross-scale modeling enhances contextual understanding, extremely compressed fringes may exceed the network’s effective receptive field. This potentially leads to localized residual errors or minor over-smoothing. Similarly, in near-zero coherence areas, signal information is severely corrupted by noise. The network may rely excessively on contextual inference. While this behavior helps suppress abrupt discontinuities, it may also introduce structural hallucination or bias toward surrounding patterns.
These potential failure cases indicate that model performance remains influenced by the intrinsic information quality of SAR observations. Future improvements may involve incorporating explicit coherence-aware constraints. Uncertainty modeling mechanisms or physics-guided priors could further enhance robustness in extremely low-signal scenarios. Despite these limitations, the proposed framework demonstrates strong stability and generalization ability across diverse terrain conditions. This confirms its effectiveness for practical InSAR phase unwrapping applications.
5. Conclusions
The proposed ResUCTransNet is primarily trained on DEM-driven simulated samples. The amount of real interferometric data involved remains relatively limited. However, external validation results indicate that the method exhibits a certain degree of cross-domain robustness. In terms of computational complexity, the introduction of the CCT and CCA modules enhances the unwrapping performance. However, it inevitably increases the number of parameters and computational overhead. This still requires further optimization.
To address these limitations, several potential improvement directions are proposed. These cover multiple perspectives: model design, computation, data, constraints, and deployment. At the model level, hyper-light deep learning network [
38] design strategies can be adopted. The model size can be compressed through structural pruning and low-rank decomposition. Standard convolutions can be replaced with Ghost convolutions and depthwise separable convolutions. Large-scale self-attention mechanisms can be substituted with lightweight attention modules. This significantly reduces computational complexity and parameter scale while maintaining unwrapping accuracy. Furthermore, a hyper-light deep learning network tailored for engineering deployment can be developed to achieve both high-precision unwrapping and fast inference, providing technical support for near-real-time deformation monitoring. For sudden deformation events such as mining subsidence, high-speed inference capability would enable rapid scanning of key areas and timely risk warnings, thereby improving monitoring responsiveness.
Regarding computational efficiency, mixed-precision training and inference can effectively shorten model runtime, while efficient sliding-window tiling strategies can improve data throughput and memory utilization. Gradient checkpointing and memory reuse mechanisms help support larger batch sizes during training. In addition, incorporating model parallelism and data parallelism strategies can alleviate memory bottlenecks when processing large-scale interferograms, providing hardware adaptation support for wide-swath data processing and near-real-time monitoring scenarios.
In terms of loss function design, the current regression framework achieves a relatively stable balance between numerical accuracy and structural fidelity. Future work may further expand the constraint dimensions of the loss function. This can be done by incorporating phase-topology consistency and residual-point constraints. These should be combined with total variation (TV) regularization or frequency–domain sparsity priors. This enhances structural preservation and reduces noise-induced step errors. Moreover, adaptive loss function design may be explored. Loss weights would be dynamically adjusted according to interferogram coherence and fringe density. This enables more refined adaptation across different scenarios and improves overall robustness.
From the perspective of data and scene adaptation, balanced learning strategies inspired by imbalanced detection tasks may be introduced. InSAR phase unwrapping exhibits distribution differences among several region types. These include high- and low-coherence regions, dense and sparse fringe areas, and flat and complex terrains. Weighted loss functions, adaptive resampling, and curriculum learning can be employed. These guide the model to focus more on low-coherence and complex fringe regions. This enhances robustness in challenging environments. In addition, a progressive processing strategy from global to local refinement can be incorporated. This constructs a “global coarse unwrapping–local fine correction” framework. By first enforcing structural consistency at the regional scale and subsequently performing pixel-level refinement, ambiguity propagation and noise accumulation can be effectively reduced.
Furthermore, data augmentation and real-data adaptation strategies may be strengthened. To address the limited availability of real interferometric data, interferogram generation methods based on physical imaging models can be developed. These simulate realistic scenarios with varying noise levels, deformation magnitudes, and fringe densities. This mitigates domain gaps between simulated and real data. Meanwhile, few-shot learning and self-supervised learning approaches may be explored. These improve model performance under limited labeled data conditions and reduce reliance on large-scale manual annotations.
Overall, the proposed ResUCTransNet integrates three key strategies: cross-scale semantic alignment, channel-selective enhancement, and multi-scale supervision. It effectively reduces unwrapping errors while preserving phase structural continuity. The method demonstrates strong engineering potential in several applications. These include mining subsidence monitoring, urban deformation analysis, and geohazard surveillance. Future research will focus on multiple directions: Conducting domain adaptation studies on large-scale real interferograms to enhance model adaptability to real-world scenarios; Advancing model compression and hyper-light network design to achieve both high precision and high speed. This supports rapid subsidence detection in wide-swath and near-real-time monitoring scenarios; Exploring multimodal inputs and time-series fusion techniques. Temporal correlation constraints should be incorporated to improve robustness under strong noise, large deformation, and extreme weather conditions, enhancing model interpretability by embedding physical constraints and visualizing feature learning processes. This improves credibility in scientific and engineering applications; Extending the method to different interferometric systems and diverse monitoring environments. Integration with 3D reconstruction and deformation inversion techniques should be explored to build a unified interferometric solution framework; Promoting engineering-oriented optimization of the algorithm by designing efficient parallel computing architectures and optimizing data processing pipelines. This improves large-scale interferogram processing efficiency.




 ,