


Abstract
This study proposes a transparent, data-driven framework for behavior recognition based exclusively on IMU measurements, hypothesizing that vehicular jerk-based features can help in differentiating driving behavior. Unlike studies relying on direct jerk values, our approach derives novel findings from jerk-based features. For rolling windows of 300 samples, a comprehensive set of statistical and dynamic descriptors is extracted, including amplitude, variance, standard deviation, coefficient of variation, standard error, skewness, and kurtosis, as well as jerk-based features such as jerk_std, jerk_variance, jerk_amplitude, and jerk_spikes. Statistical analysis is used to identify features with strong discriminative power. The selected features are used to compute the Driving Score (DS) and, along with the Kernel Density Estimation (KDE) and associated statistics, provide a driver’s profile. Low DS values are consistently associated with increased jerk variability, whereas high DS values correspond to smoother and more controlled motion profiles. The robustness of the proposed framework is evaluated using several machine learning classifiers as baselines, with the jerk-based features as inputs. For the aggressive driver class, the Driving Behavior Score (DBS) model reports a Recall of 0.952 and an F1 of 0.925. For the normal driver class, the DBS model reports a Recall of 0.839 and an F1 of 0.879. The model has a total accuracy of 0.907. Also, Logistic Regression and ensemble models like Extreme Gradient Boosting (XGB) and Random Forest (RF) perform well. The proposed framework offers an explainable, computationally efficient alternative to conventional machine-learning classifiers for identifying aggressive drivers. It relies on lightweight statistical computations being suitable for real-time implementation.
1. Introduction
Driving behavior significantly influences (positively or negatively) both road safety and the environment. A key component of modern road safety is responsible driving, reflected through a driver’s ability to anticipate, adapt, and maintain vigilance during travel. Despite the continuous development of intelligent vehicle technologies such as adaptive cruise control, automated braking, lane-keeping systems, and real-time driver monitoring, human behavior remains the dominant factor influencing crash occurrence. According to global evaluations, aggressive maneuvers, instability in motion, and abrupt changes in acceleration remain strongly associated with unsafe driving patterns, which can be effectively detected using motion-derived indicators such as jerk, amplitude variability, skewness, and kurtosis [1,2,3,4,5,6]. These approaches often rely on complex representations or heavily preprocessed data, which can reduce interpretability.
Given that driver profiling is a multifaceted approach, investigating and developing new quantitative statistical measures that capture aspects of driving style could be beneficial. Motivated by these findings, this work introduces a transparent, data-driven methodology for profiling driver behavior using jerk-related features and the Drive Score. The proposed approach does not directly use jerk values; instead, it derives novel findings from jerk-based features. Also, we are interested in preserving raw signal integrity, which avoids artificial changes to the signal that occur with traditional filtering methods. Jerk-based features better reflect movement smoothness than velocity or acceleration alone. The jerk_std captures overall variability of abrupt motion changes (high jerk_std—unstable or unsmooth movement, low jerk_std—consistent, controlled movement), jerk_variance is used for optimization or cost functions (high values indicate distracted or impaired driving), large jerk_amplitude indicates sudden corrections in motion, and jerk_spikes indicates sudden discontinuities in motion. In a first step, the algorithm segments the data into sliding windows and calculates jerk along the three axes. Next, it extracts key features including amplitude, variance, standard deviation, coefficient of variation, standard error, skewness, kurtosis, and jerk-related features (jerk_std, jerk_variance, jerk_amplitude, jerk_spikes). Finally, a classification is performed as benchmarking to validate the robustness of the proposed approach.
This study addresses a gap in the current literature. While many existing studies rely heavily on jerk parameters, several practical barriers still hinder the timely, consistent, and scalable assessment. First, relatively little research has explored statistical and dynamic descriptors based on jerk-based feature dynamics. When large positive or negative jerk values are present, a uniform approach becomes difficult. Consequently, using dynamic descriptors based on jerk-related features offers a novel and effective alternative. Second, unlike Convolutional Neural Network (CNN) or Long Short-Term Memory (LSTM) approaches that operate as black-box systems, the proposed method explicitly quantifies driving instability using physically meaningful statistical and jerk-based features. The study evaluates the robustness of the selected jerk-based descriptors using multiple machine learning baselines while maintaining interpretability and low computational complexity. The present study addresses these limitations by proposing a transparent framework based exclusively on interpretable IMU-derived jerk-based features.
The novelty of the proposed study can therefore be summarized as follows:
- (1)
- Present a methodological framework for quantifying driving behavior using interpretable IMU-based features. The significance of feature selection from IMU data is explored in relation to its impact on driver behavior. Investigate the efficacy of dimensionless jerk-based measures to quantify driving behavior.
- (2)
- Evaluate the variations and interpretability of statistical features in driver profiling based on the Driving Score (DS) measure. Using statistical analysis, the proposed driving scoring approach improves the transparency and interpretability of drivers’ behavior. This goes beyond feature-based analysis or neural network classification, which usually lack explainability.
- (3)
- Conduct a comparative validation using multiple machine learning baselines and cross-dataset evaluation.
- (4)
- Analysis of the practical significance of DS through effect-size evaluation using Cohen’s d statistics, Kernel Density Estimation (KDE), and associated statistics.
This approach addresses the increased need for robust and transparent monitoring strategies that complement intelligent transportation systems and support the design of predictive, personalized safety solutions.
2. Related Works
As transportation systems become more automated, advanced analytics are essential for detecting subtle deviations in driving styles. Smartphone-based sensors, inertial measurement units, and on-board telematics have made real-time vehicle dynamics monitoring affordable. Traditional approaches for driving behavior recognition rely primarily on handcrafted statistical indicators derived from acceleration, braking, steering, and vehicular jerk measurements. Feng et al. [3] demonstrated that longitudinal jerk can effectively distinguish aggressive drivers from normal drivers using naturalistic driving data. Mantouka et al. [7] employed smartphone accelerometer data combined with unsupervised learning techniques to identify distinct driving safety profiles. Moreover, despite existing methods for classifying driving behavior based on relative power acceleration [8] and vehicular jerk thresholds [9], no research has examined statistical differences and influence areas using real-world data. The greater variability in accelerometer signals, along with increased asymmetry (skewness), higher kurtosis, and notable jerk fluctuations, is directly linked to risky behaviors, including harsh braking, aggressive acceleration, lane instability, and quick steering corrections [10,11,12]. To assess a driver’s behavior and operational performance, it is important to focus on features that accurately reflect their impact. One essential characteristic is the jerk effect, which results from sudden acceleration and deceleration. Jerk values measure how quickly accelerations change, effectively indicating how smoothly a driver operates. Hayati et al. [10] provide a comprehensive review of jerk’s relevance in university science and engineering. The discussion focuses on jerk’s usefulness in traditional land-based vehicles and in anti-jerk controller design for autonomous vehicles. Extensive research has dealt with driving behavior parameters. They were motivated by the need for transparent analytical models capable of interpreting IMU signals and deriving meaningful behavioral categories [13,14,15,16]. Redhu & Siwach [13] investigated the effect of traffic jerk using linear stability analysis. Jerk, a factor contributing to traffic congestion, was analyzed using a lattice hydrodynamics model. This model examined vehicle braking and acceleration patterns and their dependence on the jerk parameter. They found that the jerk parameter significantly contributes to traffic jams and reducing it requires a greater emphasis on driver anticipation and normal behavior. To enhance driving safety, comfort, and operability in complex urban environments, Sun et al. [15] developed a framework for verifying online driving styles through a personalized intention-aware automated driving strategy. They evaluated driving style using various longitudinal stimuli and applied different weight coefficients to classify it as steady, general, or radical. Karrouchi et al. [16] proposed practical approaches for driver condition assessment using acceleration statistics and gyroscope measurements. These studies confirmed that variance, skewness, kurtosis, and temporal instability patterns extracted from IMU signals can reveal meaningful behavioral characteristics.
However, most existing works either focus on direct thresholding approaches or rely heavily on black-box classification models with limited interpretability. In recent years, machine learning methods have become increasingly common for driver behavior classification. Random Forest, Support Vector Machine (SVM), Logistic Regression, XGBoost, and K-Nearest Neighbors (KNN) models have demonstrated good performance when trained on telematics or IMU-derived features. Komavec et al. [17] evaluated driver performance and the likelihood of unsafe driving using data from a simulated driving session. They proposed a risk assessment score to estimate a driver’s propensity for risky behavior. Two machine learning models were then employed to classify drivers as either risky or non-risky. Machine learning algorithms are especially effective for risk assessment when the driving score stays interpretable and offers valuable feedback on driver profiling, but there is a lack of general explainability. Feng et al. [18] explored the usefulness of vehicle longitudinal jerk in identifying aggressive drivers. Their findings showed aggressive drivers had significantly higher values for both positive and negative jerk-based metrics. They concluded that a large negative jerk is effective in identifying aggressive drivers. Medarevic et al. [19] proposed a rule-based Driver Scoring System model to analyze driving simulator data and identify driver profiles. Their approach involves clustering distinct driver profiles. Three clusters are formed, and similar driving behavior reveals the driver profile (less or more aggressive). Tawadros et al. [20] proposed a method based on torque computation for jerk estimation. Automation usually leads to increased jerk and slower shift times compared to a skilled driver. They proposed a wireless torque measurement device to estimate the jerk characteristic. They conducted extensive simulations and experimental measurements and concluded that a low-cost torque sensor and Bluetooth communication could quantify the experimentally derived jerk. El mourabit et al. [21] proposed a framework for Instantaneous Time-to-Collision computation based on estimated relative distance, velocity, acceleration, and jerk to assess collision risk. They used a constant-jerk model to describe the changing velocities and accelerations as significant factors influencing drivers’ behavior.
Deep learning approaches have also emerged as important tools for driving behavior analysis. Convolutional Neural Networks (CNNs) have been used to automatically learn spatial and temporal motion patterns from raw accelerometer and gyroscope signals without extensive manual feature engineering. Patricio et al. [22] presented a comprehensive analysis of Conv1D + LSTM models on accelerometer/gyroscope smartphone sensor data to detect aggressive and non-aggressive driving behaviors using mobile sensor data. They demonstrated that integrating the segmentation process into the network using Conv1D generally yields more consistent outcomes and improves training efficiency. Pingo et al. [23] proposed a hybrid Convolution + LSTM (ConvLSTM) deep learning framework to learn spatial and temporal patterns in driving behavior for aggressive/normal classification. They confirmed that preprocessing enhances classification performance, yielding high reliability in recognizing driving behavior. Chen et al. [24] proposed a CNN-LSTM hybrid network with attention modules to extract both spatial and temporal features from radar signals for classifying driving behaviors. Escottá et al. [25] investigated CNN-based end-to-end models on raw smartphone IMU (linear acceleration and angular velocity) data for driving event classification (e.g., accelerating, braking, turning). The study shows that 1D-CNN models on raw IMU streams achieve high accuracy in classifying aggressive versus non-aggressive driving events, demonstrating the effectiveness of CNNs on smartphone sensor streams without extensive manual feature engineering. Yedilkhan et al. [26] evaluated multiple deep networks (CNN, LSTM, GRU) on inertial sensor time-series for aggressive driving behavior detection using tri-axial accelerometer and gyroscope readings. This study highlights that LSTM and CNN models trained on IMU data perform well for real-time classification of driving behavior patterns in actual driving scenarios.
Despite these advances, assessing drivers’ dangerous tendencies remains limited to questionnaires, expensive measurement tools, or intensive computational algorithms built based on advanced machine learning/deep learning models. Existing approaches rarely address statistical and dynamic descriptors, especially in scenarios involving jerk-based feature dynamics. Also, despite their strong predictive performance, deep learning methods often require large annotated datasets, intensive computational resources, and complex preprocessing pipelines.
3. Materials and Methods
This paper aims to conduct a detailed analysis of IMU data to recognize different driving behaviors and classify them into two categories: normal (labeled 0) and aggressive (labeled 1).
3.1. Data Quality
This study uses two multi-center datasets to improve diversity and heterogeneity. The two selected datasets contain real-life driving actions, not simulated ones. We used data from both the Mendeley [27] and Kaggle [28] datasets. These datasets include IMU and data labeling that are used extensively in the previous literature, providing sufficient variability to ensure the robustness of the proposed approach within this paper’s scope. Thus, heterogeneity is not a weakness but a strength. Feature extraction pipelines were applied separately and consistently. Moreover, normalization techniques reduce structural differences. Also, we are interested in using computationally lightweight classification models to enable a real-world application. According to many ML studies, classifiers intentionally use imbalanced, heterogeneous datasets to evaluate domain robustness or feature resilience. We focused on feature behavior, more than model training, and statistical symmetry between datasets is not a prerequisite. The potential bias arising from an imbalance between datasets in terms of sample size, recording duration, and driver representation is mitigated as follows.
- -
- Despite the larger Mendeley dataset’s dominance, datasets are used independently for feature extraction. Further, to demonstrate the robustness of jerk-based feature dynamics, this approach involved training on one dataset and testing on another, preventing learned patterns from reflecting only one data distribution.
- -
- To avoid skewed cross-dataset comparisons, the comparison does not directly examine dataset-specific performance. Instead, the comparison is provided at the dataset scale, and feature-scale invariance by normalization is considered.
The Mendeley dataset contains information like longitude, latitude, speed, distance, time, heading, accelerometer (Acc_X, Acc_Y, Acc_Z), and gyroscope signals recorded using IMU sensors. It also includes a label column indicating driving behavior (0 for normal and 1 for aggressive). The Mendeley dataset yielded 140 rolling/sliding windows for accelerometer signals.
The Kaggle dataset contained smartphone sensor data from Android devices, specifically accelerometer and gyroscope readings. This dataset was collected under realistic traffic conditions. The experiment involved driving the same stretch of road at three different speeds: slow, normal, and aggressive. However, the slow data was removed from the current study. The Kaggle dataset case used 41 rolling/sliding windows for accelerometer signals.
For both datasets, the instance numbers were 1927 for aggressive driving and 2197 for normal driving. The balance between classes is kept. Each window is a time series containing 300 samples. The obtained time-series windows contain data from both normal and aggressive drivers. For each window, 42 features were computed. The initial feature datasets contain 80,934 data points for aggressive driving and 92,274 for normal driving. After the Driving Score selection procedure (detailed below), a reduced subset of 22 statistically significant features remained. This results in 3080 samples for the Mendeley dataset and 902 for the Kaggle dataset. A further reduction was performed when only jerk-based features (jerk_std_x, jerk_variance_x, jerk_amplitude_x, jerk_spikes_x, jerk_std_y, jerk_max_z, jerk_amplitude_z) were considered for classification, corresponding to 980 samples for the Mendeley dataset and 140 for the Kaggle dataset. The Mendeley dataset was used for training, while Kaggle was used for testing.
3.2. Jerk Features
Vehicular jerk features, linked to driving volatility assessment, help identify deviations from normal driving and quantify speed variations during a journey. An acceleration profile illustrates how a driver accelerates and decelerates, while a jerk profile shows the rates of acceleration and deceleration. This is crucial for assessing abrupt changes in driving behavior. Jerk J [ms−3] is related to acceleration a [ms−2] and velocity v [ms−1] by the equation [29]:
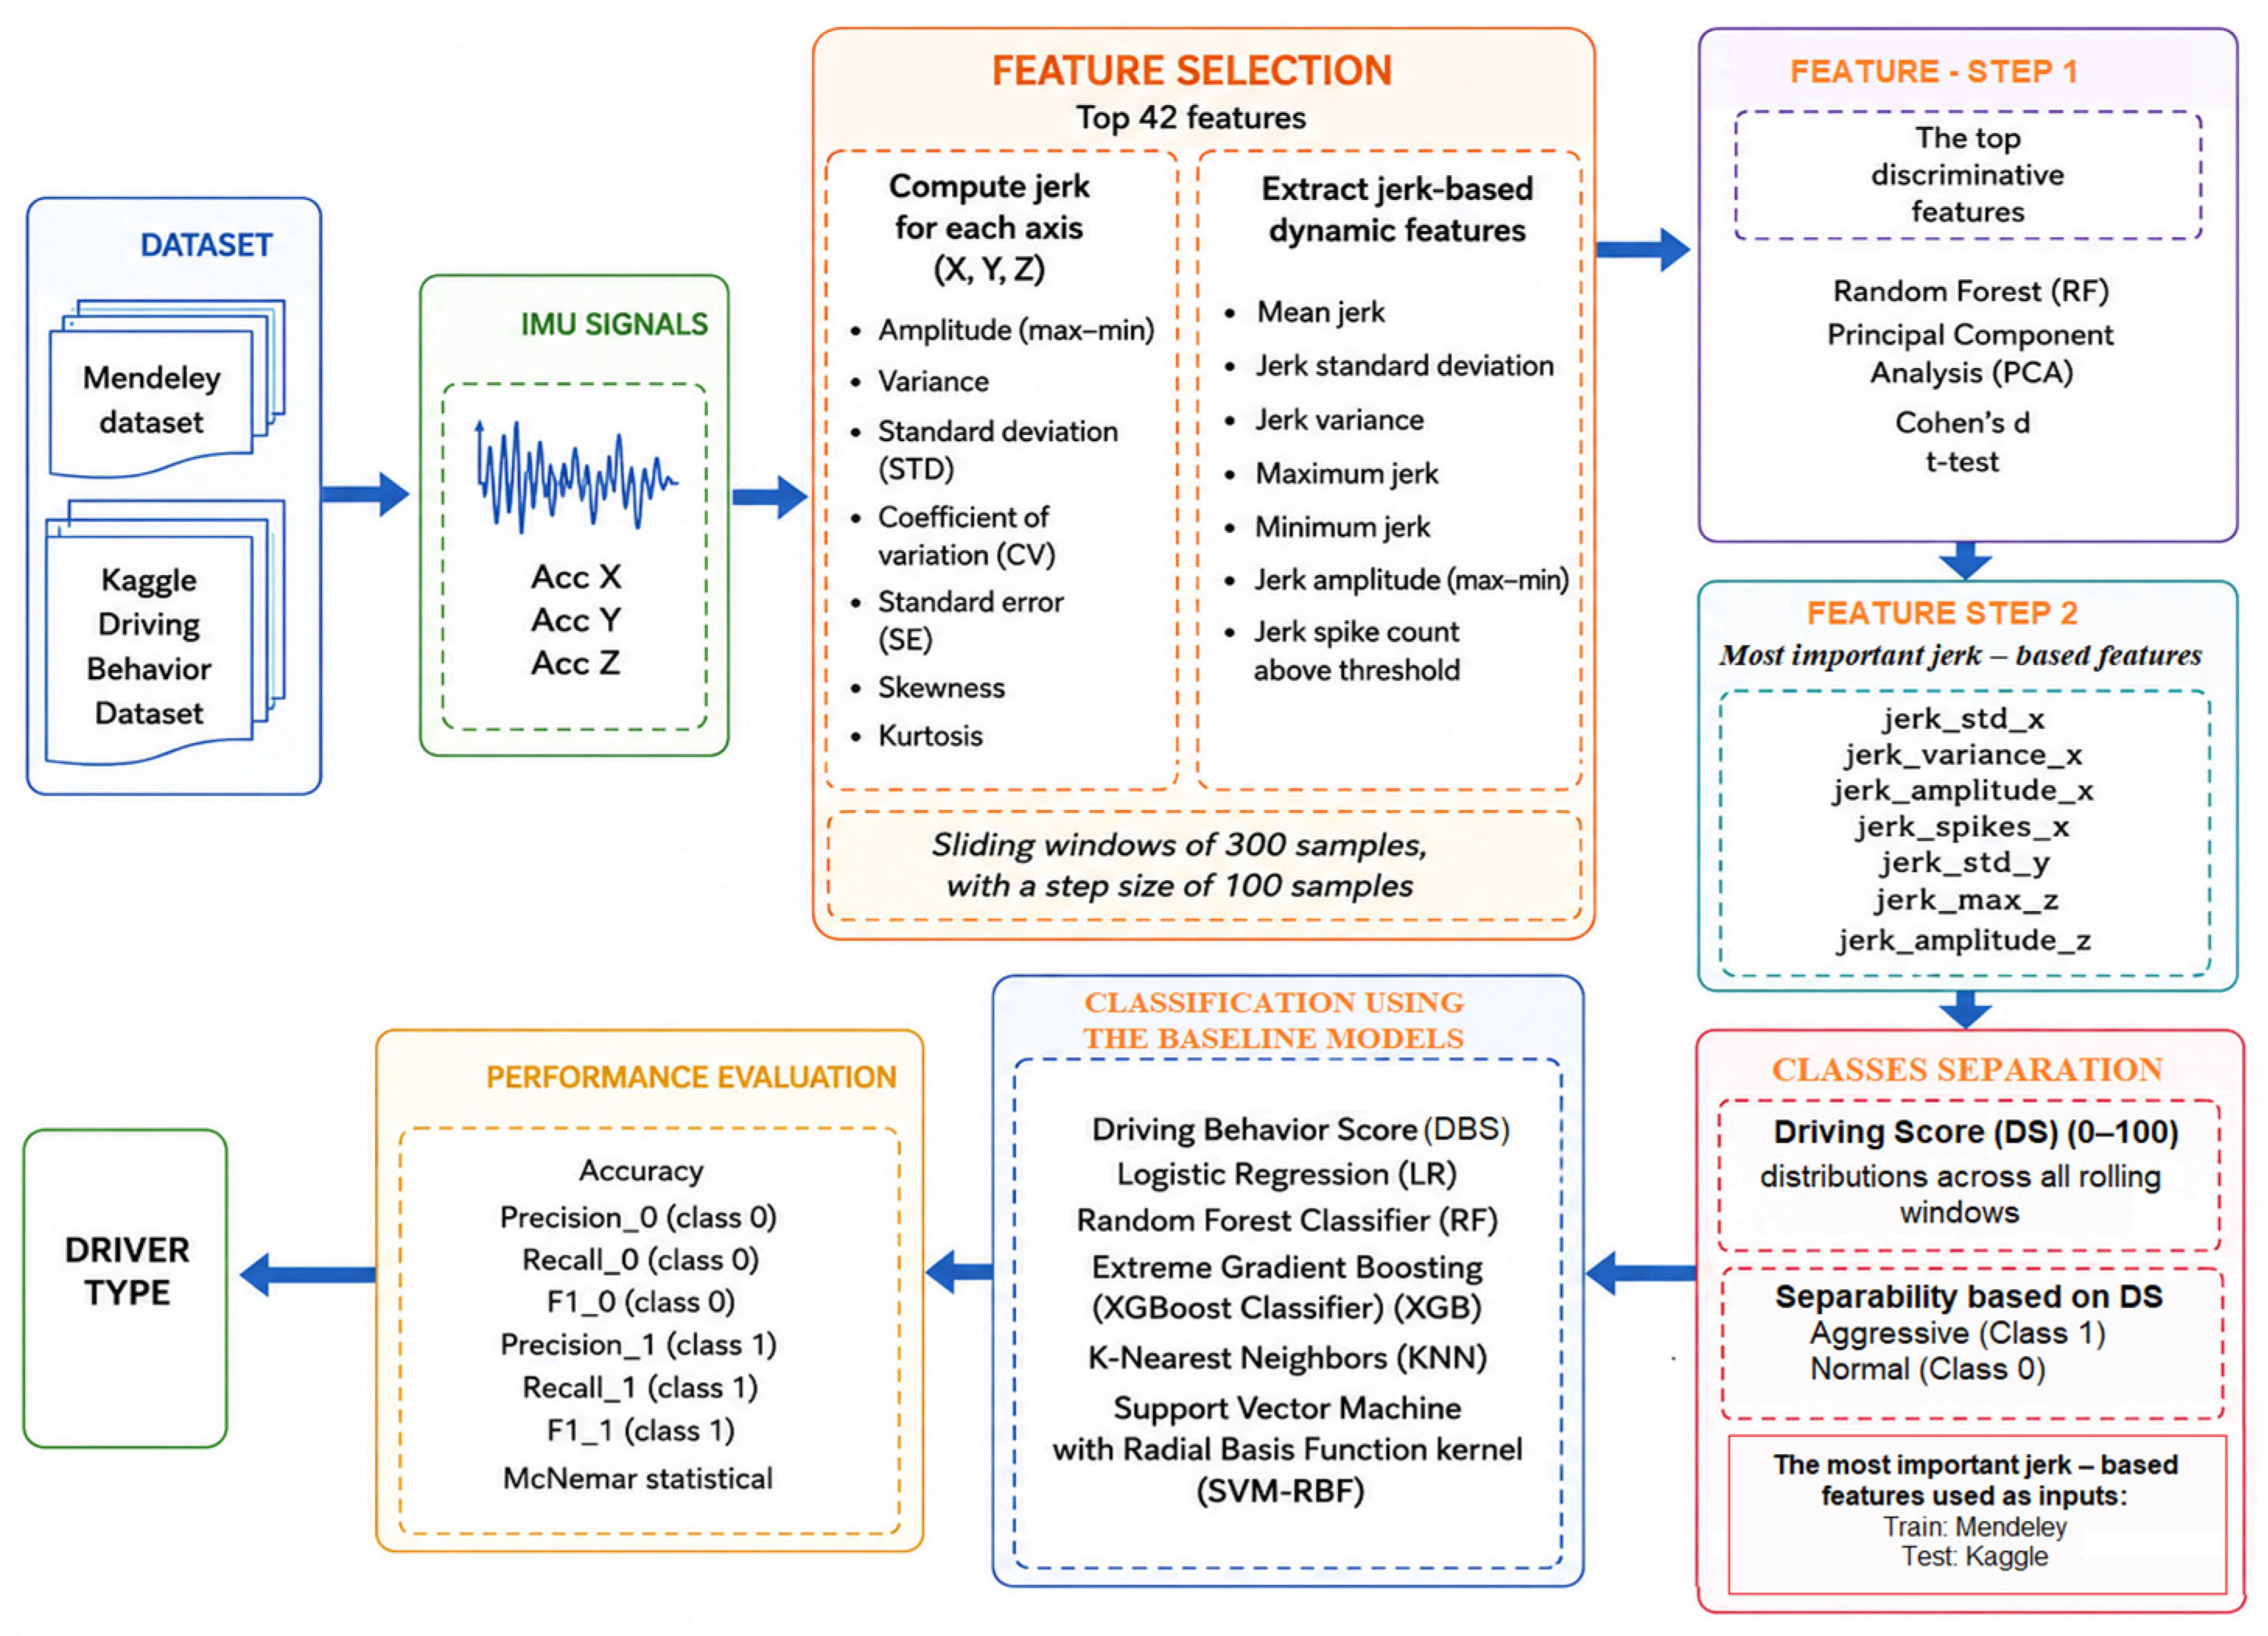
Figure 1 illustrates the proposed model framework. The feature engineering step is included to improve the performance of driving profiling. Here, apart from well-known features such as amplitude, variance, standard deviation, coefficient of variation, standard error, skewness, and kurtosis, some new derived jerk-based indicators, such as jerk_std, jerk_variance, jerk_amplitude, and jerk_spikes, are generated for each window. The IMU channels (Acc_X, Acc_Y, Acc_Z) are processed to generate a behavioral score for each window, enabling the classification of driving patterns into classes 0 and 1. Six machine learning models serve as baselines, providing a comprehensive performance benchmark.
Figure 1.
Methodology overview.
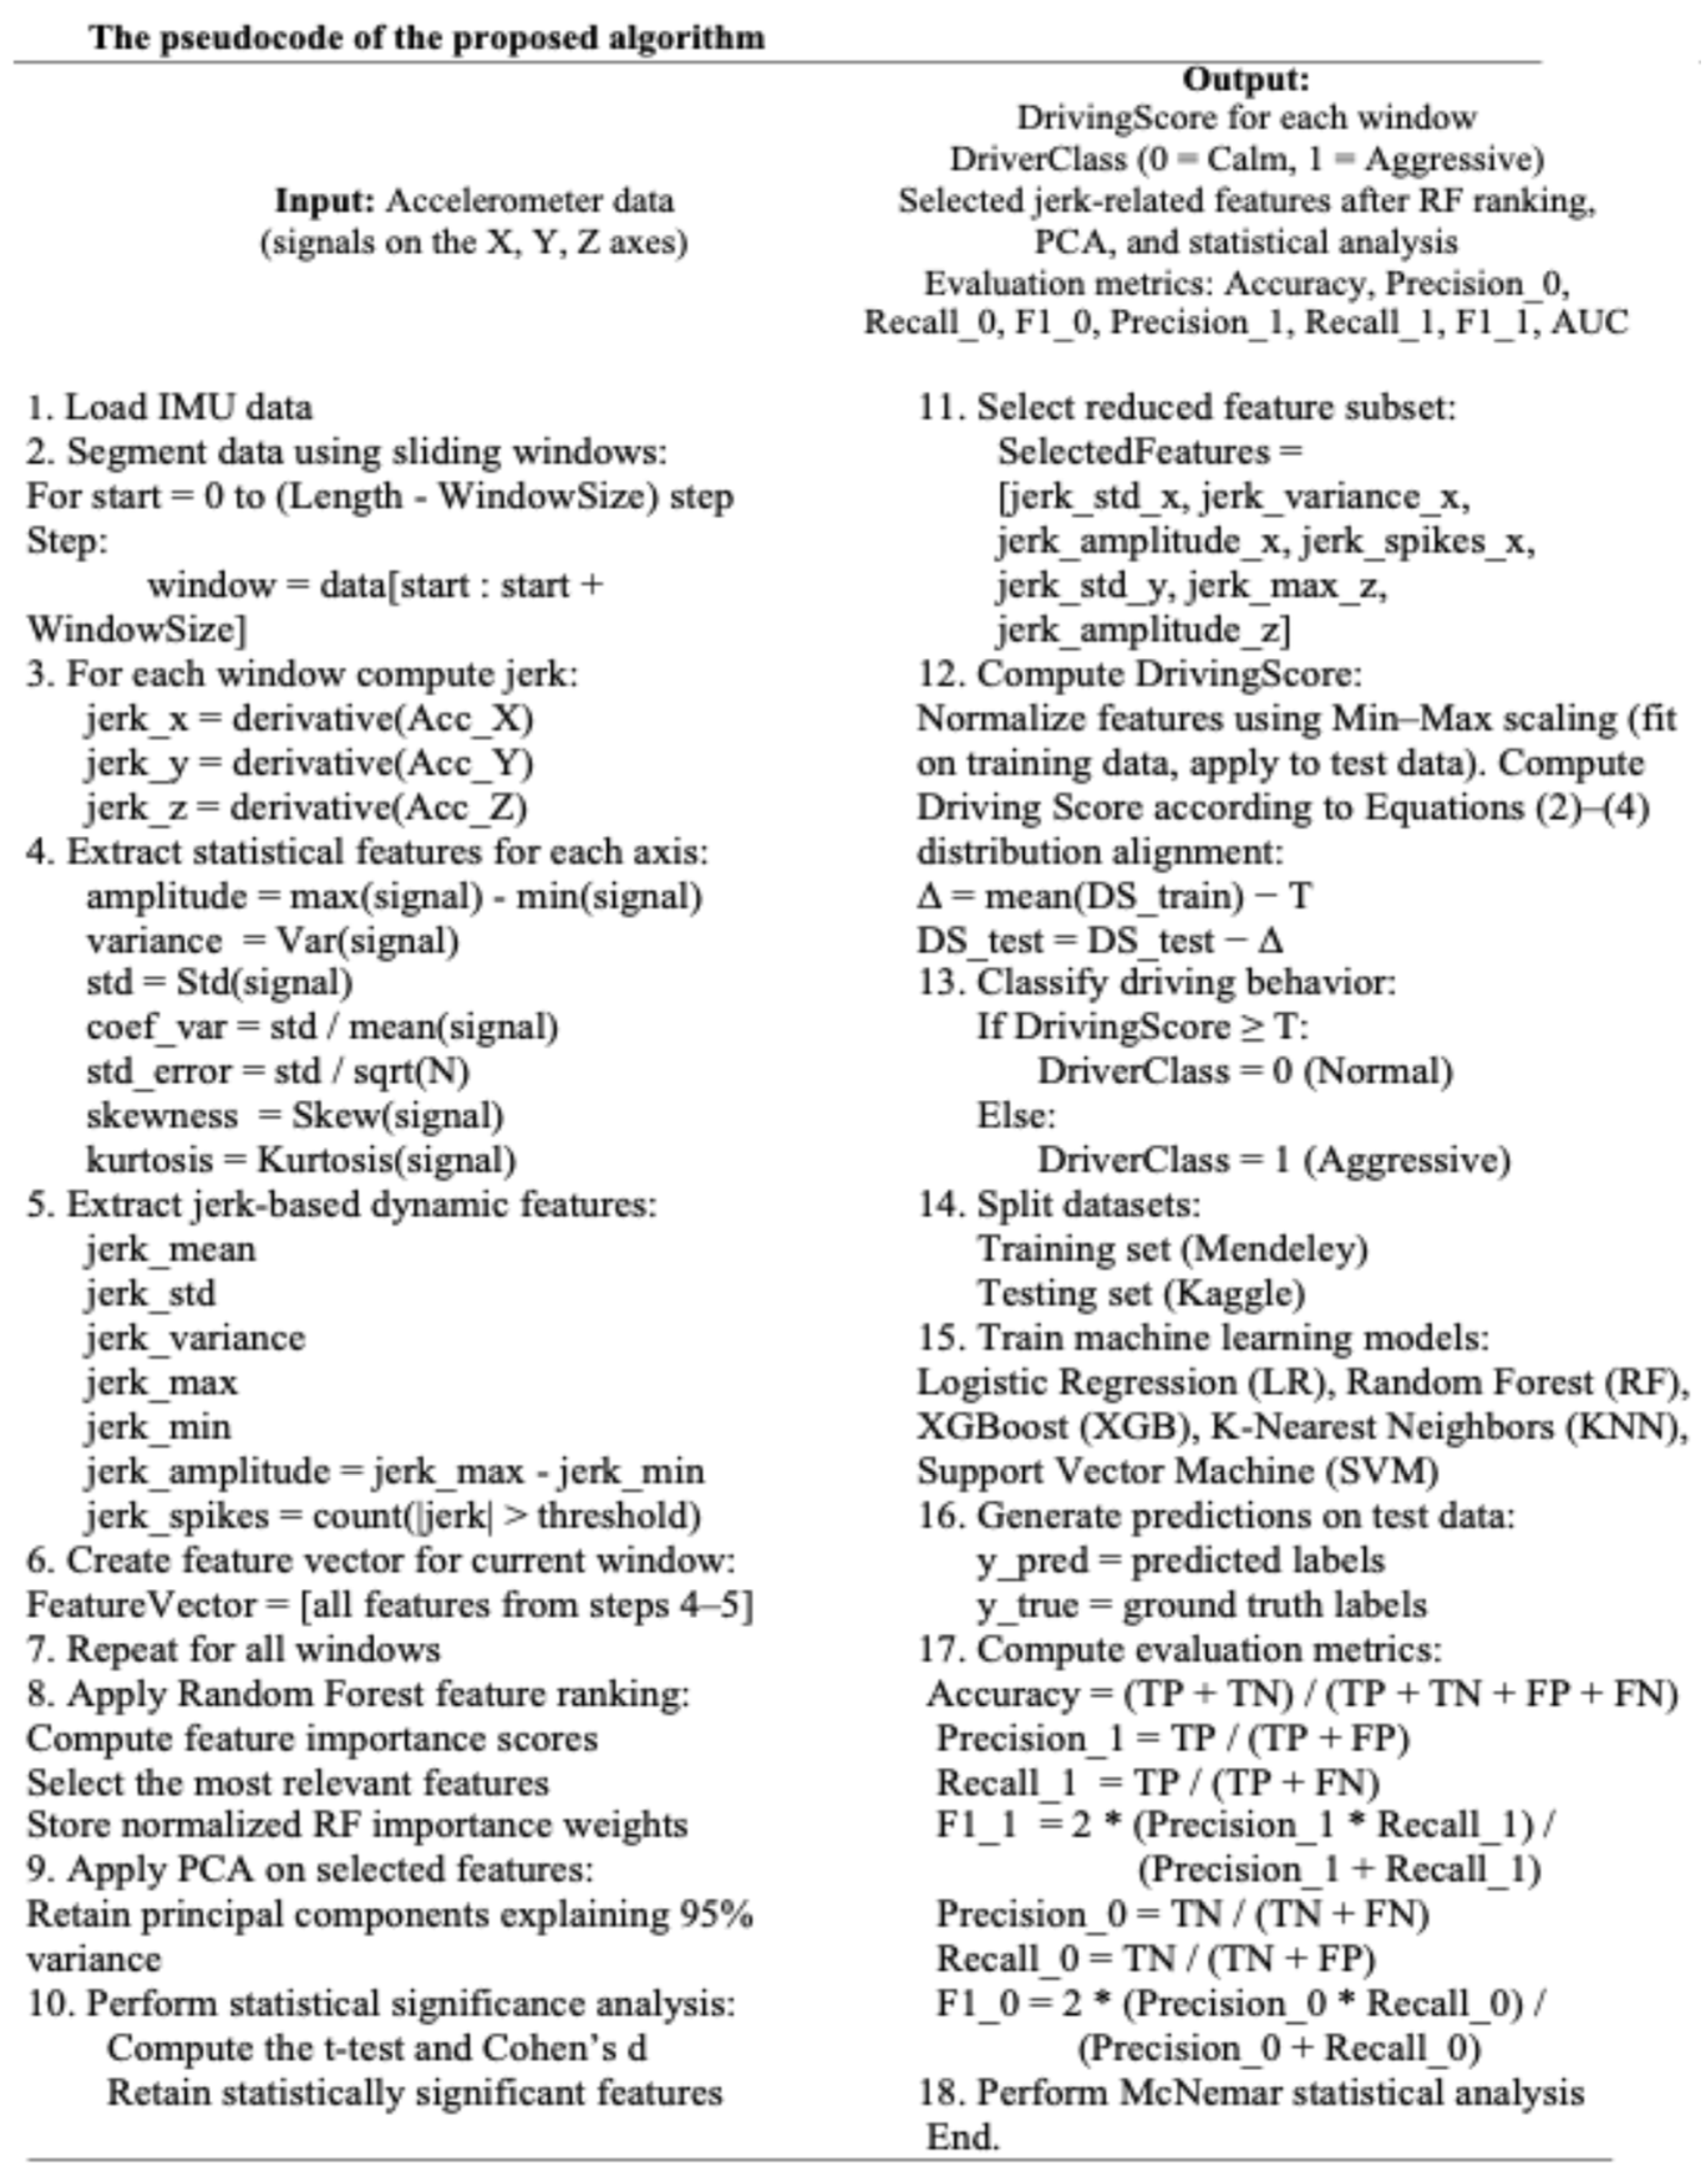
The proposed framework for feature selection and DS computation is shown in Figure 2.
Figure 2.
DS pseudocode and classification step using the baseline models.
3.3. Driving Score
The Driving Score (DS) quantifies driving behavior using normalized jerk-related features extracted from IMU signals. It considers the ‘event scores’ provided by jerk-based features. Following Random Forest feature ranking and statistical significance analysis, only the most discriminative jerk-related descriptors were retained for Driving Score computation. The extracted descriptors are normalized using Min–Max normalization, and a vector of normalized features is defined as:
To improve the discriminative capability of the DS while preserving interpretability, each jerk-related feature is weighted according to its normalized Random Forest feature importance score. The feature weights are computed as . denotes the feature importance of features obtained through Random Forest feature ranking; denotes the feature importance of the feature used for weight normalization, and N is the total number of selected jerk-based descriptors. The RawScore is defined as
The RawScore is converted into a Driving Score defined on the range [0, 100] by the relation:
The Driving Score (DS) captures the full spectrum of dynamic driving conditions, and the proposed score range is as follows (Table 1).
Table 1.
The proposed score range.
Time-series data analysis reveals a wider range of positive jerk dynamics during acceleration than during braking/deceleration. Consequently, to report a stable driving attitude, a threshold of 50 aligns with central tendency and effectively serves as a functional boundary distinguishing between normal and aggressive drivers. Cohen’s d measure characterizes the effect size, i.e., quantifies the magnitude of statistical significance difference in standard deviation units, by relating the mean difference to variability.
A large Cohen’s d value indicates the mean difference/effect size is large compared to the data’s variability. Essentially, the difference between normal and aggressive drivers is not only real but also significant.
The interpretation of the Cohen’s d measure is as follows: small (0.2), medium (0.5), and large (0.8) [30].
3.4. Statistical Tests
To evaluate the baseline classifiers’ ability to make accurate predictions when the jerk-based features are used to distinguish between normal and aggressive drivers, the McNemar statistical test was utilized. McNemar’s test is useful when multiple classifiers are evaluating the same test samples. It directly investigates discordant classifications by examining paired prediction conflicts between different classifiers rather than focusing on overall accuracy:
where n01 is the number of samples correctly classified only by the model A and misclassified by the compared baseline model B; n10 is the number of samples correctly classified only by the compared baseline B classifier and misclassified by A.
4. Experimental Results
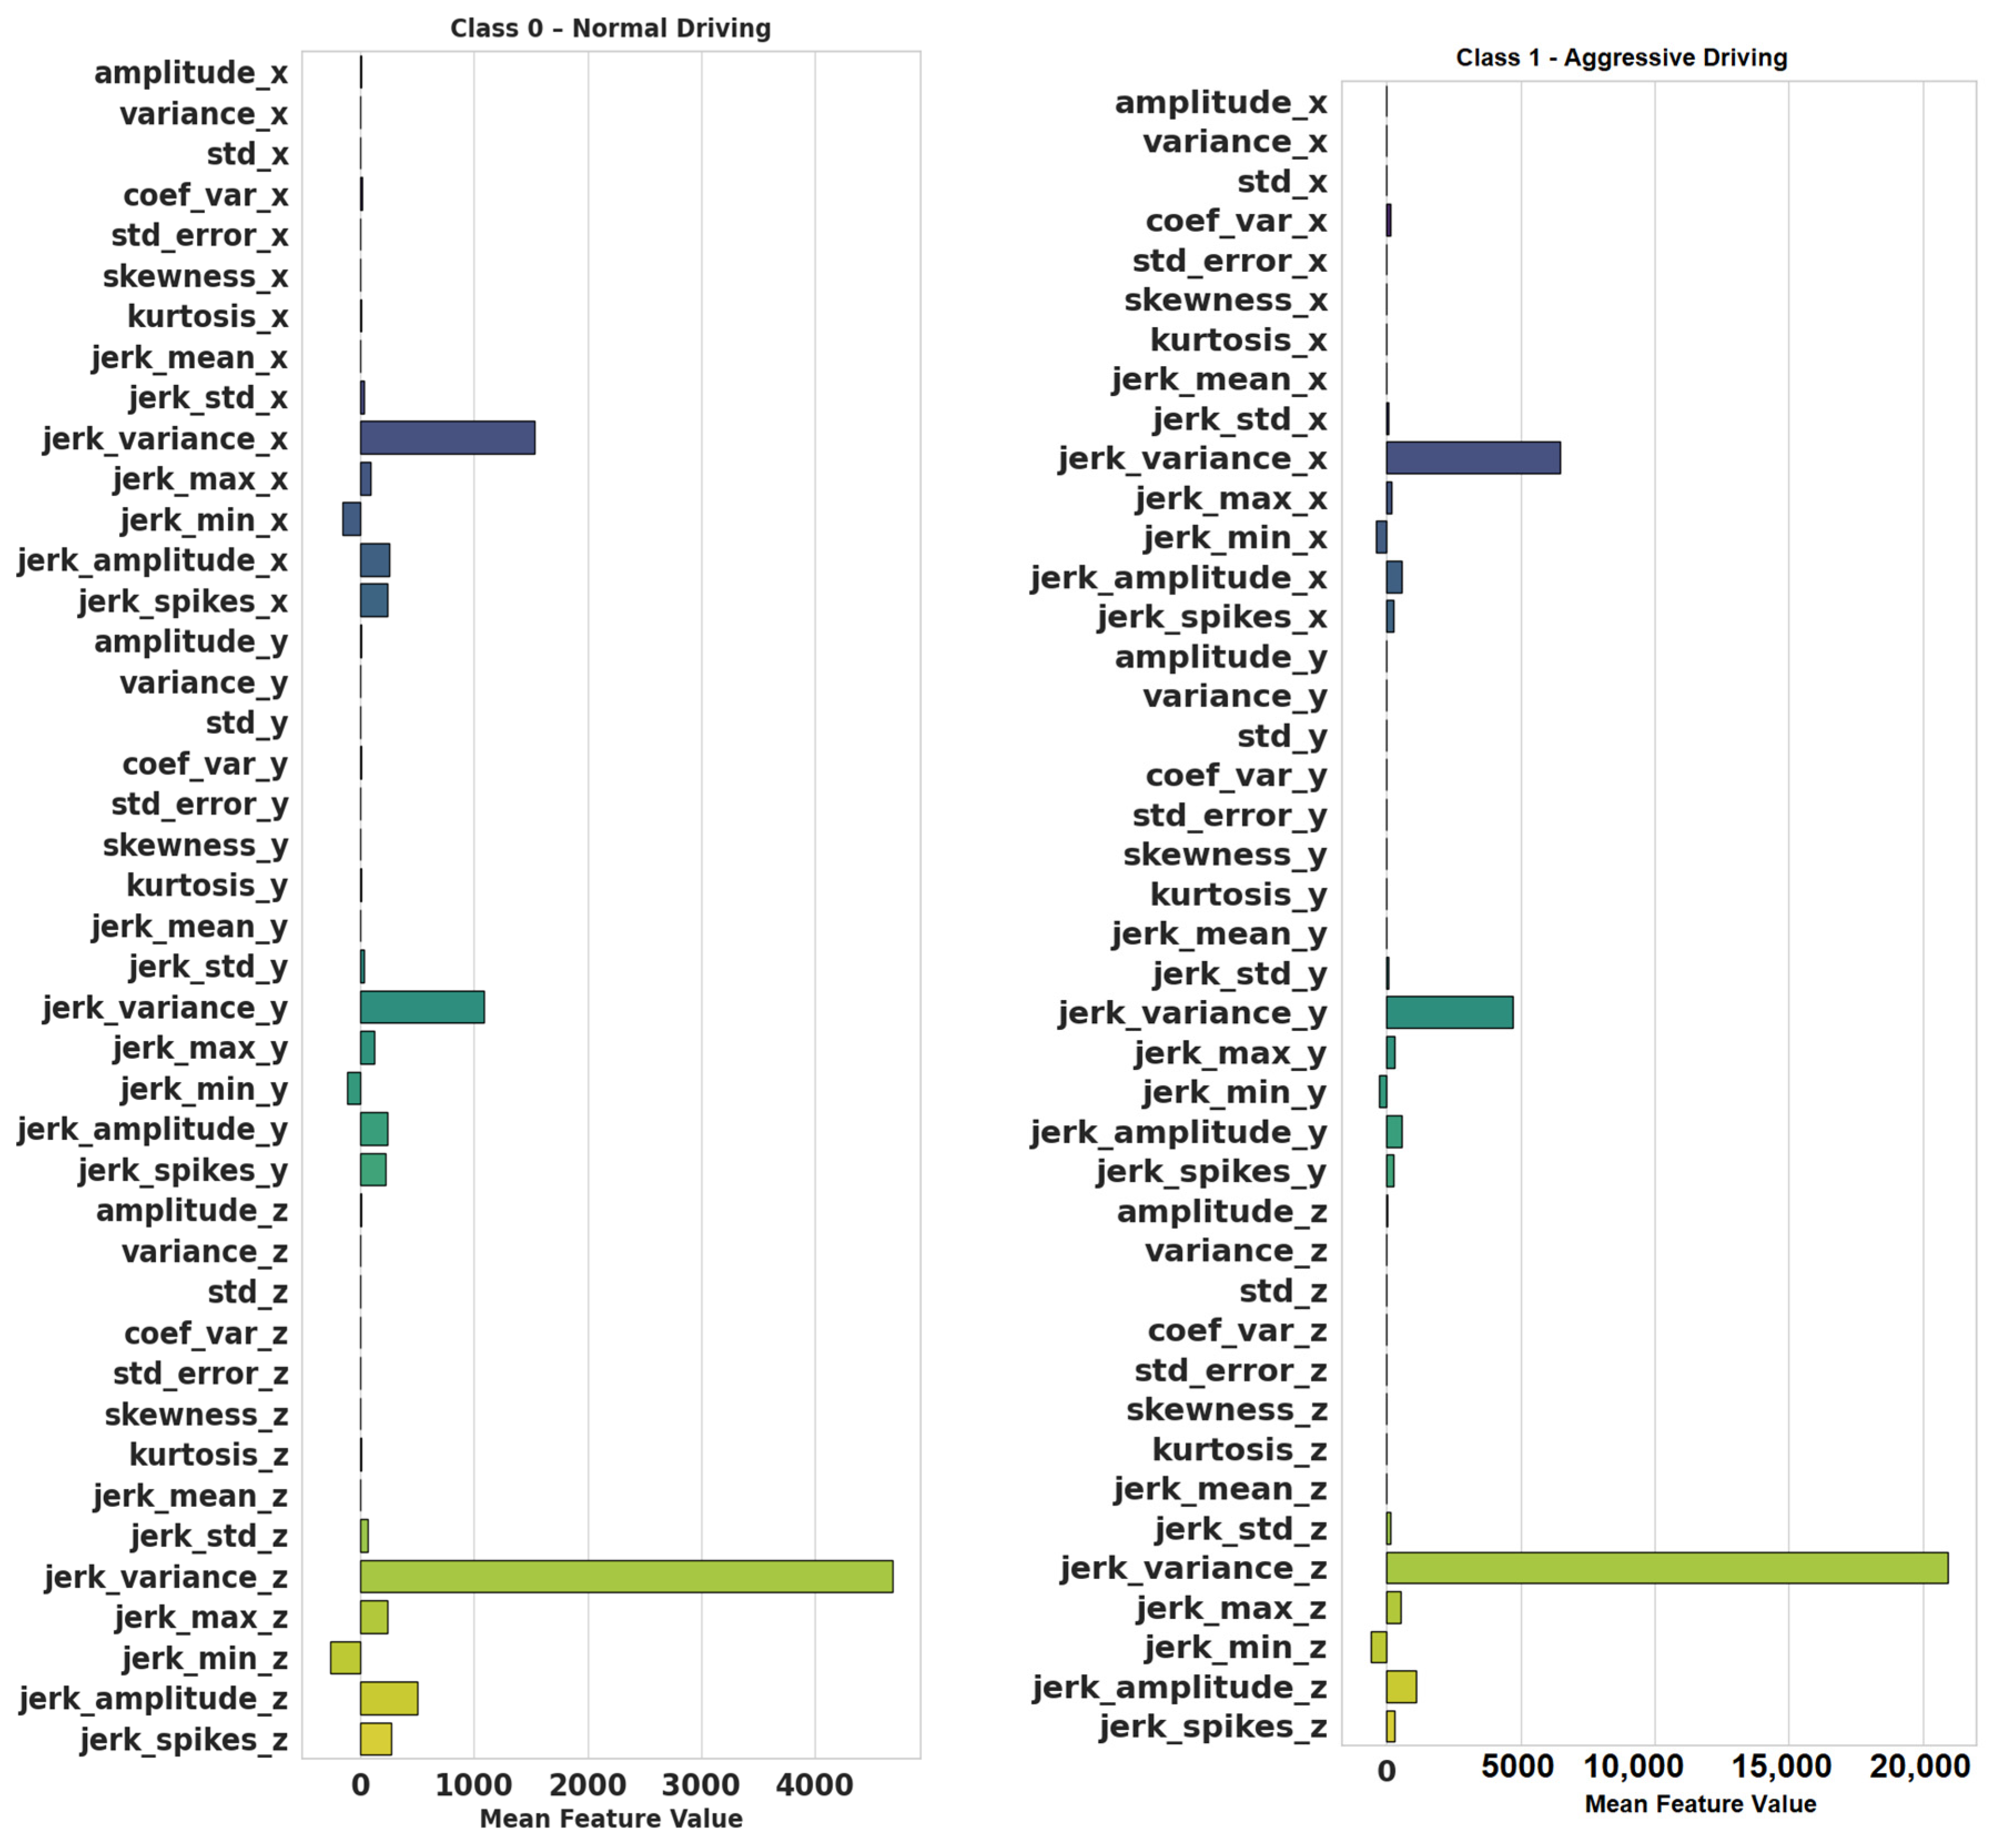
The experimental results from applying the proposed Driving Behavior Scoring framework to the IMU dataset are used to explore statistical differences between calm and aggressive driving windows. This includes examining the dynamic behavior captured by jerk-based indicators and assessing the Driving Score’s effectiveness in distinguishing between the two classes. In a first step, both datasets provide 42 features. For the Mendeley dataset, the feature importance is shown in Figure 3.
Figure 3.
Feature importance of the DBS model for the Mendeley dataset. The analysis of the 42 IMU signal features shows that jerk dynamics effectively distinguish between classes 0 and 1, while the classical statistics feature fails. For example, jerk_variance_x and jerk_variance_y make major contributions to both classes, while jerk_variance_z significantly contributes to class 0.
The 42 IMU signal features reveal that jerk dynamics clearly separate classes 0 and 1. The top three most predictive features for normal driving style are: jerk_variance_z (4684.14), jerk_variance_x (1535.74), and jerk_variance_y (1090.73). The top three most predictive features for aggressive driving style are: jerk_variance_x (6465.34), jerk_variance_y (4707.68), and jerk_amplitude_x (587.82). They indicate increased instability and irregularity in the motion patterns. Significant changes in acceleration occur during aggressive driving. Shock intensity and frequency indicators follow similar patterns. These increases suggest class 1 segments have more abrupt, irregular, high-intensity dynamics than class 0. As an example, jerk_amplitude_z rises from 503.06 (class 0) to 1109.63 (class 1). Furthermore, in the class 1 case, jerk_mean_x and jerk_mean_z are consistently higher, indicating dynamic activity during aggressive driving.
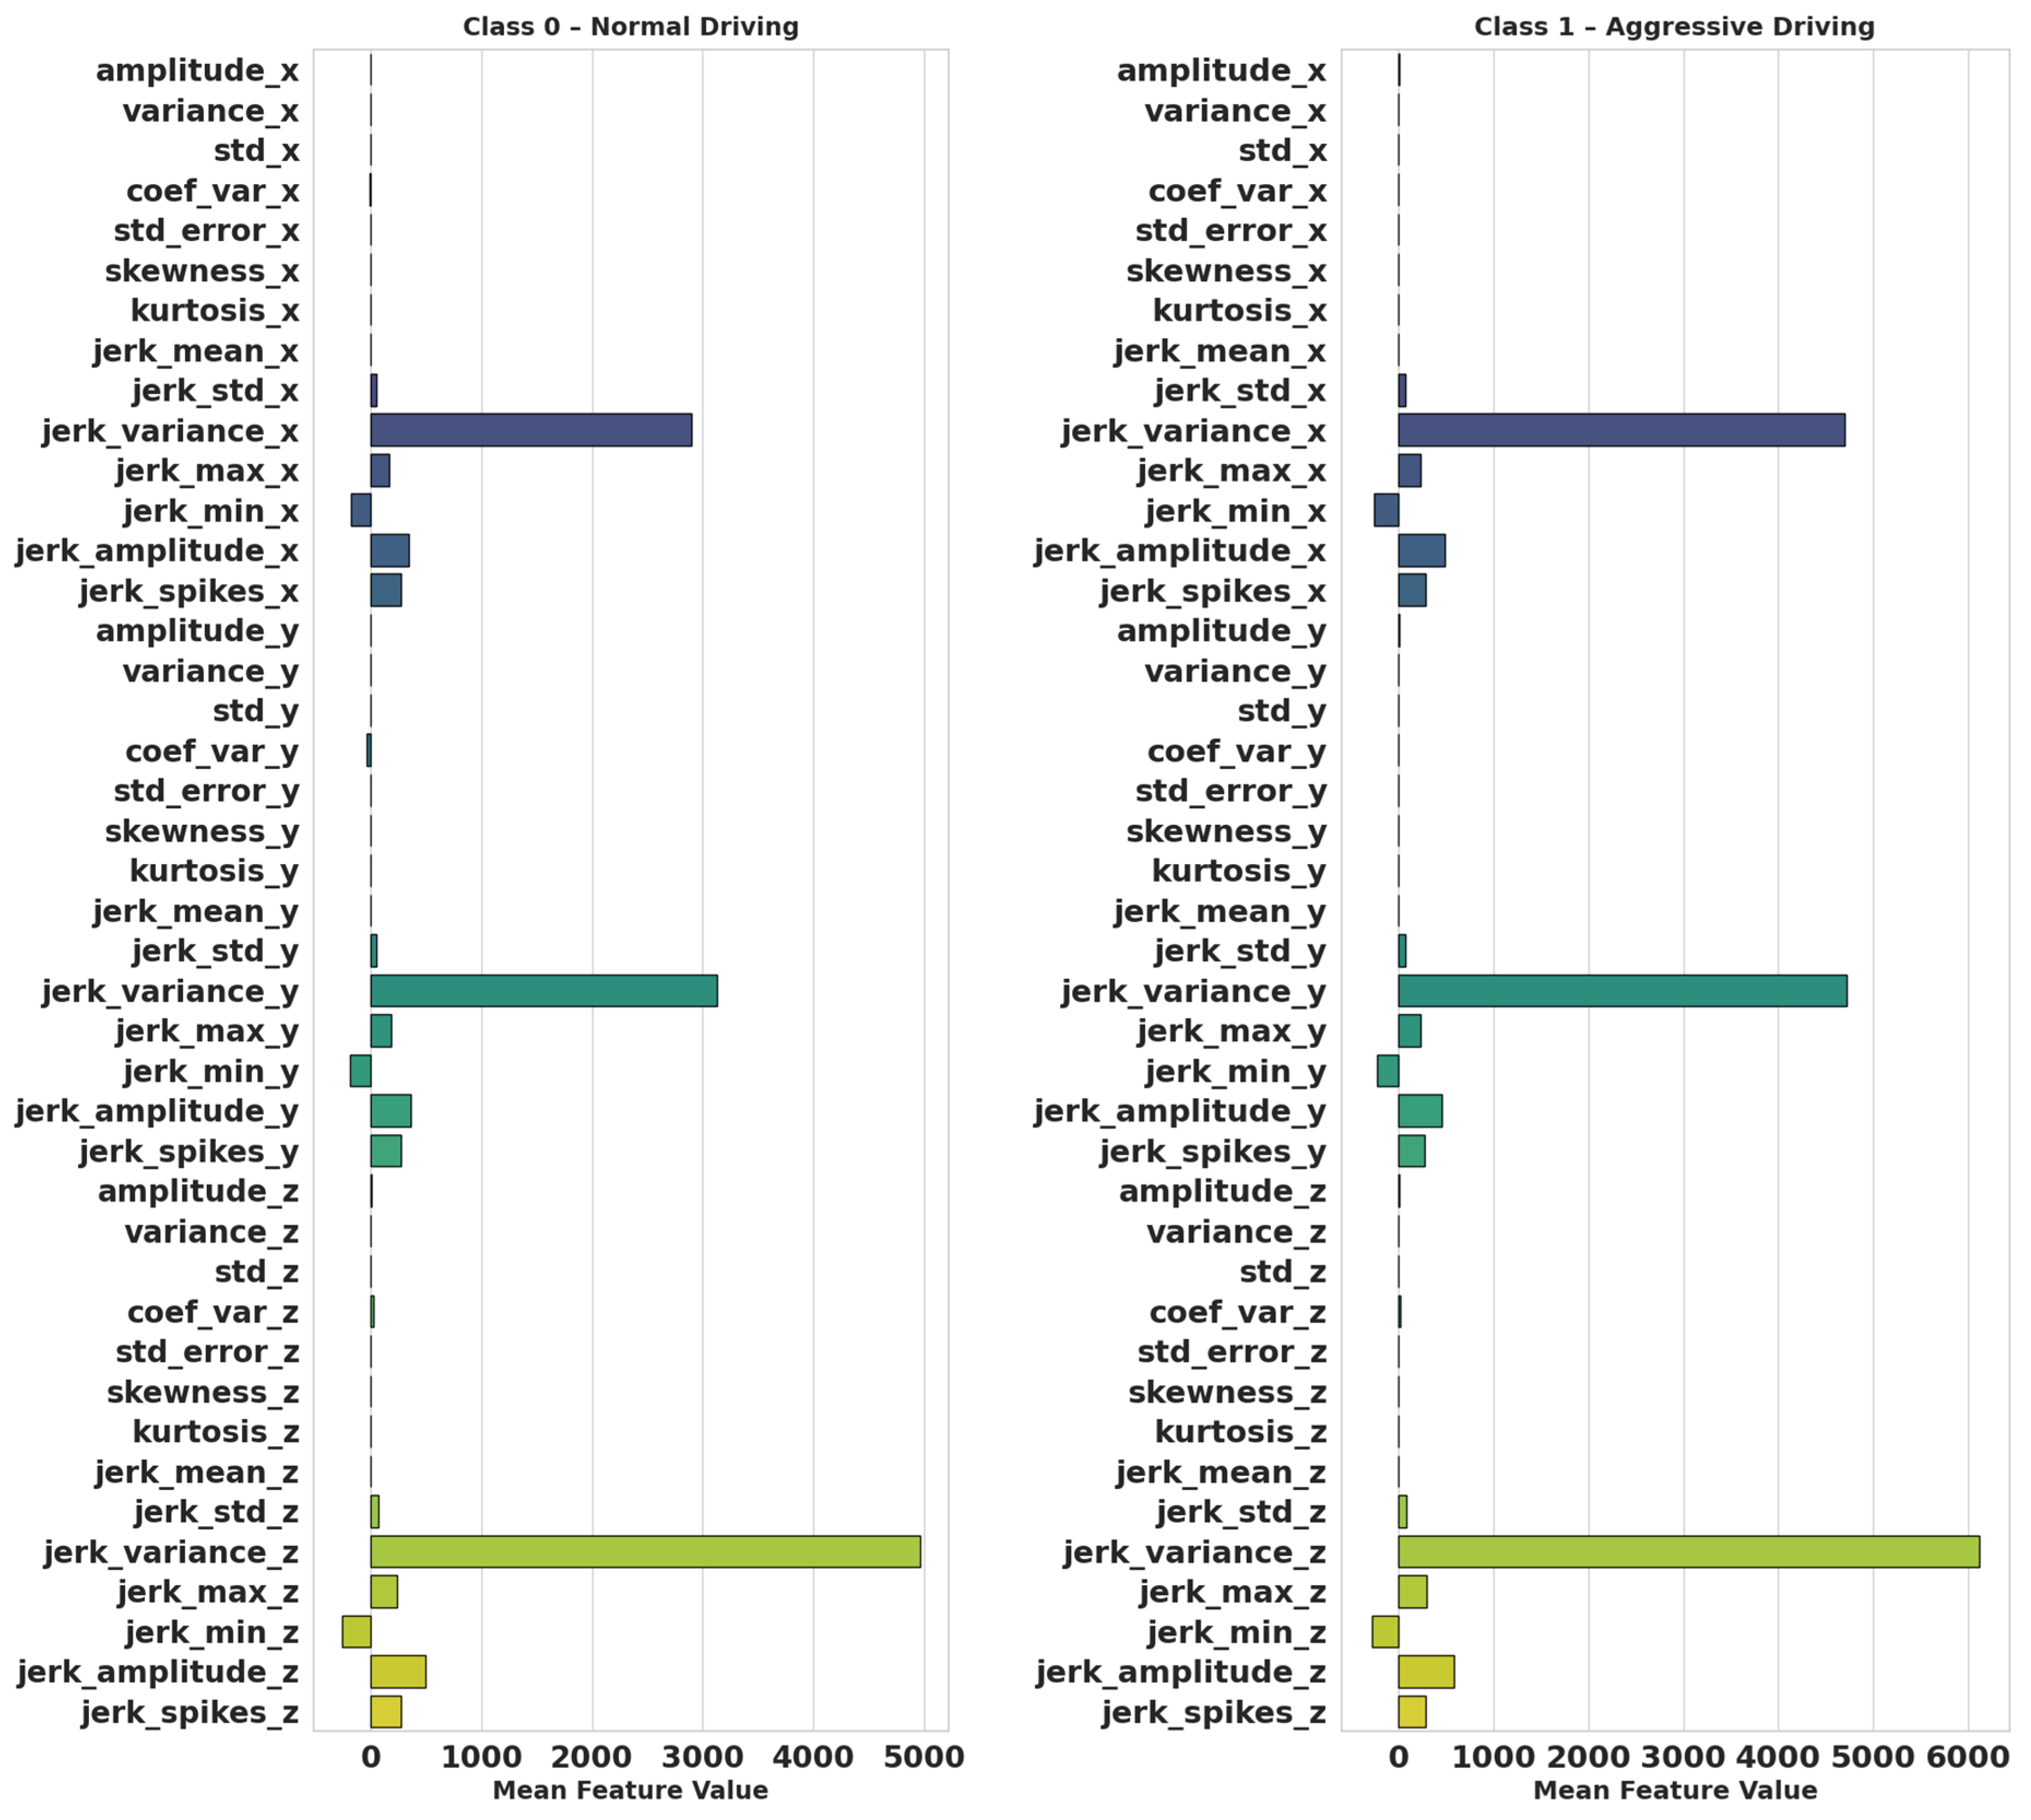
For the Kaggle dataset, the extracted statistical descriptors are presented in Figure 4. The top three most predictive features for normal driving style are: jerk_variance_z (4957.69), jerk_variance_x (2897.64), and jerk_variance_y (3129.72). The top three most predictive features for aggressive driving style are: jerk_variance_z (6118.22), jerk_variance_y (4724.43), and jerk_ variance_x (4701.71). These differences are quite evident, demonstrating a clear distinction between the two driving styles. Similarly, jerk_min_x ranges from −178.25 (class 0) to −259.05 (class 1) while jerk_min_y varies from −179.62 to −222.58 and jerk_min_z from −252.68 to −283.08. This suggests braking events are becoming more forceful.
Figure 4.
Feature importance of the BDS model for the Kaggle Driving Behavior Dataset. The analysis of the 42 IMU signal features shows that jerk dynamics effectively distinguish between classes 0 and 1, while the classical statistics feature fails. For example, most balanced contributions of jerk_variance_x, jerk_variance_y, and jerk_variance_z are observed for both classes.
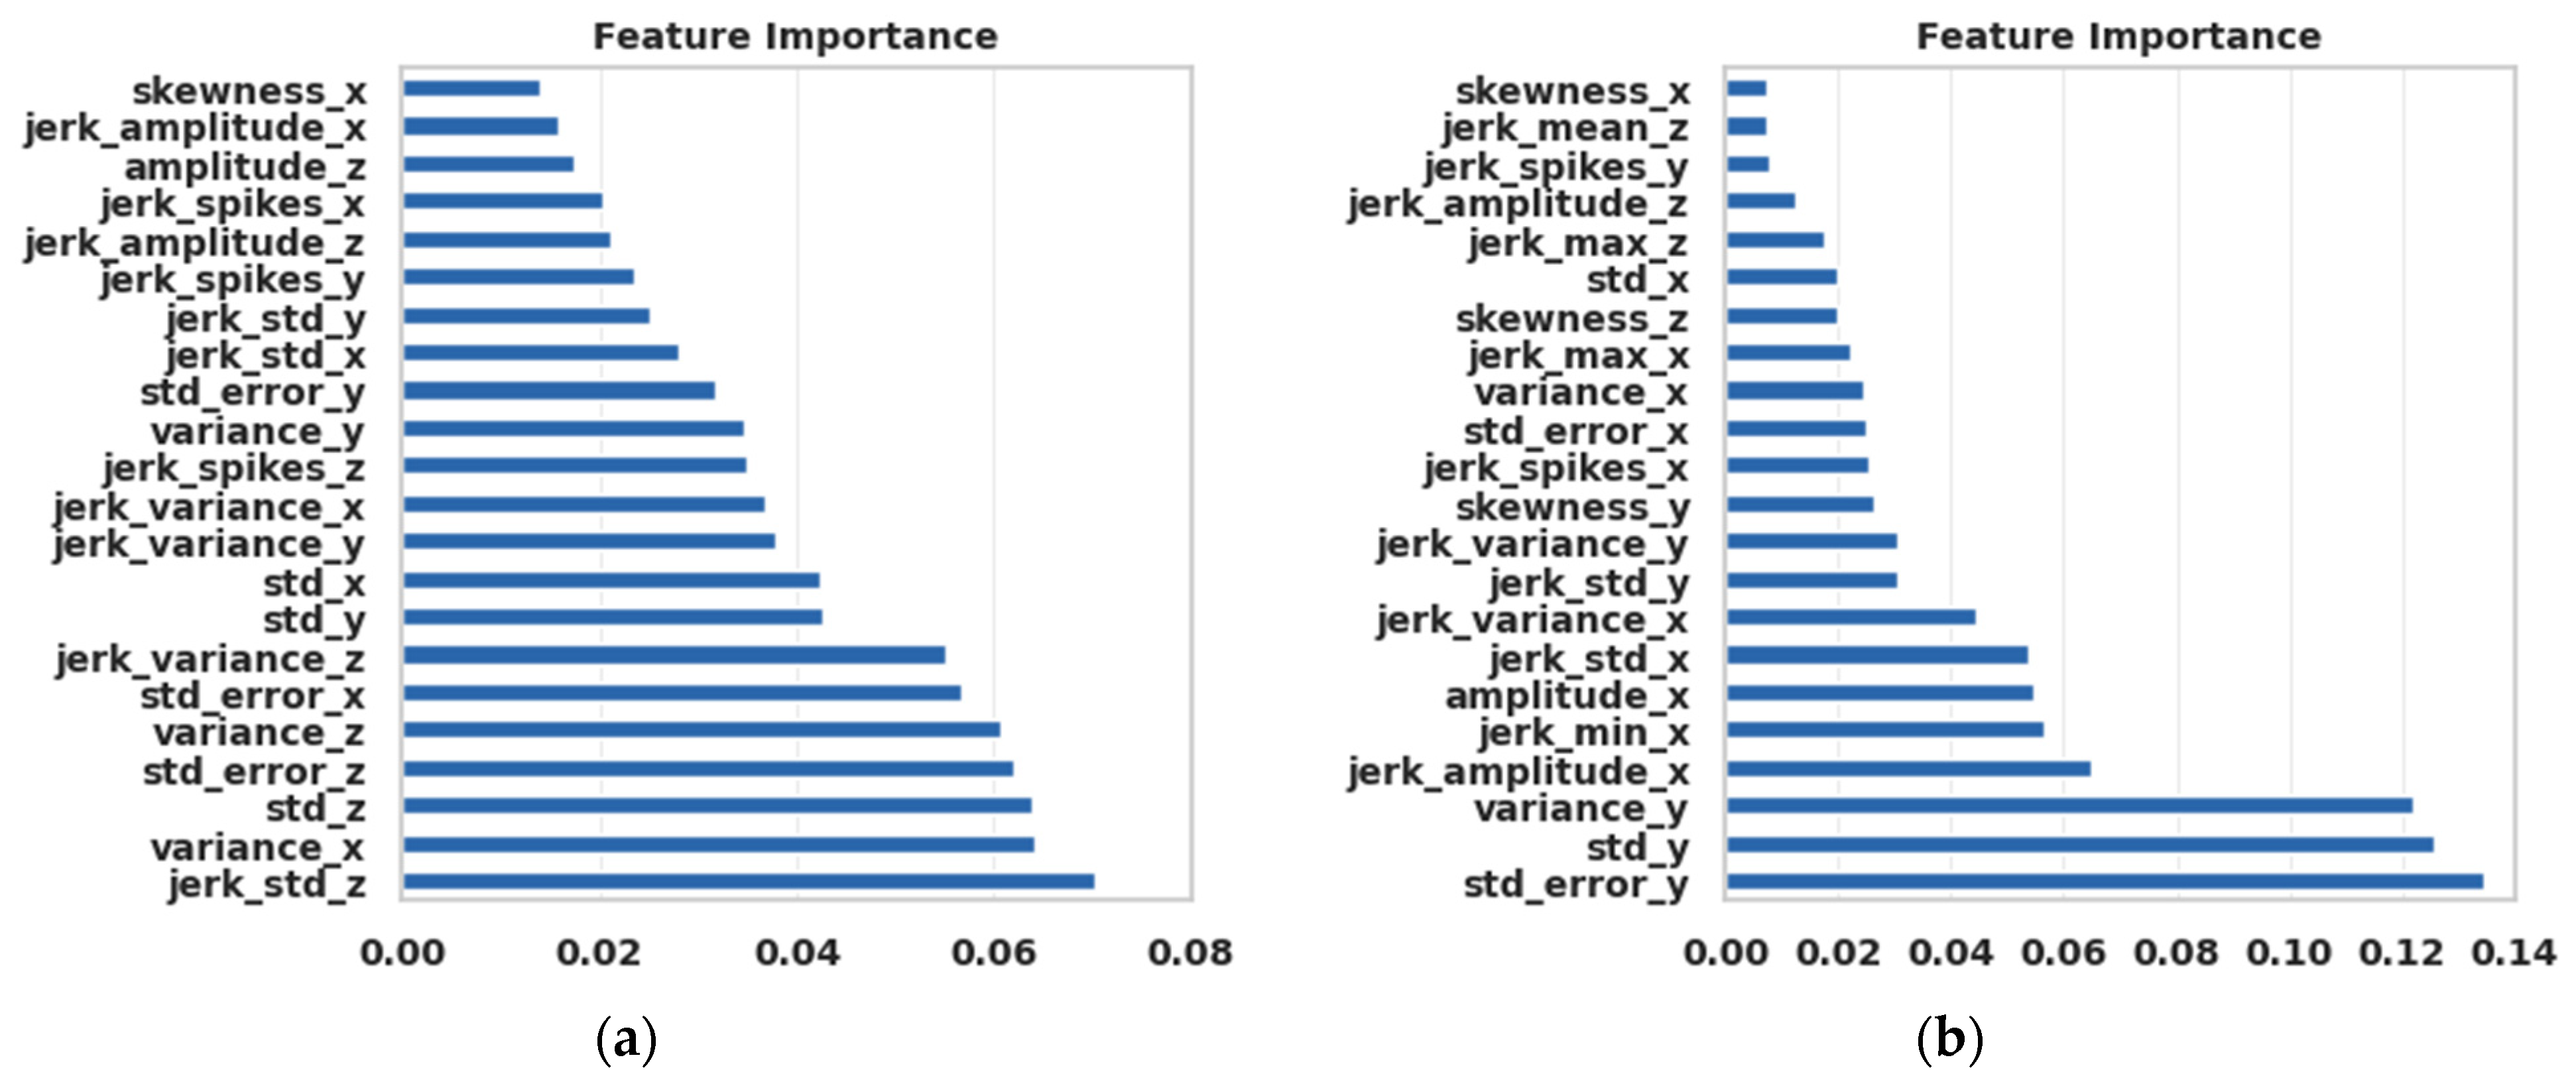
Following the comparative evaluation described above and illustrated in Figure 3 and Figure 4, we employed the Random Forest (RF) and Principal Component Analysis (PCA) to select the top-performing features from all 42 analyzed. Figure 5 shows the ranking of IMU characteristics for classification, based on the RF feature priority ranking. Thus, RF selects only 22 meaningful features.
Figure 5.
The most important IMU characteristics for classification, based on the Random Forest feature priority ranking: (a) for the Mendeley dataset; (b) for the Kaggle Driving Behavior Dataset.
Many statistical features and jerk-based features could be correlated. This correlation introduces redundancy, which inflates the number of statistical tests. To mitigate this, Principal Component Analysis (PCA) was applied to reduce the dimensionality.
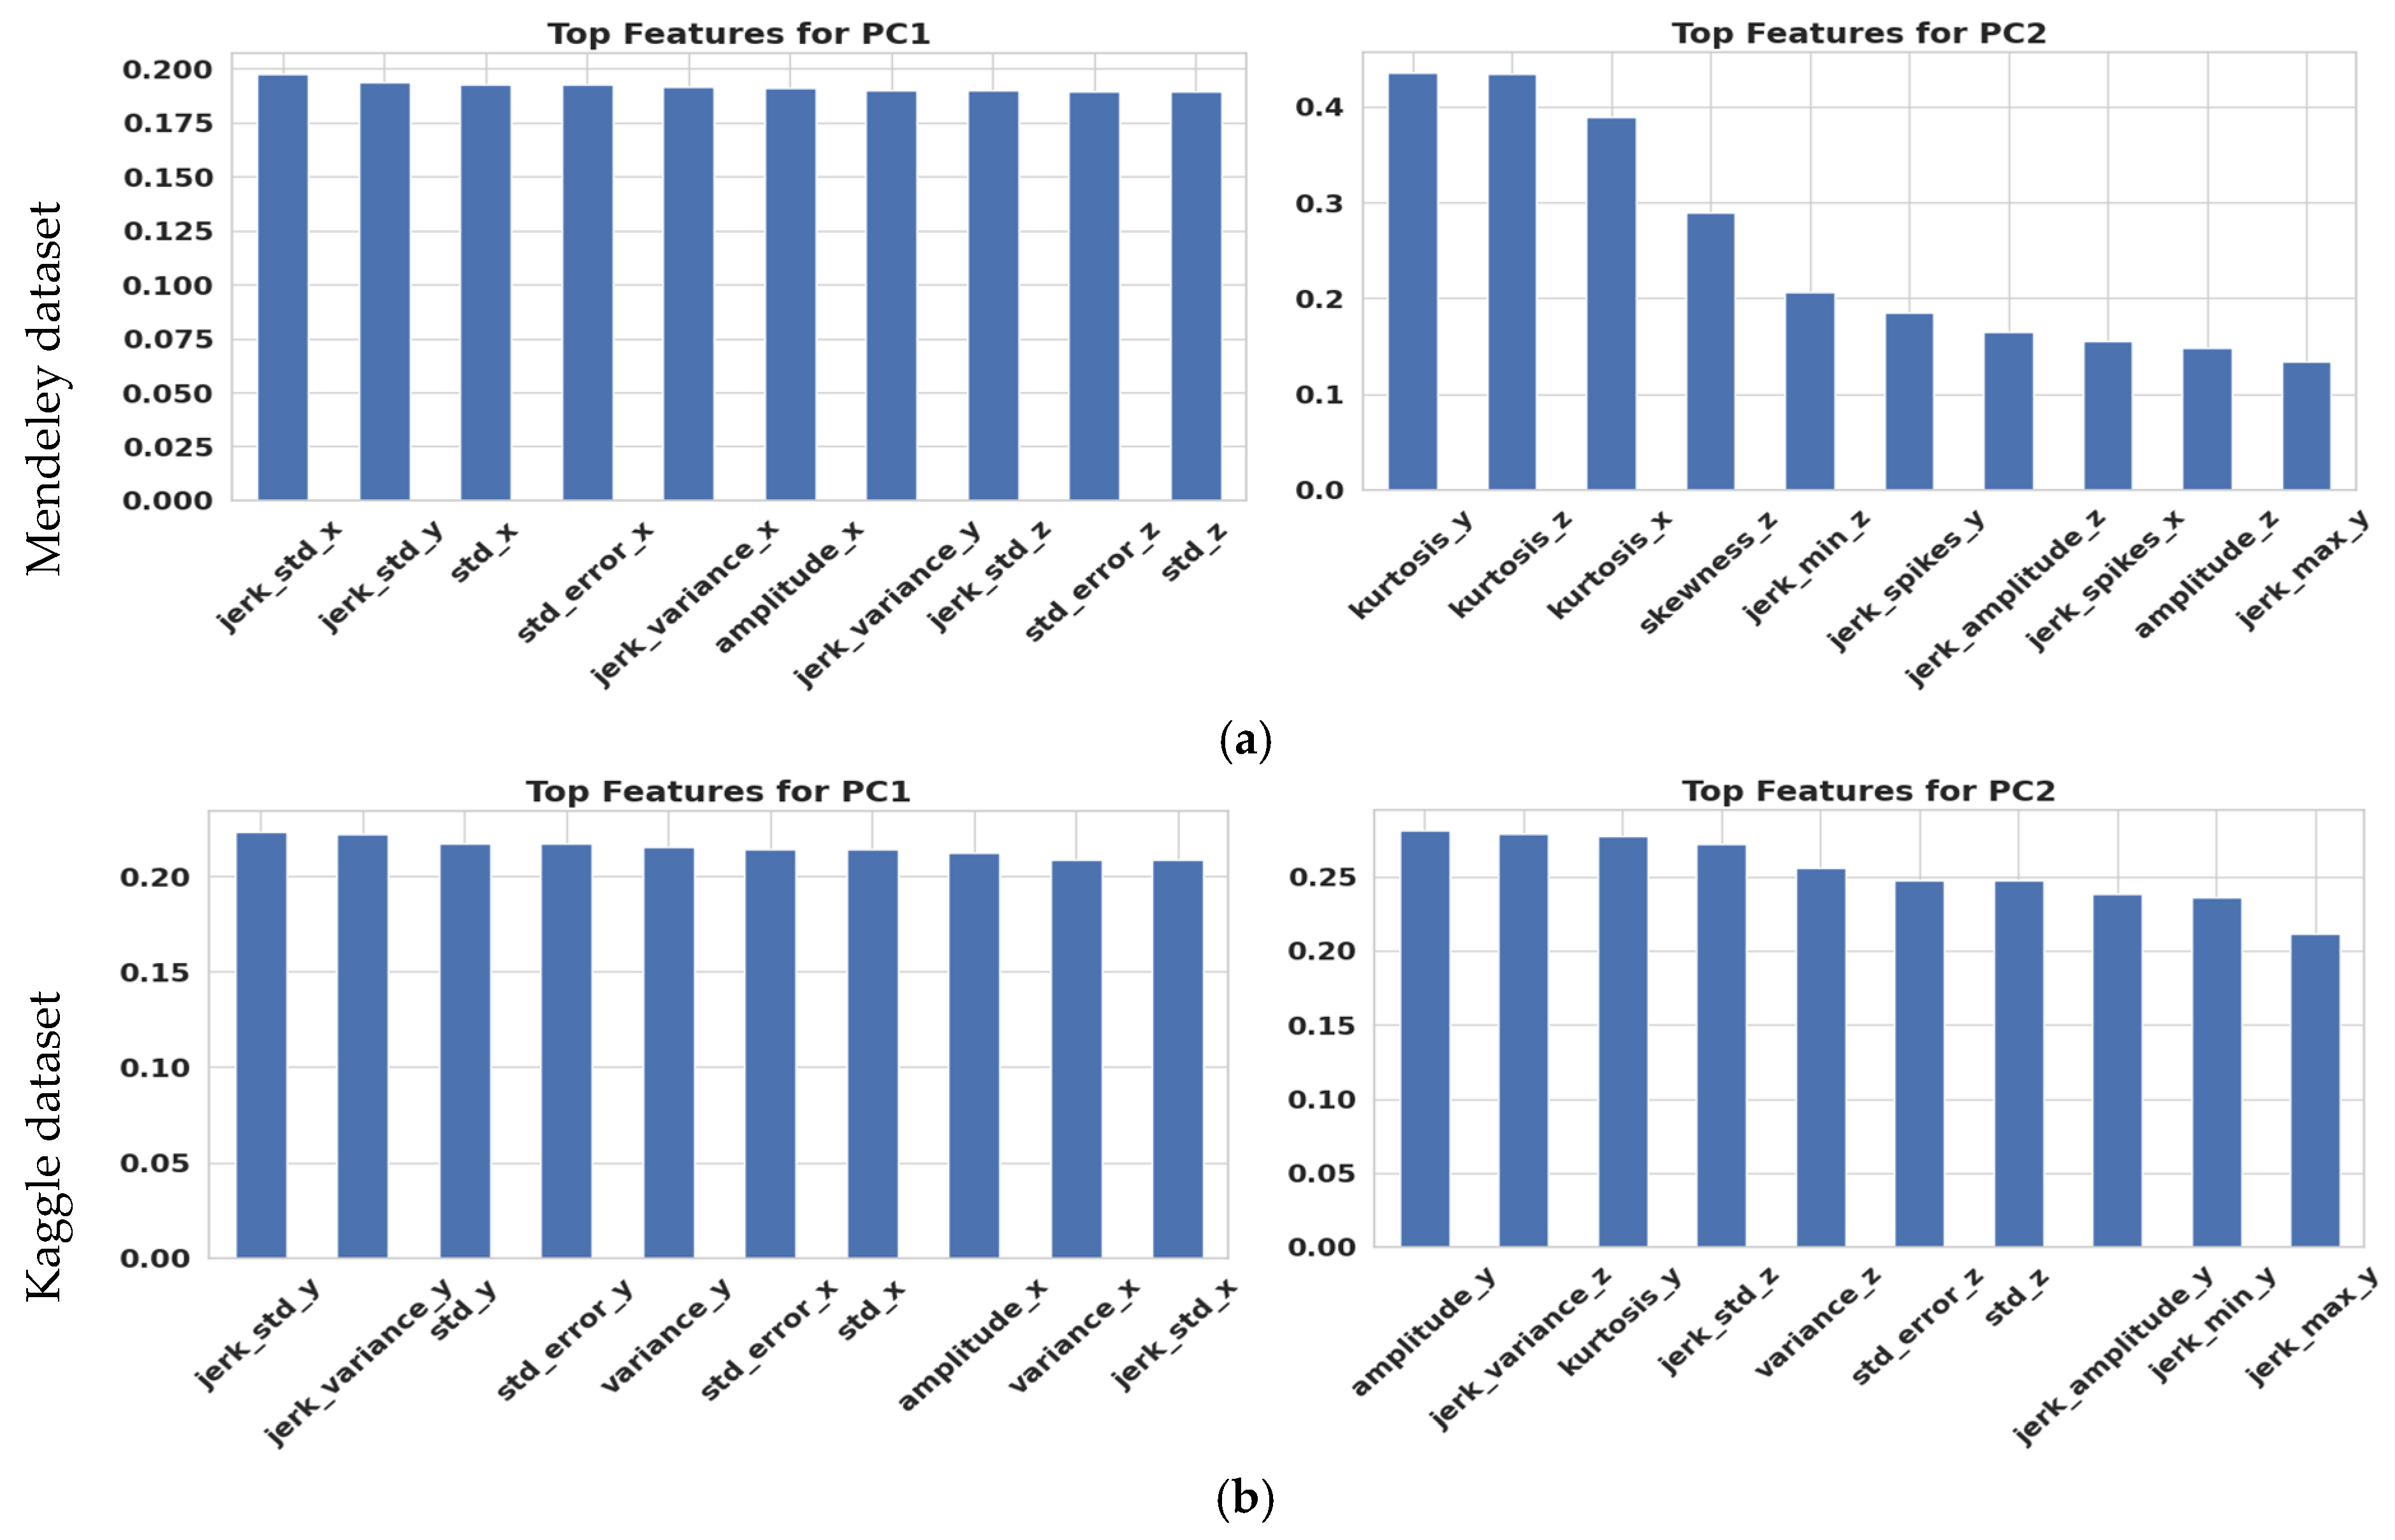
Further, to compare the robustness of the feature selection process, the PCA results for the first two principal components, PC1 (the direction capturing the maximum variance in the data) and PC2 (which captures the next highest variance while being perpendicular (orthogonal) to PC1), are shown in Figure 6.
Figure 6.
The first two principal components, PC1 and PC2, show the feature importance. (a) for the Mendeley dataset, with the following loading range PC1 [0.185–0.192] and PC2 [0.123–0.477]; (b) for the Kaggle Driving Behavior Dataset, with the following loading range PC1 [0.208–0.223] and PC2 [0.208–0.280].
These components retain 95% of the variation for both datasets. We can observe that PC2 for data in the Mendeley dataset shows a higher loading range (or a larger spread in loading values) than PC1. The loading range indicates how spread out the coefficients of the original features are on that component. Among the selected features, we find jerk-based features alongside other statistical features. These results confirm the discriminative power of jerk-based features and support our decision to focus solely on them in this analysis. Statistical tests were then performed only on these uncorrelated components, thereby eliminating redundancy and preventing multiple-comparison inflation. A statistical analysis using t-tests is performed on selected features, separately for each dataset (Table 2 and Table 3). The statistics in Table 2 show that the two classes differ significantly, particularly in jerk qualities. Classes 0 and 1 show substantial differences, with p-values < 10−15 and Cohen’s d > 2.0. This shows jerk-based signals are a useful indicator of drivers’ behavior. Using p-values (p < 0.05), impact sizes (|Cohen’s d| > 0.8), and category relevance (importance > 0.01), we confirm the soundness of the selected 22 relevant features. For all features, the distributions for Class 1 (aggressive driving) are consistently shifted toward higher values and exhibit much greater variability than those for Class 0. The t-test results confirm the relevance of these indicators in identifying the vehicle’s dynamic instability, reinforcing the class separation. Eleven of the 22 selected features are jerk-based.
Table 2.
The average values of the most relevant features based on t-test and Cohen’s d results for the Mendeley dataset.
Table 3.
The average values of the most relevant features based on t-test and Cohen’s d results for the Kaggle Driving Behavior Dataset.
The repeated statistically significant differences (p < 0.05) in the Kaggle dataset (Table 3) demonstrate a statistically significant difference between the two classes. Also, the practical significance is conveyed through effect sizes, as large Cohen’s d values exist. In the Kaggle dataset case, ten of the 22 selected features are jerk-based.
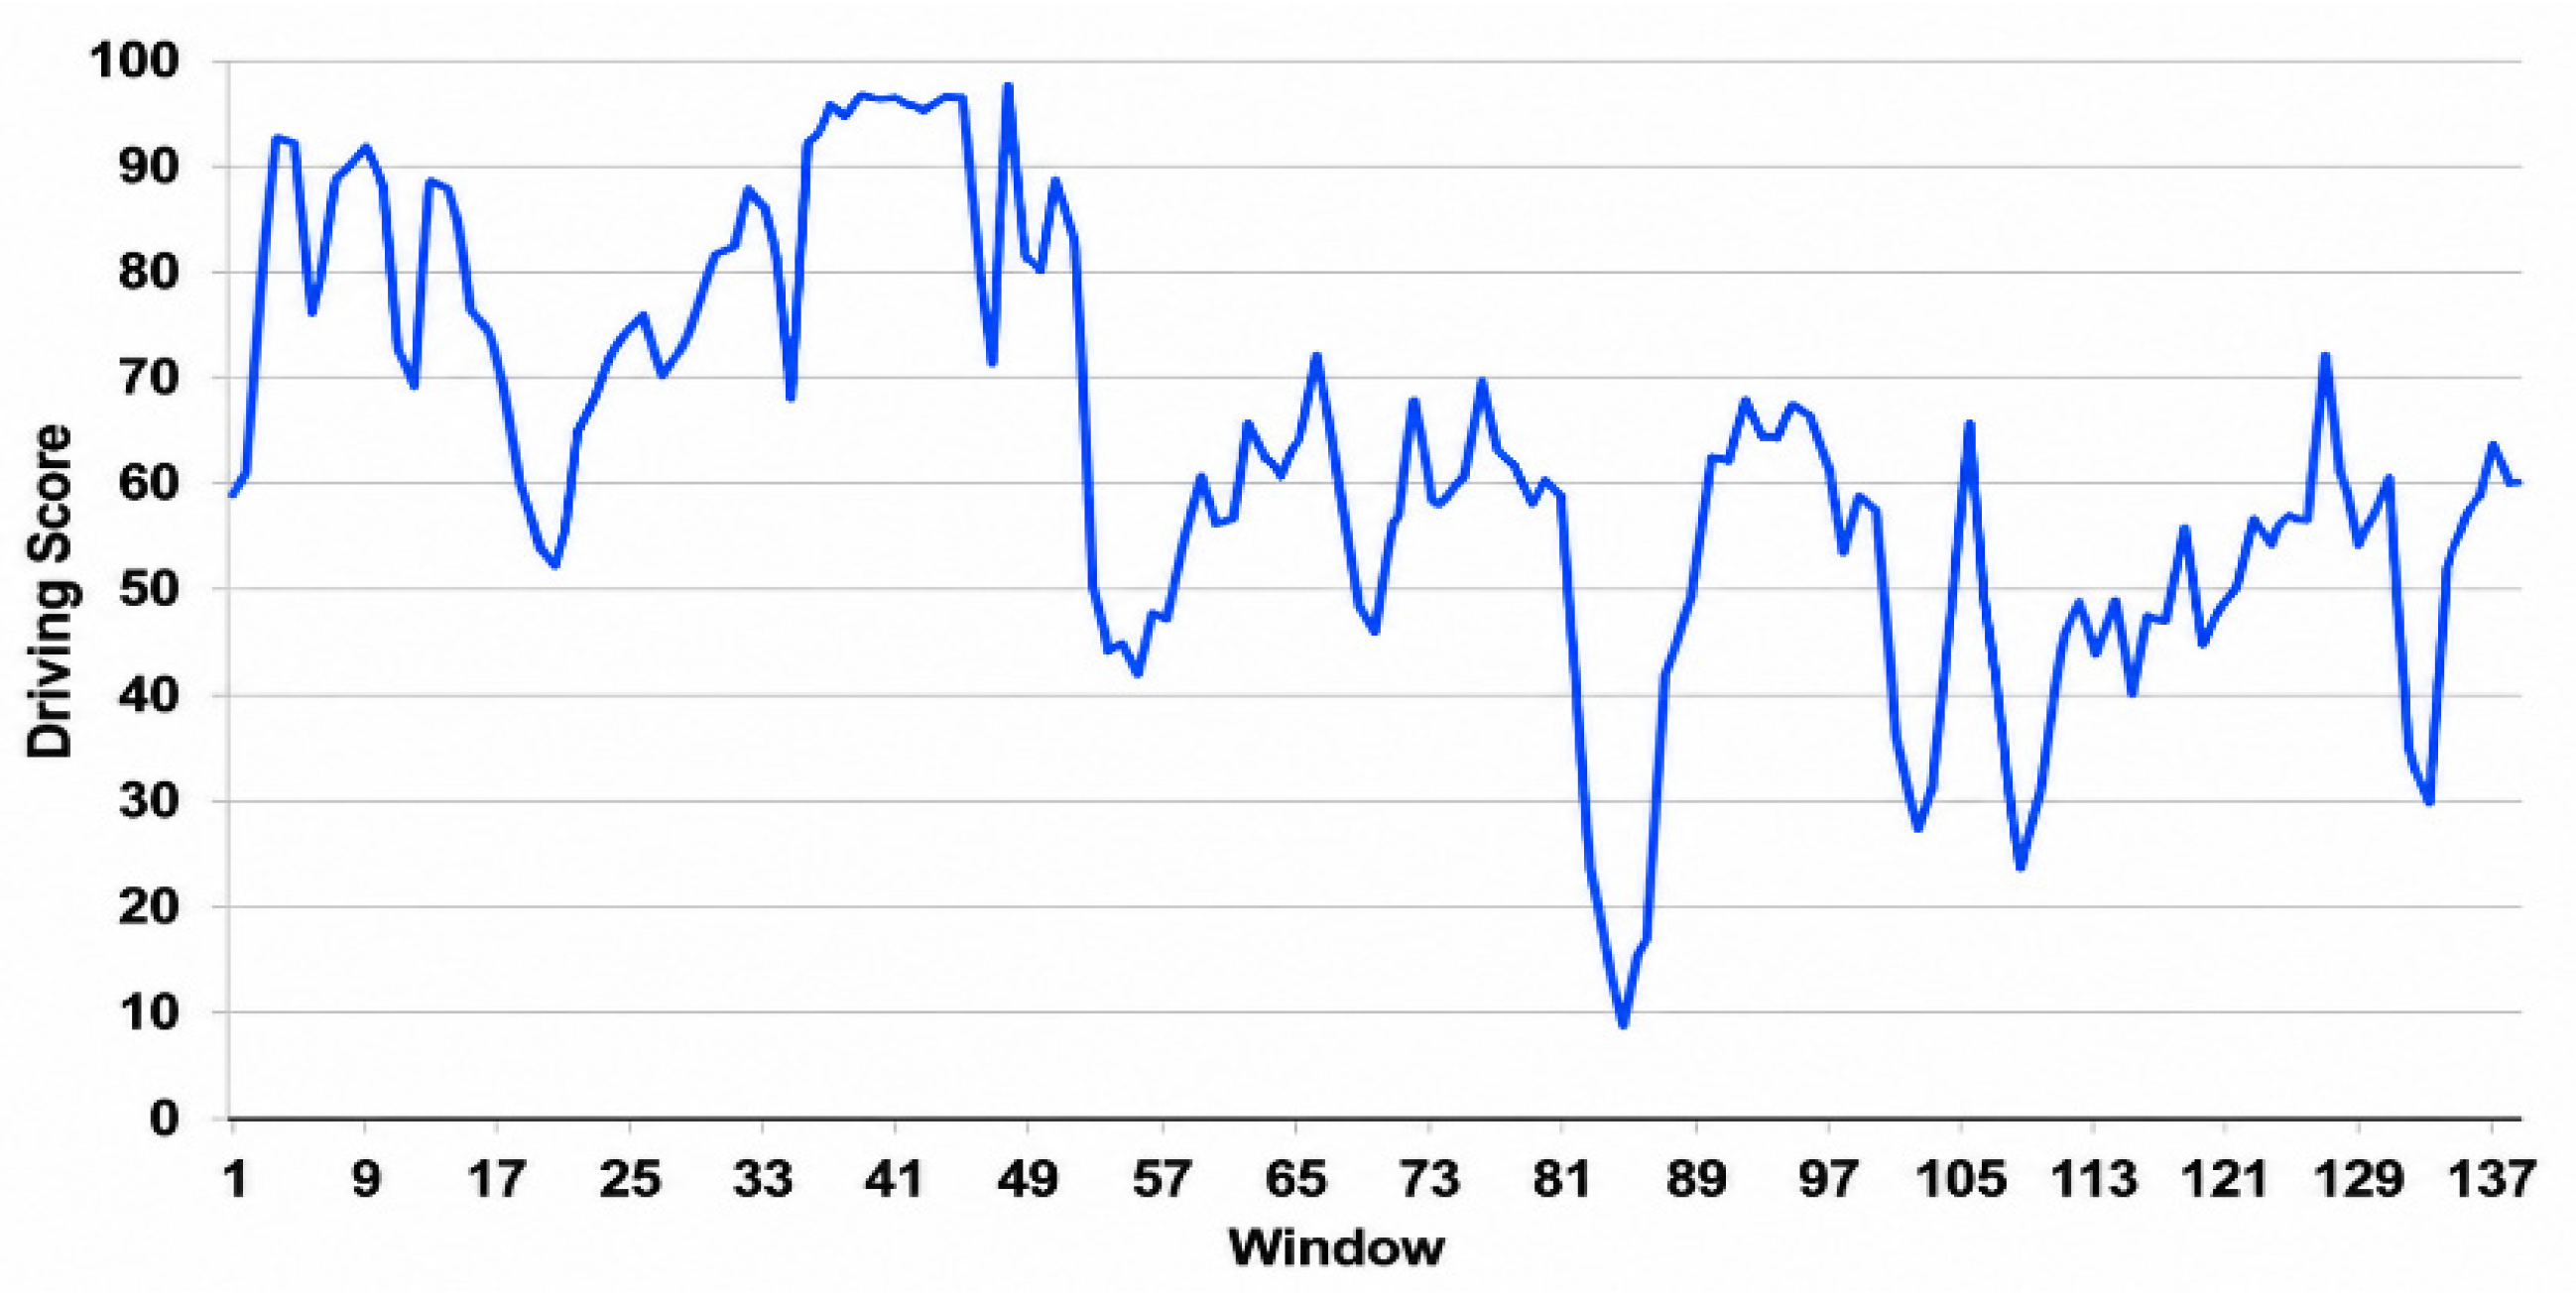
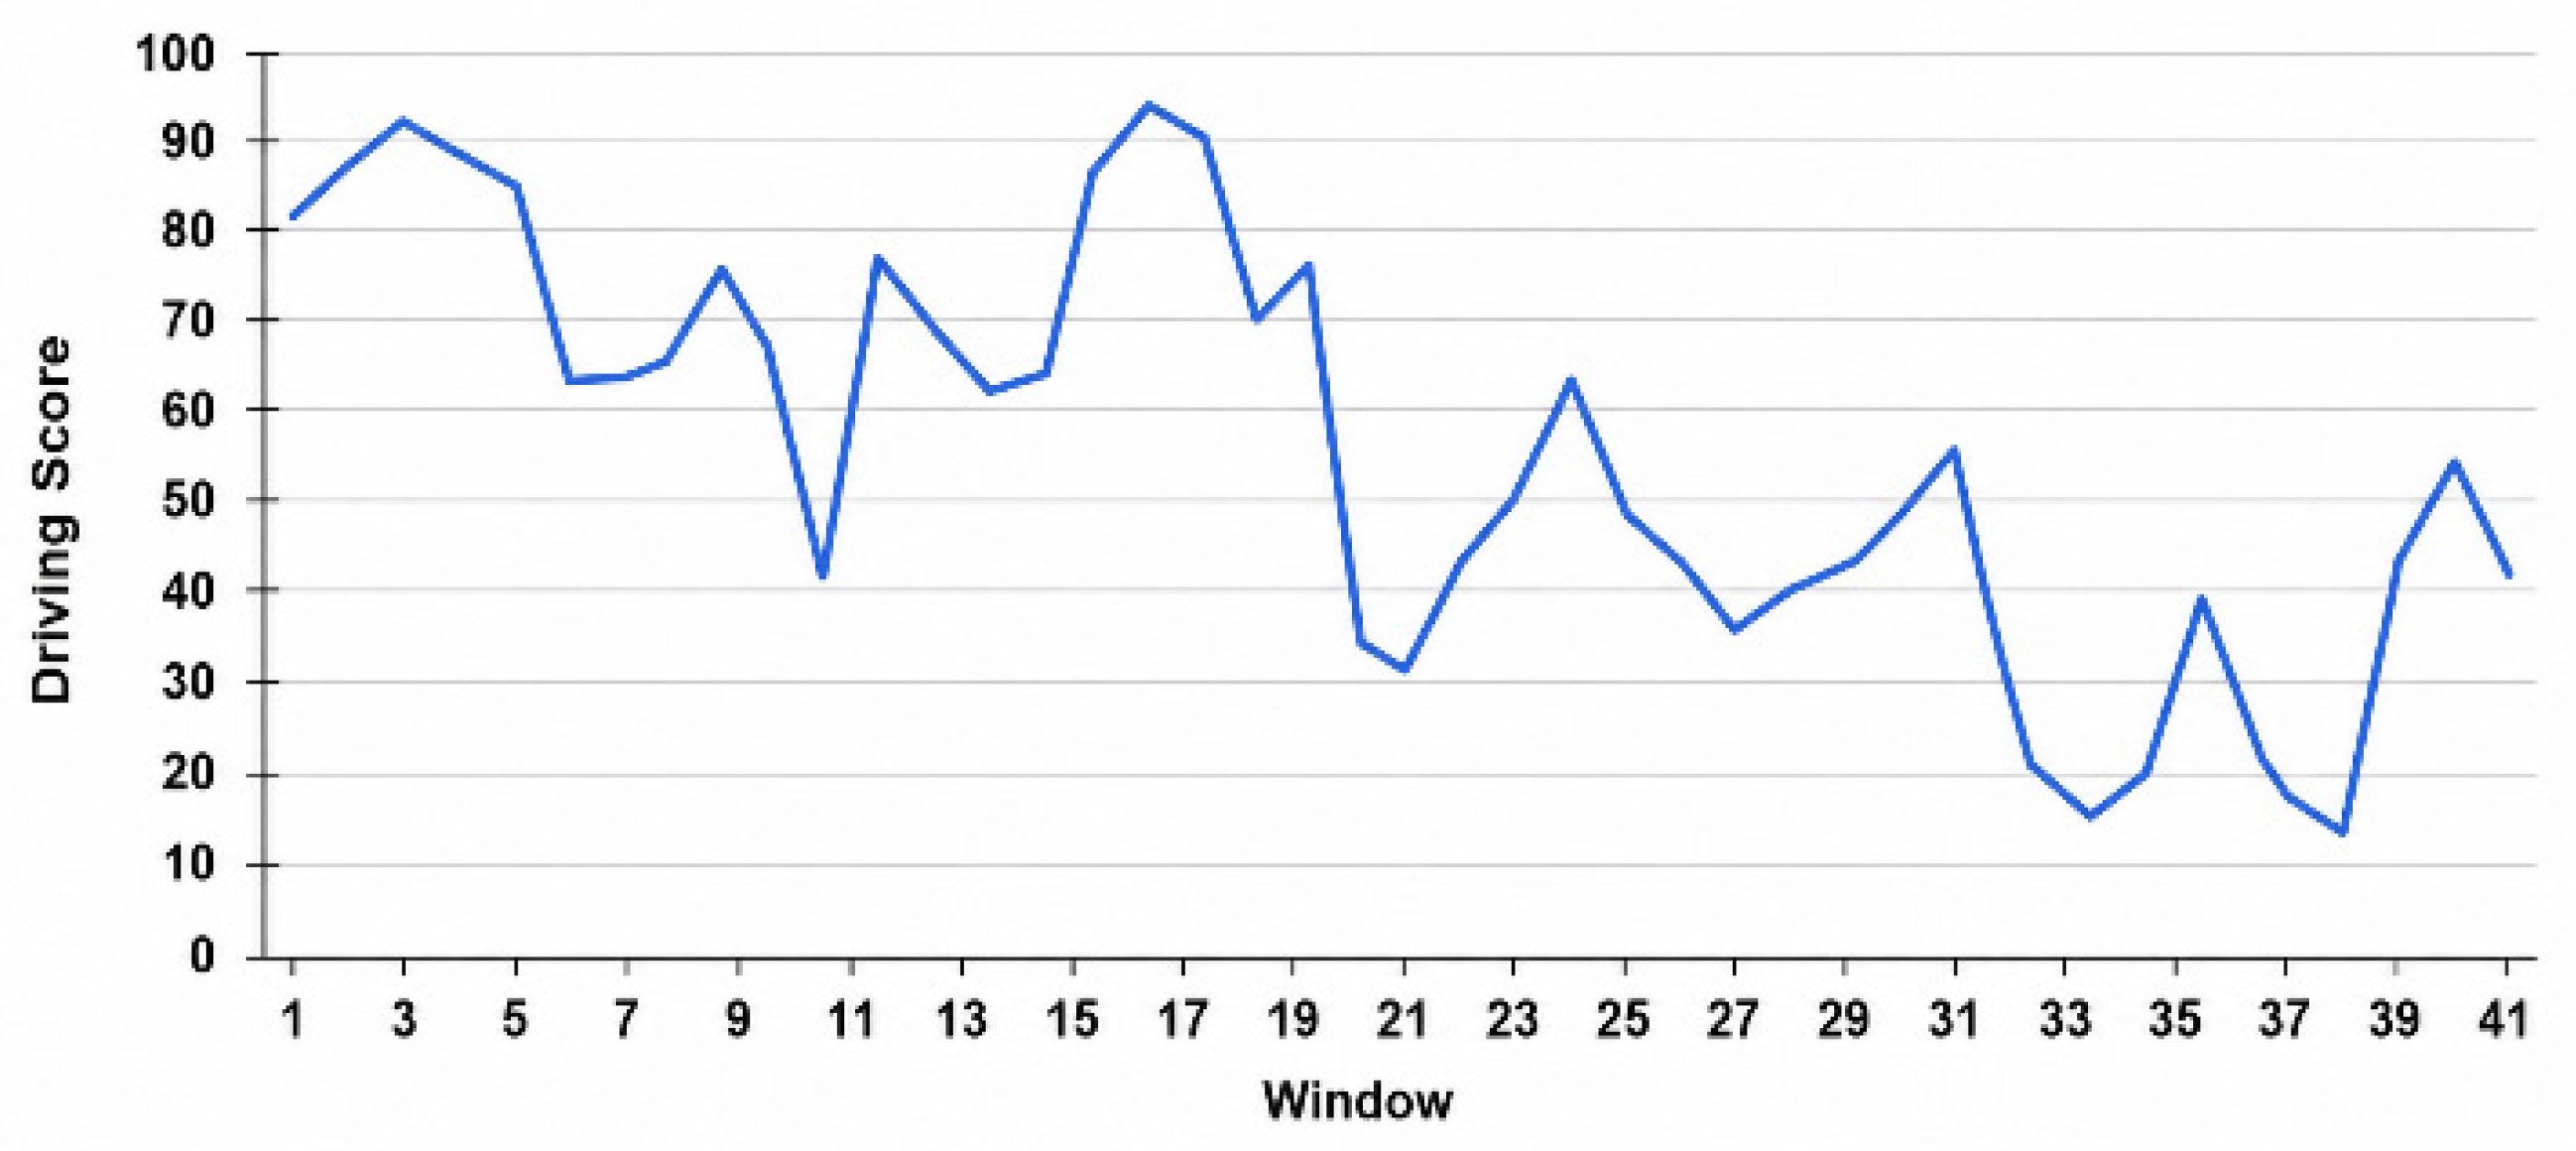
Table 4 presents the jerk-related descriptors with the highest importance scores and most predictive power, as determined by the Random Forest algorithm. These descriptors are also listed with their mean, difference, and rank. Rank 1 corresponds to the descriptor with the highest overall contribution to the Driving Score framework. They are used in calculating the Driving Score. The distribution of Driving Score values is shown in Figure 7 and Figure 8.
Table 4.
Jerk-related features’ importance in the RF model for both datasets, and related window-based statistical analysis: mean, difference, and rank.
Figure 7.
The distribution of the Driving Score measure for the Mendeley dataset.
Figure 8.
The distribution of the Driving Score measure for the Kaggle Driving Behavior Dataset.
Figure 7 shows the DS distribution across all rolling and sliding windows, revealing a wide score range from 9.27 to 93.88. This encompasses both highly unstable driving segments and remarkably stable intervals. Windows with excessive jerk movement correlate directly with low DS values, while those with stable motion and minimal jerk variability correlate with high DS values. The DS dropped sharply to values between 9.27 (window 89) and 18.83 (window 106), marking the lowest scores in the entire sequence. This indicates the most hazardous driving style. Low-scoring windows correspond to abrupt changes in vehicle motion, elevated jerk intensity, high variance, and frequent spike events, indicating an aggressive behavior. There are also more spike events and jerk variability, suggesting the driver was accelerating rapidly, decelerating quickly, or making sudden steering adjustments. Windows from 42 to 52 show consistently higher scores. This reflects smooth acceleration profiles, reduced jerk variability, and minimal peak activity, aligning with the characteristics of normal calm driving. Windows with DS values consistently above 80 have lower jerk-based metrics, which means that the acceleration limits are lower, and the acceleration profiles are smooth and gradual. This continuous scoring range allows the model to capture not only the two final behavioral classes but also the subtle transitions between the two states, which are visible in the (64–85) and (122–128) intervals.
Figure 8 provides the DS distribution across all rolling and sliding windows for the Kaggle dataset. The DS reaches its lowest values between windows 35 and 34, indicating the most unstable windows are linked to aggressive driving. The DS values for windows 36 and 39 are almost identical. Low scores suggest recurring fluctuations in driving style. Windows with moderate scores between 40 and 70 are placed in intervals 6–10 and 25–28, suggesting transitions between stable and unstable driving. This is evident from variations in acceleration and jerk without extreme levels. These segments indicate an uneven driving style. Transitions between the normal and aggressive driving styles are observed as frequent spike events, indicating an inconsistent driving style. The higher DS values (>80) indicate a calm and controlled driving style.
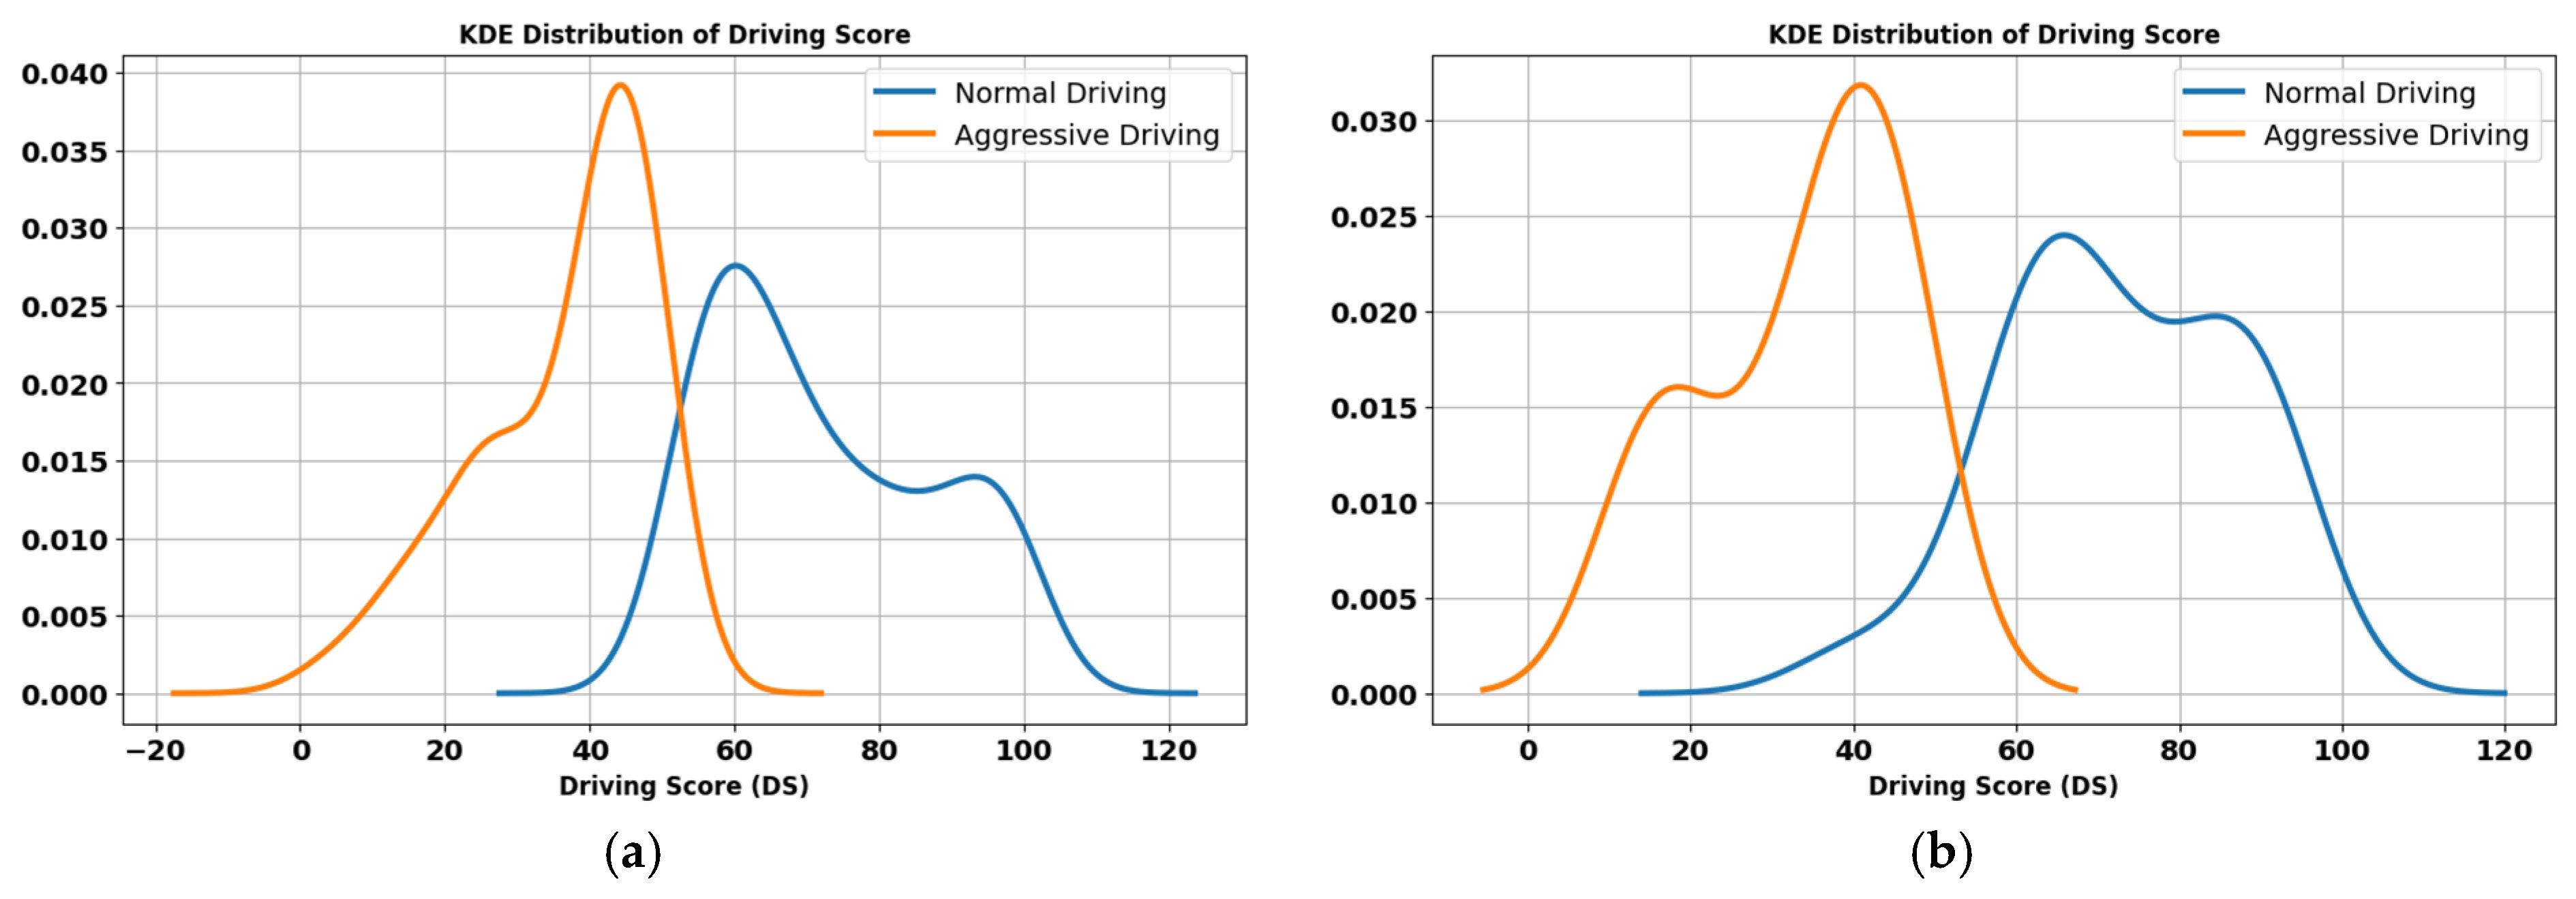
A visual representation of Kernel Density Estimation (KDE) and associated statistics of the proposed Driving Score (DS) are presented in Figure 9 and Table 5. KDE is used to estimate the probability density function of driving behaviors using the Driving Score. It distinguishes between normal and aggressive driving without assuming a specific distribution. It models jerk-based features correlated with DS to identify driver profiles and proves that the selected feature parameters maximize the discrimination of driving styles.
Figure 9.
KDE distribution analysis of the proposed Driving Score (DS). (a) The Mendeley dataset. (b) The Kaggle Driving Behavior Dataset.
Table 5.
Statistics of the Driving Score computed using jerk-based features to identify unique signatures of a driver.
The results showed a significant trend in differentiating between normal and aggressive driving behavior for both data sets, using the proposed Driving Score. This is further supported by the fact that the KDE curves have just a minor overlap zone between distributions.
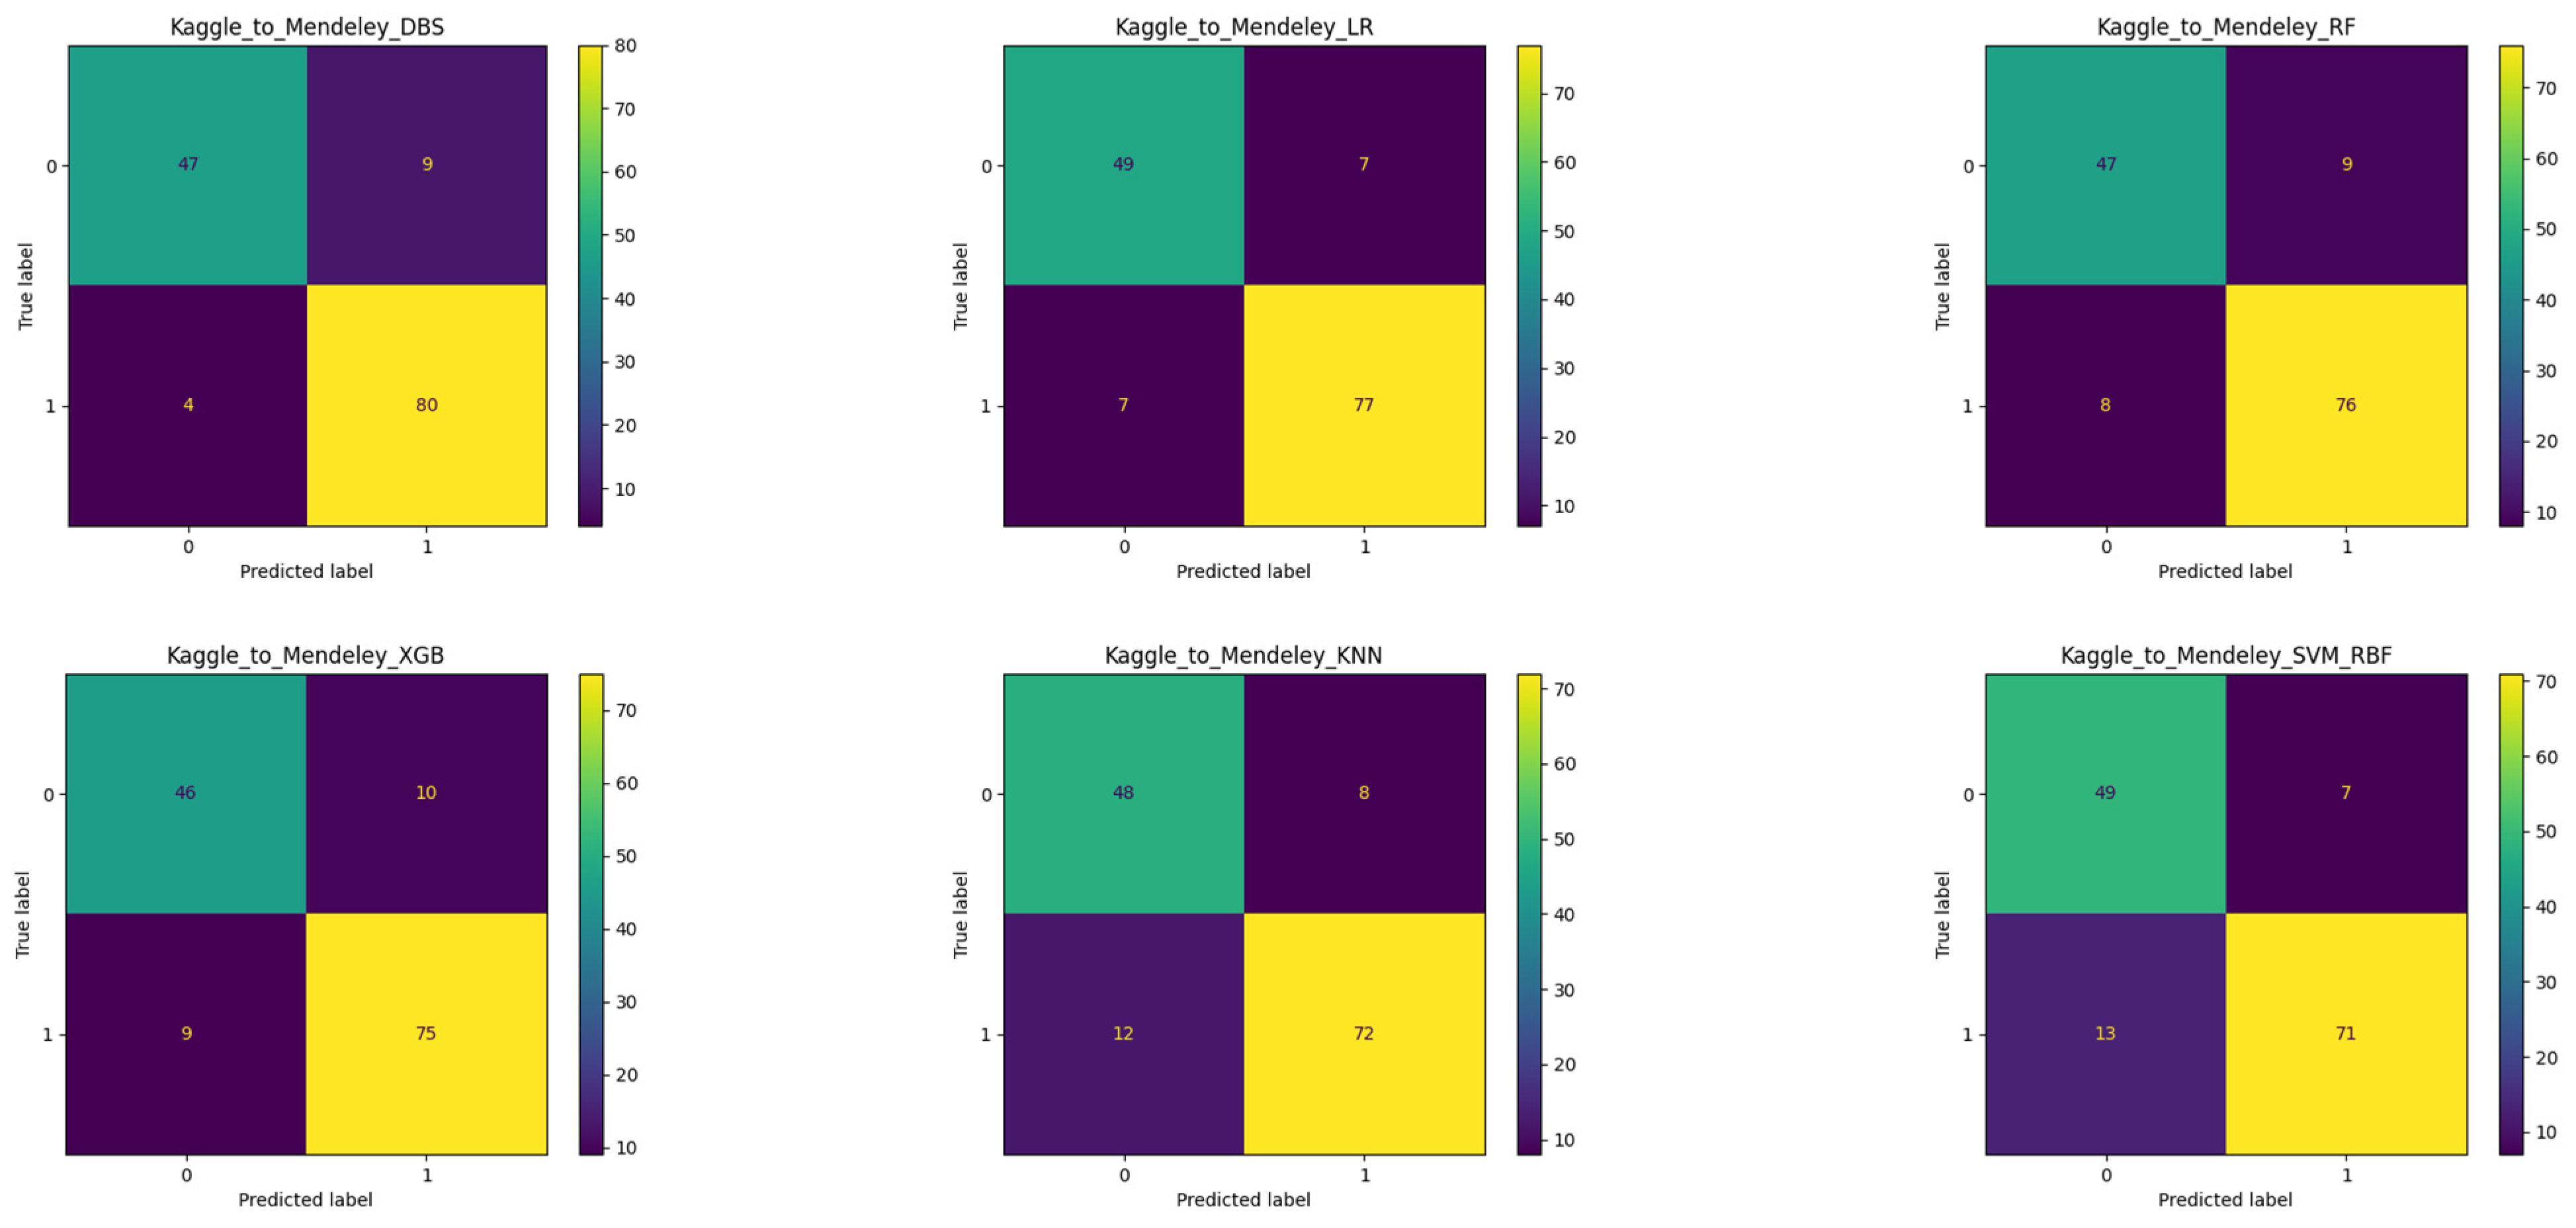
To further evaluate and validate the robustness of jerk-based feature dynamics, we carried out a series of quantitative analyses on newly generated datasets containing jerk-based features. These new datasets contain only jerk-based features (jerk_std_x, jerk_variance_x, jerk_amplitude_x, jerk_spikes_x, jerk_std_y, jerk_max_z, jerk_amplitude_z). The jerk-based features extracted from the Mendeley dataset are used as the training set, while those from the Kaggle dataset are used for testing. Table 6 presents the baseline machine learning classifiers used to confirm the robustness of our approach. The performance metrics of the proposed approach and additional baseline models, for both classes 0 and 1, are reported in Table 7. The corresponding confusion matrices for each model are illustrated in Figure 10.
Table 6.
Classifiers used as a baseline against the proposed model DBS.
Table 7.
Performance comparison between models across the newly generated jerk-based features dataset. Evaluation metrics include accuracy, specificity, sensitivity, and F1-score.
Figure 10.
Confusion matrices for each model.
The Driving Behavior Score (DBS) model identifies 80 true positives and 4 false negatives, with a Recall (class 1) of around 0.952 and an F1 (class 1) of about 0.925. The model also had a total accuracy of 0.907. There was a trade-off between sensitivity and specificity since DBS produced 9 false positives for the normal class (class 0). Logistic Regression has an accuracy of 0.90 and shows the best balance between the two classes in terms of precision and recall. Ensemble models like XGB and RF also perform well, with an overall accuracy of around 0.85. KNN and SVM_RBF classifiers show a slightly lower classification performance with an accuracy of 0.857.
Further, we are interested in exploring any inconsistencies between classifications rather than relying solely on global accuracy ratings. The McNemar test focuses primarily on the discordant prediction pairs (n01 and n10), since these values quantify the disagreement between classifiers. It specifically analyses conflicting classifications, which explains its effectiveness. The method was independently implemented for both datasets. Table 8 displays the McNemar statistical analysis results. The meaning of variables is as follows: n00 represents the number of samples correctly classified by both classifiers. n01 indicates the number of samples correctly classified only by the DBS and misclassified by the baseline model. Similarly, n10 represents the number of samples correctly classified only by the baseline model and misclassified by the DBS. Finally, n11 signifies the number of samples misclassified by both classifiers.
Table 8.
Performance comparison between baseline classifiers using McNemar statistical analysis.
5. Discussion
In this paper, we presented a new approach for driver behavior profiling using dynamic information. This study interpreted and profiled driving behavior using data-driven statistical descriptors derived from IMU signals.
Data in Figure 3 and Figure 4 displayed the feature importance of the proposed approach. The extracted statistical descriptors show clear differences between the two behavior classes with consistent differences for jerk-derived features across all IMU axes. The Random Forest algorithm selects just 22 meaningful features from the top 42 performers (Figure 5). This selection is confirmed by PCA, which facilitated an assessment of the discriminative capacity of jerk-based descriptors and provided a comprehensible visual depiction of patterns across both datasets (Figure 6). For the Mendeley dataset, the loading analysis shows that jerk variability and statistical dispersion are among the main contributors to PC1, reflecting stable differences between normal and aggressive driving styles. PC2 emphasizes extreme motion events and behavioral irregularities. For the Kaggle dataset, PC1 mainly reflects acceleration variability and jerk instability, indicating aggressive and irregular driving dynamics, while PC2 captures rapid motion dynamics and non-uniform acceleration patterns of aggressive driving behavior.
The statistical significance between the selected characteristics of the two classes was assessed using t-tests, separately for both datasets (Table 2 and Table 3). The statistics in Table 2 and Table 3 confirm that the two classes differ significantly, particularly in jerk qualities. Moreover, the practical significance of these results is reinforced through effect sizes. The large effect sizes (Cohen’s d > 1.7) confirm the significant differences between driving style classes as established by jerk-based signals. This suggests the difference between the two group means is greater than the standard deviation and often exceeds the variability within each group. Consequently, the distributions are clearly distinct with minimal overlap. These differences suggest real shifts in driving behavior. The proposed framework considers both statistical and practical significance, minimizing noise or measurement errors.
Furthermore, the data in Figure 7 and Figure 8 illustrate the distribution of DS values, supporting the interpretability of the proposed method. This step assesses the model’s robustness capabilities. It is worth noting that the composite DS does not make binary classifications; instead, it detects subtle changes in driving behavior. The strong negative correlation between DS and jerk-based indicators demonstrates that jerk is the most significant factor differentiating various driving behaviors. Higher jerk amplitudes and greater jerk variability lead to lower composite scores, while stable jerk profiles result in higher scores. This behavior supports the notion that jerk measures driving smoothness and validates the proposed composite scoring system. In the proposed scoring system, drivers with DSs above the average threshold of 50 do not need further risk management. However, those with lower DSs may benefit from auxiliary driving style corrections.
Kernel Density Estimation (KDE) and associated statistics of the proposed Driving Score (DS) revealed a large disparity between KDE peaks (Figure 9). The significant difference in KDE peaks suggests a consistent link between aggressive driving behavior and instability in motion. This includes rapid acceleration changes and greater jerk variability, all of which correlate with lower DS values. The gap and non-overlapping confidence intervals (as shown in Table 5) further support the link between aggressive driving and these factors. This demonstrates the robustness and discriminatory power of the proposed DS framework.
As data in Table 6 and Table 7, and Figure 10 show, baseline models’ performance suggests the proposed approach is suitable, and the data quality (derived from jerk-based features) is adequate for machine learning classification. While the Logistic Regression classifier serves as a strong baseline model, achieving similar overall accuracy to our method, the DBS approach offers more balanced performance across classes. This is achieved while maintaining a high F1 score for both classes. Table 8 shows no statistically significant differences between the DBS and the baseline classifiers (LR, RF, XGB, KNN, and SVM_RBF) on the Mendeley dataset. The p-values exceeding the 0.05 significance threshold suggest relatively similar predictive behavior. Statistically significant differences between DBS and LR, RF, and SVM_RBF are found on the Kaggle dataset. Thus, the models have different error rates, and DBS performs significantly better than the LR, RF, and SVM_RBF classifiers.
Due to the lack of existing research reporting experimental protocols and evaluations of DS related to statistical and dynamic descriptors, particularly in jerk-based feature dynamics, a direct comparison with prior studies is not feasible. However, based on baseline model comparison, we demonstrated that our proposed approach is a viable solution. We conducted a thorough within- and intra-study evaluation across both datasets.
To some extent, we can say that the reported findings align with the majority of existing studies demonstrating the potential of jerk to identify aggressive drivers by using data collected via sensors embedded in mobile phones [31]. Both acceleration and jerk characteristics contribute to perceived motion intensity. Consistent with the literature, the results indicated that perceived motion intensity depended both on acceleration and jerk [32]. The key difference and novelty are that our results were not derived directly from jerk values but rather from jerk-based features.
Beyond these task-specific observations, several limitations of the study should also be acknowledged.
- -
- Firstly, the Mendeley dataset documentation simply states that the sensor data was recorded from an Android phone mounted on a dashboard while driving and includes a label column for driving behavior. It does not specify how many drivers (different people) contributed their data. The dataset description does not list a count of subjects or drivers.
- -
- Secondly, the Kaggle dataset omits key predictive features from the DS value computation. For instance, it only retains jerk_spikes_x, ignoring other spike variations that signify the abrupt, high-intensity dynamics characteristic of erratic or risky driving. DS combines acceleration, speed, and jerk data to determine a driver’s profile, and missing features can impact this.
- -
- Thirdly, when the aggressive driving was assessed, only speeding was chosen to label this behavior. However, by utilizing jerk-based features from both datasets, we mitigated the underrepresentation of certain patterns in the smaller test set and avoided misleading recall and precision. These findings indicate that dataset limitations did not affect feature learning, inter-class discrimination, and predictions. Importantly, classifiers showed stable and consistent predictions across all metrics. This highlights the discriminative capability of jerk-based features across datasets.
Although the imbalance between classes is moderate, the original class distribution across all rolling-window subsets was preserved. In addition, evaluation metrics such as precision, recall, and F1-score were reported separately for each class to reduce potential bias introduced by class-frequency differences. The relatively small imbalance ratio (approximately 1:1.14) was therefore controlled during the evaluation process, minimizing its influence on model robustness and score estimation.
Overall, the results demonstrate consistent improvements in driving behavior profiling across both datasets. The proposed approach effectively transfers jerk-discriminative representations into a robust composite scoring system. Furthermore, the proposed approach is less affected by variations in IMU modality acquisition and dataset-specific differences.
6. Conclusions
This study proposed an interpretable Driving Score framework for driver profiling using statistical and jerk-based features extracted from IMU signals. Unlike conventional deep learning approaches that rely on hidden latent representations, the proposed method combines physically meaningful statistical indicators with jerk-dynamic features to quantify driving profiles transparently.
The experimental analysis conducted on both the Mendeley and Kaggle datasets demonstrated that jerk-based features provide strong discriminative capability for distinguishing aggressive and normal driving behavior. Statistical analysis confirmed highly significant differences between classes, with effect sizes up to Cohen’s d > 1.7 and low p-values. The proposed Driving Score framework successfully captured both discrete behavioral classes and gradual transitions between stable and unstable driving conditions. Low DS values were consistently associated with increased jerk variability, abrupt acceleration changes, and frequent spike events, whereas high DS values corresponded to smoother and more controlled motion profiles.
In addition, systematic comparisons with conventional machine learning models across multiple performance metrics further support the proposed approach’s favorable performance. The comparison was conducted through inter- and intra-study evaluation across both datasets. The DBS framework achieved competitive performance with an overall accuracy of 0.907 while preserving transparency and low computational complexity. Comparative analysis demonstrated that the proposed scoring approach performs similarly to conventional machine learning models while offering improved interpretability relative to black-box learning architectures. This demonstrates the robustness of jerk-based feature dynamics and their independence from the quality of the raw data.
Because the proposed framework relies exclusively on lightweight statistical computations, it is suitable for real-time implementation in smartphone-based telematics systems, driver-assistance platforms, embedded monitoring devices, and insurance-oriented behavioral analytics.
Nevertheless, several limitations remain. The Mendeley dataset does not specify the number of individual drivers, which restricts claims regarding cross-subject generalization. In addition, the Kaggle dataset defines aggressive driving mainly through speed-related conditions, excluding important aggressive maneuvers such as harsh steering and unsafe lane changes. These limitations indicate that broader datasets containing richer behavioral annotations and larger participant diversity are required.
Future research directions should therefore focus on:
- -
- Both datasets represent semi-controlled recording scenarios and partly reflect the real-world driving styles. Future work will address limitations by incorporating richer behavioral annotations, including braking aggressiveness, steering instability, lane-changing patterns, cornering dynamics, and contextual traffic information to establish more comprehensive and realistic aggressive-driving profiles.
- -
- Collecting larger multi-driver datasets with balanced demographic representation and well-defined behavioral labels.
- -
- Integrating additional contextual information such as road curvature, traffic density, and environmental conditions. Also, we will examine the impact of filters, adaptive thresholding, individualized scoring profiles, and multimodal data fusion to increase system accuracy and application.
- -
- Combining explainable statistical scoring systems with deep learning architectures such as CNNs and LSTMs to develop hybrid interpretable frameworks.
Author Contributions
F.M. and D.D.D.: Writing—review and editing, Writing—original draft, Software, Methodology, Investigation, Formal analysis. L.M.: Conceptualization, Writing—review and editing, Funding acquisition, Visualization, Validation, Supervision, Resources, Project administration, Methodology, Investigation, Formal analysis, Data curation. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data presented in this study are openly available in Mendeley Data at DOI: 10.17632/5stn873wft.1, and in Driving Behavior—Using Deep Learning and Machine Learning to Predict Driving Behavior at https://doi.org/10.34740/kaggle/dsv/3748585.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Cheng, R.; Liu, F.; Ge, H. A new continuum model based on full velocity difference model considering traffic jerk effect. Nonlinear Dyn. 2017, 89, 639–649. [Google Scholar] [CrossRef] [Scilit]
- Zhai, C.; Wu, W. Analysis of drivers’ characteristics on continuum model with traffic jerk effect. Phys. Lett. A 2018, 382, 3381–3392. [Google Scholar] [CrossRef] [Scilit]
- Szumska, E.M.; Jurecki, R. The Effect of Aggressive Driving on Vehicle Parameters. Energies 2020, 13, 6675. [Google Scholar] [CrossRef] [Scilit]
- Haselberger, J.; Schick, B.; Müller, S. Self-perception versus objective driving behavior: Subject study of lateral vehicle guidance. Transp. Res. Part F Psychol. Behav. 2025, 109, 272–298. [Google Scholar] [CrossRef] [Scilit]
- Qi, J.; Zhu, R.; Liu, C.; Mauricio, A.; Gryllias, K. Anomaly detection and multi-step estimation based remaining useful life prediction for rolling element bearings. Mech. Syst. Signal Process. 2024, 206, 110910. [Google Scholar] [CrossRef] [Scilit]
- Fernandes, P.; Ferreira, E.; Macedo, E.; Coelho, M.C. Unraveling roundabout dynamics: Analysis of driving behavior, vehicle performance, and exhaust emissions. Transp. Res. Part D Transp. Environ. 2024, 133, 104308. [Google Scholar] [CrossRef] [Scilit]
- Mantouka, E.; Barmpounakis, E.; Vlahogianni, E.; Golias, J. Smartphone sensing for understanding driving behavior: Current practice and challenges. Int. J. Transp. Sci. Technol. 2021, 10, 266–282. [Google Scholar] [CrossRef] [Scilit]
- Shahariar, G.H.; Sajjad, M.; Suara, K.A.; Jahirul, M.I.; Chu-Van, T.; Ristovski, Z.; Brown, R.J.; Bodisco, T.A. On-road CO2 and NOx emissions of a diesel vehicle in urban traffic. Transp. Res. Part D Transp. Environ. 2022, 107, 103326. [Google Scholar] [CrossRef] [Scilit]
- Ferreira, E.; Fernandes, P.; Bahmankhah, B.; Coelho, M.C. Micro-analysis of a single vehicle driving volatility and impacts on emissions for intercity corridors. Int. J. Sustain. Transp. 2022, 16, 681–705. [Google Scholar] [CrossRef] [Scilit]
- Hayati, H.; Eager, D.; Pendrill, A.-M.; Alberg, H. Jerk within the Context of Science and Engineering—A Systematic Review. Vibration 2020, 3, 371–409. [Google Scholar] [CrossRef] [Scilit]
- Shuai, Z.; Dong, A.; Liu, H.; Cui, Y. Reliability and Validity of an Inertial Measurement System to Quantify Lower Extremity Joint Angle in Functional Movements. Sensors 2022, 22, 863. [Google Scholar] [CrossRef] [Scilit]
- Chen, S.; Xiao, Y.; Wang, Y.; Xie, Y.; Zhu, T.; Duan, R.; Chen, J. Skew-normal distributions for modeling asymmetric moving tendencies in pedestrian trajectories. Neurocomputing 2026, 661, 131934. [Google Scholar] [CrossRef] [Scilit]
- Redhu, P.; Siwach, V. An extended lattice model accounting for traffic jerk. Phys. A Stat. Mech. Its Appl. 2018, 492, 1473–1480. [Google Scholar] [CrossRef] [Scilit]
- Fernandes, P.; Tomás, R.; Acuto, F.; Pascale, A.; Bahmankhah, B.; Guarnaccia, C.; Granà, A.; Coelho, M.C. Impacts of roundabouts in suburban areas on congestion-specific vehicle speed profiles, pollutant and noise emissions: An empirical analysis. Sustain. Cities Soc. 2020, 62, 102386. [Google Scholar] [CrossRef] [Scilit]
- Sun, B.; Deng, W.; Wu, J.; Li, Y.; Wang, J. An intention-aware and online driving style estimation based personalized autonomous driving strategy. Int. J. Automot. Technol. 2020, 21, 1431–1446. [Google Scholar] [CrossRef] [Scilit]
- Karrouchi, M.; Nasri, I.; Rhiat, M.; Atmane, I.; Hirech, K.; Messaoudi, A.; Melhaoui, M.; Kassmi, K. Driving behavior assessment: A practical study and technique for detecting a driver’s condition and driving style. Transp. Eng. 2023, 14, 100217. [Google Scholar] [CrossRef] [Scilit]
- Komavec, M.; Kaluža, B.; Stojmenova, K.; Sodnik, J. Risk assessment score based on simulated driving session. In Proceedings of the Driving Simulation Conference 2019 Europe VR, Driving Simulation Association, Strasbourg, France, 4–6 September 2019; pp. 67–74. [Google Scholar]
- Feng, F.; Bao, S.; Sayer, J.R.; Flannagan, C.; Manser, M.; Wunderlich, R. Can vehicle longitudinal jerk be used to identify aggressive drivers? An examination using naturalistic driving data. Accid. Anal. Prev. 2017, 104, 125–136. [Google Scholar] [CrossRef] [Scilit]
- Medarević, J.; Tomažič, S.; Sodnik, J. Simulation-based driver scoring and profiling system. Heliyon 2024, 10, e40310. [Google Scholar] [CrossRef] [Scilit]
- Tawadros, P.; Awadallah, M.; Walker, P.; Zhang, N. Using a low-cost bluetooth torque sensor for vehicle jerk and transient torque measurement. Proc. Inst. Mech. Eng. Part D J. Automob. Eng. 2020, 234, 423–437. [Google Scholar] [CrossRef] [Scilit]
- El mourabit, A.; Bouazizi, O.; Oussouaddi, M.; El Abidine, Z.; Ismaili, A.; Attaoui, Y.; Chentouf, M. Instantaneous time to collision estimation using a constant jerk model and a monocular camera. Eng. Sci. Technol. Int. J. 2025, 64, 102011. [Google Scholar] [CrossRef] [Scilit]
- Patrício, D.; Loureiro, P.; Mendes, S.P.; Bernardino, A.; Miragaia, R.; Husyeva, I. Pattern-Based Driver Aggressiveness Behavior Assessment Using LSTM-Based Models. Future Transp. 2025, 5, 135. [Google Scholar] [CrossRef] [Scilit]
- Pingo, A.; Castro, J.; Loureiro, P.; Mendes, S.; Bernardino, A.; Miragaia, R.; Husyeva, I. Driving Behavior Classification Using a ConvLSTM. Future Transp. 2025, 5, 52. [Google Scholar] [CrossRef] [Scilit]
- Chen, K.; Diao, Y.; Wang, Y.; Zhang, X.; Zhou, Y.; Gu, M.; Zhang, B.; Hu, B.; Li, M.; Li, W.; et al. MCT-CNN-LSTM: A Driver Behavior Wireless Perception Method Based on an Improved Multi-Scale Domain-Adversarial Neural Network. Sensors 2025, 25, 2268. [Google Scholar] [CrossRef] [Scilit]
- Escottá, Á.T.; Beccaro, W.; Ramírez, M.A. Evaluation of 1D and 2D Deep Convolutional Neural Networks for Driving Event Recognition. Sensors 2022, 22, 4226. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Yedilkhan, D.; Agybetov, N.; Amirgaliyev, B. Driver Behaviour Analysis Using Telematics Sensor Data and Deep Learning Models. Procedia Comput. Sci. 2025, 272, 594–600. [Google Scholar] [CrossRef] [Scilit]
- Nazirkar, S. Phone Sensor Data While Driving a Car and Normal or Aggressive Driving Behaviour Classification. Mendeley Data, V1. 2021. Available online: https://data.mendeley.com/datasets/5stn873wft/1 (accessed on 1 February 2026).
- Kaggle. Driving Behavior Dataset. Available online: https://www.kaggle.com/datasets/outofskills/driving-behavior (accessed on 1 February 2026).
- Zhang, L.; Peng, K.; Zhao, X.; Khattak, A.J. New fuel consumption model considering vehicular speed, acceleration, and jerk. J. Intell. Transp. Syst. 2023, 27, 174–186. [Google Scholar] [CrossRef] [Scilit]
- Magnusson, K. A Causal Inference Perspective on Therapist Effects. arXiv 2023. [Google Scholar] [CrossRef] [Scilit]
- Mantouka, E.G.; Barmpounakis, E.N.; Vlahogianni, E.I. Identifying driving safety profiles from smartphone data using unsupervised learning. Saf. Sci. 2019, 119, 84–90. [Google Scholar] [CrossRef] [Scilit]
- de Winkel, K.N.; Soyka, F.; Bülthoff, H.H. The role of acceleration and jerk in perception of above-threshold surge motion. Exp. Brain Res. 2020, 238, 699–711. [Google Scholar] [CrossRef] [Scilit] [PubMed]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.