
DMSNet: A Dynamic Multi-Scale Feature Fusion Segmentation Network for Precise Large Yellow Croaker Recognition in Complex Underwater Conditions
 , ,
Abstract
1. Introduction
- Compile and annotate a dedicated underwater image dataset of the large yellow croaker, called the Large Yellow Croaker Dataset (LYCD), capturing the varied clarity conditions representative of real aquaculture settings, providing a valuable resource for community-based research and application.
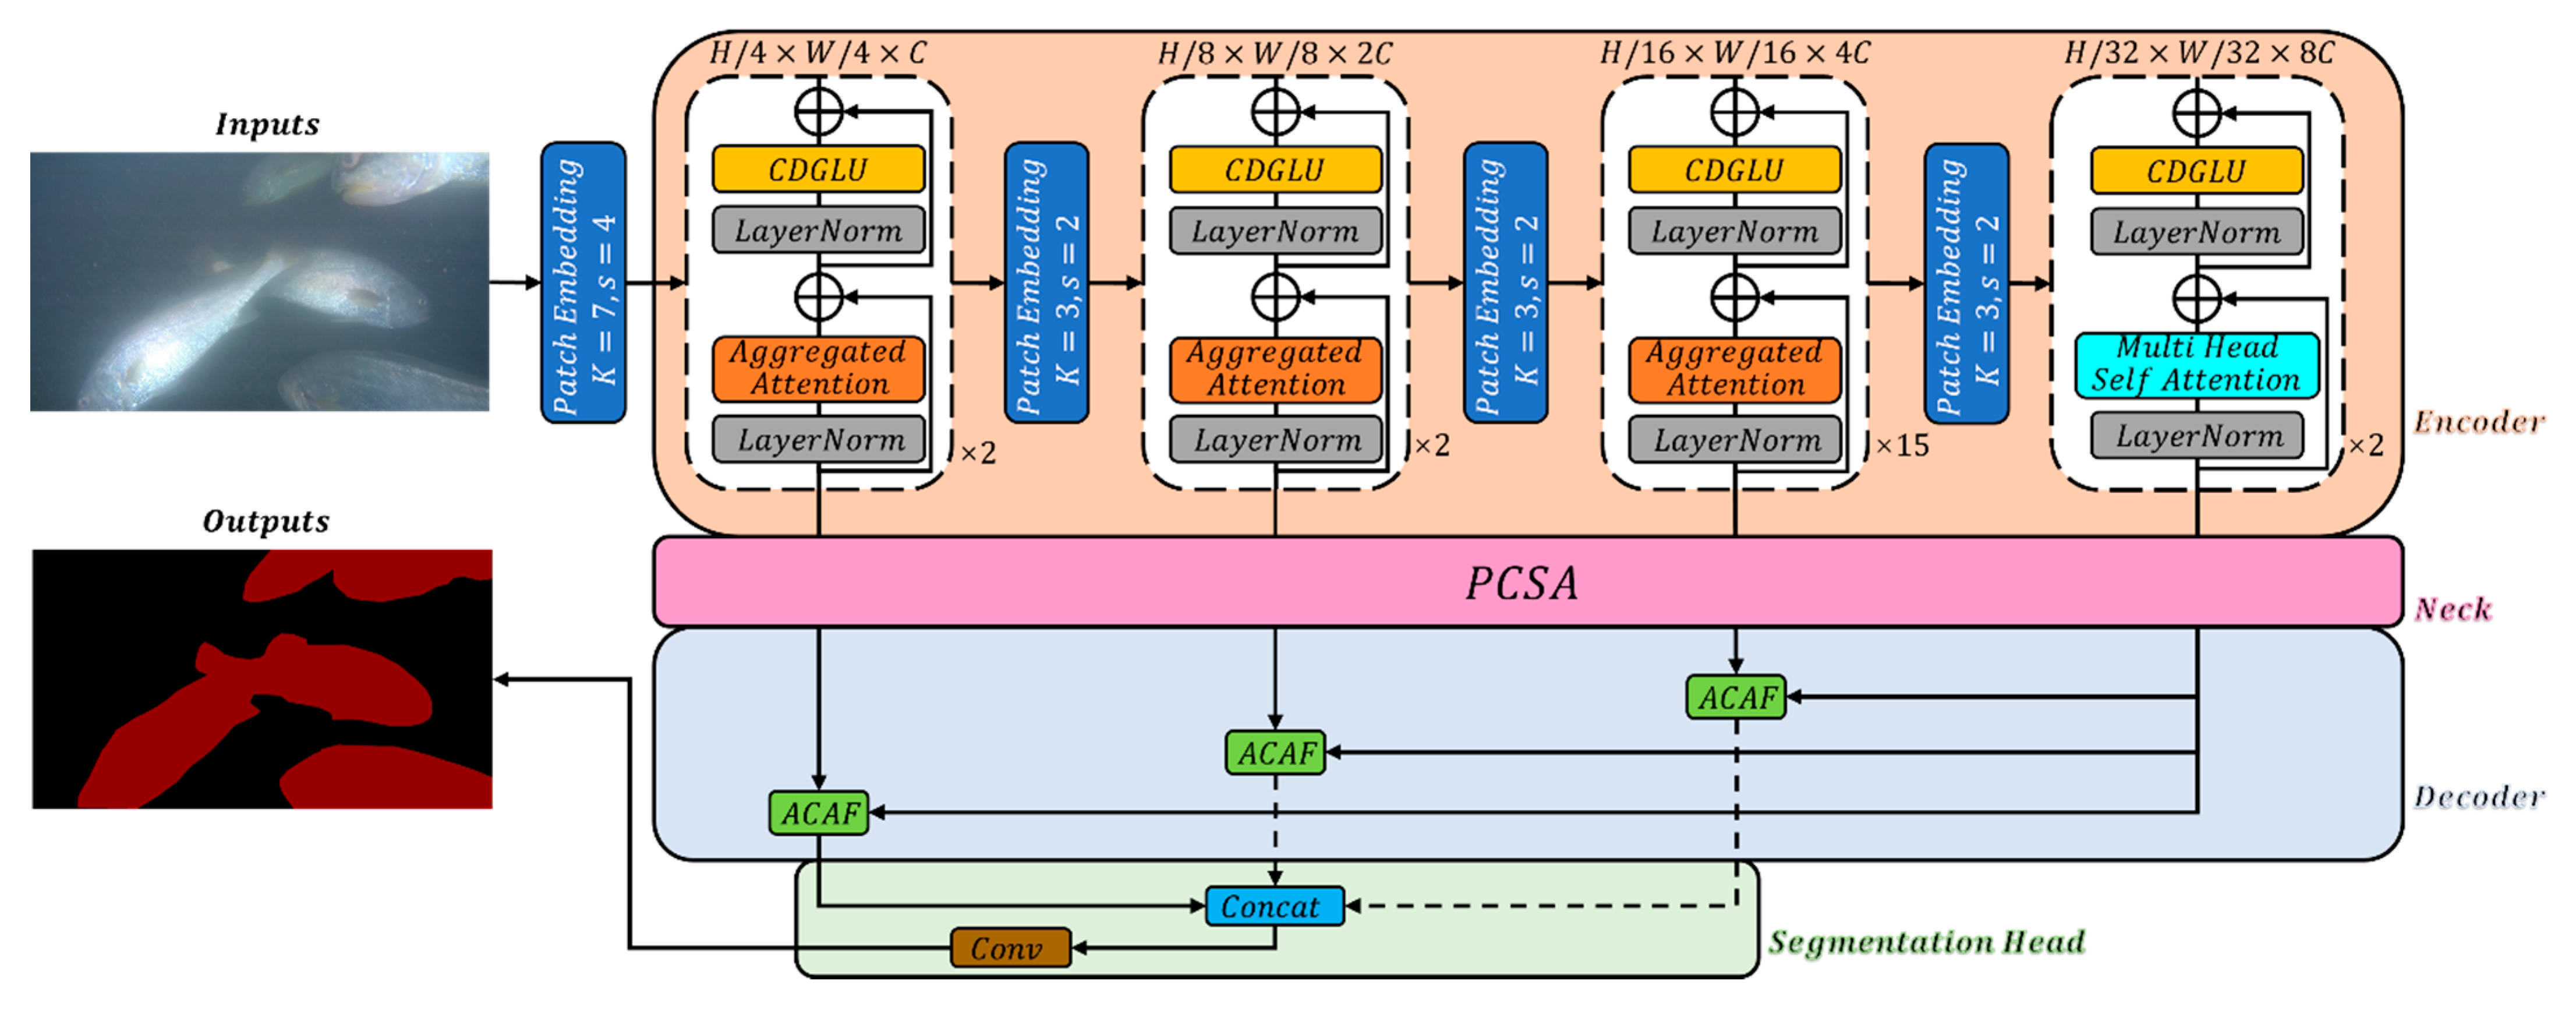
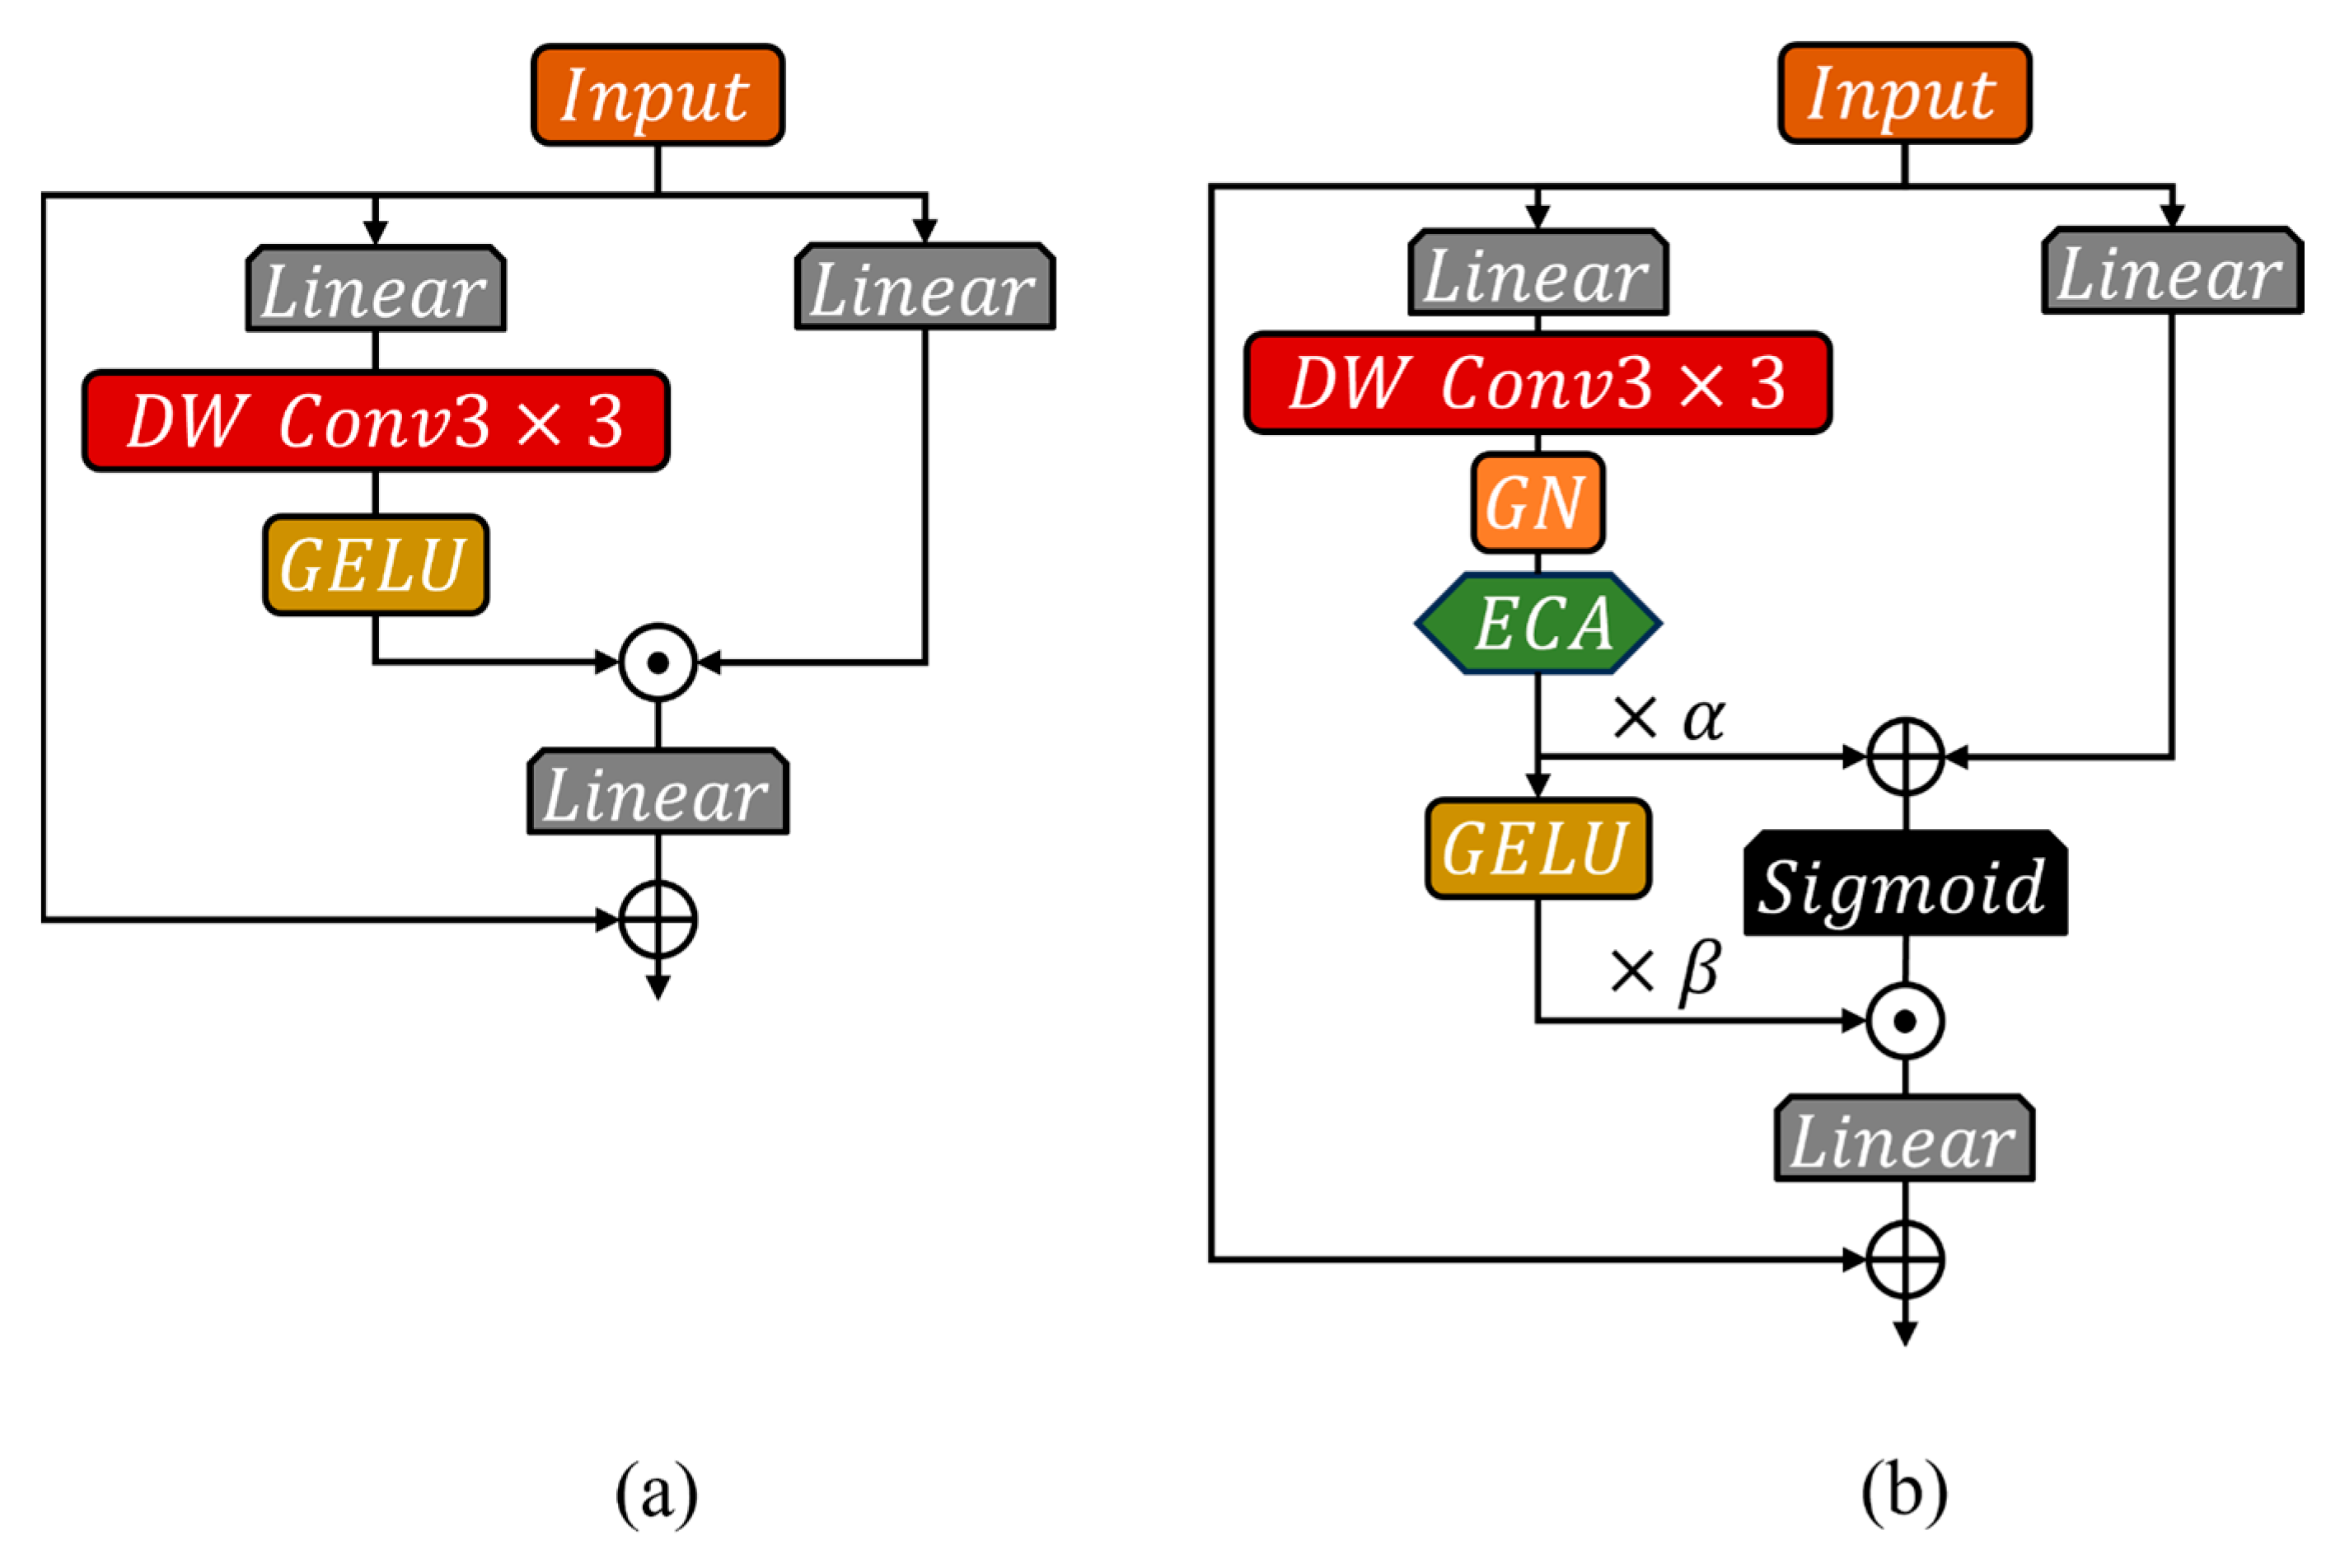
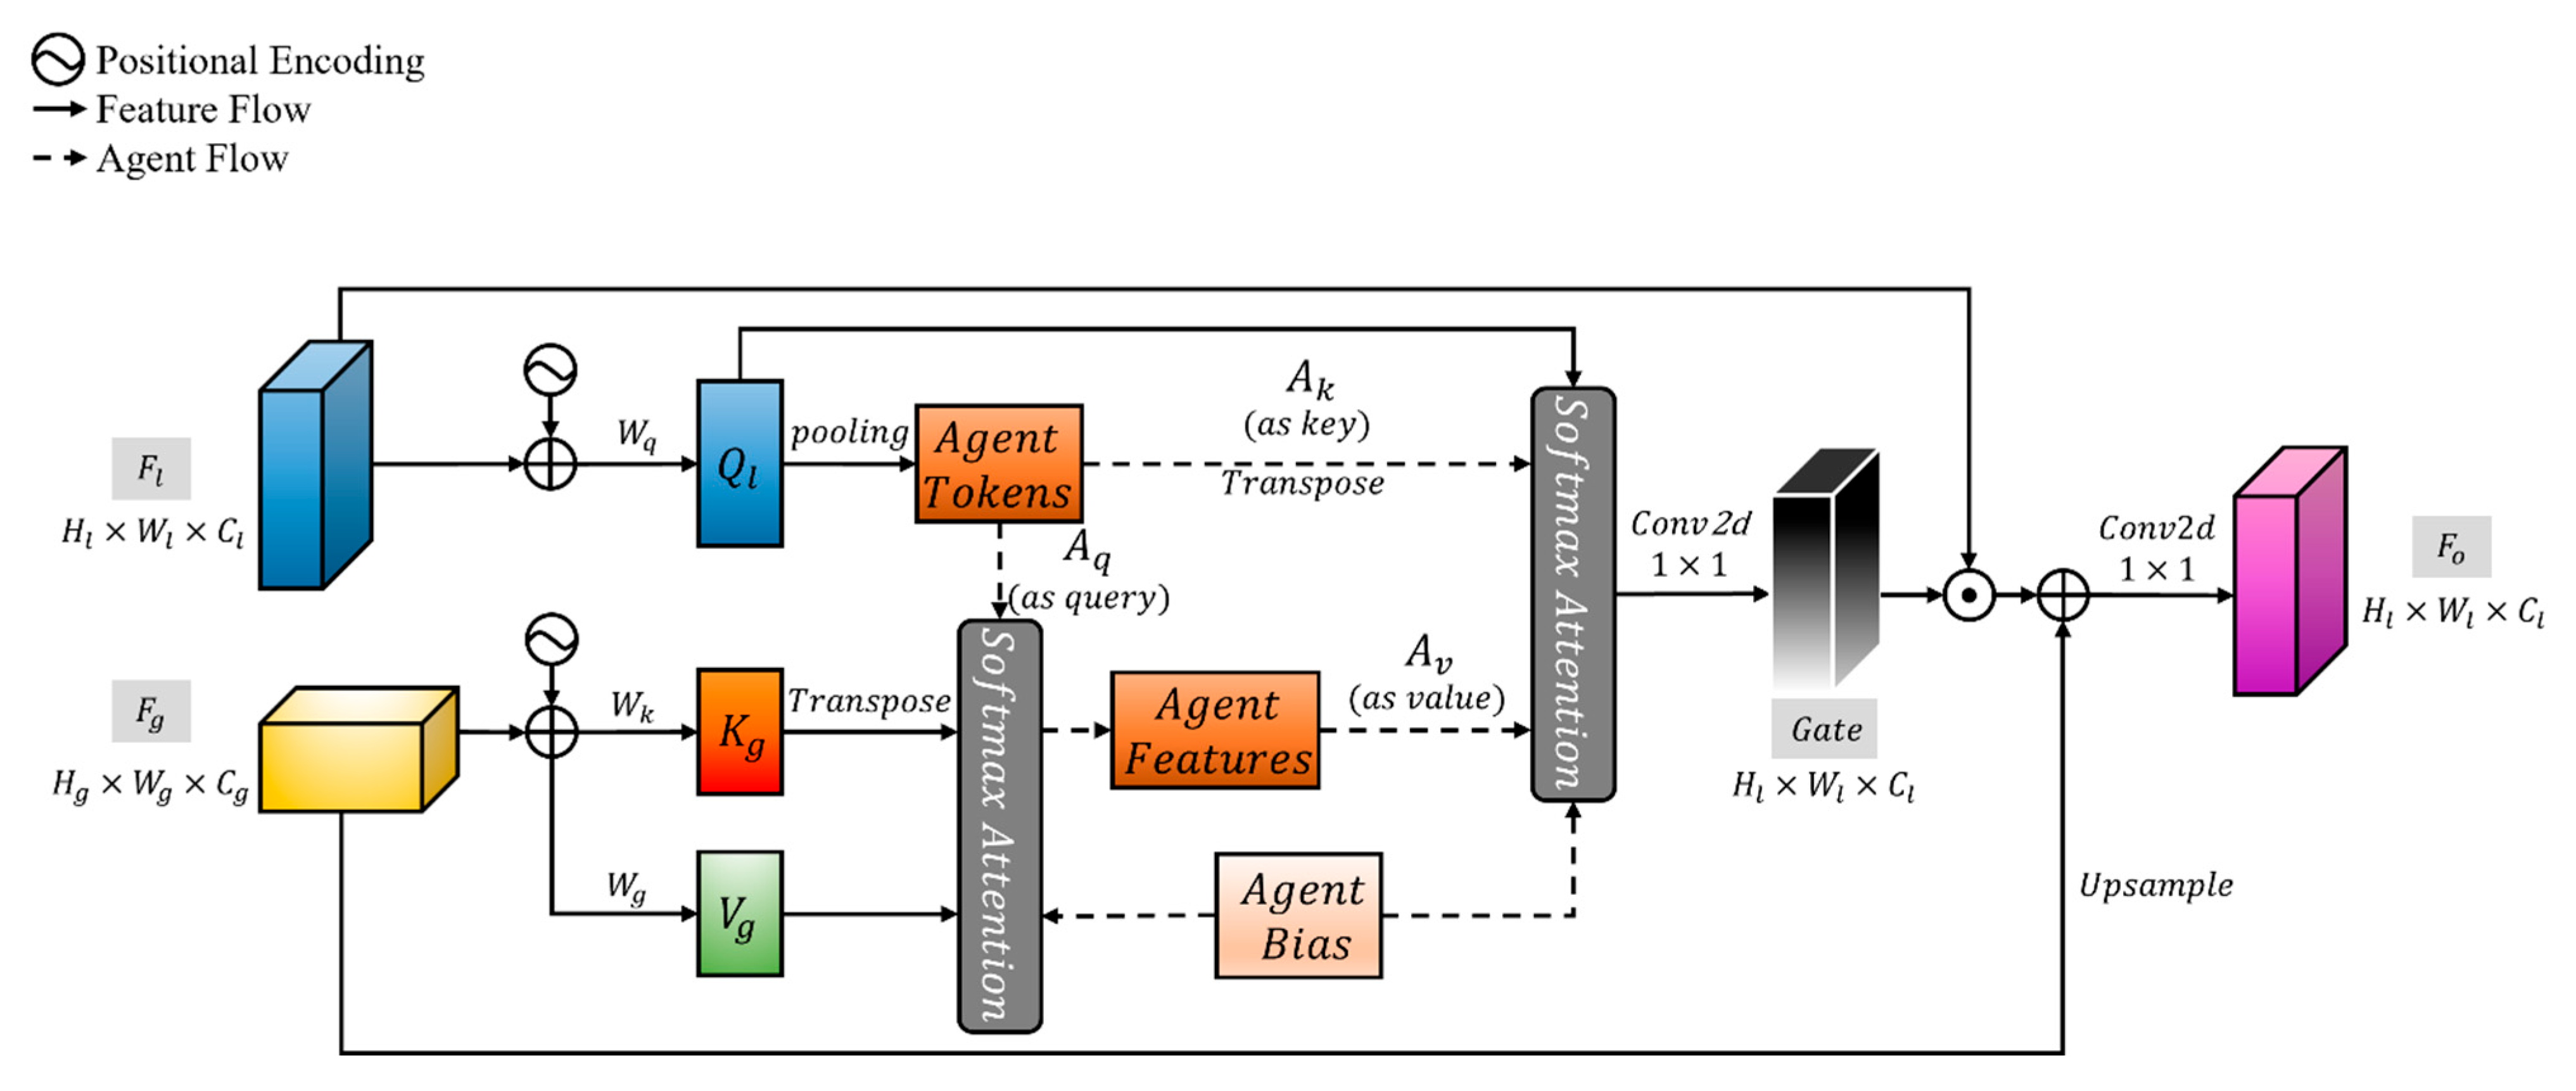
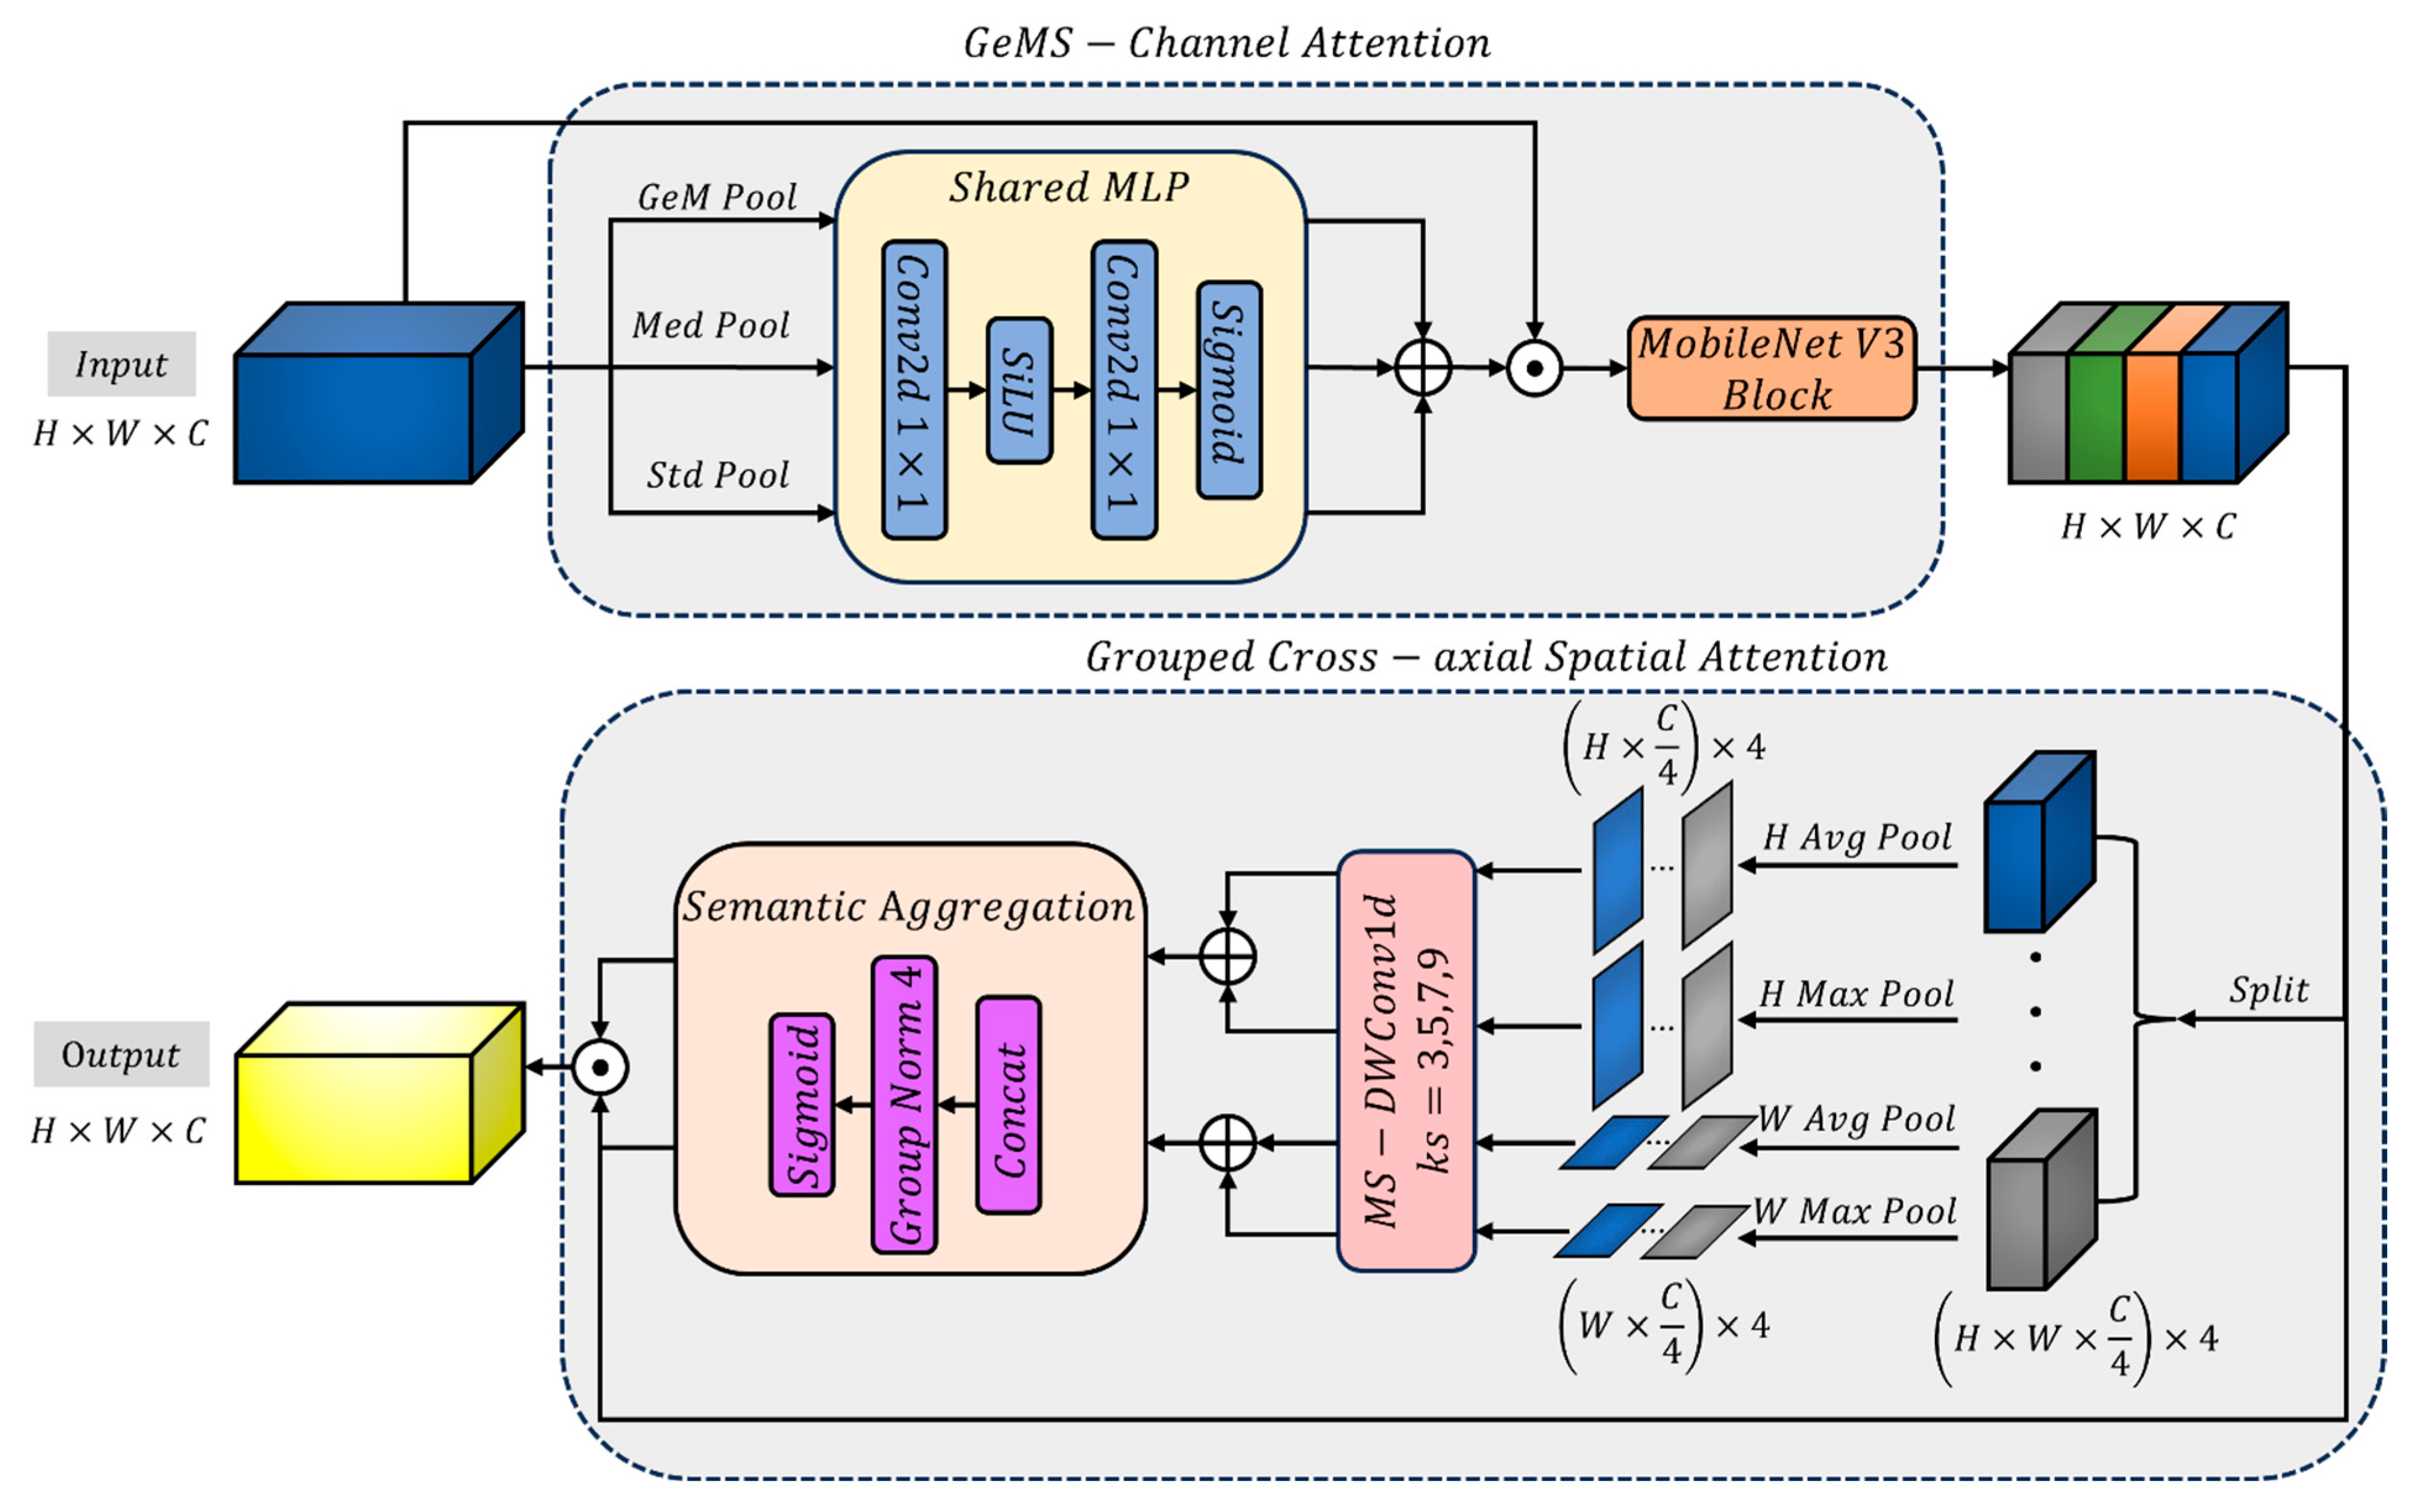
- Propose DMSNet, an improved segmentation network based on TransNeXt, which integrates three core modules—CDGLU, ACAF, and PCSA—to strengthen feature representation and fusion under challenging underwater conditions.
- Comprehensive experiments demonstrate that our method achieves state-of-the-art performance on both public datasets and LYCD, showing particularly strong robustness in the turbid and low-contrast environments common to practical aquaculture settings.
2. Materials and Methods
2.1. Dataset
2.2. Segmentation Methods
2.2.1. Overall Architecture
2.2.2. Improved TransNeXt Backbone Network
2.2.3. Agentic Cross-Attention Fusion Module
2.2.4. Pooling Channel-Spatial Attention
3. Results
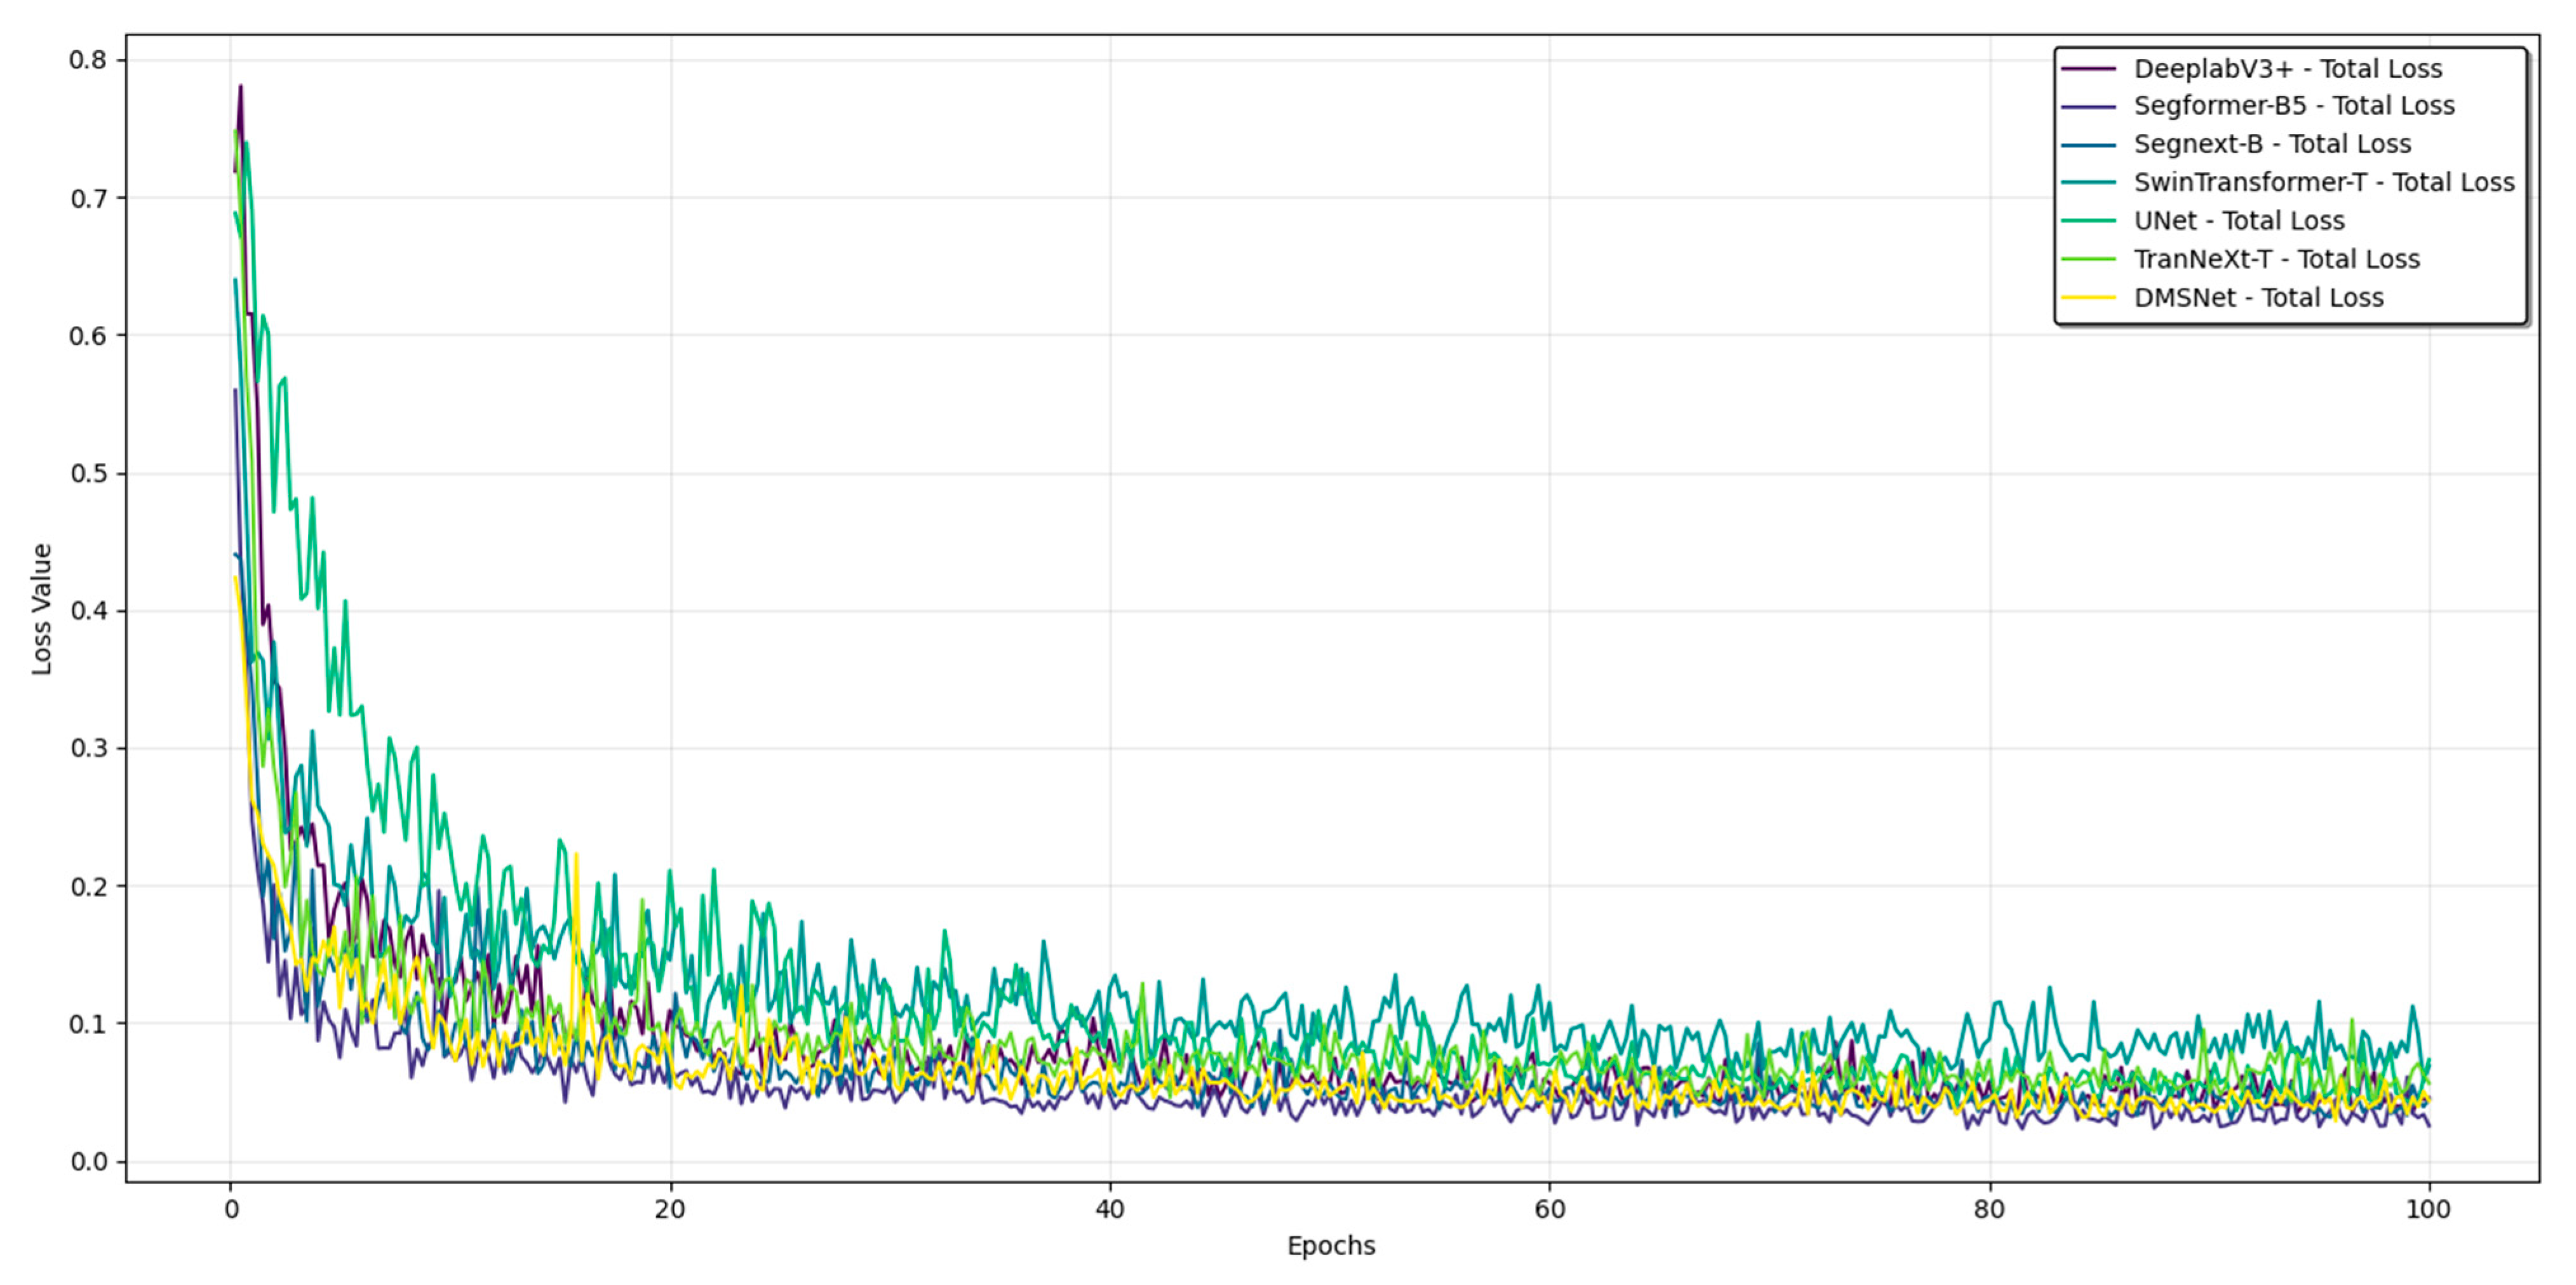
3.1. Implementation Details
3.2. Evaluation Metrics
3.3. Evaluation of the Semantic Segmentation Model in Public Dataset
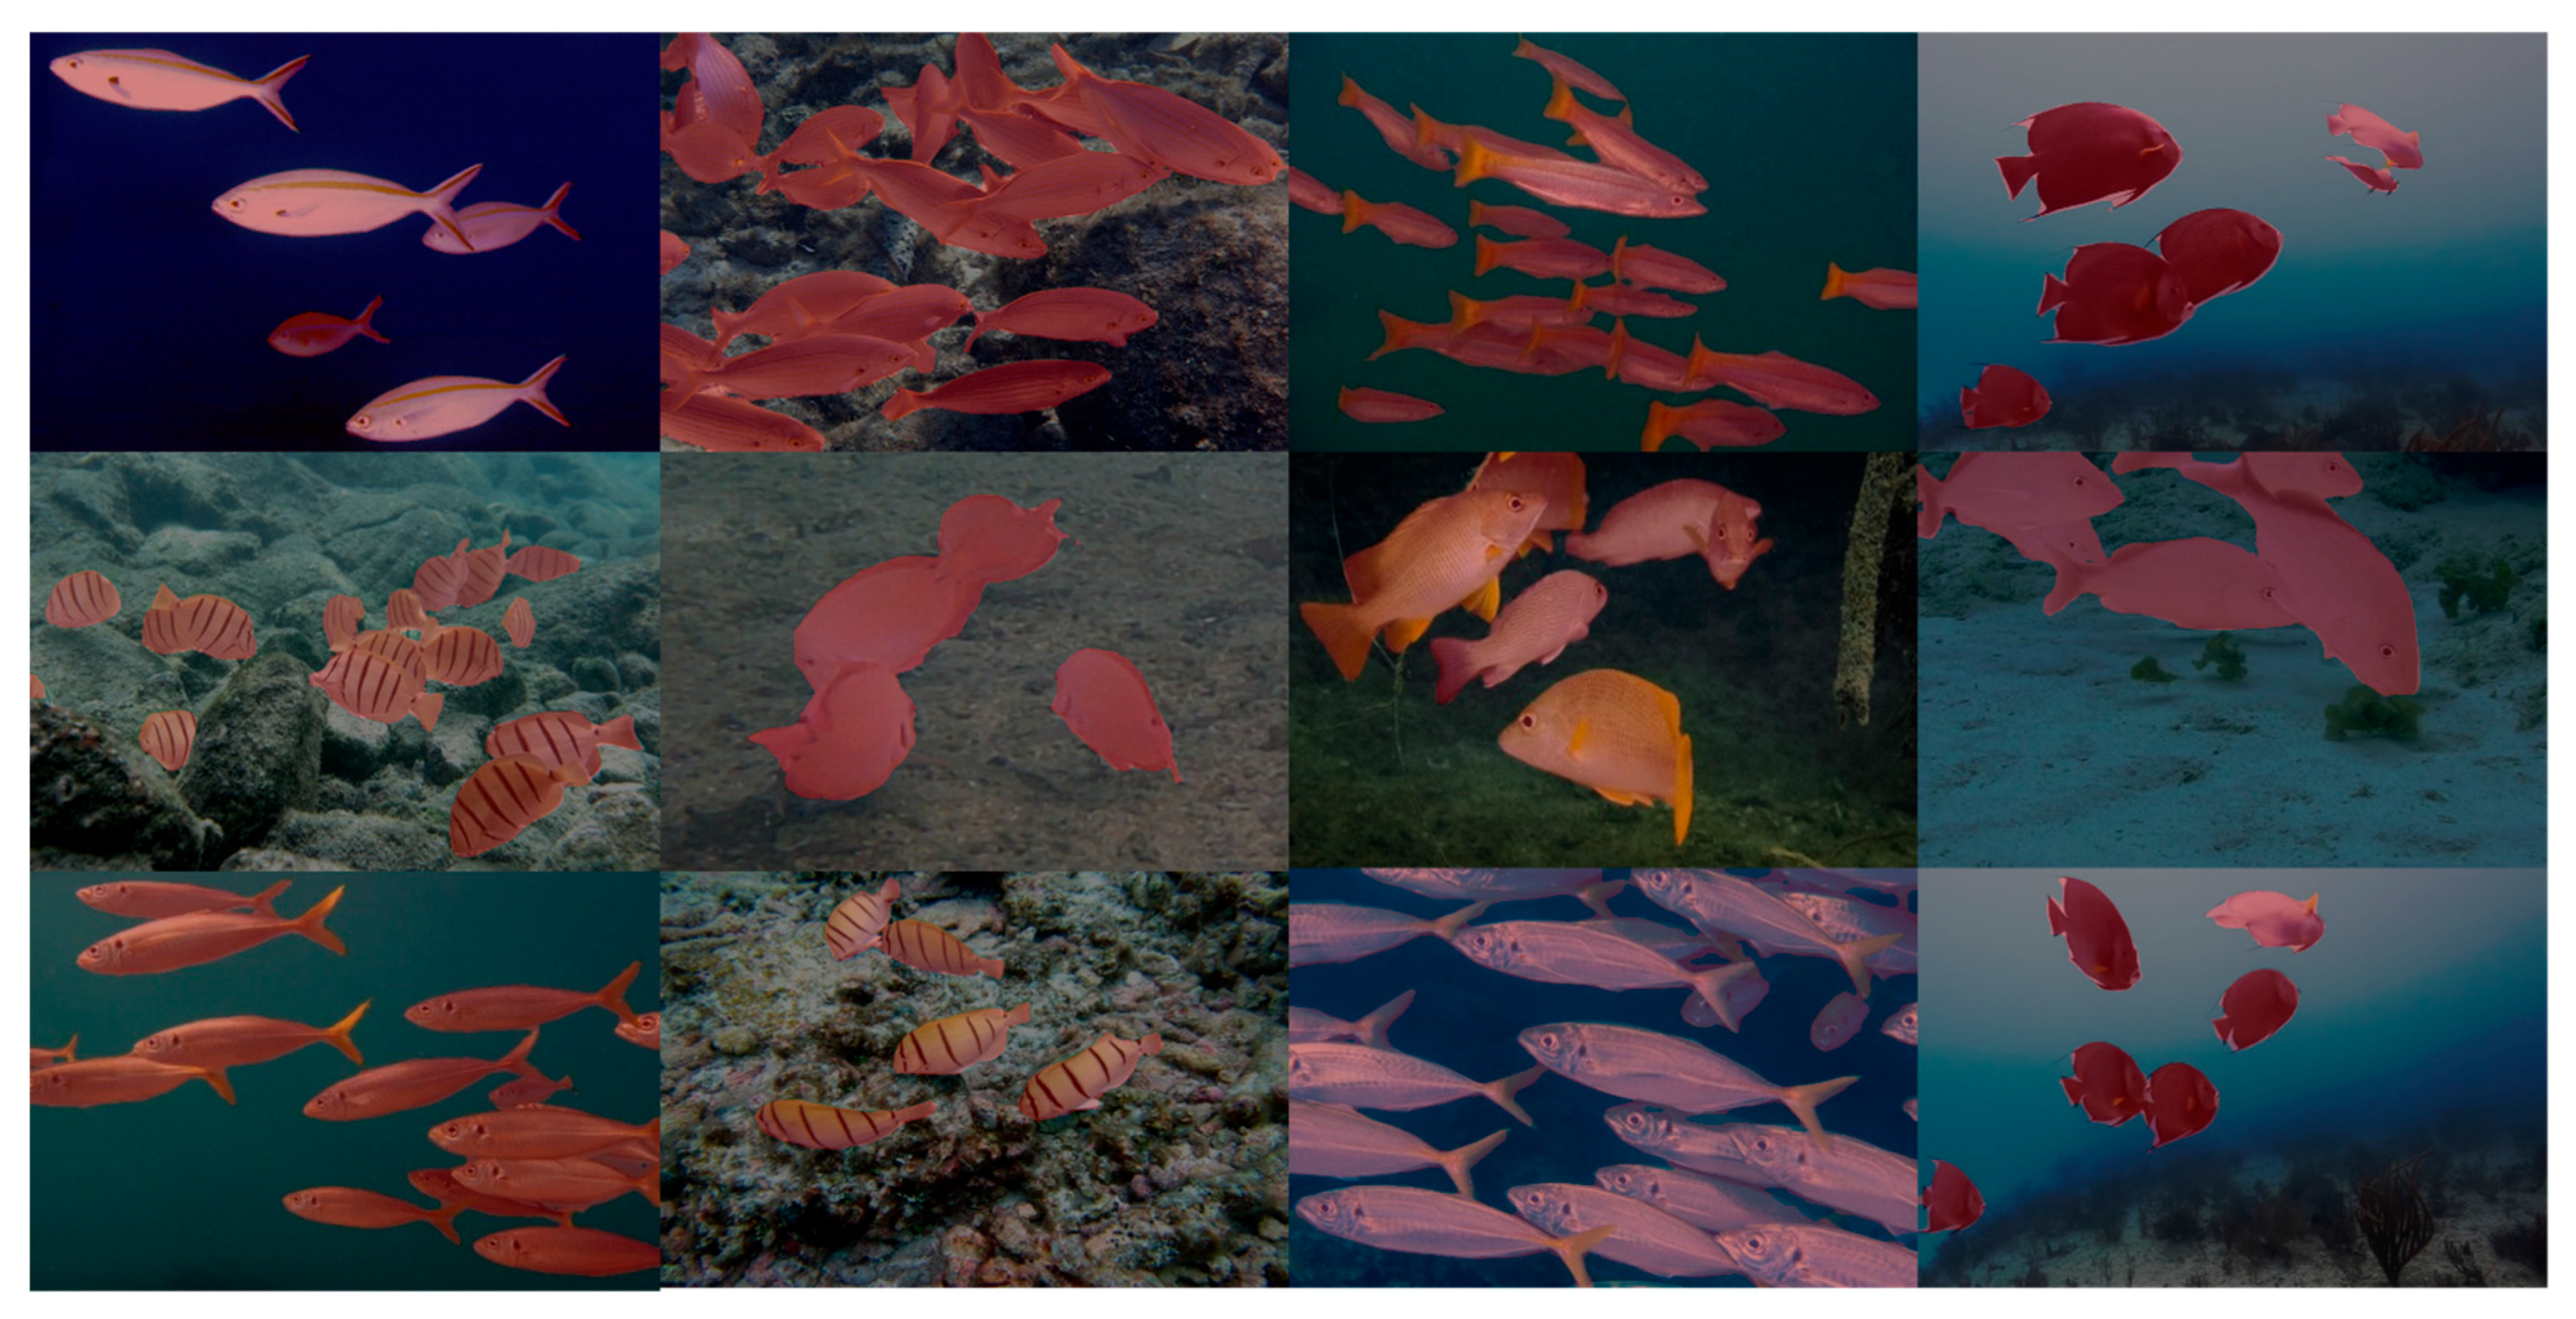
3.4. Evaluation of the Semantic Segmentation Model in LYCD
3.5. Ablation Study
3.5.1. The Ablation Experiments of Proposed Method
3.5.2. The Ablation Experiments of Attention Modules in CDGLU
4. Discussion
5. Conclusions
Author Contributions
Funding
Institutional Review Board Statement
Informed Consent Statement
Data Availability Statement
Acknowledgments
Conflicts of Interest
References
- Zhang, W.; Belton, B.; Edwards, P.; Henriksson, P.J.G.; Little, D.C.; Newton, R.; Troell, M. Aquaculture Will Continue to Depend More on Land than Sea. Nature 2022, 603, E2–E4. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Yang, L.; Liu, Y.; Yu, H.; Fang, X.; Song, L.; Li, D.; Chen, Y. Computer Vision Models in Intelligent Aquaculture with Emphasis on Fish Detection and Behavior Analysis: A Review. Arch. Comput. Methods Eng. 2020, 28, 2785–2816. [Google Scholar] [CrossRef] [Scilit]
- Yao, H.; Duan, Q.; Li, D.; Wang, J. An Improved K-Means Clustering Algorithm for Fish Image Segmentation. Math. Comput. Model. 2013, 58, 790–798. [Google Scholar] [CrossRef] [Scilit]
- Chuang, M.-C.; Hwang, J.-N.; Williams, K.; Towler, R. Automatic Fish Segmentation via Double Local Thresholding for Trawl-Based Underwater Camera Systems. In Proceedings of the 2011 18th IEEE International Conference on Image Processing, Brussels, Belgium, 11–14 September 2011; IEEE: Piscataway, NJ, USA, 2011; pp. 3145–3148. [Google Scholar] [CrossRef] [Scilit]
- Spampinato, C.; Giordano, D.; Di Salvo, R.; Chen-Burger, Y.-H.J.; Fisher, R.B.; Nadarajan, G. Automatic Fish Classification for Underwater Species Behavior Understanding. In Proceedings of the First ACM International Workshop on Analysis and Retrieval of Tracked Events and Motion in Imagery Streams—ARTEMIS ’10, Firenze, Italy, 29 October 2010; Association for Computing Machinery: New York, NY, USA, 2010; pp. 45–50. [Google Scholar] [CrossRef] [Scilit]
- Baloch, A.; Ali, M.; Gul, F.; Basir, S.; Afzal, I. Fish Image Segmentation Algorithm (FISA) for Improving the Performance of Image Retrieval System. Int. J. Adv. Comput. Sci. Appl. 2017, 8, 396–403. [Google Scholar] [CrossRef] [Scilit]
- Wang, J.; Gong, Z.; Liu, X.; Guo, H.; Yu, D.; Ding, L. Object Detection Based on Adaptive Feature-Aware Method in Optical Remote Sensing Images. Remote Sens. 2022, 14, 3616. [Google Scholar] [CrossRef] [Scilit]
- Li, L.; Dong, B.; Rigall, E.; Zhou, T.; Dong, J.; Chen, G. Marine Animal Segmentation. IEEE Trans. Circuits Syst. Video Technol. 2022, 32, 2303–2314. [Google Scholar] [CrossRef] [Scilit]
- Hu, J.; Shen, L.; Sun, G. Squeeze-and-Excitation Networks. In Proceedings of the 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–22 June 2018; IEEE: Piscataway, NJ, USA, 2018; pp. 7132–7141. [Google Scholar] [CrossRef] [Scilit]
- Zhang, L.; Peng, T. Underwater Image Enhancement Based on Improved Adaptive MSRCR and Gamma Function. In Proceedings of the 2023 2nd International Conference on Cloud Computing, Big Data Application and Software Engineering (CBASE), Chengdu, China, 3–5 November 2023; IEEE: Piscataway, NJ, USA; Volume 33, pp. 246–252. [Google Scholar] [CrossRef] [Scilit]
- Li, D.; Yang, Y.; Zhao, S.; Yang, H. A Fish Image Segmentation Methodology in Aquaculture Environment Based on Multi-Feature Fusion Model. Mar. Environ. Res. 2023, 190, 106085. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhang, W.; Wu, C.; Bao, Z. DPANet: Dual Pooling-Aggregated Attention Network for Fish Segmentation. IET Comput. Vis. 2021, 16, 67–82. [Google Scholar] [CrossRef] [Scilit]
- Kim, Y.H.; Park, K.R. PSS-Net: Parallel Semantic Segmentation Network for Detecting Marine Animals in Underwater Scene. Front. Mar. Sci. 2022, 9, 1003568. [Google Scholar] [CrossRef] [Scilit]
- Li, D.; Yang, Y.; Zhao, S.; Ding, J. Segmentation of Underwater Fish in Complex Aquaculture Environments Using Enhanced Soft Attention Mechanism. Environ. Model. Softw. 2024, 181, 106170. [Google Scholar] [CrossRef] [Scilit]
- Yu, X.; Liu, J.; Huang, J.; Zhao, F.; Wang, Y.; An, D.; Zhang, T. Enhancing Instance Segmentation: Leveraging Multiscale Feature Fusion and Attention Mechanisms for Automated Fish Weight Estimation. Aquac. Eng. 2024, 106, 102427. [Google Scholar] [CrossRef] [Scilit]
- Xie, E.; Wang, W.; Yu, Z.; Anandkumar, A.; Álvarez, J.M.A.; Luo, P. SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers. In Proceedings of the NIPS ’21: Proceedings of the 35th International Conference on Neural Information Processing Systems, Virtual, 6–14 December 2021; Curran Associates Inc.: Red Hook, NY, USA, 2021; pp. 12077–12090. [Google Scholar]
- Guo, M.-H.; Lu, C.-Z.; Hou, Q.; Liu, Z.; Cheng, M.-M.; Hu, S.-M. SegNeXt: Rethinking Convolutional Attention Design for Semantic Segmentation. arXiv 2022, arXiv:2209.08575. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Lin, Y.; Cao, Y.; Hu, H.; Wei, Y.; Zhang, Z.; Lin, S.; Guo, B. Swin Transformer: Hierarchical Vision Transformer Using Shifted Windows. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV), Montreal, QC, Canada, 10–17 October 2021; IEEE: Piscataway, NJ, USA, 2021; pp. 9992–10002. [Google Scholar] [CrossRef] [Scilit]
- Chen, L.-C.; Zhu, Y.; Papandreou, G.; Schroff, F.; Adam, H. Encoder-Decoder with Atrous Separable Convolution for Semantic Image Segmentation. In Proceedings of the Computer Vision—ECCV 2018, Munich, Germany, 8–14 September 2018; Springer-Verlag: Berlin/Heidelberg, Germany, 2018; pp. 833–851. [Google Scholar] [CrossRef] [Scilit]
- Ronneberger, O.; Fischer, P.; Brox, T. U-Net: Convolutional Networks for Biomedical Image Segmentation. In Proceedings of the Medical Image Computing and Computer-Assisted Intervention—MICCAI 2015, Munich, Germany, 5–9 October 2015; Springer: Berlin/Heidelberg, Germany, 2015; Volume 9351, pp. 234–241. [Google Scholar] [CrossRef] [Scilit]
- Shi, D. TransNeXt: Robust Foveal Visual Perception for Vision Transformers. In Proceedings of the 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 17–21 June 2024; IEEE: Piscataway, NJ, USA, 2024; Volume 3361, pp. 17773–17783. [Google Scholar] [CrossRef] [Scilit]
- Islam, M.J.; Edge, C.; Xiao, Y.; Luo, P.; Mehtaz, M.; Morse, C.; Enan, S.S.; Sattar, J. Semantic Segmentation of Underwater Imagery: Dataset and Benchmark. In Proceedings of the 2020 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), Las Vegas, NV, USA, 25–29 October 2020. [Google Scholar] [CrossRef] [Scilit]
- Lian, S.; Li, H.; Cong, R.; Li, S.; Zhang, W.; Kwong, S. WaterMask: Instance Segmentation for Underwater Imagery. In Proceedings of the 2023 IEEE/CVF International Conference on Computer Vision (ICCV), Paris, France, 1–6 October 2023; IEEE: Piscataway, NJ, USA, 2023; pp. 1305–1315. [Google Scholar] [CrossRef] [Scilit]
- Lian, S.; Zhang, Z.; Li, H.; Li, W.; Yang, L.T.; Kwong, S.; Cong, R. Diving into Underwater: Segment Anything Model Guided Underwater Salient Instance Segmentation and a Large-Scale Dataset. In Proceedings of the ICML’24: Proceedings of the 41st International Conference on Machine Learning, Vienna, Austria, 21–27 July 2024; JMLR.org: Norfolk, MA, USA, 2024; pp. 29545–29559. [Google Scholar]
- Yang, M.; Sowmya, A. An Underwater Color Image Quality Evaluation Metric. IEEE Trans. Image Process. 2015, 24, 6062–6071. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Panetta, K.; Gao, C.; Agaian, S.S. Human-Visual-System-Inspired Underwater Image Quality Measures. IEEE J. Ocean. Eng. 2016, 41, 541–551. [Google Scholar] [CrossRef] [Scilit]
- Srivastava, R.K.; Greff, K.; Schmidhuber, J. Highway Networks. arXiv 2015, arXiv:1505.00387. [Google Scholar] [CrossRef] [Scilit]
- Dauphin, Y.N.; Fan, A.; Auli, M.; Grangier, D. Language Modeling with Gated Convolutional Networks. In Proceedings of the 34th International Conference on Machine Learning, Sydney, Australia, 6–11 August 2017; PMLR: New York, NY, USA, 2017; Volume 70, pp. 933–941. [Google Scholar]
- van den Oord, A.; Kalchbrenner, N.; Vinyals, O.; Espeholt, L.; Graves, A.; Kavukcuoglu, K. Conditional Image Generation with PixelCNN Decoders. arXiv 2016, arXiv:1606.05328. [Google Scholar] [CrossRef] [Scilit]
- Ramachandran, P.; Parmar, N.; Vaswani, A.; Bello, I.; Levskaya, A.; Shlens, J. Stand-Alone Self-Attention in Vision Models. In Proceedings of the NIPS’19: Proceedings of the 33rd International Conference on Neural Information Processing Systems, Vancouver, BC, Canada, 8–14 December 2019; Cornell Curran Associates Inc.: Red Hook, NY, USA, 2019; pp. 68–80. [Google Scholar]
- Ioffe, S.; Szegedy, C. Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift. In Proceedings of the 32nd International Conference on Machine Learning, Lille, France, 6–11 July 2015; PMLR: New York, NY, USA, 2015; Volume 37, pp. 448–456. [Google Scholar]
- Wu, Y.; He, K. Group Normalization. Int. J. Comput. Vis. 2019, 128, 742–755. [Google Scholar] [CrossRef] [Scilit]
- Woo, S.; Park, J.; Lee, J.-Y.; Kweon, I.S. CBAM: Convolutional Block Attention Module. In Proceedings of the Computer Vision—ECCV 2018: 15th European Conference, Munich, Germany, 8–14 September 2018; Proceedings, Part VII. Springer: Berlin/Heidelberg, Germany, 2018; pp. 3–19. [Google Scholar] [CrossRef] [Scilit]
- Wang, Q.; Wu, B.; Zhu, P.; Li, P.; Zuo, W.; Hu, Q. ECA-Net: Efficient Channel Attention for Deep Convolutional Neural Networks. In Proceedings of the 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16–18 June 2020; IEEE: Piscataway, NJ, USA, 2020; pp. 11531–11539. [Google Scholar] [CrossRef] [Scilit]
- Yang, L.; Zhang, R.-Y.; Li, L.; Xie, X. SimAM: A Simple, Parameter-Free Attention Module for Convolutional Neural Networks. In Proceedings of the 38th International Conference on Machine Learning, Virtual, 18–24 July 2021; PMLR: New York, NY, USA, 2021; Volume 139, pp. 11863–11874. [Google Scholar]
- Li, J.; Hu, Y.; Huang, X. CaSaFormer: A Cross- and Self-Attention Based Lightweight Network for Large-Scale Building Semantic Segmentation. Int. J. Appl. Earth Obs. Geoinf. 2024, 130, 103942. [Google Scholar] [CrossRef] [Scilit]
- Han, D.; Ye, T.; Han, Y.; Xia, Z.; Pan, S.; Wan, P.; Song, S.; Huang, G. Agent Attention: On the Integration of Softmax and Linear Attention. In Proceedings of the Computer Vision—ECCV 2024, Milan, Italy, 29 September–4 October 2024; Springer: Berlin/Heidelberg, Germany, 2024; Volume 15108, pp. 124–140. [Google Scholar] [CrossRef] [Scilit]
- Si, Y.; Xu, H.; Zhu, X.; Zhang, W.; Dong, Y.; Chen, Y.; Li, H. SCSA: Exploring the Synergistic Effects between Spatial and Channel Attention. Neurocomputing 2025, 634, 129866. [Google Scholar] [CrossRef] [Scilit]
- Xiao, T.; Liu, Y.; Zhou, B.; Jiang, Y.; Sun, J. Unified Perceptual Parsing for Scene Understanding. arXiv 2018, arXiv:1807.10221. [Google Scholar] [CrossRef] [Scilit]



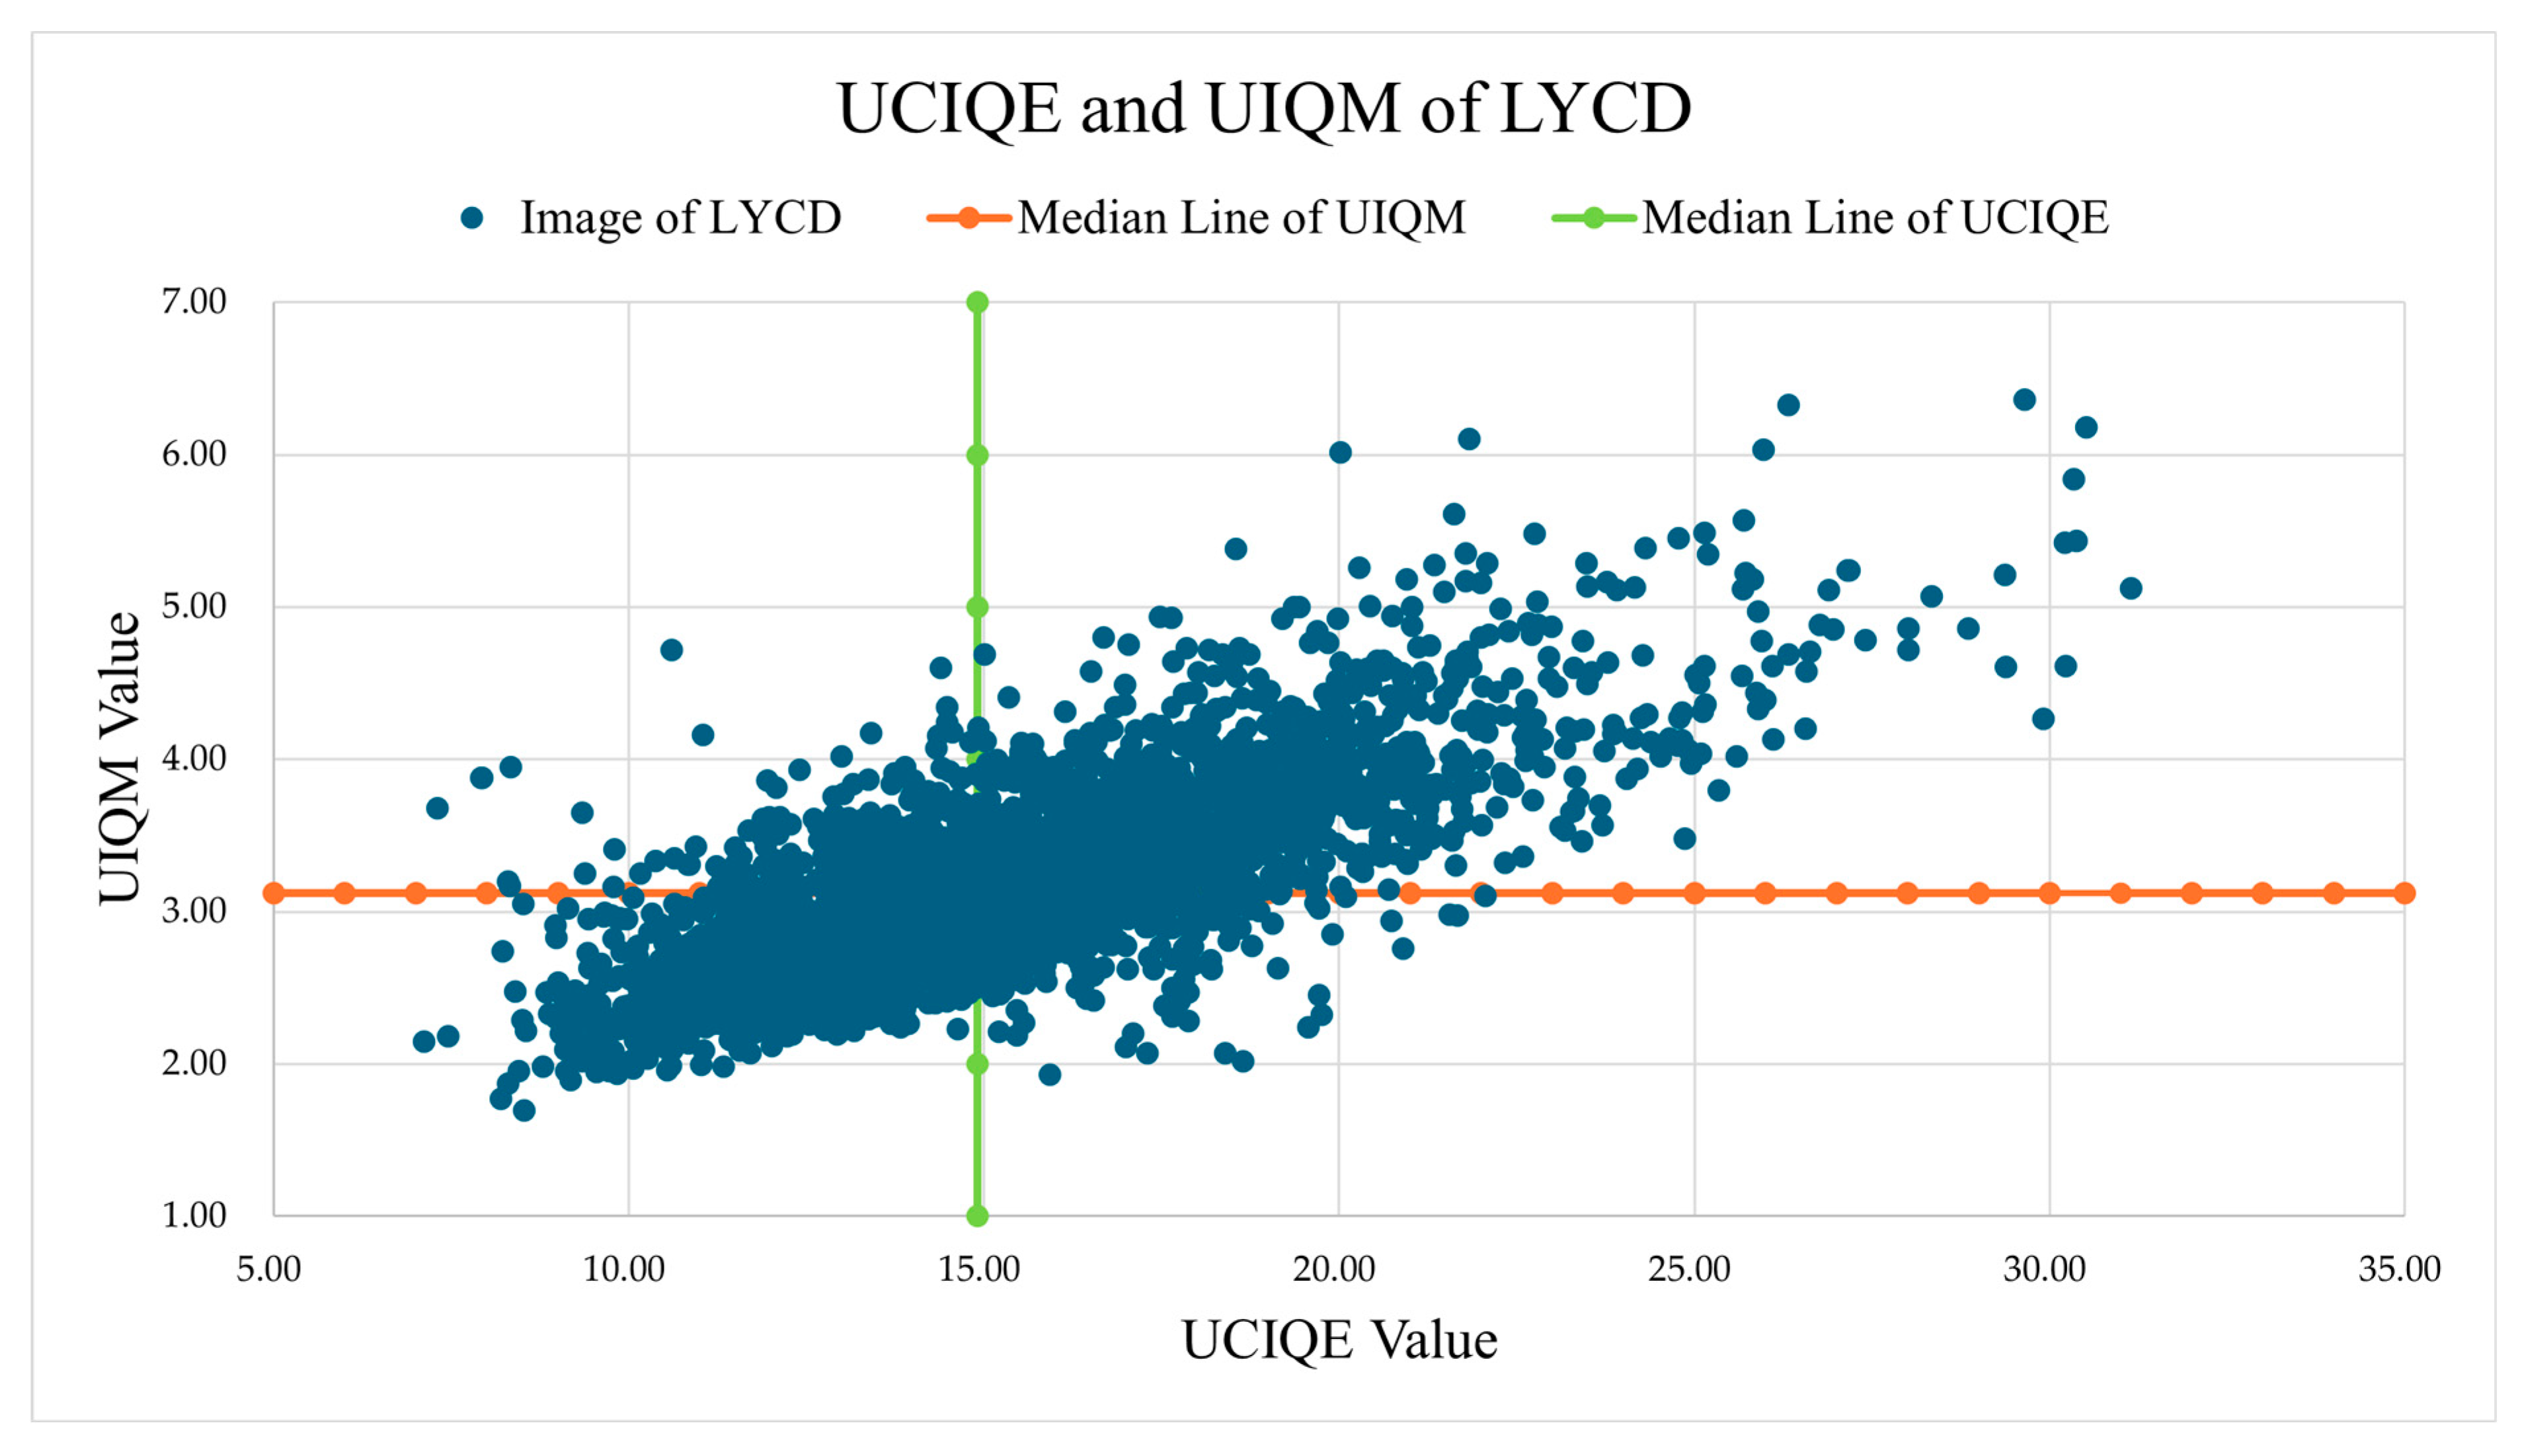
| Image Quality Metrics | Range | Variance | Mean | Median |
|---|---|---|---|---|
| UIQM | 1.69–6.36 | 0.42 | 3.20 | 3.21 |
| UCIQE | 7.12–31.14 | 8.14 | 12.47 | 14.91 |
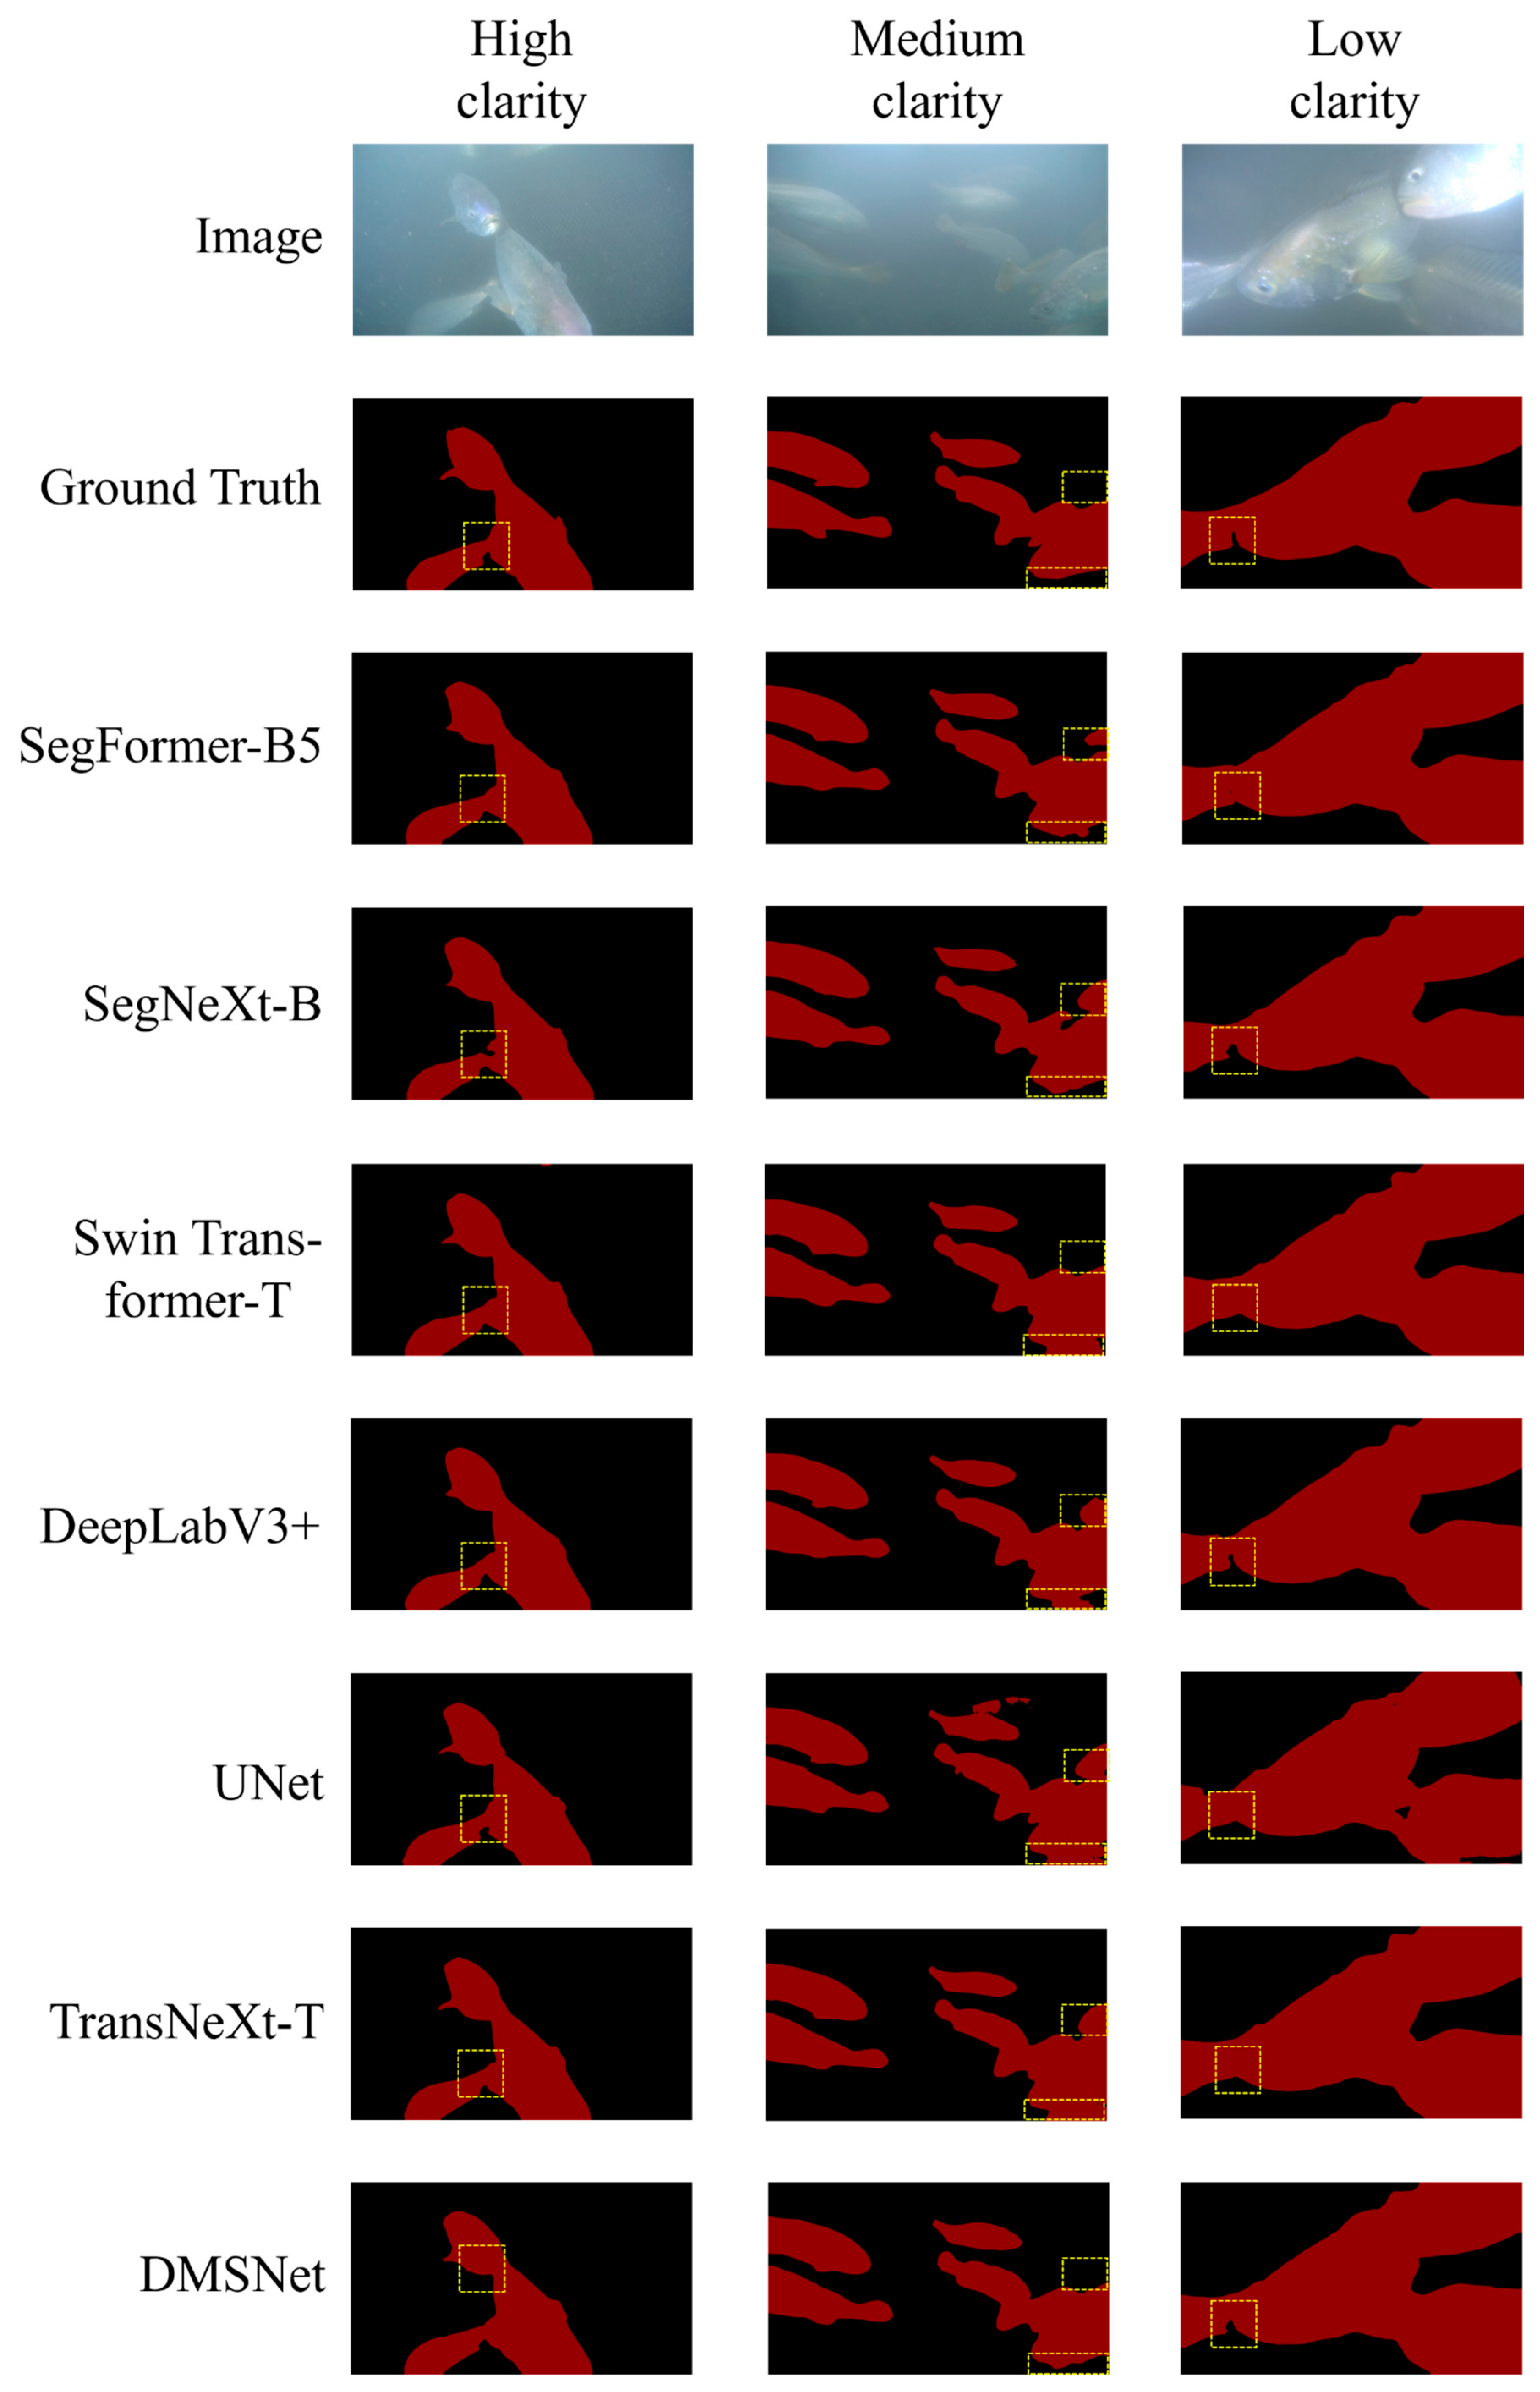
| Image Quality Level | Number of Samples | Percentage of Total Samples | Metrics Range |
|---|---|---|---|
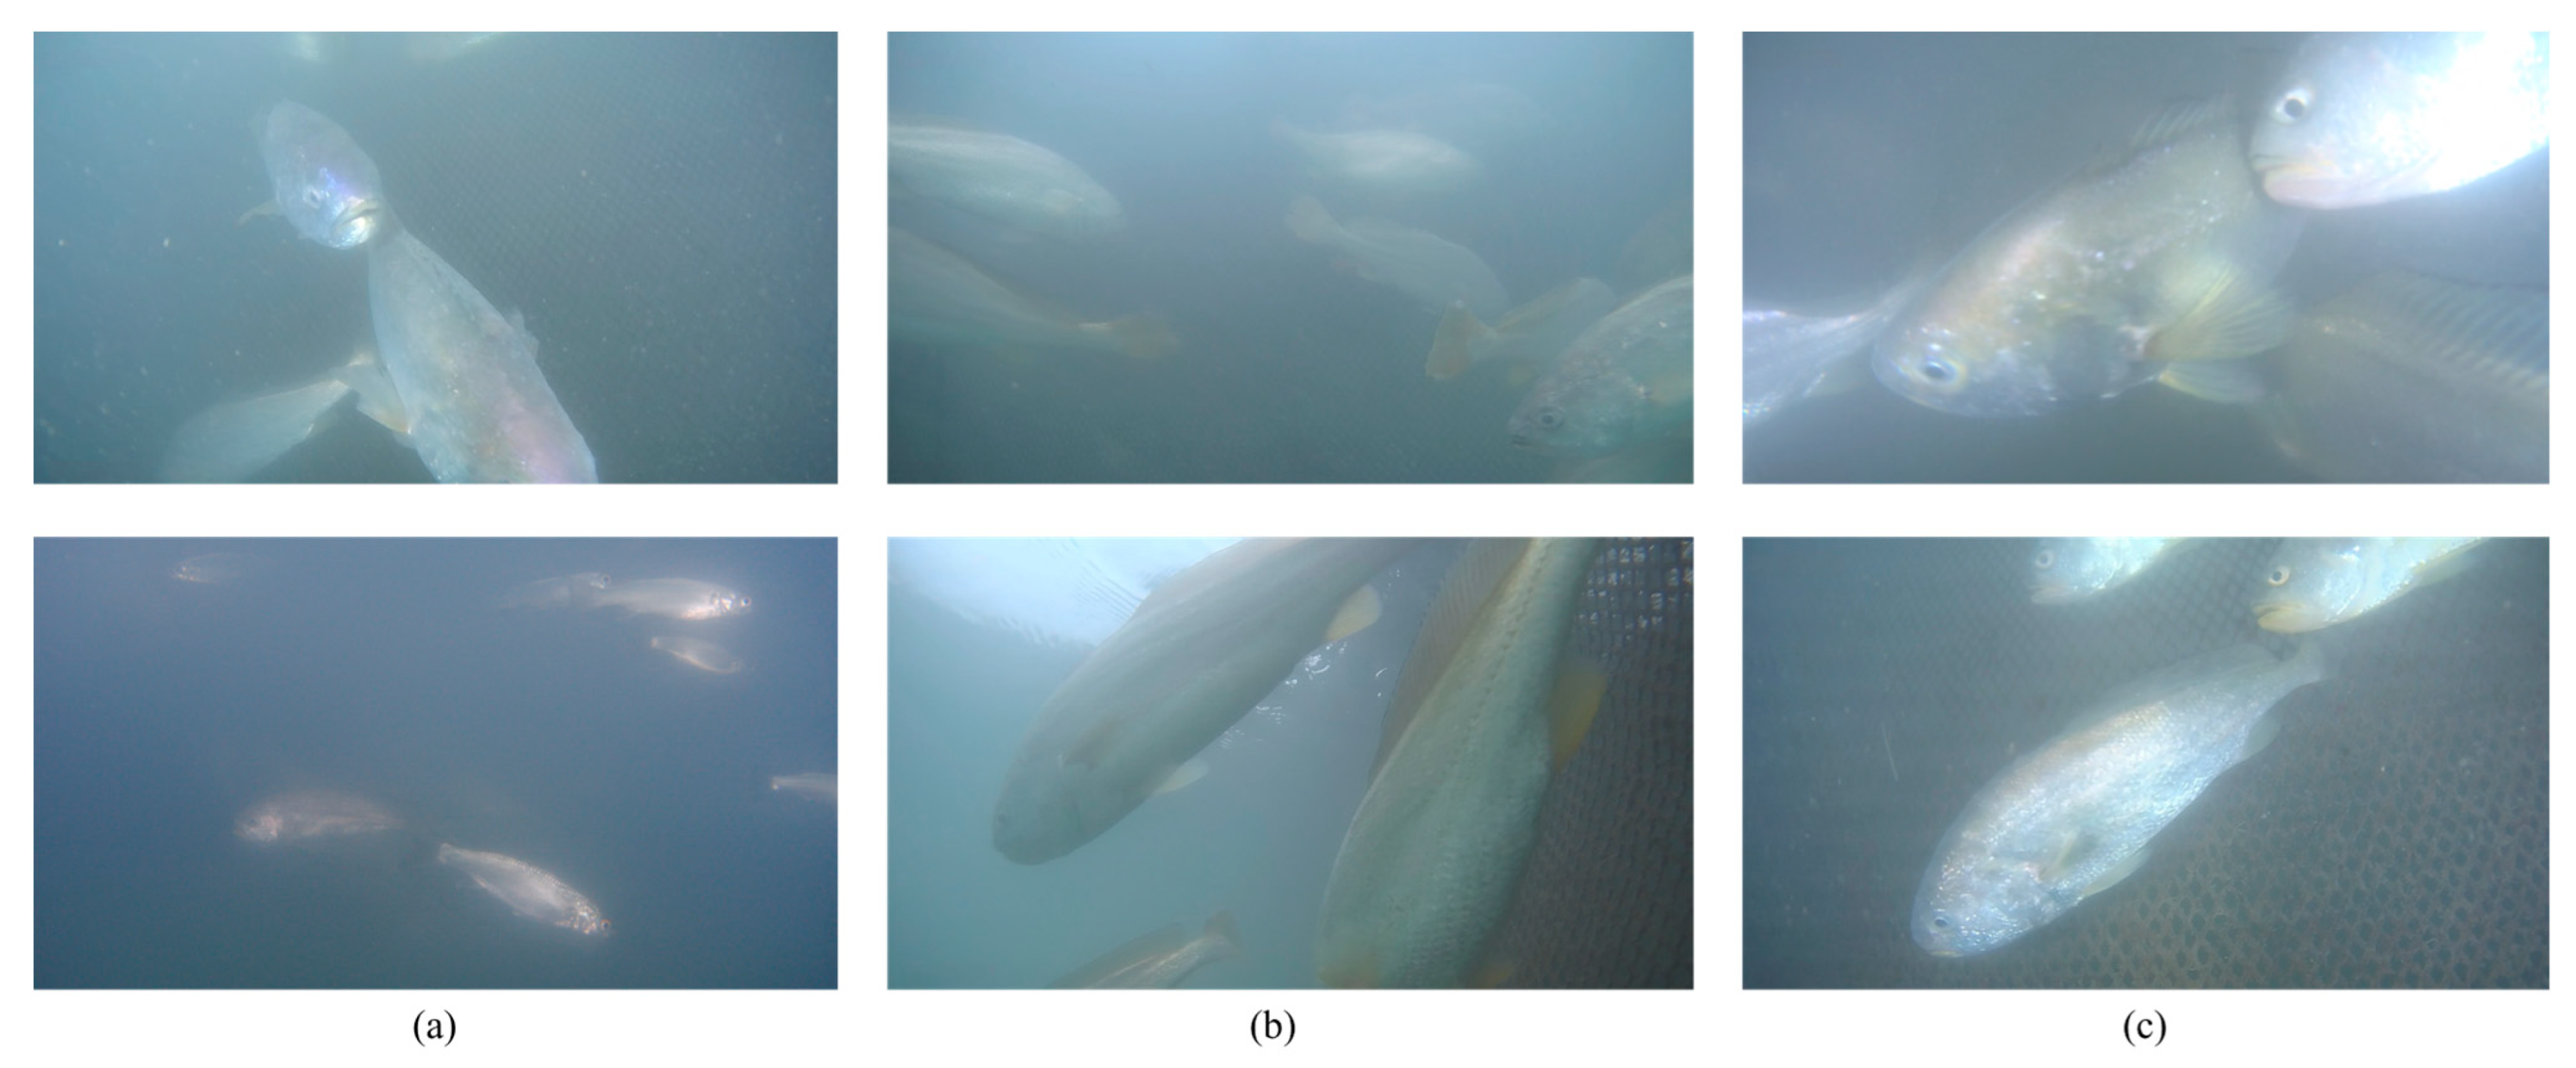
| High clarity | 1173 | 39.1% | UIQM ≥ 3.21 and UCIQE ≥ 14.91 |
| Medium clarity | 654 | 21.8 | Rest of Range |
| Low clarity | 1173 | 39.1% | UIQM ≤ 3.21 and UCIQE ≤ 14.91 |
| Actual Positive | Actual Negative | |
|---|---|---|
| Predicted Positive | TP (True Positive) | FP (False Positive) |
| Predicted Negative | FN (False Negative) | TN (True Negative) |
| Methods | PA/% | mCPA/% | mIoU/% | mF1/% | Param/M |
|---|---|---|---|---|---|
| SegFormer-B5 | 90.76 | 82.32 | 79.28 | 76.08 | 81.97 |
| SegNeXt-B | 90.44 | 84.61 | 78.23 | 78.38 | 27.56 |
| Swin-Transformer-T | 89.91 | 83.07 | 76.41 | 84.20 | 58.94 |
| DeepLabV3+ | 90.1 | 82.37 | 76.65 | 84.34 | 60.2 |
| UNet | 90.27 | 83.48 | 77.45 | 84.88 | 17.91 |
| TransNeXt-T | 90.11 | 83.69 | 77.08 | 84.65 | 28.2 |
| DMSNet | 92.87 | 87.54 | 81.79 | 88.31 | 35.03 |
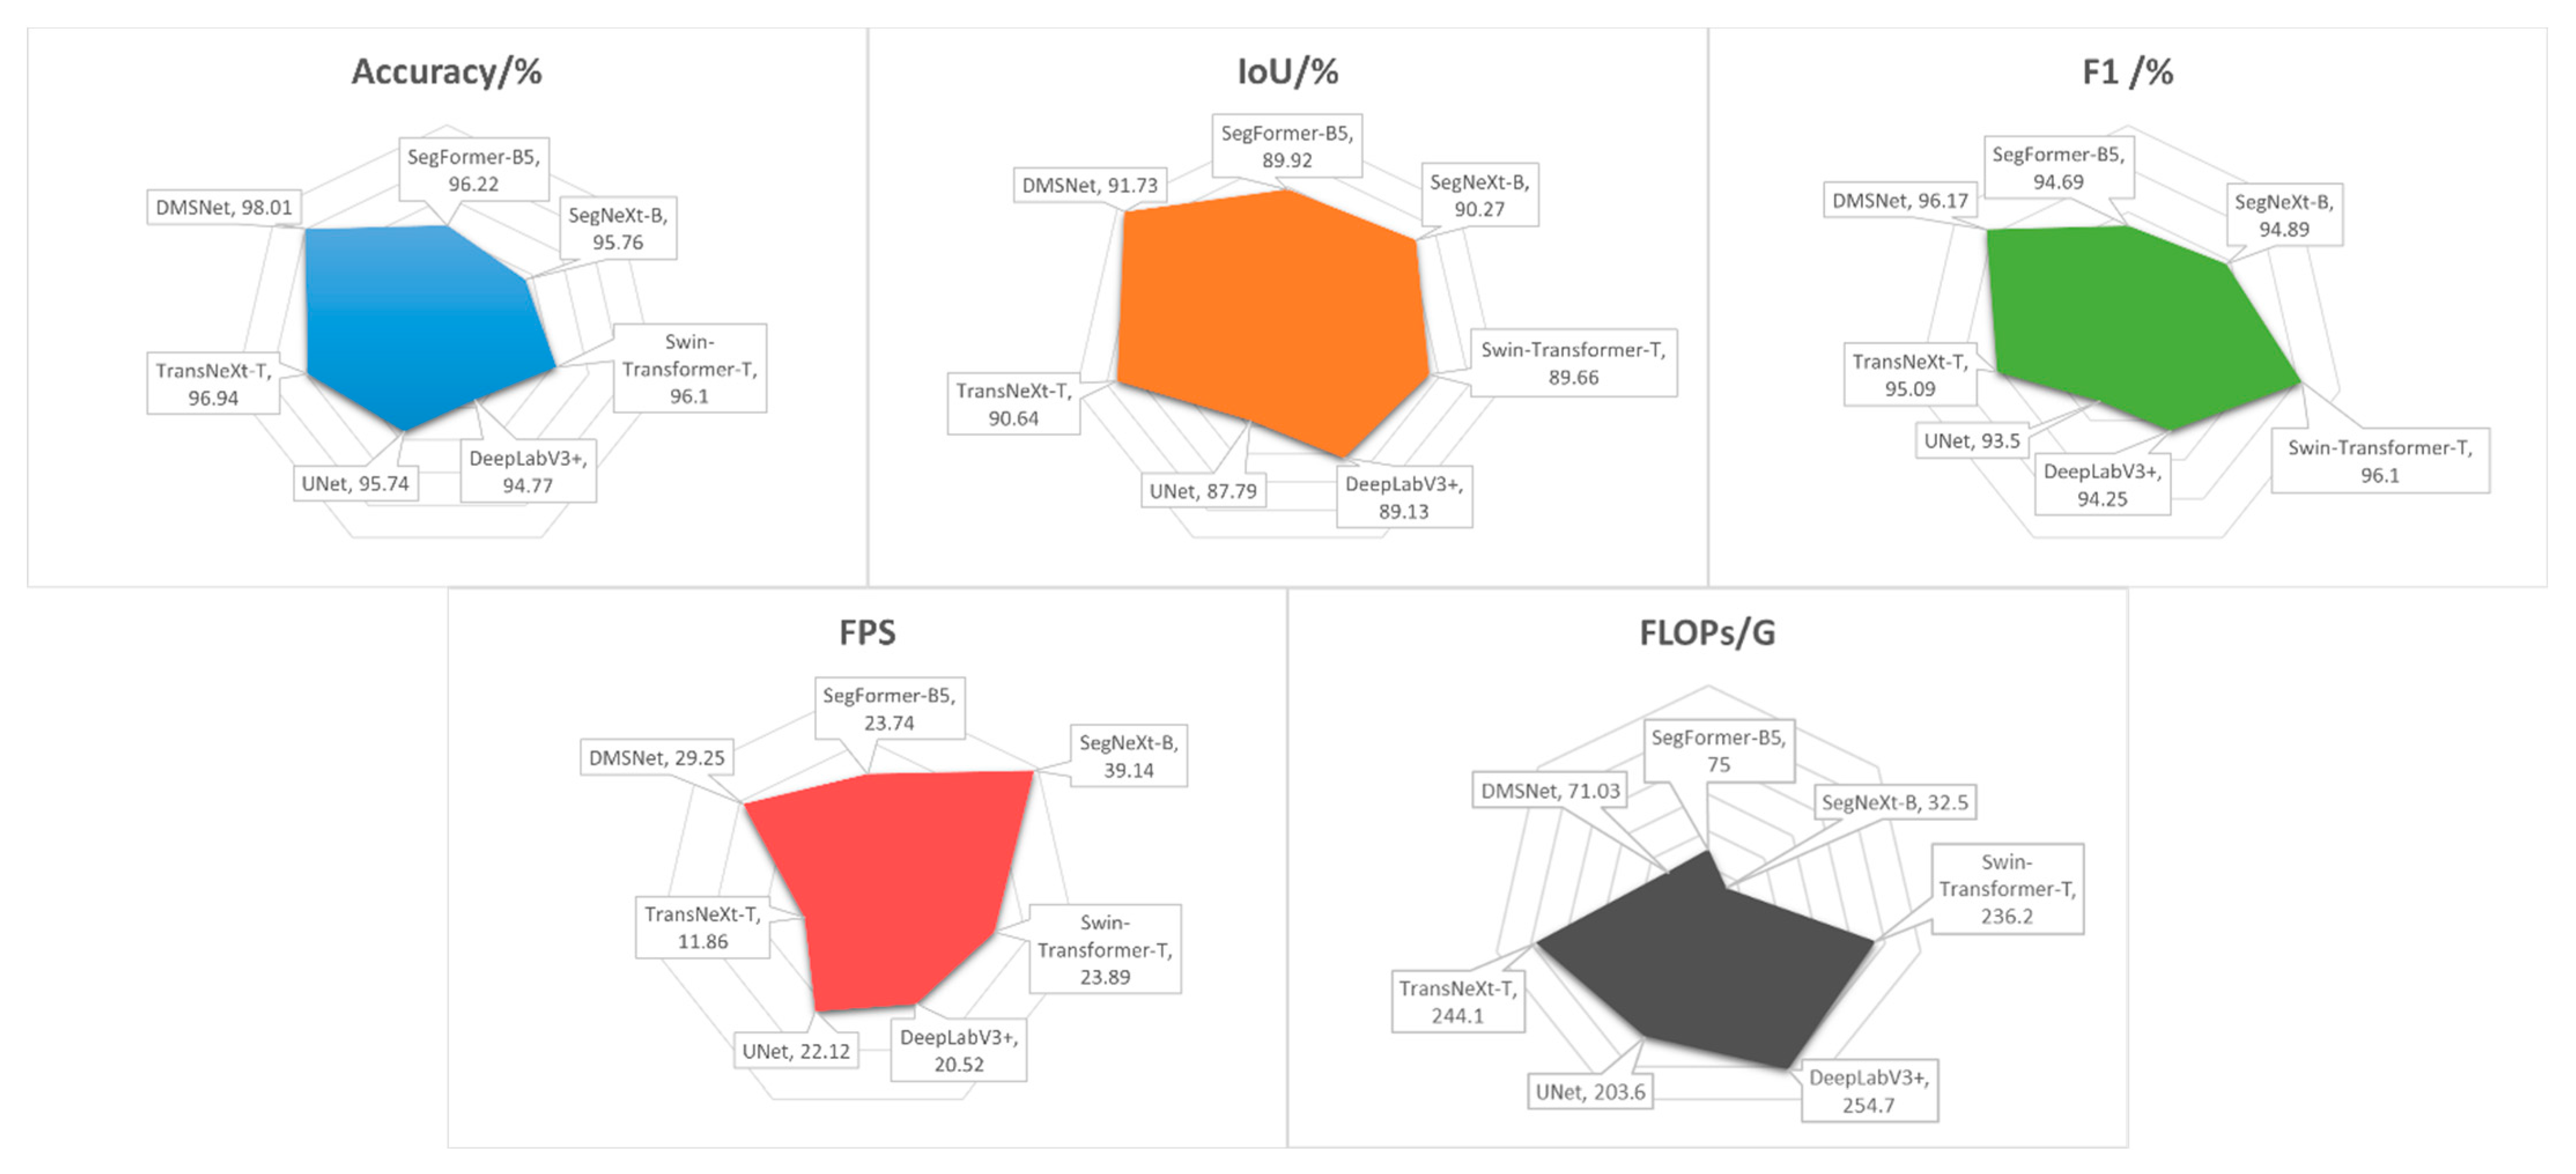
| Method | Accuracy/% | IoU/% | F1/% | FPS | FLOPs/G |
|---|---|---|---|---|---|
| SegFormer-B5 | 96.22 | 89.92 | 94.69 | 23.74 | 75.0 |
| SegNeXt-B | 95.76 | 90.27 | 94.89 | 39.14 | 32.5 |
| Swin-Transformer-T | 96.10 | 89.66 | 96.10 | 23.89 | 236.2 |
| DeepLabV3+ | 94.77 | 89.13 | 94.25 | 20.52 | 254.7 |
| UNet | 95.74 | 87.79 | 93.50 | 22.12 | 203.6 |
| TransNeXt-T | 96.94 | 90.64 | 95.09 | 11.86 | 244.1 |
| DMSNet | 98.01 | 91.73 | 96.17 | 29.25 | 71.03 |
| Method | Accuracy/% | IoU/% | F1/% | FPS | FLOPs/G |
|---|---|---|---|---|---|
| SegFormer-B5 | 95.75 | 89.33 | 94.69 | 23.74 | 75.0 |
| SegNeXt-B | 95.07 | 89.84 | 94.89 | 39.14 | 32.5 |
| Swin-Transformer-T | 95.90 | 89.22 | 96.10 | 23.89 | 236.2 |
| DeepLabV3+ | 94.32 | 88.68 | 94.25 | 20.52 | 254.7 |
| UNet | 95.18 | 87.16 | 93.50 | 22.12 | 203.6 |
| TransNeXt-T | 96.49 | 89.96 | 95.09 | 11.86 | 244.1 |
| DMSNet | 96.79 | 91.31 | 96.17 | 29.25 | 71.03 |
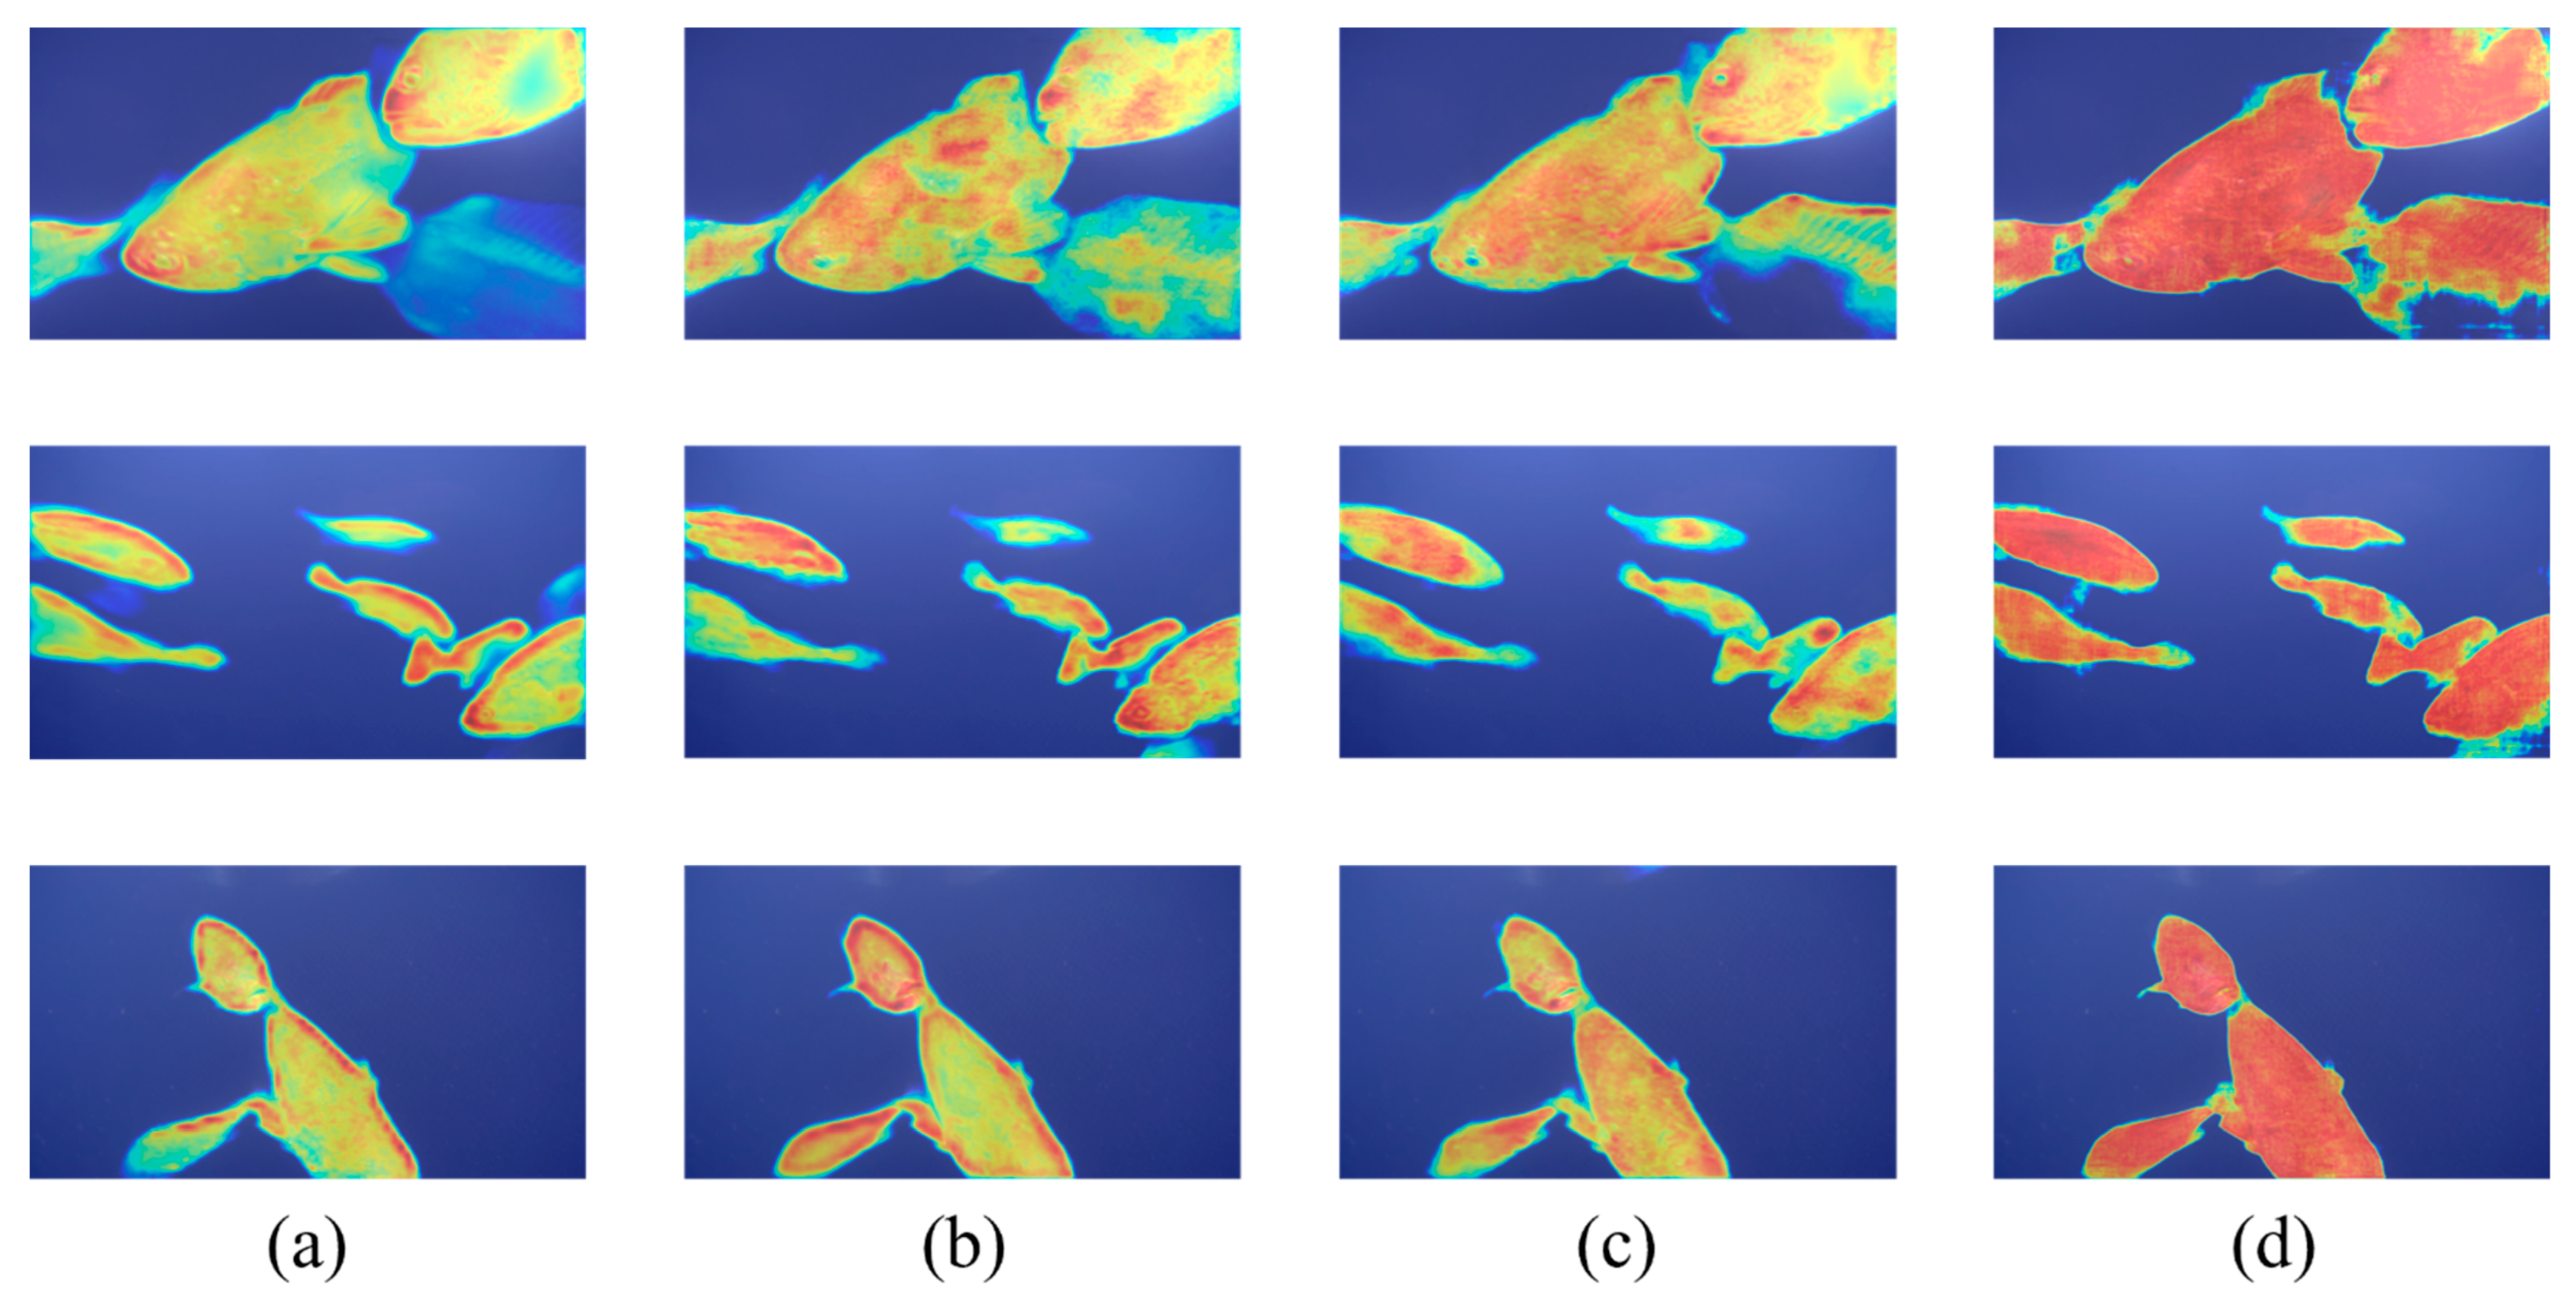
| Stage | Baseline | CDGLU | PCSA | ACAF | Acc/% | IoU/% | F1/% | FLOPs/G | Param/M | FPS |
|---|---|---|---|---|---|---|---|---|---|---|
| (a) | √ | × | × | × | 89.76 | 81.38 | 86.95 | 62.31 | 32.17 | 33.31 |
| (b) | √ | √ | × | × | 91.33 | 83.82 | 88.93 | 64.0 | 32.72 | 32.35 |
| (c) | √ | √ | √ | × | 94.82 | 85.60 | 92.71 | 68.0 | 33.12 | 30.47 |
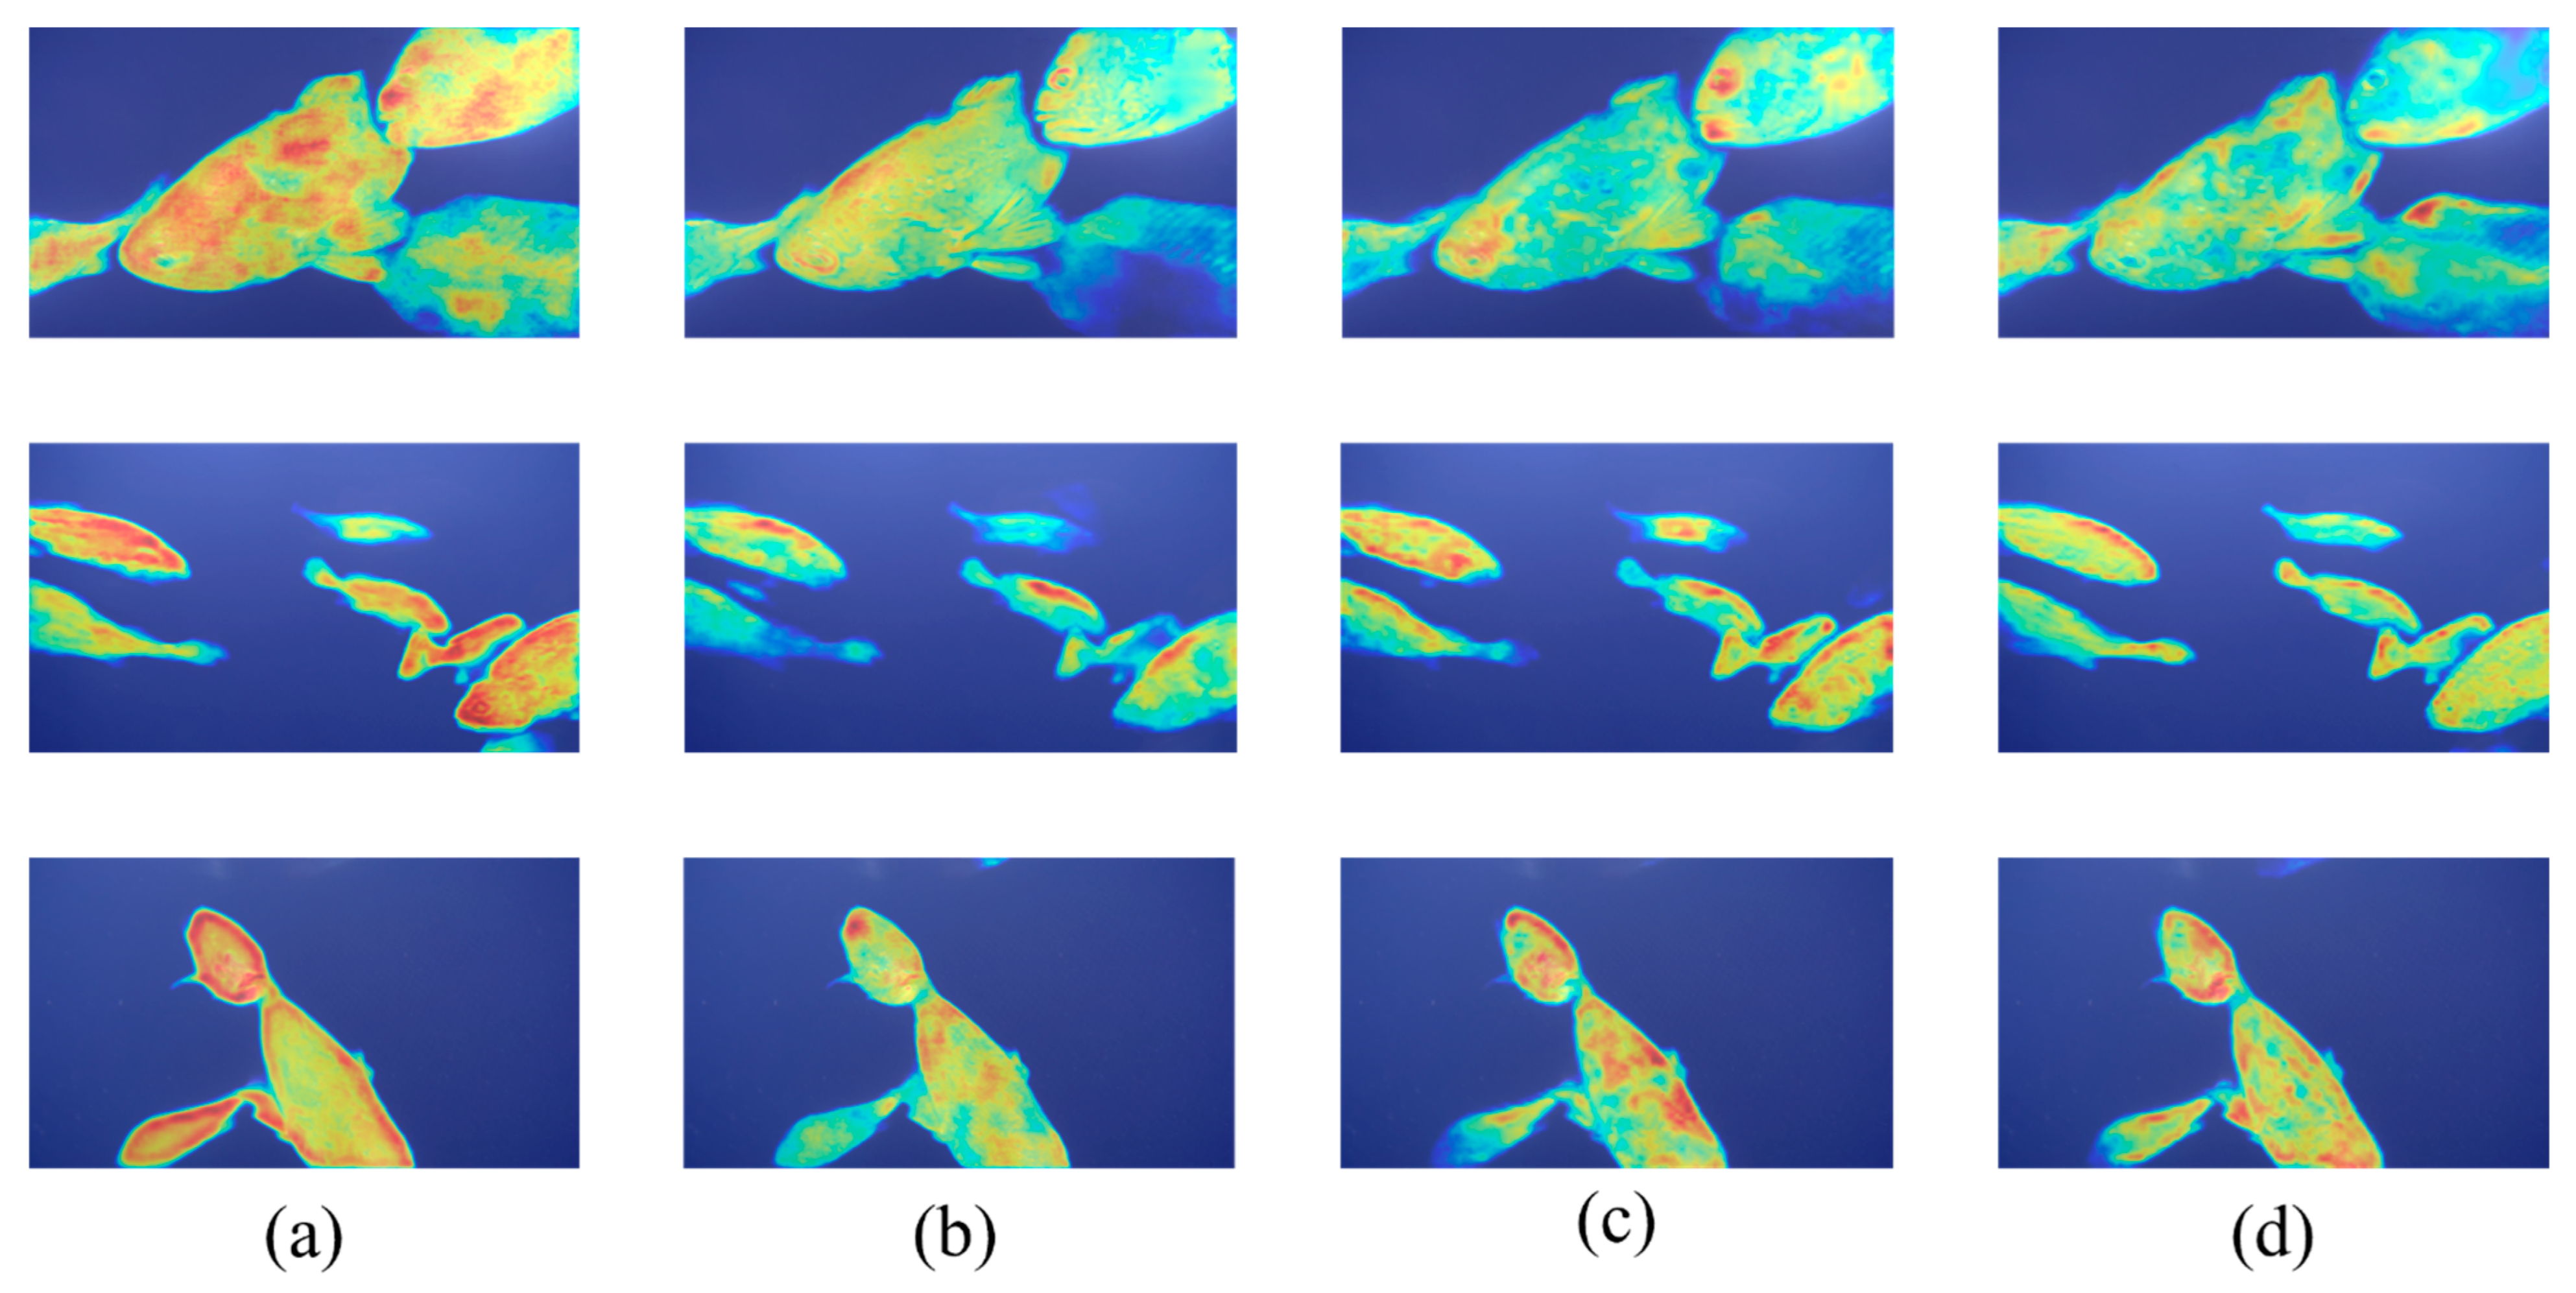
| (d) | √ | √ | √ | √ | 98.01 | 91.73 | 96.17 | 71.03 | 35.51 | 29.25 |
| Condition | Methods | Acc/% | IoU/% | F1/% | FLOPs/G | Param/M | FPS |
|---|---|---|---|---|---|---|---|
| (a) | CDGLU-ECANet | 91.33 | 83.82 | 88.93 | 64.0 | 32.72 | 32.35 |
| (b) | CDGLU-SE | 91.38 | 83.87 | 88.99 | 75.39 | 32.72 | 27.46 |
| (c) | CDGLU-CBAM | 91.53 | 84.03 | 89.86 | 77.30 | 32.73 | 26.78 |
| (d) | CDGLU-SimAM | 91.0 | 82.99 | 88.10 | 64.0 | 32.75 | 32.32 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).
Share and Cite
Wang, C.; Zhang, Z.; Shao, J.; Liao, N.; Que, P.; Kong, X.; Zhang, T. DMSNet: A Dynamic Multi-Scale Feature Fusion Segmentation Network for Precise Large Yellow Croaker Recognition in Complex Underwater Conditions. Fishes 2025, 10, 613. https://doi.org/10.3390/fishes10120613
Wang C, Zhang Z, Shao J, Liao N, Que P, Kong X, Zhang T. DMSNet: A Dynamic Multi-Scale Feature Fusion Segmentation Network for Precise Large Yellow Croaker Recognition in Complex Underwater Conditions. Fishes. 2025; 10(12):613. https://doi.org/10.3390/fishes10120613
Chicago/Turabian StyleWang, Can, Zhouming Zhang, Jianchun Shao, Naiyu Liao, Pengrong Que, Xiangzeng Kong, and Tingting Zhang. 2025. "DMSNet: A Dynamic Multi-Scale Feature Fusion Segmentation Network for Precise Large Yellow Croaker Recognition in Complex Underwater Conditions" Fishes 10, no. 12: 613. https://doi.org/10.3390/fishes10120613
APA StyleWang, C., Zhang, Z., Shao, J., Liao, N., Que, P., Kong, X., & Zhang, T. (2025). DMSNet: A Dynamic Multi-Scale Feature Fusion Segmentation Network for Precise Large Yellow Croaker Recognition in Complex Underwater Conditions. Fishes, 10(12), 613. https://doi.org/10.3390/fishes10120613