1. Introduction
Pressure is placed on educators, students, and their families to identify effective preparation methods for examinations, given their significant influence on admission decisions for undergraduate programs and institutions [
1]. Especially in English-language instructions, exams usually test the four main skills of reading, writing, listening, and speaking to assess individual learning capabilities.
English learning in a traditional classroom is generally effective at helping students acquire new skills, but it often struggles to provide personalized feedback, targeted support, and long-term motivation for students of different skill levels. One-on-one tutoring is often an effective way to deliver and improve individualized learning. By talking to them directly, tutors can determine what students need to work on, build on what they already know, and adapt lessons to fit each student’s needs [
2,
3].
In the last few years, hybrid teaching models have become more popular. They combine in-person interaction with online learning activities that utilize communication technology. This approach makes learning more accessible and flexible and makes it easier to manage resources in terms of time, place, and money while giving students more opportunities to practice [
4,
5]. Gudoniene et al.’s [
6] study identified hybrid teaching systems that not only leverage the advantages of both physical and digital environments but also offer learners diverse modalities, convenient and consistent learning and practice, adaptable scheduling, access to a wide range of resources, and immediate feedback. Many studies on English language education have investigated blended methodologies for specific skills, including reading [
7], writing [
8], listening [
9], and speaking [
10]. Also, research on individualized one-on-one instruction emphasizes the importance of interpersonal communication in encouraging learner confidence and addressing specific learning weaknesses [
11].
Blended learning and individualized tutoring have been extensively studied [
12]; however, research has rarely examined hybrid one-on-one tutoring models that merge the individualized attention of tutoring with the flexibility and technological features of hybrid instructional delivery. Research gaps have been identified in understanding the impacts of combining models for long-term skill development and sustained student engagement in preparing for high-stakes examinations. Addressing this gap is critical to enhancing educational strategies and informing effective improvement practices.
In recent years, Artificial Intelligence (AI) has provided various tools that promise to address these challenges. Many AI-based systems have been studied to deliver language education support by utilizing Natural Language Processing (NLP), Automatic Speech Recognition (ASR), and machine learning algorithms to provide objective and real-time feedback across multiple skills [
13]. In addition, AI-based scoring systems have been developed to evaluate essay writing for grammar [
14], coherence [
15], and lexical sophistication [
16]; to assess speaking for fluency [
17] and pronunciation [
18]; and to analyze reading comprehension accuracy [
19]. AI feedback capabilities enable continuous formative assessment, allowing both learners and instructors to identify progress trends, determine areas requiring skills-targeted attention, and optimize instructional time. They also facilitate personalized learning pathways to adjust content, difficulty levels, resource types, and feedback methods based on a learner’s performance history, such as through adaptive e-learning systems [
20]. Numerous prior studies on AI efficacy have identified a limitation: the lack of real-time feedback on contextually relevant data [
21]. Numerous assessment systems utilizing AI exclusively depend on user inputs, such as recorded audio or typed text. Generally, user inputs inadequately address essential components of learning processes, including engagement levels, behavioral indicators, and contextual factors influencing learning outcomes.
Existing studies on ASR systems highlight the challenges and opportunities in low-resource, real-world, and embedded environments, particularly for educational and assistive applications. Yadava et al. [
22] focused on ASR development for a low-resource language in noisy, uncontrolled environments. By integrating noise reduction techniques and time-delay neural network (TDNN) models, the system achieved measurable improvements in recognition accuracy. The importance of robust preprocessing, noise handling, and lightweight modeling strategies for real-time ASR deployment in practical applications was also highlighted. Mulfari et al. [
23] demonstrated that convolutional neural network (CNN)-based ASR models using MFCC features can be effectively deployed on resource-constrained devices while maintaining acceptable word error rates, even for atypical speech such as dysarthria. The study emphasized the importance of low computational overhead, reduced latency, and real-time feasibility, positioning edge-based ASR as an alternative to cloud-dependent systems. Fatehi et al. [
24] conducted a survey and experimental evaluation of ASR models originally trained in high-resource environments. The results showed that models optimized for large-scale datasets often perform poorly when directly applied to low-resource settings. They argued that pre-training on high-resource data followed by domain-specific fine-tuning is more effective than increasing model complexity, underlining the need to balance recognition accuracy with data availability and computational efficiency. Ahlawat et al. [
25] presented an overview of ASR evolution, covering hybrid models, end-to-end deep learning approaches, Transformers, and multilingual systems. While the survey highlighted significant advances in recognition accuracy, it also identified limitations related to data dependency, generalization across domains, and real-time deployment constraints. The study concluded that accuracy alone is insufficient for practical ASR deployment and that latency, scalability, and performance efficiency must be considered, especially for embedded and IoT-based systems.
The Internet of Things (IoT), when used as edge computing, enables real-time data collection through interconnected sensors and actuators, fostering confidence in its ability to deliver continuous, immediate insights in educational and monitoring environments [
26]. Examples of IoT-based learning include facial expression analysis [
27] and the monitoring of interaction frequency and learner activity engagement [
28], which not only provide real-time [
29] datasets and promptly inform instructional decision-making but also enable the individualization of language-learning conditions and strategies to meet the specific improvement needs of each student.
Artificial Internet of Things (AIoT), which combines AI and IoT, supports personalized, learner-focused experiences by enabling adaptive mobility, real-time interactions, and efficient device connectivity. Previous studies have demonstrated that AIoT is effective in meeting students’ needs, which can increase student engagement and academic performance [
13,
30,
31], as well as in developing an awareness of the learning environment in both primary schools and post-secondary education [
32], introducing students to digital skills, supporting learning equity, and preparing students for the many challenges of a rapidly changing digital world. Another study included issues concerning data privacy, infrastructure limitations, resource scarcity, and scalable solutions [
33].
Our study proposes an AIoT hybrid tutoring framework built on ASR AI running on IoT platforms to provide an affordable, accurate, flexible, energy-efficient, and mobile solution for English language learning and exam preparation. The AI speech testing exam is implemented on Raspberry Pi 4 and Pi 5 architectures. The system provides a centralized information dashboard and compiles individual and group historical data on learners’ performance in AI-based English speech assessments. Although the initial development stage emphasizes the English speech-test module, the system architecture promises to extend the design to support all four language skills: listening, speaking, reading, and writing. The architectural framework offers several benefits by creating new learning opportunities for students and innovative teaching tools for educators.
The research questions of this study seek to bridge the gap between individualized one-on-one learning improvement and automated real-time AIoT English skill assessments.
- (1)
How can a hybrid one-on-one tutoring framework based on AIoT be designed to support real-time evaluation of English speech performance using cost-effective embedded hardware?
- (2)
How do different ASR engines, specifically the open-source Whisper and Vosk, perform in terms of accuracy, latency, and efficiency within the AIoT architectural platforms for the development of English speech assessments?
- (3)
To what extent can the AIoT hybrid tutoring framework enhance learner engagement within hybrid one-on-one tutoring, motivation, and measurable progress in English speech proficiency?
The contributions of this study are threefold.
- (1)
The creation of a hybrid tutoring system that is AIoT-based and combines real-time English speech assessments with language performance analytics to facilitate individualized hybrid one-on-one English learning.
- (2)
The speaking test module is evaluated in the empirical study of AIoT architectural platforms, which includes the comparative benchmarking of ASR engines, the analysis of performance metrics on AIoT devices, and the evaluation of English speech assessment accuracy.
- (3)
The system establishes technological and pedagogical standards for the implementation of AIoT frameworks in hybrid one-on-one tutoring to enhance learner engagement, motivation, and achievement.
There are five parts to this article. The Related Work Section examines earlier studies on IoT in education, AI-driven language testing, hybrid learning environments, and personalized tutoring systems. The Materials and Methods Section described the suggested AIoT tutoring framework in detail, including hardware and software setups, ASR models, the AI processing pipeline, the system architecture, and evaluation methods. The Results and Discussion Section presents the most important results and how they should be interpreted. The Conclusions Section summarizes the study’s main contributions, discusses the real-life implications of the proposed system, and suggests directions for further research.
3. Materials and Methods
In this section, the development and validation of an AIoT hybrid tutoring system for real-time English speech proficiency assessment, along with the methodology, are described. For this study, only speaking ability was evaluated due to its potential for automated processing via ASR, its direct relationship to communicative competence, and its high complexity. The hybrid framework uses both ASR models and an IoT-enabled web platform to allow students to complete a speaking task and receive immediate, data-driven feedback. To compare two model families of ASR capabilities, two ASR models were used: Whisper (version v20250625—four variants in multiple quantization formats—tiny, base, small, and medium English models) [
76,
77] and Vosk (version commit a428d65—small and large English models) [
78,
79]. To measure recognition accuracy, fluency, and computational efficiency for each model, 100 repeated trials were run under identical test conditions. In addition to measuring the performance metrics of the models using word error rate (WER), accuracy percentage, recall, words per minute (WPM), pause ratio, fillers per minute, band fluency, band pronunciation, band prosody, overall speaking band, processing time, CPU utilization, memory consumption, etc., results were also visualized as a dashboard to enable learners and instructors to view results immediately following the completion of the test.
Students chose from different levels of test difficulties and time allocations, after which the system generated a random test passage. Students then completed a test within 5–7 min while speech was recorded at 16 kHz, mono, in WebM format. Following completion of the test, the resulting audio was converted into MP4 format and processed by the selected ASR model. Immediately after the test, results were displayed on the dashboard for the students and instructors to view.
Since this study did not involve any medical or psychological interventions, it did not require formal ethical approval. However, in compliance with data privacy regulations, the study implemented all necessary anonymization procedures. The study removed identifiable information from all student responses, and all audio recordings were stored on encrypted servers. All source code, configuration files, and datasets will be made available for replication and further research, except for third-party-licensed models.
3.1. AIoT Hybrid Tutoring Framework
The proposed hybrid tutoring model based on AI and IoT consists of a multilayer structure [
80]. It has been developed to provide an assessment and feedback process concerning real-time, English-speaking assessment in one-to-one tutoring settings. As depicted in
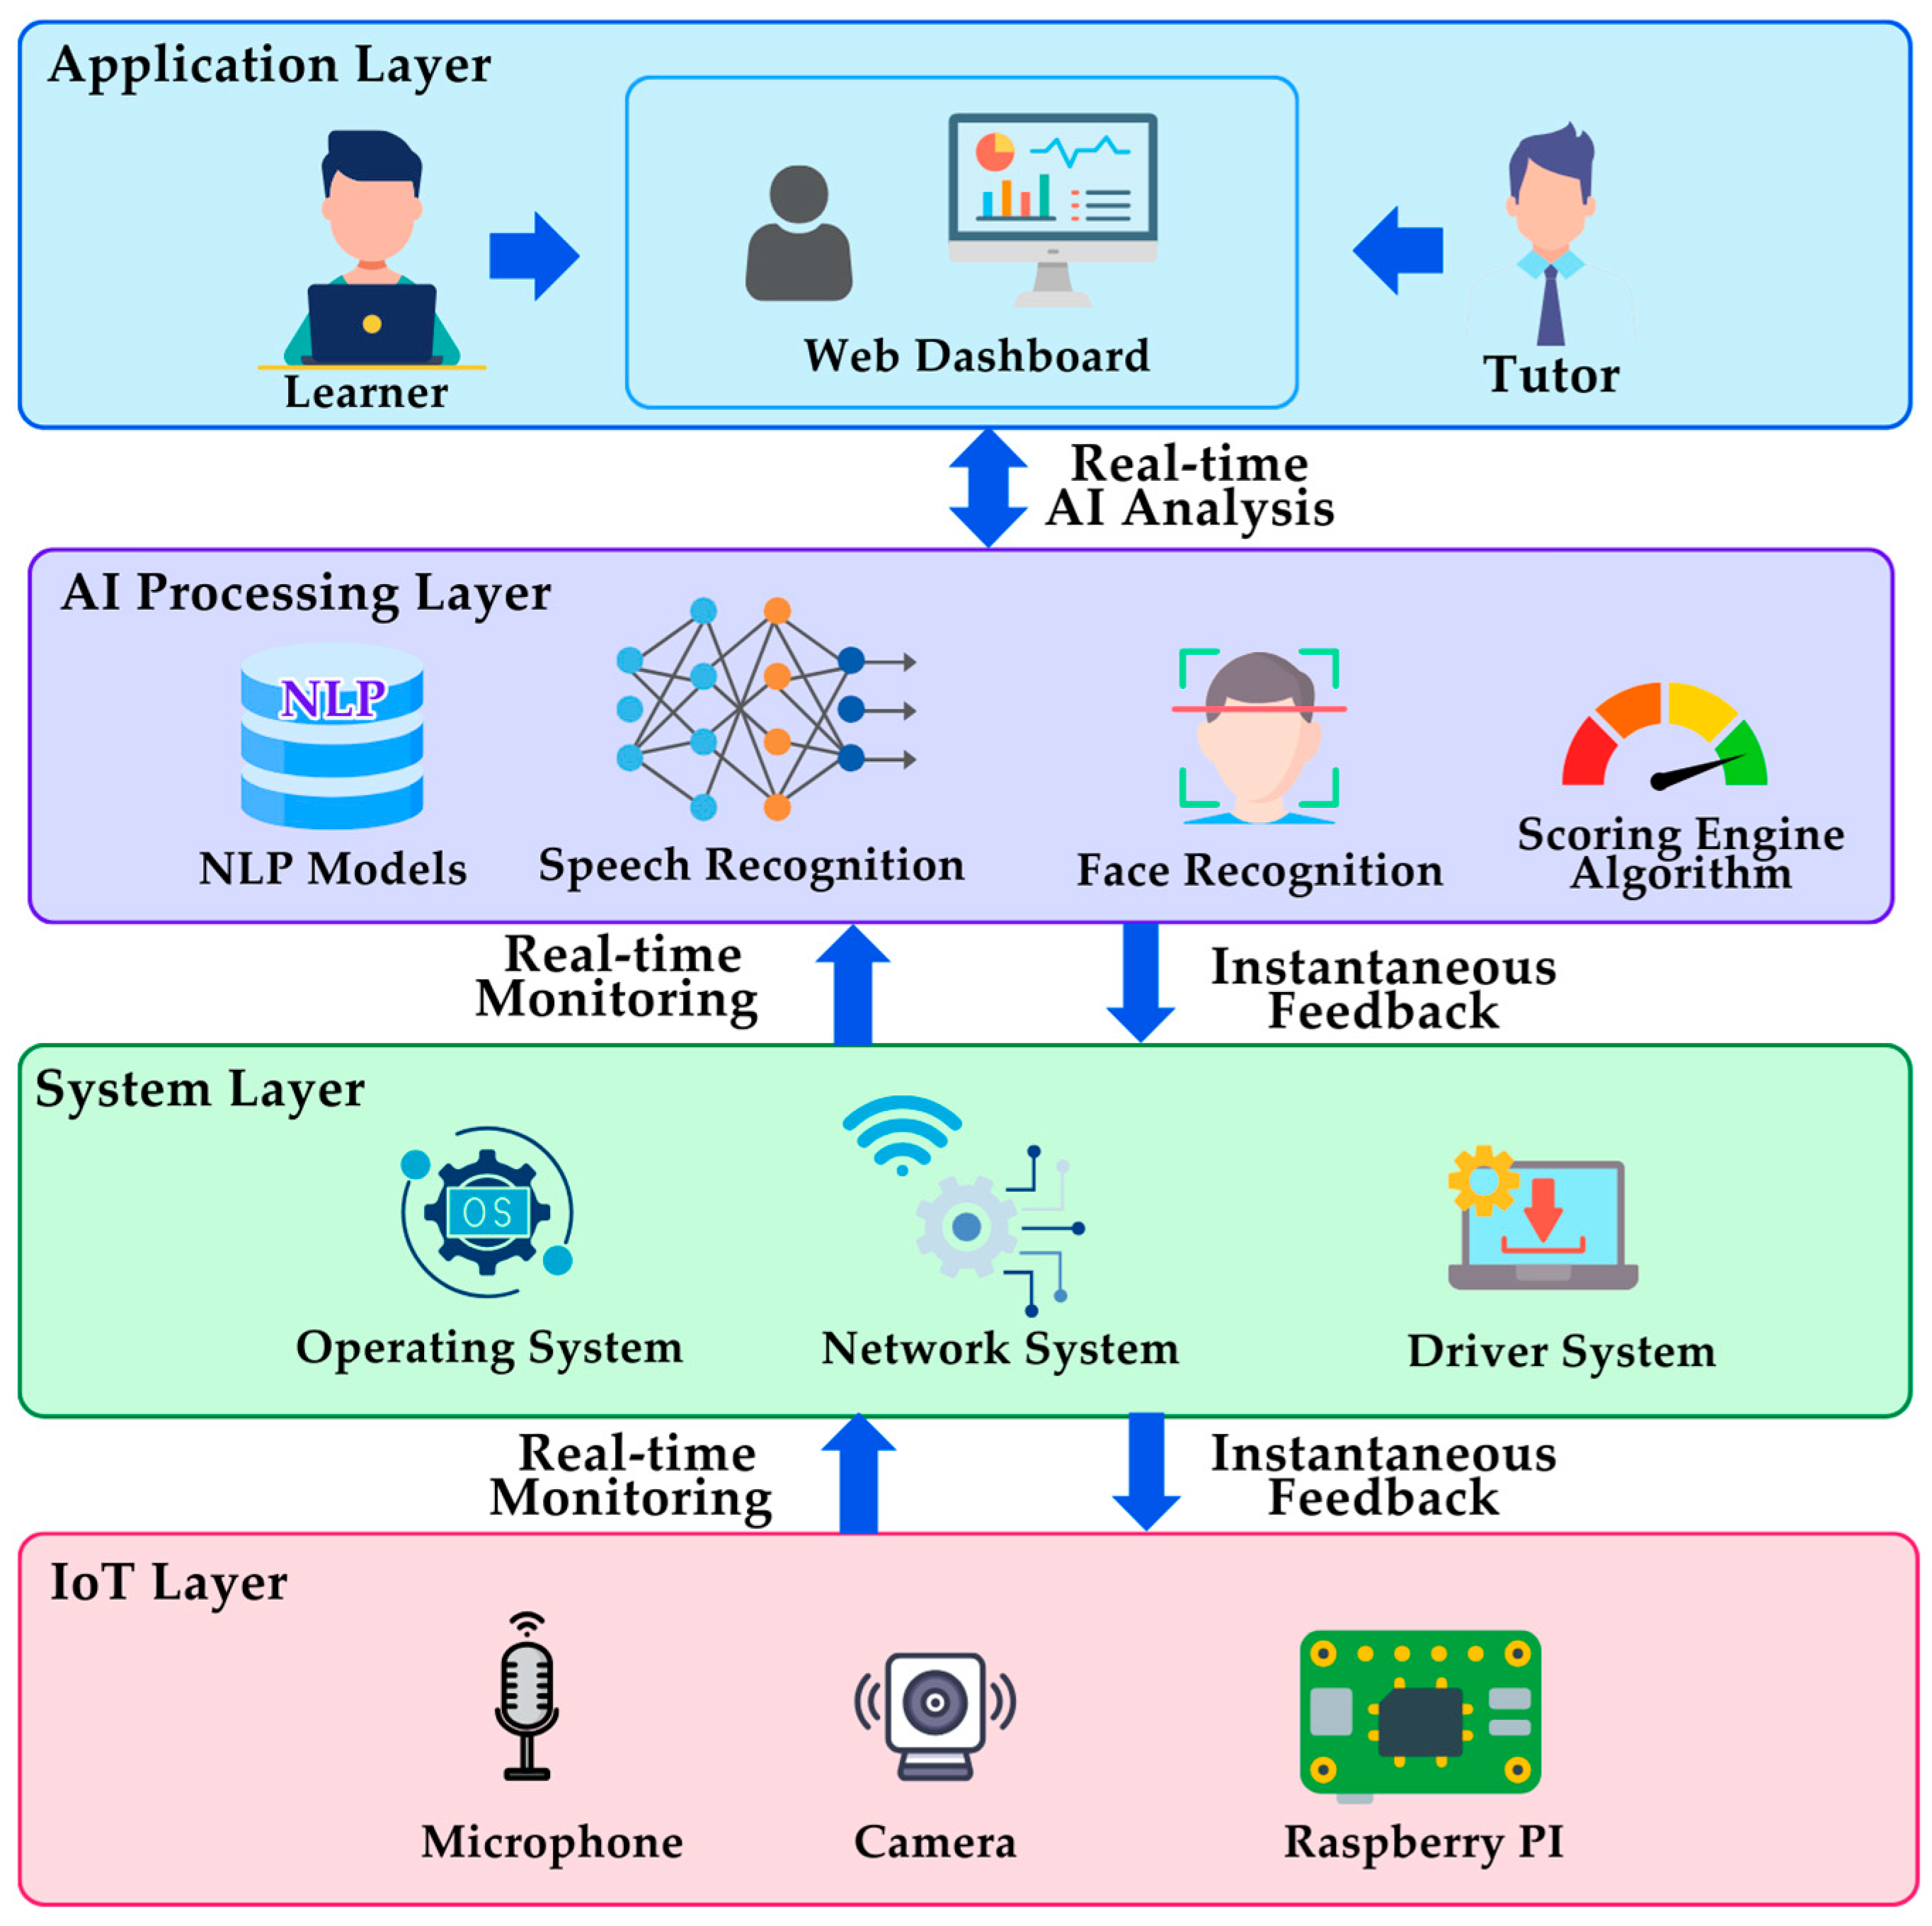
Figure 1, the system architecture was designed to achieve modularity, with each layer performing a distinct role and working together to ensure a seamless flow of data from the hardware (data capture) to the application (personalized feedback).
The base layer of the structure is the IoT layer, which captures the student’s input via a physical interface. Each layer of the structure functions separately yet together to ensure a seamless flow of data captured from the hardware to the application, providing students with personalized feedback. At the bottom of the structure, the IoT layer captures the learner’s physical input. The central hub is a Raspberry Pi equipped with a camera and a microphone to collect the learner’s spoken responses and interactions. The benefits of the layered structure are low data collection latency and minimal energy use. Since the IoT layer gathers data locally, the learner does not need to rely on an external network; thus, the learner’s experience is unaffected regardless of whether sufficient bandwidth is available.
In the provided example structure, the IoT layer is the system layer. The system layer is between the low-level hardware and the high-level processing layers. The system layer serves as a coordination layer that enables communication among processing units, microphones, and cameras through the operating system, network stack, and device drivers. A major benefit of the system layer is its coordination of resource distribution. Therefore, the system layer will provide seamless synchronization of audio and video during live assessments.
Above the system layer is the AI processing layer, which takes the raw data and converts it into computational data, information helpful for something. The NLP algorithms examine the syntax, fluency, and pronunciation of what the learner has said. Also, voice recognition engines like Vosk and Whisper transcribe the learner’s spoken response. This layer is also modular; therefore, smaller models (such as Whisper-tiny) can be used for speed when hardware allows, and larger models (such as Whisper-medium) can be used if accuracy is the most critical factor. However, the output is not just a number; it is compared to global standards because the grading system aligns with CEFR descriptions. In addition, learners receive continuous feedback through the system, allowing them to immediately see their exact mistakes and adjust their responses in real time.
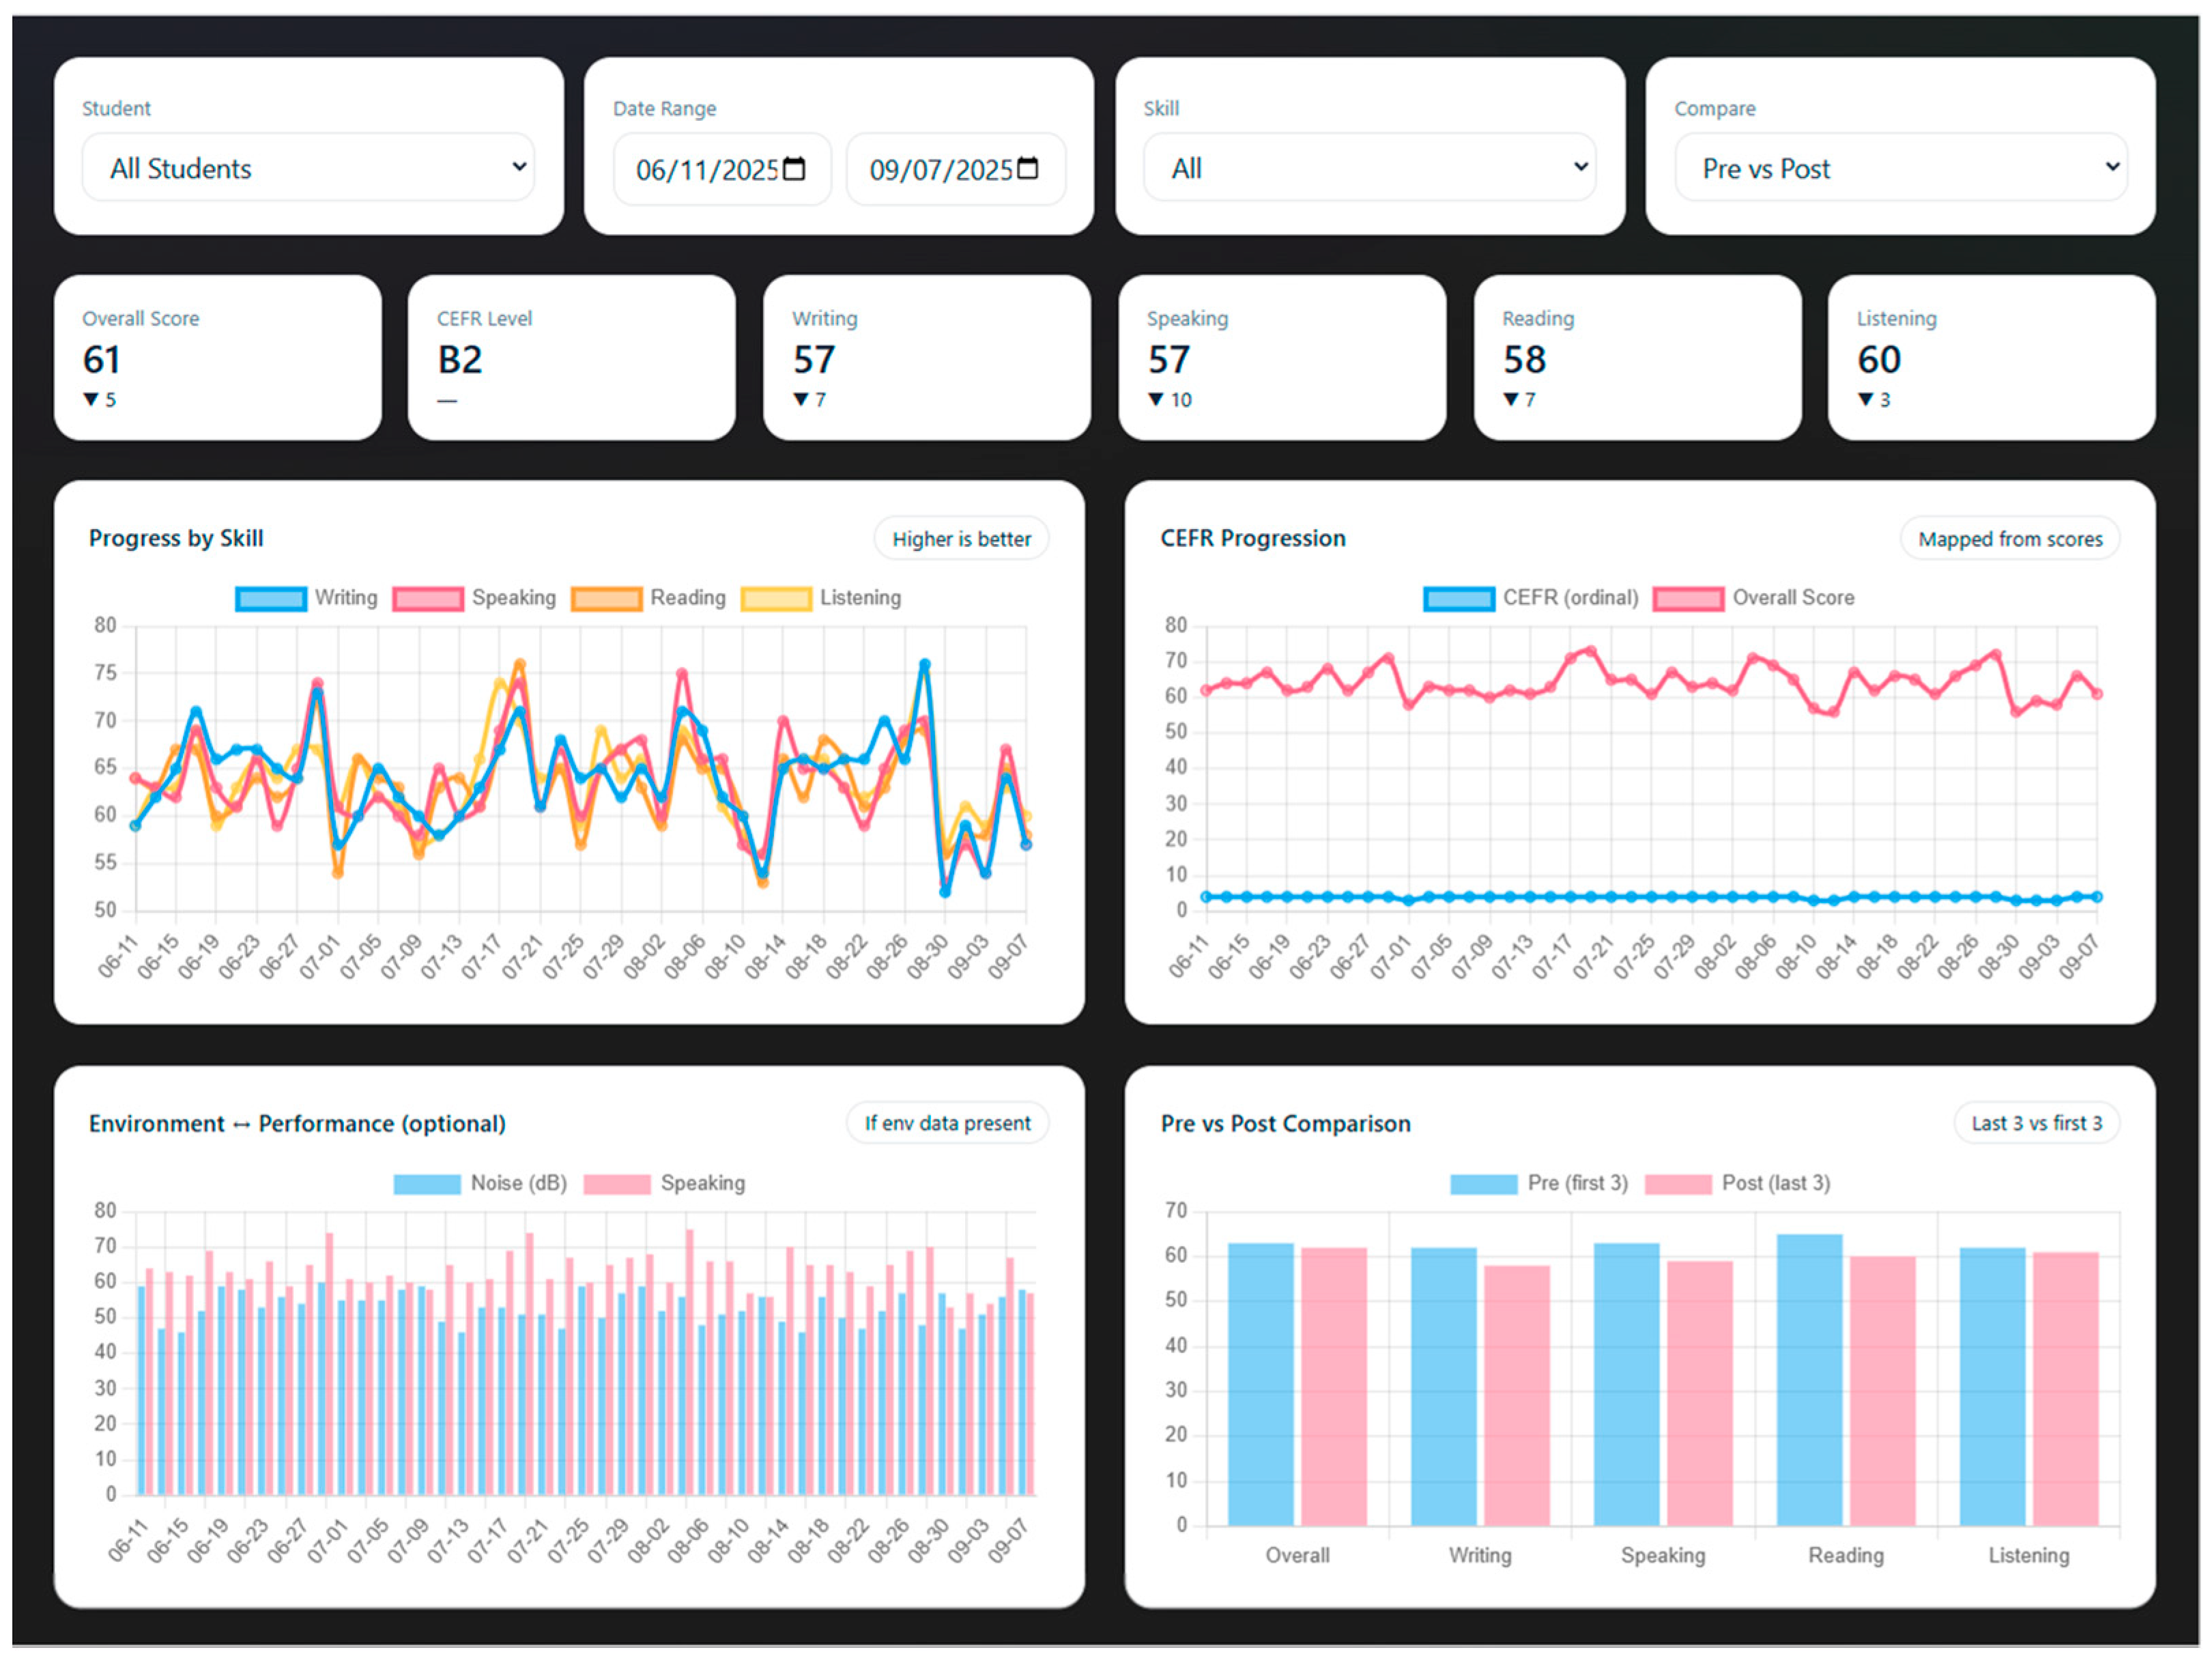
Finally, the application layer is the top layer of the structure and displays the results using a web-based dashboard. The key feature of the application layer interface is the dashboard’s functional usability. The dashboards display the learners’ overall performance, and teachers can see both current and historical results. The visual dashboard shows learners’ progress over time and helps teachers refine their teaching methods. The platform offers many display options across various devices (desktop computers, tablets, and mobile phones) and can be used in a wide range of educational settings.
The framework’s three main strengths stem from its four-layer design. This multilayer approach is adaptable, flexible, and scalable, with components and interfaces that can be upgraded without reinventing the whole architecture or its functional systems; it is also robust and tolerant enough to allow each layer to be optimized independently. By consistently capturing, analyzing, and providing actionable feedback based on learner input, these qualities make the tutoring process both reliable and personalized.
3.2. AIoT Hardware and Software Environment
Due to Python’s ability to run on different hardware and software libraries, it was chosen to provide accurate information, quick processing, and sufficient user feedback. Two single-board computer systems, the Raspberry Pi 4 Model B and Raspberry Pi 5 (both equipped with 8 GB RAM), were selected as edge-AI computing platforms for their mobility, lower power consumption than larger computers, and demonstrated ability to handle AI workloads. The Raspberry Pi 4 is the main device, while the Raspberry Pi 5 is used for more computationally intensive tasks, such as higher-quality ASR.
Table 1 lists the hardware and software elements of the hybrid AI-IoT tutoring system. A Logitech C922 camera with a built-in stereo microphone captures 1080p video and 16 kHz audio and stores them locally on a 32 GB microSD card with SSD support for redundant storage. A stable 5V/5A USB-C power supply enables continuous use. Both the Raspberry Pi 4 and 5 run Raspbian Bookworm 64-bit (Linux Kernel 6.12) and thus support Python-based programming across all layers of the system.
Whisper, a transformer-based ASR model developed by OpenAI, converts 16 kHz audio to an 80-channel log-Mel spectrogram. The encoder in Whisper uses multiple self-attention layers to contextualize temporal frames, while the decoder produces subword tokens via probabilistic beam search. In this research, Whisper was implemented using CTranslate2, reducing the model’s memory requirements from gigabytes to tens of megabytes by applying INT8 or hybrid quantization, thus enabling real-time inference on ARMv8 processors of Raspberry Pi 4 and 5.
Vosk utilizes TDNN acoustic models and WFST decoding similar to the Kaldi speech recognition toolkit. Vosk captures 13-dimensional MFCC features, optionally using i-vectors for adaptation, and supports inference directly on embedded platforms without a GPU. Vosk achieved inference latency of under 120 s per test on both Raspberry Pi platforms, demonstrating consistent, predictable performance in an interactive classroom environment. Vosk enables rapid responses during live sessions, providing complementary high-fidelity transformer-based recognition capabilities for Whisper.
Eleven Whisper configurations are tested (tiny, base, small, and medium variants) using three quantization schemes (int8, hybrid int8_float32, and float32). A uniform set of parameters is used for the preprocessing stage of Whisper (i.e., 16 kHz sampling rate, 20 ms frame length, and a beam size of 5) to manage the preprocessing load and balance the trade-off between inference time and accuracy. Hybrid quantization is used to stabilize performance in a variety of real-world scenarios.
Three Vosk configurations (small-en-us-0.15, 0.22, and 0.22-lgraph) are tested in float32 precision using an FST decoding pipeline. A 16 kHz sampling rate and a 25 ms frame length are used to enable robust word boundary detection, while a beam size of 10 improves the recognition and recall of continuous speech segments.
The IoT layer captures audio at 16 kHz mono using either sounddevice or PyAudio. When needed, video streams can also be accessed through OpenCV. The ffmpeg-python library is used to convert WebM audio into MP4 format so that the downstream ASR models can utilize the data.
The system layer enables real-time communication between the client and server via Uvicorn, with Flask managing the API endpoints. Throughout live sessions, the system layer continuously monitors system health metrics (CPU, memory, and process load) using psutil.
The AI processing layer consists of Whisper (via PyTorch) and Vosk (via Python/NumPy/SciPy) for transcribing the input audio, followed by a custom scoring module for computing WER, WPM, pause ratio, filler rate, and CEFR-aligned fluency and pronunciation bands.
The dashboard and visualization layer utilize HTML5, CSS3, JavaScript, and Chart.js to render session logs and performance metrics via Jinja2 templates. Performance metrics and session logs are stored in SQLite using SQLAlchemy.
The combined hardware–software framework allows students to record speech directly through the dashboard. The audio is then processed in near-real-time by the dual-ASR architecture and scored, resulting in the instantaneous display of the results. This feature demonstrates that complex AI processing can be hosted on Raspberry Pi devices while enabling scalable user interaction and deployment for educational purposes.
3.3. AIoT Flow and Processing Pipeline
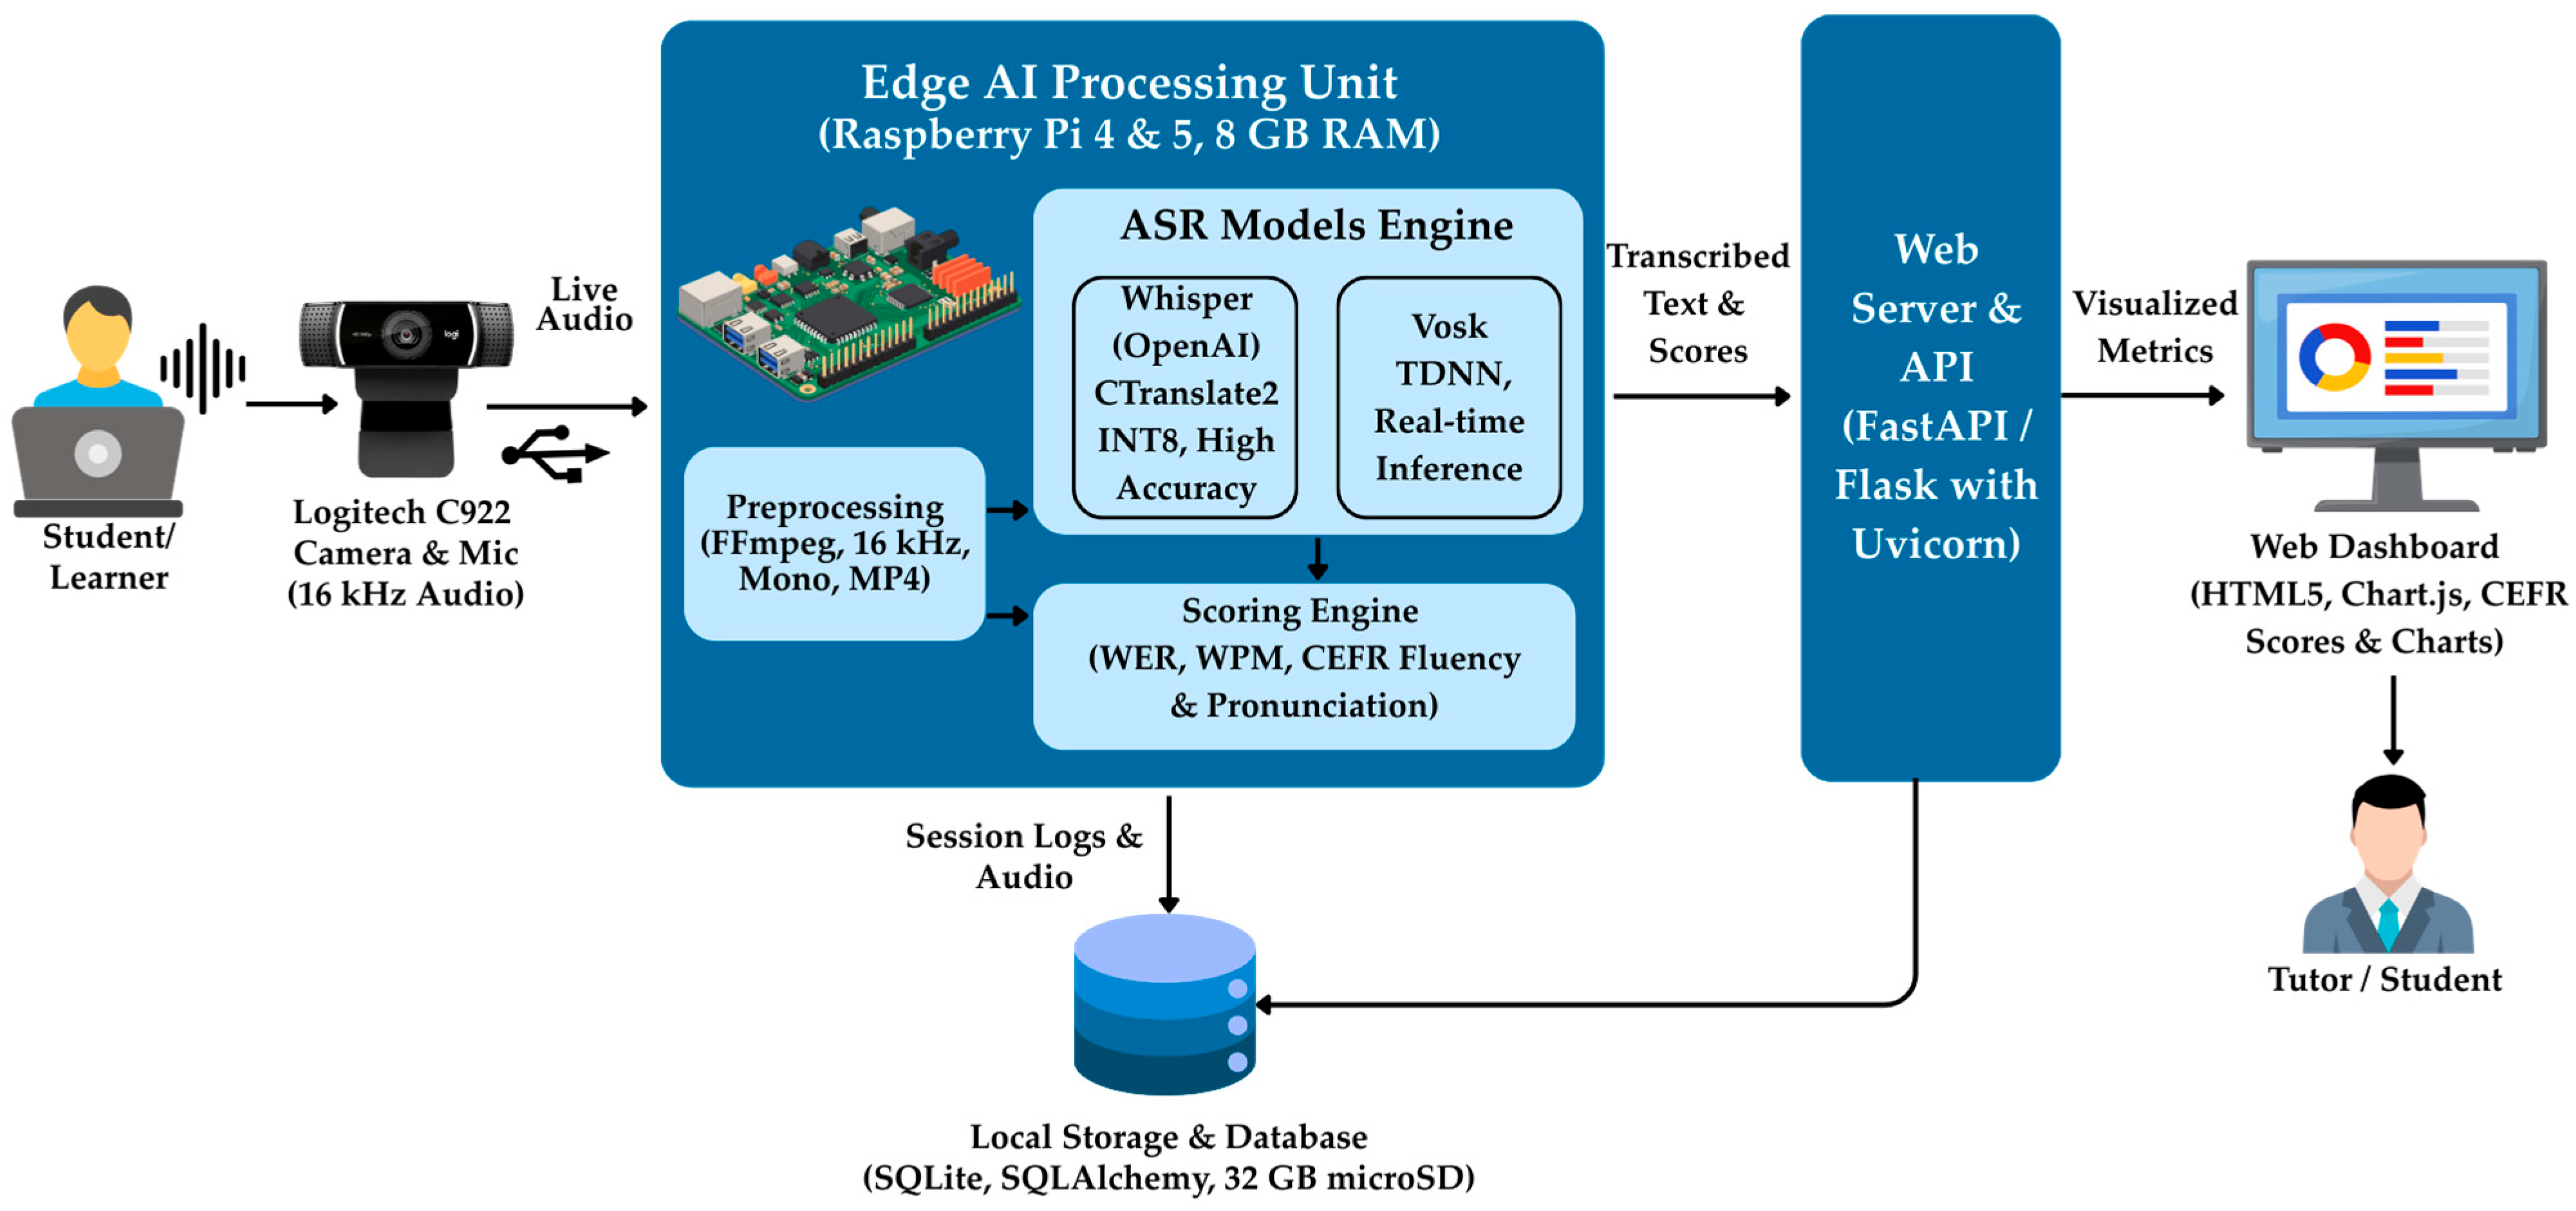
The AIoT hybrid tutoring system data flow and processing pipeline were established to seamlessly integrate the learner’s spoken input through speech recognition, model analysis, and real-time feedback delivery, as illustrated in
Figure 2. The figure shows how the architecture provides continuous assessment and improvement of the system by processing data from the beginning of the primary process, capturing a learner’s voice, through to the end of the primary process. The learner’s speaking proficiency is represented visually on the dashboard.
The processing pipeline for the framework consists of four main stages—data capture, AI processing, feedback generation, and dashboard visualization—which operate in a continuous cycle.
The primary process begins when a learner initiates a speaking test via the web interface. The speech is recorded by the embedded microphone in the Logitech C922 camera and saved at 16 kHz in mono to meet the requirements of the ASR models. Before processing, the raw audio is stored in WebM format and subsequently converted to MP4 format using the ffmpeg library. This conversion is completed to balance storage efficiency with compatibility with the processing pipeline. At this stage, clarity and precision of the recording are critical. Clarity and precision of the recording are important because the quality of the captured audio will determine the accuracy of transcription and scoring of the student’s performance at later stages of the system.
After capture, the audio is passed to the AI processing layer running on Raspberry Pi 4 and Pi 5 devices. Two different kinds of automatic speech recognition models are employed to convert spoken English voice passages into text. Although the inference complexity is greater than in the previous example, Whisper (implemented in PyTorch) is used to support the development of the more complex inference process. At the same time, the Vosk version provides a simpler model that functions well in real time on low-end devices. Following completion of the transcription, a customized evaluation component assesses all of the performance metrics from the transcription output (accuracy percentage, WER, WPM, pause ratio, filler rate, CEFR-aligned fluency, CEFR-aligned pronunciation, CEFR-aligned prosody, and CEFR-aligned overall speaking band). The above metrics provide both a numerical representation of student performance and a qualitative description.
Students’ scores are then converted into usable feedback. The automated scoring algorithm maps students’ CEFR descriptors to provide a standardized method for comparing their proficiency levels at any point in time. At the same time, the system indicates to the instructor which areas could be improved (e.g., excessive pause ratio, insufficient clarity in speech articulation, poor fluency, etc.). Since this system was designed to be an instantaneous technique, students and learners would receive continuous feedback. This feedback would presumably help students and learners practice, correct, and develop their spoken language skills.
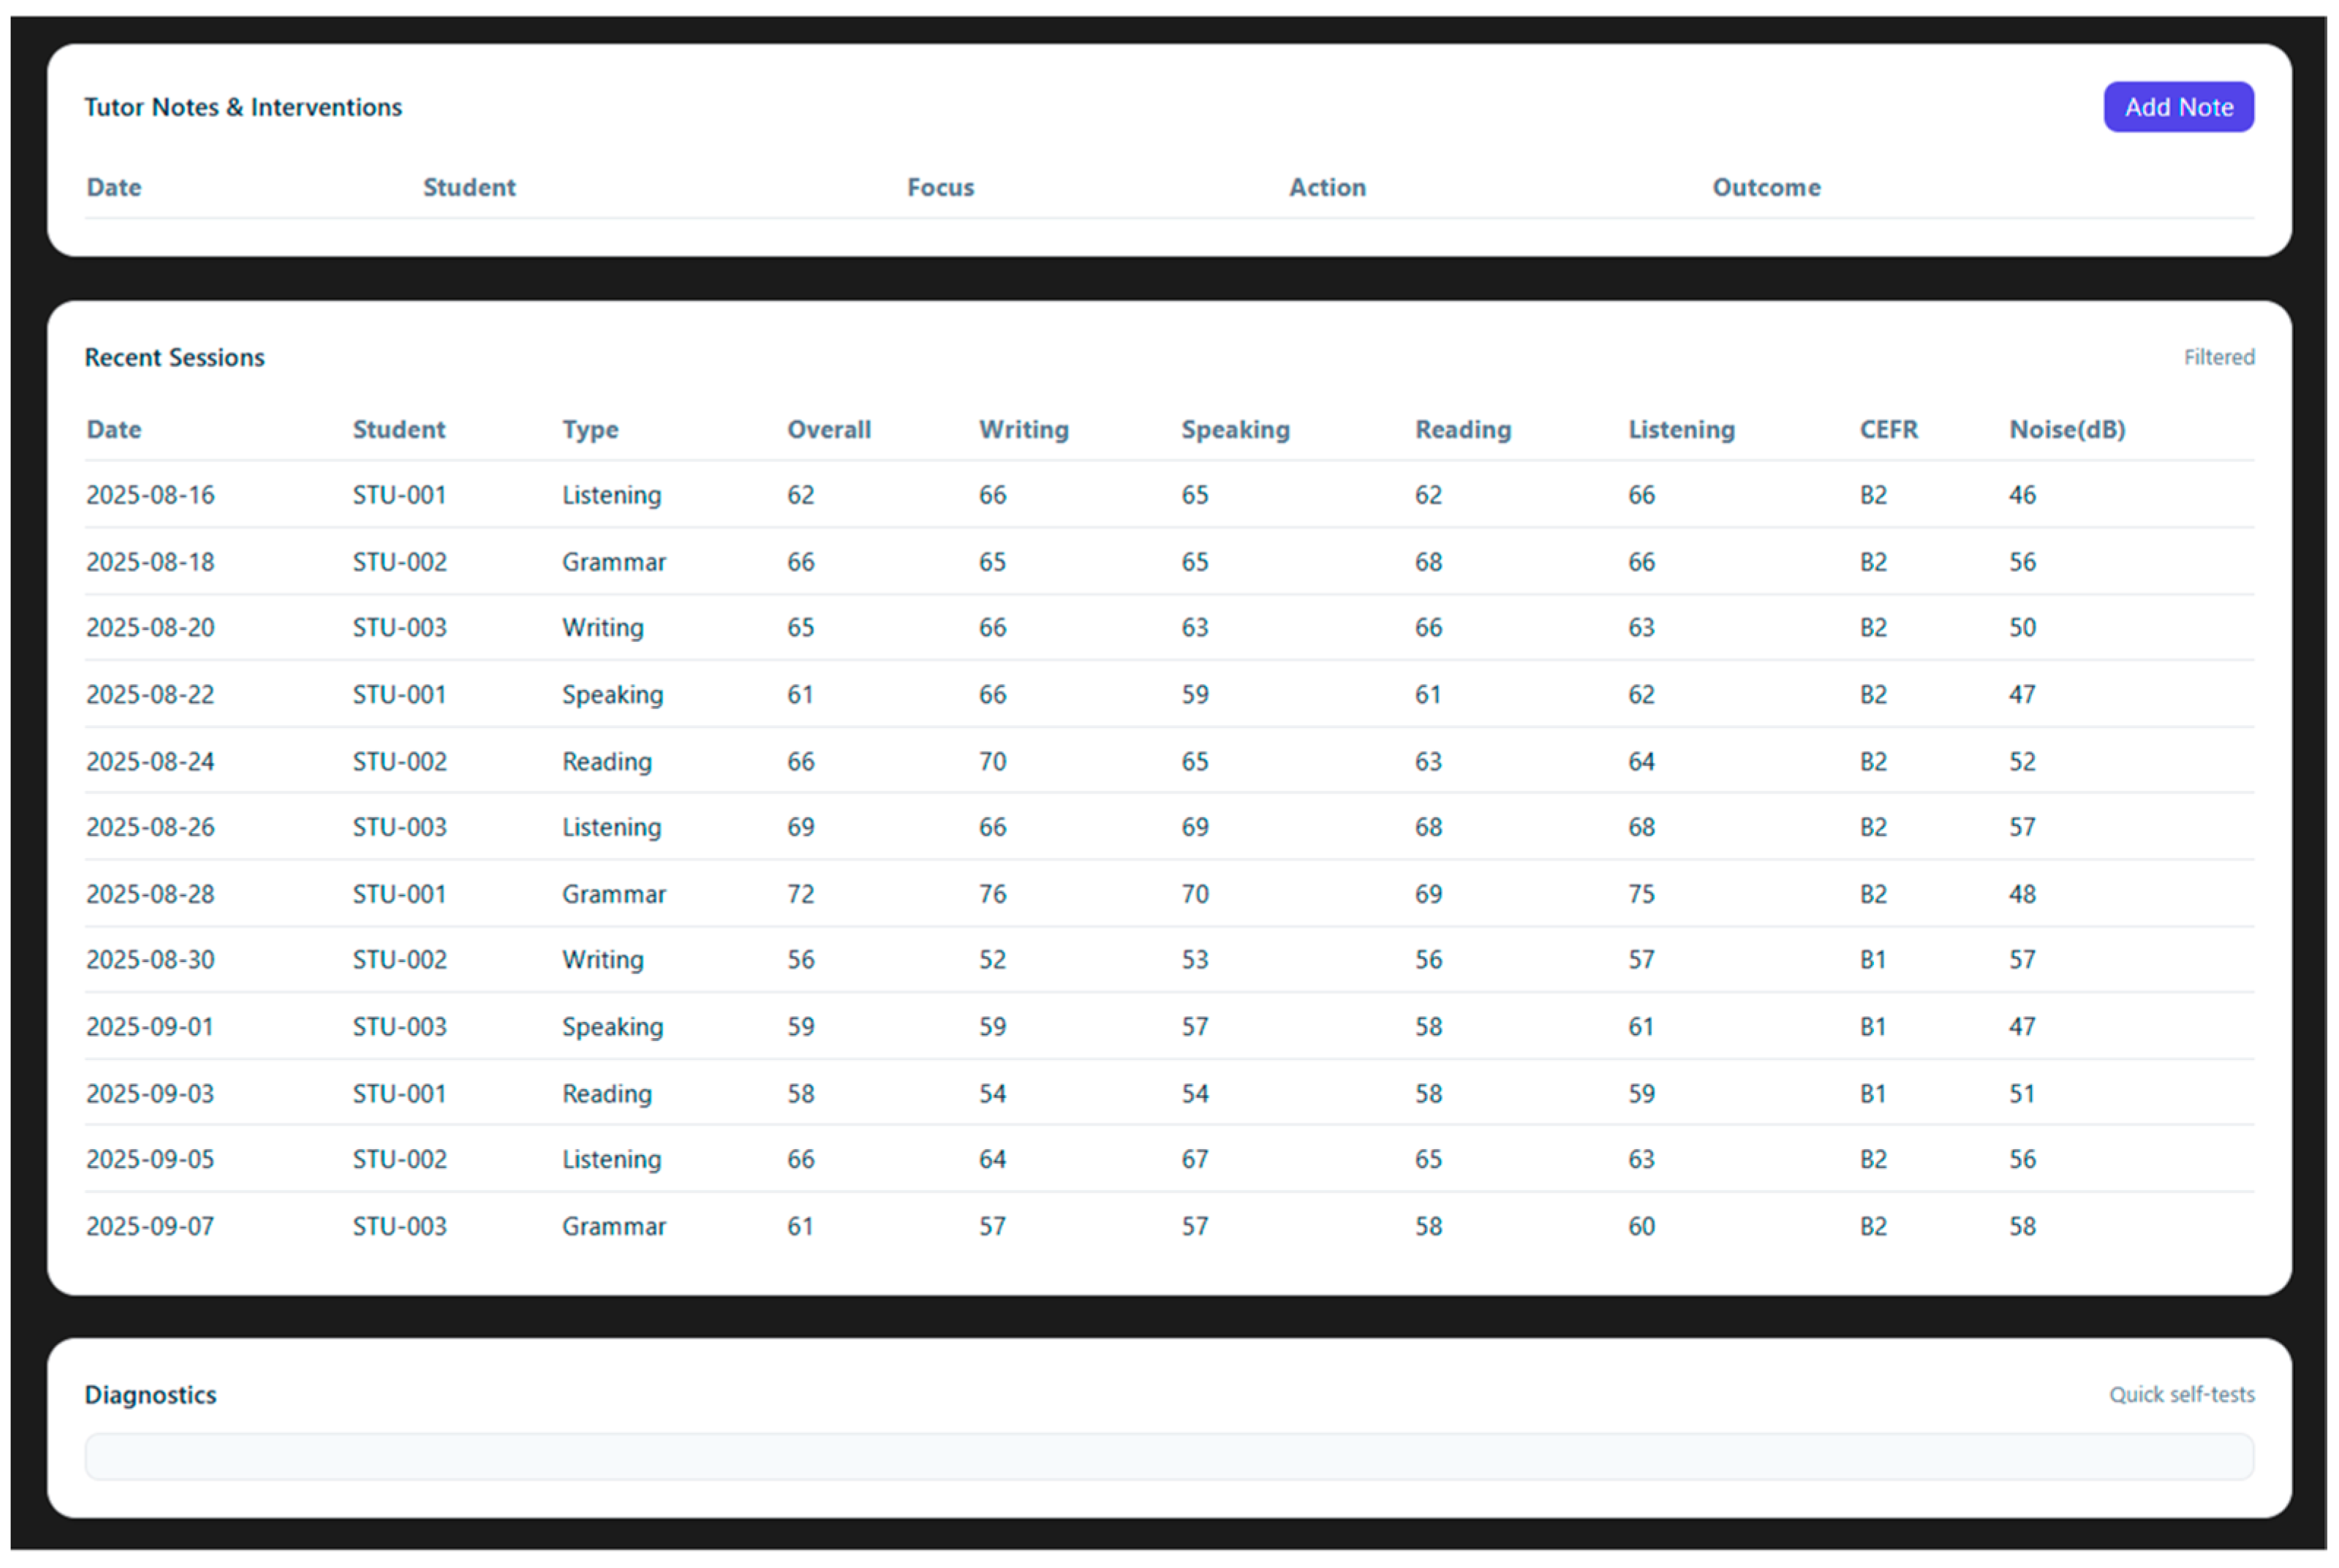
The results are then displayed on a web dashboard for students, learners, and tutors to view. The tutors or educators can observe the details of the analytics used to assess students’ or learners’ performance over a time interval, the CEFR levels of the students or learners, and the results of pre- and post-tests for each student or learner. Further, the dashboard enables tutors to record notes, intervention activities, and other details and observe their effects across multiple sustained tutoring sessions. By utilizing instantaneous feedback alongside students’ or learners’ historical data, the dashboard provides the principal location where data analytics and human involvement meet to support acquisition learning.
The pipeline is structured as a continuous loop. The dashboard output from the current iteration is connected to the next iteration’s data collection process. As a result, closed-loop design allows the system to evolve as learners’ competency increases, providing a customized, unique way for students to practice their English-speaking skills.
3.5. Speaking Test Design and Passage Generation System
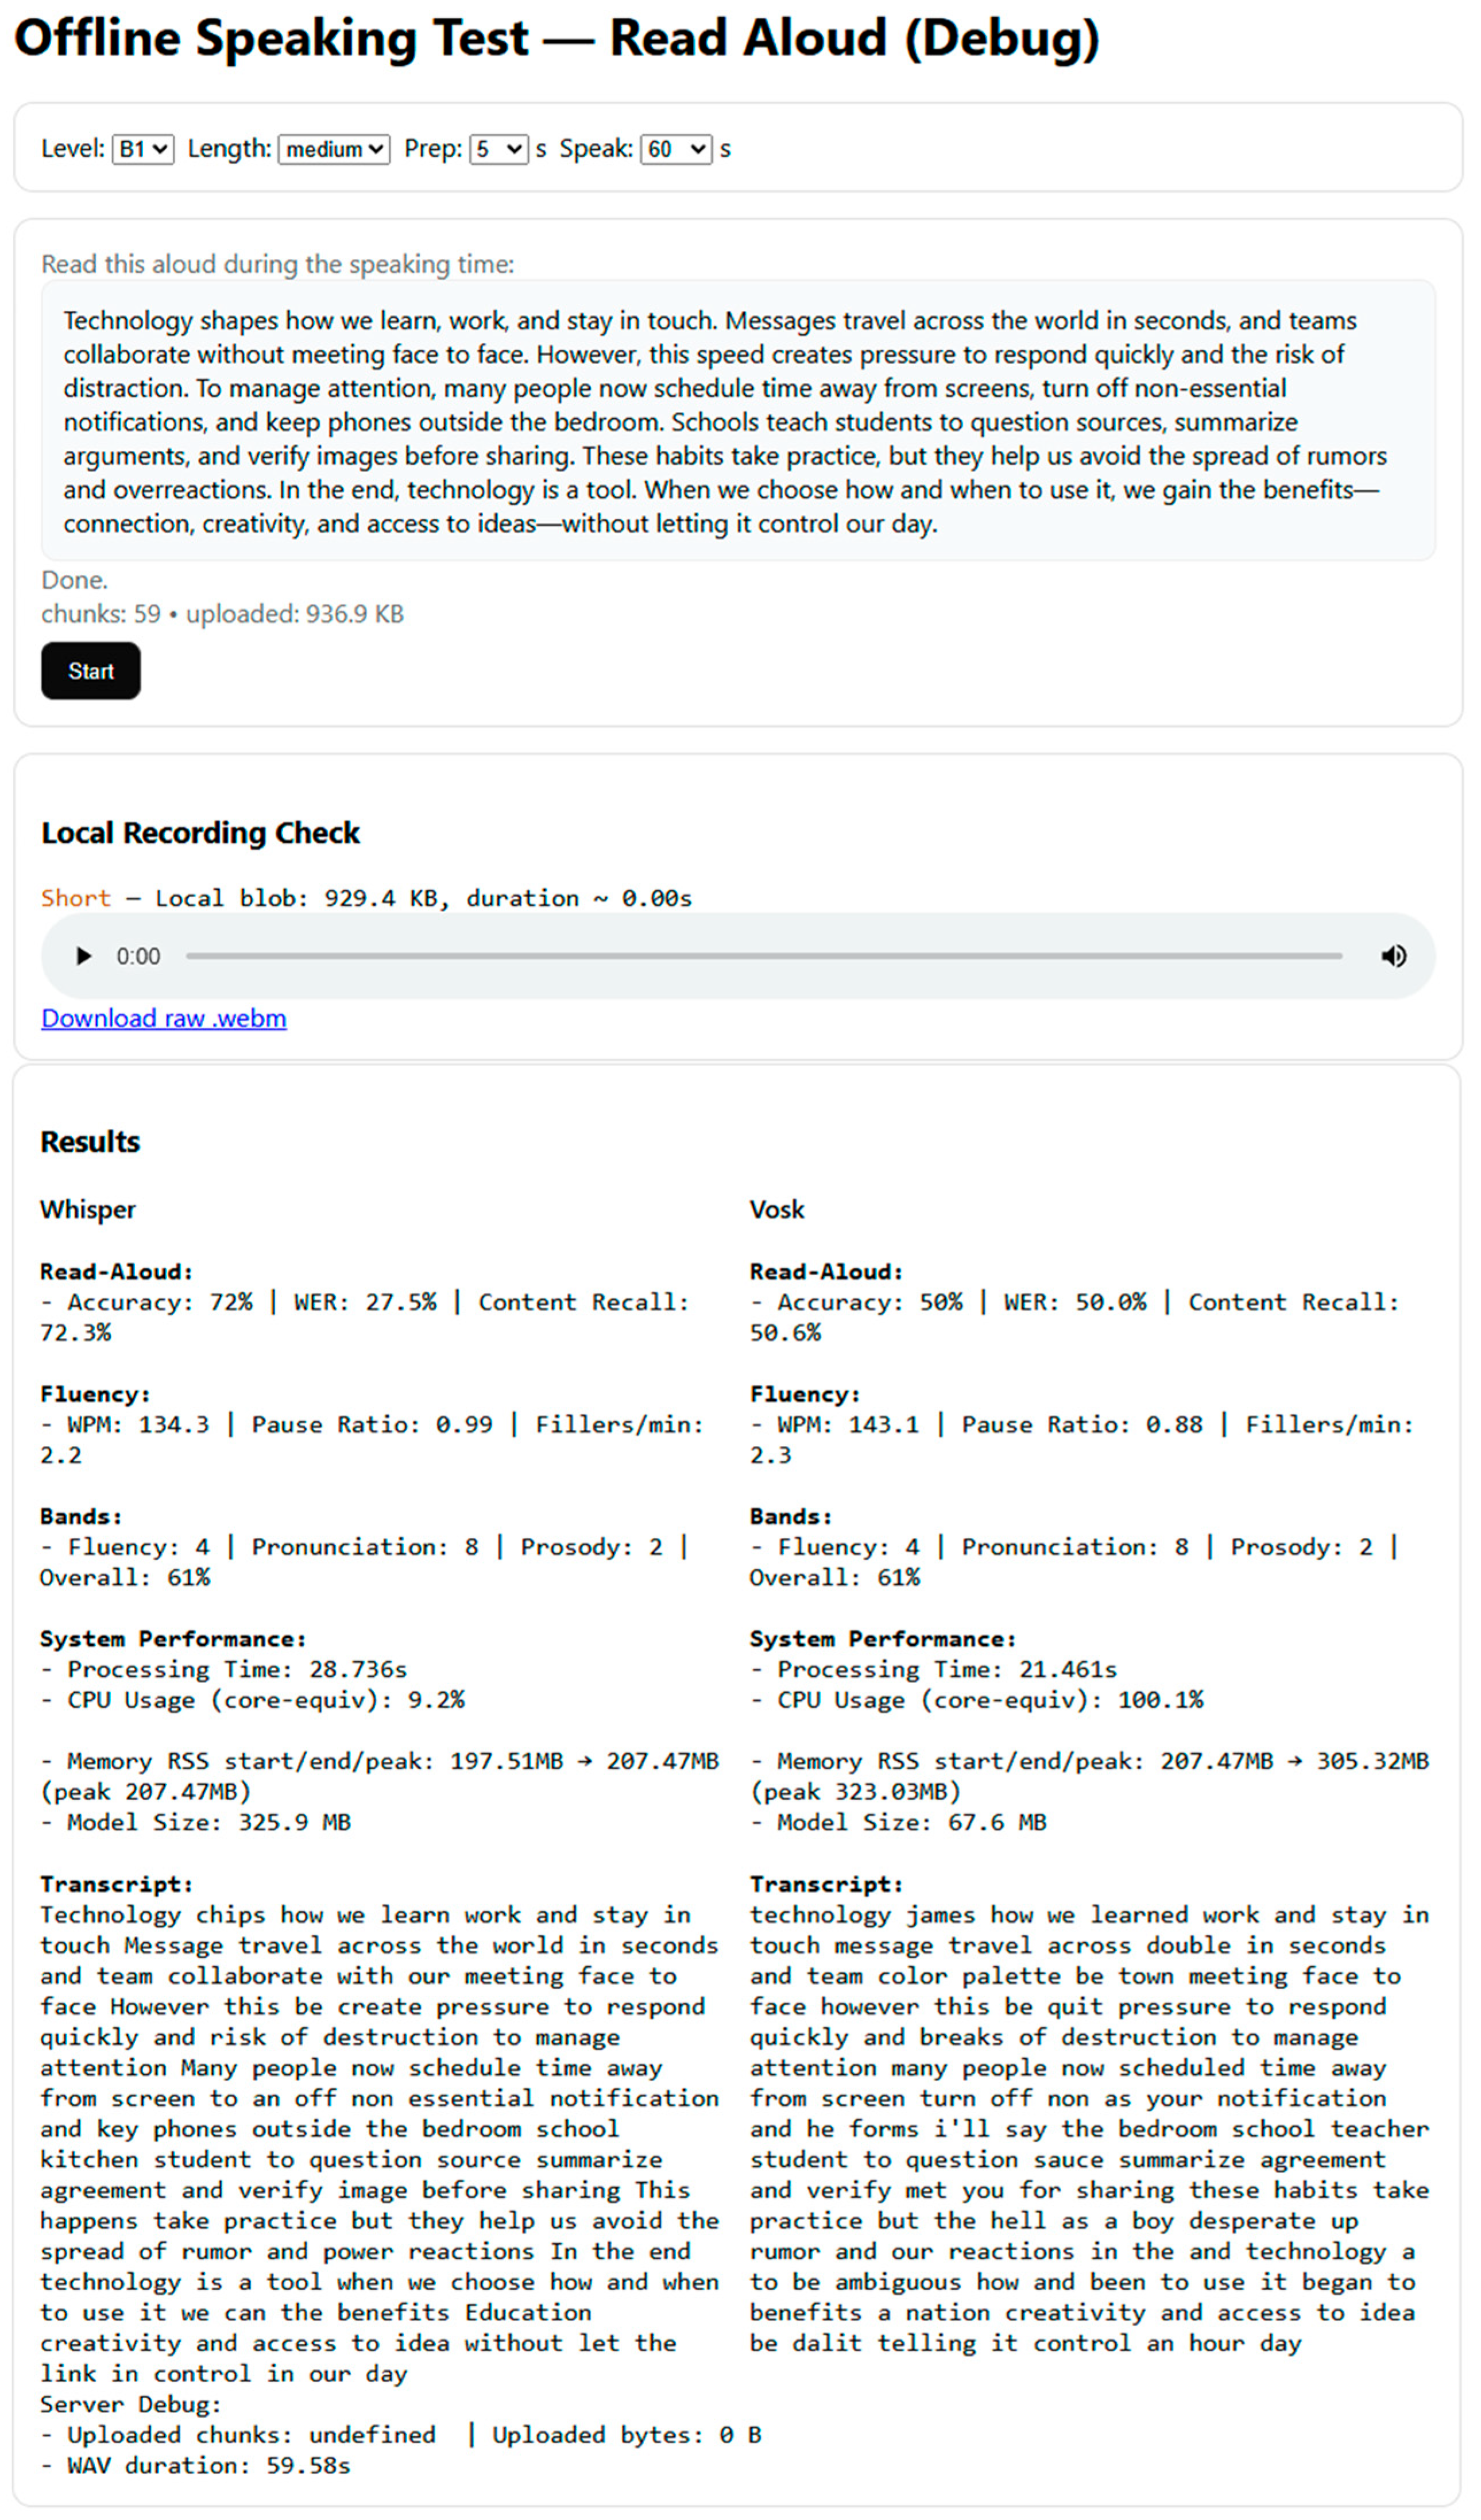
The spoken component of the hybrid tutoring framework uses artificial intelligence to generate and administer a series of tests that assess a student’s oral proficiency according to predetermined test protocols (e.g., time-limited and/or sequential). These tasks were designed to evaluate various components of spoken language performance and fluency (e.g., pronunciation, prosody, accuracy, and lexical complexity); however, the assessments were conducted under standardized testing conditions. The student’s experience with the tutoring system’s web interface is shown in
Figure 5. It includes a simple dashboard for selecting their CEFR proficiency level (A2–C1), passage length, and talking time before the assessment begins.
Once the system has identified the student’s topic of interest (e.g., daily routine, education, and technology), it initiates the first stage of a three-stage dynamic process. In this first stage, the system matches the student’s chosen topic to semantically tagged passages in its corpus. The second stage of this process, difficulty calibration, uses a fine-tuned transformer-based text model to adjust the passage’s linguistic structure to align with the CEFR level selected by the student and ensure it remains both readable and grammatically appropriate for that proficiency band. The third stage, text regeneration, utilizes controlled lexical variation (e.g., synonym substitution, minor reordering of the original text, and insertion of discourse markers) to create a new passage that is similar in difficulty to the original but sufficiently different so that each passage can be uniquely regenerated for each student test administration. All passages are validated to ensure that they fall within a word-count range of 80–120 words for A2–B1 levels and 150–180 words for B2 levels, thereby achieving a balance between the cognitive load imposed on the student during the test administration and the amount of time the student is required to speak.
The six test cases summarized in
Table 2 are operationalized within a unified AIoT task-processing pipeline that manages multimodal input, real-time inference, metric computation, and CEFR-level classification. This pipeline also presents the task design for the AI–human calibration experiments, covering six speaking task types (TC-1 to TC-6). Each test case specifies the kind of task (e.g., personal introduction, situational response, picture description, read-aloud, topic-based monologue, and analytical discussion), a representative prompt, the targeted CEFR-level range, the expected duration, the expected output length in words, and the primary assessment focus (e.g., basic fluency and coherence, pragmatic appropriateness, narrative accuracy, prosody and rhythmic control, lexical sophistication, and critical argumentation).
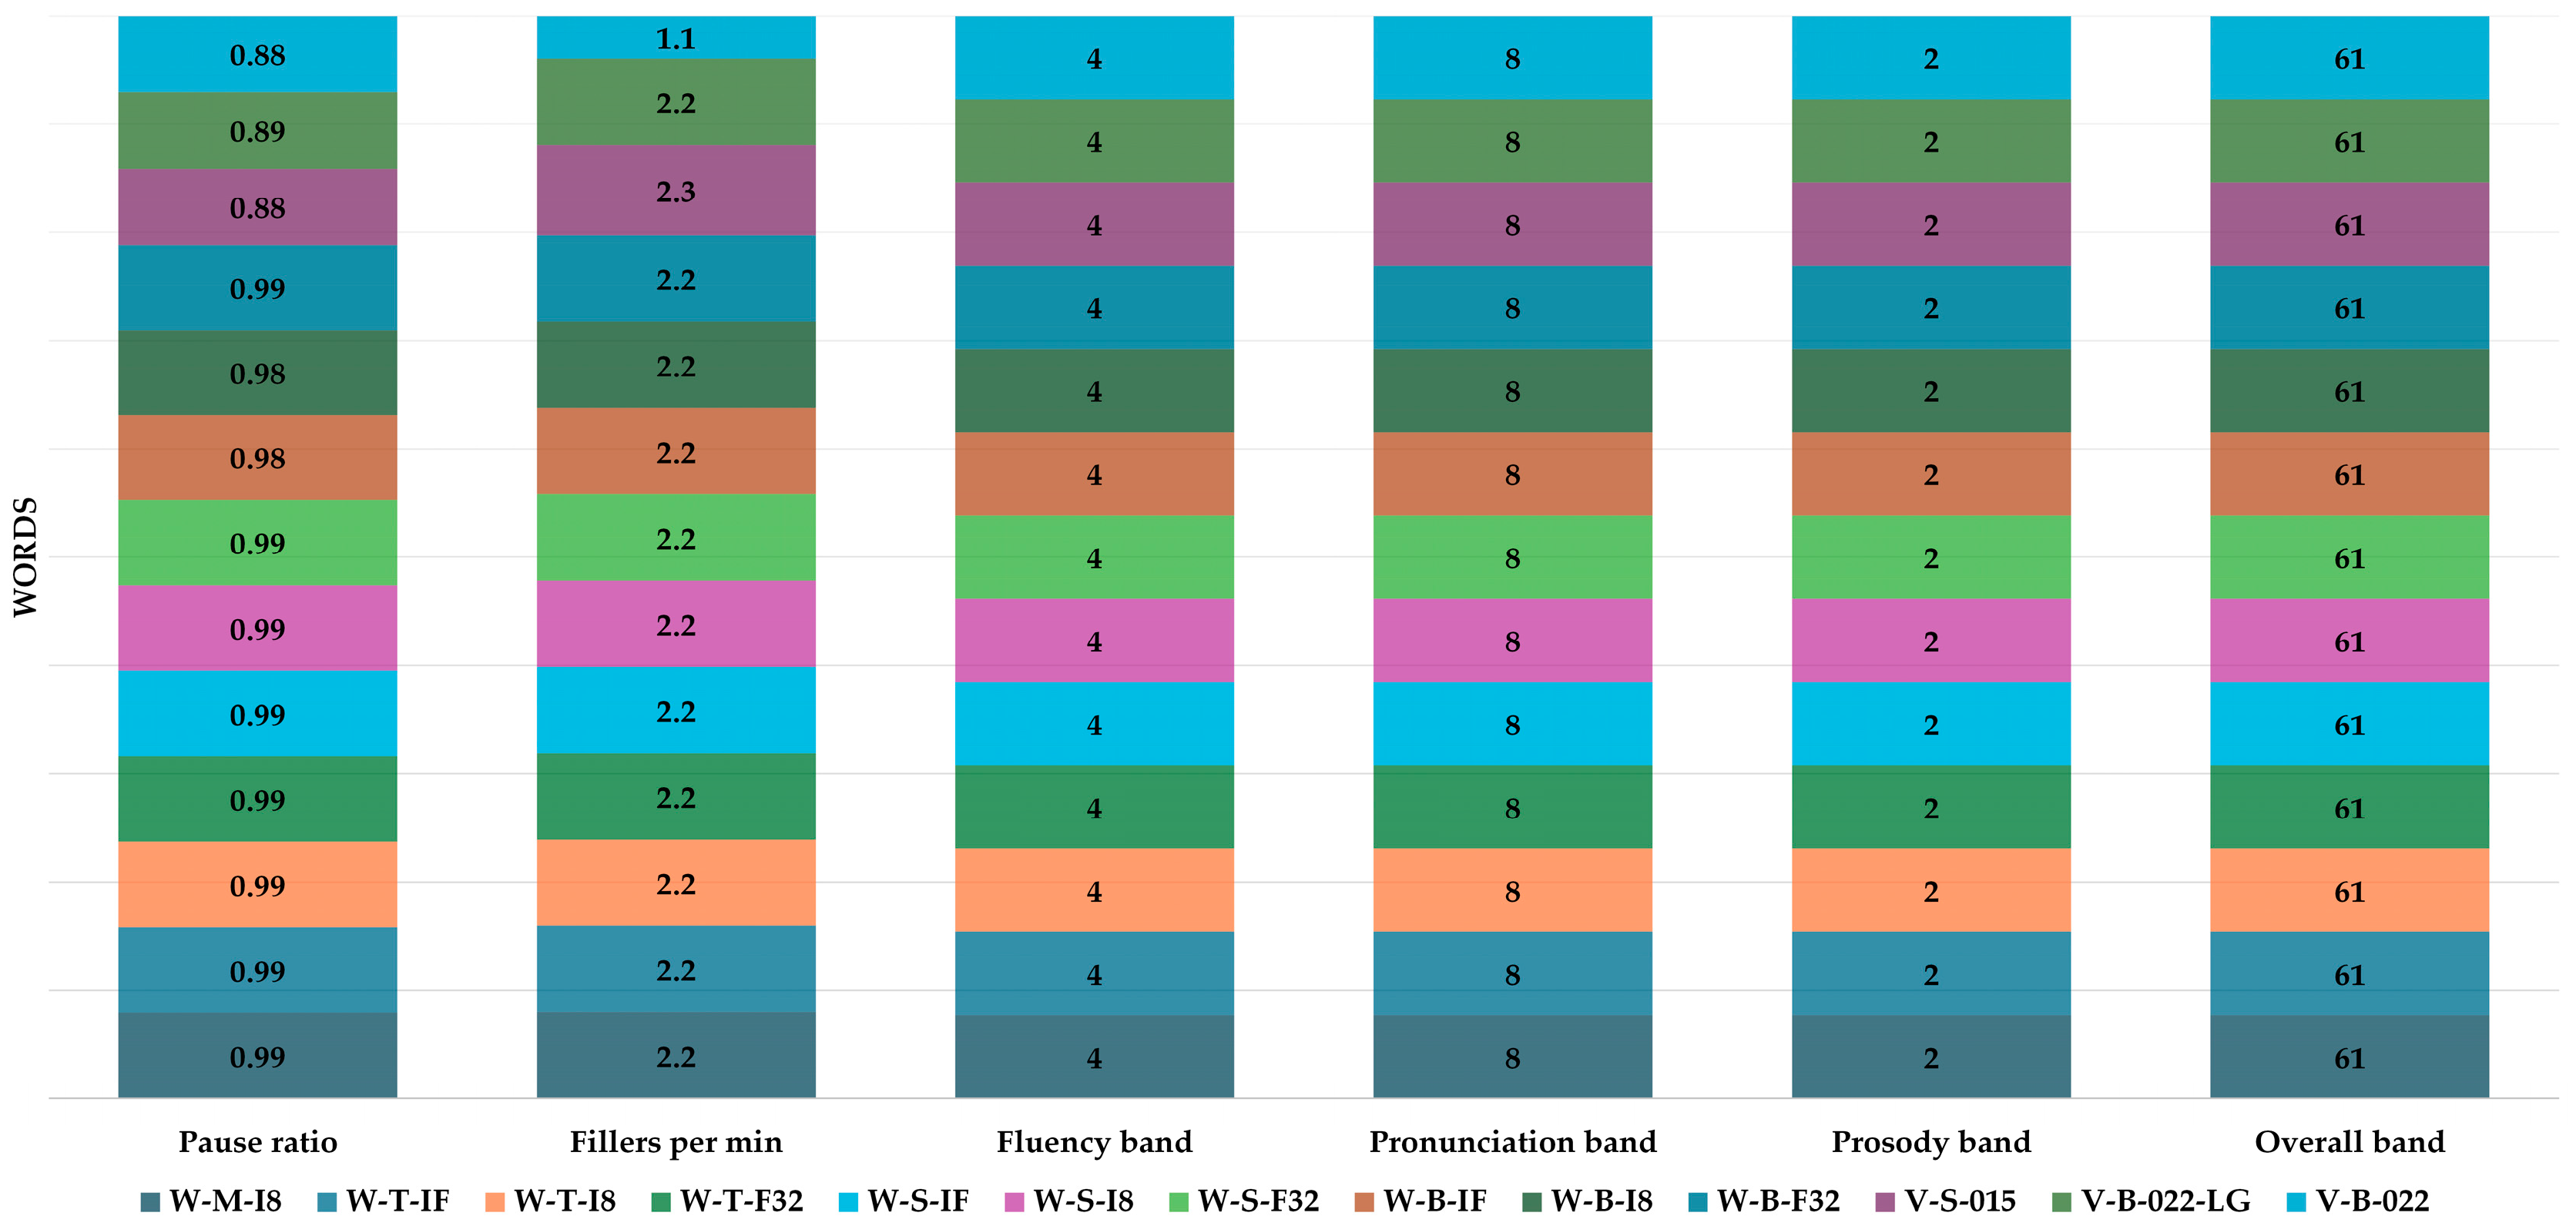
Beyond traditional performance metrics such as accuracy and word error rate, the system also evaluates three specialized fluency-based metrics designed to capture the rhythmic nature of spontaneous speech (tempo and cadence) and the overall sense of how natural the speech sounds (perceived naturalness). These fluency-based metrics are pause ratio, fillers per minute, and composite fluency band. While accuracy and word error rate primarily reflect how many words were correctly recognized, the fluency metrics reveal how the speech is produced over time and how confident or hesitant a speaker appears. Accordingly, they must be examined in conjunction with word-level accuracy to obtain a complete picture of communicative proficiency.
The pause ratio is the percentage of an individual’s total speaking time spent in silence. Each recorded response is segmented into 25-millisecond frames with a 10-millisecond hop, and low-energy intervals exceeding 200 milliseconds are identified using short-term energy analysis. The pause ratio is a continuous value ranging from 0 to 1, as represented in Equation (1), and it represents the ratio of cumulative pause duration to total utterance length:
Lower ratios of pause to speaking time are associated with smoother delivery and more automatic speech production. A lower pause ratio thus indicates how well the speaker can maintain a stable “excitation envelope” without falling below a “silence threshold”—that is, how infrequently and for how long the speaker dips below a certain energy level.
Fillers per minute indicate how many times the speaker uses hesitation markers (e.g., uh, um, or prolonged syllables) in a minute. The detection process combines lexical and acoustic criteria. First, the lexical component searches for hesitation tokens in the ASR transcription using keyword matching. Second, the acoustic component validates these tokens to ensure that they are true hesitation events rather than artifacts such as breathing or background noise, using flat-spectral and stable-formant features. Once all hesitation tokens are identified and validated, their count is divided by the total speaking time to obtain a filler rate per minute. A lower number of fillers per minute indicates lower cognitive load and better planning during spontaneous speech production.
To quantify speech tempo while accounting for pauses and hesitations, the study defines a continuous Fluency Index (FI). The FI is computed by combining three standard fluency measures—words per minute, pause ratio, and fillers per minute—into a single normalized composite score using a weighted linear formulation. Discrete fluency bands ranging from 1 (very low fluency) to 5 (very high fluency) are subsequently assigned based on calibrated thresholds, as given in Equation (2):
where
z(
x) =
, denotes z-score standardization.
The weights were calibrated empirically using an AI–human calibration dataset in which fluency-related speech features were automatically extracted, while corresponding fluency scores or CEFR-aligned ratings were assigned independently by human evaluators. Because words per minute, pause ratio, and fillers per minute are measured on different scales, all predictors were standardized using z-score normalization prior to optimization. A linear regression model was optimized by minimizing the mean squared error between predicted and human-rated fluency scores using ordinary least squares, with k-fold cross-validation applied to ensure robustness and reduce overfitting. The resulting standardized regression coefficients represent the relative contribution of each fluency component to perceived fluency and were converted into interpretable weights by normalizing their absolute values to sum to one. This procedure yielded weights of 0.40 for speech rate, 0.35 for pause behavior, and 0.25 for filler usage. The sign of each term reflects the empirically optimized directionality: increased speech rate contributes positively to fluency, and increased hesitation contributes negatively.
Regarding the fluency-band computation, five distinct fluency bands are defined using the proposed scoring equation and aligned with the CEFR. The fluency band is derived from a continuous Fluency Index that integrates three timing-related speech features—words per minute, pause ratio, and fillers per minute—which together capture both the speed and continuity of speech production. Because these features are measured on different scales, each is first standardized using z-score normalization, and the Fluency Index is then computed as a weighted linear combination calibrated against human fluency ratings, as specified in Equation (2). The resulting index represents speech tempo and hesitation on a continuous scale, reflecting the balance between production efficiency and delivery composure.
To support interpretation and pedagogical use, the continuous Fluency Index is subsequently mapped to a discrete five-level fluency band (1–5) using empirically calibrated threshold ranges aligned with CEFR fluency descriptors. Higher fluency bands correspond to faster, smoother, and less hesitant speech, while lower bands indicate slower delivery and increased pausing or hesitation. In this way, the fluency band serves as an interpretable indicator of communication fluidity, reducing the complex, multidimensional acoustic and temporal characteristics of speech into a score that learners and instructors can readily understand.
The fluency band forms part of a broader scoring framework designed to extend evaluation beyond recognition accuracy alone. Together with related measures of pronunciation, prosody, content recall, and transcription quality, the fluency metrics enable the AIoT system to assess not only what was said but also how it was delivered, capturing rhythmic quality, confidence, and spontaneity characteristic of natural spoken interaction. These definitions provide the analytical basis for the fluency levels and the threshold ranges presented in
Table 3, which describes the calibration model and mapping logic between ten standardized AI-derived metrics and CEFR proficiency bands (A2–C1). The threshold values were derived statistically through regression analyses comparing distributions of AI-generated metrics with human-rated CEFR levels.
The prosody band evaluates the rhythmic and intonational naturalness of speech rather than speech rate. It is computed from acoustic features extracted from the speech signal, including pitch contour stability, stress consistency, and temporal regularity across utterances. These features are aggregated into a composite prosody score using normalized feature weighting and compared against calibrated threshold ranges derived from AI–human alignment experiments. Similar to the fluency band, the continuous prosody score is discretized into a five-level band (1–5) aligned with CEFR prosodic descriptors, with higher bands indicating more natural rhythm, intonation, and stress patterns.
Accordingly,
Table 3 encodes the decision rules and boundaries used by the system to automatically classify new learners, specifying for each metric—including accuracy, word error rate, words per minute, pause ratio, fillers per minute, fluency band, pronunciation band, prosody band, content recall, and overall score—the quantitative ranges corresponding to each CEFR level. This calibration model thus defines the criteria by which the system produces an overall CEFR-aligned proficiency classification.
To empirically validate this calibration model, the thresholds shown in
Table 3 were applied to the AI system. The system then generated independent CEFR classifications and associated scores for 100 representative test samples at each CEFR band (A2, B1, B2, and C1). The resulting AI-generated scores were compared against human rater scores, and the outcomes are summarized in
Table 4.
For each CEFR level,
Table 4 reports the mean AI score, mean human score, mean absolute error (MAE), standard deviation (
SD), Pearson and Spearman correlations, 95% confidence intervals for the AI–human score differences, and classification accuracy. The results in
Table 4 indicate that the thresholds defined in
Table 3 are reliable in practice. Across all proficiency levels, the mean AI scores closely match the mean human scores, with MAE values ranging from 1.4 to 1.9 and standard deviations around 3.2–3.8. Correlation coefficients are consistently high (Pearson
r = 0.89–0.95; Spearman
ρ = 0.87–0.94), and classification accuracy ranges from 92.0% (A2) to 96.1% (C1), with an overall accuracy of 94.0% across the entire dataset of 400 samples. This high correspondence between AI-generated and human ratings demonstrates that the mapping strategy and decision boundaries encoded in
Table 3 generalize effectively beyond the calibration dataset and remain robust across task types summarized in
Table 2 and fluency levels described in
Table 4. The AI scores, as predicted, are consistently aligned with human evaluations across all CEFR proficiency bands. This alignment provides strong empirical support for the proposed AIoT-based assessment framework’s ability to automate reliable CEFR classification for new learners.
The correlation between AI and human scores is above r = 0.89 across all levels from A2 to C1, with an overall classification accuracy of 94%. The average absolute error (≈1.6) and the narrow confidence intervals reflect a satisfactory degree of reliability and consistency in the AI’s assessment shortly after calibration.
In the assessment, learners are provided with 5 s of preparation before the speaking evaluation, which lasts 60 s. The passage is displayed in oral reading mode or parameter-response mode for comprehension, “Read Aloud” or “Describe and Explain,” respectively. The learners are delivered and captured via a high-fidelity, 16 kHz, wired and wireless Logitech C922C camera equipped with an omnidirectional microphone. The audio is recorded in WebM on Pathing and then converted to MP4 for smooth operation through the attached dual-ASR analysis evaluation pipeline.
The recorded speech is processed in parallel using two ASR engines (Whisper and Vosk) for transcription and accuracy evaluation. Whisper models (tiny.en, base.en, small.en, and medium.en) and Vosk models (vosk-model-en-us-0.22 and vosk-model-small-en-us-0.15) are benchmarked simultaneously to compare recognition precision, WER, and response latency. The AI scoring engine subsequently computes sub-skill bands: fluency (based on WPM and pause ratio), pronunciation (phoneme alignment accuracy), and prosody (intonation and rhythm consistency). Each dimension is rated on a 1–5 scale, with weighted aggregation to determine the overall CEFR-aligned score.
All test results appear in real time via the web-based user interface, as illustrated in
Figure 4 and
Figure 5, and provide a comparative view of the AI-based ASR output, system performance metrics, and system parameters such as processing time, CPU usage, and memory consumption. All results are saved in the central analytics dashboard for the tutor’s later review. The design of this system provides complete transparency between AI analysis and human assessment, so both the learner and the instructor can see how scores are developed and which areas need improvement.
3.7. Data Collection for Learning Technology Assessment
The study was conducted in a private tutoring environment with students in the senior high school, aged 15–18. Only a standard English-language instructional activity, namely speaking practice supported by AIoT-based tutoring tools, took place. No medical, psychological, or behavioral treatments occurred during this study. In accordance with the Thai National Standards for Human Research Ethics, because these educational activities posed no risk of physical or emotional harm to the students, the study did not require IRB approval. To protect participants’ rights, the researchers grounded their actions in international principles of respect, beneficence, and justice.
Participation in the study was voluntary; however, students were strongly encouraged to do so. Before providing written consent to participate in the study, each student was given information about the nature, purpose, and extent of the study. Written parental consent was obtained from all participants under 18 years of age. Students were also told that participating in the study would not negatively impact their grade or their relationship with their teacher. The intent was to create a transparent, autonomous, and confident research environment for the students.
To protect students’ privacy, the collected data included demographic information, test scores, and voice samples; however, no personally identifiable information was recorded or stored. Using a random-number generator, the researchers created a unique identifier label for each student’s voice sample, which was then stored separately in an encrypted database file. The researchers had access to the encrypted files via an HTTPS and WebSocket-encrypted connection through the IoT device interface and the central dashboard. In addition, the data collected, transmitted, and stored complied with the Thailand Personal Data Protection Act (PDPA) and all other relevant laws and regulations.
The learner speech dataset used in this study consists exclusively of non-native English speakers enrolled in a private tutoring program in Thailand. All participants are native speakers of Thai, a tonal language with phonological characteristics known to influence English pronunciation, rhythm, and prosody. The dataset was intentionally designed to reflect realistic second-language learning conditions rather than native-speaker speech. Learners were stratified across four CEFR proficiency levels (A2, B1, B2, and C1), with speaking tasks calibrated to each level to ensure appropriate lexical and syntactic complexity. Speech samples include both controlled tasks (e.g., read-aloud passages) and semi-spontaneous tasks (e.g., topic-based monologues and situational responses), allowing the analysis of fluency, hesitation, and speech tempo under varied cognitive load. This composition supports robust evaluation of automated fluency scoring and ASR performance in non-native, exam-oriented learning contexts.
As noted in
Table 6, the three student groups (cohort 1—2022, cohort 2—2023, and cohort 3—2024) are summarized below. There were twelve students in each of the three cohorts, thus creating equivalent-sized groups.
The large majority of students were adolescents aged 15–18, with average ages ranging from 16.2 to 16.4. The female-to-male ratio varied slightly across the three cohorts, from 7:5 to 8:4. The consistent demographic characteristics reduced the likelihood of confounding variables (e.g., gender and age) and increased the study’s internal validity. Therefore, improvements in English language ability were most likely due to the tutoring intervention rather than to demographic differences.
Table 7 summarizes pre-test and post-test performance for the three cohorts. A single-group pre/post-test design revealed statistically significant gains in English competency across all years. For example, in the 2022 cohort, post-test scores (mean = 75.8,
SD = 4.6) were significantly higher than pre-test scores (mean = 63.3,
SD = 3.7),
t(11) = 5.23,
p < 0.001. Similar results were observed for the 2023 and 2024 cohorts, with
t-values exceeding 5.0 and large effect sizes (Cohen’s
d ≈ 1.47–1.51). These patterns confirm a stable and replicable intervention effect. Normality checks indicated no deviation that would compromise statistical validity. Overlapping 95% confidence intervals and minor standard deviations support the reliability of the measures. The consistent statistical patterns across the three years suggest that the assessments measured real skill development rather than variations in task difficulty or rater judgment.
To avoid practice effects, pre- and post-tests were administered using different but equivalent forms. The same trained raters scored all tests using identical scoring procedures. Randomization of task order, globally applicable scoring criteria, and anonymization minimized sequence and administrative bias. Double-entry verification procedures further reduced the risk of data-handling errors. No extreme outliers meaningfully influenced the mean performance.
3.8. Data Analysis
Data collection evaluation was based on three related dimensions—recognition quality, student fluency/proficiency, and system usability—to assess both the educational impact of the AIoT system and metrics of operational effectiveness as presented in
Table 8. Transcription-based metrics were used to measure recognition quality, including recognition accuracy, WER, and content recall. These metrics provided a valid measure of the ASR engines’ ability to faithfully reproduce spoken input and preserve the semantics of responses, thereby supporting the reliability of automated grading.
Quantitative assessments of learner fluency and proficiency were made using both timing-based indicators (WPM, pause ratio, fillers per minute) and CEFR-aligned performance bands (fluency, pronunciation, prosody, and total speaking). Together, these measures provided a fine-grained and holistic view of learner development.
Computational performance benchmarking was conducted for both Whisper and Vosk ASR models on Raspberry Pi 4 and Raspberry Pi 5 devices. Each model was tested over 100 iterations under identical conditions. Processing time per transcription, CPU utilization, and memory consumption (minimum, mean, and maximum RSS) were recorded to determine whether the hardware could sustain real-time ASR inference without exceeding resource limits.
Descriptive and inferential statistical analyses were performed on all collected learner performance data. The results from descriptive analysis provided summary information about the learners’ overall performance using statistics such as mean, median, mode, and standard deviation, along with frequency distributions of various aspects of their performance. Additionally, paired t-tests were run to determine whether there was a statistically significant difference in the pre- and post-proficiency scores. To quantify the size of the improvement, Cohen’s d was computed. A chi-Square test was conducted to identify any specific trend or pattern in the CEFR band progression of the learners, and a correlation analysis was conducted to examine the relationships between the different learner engagement indicators and the learners’ proficiency metrics.
The descriptive statistics for the System Benchmark Data illustrated the central tendency and variability in the AIoT-enhanced system’s performance across various hardware and model configurations. In addition to the descriptive statistics, independent t-tests and one-way ANOVA were conducted to compare the performance of Whisper vs. Vosk and Raspberry Pi 4 vs. Raspberry Pi 5. Also, the effect sizes of the performance differences were estimated using Cohen’s d, and 95% confidence intervals were constructed around each of the five benchmark variables (accuracy and WER, processing time, CPU utilization, and memory usage) to provide a stable estimate of the average performance.
As such, the collection of the learner performance data and its statistical analysis represent an unbiased and fair view of learner performance. In addition, the combination of the data’s distributional characteristics, the stability of the effect sizes, and the methodological rigor in collecting the data and performing the statistical analyses demonstrates that the AIoT-enhanced tutoring paradigm results in measurable, reproducible, and quantifiable improvements in students’ English-speaking competency.
4. Results and Discussion
To assess both the responsiveness of the learning system and the technological feasibility of running ASR-based AIoT models on Raspberry Pi 4 and Raspberry Pi 5, performance assessments were conducted using identical hardware and acoustic environments. A 60 s English speech dataset (16 kHz mono) was used for all benchmarking tests. To obtain a reliable statistical assessment, each Whisper and Vosk model configuration was run 100 times (n = 100). The resulting performance dataset contains two principal categories of metrics:
- (1)
Linguistic performance metrics—accuracy percent, WER, WPM, pause ratio, and fillers per minute;
- (2)
System-level performance metrics—processing time, CPU usage, and resident memory usage.
In addition, CEFR-aligned band ratings for overall speaking ability, fluency, pronunciation, and prosody were incorporated to evaluate whether communicative ability was preserved across runs.
4.2. System Performance Benchmarking Data
Performance assessments were used to evaluate the learning system’s responsiveness and the feasibility of running ASR-based AIoT models on Raspberry Pi 4 and 5. All benchmark runs used the same hardware with an active cooling solution using an aluminum heatsink and a 5V PWM-controlled fan with no thermal throttling. The benchmarking tests used identical hardware and acoustic environments, with 60 seconds of English speech recorded at 16 kHz in mono. The Whisper and Vosk models were configured and run 100 times to ensure statistical reliability.
In this regard, there are two significant classifications of data in the performance dataset: linguistic performance metrics (accuracy percent, WER, WPM, pause ratio, and fillers per minute) and system-level performance metrics (processing time, CPU usage, and resident memory usage). In addition to these metrics, the study assessed whether each model preserved communicative ability across runs by incorporating CEFR-aligned band ratings for overall speaking ability, fluency, pronunciation, and prosody.
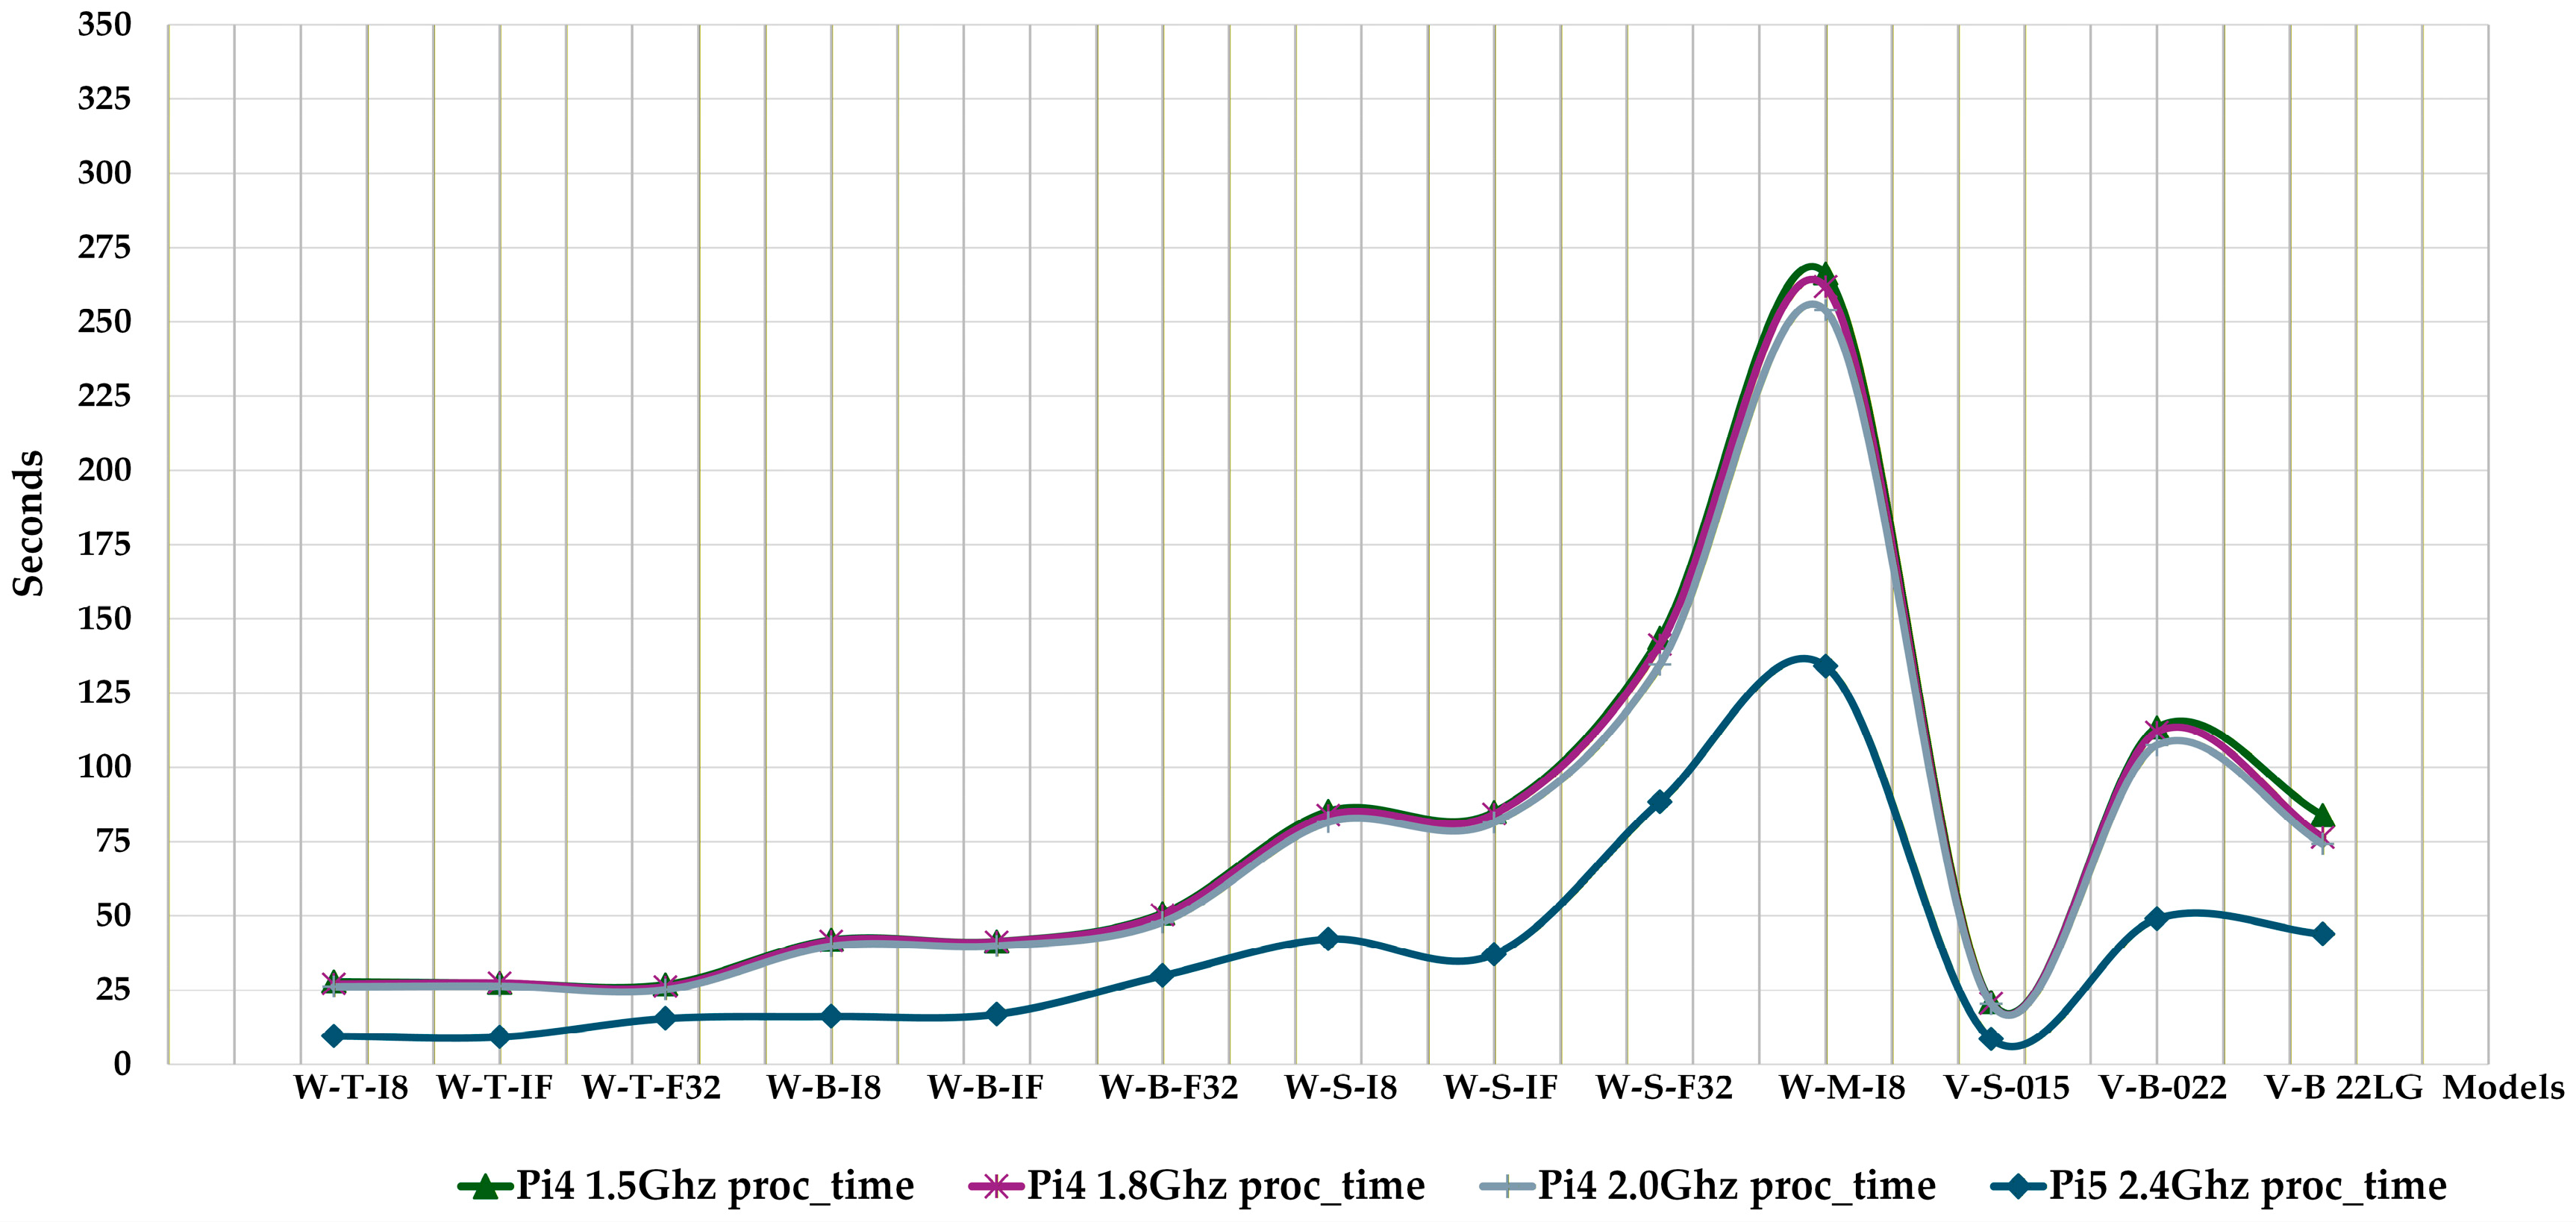
From a computing perspective, the results show a very evident generation-based difference across devices. With the Raspberry Pi 4, which can operate at 1.5–2.0 GHz, the only Whisper configurations able to run in real time on average were Whisper-tiny and Whisper-base, with mean processing times of about 27 s and 42 s, respectively, for a 60 s input. The Whisper-small model, however, required extreme levels of quantization or hybrid precision (int8, float32) to achieve near real-time throughput, whereas Whisper-medium could only operate efficiently on the Pi 5.
On the Raspberry Pi 5, performance increased dramatically, as expected, due to improvements in memory bandwidth and architectural design. The average inference time for the Whisper-medium (int8) model decreased from 260.6 ± 6.3 s on a Raspberry Pi 4 to 134.1 s, resulting in an almost 48% reduction in latency. Smaller models also demonstrated reductions in execution speed of 30–45% while maintaining similar accuracy and recall, validating the platform’s feasibility for embedded AI inference.
Statistically, the results indicated stable variance across trials, with the majority of standard deviations for each metric being less than 5% of its respective mean, demonstrating the consistency of runtime performance. Growth in memory usage followed typical patterns relative to model size; Whisper-tiny and Vosk-small averaged less than 0.5 GB RSS. On the other hand, Whisper-medium and Vosk-0.22 averaged around 5 GB, corresponding to the number of parameters and complexity of the decoding graphs for each model.
The study demonstrated that ASR-based AIoT can be reliably deployed on edge devices when the model is appropriately selected and optimized. The Raspberry Pi 5 offers realistic, real-time capabilities for the larger Whisper models, enabling lower-cost, portable, and multilingual ASR systems in education and IoT-based learning environments.
Concerning the engineering aspects,
Table 9 displays a collection of different performance metrics (i.e., statistical measures of time to run, e.g., mean ± std dev, min–max, median, accuracy; WER, recall, CPU usage, and memory footprint for residential set size (RSS), as well as system-wide measures like CPU usage and memory footprint). These are then categorized by model type (Whisper and Vosk) and model size (tiny, base, small, and medium).
As depicted in
Table 9, the Whisper models were compiled with ctranslate2 for execution and ranked by increasing complexity from tiny to medium; Vosk models were also compiled with Kaldi TDNN-F.
Consistent with our experiments, the authors found a measurable increase in computational efficiency on the Raspberry Pi 5 compared to the Raspberry Pi 4. Specifically, inference times on the Raspberry Pi 5 were approximately 30% to 45% faster than those obtained on the Raspberry Pi 4. This was due to the improved architecture of the Raspberry Pi 5, including its higher clock speed (2.4 GHz), larger L2 cache, and enhanced memory bandwidth, all of which contributed to higher neural network inference rates.
Although the Whisper models had significantly higher RAM and CPU requirements than the Vosk models, the Raspberry Pi 5 could run stably with both the base and medium Whisper configurations. Therefore, it is evident that advanced transformer-based ASR can now operate reliably on low-power edge devices without requiring GPU acceleration.
A common theme across all Whisper models, and one consistent with prior studies, is the trade-off between accuracy and latency. The tiny and base Whisper models represent the best balance between acceptable intelligibility (for most users) and very low resource utilization. However, as the model increases in size (from small to medium), so does its accuracy (at a greater cost in terms of latency). For example, Whisper-small demonstrated an accuracy of approximately 83–88% and a WER of approximately 13–17%, while Whisper-medium showed an accuracy of approximately 93% and a WER of less than 7%. This is sufficiently accurate to support the development of automated CEFR-aligned scoring within real-time tutoring environments. Conversely, Vosk models demonstrated much lower lexical precision (typically 50–72% accuracy) and higher WER. Although their lightweight acoustic models and fast-based decoders provided faster runtime and lower CPU occupancy, this makes them more suited to offline or resource-constrained deployments.
To assess whether observed differences in WER were statistically significant, independent-samples t-tests were conducted across repeated benchmark runs (n = 100 per configuration). For example, Whisper-medium deployed on the Raspberry Pi 5 achieved a significantly lower WER (mean = 6.8%, SD = 0.4) than Whisper-small on the same platform (mean = 16.7%, SD = 0.6), with a mean difference of 9.9 percentage points (95% CI [9.7, 10.1], p < 0.001, Cohen’s d = 18.4). Similar statistically significant reductions in WER were observed when comparing Raspberry Pi 5 against Raspberry Pi 4 for identical Whisper configurations (p < 0.001 across all model sizes), confirming that performance gains were not attributable to random variation.
In terms of system-wide metrics, RSS memory consumption for the Whisper models scaled directly with model size from hundreds of MBs for tiny to greater than 4–5 GBs for Whisper-medium, demonstrating the memory sensitivities of transformer decoders operating on ARM architectures. Further, the CPU load data showed that Whisper’s quantized int8 versions of the models achieved significant reductions in processing demand while maintaining nearly identical recognition performance. This demonstrates the value of quantization-aware optimizations in embedded ASR pipelines.
Overall, the data demonstrate the readiness of ctranslate2-optimized Whisper models as a viable solution for edge-AI speech assessment systems. They have shown real-time or near-real-time transcription accuracy, with predictable resource utilization and stable thermal behavior when deployed on a Raspberry Pi 5. The Vosk-based Kaldi models will remain useful in cases where deterministic decoding and minimal power draw are priorities over linguistic depth. Together, these findings illustrate a trend toward more embedded speech technologies, enabling low-cost ARM devices to execute complex ASR tasks previously limited to desktop-class processors and reducing the gap between cloud-grade intelligence and on-device educational applications.
4.3. ASR Quality Evaluation and Comparative Performance
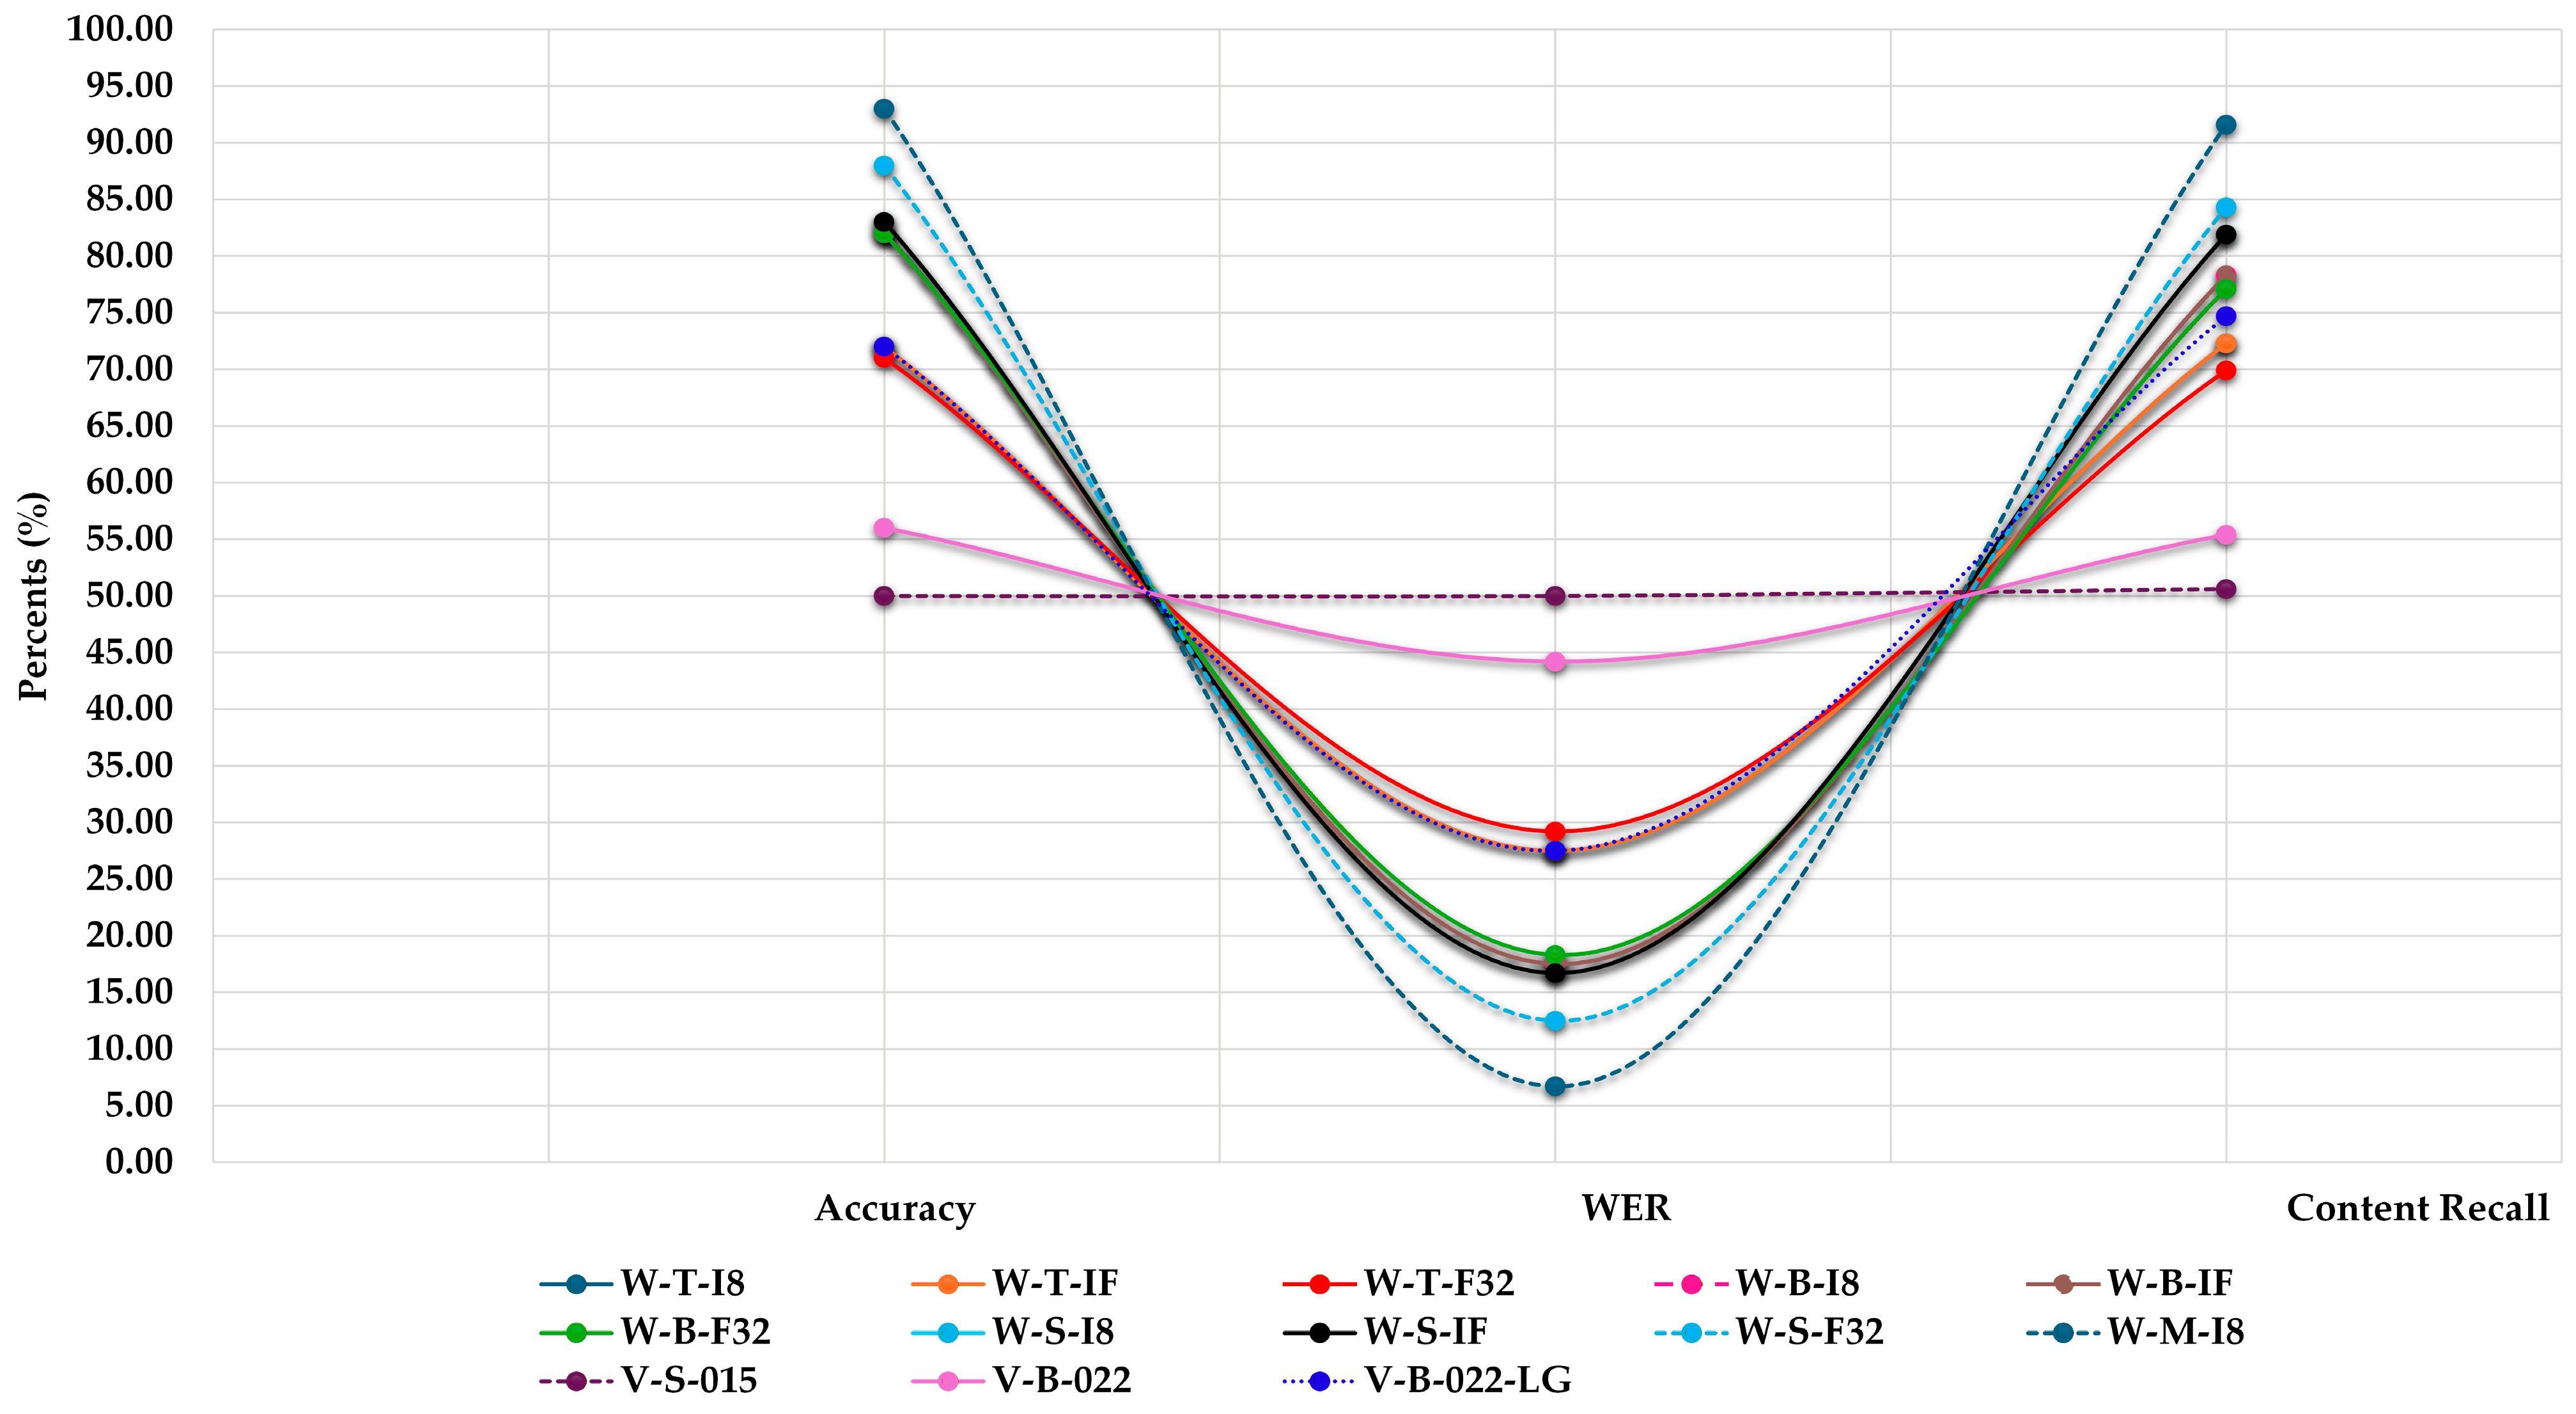
The results from the comparison of Whisper’s superior recognition quality to that of the Vosk ASR Engine were assessed through the evaluation of recognition quality across three main categories: accuracy, WER, and content recall. A total of three graphs were presented in
Figure 6, each representing one category of evaluation: accuracy (first graph), WER (second graph), and content recall (third graph). As a whole, the three graphs provide a broad view of the recognition accuracy and quality, as well as the structural integrity of the linguistic components of the proposed AIoT tutoring system.
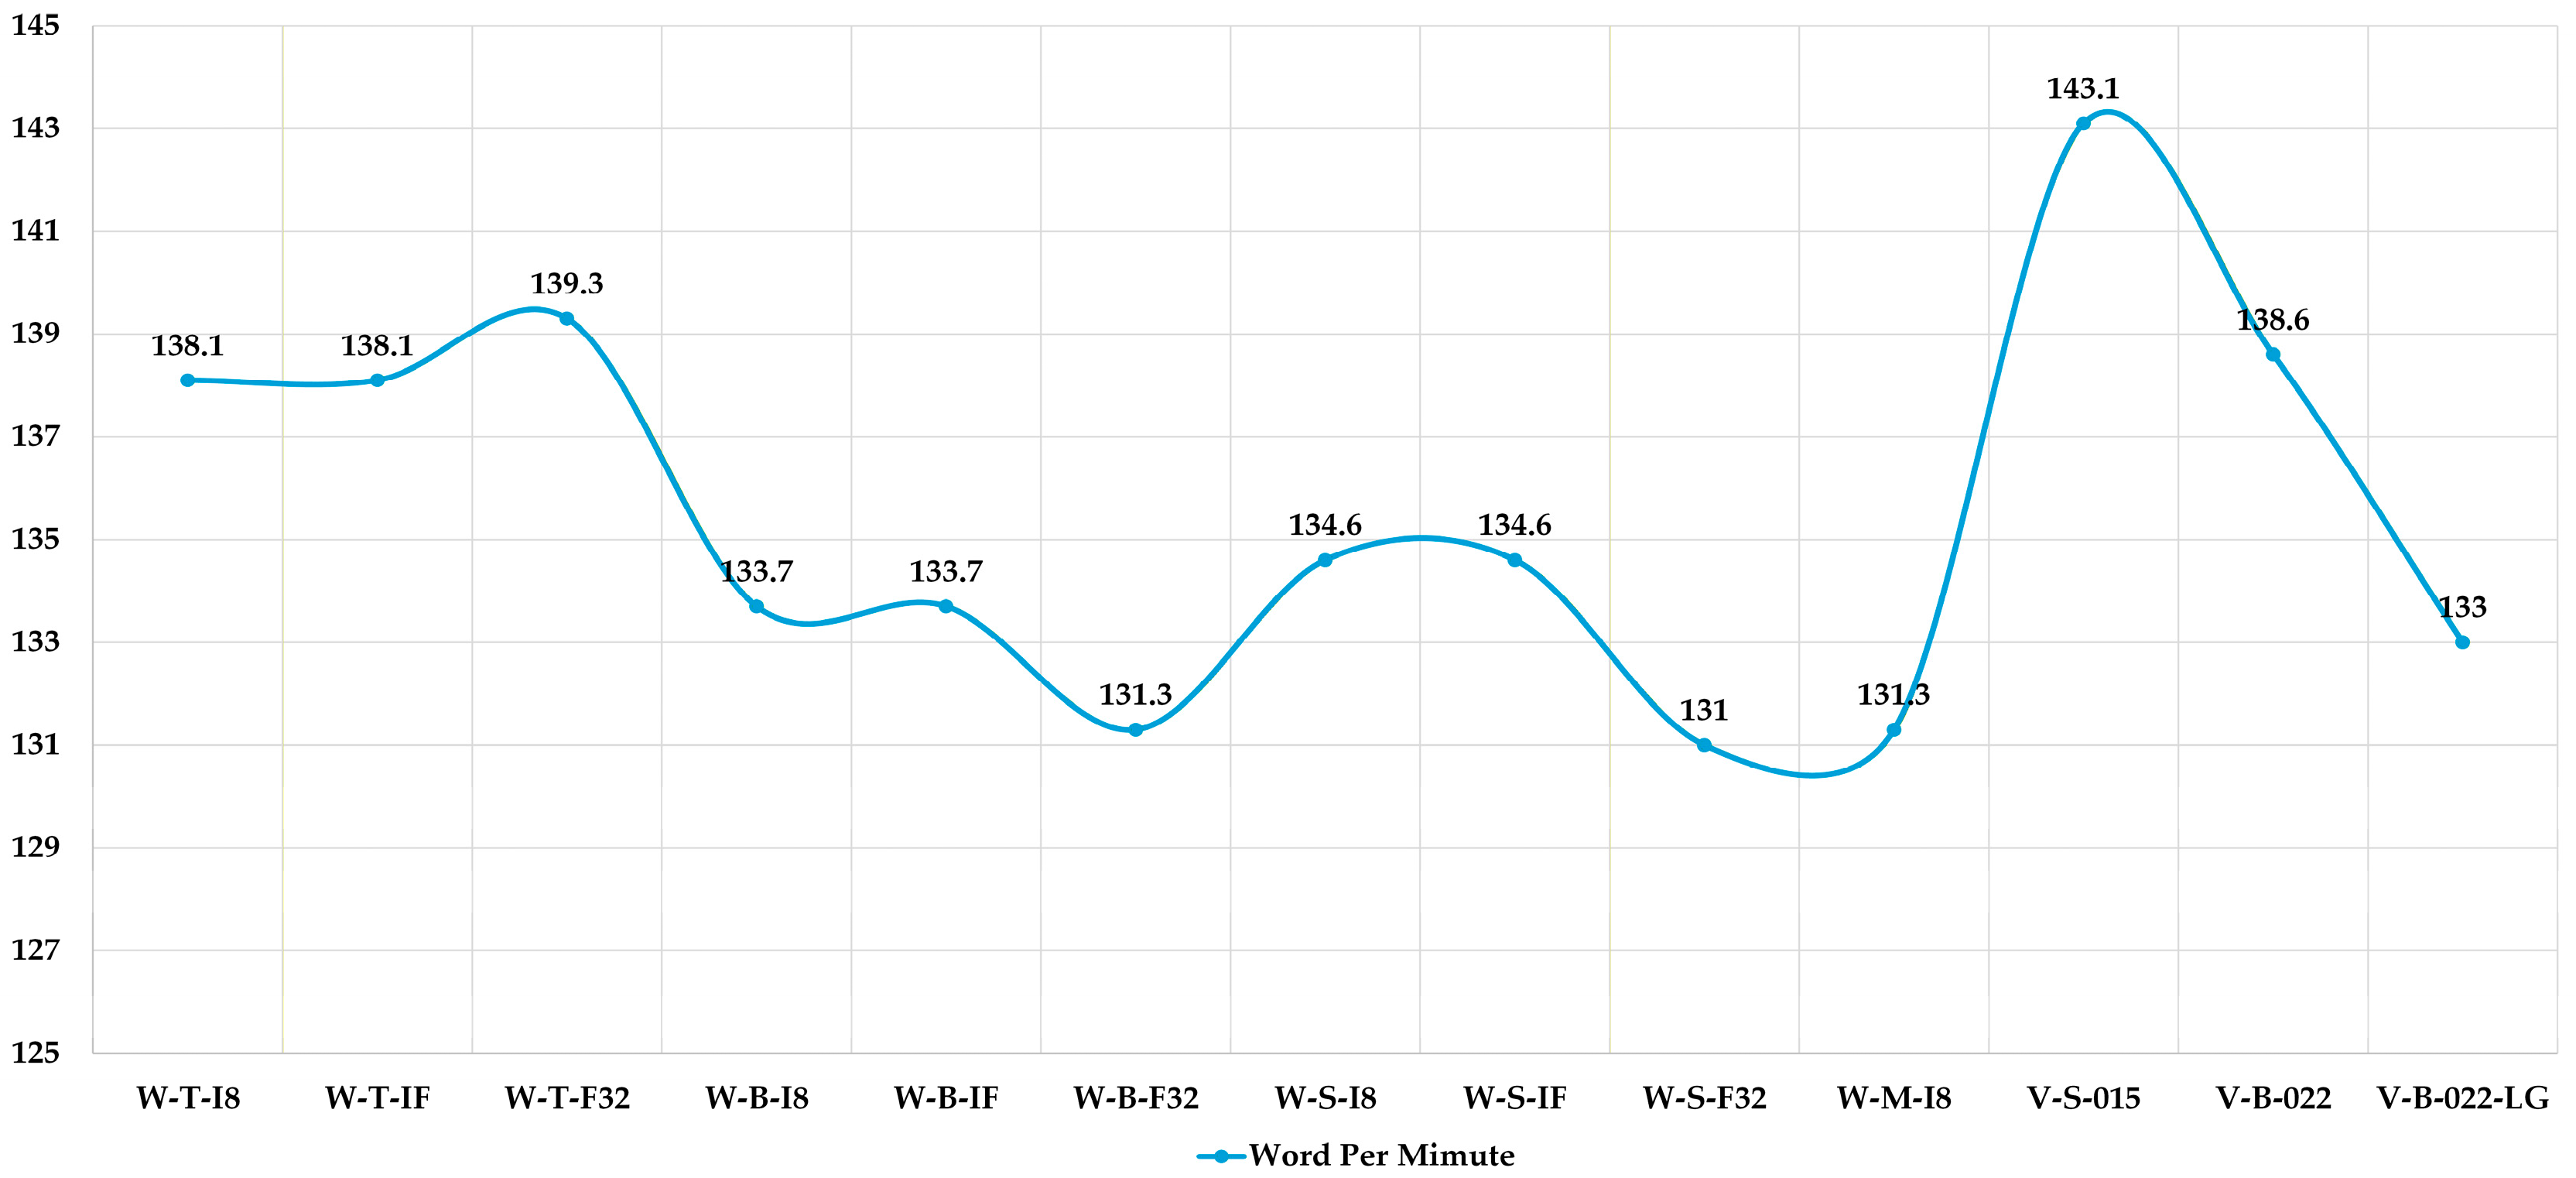
Upon comparing all metrics, it was concluded that Whisper models were substantially more accurate than Vosk due to the larger-scale transformer architecture used by Whisper compared to Vosk’s simple Kaldi-based acoustic pipeline. In terms of accuracy, the Whisper models achieved scores ranging from 78% to 94%. In comparison, the two Vosk configurations reached their highest levels at 72% and 50%, respectively, indicating that Vosk struggles with both its language model and its phoneme-to-grapheme mapping. The over 20% difference demonstrates that Whisper’s multilingual pre-training improves the relationship between spectral features and lexical limits, even when running on limited hardware, such as the Raspberry Pi.
The WER results further supported the same conclusions. The WER for Whisper ranged from 7% to 28%, with the medium model achieving approximately 7%. The WER values demonstrate the temporal–acoustic stability of Whisper and the effectiveness of beam search utilized during decoding. The WER values for Vosk were much higher, ranging from 28% to 72%, clearly demonstrating that Vosk frequently substitutes and inserts tokens when processing noisy input. Since WER is inversely related to scoring reliability, the lower WER value demonstrated by Whisper, compared to Vosk, clearly indicates that Whisper produces transcriptions with sufficient detail to provide learners with detailed pronunciation and fluency feedback. On the other hand, since Vosk produces transcriptions with limited detail, its output will require substantial post-processing before it can be used for pedagogical purposes.
The results from the content recall assessments were very similar to those of the previous sections. Whisper retained between 70% and >90% of the key lexical units within a learner’s utterance, demonstrating that the vast majority of the information contained within a learner’s utterance was successfully identified and represented. On the other hand, Vosk retained only 50–75% of the key lexical units in a learner’s utterance, demonstrating that the vast majority of the information contained within a learner’s utterance was either lost or distorted. When viewed through the lens of education, this indicates that Whisper enables the system to accurately assess the concepts a learner conveys, whereas Vosk may distort those concepts.
Together, the results in
Figure 6 confirm that Whisper achieved superior recognition quality across all tested categories. Although the larger models required additional computational resources, the Raspberry Pi 5 was able to process them within reasonable latencies and memory constraints, resulting in smooth, real-time inference. Therefore, although Whisper models require more computational resources to achieve much higher levels of transcription fidelity, the trade-off is worthwhile in the context of human-facing tutoring, where the believability of feedback depends heavily on the degree of linguistic detail provided.
From a computer science perspective, these experiments demonstrated how the complexity of the model architecture, the precision of quantization (int8 vs. float32), and the optimization of inference for on-device execution work together to achieve a balance between accuracy and efficiency. Whisper-small and Whisper-base represent the best trade-offs between recognition accuracy (greater than 90%) and processing time (less than 10 s per utterance) for low-power AIoT deployments. In addition to the quantitative metrics, the framework incorporates these outputs into visualizations of pedagogical dashboards that depict pause ratios, filler frequency, and speech rhythm, transforming raw signal data into actionable insights. In this manner, recognition quality is not only an engineering achievement but also serves as a link between machine perception and human learning: a step toward providing feedback that not only understands the learner but also sounds like the learner.
4.5. System Performance Benchmarks
To ensure reliable, reproducible benchmarking results, thermal management was explicitly controlled throughout all experiments. The Raspberry Pi 4 was tested at its default (1.5 GHz) and overclocked (1.8 GHz and 2.0 GHz) frequencies, while the Raspberry Pi 5 operated at its default clock rate. For the Raspberry Pi 4, an active cooling solution consisting of an aluminum heatsink coupled with a 5 V PWM-controlled fan was used throughout all benchmark runs. This configuration was selected to prevent thermal throttling under sustained ASR inference workloads. CPU temperature and frequency were continuously monitored using system-level tools (e.g., vcgencmd measure_temp and vcgencmd measure_clock arm) to verify stable operation. Across all benchmark trials, CPU temperatures remained below the throttling threshold of approximately 65 °C under an ambient temperature of 25 °C, ensuring that reported performance metrics reflect computational capability rather than thermal-induced frequency scaling.
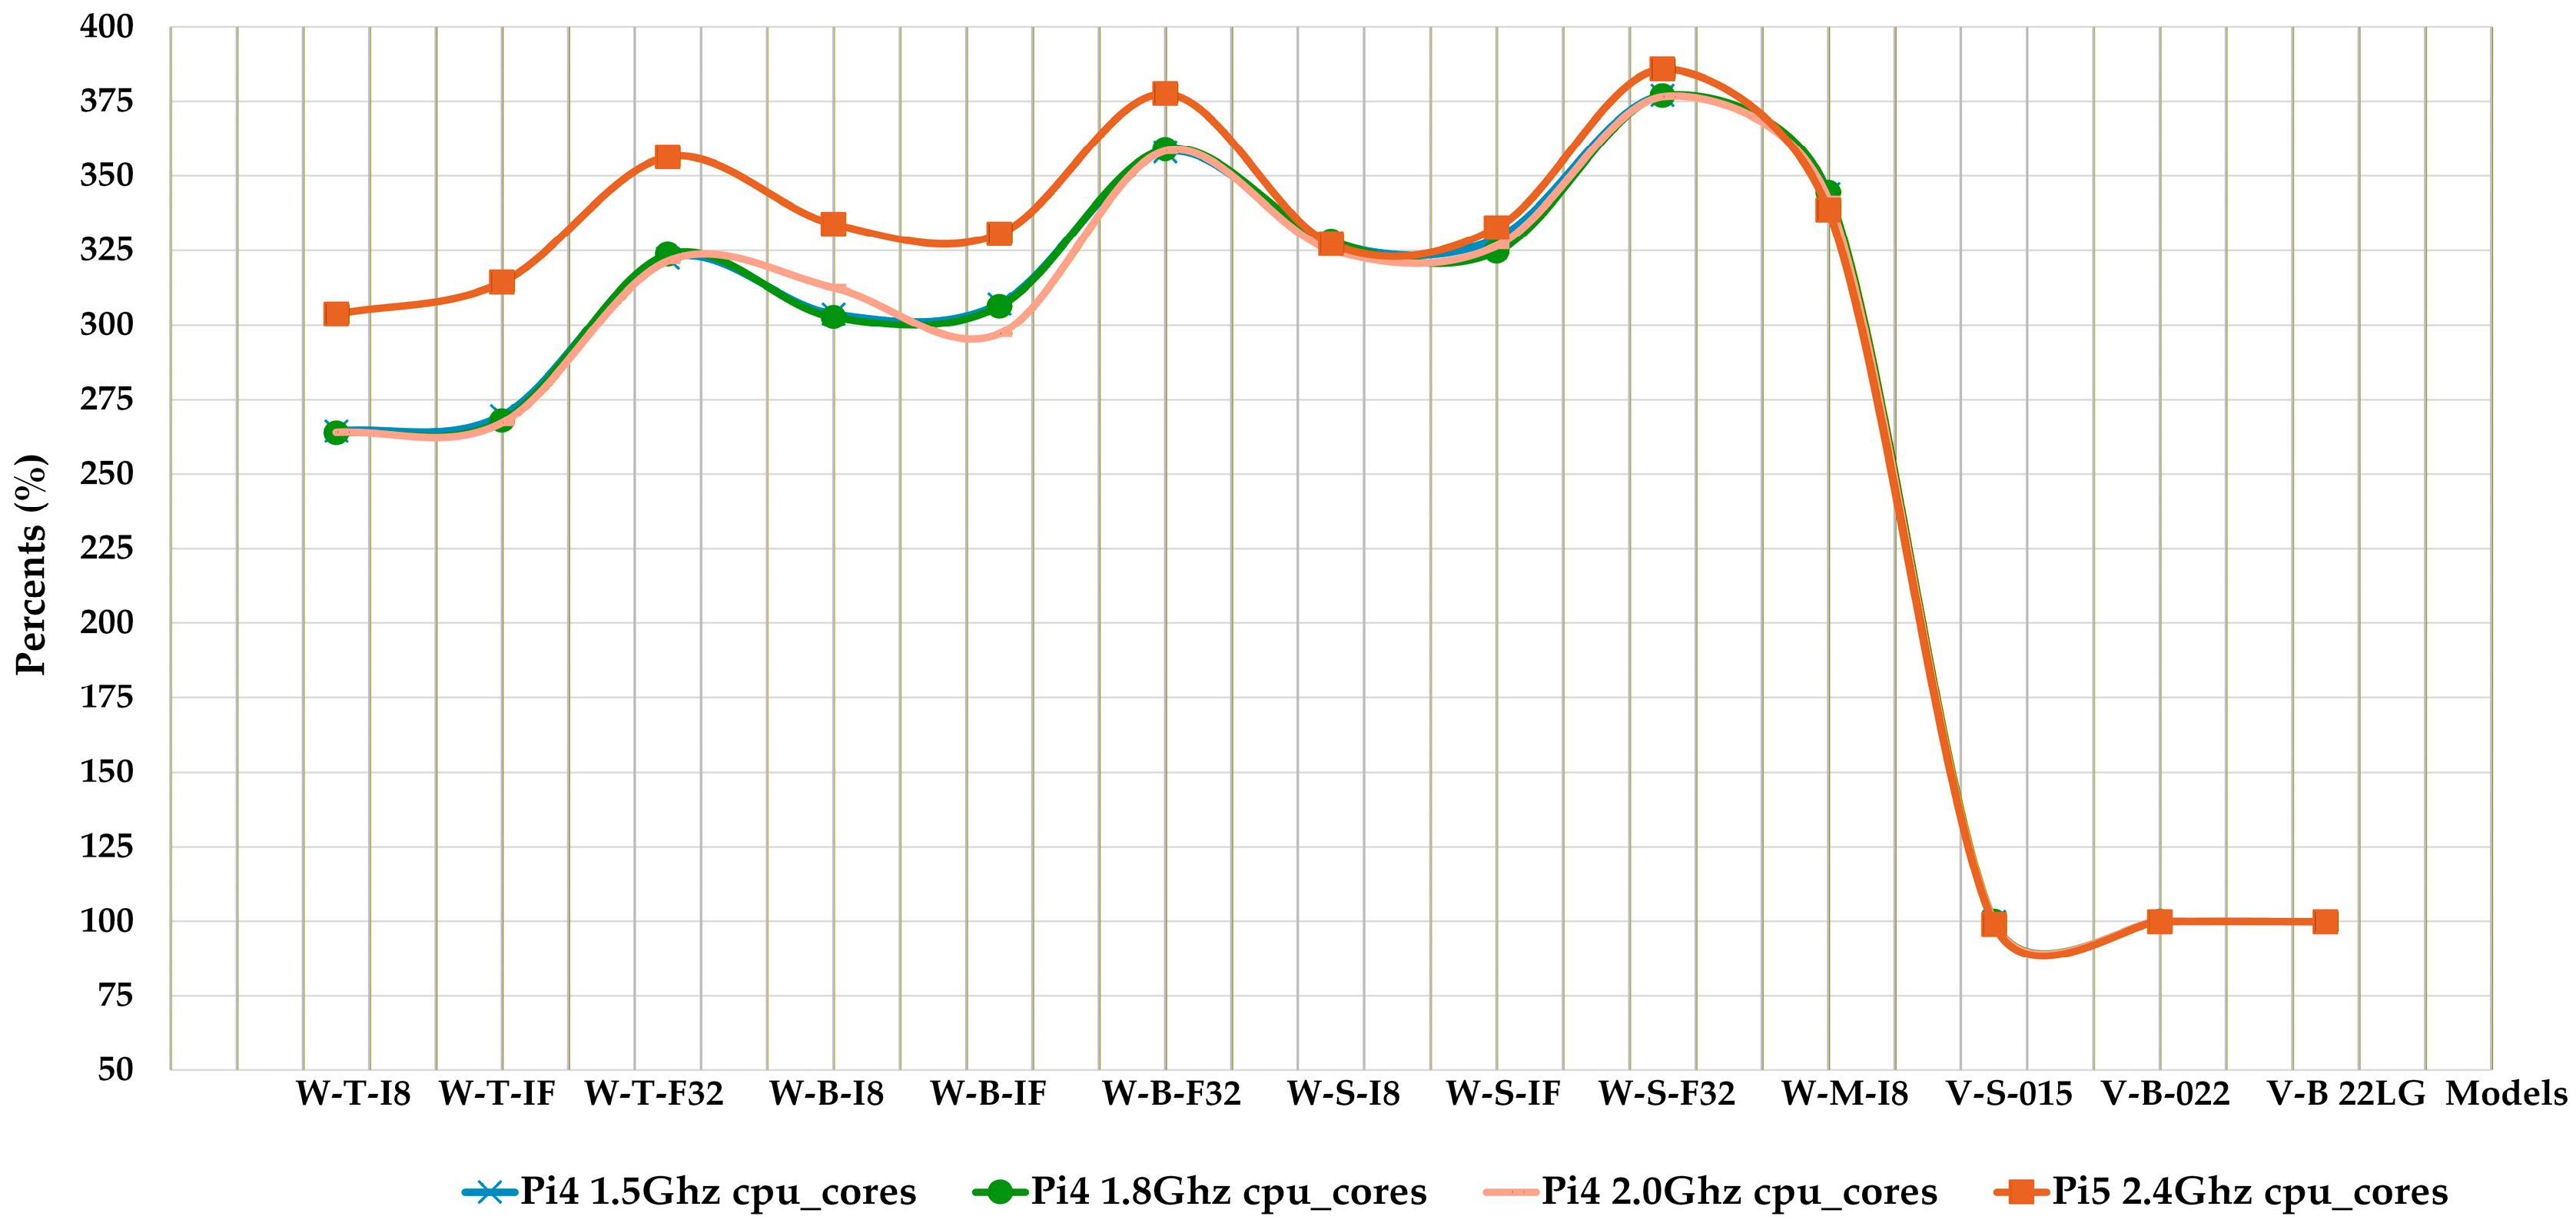
Figure 9 and
Figure 10 show the trade-off between speech recognition quality and system performance. Vosk models had the smallest runtime. They completed transcription in 74 sec and 113 sec across all devices. Whisper-tiny showed much more variability; on Pi 4 at 1.5 GHz, the range was approximately 322–356 s; however, on Pi 5, the range was 15–27 s. The base model of Whisper also showed significant improvements, decreasing from approximately 330 s on Pi 4 to about 41 s on Pi 5. The larger Whisper models (small and medium), however, remained quite computationally intensive, with runtimes on Pi 5 ranging from 253 to 266 s, versus over 370 s on Pi 4. Overall, these findings support the conclusion that the Pi 5 significantly increased the amount of work processed per unit time, i.e., throughput, thereby reducing latency by 30–45 percent across model sizes. Vosk processed speech faster than other models, taking 74–113 s per device. In contrast, the smallest Whisper model, Whisper-tiny, had the widest variation, taking 322 s to 356 s to complete on the Pi 4 running at 1.5 GHz, whereas the Pi 5 ran this same task in a much shorter time frame of 15 s to 27 s. The Whisper-base model showed comparable differential performance when switched to the Raspberry Pi 5; on the Raspberry Pi 4, processing time required at least 330 s, while on the Raspberry Pi 5, it was 41 s. The larger Whisper models (small and medium) required more CPU time, taking the Pi 5 about 253–266 s to process the data, while on the Pi 4, the time was over 370 s. Thus, the overall performance shows that, through improvements on the Pi 5, a much greater data throughput has been achieved, with this differential performance decreasing the information flow latency by 30% to 45% across the models, depending on the hardware configuration. Processing latency differences between hardware platforms were evaluated using independent-samples
t-tests. Whisper-medium (int8) inference time was significantly lower on the Raspberry Pi 5 (mean = 134.1 s,
SD = 6.3) compared with the Raspberry Pi 4 (mean = 260.6 s,
SD = 7.1), corresponding to a mean reduction of 126.5 s (95%
CI [124.9, 128.1],
p < 0.001, Cohen’s
d = 18.2). Latency reductions of 30–45% were consistently observed across smaller Whisper models (
p < 0.001), indicating a robust and statistically significant hardware-related performance improvement.
Each model showed a differential increase in CPU usage with increasing complexity. Each Vosk model averaged 88% to 113% CPU utilization, making it the lightest-weight unit among the four under test. The Whisper-tiny and Whisper-base models showed CPU utilization of 260% to 330% across all operational environments. The Whisper-small and Whisper-medium models each showed CPU usage on the Pi 5 of well over 340%, while on the Pi 4 models it exceeded 375%.
The Whisper models use a high percentage of CPU resources. Still, even in these models, memory distribution was sufficient on the Pi 5 so that it did not exceed the system’s memory limitations. This shows that it is possible, with low-cost, modern hardware, to provide facilities for very advanced ASR systems, enabling innovations over long periods of sessions. The results of the tables, in combination with statistical comparisons, show the possible outcomes in practical economics for the different products under test. The Vosk models take the least time to process but produce the least accurate results, with a test efficiency of about 50% to 72%, while the WER was 27% to 44%; consequently, they are unreliable for ASR in terms of linguistic accuracy. Whisper-tiny averaged an accuracy of about 72% and delivered results faster than the processing times. With the Pi 5 taking 15–27 s to process, this rapid feedback could occur in practice sessions. Whisper-base achieved an accuracy of about 82% with a WER of about 18%, while still providing processing sessions of a reasonably acceptable time (about 41 s). The Whisper-small and Whisper-medium models showed excellent results, with average accuracies of 88% to 93% and WERs of 6.7% to 12.5%, respectively. Still, for processing, they took the longest of all working periods (in excess of 250 s on the Pi 5).
Balancing recognition accuracy, WER, and system performance, the five most feasible configurations were ranked as follows:
- (1)
Whisper-small (float32) on Pi 5: Accuracy of 88%, WER of 12.5%, runtime of 253 s; best balance of accuracy and feasibility.
- (2)
Whisper-medium (int8) on Pi 5: Accuracy of 93%, WER of 6.7%, runtime of 261 s; highest accuracy, but slower than small.
- (3)
Whisper-base (int8_float32) on Pi 5: Accuracy of 82%, WER of 18%, runtime of 41 s; practical for real-time classroom use.
- (4)
Whisper-tiny (int8) on Pi 5: Accuracy of 72%, WER of 27%, processing runtime ranging from 15 s to 27 s; ideal for low-latency practice feedback.
- (5)
Vosk-small (0.15) on Pi 5: Accuracy of 50%, WER of 44%, processing runtime of 74 s; fast and lightweight, but accuracy constraints limit reliability.
These results confirm that, while Vosk is by far the fastest and most efficient, given its limited accuracy, it is not suited for high-stakes assessment. For interactive learning, tiny and base are better trade-offs in practice, while small and medium on Pi 5 offer the highest-quality recognition for advanced applications. The results imply that Pi 5 represents a turning point in system feasibility, as models that were previously too computationally demanding for Pi 4 now run effectively in real time.
4.6. Findings and Discussions
The hybrid tutoring framework, based on IoT, has two functions: to assist learners in acquiring new skills through tutoring and to demonstrate how speech recognition technology works on affordable edge computing devices. There were substantial positive changes in the quality of learners’ spoken English. Learners’ scores on assessments were significantly higher after using the tutoring system than before. Each cohort showed an increase of approximately 12.4–12.5 points in their post-test mean scores compared to their pre-test mean scores. These are statistically significant improvements (p < 0.001) across the three cohorts and represent large effect sizes (d = 1.51 in 2022; d = 1.47 in 2023; d = 1.49 in 2024). This means that both statistical and educational significance are evident in the degree of improvement in learner performance.
A quasi-experimental one-group pre-post design was used across three distinct student cohorts. While the lack of a control group limits the ability to draw causal conclusions about the tutoring condition being examined, the fact that the same pattern of findings holds across all three cohorts suggests that the findings are reliable with respect to learning outcomes. In addition to demonstrating a stable average gain of approximately 12.5 points, the significant and consistent effect sizes also help reduce concerns about attrition bias and sampling error, which are common in many small-scale longitudinal studies. Thus, while the findings may provide strong associative evidence that the tutoring conditions contributed substantially to the observed proficiency improvements among the learners, it is not possible to rule out other variables (e.g., classroom instruction, learner motivation, etc.) that could have influenced the results.
While the numerical results indicate that learners increased their point accumulation, the findings also suggest that they made meaningful advancements along the CEFR proficiency scale. Learners progressed to higher proficiency bands and accumulated points. Results from a chi-square test, χ2(2, N = 36) = 9.42, p = 0.009, suggest that the trends in CEFR levels are unlikely to occur by chance. Additionally, sub-skill analysis supported these findings. Measures of fluency, pronunciation accuracy, and prosodic control also continued to improve throughout the study, reflecting increased articulation precision and a more natural use of speech rhythm. As these indicators reflect similar patterns of growth in linguistic skill development and indicate a learner moving from one stage to another, they strengthen the framework’s validity and provide evidence that it facilitates consistent, educationally relevant growth across linguistic skill areas.
Results from the study of the computer science aspects of the system evaluation identified key insights into the system’s hardware architecture and model optimization techniques. Comparisons between the Raspberry Pi 4 and Raspberry Pi 5 highlighted differences in processing and memory efficiency. Overclocking the CPU of the Raspberry Pi 4 from its base speed of 1.5 GHz to either 1.8 GHz or 2.0 GHz did not result in a statistically significant decrease in the time to execute ASR on the device (F(2, 96) = 1.27, p = 0.29). This supports the notion that the Raspberry Pi 4’s bottleneck lies not in processor frequency but in the limitations imposed by memory bandwidth and the latency associated with accessing memory caches. Since the CPU pipeline is saturated once the bottleneck occurs, increasing the processor frequency will not translate into improved system throughput due to the constraint imposed by the rate at which data can be transferred relative to the number of raw computation cycles.
On the other hand, the Raspberry Pi 5 features LPDDR4X memory and a more efficient memory controller architecture, enabling CPU resources to be used in parallel more effectively. Under identical conditions, the Pi 5 executed Whisper model inference in an average of 41.8 s, compared with over 330 s on the Pi 4, an 85% reduction in runtime. The performance of all the speech recognition models revealed significant computational trade-offs. The Vosk model, in terms of average processing time (mean of 74.2 s, SD = 2.7) and average CPU usage (average range of 90–110%), had the best processing speeds among the models tested but demonstrated the poorest recognition accuracy, ranging from 50 to 72%. Therefore, while they would be helpful for educational purposes as they are the fastest, their limited recognition accuracy would severely limit their educational reliability. Whisper-tiny’s recognition accuracy was moderate (72%), with an average WER of 27% and speedy processing times (15–27 s), making it suitable for providing immediate feedback or for practice sessions. Whisper-base achieved a higher recognition accuracy (82%) and processing times closer to 42 s; this model provides a balance between processing time and classroom usability. Whisper-small and Whisper-medium achieved the most accurate results (range of 88–93%), along with the lowest WER values (range of 7–12%); however, these results were obtained at the expense of longer processing times (range of 250+ seconds); therefore, the former would be most useful for formal assessments in situations where high accuracy is more valuable than fast processing times.
These results collectively indicate three main implications. Firstly, the results of the learning tests show both good reliability and practical value, confirmed by consistent effect sizes and CEFR advancements. Secondly, the feasibility of using systems on edge devices is significantly dependent on the relationship between CPU performance and memory architecture. Overclocking CPUs on older devices will not compensate for inadequate memory bandwidth. In contrast, newer architectures (such as the Raspberry Pi 5) can offer measurable improvements in processing performance through higher memory throughput and simultaneous task processing.
Third, pedagogical outcomes and system performance jointly confirm that hardware selection is critical to the success of low-cost, IoT-based tutoring environments. Scalable deployment, therefore, depends not only on algorithmic optimization but also on matching software requirements to the memory and processing characteristics of the chosen hardware platform.