Article

Key-Frame Extraction for Reducing Human Effort in Object Detection Training for Video Surveillance

Department of Computer Engineering, Sejong University, Seoul 05006, Republic of Korea
*
Author to whom correspondence should be addressed.
Electronics 2023, 12(13), 2956; https://doi.org/10.3390/electronics12132956

Submission received: 15 May 2023 / Revised: 17 June 2023 / Accepted: 3 July 2023 / Published: 5 July 2023
(This article belongs to the Collection Computer Vision and Pattern Recognition Techniques)

Abstract

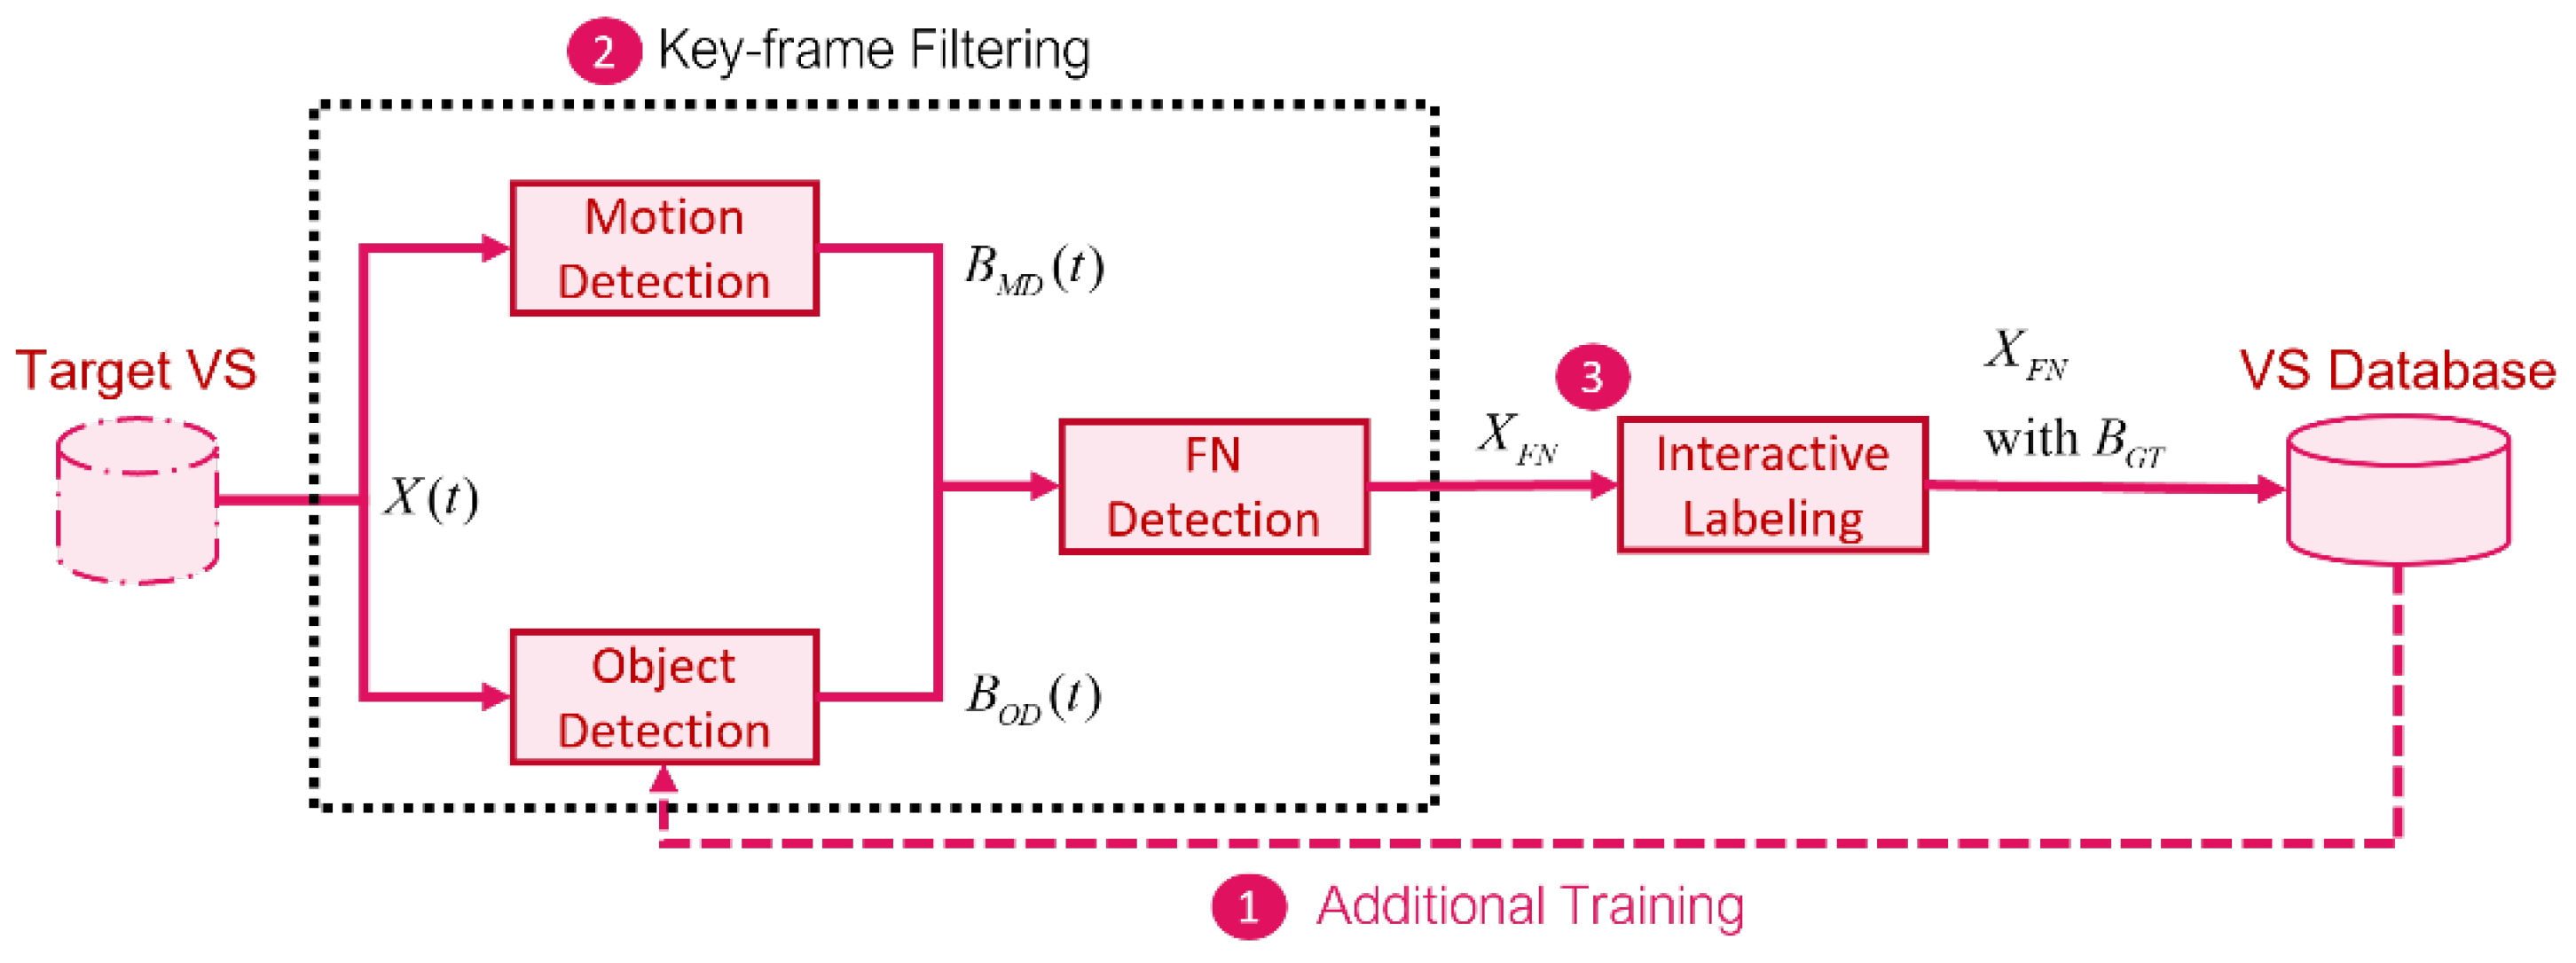
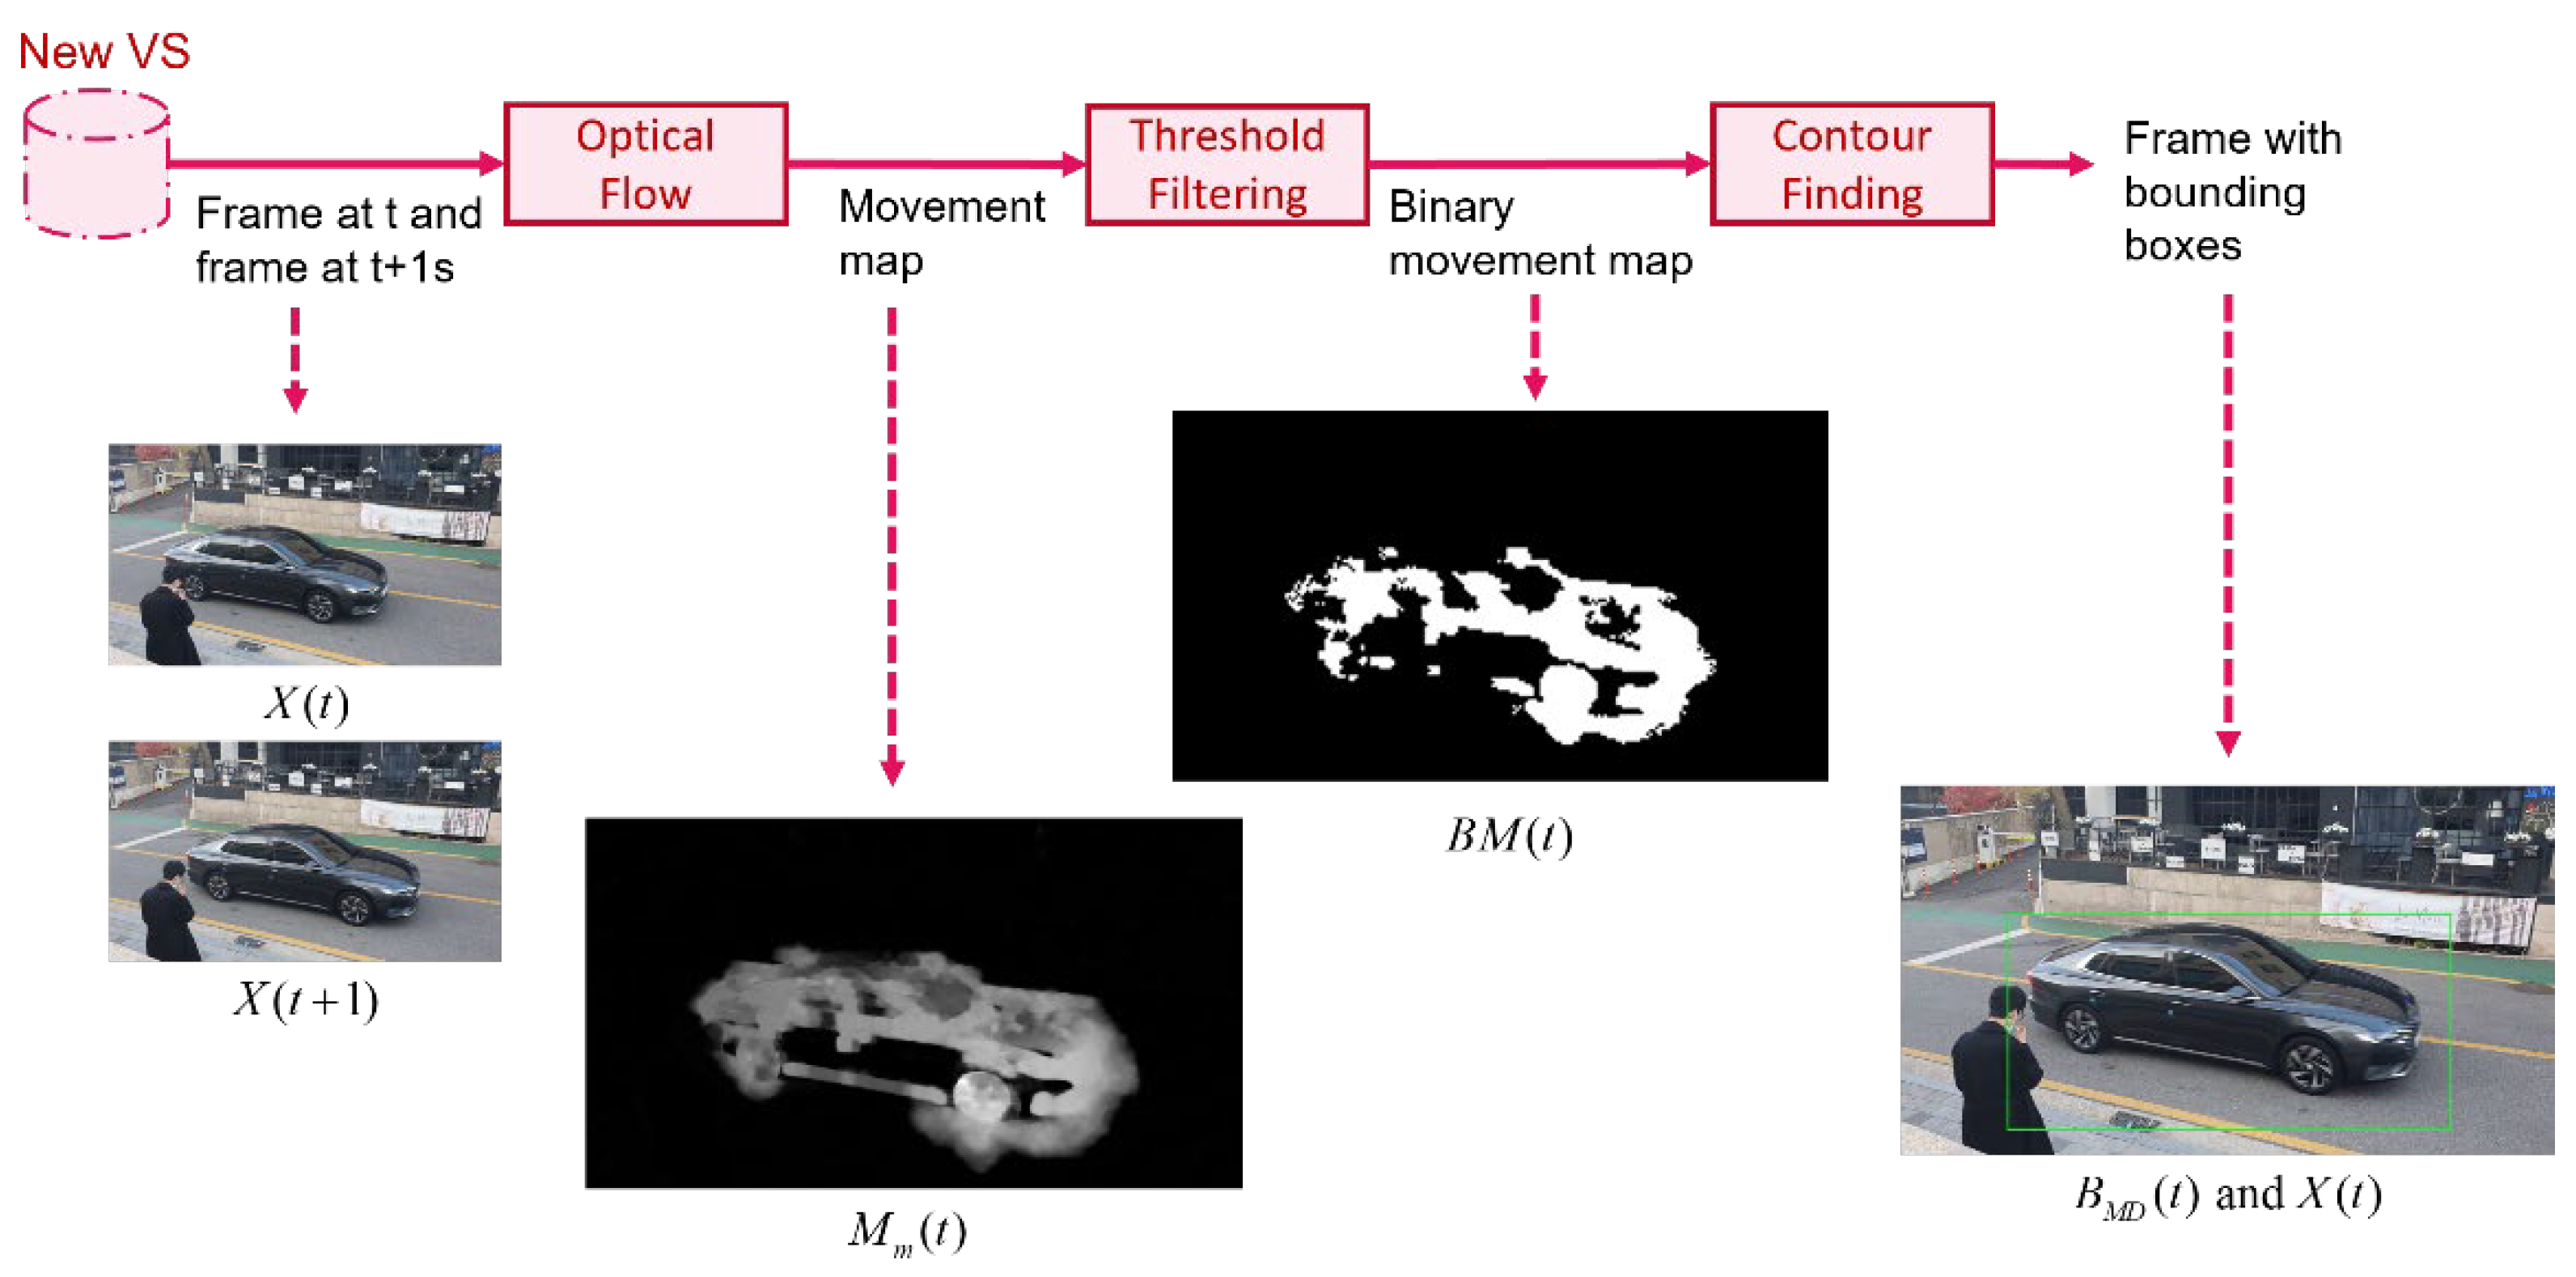
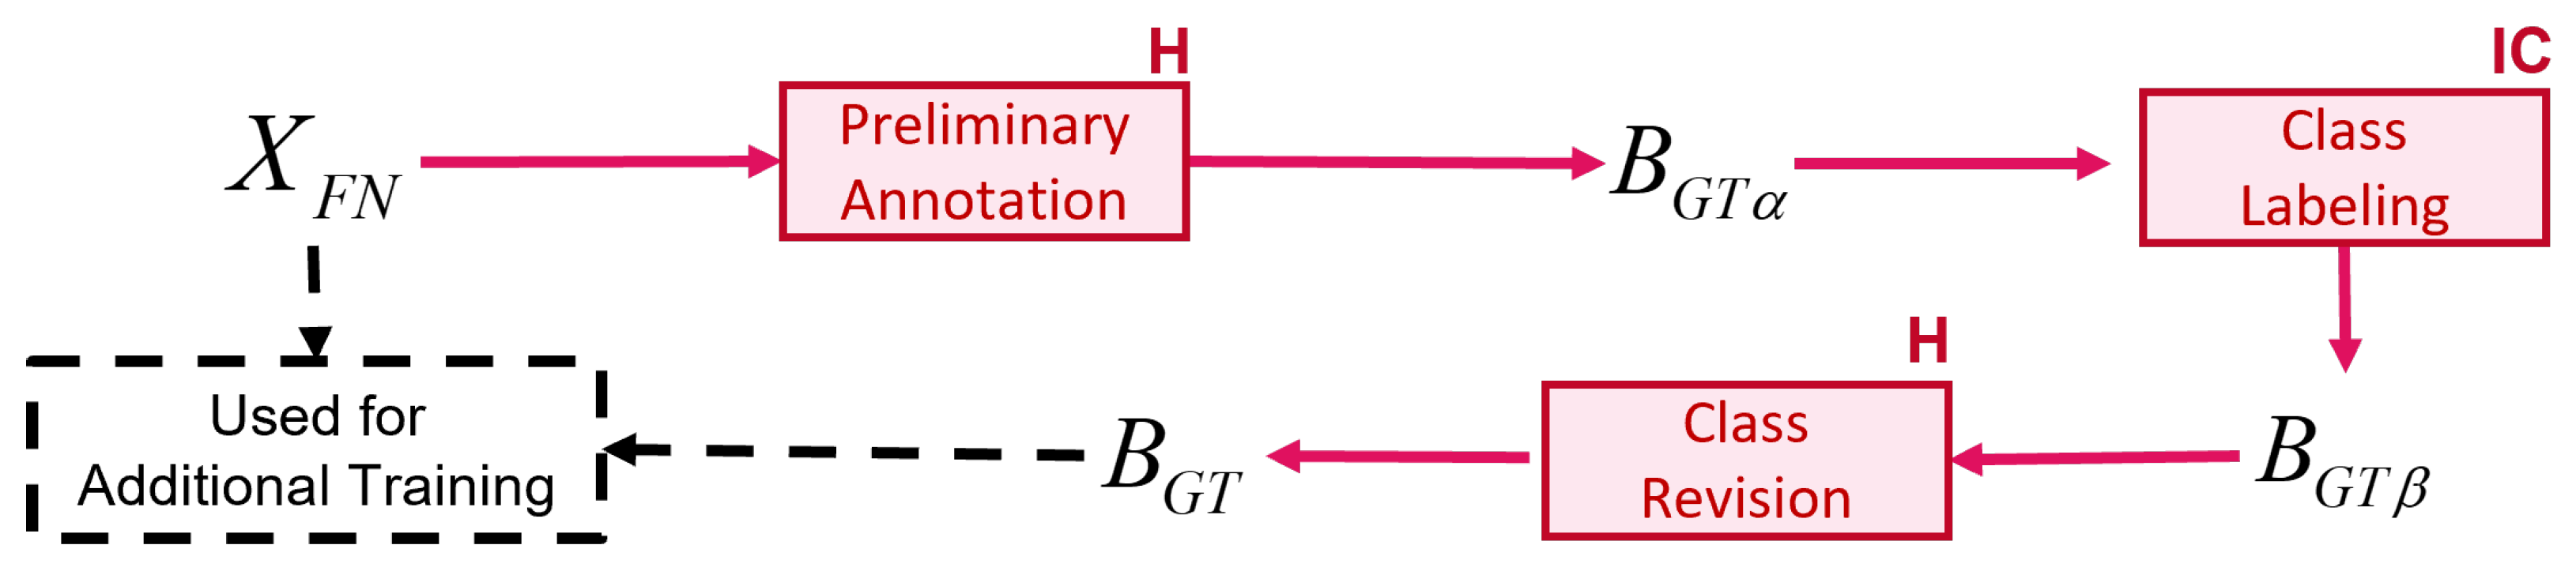
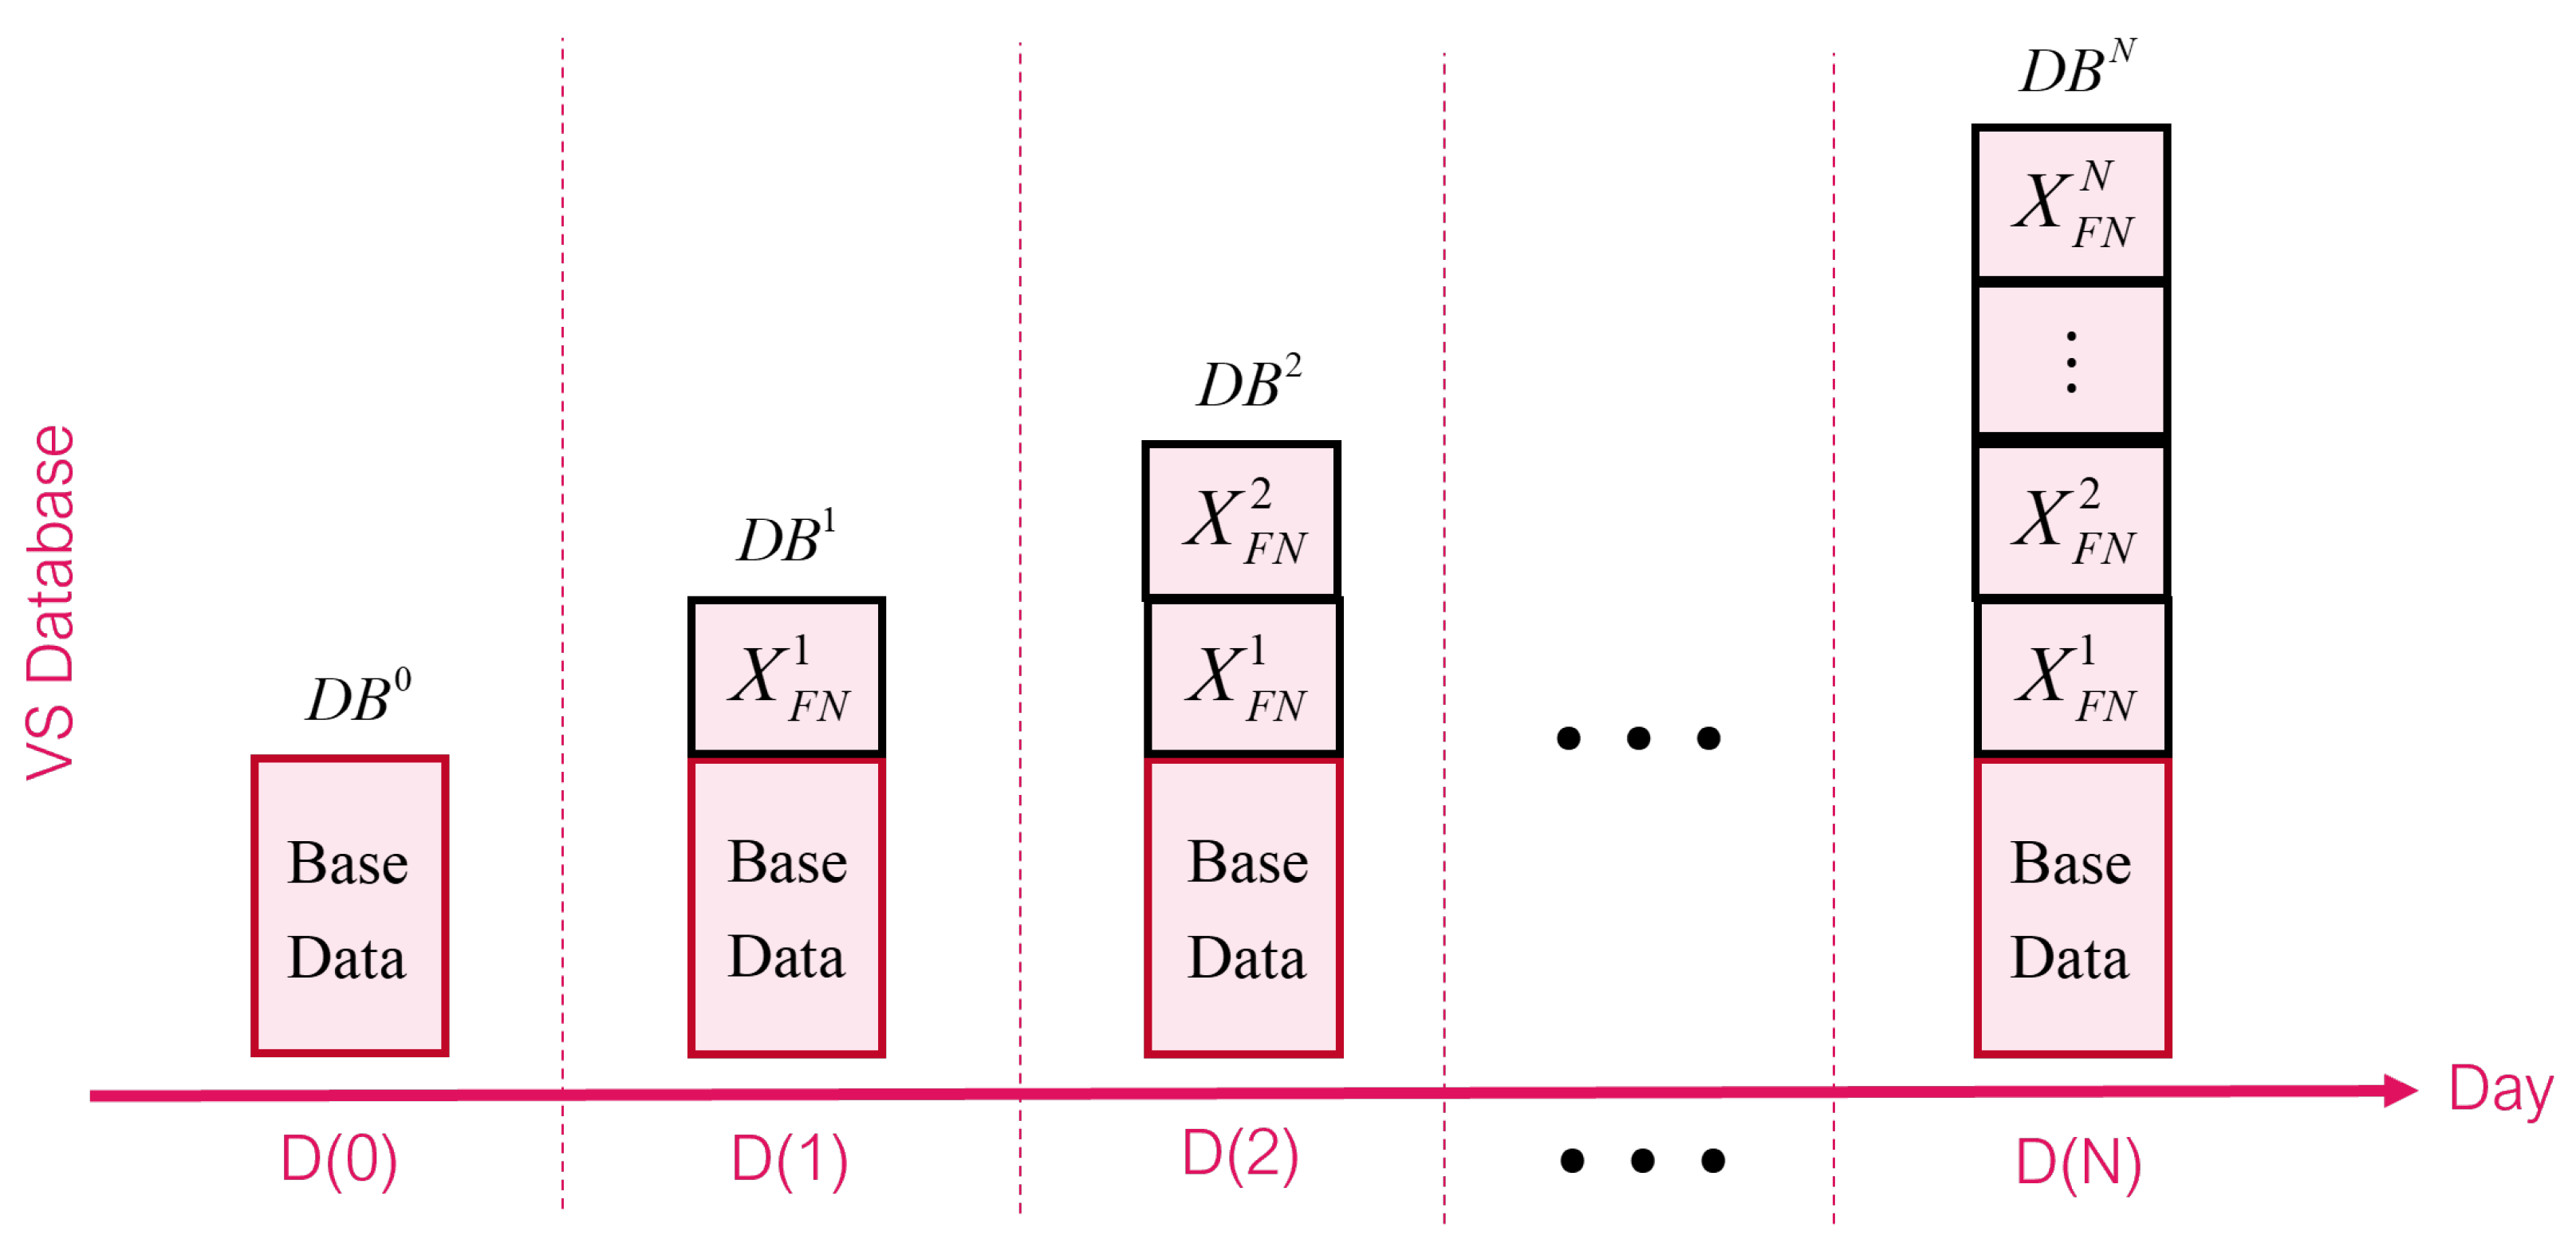
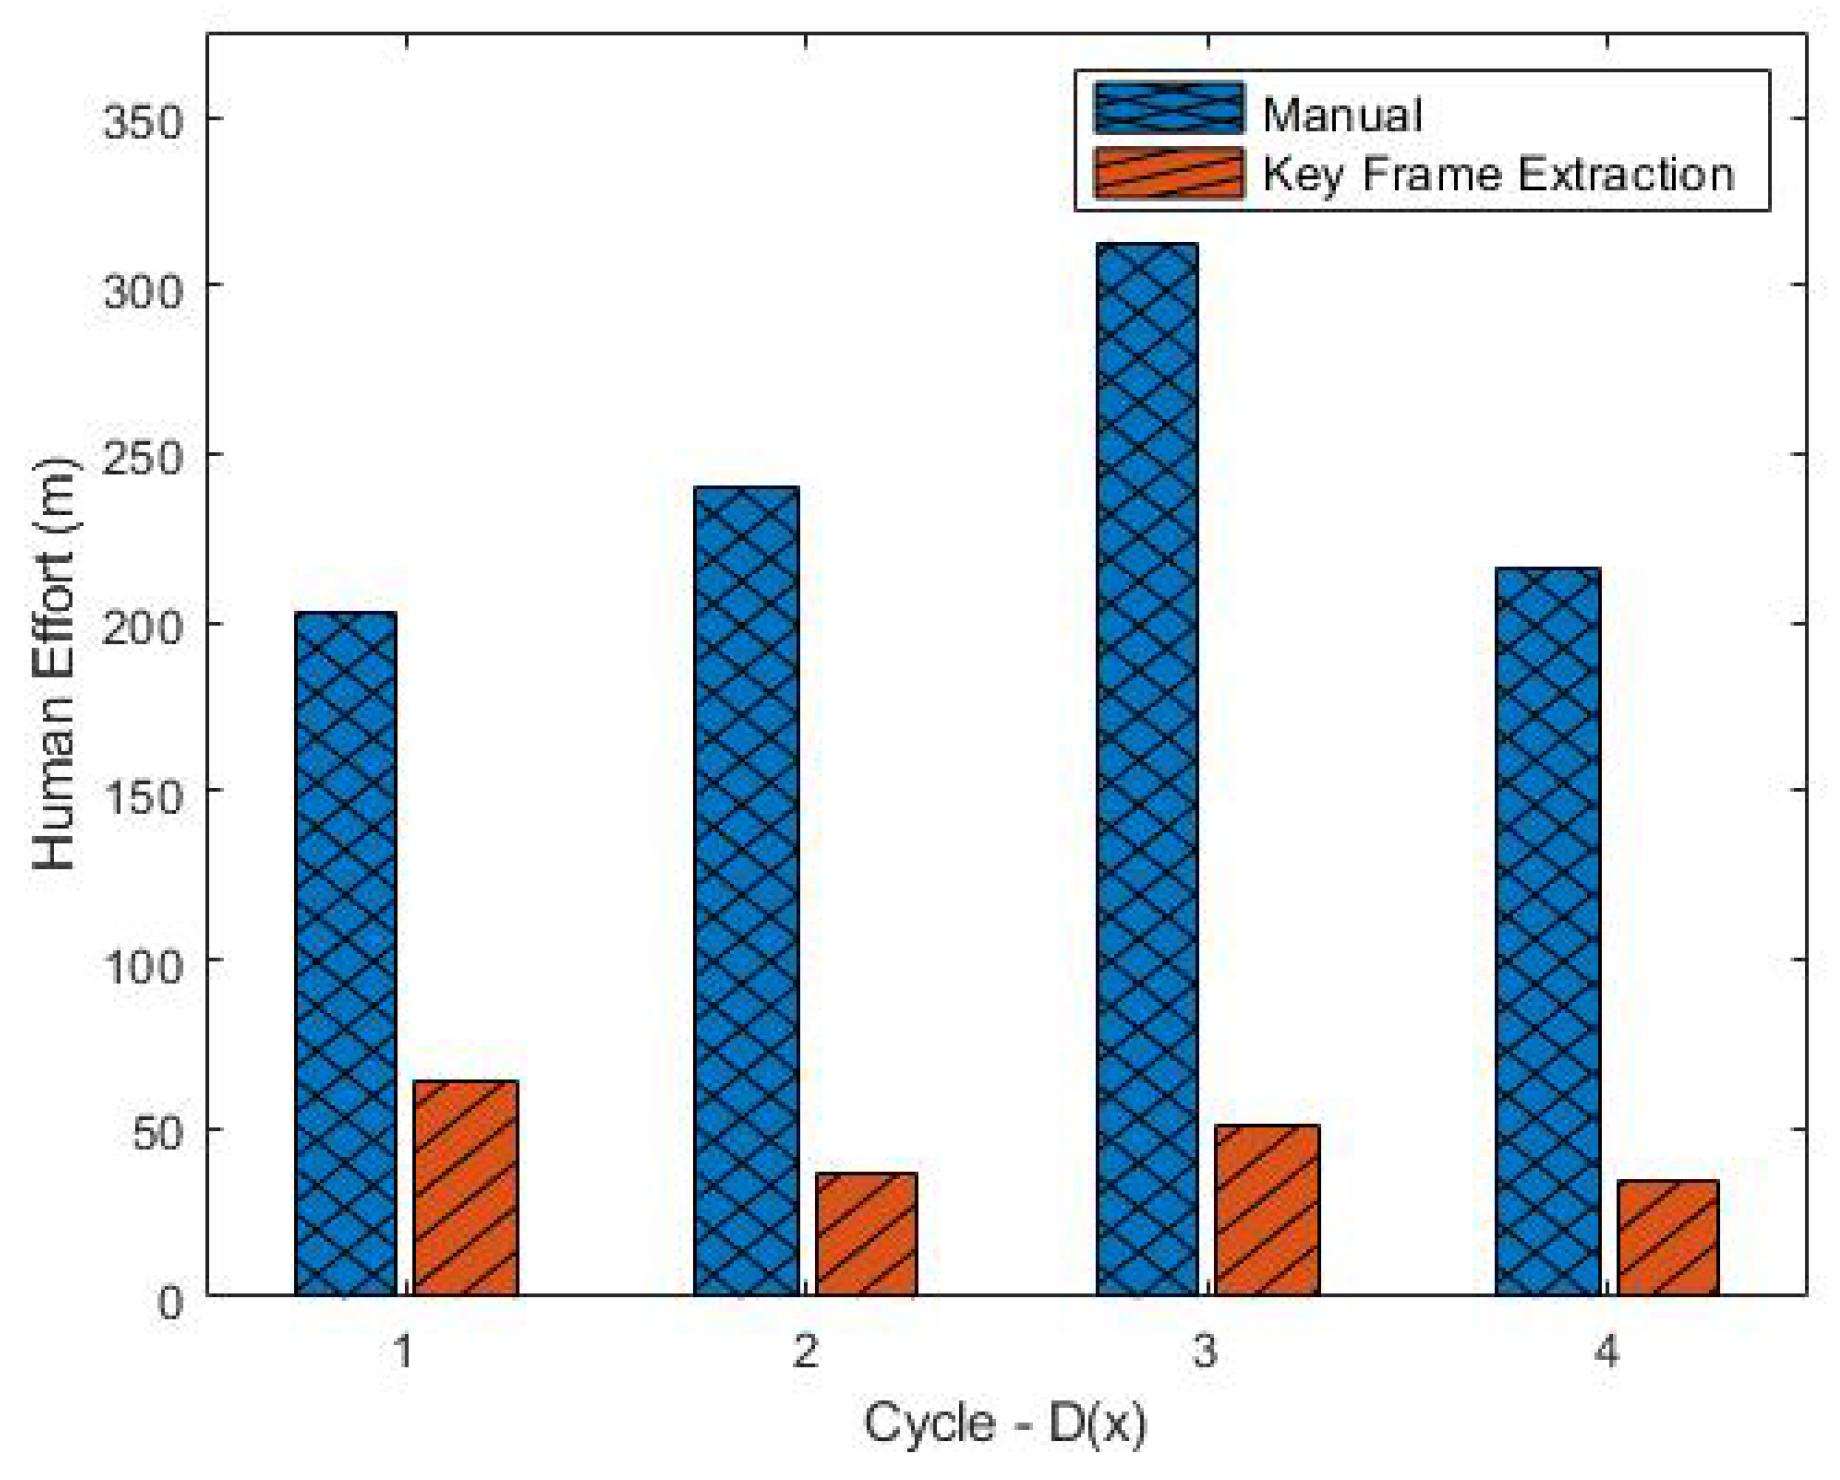
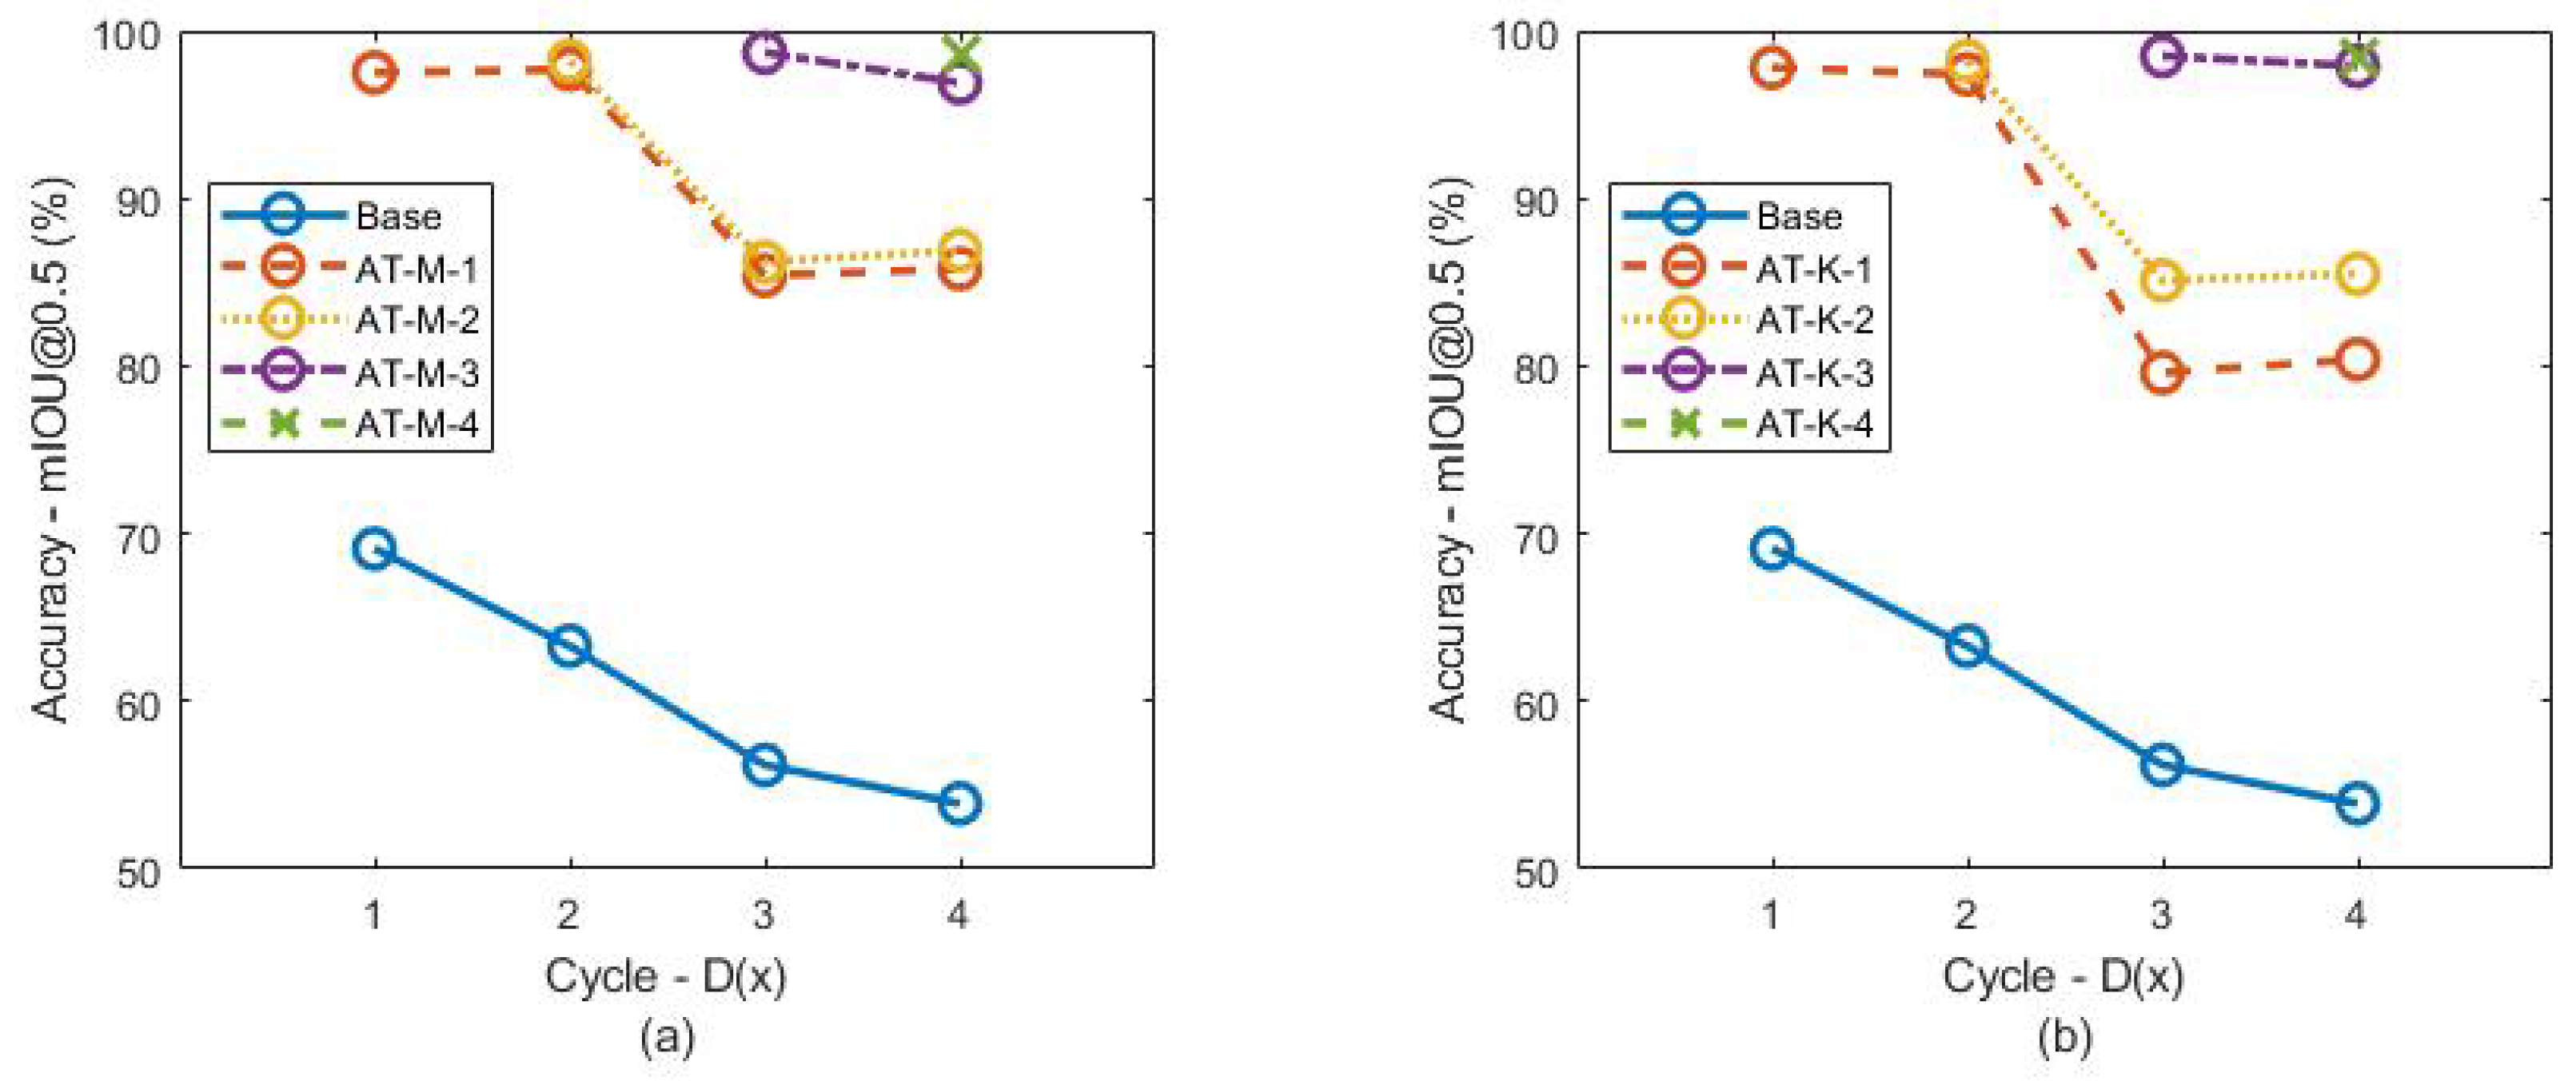
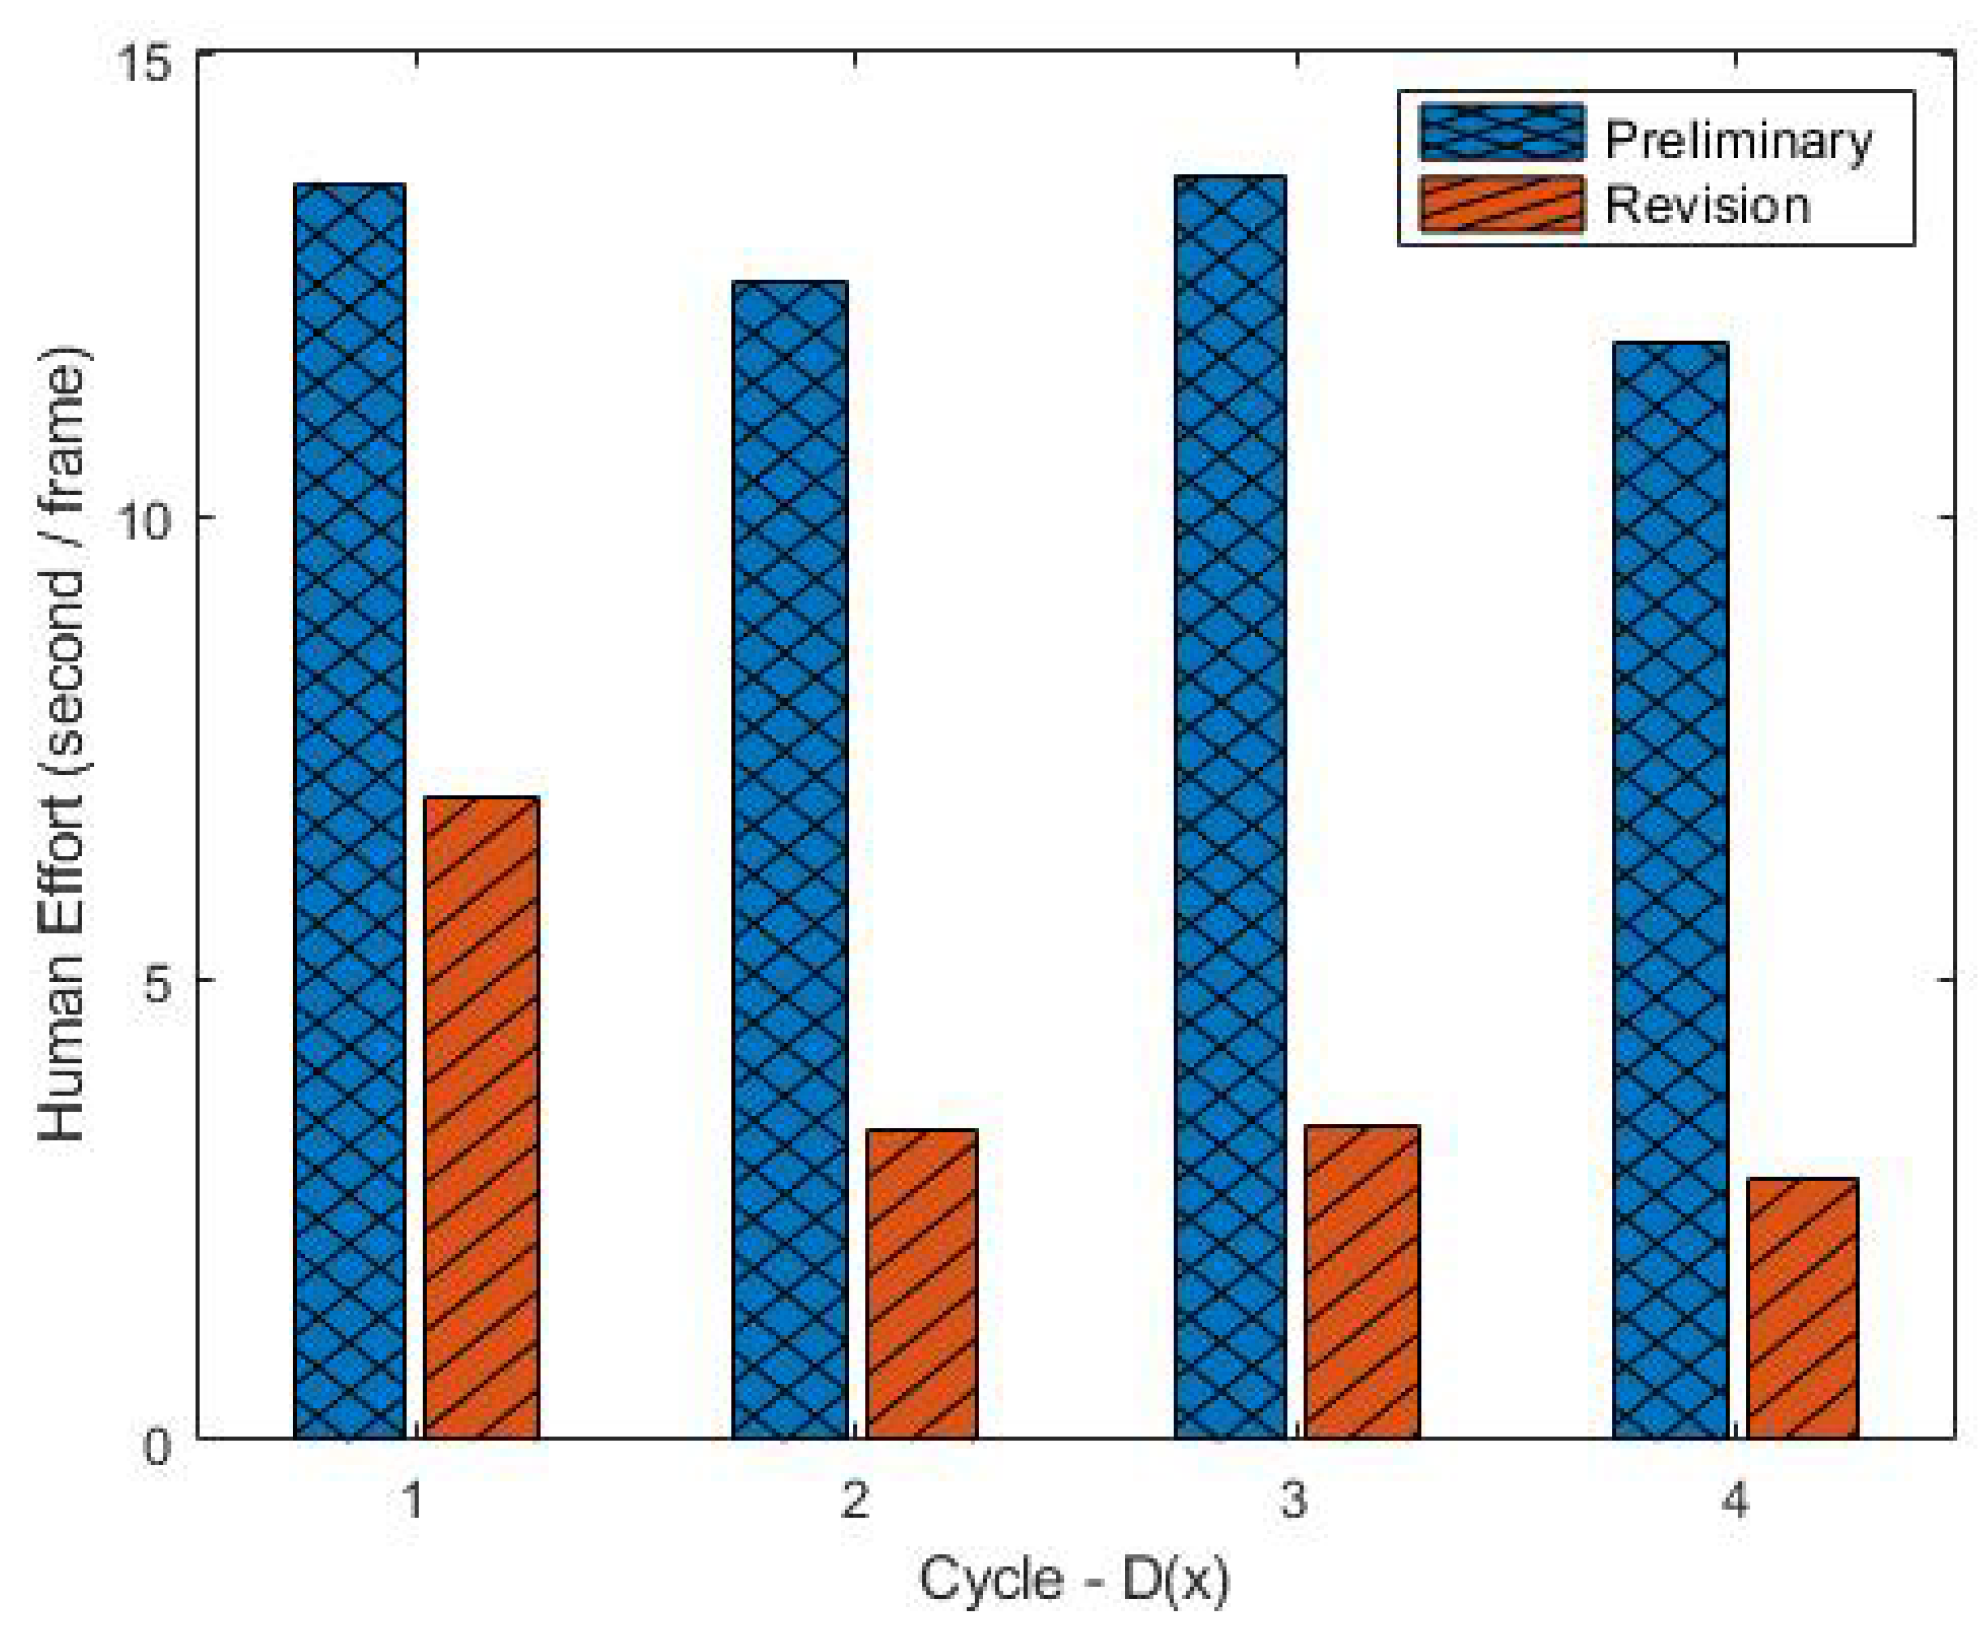
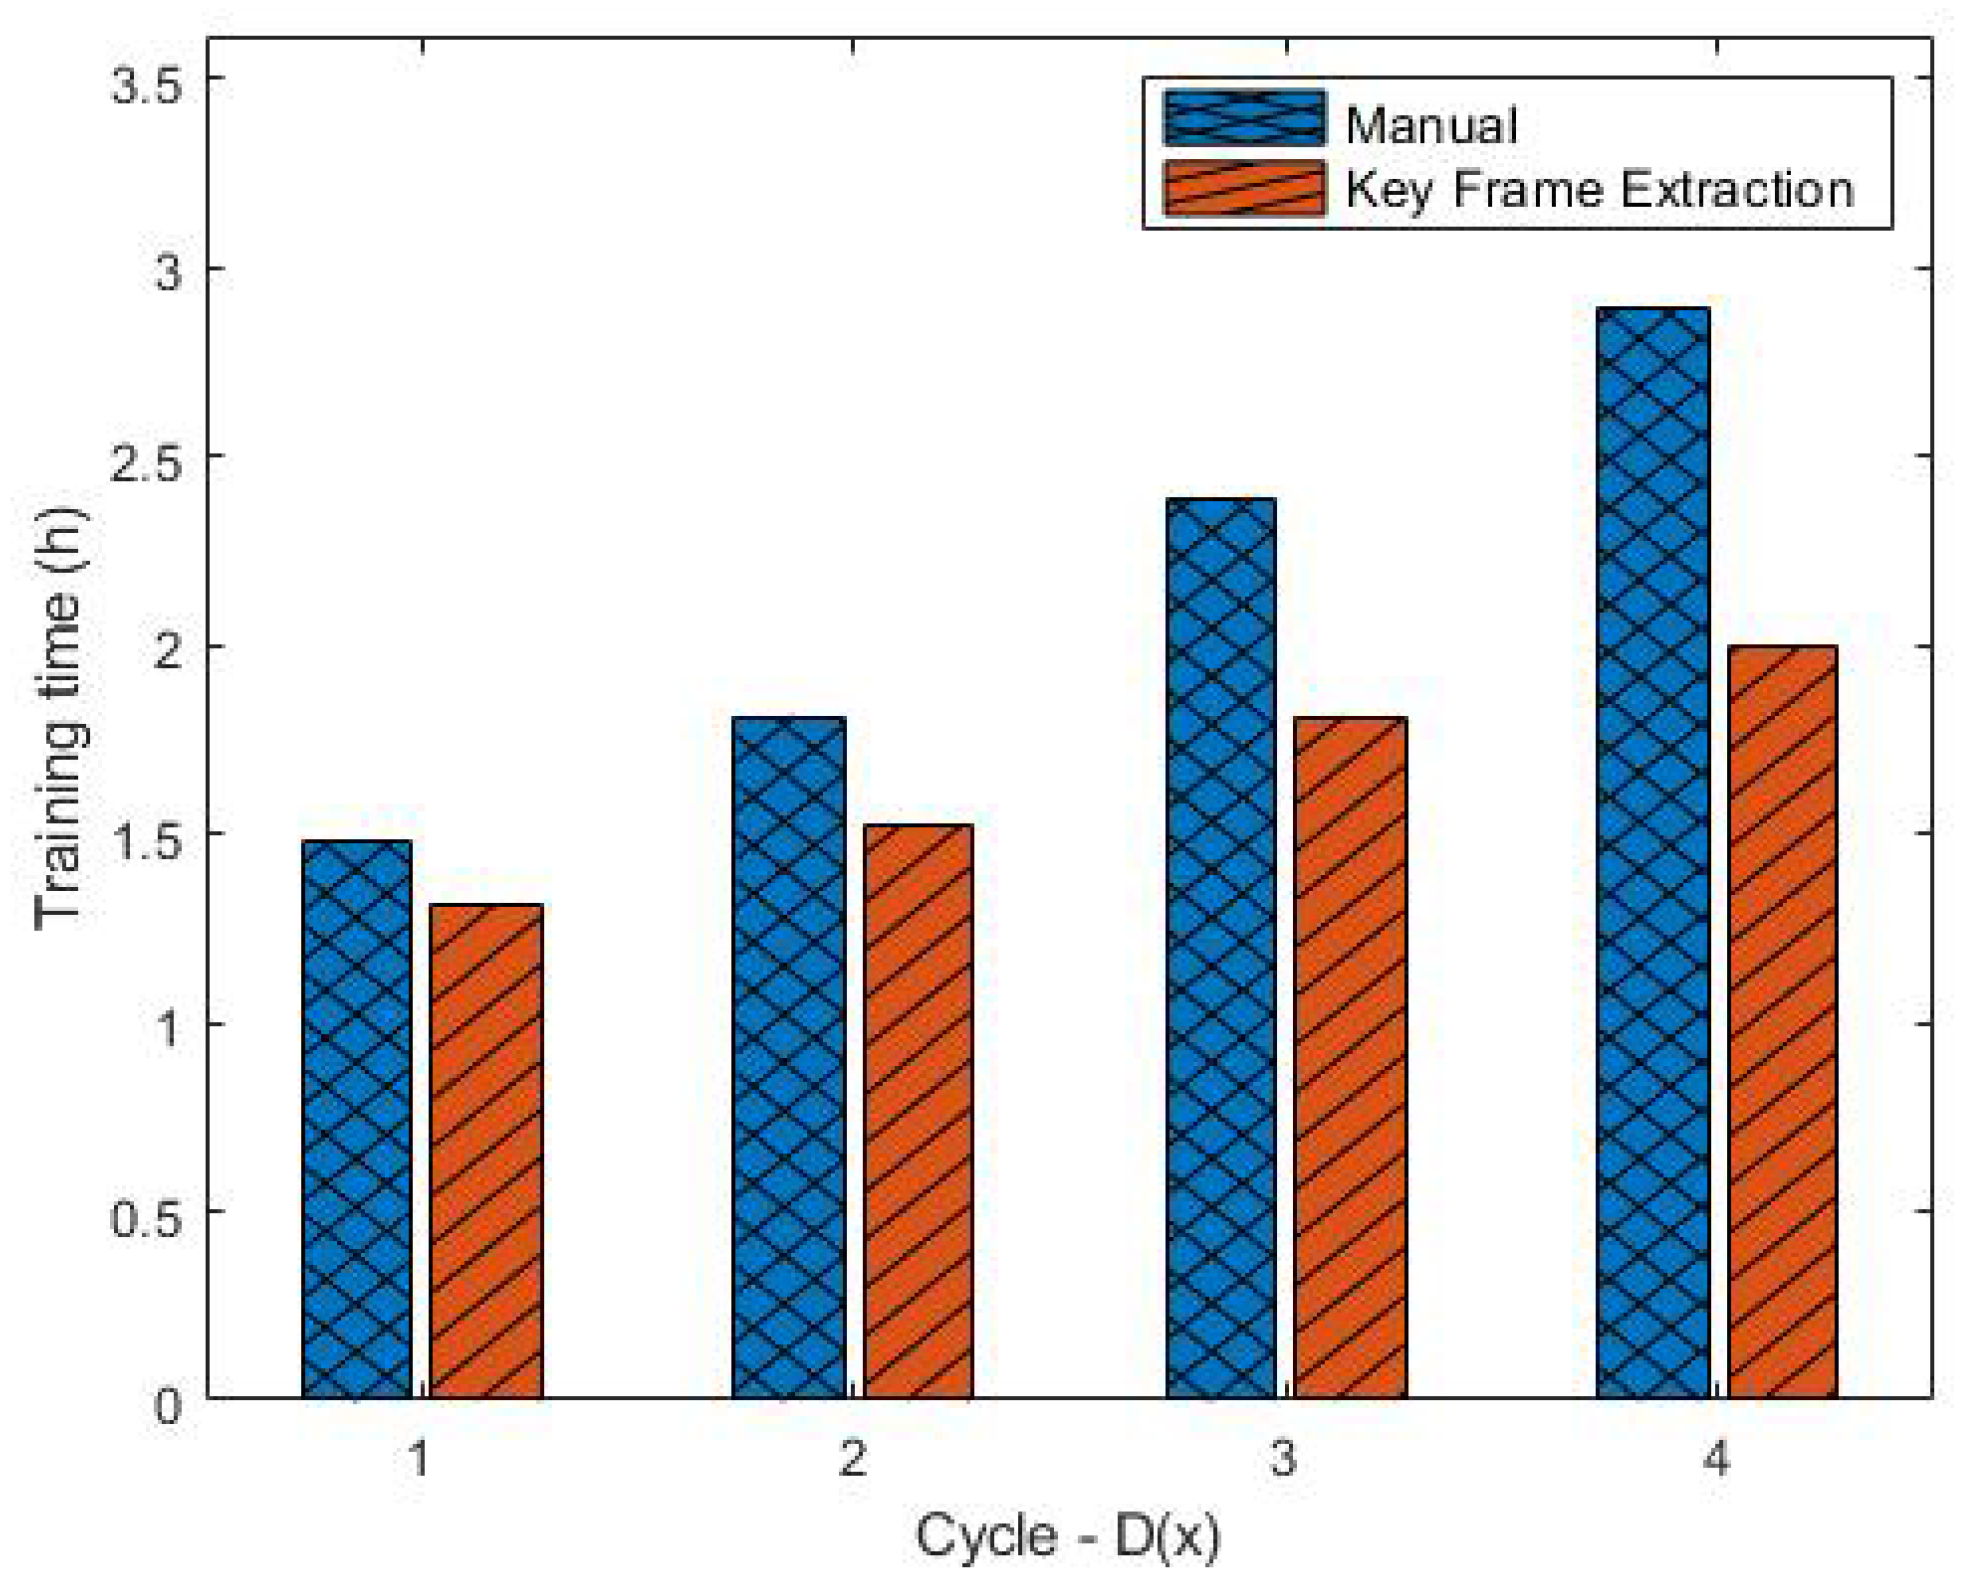
This paper presents a supervised learning scheme that employs key-frame extraction to enhance the performance of pre-trained deep learning models for object detection in surveillance videos. Developing supervised deep learning models requires a significant amount of annotated video frames as training data, which demands substantial human effort for preparation. Key frames, which encompass frames containing false negative or false positive objects, can introduce diversity into the training data and contribute to model improvements. Our proposed approach focuses on detecting false negatives by leveraging the motion information within video frames that contain the detected object region. Key-frame extraction significantly reduces the human effort involved in video frame extraction. We employ interactive labeling to annotate false negative video frames with accurate bounding boxes and labels. These annotated frames are then integrated with the existing training data to create a comprehensive training dataset for subsequent training cycles. Repeating the training cycles gradually improves the object detection performance of deep learning models to monitor a new environment. Experiment results demonstrate that the proposed learning approach improves the performance of the object detection model in a new operating environment, increasing the mean average precision (mAP@0.5) from 54% to 98%. Manual annotation of key frames is reduced by 81% through the proposed key-frame extraction method.
Keywords: object detection; video surveillance; key-frame extraction; interactive labeling; deep learning object detection; video surveillance; key-frame extraction; interactive labeling; deep learning