The Use of an Improved Lightweight Scalable Attention-Guided Super-Resolution Method for Remote Sensing Image Enhancement



Abstract
1. Introduction
- (1)
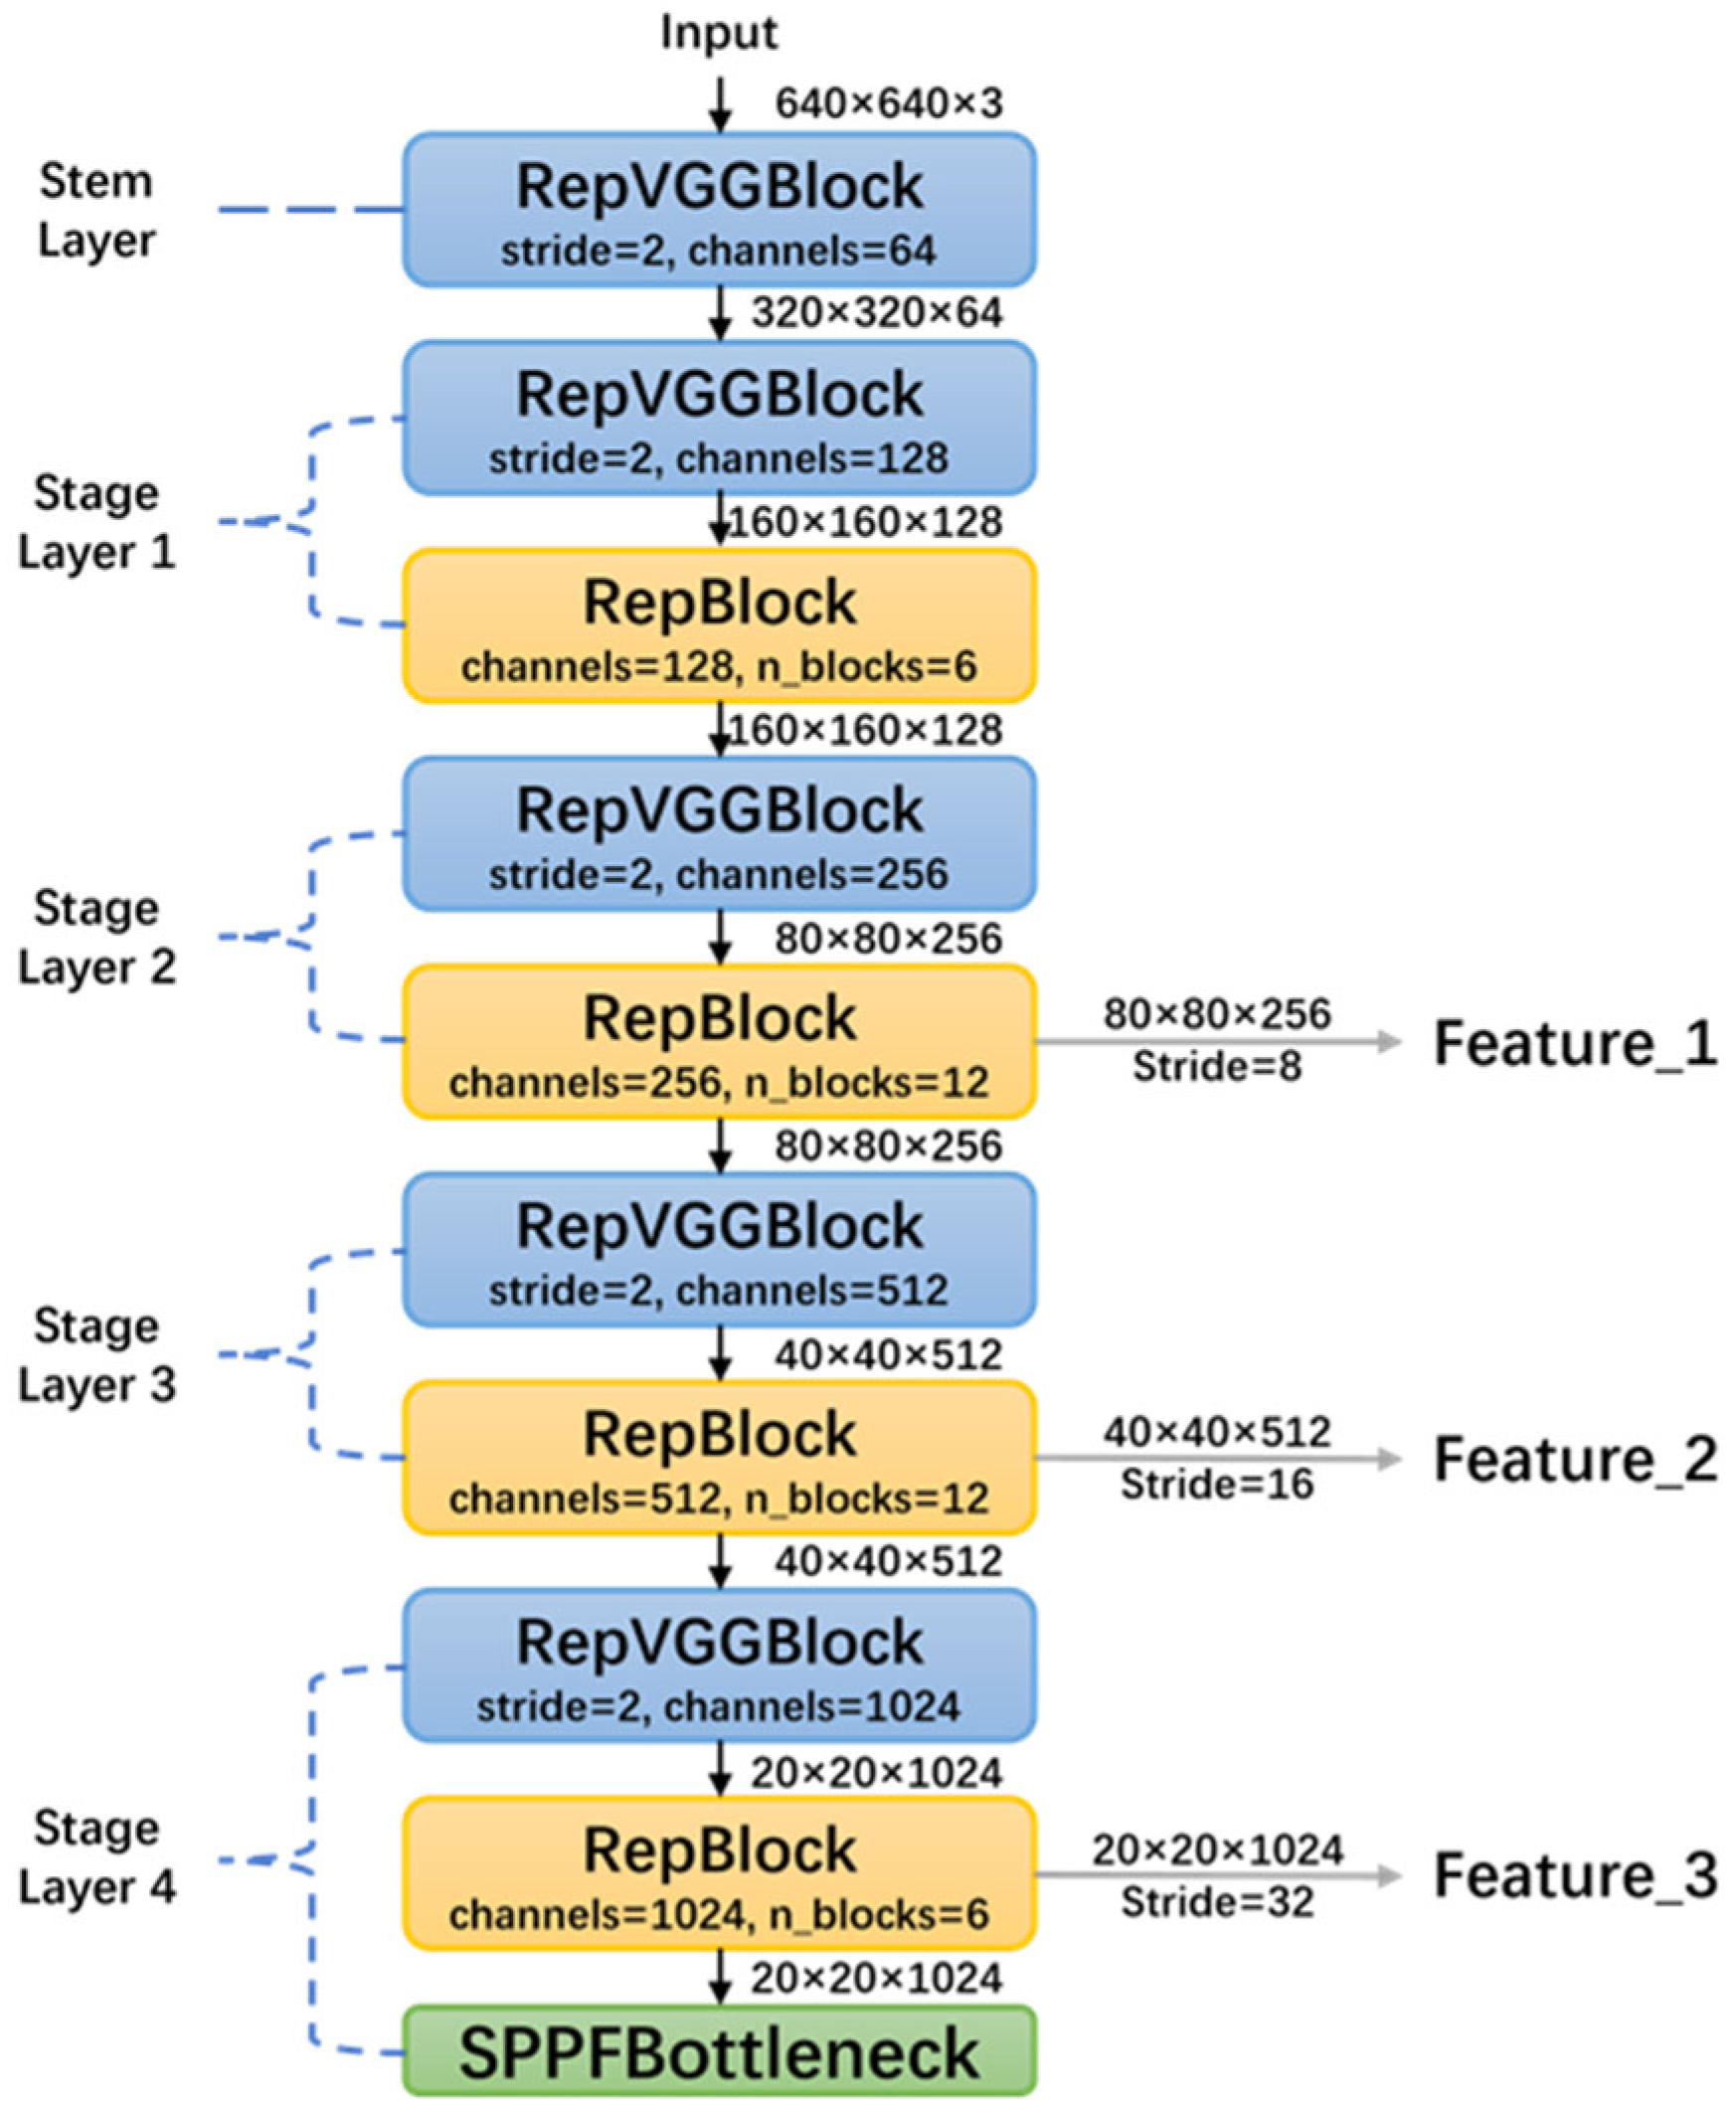
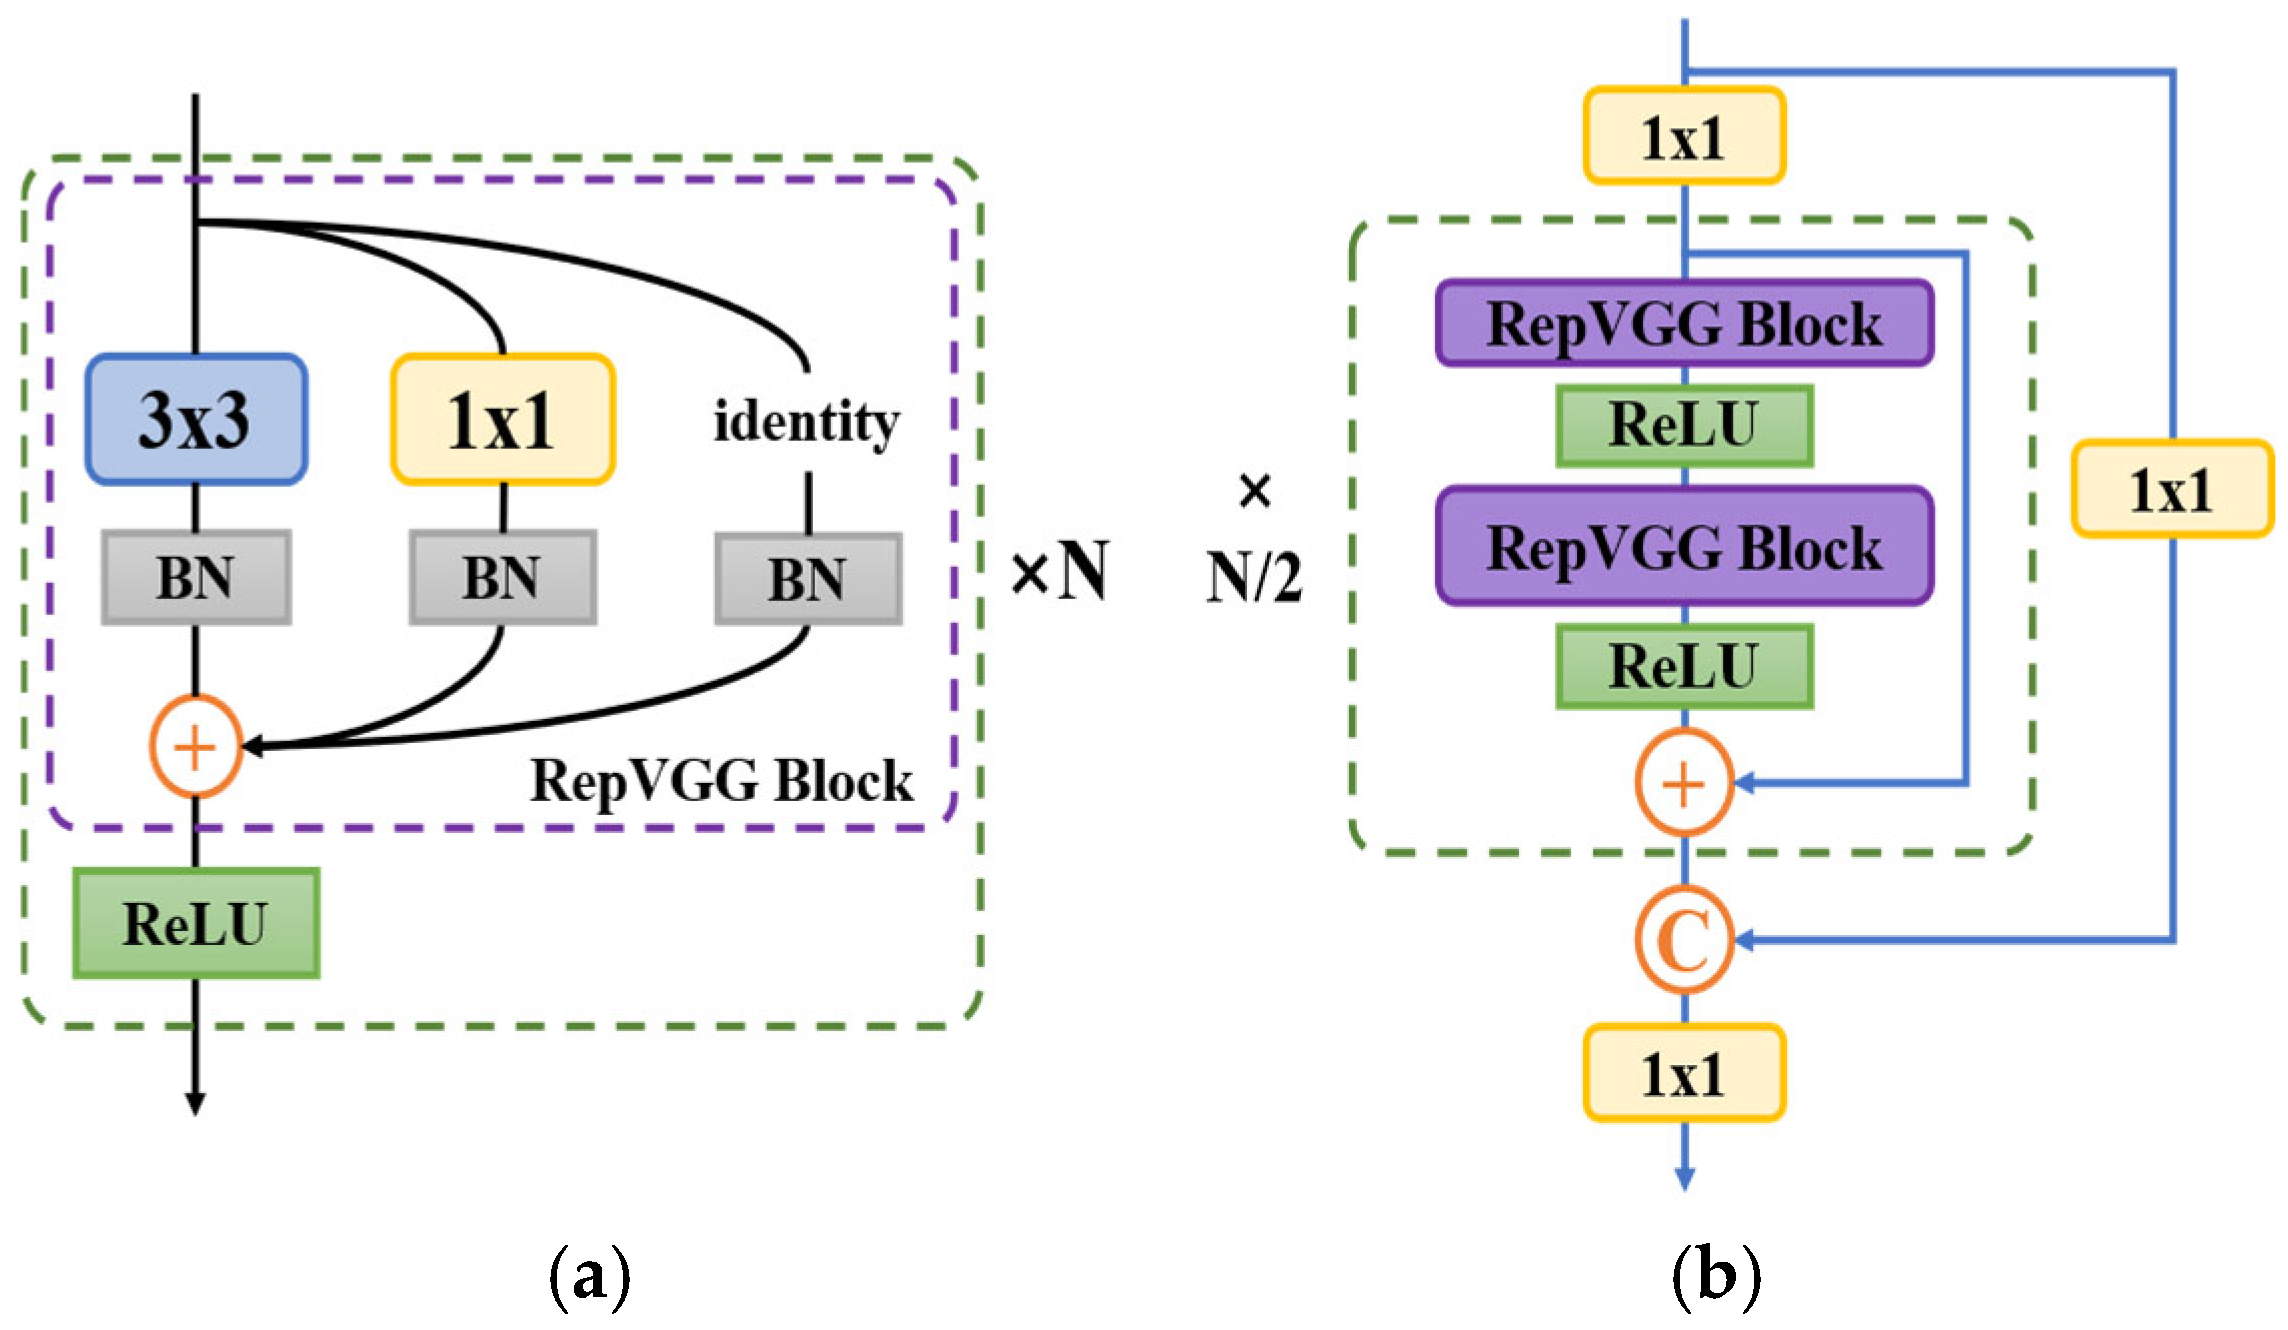
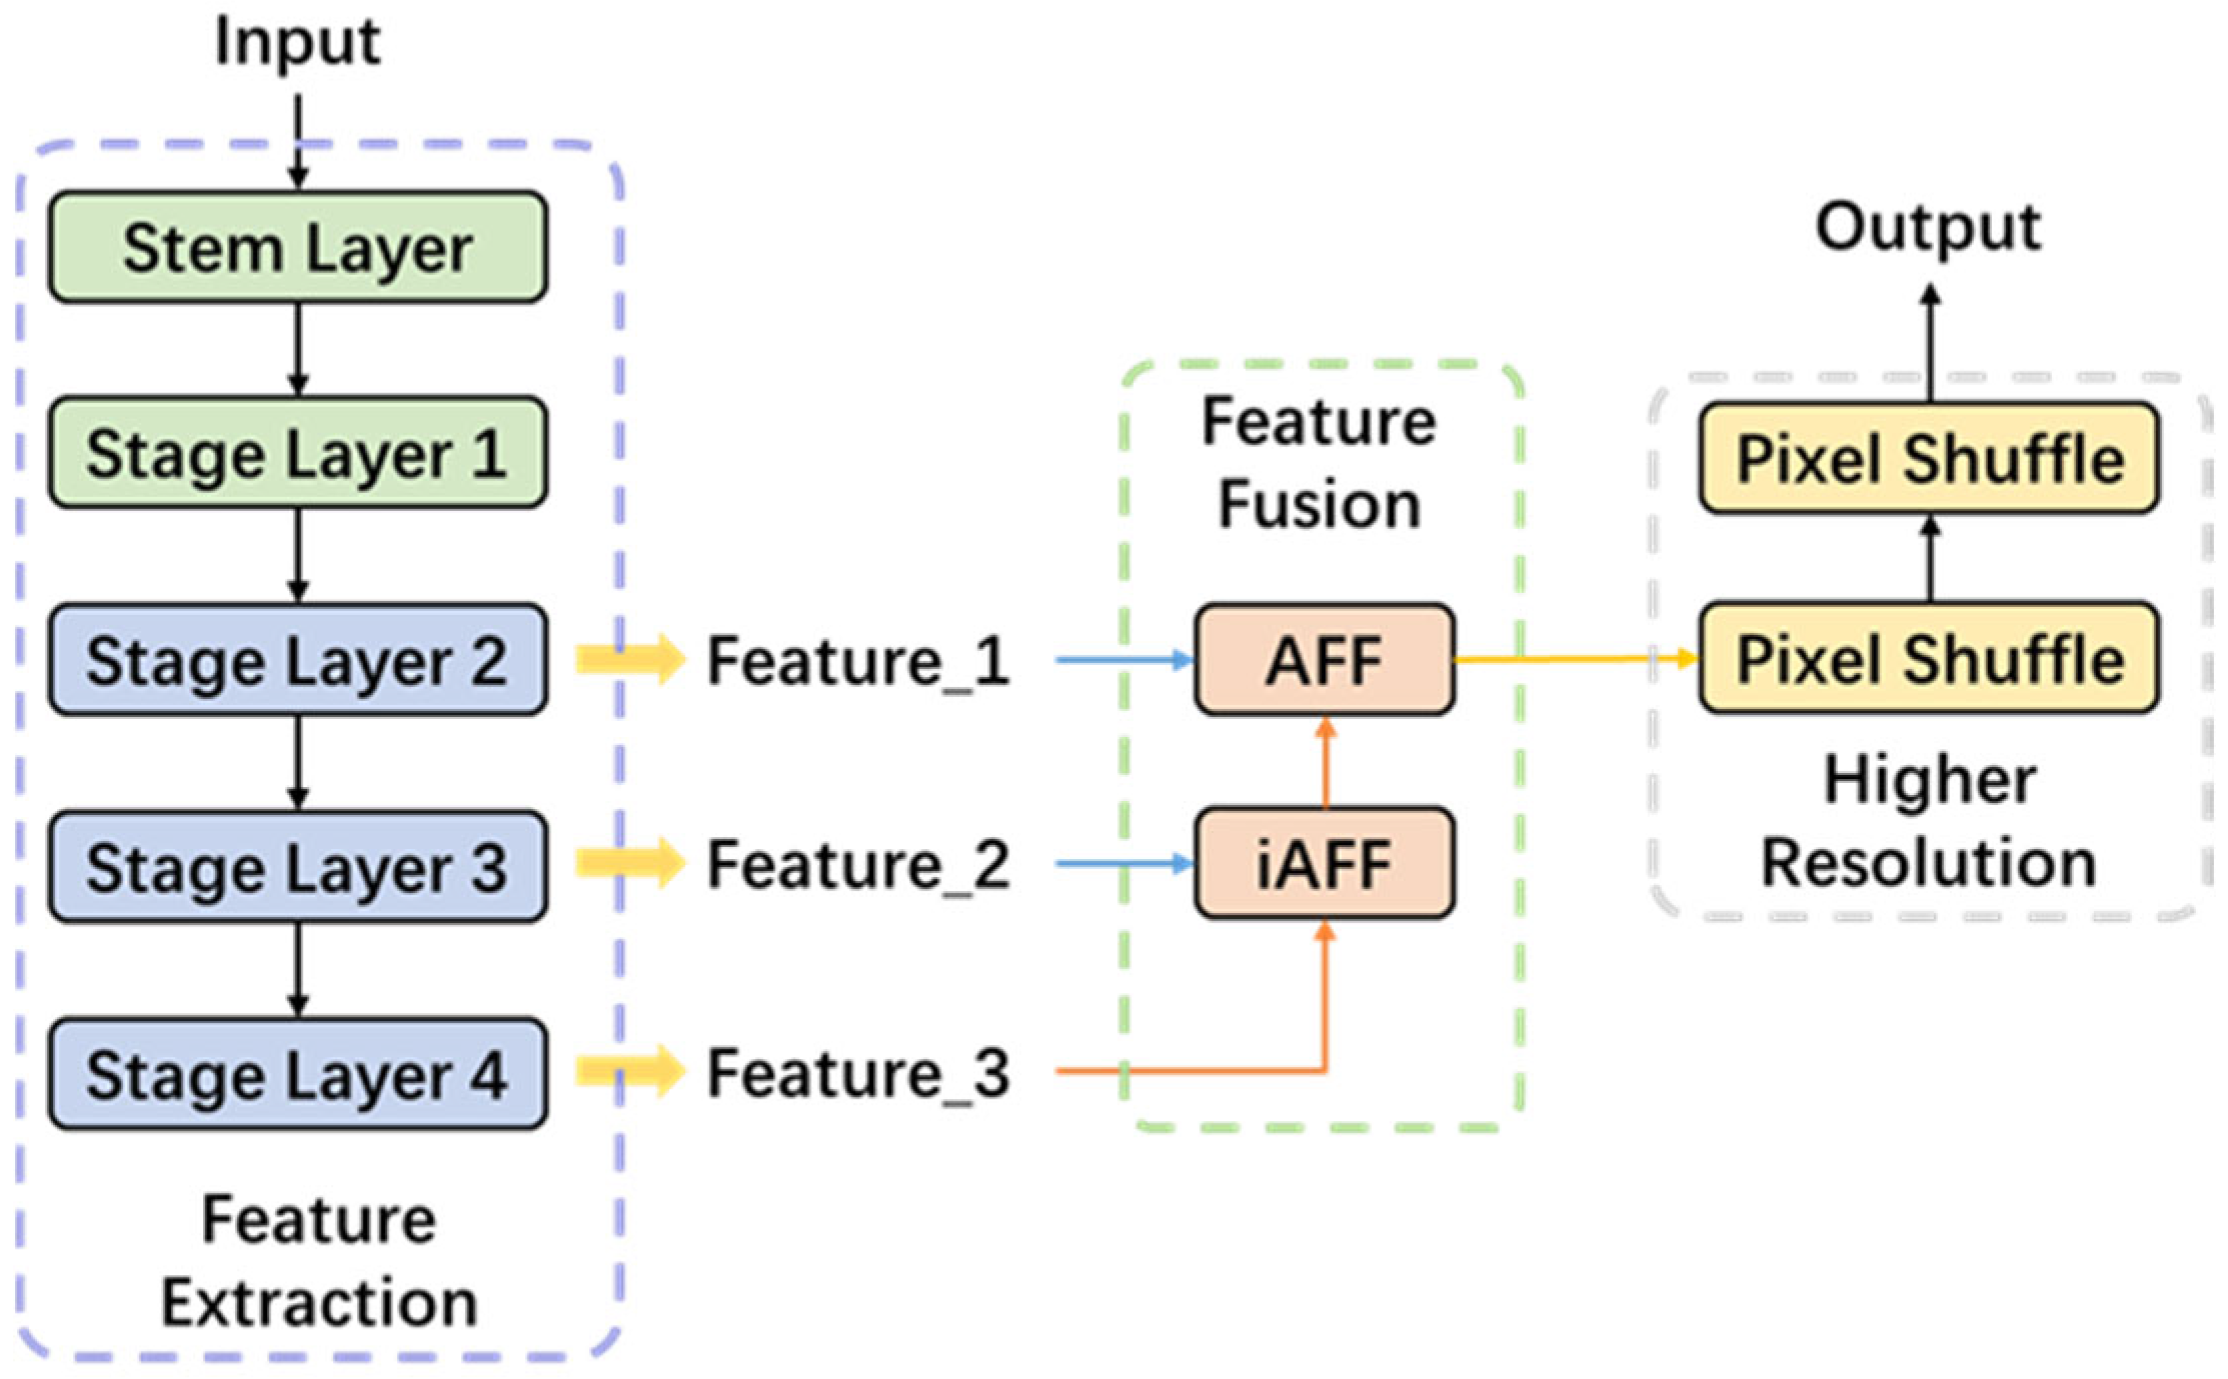
- An optimised lightweight hierarchical backbone is constructed to strengthen multi-scale feature extraction, supporting efficient information encoding for real-time reconstruction.
- (2)
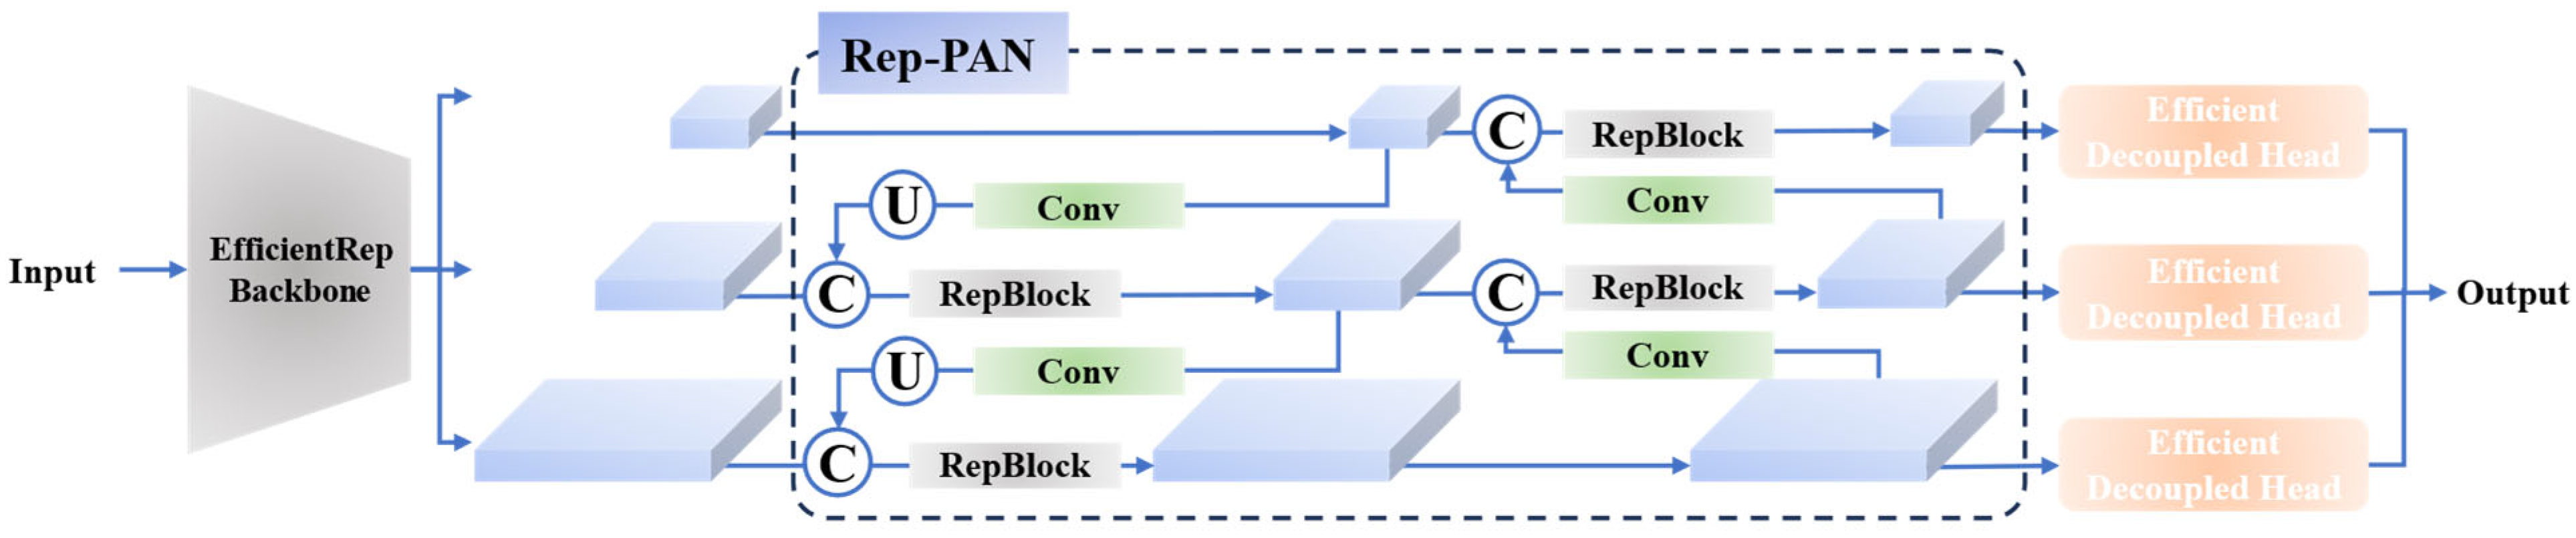
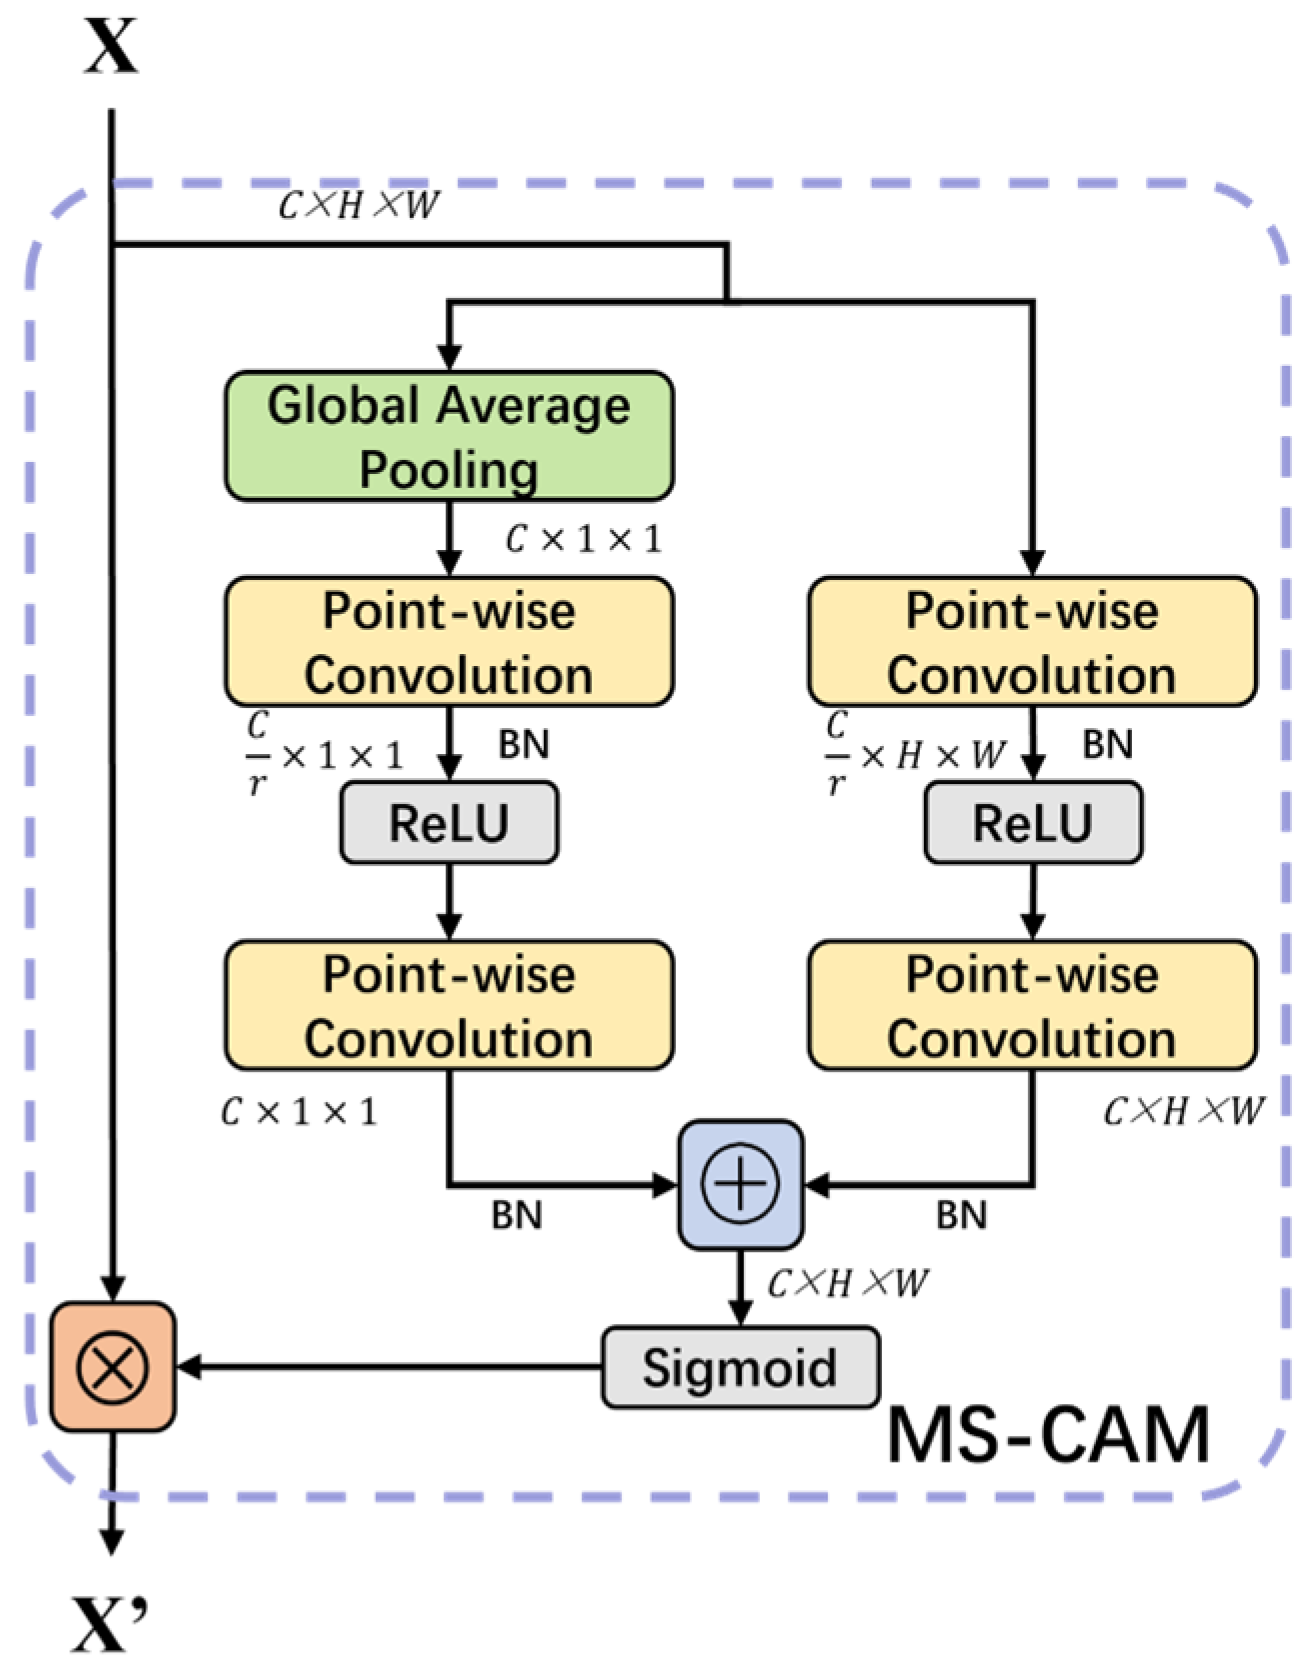
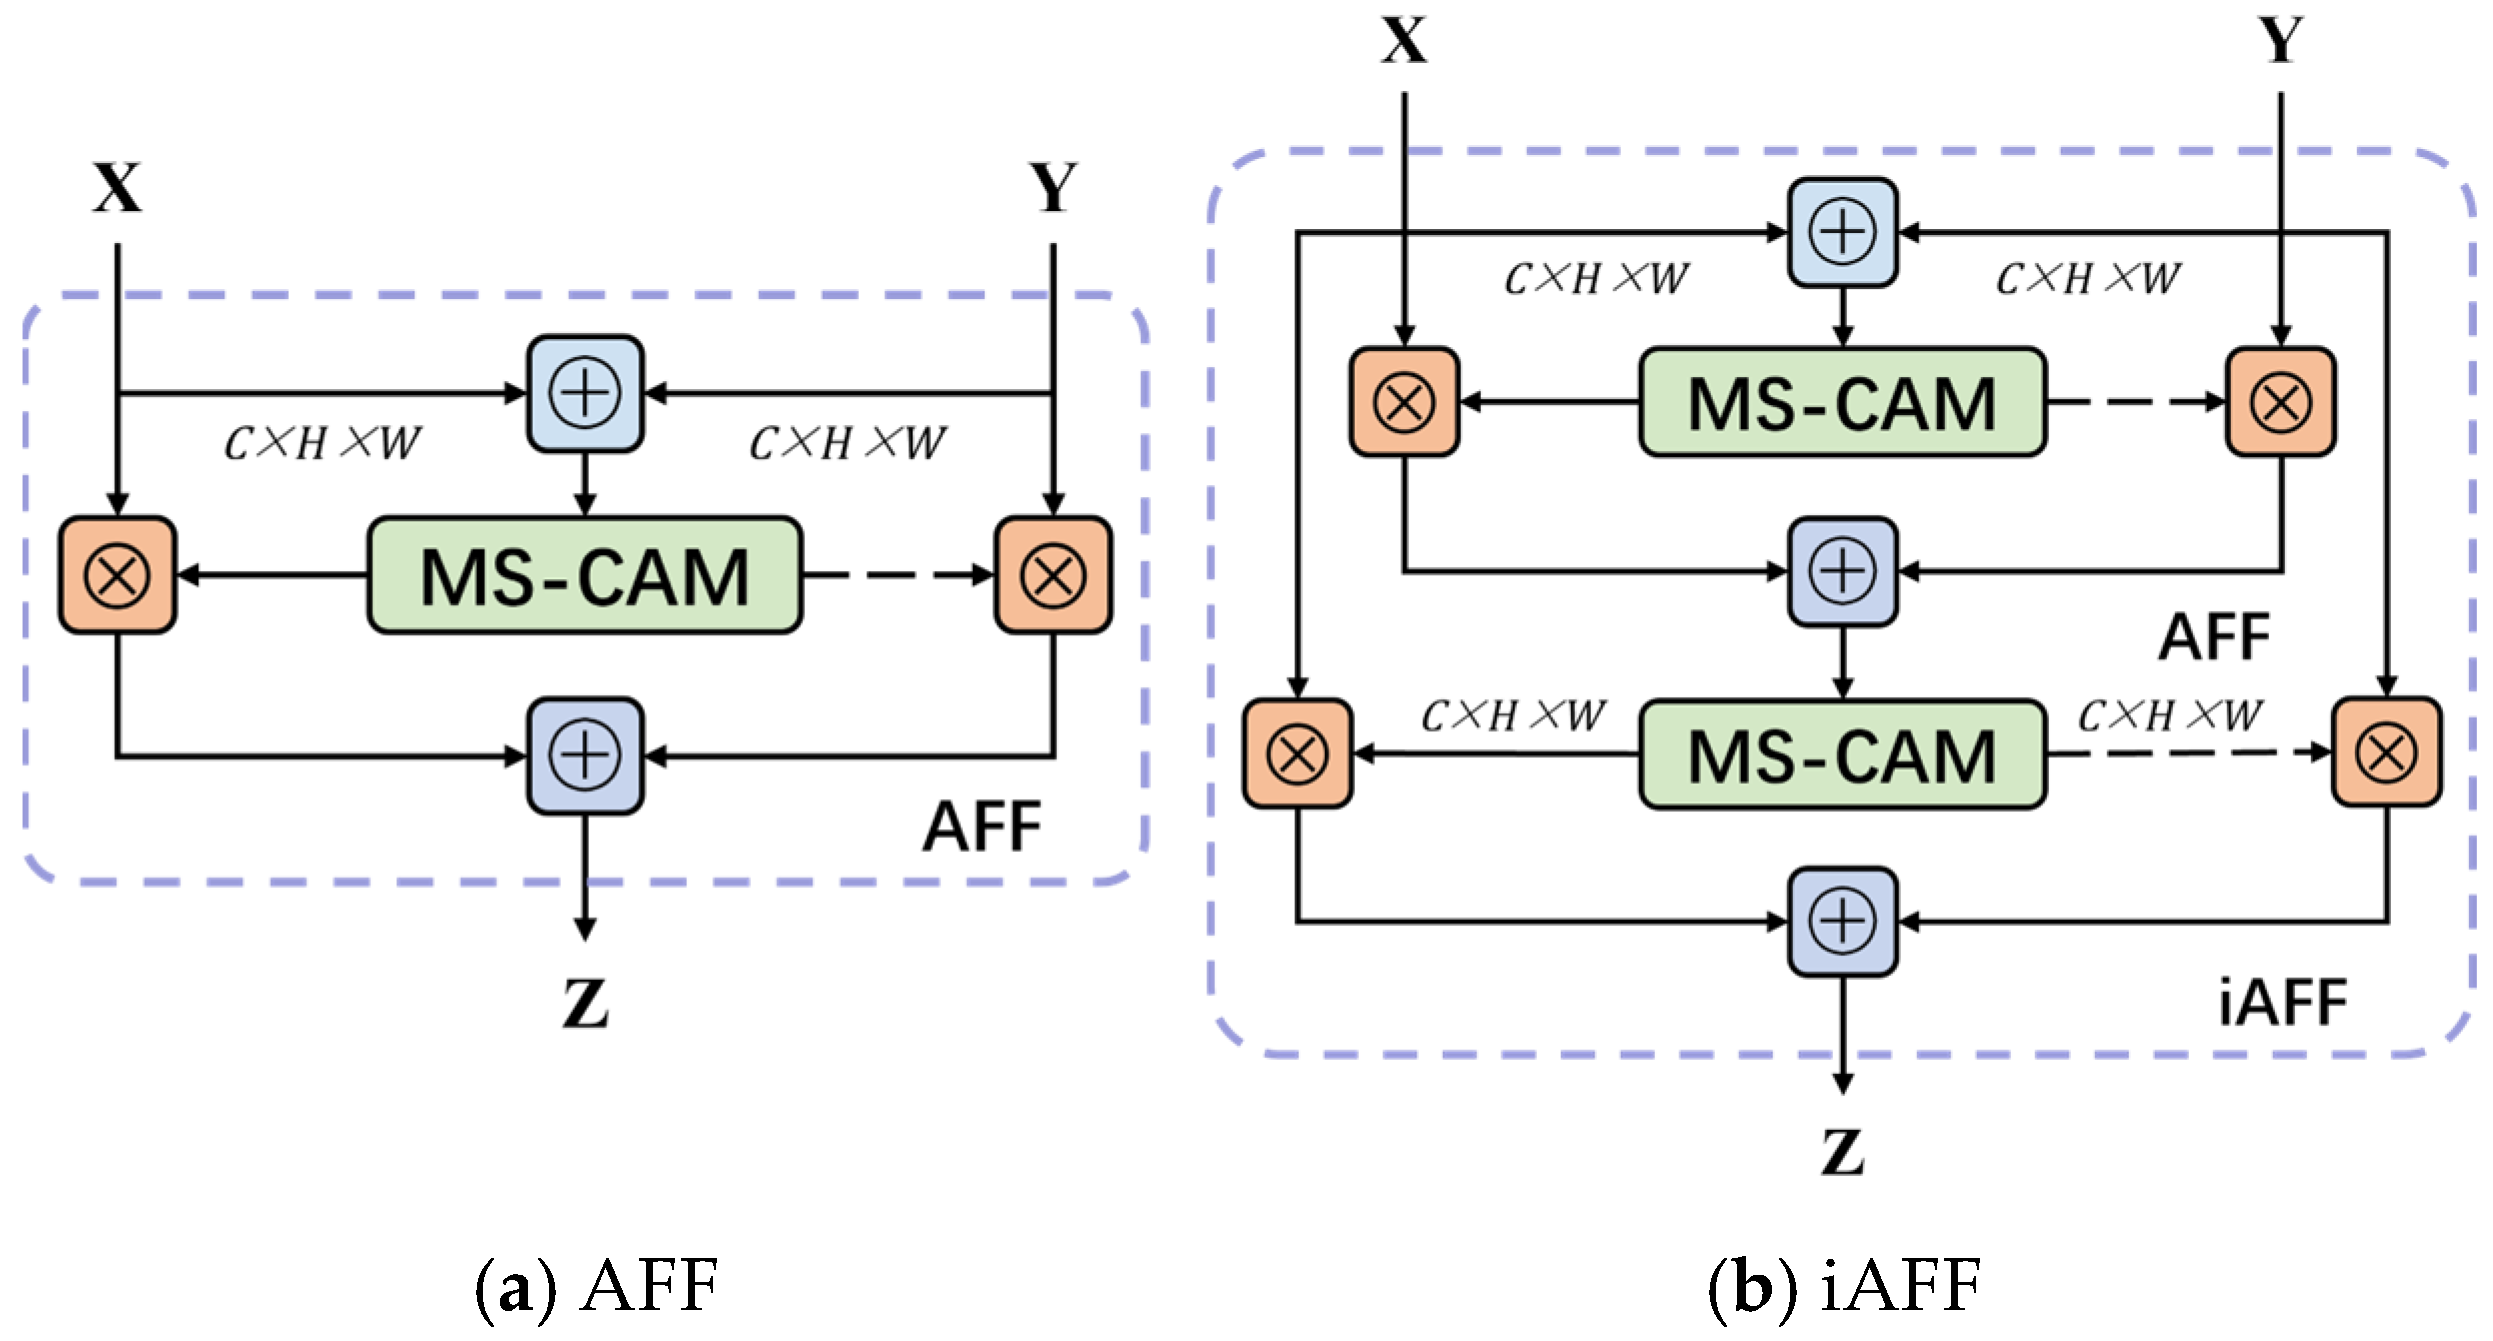
- A refined multi-scale channel attention module is embedded to enhance prior feature modelling, enabling the network to adaptively focus on key regions requiring detail compensation.
- (3)
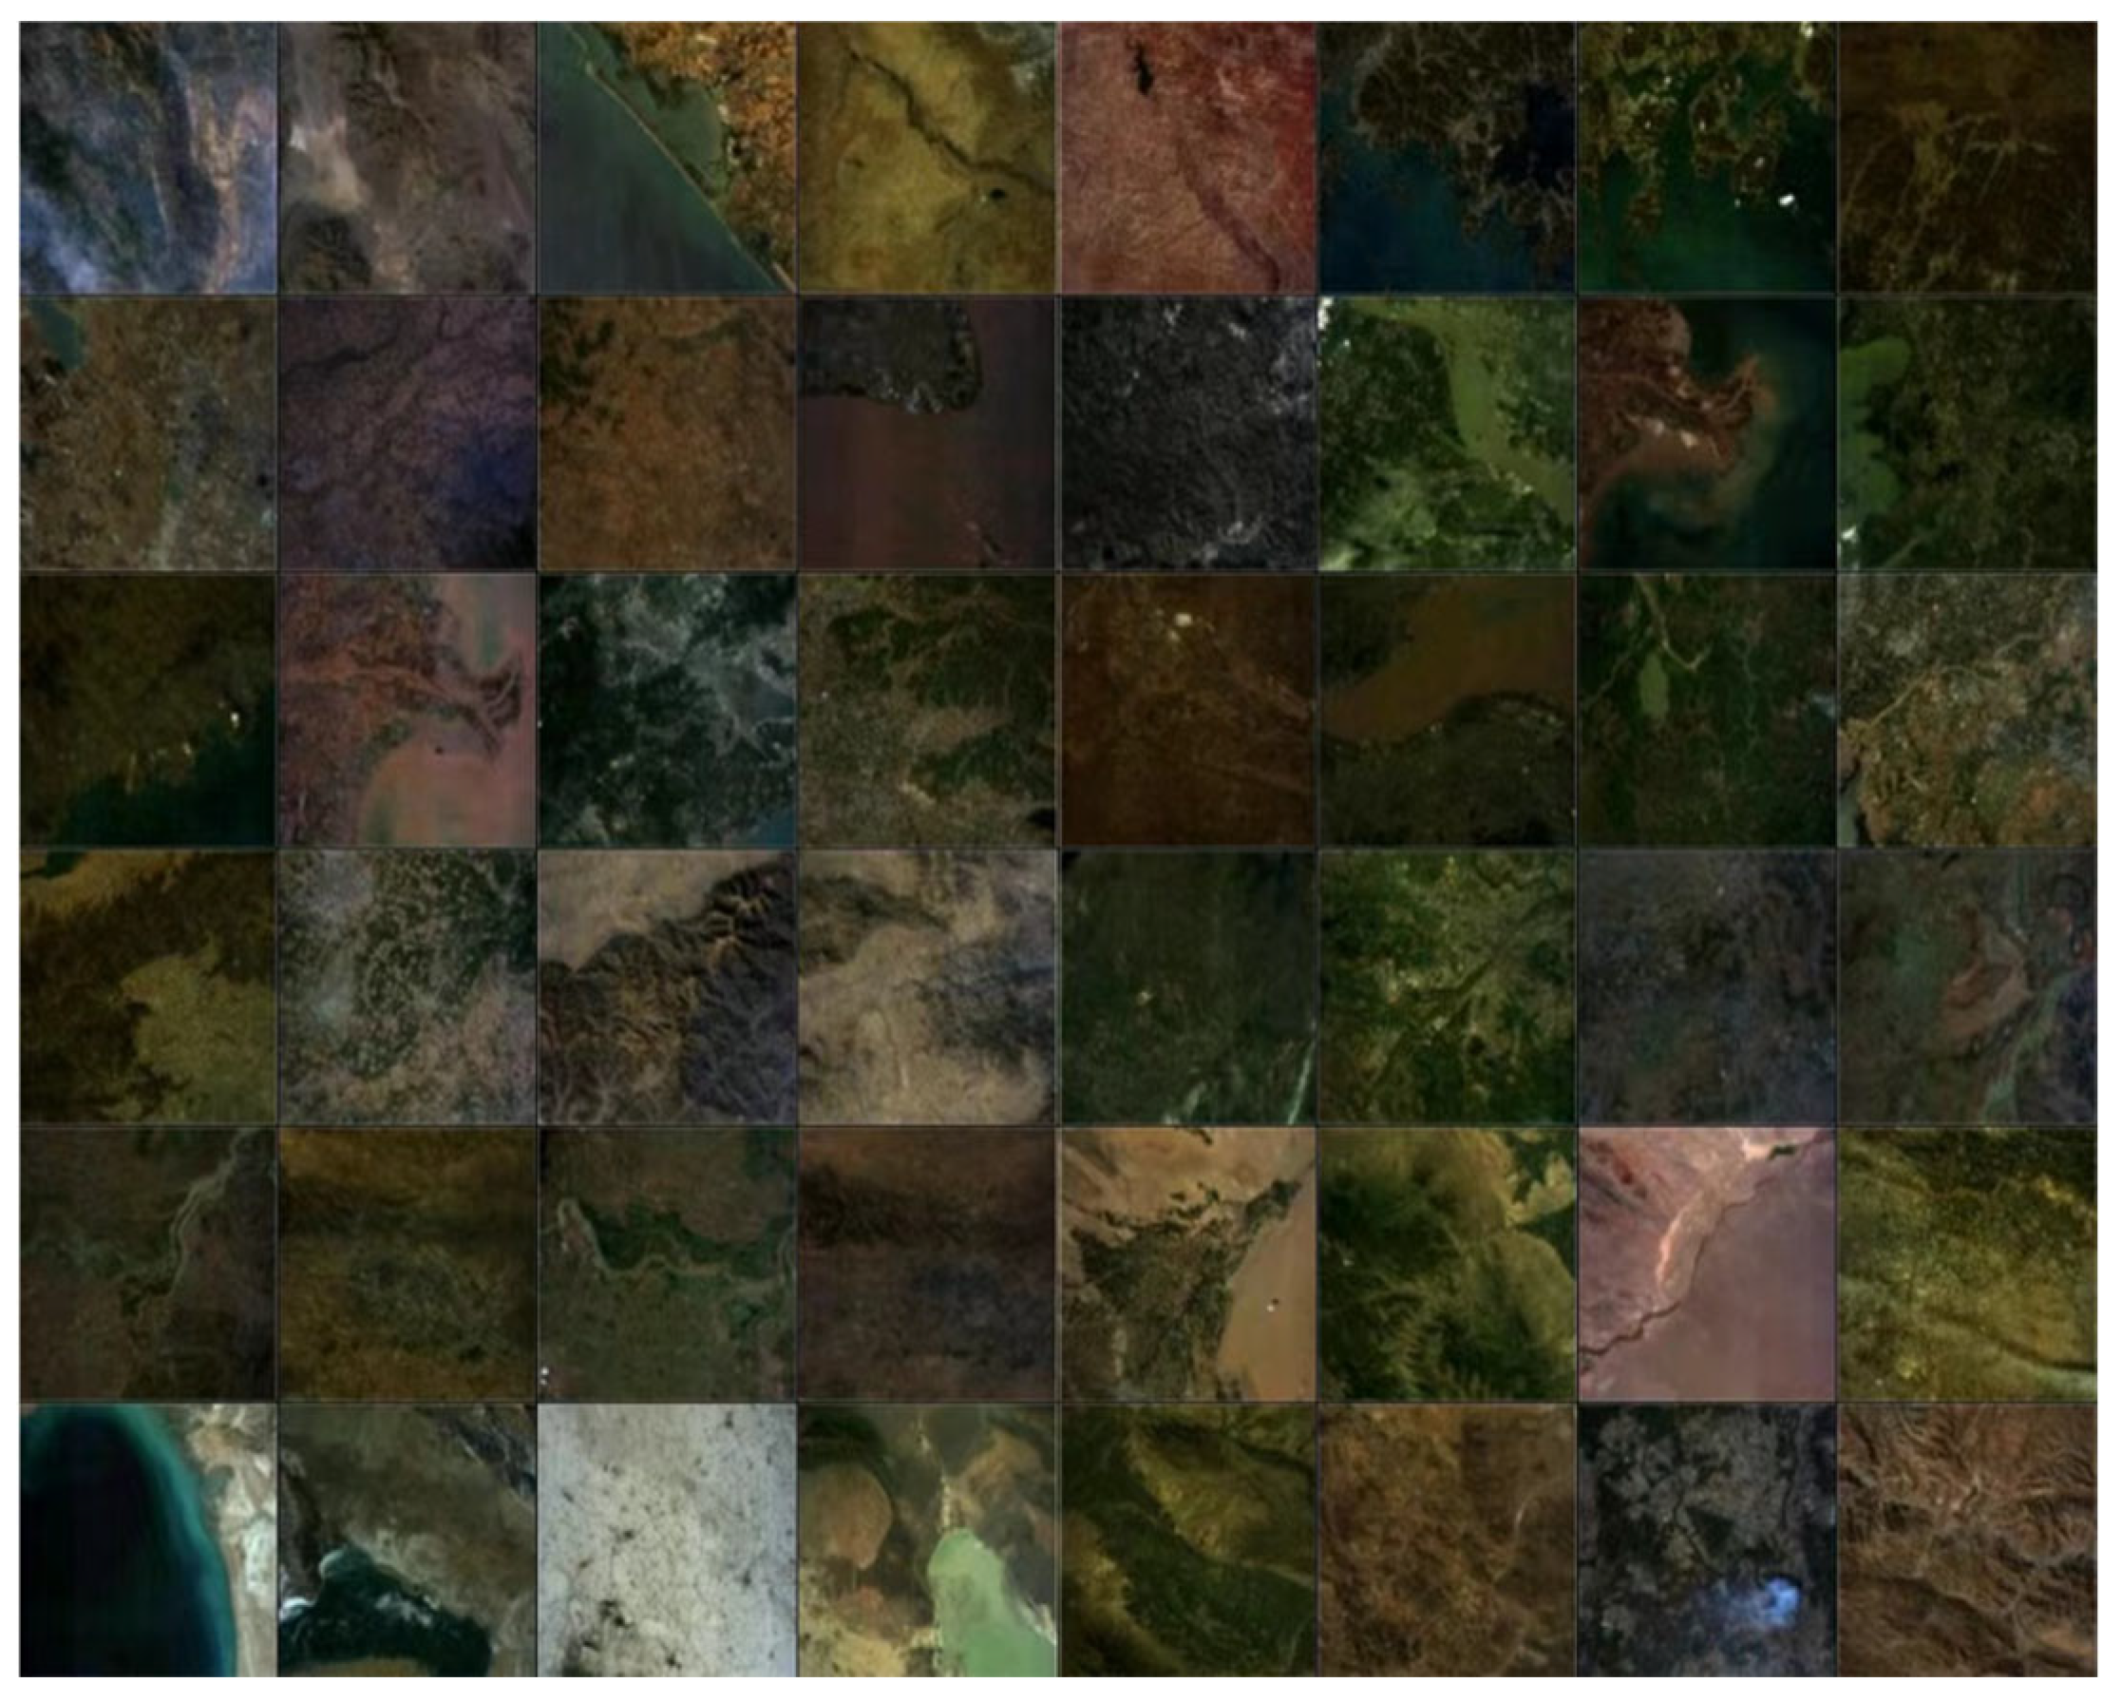
- Low-light remote sensing data are adopted for training and validation to improve restoration robustness in challenging imaging conditions. The proposed method achieves a favourable balance between reconstruction quality and model complexity.
2. Related Work
2.1. Lightweight Single-Stage Visual Feature Extraction Frameworks
- (1)
- High spatial resolution and precise feature preservation: Accurate interpretation of ground object details in low-light remote sensing scenarios relies on high-resolution reconstruction and reliable feature recognition for typical targets such as buildings, roads, and vegetation. Benefiting from outstanding multi-target feature parsing capability, the optimised lightweight network structure can cooperate with super-resolution reconstruction: it not only improves image spatial resolution, but also retains and enhances critical texture features in reconstructed images, effectively improving the practicability and analytical reliability of subsequent remote sensing interpretation.
- (2)
- Efficient processing for large-area coverage: Remote sensing data usually covers wide geographical areas, requiring algorithms to support large-scale dataset processing while ensuring complete detail retention. The end-to-end single-pass processing mechanism of classic lightweight networks significantly improves the computational efficiency of large-area remote sensing data and adapts to the characteristics of massive satellite image resources.
- (3)
- Real-time and low-latency inference: Many emergency scenarios, such as disaster early warning and dynamic security monitoring, require near real-time image enhancement and analysis. The lightweight attribute and fast inference advantage of single-stage architectures would match such demands. The combination of such network ideas and super-resolution technology can realise rapid, high-quality reconstruction of remote sensing images and support timely decision-making in emergency tasks.
- (4)
- Strong generalisation across complex scenes: Remote sensing images contain diverse terrain and landform types, which require algorithms with stable generalisation for different ground object features. The multi-category adaptive feature extraction ability of mature lightweight networks ensures stable reconstruction performance in diverse scenarios, further optimising the overall quality of super-resolution results for urban planning, agricultural classification, and natural resource investigation.
2.2. Other Recent Lightweight SR Methods
2.3. Attention Mechanism
3. Methodology
3.1. Optimised Lightweight Feature Extraction Backbone
3.2. Feature Fusion Design Based on Multi-Scale Channel Attention Mechanism
4. Experiment Settings
4.1. Datasets
4.1.1. Training Dataset
4.1.2. Test Datasets
4.2. Evaluation Criteria
4.2.1. Standard Metrics
4.2.2. Perceptual Metrics
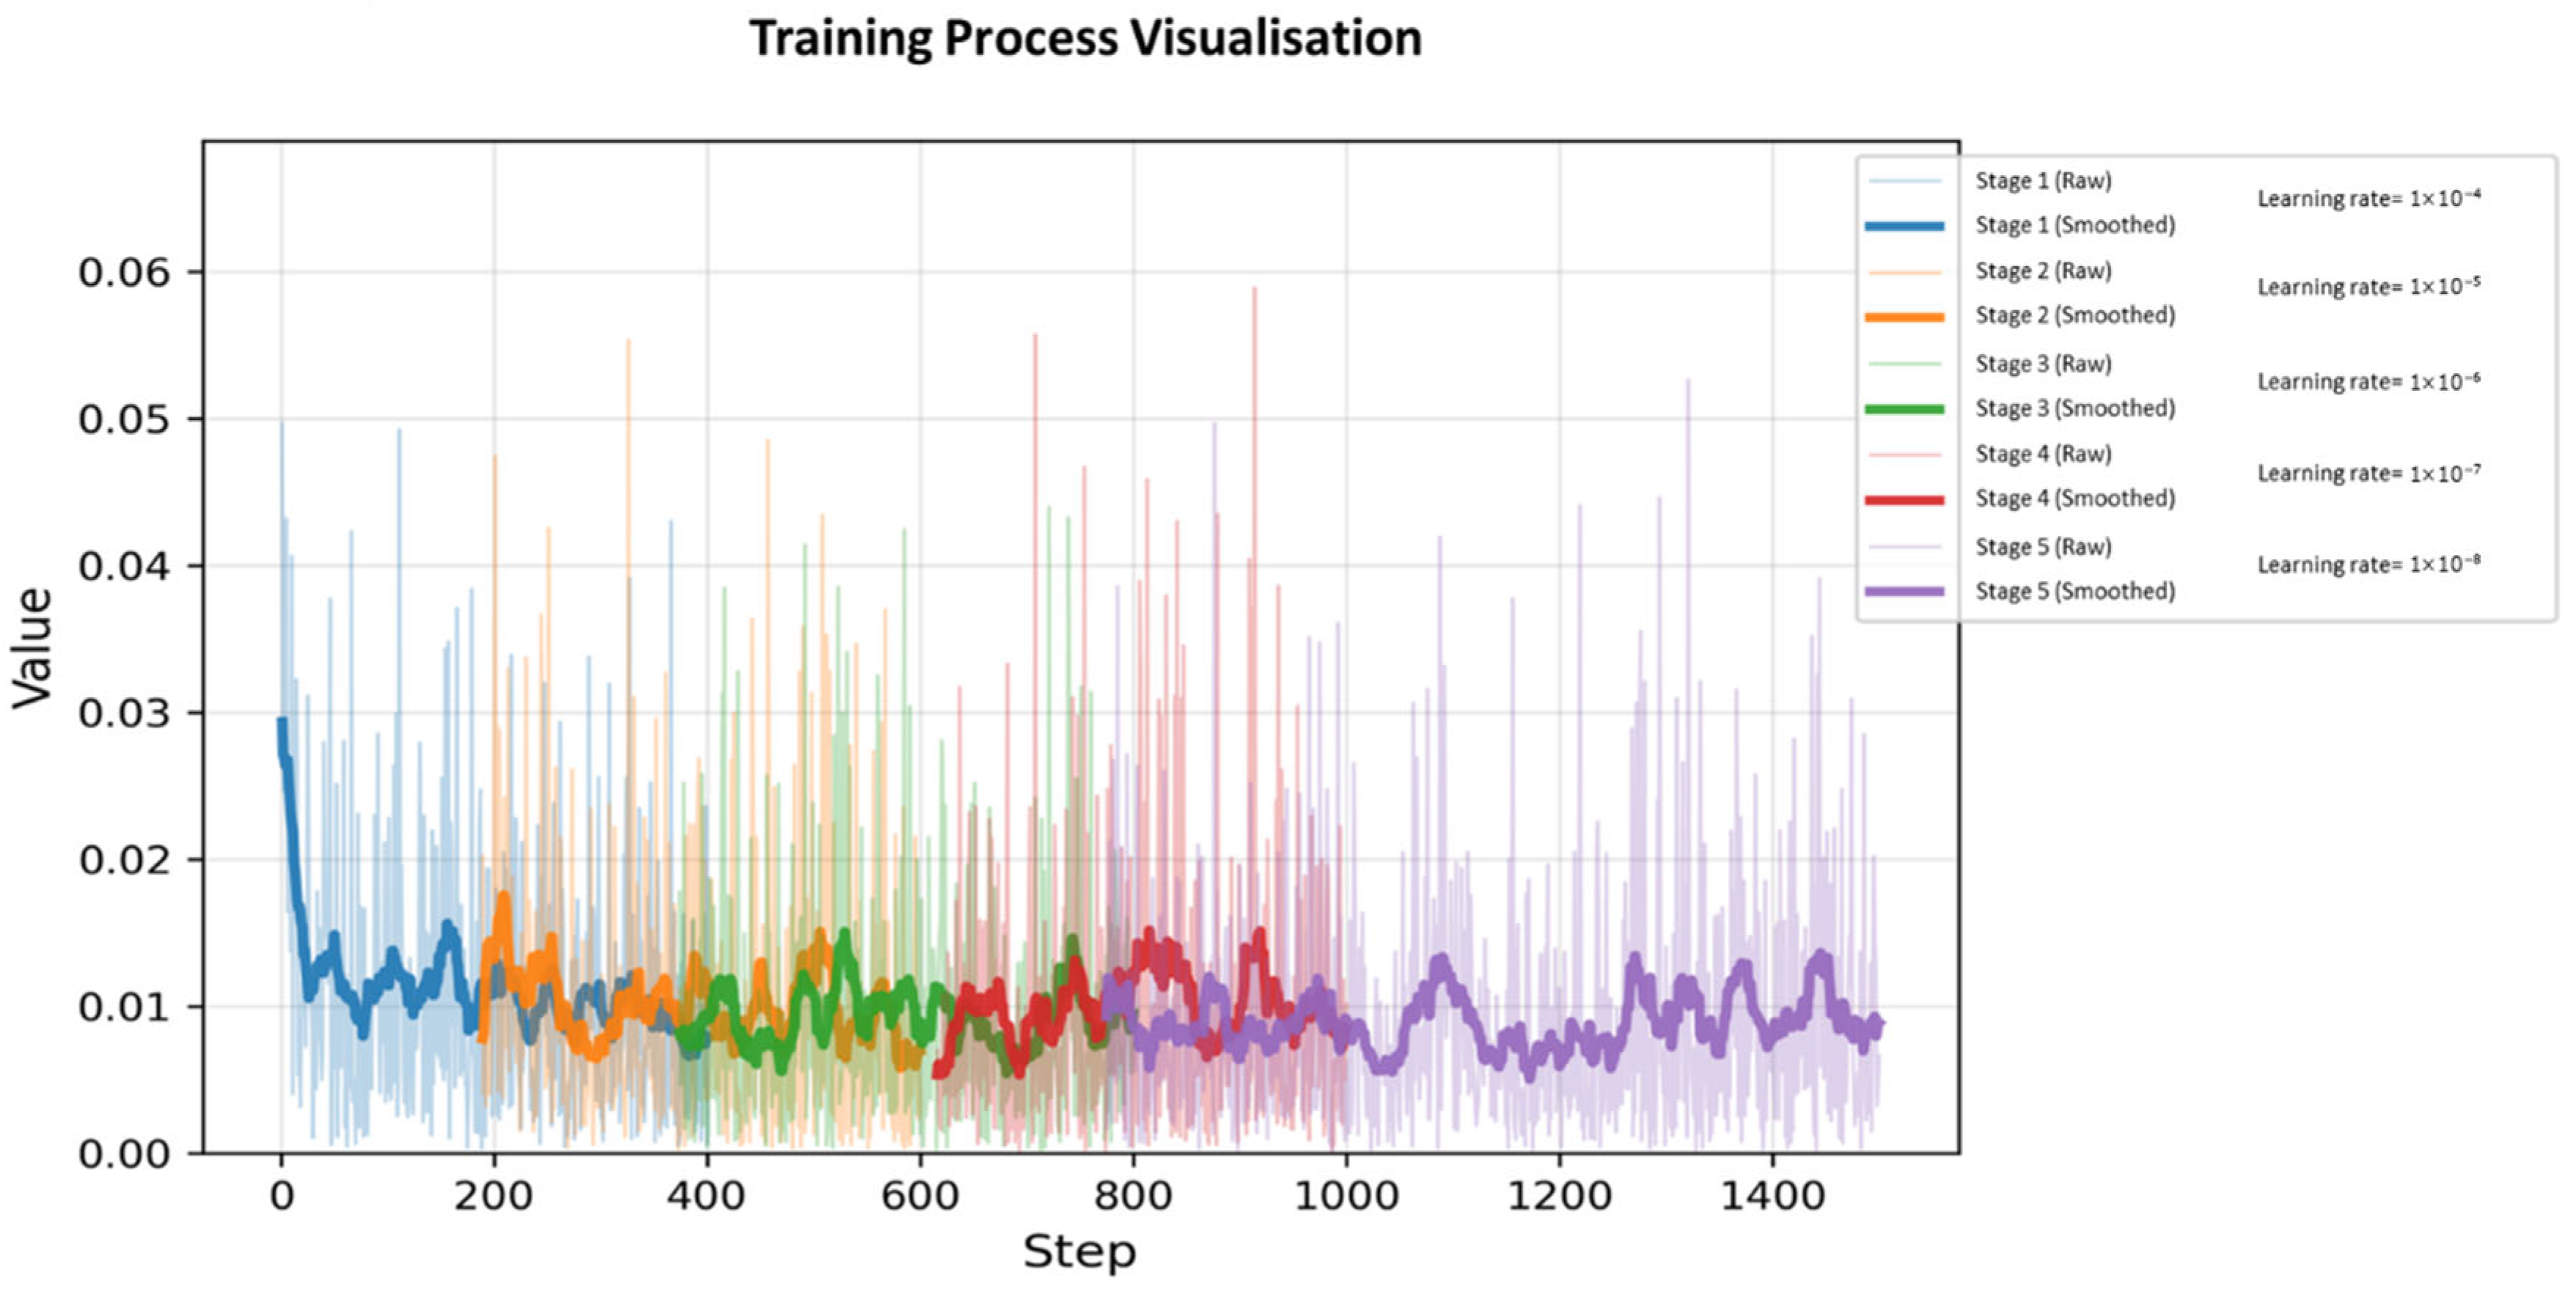
4.3. Training Process
5. Results and Discussion
5.1. Ablation Study
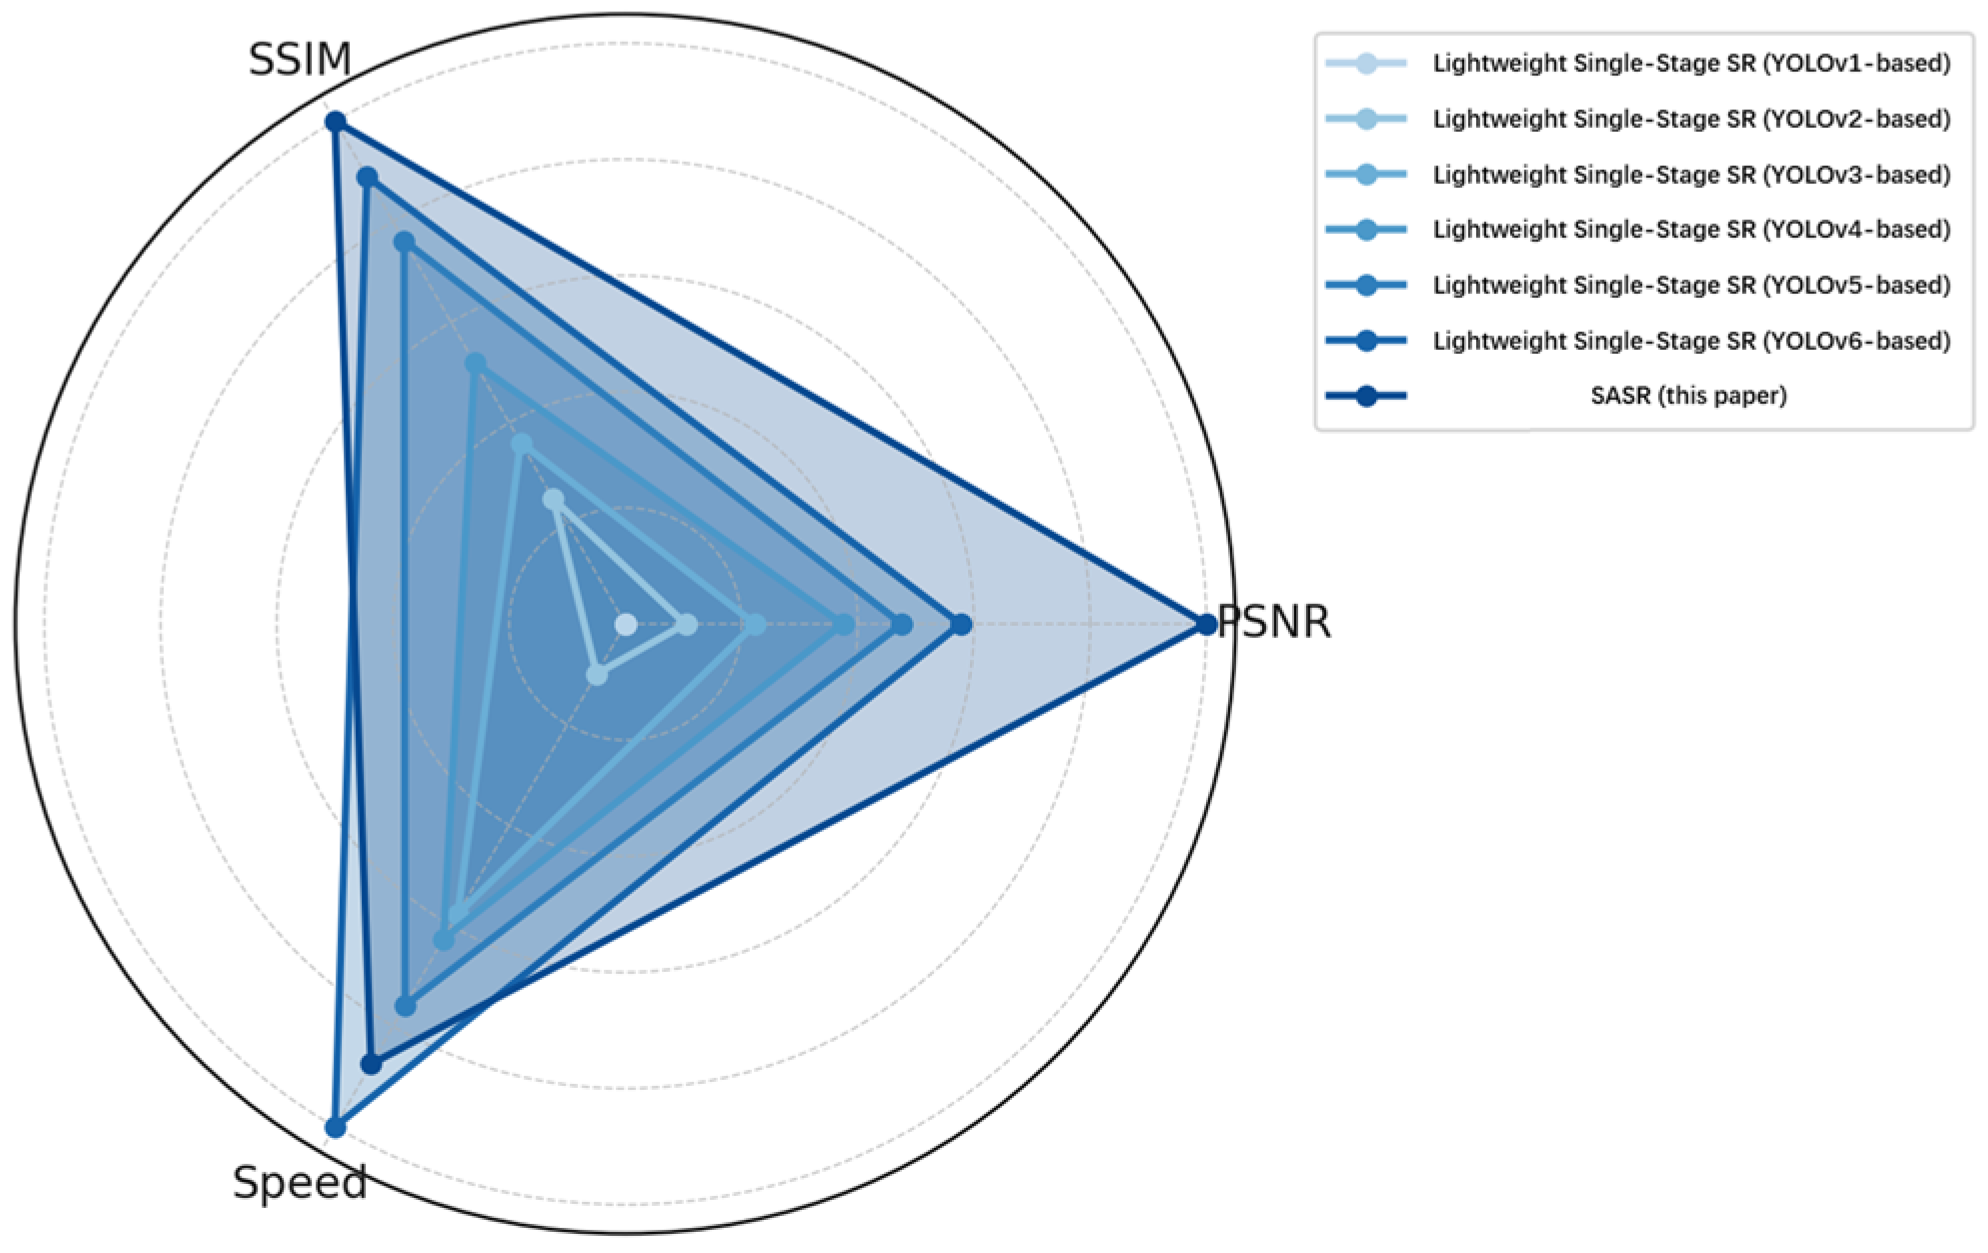
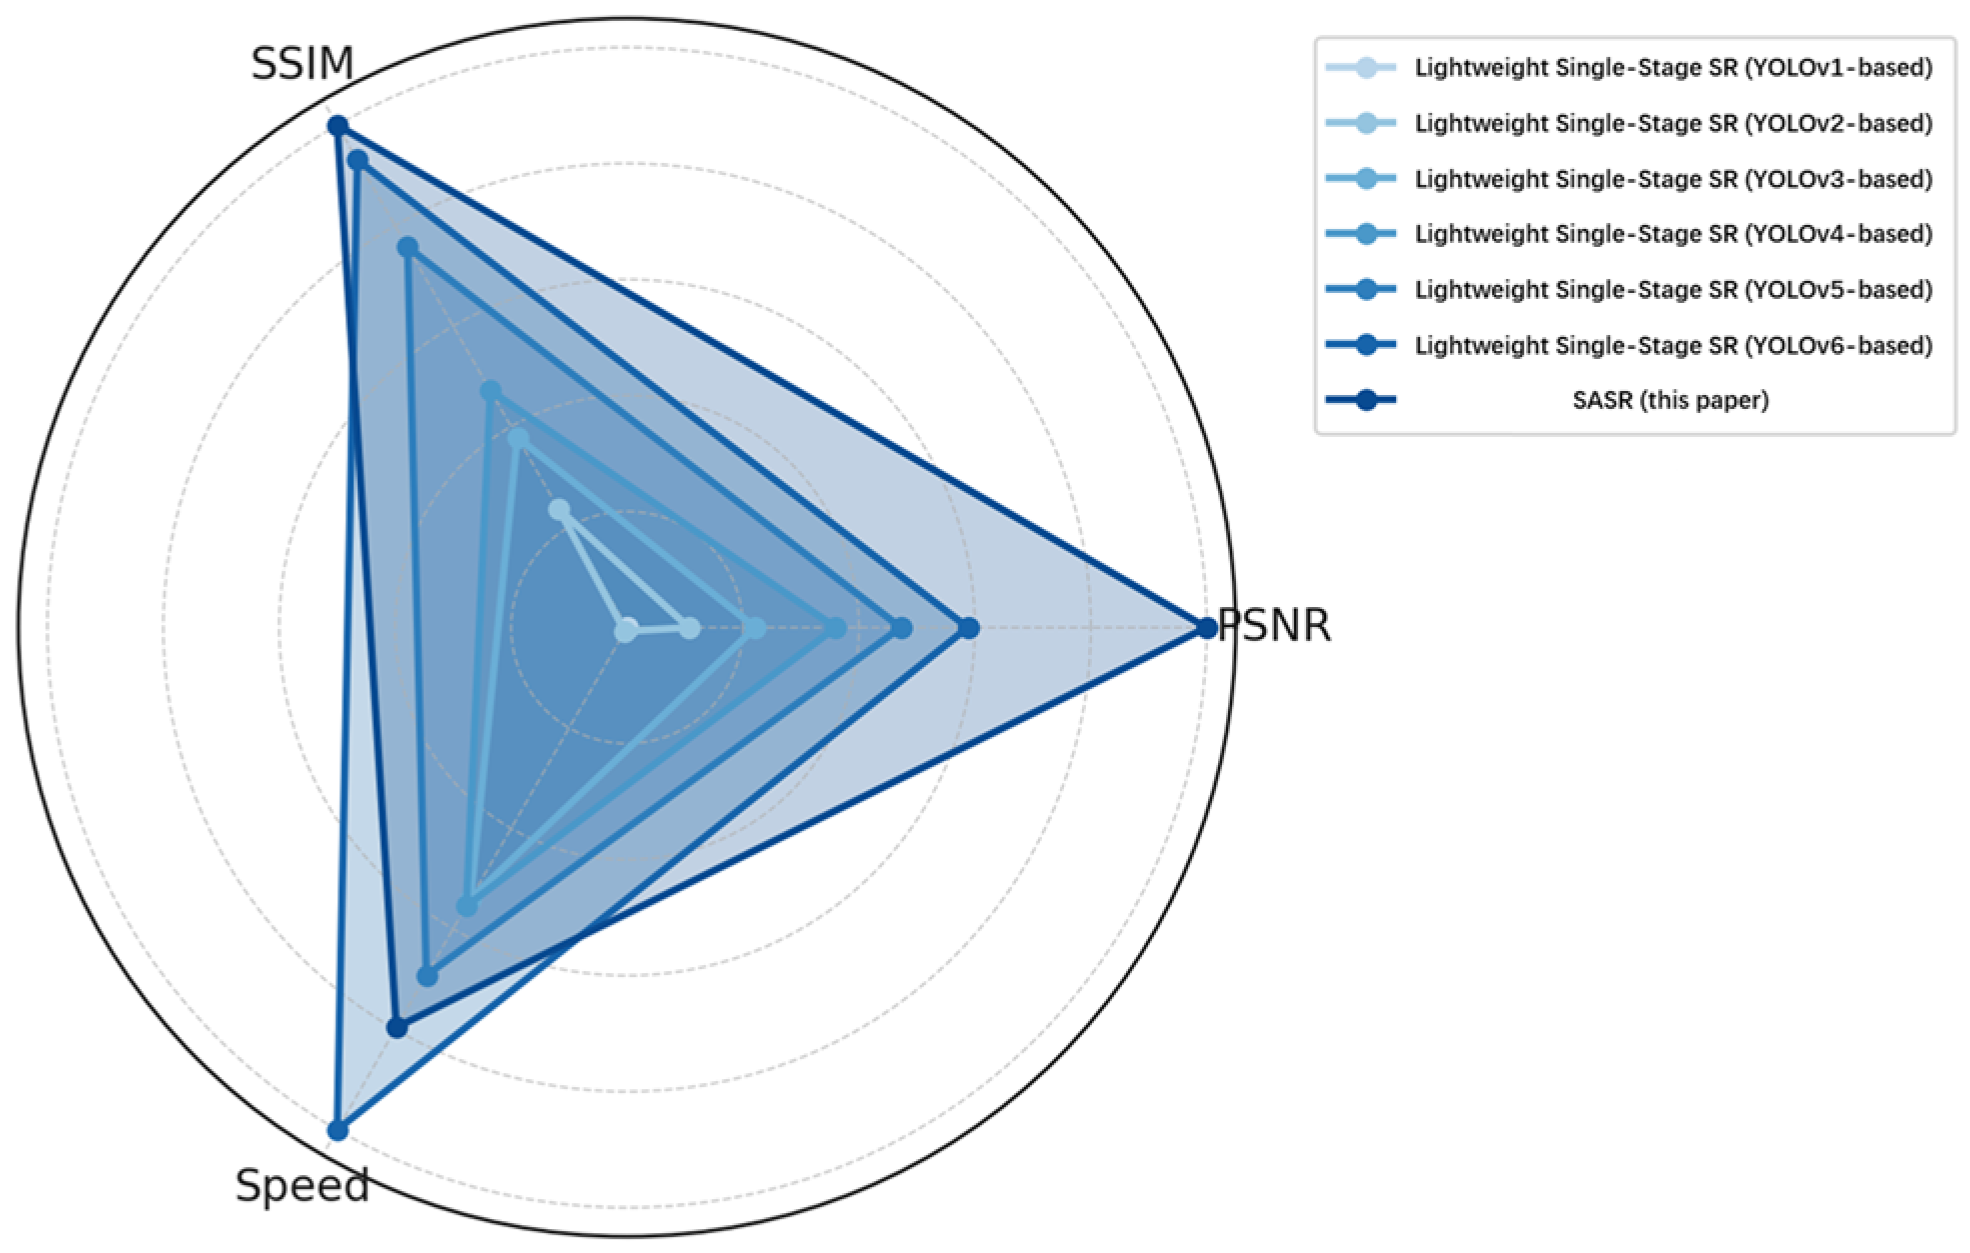
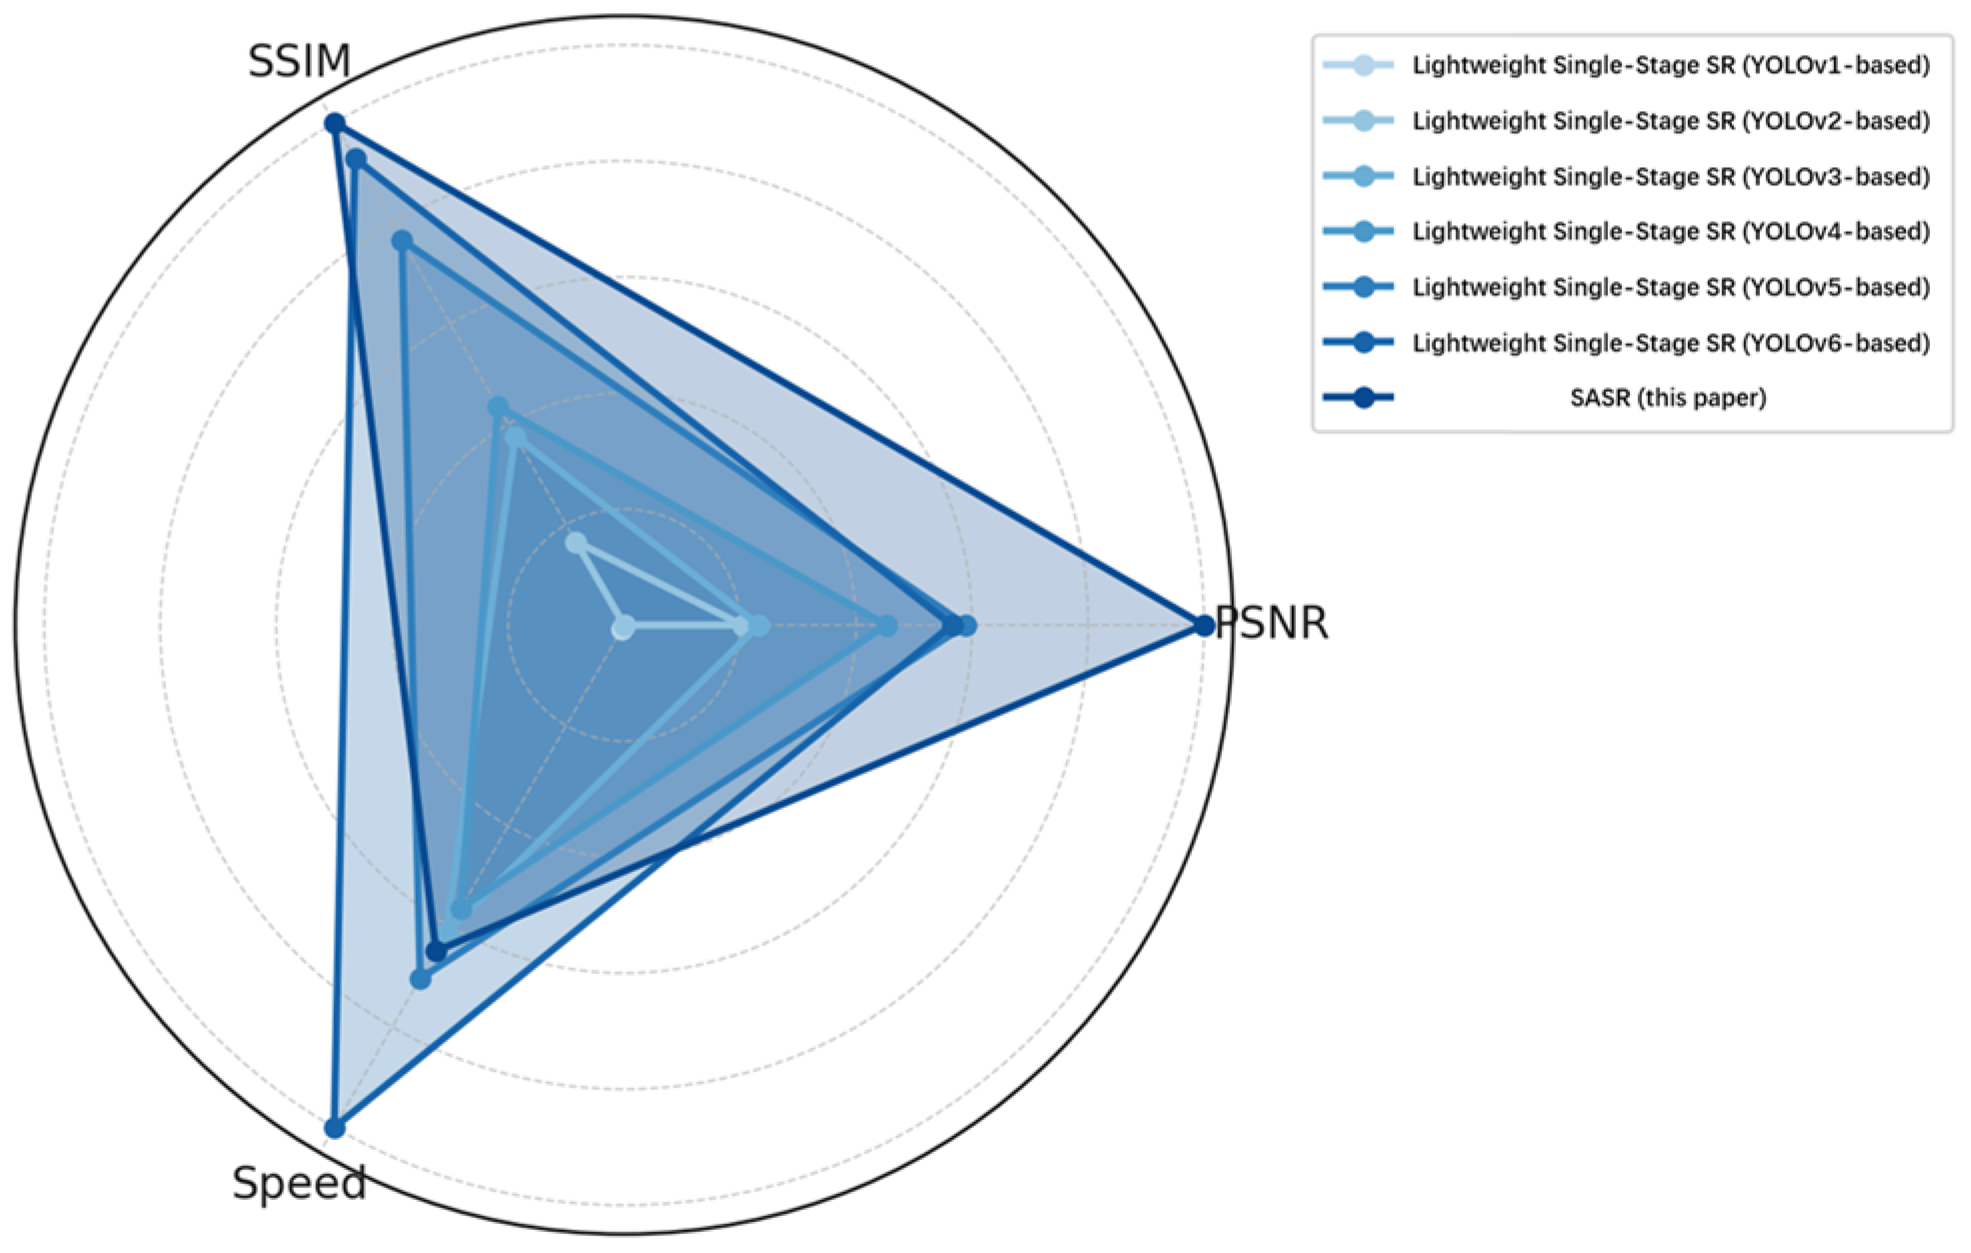
5.2. General Comparisons with Lightweight Single-Stage Backbone-Based Methods Without Attention
5.3. General Comparison with Other Recent Methods
5.4. Comparison in Detail
6. Conclusions and Prospects
Author Contributions
Funding
Institutional Review Board Statement
Informed Consent Statement
Data Availability Statement
Acknowledgments
Conflicts of Interest
References
- Ren, S.; He, K.; Girshick, R.; Sun, J. Faster r-cnn: Towards real-time object detection with region proposal networks. Adv. Neural Inf. Process. Syst. 2015, 28, 91–99. [Google Scholar] [CrossRef] [Scilit]
- Cong, X.; Li, S.; Chen, F.; Liu, C.; Meng, Y. A review of YOLO object detection algorithms based on deep learning. Front. Comput. Intell. Syst. 2023, 4, 17–20. [Google Scholar] [CrossRef] [Scilit]
- Terven, J.; Córdova-Esparza, D.-M.; Romero-González, J.-A. A comprehensive review of yolo architectures in computer vision: From yolov1 to yolov8 and yolo-nas. Mach. Learn. Knowl. Extr. 2023, 5, 1680–1716. [Google Scholar] [CrossRef] [Scilit]
- Jiang, P.; Ergu, D.; Liu, F.; Cai, Y.; Ma, B. A Review of Yolo algorithm developments. Procedia Comput. Sci. 2022, 199, 1066–1073. [Google Scholar] [CrossRef] [Scilit]
- Wan, C.; Pang, Y.; Lan, S. Overview of yolo object detection algorithm. Int. J. Comput. Inf. Technol. 2022, 2, 11–17. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Shao, Z.; Lu, T.; Liu, L.; Huang, X.; Wang, J.; Jiang, K.; Zeng, K. A lightweight distillation CNN-transformer architecture for remote sensing image super-resolution. Int. J. Digit. Earth 2023, 16, 3560–3579. [Google Scholar] [CrossRef] [Scilit]
- Xiao, L.; Liao, X.; Ren, C. Lightweight Single Image Super-Resolution via Efficient Mixture of Transformers and Convolutional Networks. Sensors 2024, 24, 5098. [Google Scholar] [CrossRef] [Scilit]
- Zhou, Y.; Li, Z.; Guo, C.-L.; Liu, L.; Cheng, M.-M.; Hou, Q. SRFormerV2: Taking a closer look at permuted self-attention for image super-resolution. arXiv 2023, arXiv:2303.09735. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhou, J.; Sun, W.; Meng, X.; Yang, G.; Chen, B.; Ren, K. Combined subspace low rank learning and nonlocal low rank estimation for spectral super-resolution of multispectral remote sensing images. Int. J. Digit. Earth 2025, 18, 2556237. [Google Scholar] [CrossRef] [Scilit]
- Xiao, Y.; Yuan, Q.; Jiang, K.; Huang, W.; Zhang, Q.; Zheng, T.; Lin, C.-W.; Zhang, L. Spiking meets attention: Efficient remote sensing image super-resolution with attention spiking neural networks. arXiv 2025, arXiv:2503.04223. [Google Scholar] [CrossRef] [Scilit]
- Li, M.; Xu, Q. Remote sensing image super-resolution guided by multi-level supervision paradigm. J. Remote Sens. 2024, 28, 1746–1759. [Google Scholar] [CrossRef] [Scilit]
- Pang, B.; Liu, Y.-N. PRO-SSRGAN: Stable super-resolution generative adversarial network based on parameter reconstructive optimization on Gaofen-5 remote-sensing images. Int. J. Remote Sens. 2024, 45, 3022–3053. [Google Scholar] [CrossRef] [Scilit]
- Hu, M.; Sun, J.; Yang, B.; Chang, K.; Yang, J. Super-resolution reconstruction of remote sensing image based on CNN and Transformer aggregation. J. ZheJiang Univ. (Eng. Sci.) 2025, 59, 938–946. [Google Scholar] [CrossRef]
- Zhang, D.; Shao, J.; Li, X.; Shen, H.T. Remote sensing image super-resolution via mixed high-order attention network. IEEE Trans. Geosci. Remote Sens. 2020, 59, 5183–5196. [Google Scholar] [CrossRef] [Scilit]
- Hu, Y.; Wang, X.; He, Z.; Yuan, X. Lighten-MST: Low-light Spectral Reconstruction via Illumination-guided Spectral-aware Transformer. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Honolulu, HI, USA, 19–20 October 2025; pp. 7383–7389. [Google Scholar]
- Liu, B.; Chen, J. A super resolution algorithm based on attention mechanism and srgan network. IEEE Access 2021, 9, 139138–139145. [Google Scholar] [CrossRef] [Scilit]
- Qi, Y.; Lou, M.; Liu, Y.; Li, L.; Yang, Z.; Nie, W. Advancing image super-resolution techniques in remote sensing: A comprehensive survey. ISPRS J. Photogramm. Remote Sens. 2026, 231, 68–100. [Google Scholar] [CrossRef] [Scilit]
- Zhu, X.; Guo, K.; Ren, S.; Hu, B.; Hu, M.; Fang, H. Lightweight image super-resolution with expectation-maximization attention mechanism. IEEE Trans. Circuits Syst. Video Technol. 2021, 32, 1273–1284. [Google Scholar] [CrossRef] [Scilit]
- Dai, Y.; Gieseke, F.; Oehmcke, S.; Wu, Y.; Barnard, K. Attentional feature fusion. In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision, Waikoloa, HI, USA, 5–9 January 2021; pp. 3560–3569. [Google Scholar]
- Lu, R.; Miao, H.; Hai, X. Efficient remote sensing image super-resolution with residual-enhanced wavelet and key-value adaptation. Front. Remote Sens. 2025, 6, 1718058. [Google Scholar] [CrossRef] [Scilit]
- Tang, T.; Ren, Y.; Feng, S. Dual-Branch Super-Resolution (DBSR): Lightweight DBSR Network for Enhancing Remote Sensing Images. Eur. J. Artif. Intell. 2025, 38, 217–237. [Google Scholar] [CrossRef] [Scilit]
- Anderson, P.; He, X.; Buehler, C.; Teney, D.; Johnson, M.; Gould, S.; Zhang, L. Bottom-up and top-down attention for image captioning and visual question answering. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–22 June 2018; pp. 6077–6086. [Google Scholar]
- Niu, Z.; Zhong, G.; Yu, H. A review on the attention mechanism of deep learning. Neurocomputing 2021, 452, 48–62. [Google Scholar] [CrossRef] [Scilit]
- Luong, M.-T.; Pham, H.; Manning, C.D. Effective approaches to attention-based neural machine translation. In Proceedings of the 2015 Conference on Empirical Methods in Natural Language Processing, Lisbon, Portugal, 17–21 September 2015; pp. 1412–1421. [Google Scholar]
- Xu, K.; Ba, J.; Kiros, R.; Cho, K.; Courville, A.; Salakhudinov, R.; Zemel, R.; Bengio, Y. Show, attend and tell: Neural image caption generation with visual attention. In Proceedings of International Conference on Machine Learning, Lille, France, 7–9 July 2015; PMLR: New York, NY, USA, 2015; pp. 2048–2057. [Google Scholar]
- Liang, J.; Cao, J.; Sun, G.; Zhang, K.; Van Gool, L.; Timofte, R. Swinir: Image restoration using swin transformer. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Montreal, QC, Canada, 10–17 October 2021; pp. 1833–1844. [Google Scholar]
- Mnih, V.; Heess, N.; Graves, A.; Kavukcuoglu, K. Recurrent models of visual attention. Adv. Neural Inf. Process. Syst. 2014, 27, 2204–2212. [Google Scholar]
- Xuanhao, Q.; Min, Z. A review of attention mechanisms in computer vision. In Proceedings of 2023 8th International Conference on Image, Vision and Computing (ICIVC), Dalian, China, 27–29 July 2023; IEEE: Piscataway, NJ, USA, 2023; pp. 577–583. [Google Scholar]
- Guo, M.-H.; Xu, T.-X.; Liu, J.-J.; Liu, Z.-N.; Jiang, P.-T.; Mu, T.-J.; Zhang, S.-H.; Martin, R.R.; Cheng, M.-M.; Hu, S.-M. Attention mechanisms in computer vision: A survey. Comput. Vis. Media 2022, 8, 331–368. [Google Scholar] [CrossRef] [Scilit]
- Hu, J.; Shen, L.; Sun, G. Squeeze-and-excitation networks. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–22 June 2018; pp. 7132–7141. [Google Scholar]
- Woo, S.; Park, J.; Lee, J.-Y.; Kweon, I.S. Cbam: Convolutional block attention module. In Proceedings of the European Conference on Computer Vision (ECCV), Munich, Germany, 8–14 September 2018; pp. 3–19. [Google Scholar]
- Zhu, H.; Xie, C.; Fei, Y.; Tao, H. Attention mechanisms in CNN-based single image super-resolution: A brief review and a new perspective. Electronics 2021, 10, 1187. [Google Scholar] [CrossRef] [Scilit]
- Chen, Y.; Liu, L.; Phonevilay, V.; Gu, K.; Xia, R.; Xie, J.; Zhang, Q.; Yang, K. Image super-resolution reconstruction based on feature map attention mechanism: Y. Chen et al. Appl. Intell. 2021, 51, 4367–4380. [Google Scholar] [CrossRef] [Scilit]
- Chen, X.; Wu, Y.; Lu, T.; Kong, Q.; Wang, J.; Wang, Y. Remote sensing image super-resolution with residual split attention mechanism. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2023, 16, 1–13. [Google Scholar] [CrossRef] [Scilit]
- Yang, X.; Li, X.; Li, Z.; Zhou, D. Image super-resolution based on deep neural network of multiple attention mechanism. J. Vis. Commun. Image Represent. 2021, 75, 103019. [Google Scholar] [CrossRef] [Scilit]
- Zadeh, A.; Chen, M.; Poria, S.; Cambria, E.; Morency, L.P. Tensor fusion network for multimodal sentiment analysis. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing, Copenhagen, Denmark, 9–11 September 2017. [Google Scholar]
- Zhang, Z.; Sun, Q.; Ye, Z.; Liu, C.; Wang, M. Adaptive multi-scale feature aggregation transformer network for single remote sensing image super-resolution. Geo-Spat. Inf. Sci. 2025, 1–22. [Google Scholar] [CrossRef] [Scilit]
- Han, Y.; Chi, H.; Huang, J.; Shi, X.; Qiu, J.; Shao, Q.; Li, Y.; Cheng, C.; Ling, F. Long-term wetland mapping at 10 m resolution using super-resolution and hierarchical classification—A case study in Jianghan Plain, China. Int. J. Digit. Earth 2025, 18, 2498605. [Google Scholar] [CrossRef] [Scilit]
- He, W.; Zhang, H.; Zhang, L.; Shen, H. Hyperspectral image denoising via noise-adjusted iterative low-rank matrix approximation. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2015, 8, 3050–3061. [Google Scholar] [CrossRef] [Scilit]
- Tang, H.; Xu, D.; Sebe, N.; Wang, Y.; Corso, J.J.; Yan, Y. Multi-channel attention selection gan with cascaded semantic guidance for cross-view image translation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Long Beach, CA, USA, 15–20 June 2019; pp. 2417–2426. [Google Scholar]
- Pang, B.; Zhao, S.; Liu, Y. The use of a stable super-resolution generative adversarial network (SSRGAN) on Remote Sensing Images. Remote Sens. 2023, 15, 5064. [Google Scholar] [CrossRef] [Scilit]
- Zhang, R.; Isola, P.; Efros, A.A.; Shechtman, E.; Wang, O. The unreasonable effectiveness of deep features as a perceptual metric. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–22 June 2018; pp. 586–595. [Google Scholar]
- Mittal, A.; Soundararajan, R.; Bovik, A.C. Making a “completely blind” image quality analyzer. IEEE Signal Process. Lett. 2012, 20, 209–212. [Google Scholar] [CrossRef] [Scilit]
- Hui, Z.; Gao, X.; Yang, Y.; Wang, X. Lightweight image super-resolution with information multi-distillation network. In Proceedings of the 27th ACM International Conference on Multimedia, Nice, France, 21–25 October 2019; pp. 2024–2032. [Google Scholar]
- Liu, J.; Tang, J.; Wu, G. Residual feature distillation network for lightweight image super-resolution. In European Conference on Computer Vision; Springer: Cham, Switzerland, 2020. [Google Scholar]
- Li, Y.; Agustsson, E.; Gu, S.; Timofte, R.; Van Gool, L. Carn: Convolutional anchored regression network for fast and accurate single image super-resolution. In Proceedings of the European Conference on Computer Vision (ECCV) Workshops, Munich, Germany, 8–14 September 2018. [Google Scholar]





| Version | Year | Training Framework | Backbone |
|---|---|---|---|
| YOLO | 2015 | Darknet | Darknet24 |
| YOLOv2 | 2016 | Darknet | Darknet24 |
| YOLOv3 | 2018 | Darknet | Darknet53 |
| YOLOv4 | 2020 | Darknet | CSPDarknet53 |
| YOLOv5 | 2020 | PyTorch | YOLOv5CSPDarknet |
| PP-YOLO | 2020 | PaddlePaddle | ResNet50-vd |
| Scaled-YOLOv4 | 2021 | PyTorch | CSPDarknet |
| PP-YOLOv2 | 2021 | PaddlePaddle | ResNet101-vd |
| YOLOR | 2021 | PyTorch | CSPDarknet |
| YOLOX | 2021 | PyTorch | YOLOXCSPDarknet |
| PP-YOLOE | 2022 | PaddlePaddle | CSPRepResNet |
| YOLOv6 | 2022 | PyTorch | EfficientRep |
| YOLOv7 | 2022 | PyTorch | YOLOv7Backbone |
| DAMO-YOLO | 2022 | PyTorch | MAE-NAS |
| YOLOv8 | 2023 | PyTorch | YOLOv8CSPDarknet |
| YOLO-NAS | 2023 | PyTorch | NAS |
| YOLOv9 | 2024 | PyTorch | GELAN + RepNCSPELAN |
| YOLOv10 | 2024 | PyTorch | C2f + Lightweight C2f |
| YOLOv11 | 2025 | PyTorch | C3 + C2f + SPPF |
| Classification Criteria | Classification Details |
|---|---|
| Focus Method | Soft attention, Hard attention |
| Focus Range | Global attention, Local attention |
| Feature Form | Item-based attention, Region-based attention |
| Construction Method | Sequential attention, Graph attention |
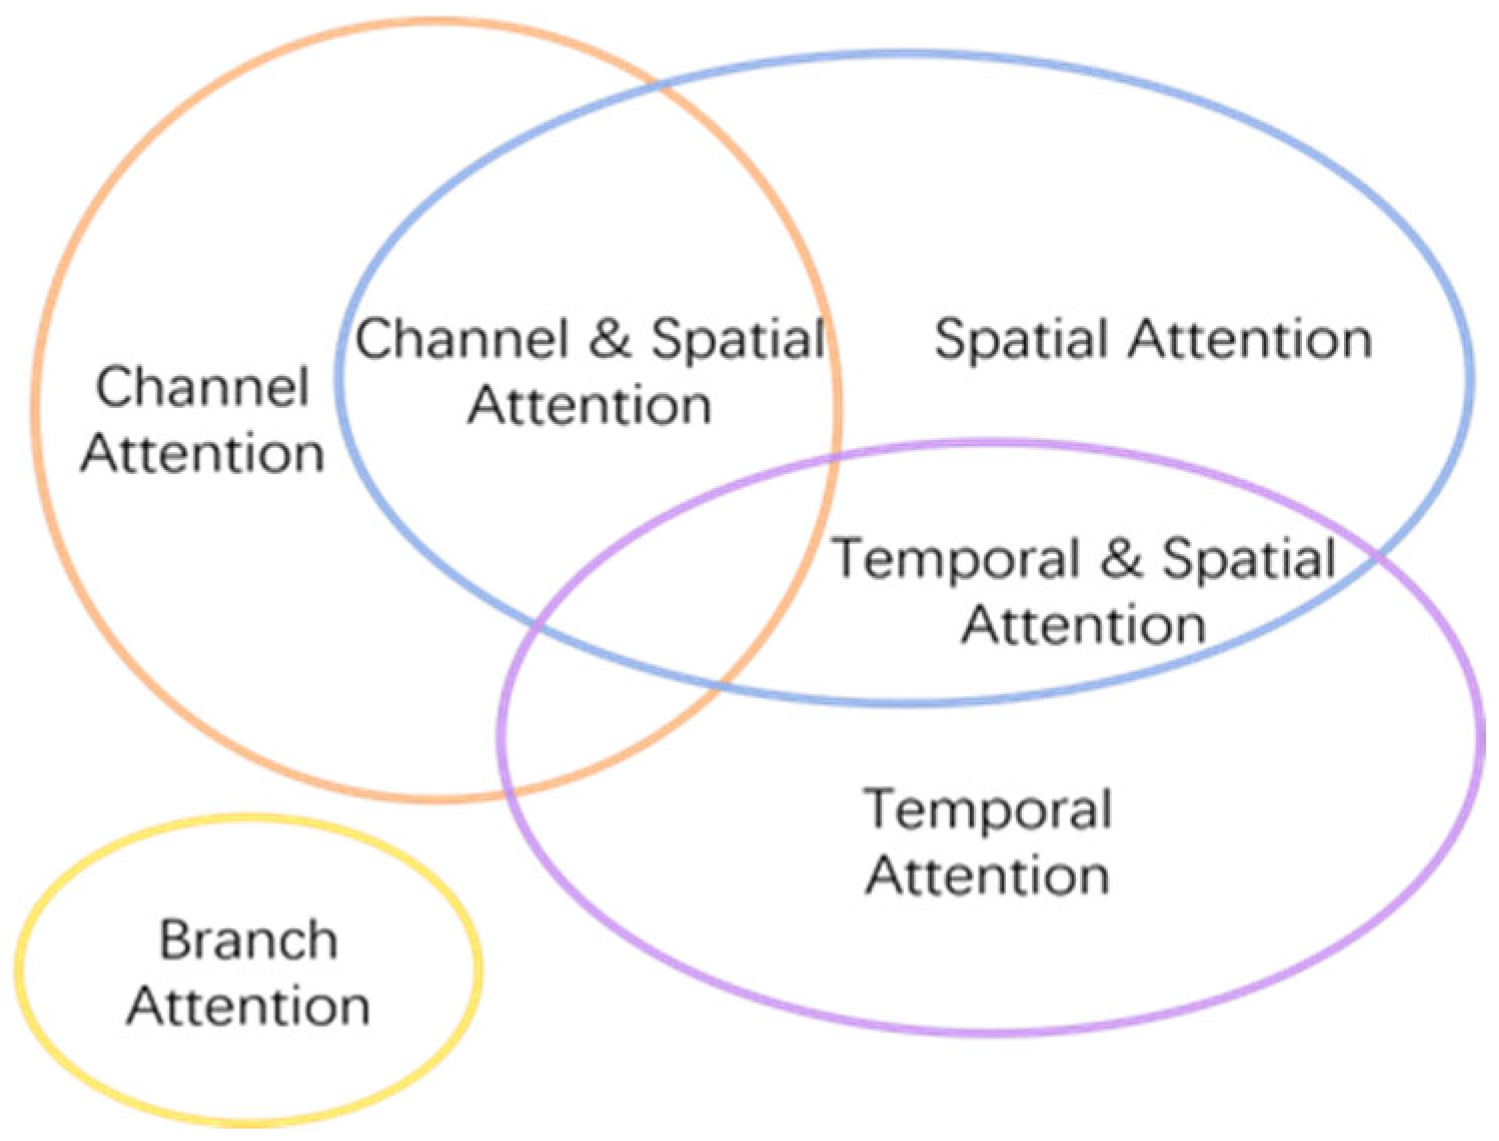
| Input Representation | Spatial attention, Channel attention, Temporal attention, Hybrid attention |
| Output Representation | Single-output attention, Multi-head attention, Multi-dimensional attention |
| Attention Mechanism | Representative Methods | Advantages | Limitations | Applications |
|---|---|---|---|---|
| Spatial Attention | RAM, STN, CCNet | Expandable scalability Focus on important regions Adaptive spatial transformation Build long-range dependencies | Rely on high-quality data High computational cost High training complexity | Image classification Image segmentation Image generation |
| Channel Attention | SE-Net, FCA-Net, ECA-Net, GCT | Increase important channels Capture global information Low computational cost Plug-and-play features | High model complexity Lack long-range dependence Complex image effect difference Potential misalignment | Image classification Image segmentation Target monitoring Image generation |
| Spatial-Channel Combined Attention | CBAM, BAM, SA-Net, EPSA | Focus on important regions Adaptive input size Build long-range dependencies Rich feature information | High model complexity Potential misalignment | Image classification Image segmentation Target monitoring Image generation |
| Magnification Ratio | Evaluation Criteria | Methods | ||
|---|---|---|---|---|
| Lightweight Backbone-SR | Attention (RCAN)-Based SR | SASR | ||
| 2× | PSNR/dB | 31.9547 | 32.2045 | 32.2346 |
| SSIM | 0.8726 | 0.8856 | 0.8791 | |
| Time/s | 0.4361 | 1.2802 | 0.4583 | |
| 3× | PSNR/dB | 31.3401 | 31.4519 | 31.6040 |
| SSIM | 0.8337 | 0.8345 | 0.8376 | |
| Time/s | 0.5660 | 1.5784 | 0.6044 | |
| 4× | PSNR/dB | 30.0952 | 30.1277 | 30.3574 |
| SSIM | 0.8011 | 0.8028 | 0.8049 | |
| Time/s | 0.6975 | 1.8521 | 0.7690 | |
| Context-Awareness | Type | Formulation | Scenario & References | Examples |
|---|---|---|---|---|
| None | Addition | Short Skip, Long Skip | ResNet | |
| Concatenation | Same Layer, Long Skip | U-Net | ||
| Partially | Refinement | Short Skip | SENet | |
| Modulation | Long Skip | GAU | ||
| Soft Selection | Short Skip | HighN | ||
| Fully | Modulation | Long Skip | SA | |
| Soft Selection | Same Layer | SKNet | ||
| Same Layer, Short Skip, Long Skip | ours |
| Methods | PSNR/dB | SSIM | Time/s |
|---|---|---|---|
| Lightweight Single-Stage SR (YOLOv1-based) | 31.5726 | 0.8203 | 0.7125 |
| Lightweight Single-Stage SR (YOLOv2-based) | 31.6411 | 0.8349 | 0.6704 |
| Lightweight Single-Stage SR (YOLOv3-based) | 31.7205 | 0.8415 | 0.5218 |
| Lightweight Single-Stage SR (YOLOv4-based) | 31.8204 | 0.8508 | 0.5101 |
| Lightweight Single-Stage SR (YOLOv5-based) | 31.8876 | 0.8651 | 0.4812 |
| Lightweight Single-Stage SR (YOLOv6-based) | 31.9547 | 0.8726 | 0.4361 |
| SASR | 32.2346 | 0.8791 | 0.4583 |
| Methods | PSNR/dB | SSIM | Time/s |
|---|---|---|---|
| Lightweight Single-Stage SR (YOLOv1-based) | 30.9635 | 0.7816 | 0.8217 |
| Lightweight Single-Stage SR (YOLOv2-based) | 31.0319 | 0.7948 | 0.8189 |
| Lightweight Single-Stage SR (YOLOv3-based) | 31.1053 | 0.8028 | 0.6606 |
| Lightweight Single-Stage SR (YOLOv4-based) | 31.1942 | 0.8080 | 0.6571 |
| Lightweight Single-Stage SR (YOLOv5-based) | 31.2660 | 0.8240 | 0.6259 |
| Lightweight Single-Stage SR (YOLOv6-based) | 31.3401 | 0.8337 | 0.5660 |
| SASR | 31.6040 | 0.8376 | 0.6044 |
| Methods | PSNR/dB | SSIM | Time/s |
|---|---|---|---|
| Lightweight Single-Stage SR (YOLOv1-based) | 29.7543 | 0.7514 | 0.9464 |
| Lightweight Single-Stage SR (YOLOv2-based) | 29.8773 | 0.7603 | 0.9488 |
| Lightweight Single-Stage SR (YOLOv3-based) | 29.8945 | 0.7715 | 0.7770 |
| Lightweight Single-Stage SR (YOLOv4-based) | 30.0271 | 0.7747 | 0.7888 |
| Lightweight Single-Stage SR (YOLOv5-based) | 30.1095 | 0.7924 | 0.7570 |
| Lightweight Single-Stage SR (YOLOv6-based) | 30.0952 | 0.8011 | 0.6975 |
| SASR | 30.3574 | 0.8049 | 0.7690 |
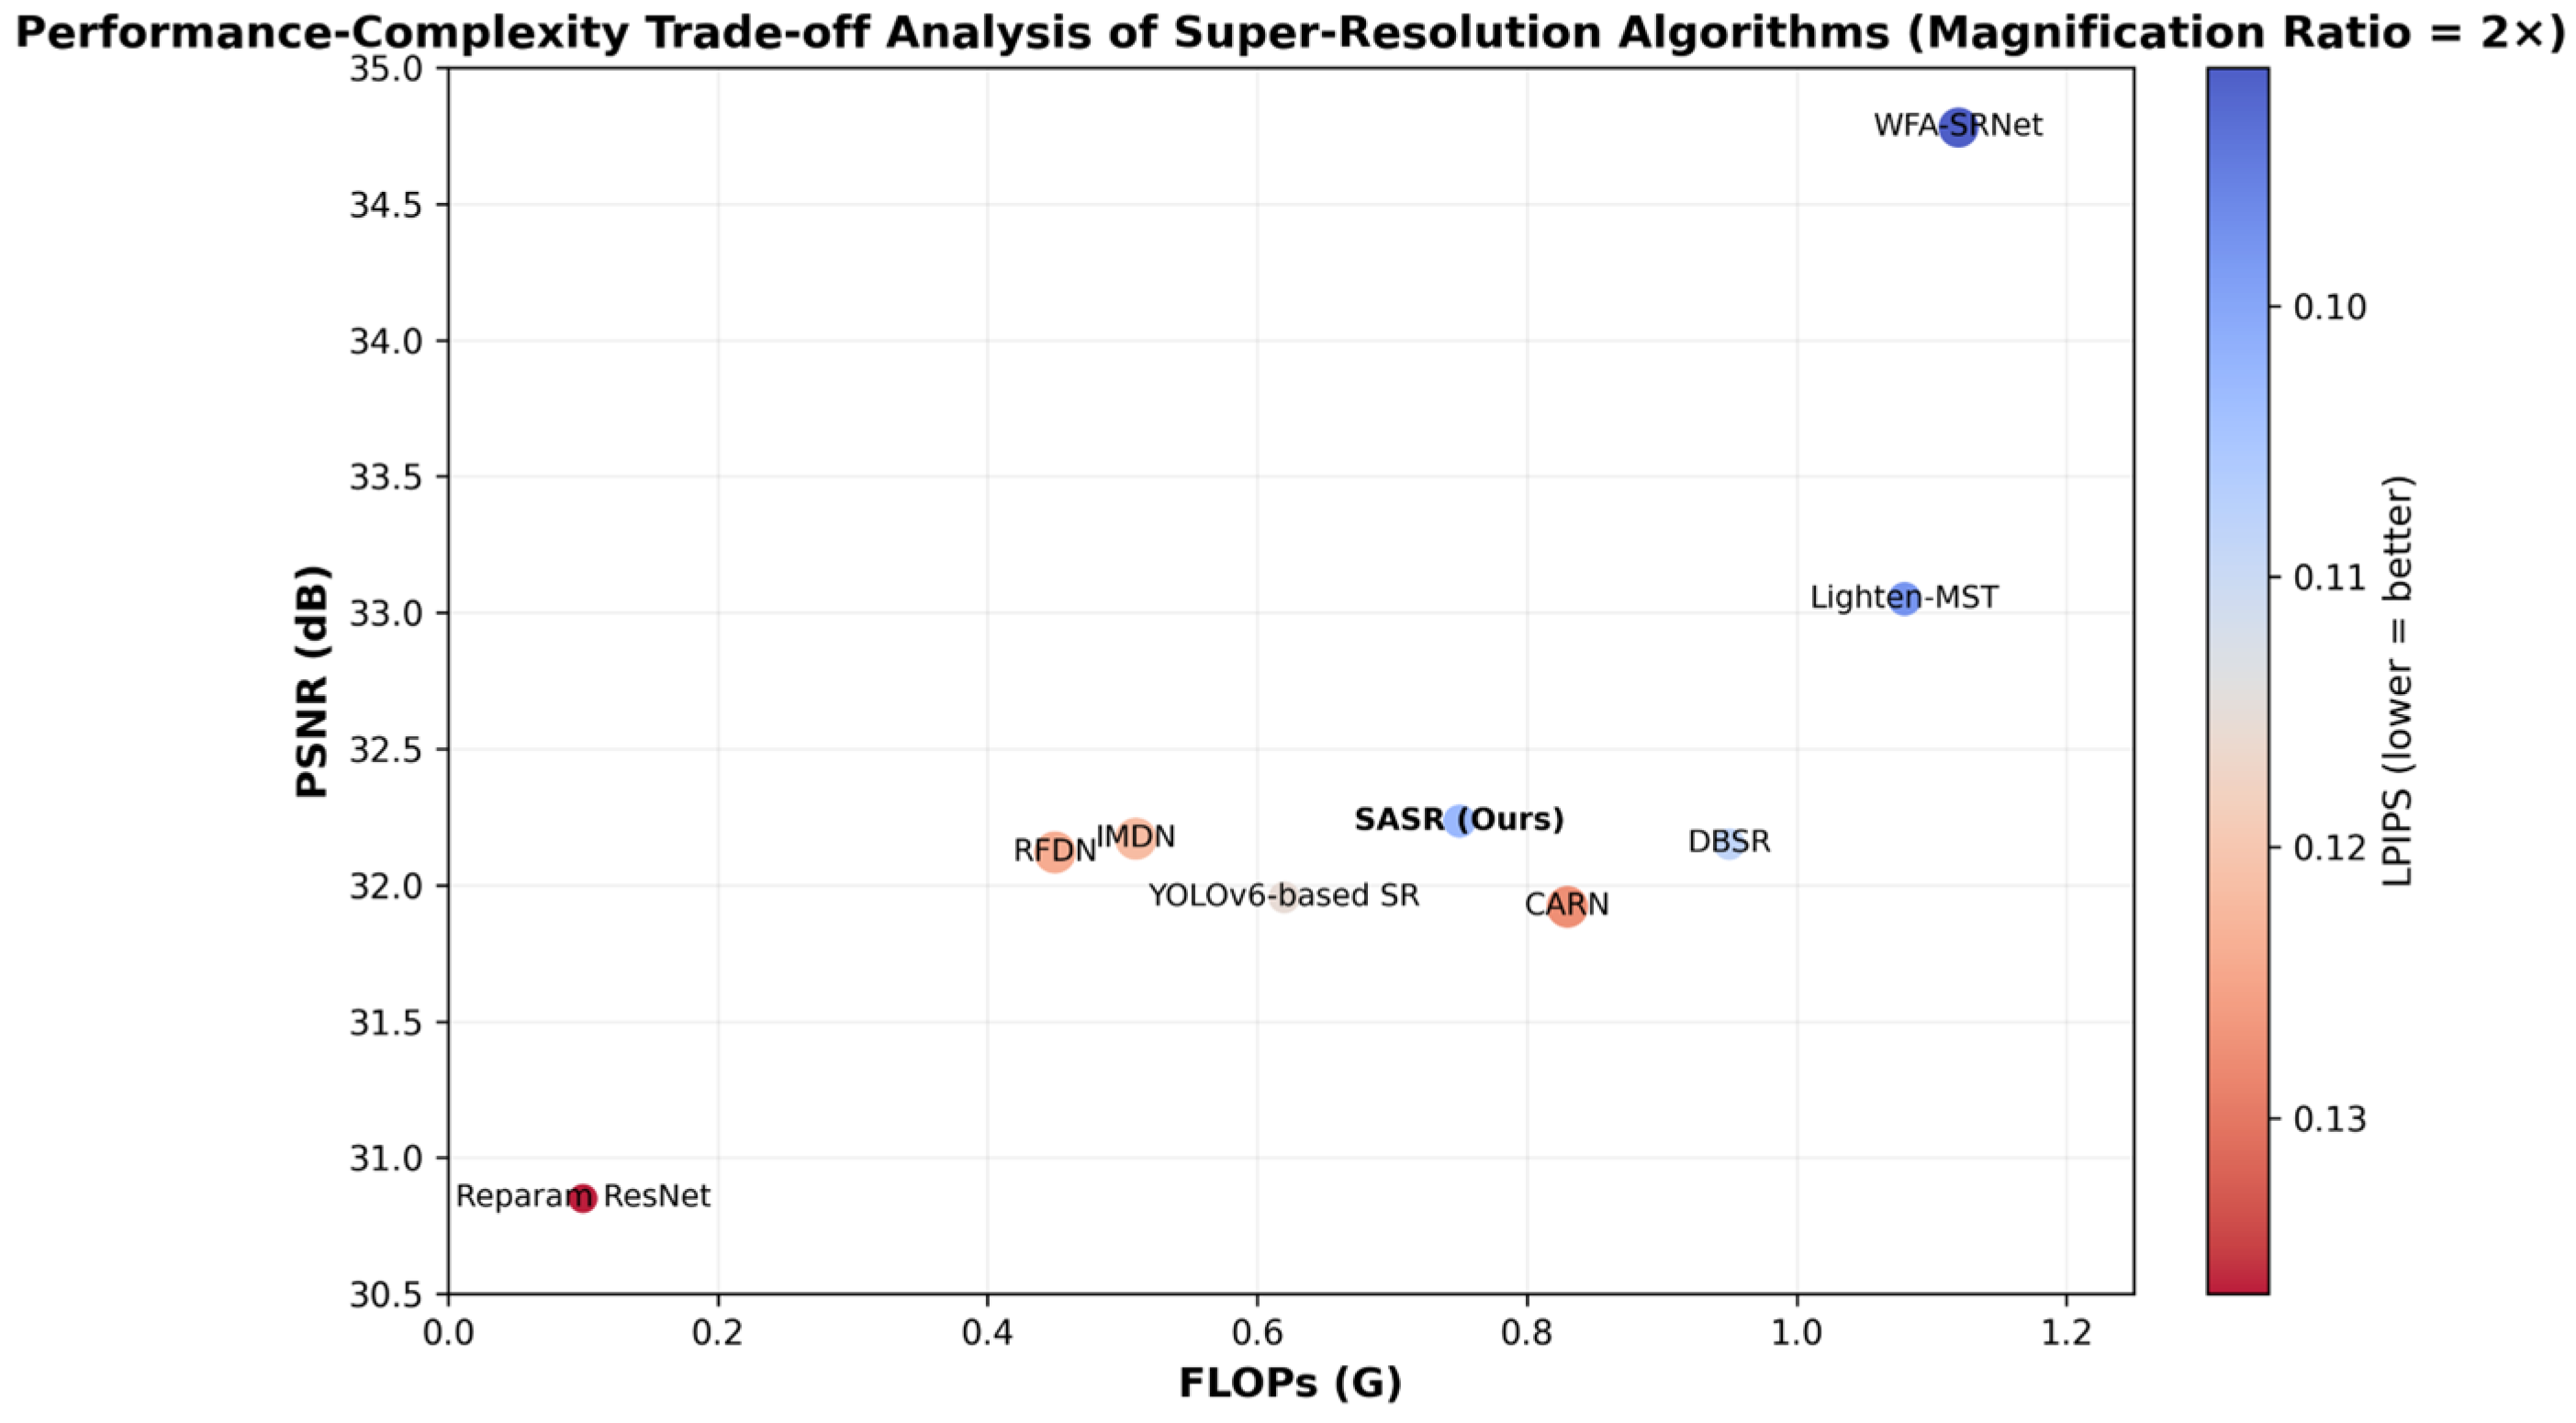
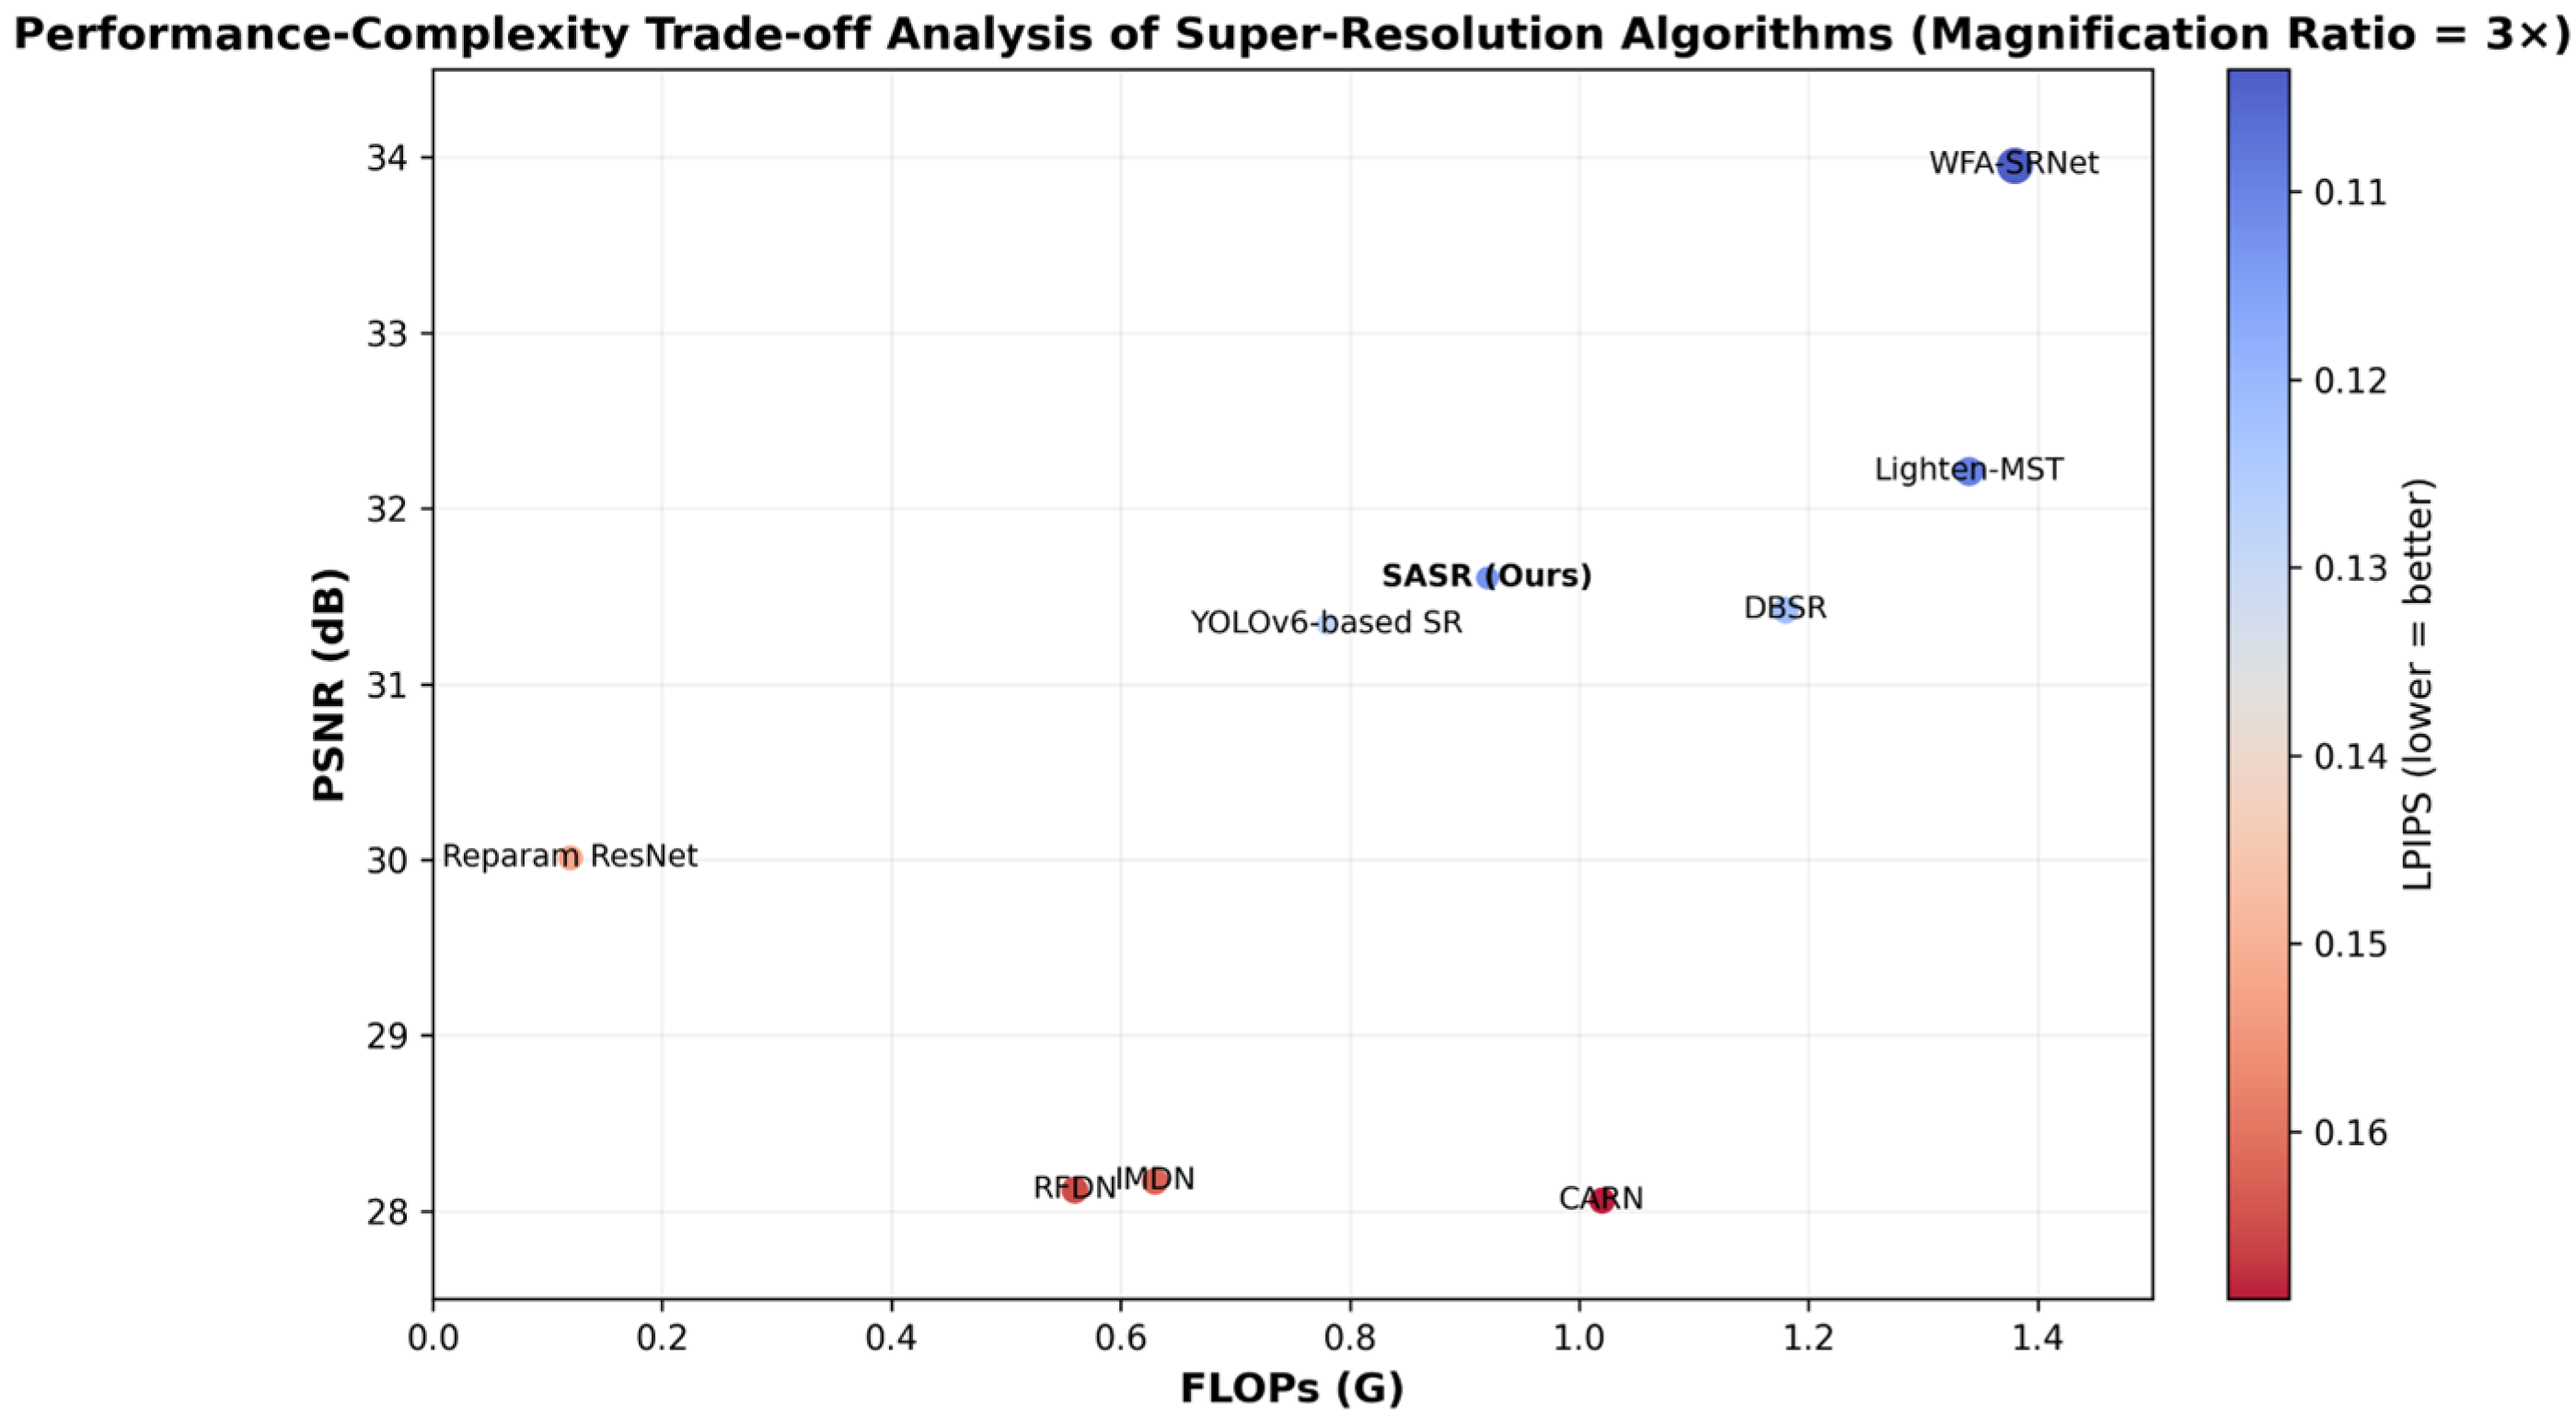
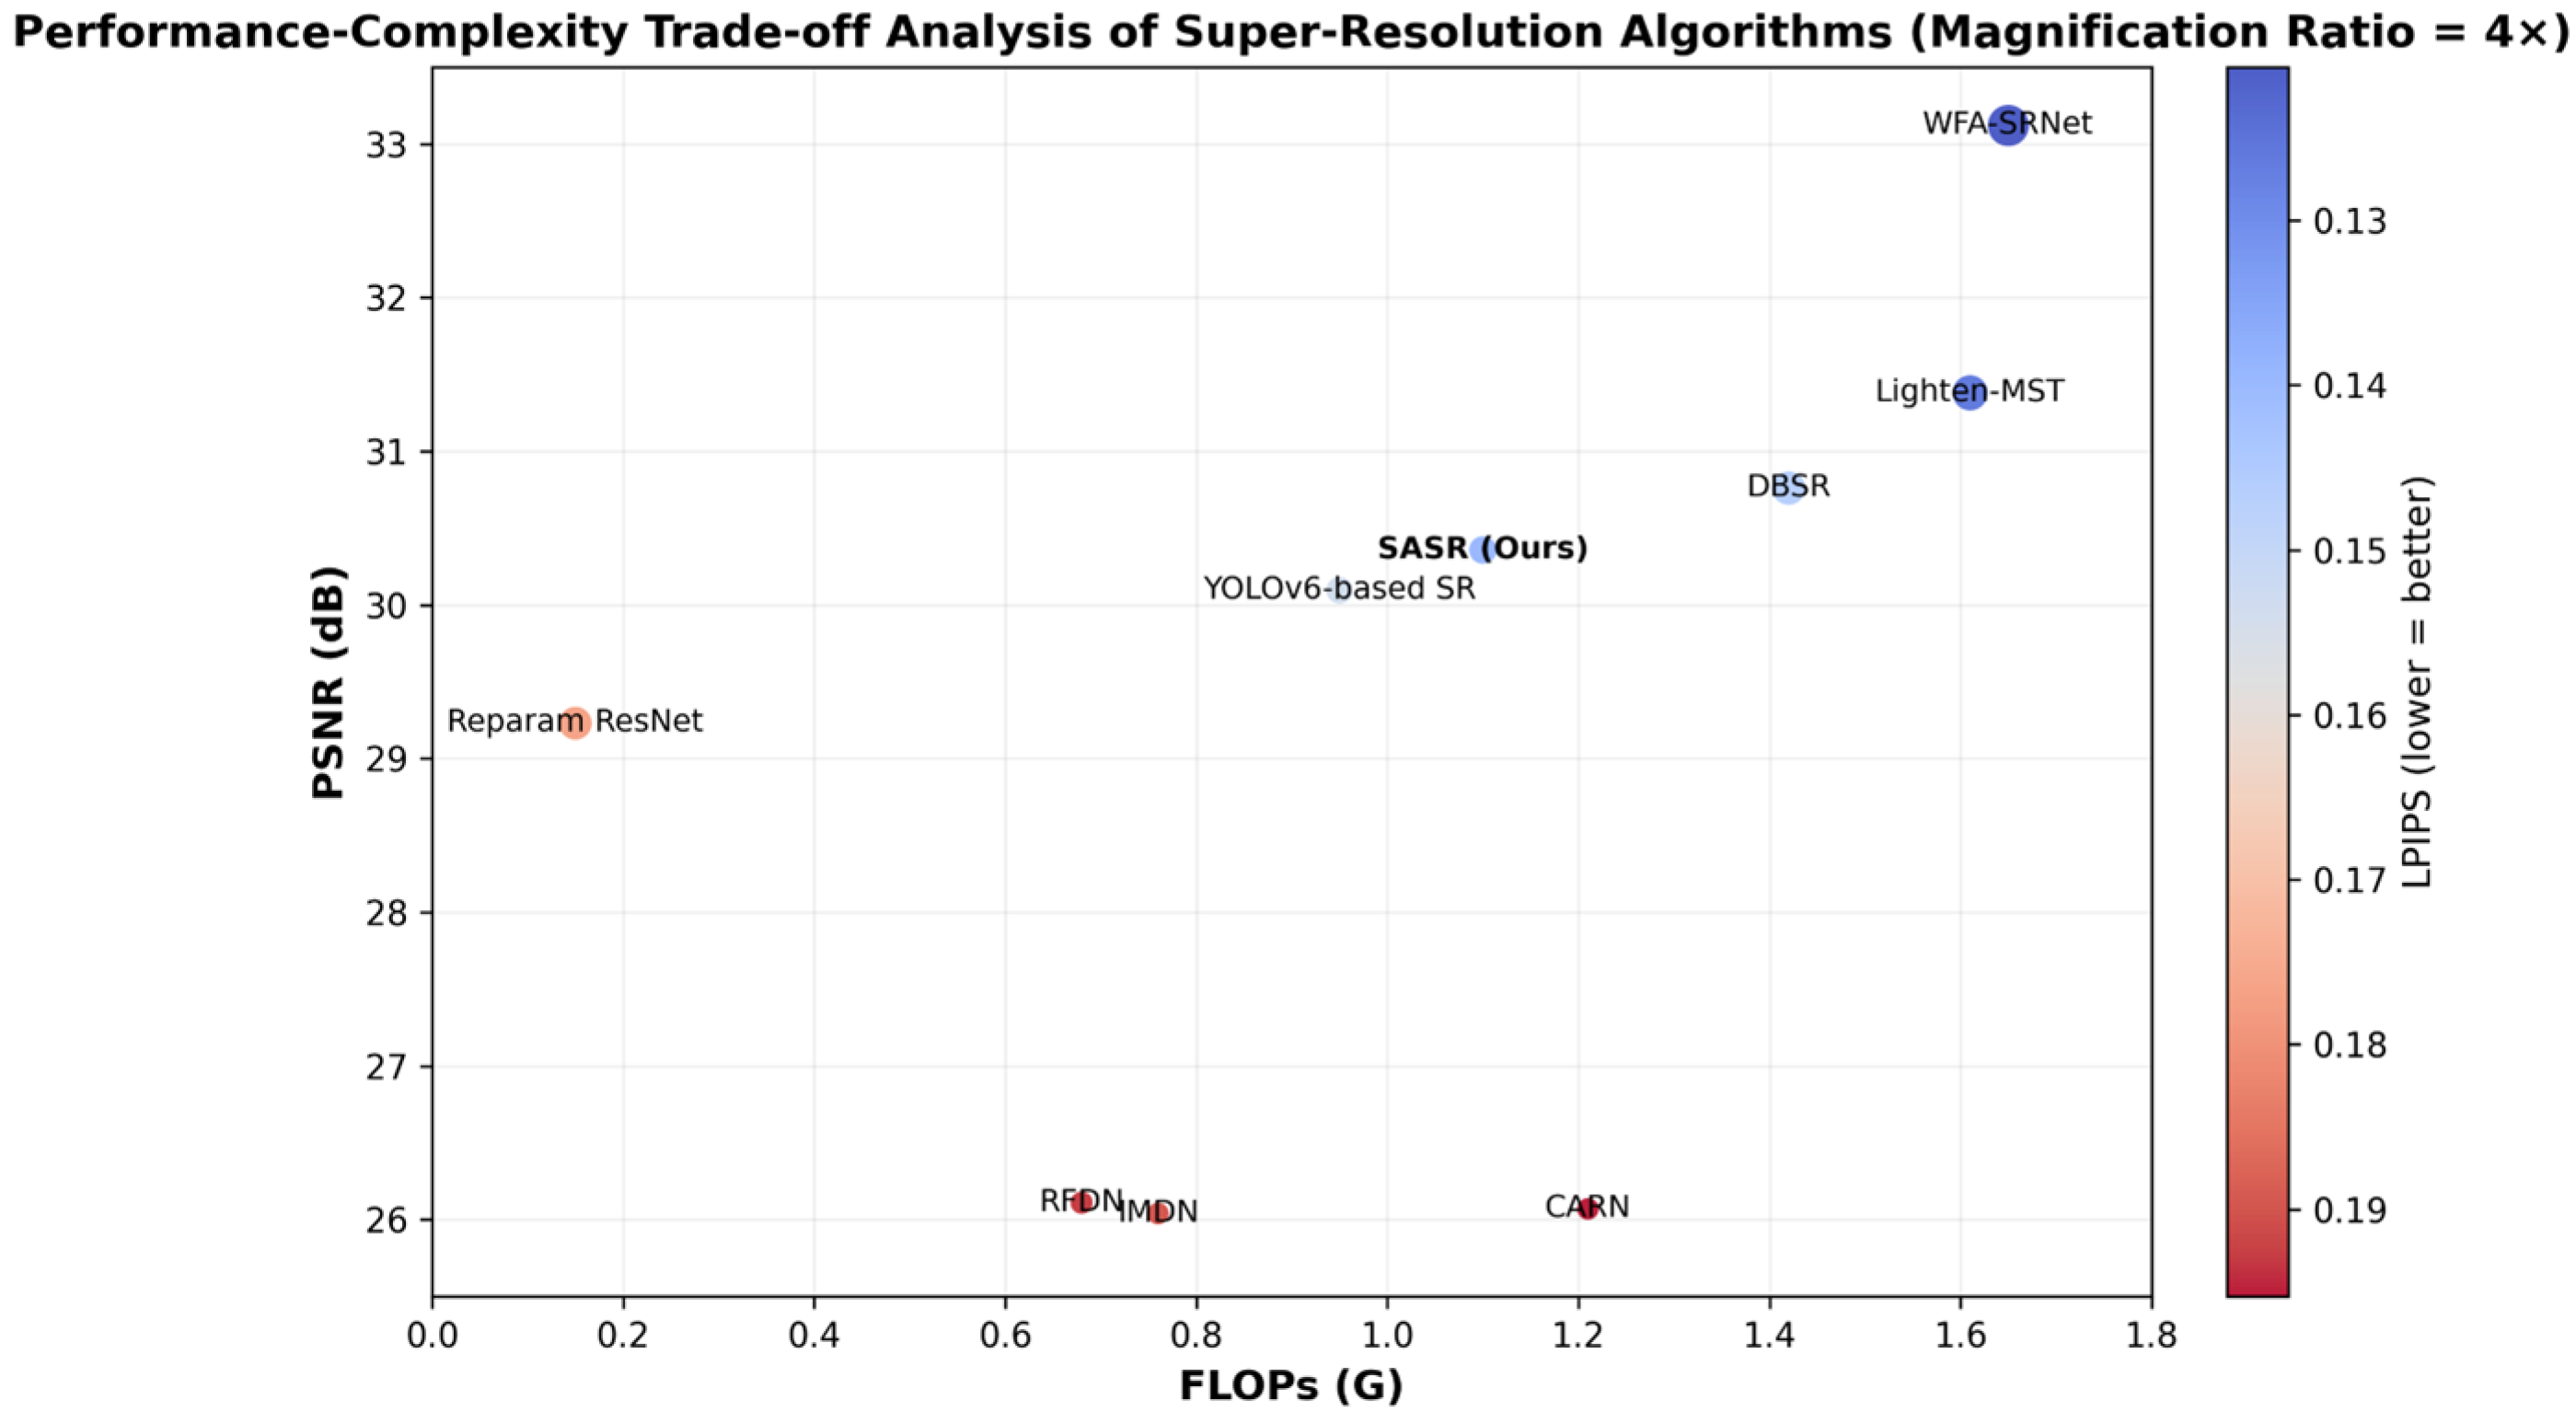
| Method | Publication Year | Magnification | PSNR (dB) | SSIM | Parameters (K) | FLOPs (G) | LIPIPS | NIQE | Time (s) |
|---|---|---|---|---|---|---|---|---|---|
| SASR (Ours) | 2026 | 2× | 32.2346 | 0.8791 | 980 | 0.75 | 0.1028 | 4.8625 | 0.4583 |
| 3× | 31.6040 | 0.8376 | 0.92 | 0.1126 | 5.1247 | 0.6044 | |||
| 4× | 30.3574 | 0.8049 | 1.10 | 0.1399 | 5.4863 | 0.7690 | |||
| Lightweight YOLOv6-based SR | / | 2× | 31.9547 | 0.8726 | 700 | 0.62 | 0.1153 | 5.2174 | 0.4361 |
| 3× | 31.3401 | 0.8337 | 0.78 | 0.1287 | 5.5392 | 0.5660 | |||
| 4× | 30.0952 | 0.8011 | 0.95 | 0.1542 | 5.9136 | 0.6975 | |||
| Re-parameterised Lightweight Residual Feature Network | 2025 | 2× | 30.85 | 0.8612 | 539 | 0.10 | 0.1365 | 5.7428 | 0.008 |
| 3× | 30.01 | 0.8449 | 0.12 | 0.1518 | 6.0571 | 0.010 | |||
| 4× | 29.23 | 0.8275 | 0.15 | 0.1764 | 6.4259 | 0.013 | |||
| Dual-Branch Super-Resolution (DBSR) | 2025 | 2× | 32.15 | 0.8732 | 1200 | 0.95 | 0.1085 | 5.0136 | 0.48 |
| 3× | 31.42 | 0.8518 | 1.18 | 0.1214 | 5.3482 | 0.62 | |||
| 4× | 30.76 | 0.8305 | 1.42 | 0.1468 | 5.6945 | 0.75 | |||
| WFA-SRNet | 2025 | 2× | 34.78 | 0.9165 | 1450 | 1.12 | 0.0912 | 4.5317 | 0.65 |
| 3× | 33.95 | 0.8942 | 1.38 | 0.1035 | 4.7862 | 0.81 | |||
| 4× | 33.12 | 0.8718 | 1.65 | 0.1207 | 5.0493 | 0.98 | |||
| Lighten-MST | 2025 | 2× | 33.05 | 0.8821 | 2060 | 1.08 | 0.0976 | 4.6825 | 0.58 |
| 3× | 32.21 | 0.8607 | 1.34 | 0.1093 | 4.9371 | 0.73 | |||
| 4× | 31.38 | 0.8392 | 1.61 | 0.1265 | 5.2748 | 0.89 | |||
| RFDN | 2020 | 2× | 32.12 | 0.9278 | 541 | 0.45 | 0.1241 | 5.3694 | 0.21 |
| 3× | 28.12 | 0.8525 | 0.56 | 0.1653 | 6.1482 | 0.27 | |||
| 4× | 26.11 | 0.7858 | 0.68 | 0.1927 | 6.7935 | 0.33 | |||
| IMDN | 2019 | 2× | 32.17 | 0.9283 | 704 | 0.51 | 0.1218 | 5.2973 | 0.25 |
| 3× | 28.17 | 0.8519 | 0.63 | 0.1624 | 6.0841 | 0.31 | |||
| 4× | 26.04 | 0.7838 | 0.76 | 0.1896 | 6.7258 | 0.38 | |||
| CARN | 2018 | 2× | 31.92 | 0.9256 | 1592 | 0.83 | 0.1275 | 5.4362 | 0.32 |
| 3× | 28.06 | 0.8493 | 1.02 | 0.1689 | 6.2175 | 0.39 | |||
| 4× | 26.07 | 0.7837 | 1.21 | 0.1953 | 6.8649 | 0.46 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Pang, B.; Liu, Y. The Use of an Improved Lightweight Scalable Attention-Guided Super-Resolution Method for Remote Sensing Image Enhancement. Appl. Sci. 2026, 16, 4298. https://doi.org/10.3390/app16094298
Pang B, Liu Y. The Use of an Improved Lightweight Scalable Attention-Guided Super-Resolution Method for Remote Sensing Image Enhancement. Applied Sciences. 2026; 16(9):4298. https://doi.org/10.3390/app16094298
Chicago/Turabian StylePang, Boyu, and Yinnian Liu. 2026. "The Use of an Improved Lightweight Scalable Attention-Guided Super-Resolution Method for Remote Sensing Image Enhancement" Applied Sciences 16, no. 9: 4298. https://doi.org/10.3390/app16094298
APA StylePang, B., & Liu, Y. (2026). The Use of an Improved Lightweight Scalable Attention-Guided Super-Resolution Method for Remote Sensing Image Enhancement. Applied Sciences, 16(9), 4298. https://doi.org/10.3390/app16094298