


Abstract
Requirements Engineering and Management (REM) tools play a significant role in ensuring project compliance and efficiency. Automotive engineering must comply with regulatory standards, requiring detailed documentation, rigorous testing, and solid traceability. Despite their importance, REM tools are underexplored from the usability and user experience perspective (UX), even though poor usability can hinder development workflows across stakeholder teams. This study presents a case study of heuristic usability evaluation of IBM DOORS Next Generation, conducted with expert evaluators, using Nielsen’s 10 Usability Heuristics as an evaluation framework. The identified issues were analyzed in terms of impacted heuristics and severity ratings. Additionally, we underwent a Large Language Model (LLM)-based heuristic evaluation, using ChatGPT-5, prompted with the same heuristic set and static screenshots. The LLM detected several issues overlapping with human findings (32%), as well as new ones (23%); therefore, 55% of its outputs are considered valid and 45% are unconfirmed. This highlights both the potential and limitations of AI-driven usability assessment. Overall, the findings underscore the usability challenges of REM tools and suggest that LLMs may serve as complementary evaluators, accelerating early-stage heuristic inspections in safety-critical engineering environments.
1. Introduction
The automotive industry continuously faces challenges in the pursuit of full autonomy, alternative propulsion solutions, and permanent interconnectivity to the infrastructure [1]. This pursuit has triggered a chain reaction inside the development cycle and processes used [2].
Requirements management (RM) plays a vital role in assisting employees as various stakeholders engaged in automotive development, offering workflows and instruments in order to facilitate the product features definition. Requirements Engineering (RE) focuses on identifying the functionalities of a system rather than its operational methods. The fast-evolving business landscapes have posed challenges to conventional RE principles, marked by a notable shift in organizational attitudes towards embracing rather than resisting changes. As requirements frequently change, adapting to these alterations is very important for project success [2,3].
The RE and RM activities take place in environments like Requirements Engineering and Management (REM) tools, such as IBM Rational DOORS (https://www.ibm.com/docs/en/engineering-lifecycle-management-suite/doors (accessed on 25 September 2025)), DOORS Next Generation [4] (DNG), Polarion [5], and Jama [6], which are designed to support activities such as requirements specification, linkage and traceability, baselining, and review and validation [4,5,6,7].
Despite their central role, REM tools remain underexamined from a usability perspective. Automotive development must also comply with regulatory standards such as Functional Safety standard ISO 26262 [8] and Automotive Spice (ASPICE) [9], which demand rigor in primary RE workflows related to traceability, validation, and documentation [10,11,12]. These standards and processes make REM tools fundamental. In this context, an efficient use of REM tools is affected by their usability.
Defined by ISO 9241-11 [13], usability is the extent to which a system, service or a product can be used by users to reach specific goals in an effective, efficient, and satisfied way, in a specific context. Aside this, the concept of user experience (UX) is related to the perceptions and overall satisfaction of users when interacting with a product [14,15,16,17]. REM tools should provide an intuitive interface to the stakeholders using it (managers, developers, testers, quality specialists), an interface for navigating, editing, and tracking requirements with minimized errors and reduced cognitive load.
A stable method to assess usability is heuristic evaluation (HE), where expert evaluators identify interface problems based on principles, called heuristics [18]. Jacob Nielsen’s 10 usability heuristics (NH) are widely recognized and defined as basic usability guidelines for interaction design [19].
However, REM tools remain underexamined from a usability perspective, especially in automotive contexts. No prior study, to our knowledge, has compared human heuristic evaluations with an AI-based approach for such tools.
This study presents a case study of HE for DNG(version 7.0.3) as the selected REM tool, using NH, conducted with five evaluators who identified issues after tool interactions while trying to perform six tasks. The identified issues are tied to the impacted heuristic and have severity ratings assigned. The issues are further analyzed quantitatively and qualitatively.
Recently, Large Language Models (LLMs) such as ChatGPT-4 [20], ChatGPT-5 [21], and Gemini 3.0 [22] demonstrated strong capabilities in tasks requiring reasoning and interpretation of amounts of information [20,21]. Using the proper prompt techniques, LLMs proved to generate structured and logical outputs [23]. Having this in mind, we also conducted an exploratory research focused on LLM-based HE of the same tool, using ChatGPT-5 as LLM, the NH set, and prompted screenshots [19,21]. Understanding whether LLMs can support heuristic evaluations could reduce evaluation effort and accelerate usability assessments in industry.
Our primary contributions are outlined below:
- We present an HE on DNG REM tool, using NH with five human evaluators across six specific workflows, revealing key usability issues and their severities;
- We present a novel LLM-based HE using ChatGPT-5 as evaluator, using the same heuristic set, to investigate the feasibility of automated usability assessment;
- We compare the results from the LLM-based HE with the human-based evaluation findings, highlighting overlaps, differences, and implications;
Despite the growing complexity of REM tools, few studies have examined their usability from both human and AI-assisted perspectives. Traditional heuristic evaluations rely exclusively on expert judgment, which may be time-consuming and subjective. However, the potential and limitations of LLMs in usability assessment remain underexplored. To the best of our knowledge, this is the first research at the intersection of REM tools used in automotive and usability/UX, in the context of HE as part of usability evaluation.
This study provides initial evidence that AI (LLMs) can assist in usability evaluations of complex engineering tools, potentially reducing the effort required for such assessments. The findings could inform the development of more efficient usability evaluation processes in the automotive industry. To highlight the benefits this study brings we have formulated the following research questions we aim to answer:
- RQ1: What are the main usability challenges identified in DNG through expert heuristic evaluation?
- RQ2: How does an LLM-based evaluation compare to expert findings in terms of coverage, accuracy, and relevance?
- RQ3: What are the implications of combining human and AI evaluators for future usability studies of engineering tools?
The paper is organized as follows: Section 1 introduces the research and highlights its significance in the domain. In Section 2, we conduct a literature review to present the context of the presented work. In Section 3, we present and explain the methodologies for the HEs, while in Section 4 we discuss the results. In Section 5, we highlight the key findings and present conclusions and future work.
2. Literature Review
2.1. Automotive Requirements Engineering
Automotive industry advanced from mechanical-based systems to software-driven platforms, with complex electrical and electronic components integrated, advanced driver assistance systems, or electric powertrains [24,25]. In parallel, the use of LLMs in automotive engineering has grown rapidly across multiple application areas, including Requirements Engineering, testing, validation, and compliance support [12,26,27,28]. This increasing adoption has also raised concerns related to resource-constrained and safety-critical deployment, motivating recent research into lightweight and quantized LLM solutions suitable for industrial environments [29,30].
RE represents the backbone of successful automotive product development, modern vehicles depending on millions of lines of code, and allocated embedded systems. RE establishes that customers’ needs are transformed into accurate, traceable, and verifiable requirements responsible for guiding the design, implementation, and validation phases across the entire development lifecycle [31].
Several processes used in automotive serve as a base for product lifecycle management, leading the collaborative teams from concept to design, implementation, validation, production, and maintenance [32]. There are several critical demands of automotive product development, which are linked to safety-critical functions such as braking, steering, autonomous driving; regulatory compliance with functional safety standard ISO 26262; UNECE WP.29 vehicle regulations [33]; globally distributed collaborating teams across disciplines of software, mechanical, hardware, compliance, or safety roles [11,33]. To accomplish all these, the industry follows process models that organize work into distinct phases with proper responsibilities, deliverables, and milestones.
One process model widely used in safety-critical system development is the V-model, which formalizes the sequence of development phases, illustrating the left side for decomposition of requirements, from stakeholder to unit level and the right side for corresponding validation of each decomposed level [34]. Using the V-model ensures traceability and supports compliance with ISO 26262 and ASPICE standards. In this context, ISO 26262 prescribes ASIL requirements traceability and hazard analysis, while ASPICE evaluates the process maturity, with accent on requirements elicitation, specification, change management, and validation [35,36]. These workflows are managed through specialized REM tools, supporting specification, traceability, validation, and continuous maintenance of requirements during the entire lifecycle.
2.2. Requirements Engineering and Management Tools
REM tools are dedicated software platforms intended to support the systematic handling of requirements during the development lifecycle. The tools are essential due to the increased number of requirements and their complexity. The rigorosity for activities like bidirectional traceability, change impact analysis, and verification planning is also driven by the use of functional safety standard ISO 26262, ASPICE and cybersecurity standards like ISO/SAE 21434 [11,36,37].
The current REM tool landscape provides professional tools designed for large-scale industrial use like DNG, Jama Connect, Siemens Polarion. The core functionalities of REM tools are as follows:
- Authoring and classification, allowing specification and formalization of requirements, supporting users to assign specific attributes such as status, priority, or safety/security classifications [38].
- Traceability and linkage, that refer to workflows implying creation of links horizontally, between requirements from different levels (system, component, detailed design) and vertically, between requirements and validation artifacts [39].
- Change and configuration management, which refer to workflows for change requests handling, analysis of impact, and management of configurations. For instance, DNG supports streams, change sets, and component management [40].
- Version control and baseline management, which ensure tracking different versions of the artifacts during the development lifecycle. Baselines represent references in time, taken for specific versions of the requirements/requirements-related artifacts [41].
- Collaboration and access control refer to simultaneous editing, real-time commenting, and user tagging, aiming to improve alignment across distributed collaborative teams.
- Integration capabilities refer to the ecosystem of platforms integrated to the REM tool, meant to ensure the complete traceability. For instance, validation tools from the same tool suite (IBM ETM (https://www.ibm.com/products/ibm-engineering-test-management (accessed on 20 November 2025))), model-based systems engineering (Rhapsody (https://www.ibm.com/products/engineering-rhapsody (accessed on 20 November 2025))) [42].
The main features presented above demonstrate the complexity of REM tools, combining requirements specification, traceability, configuration management, collaboration, and integration capabilities into one environment. Complex workflows and interconnected functionalities can introduce usability challenges among the users, becoming overwhelming and reducing the tools’ use efficiency. The next subsection focuses on reviewing literature relevant for usability and UX concepts, together with HE methodology.
2.3. Usability Heuristic Evaluation
Defined by [14], UX represents the overall perception of a person interacting with a product, service, or system. In the meantime, usability accentuates the quality of interaction between users and products, with a focus on aspects such as clarity, error prevention, and efficiency [13].
Merging the two concepts, while usability prioritizes efficiency, effectiveness and satisfaction in achieving specific goals, UX incorporates a wider range of emotional, cognitive, and contextual factors that model the entire interaction.
Usability evaluation consists of a standardized process to assess how efficiently, effectively, and satisfactorily a system or product allows users to achieve their goals [43]. Usability evaluation methods can be grouped into three main categories: empirical methods or user-based testing, inspection methods or expert-based analysis, and analytical methods [43].
The primary focus of the paper is on the HE, as part of inspection methods or expert-based analysis. HE is a widely adopted method, where a group of usability specialists reviews the interface based on a set of established usability principles called heuristics. Over the years, several heuristic frameworks have been developed as guidelines to usability evaluation for various systems and products. NH are the most popular and widely adopted heuristics, usually chosen for their general applicability [19]. Other notable heuristic sets from the literature are Shneiderman’s Eight Golden Rules, Bastien-Scapin’s Ergonomic Criteria, or Gerhardt-Powals’ Cognitive Engineering Principles [44,45,46].
NH, presented in Table 1, were introduced by Jacob Nielsen in 1994 and cover generic interaction principles, offering a base approach for most interfaces’ evaluations [19].
Table 1.
Jacob Nielsen’s 10 Usability Heuristics.
Usually, a HE implies four phases: scope and context definition (clarifying on which part of the product needs to be evaluated), choosing the heuristics (either generic principles or domain heuristics), the individual evaluations (the evaluation itself) and debriefing (collection of all outputs from the evaluators) [47].
During a HE session, a group of UX expert evaluators (typically 3–5 evaluators) are involved, individually assessing the product or system after a task-based interaction with it. Evaluators identify issues and associate them with the impacted heuristic. The issues are rated by severity, using Likert scale of 0–4, and suggested improvements are also noted by the evaluators [18,48].
In the context of the current experiment, five evaluators were involved to assess the REM tool selected for the study, DNG, using NH. The evaluators performed six tasks covering usual RE activities in the tool and classified the identified issues on the given heuristics. The results were analyzed by the authors from quantitative and qualitative perspectives, referring to the attached heuristics of the issues and to severity ratings assigned by the evaluators.
2.4. Large Language Models, Prompt Engineering
LLMs are artificial intelligence (AI) systems trained on large amounts of data to generate, interact, and interpret using human language [49].
Prompt engineering refers to the process of creating inputs as prompts to guide the responses of LLMs in an efficient way. Prompts are in fact the interface between the users and LLMs, and the way a question or task is formulated impacts the correctness and the depth of the output of a model [23]. Examples of LLMs such as ChatGPT-5 or Gemini are trained to interpret and generate responses based on the given context, so they are directly impacted by the detailed input given by users.
In the context of this experiment, ChatGPT-5 was the selected LLM for the LLM-based HE exploratory study. We used a mixture of chain-of-thought and role-prompting techniques and structured output formatting [50]. The LLM was prompted with its UX evaluator role, evaluation instructions, the tasks, the heuristic set to be used, and static screenshots from DNG relevant for each task.
The LLM-based evaluation results were analyzed in terms of quantity and quality of responses, severities assigned, and suggested improvements. The results were also analyzed in comparison with the human-based evaluation results.
2.5. Related Work
Prior research of the authors motivated exploring the HE method in the context of automotive REM tools. The authors conducted studies on the usability evaluation of the DNG REM tool, using user testing sessions.
One notable research referred to a case study on tool transitioning from DOORS to DNG, within an automotive company department [51]. Several issues were identified including inefficient filtering mechanisms, hidden navigation features, and a cluttered interface due to multiple link types. Having previous experience with DOORS demonstrated to be a double-edged sword: while it helped some users in interacting with DNG, it also confused other participants, due to several conceptual differences in DNG. Usability SUS scores [52] revealed a lower score of DNG in comparison with DOORS, while both tools were perceived similar in functionalities but different from the design point of view [53].
Another relevant study of the authors focused on assessing the usability of collaboration features of DNG, recently introduced as the new tool used for REM in an automotive company [54]. Ten participants were involved for user testing sessions and focus groups, and SUS surveys were also applied [53,55]. Usability challenges were identified for functionality areas of baseline comparison, comment visibility, and notification and tagging features of DNG. Appreciated areas were related to multimodal commenting and artifact history tracking. The SUS score was 69.25, rated as Good, but underscores needed improvements [54].
Using established heuristic sets such as NH, several studies applied heuristic usability evaluations to different products such as web platforms and mobile applications from different domains.
This relevant paper [56] presents the HE of NEUST, an online enrolment system of a state university. Their applied methodology was different from the actual HE procedure, involving users of the platform who answered a ten items survey, being asked to rate each criterion corresponding to each heuristic from NH. The usability issues found, associated with each impacted heuristic, were intended to be used for future improvements in the system interface design.
Another relevant study on HE applicability refers to a usability evaluation of the KAI Access mobile application, used in Indonesia for ticketing cancelations and e-boarding train passes [57]. The evaluation was realized based on NH principles and a lostness formula was computed for the analysis of results and performance of a task analysis. The results showed that 6 out of 10 heuristics were violated and associated with major and minor severity ratings, those related to minimization of users’ memory load, system feedback, error prevention, help and documentation, consistency, and existing shortcuts.
Recent literature reveals an increased interest in involving LLMs in usability studies. One very recent research presents a comparative study on usability issues identification in HE, using ChatGPT-4o [58] as LLM [59]. The authors compare a HE performed using ChatGPT-4o with an evaluation using human experts, based on NH. During their evaluation using the LLM, the authors prompted the LLM with screenshots from a web-based system. Some of the key findings emphasize that ChatGPT-4o identified only 21% of the issues found by humans but 27 new issues. Also, 24% of the issues were classified as false positive responses. The authors concluded that LLMs demonstrate potential as assistants to human evaluators, especially for visually impacted heuristics, but cannot replace humans due to hallucinations caused by gaps in understanding interaction dynamics [59].
Existing studies in the literature motivate the exploration of HE in the context of REM tools, where usability has a high impact on automotive collaboration, traceability, or compliance. Applying HE in this domain may open directions to explore adaptation or refinements of generic heuristics, to facilitate the assessments of usability for domain-specific platforms.
3. Methodology
The current paper focuses on the HE of a REM tool widely used in automotive, DNG: one main HE, using five evaluators and one exploratory HE, using ChatGPT-5 as LLM in the role of the heuristic evaluator.
During this section, the HE methodologies are described, and the findings will be further analyzed from quantitative and qualitative perspectives.
3.1. Heuristic Evaluation Environment
A dedicated test workspace was prepared in DNG and access to the tool was possible due to a valid corporate license, with the approval of an automotive company department, where the tool is used.
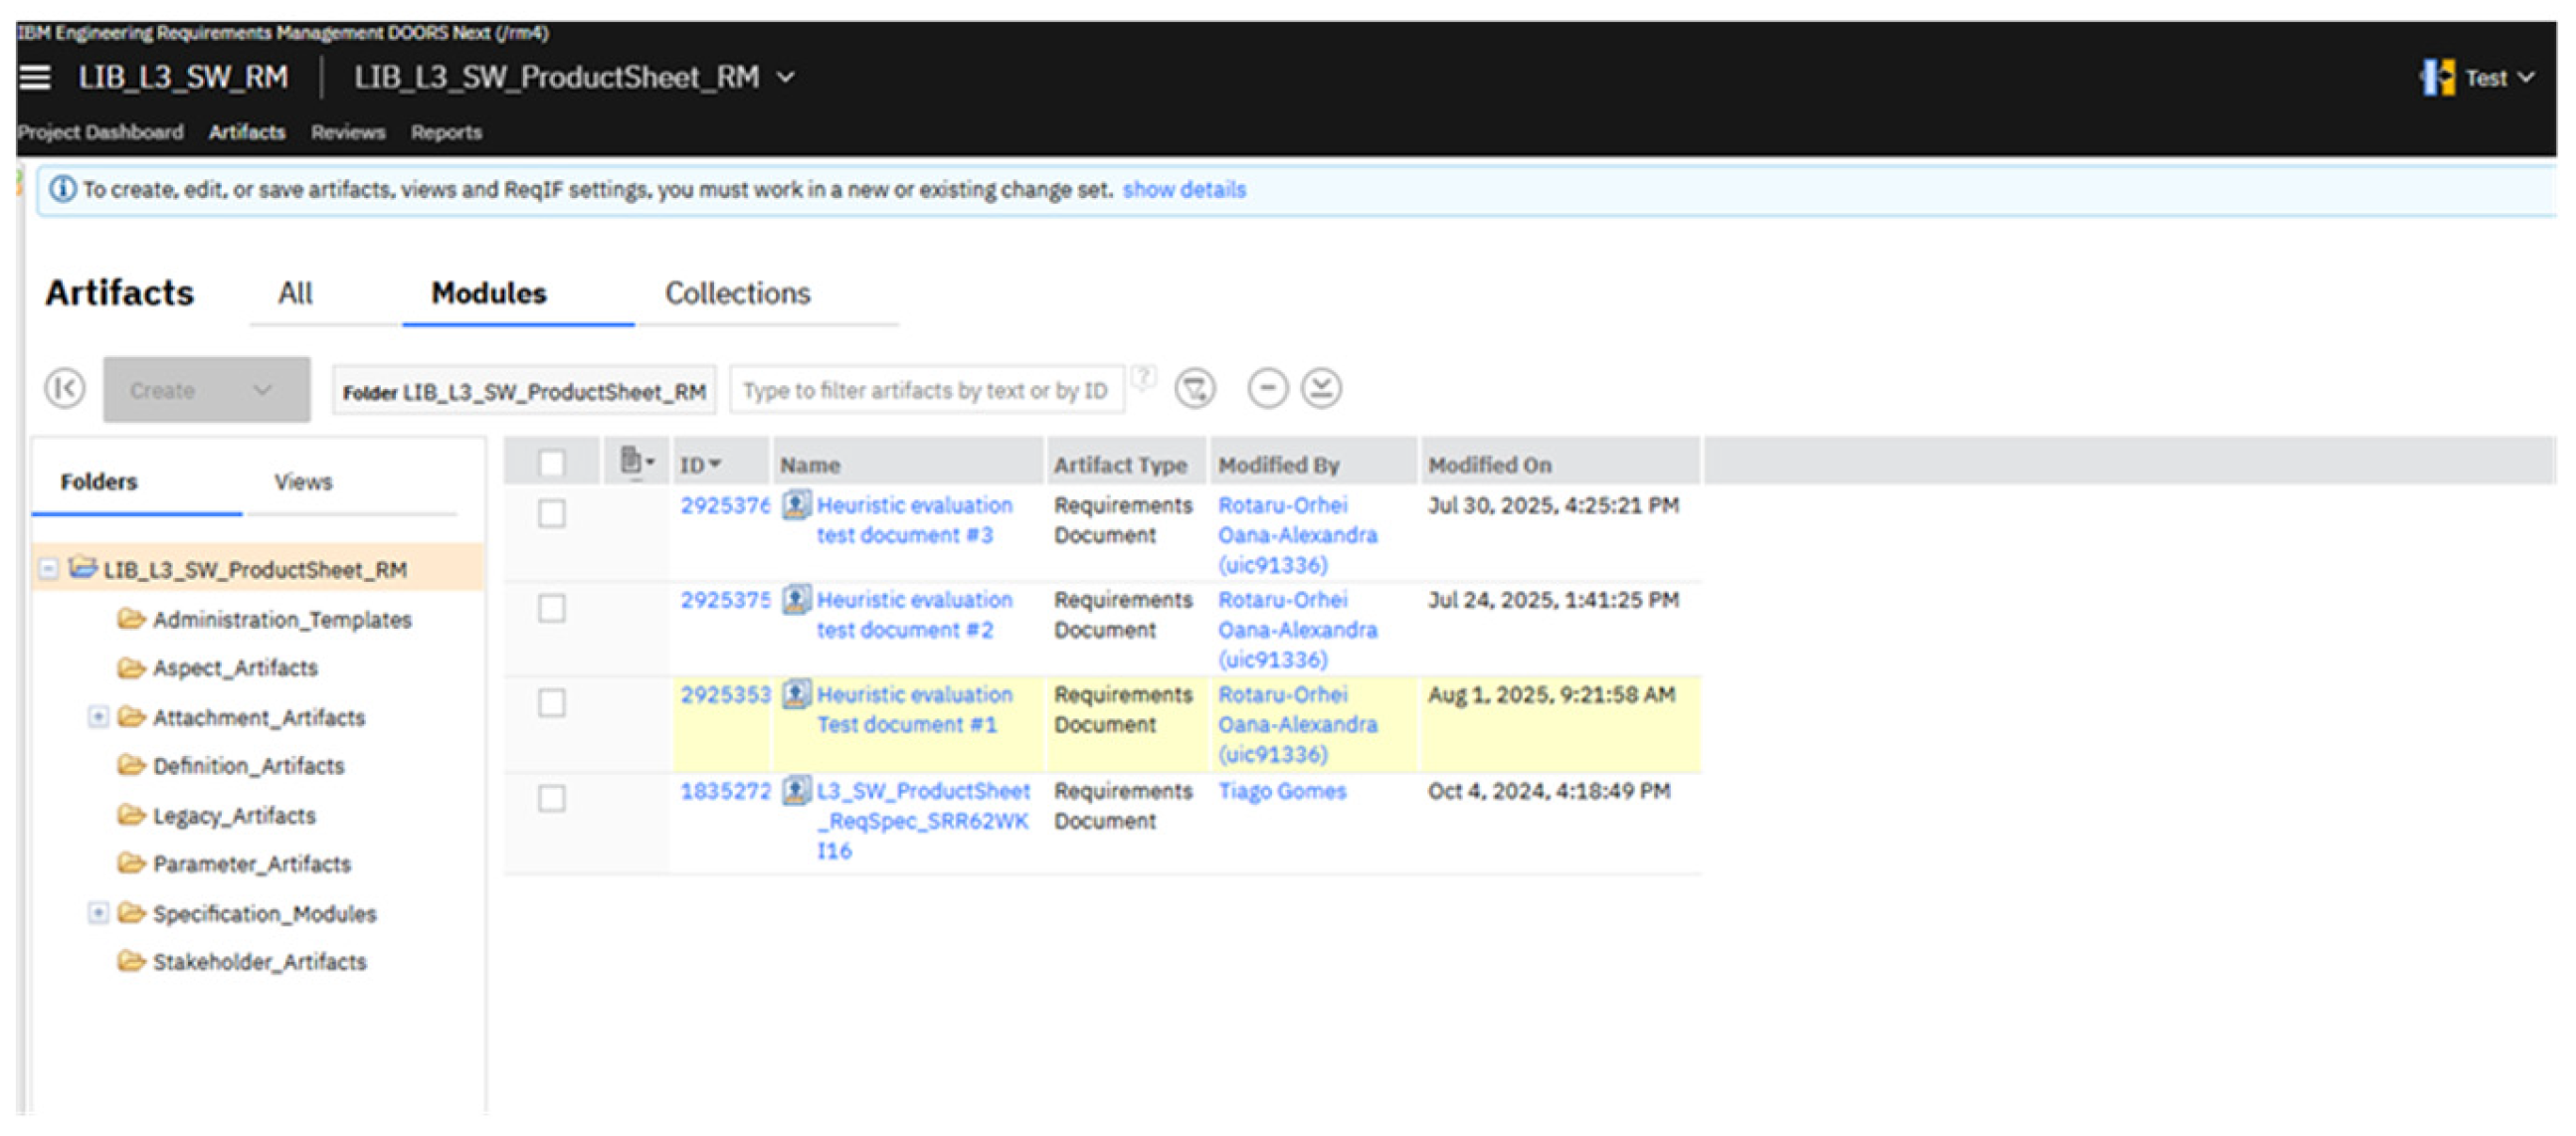
As we can observe in Figure 1, three requirements’ modules were created inside a “Test” local configuration created for the evaluation. The requirements modules are named: “Heuristic evaluation test document #1”, “Heuristic evaluation test document #2”, and “Heuristic evaluation test document #3”. Each module contained several requirements, named using structured IDs such as 1.1, 2.1, 3.2.
Figure 1.
Test workspace in DNG used for HE.
The naming of the created modules and requirements artifacts were chosen to reflect the realistic RE concepts and simplify the evaluators’ understanding on the specific.
The artifacts were pre-configured to support actions of creation, editing, linking, filtering, review of requirements, and baseline creation and comparison.
The evaluators interacted physically with the tool and the same laptop was used for consistency. One sample from the test workspace is presented in Figure 1.
3.2. Evaluators
Five evaluators were recruited for the HE, assessing DNG using the NH. They were selected based on their relevant experience in usability and interface evaluation.
All evaluators had strong usability and knowledge of Human–Computer Interaction principles and their experience with RE domain was limited to none.
The evaluators had between 3 and 7 years of experience in usability and HCI, including activities such as usability evaluations conducted, interface design, and academic activities related to HCI. Four out of five evaluators are researchers, some currently pursuing PhD degrees and some already holding doctorate degrees in engineering. The evaluators had no experience in RE domain and no practical experience with any REM tool before the study. This profile was selected intentionally, to support a novice heuristic evaluation, with focus on learnability, terminology clarity, discoverability, and cognitive load aspects when interacting with a REM tool.
The evaluators individually performed the evaluation tasks and logged the identified issues based on the heuristic set.
3.3. Materials
The HE materials, snapshot presented in Figure 2a, involved the following:
Figure 2.
(a) Snapshot of HE workbook that evaluators used. (b) Physical setup and one evaluator.
- A printed workbook with NH, where the evaluators logged the issues on each impacted heuristic, assigned a severity rating, and wrote the suggested improvement.
- An induction paper containing the main RE concepts explained, available to be checked when needed during the evaluation.
3.4. Task Design
Six tasks were created for the HE session. The tasks intended to simulate realistic user interactions within a REM tool, covering main RE activities and workflows. Each formulated task included the RE workflow-related action name, a prerequisite state and a described scenario and action, split into steps. The tasks are presented as follows in Table 2.
Table 2.
Task details received by evaluators for HE.
3.5. Evaluation Procedure
The HE sessions were organized independently with each of the five evaluators assessing DNG. Each evaluator received: a laptop with access to DNG test workspace, a printed copy of the task list, and the NH workbook. The setup is presented in Figure 2b.
The human-based HE was intentionally conducted for a novice user inspection, with a focus on characteristics such as learnability, discoverability, cognitive load, or terminology clarity while interacting with a complex REM tool.
The sessions began with an induction, covering the evaluation goal, a high-level description of the tool, and the core RE activities performed in the tool and instructions on how to complete the workbook independently.
The evaluators were instructed to familiarize themselves with the interface before beginning the tasks and to perform the six tasks in the given order. Also, after the completion of each task, the heuristic set should be consulted and the usability issues identified must be noted. For each issue, a severity rating must be assigned by them, the evaluators being instructed to describe the context of the problem and suggest improvements.
In terms of severity ratings, the following scale is used in the experiment: 0—not a usability issue; 1—cosmetic issue; 2—minor usability issue; 3—major usability issue; 4—catastrophic usability issue, blocking the release. During the evaluations, there were no issues rated 0, as the identified usability issues are clearly perceived as at least cosmetic.
All the evaluation sessions were monitored, and the evaluators did not receive any guidance during task execution, for personal authenticity and unbiased usability issues identified.
After the evaluation, each evaluator provided a completed workbook. The collected data was analyzed to compare the usability issues identified using the two evaluation frameworks.
3.6. LLM-Based Heuristic Evaluation Methodology
For the exploratory analysis, the LLM selected was ChatGPT-5, for its latest capabilities. Based on this study [60], ChatGPT-5 has been reported to exceed the capabilities of its predecessor ChatGPT-4.5 in complex tasks, in more advanced chain-of-thought reasoning and multimodal integrating, which may be relevant for interpreting usability scenarios, potentially increasing the reliability of AI-based insights in the context of automotive REM tools UX.
The LLM-based HE was conducted using the ChatGPT-5 web interface, OpenAI and as the platform does not expose a fixed model hashed or build identifier, and the results are reported using the closest available model (ChatGPT-5). The evaluation was performed on 28 August 2025, Europe/Bucharest time.
Given the nature of the HE, the prompt technique selected for this study is a combined approach between role-prompting, chain-of-thought, and a structured output formatting, resulting in a standardized template [50,61,62]. The full prompt used for the LLM-based HE is provided in Appendix A to support reproducibility.
For this exploratory evaluation, one project was created in ChatGPT-5 web interface, named “Heuristic evaluation Nielsen”. The model was run with default generation parameters, namely a temperature of ~0.7, top-p of ~1.0, and a maximum response length of 4096 tokens. The tasks fed to the model were the same tasks used for the human-based evaluation. Each task was prompted individually, together with the standardized template used, as follows.
Role: Assume you are a usability expert evaluating an automotive Requirements Engineering Management tool (IBM DOORS Next Generation) used in the automotive industry, via heuristic evaluation.
Objective: Your task is to identify usability issues according to the following heuristic set, rate their severity with values from 1 to 4 and suggest improvements.
Reasoning approach: Before providing your responses, examine the interface and think of the interaction step-by-step: (1) Observe every given screenshot to understand the entire context. (2) Identify the UI elements, potential workflows, and terminology used. (3) The observations should be compared against the heuristic set given, to identify possible heuristic violations. (4) For every possible issue, think of the reason why it is a problem and how it impacts usability. (5) Assign a severity rating for the identified issue. (6) Think of a potential improvement that can address the issue.
Heuristic Set: enunciated Nielsen heuristics (H1–H10)
Task description: T1–T6
Workspace context: A dedicated Test workspace was created in DNG REM tool for this heuristic evaluation. The workspace contains three requirements’ modules, containing a few requirements artifacts.
Screenshots: inserted relevant screenshots for the task.
Output format: Heuristic violated | Issue Description | Severity (1–4) | Suggested improvement.
Each task, from T1 to T6, was evaluated via a single LLM run, with no response regeneration or multiple runs per task. The model was used with non-zero temperature settings, so the outputs should be considered stochastic, as it reflects a typical real-world LLM usage. A systematic analysis of response stability while running the prompt repeatedly is not in the scope of the current study and it aims to be future work.
The provided screenshots correspond to the same DNG evaluation workspace used during the human HE sessions. The LLM cannot interact with the system and the resulting observations were based on the provided screenshots and task descriptions. The screenshots are shared within the Appendix A, along with the used prompt.
The current procedure used aims to ensure a consistent evaluation and enables comparability with the results obtained from the human evaluators assessment.
3.7. Data Analysis
The current manuscript includes quantitative and qualitative analysis of the results, as the identified issues as described below.
- Quantitative analysis: the data collected through the count of problems per heuristic (which heuristics are the most violated) and the severity ratings distribution per heuristic set.
- Qualitative analysis: the mapping of issues per heuristics resulting in a theme synthesis, each theme representing the heuristic principle; the suggested improvements for the issues and their implications.
3.8. Ethical Considerations
This section summarizes ethical principles that guide the research, ensuring that the research is realized with integrity and respect for participants. In this case, some key aspects are pointed as it follows:
- Informed Consent: Participants are provided clear explanations on the purpose of the study, the voluntary nature of their participation, and their possible choice to withdraw at any time.
- Confidentiality: All responses are confidential. No email addresses, names, or other personal identifiers are required from the participants. The results are reported and interpreted as cumulated findings, to ensure that individual responses cannot be tracked back.
- Use of Data: The collected data are used only for research purposes. The participants are informed on the purpose of the study and their potential contribution to future research on the topic: domain heuristics exploration for REM tools.
4. Findings
4.1. Introduction
This section presents the findings of HE session of DNG. Quantitative and qualitative analysis of HE findings are presented and the LLM-based HE results are presented, focusing on additional insights into the potential and limitations of LLM-based HE vs. human-based HE.
From 30 usability issues, a total of 19 usability problems were identified during the human-based HE of DNG, after merging the duplicates. For the consolidated problems, the severity rating was assigned computing the arithmetic mean of the severity ratings assigned by the evaluators for the identified issue and rounded to the nearest integer. Table 3 presents the impacted heuristic, the issue, severity ratings, and suggested improvements obtained from the HE session.
Table 3.
Usability problems summary identified in human HE. We used the following abbreviations: PID = Problem ID, HID = Heuristic ID, S = Severity.
4.2. Quantitative Findings
The quantitative analysis of the findings focuses on the count of problems per heuristic and the issues severity ratings, underscoring which heuristics are the most violated and which issues are the most severe.
A total of 19 usability problems were identified by all five evaluators during the HE of DNG. As mentioned, the severity ratings assigned ranged from 1 (cosmetic issue) to 4 (catastrophic issue). No issues were rated as 0, which represents the definition for “not a usability issue”.
Figure 3a illustrates the issues count on each heuristic, revealing a balanced dispersion of issues, with the maximum number of three issues reported for H7 (Flexibility and Efficiency of Use). This may indicate that the discoverability of functions and overall efficiency are problematic in DNG, with users struggling to locate features such as review feature tab or baseline creation and comparison. Most of the heuristics had 1–2 issues reported each, suggesting a balanced distribution of issues affecting aspects such as visibility of system feedback (H1), terminology (H2, H4), error prevention mechanisms (H5), memory load (H6), and help and documentation (H10).
Figure 3.
(a) Usability problems distribution with severity rating per heuristic identified by human HE. (b) Severity dispersion across the heuristic set identified by human HE.
Problem Dispersion Rate (), a common measure for HE measures how evenly issues are distributed across heuristics. is presented in Equation (1), where is the total number of heuristics (10 in NH case), the number of problems found using heuristic , and , the mean number of problems per heuristic. The value of 0.54 implies moderate concentration of usability issues in a few heuristics, which can be observed in Figure 3b.
As part of the quantitative analysis of the HE results, a notable part refers to the severity ratings dispersion across the entire heuristic set, illustrated in Figure 3b. A total of 58% of problems were rated as major, 37% of the issues were perceived minor, and 5% were considered cosmetic issues. The distribution suggests that most of the problems are not superficial, having a high impact on the user performance and their satisfaction.
In terms of severity distribution per heuristic, Figure 3a presents a more detailed perspective on the criticality of the issues. Major issues cover most of the heuristics, with a higher impact on H2 (Match between system and real world), H4 (Consistency and standards), H7 (Flexibility and efficiency of use), and H10 (Help and documentation).
In Equation (2) the average severity () is calculated, where severity score of problem and is the total number of problems considered (for that heuristic set).
Minor issues are reported for many heuristics, particularly for H1 (Feedback), H3 (User control), H5 (Error prevention), H6 (Recognition rather than recall), H7 (Flexibility and efficiency of use), and H8 (Aesthetic and minimalist design). Only one cosmetic problem was reported for H6.
Combining the HE issues count and severity ratings, H7 (Flexibility and efficiency of use) turns out to be the most impacted heuristic, which registered the highest number of three issues, out of which two were rated as major and one minor. This suggests that users are deeply affected by the lack of flexibility in finding functionalities in DNG.
Also, H2, H4, and H10 had reported major issues, suggesting that usability in DNG is critical in areas of terminology, consistency, and help mechanisms as well.
To sum up, the quantitative analysis on the HE results underscores that usability issues in DNG are evenly spread across the heuristic set and also critical. The pain points in interacting with the tool are not limited by the efficiency of interaction, but by terminology, consistency, and support mechanisms, important aspects for an effective use in RE workflows. The findings lead to targeted design improvements needed, which would enhance discoverability and consistency, clarity, and user help.
4.3. Qualitative Findings
The qualitative analysis of the findings focuses on a heuristic-issue mapping, clustering the issues into themes (themes are the NH principles), on the suggested improvements and their implications and on the severity distribution per heuristics, highlighting which heuristic uncovered the most severe issues.
As presented in Table 3, the identified issues are mapped to the impacted heuristic and a thematic analysis was realized [63]. The themes represent each heuristic itself, so the themes are presented in detail as follows.
4.3.1. Theme 1—H1 Visibility of System Status
This heuristic refers to a system’s requirement to provide feedback to users, regarding their actions.
Two issues were mapped to H1, one related to missing feedback mechanisms when requirements or links are created (severity of 2) and another related to missing feedback on actions performed inside a review session (severity of 3). The actions were performed successfully, but no feedback was displayed to the users.
In the automotive RE domain context, missing feedback in REM tools may be discouraging for users operating with requirements. Missing feedback can cause duplicated artifacts, forgotten links, or incomplete reviews. These are problems that directly affect traceability and compliance with standards such as ISO 26262 and ASPICE. Also, missing feedback can lead to slow collaborative work as, manually, work must be performed for verifications.
Evaluators suggested improvements referred to the introduction of confirmation mechanisms such as pop-up banners or inline confirmation texts after requirements-related actions: creation, linkage, or review actions.
4.3.2. Theme 2—H2 Match Between System and the Real World
The heuristic indicated that systems should use language, conventions, and structures familiar to users.
Two issues impacted H2, both considered major (severity of 3). One issue referred to the inability to discover the “Save view” button using the interface, due to its uncommon position and another referred to the inability to understand specific terms such as baseline or stream, creating confusion for the users without domain knowledge. The two issues create a gap between the REM tool’s used terminology and the user’s mental model.
These issues are considered critical in automotive, where various stakeholders (requirements engineers, managers, developers, and testers) work together but may have different expertise. An unclear terminology can confuse users, threatening RE activities. Also, an uncommon position of the interface such as view saving button can lead to errors, since users cannot find it and are not able to create helpful shortcuts.
The suggested improvements referred to the relocation of the “Save view” button above the requirements’ main table view and adding inline explanations or tooltips for domain-specific terms. This way, the tools interface would become more aligned with the users’ expectations.
4.3.3. Theme 3—H3 User Control and Freedom
The heuristic emphasizes that the systems should provide users the freedom to easily recover from unwanted actions and redo or undo actions.
One issue was reported for this heuristic and refers to missing undo options on several actions, rated as severity 2.
In the context of automotive REM, missing undo functions can increase the risk of propagating errors across linked artifacts. For instance, an unintended edited requirement can affect the linked test cases, demanding additional effort for corrections. Also, missing undo options can lead to cautious users, afraid to experiment with diverse actions in the tool.
The suggested improvements mention undo/redo capabilities implementation for critical actions such as requirements edits, reviews, besides the change set reversibility option.
4.3.4. Theme 4—H4 Consistency and Standards
The heuristic emphasizes the importance of design, terminology, and the interface elements’ placement consistency.
Two major (severity of 3) usability problems were mapped to this heuristic: one referring to button placement differently from other platforms and one to confusing terms due to unknown domain language. Together, these issues indicate interface layout and terminology inconsistencies.
In the context of automotive REM tools, inconsistent terminology and layout of elements can lead to inefficiencies and additional trainings for new or even experienced users. For instance, inconsistencies in key features placement may slow down even experienced users who expect standard UI conventions, while vague terms may confuse new users. The issues may compromise communication through collaborative teams and induce errors in RE-related actions.
The evaluators suggested improvements referring to the placement of UI elements in more standard ways or adding tooltips for domain-specific terms, useful for both new and experienced users.
4.3.5. Theme 5—H5 Error Prevention
The heuristic indicates that systems should be designed to prevent errors.
Two issues were identified for this heuristic: one related to missing prevention before creating a link and editing a requirement (severity of 2) and one related to missing prevention before marking a review as Done (severity of 3). Both issues suggest missing prevention mechanisms for RE critical workflows.
In the automotive context, missing prevention in REM tools for critical actions can induce inconsistencies across the stakeholders’ requirements, also impacting validation phases. Incorrectly created links, unintended edits, or unfinished reviews can cause traceability problems, compromising compliance with ISO 26262 for safety systems and ASPICE. These risks may reduce the users trust in the system and slow down the RE activities.
For the reported issues, evaluators suggested adding confirmation messages before irreversible actions or warning messages before closing incomplete reviews. Aside from messages, consistent warning symbols would be an alternative for implementing reliable prevention mechanisms.
4.3.6. Theme 6—H6 Recognition Rather than Recall
This heuristic refers to the capabilities of a system to minimize the users need to memorize actions, relying on providing information in a visible and accessible way.
Two issues were reported for this heuristic: one referred to the need of memorizing locations of requirements during the linkage process (severity of 2) and one related to the need to remember keyboard actions for usual activities like requirements creation (severity 1).
When interacting with automotive REM tools such as DNG, forcing users to remember locations or keyboard actions lead to inefficiencies and slow work, given that automotive projects contain usually thousands of requirements. It can also affect collaborative work, with either new or experienced users struggling to adapt.
As solutions for the reported issues, evaluators suggested ideas such as providing recently used or suggested requirements when creating links or adding inline hints for keyboard-related issues. Both suggestions would improve the applicability of recognition over recall principle of DNG.
4.3.7. Theme 7—H7 Flexibility and Efficiency of Use
This heuristic indicates that systems should provide efficient use to the users, through shortcuts for frequent actions and multiple ways to perform similar actions.
Three issues were discovered for this theme. First, evaluators were not able to locate the configuration panel for baseline creation and comparison (severity of 3). Another issue is related to history access of artifacts, inaccessible due to many dropdown lists at artifact level (severity of 3) and the third issue is regarding attributes, which were not easily accessible after being edited for a specific artifact (severity 2), with users being forced to search for their modifications.
In the context of the automotive RE domain, baselines and artifact history are important for version control, safety audits, and compliance with standards. Also, manually searching for visualizing attributes after edits increases the risk for inconsistencies. Together, the three issues decrease the efficiency of using the REM tool.
Evaluators suggested several improvements for the uncovered issues, such as right-clicking options to guide the baselining located in the configuration panel, which was not expected by the users. For artifact history access, an improvement would imply a more visible option in the first level dropdown list on the artifacts. Also, the possibility to display recently edited attributes next to the modified requirements would streamline the editing process, so it would increase efficiency.
4.3.8. Theme 8—H8 Aesthetic and Minimalist Design
This heuristic promotes minimalism and aesthetically pleasing user interfaces across the systems.
Two issues were logged for this theme. First, the review tab from the upper menu was almost invisible, making it difficult to locate (severity of 2), and second, the interface was perceived to be overcrowded due to many link types (severity 2), aspects that usually overwhelm users.
In terms of REM tools which are complex in functionalities, minimalist user interfaces are hard to achieve, although visual clarity and simplistic panels exposing essential information are needed for smoother discoverability and use of functionalities. The hidden review tab can reduce the requirements review process, introducing potential delays in validation phases. Also, an overcrowded list of link types can lead to cognitive load and confusion among the users, forcing them to focus on identifying the proper ones more than using them efficiently.
Evaluators’ suggested improvements are focused on font size and contrast changes for the menu tabs to increase visibility and accessibility. Regarding the link types, grouping them under collapsible categories that would declutter the interface would help users to identify easier the needed link types for their tasks: traceability, validation, and implementation links.
4.3.9. Theme 9—H9 Help Users Recognize, Diagnose and Recover from Errors
This heuristic indicates that the systems should provide users with clear, precise, and actionable error messages that help users find solutions.
One issue was identified as impacting this heuristic and it refers to coded errors which are not explained but still provided to users (severity of 3). The issue forces users to interpret it without any guidance to a recovering solution.
For REM tools, unclear error handling can lead to several consequences, as automotive requirements support safety-critical development. Stakeholders such are forced to troubleshoot for solutions, which can cause project delays.
The suggested improvement provided by the evaluators would imply providing detailed explanations on the error codes, which would ensure clarity to users. For example, instead of displaying “error 405”, the system should provide an explanation such as “the link cannot be created due to missing target artifact”.
4.3.10. Theme 10—H10 Help and Documentation
The Help and Documentation heuristic indicates that even if the systems should be accessible without any documentation, it should provide to users a concise help section to use.
Some major problems were identified for this theme (both rated with severity 3): one referring to a missing section of context-help and the other one claiming that the official help and documentation section is too long and not actionable.
REM tools are complex systems and insufficient support mechanisms may reduce efficiency of use. Long documentations may lead to time-consuming searches and, hence, delayed deadlines of the projects. A context-help is usually needed for quick and clear explanations, to reduce the time taken for searches.
The evaluators proposed two improvements: a context-help to be introduced, in the form of inline explanations, visible tooltips or glossaries, and a refactorization of the official help section for the most frequent actions performed in the tool.
Analyzing the findings, we observed that the issues impact all ten heuristics. The most affected heuristics are H4, H7, and H10, in terms of the number of issues and severity ratings. These reflect users’ challenges with inconsistent terminology, discoverability of domain-critical functions, and insufficient support mechanisms, all of them reducing user trust and hindering efficiency of use.
In addition, suggested improvements indicate that the evaluated system needs better feedback mechanisms and visibility (H1, H8), stronger prevention mechanisms (H5), simplified interactions (H6), and more clarity for error handling and support mechanisms (H9, H10).
Grouping the issues into themes and analyzing their implications in the context of automotive REM confirms that REM tools’ usability depends not only on visual design, but on reducing cognitive load, ensuring automotive standards compliance and supporting collaboration in safety environments.
The qualitative analysis of the findings demonstrate that DNG demands refinements in areas of interaction design and support mechanisms, to align both with user expectations and regulatory standards. The severity ratings assigned show that issues are mostly perceived major and minor, so they impact the main RE workflows. In this case, usability improvements for the assessed REM tool are needed.
4.4. LLM-Based Heuristic Evaluation Findings
This section aims to present the results of the exploratory study of LLM-based HE applied for DNG, using NH. The LLM used was ChatGPT-5.
As presented in Table 4, the HE uncovered a total of 22 usability issues, out of which 32% are common with the human-based issues, 23% represent new findings, and 45% were labeled as unconfirmed.
Table 4.
Usability problems summary identified in LLM-based HE. We used the following abbreviations: PID = Problem ID, HID = Heuristic ID, S = Severity, T = Type. For problem type the following abbreviations were used: common (C), new issue (N), potential issue (P).
The authors are experienced in both domains, UX and usability evaluations, as well as RE. The authors labeled the identified usability issues as confirmed, unconfirmed, and hallucinated. This adjudication has been conducted independently of the human HE results, to avoid bias that can be introduced by the prior knowledge of human results.
A confirmed issue defines as an issue that could be directly supported by visible evidence from the screenshots or could be reproduced via direct tool interactions during follow-up task execution.
An unconfirmed issue represents a reported problem appearing plausible, which cannot be validated solely using the provided screenshots and requiring additional interaction to be verified. For the unconfirmed issues, the authors re-executed the given tasks in the tool to assess the reproducibility of the issues. This way, the issues that could not be validated via interaction were labeled as unconfirmed, rather than obsolete, to reflect the uncertainty of LLM-based assessments.
A hallucinated issue points to an issue that refers to interface elements, workflows, or system behaviors that were not present in the provided screenshots.
Given the exploratory nature of the LLM-based HE, there are no formal inter-rater agreement metrics computed. The authors classified the LLM-identified issues and the disagreements were resolved via discussions until reaching a consensus, with the main purpose of qualitatively assessing the reliability of LLM-based usability issues, rather than quantifying the agreements between raters.
So, the notable number of unconfirmed issues represent findings which could not be validated as usability problems, as they appeared to be potentially valid only via tool interaction. The reported issues could be resulted from speculative assumptions about the tool workflows (inferring missing steps or inefficiencies imagined to be present in the tool) or hallucination of features (the LLM described features that were not visible in the screenshots, potentially extrapolated from training data).
The new issues impacted heuristics referring to the visibility of system status (H1), recognition rather than recall (H6), flexibility and efficiency of use (H7), and documentation support (H10).
The common issues were connected to missing feedback after requirements creation (H1), missing inline guidance on some actions (H10), and insufficient shortcuts caused by multiple dropdown lists to achieve certain actions (H6, H7).
In terms of severity, Figure 4b illustrates the severity ratings dispersion across the heuristic set: 41% were rated major and 59% were rated minor. No issues were rated as 0, which is defined as “not a usability issue”.
Figure 4.
(a) Usability problems distribution with severity rating per heuristic identified by LLM-based HE. (b) Severity dispersion across the heuristic set identified by LLM-based HE.
These proportions may suggest that, in the absence of real interaction with the tool, the LLM may tend to underestimate the severity of several issues, with most minor issues identified, referring to baselining and configuration terminology, domain-specific term inconsistencies, missing shortcuts, a cluttered interface due to many items to filter, undo actions, or missing inline context-help. Major issues were related to missing feedback after certain actions, missing prevention mechanisms and insufficient flexibility in performing actions via multiple ways.
Problem Dispersion Rate () for the LLM-based HE is presented in Equation 3; having a value of 1.08 indicates non-uniform distribution of usability problems across the evaluated heuristics. This aspect can be observed in Figure 4a.
In Equation (4), the average severity () is calculated for this evaluation, and we observe a similar value as the human-based HE, a value of 2.41. This value is expected looking over the distribution from Figure 4b.
The issues count for each heuristic was analyzed, as being presented in Figure 4a. The highest number of issues reported impacts H6 (Recognition rather than recall), with four issues reported. The issues were connected to ungrouped related functions, multiple menus and the users’ feeling of “getting lost”, multiple dropdown menus to track the artifact history, or baseline comparison forced by manual search instead of being visible right after creation.
All four issues reported for H6 were perceived major and rated with severity 3, which can be observed in Figure 4a.
The exploratory evaluation of DNG using ChatGPT-5 as heuristic evaluator provides meaningful insights but also underscores several limitations. While 27% of findings overlap with the ones resulted from human-based HE and even 23% are new findings, the high percentage (50%) of unconfirmed issues demonstrates the risks of AI model hallucinations in the absence of real tool interaction.
To conclude, the LLM-based HE shows that AI models demonstrate potential as complementary instruments rather than replacements of humans. Notably, the high concentration of major issues on H6 (Recognition rather than recall) highlights the LLM’s sensitivity to cognitive load-related issues, aligned with human perspectives on efficiency of use and flexibility (H7).
As we do not trust all the problems identified by the LLM, we would not undergo a qualitative evaluation by thematic analysis in this case.
4.5. Cross Comparison of Human vs. LLM-Based Findings
By analyzing the two sets of findings from Human and LLM-based HE sessions, both reflect convergence and divergences points that could highlight a potential complementary approach for HE methodology.
First, in Figure 5a, we observe a proportion of 32% of findings were commonly found during both HEs. The overlapping issues were connected to missing feedback mechanisms after requirements creation (H1), an inflexible navigation for linking and artifact history tracking (H6), insufficient shortcuts for recurrent actions (H7), and missing context-help for review feature (H10). These overlaps suggest that both humans and LLM evaluators identified usability challenges in areas of feedback, support systems, navigation, and flexibility and efficiency.
Figure 5.
(a) Problem type dispersion across the heuristic set identified by LLM-based HE. (b) Problem type distribution, per heuristic, identified by LLM-based HE.
Second, the LLM evaluator was able to identify 23% new issues which were not found by humans, in areas such as low visibility of active filters (H1), missing shortcuts for views creation and baselines comparisons (H6, H7), and missing support for baselines and configuration comparisons (H10). The proportion of new issues uncovered by the LLM highlights the potential use of AI models for HEs, as ChatGPT-5 was able to detect gaps related to efficiency and interface clarity of DNG. These findings open directions for the exploration of using LLMs in evaluating usability.
Third, 45% of the LLM-identified issues were labeled as unconfirmed, due to hallucinations and speculative assumptions. The increased proportion of these issues underscores the limitation of LLMs in HE, as it operates without tool interactions, only using static screenshots. These hallucinated outputs are the reason for mandatory human verification.
From Figure 5b, we can observe that in some heuristics, like H1 or H6, the LLM-based HE found the same problems even suggested new problems that could be confirmed easily. On the other hand, in the case of H3, no new problem was discovered.
From perspective of problem distribution on each heuristic, as presented in Figure 6a, the LLM-based HE has a more uneven distribution of problems than the human-based HE. This can be observed by comparing with the too.
Figure 6.
(a) Problem dispersion across the heuristic set identified by both HEs. (b) Problem severity dispersion across the heuristic set identified by both HEs.
From the severity distribution perspective, as we can see in Figure 6b, the human-based HE revealed a higher concentration of major issues, while the LLM-based HE revealed 59% minor issues out of its total number of issues. This difference is observed in the average severity index where while the .
In order to summarize overall cross-analysis, we computed Table 5 with relevant metrics from both HE performed.
Table 5.
Metric comparison of human and LLM HE.
These differences suggest that humans are more able to contextualize the impact of issues on RE workflows, while the LLM tends to underestimate the issues’ impact in the absence of tool interaction. Remarkably, both finding sets were aligned on the criticality of H6- and H7-related issues, the most problematic heuristics in DNG.
The cross-analysis reflects that the LLMs cannot replace human evaluators in HEs, but they can be used as auxiliary instruments for assessing usability: human evaluators are able to better contextualize issues on the domain workflows driven by regulatory standards, while LLMs are able to bring additional usability issues connected to efficiency and interface clarity.
The LLM identified several interface-related inconsistencies that were not reported by human evaluators. These reflect the LLM’s text-driven perception of interface elements rather than experiential interaction. Conversely, human evaluators identified workflow inefficiencies and error prevention issues that require contextual awareness of system behavior—aspects currently beyond static AI reasoning.
A potential limitation of the human-based HE is that the evaluators were usability experts with no experience in automotive RE domain. Consequently, the findings mainly reflect their first encounter and learnability related usability issues, like terminology misunderstandings, discoverability of domain-specific workflows, or cognitive load.
While the assessor profile may miss usability issues related to experts’ usage, the authors considered it well-suited to identify barriers encountered by novice users. Since REM tools such as DNG are used by heterogeneous roles involved in the RE domain, the findings prove themselves ecologically relevant. As part of authors’ future work, RE domain experts will be involved, to address the expert-use workflows’ usability issues.
5. Conclusions and Future Research
This study presents the first HE of DNG, a widely used REM tool in the automotive industry. We performed a dual evaluation approach: a traditional HE by five expert evaluators and an exploratory LLM-based HE using ChatGPT-5. The role and performance of LLMs in UI/UX and usability evaluation constitute an emerging research domain [64] with several benchmarks [65,66] proposed to assess general multimodal reasoning and interface understanding capabilities. However, these benchmarks primarily evaluate recognition and comprehension tasks, rather than the correct classification of usability issues within established heuristic frameworks, highlighting an important gap for future research.
The findings, presented in Table 3 and Table 4, suggest that LLM are capable of recognizing surface-level heuristic violations, by reasoning over textual and visual cues. However, they lack situational awareness to evaluate dynamic interactions and contextual feedback, which are essential for complex engineering workflows. This gap indicates that future usability assessments of enterprise tools should consider hybrid pipelines, where AI pre-screens the interface for syntactic or content-level issues, and human evaluators validate workflow-level usability problems.
By our experiment we concluded upon the research questions as it follows:
RQ1: We identified 19 usability problems resulting from a human-based HE performed by five evaluators, presented in Table 3. On top of those, we identified 5 new issues (23%) and 10 potential issues (45%) by a novel LLM-based HE, presented in Table 4 and Figure 5. The identified problems are analyzed in Section 4.2 and Section 4.3. We concluded that the most confirmed usability challenges were identified for H7 and H6, which are detailed in the theme analysis from Section 4.3.
RQ2: The LLM-based HE obtain similar severity distribution of problems ( while the ; however, the problem distribution is not ideal ( with the ). From the analysis in Section 4.4 and Section 4.5, we highlight that 45% of problems identified could not be confirmed, which suggests that this aspect should be researched further in order to improve.
RQ3: From Table 5 and Figure 5 and Figure 6, we concluded that the LLMs cannot replace human evaluators in HEs, but they can be used as auxiliary instruments for assessing usability. In terms of coverage, LLM-based HE has similar spread but focuses more on static problems as they lack situational awareness to evaluate dynamic interactions and contextual feedback.
The main contributions of the paper include the following:
- A methodical HE of DNG conducted across six RE workflows using NH.
- A quantitative analysis of the HE findings, focused on the issue count, and severity rating distributions.
- A qualitative analysis of the HE findings, focused on a thematic analysis per heuristic and the evaluators’ suggested improvements.
- An exploratory study on using LLMs in the role of evaluators for the HE of the same tool, DNG. These results highlight both the potential and the limitations of using AI models for usability evaluation.
To the best of our knowledge, the paper presents the first usability study of a REM tool used in automotive, using HE as an expert-based usability evaluation method. While HE is widely used for various profiles of web or mobile applications, this study demonstrates its applicability to safety-critical platforms, driven by regulatory standards domains such as REM-dedicated tools.
The findings reflect that usability in REM tools is hard to achieve from the interface minimalism perspective, but mainly from reducing cognitive load for complex RE projects efficiency, facilitating multidisciplinary teams by ensuring terminology clarity, improving flexibility in navigation for RE workflows, and strengthening support mechanisms on domain-specific workflows.
The limitations of the study include the following:
- The sample size of the evaluators: the HE was conducted with five evaluators, which is consistent with Jacob Nielsen’s recommendations. A larger group of evaluators, with broader perspective and expertise, might reveal additional issues.
- The exclusive focus on the DNG (version 7.0.3) tool within the automotive industry. The findings are relevant for the given context and may not generalize to other platforms.
- The subjective perspectives on severity. Evaluators’ different expertise and surface knowledge of RE influence their perspective on the severity of the identified issues.
- Generic heuristics limitations. While widely applicable, the NH may be too generic and not able to cover domain-specific aspects of REM tools, such as traceability, versioning, configuration management, or collaboration features.
As future work, several directions are open for exploration:
- A broader tool coverage, including platforms such as IBM Rational DOORS, Polarion, or Jama Connect for similar evaluations.
- Domain-specific heuristics, developed by adapting or extending generic principles such as Nielsen’s, for a better coverage of automotive RE workflows.
- Related to LLM-based evaluations, standardized prompt engineering guidelines could be tailored for HE, to reduce hallucinations.
The current research highlights that besides the functionality, usability is also essential for automotive REM tools. Using a combined approach of expert-based HE and AI models as heuristic evaluators, the study identifies existing usability gaps in DNG but also opens future directions towards domain-specific usability heuristics frameworks that would establish the evaluation of REM tools.
Author Contributions
Conceptualization, O.R., C.O. and R.V.; methodology, O.R.; software, O.R.; validation, O.R.; formal analysis, O.R. and C.O.; investigation, O.R.; resources, O.R. and C.O.; data curation, O.R.; writing—original draft preparation, O.R. and C.O.; writing—review and editing, O.R., C.O. and R.V.; visualization, O.R.; supervision, R.V.; project administration, R.V.; funding acquisition, R.V. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Informed consent was obtained from all subjects involved in the study.
Data Availability Statement
Data can be available upon request to authors.
Acknowledgments
The authors gratefully acknowledge Aumovio Autonomous Mobility Romania for approving research access to IBM DOORS Next Generation and for enabling a controlled, non-confidential test environment.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| AI | Artificial Intelligence |
| ASPICE | Automotive Spice |
| DNG | IBM DOORS Next Generation |
| HE | Heuristic evaluation |
| LLM | Large Language Models |
| NH | Jacob Nielsen’s 10 usability heuristics |
| RE | Requirements Engineering |
| REM | Requirements Engineering and Management |
| RM | Requirements management |
| UX | User Experience |
Appendix A
The prompts used for the LLM-based HE (using Nielsen) of DNG REM Tool, using ChatGPT-5.
Appendix A.1. Prompt for Task 1
Role: “Assume you are a usability expert evaluating an automotive Requirements Engineering Management tool (IBM DOORS Next Generation) for the automotive industry, via heuristic evaluation.”
Objective: “Your task is to identify usability issues according to the following heuristic set, rate their severity, and suggest improvements.”
Reasoning approach: Before providing your responses, examine the interface and think of the interaction step-by-step: (1) Observe every given screenshot to understand the entire context. (2) Identify the UI elements, potential workflows, and terminology used. (3) The observations should be compared against the heuristic set given, to identify possible heuristic violations. (4) For every possible issue, think of the reason why it is a problem and how it impacts usability. (5) Assign a severity rating for the identified issue. (6) Think of a potential improvement that can address the issue.
Heuristic set: Nielsen’s 10 heuristics. 1. Visibility of system status: The system should always keep users informed about what is going on, through appropriate feedback within reasonable time. 2. Match between system and the real world: The system should speak the users’ language, with words, phrases and concepts familiar to the user, rather than system-oriented terms. Follow real-world conventions, making information appear in a natural and logical order. 3. User control and freedom: Users often choose system functions by mistake and will need a clearly marked “emergency exit” to leave the unwanted state without having to go through an extended dialog. Support undo and redo. 4. Consistency and standards: Users should not have to wonder whether different words, situations, or actions mean the same thing. Follow platform conventions. 5. Error prevention: Even better than good error messages is a careful design which prevents a problem from occurring in the first place. Either eliminate error-prone conditions or check for them and present users with a confirmation option before they commit to the action. 6. Recognition rather than recall: Minimize the user’s memory load by making objects, actions, and options visible. The user should not have to remember information from one part of the dialog to another. Instructions for use of the system should be visible or easily retrievable whenever appropriate. 7. Flexibility and efficiency of use: Accelerators—unseen by the novice user—may often speed up the interaction for the expert user such that the system can cater to both inexperienced and experienced users. Allow users to tailor frequent actions. 8. Aesthetic and minimalist design: Dialogs should not contain information which is irrelevant or rarely needed. Every extra unit of information in a dialog competes with the relevant units of information and diminishes their relative visibility. 9. Help users recognize, diagnose, and recover from errors: error messages should be expressed in plain language (no codes), precisely indicate the problem, and constructively suggest a solution. 10. Help and documentation: Even though it is better if the system can be used without documentation, it may be necessary to provide help and documentation. Any such information should be easy to search, focused on the user’s task, list concrete steps to be carried out, and not be too large.
Task description: Create and specify a new requirement; Prerequisites: open change set needed; Create a new requirement in Heuristic evaluation test document #1, with the content “Requirement 1.4”. Set the State “In work” and add a comment.
Workspace context: A dedicated “Test’ workspace was created in DNG REM tool for this evaluation. Three requirements modules, containing some requirements’ artifacts.
Screenshots:
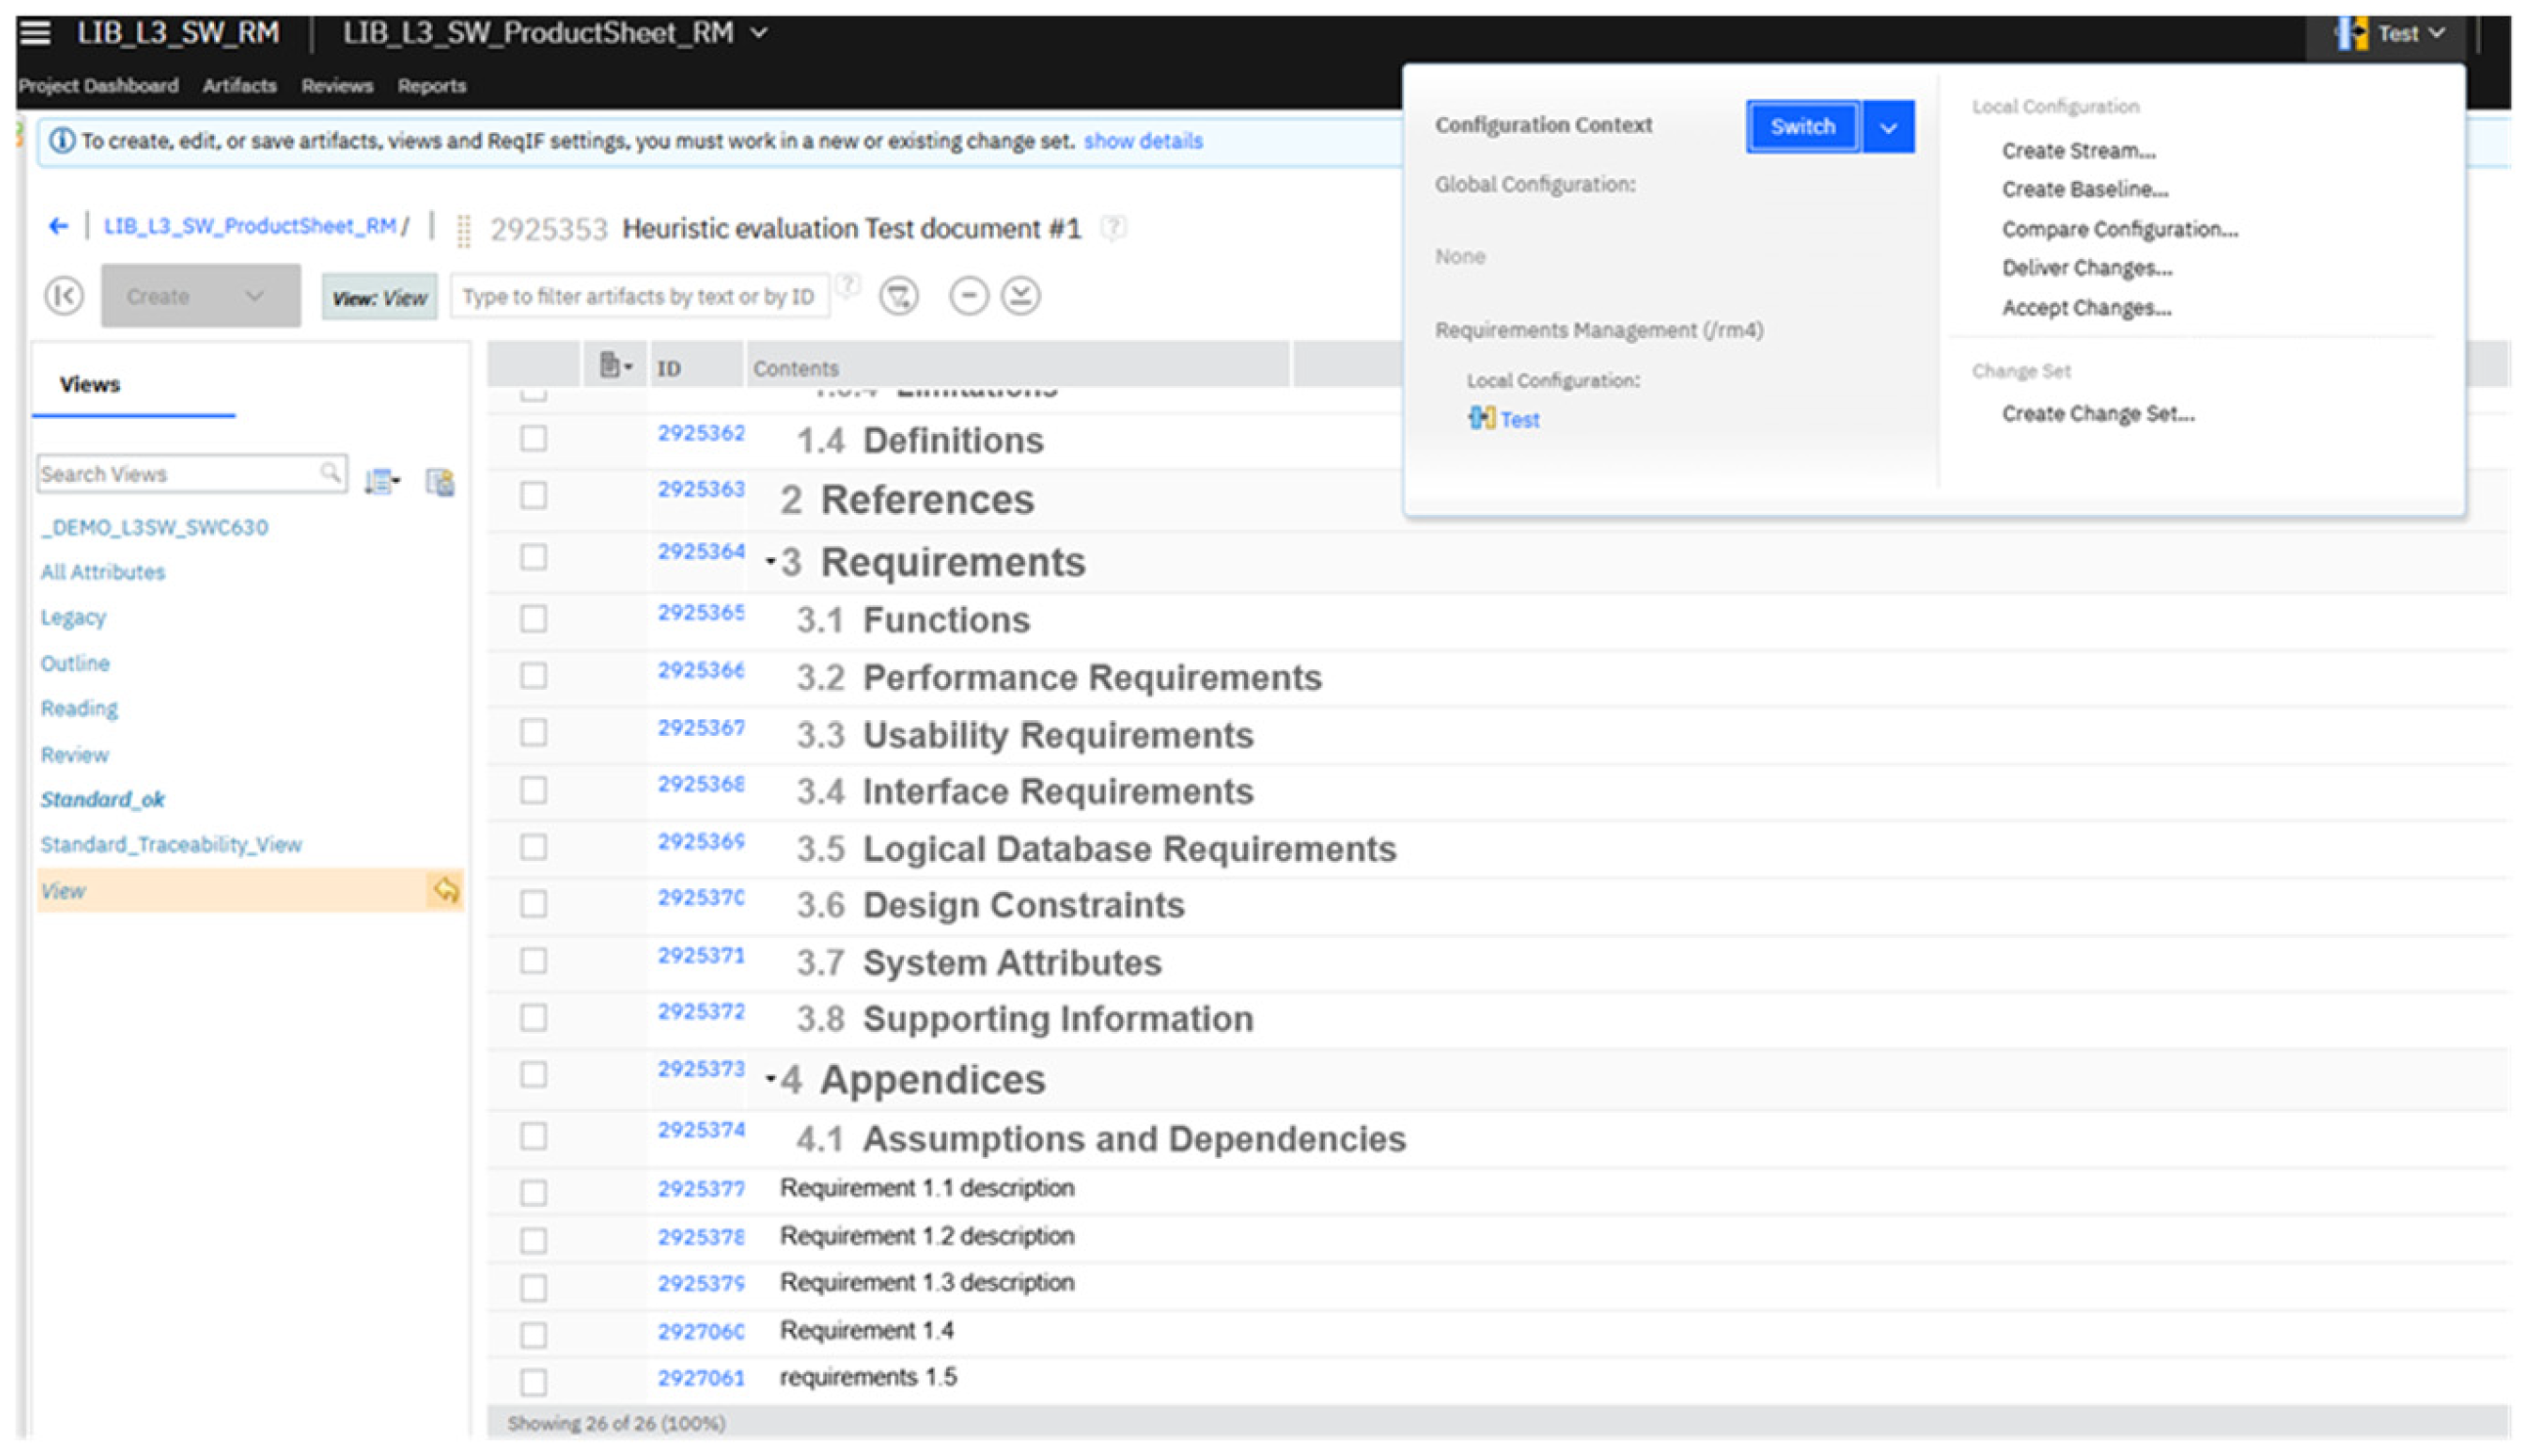
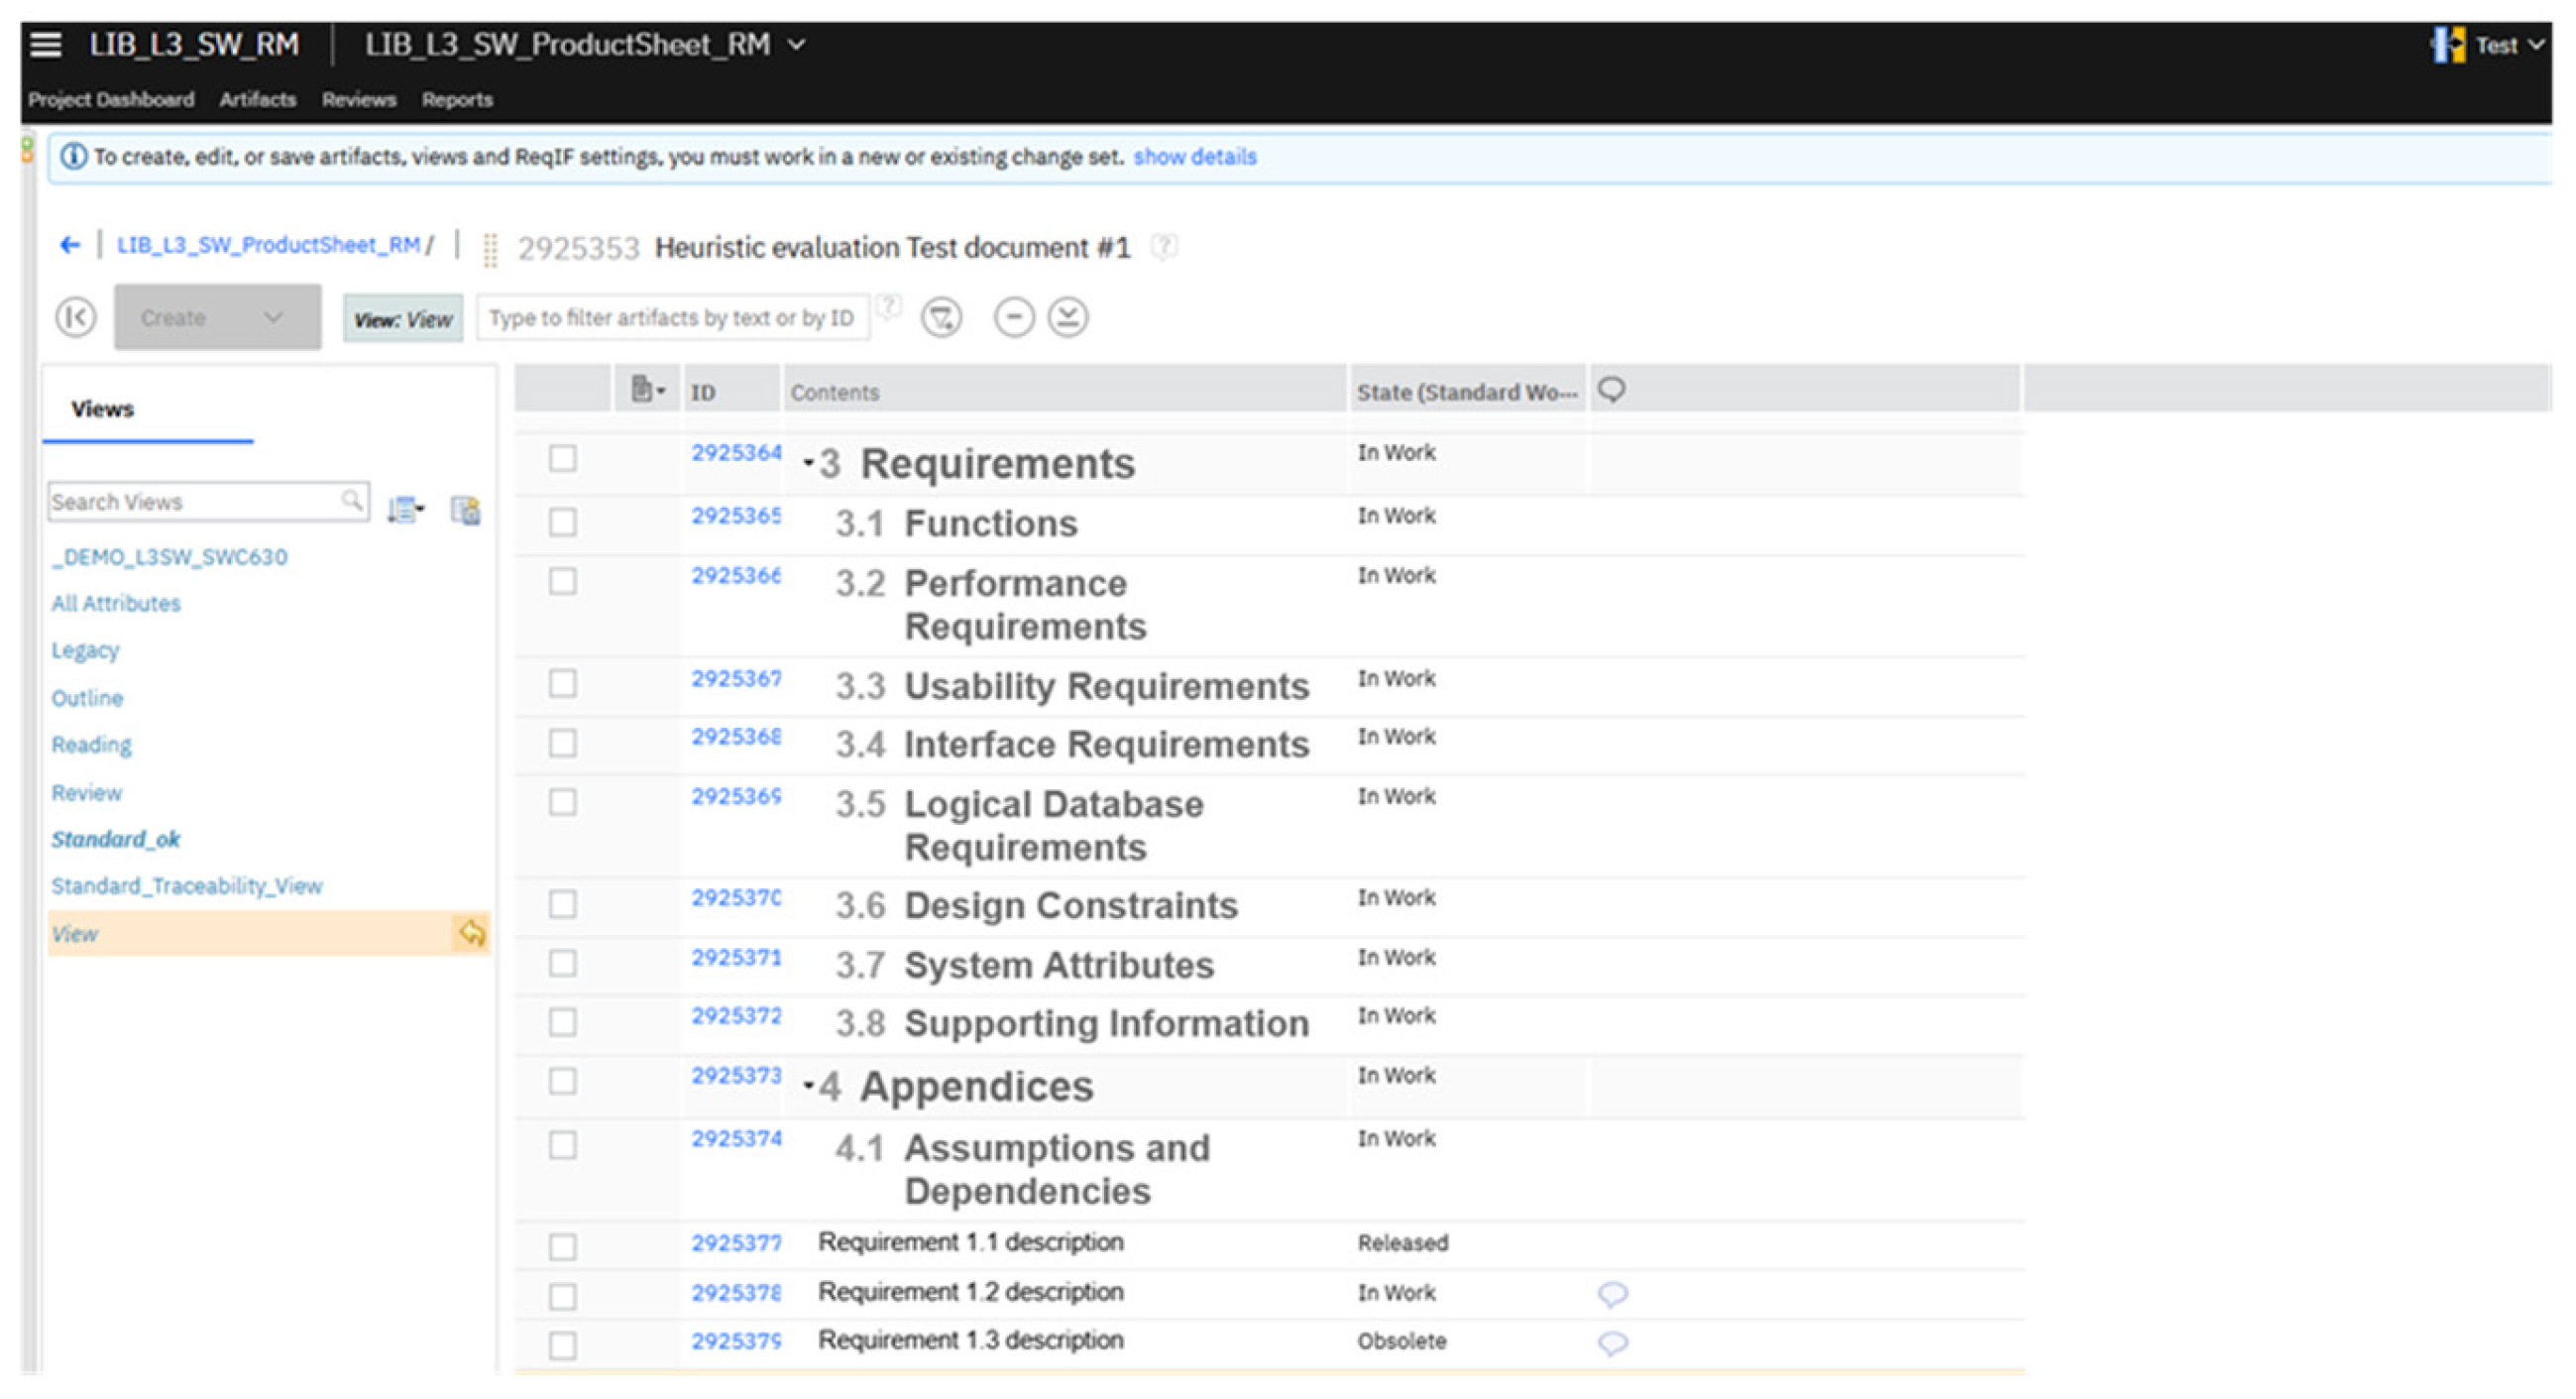
Output format:|Heuristic Violated|Issue Description|Severity (1–4)|Suggested Improvement|
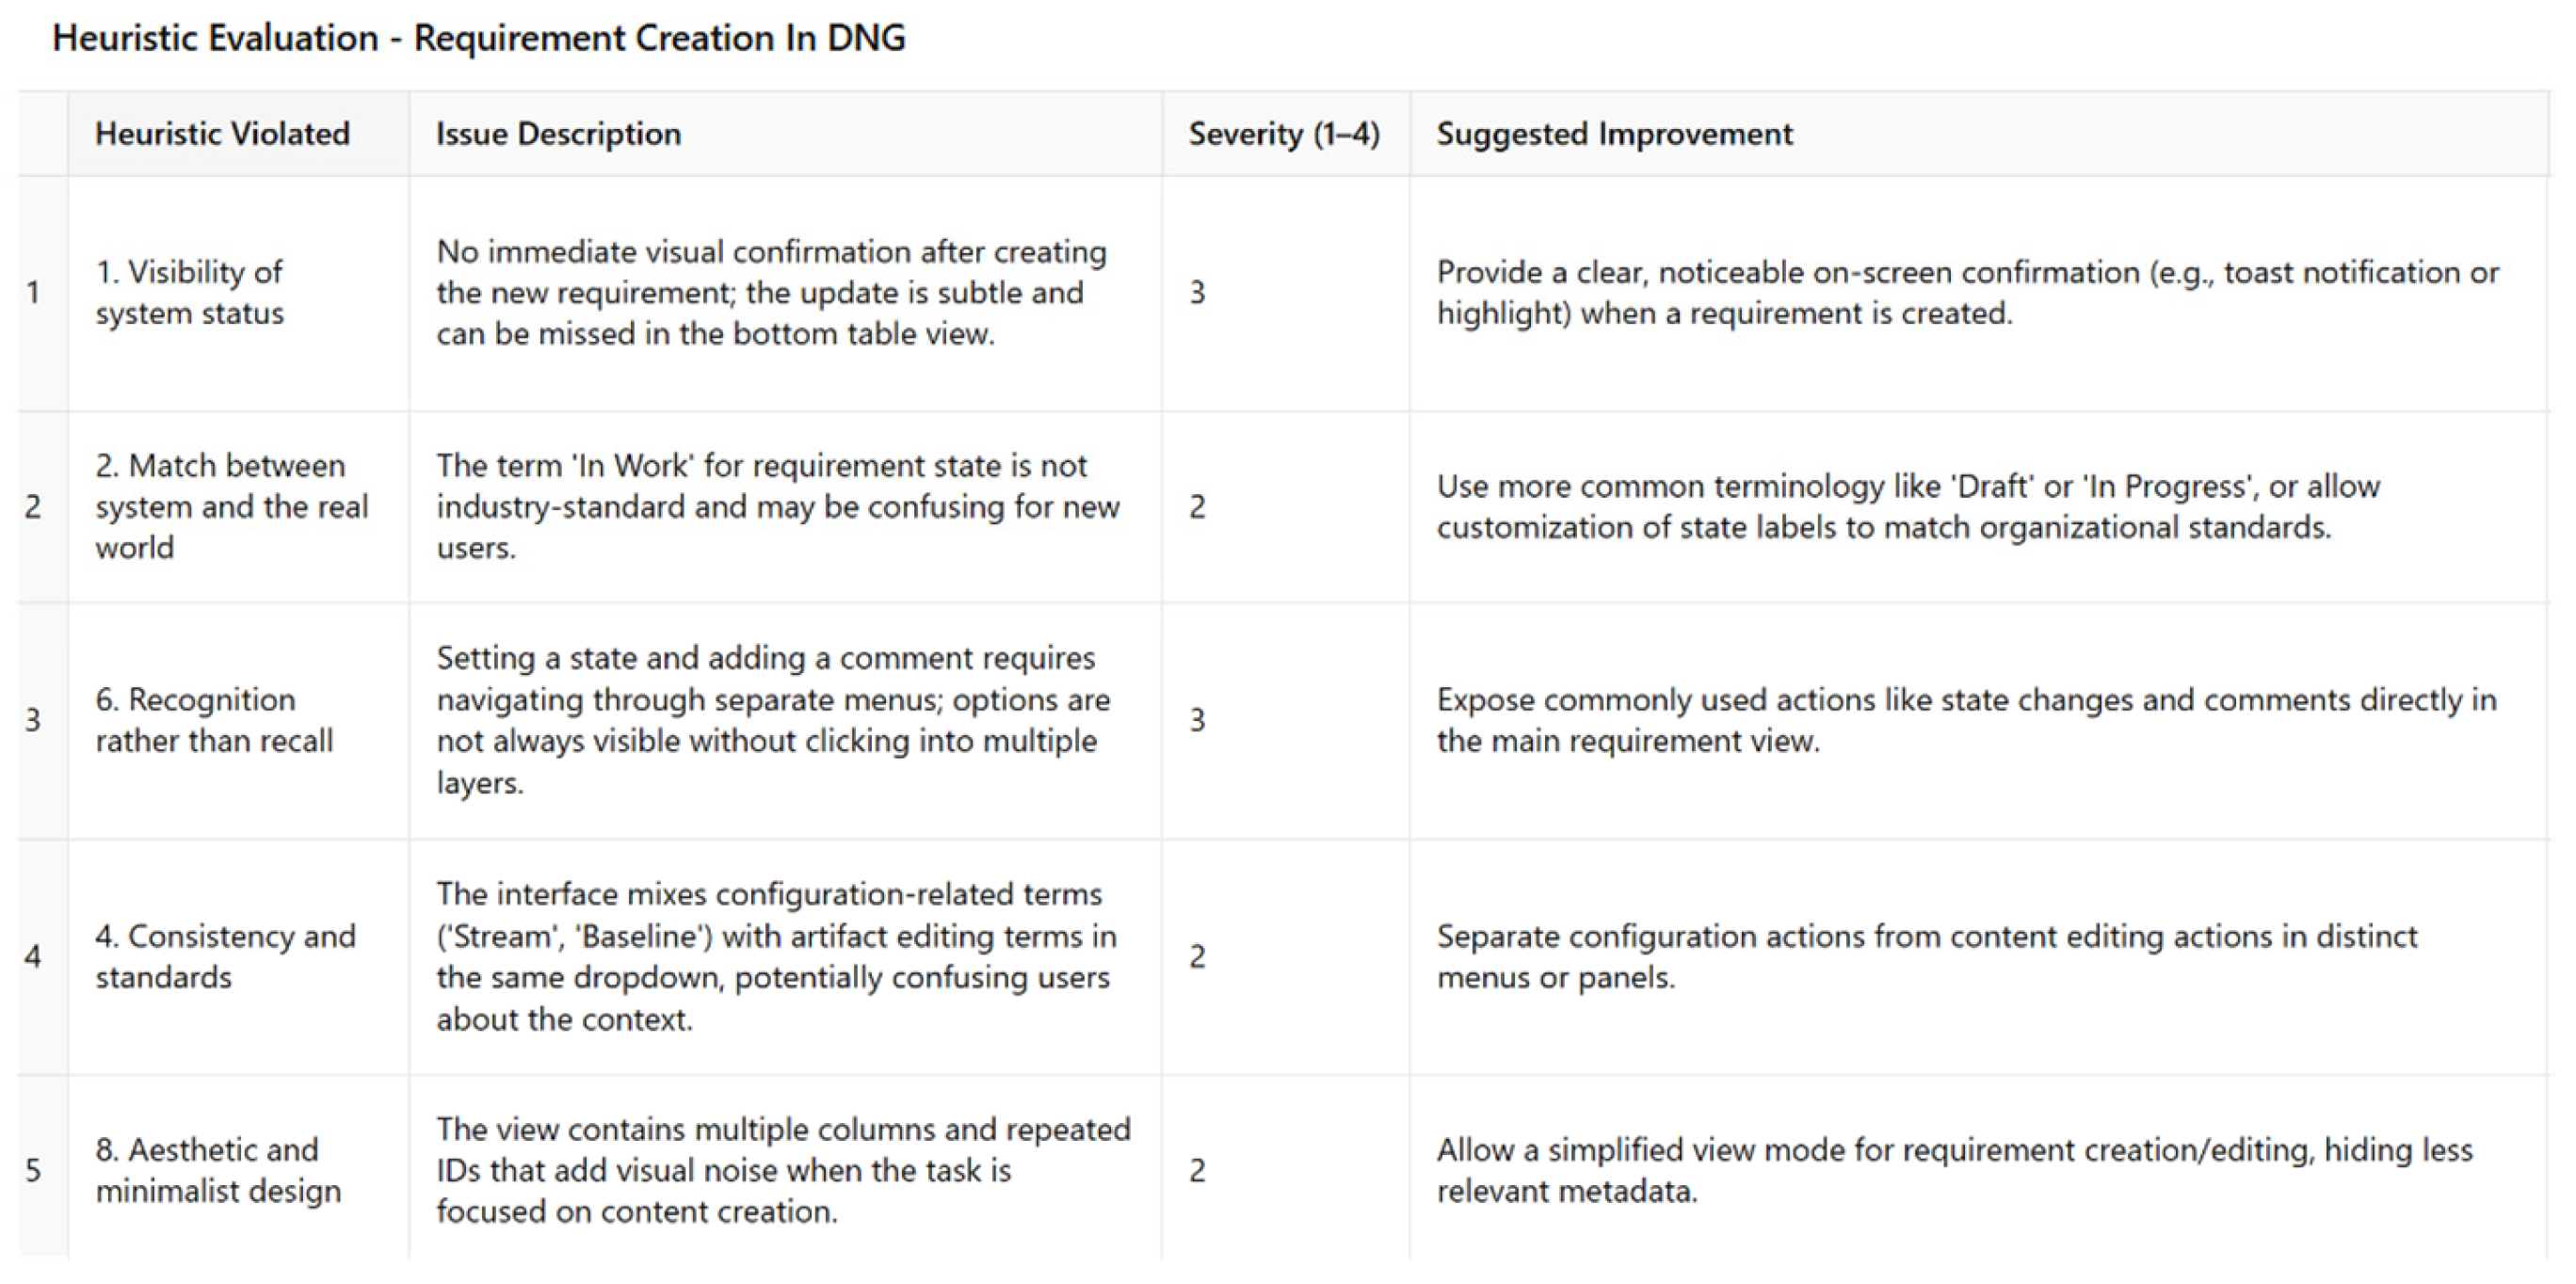
The ChatGPT-5 Output:
I’ve compiled the heuristic evaluation findings for the requirement creation task in DNG based on the screenshots and context you provided. You can now review the table to see each identified issue, its severity, and the suggested improvements.
Appendix A.2. Prompt for Task 2
Role: “Assume you are a usability expert evaluating an automotive Requirements Engineering Management tool (IBM DOORS Next Generation) for the automotive industry, via heuristic evaluation.”
Objective: “Your task is to identify usability issues according to the following heuristic set, rate their severity, and suggest improvements.”
Reasoning approach: Before providing your responses, examine the interface and think of the interaction step-by-step: (1) Observe every given screenshot to understand the entire context. (2) Identify the UI elements, potential workflows and terminology used. (3) The observations should be compared against the heuristic set given, to identify possible heuristic violations. (4) For every possible issue, think of the reason why it is a problem and how it impacts usability. (5) Assign a severity rating for the identified issue. (6) Think of a potential improvement that can address the issue.
Heuristic set: Nielsen’s 10 heuristics. 1. Visibility of system status: The system should always keep users informed about what is going on, through appropriate feedback within reasonable time. 2. Match between system and the real world: The system should speak the users’ language, with words, phrases and concepts familiar to the user, rather than system-oriented terms. Follow real-world conventions, making information appear in a natural and logical order. 3. User control and freedom: Users often choose system functions by mistake and will need a clearly marked “emergency exit” to leave the unwanted state without having to go through an extended dialogue. Support undo and redo. 4. Consistency and standards: Users should not have to wonder whether different words, situations, or actions mean the same thing. Follow platform conventions. 5. Error prevention: Even better than good error messages is a careful design which prevents a problem from occurring in the first place. Either eliminate error-prone conditions or check for them and present users with a confirmation option before they commit to the action. 6. Recognition rather than recall: Minimize the user’s memory load by making objects, actions, and options visible. The user should not have to remember information from one part of the dialogue to another. Instructions for use of the system should be visible or easily retrievable whenever appropriate. 7. Flexibility and efficiency of use: Accelerators—unseen by the novice user—may often speed up the interaction for the expert user such that the system can cater to both inexperienced and experienced users. Allow users to tailor frequent actions. 8. Aesthetic and minimalist design: Dialogues should not contain information which is irrelevant or rarely needed. Every extra unit of information in a dialogue competes with the relevant units of information and diminishes their relative visibility. 9. Help users recognize, diagnose, and recover from errors: error messages should be expressed in plain language (no codes), precisely indicate the problem, and constructively suggest a solution. 10. Help and documentation: Even though it is better if the system can be used without documentation, it may be necessary to provide help and documentation. Any such information should be easy to search, focused on the user’s task, list concrete steps to be carried out, and not be too large.
Task description: Link artifacts and explore traceability; Prerequisites: open change set needed; You are in Heuristic evaluation test document #2: requirement 2.1 should derive from 1.2 (from Heuristic evaluation test document #1). Create the linkage from 2.1 to 1.2, create a comment for the artifact 2.1 and then open the links explorer to see the linkage.
Workspace context: A dedicated “Test’ workspace was created in DNG REM tool for this evaluation. Three requirements modules, containing some requirements’ artifacts.
Screenshots:
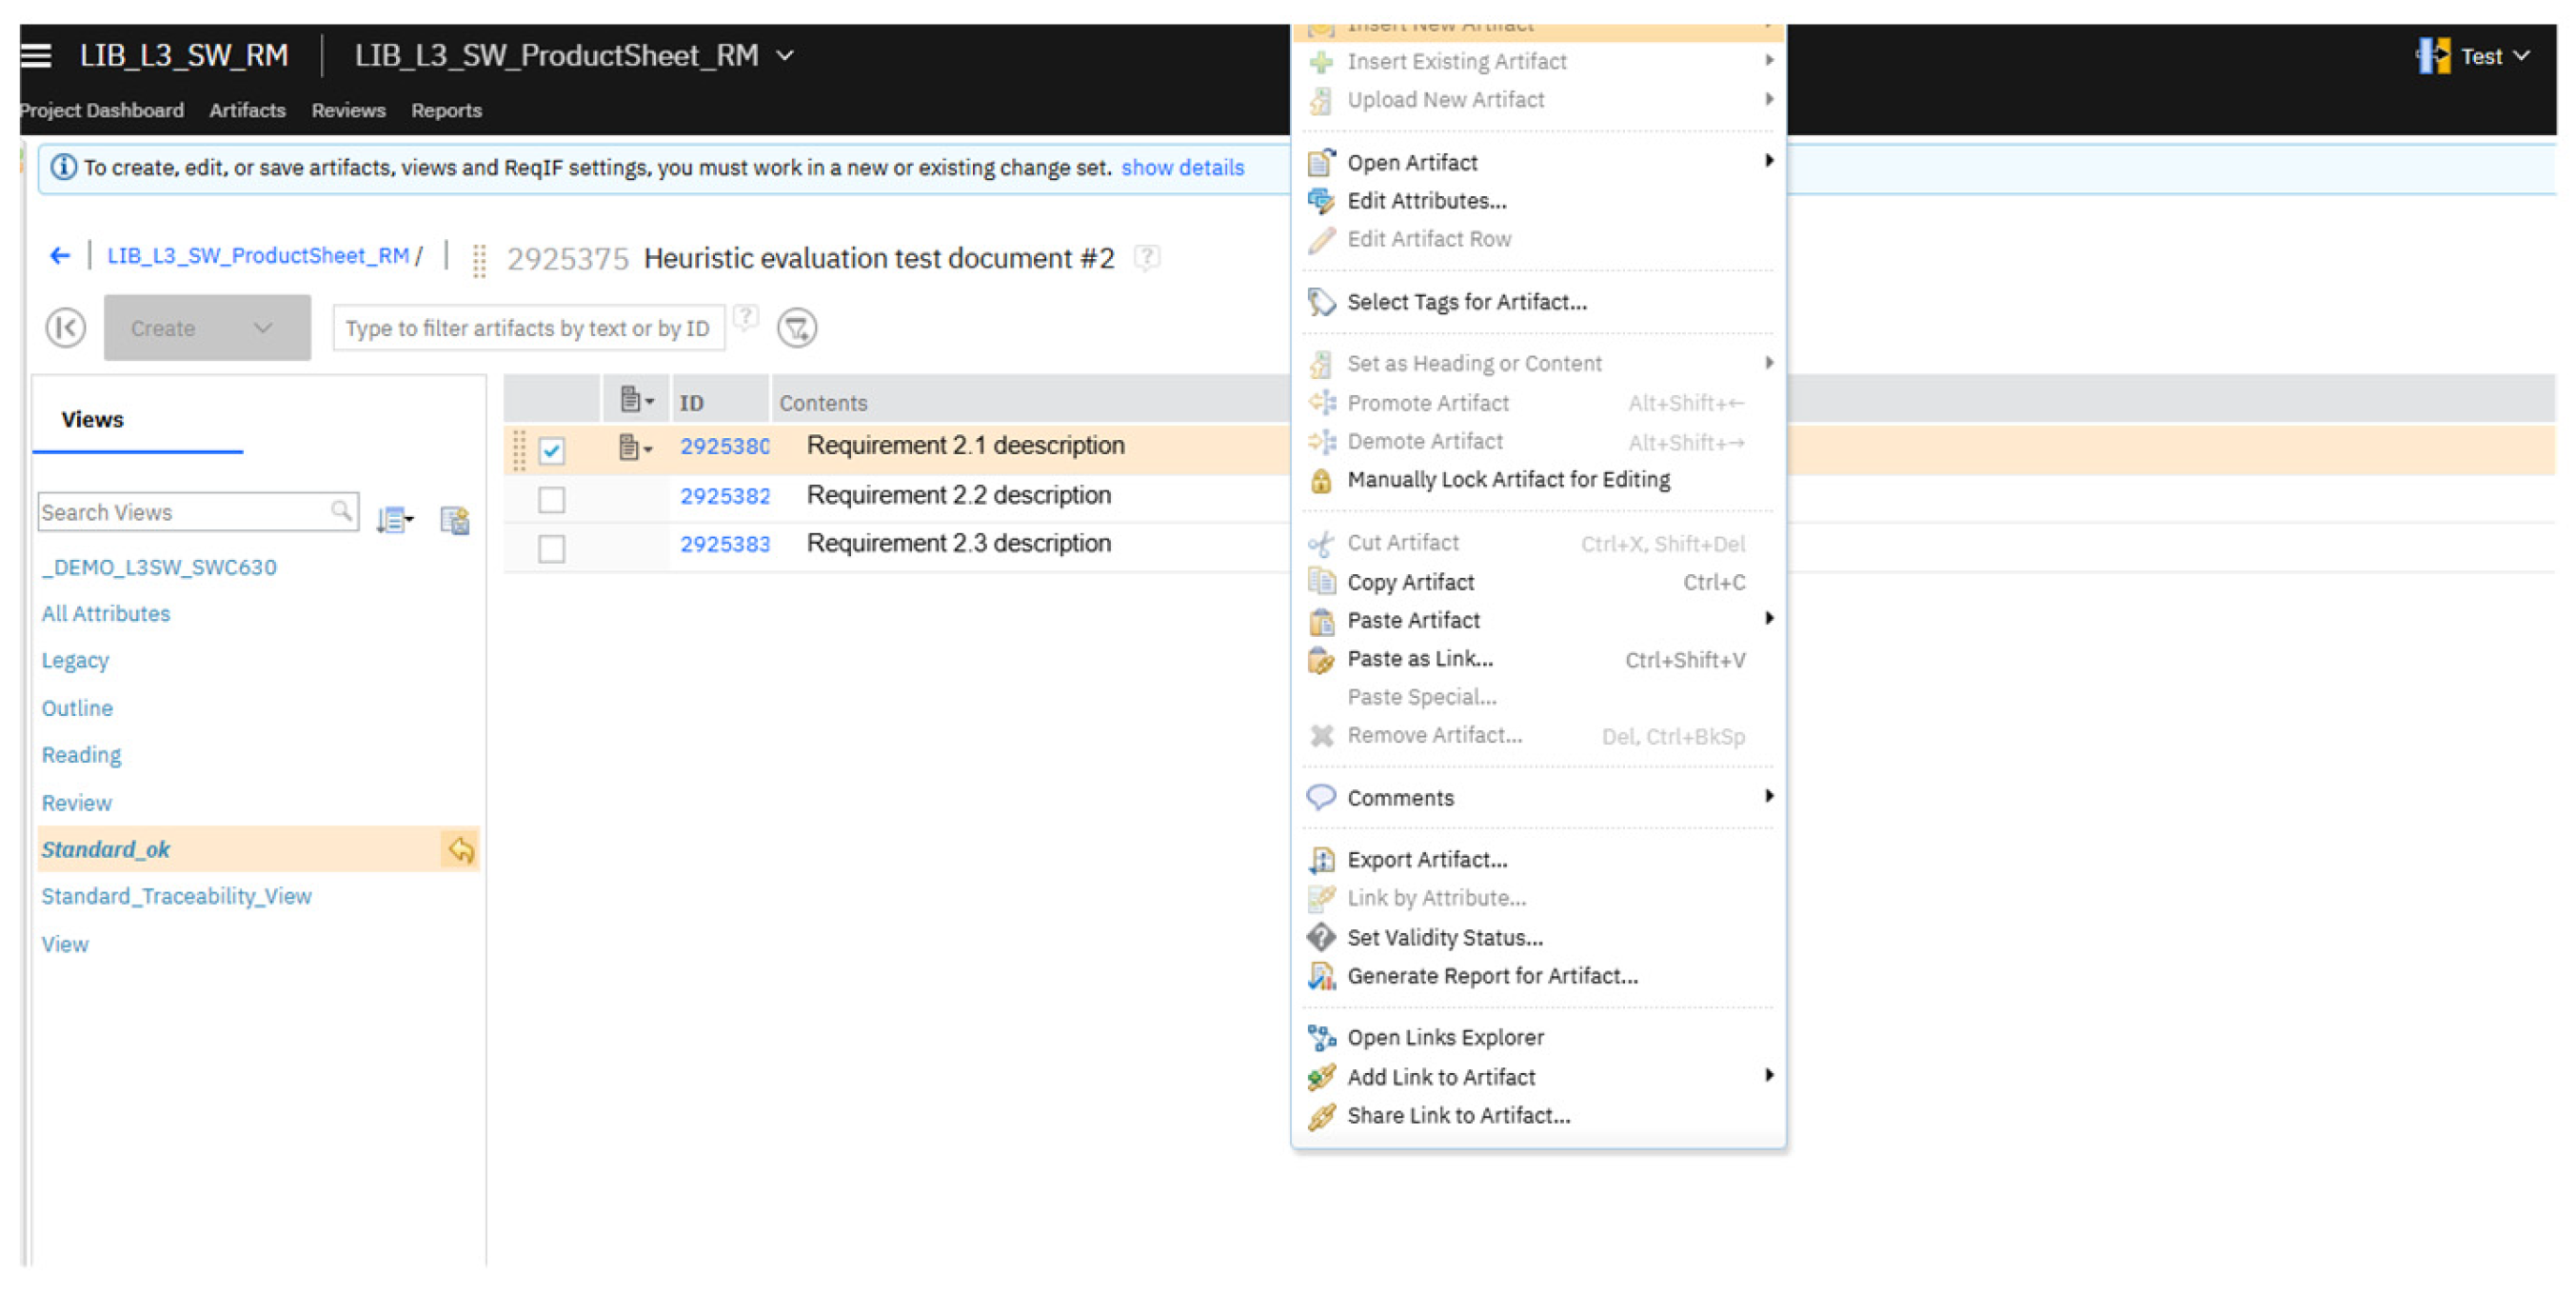
Output format:|Heuristic Violated|Issue Description|Severity (1–4)|Suggested Improvement|
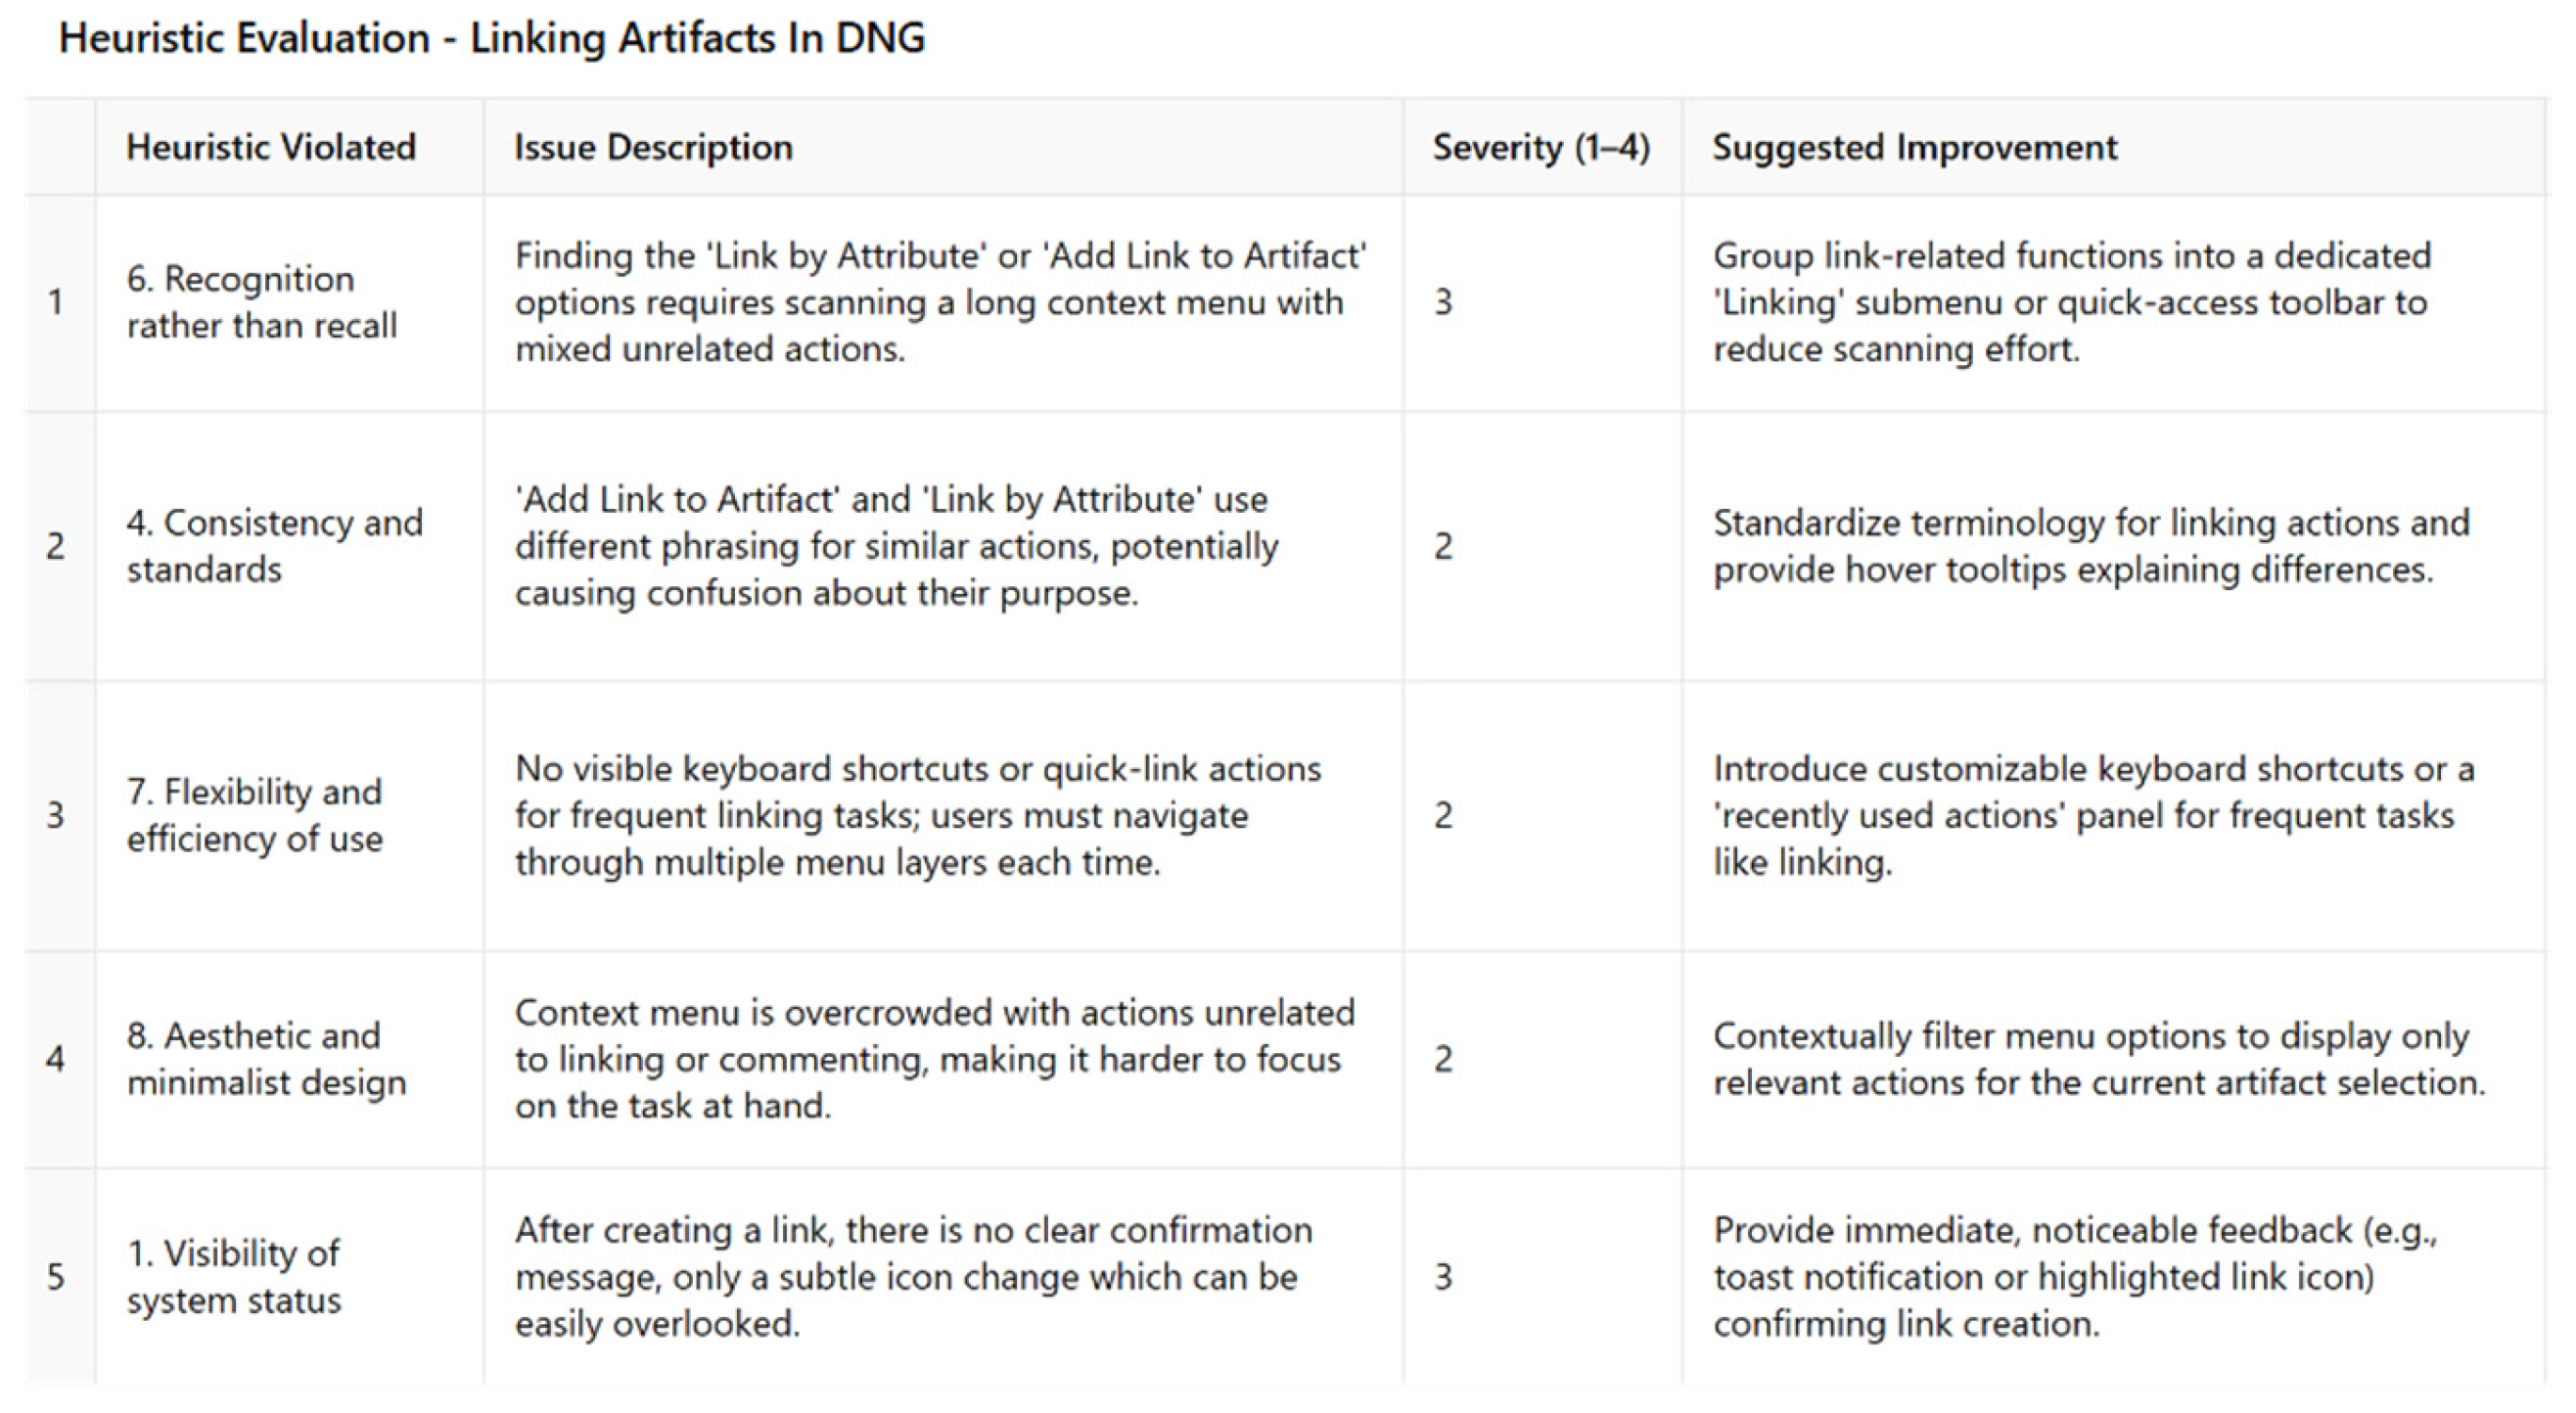
The ChatGPT-5 Output:
I’ve completed the heuristic evaluation for the linking and traceability task in DNG. The table now lists the main usability issues, their severity ratings, and proposed improvements for each heuristic violation.
Appendix A.3. Prompt for Task 3
Role: “Assume you are a usability expert evaluating an automotive Requirements Engineering Management tool (IBM DOORS Next Generation) for the automotive industry, via heuristic evaluation.”
Objective: “Your task is to identify usability issues according to the following heuristic set, rate their severity, and suggest improvements.”
Reasoning approach: Before providing your responses, examine the interface and think of the interaction step-by-step: (1) Observe every given screenshot to understand the entire context. (2) Identify the UI elements, potential workflows and terminology used. (3) The observations should be compared against the heuristic set given, to identify possible heuristic violations. (4) For every possible issue, think of the reason why it is a problem and how it impacts usability. (5) Assign a severity rating for the identified issue. (6) Think of a potential improvement that can address the issue.
Heuristic set: Nielsen’s 10 heuristics. 1. Visibility of system status: The system should always keep users informed about what is going on, through appropriate feedback within reasonable time. 2. Match between system and the real world: The system should speak the users’ language, with words, phrases and concepts familiar to the user, rather than system-oriented terms. Follow real-world conventions, making information appear in a natural and logical order. 3. User control and freedom: Users often choose system functions by mistake and will need a clearly marked “emergency exit” to leave the unwanted state without having to go through an extended dialogue. Support undo and redo. 4. Consistency and standards: Users should not have to wonder whether different words, situations, or actions mean the same thing. Follow platform conventions. 5. Error prevention: Even better than good error messages is a careful design which prevents a problem from occurring in the first place. Either eliminate error-prone conditions or check for them and present users with a confirmation option before they commit to the action. 6. Recognition rather than recall: Minimize the user’s memory load by making objects, actions, and options visible. The user should not have to remember information from one part of the dialogue to another. Instructions for use of the system should be visible or easily retrievable whenever appropriate. 7. Flexibility and efficiency of use: Accelerators—unseen by the novice user—may often speed up the interaction for the expert user such that the system can cater to both inexperienced and experienced users. Allow users to tailor frequent actions. 8. Aesthetic and minimalist design: Dialogues should not contain information which is irrelevant or rarely needed. Every extra unit of information in a dialogue competes with the relevant units of information and diminishes their relative visibility. 9. Help users recognize, diagnose, and recover from errors: error messages should be expressed in plain language (no codes), precisely indicate the problem, and constructively suggest a solution. 10. Help and documentation: Even though it is better if the system can be used without documentation, it may be necessary to provide help and documentation. Any such information should be easy to search, focused on the user’s task, list concrete steps to be carried out, and not be too large.
Task description: Edit an artifact; Prerequisites: open change set needed; Modify “Requirement 3.1” from module “Heuristic evaluation document #3”. Deliver the change set. Now, track this modification of the requirement artifact.
Workspace context: A dedicated “Test’ workspace was created in DNG REM tool for this evaluation. Three requirements modules, containing some requirements artifacts.
Screenshots:
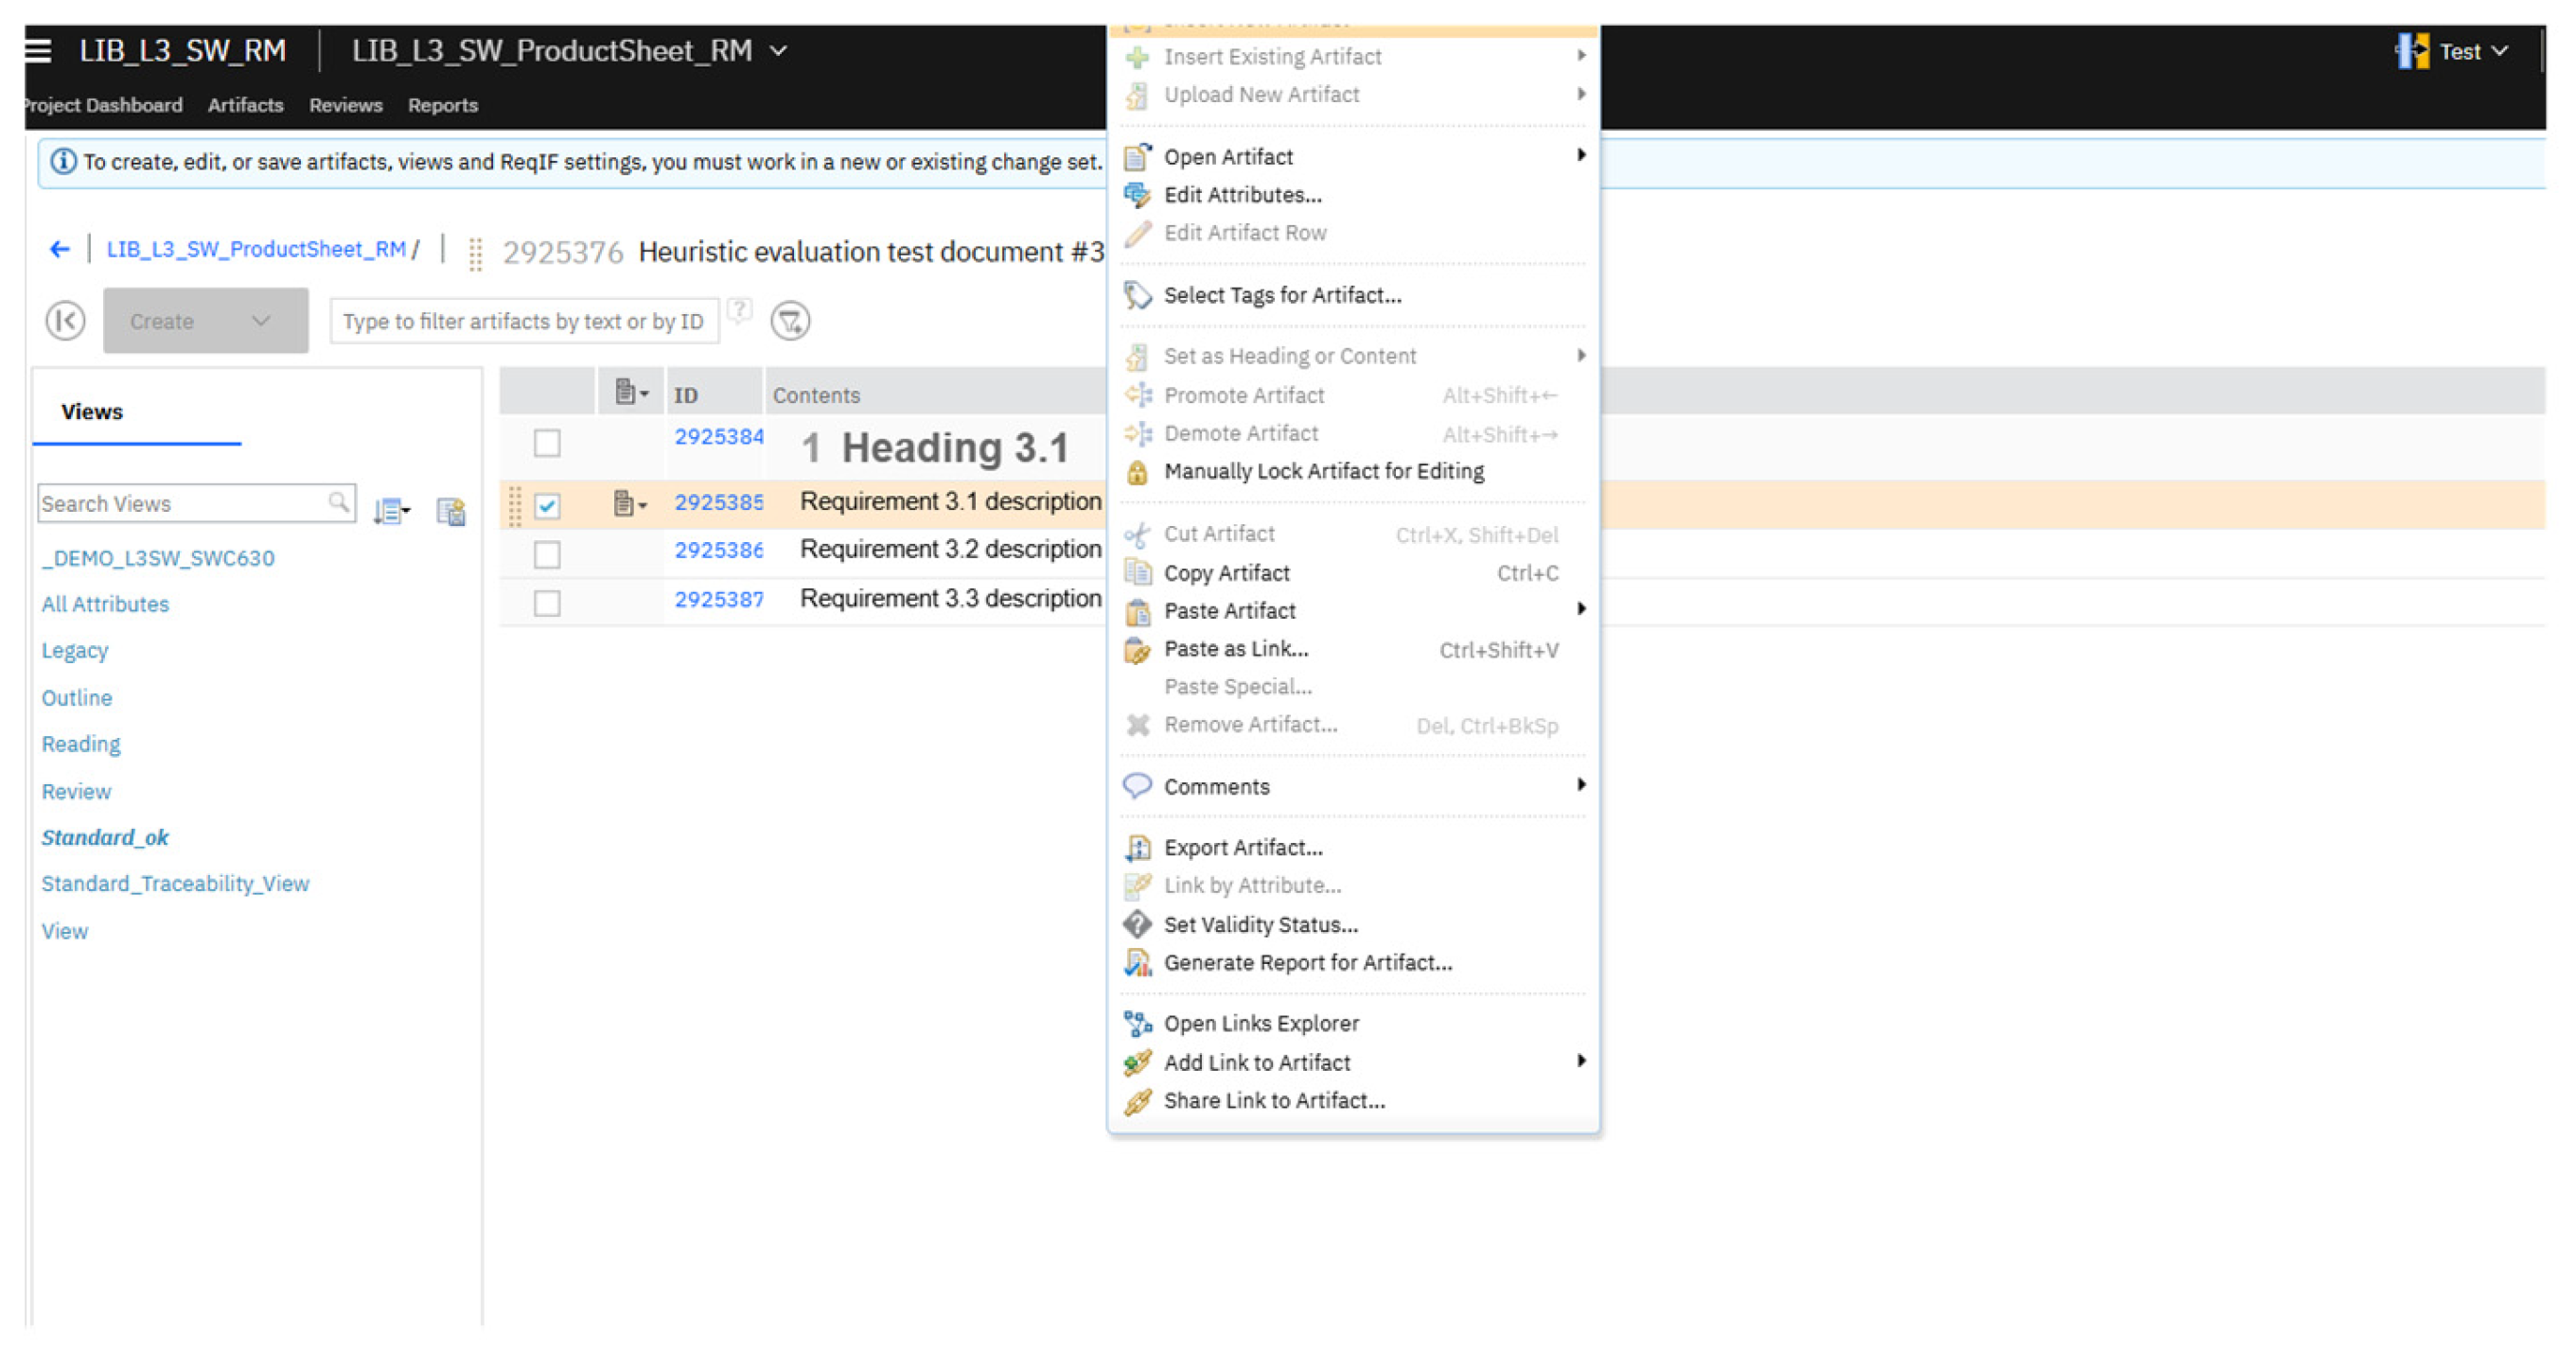
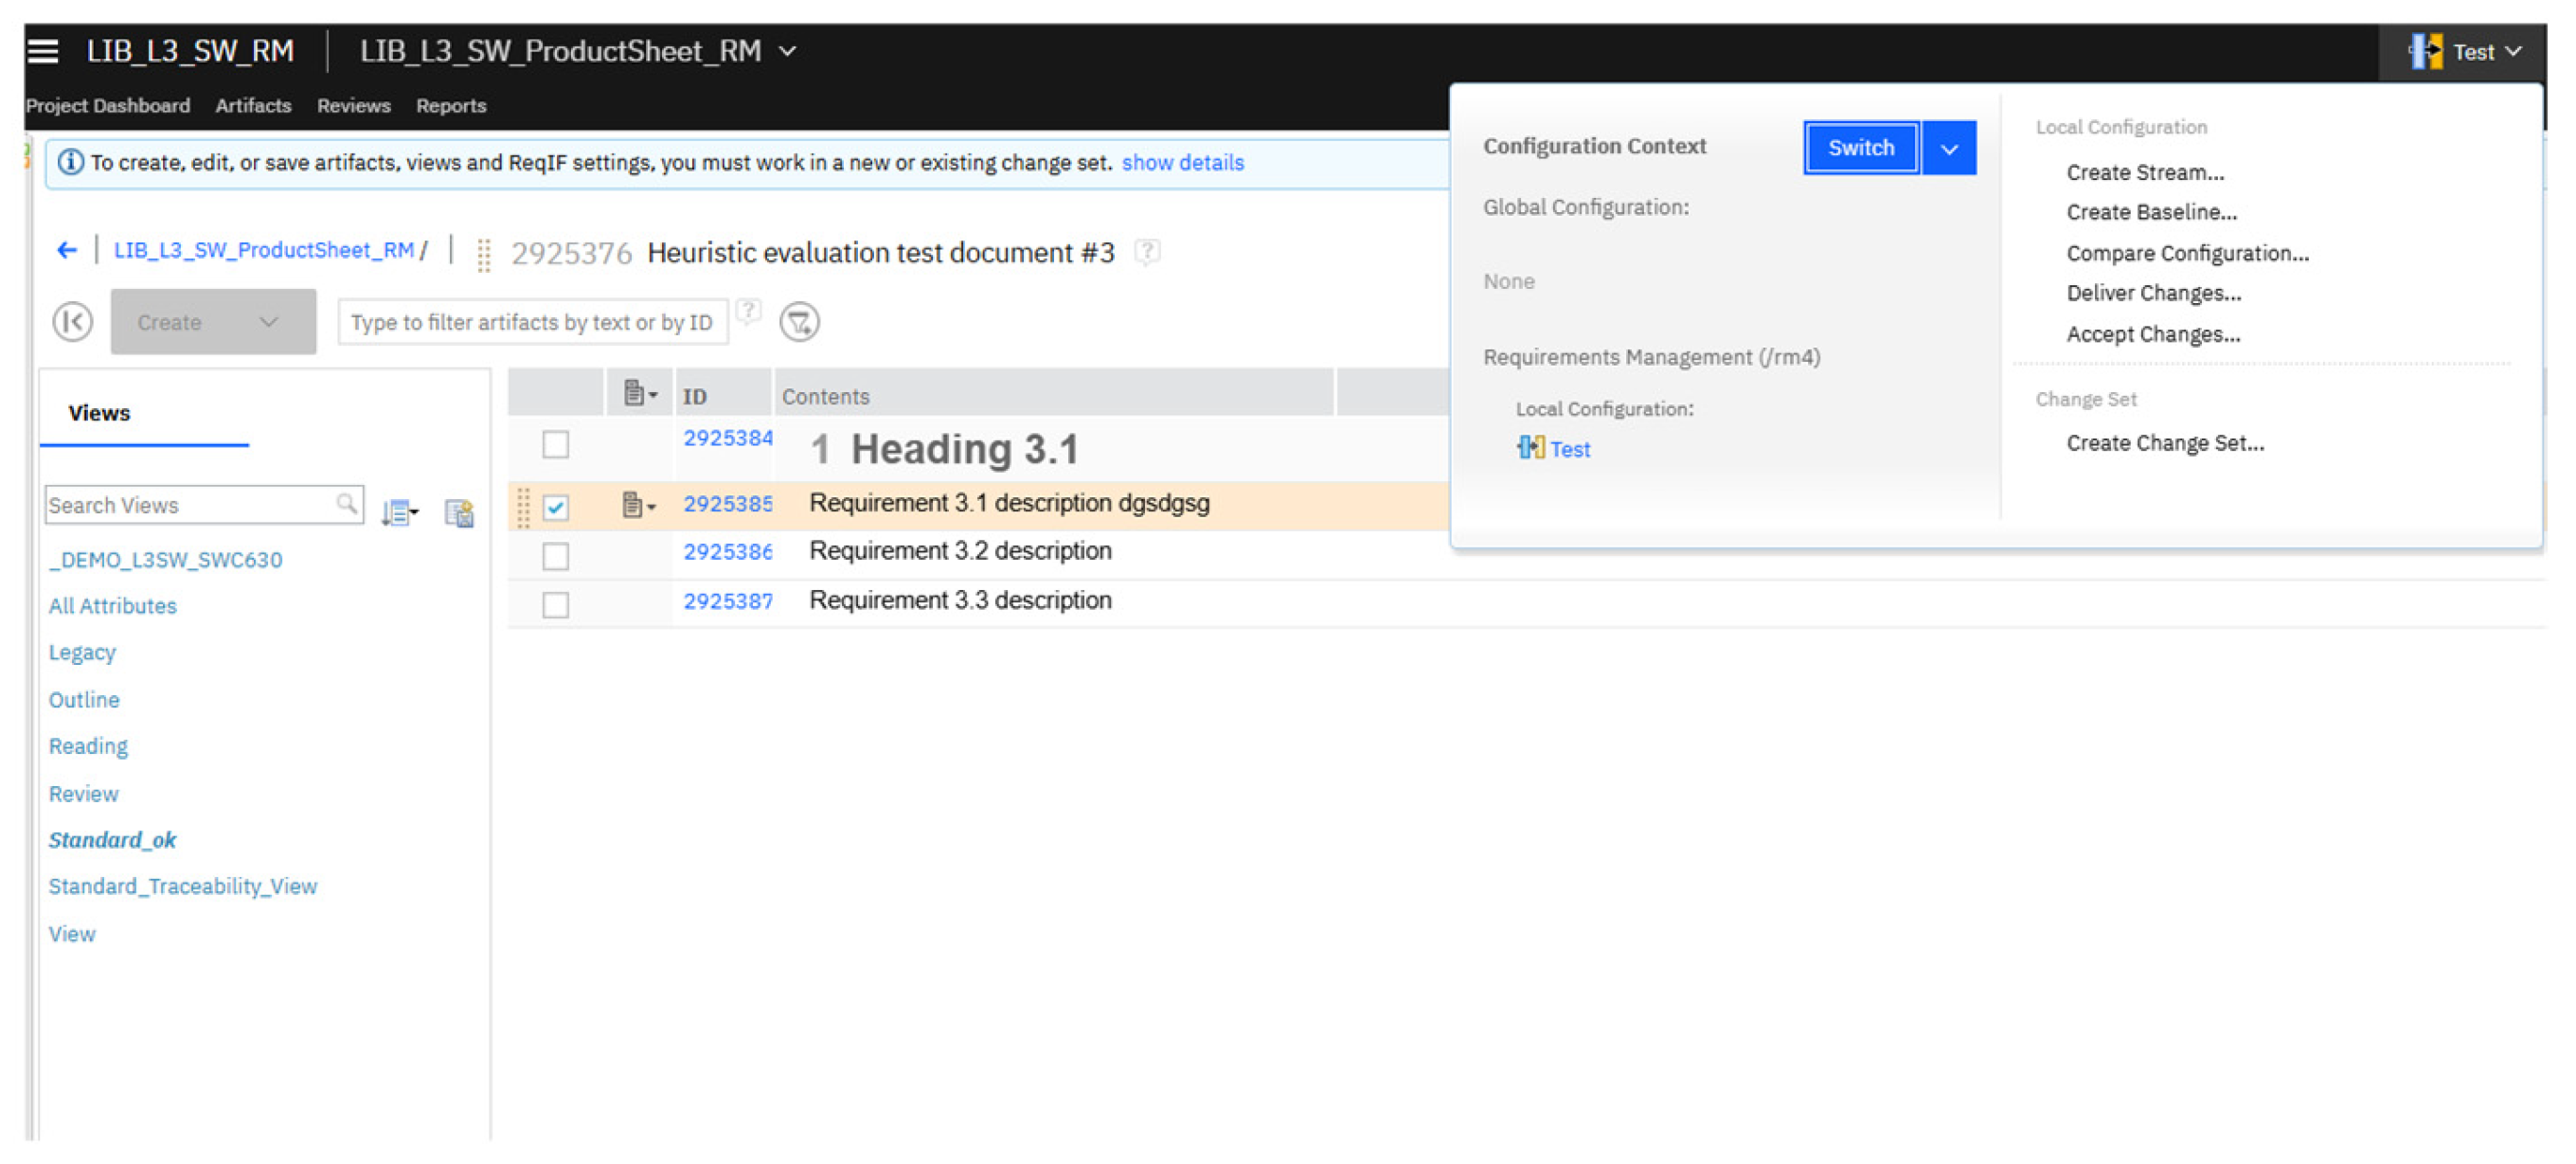
Output format:|Heuristic Violated|Issue Description|Severity (1–4)|Suggested Improvement|
The ChatGPT-5 Output:
I’ve prepared the heuristic evaluation table for the “Edit an artifact” task, showing each usability issue found, its severity, and specific recommendations for improvement.
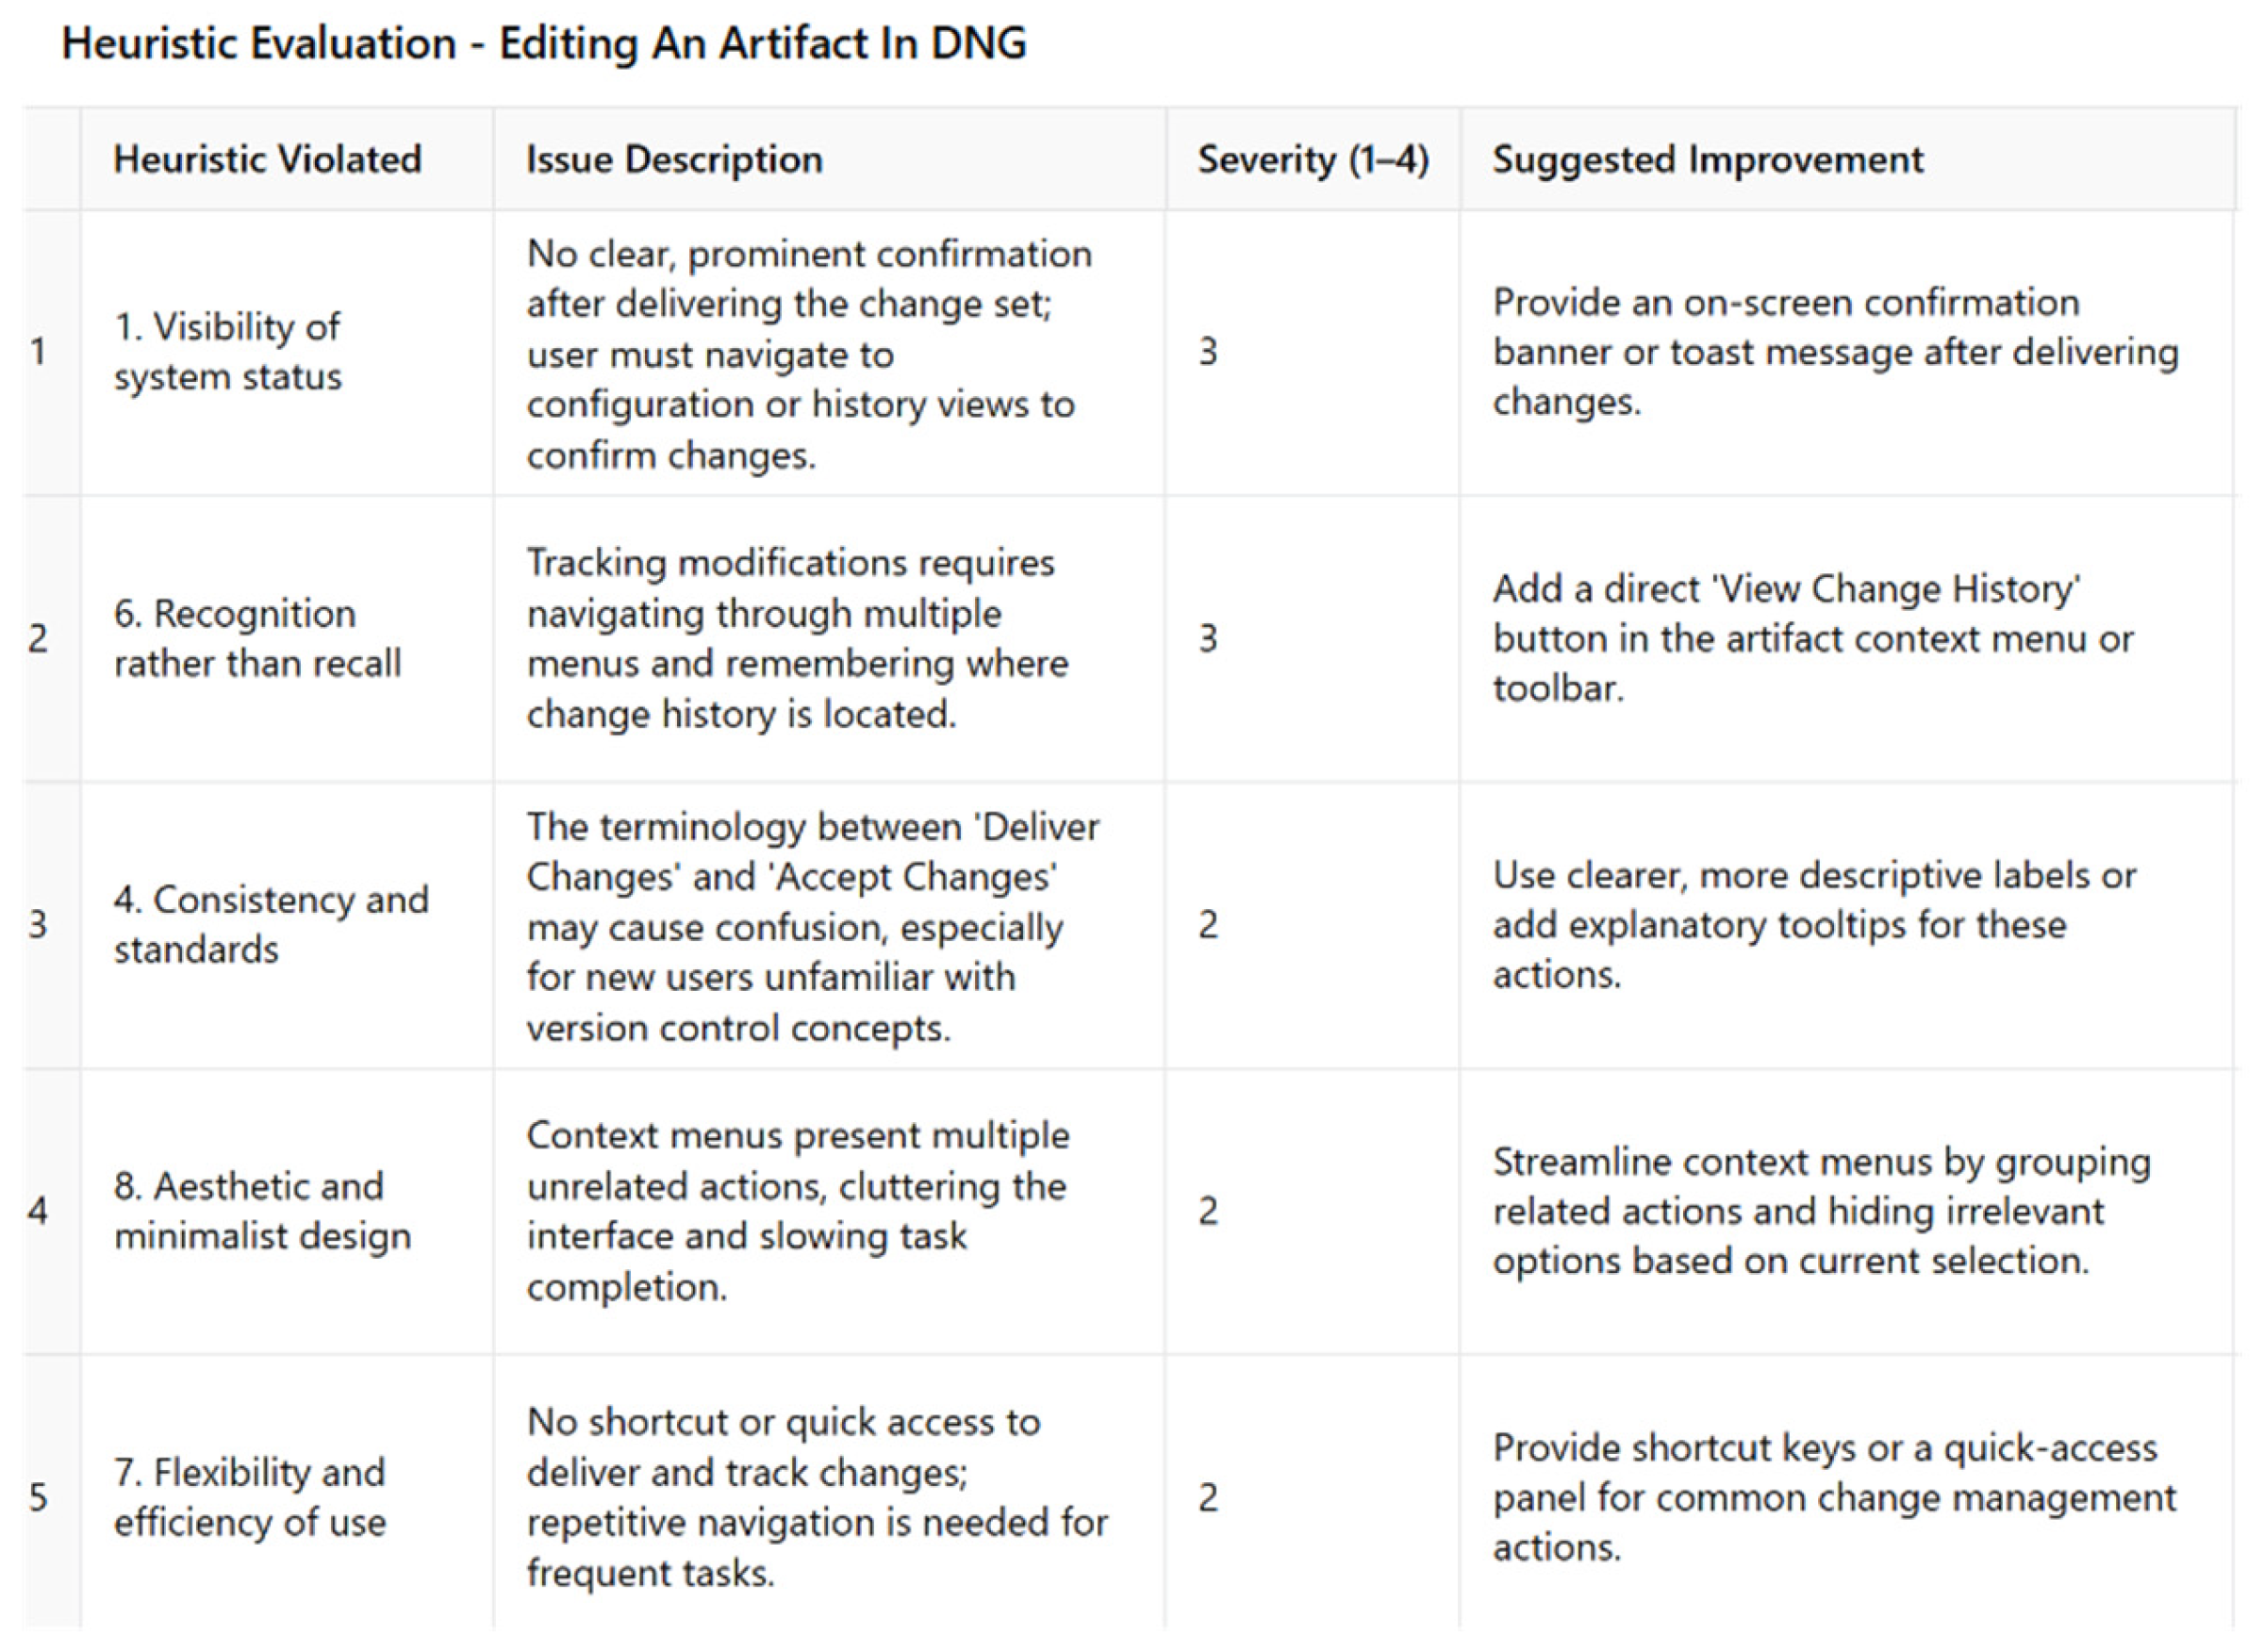
Appendix A.4. Prompt for Task 4
Role: “Assume you are a usability expert evaluating an automotive Requirements Engineering Management tool (IBM DOORS Next Generation) for the automotive industry, via heuristic evaluation.”
Objective: “Your task is to identify usability issues according to the following heuristic set, rate their severity, and suggest improvements.”
Reasoning approach: Before providing your responses, examine the interface and think of the interaction step-by-step: (1) Observe every given screenshot to understand the entire context. (2) Identify the UI elements, potential workflows and terminology used. (3) The observations should be compared against the heuristic set given, to identify possible heuristic violations. (4) For every possible issue, think of the reason why it is a problem and how it impacts usability. (5) Assign a severity rating for the identified issue. (6) Think of a potential improvement that can address the issue.
Heuristic set: Nielsen’s 10 heuristics. 1. Visibility of system status: The system should always keep users informed about what is going on, through appropriate feedback within reasonable time. 2. Match between system and the real world: The system should speak the users’ language, with words, phrases and concepts familiar to the user, rather than system-oriented terms. Follow real-world conventions, making information appear in a natural and logical order. 3. User control and freedom: Users often choose system functions by mistake and will need a clearly marked “emergency exit” to leave the unwanted state without having to go through an extended dialogue. Support undo and redo. 4. Consistency and standards: Users should not have to wonder whether different words, situations, or actions mean the same thing. Follow platform conventions. 5. Error prevention: Even better than good error messages is a careful design which prevents a problem from occurring in the first place. Either eliminate error-prone conditions or check for them and present users with a confirmation option before they commit to the action. 6. Recognition rather than recall: Minimize the user’s memory load by making objects, actions, and options visible. The user should not have to remember information from one part of the dialogue to another. Instructions for use of the system should be visible or easily retrievable whenever appropriate. 7. Flexibility and efficiency of use: Accelerators—unseen by the novice user—may often speed up the interaction for the expert user such that the system can cater to both inexperienced and experienced users. Allow users to tailor frequent actions. 8. Aesthetic and minimalist design: Dialogues should not contain information which is irrelevant or rarely needed. Every extra unit of information in a dialogue competes with the relevant units of information and diminishes their relative visibility. 9. Help users recognize, diagnose, and recover from errors: error messages should be expressed in plain language (no codes), precisely indicate the problem, and constructively suggest a solution. 10. Help and documentation: Even though it is better if the system can be used without documentation, it may be necessary to provide help and documentation. Any such information should be easy to search, focused on the user’s task, list concrete steps to be carried out, and not be too large.
Task description: Search and filter requirements; Prerequisites: open change set needed; Filter the requirements from “Heuristic evaluation document #1”, based on the Released state. Create a personal view with the filtered artifacts.
Workspace context: A dedicated “Test’ workspace was created in DNG REM tool for this evaluation. Three requirements modules, containing some requirements’ artifacts.
Screenshots:
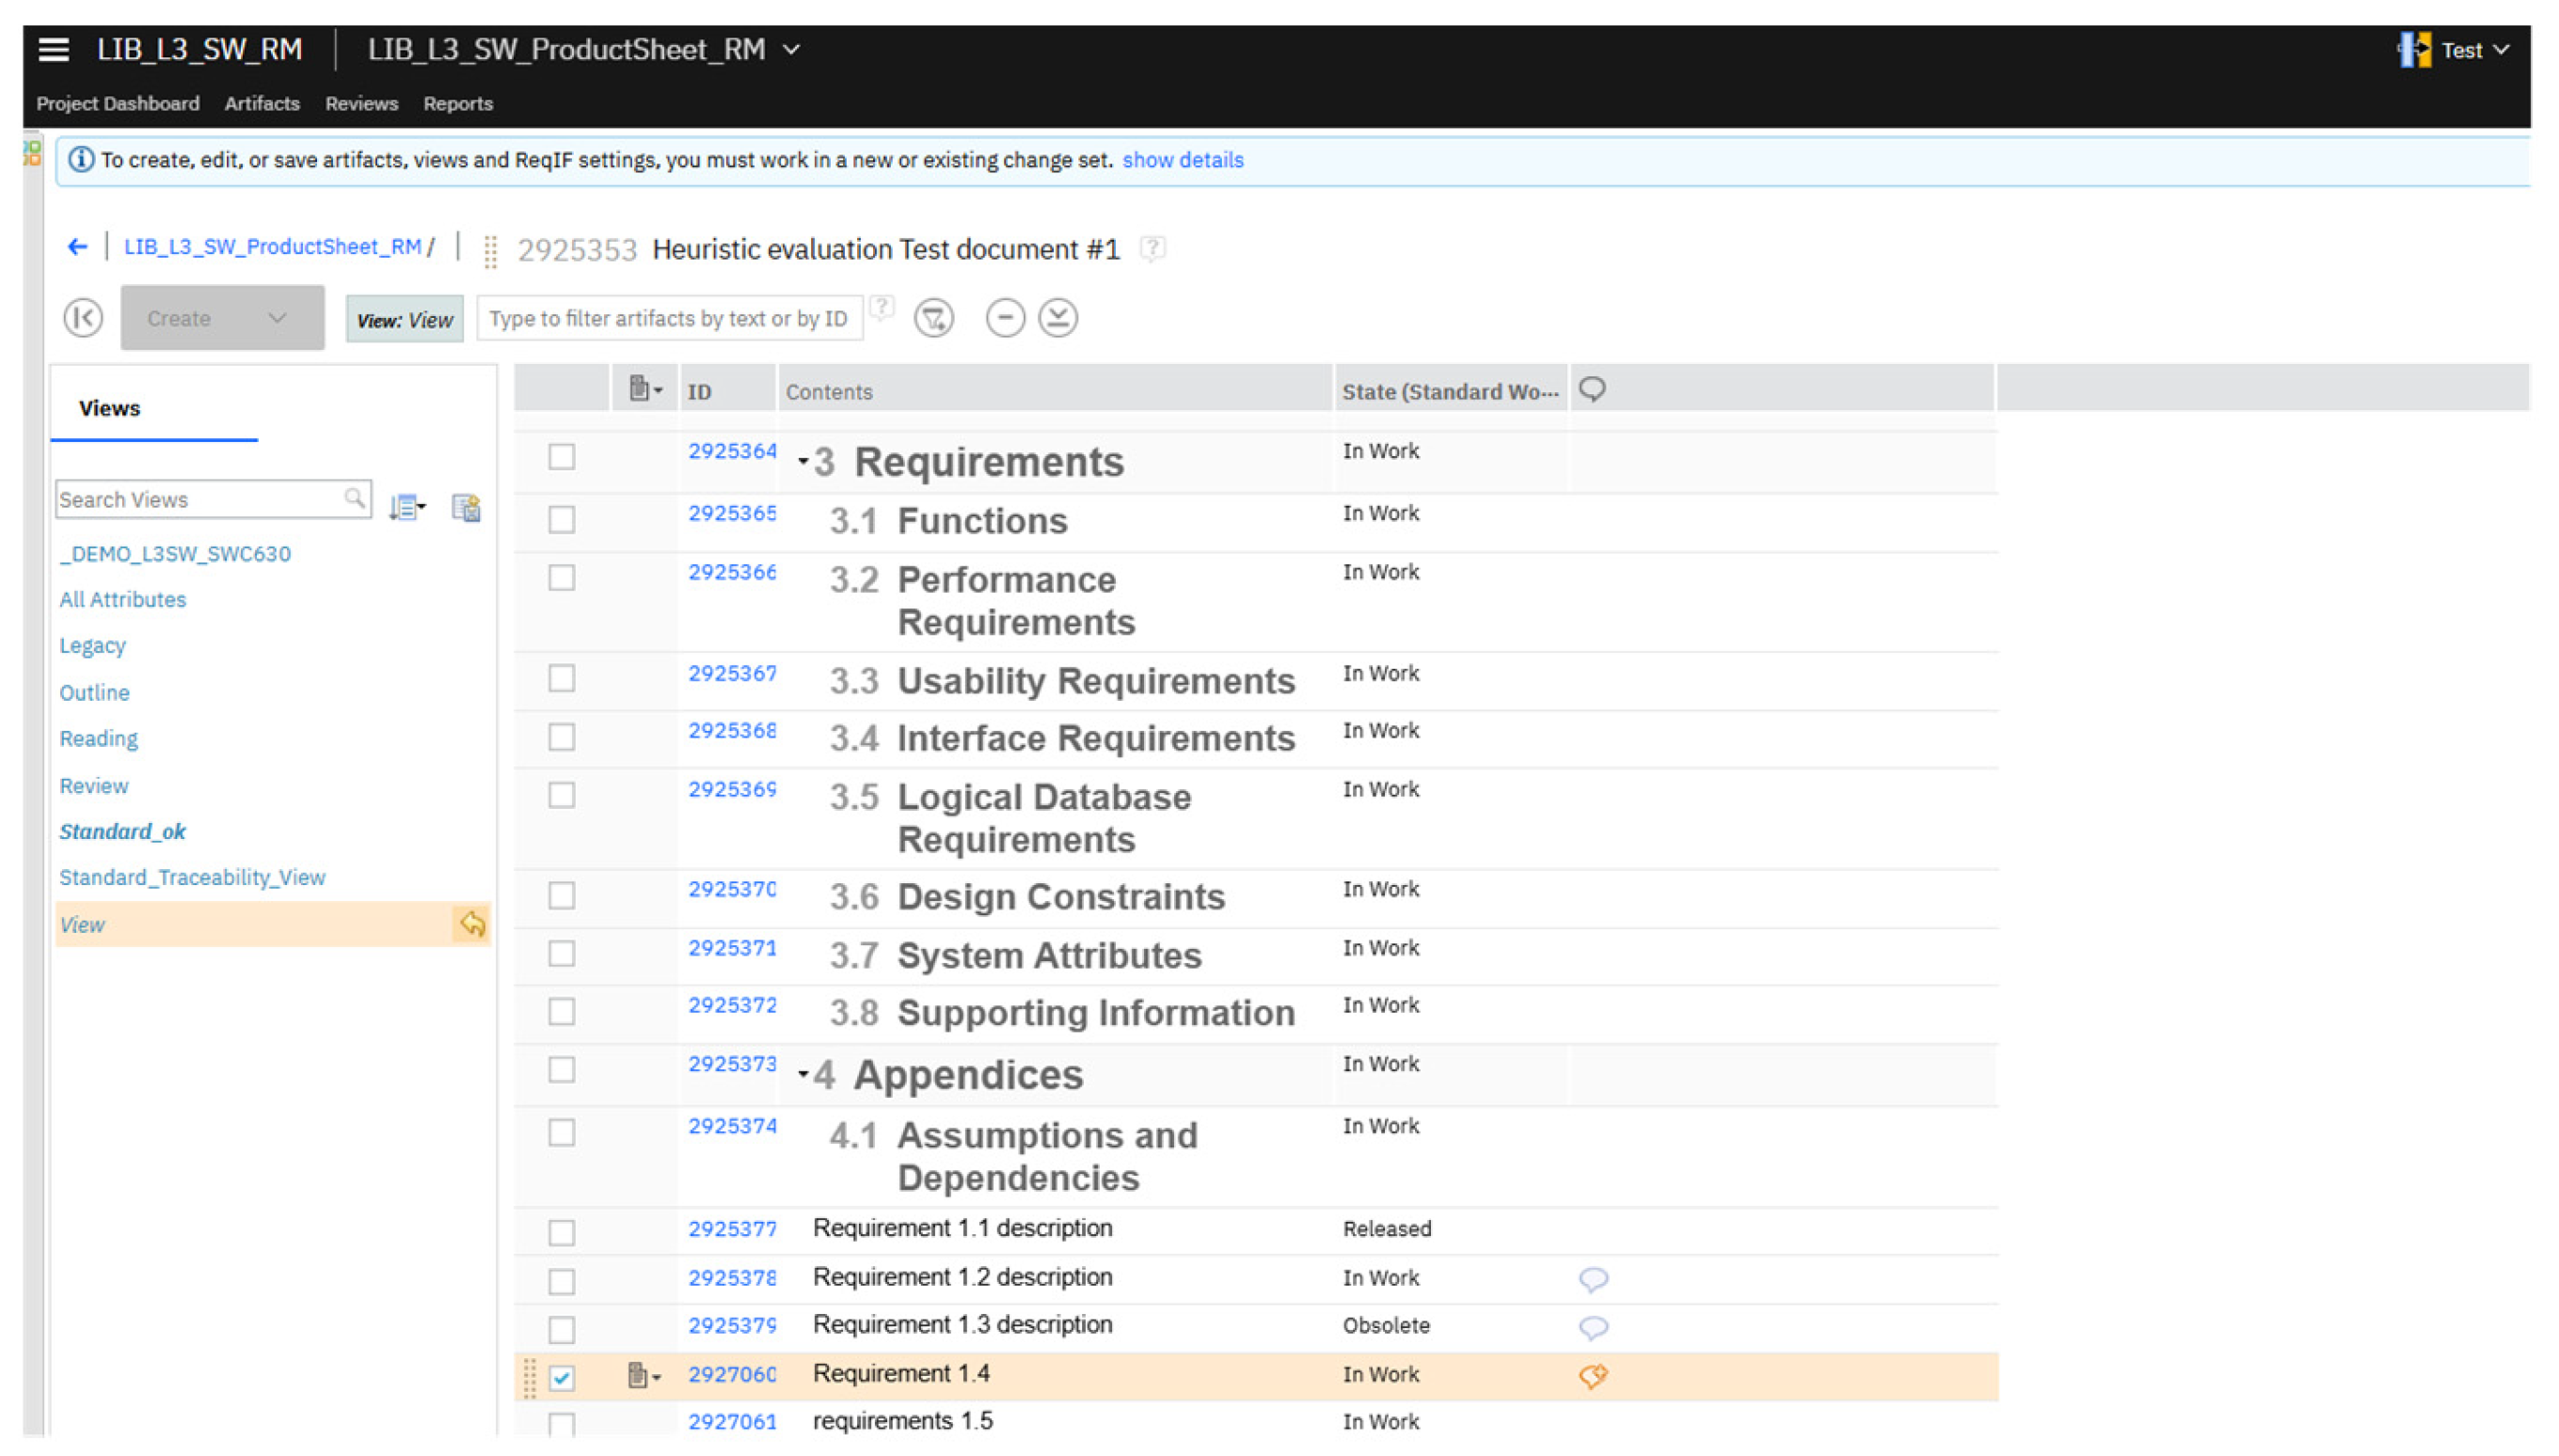
Output format:|Heuristic Violated|Issue Description|Severity (1–4)|Suggested Improvement|
The ChatGPT-5 Output:
Here’s the heuristic evaluation for the Search and filter requirements task in DNG:
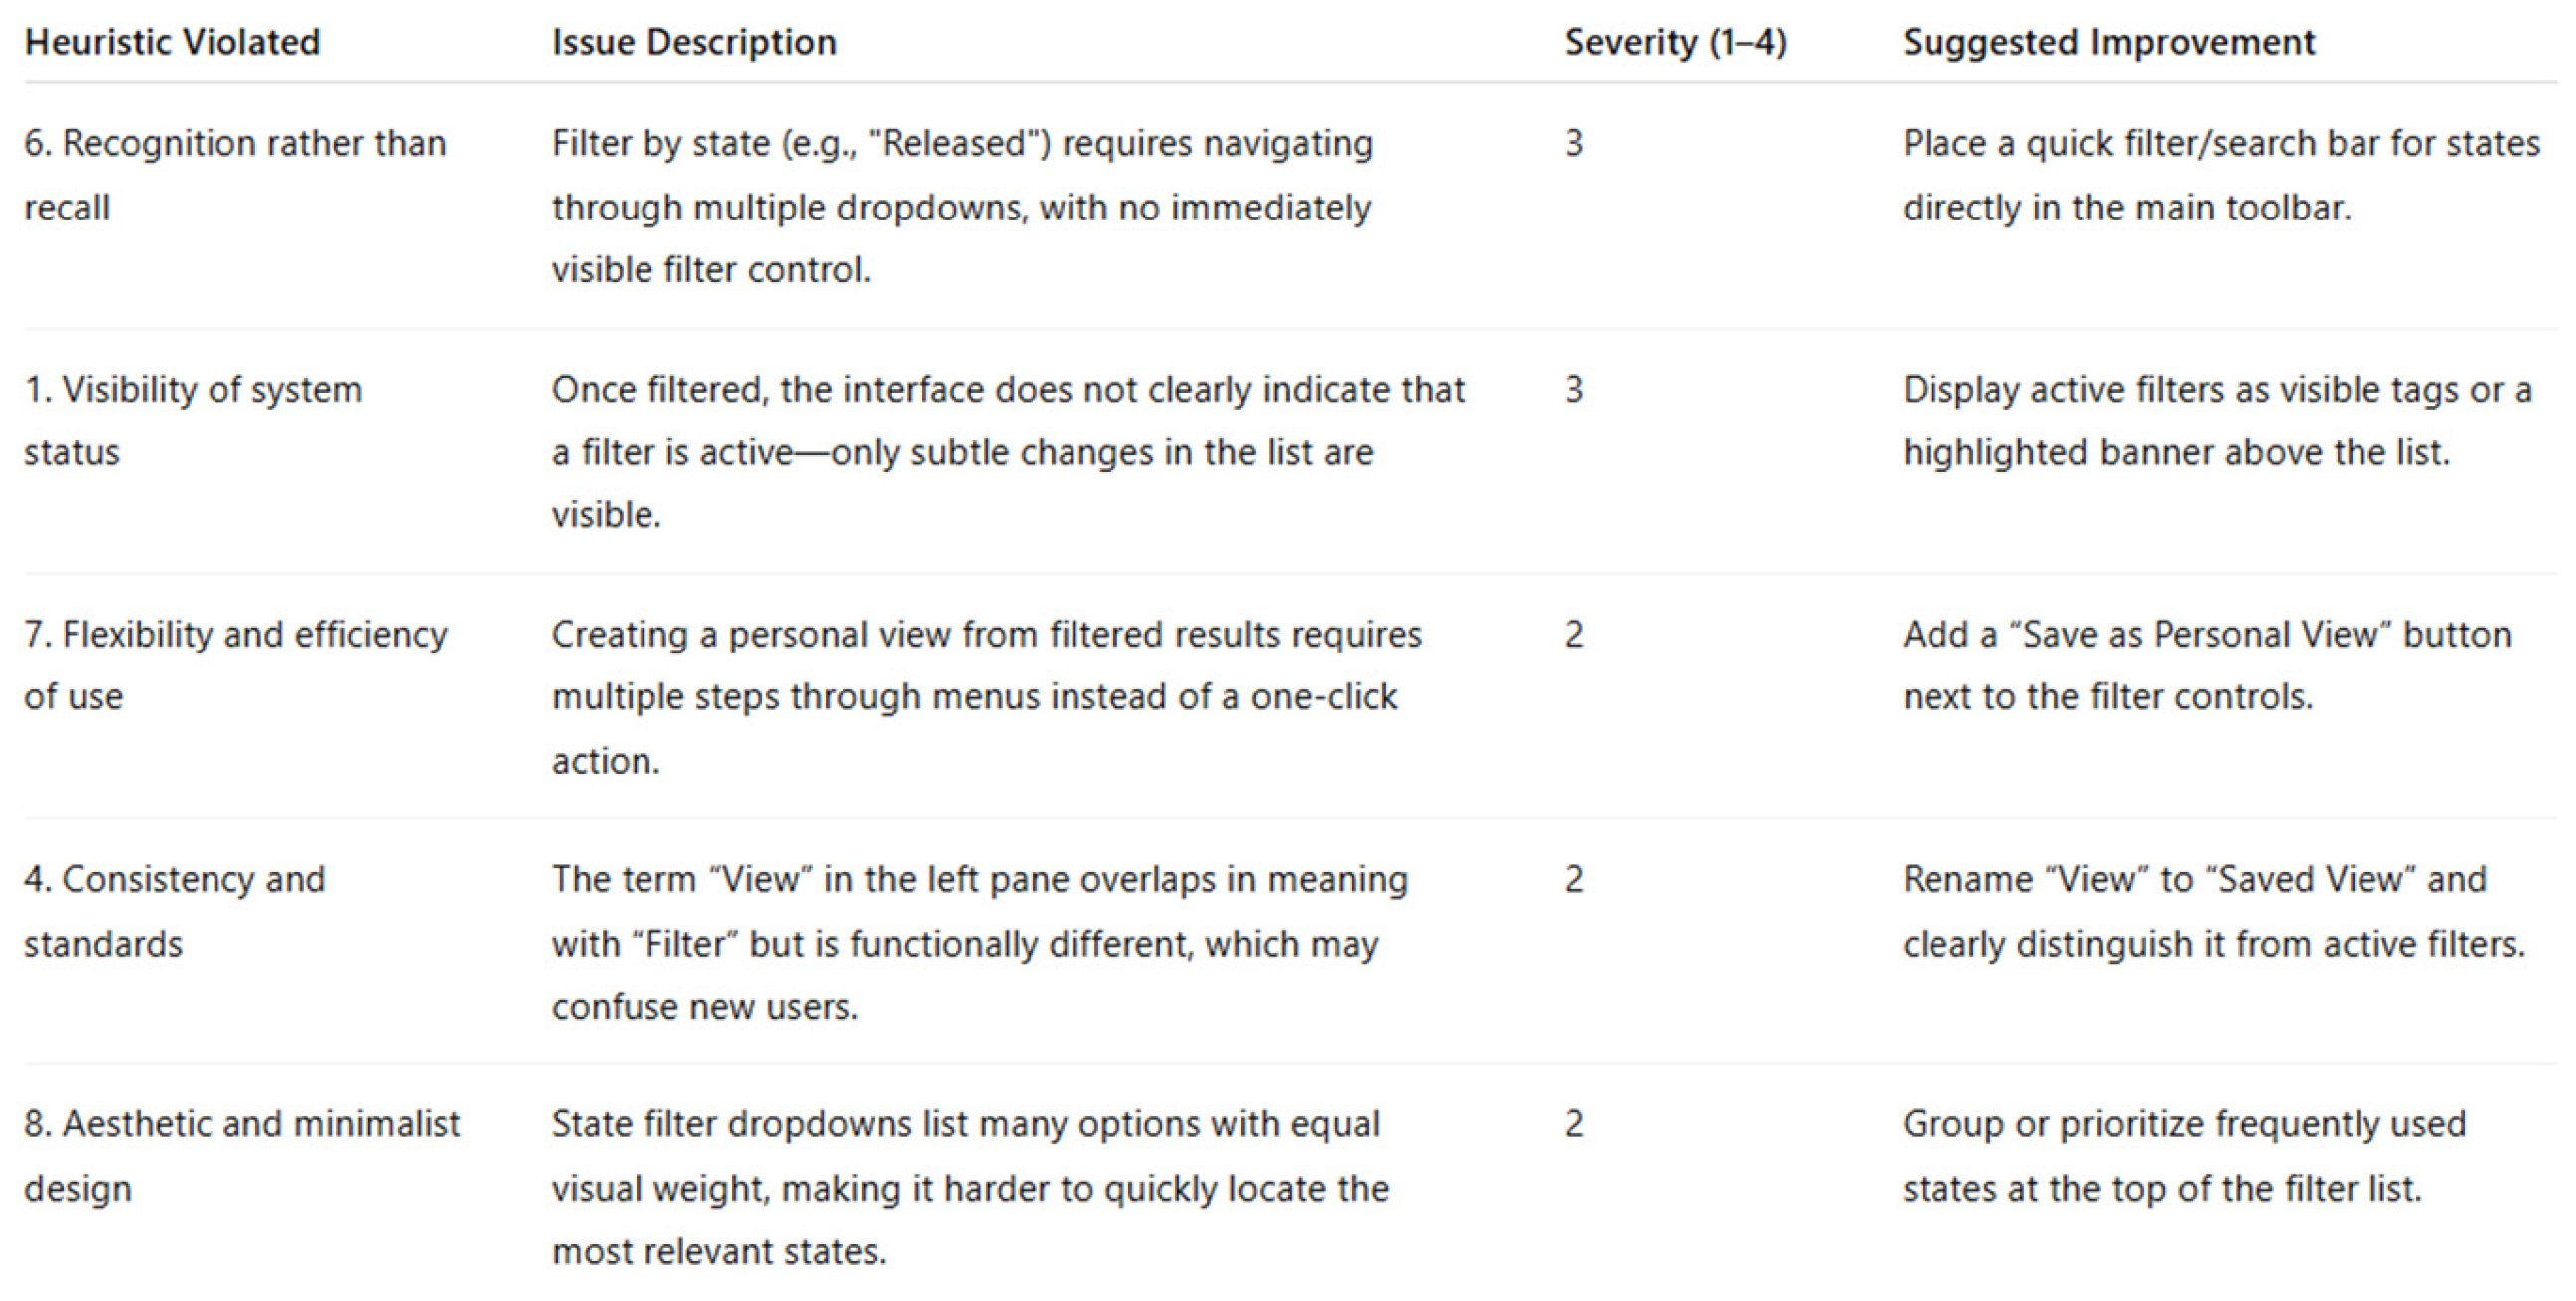
Appendix A.5. Prompt for Task 5
Role: “Assume you are a usability expert evaluating an automotive Requirements Engineering Management tool (IBM DOORS Next Generation) for the automotive industry, via heuristic evaluation.”
Objective: “Your task is to identify usability issues according to the following heuristic set, rate their severity, and suggest improvements.”
Reasoning approach: Before providing your responses, examine the interface and think of the interaction step-by-step: (1) Observe every given screenshot to understand the entire context. (2) Identify the UI elements, potential workflows and terminology used. (3) The observations should be compared against the heuristic set given, to identify possible heuristic violations. (4) For every possible issue, think of the reason why it is a problem and how it impacts usability. (5) Assign a severity rating for the identified issue. (6) Think of a potential improvement that can address the issue.
Heuristic set: Nielsen’s 10 heuristics. 1. Visibility of system status: The system should always keep users informed about what is going on, through appropriate feedback within reasonable time. 2. Match between system and the real world: The system should speak the users’ language, with words, phrases and concepts familiar to the user, rather than system-oriented terms. Follow real-world conventions, making information appear in a natural and logical order. 3. User control and freedom: Users often choose system functions by mistake and will need a clearly marked “emergency exit” to leave the unwanted state without having to go through an extended dialogue. Support undo and redo. 4. Consistency and standards: Users should not have to wonder whether different words, situations, or actions mean the same thing. Follow platform conventions. 5. Error prevention: Even better than good error messages is a careful design which prevents a problem from occurring in the first place. Either eliminate error-prone conditions or check for them and present users with a confirmation option before they commit to the action. 6. Recognition rather than recall: Minimize the user’s memory load by making objects, actions, and options visible. The user should not have to remember information from one part of the dialogue to another. Instructions for use of the system should be visible or easily retrievable whenever appropriate. 7. Flexibility and efficiency of use: Accelerators—unseen by the novice user—may often speed up the interaction for the expert user such that the system can cater to both inexperienced and experienced users. Allow users to tailor frequent actions. 8. Aesthetic and minimalist design: Dialogues should not contain information which is irrelevant or rarely needed. Every extra unit of information in a dialogue competes with the relevant units of information and diminishes their relative visibility. 9. Help users recognize, diagnose, and recover from errors: error messages should be expressed in plain language (no codes), precisely indicate the problem, and constructively suggest a solution. 10. Help and documentation: Even though it is better if the system can be used without documentation, it may be necessary to provide help and documentation. Any such information should be easy to search, focused on the user’s task, list concrete steps to be carried out, and not be too large.
Task description: Access and compare baselines; Prerequisites: outside a change set. Create a baseline for Heuristic evaluation test document #2. Compare the created baseline with the last one existent.
Workspace context: A dedicated “Test’ workspace was created in DNG REM tool for this evaluation. Three requirements modules, containing some requirements’ artifacts.
Screenshots:
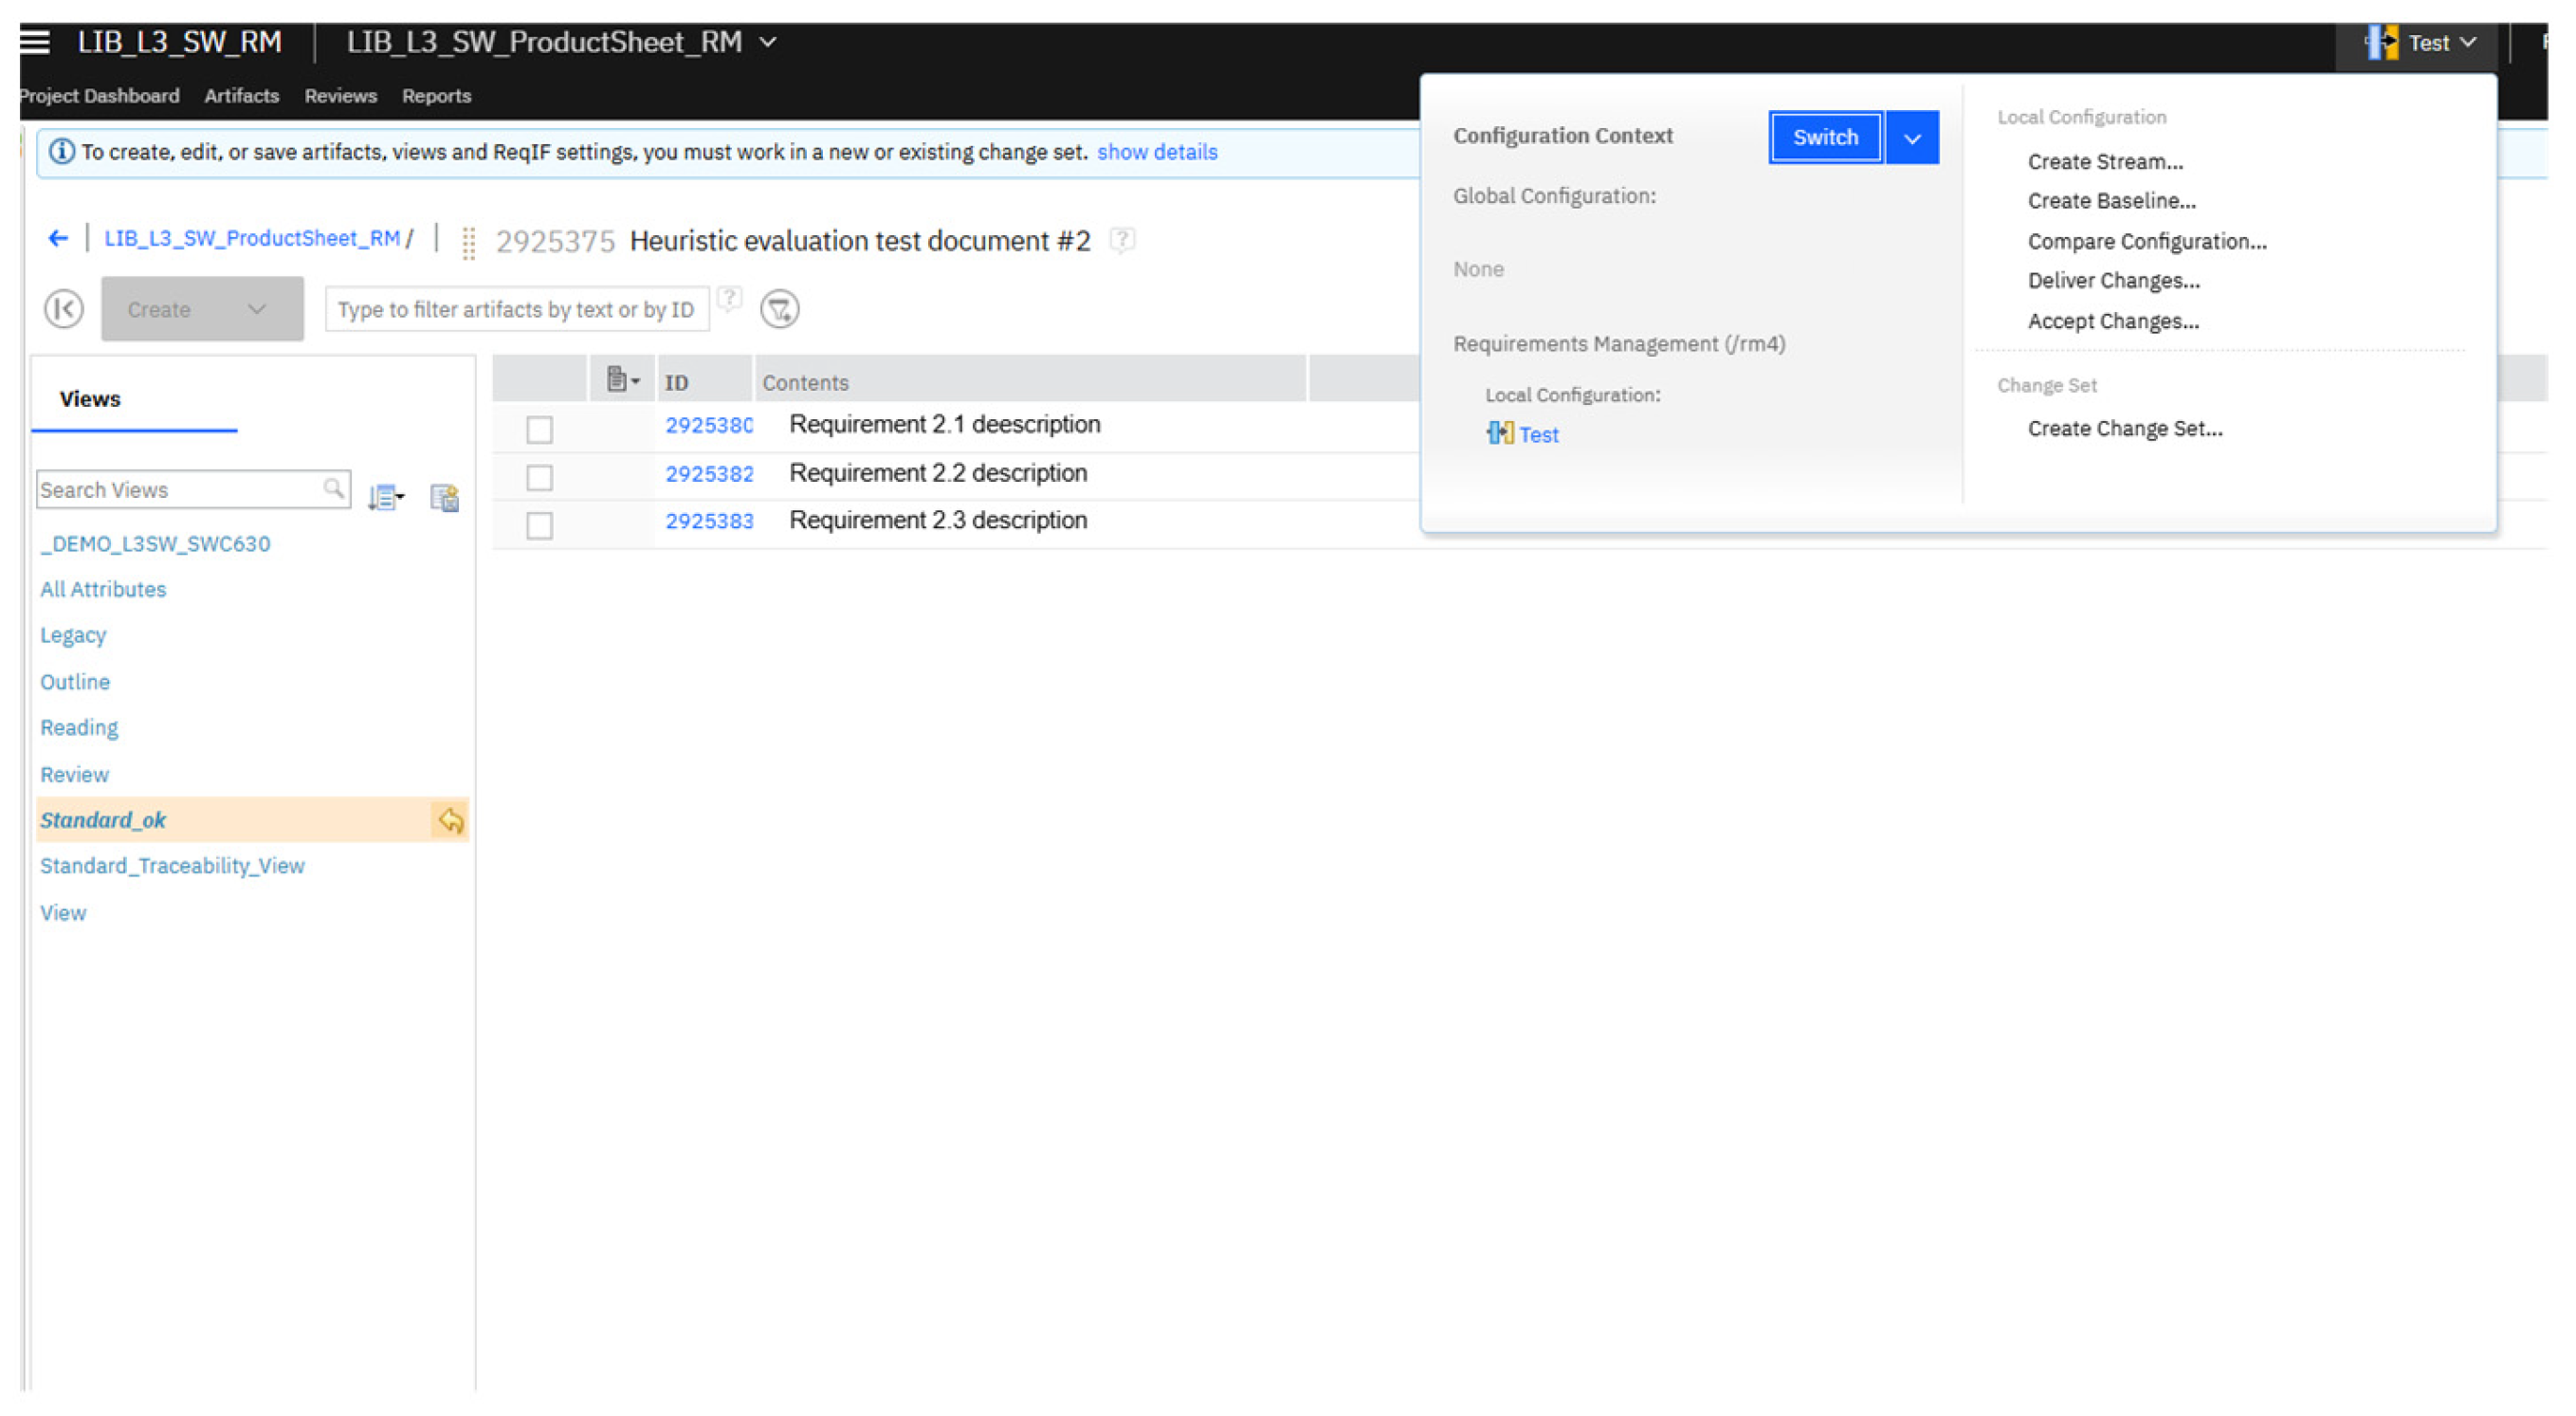
Output format:|Heuristic Violated|Issue Description|Severity (1–4)|Suggested Improvement|
The ChatGPT-5 Output:
Here’s the heuristic evaluation for Task 5: Access and compare baselines in DNG, aligned with Nielsen’s:
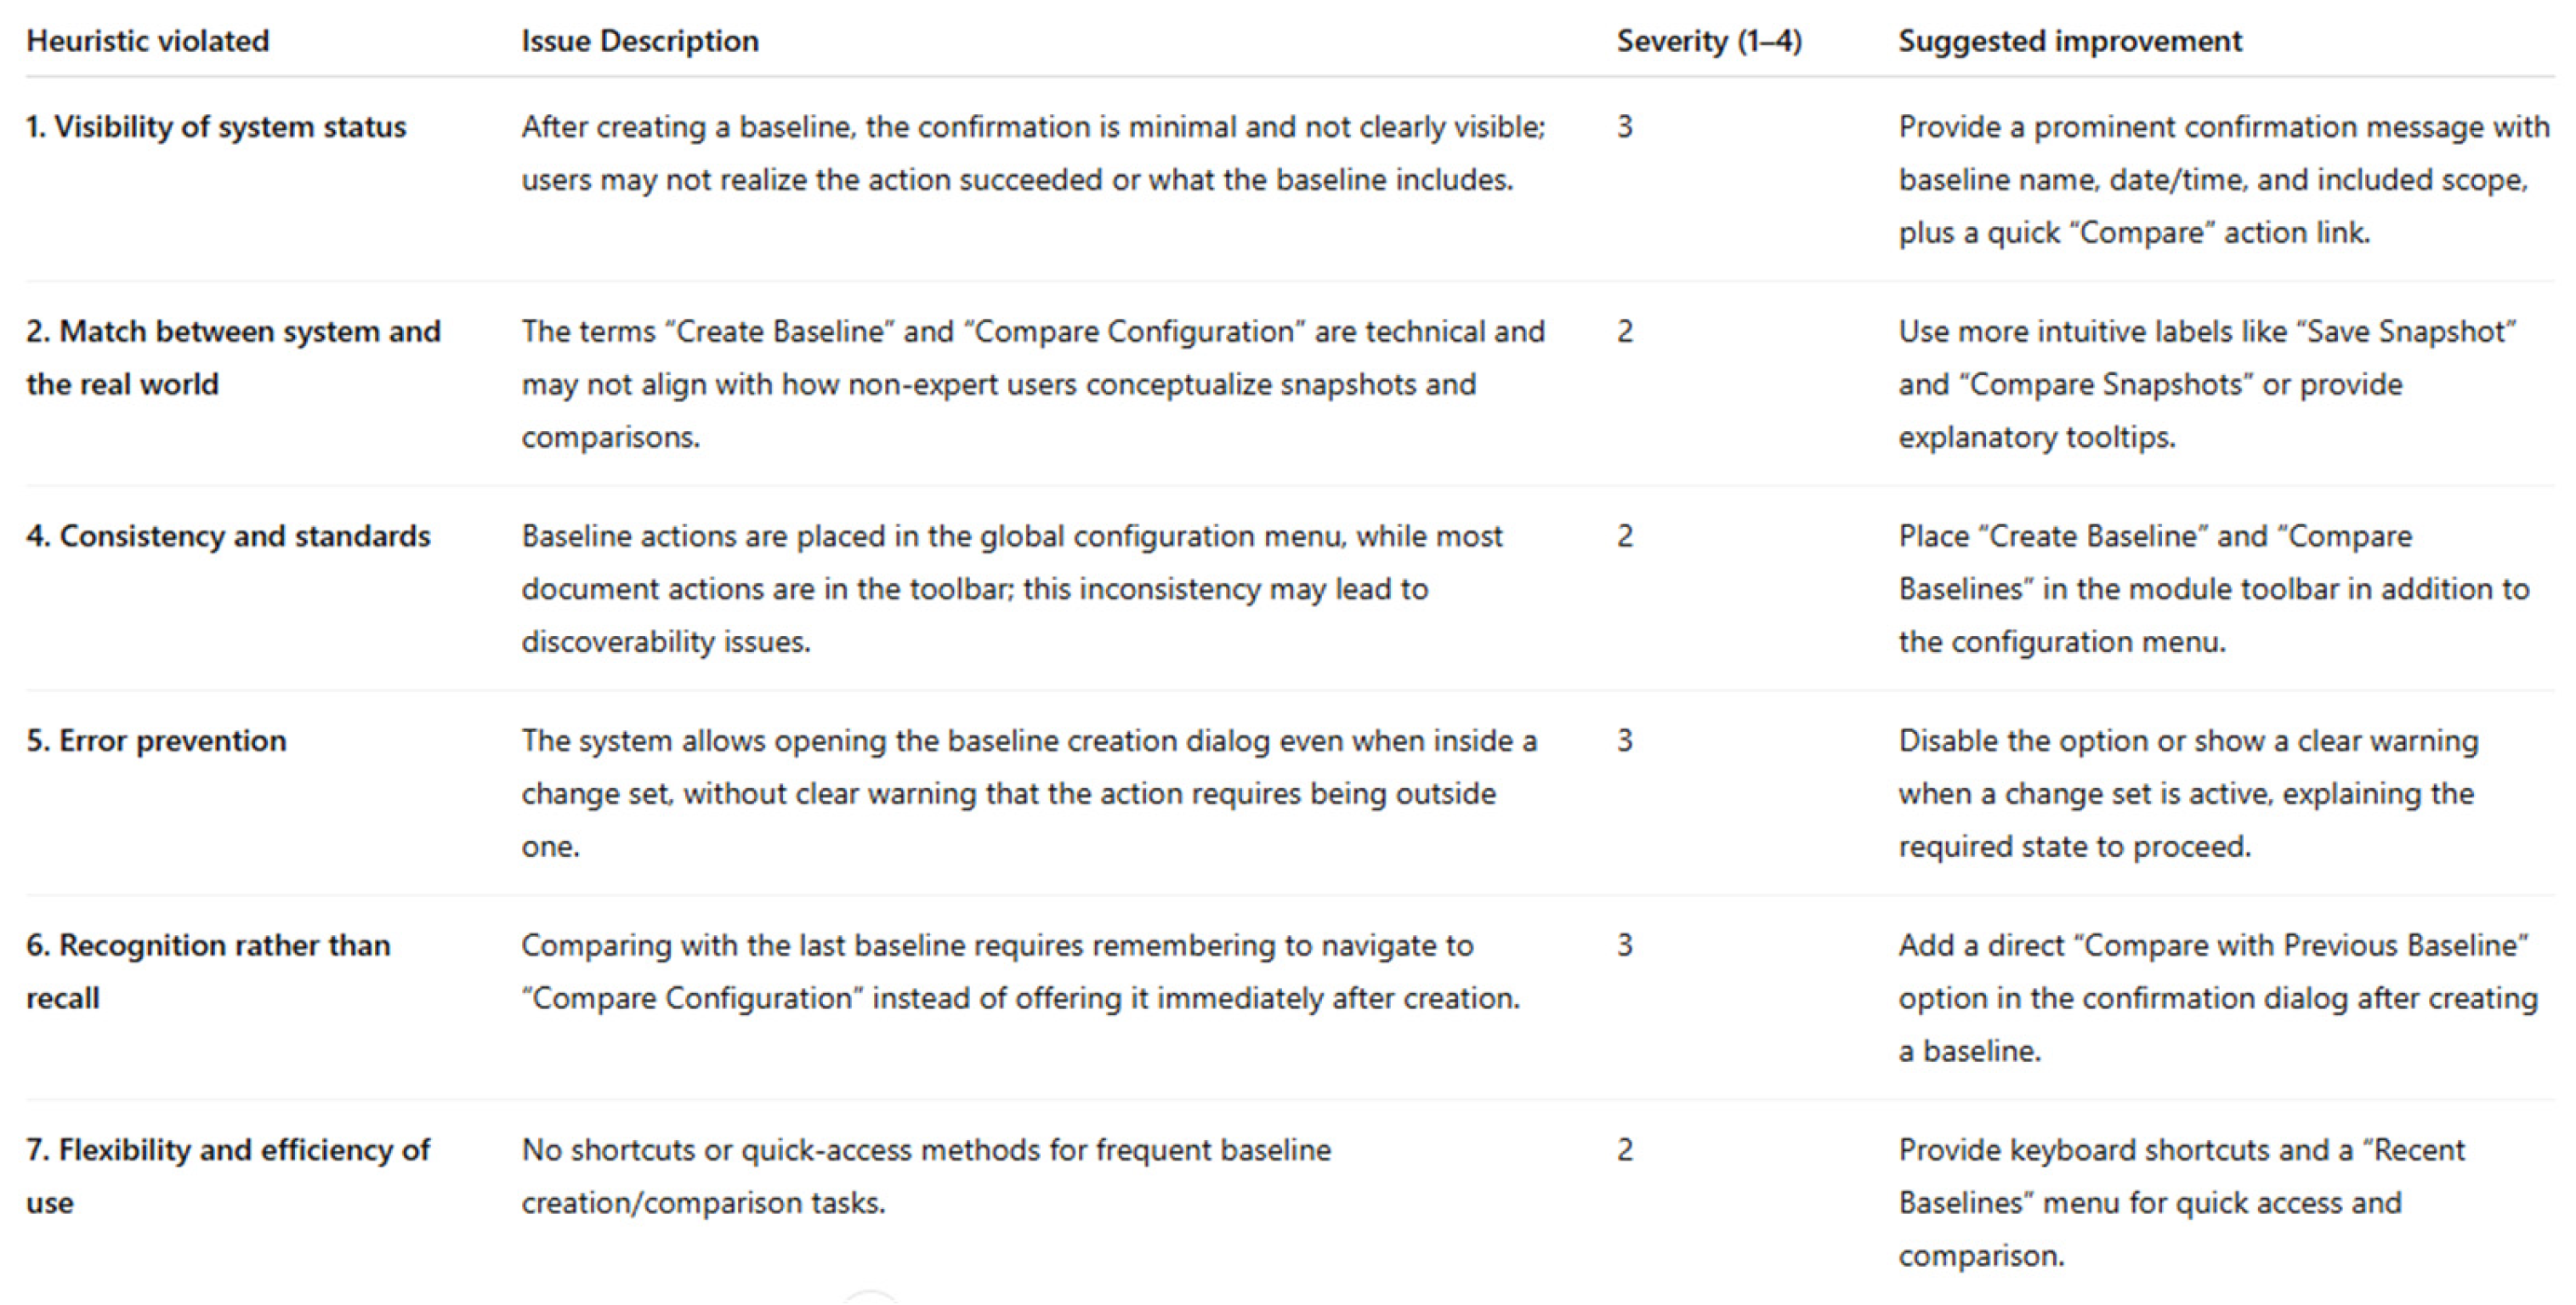
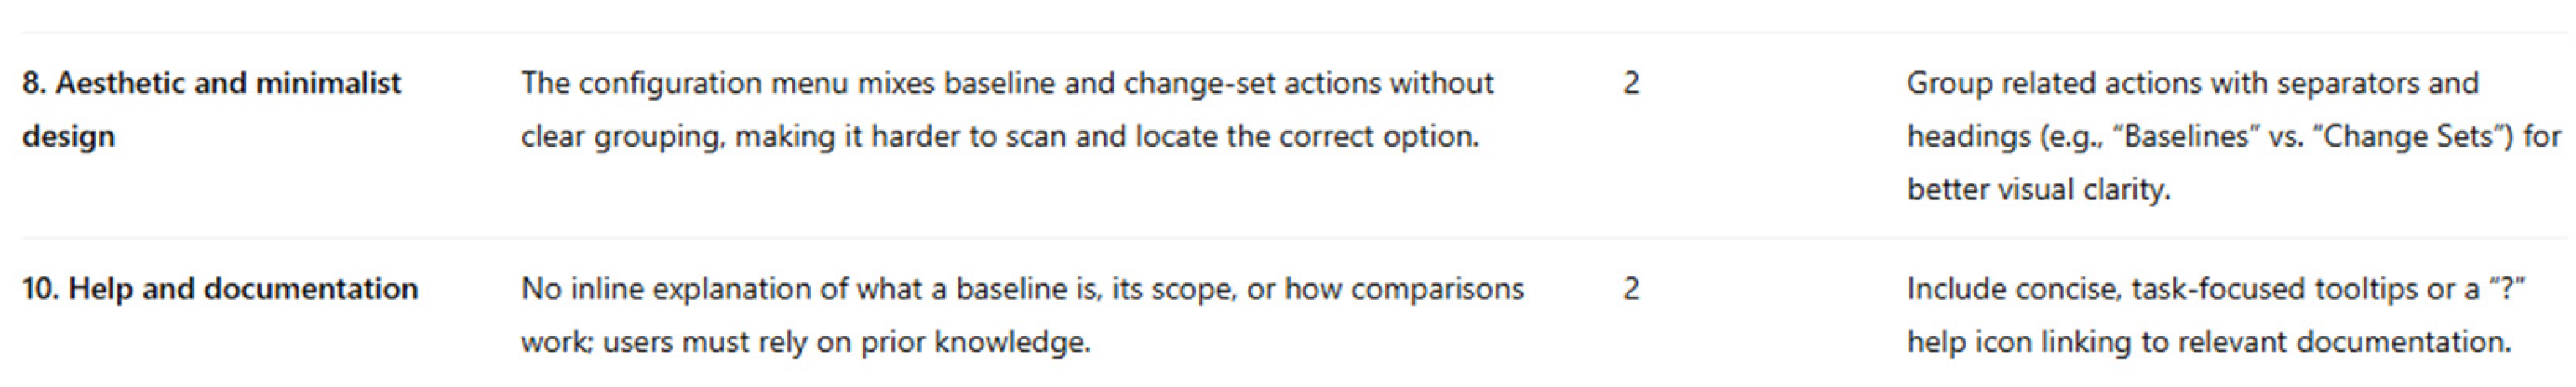
Appendix A.6. Prompt for Task 6
Role: “Assume you are a usability expert evaluating an automotive Requirements Engineering Management tool (IBM DOORS Next Generation) for the automotive industry, via heuristic evaluation.”
Objective: “Your task is to identify usability issues according to the following heuristic set, rate their severity, and suggest improvements.”
Reasoning approach: Before providing your responses, examine the interface and think of the interaction step-by-step: (1) Observe every given screenshot to understand the entire context. (2) Identify the UI elements, potential workflows and terminology used. (3) The observations should be compared against the heuristic set given, to identify possible heuristic violations. (4) For every possible issue, think of the reason why it is a problem and how it impacts usability. (5) Assign a severity rating for the identified issue. (6) Think of a potential improvement that can address the issue.
Heuristic set: Nielsen’s 10 heuristics. 1. Visibility of system status: The system should always keep users informed about what is going on, through appropriate feedback within reasonable time. 2. Match between system and the real world: The system should speak the users’ language, with words, phrases and concepts familiar to the user, rather than system-oriented terms. Follow real-world conventions, making information appear in a natural and logical order. 3. User control and freedom: Users often choose system functions by mistake and will need a clearly marked “emergency exit” to leave the unwanted state without having to go through an extended dialogue. Support undo and redo. 4. Consistency and standards: Users should not have to wonder whether different words, situations, or actions mean the same thing. Follow platform conventions. 5. Error prevention: Even better than good error messages is a careful design which prevents a problem from occurring in the first place. Either eliminate error-prone conditions or check for them and present users with a confirmation option before they commit to the action. 6. Recognition rather than recall: Minimize the user’s memory load by making objects, actions, and options visible. The user should not have to remember information from one part of the dialogue to another. Instructions for use of the system should be visible or easily retrievable whenever appropriate. 7. Flexibility and efficiency of use: Accelerators—unseen by the novice user—may often speed up the interaction for the expert user such that the system can cater to both inexperienced and experienced users. Allow users to tailor frequent actions. 8. Aesthetic and minimalist design: Dialogues should not contain information which is irrelevant or rarely needed. Every extra unit of information in a dialogue competes with the relevant units of information and diminishes their relative visibility. 9. Help users recognize, diagnose, and recover from errors: error messages should be expressed in plain language (no codes), precisely indicate the problem, and constructively suggest a solution. 10. Help and documentation: Even though it is better if the system can be used without documentation, it may be necessary to provide help and documentation. Any such information should be easy to search, focused on the user’s task, list concrete steps to be carried out, and not be too large.
Task description: Review and check for validation; Prerequisites: outside a change set. Create a review for requirement 1.3 from Heuristic evaluation test document #1. Complete the review. Check for the validation artifacts related to this requirement.
Workspace context: A dedicated “Test’ workspace was created in DNG REM tool for this evaluation. Three requirements modules, containing some requirements’ artifacts.
Screenshots:
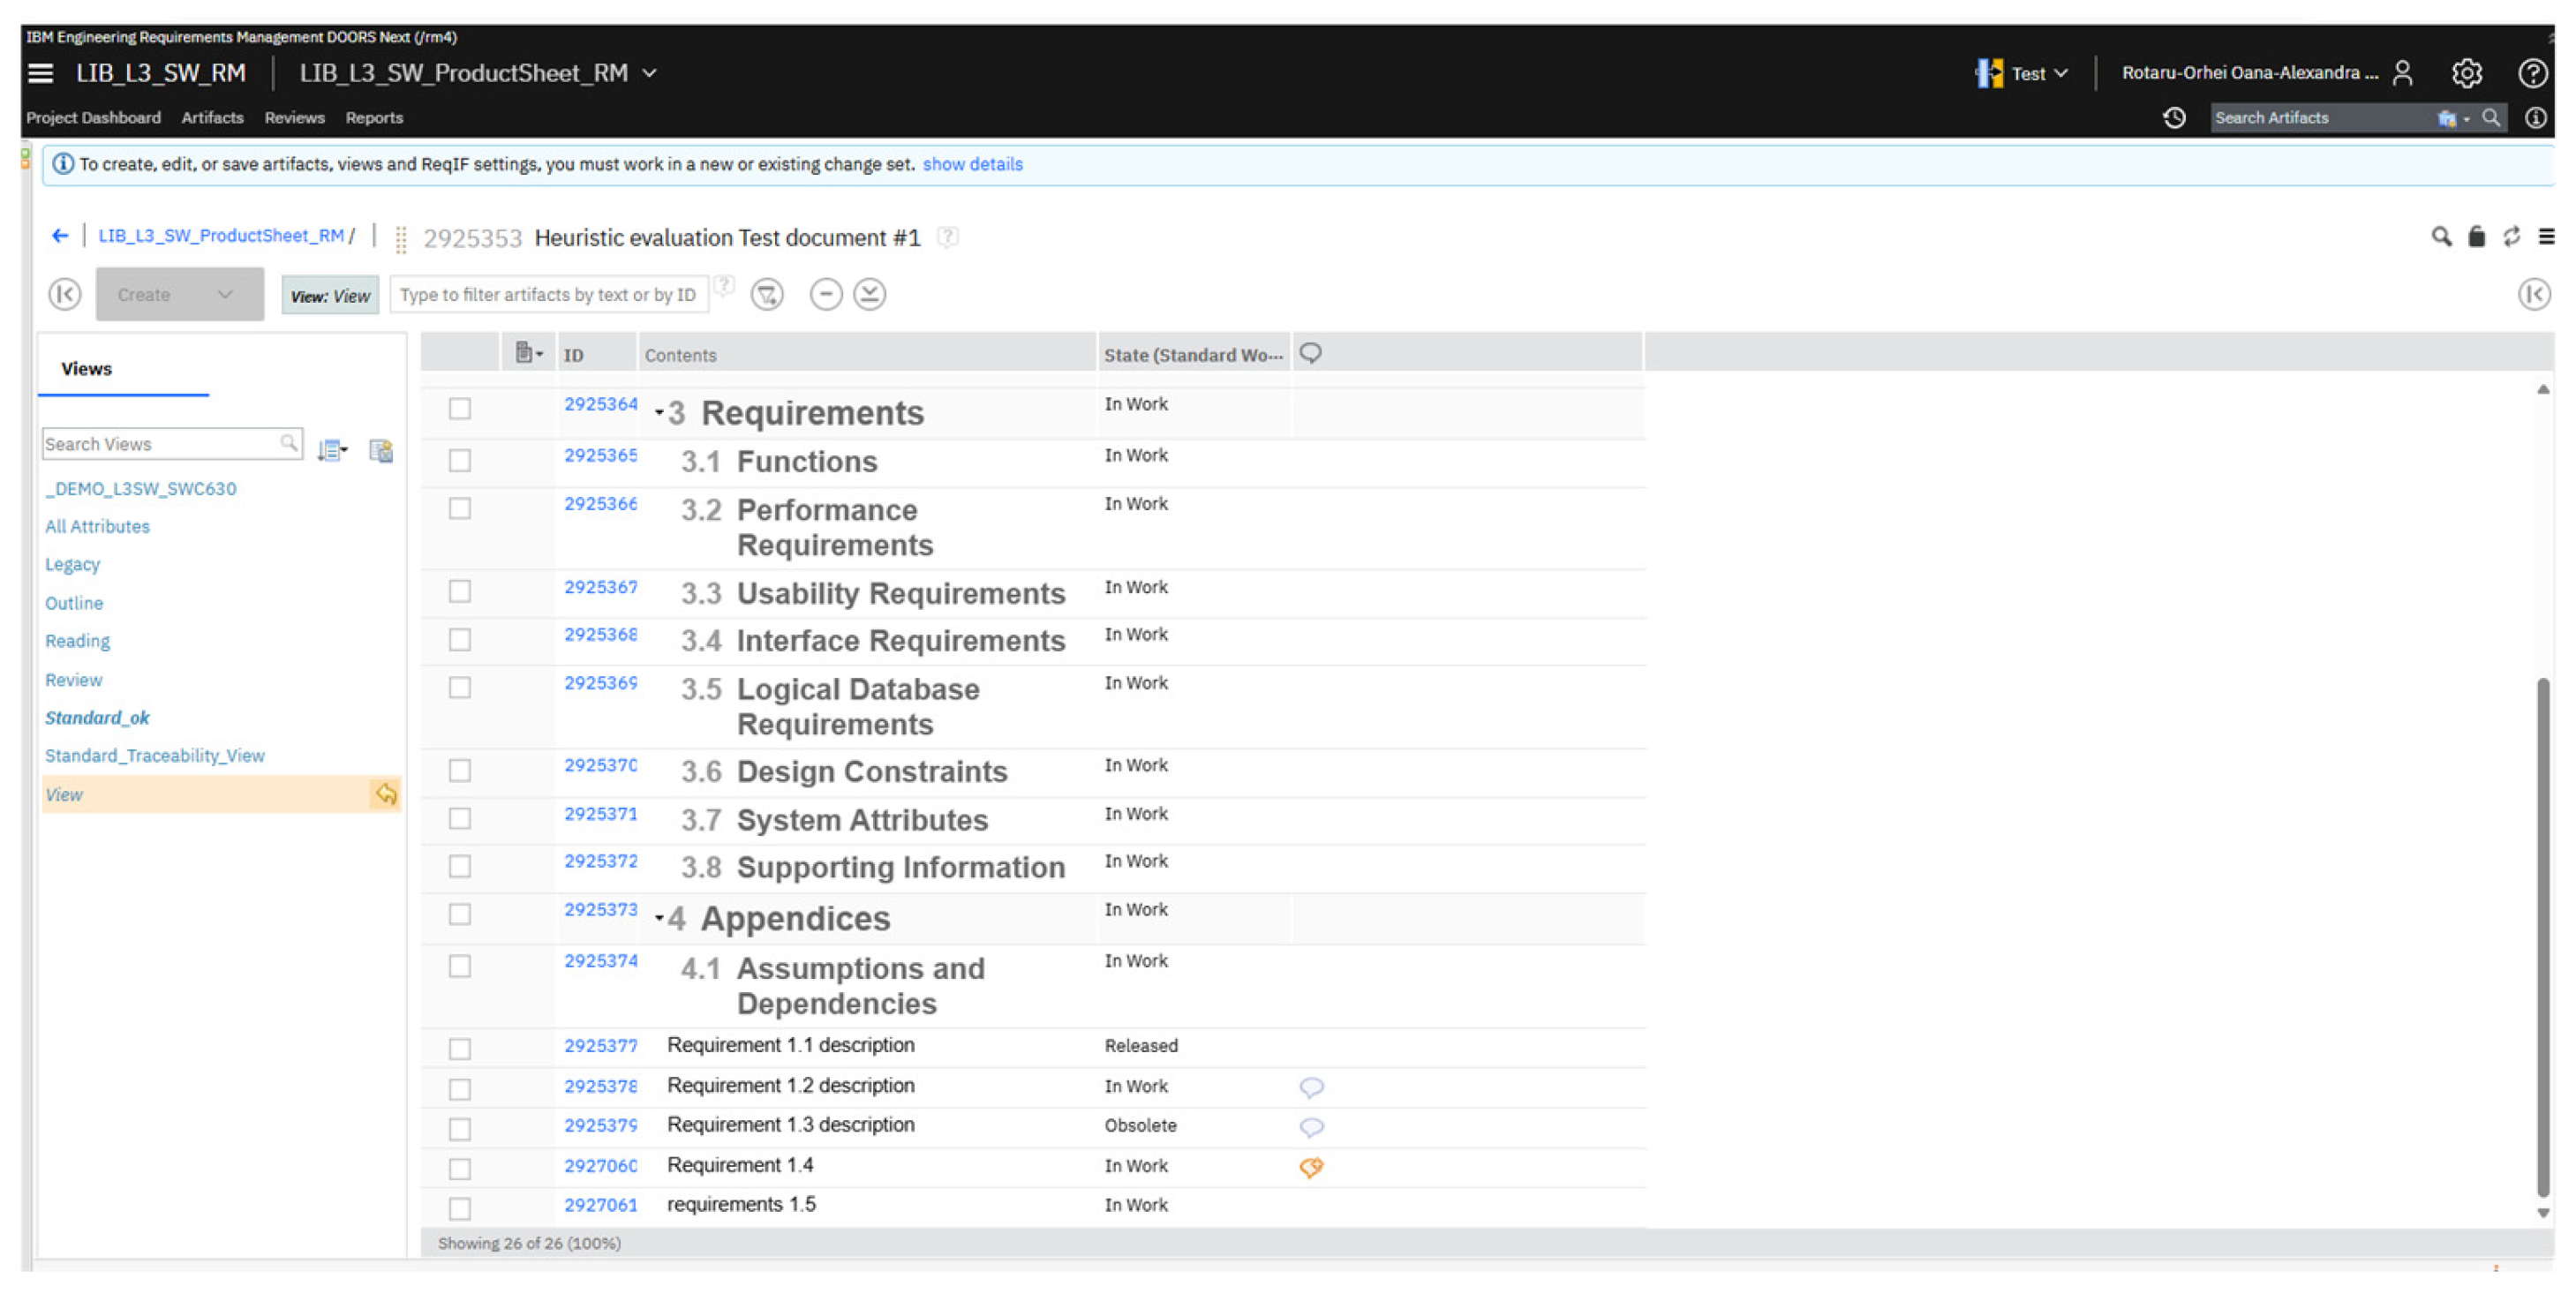
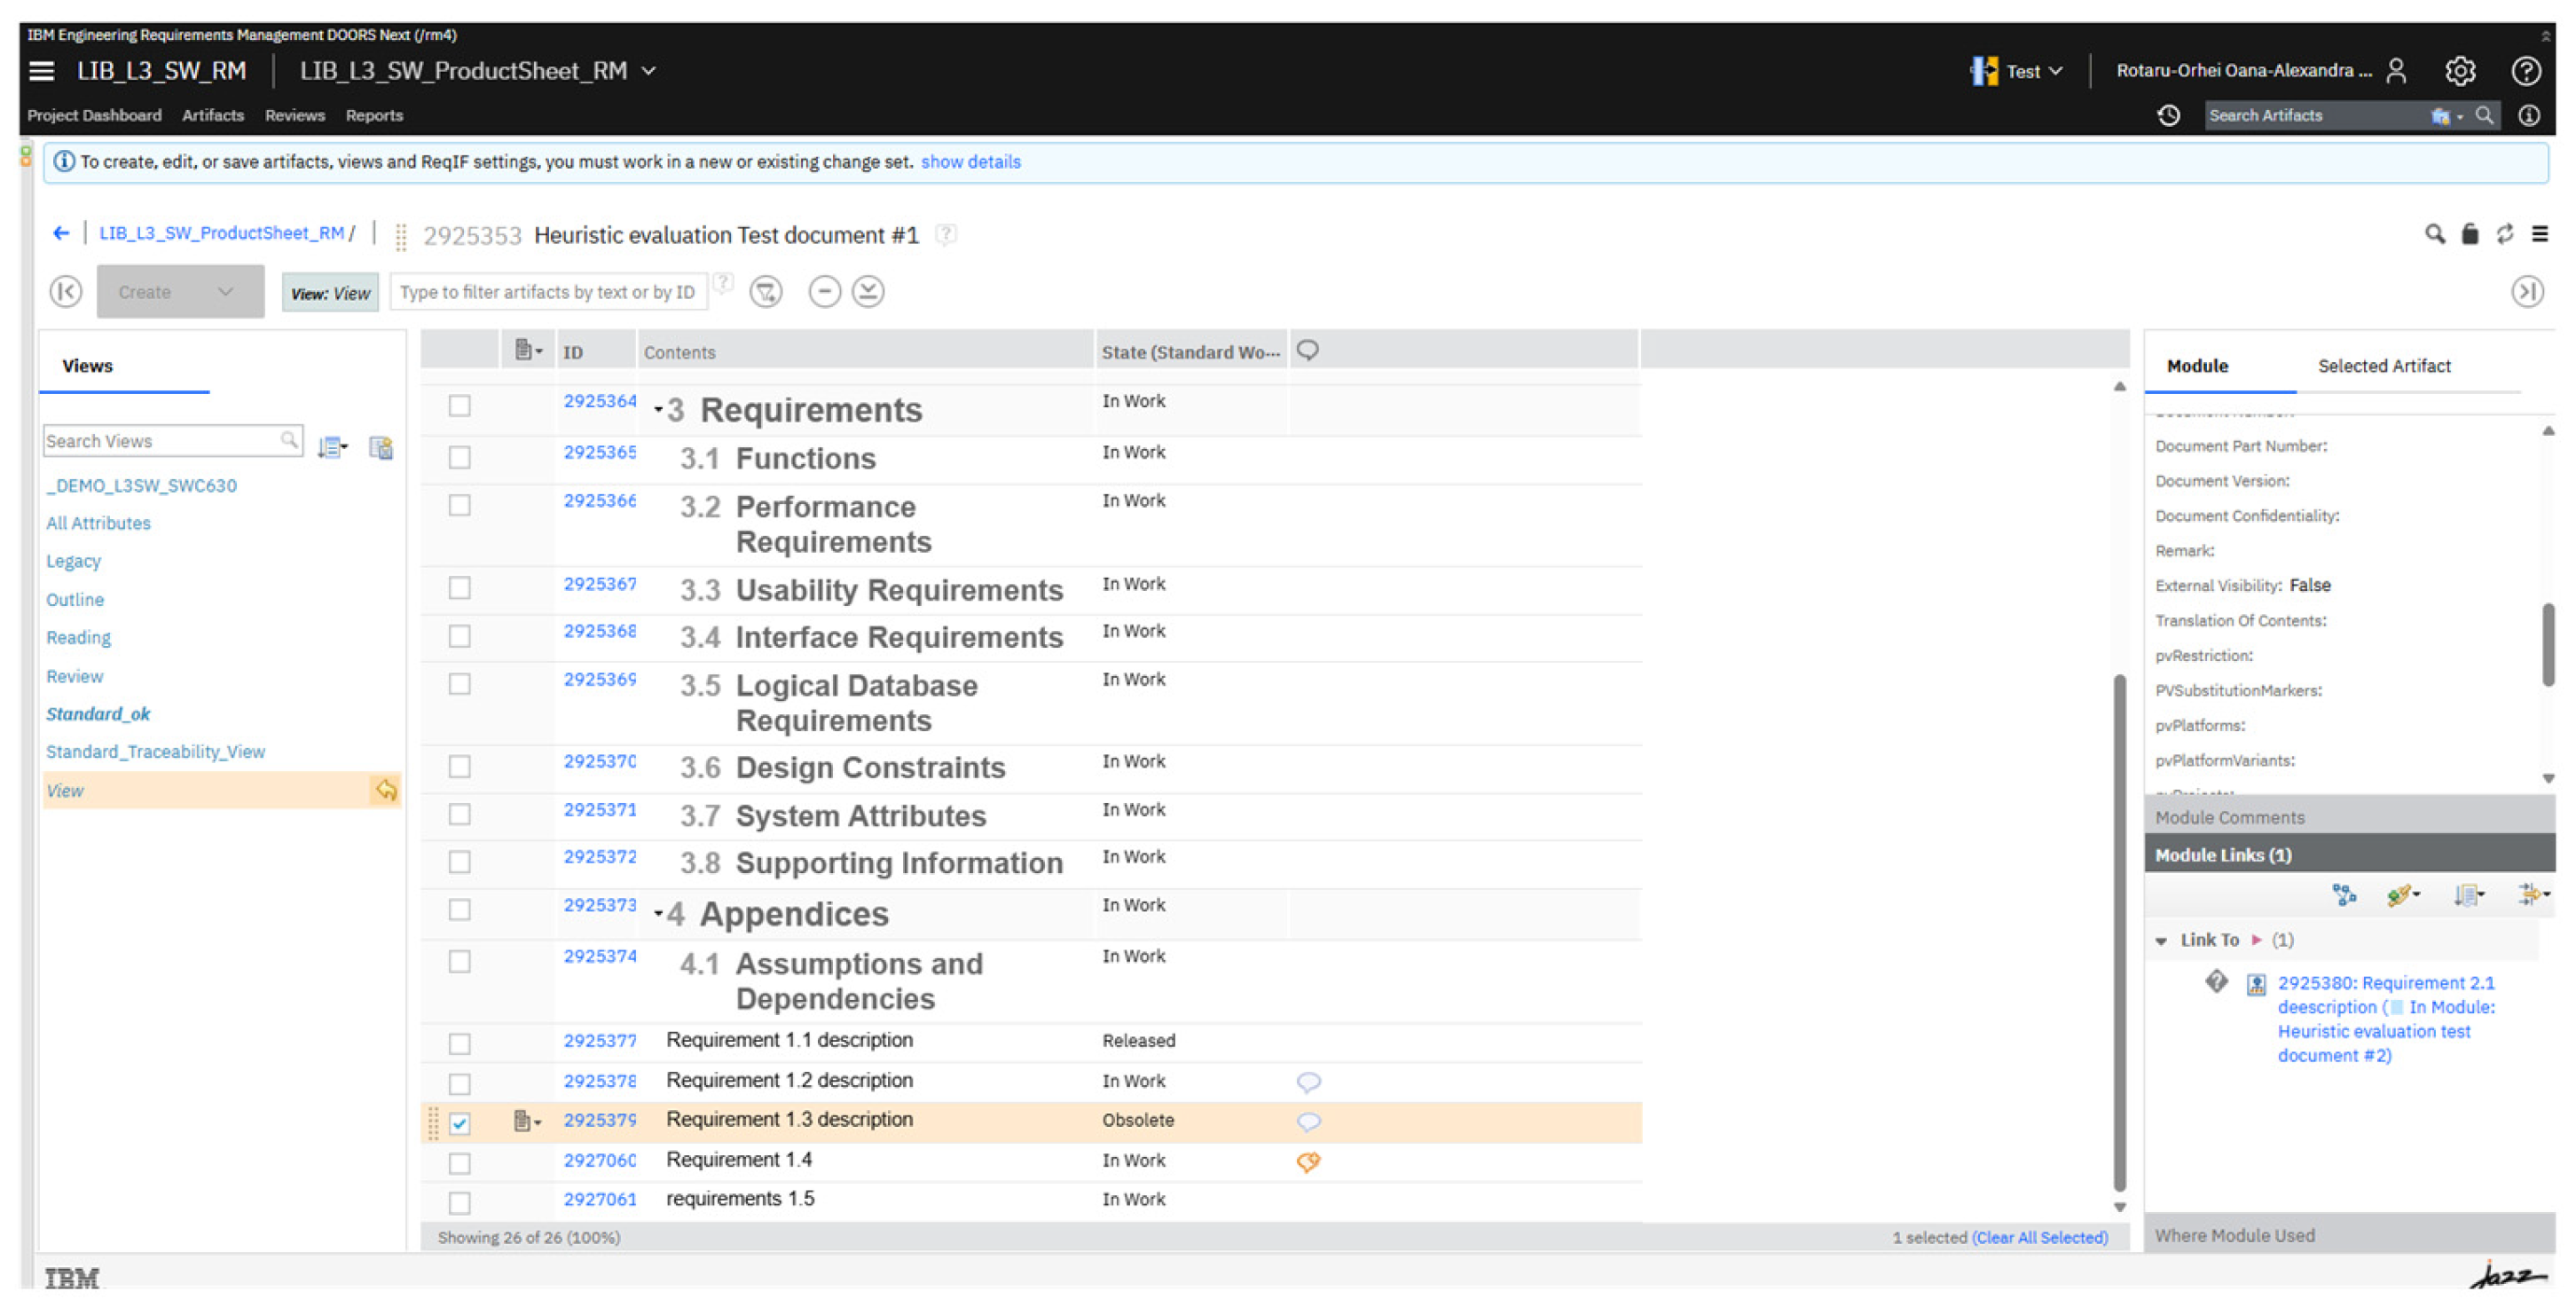
Output format:|Heuristic Violated|Issue Description|Severity (1–4)|Suggested Improvement|
The ChatGPT-5 Output:
Here’s the heuristic evaluation for Task 6: Review and check for validation in DNG, based on the screenshots and step-by-step flow you described:
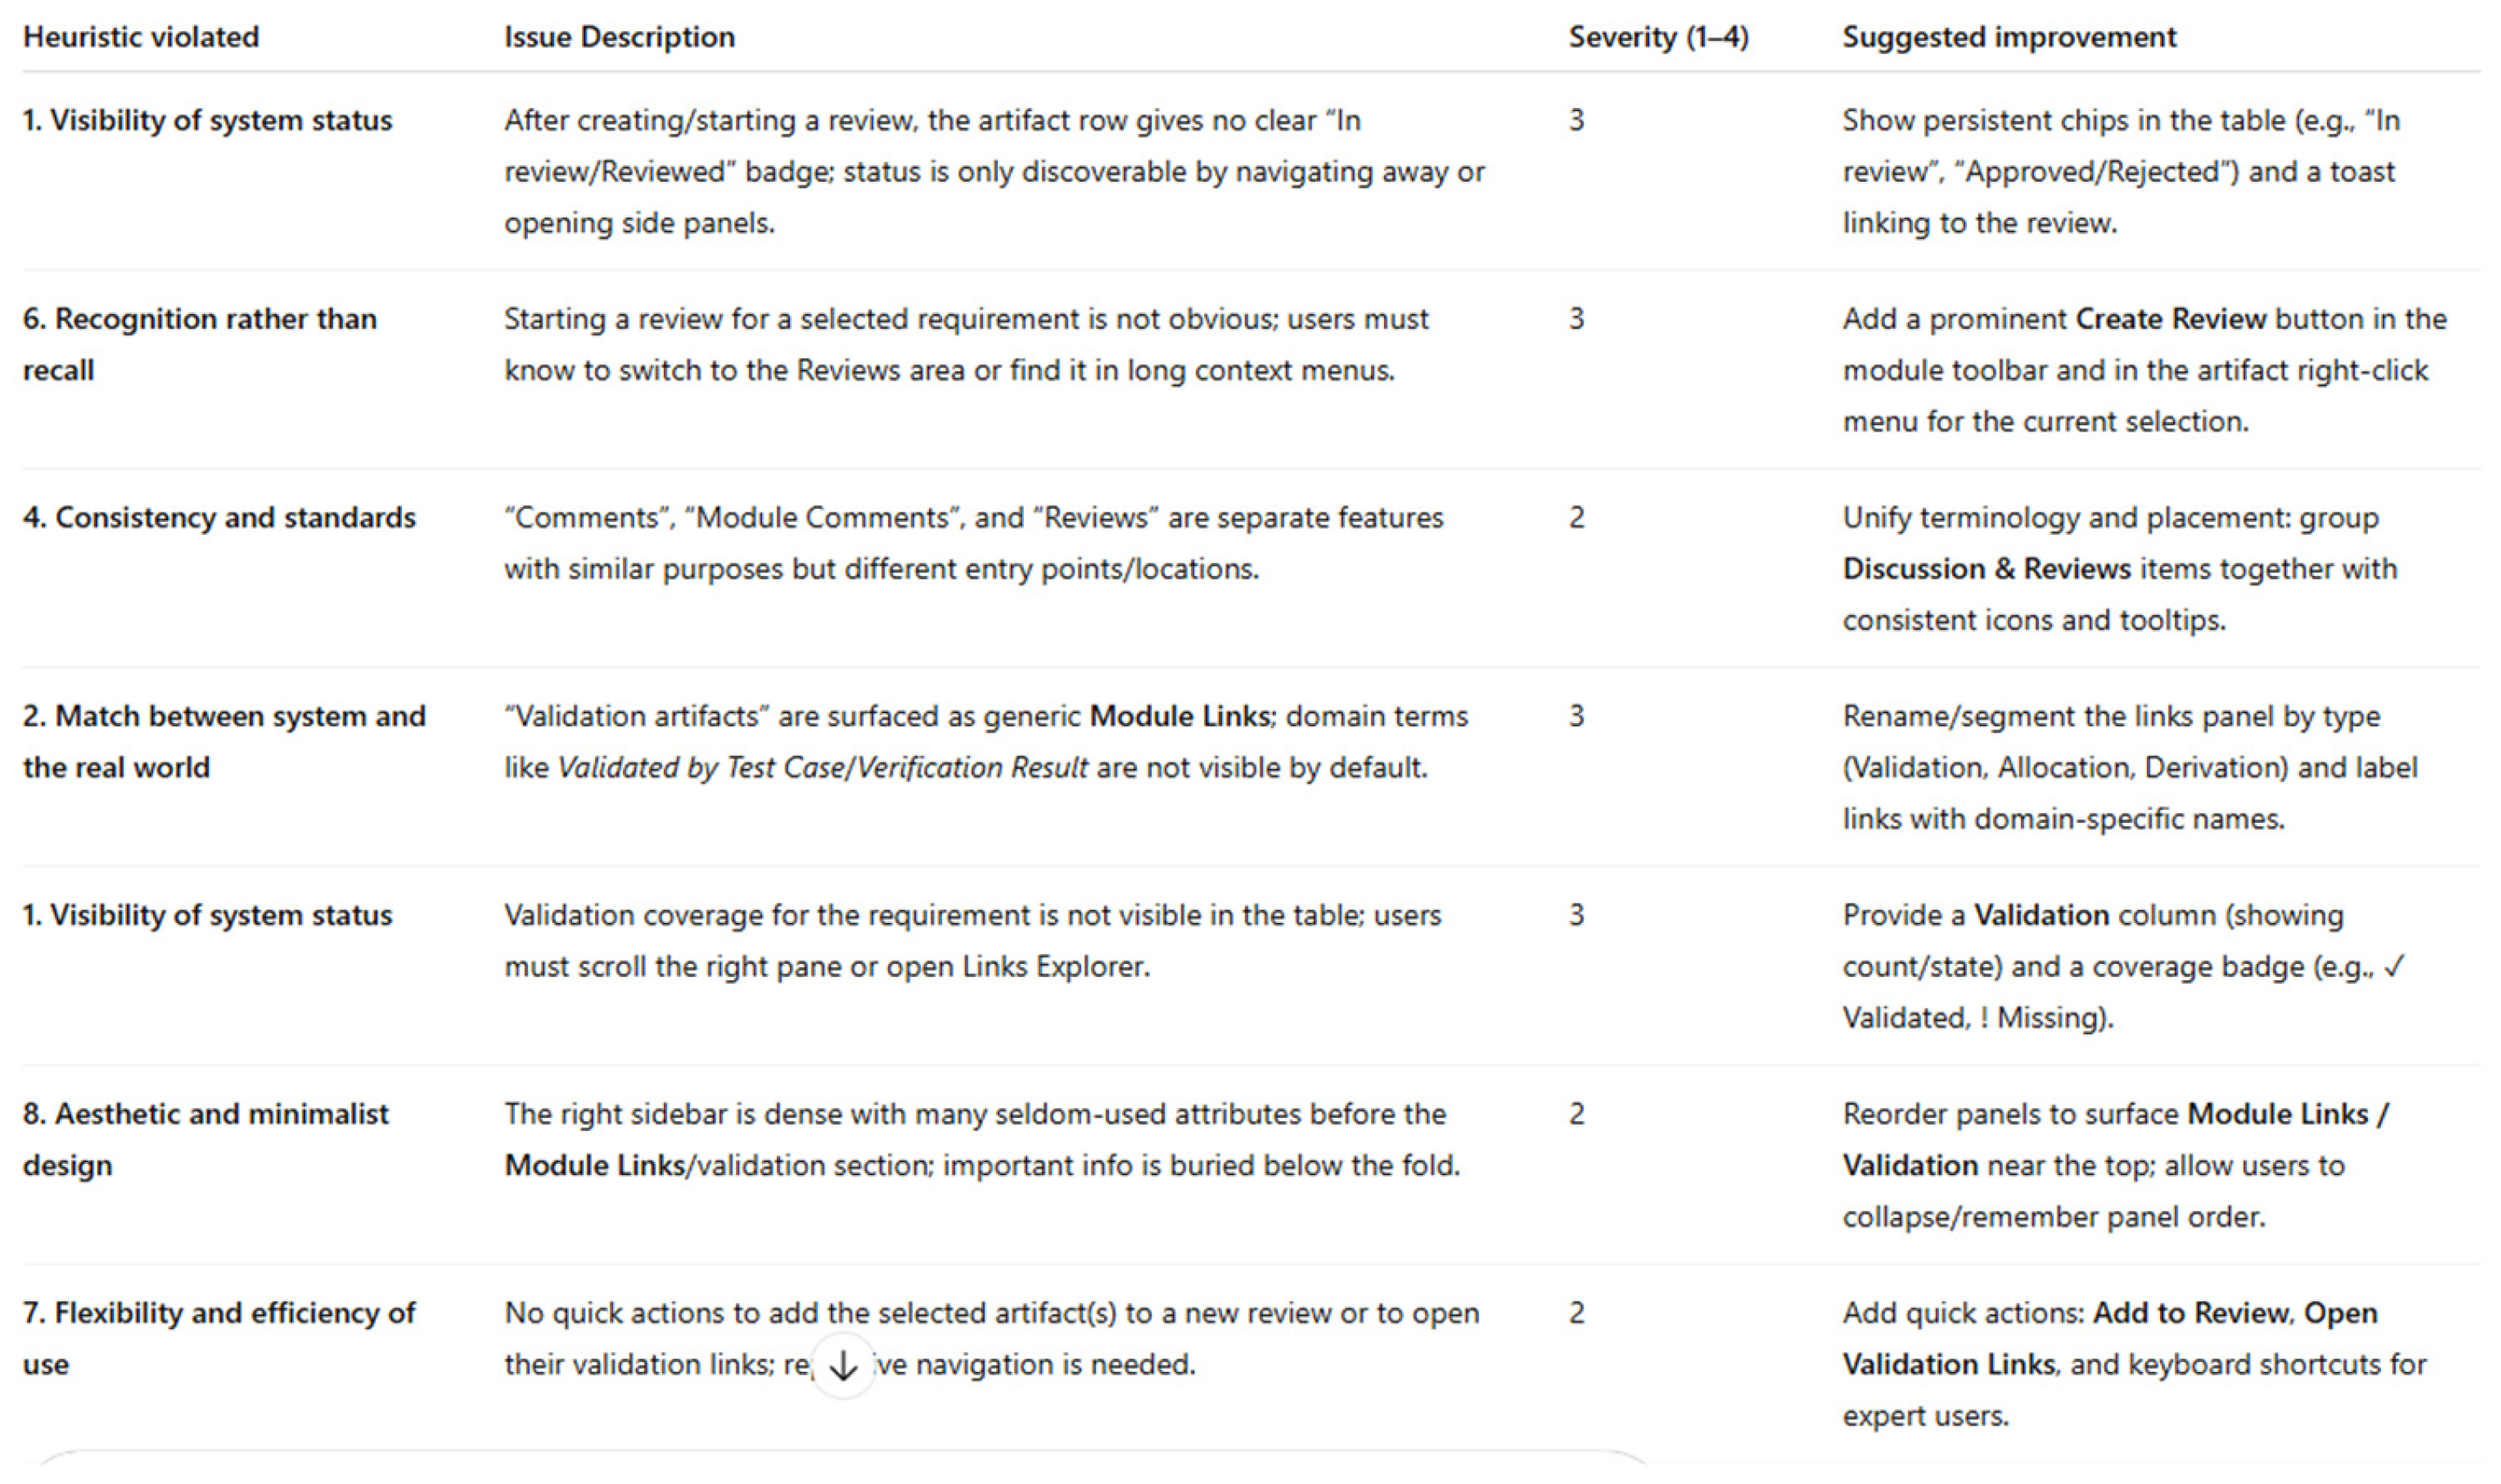
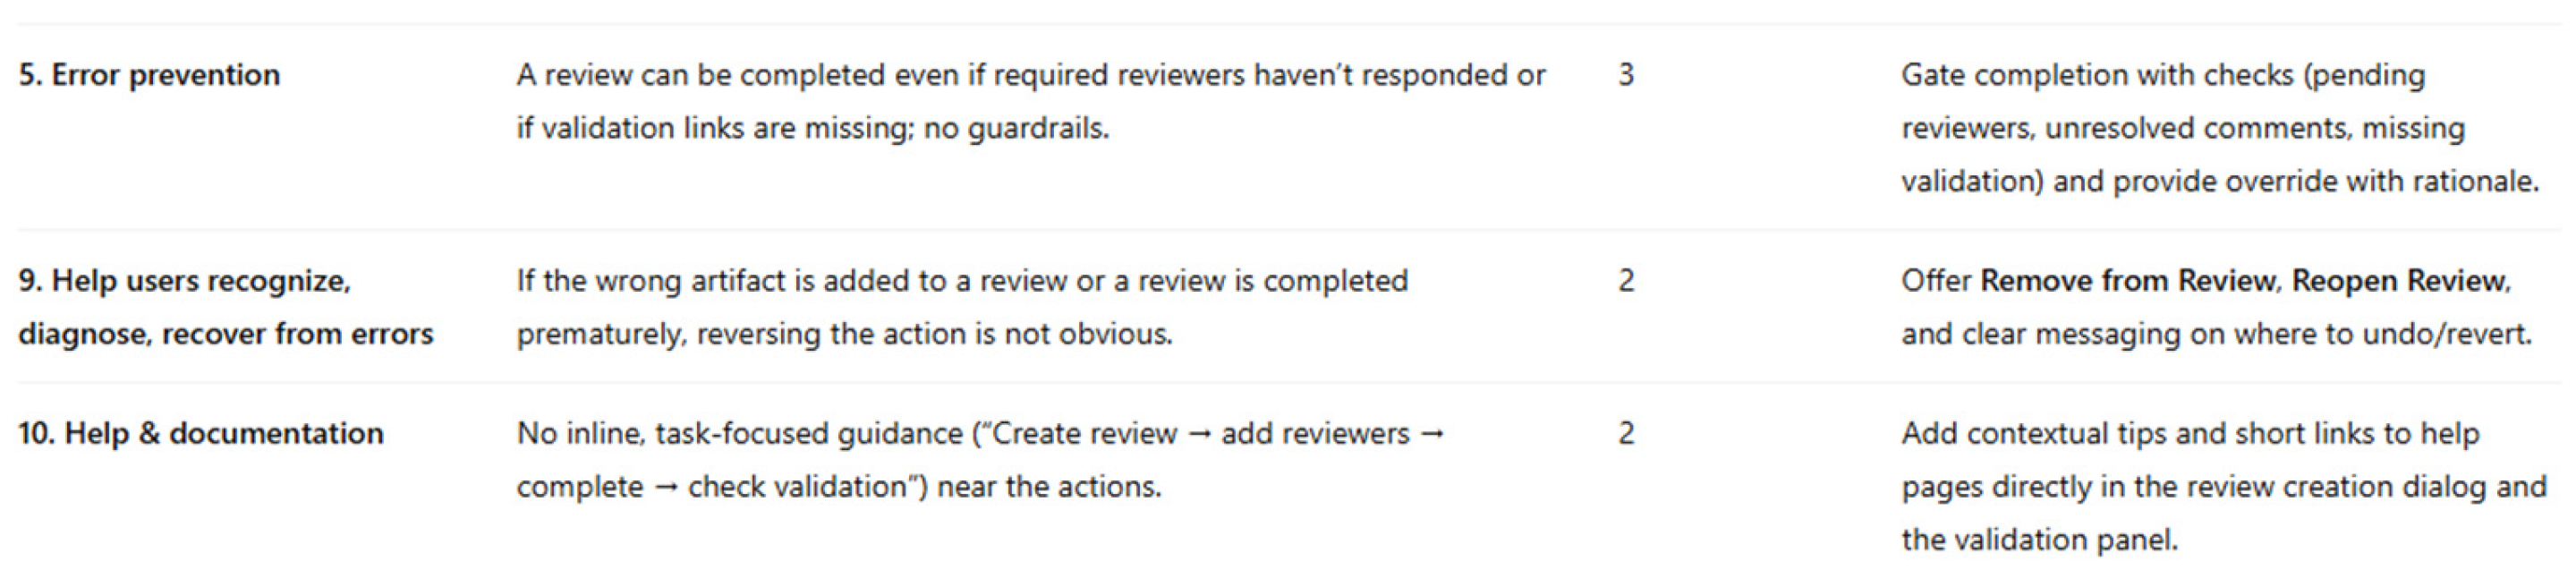
References
- Rahim, A.; Rahman, A.; Rahman, M.M.; Asyhari, A.T.; Bhuiyan, Z.A.; Ramasamy, D. Evolution of IoT-enabled connectivity and applications in automotive industry: A review. Veh. Commun. 2021, 27, 100285. [Google Scholar] [CrossRef] [Scilit]
- Gülke, T.; Rumpe, B.; Jansen, M.; Axmann, J. High-Level Requirements Management and Complexity Costs in Automotive Development Projects: A Problem Statement. In Requirements Engineering: Foundation for Software Quality; Regnell, B., Damian, D., Eds.; Springer: Berlin/Heidelberg, Germany, 2012; pp. 94–100. [Google Scholar] [CrossRef] [Scilit]
- Elshandidy, H.; Mazen, S. Agile and traditional requirements engineering: A survey. Int. J. Sci. Eng. Res. 2013, 4, 473–482. [Google Scholar] [CrossRef] [Scilit]
- Overview of Rational DOORS Next Generation—IBM Documentation. Available online: https://www.ibm.com/docs/en/engineering-lifecycle-management-suite/doors/9.7.0?topic=doors-overview-rational-next-generation (accessed on 1 October 2024).
- 2025 Siemens Product Lifecycle Management Software Inc. Requirements Management, Requirements Gathering, Requirements Management Tools—Polarion REQUIREMENTS. Available online: https://polarion.plm.automation.siemens.com/products/polarion-requirements (accessed on 3 September 2025).
- Jama Connect. Available online: https://www.jamasoftware.com/platform/jama-connect/ (accessed on 13 May 2025).
- Siddiqui, S.; Needs, M.B. Types and Benefits of Requirements Management Tools. Int. J. Trends Comput. Sci. 2013, 2, 433–441. [Google Scholar]
- ISO 26262-4:2018; Road Vehicles—Functional Safety. International Organization for Standardization: Geneva, Switzerland, 2018. Available online: https://www.iso.org/standard/68386.html (accessed on 17 May 2025).
- Automotive SPICE Process Assessment/Reference Model. Available online: https://vda-qmc.de/en/automotive-spice/ (accessed on 17 May 2025).
- Lami, G.; Falcini, F. Automotive SPICE Assessments in Safety-Critical Contexts: An Experience Report. In Proceedings of the 2014 IEEE International Symposium on Software Reliability Engineering Workshops, Naples, Italy, 3–6 November 2014; IEEE: New York, NY, USA, 2014; pp. 497–502. [Google Scholar] [CrossRef] [Scilit]
- Khan, J. ISO 26262 system level functional safety validation for battery management systems in automobiles. In Proceedings of the 2017 Innovations in Power and Advanced Computing Technologies (i-PACT), Vellore, India, 21–22 April 2017; pp. 1–5. [Google Scholar] [CrossRef] [Scilit]
- Tolontan, M.; Orhei, C.; Vasiu, R. Overview of the Technical Risk Analysis and Risk Assessment Analysis in Automotive Industry. In Proceedings of the 2024 International Symposium on Electronics and Telecommunications (ISETC), Vellore, India, 21–22 April 2017; IEEE: New York, NY, USA, 2024; pp. 1–4. [Google Scholar] [CrossRef] [Scilit]
- ISO 9241-11:2018; Ergonomics of Human-System Interaction—Part 11: Usability: Definitions and Concepts. International Organization for Standardization: Geneva, Switzerland, 2018. Available online: https://www.iso.org/obp/ui/#iso:std:iso:9241:-11:ed-2:v1:en (accessed on 21 August 2025).
- Hassenzahl, M. User experience (UX): Towards an experiential perspective on product quality. In Proceedings of the 20th Conference on l’Interaction Homme-Machine, in IHM ’08, Metz, France, 2–5 September 2008; Association for Computing Machinery: New York, NY, USA, 2008; pp. 11–15. [Google Scholar] [CrossRef] [Scilit]
- Rotaru, A.; Vert, S.; Vasiu, R.; Andone, D. Standardised Questionnaires in Usability Evaluation. Applying Standardised Usability Questionnaires in Digital Products Evaluation. In Information and Software Technologies; Lopata, A., Butkienė, R., Gudonienė, D., Sukackė, V., Eds.; Springer: Cham, Switzerland, 2020; pp. 39–48. [Google Scholar] [CrossRef] [Scilit]
- Rotaru, O.; Vert, S.; Vasiu, R. Usability Evaluation of Requirement Collaboration Features in Requirements Management Tools. In Proceedings of the 27th International Conference on Enterprise Information Systems, Porto, Portugal, 4–6 April 2025; pp. 201–208. Available online: https://www.scitepress.org/Link.aspx?doi=10.5220/0013281800003929 (accessed on 28 August 2025).
- Vert, S.; Rotaru, O.; Andone, D.; Antonica, M.; Borobar, A.; Orhei, C.; Holotescu, V. Towards User Experience Guidelines for Mobile Augmented Reality Storytelling with Historical Images in Urban Cultural Heritage. In Extended Reality and Metaverse; Springer: Cham, Switzerland, 2023; pp. 141–147. [Google Scholar] [CrossRef] [Scilit]
- Paz, F.; Paz-Sifuentes, F.-A.; Moquillaza, A.; Falconi, F.; Aguirre, J.; Lecaros, A.; Ramos, C. Qualitative and Quantitative Approaches to Conduct Heuristic Evaluations: A Comparison Study. In Design, User Experience, and Usability; Marcus, A., Rosenzweig, E., Soares, M.M., Eds.; Springer Nature: Cham, Switzerland, 2024; pp. 310–323. [Google Scholar] [CrossRef] [Scilit]
- 10 Usability Heuristics for User Interface Design. Nielsen Norman Group. Available online: https://www.nngroup.com/articles/ten-usability-heuristics/ (accessed on 21 August 2025).
- Achiam, J.; Adler, S.; Agarwal, S.; Ahmad, L.; Akkaya, I.; Aleman, F.L.; Almeida, D.; Altenschmidt, J.; Altman, S.; Avila, R.; et al. GPT-4 Technical Report. arXiv 2024, arXiv:2303.08774. [Google Scholar] [CrossRef] [Scilit]
- Open AI. GPT-5 System Card. 2025. Available online: https://cdn.openai.com/gpt-5-system-card.pdf (accessed on 24 August 2025).
- Anil, R.; Borgeaud, S.; Alayrac, J.-B.; Yu, J.; Soricut, R.; Schalkwyk, J.; Dai, A.M.; Hauth, A.; Millican, K.; Silver, D.; et al. Gemini: A Family of Highly Capable Multimodal Models. arXiv 2025, arXiv:2312.11805. [Google Scholar] [CrossRef] [Scilit]
- Sahoo, P.; Singh, A.K.; Saha, S.; Jain, V.; Mondal, S.; Chadha, A. A Systematic Survey of Prompt Engineering in Large Language Models: Techniques and Applications. arXiv 2025, arXiv:2402.07927. [Google Scholar] [CrossRef] [Scilit]
- Sonko, S.; Daudu, C.D.; Osasona, F.; Monebi, A.M.; Etukudoh, E.A.; Atadoga, A. The evolution of embedded systems in automotive industry: A global review. World J. Adv. Res. Rev. 2024, 21, 096–104. [Google Scholar] [CrossRef] [Scilit]
- Etukudoh, E.A.; Usman, F.O.; Ilojianya, V.I.; Daudu, C.D.; Umoh, A.A.; Ibekwe, K.I. Mechanical engineering in automotive innovation: A review of electric vehicles and future trends. Int. J. Sci. Res. Arch. 2024, 11, 579–589. [Google Scholar] [CrossRef] [Scilit]
- Tolontan, M.; Orhei, C.; Vasiu, R. Automotive Specific AI Based Tools for Technical Risk Analysis and Risk Assessment Analysis. In Proceedings of the 2025 IEEE 31st International Symposium for Design and Technology in Electronic Packaging (SIITME), Brasov, Romania, 22–25 October 2025; pp. 466–470. [Google Scholar] [CrossRef] [Scilit]
- Xu, T.; Zhou, Z.; Chen, X.; Xue, Z.; Zhao, Y.; Zhang, M.; Jin, Z. Requirements Dependency Driven Test Case Generation: An Automotive Industry Practice. In Proceedings of the 2025 IEEE 33rd International Requirements Engineering Conference (RE), Valencia, Spain, 1–5 September 2025; pp. 400–404. [Google Scholar] [CrossRef] [Scilit]
- Zolfaghari, V.; Petrovic, N.; Pan, F.; Lebioda, K.; Knoll, A. Adopting RAG for LLM-Aided Future Vehicle Design. In Proceedings of the 2024 2nd International Conference on Foundation and Large Language Models (FLLM), Dubai, United Arab Emirates, 26–29 November 2024; pp. 437–442. [Google Scholar] [CrossRef] [Scilit]
- Frantar, E.; Ashkboos, S.; Hoefler, T.; Alistarh, D. GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers. arXiv 2023, arXiv:2210.17323. [Google Scholar] [CrossRef] [Scilit]
- Chen, J.; Li, J.; Peng, Z.; Wang, W.; Ren, Y.; Shi, L.; Hu, X. LoTA-QAF: Lossless Ternary Adaptation for Quantization-Aware Fine-Tuning. arXiv 2025, arXiv:2505.18724. [Google Scholar] [CrossRef] [Scilit]
- Flores, F.; Mora, M.; Alvarez, F.; O’Connor, R.; Macias-Luevano, J. Requirements Engineering: A Review of Processes and Techniques. In Handbook of Research on Modern Systems Analysis and Design Technologies and Applications; IGI Global: Palmdale, PA, USA, 2009; pp. 90–104. [Google Scholar] [CrossRef]
- Tang, D.; Qian, X. Product lifecycle management for automotive development focusing on supplier integration. Comput. Ind. 2008, 59, 288–295. [Google Scholar] [CrossRef] [Scilit]
- UNECE—ECE/TRANS/WP29/2016/2—Agreement Concerning the Adoption of Harmonized Technical United Nations Regulations for Wheeled Vehicles, Equipment and Parts Which Can be Fitted and/or be Used on Wheeled Vehicles and the Conditions for Reciprocal Recognition of Approvals Granted on the Basis of these United Nations Regulations. 2017. Available online: https://unece.org/wp29-introduction (accessed on 3 May 2025).
- Staron, M. Software Architectures: Views and Documentation. In Automotive Software Architectures: An Introduction; Staron, M., Ed.; Springer International Publishing: Cham, Switzerland, 2017; pp. 19–50. [Google Scholar] [CrossRef] [Scilit]
- Bellairs, R. What Is ISO 26262? Overview + ASIL | Perforce. Available online: https://www.perforce.com/blog/qac/what-is-iso-26262 (accessed on 30 September 2024).
- Ekert, D.; Povirnaru, E.-F.; Gasch, A.; Mayer, R.; Norimatsu, S.; Feulner, A.; Kurz-Grießnig, B.; Lindermuth, P.; Dreves, R.; Grave, R.; et al. Analysis of Automotive SPICE V4.0 Changes. In Systems, Software and Services Process Improvement; Yilmaz, M., Clarke, P., Riel, A., Messnarz, R., Greiner, C., Peisl, T., Eds.; Springer Nature: Cham, Switzerland, 2024; pp. 339–352. [Google Scholar] [CrossRef] [Scilit]
- Costantino, G.; De Vincenzi, M.; Matteucci, I. In-Depth Exploration of ISO/SAE 21434 and Its Correlations with Existing Standards. IEEE Commun. Stand. Mag. 2022, 6, 84–92. [Google Scholar] [CrossRef] [Scilit]
- Franch, X.; Palomares, C.; Quer, C.; Chatzipetrou, P.; Gorschek, T. The state-of-practice in requirements specification: An extended interview study at 12 companies. Requir. Eng. 2023, 28, 377–409. [Google Scholar] [CrossRef] [Scilit]
- Gotel, O.; Cleland-Huang, J.; Hayes, J.H.; Zisman, A.; Egyed, A.; Grünbacher, P.; Dekhtyar, A.; Antoniol, G.; Maletic, J.; Mäder, P. Traceability Fundamentals. In Software and Systems Traceability; Cleland-Huang, J., Gotel, O., Zisman, A., Eds.; Springer: London, UK, 2012; pp. 3–22. [Google Scholar] [CrossRef] [Scilit]
- Baillargeon, R. Managing Changes with Configurations in DOORS Next. Available online: https://www.sodiuswillert.com/en/blog/recommendations-on-using-changes-with-configurations-in-doors-next (accessed on 21 May 2025).
- Jain, A.; Solutions, V. What is Requirements Versioning: Definition, Best Tools & Practices. Available online: https://visuresolutions.com/alm-guide/requirements-versioning/ (accessed on 3 September 2025).
- Ma, J.; Wang, G.; Lu, J.; Vangheluwe, H.; Kiritsis, D.; Yan, Y. Systematic Literature Review of MBSE Tool-Chains. Appl. Sci. 2022, 12, 3431. [Google Scholar] [CrossRef] [Scilit]
- Madan, A.; Kumar, S. Usability evaluation methods: A literature review. Int. J. Eng. Sci. Technol. 2012, 4, 590–599. [Google Scholar]
- Gerhardt-Powals, J. Cognitive engineering principles for enhancing human-computer performance. Int. J. Hum.–Comput. Interact. 1996, 8, 189–211. [Google Scholar] [CrossRef] [Scilit]
- Scapin, D.L.; Bastien, J.M.C. Ergonomic criteria for evaluating the ergonomic quality of interactive systems. Behav. Inf. Technol. 1997, 16, 220–231. [Google Scholar] [CrossRef] [Scilit]
- Shneiderman, B.; Plaisant, C.; Cohen, M.; Jacobs, S.; Elmqvist, N.; Diakopoulos, N. Designing the User Interface: Strategies for Effective Human-Computer Interaction, 6th ed.; Pearson: London, UK, 2016. [Google Scholar]
- Moran, K.; Evaluations, K.G.H. How to Conduct a Heuristic Evaluation. 2025. Available online: https://www.nngroup.com/articles/how-to-conduct-a-heuristic-evaluation/ (accessed on 6 February 2025).
- Nielsen, J. Severity Ratings for Usability Problems: Article by Jakob Nielsen. Nielsen Norman Group. Available online: https://www.nngroup.com/articles/how-to-rate-the-severity-of-usability-problems/ (accessed on 2 June 2025).
- Raiaan, M.A.K.; Mukta, S.H.; Fatema, K.; Fahad, N.M.; Sakib, S.; Mim, M.M.J.; Ahmad, J.; Ali, M.E.; Azam, S. A Review on Large Language Models: Architectures, Applications, Taxonomies, Open Issues and Challenges. IEEE Access 2024, 12, 26839–26874. [Google Scholar] [CrossRef] [Scilit]
- Cohn, C.; Hutchins, N.; Le, T.; Biswas, G. A Chain-of-Thought Prompting Approach with LLMs for Evaluating Students’ Formative Assessment Responses in Science. Proc. AAAI Conf. Artif. Intell. 2024, 38, 23182–23190. [Google Scholar] [CrossRef] [Scilit]
- Rotaru, O.; Vert, S.; Vasiu, R. Switching from DOORS to DOORS Next Generation. Identifying the Main Usability Issues. A Case Study. In Proceedings of the Ninth International Congress on Information and Communication Technology, London, UK, 19–22 February 2024; Yang, X.-S., Sherratt, S., Dey, N., Joshi, A., Eds.; Springer Nature: Singapore, 2024; pp. 261–276. [Google Scholar] [CrossRef] [Scilit]
- Brooke, J. SUS: A retrospective. JUX—J. User Exp. 2013, 8, 2. [Google Scholar]
- Sauro, J. Measuring Usability with the System Usability Scale (SUS)—MeasuringU. Available online: https://measuringu.com/sus/ (accessed on 30 May 2025).
- Rotaru, O.; Vert, S.; Vasiu, R. Usability Evaluation of Requirements Collaboration Features in RM Tools. 2023 International Conference on Engineering and Emerging Technologies, Istanbul, Turkey, 27–28 October 2023; IEEE: Istanbul, Turkey, 2023. [Google Scholar]
- Moran, K. Usability (User) Testing 101. Nielsen Norman Group. 2025. Available online: https://www.nngroup.com/articles/usability-testing-101/ (accessed on 6 February 2025).
- Bantug, T.; Luciano, R.G.; Bauat, R.V. Heuristic Usability Evaluation: A Case Study of Online Enrolment System of a State University. Int. J. Adv. Eng. Res. Sci. 2021, 8, 6. [Google Scholar] [CrossRef] [Scilit]
- Mahfudz, M.S.; Agusti, F.; Zahra, S.A.; Dhini, B.R. Heuristic evaluation analysis using the 10 Nielsen rule usability method on the KAI Access application. Proceeding of the 3rd International Conference Health, Science And Technology (ICOHETECH), Surakarta, Indonesia, 17 September 2022; pp. 325–337. [Google Scholar] [CrossRef] [Scilit]
- Hurst, A.; Lerer, A.; Goucher, A.P.; Perelman, A.; Ramesh, A.; Clark, A.; Ostrow, A.J.; Welihinda, A.; Hayes, A.; Radford, A.; et al. GPT-4o System Card. arXiv 2024, arXiv:2410.21276. [Google Scholar] [CrossRef] [Scilit]
- Guerino, G.; Rodrigues, L.; Capeleti, B.; Ferreira, R.; Freire, A.; Zaina, L. Can GPT-4o Evaluate Usability Like Human Experts? A Comparative Study on Issue Identification in Heuristic Evaluation. arXiv 2025, arXiv:2506.16345. [Google Scholar] [CrossRef] [Scilit]
- Wang, S.; Hu, M.; Li, Q.; Safari, M.; Yang, X. Capabilities of GPT-5 on Multimodal Medical Reasoning. arXiv 2025, arXiv:2508.08224. [Google Scholar] [CrossRef] [Scilit]
- Liu, X.; Ni, Z. Role-playing Prompt Framework: Generation and Evaluation. arXiv 2024, arXiv:2406.00627. [Google Scholar] [CrossRef] [Scilit]
- Zhao, Y.; Wang, Z.; Jung, C.; Zhang, Z. Large Language Model-Driven Structured Output: A Comprehensive Benchmark and Spatial Data Generation Framework. ISPRS Int. J. Geo-Inf. 2024, 13, 405. [Google Scholar] [CrossRef] [Scilit]
- Braun, V.; Clarke, V. Thematic Analysis: A Practical Guide; SAGE Publications Ltd.: Thousand Oaks, CA, USA, 2021; Available online: https://www.torrossa.com/it/resources/an/5282292 (accessed on 3 September 2025).
- Ahmed, A.; Imran, A.S. The role of large language models in UI/UX design: A systematic literature review. arXiv 2025, arXiv:2507.04469. [Google Scholar] [CrossRef] [Scilit]
- Chen, Z.; Liu, Y.; Shi, L.; Wang, Z.-J.; Chen, X.; Zhao, Y.; Ren, F. MDEval: Evaluating and Enhancing Markdown Awareness in Large Language Models. In Proceedings of the ACM on Web Conference 2025, Sydney, Australia, 28 April–2 May 2025; pp. 2981–2991. [Google Scholar] [CrossRef] [Scilit]
- Hsiao, Y.-C.; Zubach, F.; Baechler, G.; Sunkara, S.; Carbune, V.; Lin, J.; Wang, M.; Zhu, Y.; Chen, J. ScreenQA: Large-Scale Question-Answer Pairs Over Mobile App Screenshots. In Proceedings of the 2025 Conference of the Nations of the Americas Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers); Chiruzzo, L., Ritter, A., Wang, L., Eds.; Association for Computational Linguistics: Albuquerque, NM, USA, 2025; pp. 9427–9452. [Google Scholar] [CrossRef] [Scilit]
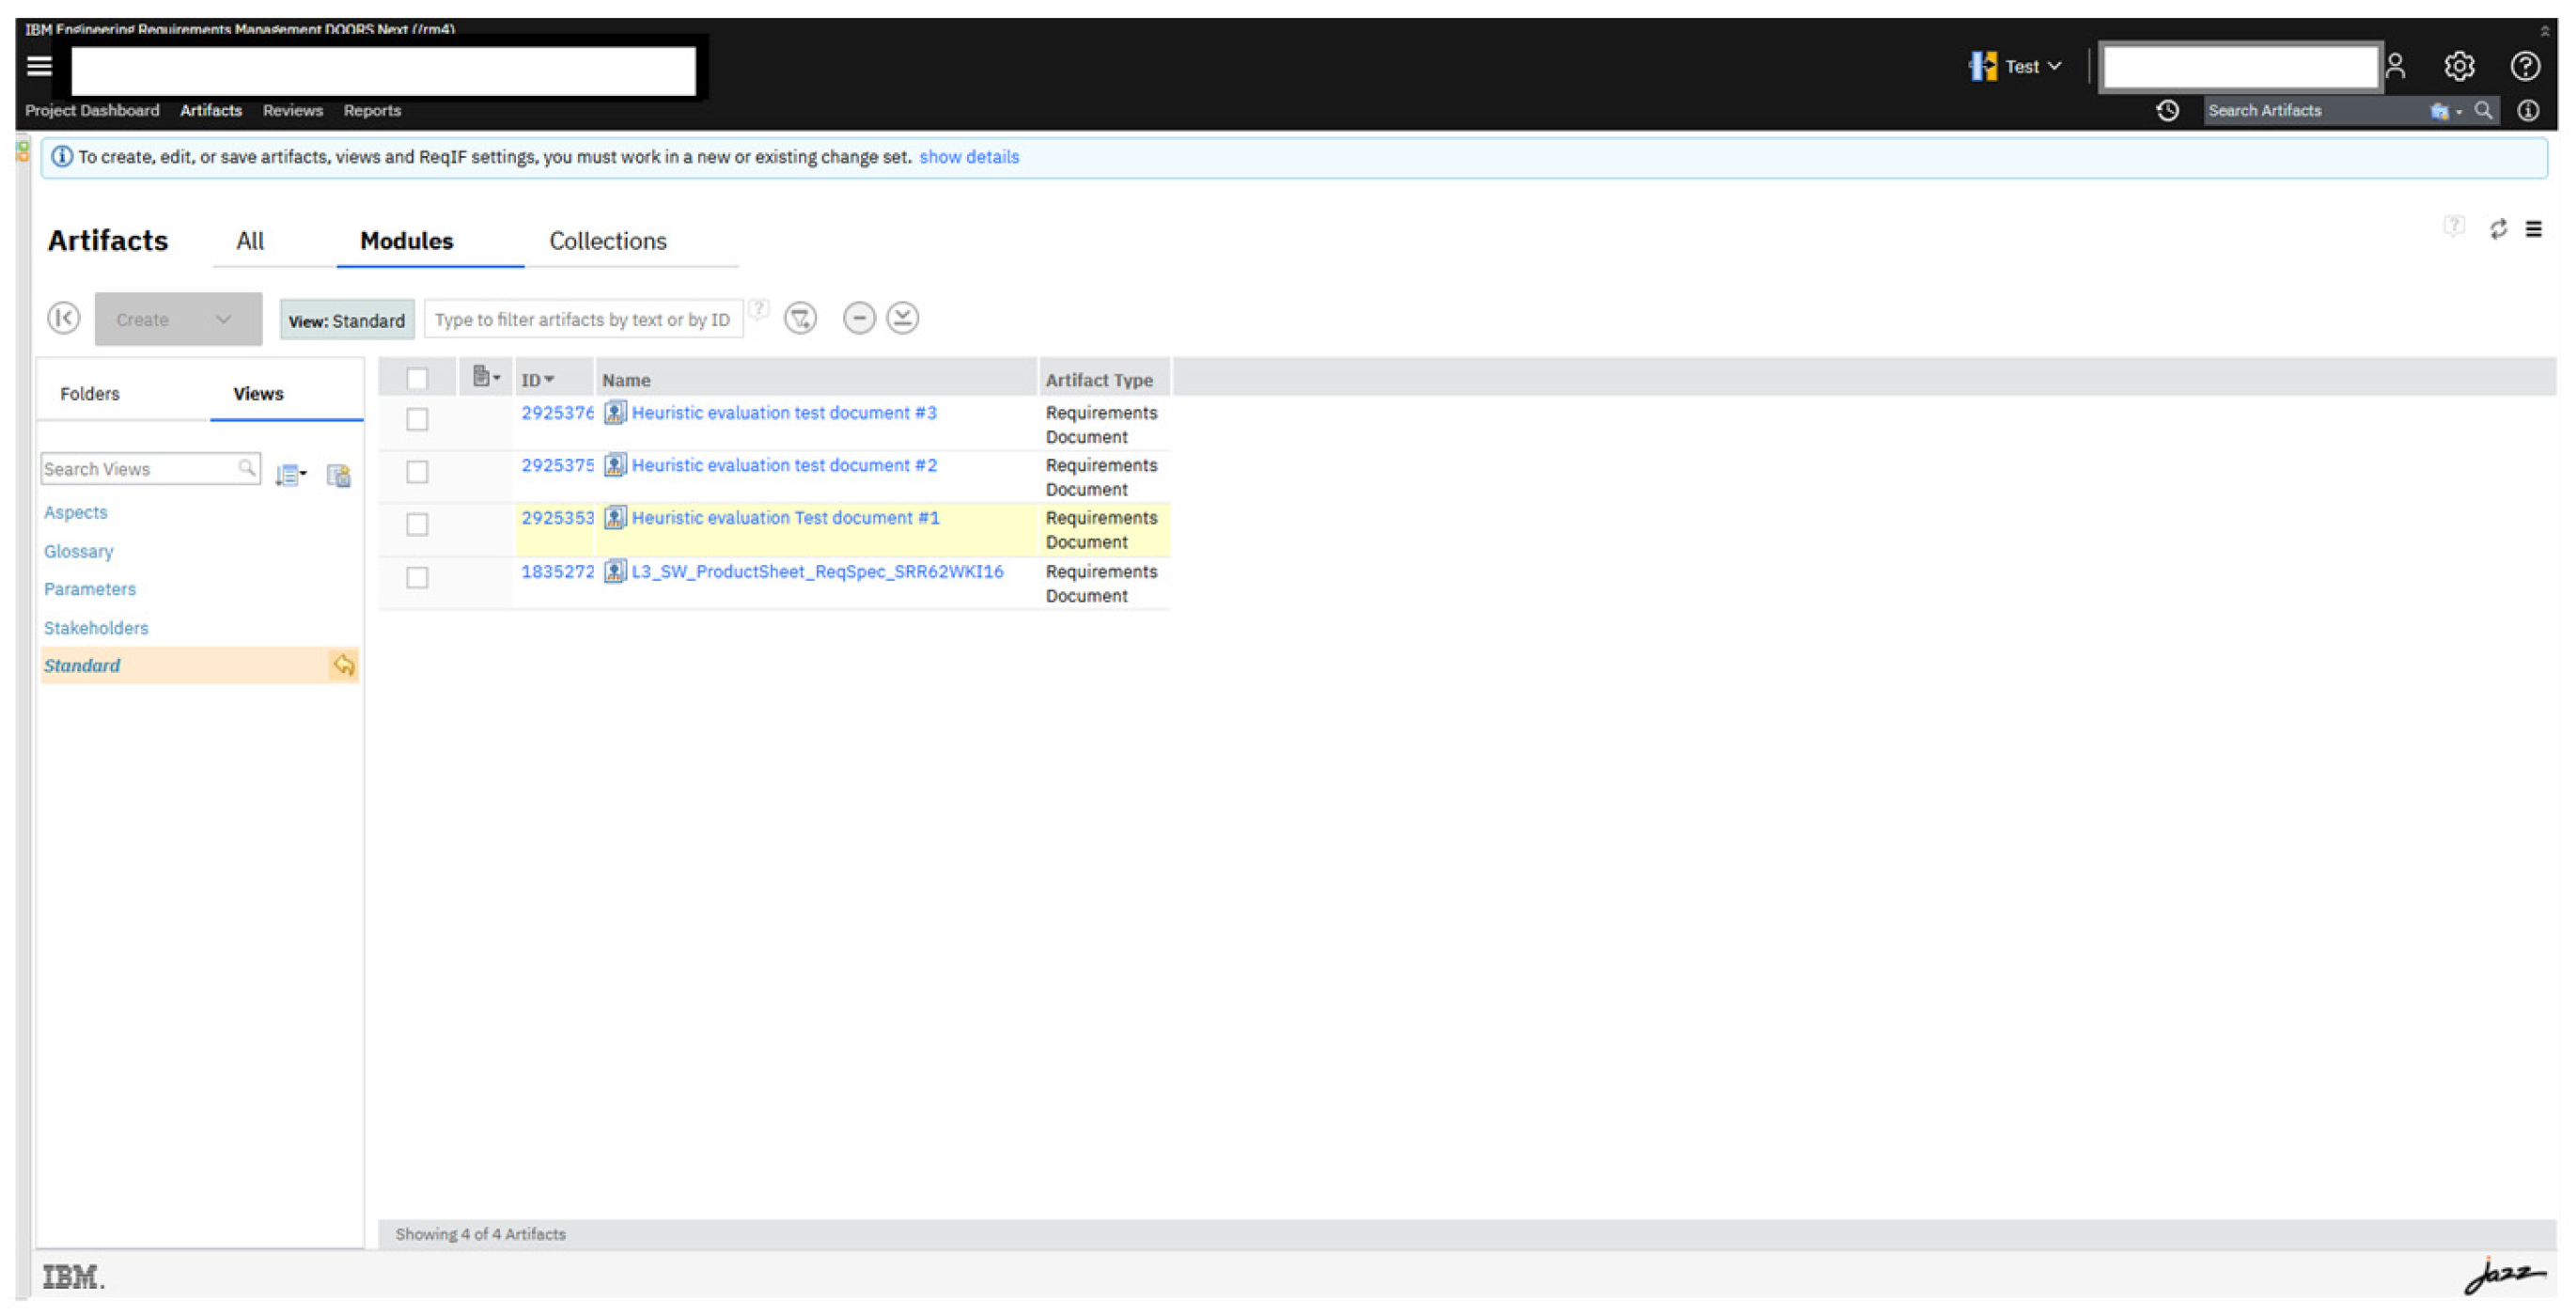
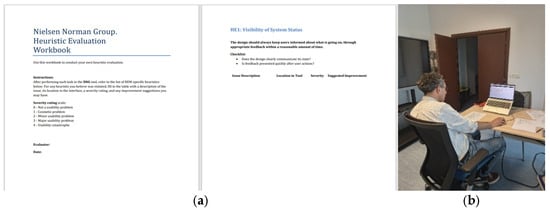
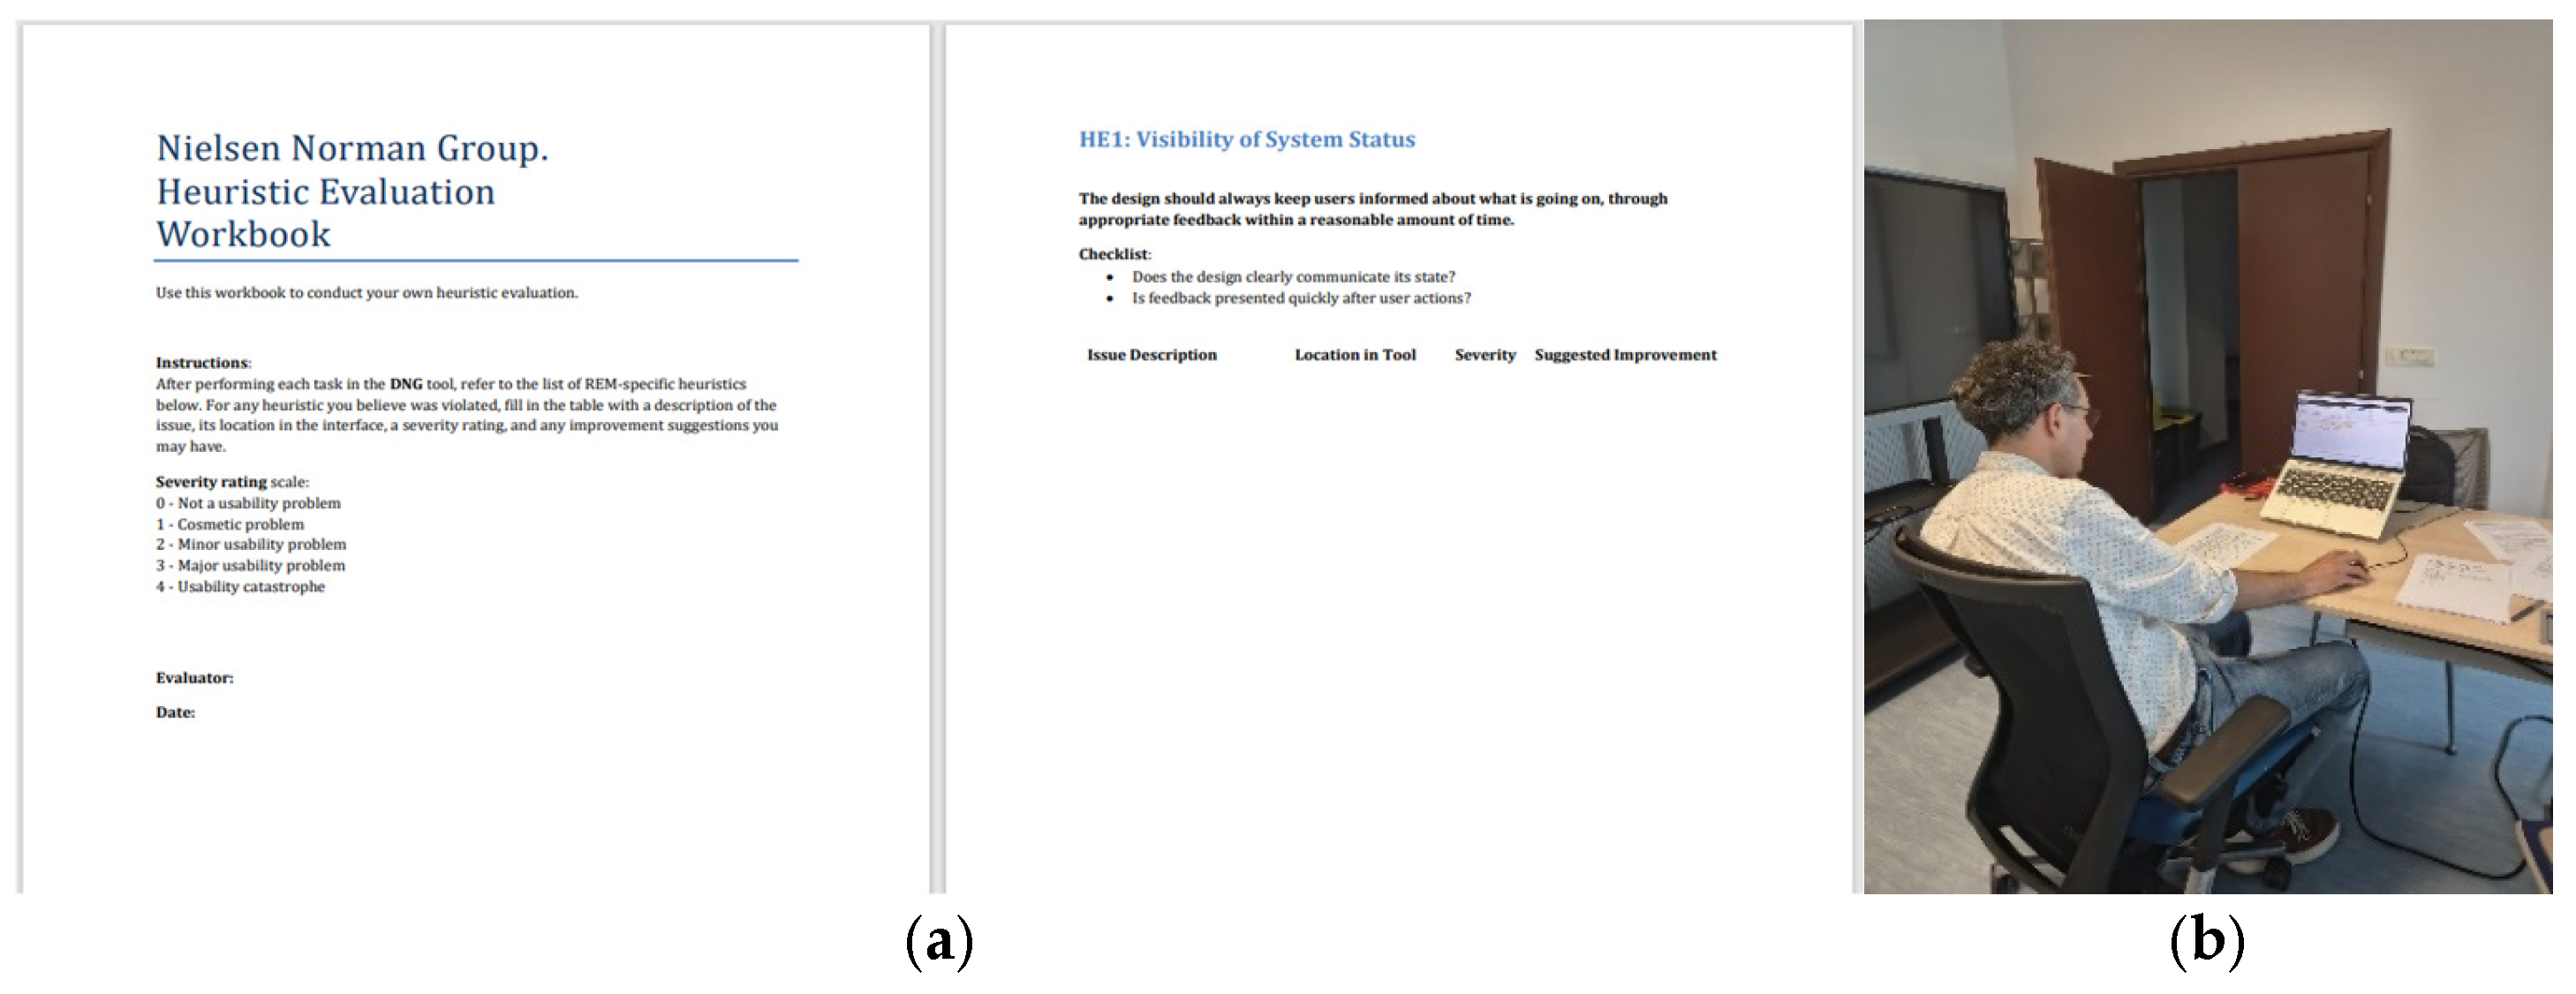
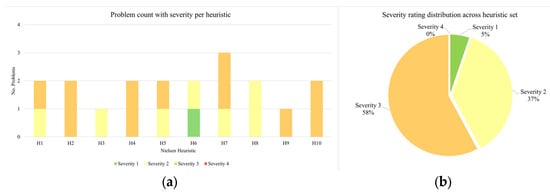
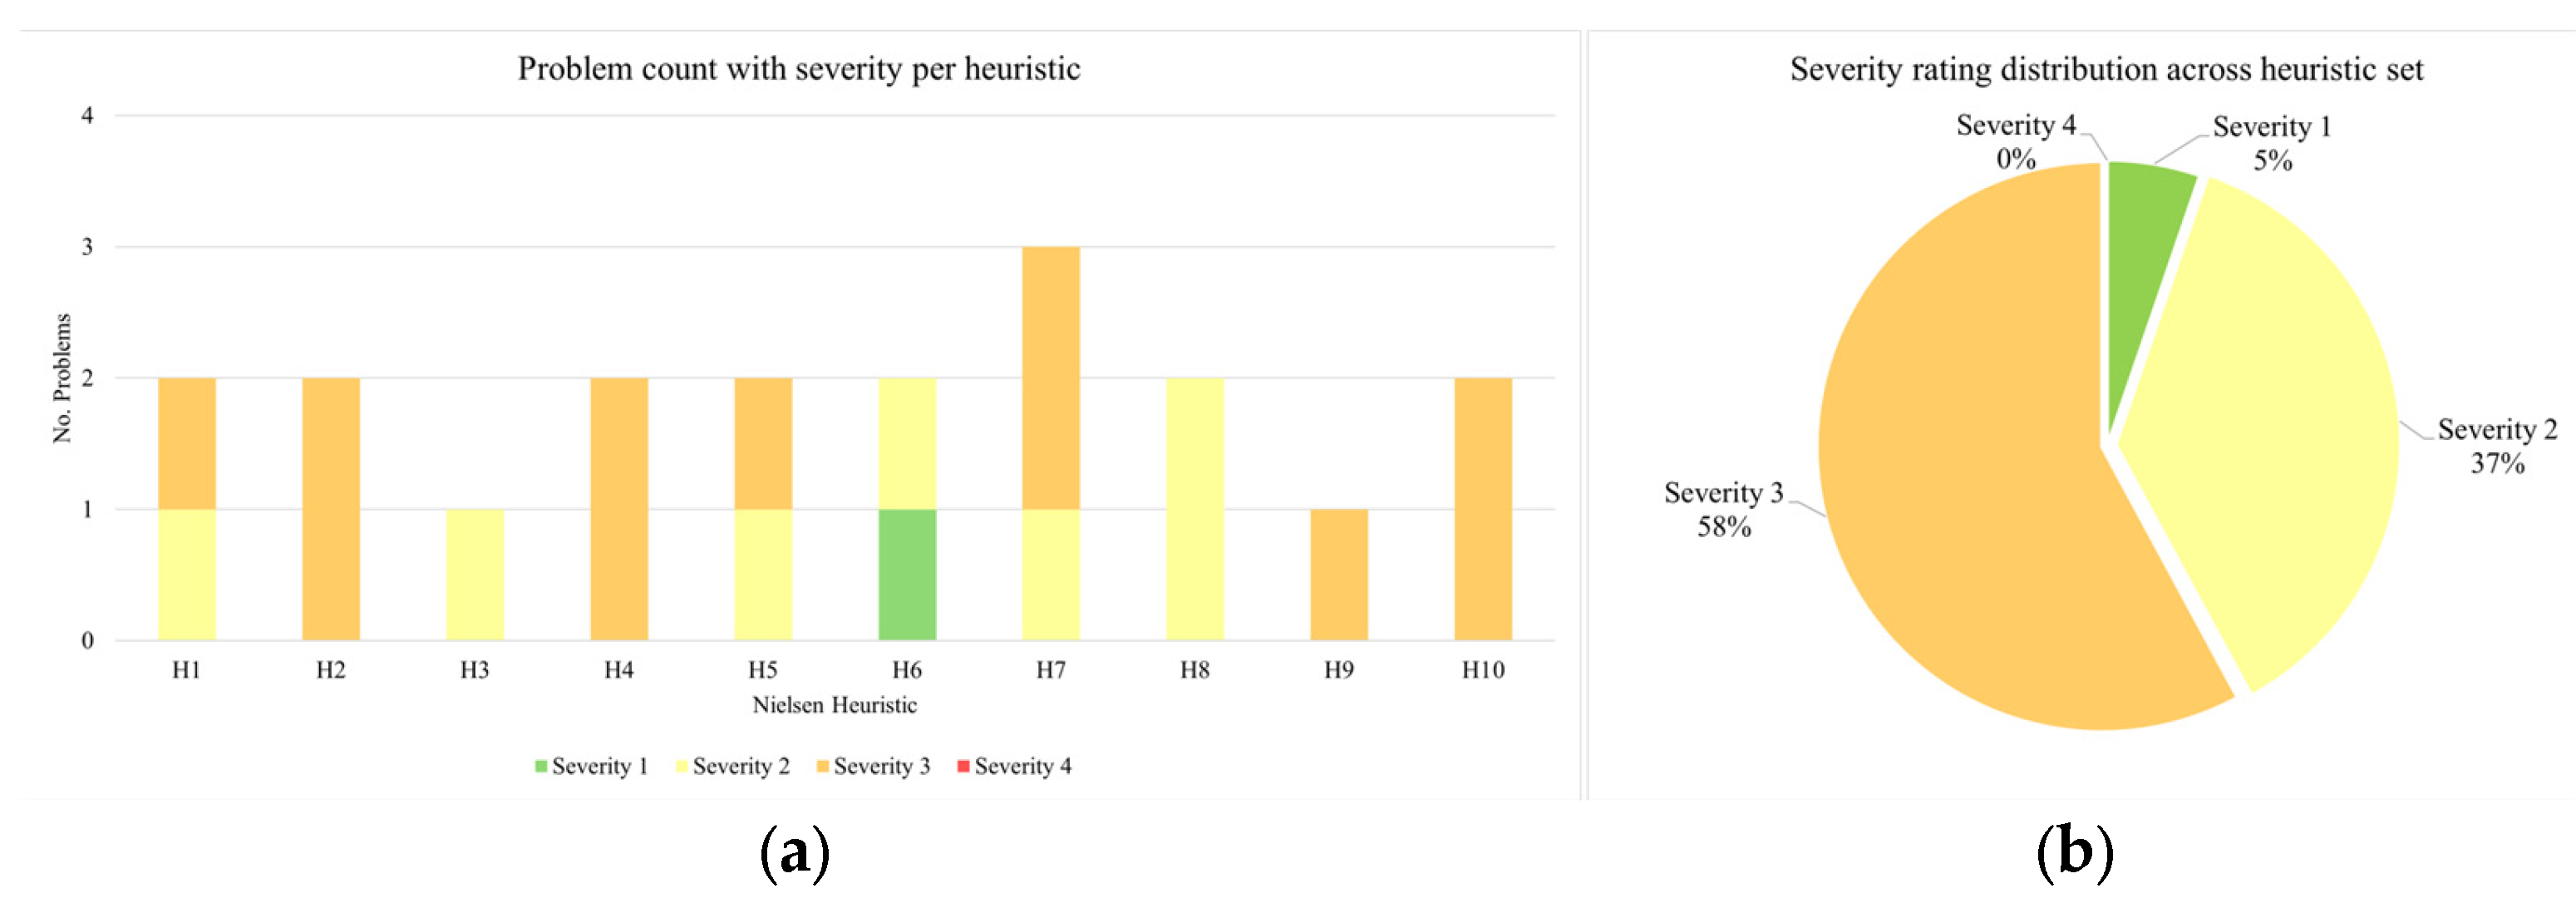
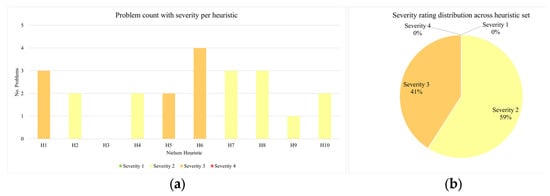
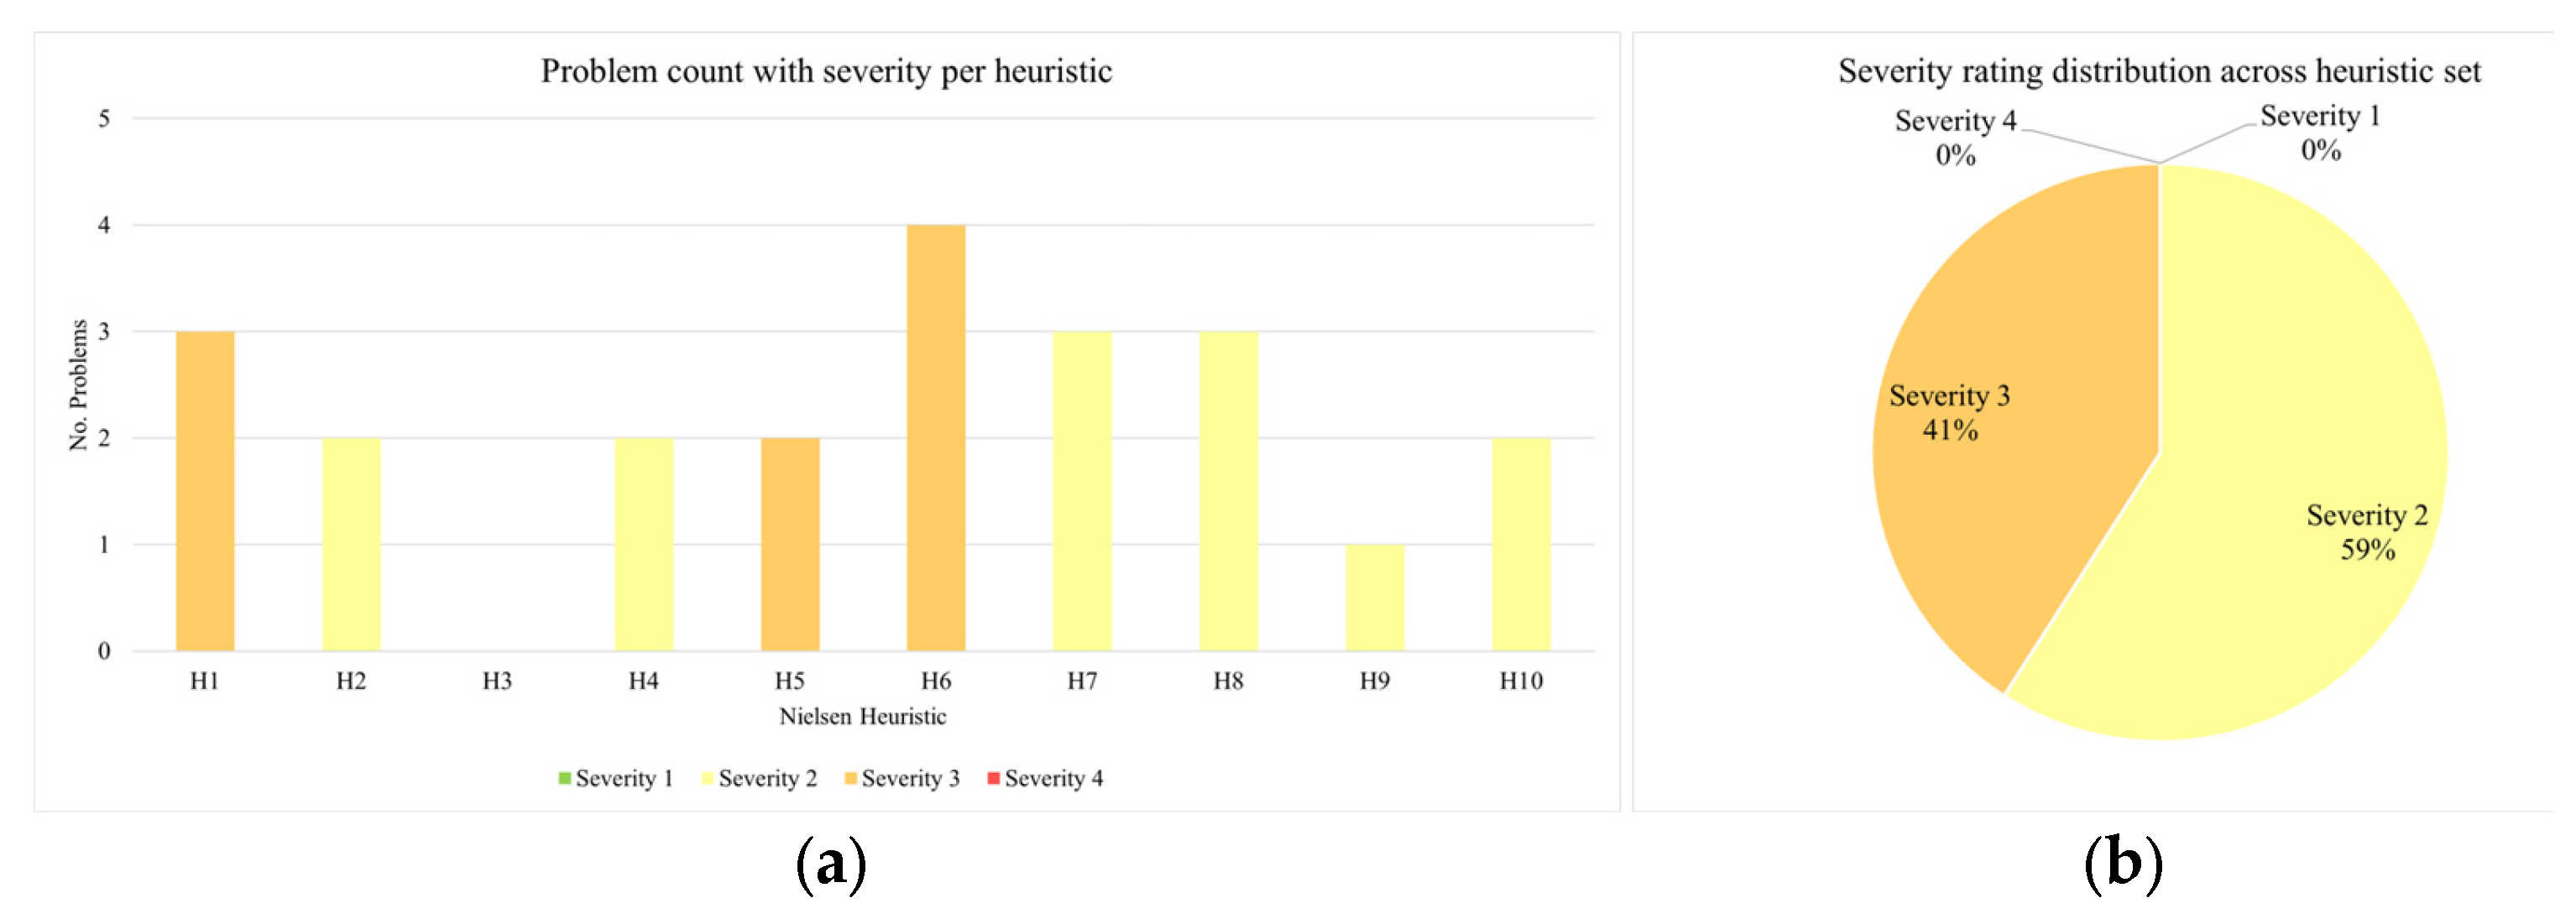
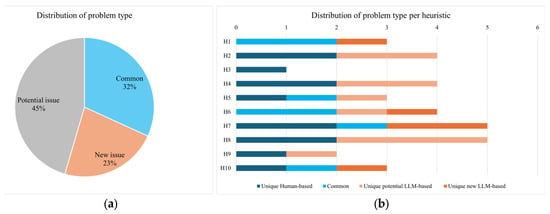
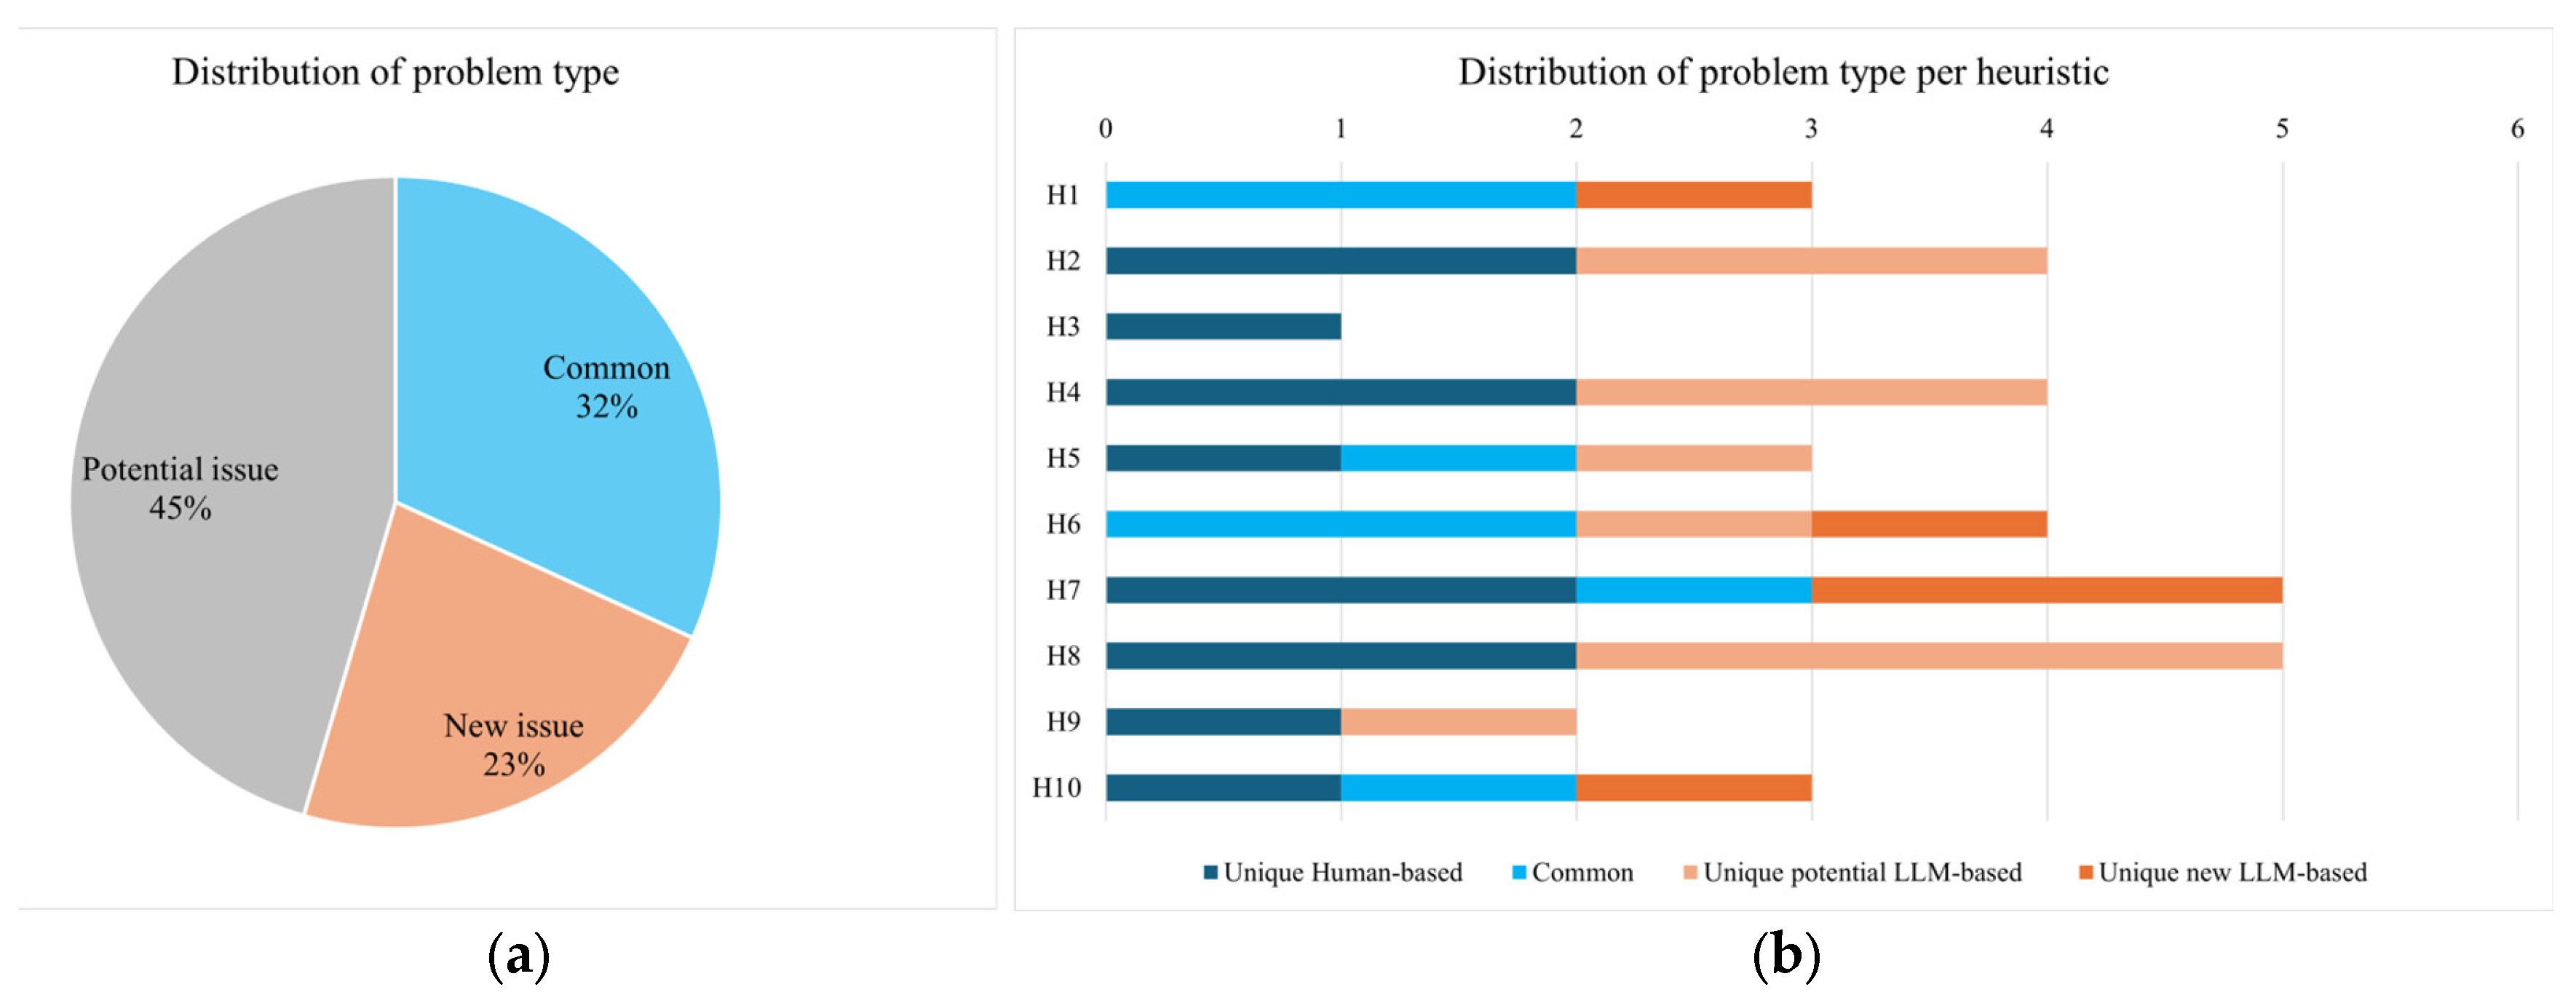
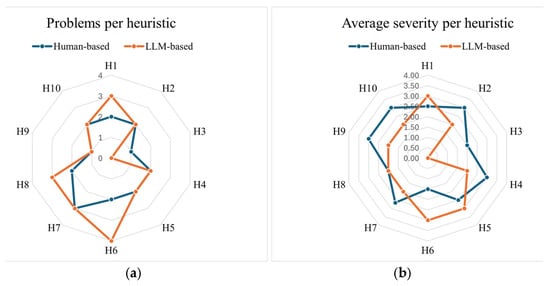
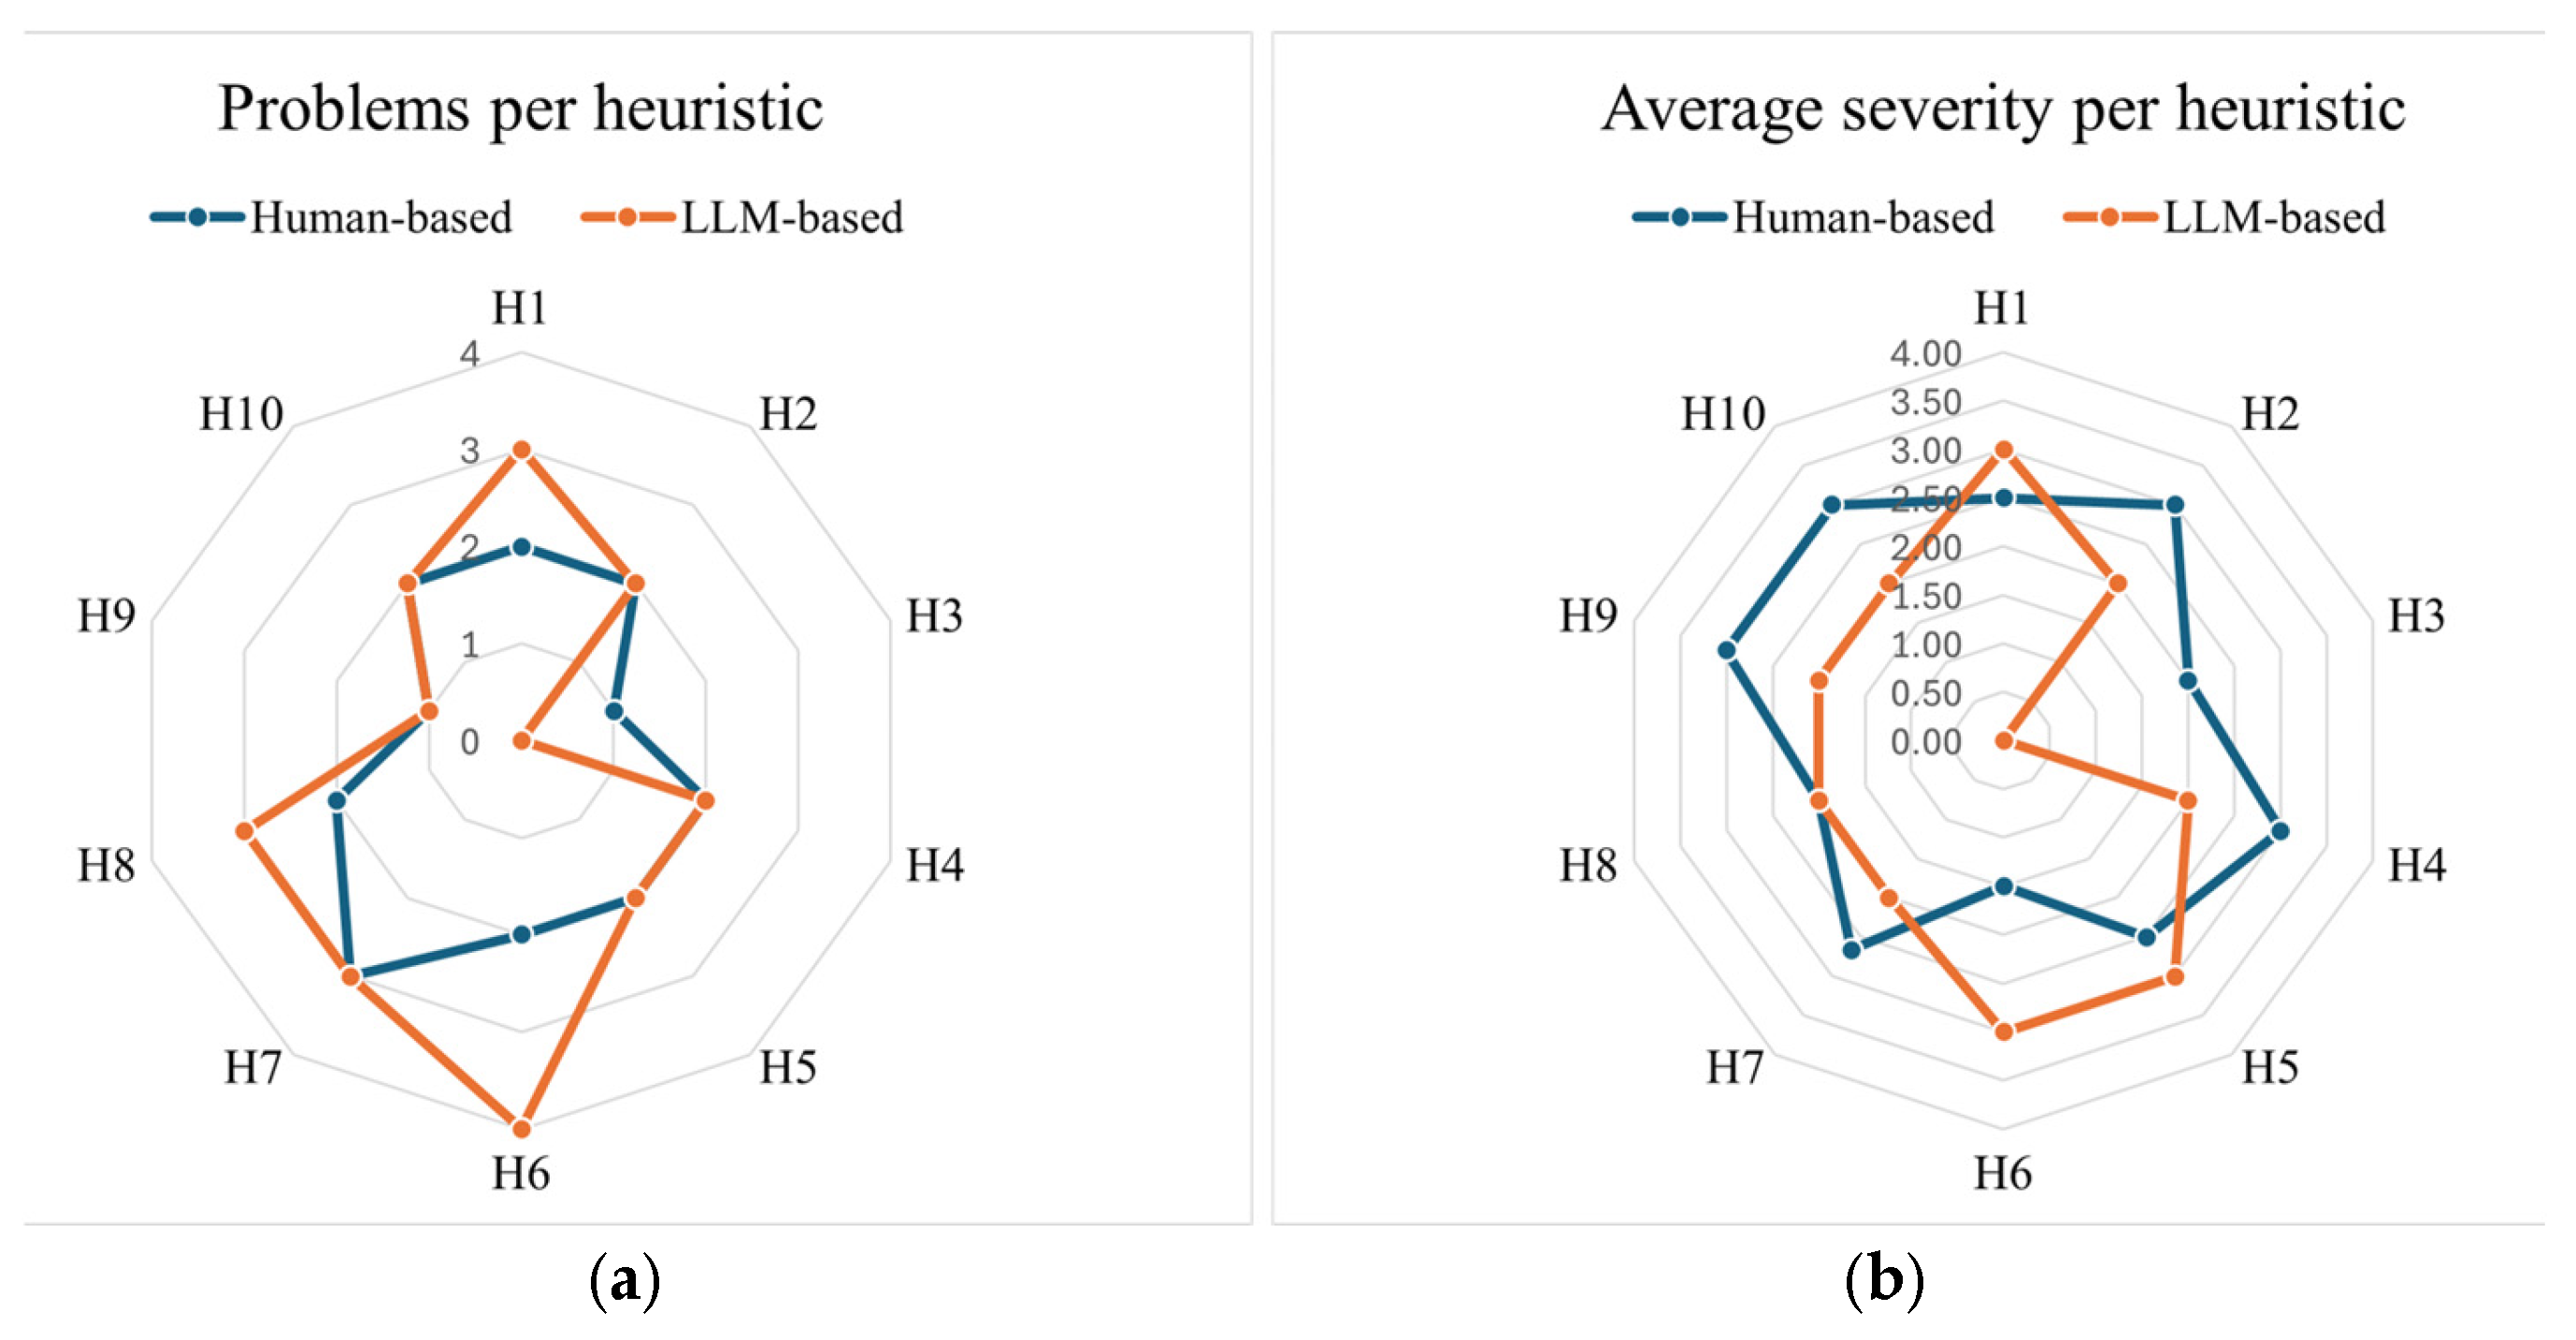

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.