Article

Geometry-Guided Semi-Supervised Multimodal Segmentation for UAV-Based Rice-Lodging Mapping

College of Information Science and Technology and Artificial Intelligence, Nanjing Forestry University, Nanjing 210037, China
*
Author to whom correspondence should be addressed.
Remote Sens. 2026, 18(17), 2961; https://doi.org/10.3390/rs18172961
Submission received: 4 May 2026 / Revised: 8 July 2026 / Accepted: 17 July 2026 / Published: 2 September 2026

Highlights

What are the main findings?
  • We propose GUMatch, a geometry-guided RGB–DSM semi-supervised framework for UAV rice-lodging segmentation with limited labels.
  • Evaluation on the three-parcel UAV rice-lodging collection shows that reliability-aware geometric guidance improves lodged-rice delineation, crop–background discrimination, and cross-scene robustness under limited pixel-level labels.
What are the implications of the main findings?
  • For limited-label UAV agricultural segmentation, DSM information is most useful when it acts as a reliability signal for supervision and boundary recovery rather than as a fixed auxiliary input.
  • The proposed design supports annotation-efficient rice-lodging assessment from co-registered RGB–DSM imagery and offers a reusable paradigm for structure-sensitive multimodal remote-sensing segmentation.

Abstract

Accurate rice-lodging mapping from unmanned aerial vehicle (UAV) imagery supports post-disaster loss assessment, crop insurance, and precision field management. Existing deep-learning methods typically require dense pixel-level annotations, which are costly and time-consuming to produce. Moreover, RGB imagery alone often fails to distinguish lodged from healthy rice when their canopy colors and textures are similar. To address these challenges, we propose Geometry-Guided UniMatch (GUMatch), a semi-supervised multimodal segmentation framework that leverages registered RGB imagery and UAV-derived digital surface models (DSMs). Unlike conventional approaches that treat DSMs as uniformly fused auxiliary channels, GUMatch uses them as reliability-aware geometric priors, incorporating height and boundary evidence to guide lodging segmentation. Our framework integrates three key components. First, Adaptive Geometric Prompting (AGP) injects DSM-based prompt features into the decoder based on local geometric reliability and RGB–DSM compatibility. Second, Geometry-Calibrated Pseudo-Label Learning (GPL) down-weights uncertain pseudo-label supervision within teacher-identified boundary-risk regions. Third, Boundary-Aware Geometric Regularization (BGR) refines boundary localization exclusively where pseudo-labels and geometric evidence are jointly reliable. Experiments are conducted on a three-parcel UAV rice-lodging collection. The main semi-supervised benchmark trains and selects models on the Huai’an parcel HA-P2 under labeled ratios of 10%, 20%, and 40%, and evaluates them on the held-out HA-P1 parcel. The external Wuxi parcel WX-P3 is reserved solely for direct cross-region testing. With an RN-101 backbone, GUMatch achieves 80.12%, 82.98%, and 85.06% mIoU under the three labeled ratios, consistently outperforming representative semi-supervised baselines including UniMatch V2 and RSProtoSemiSeg. With a DINOv2-B backbone, GUMatch further reaches 82.64%, 84.95%, and 86.72% mIoU. On WX-P3 under the 40% labeled setting with models trained on HA-P2, GUMatch with DINOv2-B achieves 68.34% mIoU, improving over UniMatch V2 by 5.39 points. These results demonstrate that reliability-aware geometric guidance enhances annotation-efficient UAV-based rice-lodging mapping.

1. Introduction

Rice feeds more than half of the world’s population, making stable production closely linked to food security and rural livelihoods—particularly in Asian monsoon regions, where yield fluctuations can have broad socioeconomic effects [1,2]. Lodging, the permanent displacement of rice stems from their upright position, is one of the most damaging stresses in rice production. It reduces yield, lowers grain quality, and interferes with mechanical harvesting [3,4,5]. Timely mapping of lodged areas is therefore critical for disaster assessment, crop insurance, phenotyping, and field management [6,7,8]. Compared with labor-intensive field surveys and coarse-resolution satellite observations, unmanned aerial vehicle (UAV) remote sensing offers a flexible, high-resolution, and nondestructive solution for field-scale lodging monitoring [9,10,11,12]. Consequently, UAV-based lodging assessment has become an important topic in precision agriculture.
Deep-learning-based semantic segmentation has recently emerged as the dominant paradigm for extracting lodging information from UAV optical imagery. Su et al. [13] proposed LodgeNet, which integrates DenseNet blocks, dilated convolutions, and channel attention into a U-Net backbone, achieving 97.30% pixel accuracy on UAV rice-lodging imagery. Sun et al. [14] developed RL-DeepLabv3+, a lightweight DeepLabV3+ variant with a channel-wise feature-pyramid backbone and depth-wise separable convolutions for real-time lodging detection on unmanned rice harvesters. Kang et al. [15] introduced GloAN, a plug-in global-attention module that can be embedded into various CNN backbones to improve rice-lodging segmentation with limited computational overhead. Zhang et al. [16] presented AAUConvNeXt, which couples a U-Net–ConvNeXt encoder with an intelligent optimization algorithm for automatic hyperparameter selection. While these studies demonstrate the feasibility of deep-learning-based lodging segmentation from UAV RGB imagery, they leave two important limitations unaddressed.
The first limitation concerns input modality. Most existing lodging-mapping methods rely solely on RGB imagery, despite the fact that spectral and textural contrast between lodged and healthy rice is often weak. Lodged canopies may resemble healthy canopies under varying illumination and growth-stage conditions, while bare soil and field ridges introduce confounding textures. Consequently, color information alone is frequently insufficient for separating crop and background regions [6,7,8]. Moreover, lodging is inherently a structural phenomenon: it reduces canopy height and weakens vertical structure—three-dimensional cues that cannot be fully captured by two-dimensional appearance features [3,17,18,19]. Digital surface models (DSMs), derived from photogrammetric reconstruction or LiDAR, encode canopy-height and surface-structure information [20,21]. Studies on wheat lodging have shown that RGB–DSM fusion improves accuracy over RGB alone [20], and multimodal remote-sensing research broadly indicates that elevation or geometric cues can strengthen spectral features for land-cover classification [22,23,24,25,26]. These findings suggest that DSM is a promising information source for rice-lodging segmentation, yet its integration into a dedicated framework remains underexplored.
The second limitation is annotation cost. Semantic segmentation demands dense pixel-level labels, which are expensive to produce for lodging scenes due to heterogeneous field conditions and gradual, often ambiguous boundaries [7,16]. Most existing lodging-segmentation studies operate in a fully supervised setting, assuming the availability of large annotated training sets [13,14,16,27]. Semi-supervised semantic segmentation addresses this issue by combining a small labeled subset with abundant unlabeled imagery. Teacher–student frameworks with weak-to-strong consistency, such as UniMatch [28] and UniMatch V2 [29], have substantially narrowed the gap between semi-supervised and fully supervised segmentation. Remote-sensing methods like RSProtoSemiSeg [30] further adapt semi-supervised learning to RGB imagery through prototype-based regularization. However, these methods remain predominantly appearance-driven: their pseudo-label selection or weighting relies mainly on RGB semantic confidence, without leveraging DSM geometry to verify uncertain boundaries. In contrast, RGB–DSM segmentation networks such as CMGFNet [22], LMFNet [24], and GIMMNet [26] focus on supervised cross-modal feature fusion and assume dense labels. They do not address pseudo-label noise in unlabeled multimodal data, nor do they explicitly assess whether local DSM evidence is reliable. Consequently, a direct combination of UniMatch V2 with a standard RGB–DSM fusion module is insufficient for limited-label rice-lodging segmentation. An effective method must exploit DSM height and boundary cues while simultaneously managing unreliable geometry and ambiguous pseudo-label supervision.
To address these limitations, we propose Geometry-Guided UniMatch (GUMatch), a semi-supervised segmentation framework for registered UAV RGB and DSM imagery. GUMatch is neither a simple DSM-input extension of UniMatch V2 nor a semi-supervised version of a fully supervised RGB–DSM fusion network. It retains the effective teacher–student optimization scaffold of UniMatch V2 but fundamentally changes how geometric information enters both representation learning and unlabeled supervision. The core idea is to treat DSM not as a uniformly fused auxiliary channel but as a reliability-aware geometric prior for height and boundary reasoning. This design is motivated by two observations: (1) DSM quality is spatially nonuniform because height estimates can be affected by canopy occlusion, reconstruction noise, surface discontinuities, and residual mis-registration; and (2) geometric cues are most valuable where RGB appearance is ambiguous, particularly near lodging boundaries and mixed-canopy areas.
Based on these observations, GUMatch integrates three geometry-guided components at different levels of the semi-supervised pipeline: Adaptive Geometric Prompting (AGP) for reliability-aware decoder prompting, Geometry-Calibrated Pseudo-Label Learning (GPL) for geometry-calibrated pseudo-label supervision, and Boundary-Aware Geometric Regularization (BGR) for conservative boundary refinement. This decomposition allows DSM evidence to guide representation learning and unlabeled supervision without treating every DSM response as equally trustworthy. During weak-to-strong training, strong appearance perturbations are applied only to RGB images, while DSM inputs follow synchronized geometric transformations to preserve height meaning and cross-modal alignment.
The main contributions of this study are summarized as follows:
  • We propose GUMatch, a geometry-guided semi-supervised multimodal segmentation framework for UAV rice-lodging mapping. Unlike single-modal semi-supervised methods, GUMatch leverages DSM to guide both feature decoding and pseudo-label reliability. Unlike supervised RGB–DSM fusion networks, it is designed for unlabeled RGB–DSM pairs and explicitly models unreliable local geometry.
  • We design AGP, a reliability-aware decoder prompting module that selectively injects DSM height and boundary evidence based on local geometric reliability and RGB–DSM compatibility.
  • We develop a coupled geometry-calibrated supervision strategy combining GPL and BGR to suppress boundary-risk pseudo-label noise and apply conservative geometric boundary constraints.
  • We construct a three-parcel UAV rice-lodging collection and evaluate GUMatch under a strict parcel-level split. HA-P2 serves for training and validation with 10%, 20%, and 40% labeled ratios; HA-P1 is the held-out Huai’an test parcel; and WX-P3 provides external cross-region testing. Under the DINOv2-B setting, GUMatch improves over UniMatch V2 by 5.39 mIoU points on WX-P3. The results demonstrate consistent gains over representative semi-supervised baselines, particularly in lodged-rice boundary recovery and heterogeneous-background suppression.

2. Dataset Acquisition

2.1. Study Area and Data Acquisition

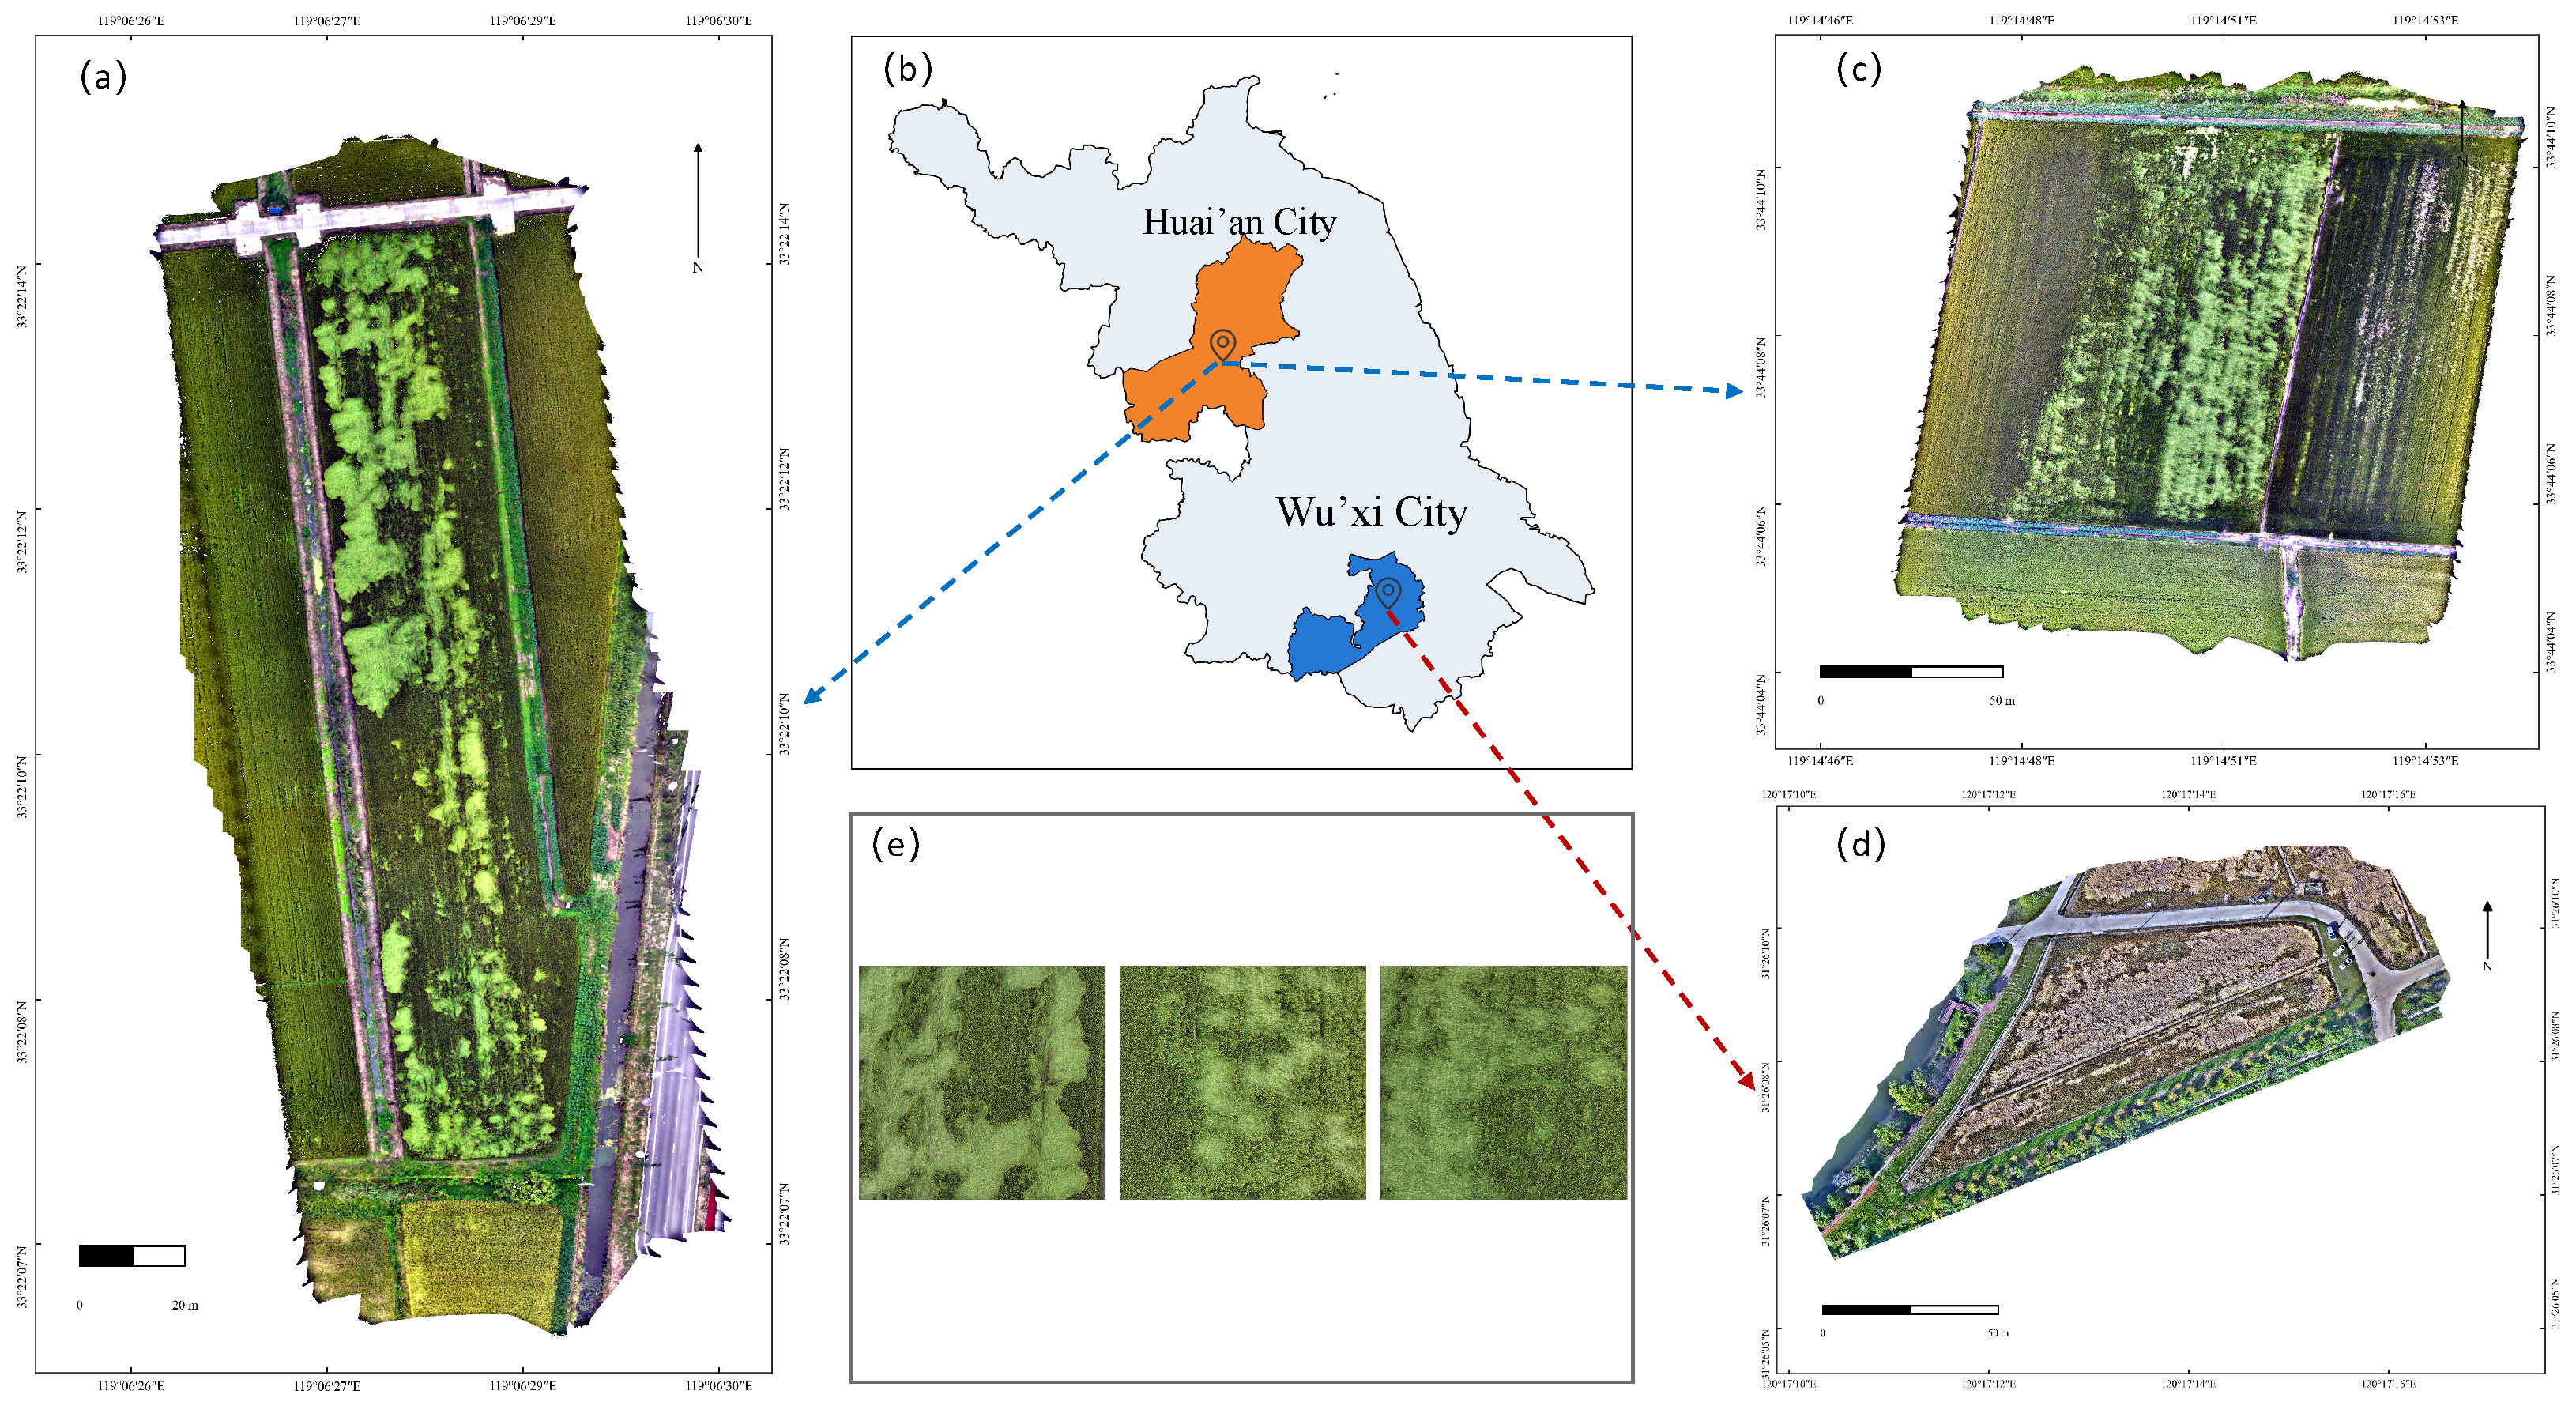
The UAV rice-lodging data comprise three parcel-level subsets collected from two rice-production regions in Jiangsu Province, China. Two parcels were acquired at Baimahu Farm, a national seed-production base in Huai’an District, Huai’an City: the 4.2 ha parcel shown in Figure 1a, denoted as HA-P1, and the 4.9 ha parcel in Figure 1c, denoted as HA-P2. Located near 33 22 N and 119 06 E on the eastern Jianghuai Plain, the farm features flat terrain suitable for large-scale rice cultivation. The region has a temperate monsoon climate, with an annual mean temperature of 13.8–14.8 °C, annual precipitation of 906–1007 mm, and approximately 2160 h of sunshine annually. Paddy soil and fluvo-aquic soil are the dominant soil types.
A third 2.7 ha parcel from Binhu District, Wuxi City, denoted as WX-P3 and shown in Figure 1d, is also included. Located near 31 26 N and 120 17 E on the northern Taihu Plain, this region has a northern subtropical humid monsoon climate, with an annual mean temperature of 15.4–16.5 °C, annual precipitation of 1050–1150 mm, and approximately 1920 h of sunshine annually. Paddy soil and fluvo-aquic soil are again the main soil types. The Huai’an parcels were imaged during the growing stage, whereas WX-P3 was imaged near harvest. Consequently, WX-P3 contains more complex backgrounds due to stronger shadow effects and more exposed soil.
Figure 1 provides an overview of the three-parcel collection: Figure 1a,c shows the global previews of HA-P1 and HA-P2, Figure 1b marks the locations of Huai’an and Wuxi within Jiangsu Province, Figure 1d shows the global preview of WX-P3, and Figure 1e presents representative lodged-rice image samples. In our evaluation protocol, HA-P2 serves as the model-development parcel, HA-P1 is the held-out Huai’an test parcel, and WX-P3 provides the external cross-region test.
UAV observations were acquired with a DJI Matrice 300 RTK platform equipped with a Zenmuse L2 LiDAR payload. The system synchronously collected RGB imagery and point-cloud data, from which co-registered orthophoto mosaics and DSM products were generated. Table 1 summarizes the main platform, sensor, flight, and image-product parameters.

2.2. RGB and DSM Preprocessing

The raw UAV observations were processed in DJI Terra to generate co-registered multimodal products. The workflow included image mosaicking, radiometric correction, color correction, spatial registration, point-cloud reconstruction, and the generation of digital orthophoto maps and DSMs. The resulting RGB images and DSMs were exported as paired .tif files to preserve georeferencing information and pixel-level alignment. This alignment is essential because the proposed framework uses DSM not only as an input modality but also as a source of geometric priors for decoder prompting, pseudo-label calibration, and boundary regularization.
Pixel-wise annotations were produced in ArcGIS Pro 3.1 on the high-resolution orthophoto mosaics. Each pixel was assigned to one of three semantic categories: lodged rice, healthy rice, or background. Lodged rice denotes areas with visible tilting, flattening, or canopy collapse following wind, heavy rainfall, or related disturbances; these regions typically exhibit disordered texture, darker tones, and irregular canopy structure. Healthy rice denotes upright rice with normal growth, appearing as brighter and more spatially homogeneous canopy cover. Field ridges, roads, bare soil, shadows, water surfaces, weeds, and other nontarget objects were assigned to the background class.
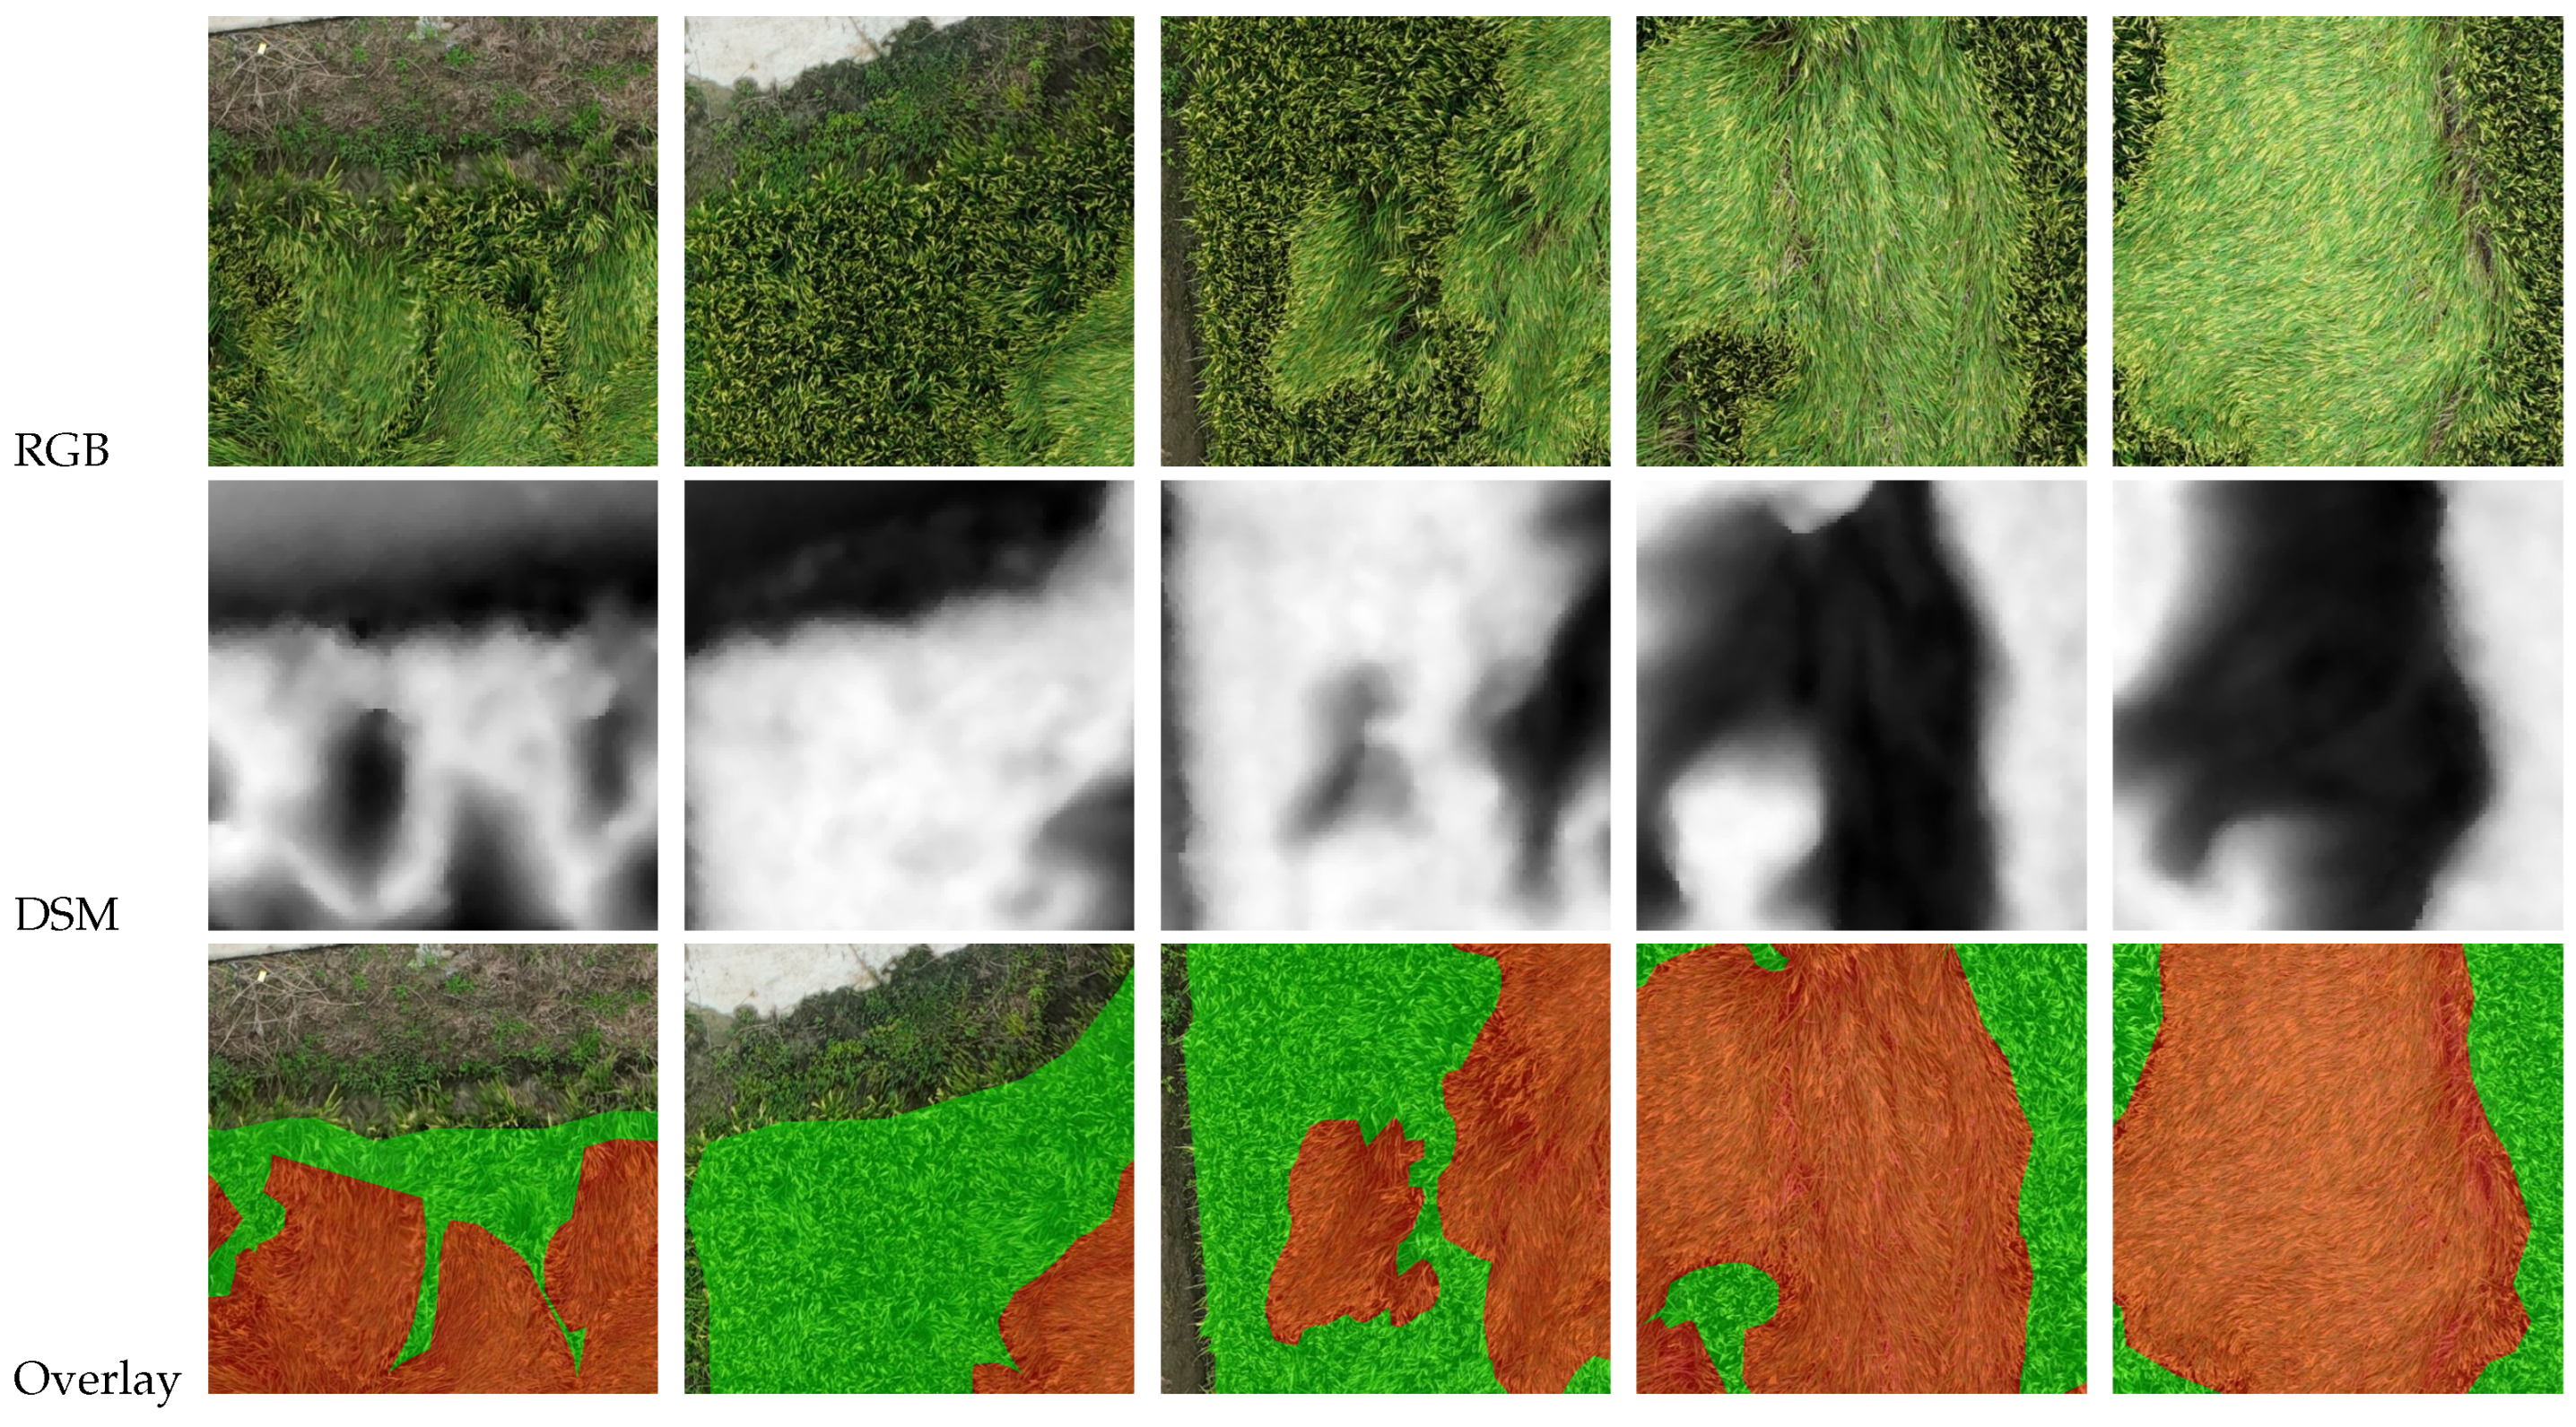
The annotation workflow comprised three steps. First, trained annotators delineated category polygons on the georeferenced orthophoto mosaics according to the visual interpretation rules above. Second, experts in UAV agricultural image interpretation reviewed the polygon layers and verified category consistency across parcels. Third, boundary correction was performed by jointly inspecting the RGB mosaic, DSM product, and annotation layer, particularly near gradual lodging transitions, narrow ridges, shadowed areas, and mixed crop–background boundaries. The final vector annotations were rasterized to the same grid as the RGB and DSM products and exported as pixel-level label masks. Figure 2 shows representative examples.  

2.3. Parcel-Level Split and Semi-Supervised Setting

To evaluate annotation-efficient rice-lodging mapping while reducing spatial leakage, we adopted a parcel-level semi-supervised split protocol with explicit cross-scene testing. In the main HA-P2/HA-P1 benchmark, HA-P2 was used for training and validation, while HA-P1 served as the held-out in-region test parcel. The external WX-P3 parcel was reserved for direct cross-region testing. No tile from HA-P1 or WX-P3 was used for parameter updates, model selection, or hyperparameter tuning. Random tile-level splitting was avoided because neighboring UAV tiles often share similar texture, illumination, canopy structure, and height patterns, which can lead to overly optimistic accuracy estimates.
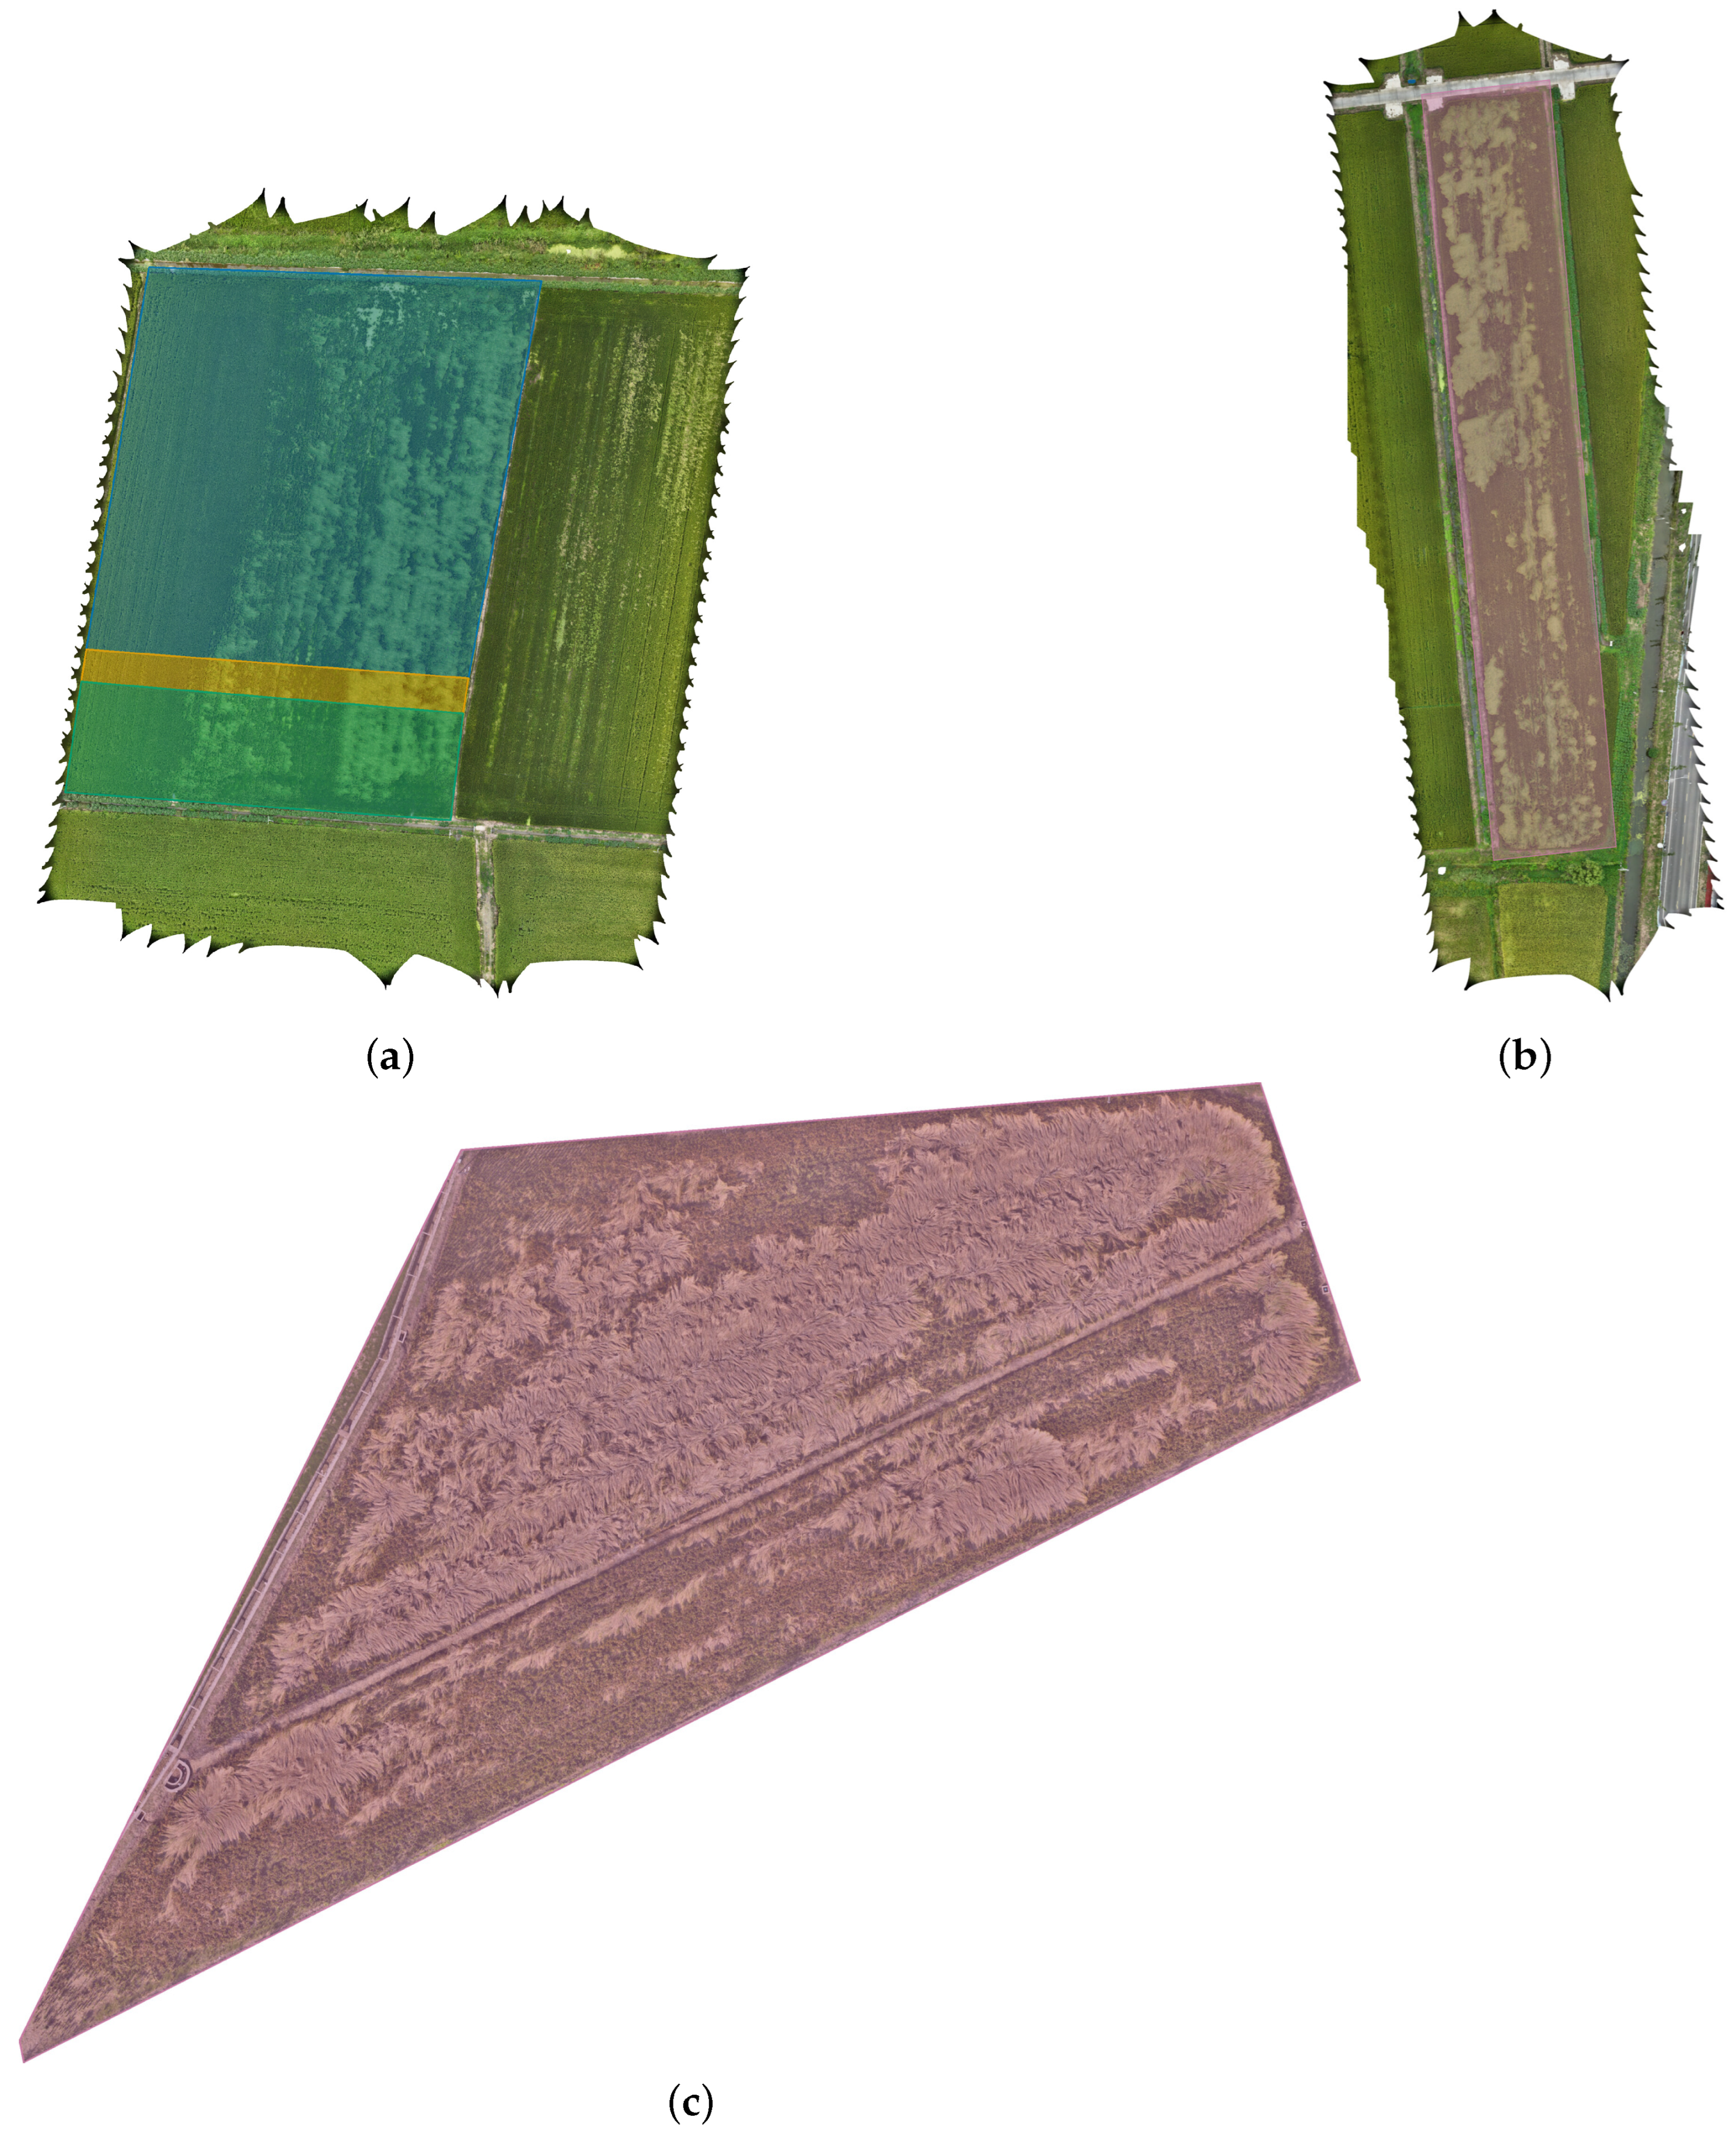
Appendix A provides spatial partition maps with semi-transparent overlays for all three parcels, complementing Figure 1 and allowing readers to inspect the spatial separation among the HA-P2 model-development regions, the HA-P1 in-region test parcel, and the WX-P3 external test parcel.
For the main benchmark, HA-P2 was first divided into spatially contiguous training and validation regions. All parcels were then synchronously cropped into 512 × 512 pixel RGB and DSM tiles. Tiles with large blank regions, insufficient valid content, or poor image quality were removed. The main benchmark contains approximately 1400 high-quality paired tiles, and the external WX-P3 set contributes 300 additional fully annotated paired tiles for direct cross-region testing. Under the semi-supervised setting, only 10%, 20%, or 40% of the HA-P2 training tiles retained pixel-level annotations, while the remaining training tiles were used as unlabeled data. The validation set was used for model selection and hyperparameter tuning but not for parameter updates. The HA-P1 test set was fixed across all labeled ratios and used only for final evaluation. Unless otherwise stated, each experiment was repeated three times with different labeled and unlabeled splits using seeds 0, 1, and 2, and the mean performance is reported.
To further examine cross-region generalization, we directly evaluated the 40% labeled HA-P2-source models on WX-P3. All training, validation, and model-selection operations remained confined to HA-P2; WX-P3 was used only for final testing and was not involved in parameter updates or hyperparameter tuning. The WX-P3 results are reported in Section 4.4.
This protocol defines the learning problem considered in the following Section 3. The labeled set is denoted as
D l = x i r , x i d , y i i = 1 N l ,
where x i r R H × W × 3 is the RGB tile, x i d R H × W × 1 is the aligned DSM tile, and y i { 1 , , C } H × W is the pixel-level annotation. The unlabeled set is denoted as
D u = x j r , x j d j = 1 N u .
GUMatch uses paired RGB and DSM inputs in both sets. The labels in D l provide supervised category learning, whereas the unlabeled pairs in D u are used to construct geometry-guided pseudo-label supervision during teacher–student training.

3. Method

To improve readability, we use bold uppercase symbols for image-level maps or tensors and lower-case indexed symbols for their pixel values, e.g., U and u i . Algorithms 1 and 2 use the same map-level symbols as the corresponding formulas. The main abbreviations and symbols are also summarized in the “Abbreviations and Symbols” section at the end of the paper.

3.1. Framework Overview

Figure 3 compares UniMatch V2 with the proposed GUMatch. UniMatch V2 [29] employs an EMA teacher–student framework with weak-to-strong consistency. The teacher generates pseudo-labels from a weakly augmented view, while the student learns from two strong views derived from the same image. Complementary channel-wise dropout is applied to strong-view features before decoding, enabling the same weak-view supervision to regularize both streams. GUMatch retains this effective optimization scaffold but introduces a DSM encoder, a DSM edge prior, reliability-aware decoder prompting, geometry-calibrated pseudo-label weights, and a boundary regularizer. These components allow DSM evidence to guide both feature decoding and teacher–student supervision.
Unlike supervised RGB–DSM segmentation networks such as CMGFNet and LMFNet, which learn cross-modal feature interaction from densely labeled data, GUMatch focuses on unlabeled RGB–DSM pairs and explicitly assesses whether DSM evidence should be trusted before modifying decoder features or pseudo-label supervision. This distinction is critical for UAV rice-lodging scenes, where photogrammetric DSMs may contain local noise, voids, and residual mis-registration.
The data flow in GUMatch links AGP, GPL, and BGR through a shared DSM edge prior. For each RGB–DSM branch, the DSM encoder produces a prompt pyramid and an edge-prior map. AGP uses these signals to gate the RGB decoder features. On the weak view, the teacher prediction provides pseudo-labels, confidence scores, and a semantic boundary response. GPL combines these teacher outputs with the DSM edge prior to generate calibrated confidence weights, valid pseudo-label masks, and boundary bands in weak-view coordinates. The same geometric transformations then transfer these targets and the DSM edge prior to the two strong views. BGR is applied to the strong-view student predictions only within the transferred valid boundary regions. Thus, the edge prior flows from decoder prompting to pseudo-label calibration and boundary regularization, while GPL controls where the boundary loss is permitted to act.
During weak-to-strong training, strong appearance perturbations are applied only to RGB, whereas DSM follows synchronized geometric transformations to preserve height meaning and RGB–DSM alignment. GUMatch uses paired RGB–DSM inputs during both training and inference, so the DSM branch is not merely a training-only auxiliary module. AGP requires DSM to produce gated decoder features, and the geometry-guided losses use DSM to define boundary-risk and edge-prior signals during training.

3.2. Adaptive Geometric Prompting Module

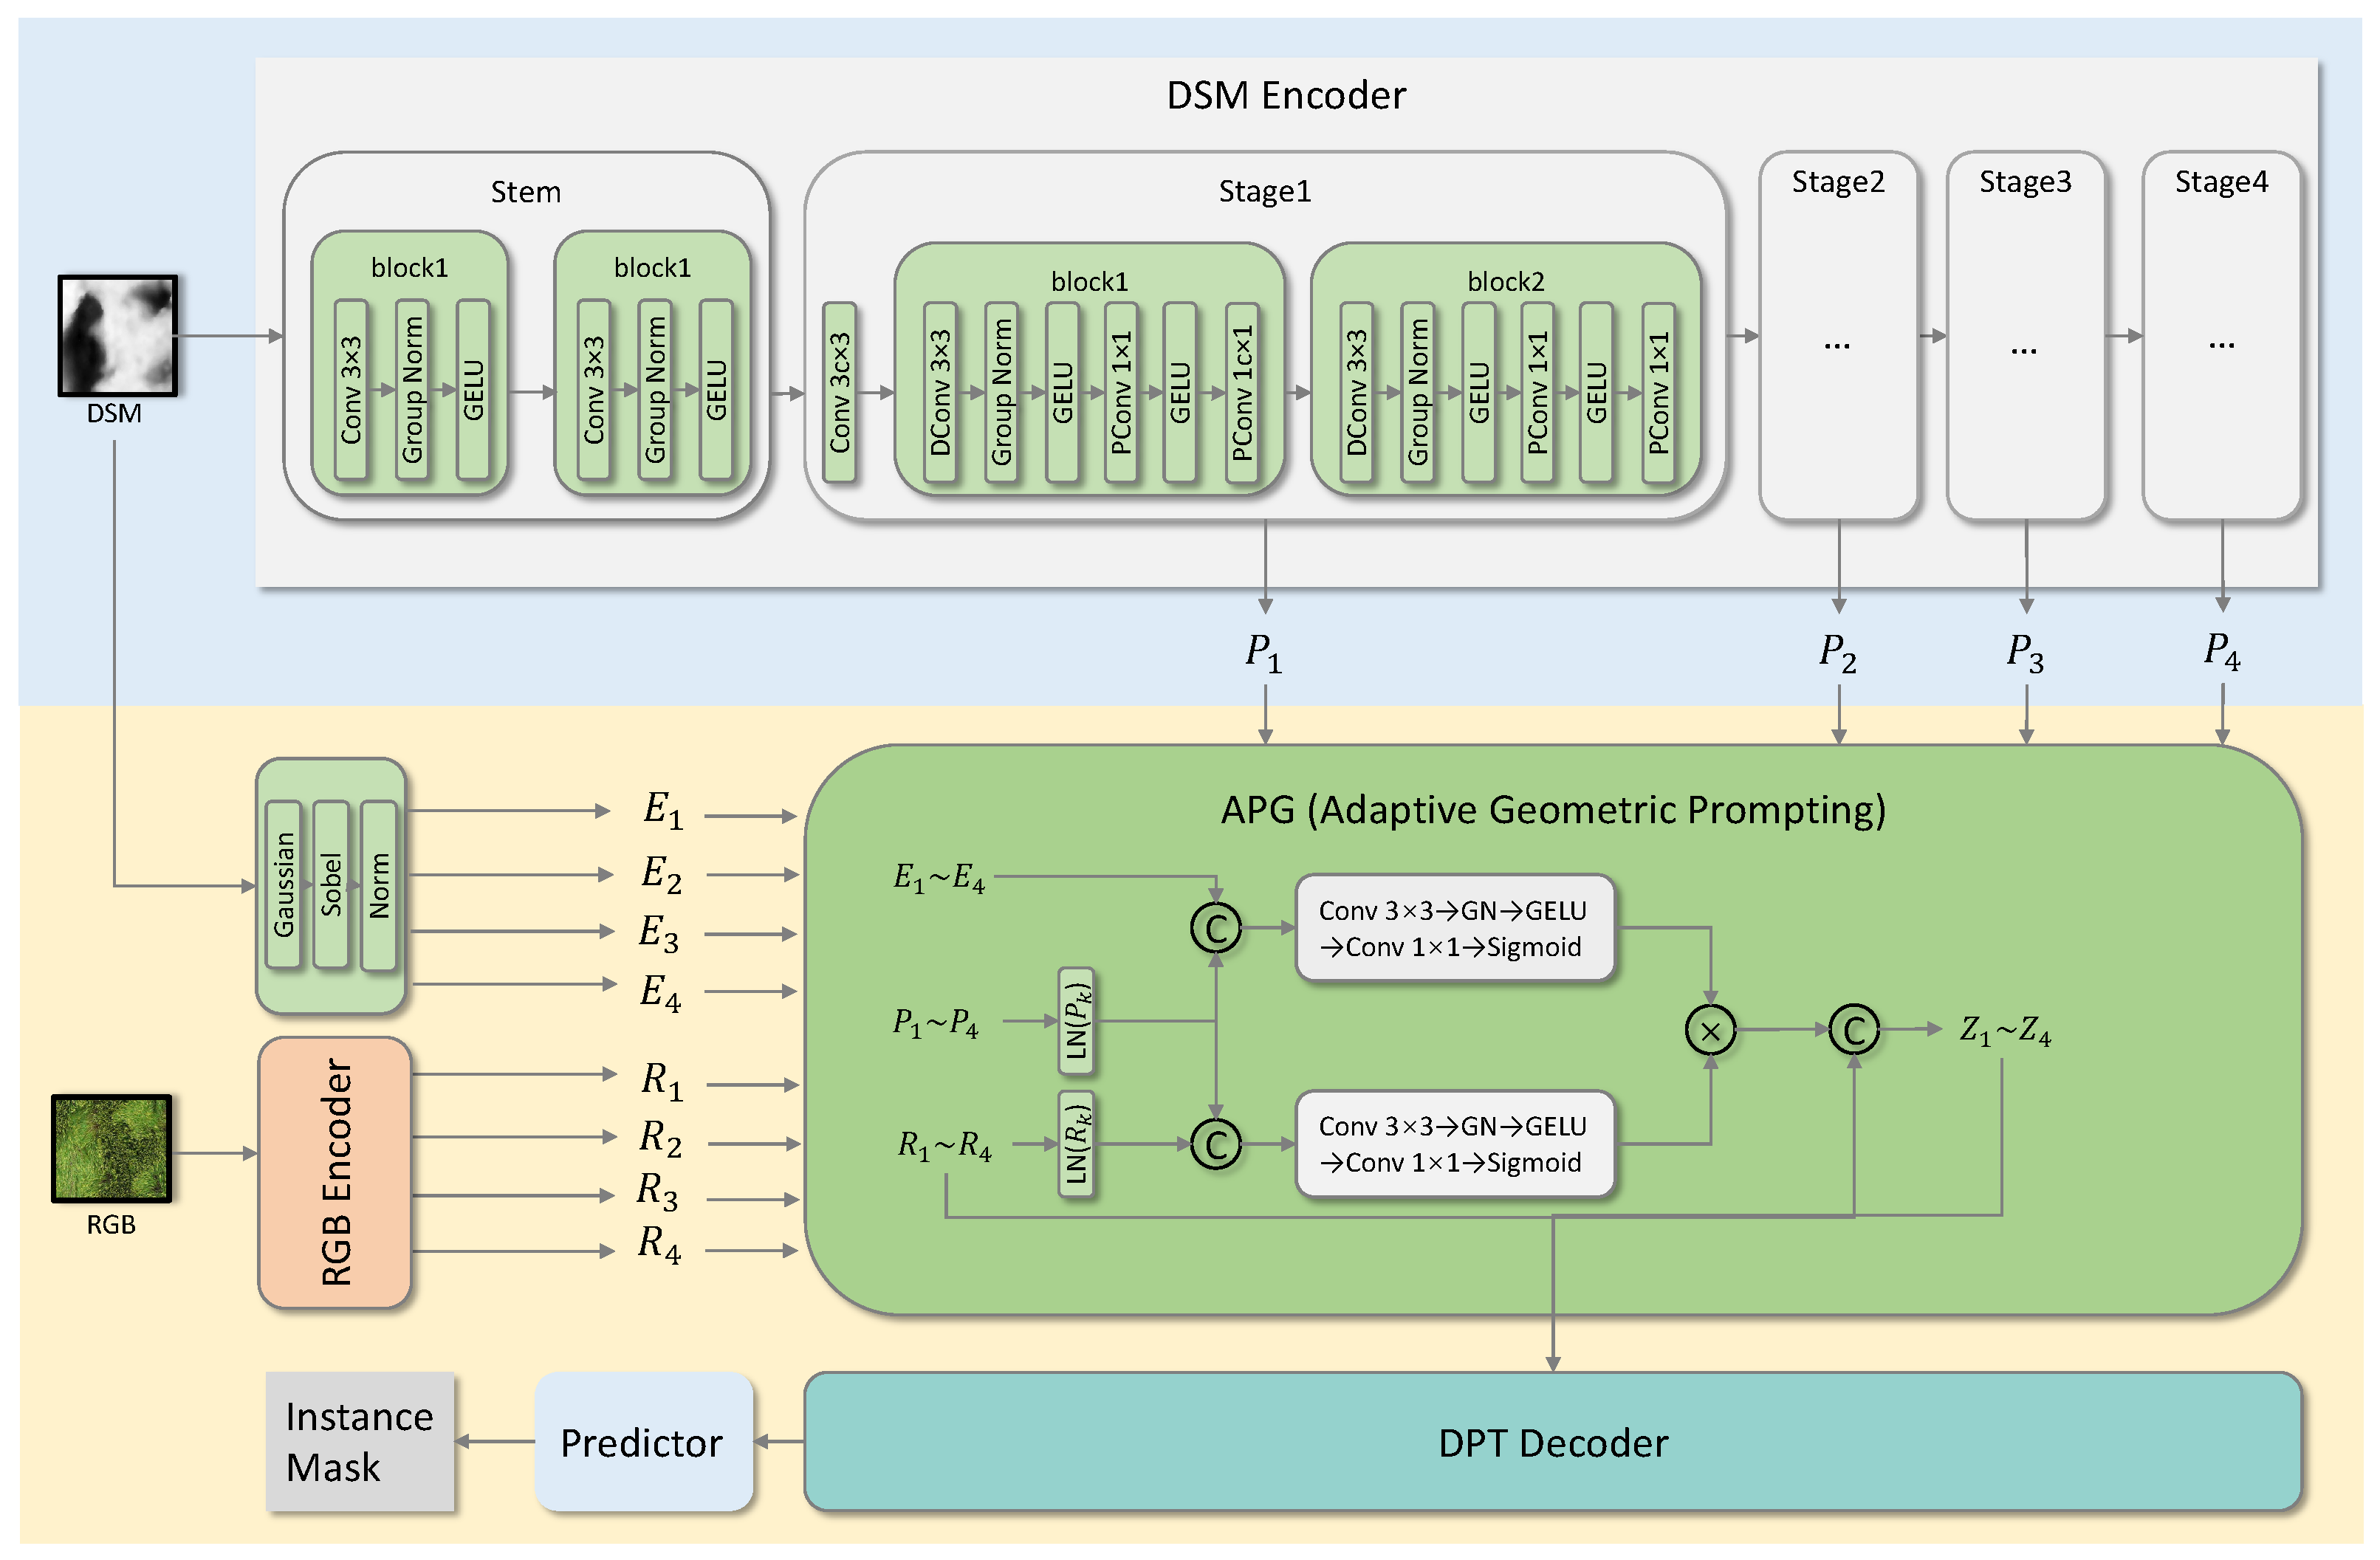
AGP transforms DSM from an auxiliary input into a structured geometric prior through a selective three-stage design: multiscale DSM prompt construction, edge-prior extraction, and reliability-aware prompt gating. This design mitigates the risk of uniformly injecting DSM features into the decoder when DSMs contain reconstruction noise, local voids, or mis-registration. Figure 4 provides the network-level view. For branch ★, the DSM branch produces the prompt pyramid { P k } k = 1 K , the geometric branch derives the edge prior E d , , and scale matching supplies Γ k ( E d , ) to the gate. AGP then combines these terms with the RGB decoder feature F ¯ k r , to compute the gated residual correction before DPT decoding.

3.2.1. DSM Encoder

RGB imagery and DSM provide complementary but fundamentally different evidence: RGB primarily contributes semantic appearance, whereas DSM captures local elevation changes and surface discontinuities. We therefore adopt an asymmetric dual-encoder design. Let g r and g d denote the RGB and DSM encoders, respectively. For branch ★, which denotes a labeled, weak, or strong view, multiscale features are extracted as
F k r , k = 1 K = g r x r , F k d , k = 1 K = g d x d , P k = ϕ k F k d , ,
where K = 4 in our implementation. The RGB encoder g r is instantiated by DINOv2 [31], and g d is a lightweight hierarchical convolutional encoder. The projection ϕ k ( · ) maps DSM features to the decoder channel dimension, so P k acts as a scale-aligned carrier of geometric evidence rather than as a second semantic stream.  

3.2.2. DSM Edge Prior Construction

AGP also extracts a class-agnostic DSM edge prior as the shared geometric reference for prompt gating, GPL, and BGR. Because raw DSM gradients may contain large local outliers from reconstruction artifacts, we define a robust normalization operator for any nonnegative response map X R 0 H × W :
Norm ( X ) = 1 exp X 1 | Ω | i Ω X i + ϵ n ,
where Ω is the pixel set and ϵ n > 0 prevents division by zero. Equation (4) scales responses by the image-wide average magnitude and saturates smoothly, making it less sensitive to isolated DSM artifacts or spurious prediction gradients than max-based normalization. The class-agnostic DSM edge-magnitude map is then
E ¯ d x d = K x ( G σ x d ) 2 + K y ( G σ x d ) 2 ,
where K x , K y are Sobel kernels, G σ is Gaussian smoothing, and ∗ denotes convolution. For the labeled and weak branches, Equation (4) gives E d , l and E d , w from E ¯ d , l = E ¯ d ( x d l ) and E ¯ d , w = E ¯ d ( x d w ) . For the strong branches, we transform the raw weak-view edge magnitude before normalization to avoid CutMix-induced artificial edges:
E ¯ d , s , v = T v E ¯ d , w , E d , s , v = Norm E ¯ d , s , v , v { 1 , 2 } .
When CutMix pastes a region from another unlabeled sample, the paired raw edge magnitude is pasted into the same region before normalization, ensuring that E d , s , v remains tied to scene geometry rather than augmentation artifacts.

3.2.3. Reliability-Aware Prompt Gating and Decoder Injection

Given the prompt features and edge prior, AGP estimates where DSM should influence decoding. Let F ¯ k r , be the RGB feature entering AGP; it equals the raw RGB feature on the labeled and weak branches and the complementary-dropout feature on the strong branches (Section 3.3.1). The spatial gate is
Q k = σ ψ k r LN ( P k ) ; Γ k ( E d , ) response term σ ψ k c LN ( F ¯ k r , ) ; LN ( P k ) compatibility term ,
where Γ k ( · ) is scale matching, LN ( · ) is feature normalization, and ψ k r , ψ k c are lightweight convolutional predictors. The first term measures intrinsic geometric reliability, and the second term measures RGB–DSM compatibility. Both terms are single-channel spatial maps broadcast along feature channels.
At scale k, the DPT decoder consumes the fused feature
Z k = F ¯ k r , + λ k Q k P k ,
where λ k is a learnable scale-specific coefficient. The residual formulation preserves RGB as the primary semantic carrier and allows DSM to contribute only through a gated correction. We denote the complete segmentation network as f θ ( x r , x d ; E d , ) .

3.3. Geometry-Guided Semi-Supervised Optimization

After AGP establishes the shared geometric prior, unlabeled training must use it without corrupting the physical meaning of DSM. GUMatch achieves this through a modality-preserving weak-to-strong protocol, geometry-calibrated pseudo-label supervision, and a conservative boundary refinement loss.

3.3.1. Modality-Preserving Weak-to-Strong Training Protocol

Weak-to-strong semi-supervised learning requires strong student perturbations, but RGB–DSM training must preserve DSM height meaning. For each unlabeled sample ( x r , x d ) D u , we first build a weak teacher view ( x r w , x d w ) = A w ( x r , x d ) , where A w comprises geometry-preserving resize, crop, and horizontal flip shared by RGB and DSM. Two student strong views are derived as
x r s , v = A a p p v T v ( x r w ) , x d s , v = T v ( x d w ) , v { 1 , 2 } ,
where A a p p v is RGB-only appearance perturbation and T v is the synchronized spatial transform, primarily CutMix in our implementation. This asymmetric protocol perturbs RGB appearance while keeping DSM photometrically unchanged; we refer to it as ASV in the ablation study.
We retain complementary dropout only on the RGB strong-view features. To avoid conflict with the pseudo-label valid mask M used in GPL, the channel-wise dropout masks are denoted by Δ 1 and Δ 2 , with Δ 1 , Δ 2 { 0 , 2 } C × 1 × 1 and Δ 1 + Δ 2 = 2 1 . The same mask pair is shared across all selected RGB backbone scales:
F ¯ k r , s , 1 = Δ 1 F k r , s , 1 , F ¯ k r , s , 2 = Δ 2 F k r , s , 2 ,
For the weak teacher and labeled branches, complementary dropout is disabled, so F ¯ k r , w = F k r , w and F ¯ k r , l = F k r , l . DSM prompt features P k are never masked.

3.3.2. Geometry-Calibrated Pseudo-Label Supervision

In lodging scenes, the teacher’s most harmful errors typically arise near ambiguous boundaries, where RGB appearance is weakly discriminative but supervision decisions carry high geometric consequence. GPL therefore does not alter the teacher’s semantic prediction itself; instead, it regulates how much each pseudo-label should be trusted, with geometry-guided down-weighting activated only within teacher-identified boundary-risk regions.
The student and teacher networks are parameterized by θ and θ , respectively, with θ updated as the EMA of θ with momentum η ( 0 , 1 ) . On the weak view ( x r w , x d w ) , the teacher produces logits z t w = f θ ( x r w , x d w ; E d , w ) and probabilities p w = softmax ( z t w ) . For each pixel i, the pseudo-label is y ^ i = arg max c p w i , c and the raw confidence is s i = max c p w i , c . The corresponding map-level symbols used in Algorithm 1 are Y ^ and S . To localize where calibration is needed, we derive the teacher boundary response
B w = Norm c = 1 C K x p w ( c ) 2 + K y p w ( c ) 2 ,
and activate calibration only within the teacher-derived boundary band
u i = I MaxPool r b ( B w ) i > τ b ,
where MaxPool r b ( · ) is max pooling with radius r b and τ b controls the band width. The semantic-geometric agreement is
a i = ( 1 u i ) + u i exp B i w E i d , w τ g ,
where τ g > 0 controls the tolerance to RGB–DSM boundary mismatch. As a i = 1 outside the boundary band, nonboundary pixels are not penalized. The calibrated confidence is
c ˜ i = s i 1 ( 1 α ) u i ( 1 a i ) ,
where α [ 0 , 1 ] controls the down-weighting strength. The factor in Equation (14) lies in [ α , 1 ] , so geometry can suppress but never inflate teacher confidence. The valid pseudo-label mask is m i = I ( c ˜ i τ c ) .
The map-level targets Y ^ , C ˜ , M , and U are generated in weak-view coordinates and transferred to each strong branch by the same T v used in Equation (9); E d , s , v follows Equation (6). Discrete targets use nearest-neighbor transformation, whereas continuous confidence and edge maps use bilinear interpolation before CutMix pasting. Algorithm 1 summarizes this calibration-and-transfer procedure with symbols matched to Equations (11)–(14).
Given the transformed teacher targets, the student produces strong-view logits z s , v = f θ x r s , v , x d s , v ; E d , s , v and probabilities p s , v = softmax z s , v for v { 1 , 2 } . The resulting per-view unsupervised loss is a confidence-weighted cross-entropy:
L u v = i M i v C ˜ i v CE z i s , v , Y ^ i v i M i v C ˜ i v + ϵ , v { 1 , 2 } ,
where CE ( · , · ) is pixel-wise cross-entropy and ϵ prevents division by zero. The final unlabeled objective averages the two strong views, L u = 1 2 ( L u 1 + L u 2 ) . Equation (15) maintains the weak-to-strong consistency principle of UniMatch V2 while employing modality-preserving strong views and geometry-calibrated pseudo-label weights. RGB is optimized for appearance robustness, whereas DSM remains a stable geometric condition across the two strong branches.  
Algorithm 1 GPL target generation and transfer with formula-matched notation
Input: 
weak view ( x r w , x d w ) , weak-view DSM prior E d , w
Input: 
EMA teacher f θ , strong-view operators { T v } v = 1 2
Output: 
transformed targets { Y ^ v , C ˜ v , M v , U v } v = 1 2
  1:
z t w f θ x r w , x d w ; E d , w and p w softmax z t w
  2:
Y ^ arg max c p w and S max c p w                                   ▹ map forms of y ^ i and s i
  3:
Compute teacher boundary response B w by Equation (11)
  4:
Compute boundary-band indicator U by Equation (12)
  5:
Compute geometry agreement A by Equation (13)
  6:
Compute calibrated confidence C ˜ from S , U , and A by Equation (14)
  7:
M I C ˜ τ c
  8:
for  v { 1 , 2 }   do
  9:
        Y ^ v T v Y ^ and C ˜ v T v C ˜
10:
       M v T v M and U v T v U
11:
return  { Y ^ v , C ˜ v , M v , U v } v = 1 2

3.3.3. Boundary-Aware Geometric Regularization

GPL improves pseudo-label reliability, but the supervision remains primarily category-level and does not directly constrain boundary shape. We therefore add BGR as a conservative refinement loss atop GPL-filtered supervision. It avoids global alignment to all DSM edges, as field ridges, tractor ruts, and drainage channels can create strong height discontinuities unrelated to lodging boundaries.
For each strong view, the student boundary response is extracted from the soft prediction analogously to Equation (11):
B ^ s , v = Norm c = 1 C K x p s , v , ( c ) 2 + K y p s , v , ( c ) 2 , v { 1 , 2 } ,
Using the transformed DSM prior E d , s , v from Equation (6), BGR activates boundary supervision only at the intersection of valid pseudo-labels, boundary candidates, and nontrivial DSM edges:
M b v = M v valid pseudo label U v boundary candidate I E d , s , v > τ d nontrivial DSM edge , v { 1 , 2 } ,
where τ d is the DSM-edge threshold. The per-view boundary regularization loss is
L e d g e v = i M b , i v C ˜ i v B ^ i s , v E i d , s , v i M b , i v C ˜ i v + ϵ , v { 1 , 2 } ,
and the overall boundary regularizer averages the two strong views:
L e d g e = 1 2 L e d g e 1 + L e d g e 2 .
Thus, Equation (18) refines GPL-filtered supervision only where pseudo-labels and DSM evidence are jointly reliable.
Here, B ^ s , v is a semantic-boundary response, whereas E d , s , v is a DSM height-discontinuity response. We use L1 amplitude matching because Equation (4) puts the two responses into a comparable dynamic range under the mask in Equation (17). Alternatives such as Dice on binarized maps or active-contour-style losses [32] were less stable in our experiments, as they may lose useful gradients on weak boundaries or fit noisy DSM ridges too aggressively. reports the empirical comparison.

3.4. Supervised Loss and Overall Objective

For labeled samples, the student predicts logits z l = f θ x r l , x d l ; E d , l , and the supervised loss is the standard pixel-wise cross-entropy:
L s u p = 1 | Ω | i Ω CE z i l , y i ,
over the labeled pixel set Ω . The overall training objective combines the supervised loss with the two unsupervised components:
L = L s u p + λ u L u + λ e L e d g e ,
where λ u and λ e balance the two unsupervised terms. The teacher parameters are updated as the EMA of the student with momentum η . Algorithm 2 summarizes the full training routine and references the equations used in each step.  
Algorithm 2 Overall training procedure of GUMatch
Input: 
labeled set D l , unlabeled set D u
Input: 
student f θ , EMA teacher f θ , weak augmentation A w
Input: 
strong-view operators { A a p p v , T v } v = 1 2 , λ u , λ e , η
Output: 
trained student θ and teacher θ
  1:
Initialize θ θ
  2:
for each training iteration do
  3:
     Sample ( x r l , x d l , Y l ) D l and ( x r , x d ) D u
  4:
      ( x r w , x d w ) A w ( x r , x d )
  5:
     Compute E ¯ d , l , E ¯ d , w by Equation (5) and E d , l , E d , w by Equation (4)
  6:
     for  v { 1 , 2 }  do
  7:
          Generate ( x r s , v , x d s , v ) by Equation (9)
  8:
          Generate E d , s , v by Equation (6)
  9:
      ( Y ^ 1 , C ˜ 1 , M 1 , U 1 , Y ^ 2 , C ˜ 2 , M 2 , U 2 ) GPL TARGETS ( x r w , x d w , E d , w , f θ , { T v } v = 1 2 )
10:
     for  v { 1 , 2 }  do
11:
           z s , v f θ x r s , v , x d s , v ; E d , s , v
12:
          Compute L u v by Equation (15) and L e d g e v by Equation (18)
13:
      z l f θ x r l , x d l ; E d , l and compute L s u p
14:
      L u ( L u 1 + L u 2 ) / 2 and L e d g e ( L e d g e 1 + L e d g e 2 ) / 2
15:
     Compute L by Equation (21)
16:
     Update θ by back-propagating L
17:
     Update θ η θ + ( 1 η ) θ
18:
return  θ , θ

4. Experimental Results and Analysis

4.1. Experimental Setting

All experiments were run on Ubuntu 20.04 using Python 3.11.9, PyTorch 2.5.0, and CUDA 12.4 under Miniconda. The workstation contained an Intel Xeon 8360Y CPU (2.40 GHz) and one NVIDIA RTX 3090 GPU (24 GB).
Following the parcel-level protocol in Section 2, the main HA-P2/HA-P1 benchmark contained 1400 RGB–DSM tiles: 900 training tiles from HA-P2, 200 validation tiles from HA-P2, and 300 in-region test tiles from HA-P1. The external WX-P3 set contained 300 fully annotated tiles and was used only for direct cross-region testing. All models were trained and selected only on HA-P2; HA-P1 and WX-P3 were used only as final test parcels.
The labeled ratios were applied only to the HA-P2 training set: 10%, 20%, and 40% correspond to 90, 180, and 360 labeled tiles, respectively, with the remaining training tiles used as unlabeled data. Inputs were cropped to 512 × 512 , and all models were trained for 200 epochs. Each iteration drew one labeled mini-batch and one unlabeled mini-batch, each with batch size 2. Validation and testing used batch size 1. Weak augmentation applied synchronized random resize, random crop, and horizontal flip to RGB and DSM. Strong student views further applied RGB-only color jitter, grayscale conversion, Gaussian blur, and CutMix (probability 0.5), while DSM retained only the same geometric transforms to preserve height structure.
We used AdamW ( β 1 = 0.9 , β 2 = 0.999 , weight decay 0.01). For DINOv2-B, the pretrained RGB backbone used an initial learning rate of 5 × 10 6 ; the decoder, DSM encoder, AGP module, and other newly initialized layers used a 40 × multiplier. We adopted a polynomial decay schedule, l r t = l r 0 ( 1 t / T ) 0.9 , with t and T the current and total iterations. DINOv2-B was initialized from the official checkpoint, and RN-101 from ImageNet weights; the DSM encoder, AGP module, and task-specific decoder layers were randomly initialized. The pseudo-label confidence threshold was τ c = 0.85 . The unsupervised consistency and boundary regularization weights were λ u = 1.0 and λ e = 0.5 . The EMA teacher momentum was updated as η t = min ( 1 1 / ( t + 1 ) , 0.996 ) . For GPL and BGR, we set r b = 3 , τ b = 0.2 , τ g = 0.25 , α = 0.40 , and τ d = 0.2 . Each setting was repeated with seeds 0, 1, and 2, and we report the mean. For the seed-matched method comparisons in Table 2, we used a paired nonparametric sign test.

4.2. Evaluation Metrics

We adopt mean intersection over union (mIoU) as the primary metric and report class-wise IoU for per-category analysis. All metrics are computed on the corresponding fixed test parcel over three classes: lodged rice, healthy rice, and background. As lodging boundaries are often gradual and spatially ambiguous, we further report the boundary F1-score (BF1) in the ablation and robustness analyses. We extract class-agnostic boundaries from the predicted and ground-truth maps and count a boundary pixel as matched if it lies within a small tolerance band of the other boundary. All metrics are reported as percentages.

4.3. Comparison with State of the Art

Table 2 is organized into three comparison groups. Panel A reports the RN-101 benchmark, including single-modal semi-supervised baselines, supervised RGB–DSM references trained on the same labeled subsets, simple RGB–DSM UniMatch V2 variants, and GUMatch with RN-101. Panel B reports the multimodal semi-supervised baselines M3L and DepMatch with their corresponding encoders. Panel C focuses on the DINOv2-B variants of UniMatch V2 and GUMatch, isolating the effect of geometry-guided learning from the backbone upgrade. The 100% fully supervised RGB and RGB–DSM references are reported separately in Table 3.
Under the RN-101 setting, GUMatch consistently outperforms the best single-modal baseline (RSProtoSemiSeg) and the strongest simple RGB–DSM UniMatch V2 variant across all three labeled ratios. These results indicate that the gain does not come from adding DSM as a fixed auxiliary input alone. M3L and DepMatch provide a more stringent multimodal semi-supervised comparison. Against these directly related baselines, GUMatch with DINOv2-B achieves the highest mIoU under all three labeled ratios. Panel C further confirms that the improvement is not simply a backbone effect: with the same DINOv2-B backbone, GUMatch consistently outperforms UniMatch V2 and its decoder-add RGB–DSM extension.
Table 3 provides a direct annotation-efficiency comparison. With all 900 labeled tiles, the RGB–DSM full-supervision version of GUMatch outperforms the RGB-only UniMatch V2 reference by 1.72 mIoU points, with larger gains in lodged rice and background IoU than in healthy rice IoU. The semi-supervised rows show that as the labeled ratio increases from 10% to 40%, GUMatch improves from 82.64% to 86.72% mIoU. Notably, the 40% semi-supervised model surpasses the pure RGB 100% full-supervision reference in mIoU, lodged rice IoU, precision, and F1, though it remains below the RGB–DSM 100% full-supervision model.
To provide a more complete view of segmentation quality beyond mIoU, Table 4 summarizes the class-wise IoU and mean precision/recall/F1 results across all three labeled ratios.
The detailed metrics in Table 4 reveal complementary behavior among the multimodal semi-supervised baselines. M3L obtains competitive lodged-rice IoU at 10% labels and the highest background IoU at 40% labels, but its healthy-rice IoU is consistently lower than that of GUMatch with DINOv2-B. DepMatch gives the highest recall in all three settings, but its lodged-rice IoU, background IoU, and F1-score are generally lower than those of GUMatch. GUMatch with DINOv2-B achieves the highest F1-score, lodged-rice IoU, healthy-rice IoU, and precision across all three settings.
The comparison with UniMatch V2 using DINOv2-B further pinpoints where the gains occur. GUMatch improves lodged-rice IoU by 2.23–2.53 points, healthy-rice IoU by 1.27–1.46 points, background IoU by 3.15–3.25 points, and F1-score by 1.36–1.57 points across the three labeled ratios. The largest class-wise gain is observed for background IoU, which is consistent with the qualitative examples where geometry-guided calibration reduces appearance-driven background confusion.
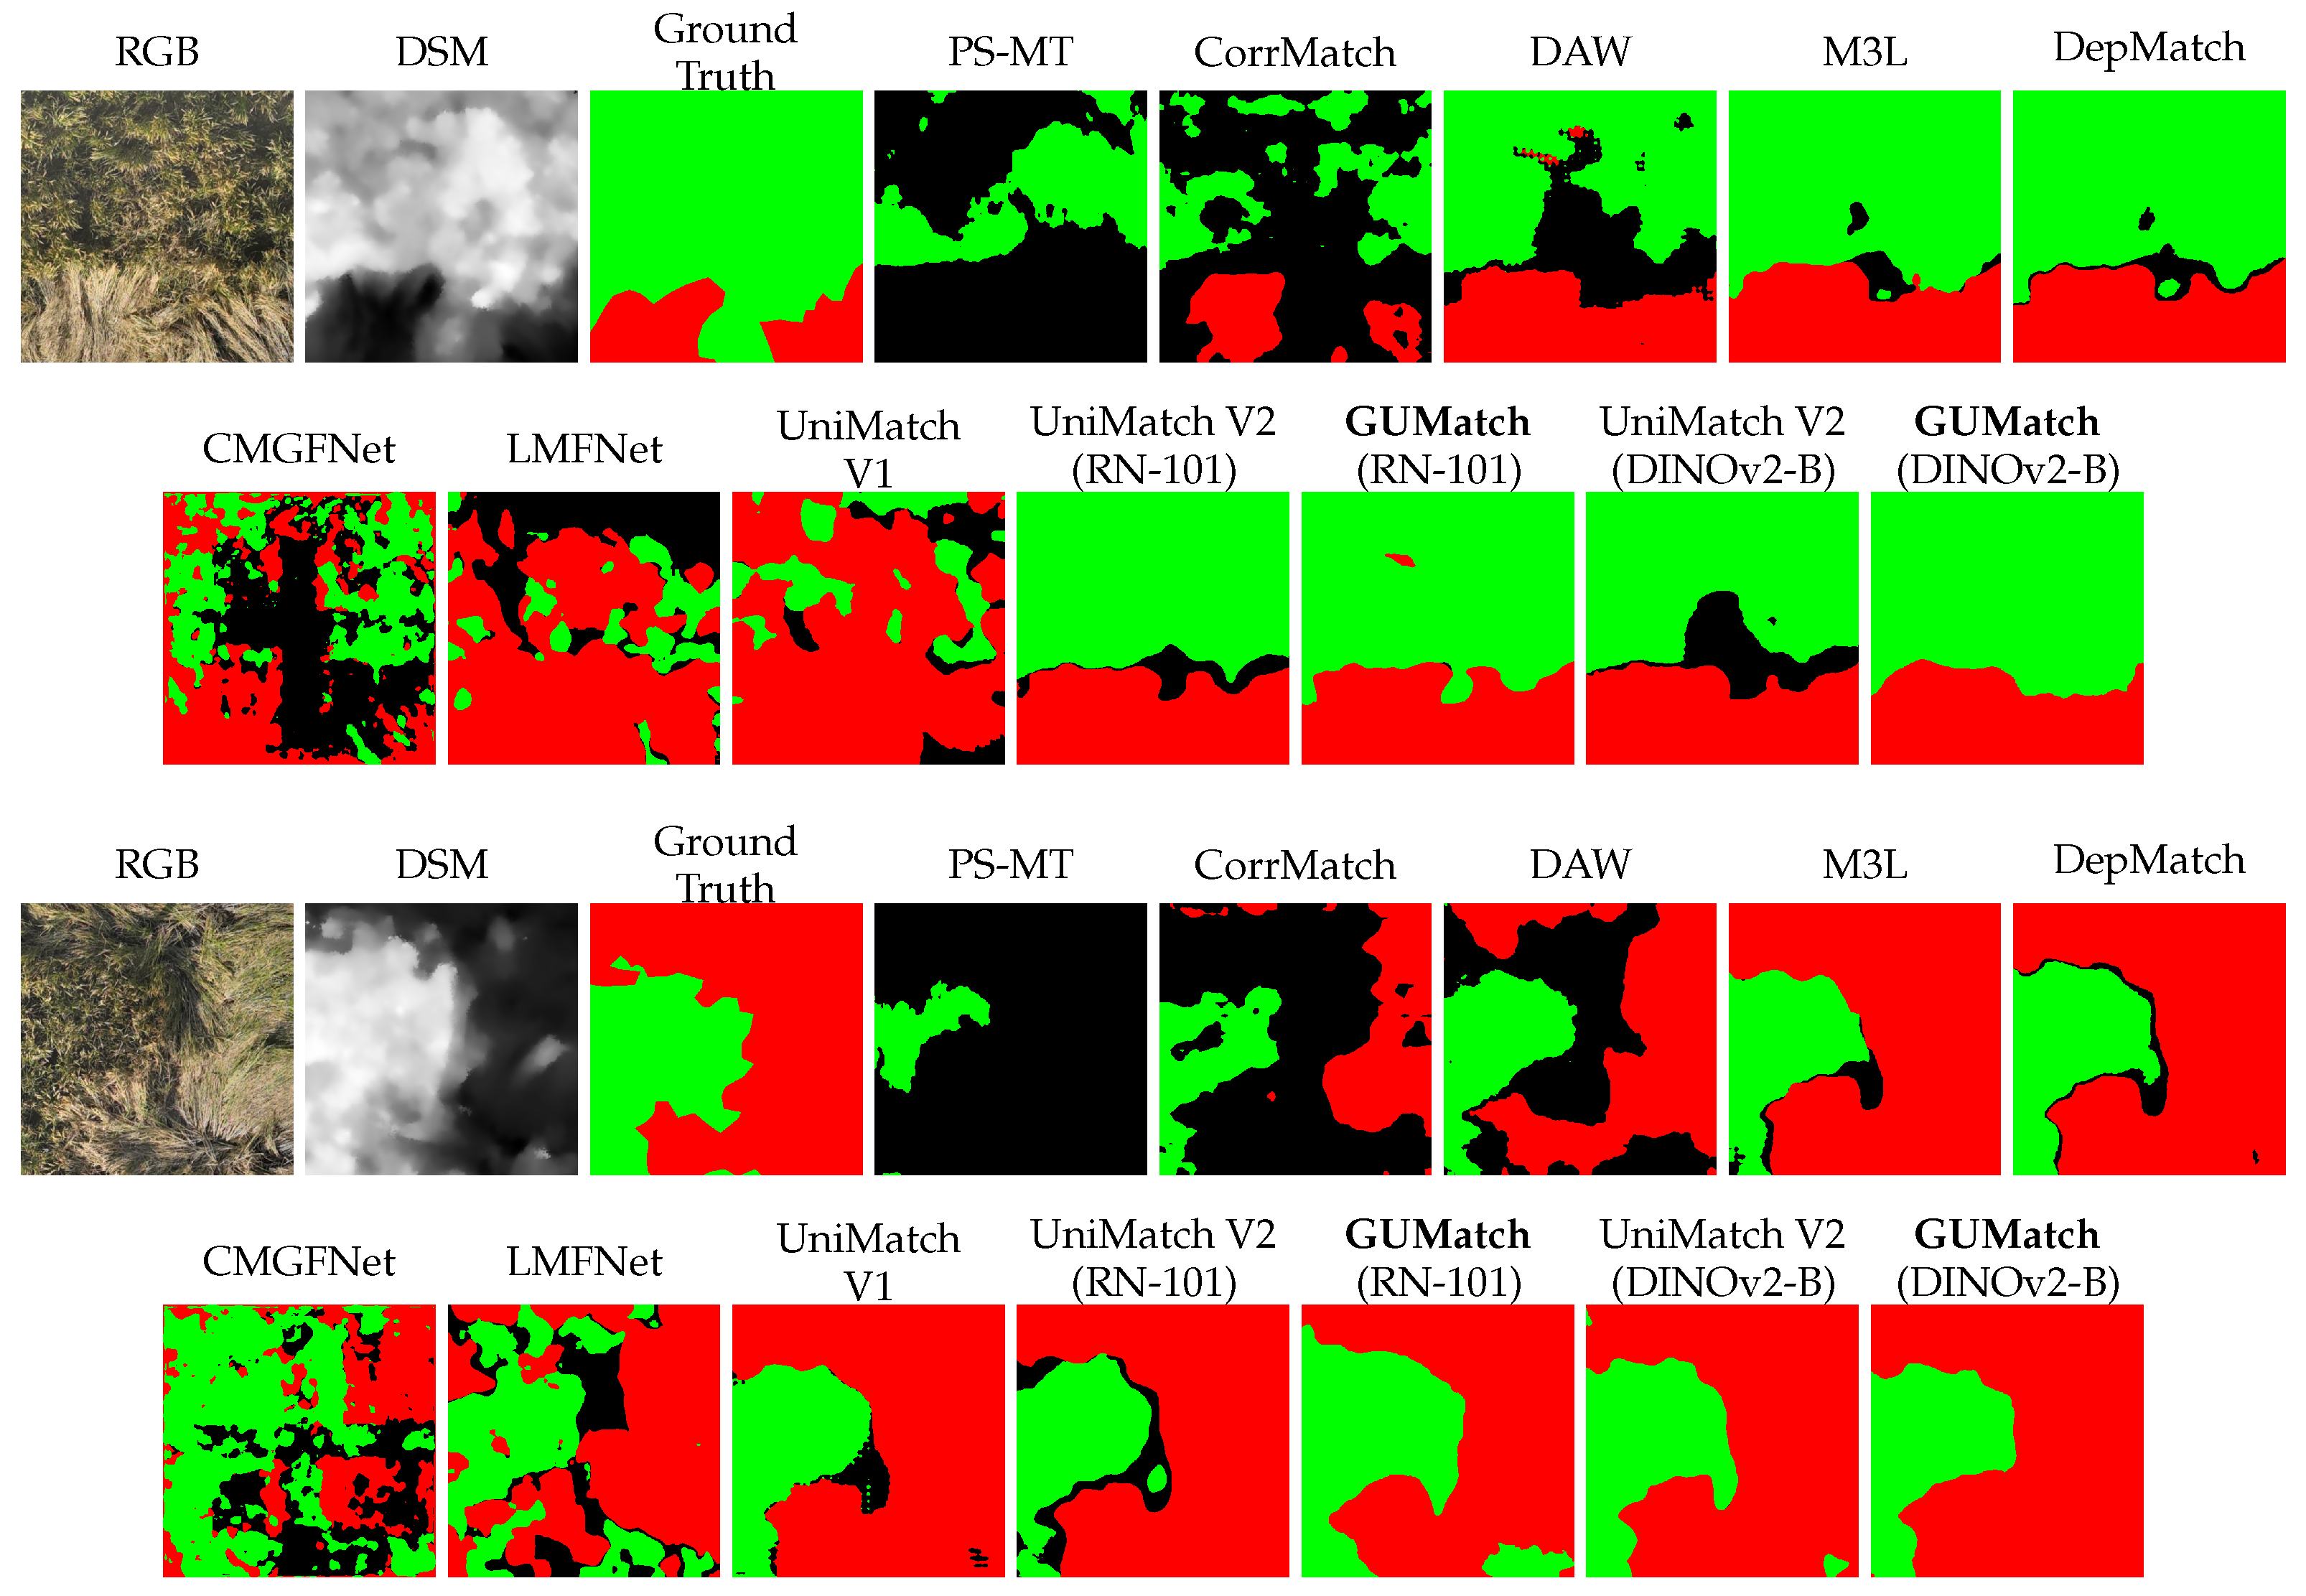
Figure 5 provides local zoom-in comparisons on two representative difficult regions containing mixed crop–background boundaries, fragmented lodged-rice areas, and confusing background patterns. M3L and DepMatch reduce some errors compared with weaker baselines, but still show local fragmentation or boundary discontinuities. GUMatch recovers more complete lodged-rice areas, suppresses background false positives, and preserves clearer local boundaries. The DINOv2-B version is visually closest to the ground truth in both examples.

4.4. Source-Parcel Generalization from HA-P2 to WX-P3

To evaluate cross-region transfer, we conducted an external source-parcel generalization experiment on WX-P3. All models were trained and selected under the 40% labeled setting using only HA-P2. The WX-P3 parcel was then used only for direct testing, with no tile used for parameter updates, model selection, or hyperparameter tuning. Table 5 reports the results.
A clear cross-region domain gap exists. With DINOv2-B, GUMatch drops from 86.72% mIoU on HA-P1 to 68.34% mIoU on WX-P3, confirming that the Wuxi scene is substantially more challenging. Nevertheless, GUMatch remains the strongest method on WX-P3, improving over UniMatch V2 with the same backbone by 5.39 mIoU points. The class-wise results indicate that geometry-guided prompting and pseudo-label calibration help suppress background-driven errors under distribution shift, though lodged-rice IoU is not the highest among all methods.
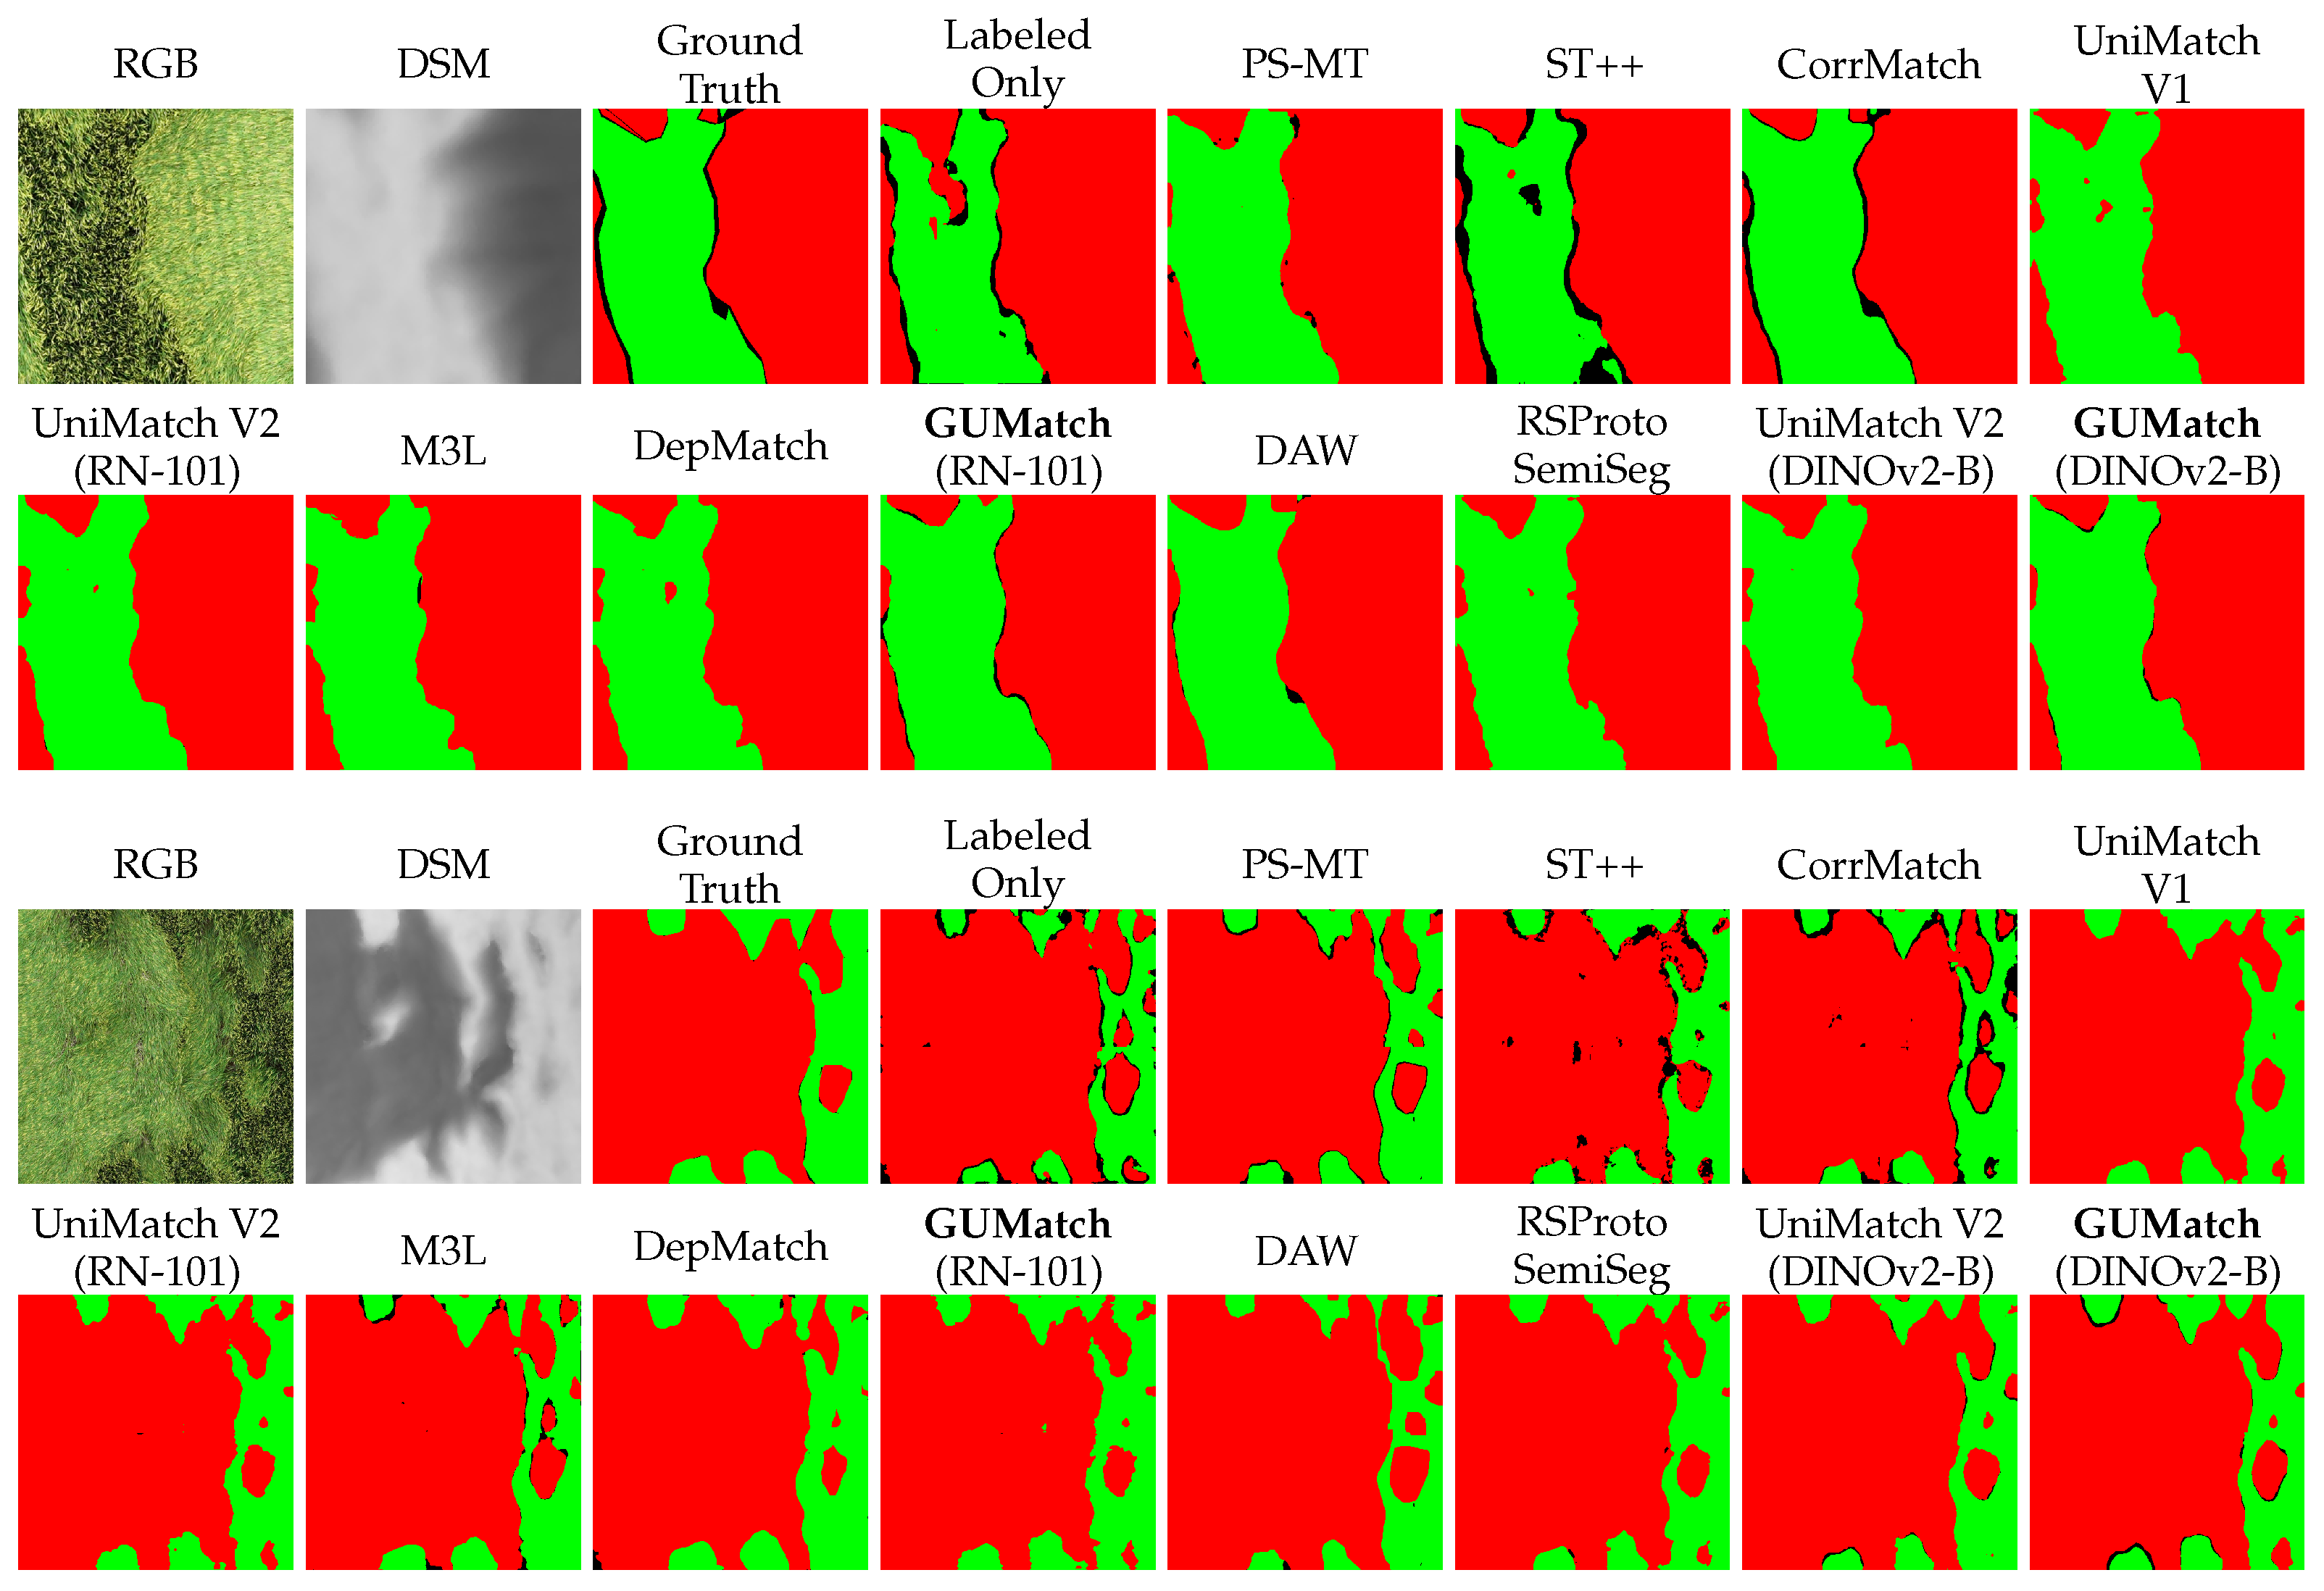
Figure 6 provides a visual companion: several baselines produce fragmented masks or large background-confusion regions, while GUMatch gives more spatially coherent predictions.

4.5. Ablation Studies

Unless otherwise stated, all ablation experiments use the 20% labeled split with DINOv2-B. We focus on the three main components of GUMatch: AGP for geometry-guided feature prompting, GPL for pseudo-label calibration, and BGR for boundary refinement. We also evaluate the edge-prior extraction and response-normalization functions.

4.5.1. Contribution of the Core Design Elements

Table 6 shows the progression from a simple RGB–DSM extension to the full geometry-guided design. Fixed decoder summation of DSM features gives only a modest improvement, suggesting that simple multimodal stacking is insufficient. AGP improves the result through reliability gating, GPL further enhances pseudo-label reliability, and BGR gives the best BF1 and mIoU.

4.5.2. Fusion Strategy and Injection Position

We introduce DSM as an adaptive geometric prompt after RGB complementary dropout and before DPT decoding. Table 7 supports this choice. Early concatenation and backbone fusion are weaker than decoder-side integration. Injecting DSM after RGB complementary dropout outperforms injection before dropout.

4.5.3. Teacher–Student Modality Configuration

Table 8 shows the best performance when both teacher and student receive RGB–DSM inputs. This symmetric setting allows geometry to contribute to both pseudo-label generation and student learning.

4.5.4. Pseudo-Label Quality Analysis

We evaluate pseudo-label quality on the unlabeled training set using hidden annotations only for post hoc evaluation. Table 9 shows that geometry-calibrated confidence retains slightly fewer pixels than raw semantic confidence from the same teacher, but improves precision, recall, and BF1.

4.5.5. Edge-Prior Extraction and Normalization

The DSM edge prior is shared by AGP, GPL, and BGR. We conduct two controlled ablations: fixing normalization and varying edge extraction, and fixing edge extraction and varying normalization.
Table 10 shows that Gaussian-smoothed Sobel gives the best overall result. Removing smoothing weakens both mIoU and BF1. Scharr yields close results but offers no clear advantage. LoG and Canny perform worse, especially in BF1. The normalization results support the proposed mean-exponential form, which preserves relative edge strength while smoothly saturating large outliers.
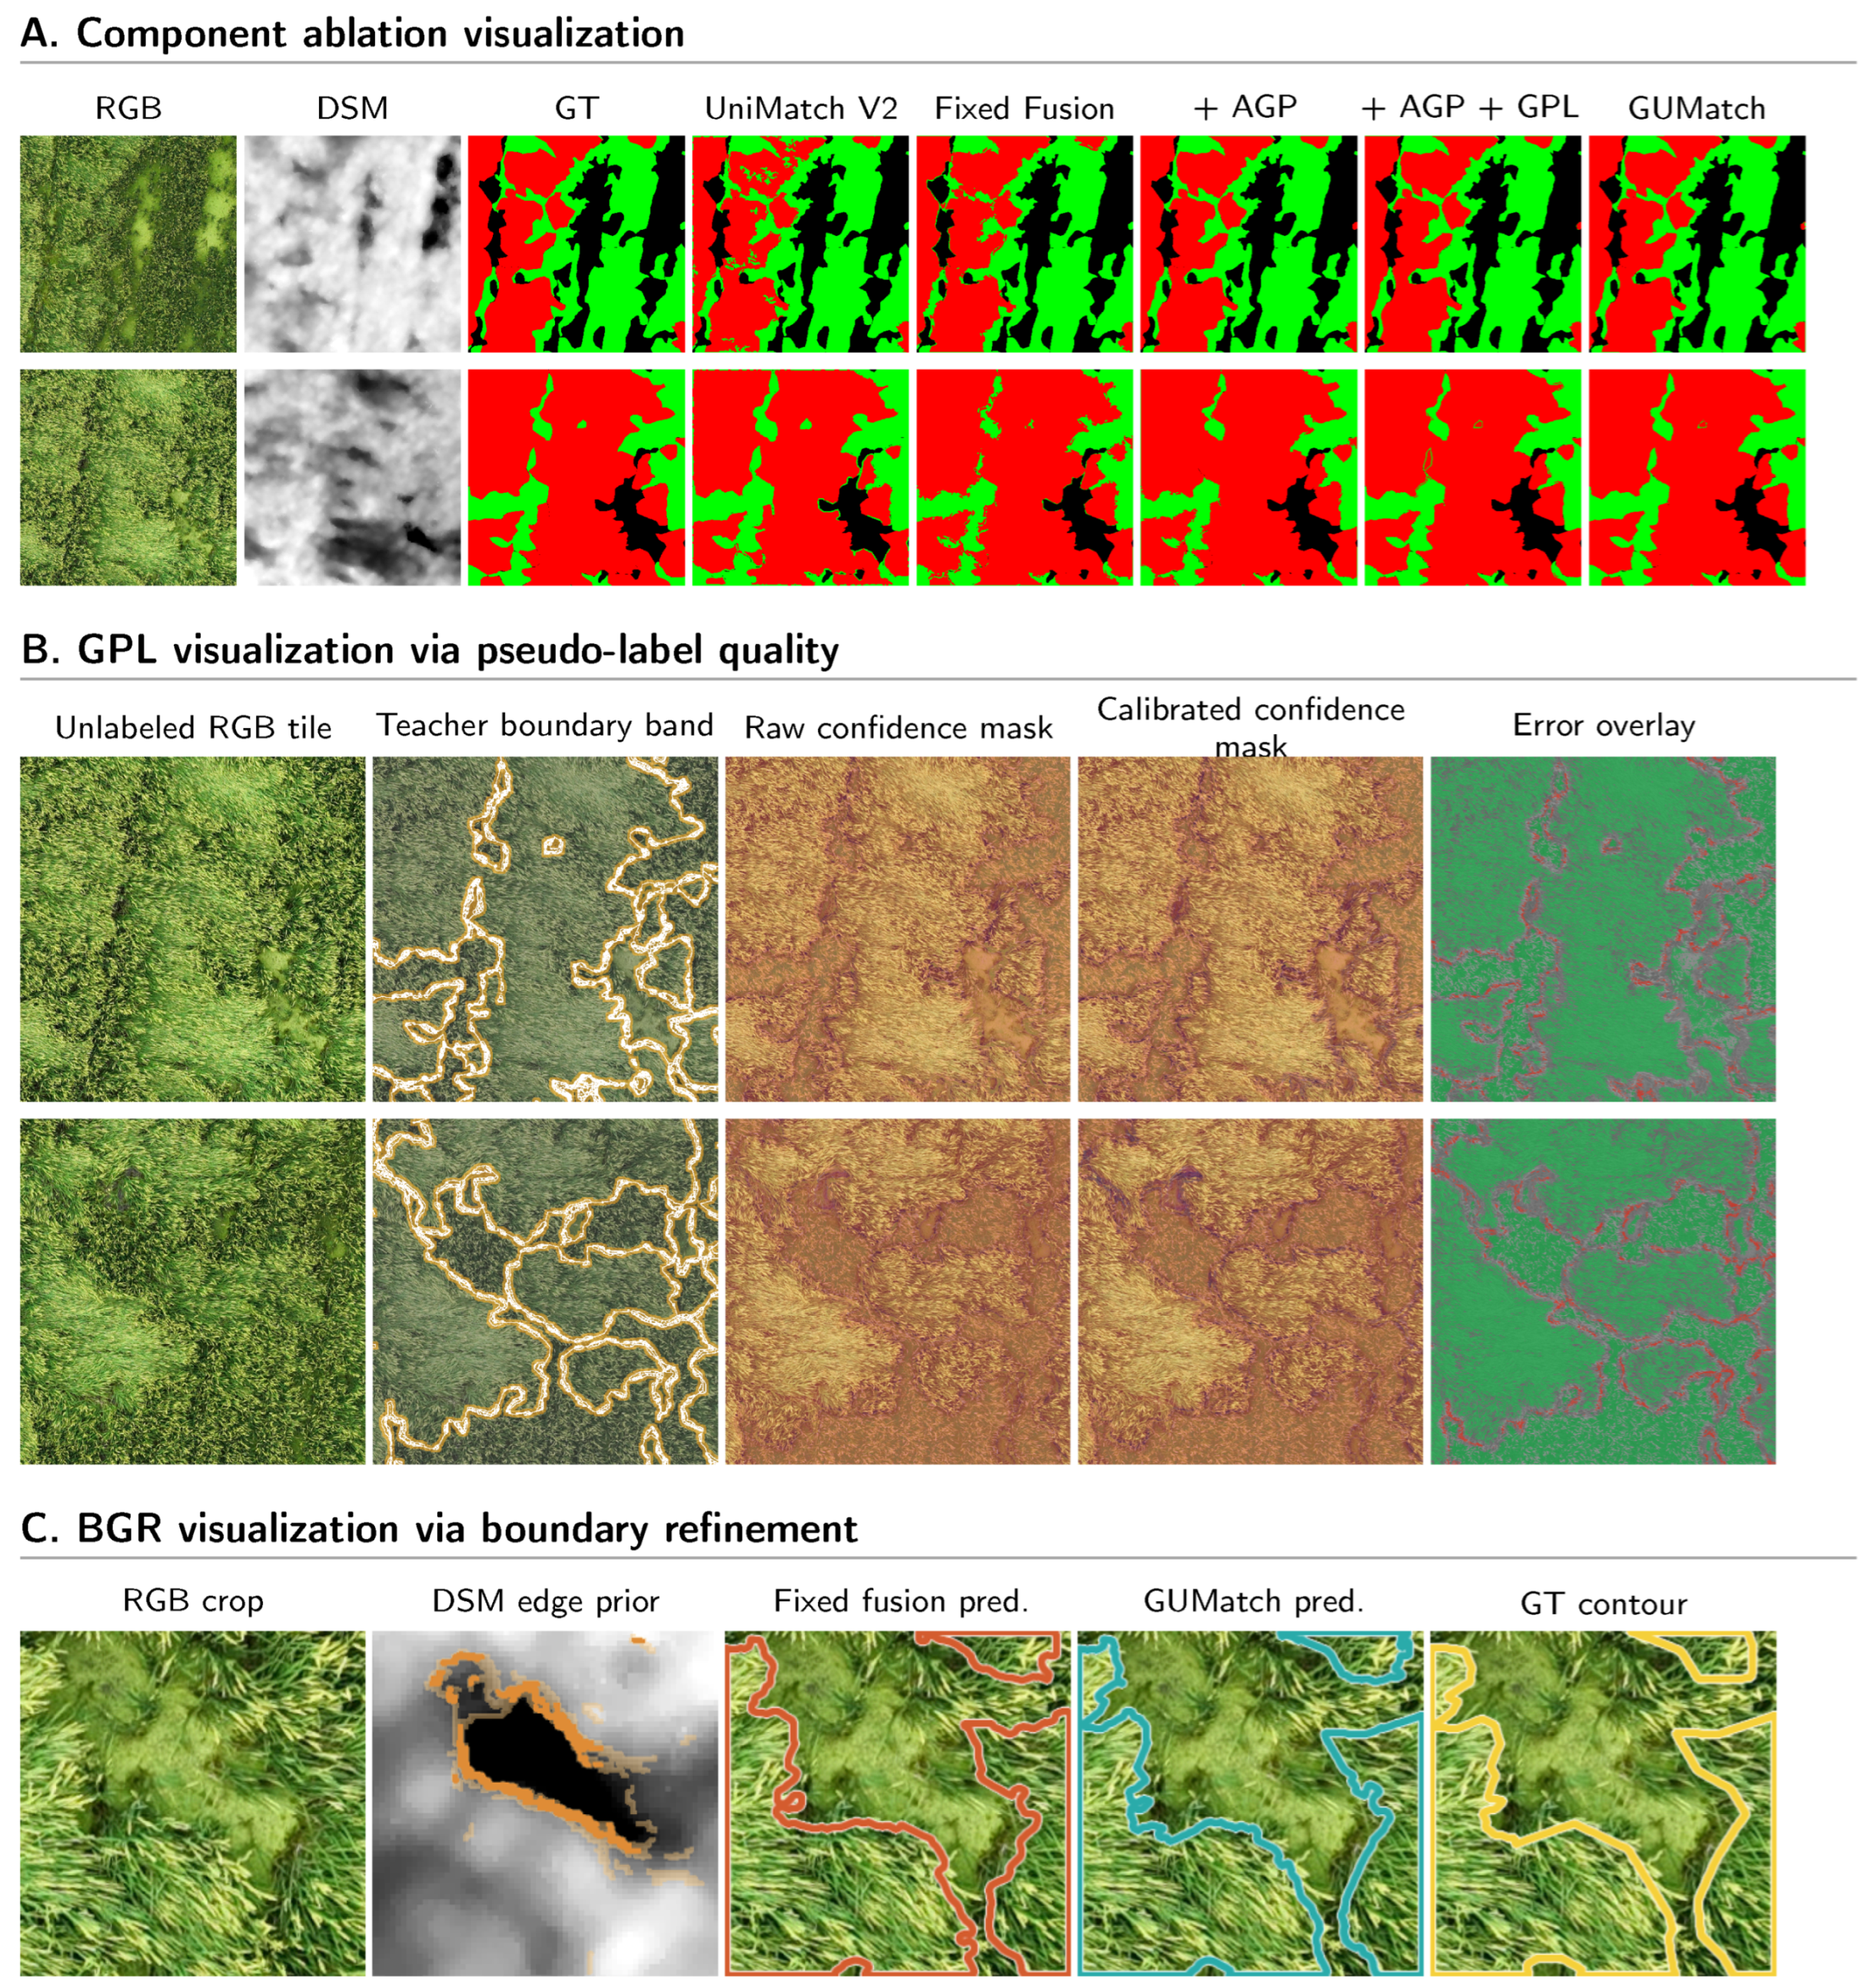
Figure 7 provides mechanism-oriented qualitative analysis. Panel A shows progressive improvement from UniMatch V2 to the full model. Panel B visualizes GPL’s effect on pseudo-label quality. Panel C demonstrates BGR’s boundary refinement.

4.6. Robustness, Sensitivity, and Efficiency Analysis

Remote-sensing DSMs may contain spatially correlated reconstruction failures. We therefore focus on structured DSM degradation that better reflects photogrammetric failure patterns, with simpler controlled perturbations reported in Appendix B. Unless otherwise stated, this analysis uses the 20% labeled split with DINOv2-B and compares GUMatch with DepMatch.

4.6.1. Structured DSM Degradation Protocol

We evaluate three structured degradation modes: (1) spatially correlated height distortion, (2) regional topological collapse, and (3) interpolated voids and smoothed holes. Their physical interpretations and severity-specific parameter settings are summarized in Table 11. Degradation is applied to unlabeled DSMs during semi-supervised training; labeled samples, validation, and test sets remain clean.
Table 12 shows that GUMatch maintains higher absolute mIoU and BF1 than DepMatch under all settings, with smaller Δ mIoU values. Regional topological collapse remains the most challenging degradation.

4.6.2. Hyperparameter Sensitivity

We sweep the four most influential parameters around their defaults. Table 13 shows that mIoU varies by less than 0.7 points across the swept ranges, and GUMatch’s superiority over the strongest non-GUMatch baseline is preserved.
We additionally evaluated three boundary objectives within BGR. Table 14 shows that the L1 formulation yields the best BF1.

4.6.3. Computational Cost

Table 15 shows that DINOv2-B GUMatch adds only moderate parameters and FLOPs compared with UniMatch V2, with the extra cost mainly from the lightweight DSM encoder and adaptive prompting layers.


5. Conclusions

This study proposes GUMatch, a geometry-guided semi-supervised framework that leverages UAV RGB–DSM data for rice-lodging segmentation with limited annotations. By selectively using DSM-derived height and boundary cues, GUMatch suppresses unreliable geometric evidence while preserving RGB appearance as the primary semantic source. Experiments on the HA-P2HA-P1 benchmark demonstrate consistent mIoU improvements across 10% to 40% labeled ratios with both RN-101 and DINOv2-B backbones, reaching up to 86.72% mIoU. External testing on WX-P3 confirms a substantial domain gap but also shows that GUMatch maintains stronger cross-region performance than the corresponding UniMatch V2 baseline. Together, these results demonstrate that reliability-aware geometric guidance enhances annotation-efficient lodging mapping when RGB appearance is ambiguous. Future work will extend validation across broader agricultural conditions and sensing settings, while exploring lightweight deployment, improved robustness to degraded or missing modalities, and applications to other structure-sensitive remote-sensing tasks.

Author Contributions

Conceptualization, X.F. and Z.S.; methodology, Z.W. and X.F.; software, Z.W. and X.Z.; validation, Z.W., Z.S. and X.F.; formal analysis, Z.W. and X.Z.; investigation, Z.W.; data curation, Z.W.; writing—original draft preparation, Z.W.; writing—review and editing, Z.W., Z.S. and X.F.; visualization, Z.W. and Z.S.; supervision, X.F.; data curation, S.D. All authors have read and agreed to the published version of the manuscript.

Funding

This research received no external funding.

Institutional Review Board Statement

Not applicable.

Informed Consent Statement

Not applicable.

Data Availability Statement

The UAV rice-lodging data used in this study, including HA-P1, HA-P2, and WX-P3, are available from the corresponding author upon reasonable request.

Conflicts of Interest

The authors declare no conflicts of interest.

Abbreviations

Abbreviations
UAVUnmanned aerial vehicle
RGBRed–green–blue optical image
DSMDigital surface model
LiDARLight detection and ranging
RTKReal-time kinematic positioning
GSDGround sampling distance
EMAExponential moving average
DPTDense prediction transformer decoder
AGPAdaptive geometric prompting
GPLGeometry-Calibrated Pseudo-Label Learning
BGRBoundary-Aware Geometric Regularization
ASVModality-preserving asymmetric strong view
IoU/mIoUIntersection over union/mean intersection over union
BF1Boundary F1-score
PAPixel accuracy
Main symbols
D l , D u Labeled and unlabeled training sets
x r , x d , Y RGB tile, DSM tile, and pixel-level label map
Ω , C , K Pixel set, number of semantic classes, and number of decoder scales
Branch/view index; l, w, and s , v denote labeled, weak, and the v-th strong view
g r , g d , ϕ k RGB encoder, DSM encoder, and scale-k DSM projection layer
F k r , , F k d , , P k                RGB feature, DSM feature, and DSM prompt feature at scale k
E ¯ d , , E d , Raw and normalized DSM edge prior
Norm ( · ) Mean-exponential response normalization in Equation (4)
Q k , Z k AGP gate and fused decoder feature at scale k
f θ , f θ Student and EMA teacher segmentation networks
A w , A a p p v , T v Weak augmentation, RGB-only appearance perturbation, and synchronized spatial transform
Δ 1 , Δ 2 Complementary channel-dropout masks for the two strong RGB branches
p w , Y ^ , S Teacher weak-view probability map, pseudo-label map, and raw confidence map
B w , B ^ s , v Teacher and student semantic-boundary response maps
U , A , C ˜ , M Boundary-band indicator, geometry-agreement map, calibrated confidence map, and valid pseudo-label mask
M b v BGR boundary-supervision mask for the v-th strong view
L s u p , L u , L e d g e , L Supervised, unsupervised, boundary, and total training losses
τ b , τ g , τ c , τ d , α , λ u , λ e Boundary-band threshold, geometry-agreement tolerance, confidence threshold, DSM-edge threshold, calibration strength, unsupervised-loss weight, and boundary-loss weight

Appendix A. Spatial Parcel Partition of the Three-Parcel UAV Rice-Lodging Collection

Figure A1 provides the parcel-level spatial partition maps used to clarify the dataset division. The orthomosaic of each parcel is overlaid with semi-transparent colors so that the spatial relationship among the source, validation, in-region test, and external test parcels can be inspected directly. In the main benchmark, Partition 2 shows the HA-P2 training and validation regions, Partition 1 shows the HA-P1 in-region held-out test parcel, and Partition 3 shows the WX-P3 external parcel used only for direct cross-region testing.
Figure A1. Parcel-level spatial partition of the three-parcel UAV rice-lodging collection. In the main benchmark, Partition 2 denotes the HA-P2 training, buffer, and validation regions, Partition 1 shows the HA-P1 in-region held-out test parcel, and Partition 3 shows the WX-P3 external parcel used only for direct cross-region testing. (a) Partition 1: HA-P1 parcel. (b) Partition 2: HA-P2 parcel. (c) Partition 3: WX-P3 parcel.
Remotesensing 18 02961 g0a1

Appendix B. Controlled DSM Perturbation Analysis

As an additional sensitivity analysis, this appendix reports controlled DSM perturbation experiments that isolate additive noise, rigid RGB–DSM shifts, random missing pixels, and missing DSM at inference. These tests complement the structured DSM degradation experiments in Section 4.6.1, which focus on spatially correlated photogrammetric failure modes in unlabeled training DSMs.

Appendix B.1. Robustness to DSM Noise

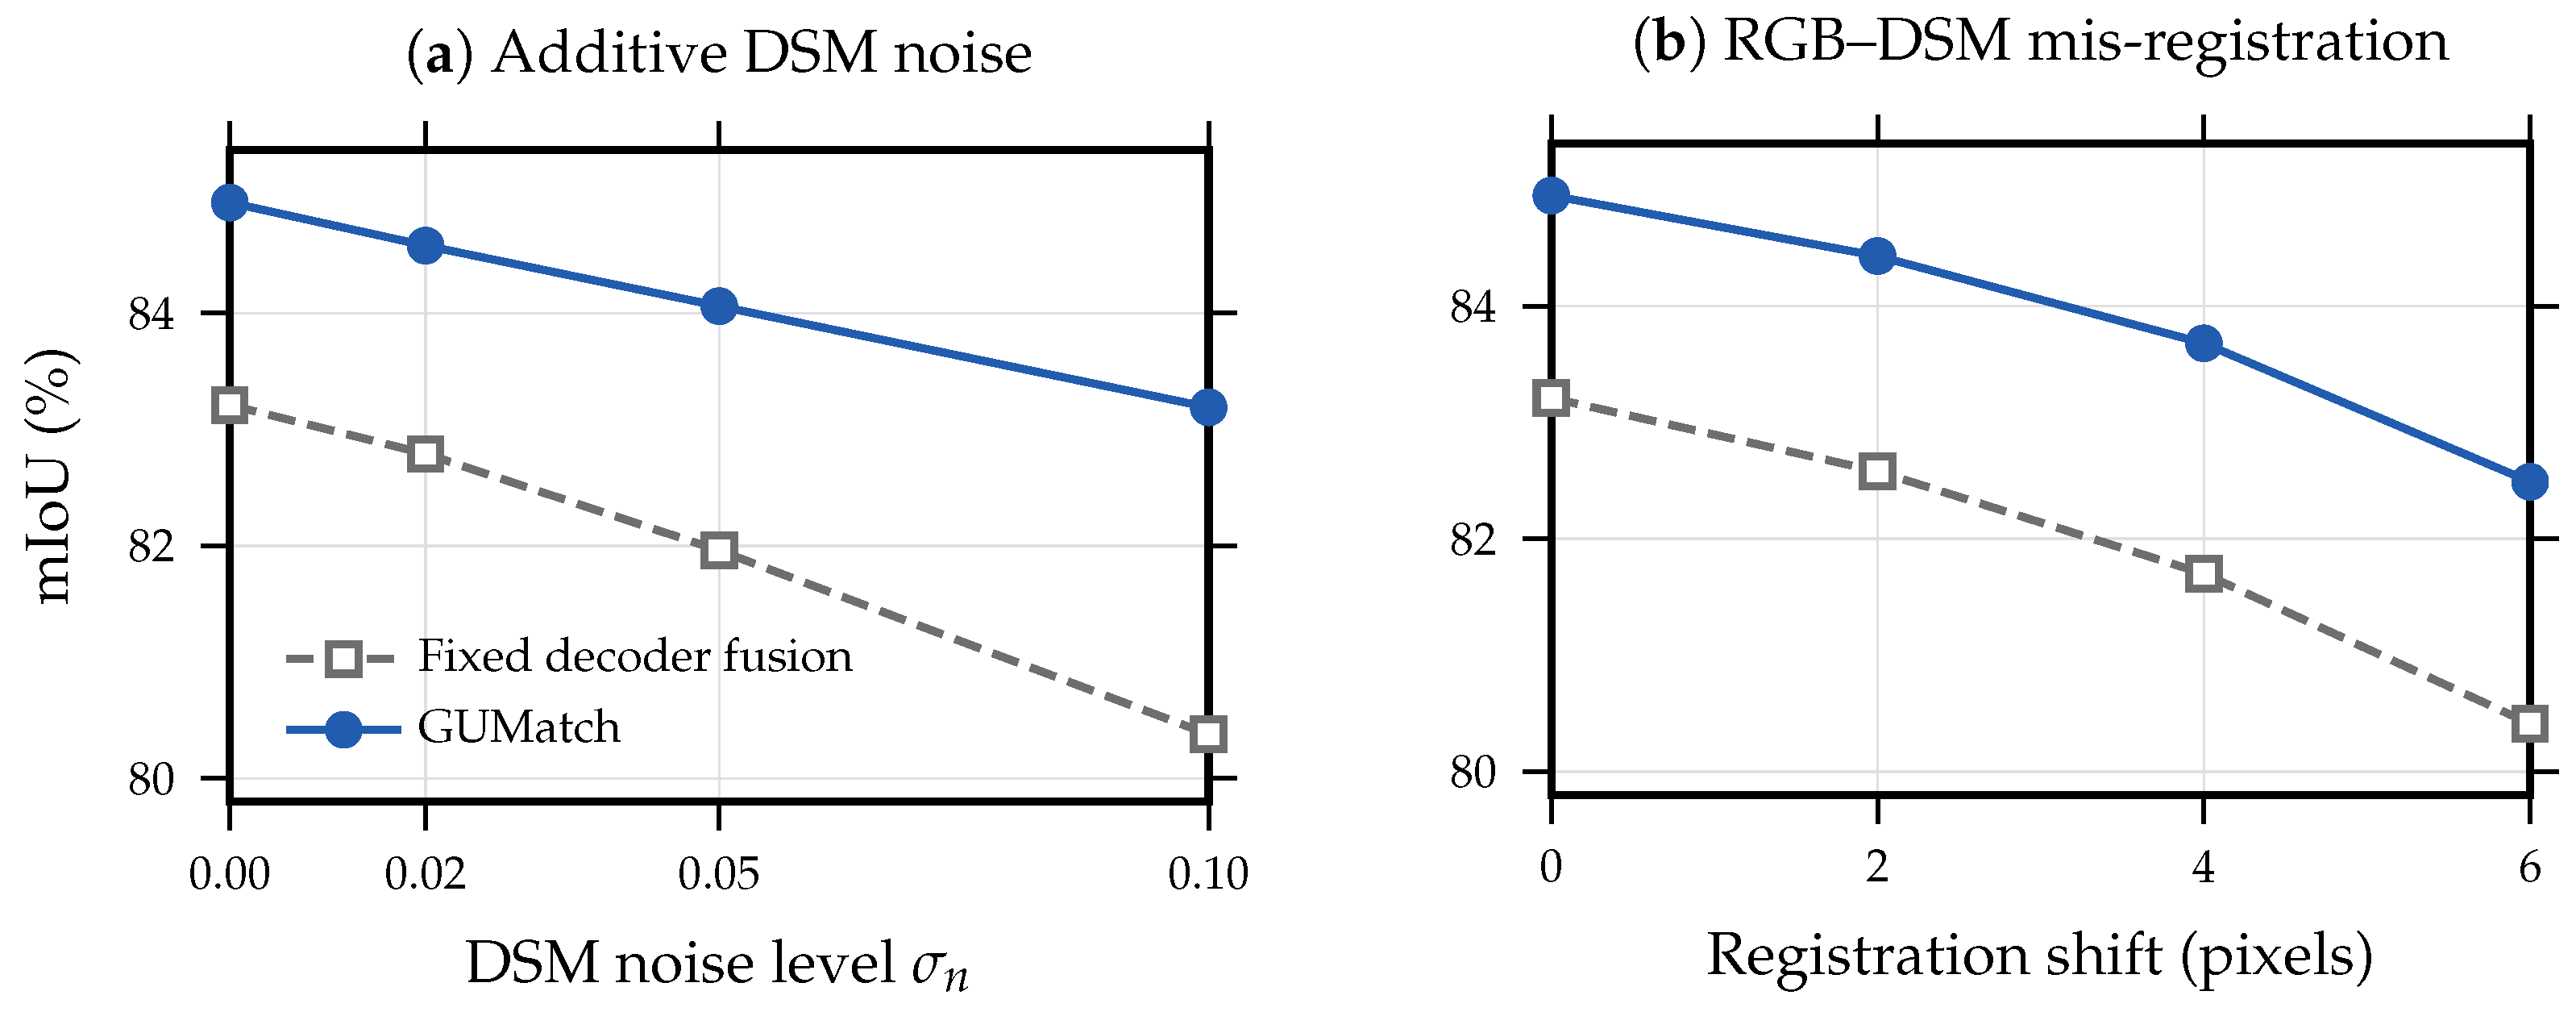
We first perturb the DSM of unlabeled samples during semi-supervised training by adding zero-mean Gaussian noise with standard deviation σ n , while keeping the labeled data and the final test set clean. As shown in Figure A2a, both methods degrade as the training-time noise level increases, but GUMatch drops more slowly than the fixed decoder fusion baseline. This trend supports the design of AGP and GPL: unstable DSM responses are attenuated before they distort pseudo-label calibration or feature prompting.
Figure A2. Robustness of the fixed decoder fusion baseline and GUMatch under training-time DSM corruption on the 20 % split. Panel (a) reports additive DSM noise with standard deviation σ n , and panel (b) reports residual RGB–DSM mis-registration. In both settings, GUMatch exhibits a slower accuracy drop, indicating stronger tolerance to noisy or imperfect geometric cues.
Remotesensing 18 02961 g0a2

Appendix B.2. Robustness to Modal Mis-Registration

We next simulate residual co-registration errors during semi-supervised training by shifting the unlabeled DSM relative to the RGB image by 2, 4, and 6 pixels, while evaluation is still performed on the clean test set. Figure A2b shows that residual shift harms both methods, but GUMatch remains consistently more stable. This behavior is consistent with AGP suppressing incompatible prompts and BGR restricting boundary alignment to the masked regions specified by Equation (17), which prevents misaligned DSM edges from dominating training.

Appendix B.3. Robustness to DSM Voids and Missing Modality at Inference

To complement the additive-noise and rigid-shift experiments, we further test two failure modes that are common in operational UAV photogrammetry but are not captured by Gaussian noise alone. First, we randomly mask 5 % , 10 % , and 20 % of the unlabeled DSM pixels with zero values, simulating reconstruction holes. Second, we replace the test-time DSM by an all-zero map to bound the cost of the modality-required-at-inference assumption discussed in Section 3.1. Results are summarized in Table A1.
Table A1. Robustness to random DSM voids (training-time) and to missing test-time DSM (all-zero replacement) on the 20 % DINOv2-B split. Values in italics are the absolute mIoU drop relative to the corresponding 0% void column.
Setting0% Void5% Void10% Void20% Void
Fixed decoder fusion83.2182.6481.5579.21
GUMatch84.9584.6183.9782.40
Test-time DSM replaced by all-zero map
Fixed decoder fusion75.04 ( 8.17 )
GUMatch78.62 ( 6.33 )
Reliability gating makes GUMatch less dependent on local DSM validity. At 20 % random voids, the absolute drop is 2.55 mIoU for GUMatch and 4.00 mIoU for fixed fusion. The all-zero replacement test also shows that GUMatch keeps part of the multimodal advantage when DSM is unavailable at inference, although this setting still causes a clear accuracy loss and should be treated only as a fallback.

References

  1. Thai, V.T.; Checco, J.; Mitchell, J.; Garba, I.I.; Akber, M.A.; Aziz, A.A. Producing More Rice with Fewer Emissions: A Global Meta-Analysis. npj Sustain. Agric. 2026, 4, 27. [Google Scholar] [CrossRef] [Scilit]
  2. Fukagawa, N.K.; Ziska, L.H. Rice: Importance for Global Nutrition. J. Nutr. Sci. Vitaminol. 2019, 65, S2–S3. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  3. Chauhan, S.; Darvishzadeh, R.; Boschetti, M.; Pepe, M.; Nelson, A. Remote Sensing-Based Crop Lodging Assessment: Current Status and Perspectives. ISPRS J. Photogramm. Remote Sens. 2019, 151, 124–140. [Google Scholar] [CrossRef] [Scilit]
  4. Liao, P.; Bell, S.M.; Chen, L.; Huang, S.; Wang, H.; Miao, J.; Qi, Y.; Sun, Y.; Liao, B.; Zeng, Y.; et al. Improving Rice Grain Yield and Reducing Lodging Risk Simultaneously: A Meta-Analysis. Eur. J. Agron. 2023, 143, 126709. [Google Scholar] [CrossRef] [Scilit]
  5. Niu, Y.; Chen, T.; Zhao, C.; Zhou, M. Lodging Prevention in Cereals: Morphological, Biochemical, Anatomical Traits and Their Molecular Mechanisms, Management and Breeding Strategies. Field Crops Res. 2022, 289, 108733. [Google Scholar] [CrossRef] [Scilit]
  6. Wang, Y.; Fan, X.; Wang, J.; Ye, Q.; Liu, J.; Bai, Z.; Huan, H. Complementary-aware collaborative fusion: Advancing precise wheat lodging mapping using UAV-borne RGB imagery and LiDAR data. Comput. Electron. Agric. 2026, 253, 112109. [Google Scholar] [CrossRef] [Scilit]
  7. Kumar, M.; Bhattacharya, B.K.; Pandya, M.R.; Handique, B.K. Machine Learning Based Plot Level Rice Lodging Assessment Using Multi-Spectral UAV Remote Sensing. Comput. Electron. Agric. 2024, 219, 108754. [Google Scholar] [CrossRef] [Scilit]
  8. Jung, S.; Kim, S.; Kang, D.; Kim, H.; Park, K.S.; Ahn, H.G.; Choi, J.; Park, K. Automated Calculation of Rice-Lodging Rates Within a Parcel Area in a Mobile Environment Using Aerial Imagery. Remote Sens. 2026, 18, 21. [Google Scholar] [CrossRef] [Scilit]
  9. Zhang, C.; Kovacs, J.M. The Application of Small Unmanned Aerial Systems for Precision Agriculture: A Review. Precis. Agric. 2012, 13, 693–712. [Google Scholar] [CrossRef] [Scilit]
  10. Zhou, Y.; Fan, X.; Bai, Z.; Huan, H.; Ye, Q. Wheat lodging mapping from UAV imagery using WheatSegNet with lodging-aware copy-paste augmentation. Smart Agric. Technol. 2026, 9, 102144. [Google Scholar] [CrossRef] [Scilit]
  11. Wang, J.; Zhang, S.; Lizaga, I.; Zhang, Y.; Ge, X.; Zhang, Z.; Zhang, W.; Huang, Q.; Hu, Z. UAS-Based Remote Sensing for Agricultural Monitoring: Current Status and Perspectives. Comput. Electron. Agric. 2024, 227, 109501. [Google Scholar] [CrossRef] [Scilit]
  12. Yang, G.; Liu, J.; Zhao, C.; Li, Z.; Huang, Y.; Yu, H.; Xu, B.; Yang, X.; Zhu, D.; Zhang, X.; et al. Unmanned Aerial Vehicle Remote Sensing for Field-Based Crop Phenotyping: Current Status and Perspectives. Front. Plant Sci. 2017, 8, 1111. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  13. Su, Z.; Wang, Y.; Xu, Q.; Gao, R.; Kong, Q. LodgeNet: Improved Rice Lodging Recognition Using Semantic Segmentation of UAV High-Resolution Remote Sensing Images. Comput. Electron. Agric. 2022, 196, 106873. [Google Scholar] [CrossRef] [Scilit]
  14. Sun, J.; Zhou, J.; He, Y.; Jia, H.; Liang, Z. RL-DeepLabv3+: A Lightweight Rice Lodging Semantic Segmentation Model for Unmanned Rice Harvester. Comput. Electron. Agric. 2023, 209, 107823. [Google Scholar] [CrossRef] [Scilit]
  15. Kang, G.; Wang, J.; Zeng, F.; Cai, Y.; Kang, G.; Yue, X. Lightweight Detection System with Global Attention Network (GloAN) for Rice Lodging. Plants 2023, 12, 1595. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  16. Zhang, P.; Niu, L.; Cai, M.; Chen, H.; Sun, X. AAUConvNeXt: Enhancing Crop Lodging Segmentation with Optimized Deep Learning Architectures. Plant Phenomics 2024, 6, 0182. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  17. Berry, P.M.; Sterling, M.; Spink, J.H.; Baker, C.J.; Sylvester-Bradley, R.; Mooney, S.J.; Tams, A.R.; Ennos, A.R. Understanding and Reducing Lodging in Cereals. Adv. Agron. 2004, 84, 217–271. [Google Scholar] [CrossRef] [Scilit]
  18. Pinthus, M.J. Lodging in Wheat, Barley, and Oats: The Phenomenon, Its Causes, and Preventive Measures. In Advances in Agronomy; Academic Press: Cambridge, MA, USA, 1973; Volume 25, pp. 209–263. [Google Scholar] [CrossRef] [Scilit]
  19. Fan, X.; Zhi, S.; Tjahjadi, T.; Liu, J.; Bai, Z.; Ye, Q.; Huan, H. Integrating UAV-acquired RGB and LiDAR point cloud data using multimodal learning for wheat lodging mapping and area estimation. IEEE J. Sel. Top. Signal Process. 2026, 20, 1–16. [Google Scholar] [CrossRef] [Scilit]
  20. Yu, J.; Cheng, T.; Cai, N.; Zhou, X.G.; Diao, Z.; Wang, T.; Du, S.; Liang, D.; Zhang, D. Wheat Lodging Extraction from Multi-Channel UAV Images Using a Lightweight Network Model. Sensors 2021, 21, 6826. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  21. Yang, M.D.; Huang, K.S.; Kuo, Y.H.; Tsai, H.P.; Lin, L.M. Spatial and Spectral Hybrid Image Classification for Rice Lodging Assessment Through UAV Imagery. Remote Sens. 2017, 9, 583. [Google Scholar] [CrossRef] [Scilit]
  22. Hosseinpour, H.; Samadzadegan, F.; Javan, F.D. CMGFNet: A Deep Cross-Modal Gated Fusion Network for Building Extraction from Very High-Resolution Remote Sensing Images. ISPRS J. Photogramm. Remote Sens. 2022, 184, 96–115. [Google Scholar] [CrossRef] [Scilit]
  23. Wei, K.; Dai, J.; Hong, D.; Ye, Y. MGFNet: An MLP-Dominated Gated Fusion Network for Semantic Segmentation of High-Resolution Multi-Modal Remote Sensing Images. Int. J. Appl. Earth Obs. Geoinf. 2024, 135, 104241. [Google Scholar] [CrossRef] [Scilit]
  24. Wang, T.; Chen, G.; Zhang, X.; Liu, C.; Wang, J.; Tan, X.; Zhou, W.; He, C. LMFNet: Lightweight Multimodal Fusion Network for High-Resolution Remote Sensing Image Segmentation. Pattern Recogn. 2025, 164, 111579. [Google Scholar] [CrossRef] [Scilit]
  25. Zhang, H.; Yang, C.; Fan, X. MTCDNet: Multimodal feature fusion-based tree crown detection network using UAV-acquired optical imagery and LiDAR data. Remote Sens. 2025, 17, 1996. [Google Scholar] [CrossRef] [Scilit]
  26. Pan, C.; Fan, X.; Tjahjadi, T.; Guan, H.; Fu, L.; Ye, Q.; Wang, R. Vision foundation model guided multimodal fusion network for remote sensing semantic segmentation. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2025, 18, 9409–9431. [Google Scholar] [CrossRef] [Scilit]
  27. Chen, Q.; Xia, C.; Shi, Y.; Wang, X.; Huang, X.; Wang, L.; Zhang, X.; Zheng, E.; Gao, X.; Liu, F. UAV Remote Sensing Imagery-Based Semantic Segmentation Approach for Lodged Rice Region. Smart Agric. Technol. 2026, 13, 101689. [Google Scholar] [CrossRef] [Scilit]
  28. Yang, L.; Qi, L.; Feng, L.; Zhang, W.; Shi, Y. Revisiting Weak-to-Strong Consistency in Semi-Supervised Semantic Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, BC, Canada, 17–24 June 2023; IEEE: Piscataway, NJ, USA, 2023; pp. 7236–7246. [Google Scholar] [CrossRef] [Scilit]
  29. Yang, L.; Zhao, Z.; Zhao, H. UniMatch V2: Pushing the Limit of Semi-Supervised Semantic Segmentation. IEEE Trans. Pattern Anal. Mach. Intell. 2025, 47, 3031–3048. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  30. Sun, W.; Lei, Y.; Hong, D.; Hu, Z.; Li, Q.; Zhang, J. RSProtoSemiSeg: Semi-Supervised Semantic Segmentation of High Spatial Resolution Remote Sensing Images with Probabilistic Distribution Prototypes. ISPRS J. Photogramm. Remote Sens. 2025, 228, 771–784. [Google Scholar] [CrossRef] [Scilit]
  31. Oquab, M.; Darcet, T.; Moutakanni, T.; Vo, H.; Szafraniec, M.; Khalidov, V.; Fernandez, P.; Haziza, D.; Massa, F.; El-Nouby, A.; et al. DINOv2: Learning robust visual features without supervision. arXiv 2024, arXiv:2304.07193. [Google Scholar] [CrossRef] [Scilit]
  32. Chen, X.; Williams, B.M.; Vallabhaneni, S.R.; Czanner, G.; Williams, R.; Zheng, Y. Learning Active Contour Models for Medical Image Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, CA, USA, 15–20 June 2019; IEEE: Piscataway, NJ, USA, 2019; pp. 11632–11640. [Google Scholar] [CrossRef] [Scilit]
  33. Yang, L.; Zhuo, W.; Qi, L.; Shi, Y.; Gao, Y. ST++: Make Self-Training Work Better for Semi-Supervised Semantic Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; IEEE: Piscataway, NJ, USA, 2022; pp. 4258–4267. [Google Scholar] [CrossRef] [Scilit]
  34. Liu, Y.; Tian, Y.; Chen, Y.; Liu, F.; Belagiannis, V.; Carneiro, G. Perturbed and Strict Mean Teachers for Semi-Supervised Semantic Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; IEEE: Piscataway, NJ, USA, 2022; pp. 4248–4257. [Google Scholar] [CrossRef] [Scilit]
  35. Sun, R.; Mai, H.; Zhang, T.; Wu, F. DAW: Exploring the Better Weighting Function for Semi-Supervised Semantic Segmentation. In Proceedings of the Annual Conference on Neural Information Processing Systems (NeurIPS), New Orleans, LA, USA, 10–16 December 2023; Neural Information Processing Systems Foundation, Inc.: San Diego, CA, USA, 2023; Volume 36, pp. 61792–61805. Available online: https://proceedings.neurips.cc/paper_files/paper/2023/hash/c28ef8449dc21c90696c80ce47b3b5cc-Abstract-Conference.html (accessed on 1 August 2020).
  36. Sun, B.; Yang, Y.; Zhang, L.; Cheng, M.M.; Hou, Q. CorrMatch: Label Propagation via Correlation Matching for Semi-Supervised Semantic Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16–22 June 2024; IEEE: Piscataway, NJ, USA, 2024; pp. 3097–3107. [Google Scholar] [CrossRef] [Scilit]
  37. Maheshwari, H.; Liu, Y.C.; Kira, Z. Missing Modality Robustness in Semi-Supervised Multi-Modal Semantic Segmentation. In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), Waikoloa, HI, USA, 3–8 January 2024; IEEE: Piscataway, NJ, USA, 2024; pp. 1009–1019. [Google Scholar] [CrossRef] [Scilit]
  38. Yin, J.; Jiang, X.; Chen, T.; Pei, G.; Yao, Y.; Shen, F.; Shen, H.T. DepMatch: Boosting Semi-Supervised Semantic Segmentation by Exploring Depth Difference Knowledge. IEEE Trans. Image Process. 2026, 35, 3256–3270. [Google Scholar] [CrossRef] [Scilit] [PubMed]
Figure 1. Overview of the three-parcel UAV rice-lodging collection. (a) HA-P1 (4.2 ha), (b) locations of Huai’an and Wuxi in Jiangsu Province, (c) HA-P2 (4.9 ha), (d) WX-P3 (2.7 ha), and (e) representative lodged-rice samples.
Remotesensing 18 02961 g001
Figure 2. Representative pixel-level annotation examples. Each column displays the RGB tile, the corresponding DSM tile, and the annotation overlay for the semantic categories, where red indicates lodged rice and green represents healthy rice.
Remotesensing 18 02961 g002
Figure 3. Comparisonbetween the baseline UniMatch V2 and the proposed GUMatch. (a) UniMatch V2 [29] uses an EMA teacher to produce pseudo-labels from a weak view, while two strong views derived from the same image are optimized in parallel with complementary dropout and weak-to-strong consistency. (b) GUMatch preserves this teacher–student training scaffold for co-registered RGB–DSM segmentation, but uses DSM as an explicit source of geometric structure. AGP converts DSM into aligned prompt features and an edge prior; the prompt features are injected into the decoder, and the edge prior supports GPL-based pseudo-label calibration and BGR-based boundary refinement.
Remotesensing 18 02961 g003
Figure 4. Overview of the proposed Adaptive Geometric Prompting (AGP) module. A lightweight DSM encoder produces scale-aligned prompt features and DSM edge priors. At each decoder scale, AGP combines the RGB feature, DSM prompt, and edge prior to generate a gated residual correction, yielding fused features for the DPT decoder.
Remotesensing 18 02961 g004
Figure 5. Local zoom-in qualitative comparison of segmentation results on two challenging UAV rice-lodging regions. GUMatch better preserves fragmented lodged-rice regions, suppresses local background confusion, and produces clearer lodging boundaries.
Remotesensing 18 02961 g005
Figure 6. Cross-regionqualitative comparison on two WX-P3 samples. GUMatch produces more coherent healthy-rice and lodged-rice regions while reducing large background-confusion errors.
Remotesensing 18 02961 g006
Figure 7. Mechanism-orientedqualitative analysis under the 20% labeled DINOv2-B setting.
Remotesensing 18 02961 g007
Table 1. Main UAV, sensor, and image-product parameters of the three-parcel UAV rice-lodging collection.
ParameterValue
UAV platformDJI Matrice 300 RTK
Sensor payloadZenmuse L2 LiDAR payload with integrated RGB mapping camera
Camera sensorCMOS
Shutter speed1/8000–30 s
ISO range100–12,800
Storage mediumHigh-speed SD card
Camera weightApproximately 500 g
ParcelMosaic size/GSD
HA-P116,092 × 34,816 px/0.847 cm pixel−1
HA-P224,575 × 27,455 px/0.852 cm pixel−1
WX-P322,333 × 16,748 px/0.850 cm pixel−1
Table 2. mIoU (%) results on the HA-P2HA-P1 in-region benchmark. Each cell is the mean ± standard deviation over three independent labeled/unlabeled splits with seeds 0, 1, and 2. denotes fully supervised methods retrained on the same labeled subsets to provide a multimodal reference under scarce labels. Panel A reports the RN-101 benchmark and RGB–DSM references, panel B reports multimodal semi-supervised baselines, and panel C reports the DINOv2-B variants.
MethodEncoder10% Labels20% Labels40% Labels
Panel A. RN-101 Benchmark and RGB–DSM References
Labeled OnlyRN-10171.62 ± 0.3175.48 ± 0.2778.96 ± 0.22
ST++ [33]RN-10175.88 ± 0.2678.92 ± 0.2181.24 ± 0.18
PS-MT [34]RN-10175.41 ± 0.2478.55 ± 0.2081.47 ± 0.16
UniMatch V1 [28]RN-10177.03 ± 0.2279.84 ± 0.1882.36 ± 0.15
DAW [35]RN-10176.84 ± 0.2180.02 ± 0.2082.28 ± 0.16
CorrMatch [36]RN-10177.46 ± 0.2080.38 ± 0.1882.54 ± 0.14
UniMatch V2 [29]RN-10177.82 ± 0.1880.76 ± 0.1682.93 ± 0.13
RSProtoSemiSeg [30]RN-10178.41 ± 0.1981.18 ± 0.1783.39 ± 0.14
Multimodal RGB–DSM baselines
CMGFNet [22]RN-10176.92 ± 0.2580.21 ± 0.2082.74 ± 0.16
LMFNet [24]RN-10177.45 ± 0.2280.74 ± 0.1983.08 ± 0.15
UniMatch V2 + DSM (early concat)RN-10178.34 ± 0.2081.07 ± 0.1883.21 ± 0.15
UniMatch V2 + DSM (decoder add)RN-10178.61 ± 0.1981.25 ± 0.1783.46 ± 0.15
GUMatchRN-10180.12 ± 0.1882.98 ± 0.1585.06 ± 0.13
Panel B. Multimodal Semi-Supervised Baselines
M3L [37]MiT-B478.90 ± 0.2181.88 ± 0.1884.05 ± 0.17
DepMatch [38]DINOv2-B80.55 ± 0.1481.49 ± 0.1684.31 ± 0.13
Panel C. Backbone Upgrade with DINOv2-B
UniMatch V2 [29]DINOv2-B80.35 ± 0.1682.54 ± 0.1484.44 ± 0.12
UniMatch V2 + DSM (decoder add)DINOv2-B81.18 ± 0.1583.21 ± 0.1384.97 ± 0.12
GUMatchDINOv2-B82.64 ± 0.1484.95 ± 0.1386.72 ± 0.11
Table 3. Detailed comparison among pure RGB full supervision, RGB–DSM full supervision, and the proposed semi-supervised GUMatch on the HA-P2HA-P1 benchmark with DINOv2-B. Full supervision rows use all 900 labeled training tiles and no unlabeled objective. Semi-supervised rows use the listed labeled subset and the remaining training tiles as unlabeled data.
Training ProtocolInputLabelsLodged IoUHealthy IoUBackground IoUmIoUPrecisionRecallF1
Full supervision (UniMatch V2)RGB100%86.8392.7479.6686.4192.3393.2292.62
Full supervision (GUMatch)RGB–DSM100%89.3293.0881.9988.1392.2295.6393.63
Semi-supervision (GUMatch)RGB–DSM10%83.2890.3874.2682.6491.5988.8190.18
Semi-supervision (GUMatch)RGB–DSM20%86.7991.6376.4384.9592.8390.5891.69
Semi-supervision (GUMatch)RGB–DSM40%87.9792.8079.3986.7293.5291.8692.68
Table 4. Detailedclass-wise and mean-metric results across all labeled ratios. Panels A, B, and C correspond to the 10%, 20%, and 40% labeled settings, respectively.
MethodEncoderClass-Wise IoU (%)Mean Metrics (%)
LodgedHealthyBackgroundPrecisionRecallF1-Score
Panel A. 10% Labeled
Labeled OnlyRN-10170.4185.6158.8484.3180.7482.49
ST++ [33]RN-10176.1286.6664.8687.1884.2885.71
PS-MT [34]RN-10175.6386.5864.0286.9284.0585.46
UniMatch V1 [28]RN-10177.5387.4566.1187.9484.9686.42
DAW [35]RN-10177.1887.4265.9287.7684.8186.26
CorrMatch [36]RN-10177.8488.0066.5488.1485.2786.68
UniMatch V2 [29]RN-10178.1888.1767.1188.3785.5986.96
RSProtoSemiSeg [30]RN-10178.7788.6367.8388.9085.9887.41
GUMatchRN-10180.5089.4470.4289.9287.1888.53
M3L [37]MiT-B481.5583.4571.7088.4987.5188.00
DepMatch [38]DINOv2-B80.4389.1872.0389.3488.9189.20
UniMatch V2 [29]DINOv2-B80.8689.1171.0890.1187.3588.71
GUMatchDINOv2-B83.2890.3874.2691.5988.810.18
Panel B. 20% Labeled
Labeled OnlyRN-10175.9286.5863.9486.7183.9285.26
ST++ [33]RN-10180.7287.8968.1588.8486.2787.54
PS-MT [34]RN-10180.2187.8267.6288.6185.9887.27
UniMatch V1 [28]RN-10181.2988.8969.3489.3486.7988.04
DAW [35]RN-10181.4789.0869.5189.4586.9588.18
CorrMatch [36]RN-10181.8889.3269.9489.7287.2188.45
UniMatch V2 [29]RN-10182.3589.6570.2889.9887.4888.71
RSProtoSemiSeg [30]RN-10182.6389.7771.1490.3188.0489.16
GUMatchRN-10184.7490.7173.4991.5689.3190.42
M3L [37]MiT-B483.1188.1174.4290.1789.5789.86
DepMatch [38]DINOv2-B81.1490.5572.7991.1890.6789.78
UniMatch V2 [29]DINOv2-B84.2690.1873.1891.3488.9490.12
GUMatchDINOv2-B86.7991.6376.4392.8390.5891.69
Panel C. 40% Labeled
Labeled OnlyRN-10180.0188.4168.4688.5586.5187.52
ST++ [33]RN-10182.8988.7372.1090.1187.9889.03
PS-MT [34]RN-10182.9489.5971.8890.0288.1489.07
UniMatch V1 [28]RN-10183.7190.1173.2690.6488.6389.62
DAW [35]RN-10183.6590.0873.1190.5788.7489.64
CorrMatch [36]RN-10183.9490.2273.4690.7988.9289.85
UniMatch V2 [29]RN-10184.2890.6873.8390.9889.1890.07
RSProtoSemiSeg [30]RN-10184.7690.9974.4191.2689.4190.29
GUMatchRN-10186.4991.6677.0392.4890.9891.72
M3L [37]MiT-B484.9486.9880.2391.3591.0391.19
DepMatch [38]DINOv2-B85.9892.2974.6792.0591.9891.48
UniMatch V2 [29]DINOv2-B85.7491.3476.2492.1990.4691.32
GUMatchDINOv2-B87.9792.8079.3993.5291.8692.68
Table 5. Source-parcelgeneralization results on the external WX-P3 set under the 40% labeled setting. Models were trained and selected using only HA-P2; WX-P3 was reserved for direct testing.
MethodClass-Wise IoU (%)Mean Metrics (%)
LodgedHealthyBackgroundmIoUPrecisionRecallF1-ScorePA
PS-MT31.4225.6411.9523.0138.9336.4036.6638.78
CorrMatch65.0110.4031.3535.5970.2858.6548.4654.73
CMGFNet67.598.4735.2737.1172.1658.9449.4759.58
LMFNet80.2329.3749.8453.1576.2973.2566.9972.71
M3L82.7628.5555.6055.6478.8272.8068.8276.88
DAW80.1138.1055.2057.8076.4376.2071.7675.79
DepMatch82.5438.9959.7660.4378.2275.7373.7879.33
UniMatch V2 (RN-101)79.7542.3061.1061.0579.1678.4974.6878.06
GUMatch (RN-101)79.6448.4669.4065.8382.6377.5978.6382.00
UniMatch V2 (DINOv2-B)80.4443.9264.4962.9581.0177.6875.8281.06
GUMatch (DINOv2-B)79.8650.3474.8168.3483.3681.1180.6981.79
Table 6. Ablation of the core design elements on the 20% split.
SettingAGPGPLBGRmIoUmF1BF1
UniMatch V2 82.5490.1271.86
+ Fixed Decoder Fusion 83.2190.6373.18
+ AGPY 83.8691.0574.24
+ GPLYY 84.2991.3175.37
GUMatchYYY84.9591.6977.21
Table 7. Ablation of fusion strategy and DSM injection position on the 20% split.
Fusion StrategyInjection StagemIoU (%)BF1 (%)
Early concatenationinput level82.8972.44
Backbone fusionencoder stage 3–482.9772.87
Fixed additionbefore RGB comp-drop82.9472.96
Fixed additionafter RGB comp-drop83.2173.18
AGP (ours)after RGB comp-drop84.9577.21
Table 8. Effect of teacher–student modality configuration on the 20% split.
Teacher InputStudent InputPseudo-Label Precision (%)mIoU (%)
RGBRGB85.782.54
RGB–DSMRGB87.483.32
RGBRGB–DSM85.783.57
RGB–DSMRGB–DSM88.584.95
Table 9. Pseudo-label quality analysis. Hidden annotations are used only for analysis and never for optimization.
Pseudo-Label SelectionPrecision (%)Recall (%)Retained Ratio (%)BF1 (%)
UniMatch V2 (RGB) + raw confidence85.774.464.868.1
UniMatch V2 + DSM (decoder add) + raw confidence86.575.064.369.4
GUMatch teacher + raw confidence87.676.163.870.9
GUMatch teacher + calibrated confidence (full GPL)88.576.860.572.6
Table 10. Ablation of DSM edge extraction and response normalization on the 20% DINOv2-B split.
Design FactorVariantmIoU (%)mF1 (%)BF1 (%)
Edge extraction with fixed mean-exponential normalization
Edge extractionSobel, no smoothing84.3191.2875.82
Gaussian + Scharr84.8791.6376.94
LoG response84.0591.1475.08
Canny83.9191.0274.62
Gaussian + Sobel (ours)84.9591.6977.21
Normalization with fixed Gaussian + Sobel edge extraction
NormalizationMax/min–max84.1891.1875.34
Percentile clipping84.6291.4776.43
Mean-linear clipping84.7091.5376.56
Z-score + sigmoid84.3491.3075.91
Mean-exp (ours)84.9591.6977.21
Table 11. Structured DSM degradation settings for robustness evaluation.
Degradation ModePhysical InterpretationMildModerateSevere
Low-frequency height distortionCorrelated canopy/reconstruction driftβ = 0.03,β = 0.06,β = 0.10,
σl = 32 pxσl = 32 pxσl = 32 px
Regional topological collapseContinuous local surface collapsearea = 10%,area = 20%,area = 30%,
γ = 0.05γ = 0.75γ = 1.00
Interpolated voids and smoothed holesFilled holes and interpolation artifactsarea = 10%,area = 20%,area = 30%,
σh = 16 pxσh = 24 pxσh = 32 px
Table 12. Results under structured degradation of unlabeled training DSMs on the 20% DINOv2-B split. Δ mIoU = clean-DSM mIoU minus degraded-DSM mIoU.
Training DSM SettingLevelDepMatch [38]GUMatch
mIoUBF1 Δ mIoUmIoUBF1 Δ mIoU
Clean DSM81.4973.180.0084.9577.210.00
Low-frequency height distortionMild80.6872.540.8184.5776.780.38
Low-frequency height distortionModerate80.0371.381.4684.1376.150.82
Low-frequency height distortionSevere79.7269.961.7783.3975.021.56
Regional topological collapseMild80.3172.041.1884.3776.500.58
Regional topological collapseModerate79.9370.031.5683.5275.211.43
Regional topological collapseSevere78.7467.212.7582.5773.722.38
Interpolated voids and smoothed holesMild80.7772.220.7284.5576.700.40
Interpolated voids and smoothed holesModerate80.3670.581.1383.8675.741.09
Interpolated voids and smoothed holesSevere78.6868.612.8182.6174.022.34
Table 13. Sensitivity analysis on the 20% DINOv2-B split.
ParameterDefaultLowMidHighRange (mIoU)
α (calibration strength)0.400.200.600.8084.62–84.95
τ c (pseudo-label threshold)0.850.750.800.9084.51–84.95
τ d (DSM-edge threshold)0.200.100.300.4084.43–84.95
λ e (BGR weight)0.50.11.02.084.30–84.95
Table 14. Ablation of the boundary objective inside BGR on the 20% DINOv2-B split.
Boundary Loss for BGRmIoU (%)BF1 (%)
Dice on binarized maps84.5176.18
Active-contour-style [32]84.6276.41
L1 amplitude (ours)84.9577.21
Table 15. Efficiency comparison on the 20% split.
MethodParams (M)FLOPs (G)FPSmIoU (%)
UniMatch V262.8164.218.782.54
Fixed decoder fusion68.1171.417.983.21
GUMatch69.0173.817.484.95
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.