Article

C3Net: Cross-Modal Feature Recalibrated, Cross-Scale Semantic Aggregated and Compact Network for Semantic Segmentation of Multi-Modal High-Resolution Aerial Images

1
Aerospace Information Research Institute, Chinese Academy of Sciences, Beijing 100190, China
2
Key Laboratory of Network Information System Technology (NIST), Aerospace Information Research Institute, Chinese Academy of Sciences, Beijing 100190, China
3
University of Chinese Academy of Sciences, Beijing 100190, China
4
School of Electronic, Electrical and Communication Engineering, University of Chinese Academy of Sciences, Beijing 100190, China
5
Key Laboratory on Microwave Imaging Technology, Institute of Electronics, Chinese Academy of Sciences, Beijing 100190, China
*
Author to whom correspondence should be addressed.
Remote Sens. 2021, 13(3), 528; https://doi.org/10.3390/rs13030528
Submission received: 30 December 2020 / Revised: 27 January 2021 / Accepted: 29 January 2021 / Published: 2 February 2021
(This article belongs to the Special Issue Big Remotely Sensed Data)

Abstract

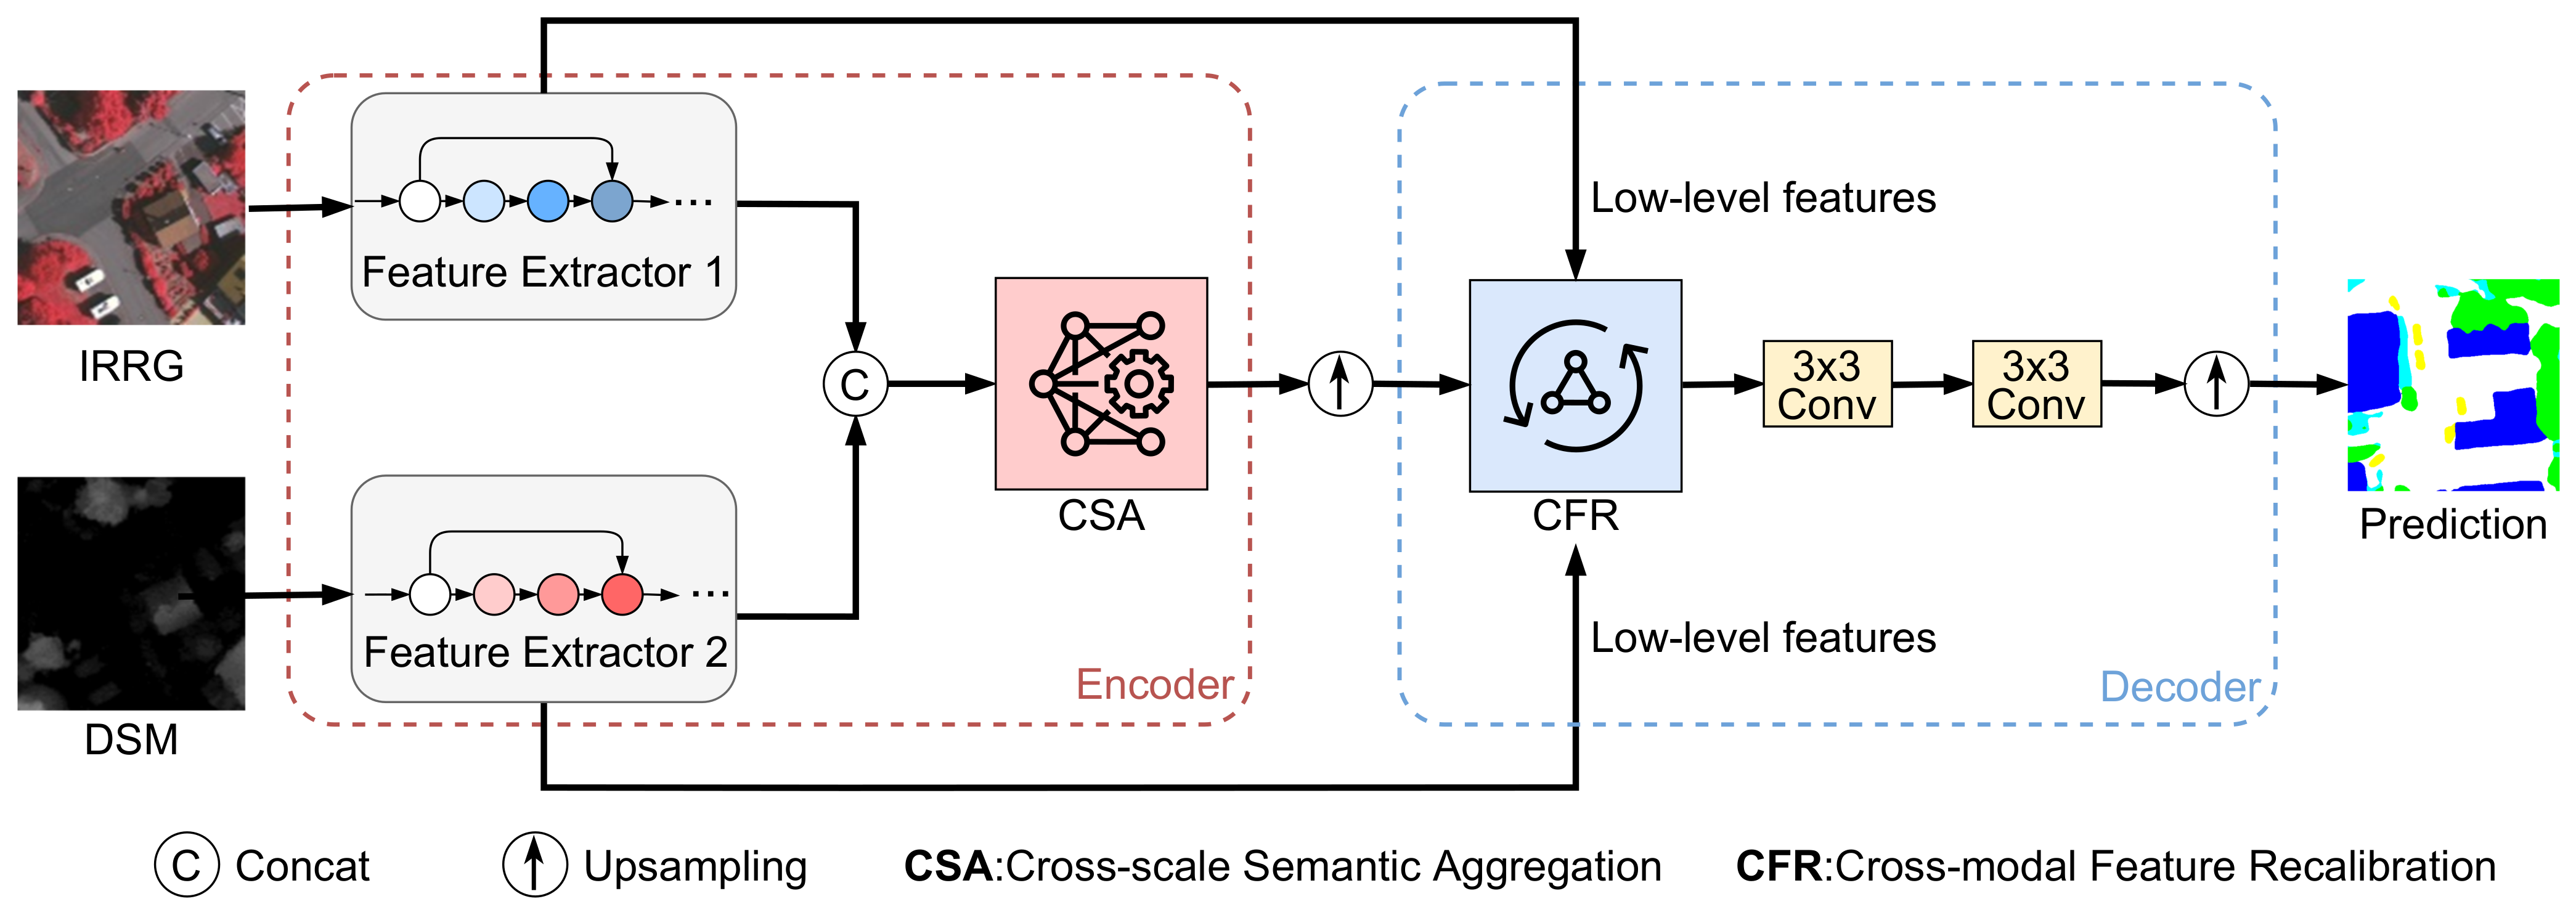
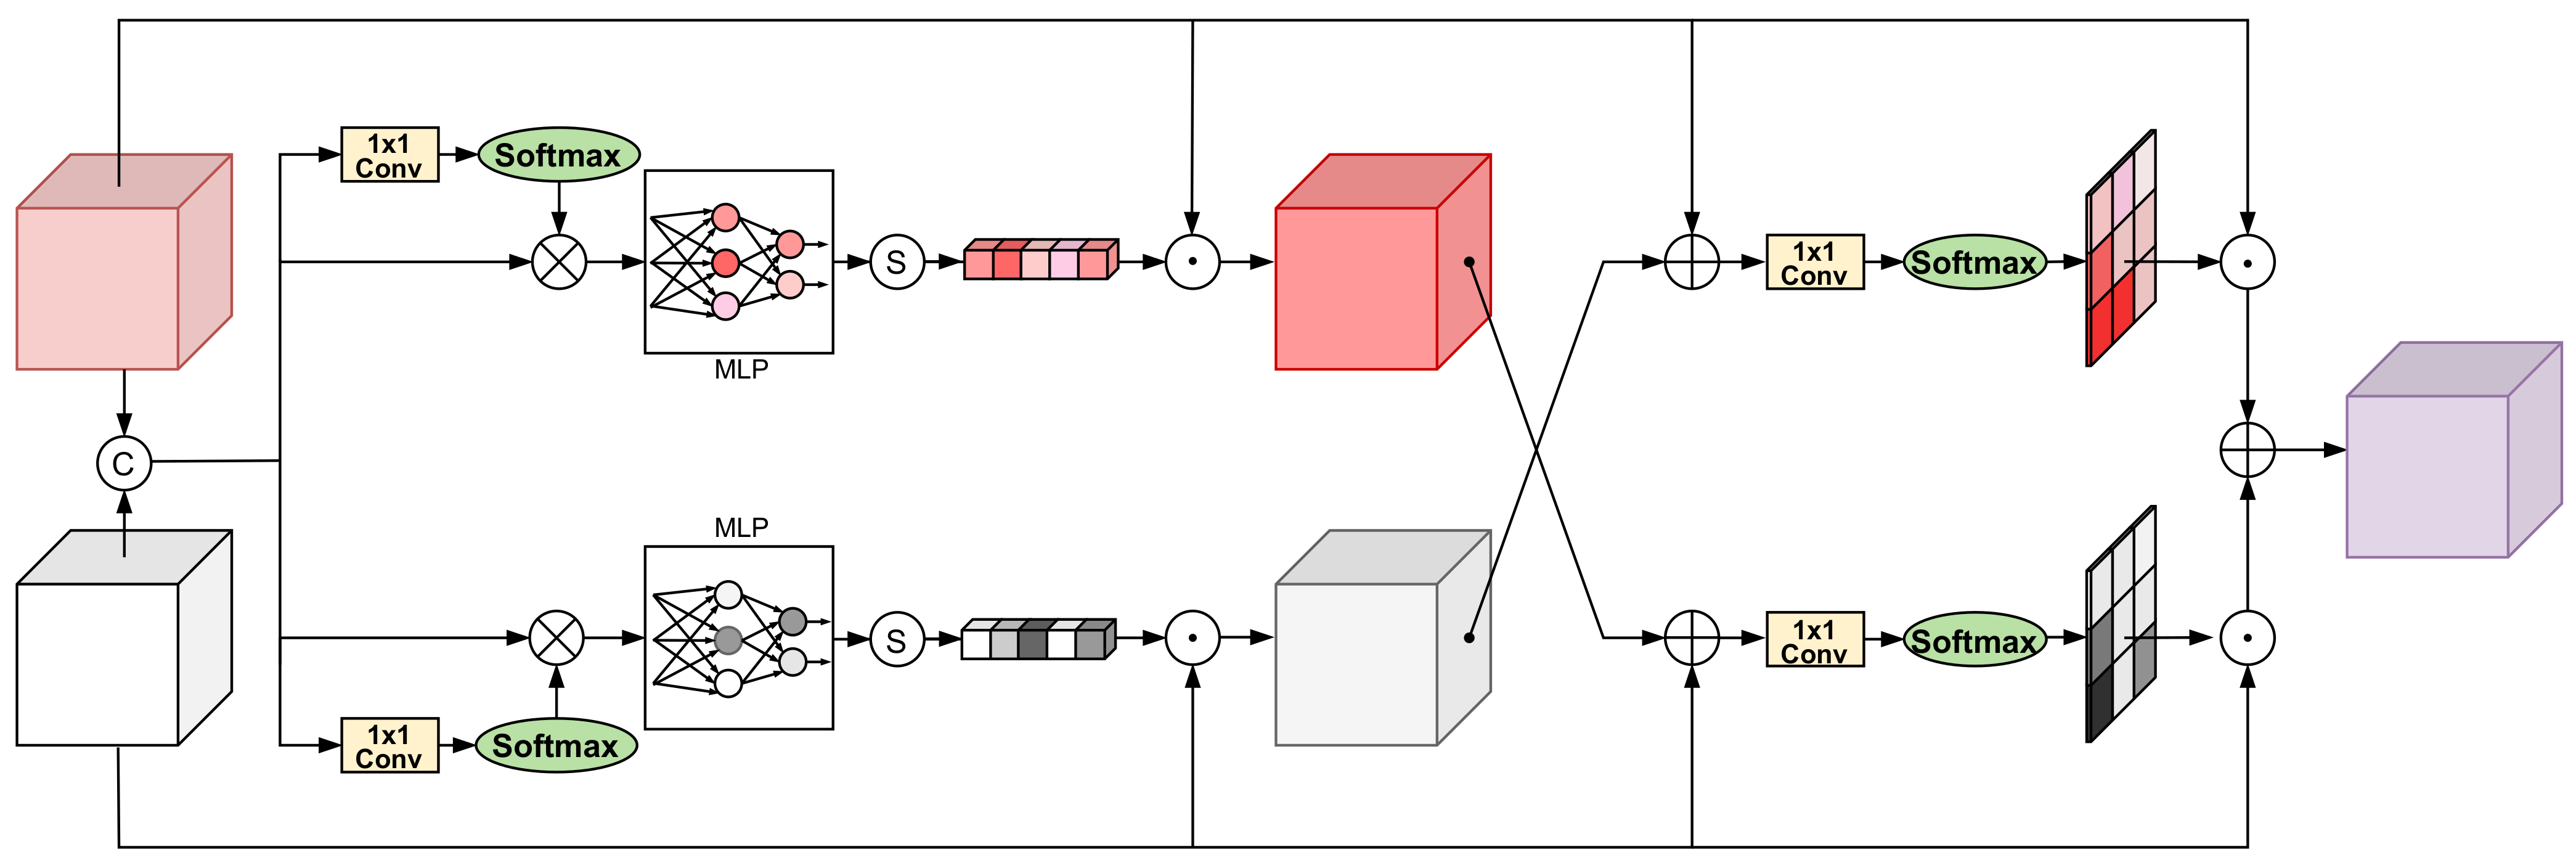
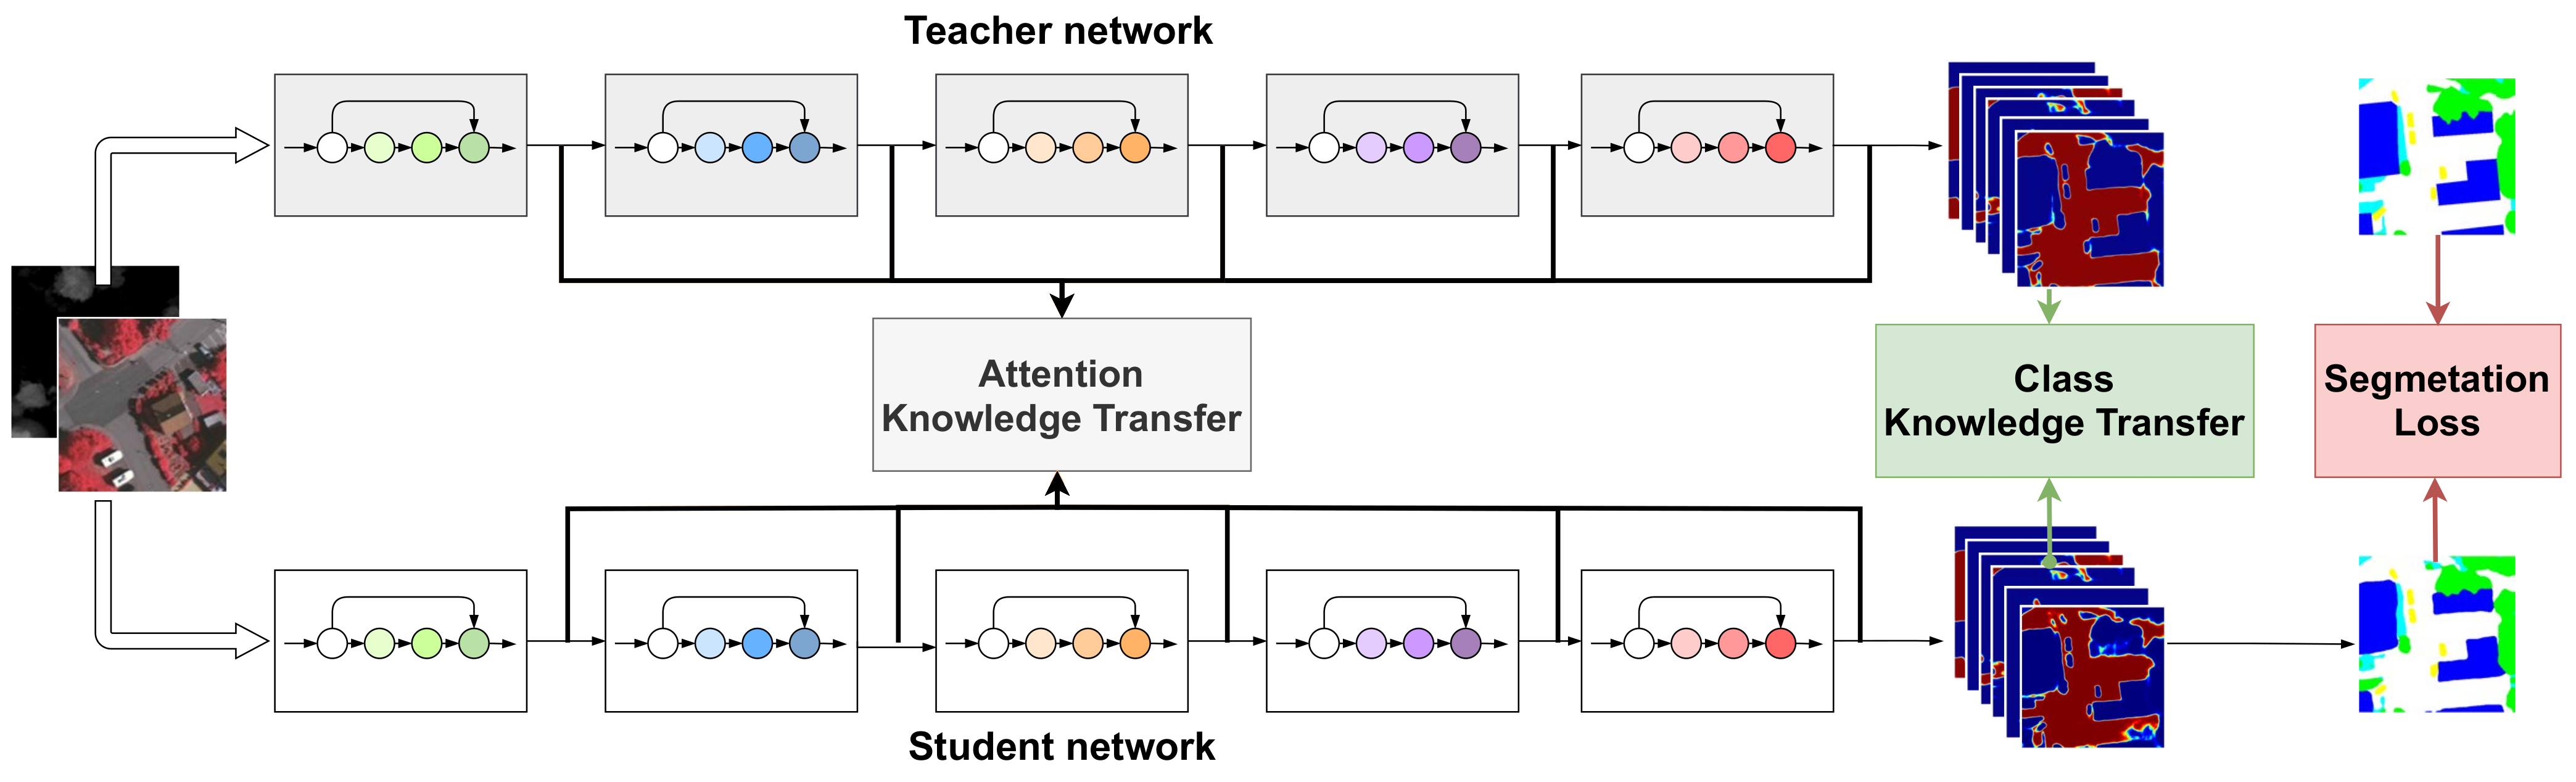
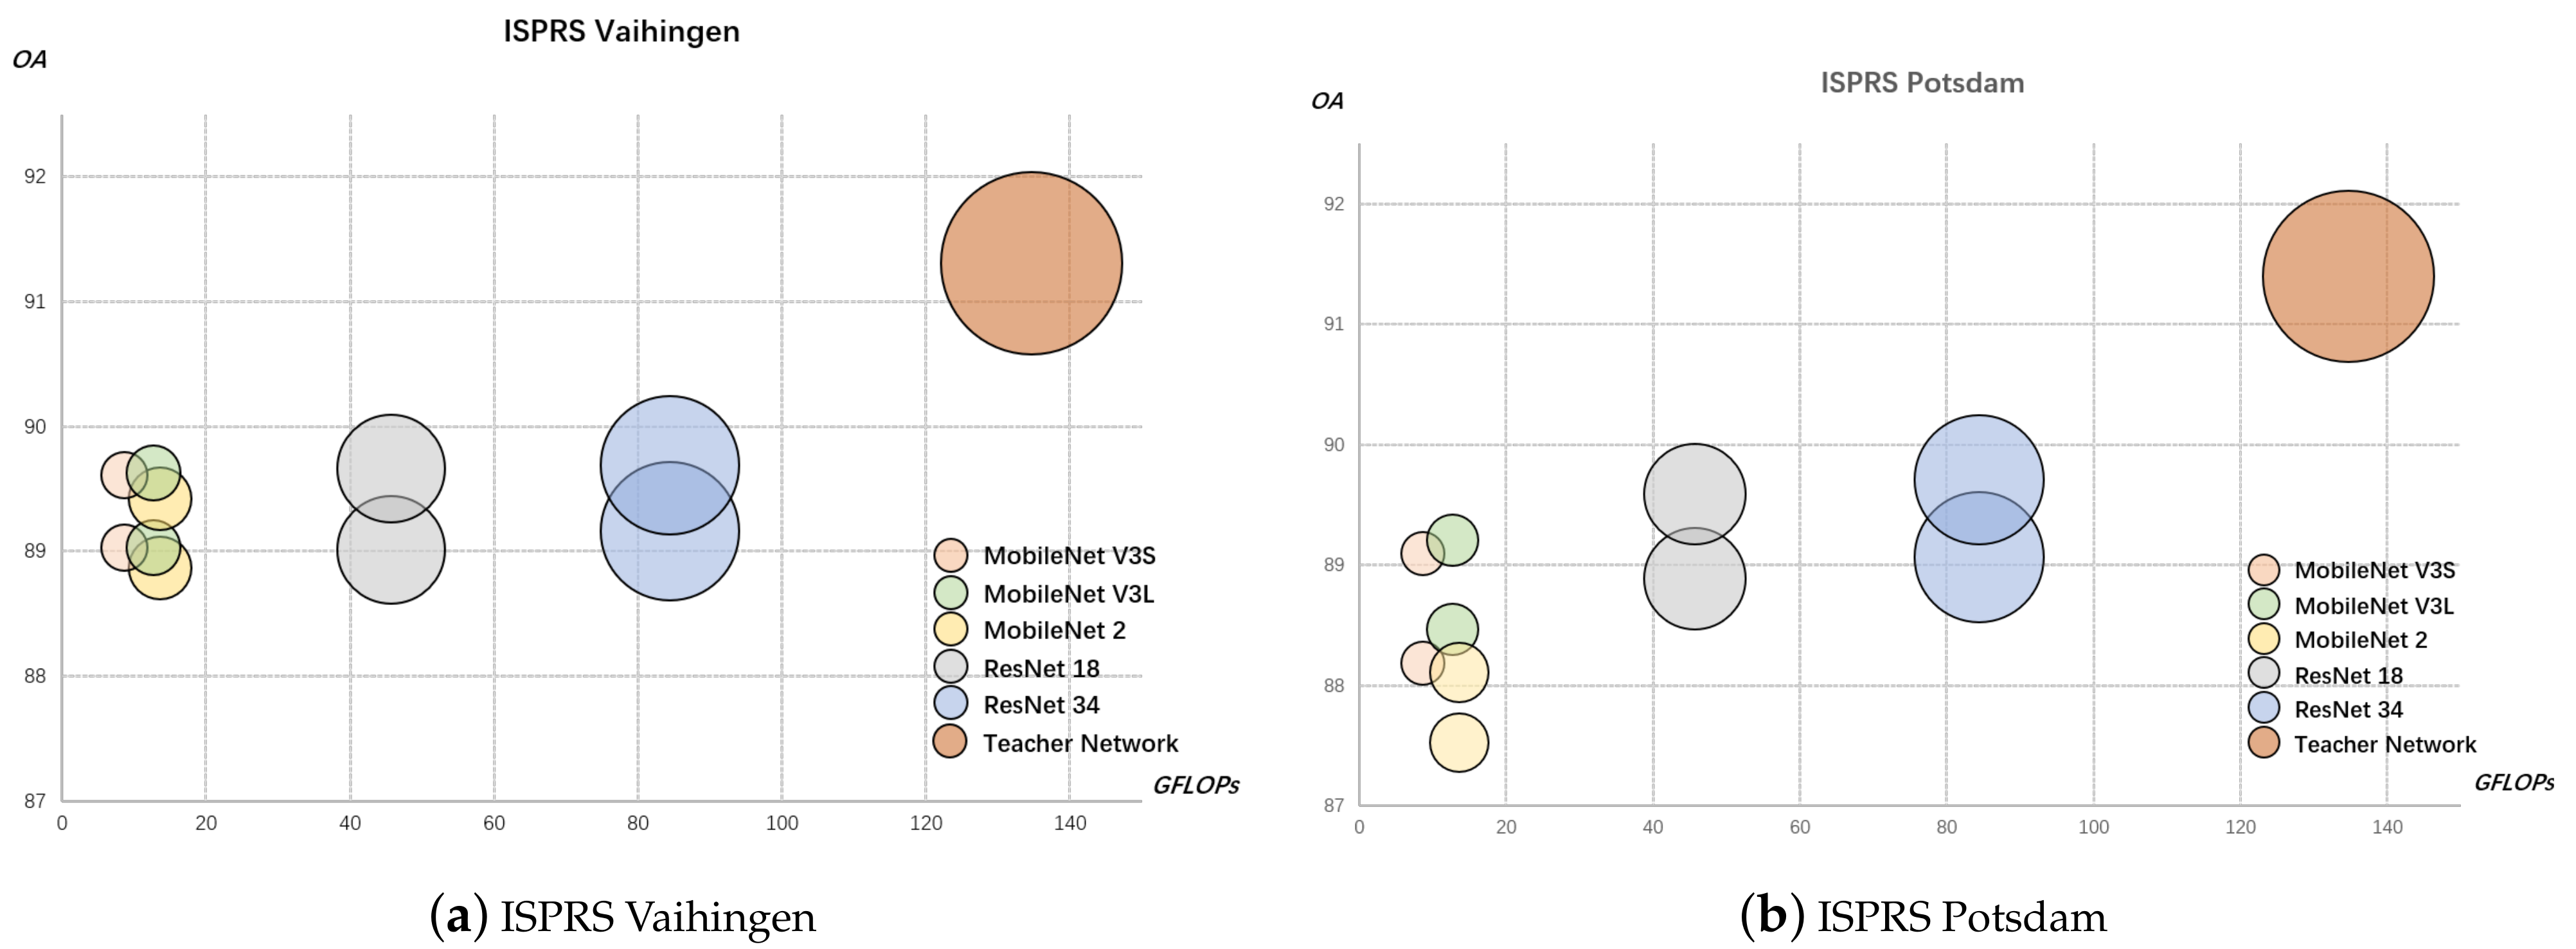
Semantic segmentation of multi-modal remote sensing images is an important branch of remote sensing image interpretation. Multi-modal data has been proven to provide rich complementary information to deal with complex scenes. In recent years, semantic segmentation based on deep learning methods has made remarkable achievements. It is common to simply concatenate multi-modal data or use parallel branches to extract multi-modal features separately. However, most existing works ignore the effects of noise and redundant features from different modalities, which may not lead to satisfactory results. On the one hand, existing networks do not learn the complementary information of different modalities and suppress the mutual interference between different modalities, which may lead to a decrease in segmentation accuracy. On the other hand, the introduction of multi-modal data greatly increases the running time of the pixel-level dense prediction. In this work, we propose an efficient C3Net that strikes a balance between speed and accuracy. More specifically, C3Net contains several backbones for extracting features of different modalities. Then, a plug-and-play module is designed to effectively recalibrate and aggregate multi-modal features. In order to reduce the number of model parameters while remaining the model performance, we redesign the semantic contextual extraction module based on the lightweight convolutional groups. Besides, a multi-level knowledge distillation strategy is proposed to improve the performance of the compact model. Experiments on ISPRS Vaihingen dataset demonstrate the superior performance of C3Net with 15× fewer FLOPs than the state-of-the-art baseline network while providing comparable overall accuracy.
Keywords: semantic segmentation; multi-modal learning; deep neural network design semantic segmentation; multi-modal learning; deep neural network design