


Abstract
Lean Six Sigma (LSS) improvement work increasingly depends on information-intensive activities such as document handling, data interpretation, reporting, and communication, yet current discussions of Artificial Intelligence in LSS remain largely technology-centric. This paper proposes a task-first, process-centric framework to support the governed application of Large Language Model (LLM)-enabled tools in such environments. The study makes three contributions: (i) a set of cross-functional organizational process types relevant to LSS practice, (ii) a functional classification of recurring tasks and LLM-enabled tool categories, and (iii) a dual-encoded task–tool matching matrix that separates alignment strength from interaction mode, distinguishing capability fit from governance logic. The framework is empirically anchored through two real-world industrial applications: customs document processing and shop-floor data digitalization and reporting. The results show that (i) stronger outcomes emerge when LLM-enabled support is matched to bounded, repetitive, and structured work, or when analytical support is built on stable and traceable data layers; (ii) operational value depends not only on technical capability, but on workflow embeddedness, data readiness, and human validation checkpoints. The framework also clarifies where support, augmentation, and partial automation are appropriate for different task classes and under explicit accountability constraints in information-intensive administrative work connected to improvement practice and governance.
1. Introduction
Lean Six Sigma (LSS) remains a widely adopted approach for operational improvement because it combines flow efficiency and waste elimination with a disciplined, data-driven cycle for variation reduction and control [1,2]. However, many LSS projects are now executed in data-intensive, digitally mediated environments where performance evidence is dispersed across systems, records, dashboards, and heterogeneous documentation. In this setting, the practical burden often shifts toward “information work,” namely, consolidating evidence, producing traceable documentation, and communicating decisions across stakeholders, under persistent constraints related to data availability, reliability, and sustainability of improvements [3,4]. A common response has been the integration of LSS with Industry 4.0 (I4.0) technologies to improve baselines, accelerate diagnosis, and enable more continuous monitoring across DMAIC (Define, Measure, Analyze, Improve, Control) phases, frequently discussed under LSS 4.0 [5,6,7,8]. While this literature provides valuable high-level frameworks and insights into barriers and enablers, it often remains technology-centric and offers limited guidance on how such support can be operationalized at the task level, where practitioners spend substantial effort in transversal organizational processes [5,6].
In parallel, large language models (LLMs) have rapidly expanded the scope of language-based support for organizational work, and their capabilities are increasingly embedded in tools that interact with documents, data environments, and workflow systems [9,10]. Yet, LSS settings amplify the need for defensibility and traceability, making well-known LLM limitations, including hallucination risk and variable reliability, particularly salient, and motivating grounded, governed use patterns rather than open-ended generation [11,12]. Research on human–LLM interaction also emphasizes that value and risk depend strongly on interaction modes and the placement of validation and escalation checkpoints [13,14].
This paper addresses the resulting translation gap, namely the move from generic statements about LLM capability to actionable guidance on which recurring LSS-relevant tasks should be supported, which functional categories of LLM-enabled tools are most appropriate, and which governance assumptions are required. This paper proposes a task-first, process-centric matching approach that classifies tasks by functional work type and aligns them to functional tool categories using a dual judgment that separates (i) alignment strength (capability fit) from (ii) interaction mode (support, augmentation, partial automation) consistent with LSS accountability [13,15,16]. The contributions are threefold: a transversal-process basis for LSS-relevant work, a functional classification of tasks and LLM-enabled tool categories, and a dual-encoded matching matrix and heatmap that make both fit and governance explicit. The framework is empirically anchored through two real-world application cases with baseline versus LLM-enabled comparisons. The proposed framework also specifies operational assignment rules for task classes, alignment-strength levels, and interaction modes, improving transparency and supporting replication by other researchers or practitioners.
Accordingly, the study is guided by two research questions:
- (RQ1) How can transversal LSS-relevant work be decomposed and classified at the task level to enable a defensible mapping between functional task classes and functional categories of LLM-enabled tools, while making governance assumptions explicit (fit versus interaction mode)?
- (RQ2) When this mapping is applied in real organizational workflows, what impact patterns emerge from baseline versus LLM-enabled execution in terms of time, workload, resources, and operational adequacy, and how do these patterns relate to the predicted alignment strength and interaction modes?
The remainder of the paper is structured as follows. Section 2 synthesizes background on LSS in data-intensive operations and the organizational implications of LLM-enabled tools. Section 3 details the method, including process selection, task decomposition, functional classifications, and the matching framework. Section 4 reports two real application case studies and presents the baseline versus LLM-enabled comparisons used to empirically anchor the matching logic and its boundary conditions, without assuming organization-wide adoption. Section 5 and Section 6 present the discussion, practical implications, limitations, and conclusions.
2. Literature Review
2.1. Lean Six Sigma in Contemporary, Data-Intensive Operations
LSS remains one of the most widely adopted improvement approaches because it combines (i) Lean’s emphasis on flow efficiency, waste elimination, and employee-driven continuous improvement (CI) with (ii) Six Sigma’s statistical discipline for variation reduction and process stabilization through DMAIC [1,17]. In practice, this combination allows organizations to pursue both efficiency and quality outcomes, using structured problem definition, measurement baselines, analytical validation, and standardized control plans [2].
Despite its maturity, the literature consistently reports recurring implementation and sustainability challenges. These challenges include limitations in data availability and reliability (especially when data are fragmented, manually recorded, or not traceable), lengthy and resource-intensive project cycles that can conflict with fast operational rhythms, and difficulties in sustaining gains without continuous monitoring and governance mechanisms [3,4]. As operations become more interconnected and variable, classical LSS tools may struggle to address greater data volume, velocity, and heterogeneity, particularly when improvement cycles depend on manual consolidation of dispersed information and expert-driven interpretation [6,18].
A major response to these limitations has been the increasing integration between LSS and I4.0 technologies. I4.0 capabilities such as IoT sensing, cyber-physical systems, cloud infrastructures, and advanced analytics have been framed as enabling higher-resolution baselines, more timely measurement, and improved diagnostic capability in the Measure and Analyze phases, while simulation and digital twins support safer and faster experimentation in Improve [5,6]. Conversely, Lean is frequently presented as providing essential operational discipline for digital transformation by stabilizing processes, reducing “digital waste,” and clarifying value flows before digitization initiatives scale [19,20].
Within this trajectory, “LSS 4.0” is often used to denote the extension of DMAIC with digital and AI-enabled capabilities, aiming to reduce manual burden, increase responsiveness, and strengthen closed-loop improvement and control through real-time monitoring and predictive insights [8,18]. Empirical and review studies also suggest that AI techniques can contribute across DMAIC, for example, natural language processing (NLP) to support Define through complaint analysis, sensor infrastructures can strengthen Measure, Machine Learning (ML) for pattern discovery in Analyze, simulation for Improve, and intelligent monitoring in Control [21,22].
2.2. Generative Artificial Intelligence and Large Language Models
AI has evolved from early symbolic approaches toward data-driven ML and deep learning (DL), with transformer-based foundation models enabling a rapid expansion of language and multimodal capabilities. Within this landscape, GenAI shifts emphasis from classification to content generation, with LLMs emerging as a dominant family of models for language understanding and generation [10]. The transformer architecture and large-scale self-supervised pretraining are commonly highlighted as key technical drivers of LLM performance in summarization, question answering, drafting, and instruction-following tasks [9,10].
Recent surveys classify LLMs along several axes, including architectural form (encoder-only, encoder–decoder, decoder-only), modality (text-only vs. multimodal LLMs), and specialization (general-purpose vs. domain-adapted models) [9,10]. In parallel, the literature increasingly emphasizes “agentic” directions, where LLM-centered systems are combined with planning, tool-use, memory, and workflow orchestration, enabling more autonomous interaction with digital environments [23,24]. For organizational settings, this is important because practical value often depends not on a standalone model but on how LLM capabilities are embedded into tools that connect to documents, datasets, APIs, and enterprise workflows. In operations and supply-chain contexts, recent work has also highlighted both the potential benefits and adoption challenges of GenAI and ChatGPT, reinforcing the need to connect model capabilities with operational governance and implementation conditions [25,26].
However, LLMs also exhibit limitations that are particularly salient in evidence-driven improvement contexts. The literature repeatedly notes hallucination risks (fluent but incorrect output), bias and uneven multilingual performance, limited interpretability and auditability, temporal staleness arising from static training corpora, and vulnerabilities such as prompt injection. These constraints motivate the use of grounding mechanisms. such as retrieval-augmented generation and knowledge integration, and stricter evaluation and governance practices when LLMs are used in operational decision support [11,27,28].
2.3. LLMs in LSS Workflows: Opportunities, Constraints, and the Gap Addressed by This Study
The practical complementarity between LLMs and LSS stems from the fact that a substantial share of LSS effort is knowledge-intensive and documentation-driven work. Improvement cycles routinely require transforming dispersed, unstructured information (operator notes, maintenance records, meeting minutes, audit comments, customer feedback) into structured artifacts that support analysis, reporting, and control. Because LLMs are particularly effective at synthesis, summarization, drafting, and reformatting, they are naturally positioned to reduce friction in these recurring tasks, especially where the deliverable is a standardized narrative or a template-bound report [9,10]. This positioning becomes even more relevant in LSS 4.0 settings, where process mining, IoT, and analytics infrastructures increase the volume and heterogeneity of contextual information that must be interpreted and communicated, suggesting a role for LLM-enabled acting as interfaces that translate mixed evidence into decision-support artifacts rather than replacing quantitative analytics [6,29].
At the same time, LSS places unusually strong demands on traceability and defensibility. Baselines, root-cause arguments, and control plans must remain auditable, and outputs that are not grounded in controlled inputs (datasets, approved documents, explicit templates) can introduce variation, incorrectness, or non-reproducible reasoning [12]. This makes well-known LLM limitations, such as hallucination risk and uneven reliability across tasks, particularly consequential in improvement contexts [11]. As a result, LLM-enabled support needs to be embedded in governed workflows that emphasize evidence linkage, constrained generation, for example, document-bound generation or retrieval-augmented setups, and explicit human validation checkpoints, rather than open-ended generation [12,13,14].
This highlights a translation gap in the current literature. LSS–I4.0 reviews provide strategic integration frames and enabling-technology perspectives but rarely resolve the task-level question practitioners face, which types of work should be supported, how they should be supported, and under which controls [5,6]. Conversely, LLM surveys and recent AI-augmented BPM contributions emphasize capabilities, process-aware systems, and application families, but typically do not anchor guidance in LSS-oriented task classification and accountability-driven improvement practice [10,30]. Addressing this gap motivates a task-first, process-centric approach that classifies organizational work by functional work type before mapping it to tool categories, consistent with emerging BPM-oriented discussions of LLM opportunities, challenges, and practitioner guidance [31]. This intermediate abstraction is consistent with established perspectives on information work and lifecycle reasoning, where task comparability requires grouping context-dependent activities into stable functional types (for example, acquisition, preparation, analysis, reporting), and it aligns with human–LLM interaction research showing that appropriate oversight depends on interaction mode and UI/UX framing [13,14,15,16].
3. Materials and Methods
3.1. Research Orientation and Methodological Framework
This study adopts a process-centric, task-level analytical orientation to examine how LLMs and LLM-enabled tools may support, enhance, or partially automate recurring organizational work within LSS contexts. The focus is not on evaluating tools as technologies, but on analyzing organizational processes, their constituent activities, and the tasks performed by individuals, together with the cognitive and informational demands associated with those tasks.
The methodological scope is conceptual and analytical, not technical or implementation-oriented. The objective is to develop a structured understanding of where LLM-based capabilities can realistically contribute to work as it is currently performed, rather than to design, benchmark, or compare specific AI systems. Transferability is treated as a design principle through the adoption of a task-level perspective, intended to generalize across organizational contexts and industries. Human judgment and accountability remain central, with LLMs treated as support elements rather than autonomous decision-makers.
3.1.1. Distinction Between LLMs and LLM-Enabled Tools
A key methodological principle is the explicit distinction between LLMs as foundational models and LLM-enabled tools as organizational instantiations of those models. LLMs provide language and reasoning capabilities (for example, text generation, summarization, contextual reasoning) but do not, by themselves, interact with organizational processes or information systems. LLM-enabled tools embed or connect LLMs to enterprise software, databases, APIs, and user interfaces, translating model capabilities into concrete organizational functions (for example, document generation, workflow orchestration, data analysis support, decision assistance). The same underlying capability may therefore be operationalized differently across tools and organizational contexts.
Maintaining this distinction helps separate what the model can generate and what the organization can operationalize in practice. Accordingly, tools are referenced only to illustrate how functional capabilities are instantiated in practice, not as objects of comparative performance assessment.
3.1.2. Analytical Structure of the Study
The analysis follows a progressive structure that moves from existing organizational work toward governed technological support. First, transversal organizational processes are selected and decomposed into activities and tasks without assuming AI intervention. Second, the resulting tasks are classified according to their dominant functional work type. Third, LLM capabilities and categories of LLM-enabled tools are examined from a functional standpoint, with tools introduced as illustrative implementations of functional roles. Finally, task classes and tool categories are matched through a dual judgment that separates alignment strength from interaction mode. This sequence provides the methodological bridge between the research questions, the matching framework, and the case-based evaluation, as summarized in Figure 1.
Figure 1.
Analytical chain linking framework construction and case-based evaluation.
This sequencing keeps the analysis anchored in work practices, while making explicit the assumptions of supervision and accountability that are consistent with human-in-the-loop interaction models discussed in the broader LLM interaction literature [13].
3.2. Transversal Organizational Processes in the Context of LSS
This section establishes the process basis for the subsequent task-level analysis. Four transversal organizational processes are selected to represent recurring organizational work that is sufficiently varied to provide analytical breadth, while remaining comparable at the task level.
3.2.1. Identification of Transversal Organizational Processes and Selection Criteria
Across sectors (manufacturing, services, healthcare, logistics, public sector), organizations rely on a set of processes that are largely independent of sector-specific production technologies and underpin coordination, control, compliance, and decision-making. These are defined here as transversal organizational processes, emphasizing cross-functional and cross-industry scope and suitability for comparative task-level analysis.
Process selection follows three criteria:
- Cross-context, occurrence, and structural comparability: the process should occur across different organizational contexts with broadly comparable purpose and structure, enabling analysis to focus on task characteristics rather than sector-specific details.
- Information-intensive work: the process should rely predominantly on creating, interpreting, validating, transforming, and communicating information in textual or structured forms, where language- and reasoning-based technologies are most relevant.
- Relevance to LSS goals and DMAIC: the process should support core LSS practices (measurement, analysis, standardization, control) and reflect known practical constraints of traditional LSS work, such as manual data handling, fragmented documentation, and delayed feedback.
3.2.2. Selected Transversal Process Types
Based on these criteria, four process types are selected for analysis and defined at a high level (Table 1).
Table 1.
Transversal Organizational Process Types Used for Task-Level Analysis.
- Process-Type 1: Team Management and Systematic Performance AnalysisFocuses on team coordination and periodic performance review, including monitoring indicators, defining tasks, and registering operational activities in support of continuous improvement.
- Process-Type 2: Operational Data Analysis and Performance MonitoringCenters on interpreting operational data to assess performance, identify deviations and trends, support root-cause analysis, and inform improvement actions and decisions.
- Process-Type 3: Operational Reporting and Information CommunicationCovers the preparation, consolidation, and communication of operational information and performance results via reports, dashboards, and structured documentation for internal stakeholders and management.
- Process-Type 4: Regulatory and Procedural Compliance ManagementFocuses on monitoring regulatory updates, assessing their operational impact, updating internal procedures, communicating changes to stakeholders, and maintaining compliance records and traceability.
To support systematic decomposition, the study adopts a hierarchical representation in which processes are structured end-to-end flows composed of activities [32], and activities are decomposed into ordered tasks, which are treated as standardized when they involve the same dominant action and information handling, abstracting from local terminology and roles. This decomposition logic is consistent with the conceptual layering used in BPMN 2.0.2 [32].
3.3. Process Decomposition and Task Standardization
This study operationalizes a process-centric unit of analysis by decomposing each transversal process-type into a hierarchical structure of process → activities → tasks. The decomposition is intentionally analytical and non-prescriptive; it does not aim to capture all tasks that may exist in a given organization, nor does it assume that the resulting workflows are optimal or especially suited for LLM-based support. Instead, it provides a coherent representation of work that is “sufficiently rich” to enable systematic task classification and later assessment of where LLM-enabled tools may contribute.
A process is defined as an end-to-end organizational flow designed to achieve a specific operational goal and composed of interrelated activities. The activities group coordinated sequences of tasks that share a common informational context and execution logic, enabling comparative analysis across contexts. Finally, tasks are defined as ordered, step-by-step units of work within the activity scope.
For analytical clarity, Process-Type 1 is used in this document as the detailed exemplar for task-level decomposition (Figure 2), while the remaining process types follow the same methodological logic and are presented in Appendix A (Figure A1, Figure A2 and Figure A3). Process-Type 1 (Team Management and Systematic Performance Analysis) encompasses the coordinated management of team activities and the structured monitoring of operational performance. It includes task definition and allocation, the systematic collection and registration of operational data generated during daily activities, and the periodic review and analysis of performance indicators to assess progress and detect deviations. Structured performance discussions and documentation activities ensure traceability and alignment with CI goals. Overall, the process integrates coordination, monitoring, analysis, and feedback mechanisms within a recurring management cycle. This decomposition provides the basis for the task-level analysis and functional classification presented in the following sections.
Figure 2.
Process-Type 1—Process, Activity, and Task Decomposition.
To support cross-context comparability, tasks are treated as standardized whenever they involve the same dominant action and information handling, even if they appear in different activities with contextual variations. Standardization is performed by abstracting from local terminology, organizational roles, and structural arrangements, while preserving a level of granularity that captures meaningful differences in the nature of work performed.
Although the decomposition is not derived from a prescriptive research standard, its hierarchical structure is consistent with the conceptual layering described in BPMN 2.0.2 [32], where processes can be represented through successive abstractions into activities and tasks. This alignment supports structural validity for representing organizational workflows using process decomposition.
3.4. Functional Task Classification Framework
3.4.1. Motivation for Task-Level Abstraction
While process decomposition provides a detailed description of how work is performed, it does not automatically enable systematic comparison across processes or organizations because operational tasks can be numerous, context-dependent, and expressed using local terminology. To address this limitation, the methodology introduces an additional abstraction layer that groups tasks according to the dominant type of work they involve, rather than the specific operational context. This enables identification of recurring patterns of work across processes while maintaining a clear link to actual execution.
Within the scope of LLM applicability analysis, this abstraction is essential because LLMs do not operate on “organizational tasks” as situated in a specific workflow; they operate on underlying functional activities such as language processing, interpretation, reasoning, and communication. A functional task abstraction, therefore, creates the conceptual bridge between organizational work and technological capability.
3.4.2. Rationale and Conceptual Grounding
Several established approaches were considered as potential bases for task classification, including process modeling standards (for example, BPMN), CRUD-based data operation models, and records and document management standards (for example, ISO 15489 [33] and ISO 16175 [34]). These frameworks are well-suited to system design, execution modeling, or governance, but they do not provide a unified task-level abstraction centered on the dominant cognitive and communicative nature of administrative work. They emphasize control-flow semantics or data state transitions rather than the type of human activity performed in each task [32,35,36,37].
By contrast, analytics lifecycle models such as CRISP-DM and broader data lifecycle concepts distinguish stages according to interaction modes with information (acquisition, preparation, analysis, reporting) [15,16]. In this research, the stage-based logic is adapted from system-level workflows to the task level by shifting the focus to the dominant type of human work performed within each task.
3.4.3. Definition of Functional Task Categories (Classes A–E)
Following this rationale, five functional task categories are defined to enable technology-independent analysis of organizational work (Table 2): Class A, Document and Content Generation, covers the creation or revision of textual and documentary artefacts; Class B, Data Analysis and Interpretation, covers the extraction of meaning from structured or semi-structured evidence; Class C, Communication and Information Dissemination, covers the adaptation and transmission of information to stakeholders; Class D, Data Collection and Recording, covers the capture of operational or external inputs into structured records; and Class E, Data Maintenance and Information Management, covers the validation, organization, updating, and preservation of records and datasets.
Table 2.
Operational criteria used for assigning standardized tasks to functional task classes.
Collectively, these categories cover principal modes of interaction with information in administrative and information-intensive work, translating lifecycle stages into categories of human task execution. This mapping is explicitly aligned with the adapted stage-based logic derived from CRISP-DM and the data life cycle [15,16].
To make the classification procedure more transparent and reproducible, Table 2 summarizes the operational decision criteria used to assign each standardized task to one dominant functional class. The table does not replace the conceptual definitions above. Rather, it specifies the observable task features used during classification.
3.4.4. Task-to-Class Assignment Procedure
Each standardized task obtained from the process decomposition is assigned to one functional category (Classes A–E) using the criteria summarized in Table 2. The assignment was based on the dominant action performed in the task, the main information object being transformed, and the output that defines task completion. This rule was applied independently of the tool used, the organizational role executing the task, or the local terminology used in the case context.
A single-label rule was used for analytical clarity because the subsequent matching matrix requires each task to be represented by its dominant functional demand. Nevertheless, this does not imply that real organizational tasks are cognitively simple. Some tasks combine secondary actions, such as collecting information and then summarizing it. In such cases, the assigned class corresponds to the action that defines the task’s primary purpose and deliverable. This choice makes the classification reproducible while preserving a manageable level of abstraction for cross-process comparison.
The resulting classification is reported visually by overlaying the assigned functional categories onto the decomposed process structure for the exemplar process (Process-Type 1) in Figure 3. It makes explicit how different work types are distributed across activities and shows that organizational processes are heterogeneous at the task level, combining recurring cycles of collection, interpretation, documentation, and communication rather than progressing through isolated, single-function stages. In Process-Type 1 specifically, the overlay highlights a dominant concentration of interpretation-oriented tasks (consistent with the process goal of systematic performance review), alongside recurring documentation, coordination, collection, and data maintenance tasks that appear across multiple activities.
Figure 3.
Functional classification of tasks in Process-Type 1 (Color coding indicates functional task categories).
To avoid tying the logic too closely to a single exemplar, the same classification procedure is applied to the remaining transversal processes, and the corresponding overlays are reported in Appendix A (Figure A1, Figure A2 and Figure A3). These supplementary overlays confirm that the recurrence of mixed functional task types is not specific to Process-Type 1, supporting the use of functional categories as a stable abstraction for cross-process analysis and subsequent task–tool matching.
3.5. Functional Types of LLM-Enabled Tools
3.5.1. Rationale for a Functional LLM-Enabled Tool Classification
Building on the task-level decomposition and functional task classification (Section 3.3 and Section 3.4), this study introduces an analytical, non-prescriptive classification of LLM-enabled tools relevant to organizational contexts.
Prior work offers useful classifications of LLM-based systems, including taxonomies of human–LLM interaction modes and system-level discussions associated with retrieval-augmented generation (RAG). However, these perspectives typically do not provide an explicit link between tool types and the functional roles performed within organizational tasks, which is the level of analysis required for disciplined LSS integration [12,13].
Accordingly, tools are classified here by the primary type of work they enable, rather than by technical implementation (for example, model family, deployment modality, or API architecture). When a tool supports multiple functions, classification is based on the capability most central to its typical deployment context.
3.5.2. Functional Tool Categories
Five functional categories are used to represent how LLM capabilities are operationalized in organizational settings: general-purpose LLM interfaces; text and document processing tools; data analysis and decision support tools; automation and orchestration tools; and multimodal and perception-oriented tools. These categories distinguish the dominant role played by the tool in the workflow, ranging from broad conversational support to structured document handling, analytical interpretation, workflow execution, and extraction from non-textual inputs. Table 3 summarizes the main features of each functional tool category. Figure A4 (in Appendix A) provides an expanded functional characterization (organizational role, supported functions, representative examples) to document the criteria used for this categorization.
Table 3.
Illustrative Examples of LLM-Enabled Tools by Functional Category (tools’ releases available until February 2026).
These categories should not be interpreted as mutually exclusive. Many contemporary solutions combine components across categories, for example, a general-purpose interface used for drafting, a document tool used for standardization, and orchestration used for routing and execution. The classification is therefore intended as a functional abstraction that captures the dominant role a tool plays in practice, rather than as a rigid taxonomy. Figure 4 positions the five LLM-enabled tool categories along two practical dimensions, degree of workflow embeddedness and degree of input/output structure, providing a compact bridge to the task–tool matching logic developed in Section 3.6.
Figure 4.
Conceptual positioning of LLM-enabled tool categories by workflow embeddedness and input/output structure.
3.6. Task–Tool Matching Framework and Output
3.6.1. Purpose and Design Principle
This section defines the matching logic that links the functional task classes (A–E) to the functional categories of LLM-enabled tools introduced in Section 3.5. The goal is to produce a decision-oriented representation of where LLM-enabled tools are plausibly useful in LSS-related work, while avoiding a drift toward tool benchmarking or vendor comparison. The framework is explicitly task-level and process-centric, because it is built on standardized tasks extracted from transversal process types (Section 3.2, Section 3.3 and Section 3.4), not on generic “use cases”.
3.6.2. Core Assumptions for LSS-Compatible Use
The matching framework is constructed under three assumptions that reflect typical LSS requirements for traceability, defensibility, and control.
First, human accountability cannot be transferred to the tool. LLM-enabled tools may draft, assist, or execute well-bounded subtasks, but humans remain responsible for validation, acceptance, and exception handling, particularly when outputs influence decisions, compliance, quality, or safety. This assumption is consistent with human–LLM interaction modes that emphasize oversight and review as a default in organizational settings [13,14].
Second, evidence linkage and grounding are necessary whenever outputs must be justified. When tasks depend on organizational facts, datasets, or approved documents, the workflow must constrain LLM outputs to controlled inputs, for example, via retrieval-augmented setups, document-bound generation, or other grounding mechanisms, rather than relying on open-ended generation [12].
Third, tools are rarely used in isolation. In practice, value often emerges from sequencing tool roles across a workflow, for example, drafting in a general-purpose interface, standardizing in a document tool, then routing through orchestration. The matching, therefore, supports both single-tool and multi-tool configurations, provided checkpoints remain explicit.
3.6.3. Interaction Mode as a Governance Construct
The first classification assigned to each cell is the interaction mode, denoted , which describes the governance pattern that is appropriate when applying the tool category to the task class . It captures allocation of agency, validation burden, and where control points should exist. Three modes are used.
Support (S) denotes assistive use, where the tool reduces effort (drafting, summarizing, reformatting, querying) but does not change ownership of reasoning or decision-making. This is typically the most appropriate default when tasks are contextual, ambiguous, or require evidentiary justification [18].
Augmentation (A) denotes a stronger contribution, where the tool substantively improves consistency, clarity, or analytical synthesis, while the human still validates correctness and retains final authority. This is common when tools operate within structured constraints, for example, templates, controlled corpora, or bounded datasets [12,38].
Partial automation (P) denotes that a well-defined subtask can be executed automatically under standardized conditions, typically when inputs and outputs are structured, acceptance criteria are explicit, and exception handling is designed. Even here, humans remain responsible for monitoring and handling edge cases [29]. “Partial automation” is therefore an interaction mode, not a claim of superiority, and it can be inappropriate even when fit is high if governance conditions are not met.
In a small number of pairings, the interaction mode can be conditional, moving from Support to Augmentation as grounding and controls mature. In such cases, the matrix can show “S/A” to indicate that the default is supportive, with augmentation possible under stronger constraints [13,14].
To reduce ambiguity in assigning interaction modes, the mode was selected according to the level of agency delegated to the tool, the degree of human validation required, and the consequences of an erroneous output. The decision rules used in the matching exercise are summarized in Table 4 together with the alignment-strength criteria.
Table 4.
Scoring rubric for alignment strength and interaction mode.
3.6.4. Alignment Strength as a Capability-Fit Construct
The second classification assigned to each cell is alignment strength, denoted , which captures the intensity of matching between the dominant work type of task class and the dominant functional capability of tool category . Alignment strength is independent of interaction mode: a pairing can have high fit but still require a conservative mode if accountability risk is high.
Alignment strength was encoded on a four-level ordinal scale, from Limited (0) to Strong fit (3), using the decision rules presented in Table 4. The score reflects the degree to which the dominant capability of a tool category corresponds to the dominant work type of a task class. A low score does not mean that the tool is unusable; rather, it means that the tool should not be treated as the primary mechanism for that task class. Conversely, a high score indicates structural fit, but does not imply autonomous use, because deployment mode remains governed by accountability, evidence linkage, and validation requirements.
This separation is the key methodological refinement: alignment strength measures fit, whereas interaction mode specifies safe deployment logic. Keeping both avoids the common error of treating “automation” as if it were a stronger outcome than “augmentation”.
3.6.5. Matrix Construction and Visual Encoding
The matching matrix was constructed by evaluating each pairing between functional task classes (A–E) and functional tool categories using the decision rules in Table 4. Each cell was assigned two independent judgments: alignment strength, which represents capability fit, and default interaction mode, which represents the appropriate governance pattern for use in an LSS context. The assignment was based on the dominant work type of the task class, the primary capability of the tool category, the expected structure of inputs and outputs, and the level of human validation required.
The full matrix, using qualitative descriptors, is presented in the heatmap of Figure 5. In this visual encoding, cell color represents alignment strength, while cell text reports the default interaction mode. This dual encoding makes explicit that technical suitability and governance mode are related but not equivalent.
Figure 5.
Matching Between Task Classes and Functional Categories of LLM-Enabled Tools.
Once both dimensions have been assigned to each pairing, the matrix provides a compact, task-level view of where LLM-enabled tool categories are structurally well aligned with recurring work types and what governance pattern is appropriate in an LSS context. Two patterns dominate. First, alignment strength is highest when the tool category is designed around the dominant work type of the task class, content, and document tools for Class A, data insight tools for Class B, and orchestration for Classes D and E, with multimodal tools becoming strong only where data capture depends on non-text artifacts (Class D). Second, interaction modes reflect accountability rather than intensity: Augmentation is the default, where outputs remain interpretive or communicative and must be defensible, whereas Partial Automation is reserved for bounded, rule-driven subtasks with explicit acceptance criteria and exception handling. General-purpose interfaces tend to sit between these extremes, offering broad Support that can shift toward Augmentation when grounding, templates, and checkpointed review are enforced.
Taken together, the matching matrix and heatmap provide a compact, task-level rationale for selecting LLM-enabled tool categories and for specifying how they should be embedded in LSS-relevant work. Importantly, the matrix is not presented as a tool benchmark, but as an evidence-informed mapping that makes two dimensions explicit: the strength of alignment between a task class and a tool category, and the interaction mode that preserves accountability under LSS constraints. This dual encoding clarifies where LLM-enabled support is structurally plausible and where it is likely to be incidental or offset by supervision and rework, particularly when outputs must remain traceable and defensible [11,12,13]. Building on this rationale, Section 4 reports two real-world application cases in which the matrix is used to select tool configurations, describe baseline execution, and compare baseline versus LLM-enabled performance in terms of time, resource burden, and operational adequacy.
However, structural alignment alone is not sufficient for operational adoption in LSS contexts. Because outputs must remain traceable, reviewable, and compatible with explicit accountability requirements, the matching logic should be complemented by a governance and evaluation protocol, presented in the following section.
3.7. Governance and Evaluation Protocol for LSS-Compatible LLM Use
The task–tool matching framework clarifies where LLM-enabled tool categories are structurally aligned with functional task classes. However, in LSS-related work, alignment is not sufficient for operational adoption. Because LSS practice depends on traceability, evidence-based reasoning, and clear accountability, LLM-enabled support must also be embedded in governed workflows. This section, therefore, complements the matching matrix by proposing a governance and evaluation protocol that specifies how LLM-enabled tasks should be bounded, reviewed, and monitored.
The protocol is built on three assumptions. First, responsibility for process outcomes remains human and organizational, even when a task is supported, augmented, or partially automated by an LLM-enabled tool. Second, outputs that influence operational records, reporting, compliance, or improvement decisions must remain linked to controlled inputs, approved data sources, and explicit validation checkpoints. Third, performance evaluation should not be limited to time or cost reduction, because LLM-enabled workflows may reduce manual effort while increasing the importance of validation, exception handling, and oversight [11,12,13,39].
From an organizational perspective, five roles should be distinguished. A process owner or LSS lead defines the workflow scope, task boundaries, acceptance criteria, and permitted level of tool autonomy. The domain expert or reviewer validates outputs that require contextual knowledge, compliance interpretation, or improvement judgment. The tool developer or analyst configures prompts, templates, data connections, workflows, logs, and version-control mechanisms. Users and operators interact with the workflow in practice and identify anomalies or exceptions. The data or system owner ensures data quality, access control, security, and consistency of the information sources used by the tool. Making these roles explicit helps avoid diffusion of responsibility and clarifies who validates outputs and who handles exceptions.
The operational sequence of the protocol follows seven steps, as synthesized in Figure 6. First, the workflow scope, task boundaries, and acceptance criteria are defined. Second, the appropriate LLM-enabled tool category and interaction mode are selected using the task–tool matching logic presented in Section 3.6. Third, inputs, data sources, and access permissions are constrained so that outputs are grounded in controlled information rather than open-ended generation. Fourth, the LLM-enabled task is executed within the workflow. Fifth, the output is checked against validation criteria such as completeness, correctness, format conformity, and traceability. Sixth, low-confidence, incomplete, ambiguous, or non-compliant outputs are routed to human review. Seventh, approved outputs are logged, monitored, and periodically revalidated, especially when prompts, models, data sources, or connected systems change.
Figure 6.
LSS-compatible governance protocol for LLM-enabled workflow support.
This protocol also broadens the evaluation logic used in LLM-enabled process improvement. Efficiency remains relevant and can be assessed through time, HITL effort, and cost. However, additional dimensions are needed to assess whether the workflow remains compatible with LSS requirements. Quality refers to the correctness and consistency of outputs. Governance refers to traceability, auditability, and compliance. Risk refers to hallucination exposure, privacy, security, and inappropriate reliance on generated outputs. Sustainability refers to maintenance, retraining, prompt or workflow updates, and version control. These dimensions are not intended to replace quantitative time and cost indicators, but to contextualize them and prevent efficiency gains from being interpreted independently of operational robustness [40].
Overall, the governance protocol reinforces that operational value in LSS contexts depends not only on model capability, but on workflow design. LLM-enabled tools are most defensible when their use is bounded by clear task definitions, controlled inputs, explicit review points, exception-handling rules, and continuous monitoring. This governance logic is used in Section 4 to interpret the two case applications, particularly the distinction between governed partial automation in document-to-record workflows and human-validated augmentation in analytical and reporting workflows.
4. Application Case Studies and Results
This section reports two real-world industrial application cases used to examine how the framework developed in Section 3 can be translated into concrete workflow redesign and measurable operational impact. In both cases, the task–tool matching matrix (Figure 5) is used to justify the selection of LLM-enabled tool categories and interaction modes, while the governance and evaluation protocol introduced in Section 3.7 is used to interpret validation checkpoints, role allocation, exception handling, and performance implications. Tool use is therefore analyzed under explicit human accountability assumptions consistent with LSS practice [13,14].
The empirical logic is deliberately bounded: each case begins with a baseline workflow description and information on execution time and resource burden, then an LLM-enabled approach is specified and applied. Performance is first assessed through comparative estimates of time, workload, and cost, and then complemented in the cross-case synthesis through additional evaluation dimensions related to quality, traceability, governance, risk, and sustainability of use. These comparisons should be read as evidence-based operational estimates anchored in the case material, not as causal estimates of organization-wide adoption or as statistically generalizable results.
For each approach, development began by defining the workflow scope, task boundaries, input and output schemas, and acceptance criteria, including completeness, correctness, and traceability. The case evidence combined workflow mapping, user inputs, observed or reconstructed activity sequences, document or record volumes, implementation effort, and offline validation using representative examples. Validation combined component-level checks, for extraction, normalization, calculation, and reporting, with end-to-end trials on representative cases, using error logging, documented iteration, and human review checkpoints. This common validation logic was applied in both case studies and is important because it reinforces that the results reflect governed LLM-enabled support rather than unconstrained generation [39].
Because the cases were not designed as controlled experiments with repeated baseline and intervention observations, statistical significance testing was not applied. Applying inferential statistics to reconstructed or workflow-estimate data would risk creating a misleading impression of precision. The results are therefore interpreted as operational estimates under stated assumptions, while the limitations and future research agenda identify the need for longitudinal measurement, audit-log analysis, repeated observations, and controlled or quasi-controlled study designs.
Table A1, in Appendix A, summarizes the technical configuration of the four LLM-enabled approaches, including the dominant tool setup, grounding mechanism, workflow integration, validation logic, and main integration constraints. The table is intended to support transparency and replicability without shifting the paper toward vendor benchmarking. Across the four approaches, no configuration relies on open-ended LLM generation as the sole source of operational information. In all cases, outputs are constrained by source documents, structured datasets, predefined fields, dashboard indicators, templates, or human validation. This design choice is consistent with the governance logic introduced in Section 3.7 and with the paper’s emphasis on LSS-compatible accountability.
4.1. Oil Refinery Case Study: Customs Document Processing
The first case concerns the Logistics and Customs Management team of an oil refinery, focusing on the workflow through which inbound road-freight documentation, received by email as CMR files in PDF format, is interpreted and consolidated into a structured operational registry maintained in Excel. The baseline workflow is sequential and manual: document reception, opening and reading, field identification, transcription into the registry, verification, and archiving. Based on the revised case-study results, the workflow handles approximately 15 documents per day, equivalent to about 330 documents per month.
The baseline values for this case were derived from the mapped document-processing sequence, the reported document volume, and the estimated time required for document reading, field identification, transcription, verification, and clarification of inconsistent or incomplete CMR information. The resulting values should therefore be interpreted as operational workflow estimates rather than as repeated time-study measurements. This distinction is important because the case is intended to assess the plausibility and practical effect of governed LLM-enabled support in a bounded document-to-record workflow, not to provide a statistically generalizable estimate of customs-processing performance.
At the task level, this case is dominated by Class D and Class E work, since the operational core lies in the capture, validation, and maintenance of records generated from external documents. Within the taxonomy proposed in this study, this workflow is most closely aligned with Process-Type 2 characteristics when discrepancies require structured verification and data-quality control. It also exhibits some Process-Type 4 characteristics, given its emphasis on document validation, traceability, and maintenance of compliance-relevant records. This makes it a suitable case for examining whether strong-fit tool categories, namely multimodal extraction, orchestration, and controlled LLM support, can reduce repetitive effort without removing human accountability.
The baseline workflow (Figure 7) shows a clear concentration of effort in repetitive interpretation, transcription, and verification activities. The revised results indicate a total baseline processing time of 15 min per document, with human intervention also at 15 min per document, corresponding to about 82.5 h of monthly human intervention time. In addition, the process includes a meaningful rework burden due to transcription errors, record verification (NVA activities accounting for 25% of the 10 min direct processing time), and inconsistencies in received CMR documentation (around 5 min per unit), which often require reopening documents or clarifying missing information before final registration.
Figure 7.
Baseline execution flow of the document processing workflow with estimated execution time and rework rates.
Two alternative configurations were developed. Approach I (Figure 8) implements a workflow-embedded pipeline in which incoming email attachments are automatically detected, processed through Optical Character Recognition (OCR), semantically normalized by an LLM, and then written to the Excel registry, with human validation reserved for low-confidence fields. This approach required about 160 development hours and 2 h of one-to-one training. Approach II (Figure 9) keeps the workflow human-driven, but uses a general-purpose LLM interface to extract and structure information from uploaded CMR documents before the user validates and transfers the output to the registry. This second configuration required about 5 development hours and 4 h of training, reflecting its lighter implementation burden.
Figure 8.
Approach I—Embedded automated pipeline for CMR document processing using OCR and LLM-based information extraction. The task color coding is the same as in Figure 3.
Figure 9.
Approach II—Prompt-based standalone workflow for CMR document processing using an LLM interface. The task color coding is the same as in Figure 3.
From an operational perspective, the embedded pipeline achieved the strongest gains (Table 5). Approach I reduced total processing time from 15 to 4 min per document and reduced Human-in-the-Loop (HITL) time from 15 to 3 min per document, corresponding to an 80% reduction in HITL effort and about 66.0 h of monthly time saved. Approach II reduced total processing time to 6 min per document and HITL time to 5.5 min per document, corresponding to a 63% HITL reduction and about 52.3 h of monthly time saved. These results are consistent with the task–tool matching logic proposed in Section 3 and with broader literature arguing that the strongest gains from digital and AI-enabled LSS interventions tend to arise in bounded, repetitive, and structured tasks, especially when traceability and validation checkpoints are explicitly designed into the workflow [8,13,14,18]. In this sense, the customs-document workflow provides an empirical example of how LLM-enabled tools can move beyond generic assistance and support governed partial automation in Class D and Class E tasks without removing human accountability. A concise structural comparison between the baseline workflow and the two LLM-enabled configurations, including automation depth, interaction mode, scalability, traceability, and tool-category composition, is provided in Appendix A, Figure A5.
Table 5.
Operational and economic comparison of Oil Refinery Case Study.
The economic comparison points to the same pattern (Table 5). The embedded pipeline is operationally superior and more cost-efficient per processed document, whereas the prompt-based configuration offers a lower-barrier entry point with much lower upfront investment.
4.2. Case Study: Packaged Snacks SME: Shop-Floor Data Digitalization and Operational Analysis
The Packaged Snacks SME Case Study concerns a Portuguese family-owned SME producing packaged snack products, where shop-floor production data supports operational monitoring and quality management. In the initial condition, most production data was recorded on paper forms and later consolidated into Excel, with physical archiving used mainly for traceability. This setup limited systematic KPI monitoring, slowed retrieval, and placed a substantial burden on manual consolidation and interpretation (Figure 10). In the shop-floor data baseline, the overall workflow requires about 48 h/month, with an overall NVA share of 40%. The largest NVA burden is associated with manual consolidation into Excel (90% NVA), together with repetitive monitoring/reporting effort and paper-based data-quality problems such as incomplete entries, lack of real-time validation, and resulting inconsistencies.
Figure 10.
Baseline workflow for shop-floor production data management and analysis, including estimated execution time and NVA share.
A methodological clarification is important in this case. The baseline does not represent a previously stabilized routine already performed in that exact form. Rather, it represents a reference configuration reconstructed from the observed initial condition, the paper-based data-recording practice, the Excel consolidation requirement, and the expected routines of a structured Lean monitoring and reporting workflow without additional digital support. This reconstruction was necessary because the initial condition did not include a mature digital monitoring routine against which the LLM-enabled configurations could be directly compared. The reconstructed baseline may therefore overestimate or underestimate the effort that would have emerged if the organization had first implemented a non-LLM digital monitoring system. Overestimation could occur if conventional dashboards alone had already reduced part of the reporting and consolidation burden. Underestimation could occur if the paper-based system generated additional hidden effort through missing entries, late corrections, informal clarification, or retrieval problems not fully captured in the baseline estimate. For this reason, the case is interpreted as a structured comparison of alternative workflow configurations rather than as an isolated causal estimate of the LLM component. Under the case-study assumptions, about 600 production records per month and 4 reports per month were considered, leading to an estimated baseline workload of 48 h per month.
Unlike the Oil Refinery Case Study, this workflow spans several task classes and process types. Data capture and dataset maintenance correspond to Class D and Class E work, while KPI interpretation, report preparation, and dissemination correspond to Classes B, A, and C. Within the current manuscript taxonomy, this case is primarily aligned with Process-Type 2 (Operational Data Analysis and Performance Monitoring), as it centers on KPI monitoring, deviation identification, and structured operational analysis. It also exhibits strong Process-Type 3 characteristics because analytical outputs are translated into recurring reports and communicated to decision-makers. Some Process-Type 1 features are also present where the workflow supports periodic managerial review and performance follow-up. This makes it particularly useful for showing that LLM-enabled gains in Class B and Class A depend on first stabilizing the upstream data layer.
To make the comparison more transparent, both alternative configurations, Approach III and Approach IV, were built on the same digitalization layer. Production data is captured through a Power Apps interface, stored in a structured Excel-based dataset, and then used as the common input for analytical and reporting activities. This design does not isolate the independent contribution of the LLM-enabled components, because the workflow also benefits from front-end digitalization, structured data storage, and dashboard-based monitoring. Instead, it allows the two configurations to be compared under a common data foundation, showing how different forms of LLM-enabled analytical and reporting support operate once the upstream data layer has been stabilized. Approach III uses Tableau dashboards and Tableau Pulse for continuous KPI monitoring and AI-generated insights, which are then converted into structured managerial reports through Microsoft Copilot and distributed through Power Automate (Figure 11). It required about 70 developer hours, 4 user hours, and 10 h of one-to-one training. Approach IV uses the same structured dataset, but replaces dashboard-driven monitoring with conversational analytics in ThoughtSpot, allowing supervisors to query the data directly in natural language before generating reports through Copilot (Figure 12). It required about 55 developer hours, 10 user hours, and 12 h of training.
Figure 11.
Approach III—AI-assisted digital workflow for shop-floor production data management and analysis. The color code of Tasks is the same as that used in Figure 3.
Figure 12.
Approach IV—Conversational analytics workflow for production data management and analysis. The color code of Tasks is the same as that used in Figure 3.
Operationally, both approaches substantially reduce recurring analytical effort (Table 6). Approach III reduced total processing time from 48 to 15.5 h per month and total HITL effort from 48 to 15.4 h per month. Approach IV reduced total processing time to 18.4 h per month and HITL effort to 17.4 h per month. However, the most informative comparison is the one excluding data-recording effort, because the economic analysis focuses on the analytical and reporting layer. When the data registry is excluded, the HITL effort falls from 18 h per month in the baseline to 0.4 h in Approach III and to 2.4 h in Approach IV, corresponding to reductions of 98% and 87%, respectively. These results should therefore not be read as evidence that the LLM component alone produced the observed efficiency gains. The main performance improvement results from the combination of structured data capture, consistent storage, dashboard-supported monitoring, and controlled language-based support for interpretation and reporting. The LLM-enabled layer remains relevant because it reduces the effort required to formulate insights and prepare recurring reports, but its usefulness depends on the availability of reliable and traceable data. This pattern is aligned with LSS 4.0 literature emphasizing that advanced analytical support depends on stable digital baselines, traceable data flows, and monitoring infrastructures capable of sustaining more continuous improvement cycles [5,18,19,22].
Table 6.
Operational and economic comparison of Packaged Snacks SME Case Study.
The operational profiles of the two approaches are also different. Approach III is largely system-driven: dashboards and Tableau Pulse continuously monitor the dataset and generate standardized insights, which supervisors then validate and convert into reports. In this configuration, data recording remains the main human activity, at about 15 h per month, while report generation represents only a very small share of the total effort, approximately 28 min per month. Approach IV is more user-driven: supervisors actively formulate queries in the conversational analytics layer and validate the returned insights before report generation. Here, data recording still accounts for about 15 h per month, while analytical effort is concentrated in query formulation, at about 2 h per month for weekly reporting. The main structural differences between the baseline analytical workflow and the two LLM-enabled configurations are summarized in Appendix A, Figure A6.
The economic results again favor the more embedded configuration (Table 6). Although both approaches require more substantial payback periods than in the Oil Refinery Case Study, they also improve the quality, consistency, and breadth of analytical outputs by structuring a previously weak monitoring process and reducing reliance on purely manual interpretation. At the same time, the contrast between the two approaches also reinforces findings from human–LLM interaction research: more workflow-embedded configurations reduce recurring effort more strongly, whereas user-driven interaction preserves flexibility but introduces greater dependence on user initiative, query quality, and variability in use [13,14]. The case therefore shows that, for Class B and Class A work, LLM-enabled value is strongest after the upstream Class D and Class E layer has first been stabilized.
4.3. Cross-Case Synthesis
Across both applications, the observed patterns are consistent with the task–tool matching logic used to select tool categories. In the Oil Refinery Case Study, where the task mix is dominated by bounded Class D and Class E work, the strongest gains arise when multimodal extraction and orchestration are embedded directly in the workflow and combined with explicit validation checkpoints. In the shop-floor data case (Packaged Snack SME Case Study), where higher-value gains depend on interpretation and reporting, the results show that LLM-enabled support becomes substantially more effective once upstream data capture and dataset maintenance have been stabilized.
To avoid interpreting these results only as time and cost reductions, Table 7 summarizes the two applications using the broader evaluation dimensions introduced in Section 3.7. The table does not add new statistical evidence; rather, it makes explicit the operational robustness criteria that were considered when interpreting the LLM-enabled configurations. This is particularly important because LLM-enabled workflows may reduce repetitive manual work while increasing the relative importance of validation, exception handling, data quality, and continued monitoring.
Table 7.
Multi-dimensional evaluation of the two LLM-enabled case applications.
Table 7 shows that the interpretation of the two cases becomes richer when evaluation moves beyond efficiency alone. Taken together, the results indicate that stronger performance improvements emerge when the predicted task–tool alignment is high, and the interaction mode is supported by an appropriate workflow design. In the Oil Refinery case, the main value of the embedded configuration is not only the reduction in processing time, but also the stabilization of a repetitive document-to-record workflow through structured extraction, validation, and traceability. In this context, strong-fit Class D/E pairings enabled workflow-embedded and partially automated support, while preserving human review for validation and exceptions. In the Packaged Snacks SME case, the main value cannot be attributable to LLM-enabled reporting alone, but to the combination of digital data capture, structured storage, dashboard-based monitoring, and human-validated language-based interpretation. Here, the strongest benefits appeared after the data layer was stabilized, allowing Class B/A support to operate on structured and traceable inputs. Beyond time and workload reduction, the two cases therefore suggest operational adequacy through preserved traceability, maintained human validation, and improved timeliness and consistency of monitoring and reporting. This reinforces the view that LLM-enabled value in LSS contexts is conditional on data readiness, workflow embeddedness, and explicit accountability mechanisms.
5. Discussion, Practical Implications, and Limitations
5.1. Discussion in Relation to the Research Questions
The results support the central premise behind RQ1: a task-first, process-centric representation provides a practical bridge between LSS work and LLM-enabled tool capabilities. More specifically, the study shows that decomposing transversal work into functional task classes enables a defensible mapping between task characteristics, tool categories, and governance assumptions. The separation of alignment strength from interaction mode was particularly useful because it distinguishes capability fit from governance logic, clarifying not only where LLM-enabled support is structurally plausible, but also how it can be deployed without compromising LSS accountability. This addresses the translation gap identified in prior LSS 4.0 and LLM literature, where strategic discussions of AI integration are more common than task-level guidance on where support, augmentation, or partial automation are most appropriate [5,13,14,18].
For RQ2, the two cases reveal a consistent but bounded pattern: the greatest improvements occur where LLM-enabled support targets high-frequency work with clear task boundaries, structured inputs, and explicit acceptance criteria. The observed results are coherent with the predicted alignment strengths and interaction modes proposed in Section 3: workflow-embedded and partially automated configurations performed better in bounded Class D/E work, whereas Class B/A support became more useful after the upstream data layer had been stabilized. However, these findings should be interpreted as case-based operational evidence rather than causal evidence of LLM adoption effects. As summarized in Table 7, the more robust configurations were those that combined efficiency gains with output consistency, traceability, reviewability, explicit human responsibility, and defined conditions for exception handling and continued monitoring. This interpretation is aligned with literature on LSS 4.0, continuous monitoring, and grounded LLM use in evidence-driven environments [8,12,19,22,39].
5.2. Practical Implications
For practitioners, Figure 13 synthesizes the proposed implementation logic into a progressive decision scheme, translating the task–tool matching framework into an actionable sequence for the adoption of LLM-enabled tools in information-intensive administrative work. Rather than starting from tool selection alone, the scheme suggests a more disciplined sequence beginning with task characterization and assessment of data, workflow readiness, functional tool-category selection, definition of interaction mode, and the explicit design of governance and validation checkpoints.
Figure 13.
Decision scheme for the progressive application of LLM-enabled tools in information-intensive administrative work.
Across both archetypes, implementation effort should be directed less toward maximizing autonomy and more toward designing robust data structures, explicit review points, evidence linkage, and exception handling. The decision scheme also reinforces that adoption should be progressive: organizations should begin with bounded tasks, monitor performance, refine prompts and workflows, and scale only when reliability and governance conditions are stable, in line with current guidance on governed LLM deployment in operational settings [11,12,13,39].
To make the practical use of the decision scheme explicit, Table 8 applies Figure 13 retrospectively to the two case studies. This retrospective application does not constitute an independent validation of the scheme, but it shows how the decision steps help explain the observed differences between the two applications and identify the main implementation deviations or boundary conditions.
Table 8.
Retrospective application of the decision scheme to the two case studies.
This retrospective application shows that the decision scheme helps distinguish two different adoption logics. In the Oil Refinery case, the process is narrow, repetitive, and structured enough to support a stronger move toward workflow-embedded partial automation, provided that validation and exception handling remain explicit. In the Packaged Snacks SME case, the contribution is more incremental: the first requirement is to stabilize data capture and storage, after which LLM-enabled tools can support interpretation, reporting, and communication. This explains why the observed gains in the second case should not be attributed to the LLM layer alone, but to the combined effect of data readiness, workflow embeddedness, and human-validated analytical support.
5.3. Limitations
This study is intentionally framed as an investigator-led, feasibility-oriented assessment rather than as a controlled adoption study. Baseline and impact values are based on case-study evidence, including workflow mapping, interviews, observation, implementation records, and operational estimates provided or validated in the case context. The LLM-enabled configurations reflect defined workflows and offline validation activities rather than organization-wide deployment over an extended period. As a result, the reported differences should be interpreted as operational estimates under stated assumptions, not as causal estimates of adoption outcomes or statistically generalizable effects. Tool performance may also vary across versions, configurations, and data conditions, and the functional mapping abstracts away vendor-specific differences.
The absence of repeated baseline and intervention observations also means that statistical significance testing and confidence intervals were not applied. This is a limitation of the study; however, it also avoids presenting reconstructed or estimate-based data with an unsupported level of statistical precision. Future research should address this limitation through longitudinal designs, repeated time observations, audit-log analysis, error-rate measurement, controlled or quasi-controlled comparisons, and inter-organizational replication across sectors with different levels of digital maturity.
A second limitation concerns the attribution of effects. This is particularly relevant in the Packaged Snacks SME case, where the LLM-enabled configurations were introduced alongside front-end data digitalization, structured storage, and dashboard-supported monitoring. The study, therefore, cannot isolate the independent causal contribution of the LLM-enabled reporting layer. Instead, the case shows that LLM-enabled analytical and reporting support becomes more useful when upstream data capture and maintenance have first been stabilized.
Although the functional classes and scoring criteria were made explicit to improve transparency and reproducibility, they remain analytically derived rather than empirically validated through statistical testing. The single-label classification supports matrix construction and cross-process comparison, but it necessarily simplifies composite real-world tasks. Similarly, the governance protocol and the evaluation dimensions in Table 7 were applied retrospectively to the two cases and should be further tested through prospective implementation, independent coding, audit-log analysis, error-rate monitoring, user-workload assessment, and longitudinal validation. Future research should also test inter-rater agreement among independent coders, compare single-label and multi-label classification schemes, and assess whether the same task classes remain stable across sectors with different digital maturity and regulatory constraints.
The multi-dimensional evaluation introduced in Table 7 also has limitations. Several dimensions, such as traceability, consistency, risk exposure, and sustainability of use, were assessed interpretively from the workflow design and case evidence rather than through independent quantitative measurement. The table should therefore be read as a structured evaluation frame for case interpretation, not as a validated measurement instrument. Future studies should operationalize these dimensions through repeated observations, error-rate measurement, audit-log analysis, user workload assessment, and longitudinal monitoring of maintenance effort.
Finally, the economic indicators should be read as base-case operational estimates rather than full life-cycle cost assessments. The analysis includes development effort, user effort, training, recurring time savings, and cost per unit, but does not fully quantify ongoing maintenance costs associated with prompt or template updates, tool-version changes, monitoring of output quality, audit effort, data-access management, user retraining, or exception handling. These factors may reduce the effective payback of LLM-enabled configurations and should be explicitly measured in future deployment studies. Although the framework clarifies where LLM-enabled support is plausible, it does not by itself quantify risk, compliance exposure, or downstream effects on decision quality, which would require extended organizational validation and governance assessment. This is particularly relevant in LSS environments, where operational usefulness alone is insufficient if outputs cannot also be audited, explained, and reproduced over time [11,12].
6. Conclusions
This paper addresses the practical gap between high-level discussions of LSS 4.0 and the operational reality of embedding LLM-enabled support into recurring improvement work. By adopting a task-first, process-centric perspective, the study develops a dual-encoded matching approach that links functional task classes to functional categories of LLM-enabled tools while keeping two dimensions explicit and separable: alignment strength (capability fit) and interaction mode (governance under accountability constraints). This framing clarifies that the key question is not whether LLMs can generate plausible outputs, but where they can be positioned in workflows to reduce effort without weakening traceability and human responsibility.
The empirical results show that the strongest gains emerge when LLM-enabled support is aligned with bounded task structures, structured inputs, and explicit validation checkpoints. Across the two cases, this pattern was most visible where workflows were sufficiently stable to support controlled automation or augmentation without bypassing evidence-based analysis. These results should therefore be interpreted as case-based evidence of plausible workflow effects under defined assumptions, rather than as statistically generalizable evidence of LLM adoption impact. The decision scheme derived from the framework further translates this contribution into a practical implementation logic for progressive deployment under explicit governance constraints.
Beyond these empirical results, the study contributes to the state of the art by operationalizing, at the task level, a problem that is often treated more generically in both LSS 4.0 and LLM literature. While prior LSS 4.0 reviews have clarified the strategic role of AI, analytics, and digital monitoring, and the human-LLM interaction literature has clarified governance modes of assistance and augmentation, few studies have connected these perspectives in a way that helps practitioners decide which recurring LSS-relevant tasks are better suited to support, augmentation, or partial automation [5,13,14,18]. The findings presented here suggest that this decision depends strongly on functional task type, workflow embeddedness, data readiness, and the explicit design of validation checkpoints.
Overall, the findings support the paper’s central argument that operational value depends on matching tool roles to dominant work types and on choosing an interaction mode that fits the risk and accountability profile of the task. The proposed matrix and its dual encoding offer a compact decision aid for practitioners to identify plausible entry points, avoid structurally weak pairings, and specify governed use patterns that remain compatible with LSS discipline. At the same time, the results reinforce an equally important boundary condition: in evidence-driven improvement settings, LLM-enabled support is most robust when it complements, rather than bypasses, structured data, traceable workflows, and human validation [11,12].
Author Contributions
Conceptualization, P.P.; Methodology, L.M.d.C.; Software, L.M.d.C.; Formal analysis, P.P. and D.J.; Investigation, L.M.d.C.; Resources, P.P.; Data curation, L.M.d.C., P.P. and D.J.; Writing—original draft, L.M.d.C.; Writing—review & editing, P.P. and D.J.; Visualization, L.M.d.C. and D.J.; Supervision, P.P.; Project administration, P.P.; Funding acquisition, P.P. All authors have read and agreed to the published version of the manuscript.
Funding
The authors acknowledge Fundação para a Ciência e a Tecnologia (FCT) for its financial support via LAETA (project https://doi.org/10.54499/UID/50022/2025). This work has been supported by the European Union under the Next Generation EU, through a grant of the Portuguese Republic’s Recovery and Resilience Plan (PRR) Partnership Agreement, within the scope of the project PRODUTECH R3—“Agenda Mobilizadora da Fileira das Tecnologias de Produção para a Reindustrialização”, Total project investment: 166.988.013,71 Euros; Total Grant: 97.111.730,27 Euros.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The original contributions presented in this study are included in the article. Further inquiries can be directed to the author.
Conflicts of Interest
Authors Diogo Jorge and Paulo Peças were employed by the company Efficiencyrising. The remaining authors declare that the research was conducted without any commercial or financial relationships that could be construed as a potential conflict of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| AI | Artificial Intelligence |
| API/APIs | Application Programming Interface/Interfaces |
| BPMN | Business Process Model and Notation |
| CI | Continuous Improvement |
| CRUD | Create, Read, Update, Delete |
| DL | Deep Learning |
| DMAIC | Define, Measure, Analyze, Improve, Control |
| GenAI | Generative Artificial Intelligence |
| HITL | Human-in-the-Loop |
| I4.0 | Industry 4.0 |
| ISO | International Organization for Standardization |
| KPI/KPIs | Key Performance Indicator/Indicators |
| LLM/LLMs | Large Language Model/Models |
| LSS | Lean Six Sigma |
| ML | Machine Learning |
| NIST | National Institute of Standards and Technology |
| NLP | Natural Language Processing |
| NVA | Non-Value-Added |
| OCR | Optical Character Recognition |
| OMG | Object Management Group |
| Portable Document Format | |
| RAG | Retrieval-Augmented Generation |
| RQ1/RQ2 | Research Question 1/2 |
| SME | Small and Medium-Sized Enterprise |
| UI/UX | User Interface/User Experience |
Appendix A
Figure A1.
Functional classification of tasks in Process-Type 2 (Color coding indicates functional task categories).
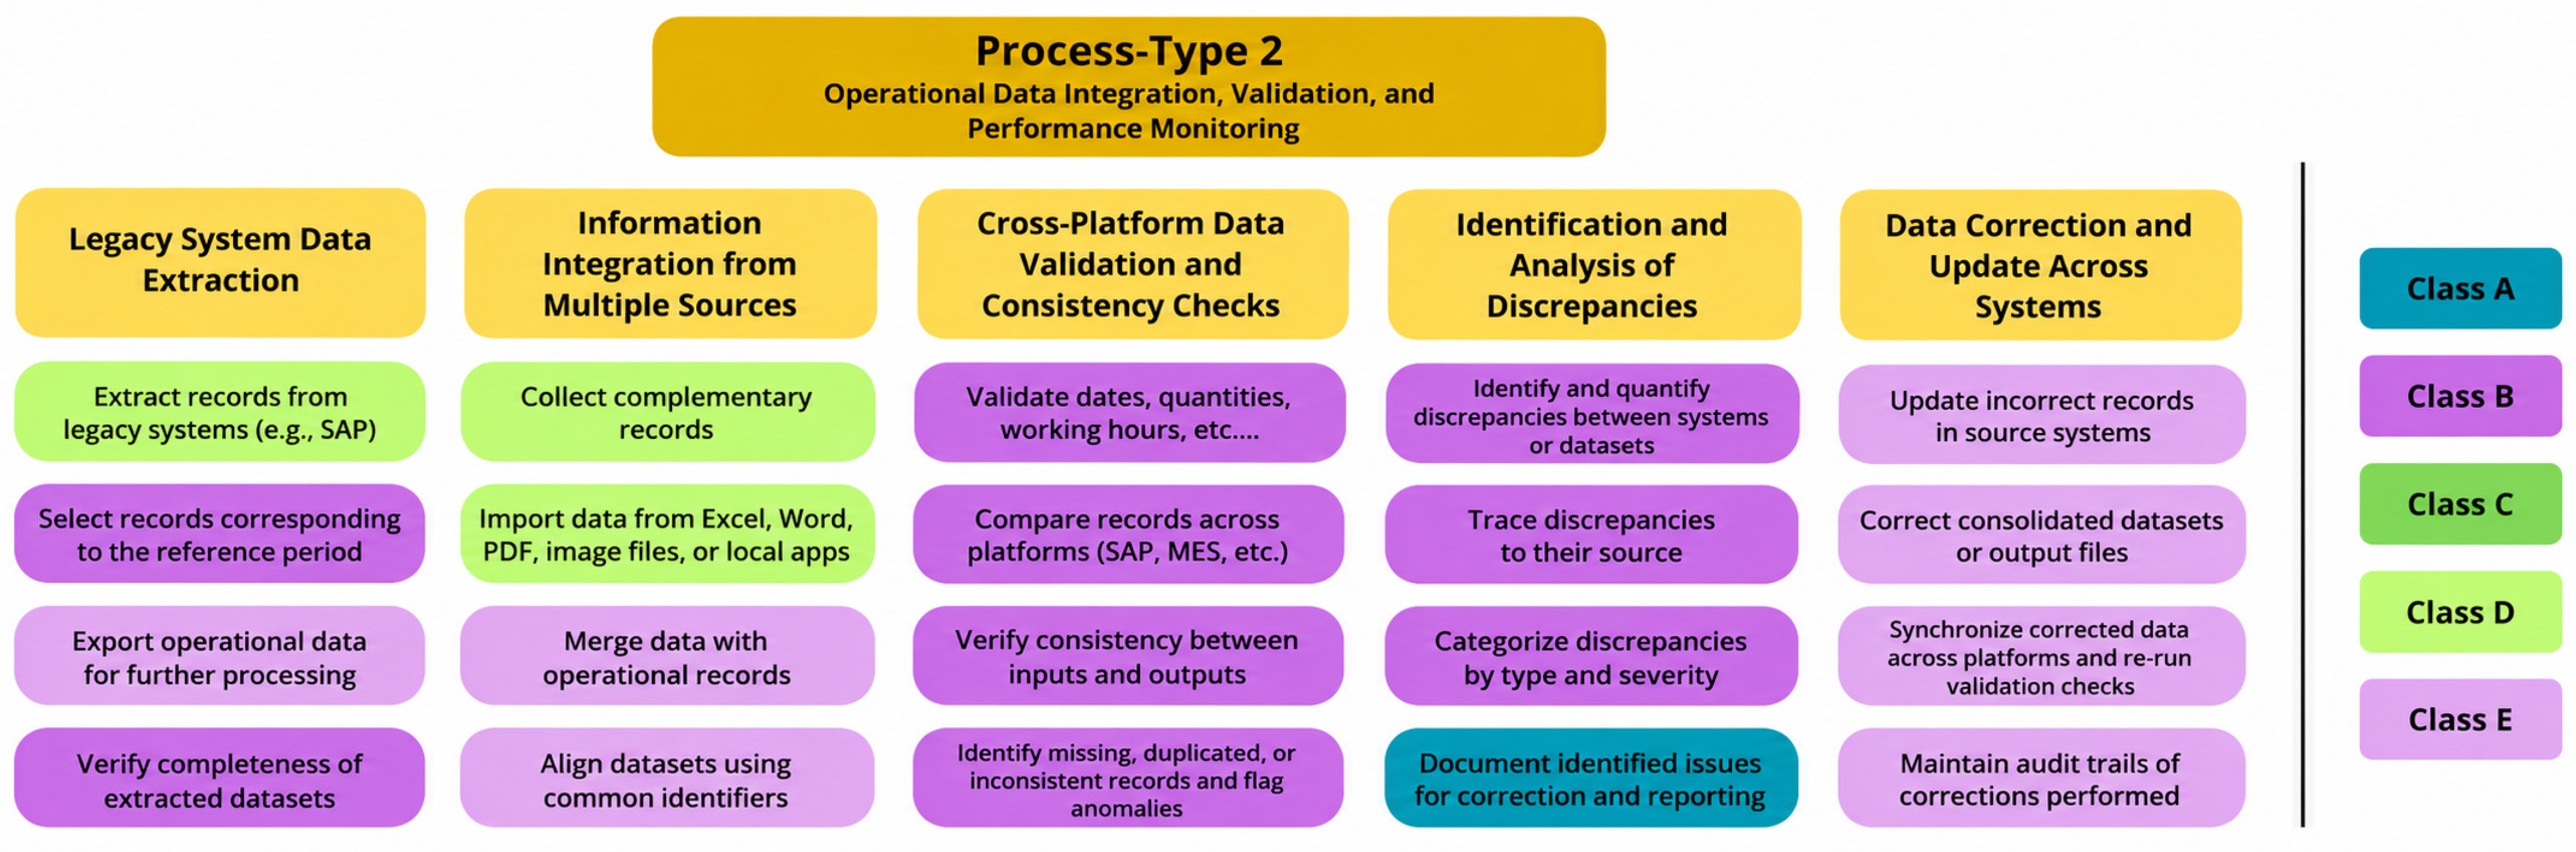
Figure A2.
Functional classification of tasks in Process-Type 3 (Color coding indicates functional task categories).
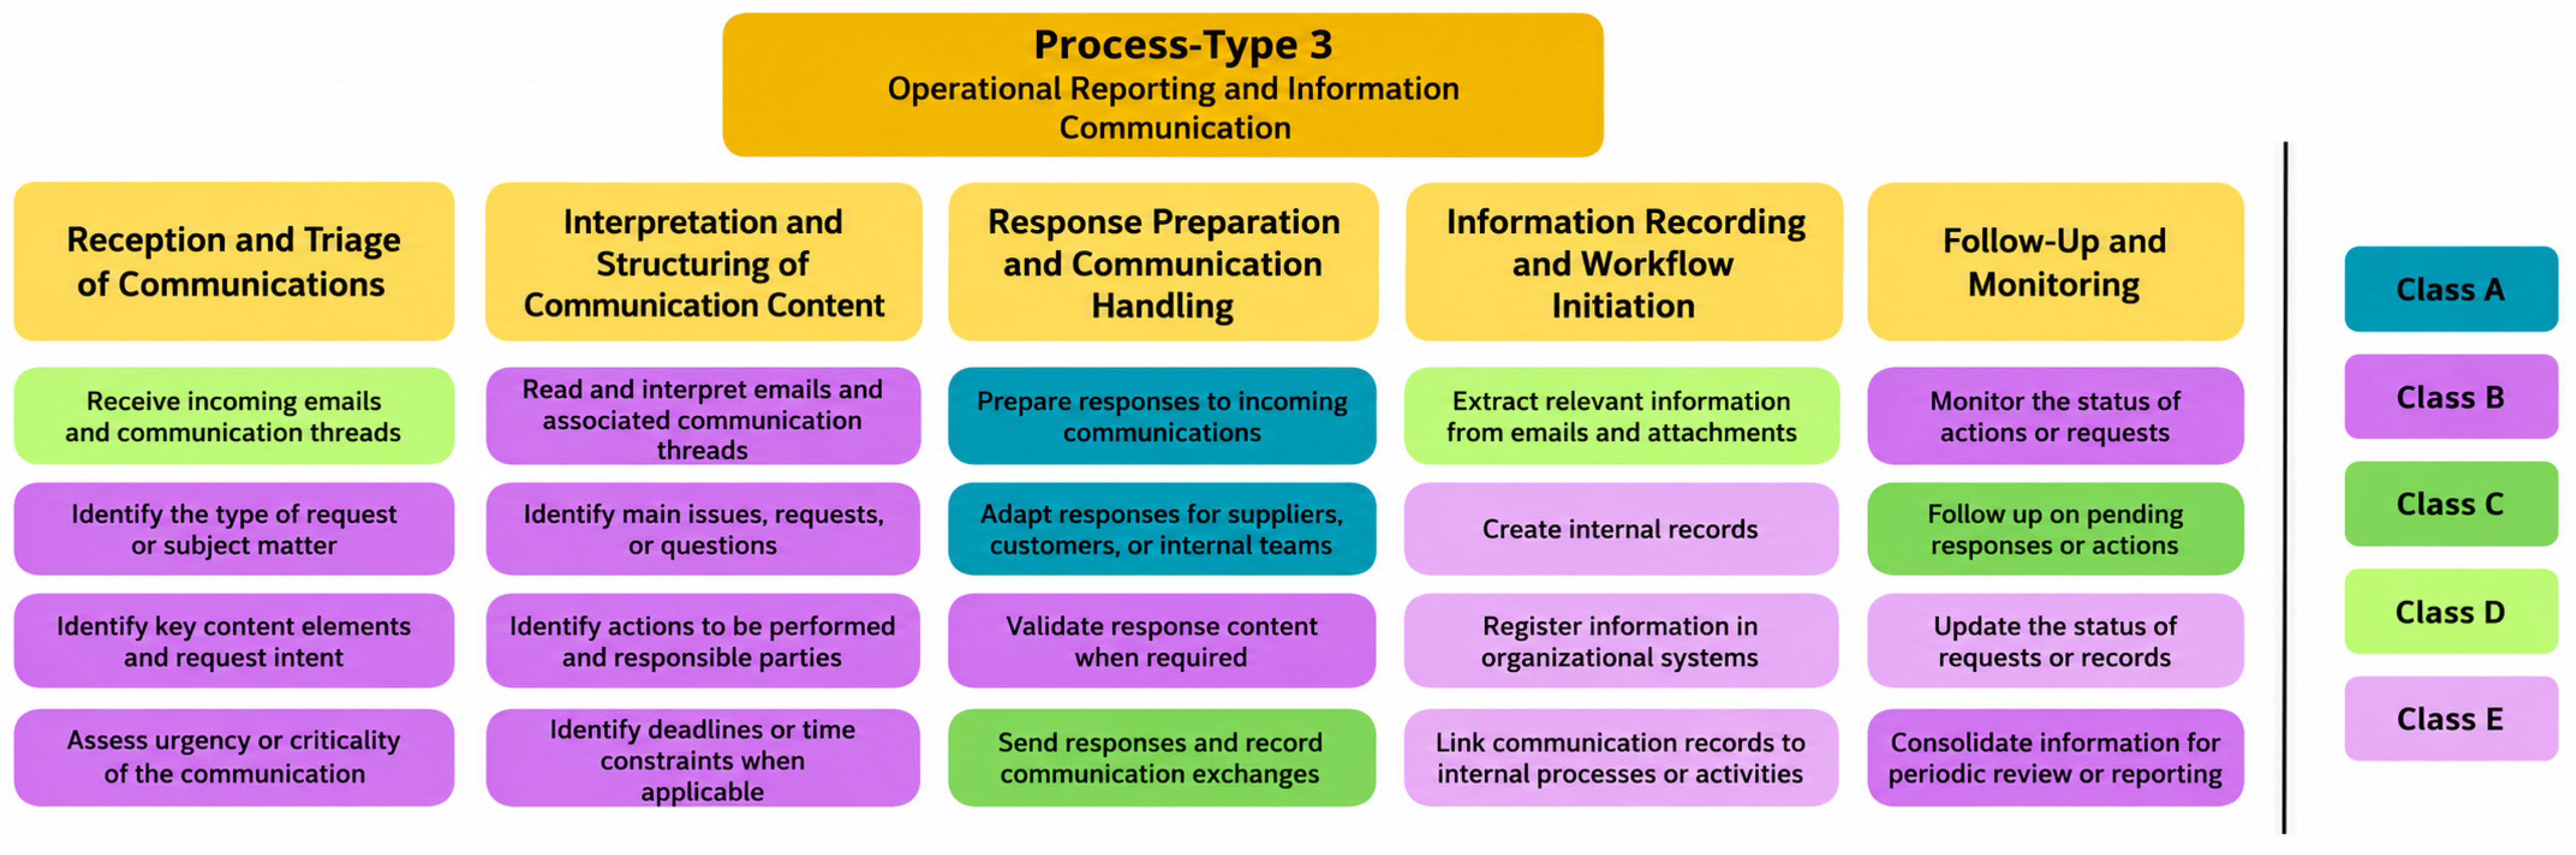
Figure A3.
Functional classification of tasks in Process-Type 4 (Color coding indicates functional task categories).
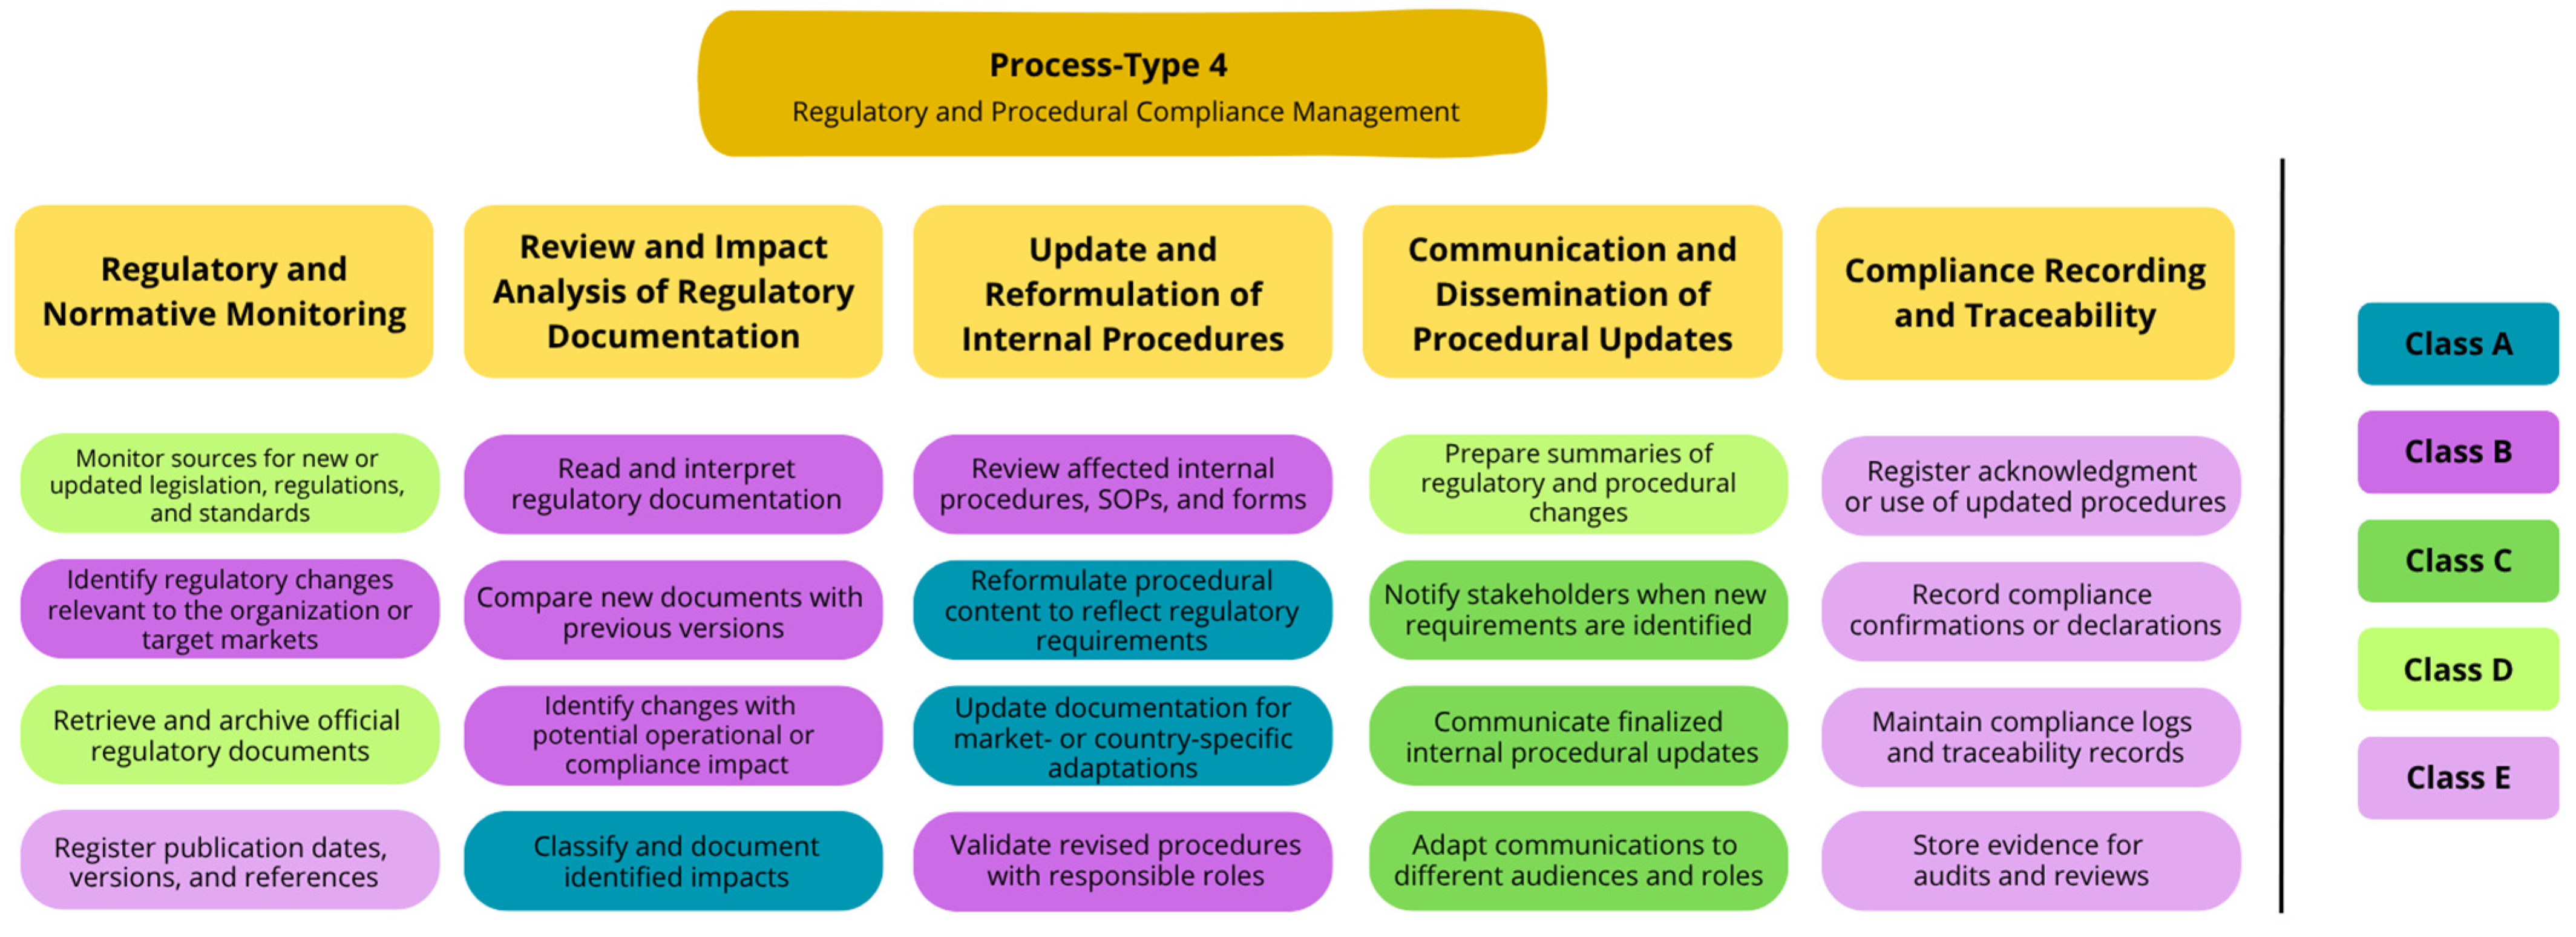
Figure A4.
Functional Characterization of LLM-Enabled Tool Categories.
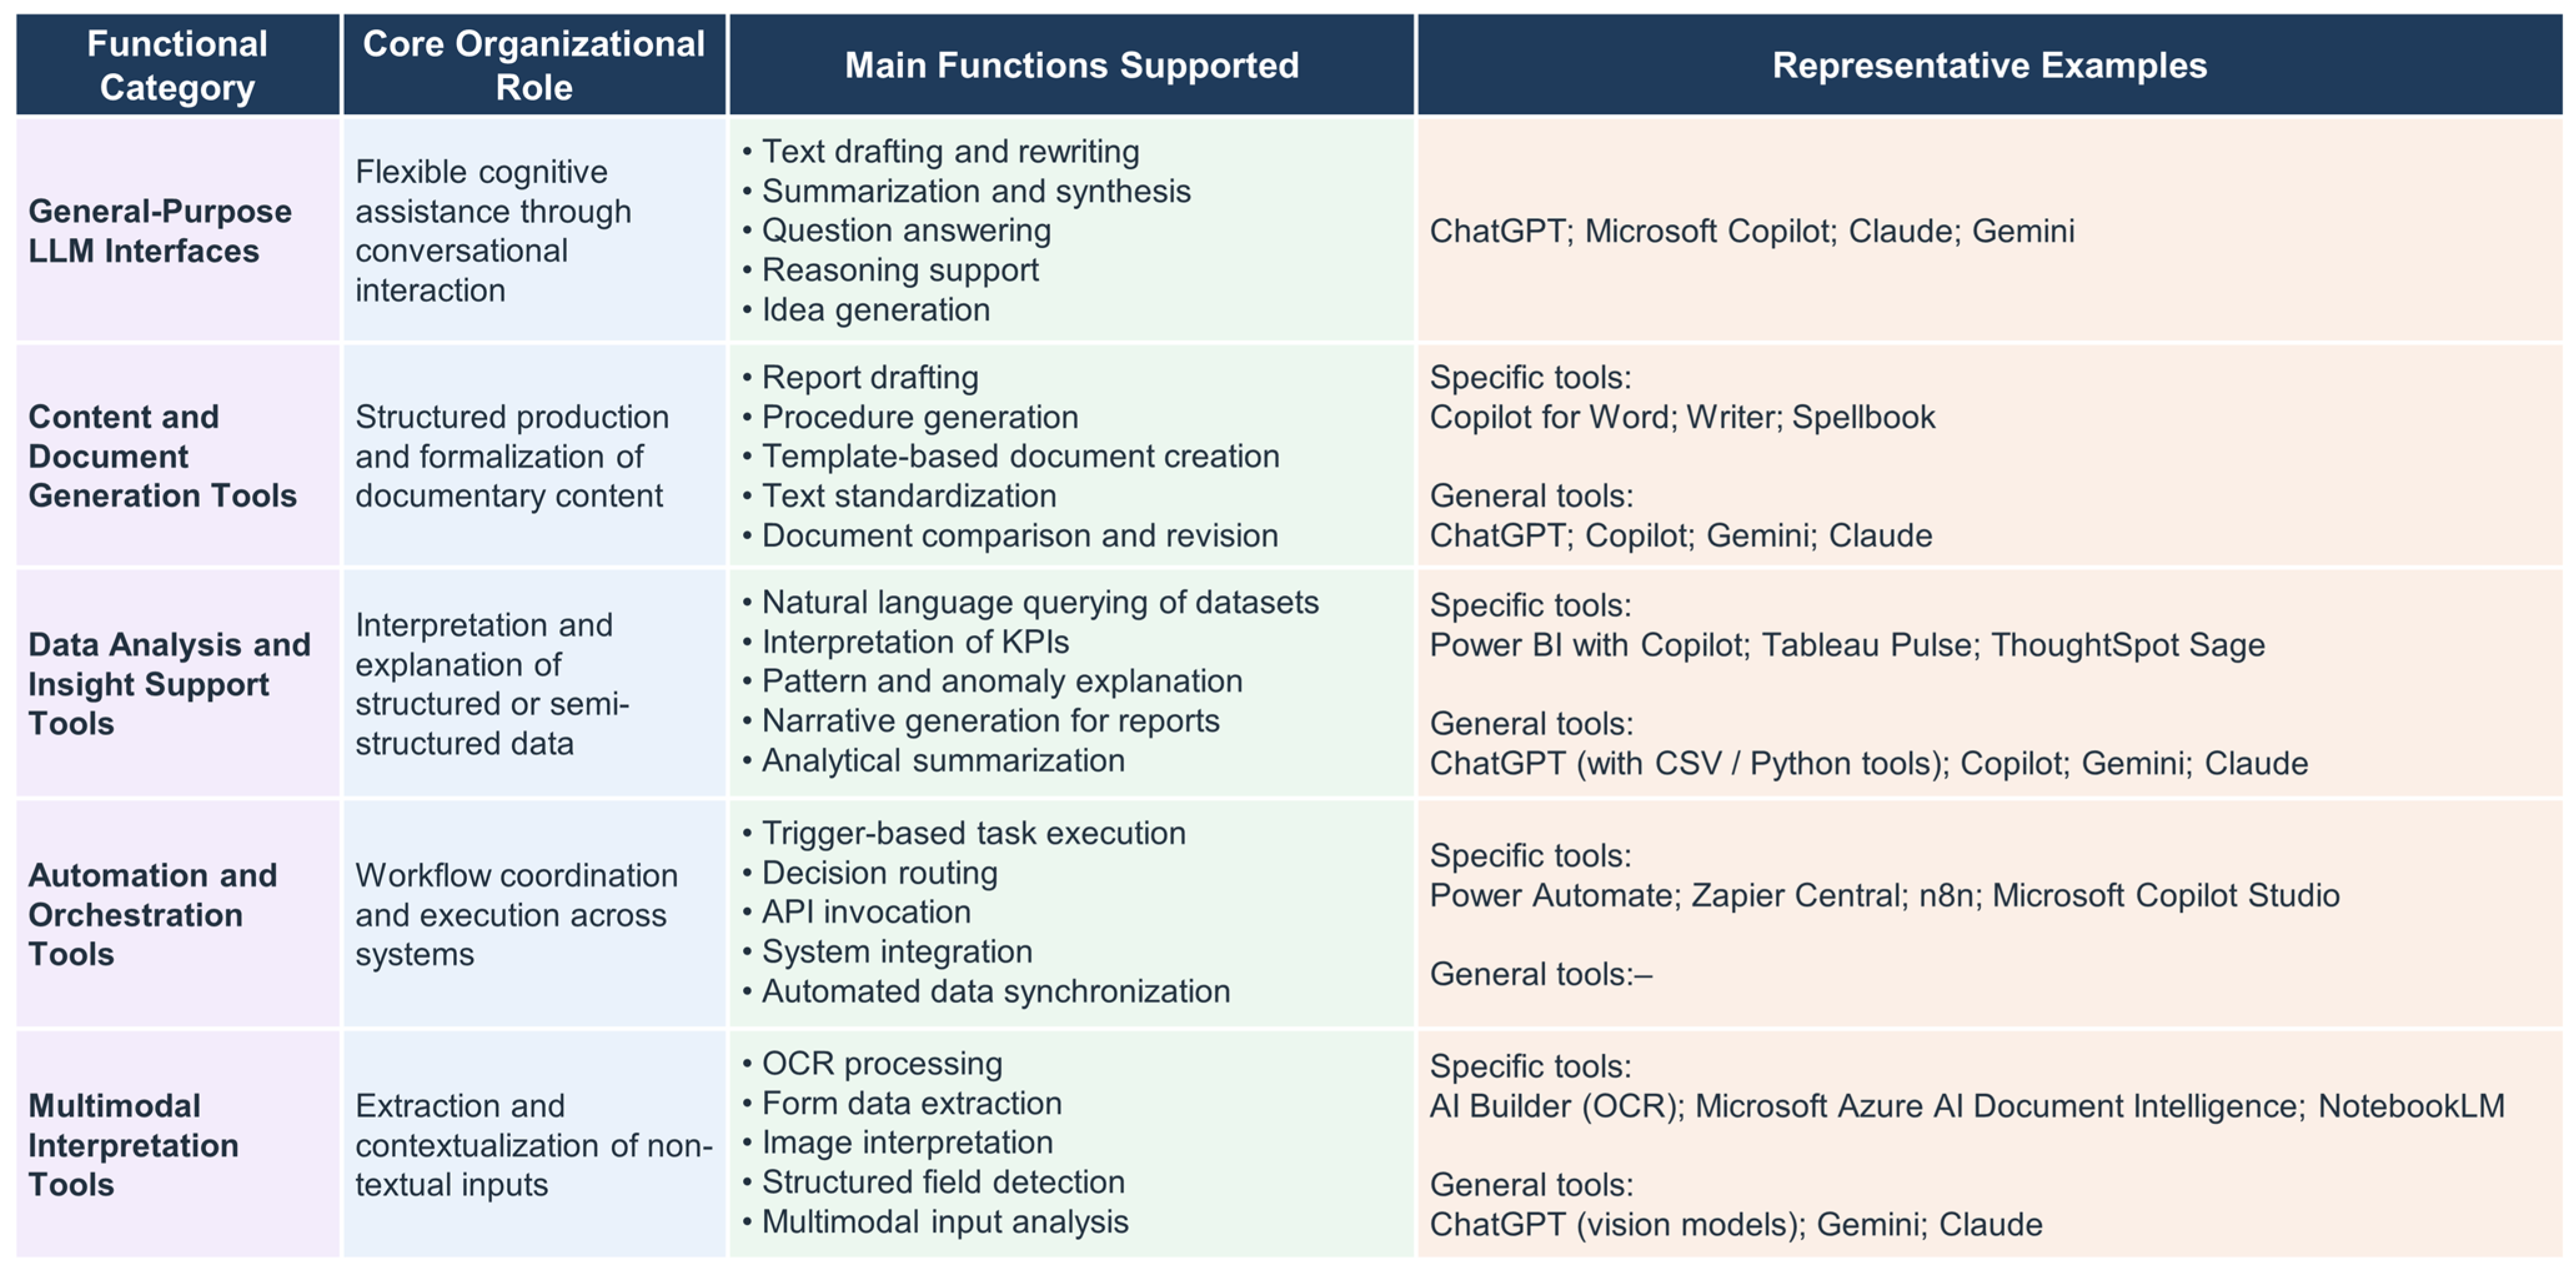
Figure A5.
Conceptual comparison between baseline workflow and LLM integration approaches for the Oil Refinery case study.
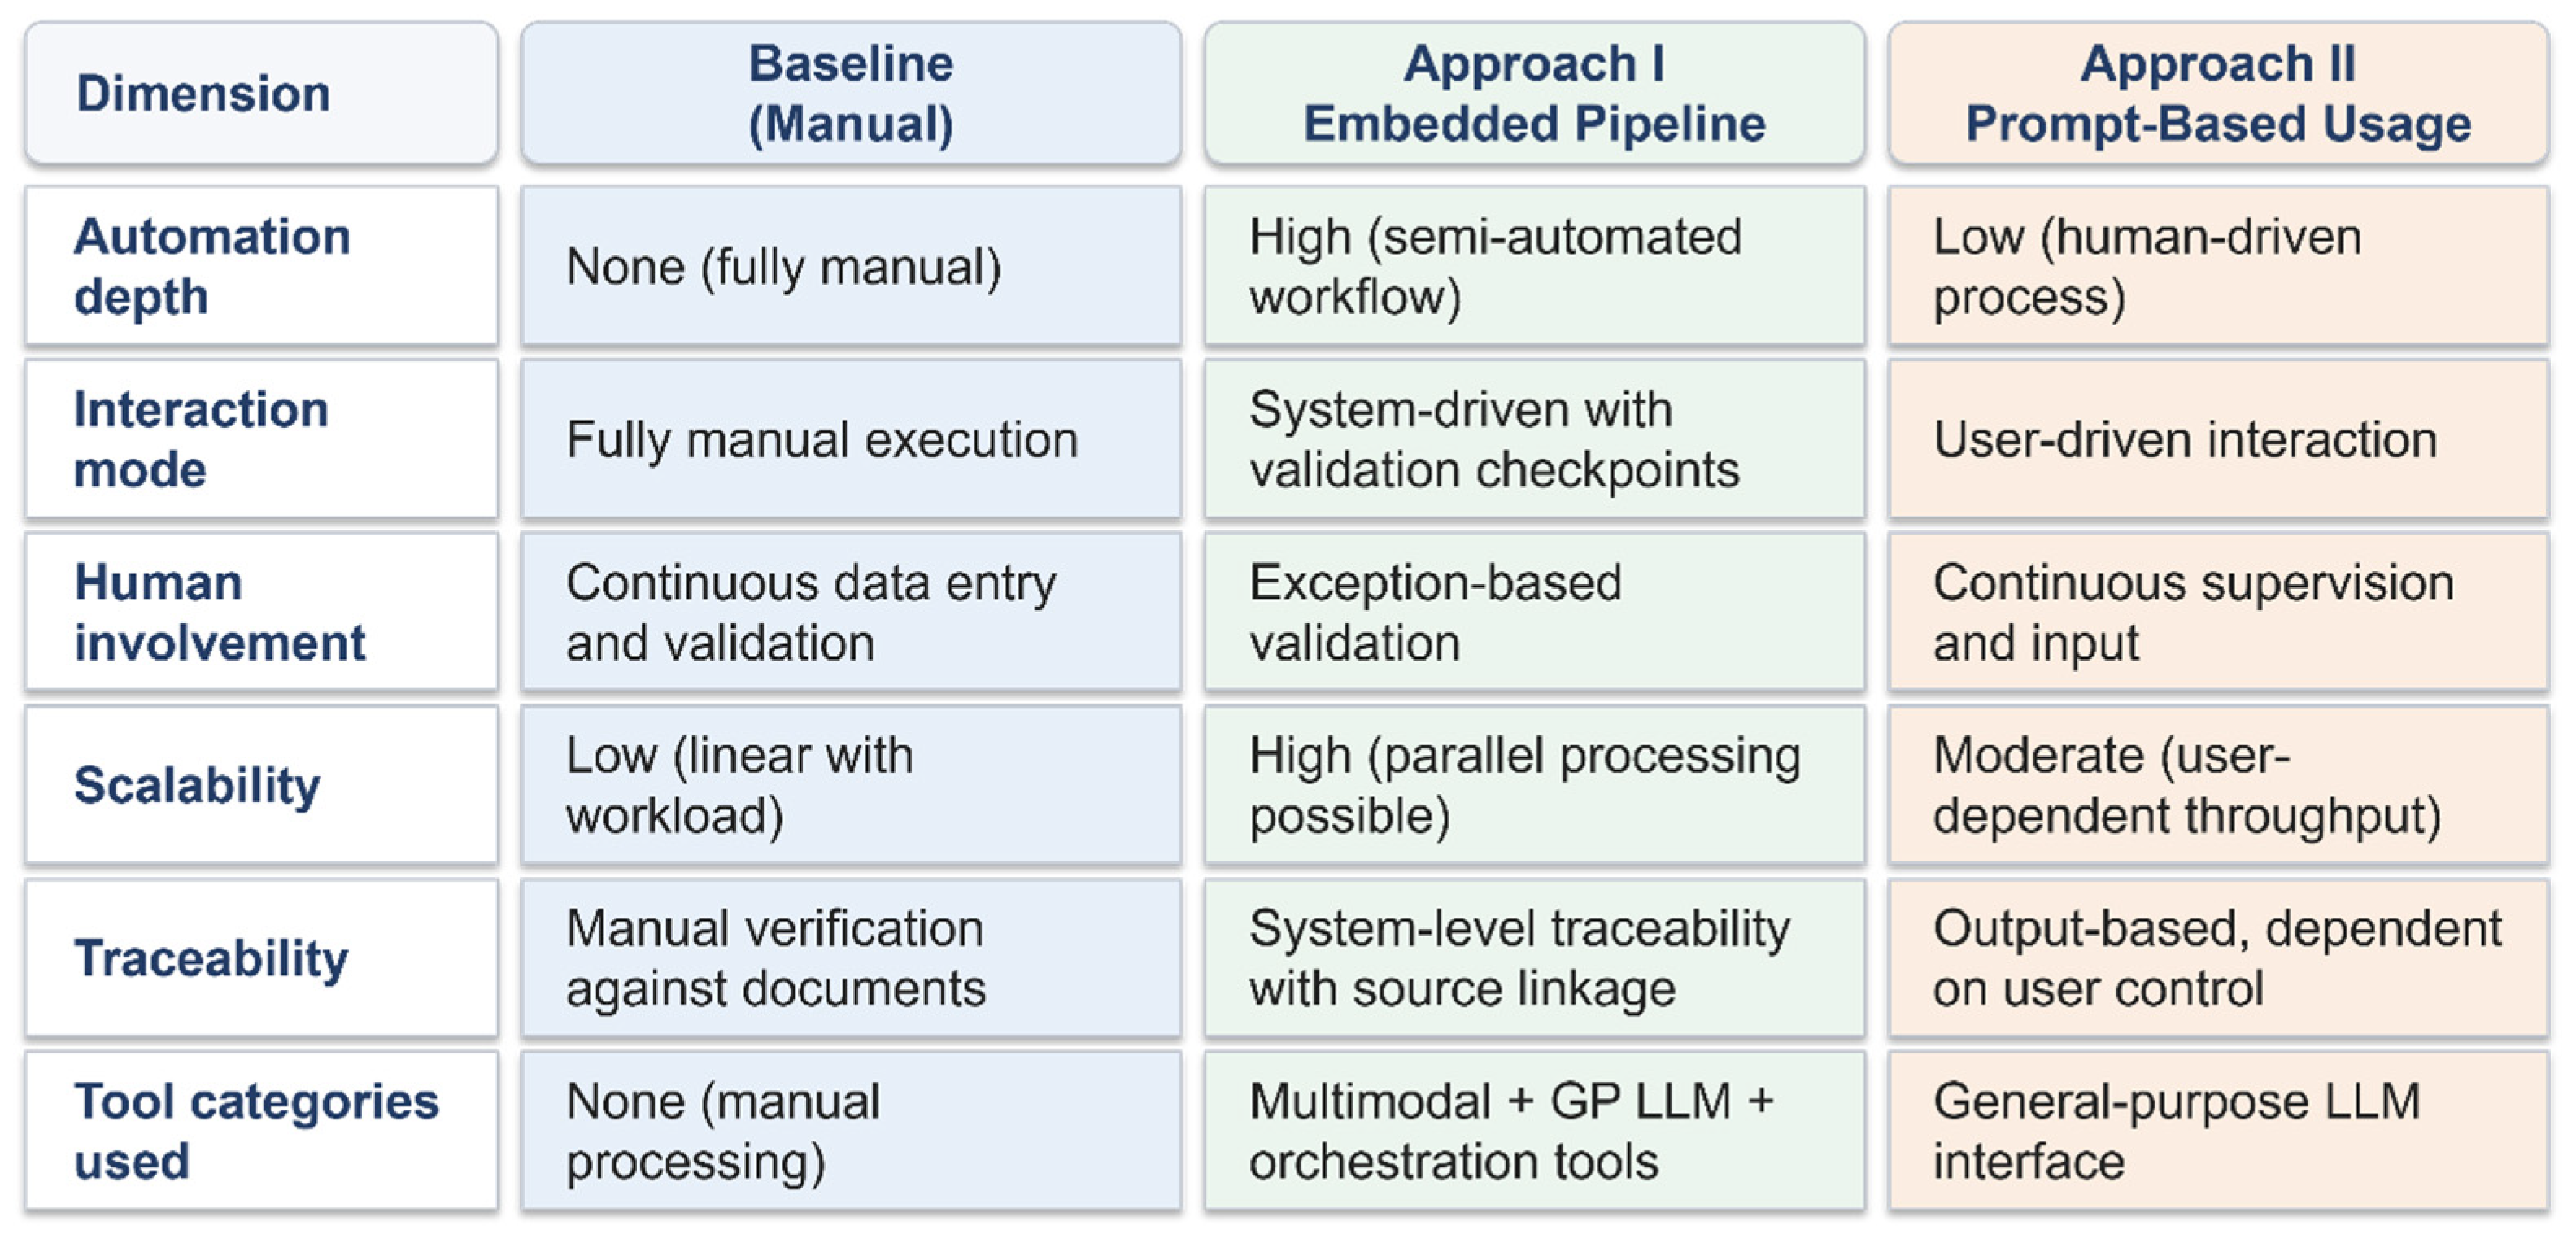
Figure A6.
Conceptual comparison between baseline workflow and LLM integration approaches for the Packaged Snack SME Case Study.
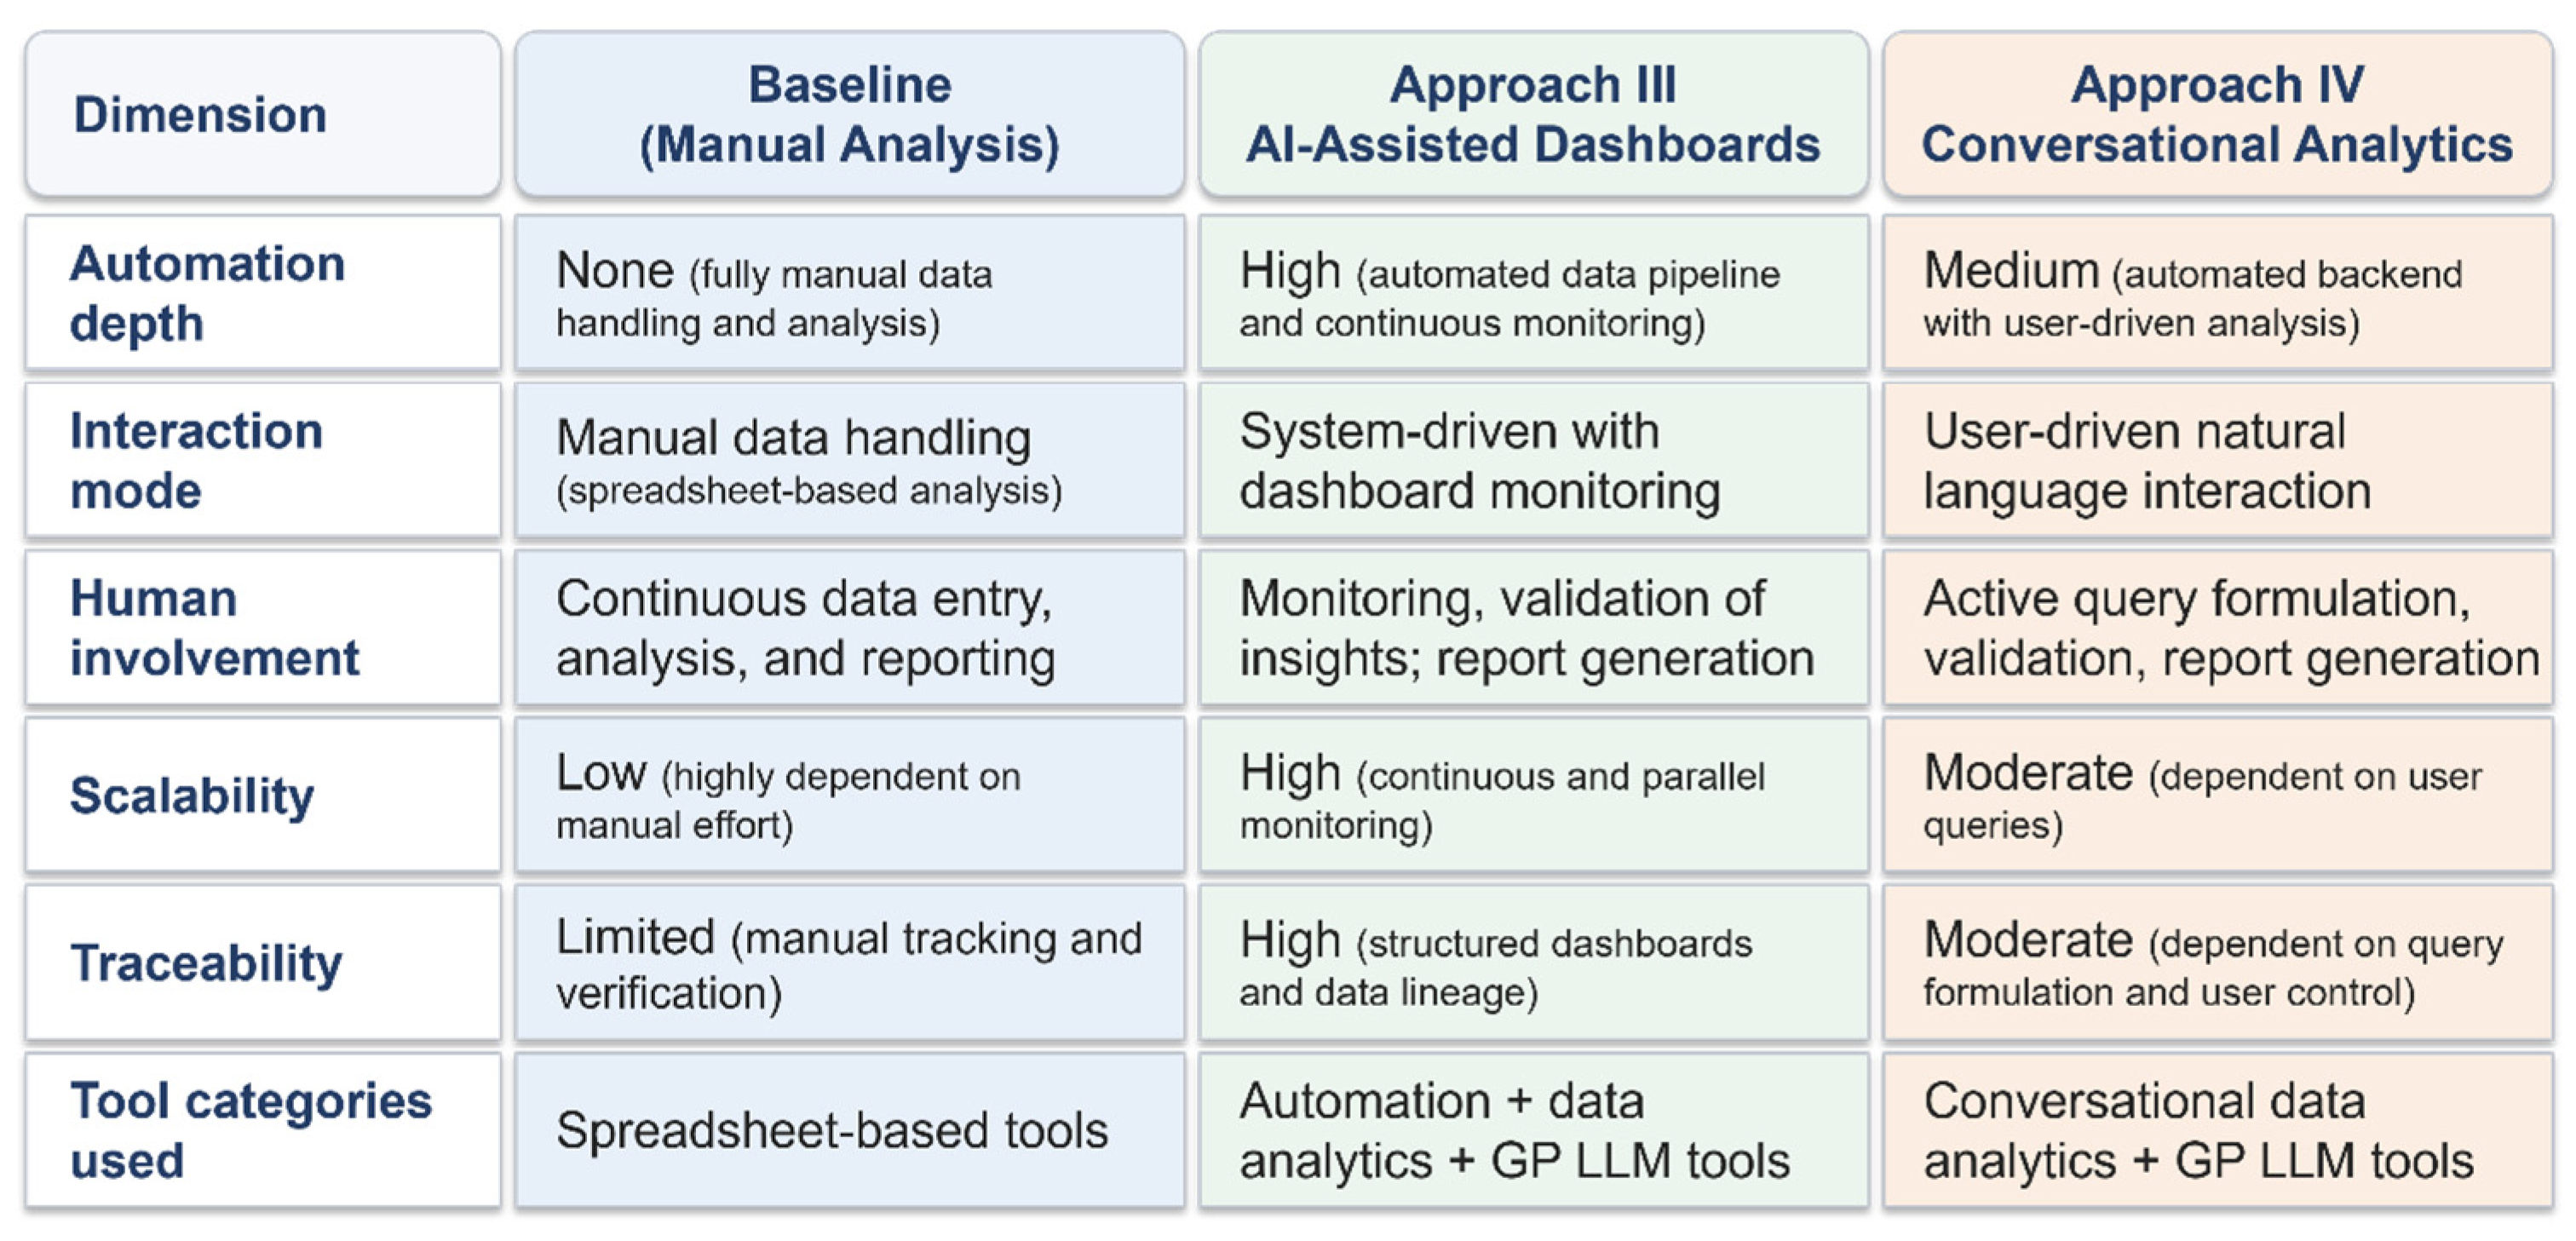
Table A1.
Technical configuration and integration characteristics of the four LLM-enabled approaches.
References
- George, L.M. Lean Six Sigma: Combining Six Sigma Quality with Lean Production Speed, 1st ed.; McGraw Hill: North Ryde, Australia, 2002. [Google Scholar]
- Antony, J.; Snee, R.; Hoerl, R. Lean Six Sigma: Yesterday, today and tomorrow. Int. J. Qual. Reliab. Manag. 2017, 34, 1073–1093. [Google Scholar] [CrossRef] [Scilit]
- Albliwi, S.; Antony, J.; Lim, S.A.H.; van der Wiele, T. Critical failure factors of Lean Six Sigma: A systematic literature review. Int. J. Qual. Reliab. Manag. 2014, 31, 1012–1030. [Google Scholar] [CrossRef] [Scilit]
- Antony, J.; Gijo, E.V.; Vinodh, S. Lean Six Sigma for Small and Medium Sized Enterprises, 1st ed.; CRC Press: Boca Raton, FL, USA, 2021. [Google Scholar]
- Macias-Aguayo, J.; Garcia-Castro, L.; Barcia, K.F.; McFarlane, D.; Abad-Moran, J. Industry 4.0 and Lean Six Sigma Integration: A Systematic Review of Barriers and Enablers. Appl. Sci. 2022, 12, 11321. [Google Scholar] [CrossRef] [Scilit]
- Skalli, D.; Cherrafi, A.; Charkaoui, A.; Chiarini, A.; Shokri, A.; Antony, J.; Garza-Reyes, J.A.; Foster, M. Integrating Lean Six Sigma and Industry 4.0: Developing a design science research-based LSS4.0 framework for operational excellence. Prod. Plan. Control 2025, 36, 1060–1086. [Google Scholar] [CrossRef] [Scilit]
- John, L.; Sampayo, M.; Peças, P. Lean & Green on Industry 4.0 Context—Contribution to Understand L&G Drivers and Design Principles. Int. J. Math. Eng. Manag. Sci. 2021, 6, 1214–1229. [Google Scholar] [CrossRef] [Scilit]
- Peças, P.; Encarnação, J.; Gambôa, M.; Sampayo, M.; Jorge, D. PDCA 4.0: A New Conceptual Approach for Continuous Improvement in the Industry 4.0 Paradigm. Appl. Sci. 2021, 11, 7671. [Google Scholar] [CrossRef] [Scilit]
- Shao, Z.; Zhao, R.; Yuan, S.; Ding, M.; Wang, Y. Tracing the evolution of AI in the past decade and forecasting the emerging trends. Expert Syst. Appl. 2022, 209, 118221. [Google Scholar] [CrossRef] [Scilit]
- Shao, M.; Basit, A.; Karri, R.; Shafique, M. Survey of Different Large Language Model Architectures: Trends, Benchmarks, and Challenges. IEEE Access 2024, 12, 188664–188706. [Google Scholar] [CrossRef] [Scilit]
- Ji, Z.; Lee, N.; Frieske, R.; Yu, T.; Su, D.; Xu, Y.; Ishii, E.; Bang, Y.J.; Madotto, A.; Fung, P. Survey of Hallucination in Natural Language Generation. ACM Comput. Surv. 2023, 55, 1–38. [Google Scholar] [CrossRef] [Scilit]
- Klesel, M.; Wittmann, H.F. Retrieval-Augmented Generation (RAG). Bus. Inf. Syst. Eng. 2025, 67, 551–561. [Google Scholar] [CrossRef] [Scilit]
- Gao, J.; Gebreegziabher, S.A.; Choo, K.T.W.; Li, T.J.-J.; Perrault, S.T.; Malone, T.W. A Taxonomy for Human-LLM Interaction Modes: An Initial Exploration in Extended Abstracts of the CHI Conference on Human Factors in Computing Systems; ACM: New York, NY, USA, 2024; pp. 1–11. [Google Scholar] [CrossRef] [Scilit]
- Kim, T.-S.; Ignacio, M.J.; Yu, S.; Jin, H.; Kim, Y.-G. UI/UX for Generative AI: Taxonomy, Trend, and Challenge. IEEE Access 2024, 12, 179891–179911. [Google Scholar] [CrossRef] [Scilit]
- Wing, J.M. The Data Life Cycle. Harv. Data Sci. Rev. 2019, 1, e26845b4. [Google Scholar] [CrossRef] [Scilit]
- Chapman, P. CRISP-DM 1.0: Step-by-Step Data Mining Guide. 2000. Available online: https://public.dhe.ibm.com/software/analytics/spss/documentation/modeler/14.2/es/CRISP-DM.pdf (accessed on 1 February 2026).
- Voehl, F.; Charron, R.; Mignosa, C.; Harrington, H.J. The Lean Six Sigma Black Belt Handbook, Tools And Methods For Process Acceleration, 1st ed.; Taylor & Francis Inc.: Oxfordshire, UK, 2013. [Google Scholar]
- Pongboonchai-Empl, T.; Antony, J.; Garza-Reyes, J.A.; Komkowski, T.; Tortorella, G.L. Integration of Industry 4.0 technologies into Lean Six Sigma DMAIC: A systematic review. Prod. Plan. Control 2024, 35, 1403–1428. [Google Scholar] [CrossRef] [Scilit]
- Peças, P.; Faustino, M.; Lopes, J.; Amaral, A. Lean methods digitization towards lean 4.0: A case study of e-VMB and e-SMED. Int. J. Interact. Des. Manuf. 2022, 16, 1397–1415. [Google Scholar] [CrossRef] [Scilit]
- Hines, P.; Tortorella, G.L.; Antony, J.; Romero, D.; Walsh, A.; Taylor, D.; Alves, A.C.; Bertolini, M.; Caiado, R.; Demeterj, K.; et al. A global industrial perspective on lean industry 4.0: A qualitative wide-angle lens approach. Prod. Plan. Control 2025, 37, 225–246. [Google Scholar] [CrossRef] [Scilit]
- Joung, J.; Jung, K.; Ko, S.; Kim, K. Customer Complaints Analysis Using Text Mining and Outcome-Driven Innovation Method for Market-Oriented Product Development. Sustainability 2018, 11, 40. [Google Scholar] [CrossRef] [Scilit]
- Martinho, R.; Lopes, J.; Jorge, D.; de Oliveira, L.C.; Henriques, C.; Peças, P. IoT Based Automatic Diagnosis for Continuous Improvement. Sustainability 2022, 14, 9687. [Google Scholar] [CrossRef] [Scilit]
- Ali, M.A.; Dornaika, F.; Charafeddine, J. Agentic AI: A comprehensive survey of architectures, applications, and future directions. Artif. Intell. Rev. 2025, 59, 11. [Google Scholar] [CrossRef] [Scilit]
- Bandi, A.; Kongari, B.; Naguru, R.; Pasnoor, S.; Vilipala, S.V. The Rise of Agentic AI: A Review of Definitions, Frameworks, Architectures, Applications, Evaluation Metrics, and Challenges. Future Internet 2025, 17, 404. [Google Scholar] [CrossRef] [Scilit]
- Wamba, S.F.; Guthrie, C.; Queiroz, M.M.; Minner, S. ChatGPT and generative artificial intelligence: An exploratory study of key benefits and challenges in operations and supply chain management. Int. J. Prod. Res. 2024, 62, 5676–5696. [Google Scholar] [CrossRef] [Scilit]
- Wamba, S.F.; Queiroz, M.M.; Jabbour, C.J.C.; Shi, C. Are both generative AI and ChatGPT game changers for 21st-Century operations and supply chain excellence? Int. J. Prod. Econ. 2023, 265, 109015. [Google Scholar] [CrossRef] [Scilit]
- Yang, W.; Some, L.; Bain, M.; Kang, B. A comprehensive survey on integrating large language models with knowledge-based methods. Knowl. Based. Syst. 2025, 318, 113503. [Google Scholar] [CrossRef] [Scilit]
- Yao, Y.; Duan, J.; Xu, K.; Cai, Y.; Sun, Z.; Zhang, Y. A survey on large language model (LLM) security and privacy: The Good, The Bad, and The Ugly. High-Confid. Comput. 2024, 4, 100211. [Google Scholar] [CrossRef] [Scilit]
- Graafmans, T.; Turetken, O.; Poppelaars, H.; Fahland, D. Process Mining for Six Sigma. Bus. Inf. Syst. Eng. 2021, 63, 277–300. [Google Scholar] [CrossRef] [Scilit]
- Dumas, M.; Fournier, F.; Limonad, L.; Marrella, A.; Montali, M.; Rehse, J.-R.; Accorsi, R.; Calvanese, D.; De Giacomo, G.; Fahland, D.; et al. AI-augmented Business Process Management Systems: A Research Manifesto. ACM Trans. Manag. Inf. Syst. 2023, 14, 1–19. [Google Scholar] [CrossRef] [Scilit]
- Vidgof, M.; Bachhofner, S.; Mendling, J. Large Language Models for Business Process Management: Opportunities and Challenges. In Business Process Management Forum; Springer: Berlin/Heidelberg, Germany, 2023; pp. 107–123. [Google Scholar] [CrossRef] [Scilit]
- OMG. Business Process Model and Notation (BPMN), Version 2.0.2; Object Management Group (OMG): Milford, MA, USA, 2013; Available online: http://www.omg.org/oceb-2/ (accessed on 4 March 2026).
- ISO 15489-1:2016; Information and Documentation—Records Management—Part 1: Concepts and Principles. International Organization for Standardization (ISO): Geneva, Switzerland, 2016.
- ISO 16175-1:2020; Information and Documentation—Processes and Functional Requirements for Software for Managing Records—Part 1: Functional Requirements and Associated Guidance for any Applications that Manage Digital Records. International Organization for Standardization (ISO): Geneva, Switzerland, 2020.
- Healy, S. ISO 15489 Records Management: Its development and significance. Rec. Manag. J. 2010, 20, 96–103. [Google Scholar] [CrossRef] [Scilit]
- Giménez-Chornet, V. UNE-ISO 16175 on document management in the paperless office: Scope and limitations. Prof. Inf. 2013, 22, 455–458. [Google Scholar] [CrossRef] [Scilit]
- Oliver, G.; Foscarini, F. The value of international standards for records management: Perspectives from education and training. Arch. Manuscr. 2015, 43, 181–193. [Google Scholar] [CrossRef] [Scilit]
- Varriale, V.; Cammarano, A.; Michelino, F.; Caputo, M. Critical analysis of the impact of artificial intelligence integration with cutting-edge technologies for production systems. J. Intell. Manuf. 2025, 36, 61–93. [Google Scholar] [CrossRef] [Scilit]
- NIST. Artificial Intelligence Risk Management Framework (AI RMF 1.0); NIST AI 100-1; U.S. Department of Commerce: Washington, DC, USA, 2023. [CrossRef] [Scilit]
- Fahland, D.; Fournier, F.; Limonad, L.; Skarbovsky, I.; Swevels, A.J.E. How well can a large language model explain business processes as perceived by users? Data Knowl. Eng. 2025, 157, 102416. [Google Scholar] [CrossRef] [Scilit]
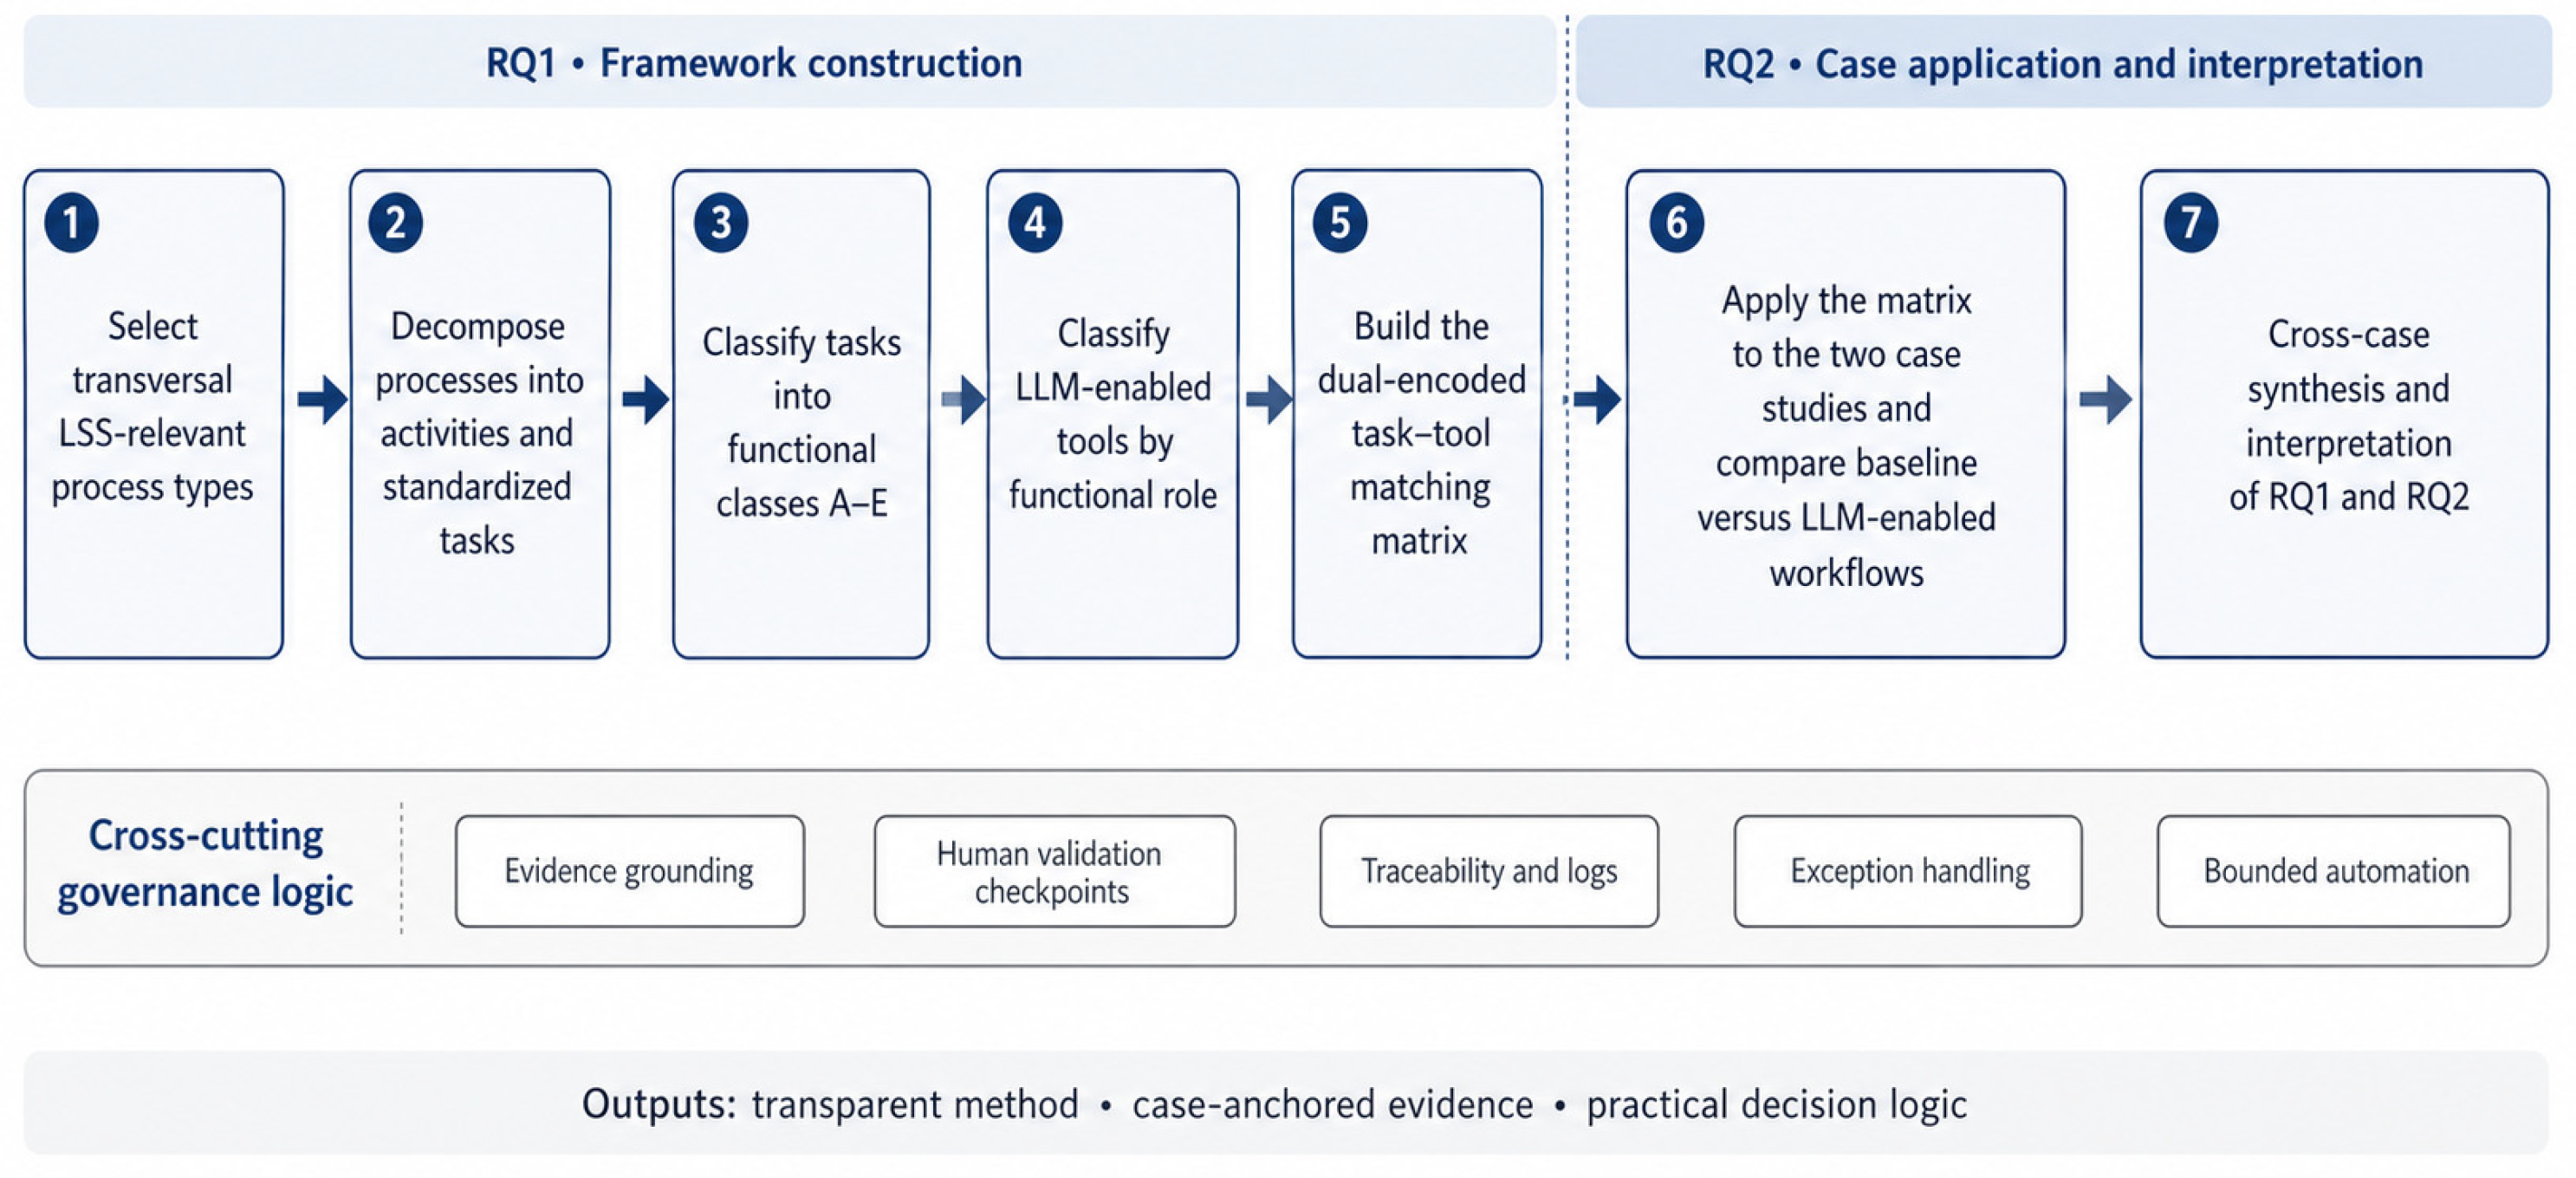
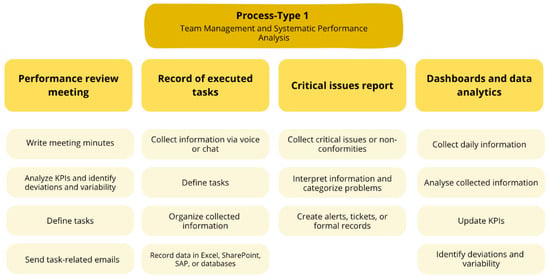
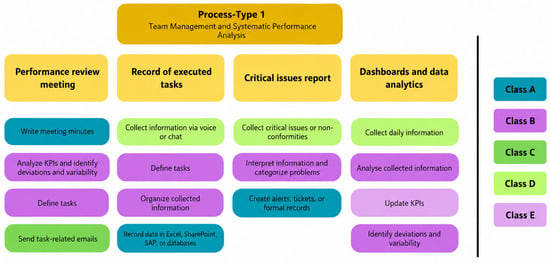
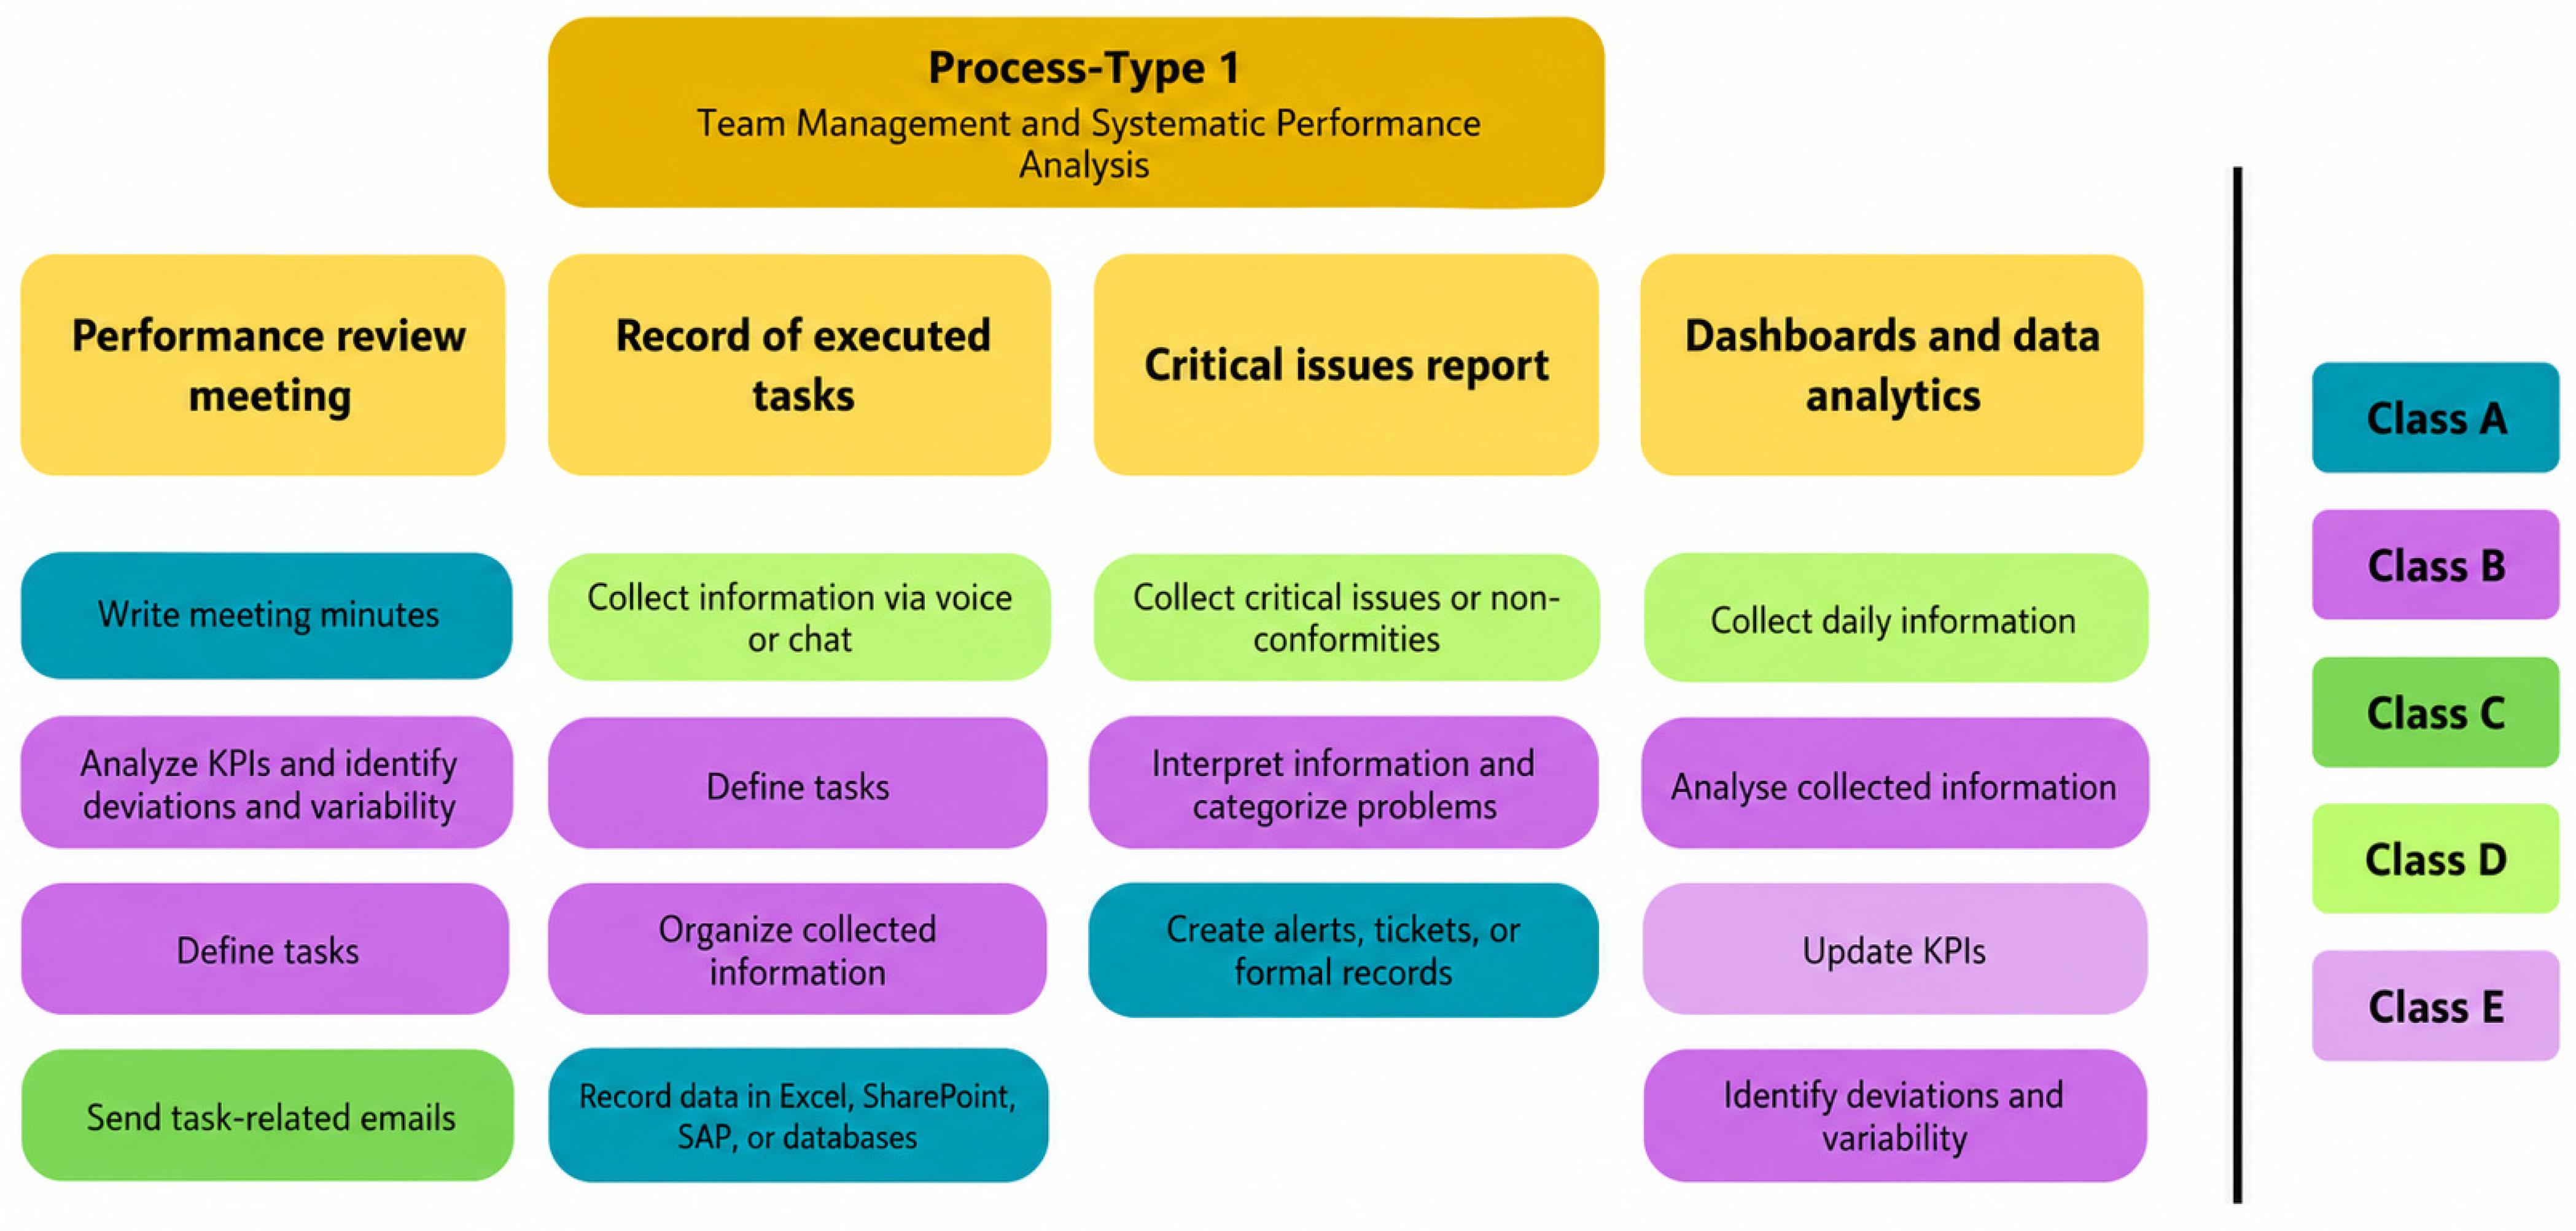
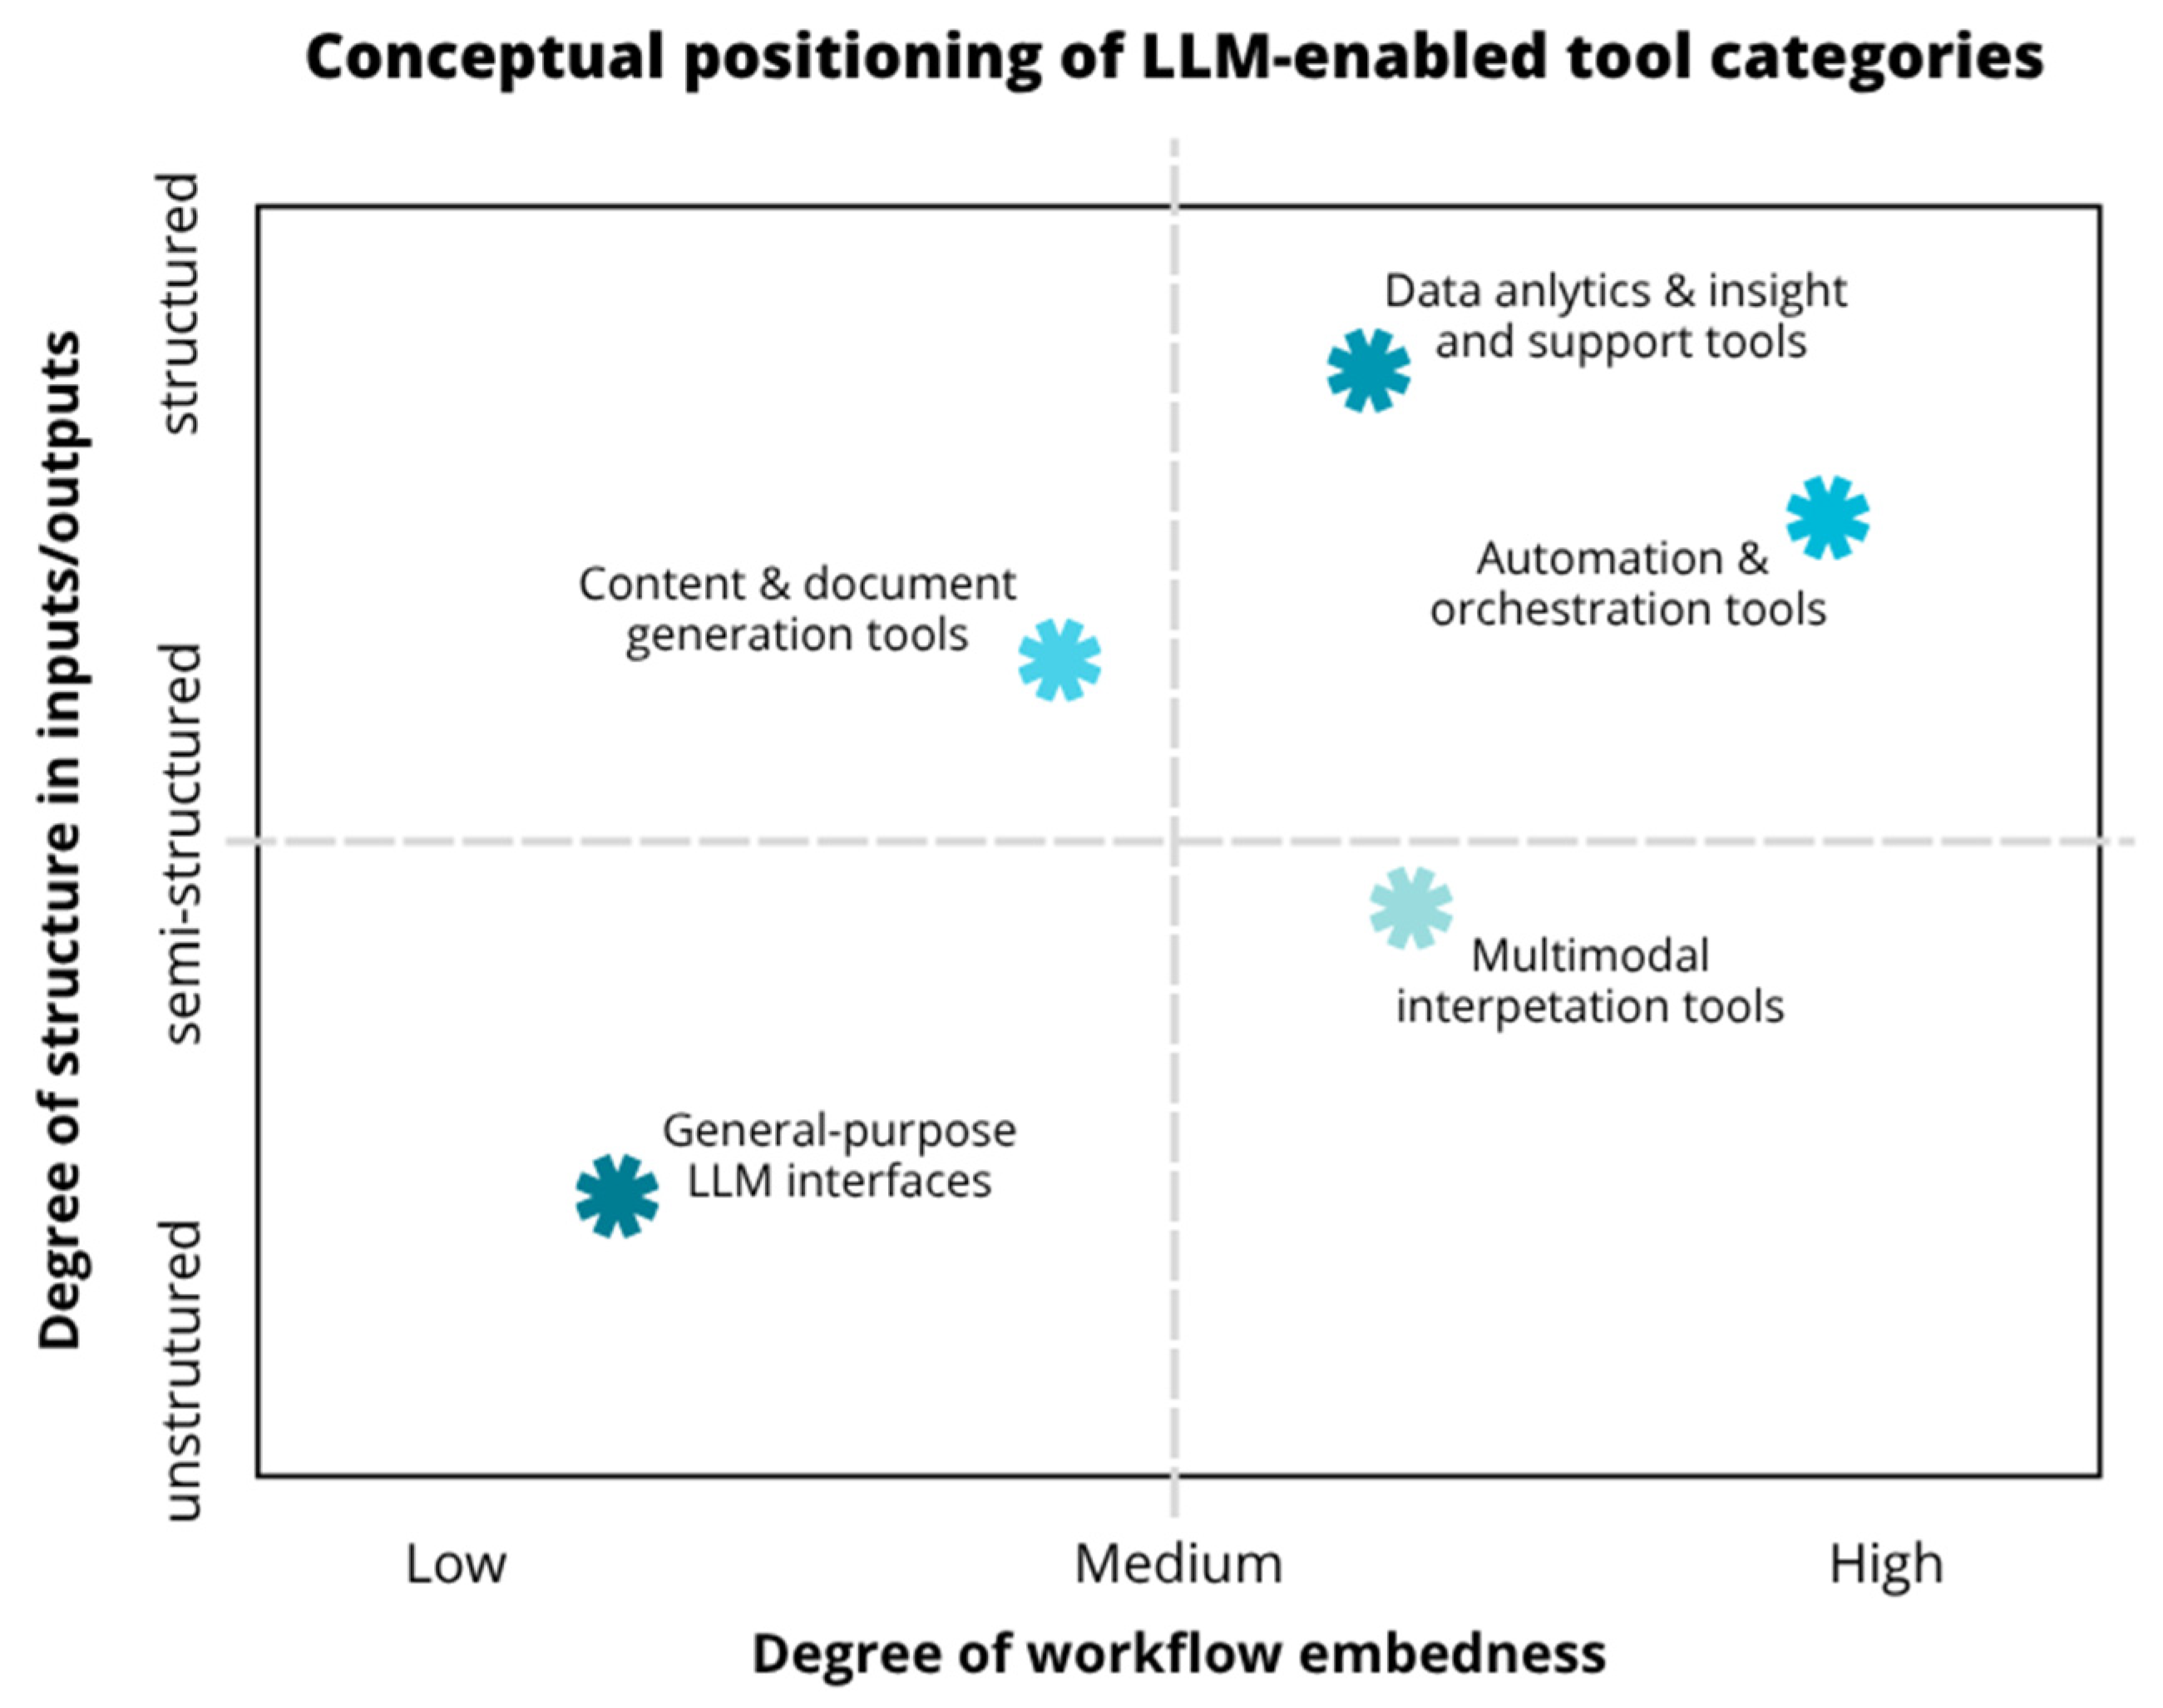
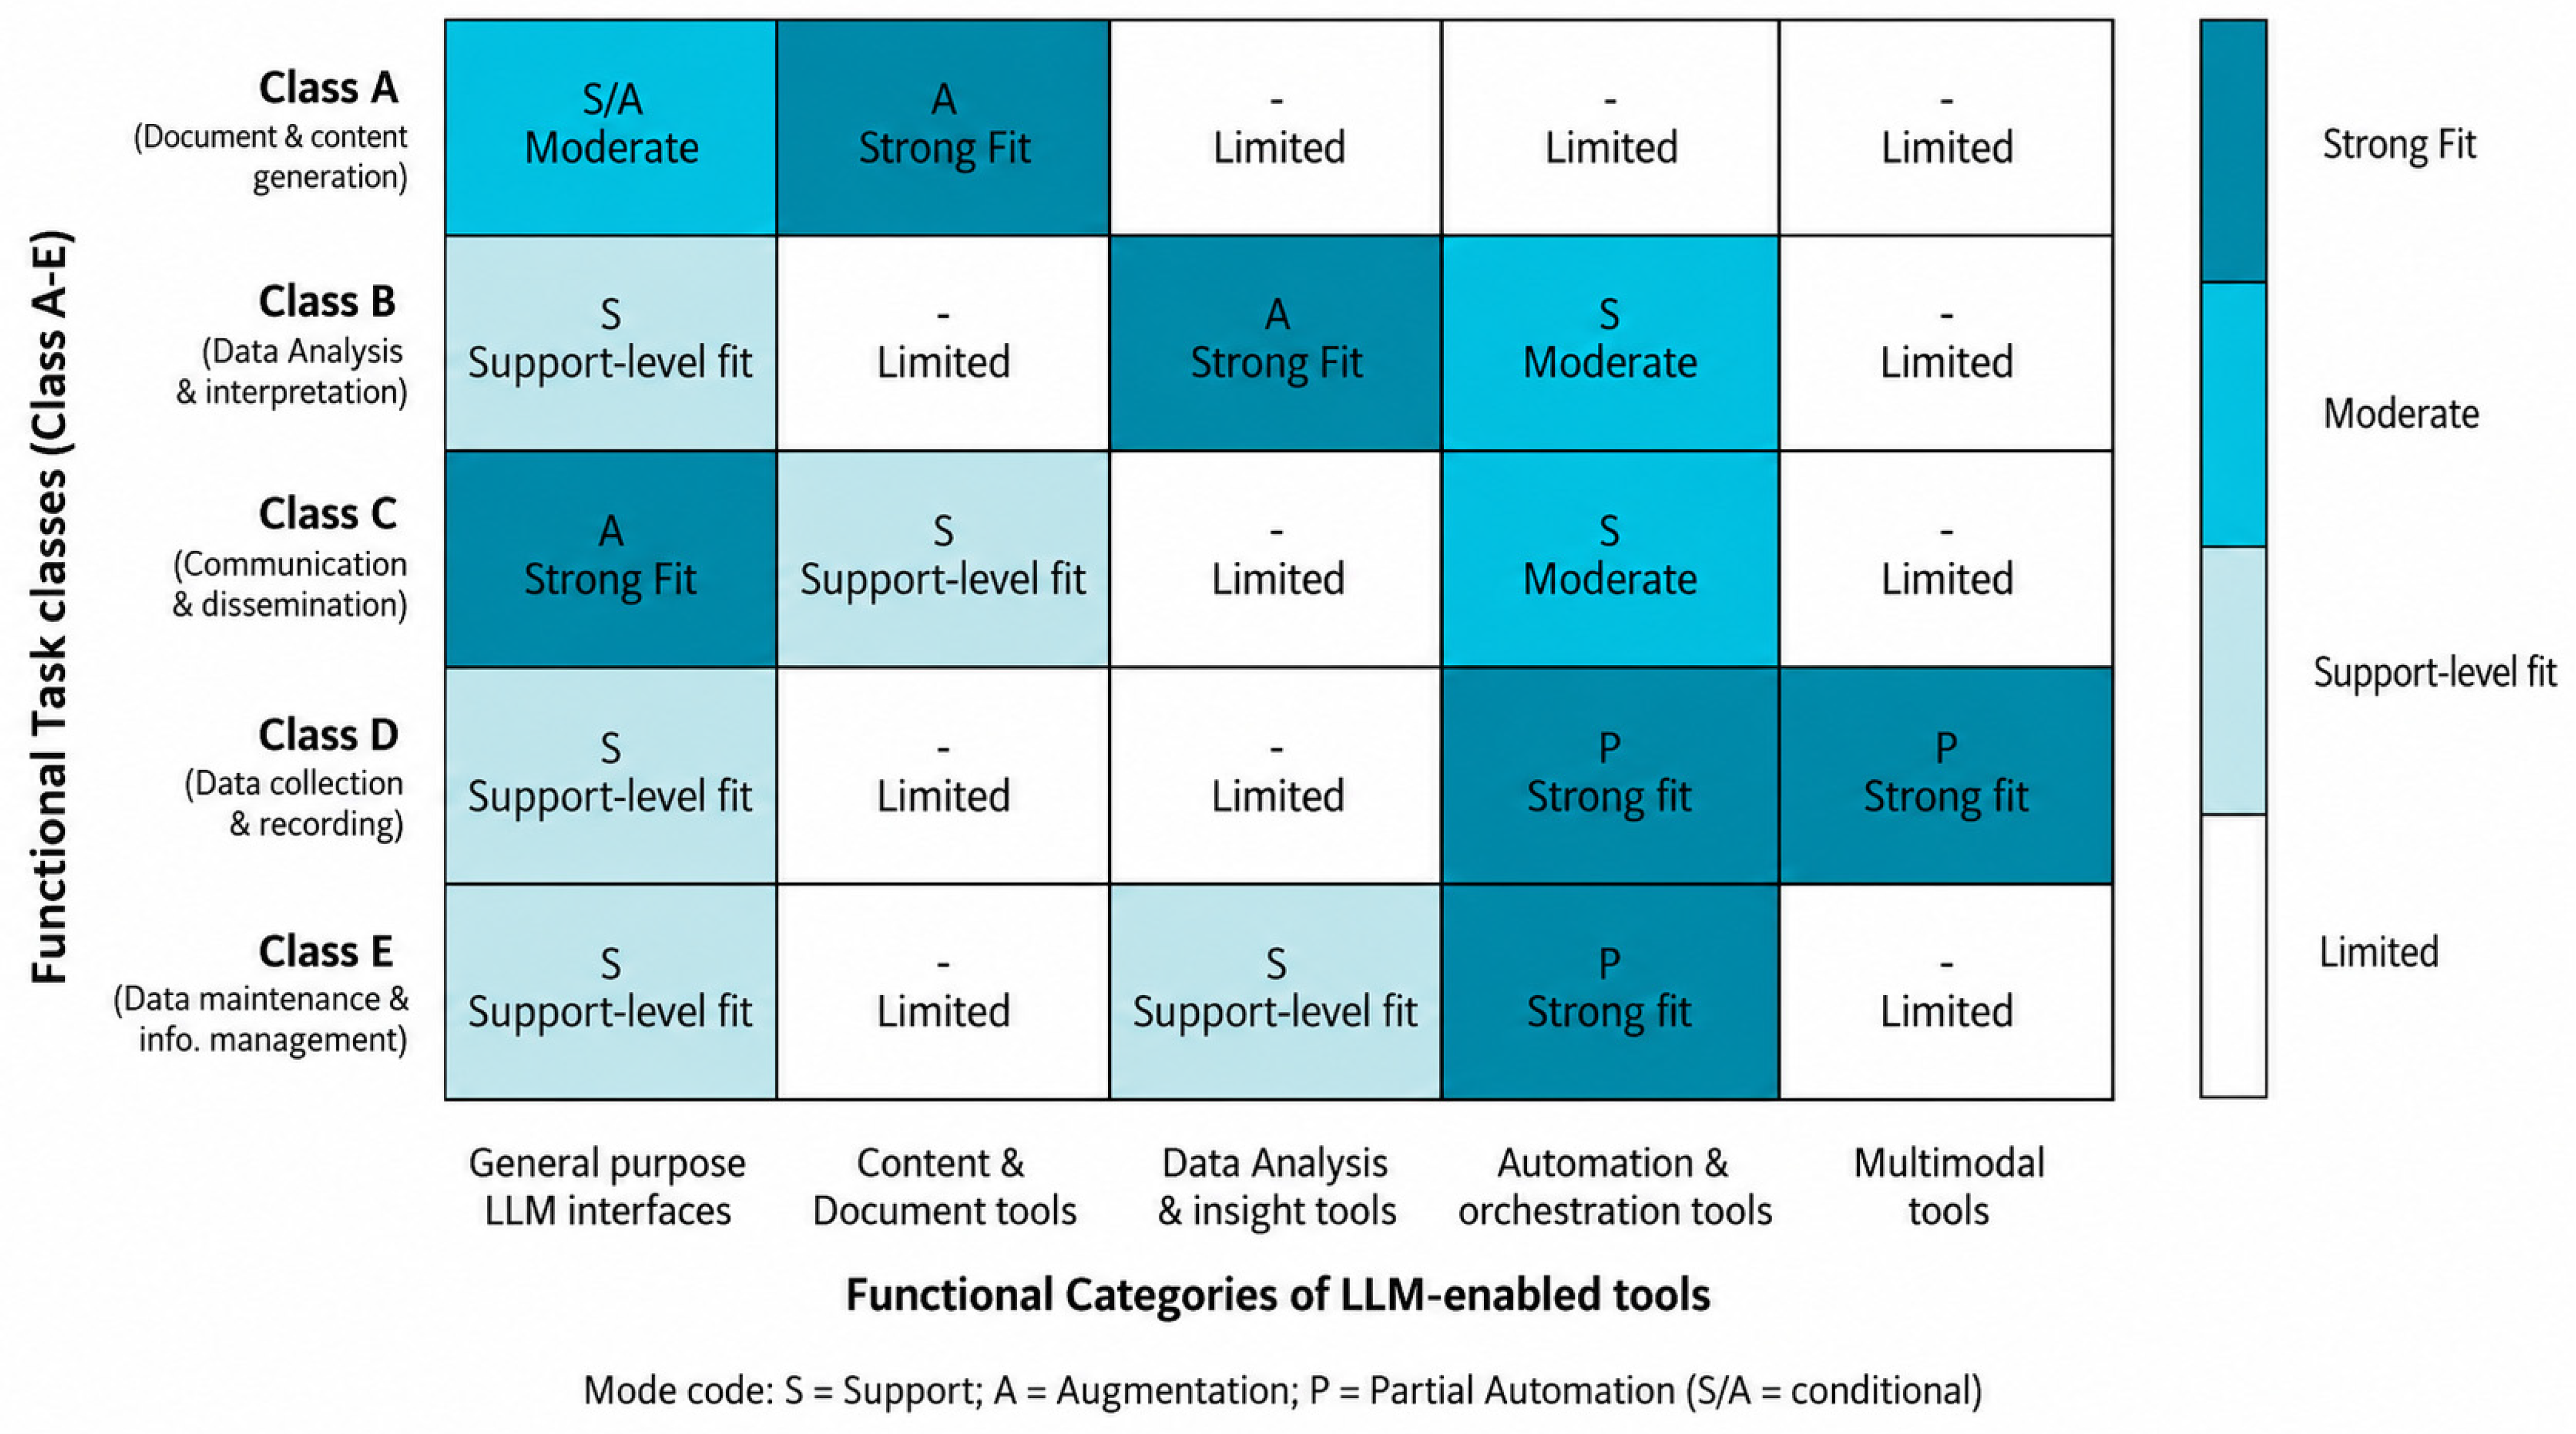
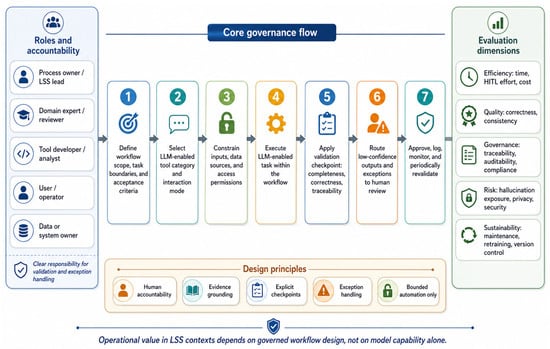
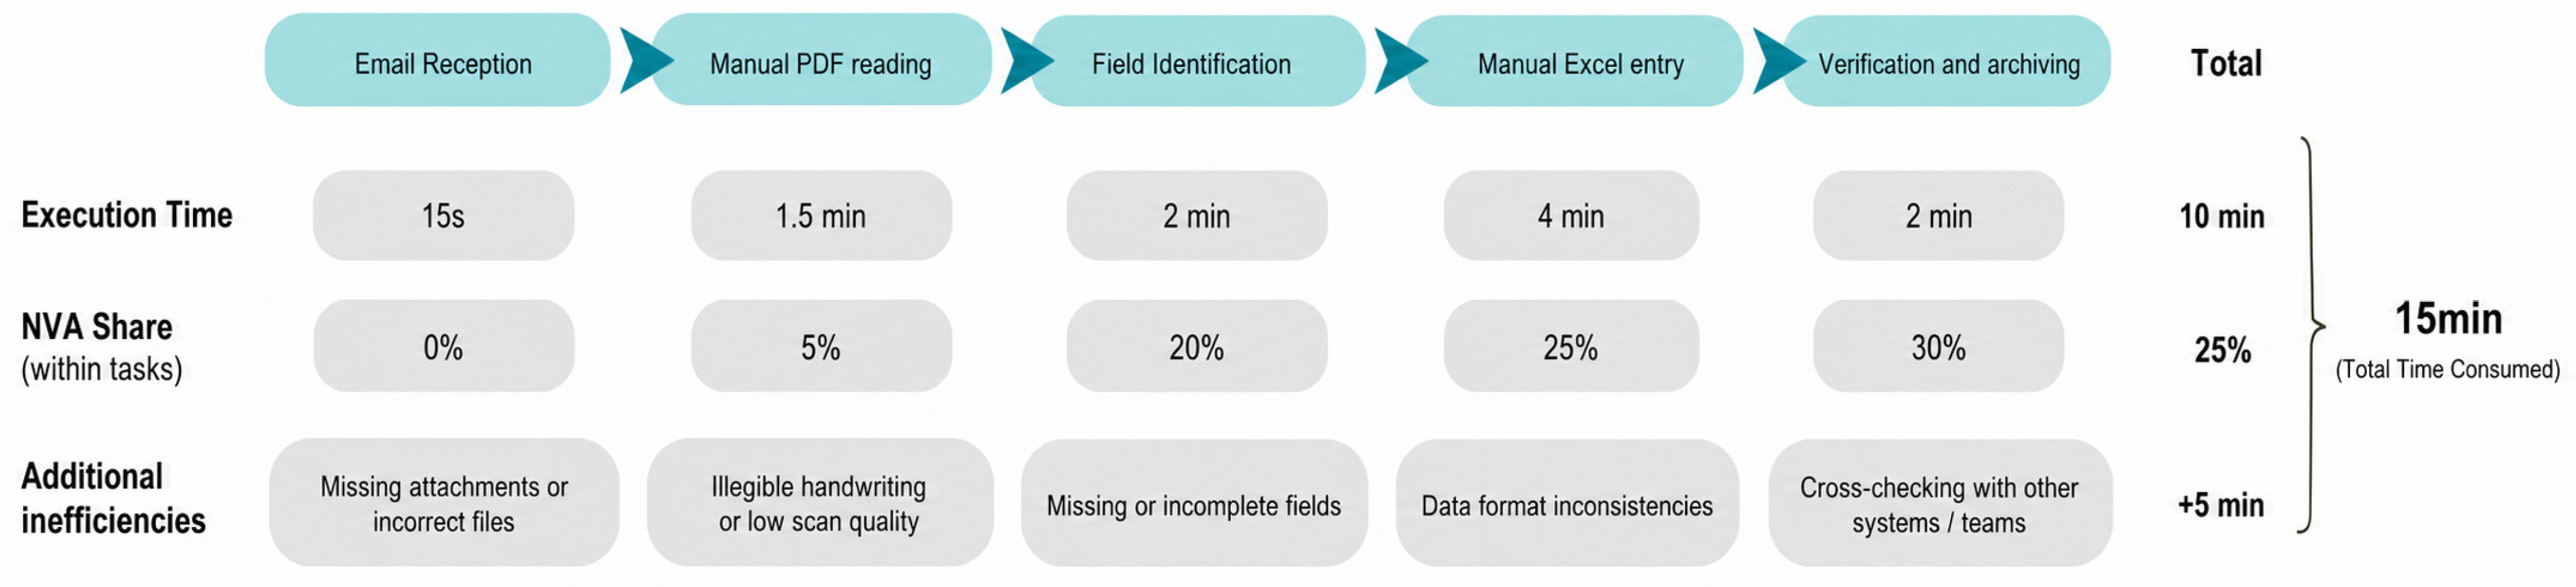
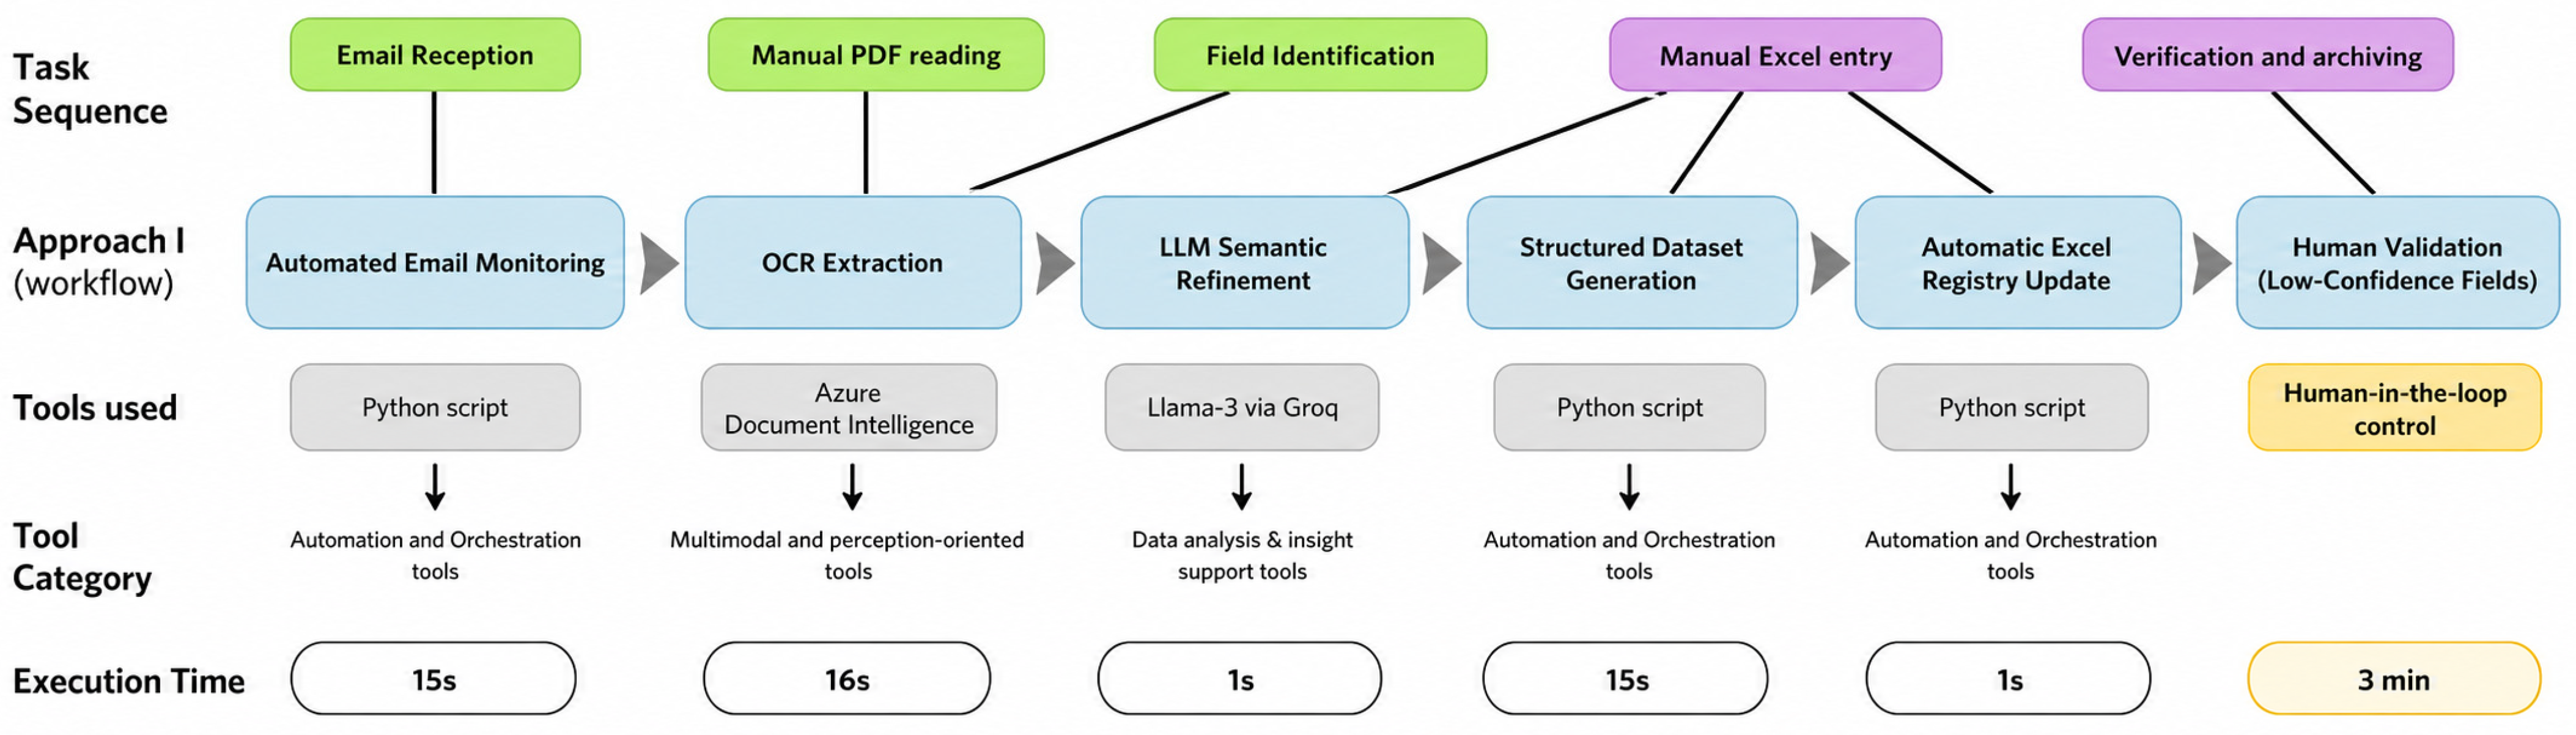
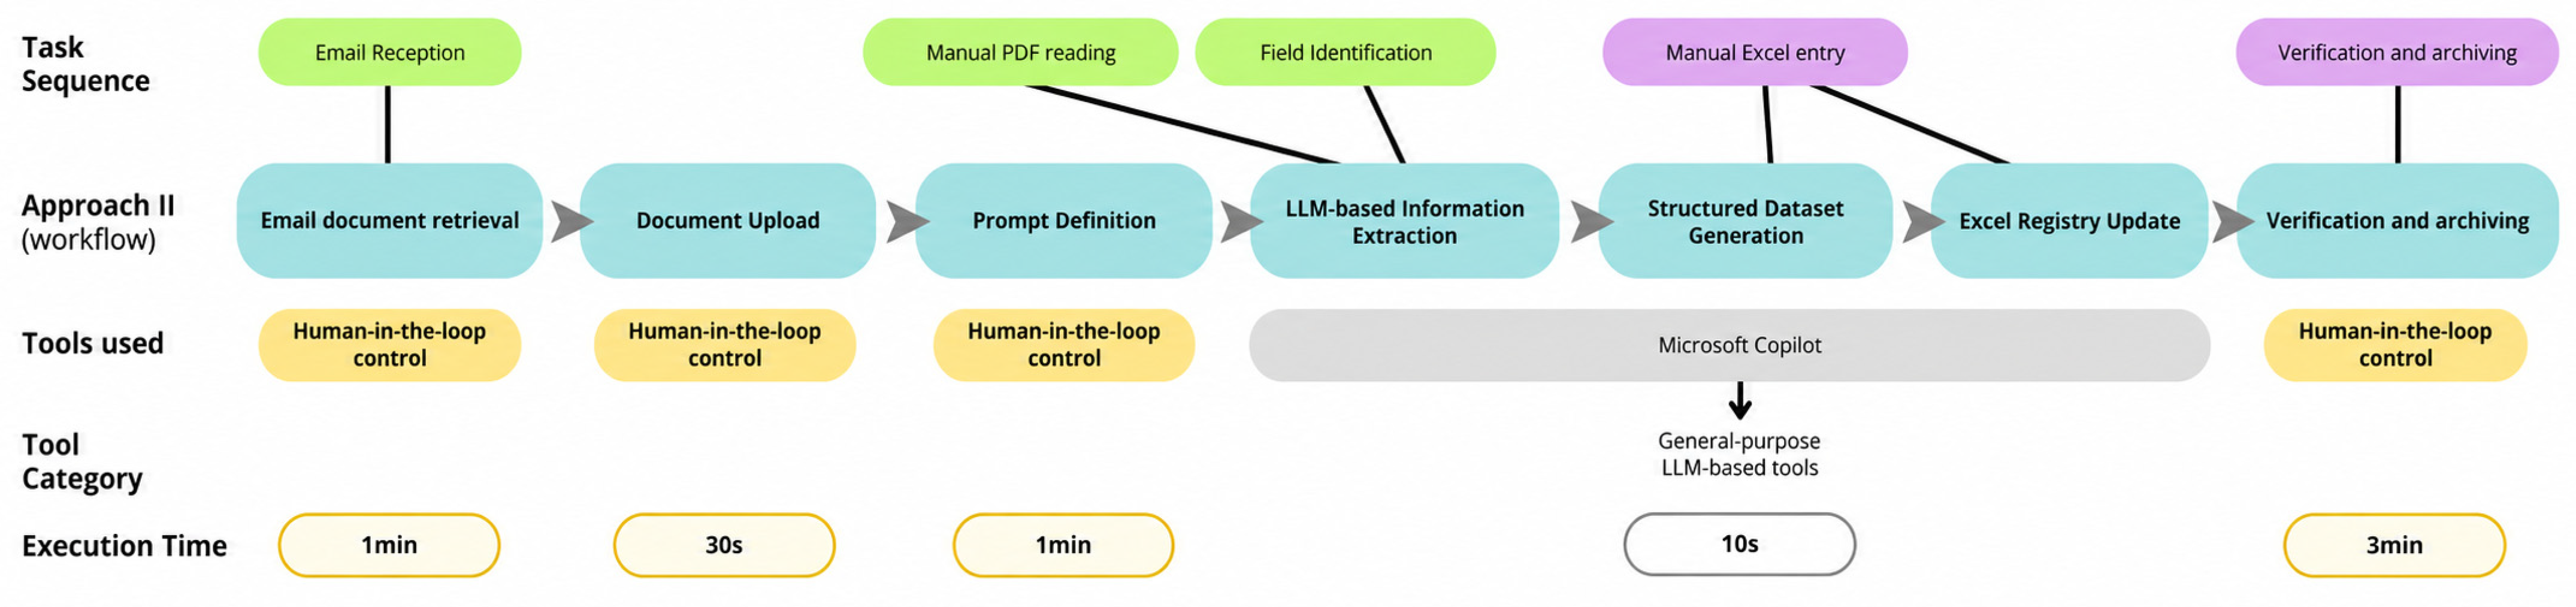
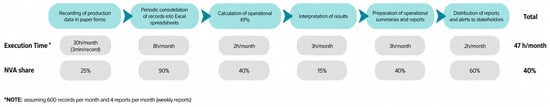
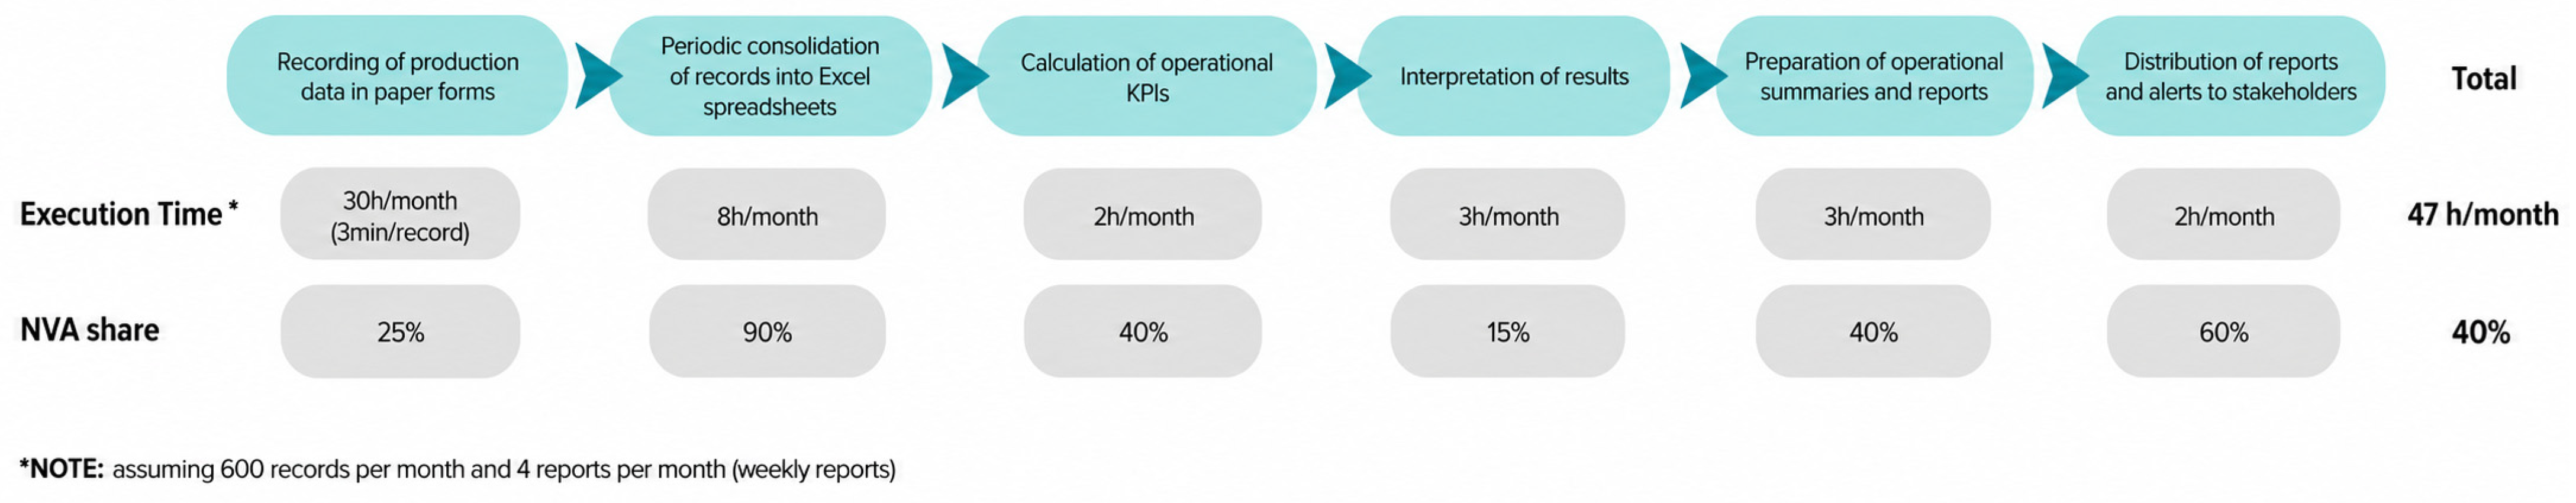
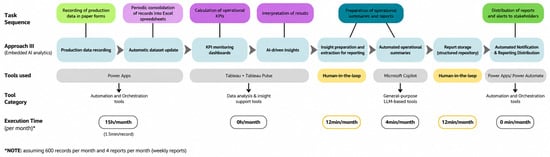
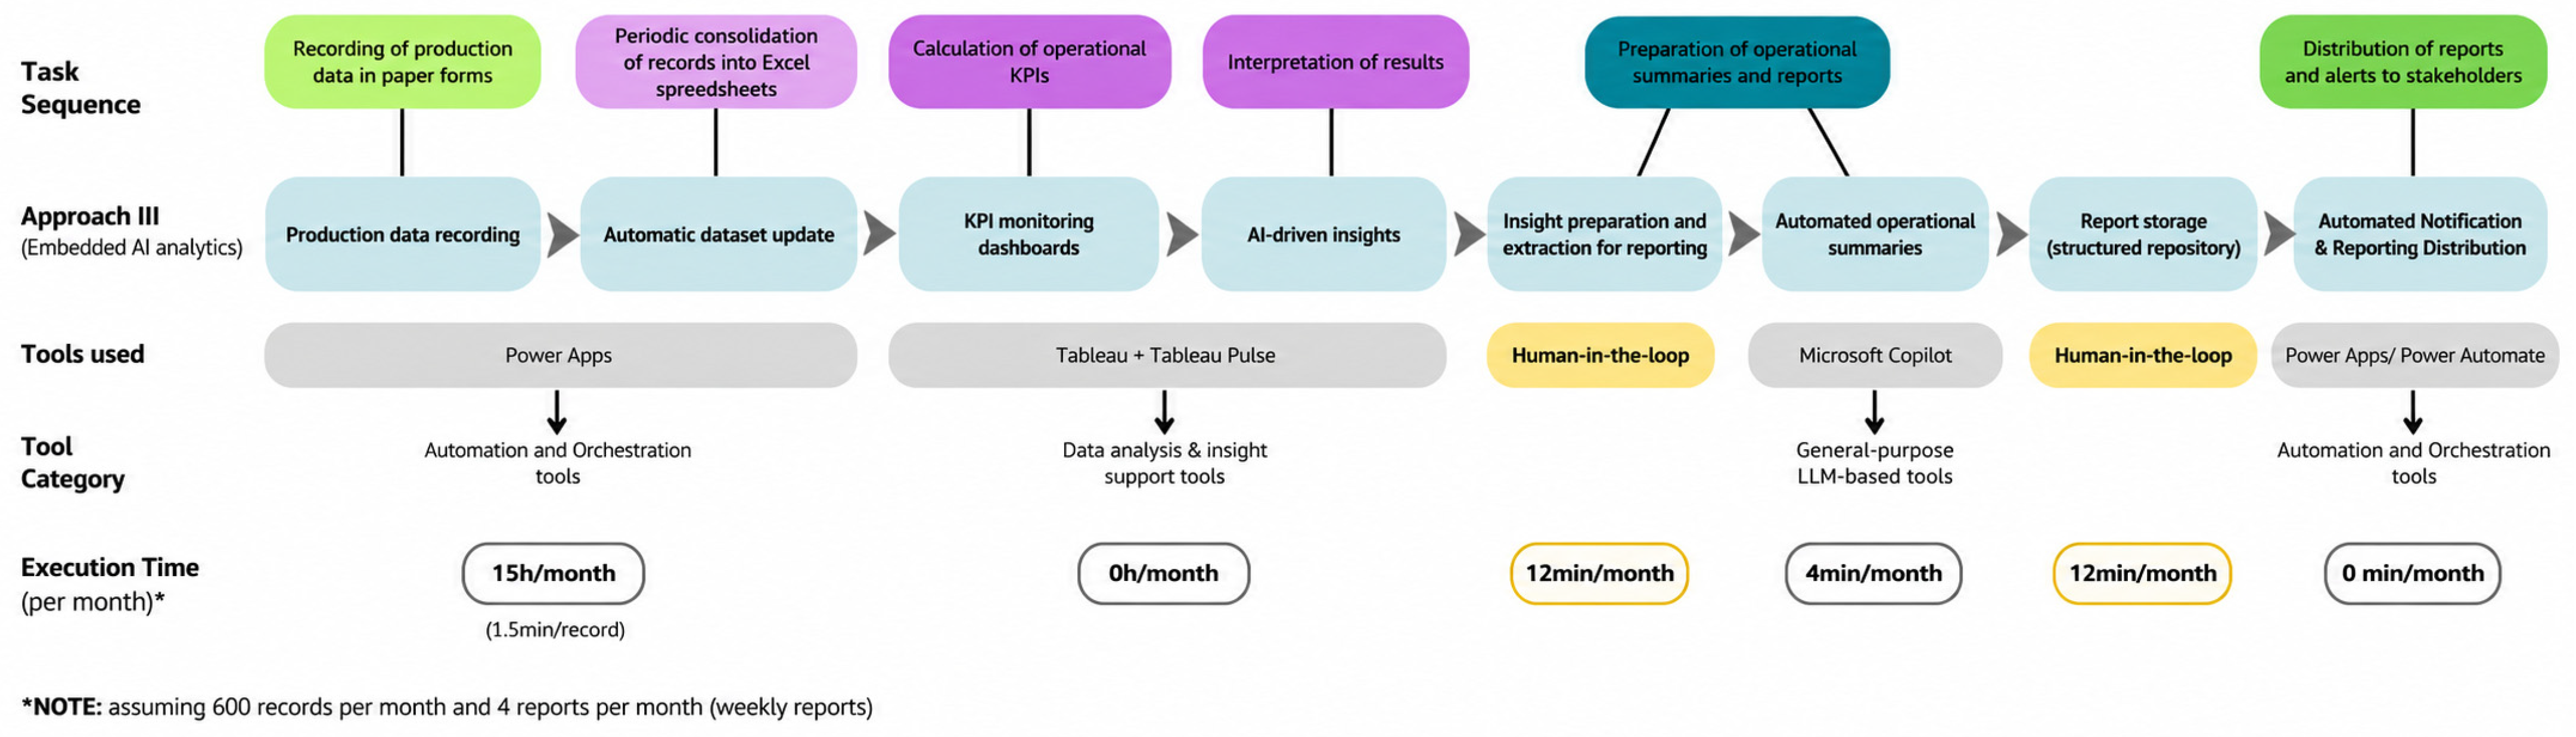
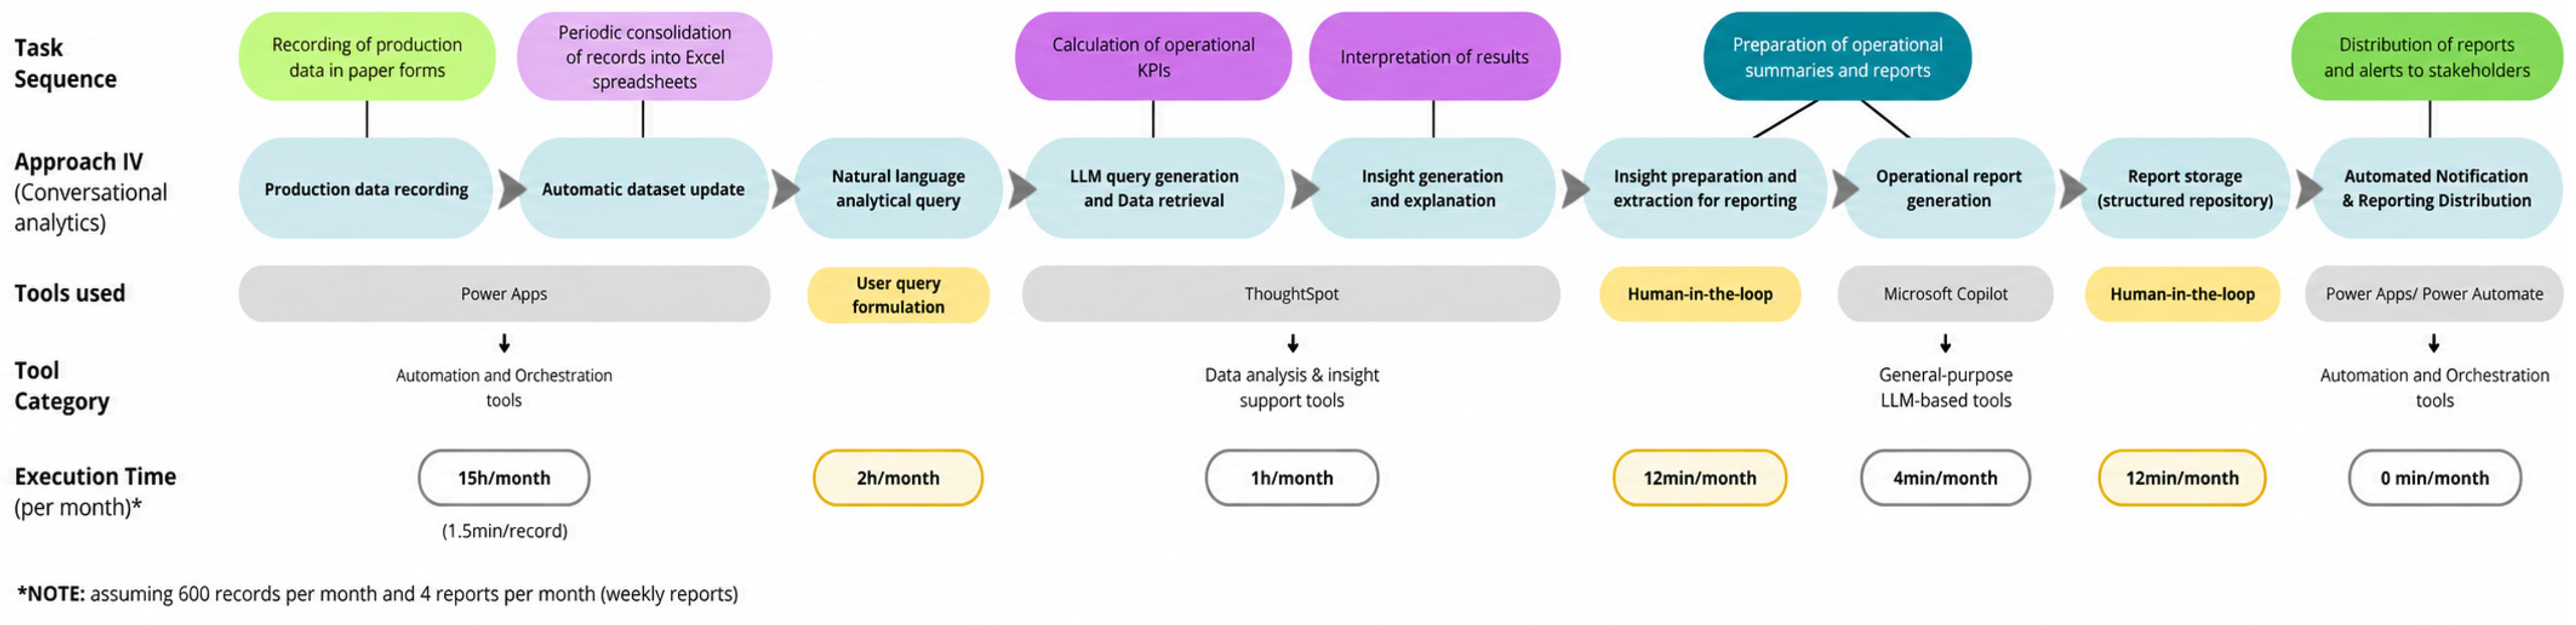
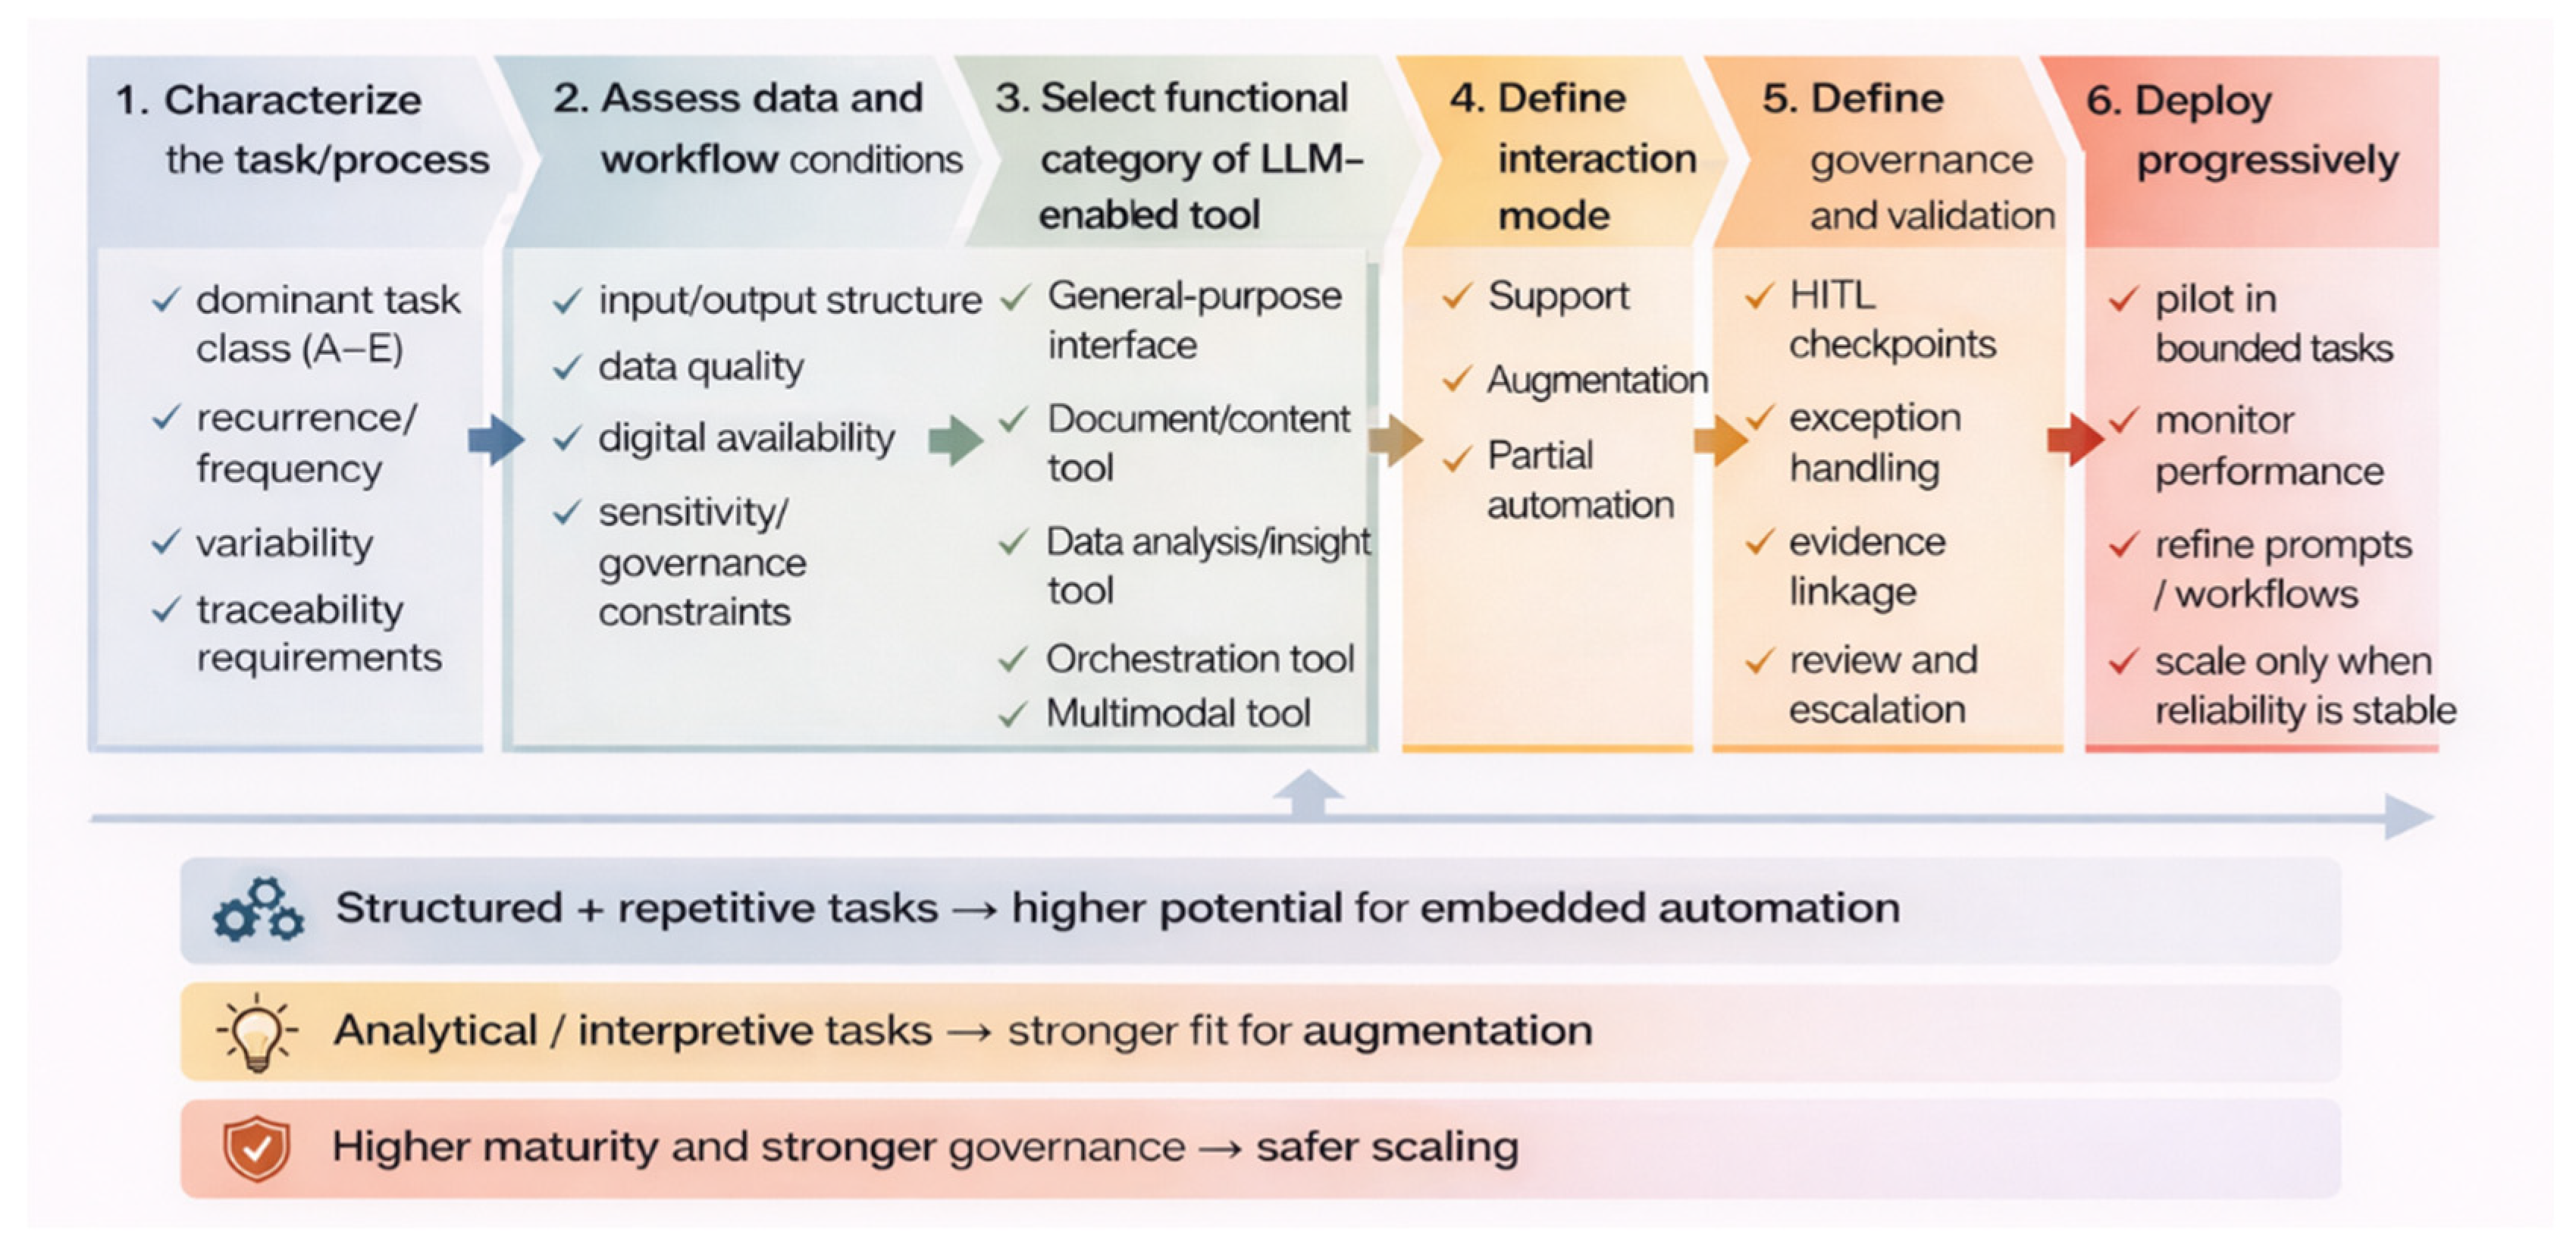

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.