1. Introduction
Learning Management Systems (LMSs) have become essential components of modern higher education, providing web-based platforms that support teaching, learning, assessment, and institutional administration [
1]. Their accessibility enables flexible and continuous engagement with learning resources while supporting collaborative learning through discussion forums, quizzes, live chats, and virtual classrooms [
2,
3,
4]. The rapid expansion of online learning, accelerated by the COVID-19 pandemic, has further reinforced the importance of LMSs in ensuring educational continuity and promoting student-centred learning [
5,
6]. Empirical studies have consistently shown that both active participation and passive engagement, such as frequent access to course materials and discussion forums, are passively associated with academic performance and deeper learning [
7].
The widespread adoption of LMS has generated large volumes of student interaction data, including behavioural, cognitive, and performance-related information. Learning analytics leverages these data to identify engagement patterns, personalise learning experiences, and support the early identification of students at risk of poor academic performance or dropout [
8]. Furthermore, advances in artificial intelligence (AI) and machine learning have enhanced the ability of higher education institutions to analyse LMS data and support data-driven educational decision-making [
9,
10]. Despite these developments, LMS data remain underutilised for predicting specific engagement behaviours such as student forum consumption, while the high dimensionality, sparsity, redundancy, and nonlinear complexity of LMS datasets continue to challenge predictive accuracy and model generalisability [
2,
7,
11].
Deep learning models have demonstrated strong predictive performance by learning complex nonlinear patterns from educational data [
12]. However, these approaches often function as computationally intensive “black-box” models with limited interpretability. Likewise, conventional dimensionality reduction and feature selection methods exhibit important limitations. Principal Component Analysis (PCA) improves computational efficiency by transforming variables into latent components but obscures the semantic meaning of the original engagement indicators [
13,
14]. Recursive Feature Elimination (RFE) and mutual information-based methods primarily evaluate variables individually or through pairwise relationships, limiting their ability to capture higher-order behavioural interactions that are informative only when variables act together [
15,
16]. Similarly, filter-based approaches may overlook interaction-dependent features, while post hoc explainability techniques such as Shapley Addictive exPlanations (SHAP) and Local Interpretable Model-agnostic Explanations (LIME) explain model predictions without explicitly modelling interaction structures. Generalised Addictive Models (GAMs) improve interpretability through nonlinear additive effects but remain limited in representing complex cooperative interactions unless interaction terms are manually specified [
17]. These limitations are particularly important in LMS environments, where behavioural, cognitive, and social engagement are inherently interconnected [
18,
19].
Feature selection (FS) techniques are commonly classified into three categories: filter, embedded, and wrapper methods, each differing in the extent to which they interact with the learning algorithm. Filter methods are model-independent and rank features using statistical measures without involving a predictive model. Although computationally efficient, they may retain redundant features because dependencies and interactions among variables are not explicitly considered [
20]. Embedded methods incorporate FS directly into the model training process, enabling simultaneous FS and model construction. While computationally efficient, they are inherently algorithm-specific and often produce model-specific feature importance rather than explicit feature subsets, limiting interpretability and cross-model comparison. In contrast, wrapper methods evaluate candidate feature subsets based on the predictive performance of a learning algorithm, selecting those that maximise prediction accuracy and generalisability [
21]. By considering feature interactions during the search process, wrapper methods typically produce feature subsets that are better aligned with the learning algorithm, thereby improving predictive performance while retaining a compact and interpretable set of predictors.
Despite the growing use of machine learning techniques in educational data mining, accurately predicting student engagement from LMS interaction data remains challenging because engagement indicators are often multidimensional, highly correlated, and may contain redundant information, which can reduce predictive performance and model interpretability. Although previous studies have demonstrated an association between LMS engagement metrics and academic outcomes, comparatively few have systematically investigated the combined role of feature optimisation and ensemble learning for predicting students’ forum consumption behaviour. Consequently, there remains a need for predictive frameworks capable of identifying the most informative engagement indicators while maintaining robust predictive performance and producing interpretable insights that can support educational decision-making [
22,
23].
FS has therefore emerged as an important preprocessing step in predictive modelling because it reduces feature redundancy, improves computational efficiency, enhances model interpretability, and frequently improves performance by retaining only the most informative variables [
24]. Among wrapper-based optimisation techniques, BIO-inspired algorithms have demonstrated considerable success in identifying optimal feature subsets for complex, high-dimensional datasets owing to their adaptive search capabilities and ability to balance exploration and exploitation during optimisation [
25,
26]. In particular, ACO has shown considerable promise for wrapper-based FS by efficiently exploring the feature space and identifying informative combinations of predictors while avoiding premature convergence to locally optimal solutions [
27].
Motivated by limitations of traditional FS and engagement modelling methods, which often fail to account for the complex, nonlinear, and interdependent nature of student interactions in LMS environments, this study proposes a hybrid ACO–ensemble learning framework for predicting students’ forum consumption behaviour using LMS-derived engagement indicators. Guided by EDM and SLT, behavioural, cognitive, and social engagement indicators are operationalised as measurable predictors of forum consumption behaviour.
Within the proposed framework, ACO performs wrapper-based FS to identify an optimal subset of engagement indicators before model development. The selected features are subsequently evaluated using three complementary ensemble regression algorithms: Random Forest (RF), Gradient Boosting (GB), and Stacking, which represent the bagging, boosting, and meta-learning paradigms, respectively [
28]. This comparative strategy enables evaluation of the effectiveness and robustness of optimised feature subsets across different ensemble learning mechanisms while supporting interpretability and reducing feature redundancy. By integrating feature optimisation with ensemble learning, the proposed framework seeks to improve prediction accuracy, reduce feature redundancy, and provide theoretically grounded insights into the engagement behaviours associated with students’ forum consumption in online learning environments.
The remainder of this paper is organised as follows:
Section 2 provides a review of the relevant literature,
Section 3 details materials and methods,
Section 4 presents and analyses the results,
Section 5 discusses the implications of the findings, and
Section 6 concludes the paper and outlines directions for future research.
3. Materials and Methods
3.1. Theoretical Framework
The study is situated within a positivist research paradigm, which emphasises objective measurement, empirical observation, and the quantitative evaluation of phenomena [
56]. The paradigm is particularly appropriate for EDM, where large-scale LMS interaction data are systematically analysed to identify behavioural patterns and evaluate predictive models using objective performance metrics.
The study is further informed by EDM and Social Learning Theory (SLT), which collectively provide the conceptual basis for modelling students’ forum consumption behaviour. EDM focuses on extracting meaningful knowledge from educational databases by analysing students’ digital learning traces to understand learning behaviour and support data-informed educational decision-making [
54]. Within LMS environments, these digital traces represent observable indicators of students’ engagement with learning resources, course activities, and collaborative interactions.
SLT proposes that learning occurs through observation, interaction, and participation within collaborative environments [
52,
53]. In online learning environments, discussion forums provide opportunities for students to observe peer interactions, exchange ideas, and construct knowledge collaboratively. Consequently, forum consumption behaviour is viewed as an important manifestation of students’ engagement within collaborative learning environments.
Consistent with these theoretical perspectives, this study conceptualises student engagement as a multidimensional construct comprising behavioural, cognitive, and social engagement, operationalised using observable LMS interaction data. These engagement dimensions provide the theoretical foundation for selecting predictor variables used to model students’ forum consumption behaviour.
3.2. Dataset Description
This study uses a simulated dataset of students’ online engagement and academic achievement throughout a programme of study. The dataset was developed based on findings from a published study that analysed student interaction logs obtained from a university Moodle Learning Management System (LMS) for the period 2015–2018. The original data were used to derive indicators of learning-activity frequency, session activity, total online duration, active days, and activity regularity [
57]. The resulting dataset was imported into a Jupyter Notebook using the Python Pandas library (version 2.x) for preprocessing and analysis. Jupyter Notebook (
https://jupyter.org/) is an open-source, web-based interactive computing environment that supports data analysis and scientific computing.
The simulated dataset contains 1136 student course records representing 142 students across eight sequential courses. For the present study, Freq_Forum_Consume, representing the number of forum posts viewed, was used as the target variable. After removing Regularity_Forum_Consume and Final_Grade to address potential target overlap and future information concerns, nine LMS engagement indicators were retained as predictors.
In the source study, engagement indicators were analysed using Latent Class Analysis (LCA) to classify students as Active, Average, or Disengaged, and final grades as Achiever, Intermediate, or Low. These classifications provide context for the construction of the simulated dataset but were not used as predictors in the present study [
57]. The dataset is distributed under a CC BY 4.0 licence.
Table 1 presents the definitions and descriptive statistics of the variables used in the analysis. The descriptive statistics include the number of observations, mean, standard deviation, minimum, first quartile, median, third quartile, and maximum. All nine predictors and the target feature contain 1136 observations, with no missing observations in the features included in the modelling analysis.
3.3. Research Design
The study employed a quantitative, comparative predictive modelling design to investigate the effect of ACO-guided FS on predicting students’ forum consumption behaviour using LMS engagement indicators. Three complementary ensemble regression algorithms—RF, GB, and Stacking—were first developed as baseline models using the nine retained LMS engagement predictors. A corresponding ACO–ensemble model was then developed for each algorithm, with ACO performing wrapper-based FS before training the respective regression model.
The research design enabled a systematic comparison between models trained using the full set of nine predictors and their corresponding ACO–ensemble models trained using reduced feature subsets. This comparison addressed the study objectives by examining the effect of ACO-guided FS on predictive performance and feature reduction, identifying informative engagement indicators, and assessing the consistency of the selected feature subsets across different ensemble learning algorithms. The resulting feature reduction also provided a more parsimonious predictor space for interpreting the engagement indicators associated with students’ forum consumption behaviour.
The comparison design specifically addresses four objectives:
To evaluate the effect of ACO-based FS on the predictive performance of ensemble regression models for forum consumption behaviour.
To identify informative behavioural, cognitive, and social LMS engagement indicators associated with forum consumption behaviour.
To assess the consistency of ACO-selected feature subsets across complementary ensemble learning algorithms and tested ACO parameter configurations.
To examine the relationship between feature-space reduction and predictive performance, with emphasis on developing a more parsimonious and interpretable predictor set.
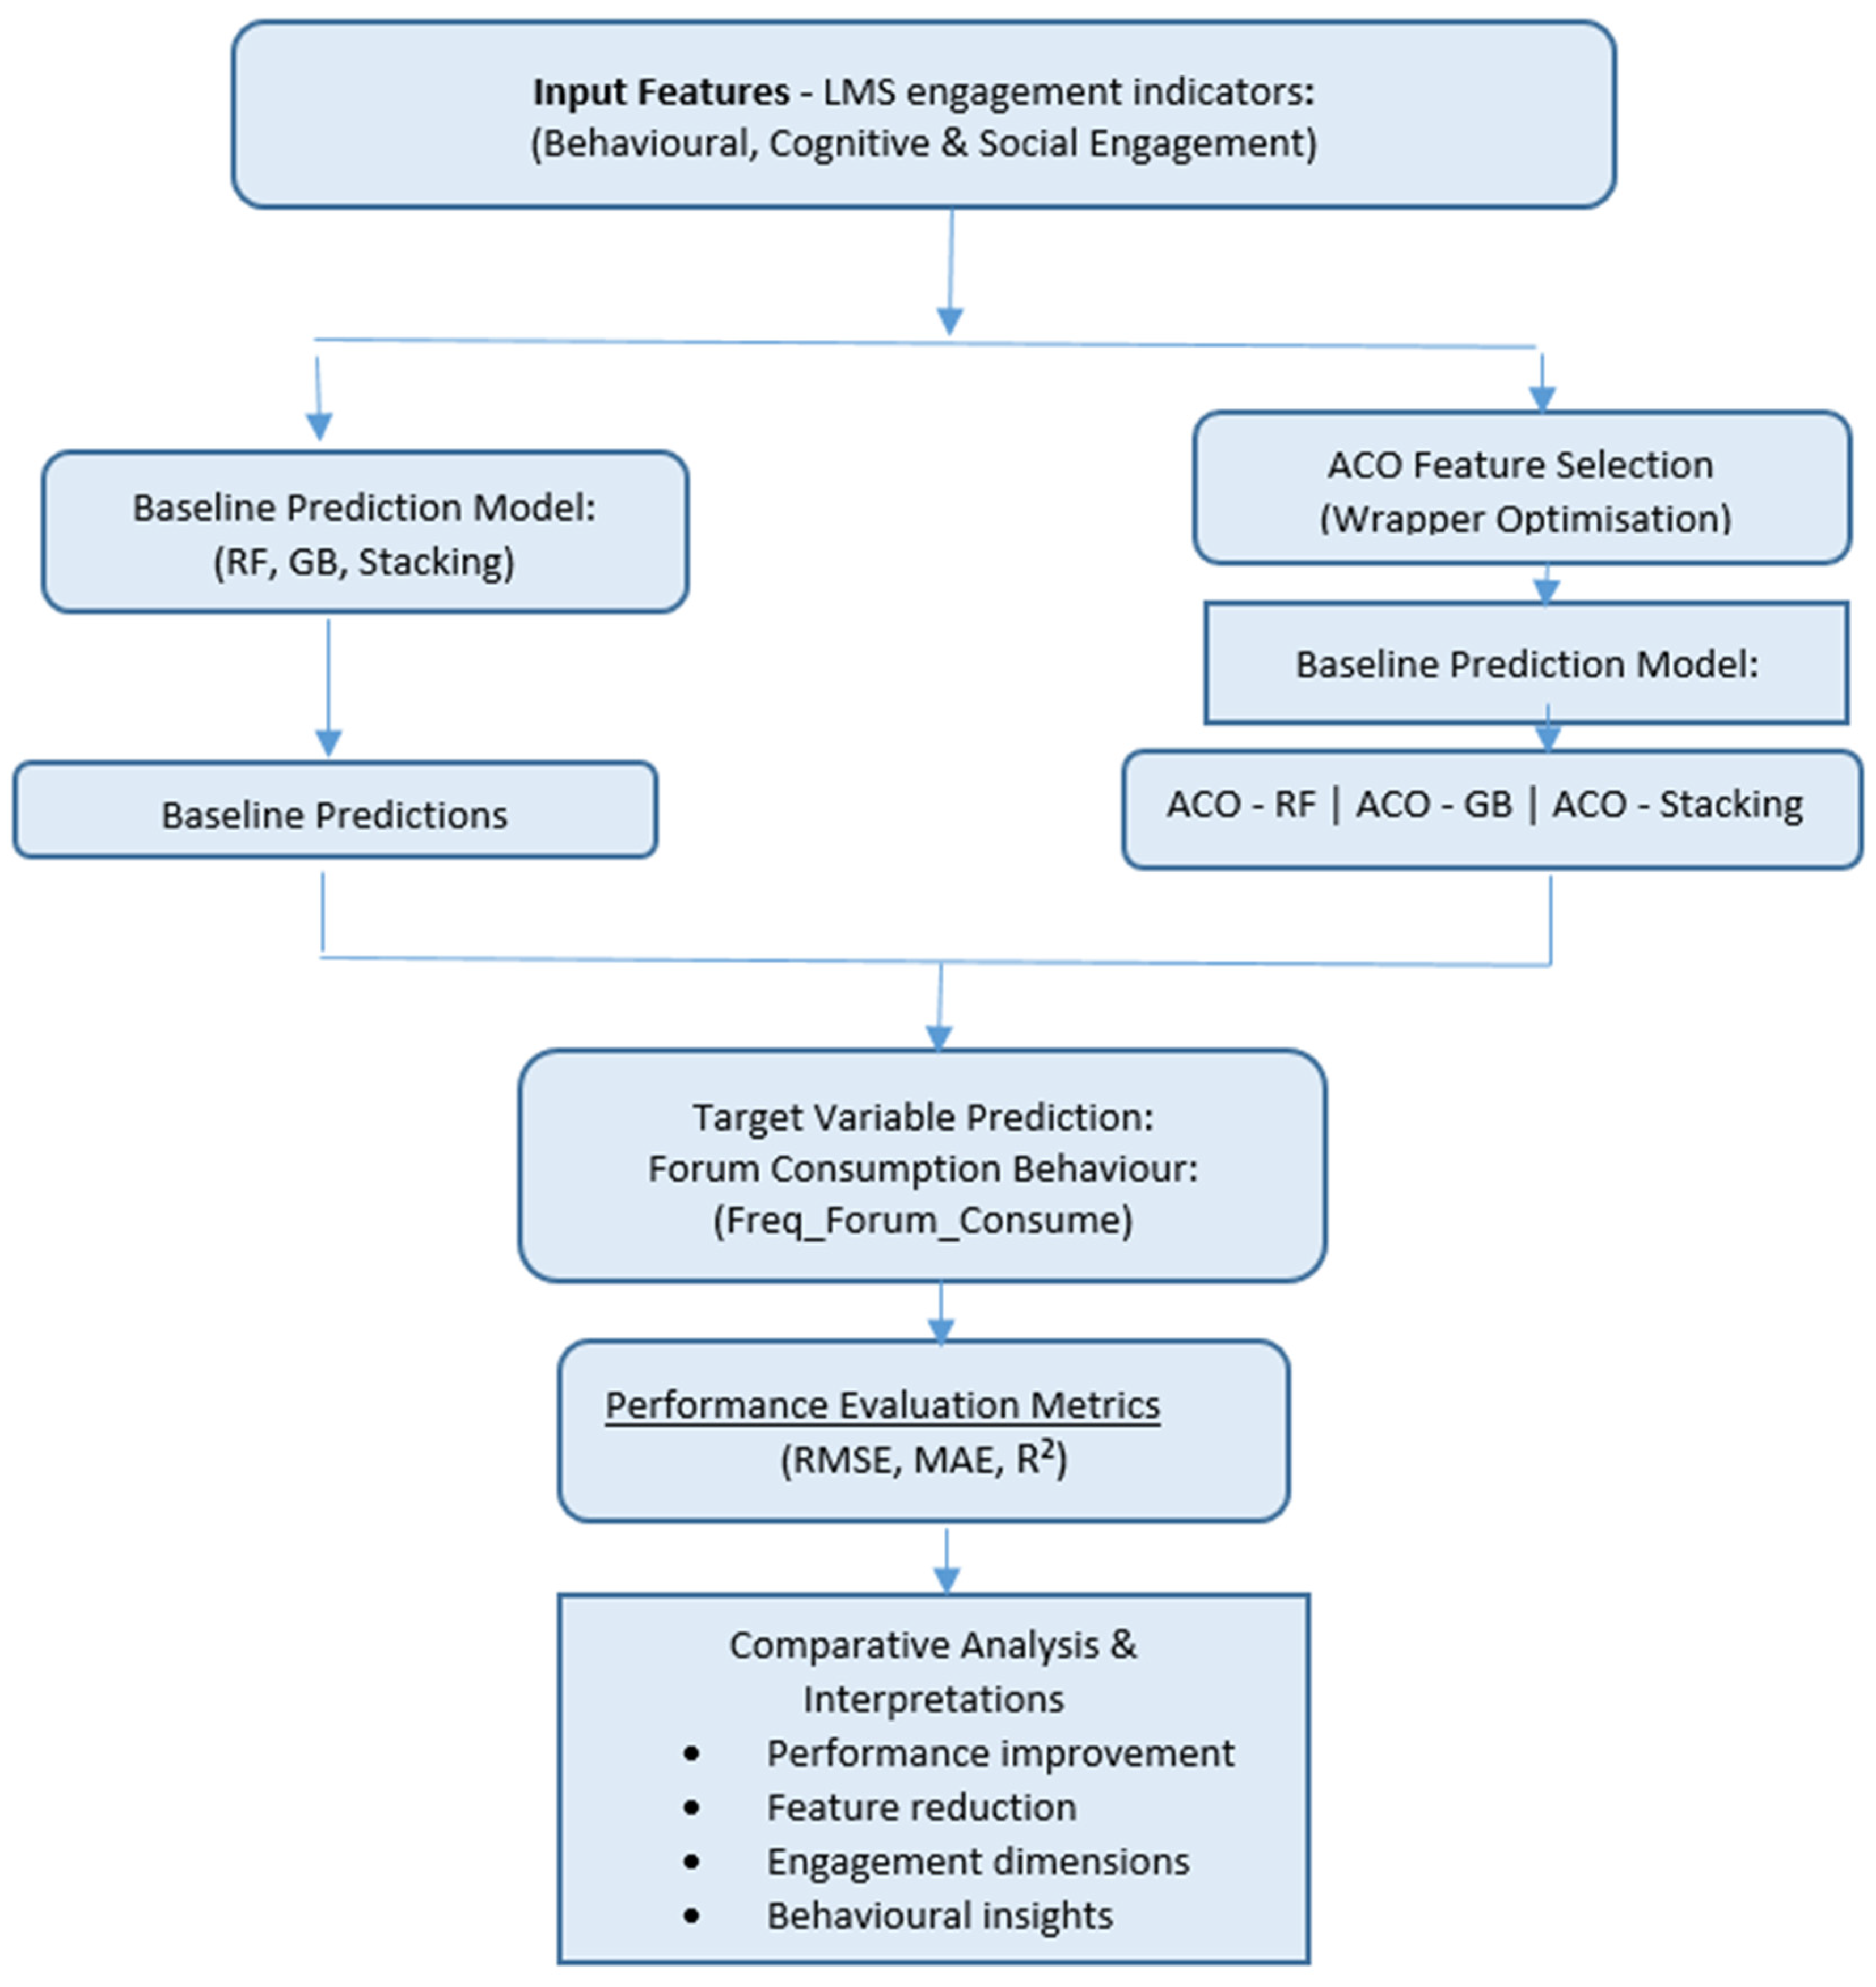
Figure 1 illustrates the conceptual framework underpinning the proposed predictive modelling approach. The framework integrates EDM, feature optimisation, and ensemble learning to predict students’ forum consumption behaviour from LMS engagement data.
Following data preparation, the workflow branches into parallel modelling pathways. The first pathway develops the baseline ensemble regression models (RF, GB, and Stacking) using the complete set of original engagement variables. These models establish the reference level of predictive performance against which the effectiveness of feature optimisation can be evaluated. The second pathway applies ACO as a wrapper-based FS technique to identify an optimal subset of engagement indicators. The selected features are subsequently used to train the corresponding hybrid ACO-RF, ACO-GB, and ACO–Stacking models. This optimisation process reduces feature redundancy while preserving the engagement indicators that contribute most to predicting forum consumption behaviour.
Predictions generated by both modelling pathways are subsequently evaluated using the R2, MAE, and RMSE. These complementary evaluation metrics facilitate a comprehensive comparison of predictive accuracy and model robustness.
Finally, the comparative analysis is used to determine whether ACO-guided FS improves predictive performance while simultaneously reducing model complexity and enhancing interpretability. The selected features are subsequently interpreted according to the behavioural, cognitive, and social engagement dimensions defined in
Table 2, thereby providing meaningful educational insights into the factors associated with students’ forum consumption behaviour.
3.4. Operationalised Student Engagement Dimensions
To translate the theoretical constructs into measurable variables, student engagement was operationalised using LMS-derived indicators extracted from system interaction logs. Behavioural engagement was represented through students’ observable participation in learning activities, cognitive engagement through indicators reflecting persistence and structured learning behaviours, and social engagement through participation in collaborative discussion forums. Consistent with the study objective, forum consumption behaviour (Freq_Forum_Consume) constituted the dependent variable to be predicted.
The operationalisation presented in
Table 2 establishes the conceptual relationship between the theoretical engagement dimensions and the measurable LMS indicators used throughout the predictive modelling process.
Operationalisation provides a theoretically grounded framework for interpreting the selected predictors identified through ACO. Rather than representing isolated activities, the indicators collectively capture complementary dimensions of student engagement that underpin the predictive models developed in this study.
3.5. Preprocessing
Prior to model development, the dataset was examined for data quality issues. No missing values were identified; therefore, no imputation or data exclusion procedures were required. To ensure consistency across the modelling framework, all predictor variables were standardised using the Standard Scaler implementation in Scikit-learn, which transforms each feature to have a mean of zero and a standard deviation of one. Although tree-based algorithms are generally insensitive to feature scaling, standardisation was applied uniformly across all models to maintain a consistent preprocessing pipeline and facilitate comparison among the ensemble learning algorithms.
For the baseline models, standardisation was applied to the complete set of nine LMS engagement indicators prior to model training. Within the ACO–ensemble framework, the same standardised predictor set was used as input to the wrapper-based ACO FS process. The selected feature subsets were subsequently used to train the corresponding RF, GB, and Stacking models.
3.6. Ensemble Predictive Models
This study employed three complementary ensemble regression algorithms—RF, GB, and Stacking—to predict students’ forum consumption behaviour from LMS engagement indicators. The models were selected to provide complementary learning mechanisms and to enable evaluation of whether ACO-selected features remained informative across different ensemble learning paradigms.
RF was included as a bagging-based ensemble that combines predictions from multiple decision trees, making it well suited to LMS engagement data containing potentially correlated predictors. Its ability to capture nonlinear relationships and interactions without requiring strong assumptions about the underlying data distribution further supports its application in this context. GB was selected as a boosting-based approach that sequentially learns from prediction errors, enabling it to capture complex nonlinear relationships among engagement indicators [
58]. Stacking, in turn, was included as a meta-learning ensemble that combines predictions from multiple base learners, providing a complementary modelling approach for assessing whether the ACO-selected feature subsets retain predictive value across different learning mechanisms [
59].
For each algorithm, a baseline model was first developed using the complete set of nine original LMS engagement indicators. A corresponding ACO-optimised model was then developed using the feature subset identified through ACO-based wrapper FS. This design enabled a direct comparison between models trained using the full feature set and those trained using the reduced ACO-selected feature sets. The comparison was used to determine whether ACO could reduce feature redundancy and model dimensionality while maintaining or improving predictive performance.
The integration of ACO with the ensemble models was therefore structured as a two-stage process: feature optimisation followed by predictive modelling. ACO searched for informative combinations of LMS engagement indicators, while RF, GB, and Stacking independently evaluated the predictive utility of the resulting subsets. Evaluating the selected features across these complementary ensemble approaches also enabled the study to assess whether the identified predictors were consistently informative rather than being specific to a single learning algorithm. This directly supports the study objectives of identifying informative engagement indicators, reducing redundant predictors, and evaluating the predictive effectiveness of the resulting compact feature subsets.
3.7. ACO-Based Wrapper Feature Selection
ACO was employed as a wrapper-based feature-selection method to identify compact subsets of the nine retained LMS engagement predictors. FS was performed independently for Gradient Boosting (GB), Stacking, and Random Forest (RF).
Each engagement indicator was treated as a candidate feature. ACO assigned pheromone values to the features and updated them according to the predictive performance of candidate subsets. Selection probabilities were influenced by pheromone and heuristic information, controlled by α and β, respectively.
Each ant generated a subset containing four to nine predictors. Candidate subsets were evaluated using 5-fold cross-validation, with mean R2 serving as the fitness measure. Higher-performing subsets received greater pheromone reinforcement, while pheromone evaporation and deposition controlled subsequent updates.
The search continued until the specified iteration limit or early-stopping criterion was reached. The subset achieving the highest cross-validation R2 was retained for the respective ensemble model and used for subsequent training and evaluation.
A fixed random seed of 42 was applied to support reproducibility. Different ant populations, iteration budgets, and combinations of α, β, and ρ were examined in the ACO Parameter Sensitivity Analysis (
Section 3.8) to determine whether the optimisation configuration materially affected feature-selection outcomes or predictive performance.
Finally, the ACO-selected subsets were compared with the full nine-predictor models to determine whether feature reduction could maintain or improve predictive performance while reducing the predictor space.
3.8. ACO Parameter Selection and Sensitivity Analysis
ACO performance can be influenced by the configuration of its search parameters, including ant population, iteration budget, pheromone influence (α), heuristic influence (β), evaporation rate (ρ), and pheromone deposit. These parameters affect the balance between exploration and exploitation and may influence feature-selection outcomes [
24,
25,
26].
As shown in
Table 3, parameter sensitivity was examined across the ACO-GB, ACO–Stacking, and ACO-RF models by varying the ant population and iteration budget. The tested configurations included 30, 50, and 80 ants and 30, 50, and 100 maximum iterations. Combinations of α, β, and ρ were also examined, while the pheromone deposit was set to 0.5. The feature-subset size was constrained to four to nine predictors, and candidate subsets were evaluated using 5-fold cross-validation.
Early-stopping thresholds of 10 and 20 iterations were additionally examined to determine whether extending the search produced further improvements. A fixed random seed of 42 was used throughout to support reproducibility. Feature-selection outcomes and predictive performance were compared across the tested configurations.
The analysis was intended to determine whether variations in the tested ACO configurations materially affected feature-selection outcomes or predictive performance. The results provide evidence of consistency across the configurations investigated.
3.9. Validation and Evaluation Strategy
A multi-stage validation and evaluation strategy was employed to ensure consistent and reliable assessment of predictive performance. A fixed random seed of 42 was used throughout the experiments to support reproducibility.
During the ACO wrapper-based feature-selection stage, candidate feature subsets were evaluated using 5-fold cross-validation, as specified in
Table 3. The mean R
2 across the five folds served as the fitness measure for selecting the best-performing feature subset for each ensemble model.
Following FS, the ACO-optimised models were evaluated using 3-fold cross-validation with 10 repetitions (30 folds). The same evaluation procedure was applied to the baseline GB, Stacking, and RF models using the original predictor set, providing a consistent basis for comparison. Model hyperparameter optimisation, where applicable, was conducted using cross-validation prior to final evaluation.
An independent test set, excluded from ACO FS and model optimisation, was subsequently used to assess predictive performance on previously unseen observations. Performance was evaluated using R2, MAE, and RMSE, with higher R2 and lower MAE and RMSE indicating better predictive performance.
Thus, the evaluation strategy clearly distinguishes between 5-fold cross-validation for ACO FS, 3-fold cross-validation for comparative model evaluation, and independent test-set evaluation. This framework enabled assessment of whether ACO could reduce the predictor space while maintaining or improving the prediction of students’ forum consumption behaviour.
3.10. Algorithm of the Proposed ACO–Ensemble Framework
The following pseudocode summarises the overall workflow of the proposed ensemble framework, integrating data preparation, model-specific wrapper-based FS, ensemble model development, and performance evaluation. Algorithm 1 provides a reproducible overview of the methodological sequence described in
Section 3.7,
Section 3.8 and
Section 3.9.
| Algorithm 1. ACO–Ensemble Framework |
Input:
LMS dataset D Target variable: Freq_Forum_Consume Ensemble models: GB, Stacking, RF ACO parameter configurations Random seed = 42
Prepare dataset D Remove variables excluded from prediction: Regularity_Forum_Consume Final_Grade Define the remaining LMS engagement indicators as candidate predictors. Split D into development/training data and an independent test set. For each ensemble model M = (GB, Stacking, RF):
Apply ACO wrapper-based FS to the development/training data. Generate candidate feature subsets using ACO. Evaluate each candidate subset using 5-fold cross-validation and mean R2. Update pheromone information according to subset performance. Retain the highest-performing feature subset. Train and optimise model M using the selected features. Evaluate M using repeated 3-fold cross-validation with 10 repetitions. Evaluate the final optimised model on the independent test set. Record R2, MAE, and RMSE.
Compare:
Full-feature and ACO-selected models. ACO-selected feature subsets across GB, Stacking, and RF. Performance across ACO parameter configurations. Cross-validation and independent test performance.
Report the selected predictors and predictive performance.
Output:
ACO-selected feature subsets Optimised ensemble models R2, MAE, and RMSE Comparative performance results
|
4. Results
4.1. ACO Parameter Sensitivity and Sensitivity Analysis
Table 4 presents the ACO parameter sensitivity analysis conducted across the GB, Stacking, and RF models. The analysis considered different combinations of ant population, iteration budget, pheromone influence (α), heuristic influence (β), evaporation rate (ρ), and early-stopping thresholds to examine whether changes in the optimisation configuration affected FS and predictive performance. The pheromone deposit value was maintained at 0.5 across all configurations.
As shown in
Table 4, the predictive performance of each ACO–ensemble model remained unchanged across the tested configurations. GB consistently achieved R
2 = 0.8332, MAE = 55.3173, and RMSE = 71.4150, while selecting six features in all three configurations. Stacking similarly maintained R
2 = 0.8313, MAE = 55.9915, and RMSE = 71.8245, consistently selecting seven features. RF produced R
2 = 0.8265, MAE = 56.7765, and RMSE = 72.8403 across all configurations and also retained seven features.
The consistency of these results across different ant populations, iteration budgets, and combinations of α, β, and ρ indicates that the predictive outcomes were not materially affected by the tested ACO configurations. Although the number of selected features differed between GB and the other two models, each model produced the same feature-space size across its tested configurations. This suggests consistency in the optimisation outcome within each ensemble modelling approach.
The early-stopping analysis provides additional evidence of convergence consistency. Early-stopping thresholds of 10 and 20 iterations produced the same predictive results for all three ACO–ensemble models. Thus, extending the optimisation beyond 10 iterations did not yield further predictive improvement under the tested configurations.
4.2. Feature Selection Results
Table 5 presents the LMS engagement indicators selected by ACO across the B, Stacking, and RF ensemble models. Nine LMS engagement indicators were considered for FS, with Freq_Forum_Consume retained as the prediction target. ACO selected six predictors for ACO-GB and seven predictors for both ACO–Stacking and ACO-RF. This corresponds to reductions of 33.3% and 22.2%, respectively, in the predictor space.
A high degree of agreement was observed across the three ACO–ensemble models. Five indicators—Freq_Course_View, Freq_Forum_Contribute, Session_Count, Freq_Lecture_View, and Total_Duration—were selected by all three models. Their consistent selection indicates that general LMS activity, learning-resource access, and direct participation in forums provide important predictive information for modelling students’ forum consumption frequency.
From a behavioural engagement perspective, the consistent selection of Freq_Course_View, Session_Count, Freq_Lecture_View, and Total_Duration is notable. These indicators capture different aspects of students’ observable interaction with the LMS, including course access, learning sessions, lecture viewing, and time spent online. Their selection across all three ensemble approaches suggests that the intensity and extent of students’ broader LMS participation provide useful information for predicting forum consumption frequency.
The results also highlight the importance of social engagement. Freq_Forum_Contribute and Regularity_Forum_Contribute were retained across the ACO-GB, ACO–Stacking, and ACO-RF models. Freq_Forum_Contribute represents the frequency of students’ active participation in forums, while Regularity_Forum_Contribute reflects the consistency of this participation. Their selection alongside the broader LMS activity indicators suggests that students’ active discussion participation provides complementary information for predicting the frequency with which they consume forum content.
The cognitive engagement indicators showed greater variation across models. Regularity_Lecture_View was selected by ACO–Stacking and ACO-RF but not by ACO-GB. This suggests that the regularity of accessing lecture material provided additional predictive information for the two models, whereas its contribution was not sufficient for retention by ACO-GB. In contrast, Regularity_Course_View was excluded by all three ACO–ensemble models, indicating that it provided limited additional predictive information when considered alongside the retained engagement indicators.
Model-specific differences were therefore relatively limited. ACO-GB selected Freq_Course_View, Freq_Forum_Contribute, Session_Count, Freq_Lecture_View, Regularity_Forum_Contribute, and Total_Duration, whereas ACO–Stacking and ACO-RF additionally retained Regularity_Lecture_View. This pattern indicates that the three ensemble learning approaches identified a common set of predictors, while Stacking and RF extracted additional information from the regularity of lecture access.
Conversely, Regularity_Course_View and Active_Days were excluded by all three ACO–ensemble models. Their exclusion should not be interpreted as indicating that these variables are unimportant measures of student engagement. Rather, within the present predictive framework, they provided limited additional predictive information after the retained indicators were considered jointly. Their information may overlap with measures such as Session_Count, Freq_Course_View, Freq_Lecture_View, and Total_Duration, which capture related aspects of students’ LMS activity.
Overall, the results in
Table 4 demonstrate that ACO identified a compact and largely consistent subset of LMS engagement indicators for predicting Freq_Forum_Consume. Five predictors were consistently selected across all three ACO–ensemble models, while Regularity_Lecture_View provided additional information for ACO–Stacking and ACO-RF. The reduction from nine candidate predictors to six or seven therefore demonstrates that ACO can reduce the predictor space while retaining the engagement indicators most useful for predicting forum consumption behaviour. The consistency of the selected predictors across the three complementary ensemble learning approaches further supports their relevance within the proposed ACO-based feature-selection framework.
4.3. Performance Comparison Between Full-Feature and ACO-Selected Models
Table 6 compares the predictive performance of the baseline ensemble models trained using the nine original LMS engagement predictors with their corresponding ACO–ensemble models trained using the ACO-selected feature subsets. Performance was assessed using the R
2, MAE, and RMSE.
The results show that ACO reduced the predictor space while maintaining or improving predictive performance across all three ensemble models. For GB, the predictor set was reduced from nine to six variables, representing a 33.3% reduction in dimensionality. Stacking and RF were each reduced from nine to seven predictors, corresponding to a 22.2% reduction. These findings indicate that several original predictors provided limited additional information for predicting students’ forum consumption behaviour.
Among the three models, ACO-GB achieved the strongest overall predictive performance. Its R2 increased from 0.8310 for the full-feature model to 0.8332 following FS. MAE decreased from 55.4174 to 55.3173, while RMSE decreased from 71.8776 to 71.4150. Although these improvements were modest, they were achieved alongside a reduction of three predictors, indicating that the excluded variables contributed limited additional predictive information to the GB model.
A similar improvement was observed for ACO–Stacking. R2 increased from 0.8302 to 0.8313, while MAE decreased from 56.1305 to 55.9915, and RMSE decreased from 72.0548 to 71.8245. The predictor space was reduced from nine to seven variables, indicating that the ACO-selected subset retained the information required to predict forum consumption behaviour while eliminating two predictors.
The largest improvement was observed for ACO-RF. R2 increased from 0.8109 to 0.8265, representing an improvement of ΔR2 = +0.0156. MAE decreased from 58.2091 to 56.7765, while RMSE decreased from 76.0312 to 72.8403. This improvement was achieved despite reducing the predictor set from nine to seven variables, suggesting that removing less informative or redundant predictors was particularly beneficial for RF.
Overall, the results in
Table 6 demonstrate that ACO-guided FS reduced the dimensionality of the LMS predictor space without compromising predictive performance. All three ACO–ensemble models showed improvements in R
2 and reductions in prediction error relative to their corresponding full-feature models. These findings provide empirical support for the study’s objective of identifying a compact set of informative LMS engagement indicators for predicting students’ forum consumption behaviour.
The magnitude of improvement varied across the ensemble approaches. ACO-RF produced the largest relative improvement following FS, whereas ACO-GB achieved the strongest overall predictive performance. This variation suggests that the contribution of individual engagement indicators may depend partly on the learning mechanism employed by the ensemble model. Nevertheless, the consistent improvement following feature reduction across all three models provides evidence that ACO was able to remove predictors contributing limited additional information while retaining indicators relevant to the prediction of forum consumption behaviour.
4.4. Predicted vs. Actual Performance
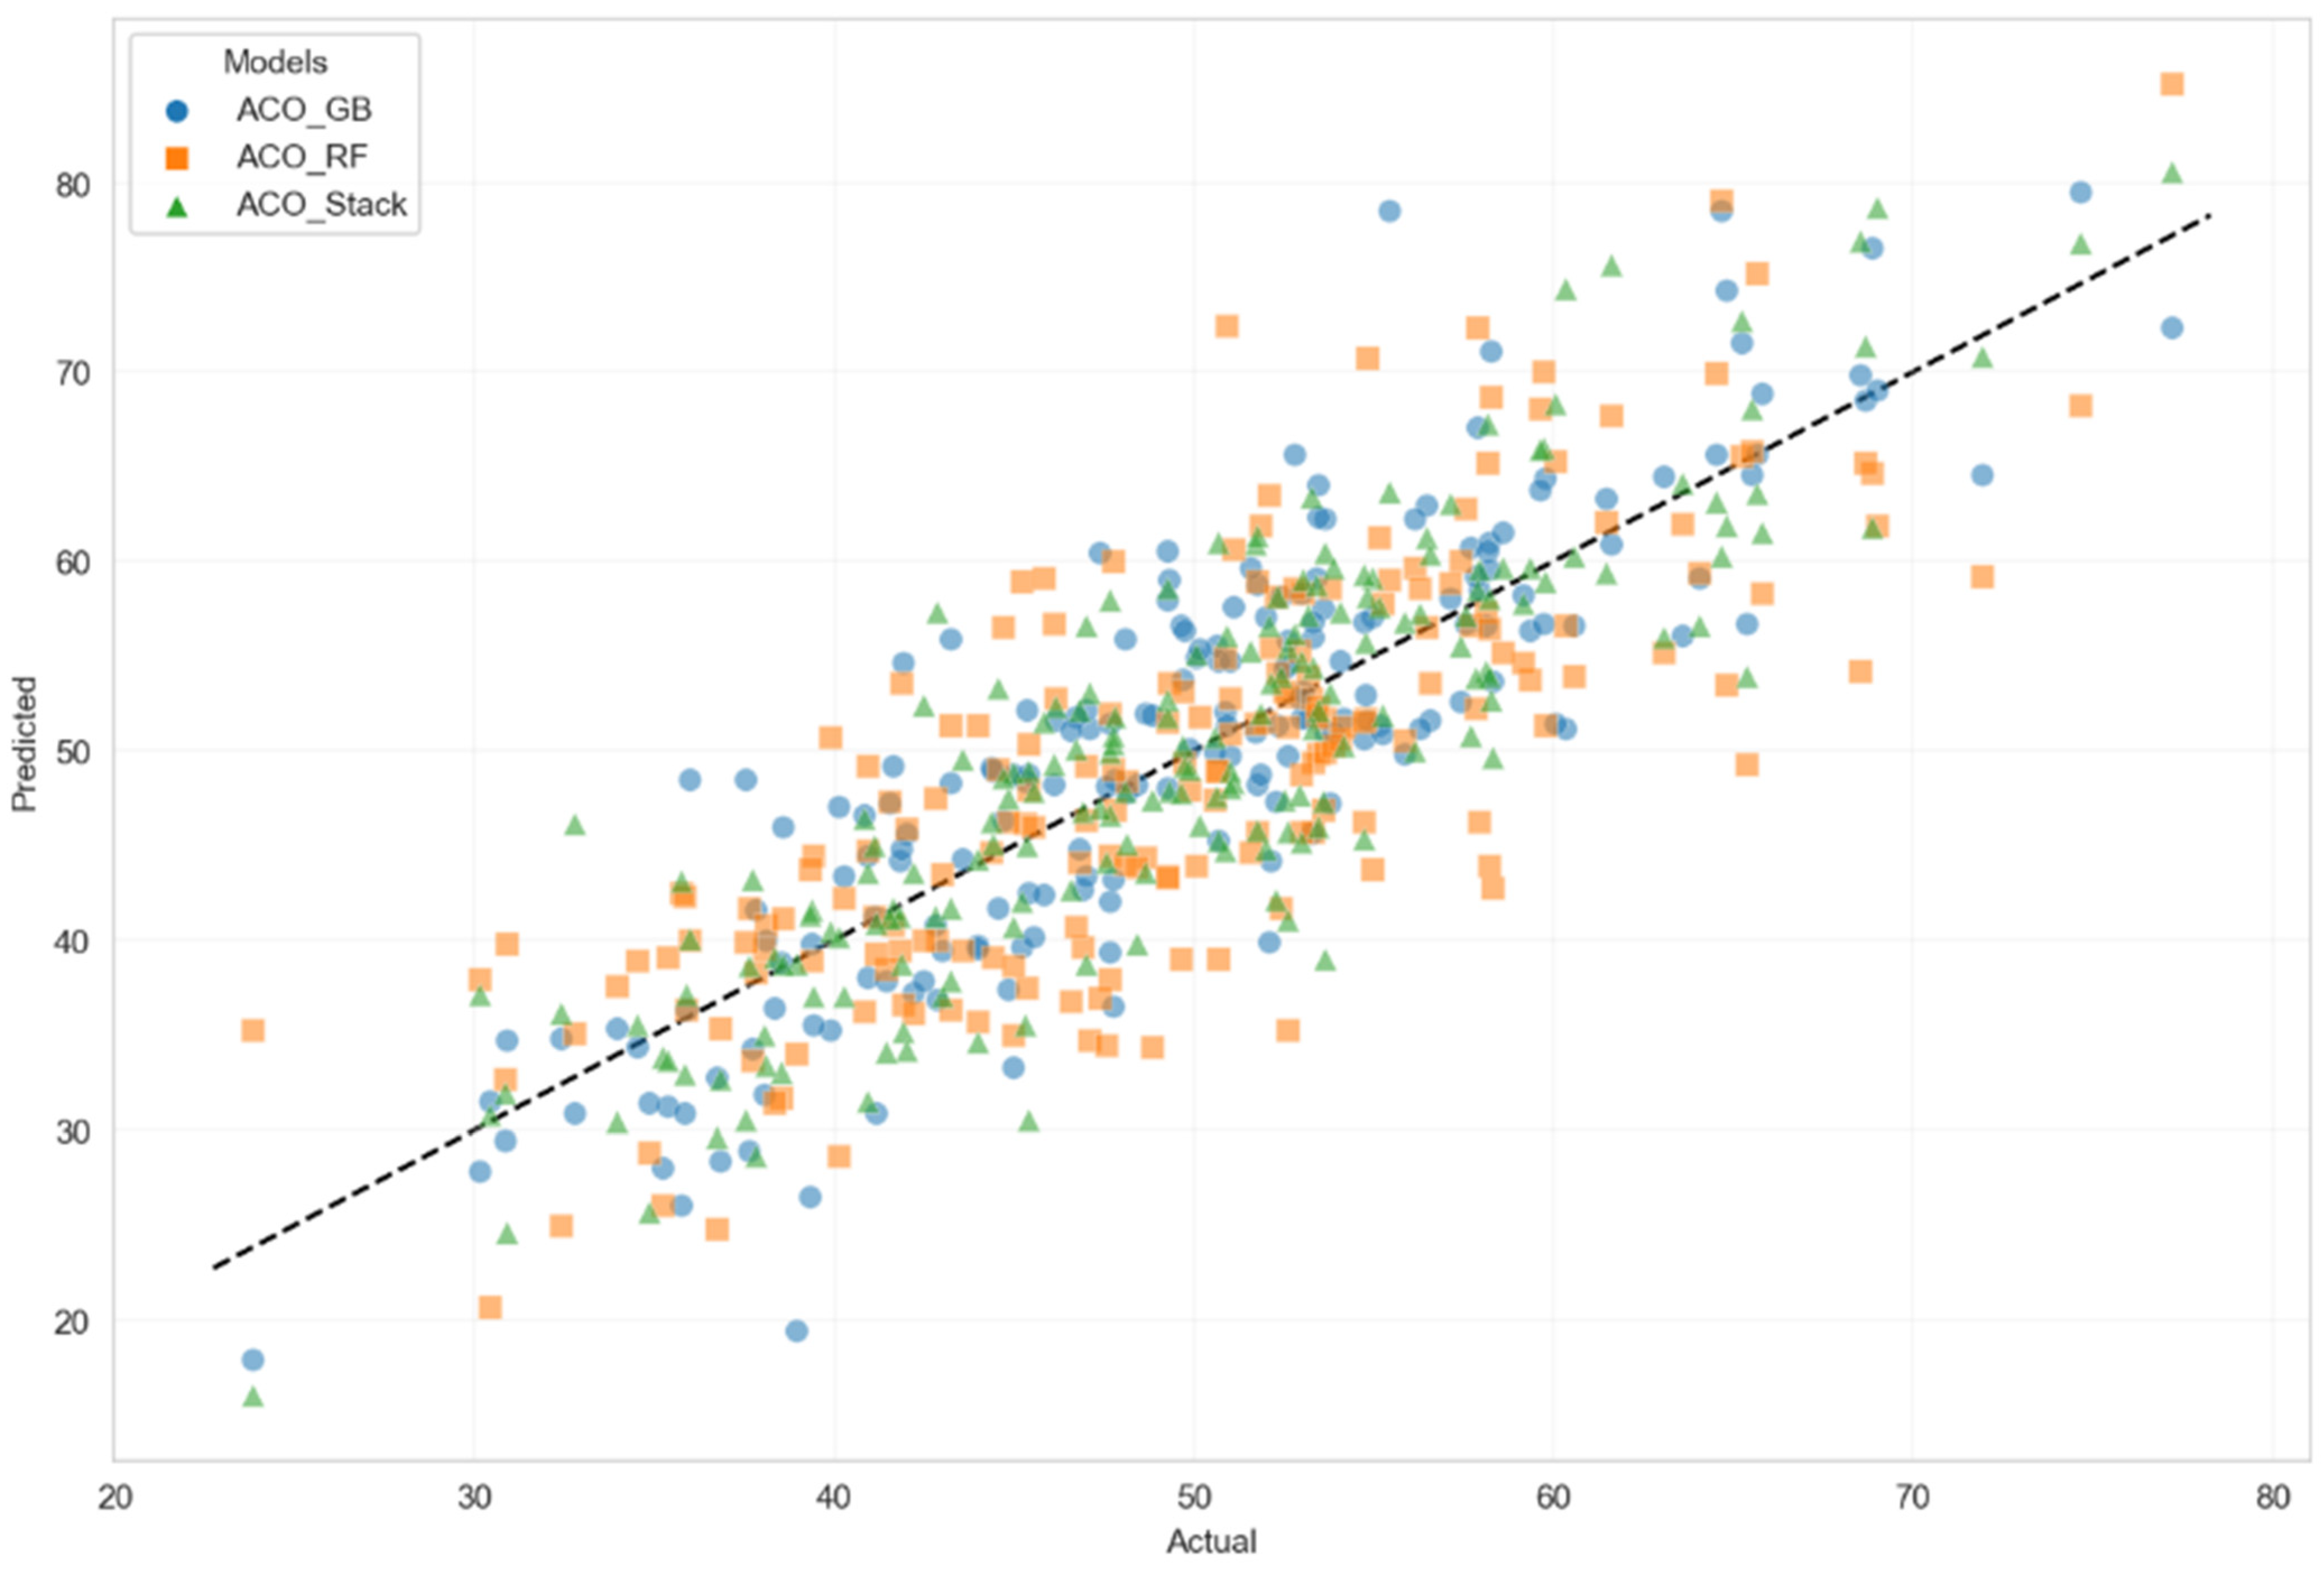
Figure 2, titled “Predicted vs. Actual,” illustrates the relationship between the observed and predicted values of students’ forum consumption behaviour for the three ACO–ensemble models: ACO-GB, ACO-RF, and ACO–Stacking. The target variable, Freq_Forum_Consume, operationalises forum consumption behaviour as the frequency with which students viewed forum posts. The dashed diagonal line represents perfect prediction, where predicted values equal observed values. Observations closer to this reference line therefore indicate greater agreement between predicted and actual forum consumption behaviour.
Overall, the predictions from the three ACO–ensemble models follow the diagonal reference line reasonably closely, indicating that the models captured important relationships between the selected LMS engagement indicators and forum consumption behaviour. The clustering of observations around the reference line is consistent with the quantitative results reported in
Table 6, where all three ACO–ensemble models improved on their corresponding full-feature models.
Among the models, ACO-GB shows a strong concentration of predictions around the reference line and achieved the highest R2 (0.8332) and lowest RMSE (71.4150). ACO–Stacking displays a comparable prediction pattern, with an R2 of 0.8313. ACO-RF also shows a close relationship between predicted and observed values and achieved the largest improvement relative to its corresponding full-feature model.
Some dispersion around the reference line is evident, particularly for observations with higher Freq_Forum_Consume values. This indicates greater prediction error for some observations with relatively high levels of forum consumption. However, the deviations occur on both sides of the reference line, with no pronounced systematic pattern of overprediction or underprediction across the observed range.
Overall,
Figure 2 provides visual support for the quantitative findings in
Table 5. The correspondence between observed and predicted values indicates that the ACO-selected feature subsets retained sufficient predictive information for modelling forum consumption behaviour while reducing the predictor space. Specifically, ACO reduced the predictor set from nine variables to six for GB and seven for both Stacking and RF. The broadly similar prediction patterns across the three ACO–ensemble models further support the predictive relevance of the selected LMS engagement indicators across different ensemble learning mechanisms.
4.5. Actual vs. Predicted Distribution
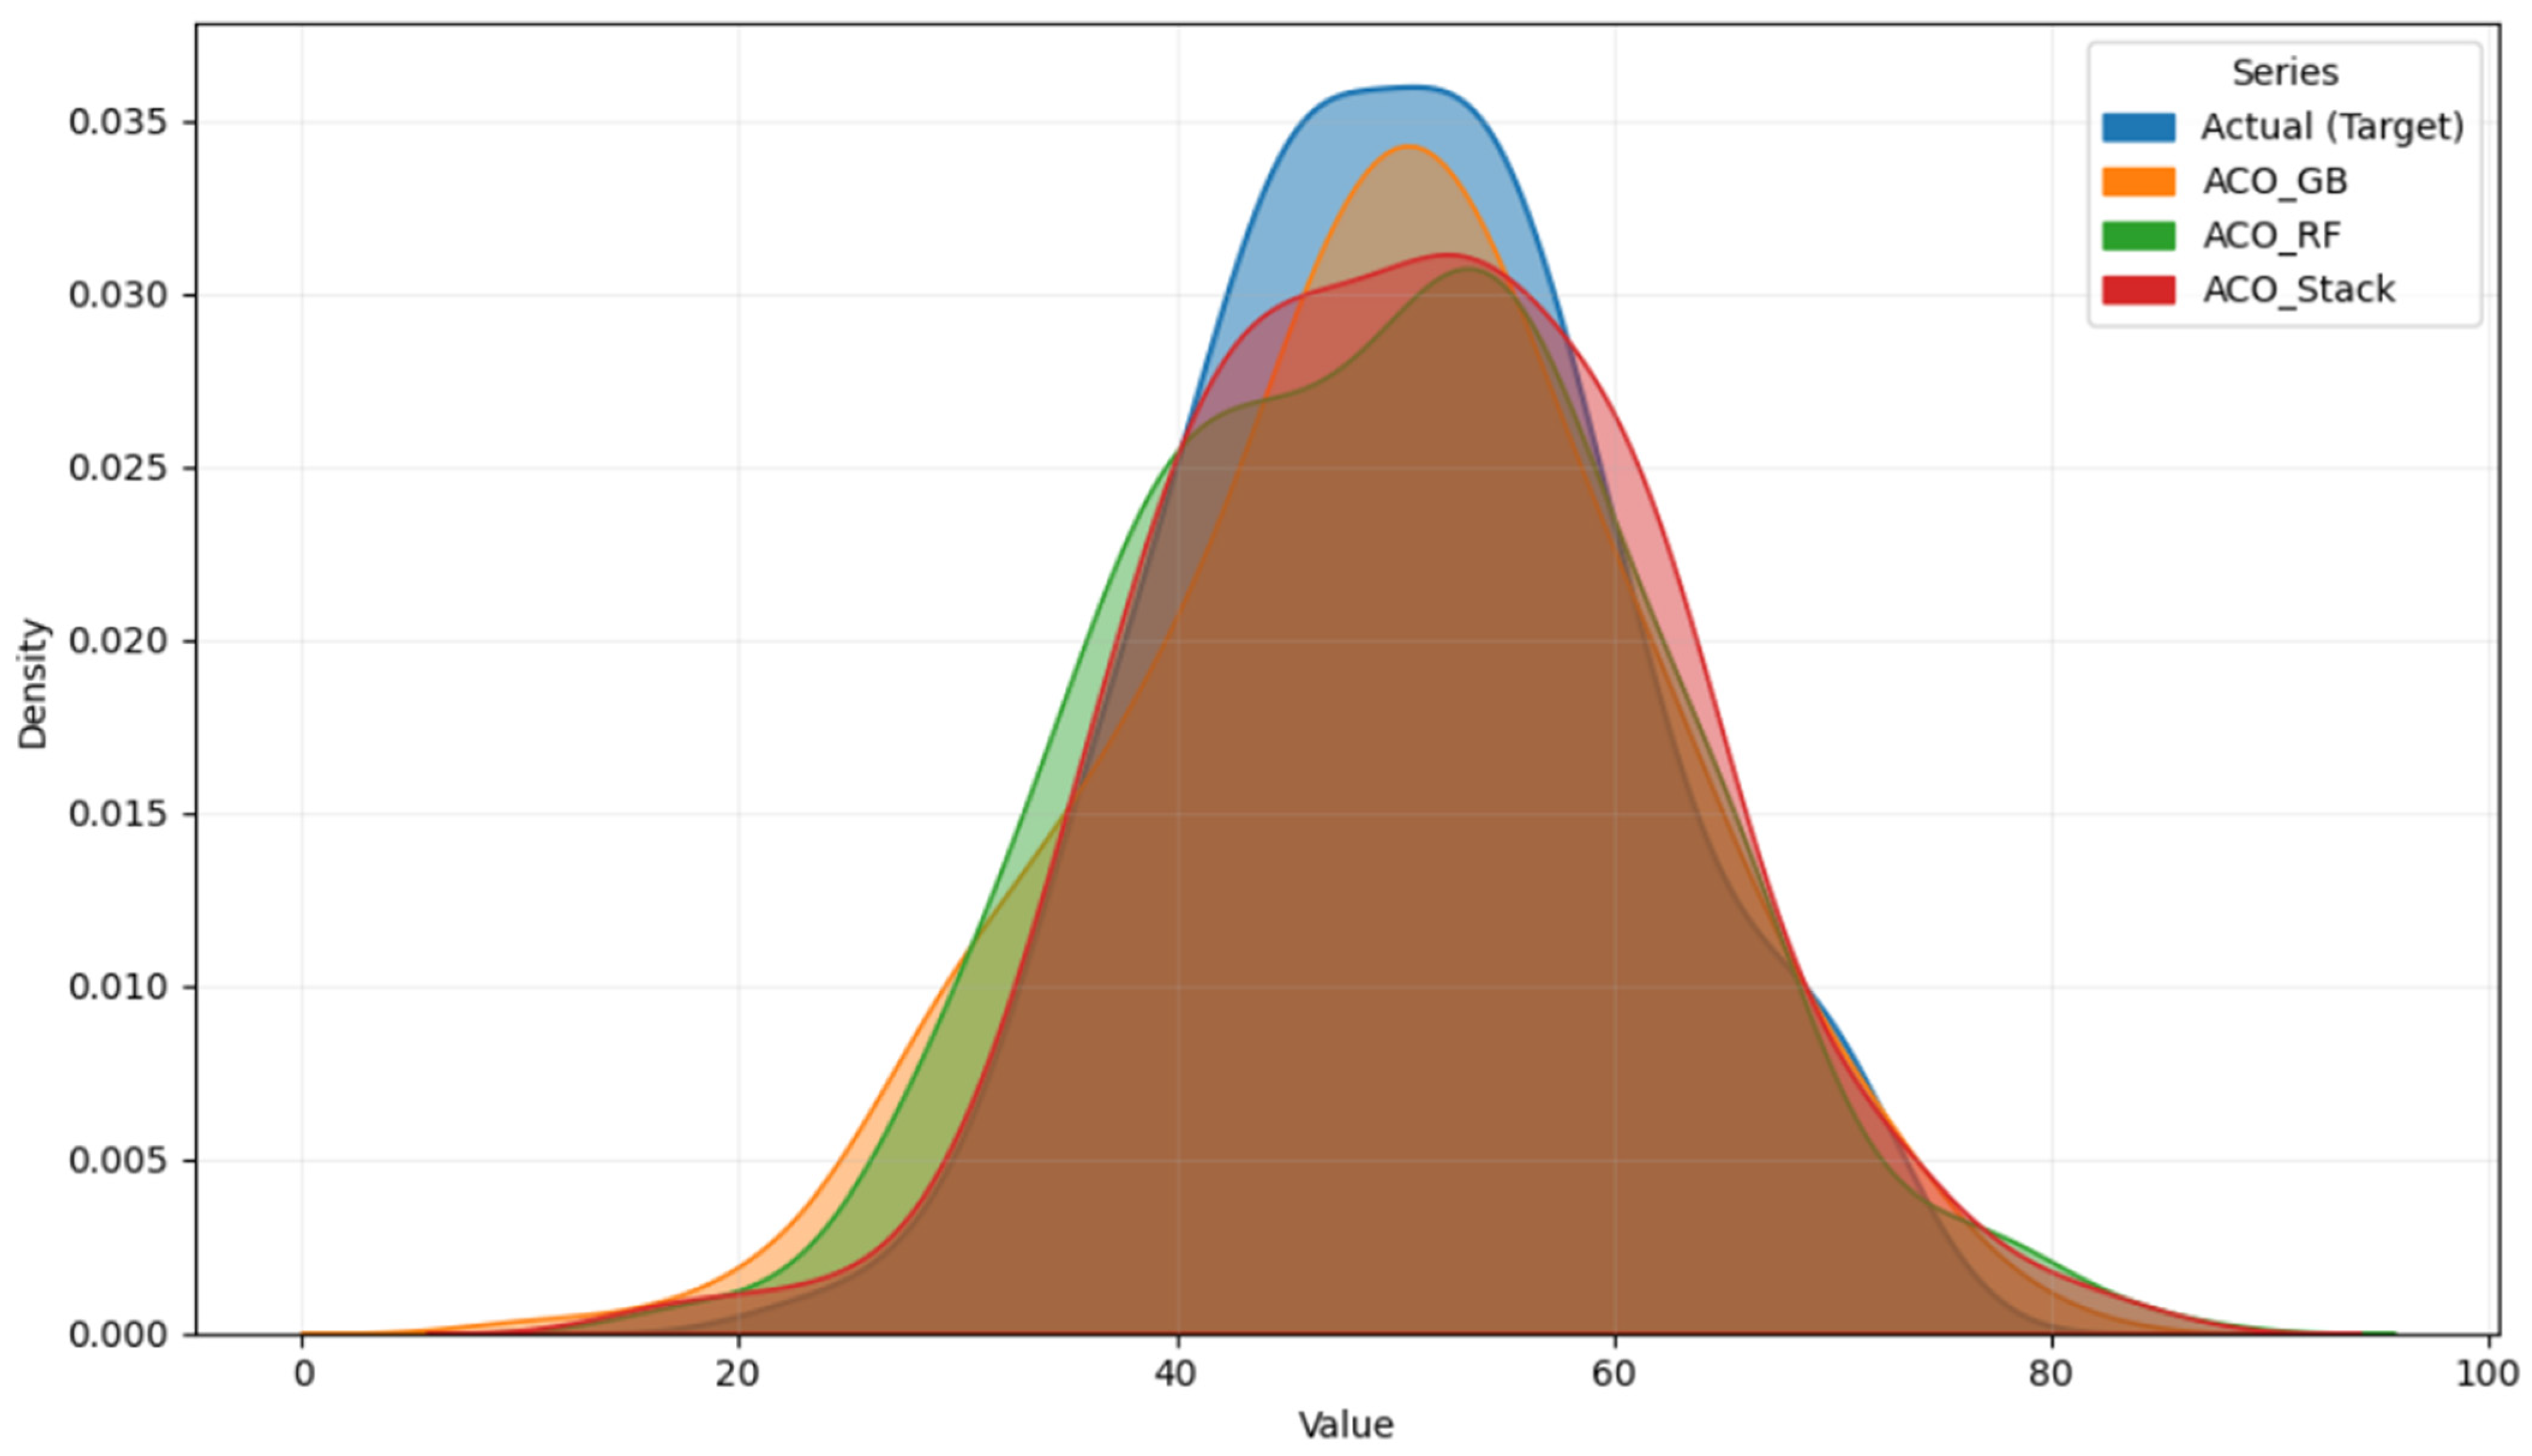
Figure 3 compares the distributions of the observed and predicted values of forum consumption behaviour generated by the three ACO–ensemble models: ACO-GB, ACO-RF, and ACO–Stacking. The density curves provide a visual assessment of how closely the predicted values reproduce the distribution of the observed target values.
Overall, the predicted distributions show substantial overlap with the observed distribution, indicating that the three ACO–ensemble models captured the main distributional characteristics of forum consumption behaviour. The highest density for both observed and predicted values occurs approximately within the 45–60 range, suggesting that the models reproduced the region containing the largest concentration of observations reasonably well.
Among the three models, ACO-GB shows the closest alignment with the observed distribution. The similarity in the location of the peak and the overall shape of the density curve indicates that the model reproduced the central pattern of forum consumption behaviour effectively. This observation is consistent with the quantitative results in
Table 6, where ACO-GB achieved the highest R
2 and lowest RMSE among the three ACO–ensemble models.
The ACO-RF and ACO–Stacking models also show substantial overlap with the observed distribution. Although some differences are visible across portions of the distribution, particularly toward the lower and upper ranges, the overall patterns remain similar to the observed values. The predicted distributions therefore indicate that both models captured the general variation in forum consumption behaviour.
Overall,
Figure 3 provides additional visual support for the quantitative results presented in
Table 6. The similarity between the observed and predicted distributions indicates that the ACO-selected feature subsets retained sufficient predictive information to model forum consumption behaviour, despite reducing the number of LMS predictors. The broadly similar distributions produced by the three ACO–ensemble models further support the usefulness of the selected engagement indicators across different ensemble learning mechanisms.
4.6. Cross-Validation and Independent Test Performance
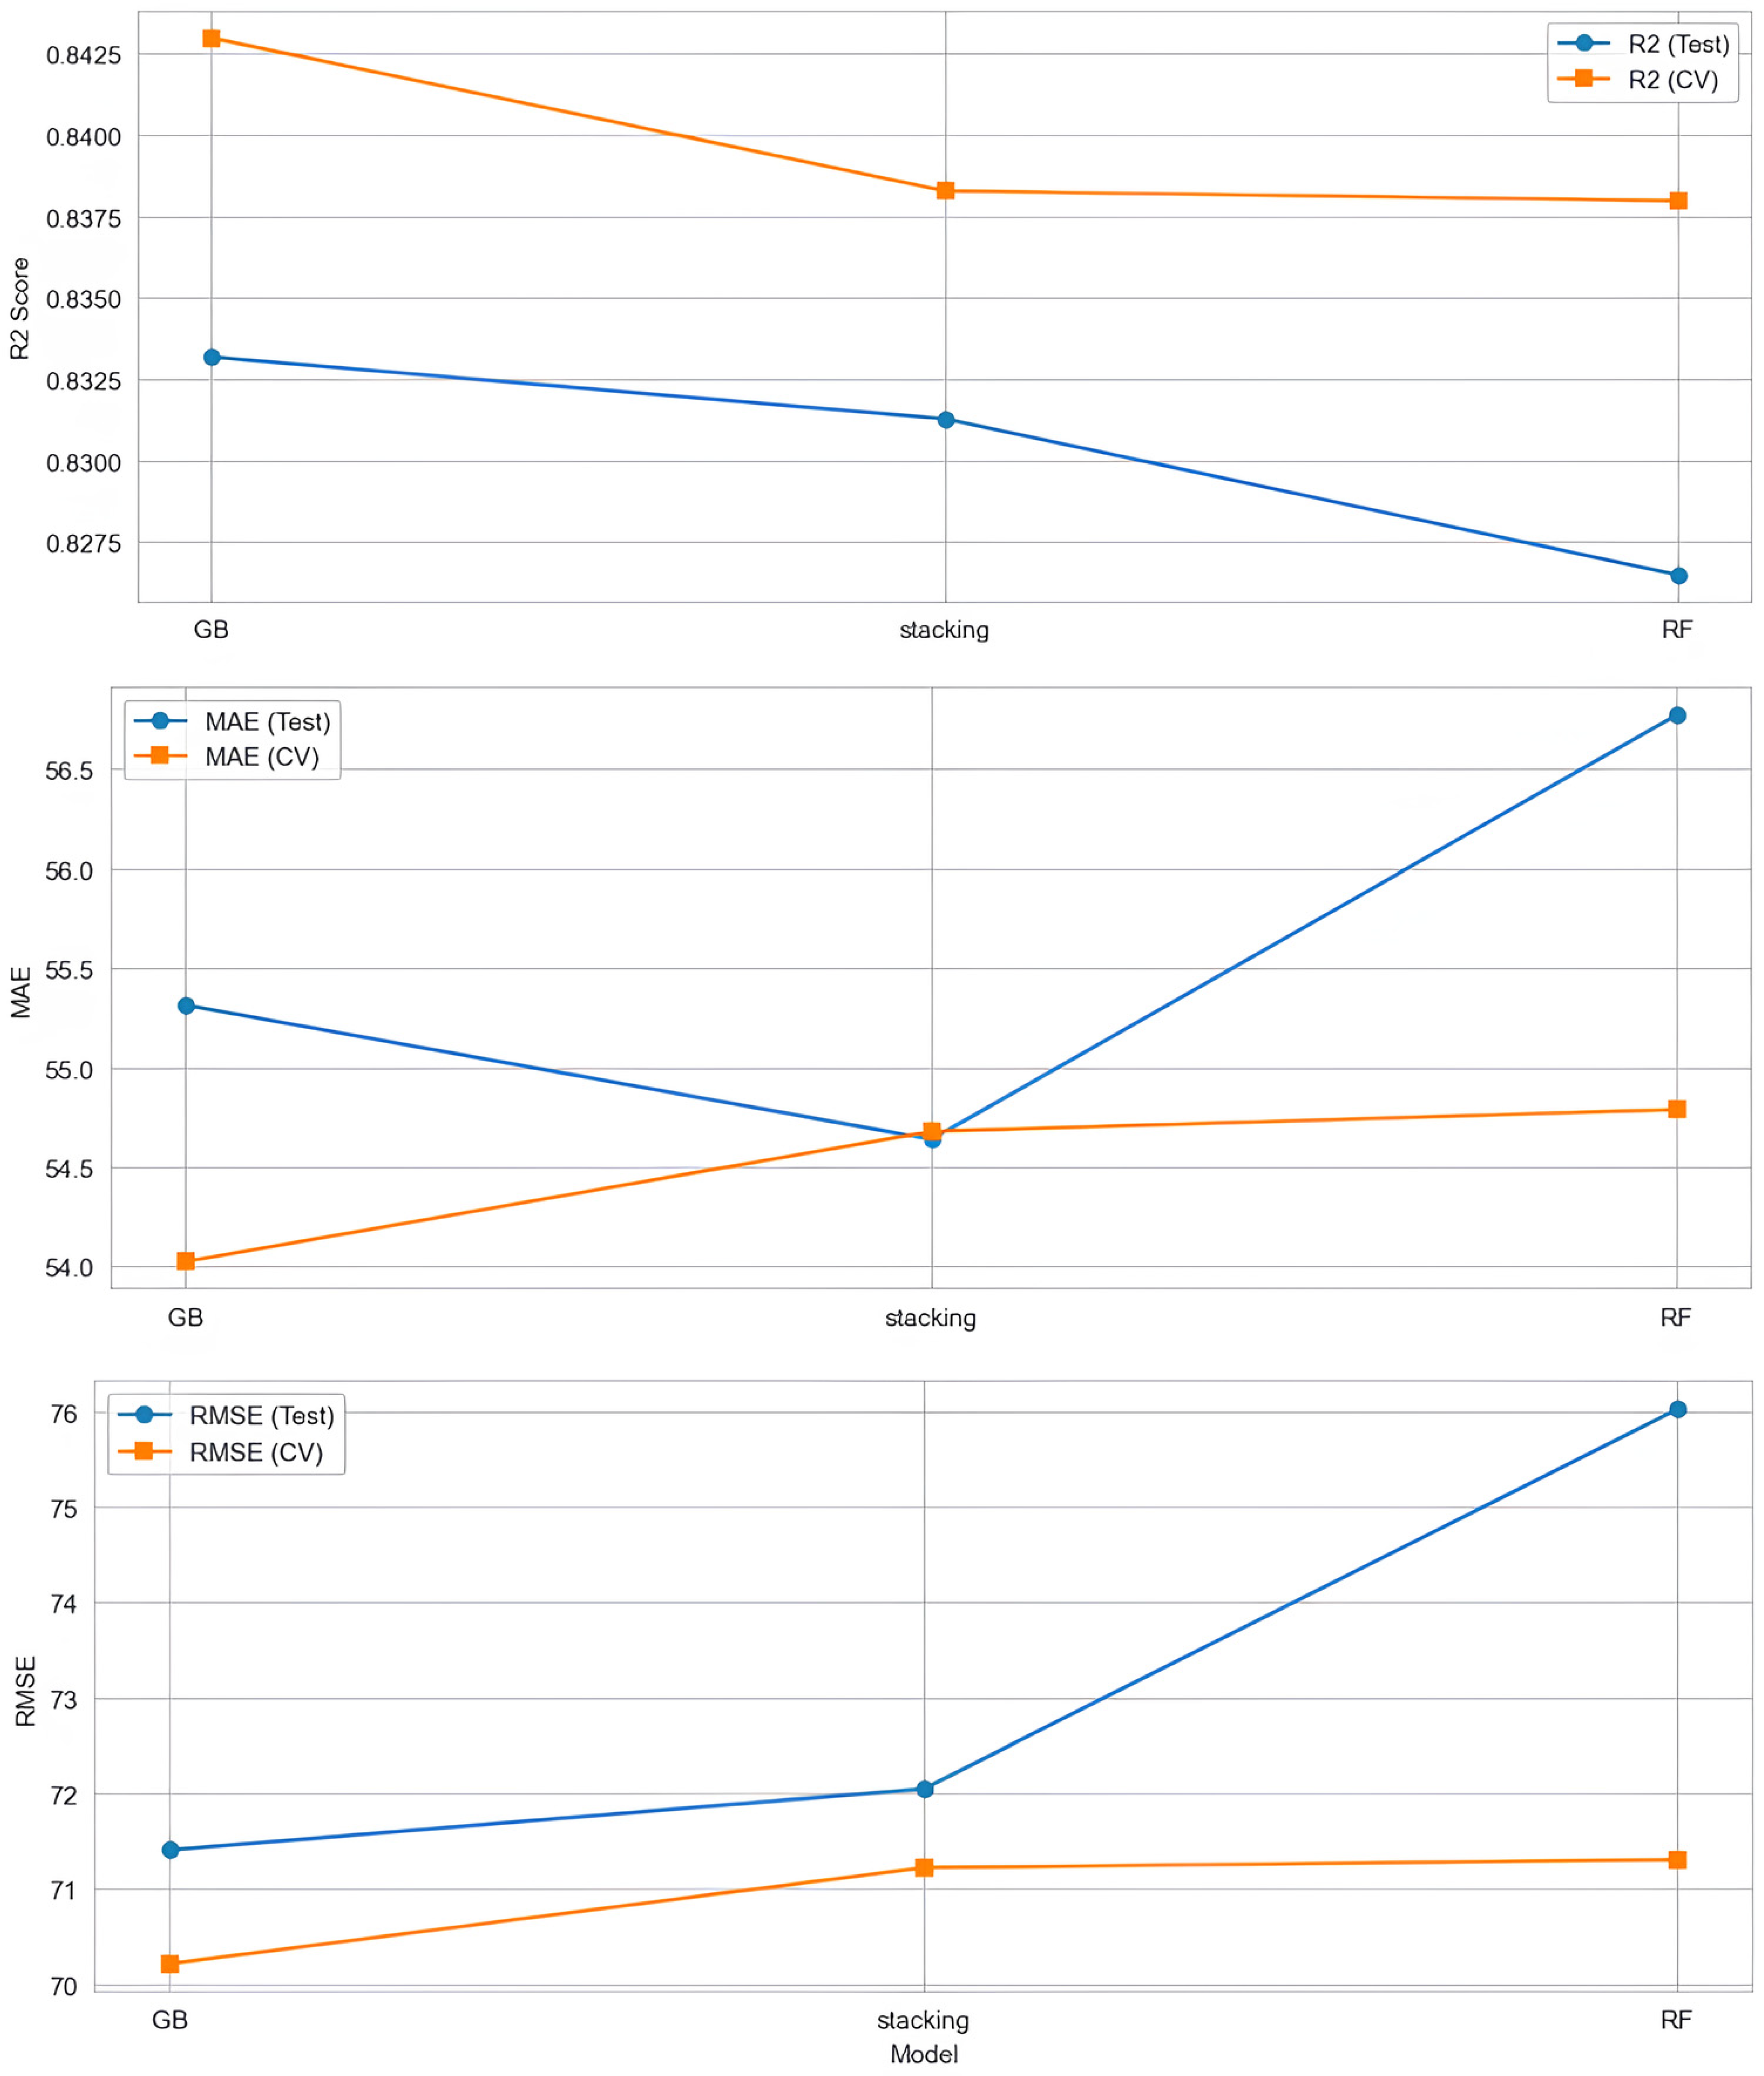
Figure 4 compares the cross-validation (CV) and test-fold performance of the three ACO–ensemble models: ACO-GB, ACO–Stacking, and ACO-RF using the 3-fold × 10-repeated Repeated Fold procedure. The comparison considers R
2, MAE, and RMSE to assess the consistency of model performance across repeated data partitions.
Overall, the results show relatively small differences between the CV and test-fold performance across the three models. This indicates that the models maintained broadly consistent predictive performance across the repeated training and held-out fold evaluations. The close correspondence between the two sets of results also suggests that model performance was not strongly influenced by individual data partitions.
For R2, ACO-GB achieved the highest test-fold performance (R2 = 0.8332), with a higher CV R2 of approximately 0.8425. ACO–Stacking recorded a test-fold R2 of 0.8313 and a CV R2 of approximately 0.8382, while ACO-RF achieved a test-fold R2 of 0.8265 and a CV R2 of approximately 0.8380. The relatively small differences between CV and test-fold R2 indicate consistent explanatory performance across the repeated folds.
The error-based metrics show a similar pattern. ACO-GB recorded a test-fold MAE of 55.3173 compared with a CV MAE of approximately 54.0. ACO–Stacking produced a test-fold MAE of 55.9915 and a CV MAE of approximately 54.7, while ACO-RF recorded 56.7765 and approximately 54.8, respectively. For RMSE, the test-fold values were 71.4150 for ACO-GB, 71.8245 for ACO–Stacking, and 72.8403 for ACO-RF. The corresponding CV values were approximately 70.2, 71.2, and 71.3. Thus, the test-fold errors were generally slightly higher than the CV estimates; however, the differences remained relatively small.
Among the three models, ACO-GB demonstrated the strongest overall predictive performance, achieving the highest test-fold R2 and the lowest test-fold MAE and RMSE. ACO–Stacking showed comparable performance, while ACO-RF produced somewhat lower explanatory power and higher prediction errors. Nevertheless, all three models exhibited similar relationships between their CV and test-fold results, supporting the consistency of the ACO-selected feature subsets across the different ensemble learning mechanisms.
Overall,
Figure 4 demonstrates consistent predictive performance across repeated cross-validation and test-fold evaluations. These findings support the reliability of the ACO-selected feature subsets within the evaluated dataset and complement the feature-selection and model-performance results presented in the preceding sections.
4.7. Comparative Performance Evaluation
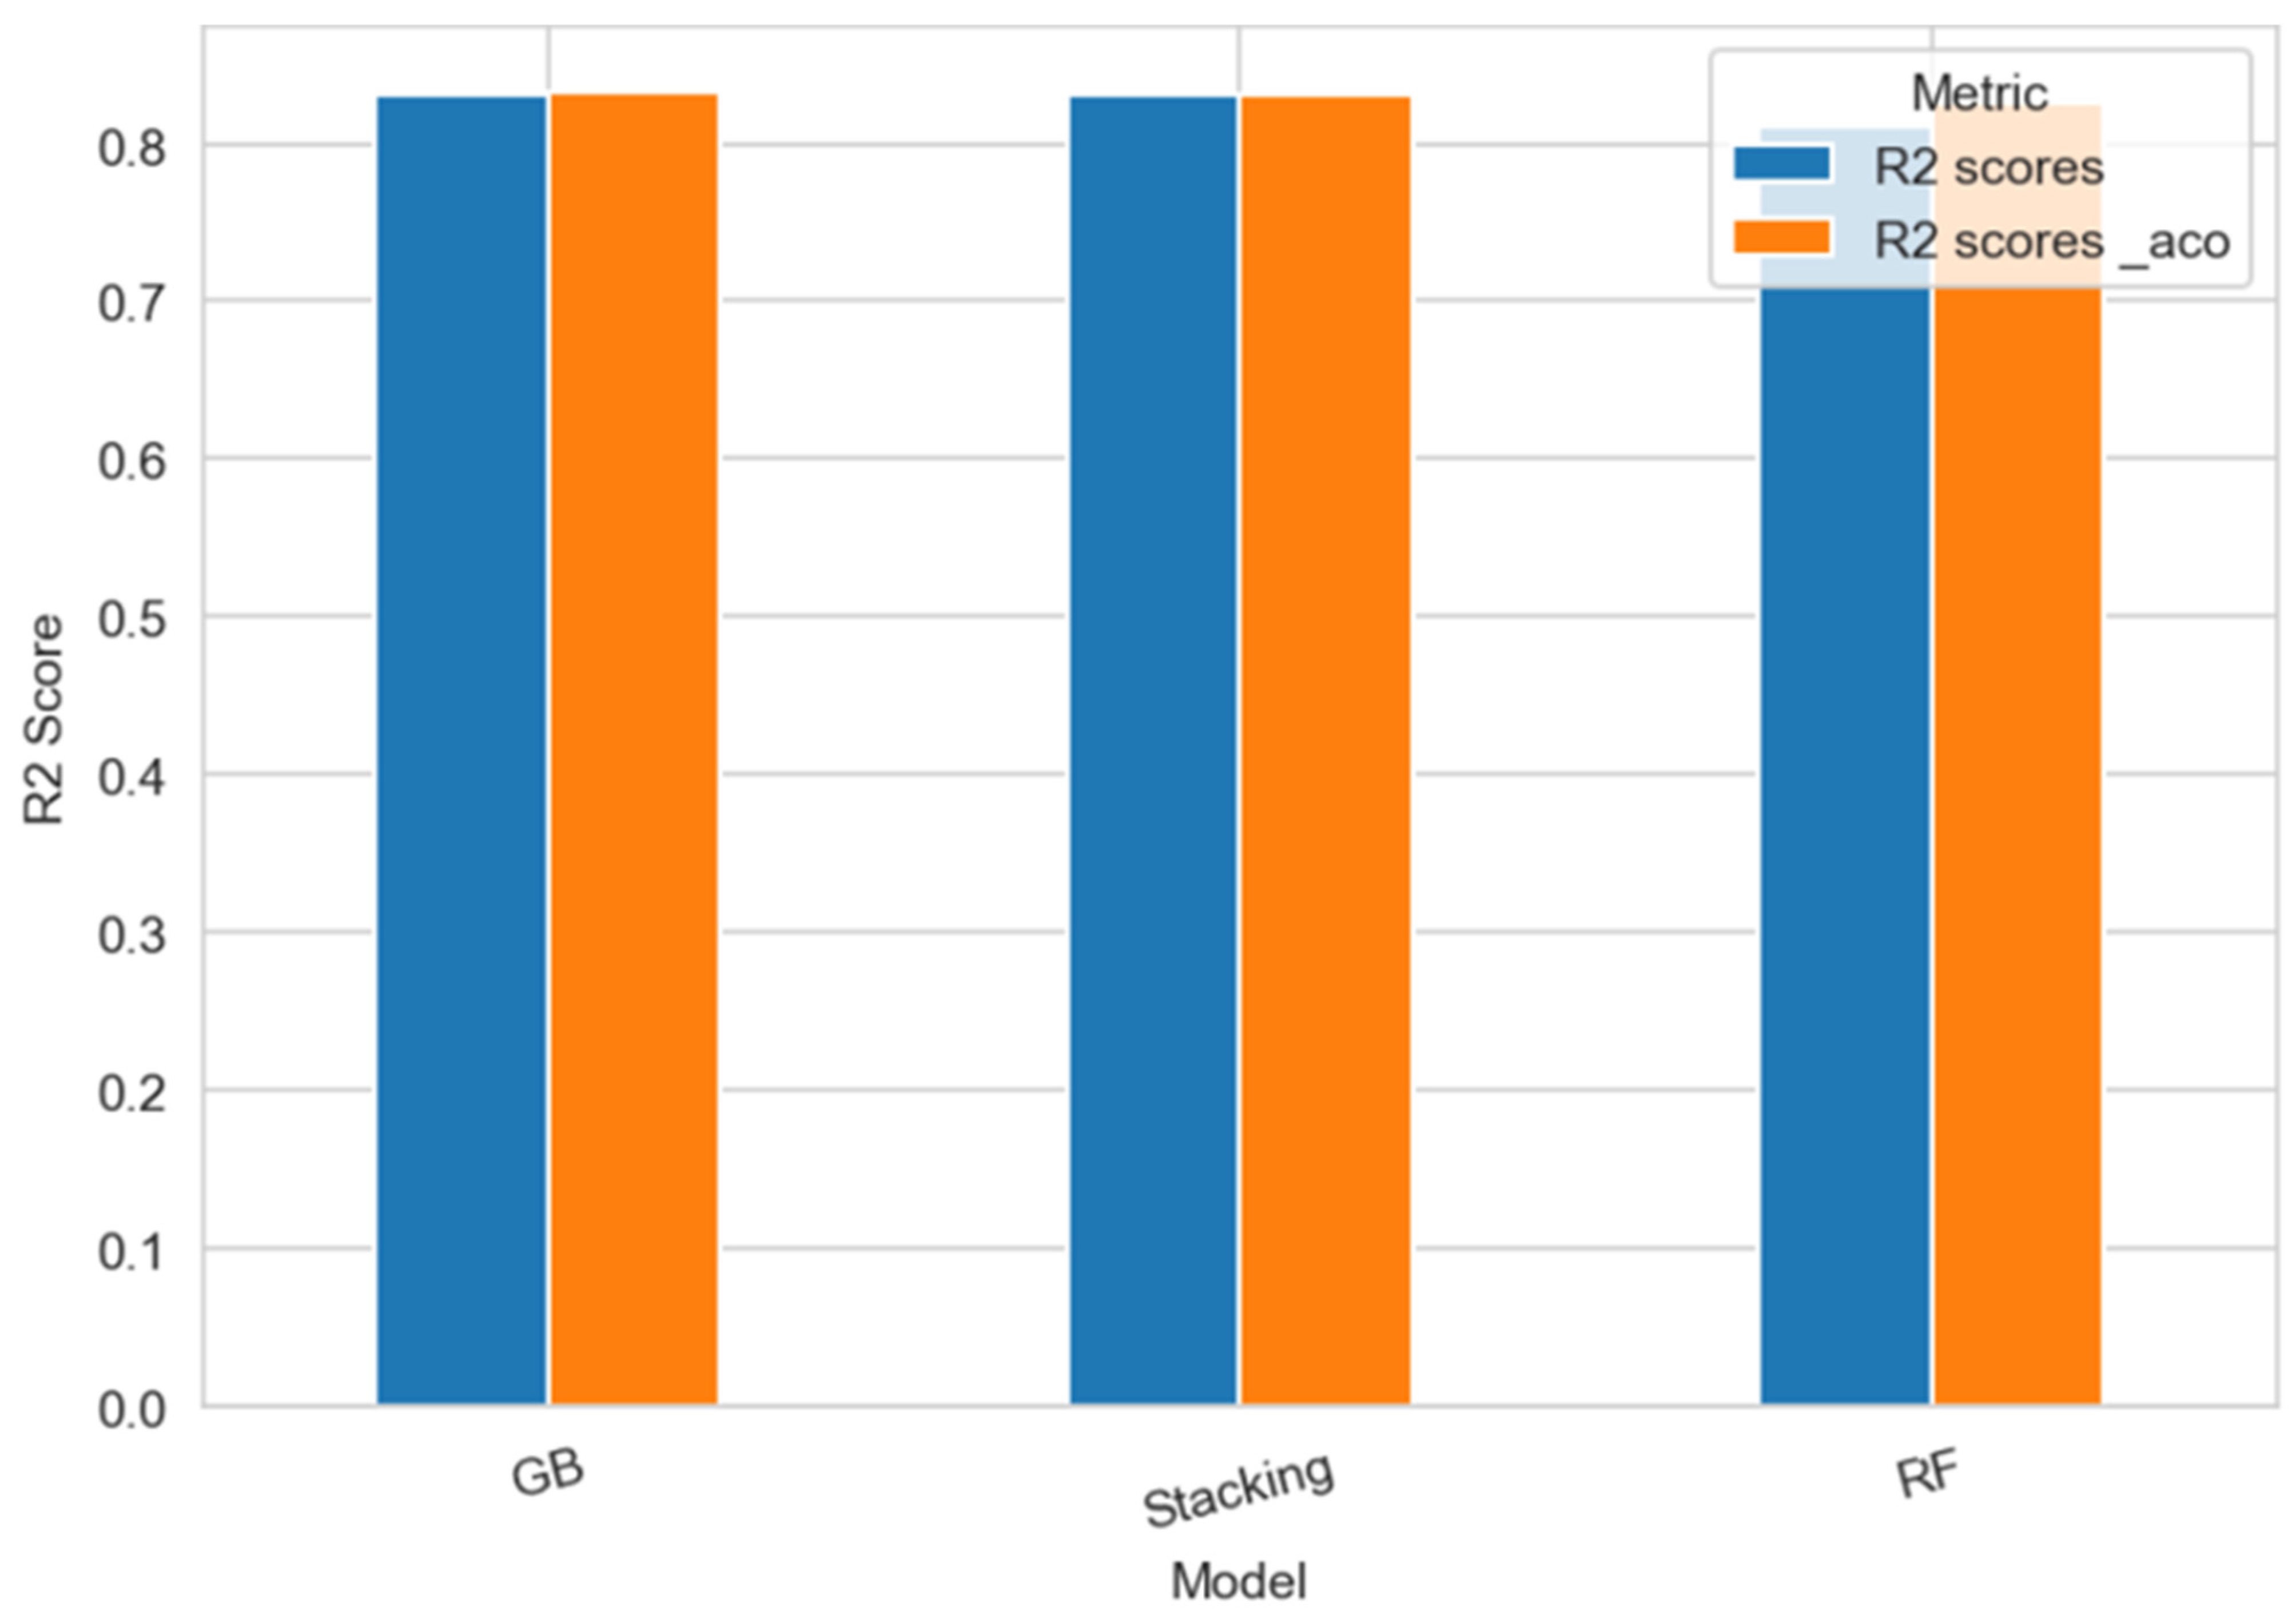
Figure 5 compares the R
2 values of the baseline ensemble models with those of their corresponding ACO–ensemble models. The comparison assesses whether ACO-based FS affected the explanatory performance of GB, Stacking, and RF after reducing the number of LMS engagement predictors.
The results show that ACO-based FS improved R2 across all three ensemble models. For GB, R2 increased from 0.8310 for the baseline model to 0.8332 for the ACO–ensemble model. Similarly, Stacking increased from 0.8302 to 0.8313, while RF showed the largest improvement, increasing from 0.8109 to 0.8265. These results indicate that reducing the predictor space did not compromise the explanatory performance of the models.
The improvement was most pronounced for ACO-RF, with an increase of ΔR2 = 0.0156. This suggests that some of the predictors removed during ACO-based feature FS contributed limited additional information for RF and that their removal consequently enhanced predictive performance. The smaller improvements observed for GB and Stacking indicate that these models were less affected by the removal of the excluded predictors.
The reduction in feature space was also achieved with fewer predictors. The GB model was reduced from nine to six predictors, while Stacking and RF were reduced from nine to seven predictors. Thus, ACO removed predictors without reducing the proportion of variance explained by any of the three ensemble models. Rather, the observed increases in R2 suggest that the retained predictors provided a more concise representation of the information relevant to predicting students’ forum consumption behaviour.
Overall,
Figure 5 provides visual evidence that ACO-based FS enhanced or preserved model explanatory performance while reducing the number of LMS engagement predictors. The results support the study objective of identifying a compact set of informative engagement indicators for predicting forum consumption behaviour, while demonstrating that the effect of feature reduction varied across the three ensemble learning mechanisms.
6. Conclusions
This study proposed a hybrid ACO–ensemble learning framework for predicting students’ forum consumption behaviour using LMS-derived engagement indicators. Guided by EDM and Social Learning Theory SLT, the framework integrated wrapper-based Ant ACO with three complementary ensemble regression models—RF, GB, and Stacking—to identify informative engagement indicators while reducing predictor redundancy.
The results demonstrate that ACO-based FS effectively reduced the original nine LMS predictors to six for GB and seven for Stacking and RF, without compromising predictive performance. All three ACO–ensemble models achieved improved R2 and reduced prediction errors compared with their corresponding baseline models. ACO-GB achieved the strongest overall predictive performance, while ACO-RF demonstrated the largest improvement relative to its baseline model. These findings indicate that the excluded predictors contributed limited additional predictive information and that ACO was able to identify more compact subsets while retaining the information required to predict forum consumption behaviour.
The consistency of the results across the evaluated ACO parameter configurations provides empirical evidence of parameter consistency within the tested search settings. Furthermore, the close agreement between repeated cross-validation and test-fold performance indicates that the ACO–ensemble models maintained consistent predictive performance across repeated data partitions. These findings collectively address the study objectives by demonstrating that ACO-based wrapper FS can reduce LMS predictor dimensionality while maintaining or improving predictive performance across complementary ensemble learning approaches.
The study also provides educational insights into the multidimensional nature of student engagement. The selected predictors represented behavioural, cognitive, and social engagement dimensions, suggesting that forum consumption behaviour is associated with broader patterns of LMS participation, learning-resource interaction, and forum participation. This supports the use of LMS interaction indicators as measurable proxies for understanding student engagement within online learning environments.
Methodologically, the study demonstrates the potential of combining intelligent FS with complementary ensemble learning mechanisms to develop more parsimonious predictive models. The resulting feature reduction also improves the interpretability of the predictor space by highlighting engagement indicators that contributed most consistently to the prediction task. From a learning analytics perspective, these findings can support the development of data-driven approaches for monitoring student engagement and identifying patterns associated with forum consumption behaviour.
Future research should validate the framework using datasets from different institutions, disciplines, student populations, and LMS platforms to assess its broader applicability. Future studies could also examine multiple random seeds and more extensive ACO sensitivity analyses to further assess stochastic stability, as well as investigate alternative optimisation algorithms and additional LMS engagement indicators. Such extensions could provide further evidence regarding the robustness, generalisability, and interpretability of ACO-based FS for educational predictive modelling.