


Abstract
Accurate short-term forecasting of solar photovoltaic (PV) power output is essential for efficient grid integration and energy management, especially given the widespread global adoption of PV systems. To address this research gap, the present study introduces a scalable, interpretable ensemble learning model of PV power prediction with respect to a large PVOD v1.0 dataset, which encompasses more than 270,000 points representing ten PV stations. The proposed methodology involves data preprocessing, feature engineering, and a hybrid ensemble model consisting of Random Forest, XGBoost, and CatBoost. Temporal features, which included hour, day, and month, were created to reflect the diurnal and seasonal characteristics, whereas feature importance analysis identified global irradiance, temperature, and temporal indices as key indicators. The hybrid ensemble model presented has a high predictive power, with an R2 = 0.993, a Mean Absolute Error (MAE) = 0.227 kW, and a Root Mean Squared Error (RMSE) = 0.628 kW when applied to the PVOD v1.0 dataset to predict short-term PV power. These findings were achieved on standardized, multi-station, open access data and thus are not in an entirely rigorous sense comparable to previous studies that may have used other datasets, forecasting horizons, or feature sets. Rather than asserting numerical dominance over other approaches, this paper focuses on the real utility of integrating well-known tree-based ensemble techniques with time-related feature engineering to derive real, interpretable, and computationally efficient PV power prediction models that can be used in smart grid applications. This paper shows that a mixture of conventional ensemble methods and extensive temporal feature engineering is effective in producing consistent accuracy in PV forecasting. The framework can be reproduced and run efficiently, which makes it applicable in the integration of smart grid applications.
1. Introduction
The accelerating shift toward renewable energy has positioned solar PV systems at the forefront of global strategies aimed at reducing carbon footprints and achieving energy sustainability [1]. Supported by favorable policies and substantial investments, PV installations have rapidly expanded across both developed and emerging economies. However, the inherent variability and intermittency of solar energy, driven by fluctuating meteorological conditions such as irradiance, temperature, humidity, and cloud cover pose significant challenges for grid operators [2]. This unpredictability complicates energy dispatch planning, real-time balancing, and the overall stability of power systems. Against this backdrop, accurate short-term forecasting of PV power output has become critically important [3]. Reliable predictions enable better integration of solar energy into smart grids, optimize renewable scheduling, and help contain operational costs [4]. Traditional forecasting approaches rooted in physical modeling or classical statistical methods often fall short, primarily due to their assumptions of linearity or static environmental relationships. These limitations hinder their effectiveness under diverse and rapidly changing weather scenarios [5].
In contrast, data-driven approaches, particularly machine learning (ML) and deep learning (DL) techniques, have emerged as powerful alternatives. These methods can capture complex, nonlinear dependencies directly from historical data without imposing rigid parametric assumptions [6,7]. Despite their promise, several gaps persist in the current literature. Many existing studies rely on small or site-specific datasets, limiting the generalizability of their models. Moreover, the rich temporal structures inherent in solar power generation data, such as daily and seasonal cycles, are often underutilized [8]. Additionally, hybrid ensemble strategies that could harness the strengths of multiple algorithms remain relatively unexplored, particularly in the context of PV forecasting [9,10].
To address these challenges, this study proposes a scalable and interpretable ensemble learning framework for short-term PV power prediction. Using the comprehensive PVOD v1.0 dataset, which comprises over 270,000 high-frequency observations across multiple PV stations, the framework integrates robust temporal feature engineering with a hybrid ensemble of Random Forest, XGBoost, and CatBoost models. This approach not only captures the intricate nonlinear relationships between environmental and temporal variables but also ensures computational efficiency and interpretability, key requirements for real-time applications in smart grids. This work contributes a reproducible, practical solution by systematically integrating temporal feature engineering with an ensemble of established tree-based algorithms, thereby demonstrating the effectiveness of this integration strategy for operational deployment in smart grids.
2. Literature Review
The prediction of photovoltaic (PV) power output has seen continuous use of machine learning (ML) and deep learning (DL) methods, due to the demand for accurate and real-time forecasting of solar energy in smart grid systems. Numerous studies have explored various models, datasets, and feature combinations to enhance forecasting performance, yet several methodological and practical gaps remain.
Hamad et al. conducted a broad comparative study using classical ML models, including Linear Regression, Ridge Regression, Decision Tree Regression (DTR), Gradient Boosting Regressor (GBR), and Artificial Neural Networks (ANN), for predicting the maximum power point (MPP) in PV systems. Tree-based models, particularly DTR and GBR, exhibited superior performance (R2 > 0.999). However, their use of simulated data from a single configuration limited generalizability across real-world systems [11]. Recognizing the need for robust, multi-site datasets, Yao et al. introduced the PVOD v1.0 dataset comprising over 270,000 observations from ten PV stations in China, capturing both meteorological and numerical weather predictions. This dataset has become foundational for reproducible ML experimentation. Despite its richness, many studies underutilized the temporal structure inherent in the data, such as daily and seasonal trends, thereby limiting insights into systematic variations. Ma et al. explored input dimensionality using Long Short-Term Memory (LSTM) models. Their results showed that irradiance combined with historical power data yielded the highest accuracy, while excessive feature inclusion degraded performance due to multicollinearity. Notably, the study lacked exploration of ensemble techniques and interpretability, both crucial for practical deployment [12]. Similarly, Tripathi et al. tested Support Vector Machine Regression (SVMR), Gaussian Process Regression (GPR), and Multivariate Regression (MR) on rooftop solar data, demonstrating strong performance (R2 = 0.99) for SVMR. However, their focus on a single rooftop limited climate generalization [13]. Dinh et al. employed ANN models enhanced with Relief and correlation-based feature selection (CFS), which improved accuracy, though their model relied heavily on manual hyperparameter tuning and a narrow environmental scope [14].
Several recent studies have shifted toward boosting-based models as shown in Table 1. A 2020 study comparing XGBoost, Random Forest, and Linear Regression found that XGBoost outperformed others in R2 and MAE, effectively modeling nonlinear behavior, though neglecting external factors such as shading [15,16]. In 2021, ensemble and kernel-based models (KNN, ANN, SVR, RF) reaffirmed Random Forest and SVR’s effectiveness, despite limited metric depth and hyperparameter tuning [17,18,19]. Deep learning began to gain traction by 2022, with comparisons of ANN, SVM, and XGBoost revealing XGBoost’s top accuracy and ANN’s proficiency in nonlinear mapping [20,21]. Still, small datasets and limited optimization posed issues. By 2023, studies benchmarked traditional models like LR, DT, RF, and Gradient Boosting, again affirming the dominance of tree-based models, although deep learning models were not compared [22]. In 2024, LightGBM and KNN were evaluated in a microgrid context. LightGBM outperformed KNN across all metrics but incurred higher memory and training time costs. Another study validated XGBoost’s strength across multiple stations for daily solar radiation prediction, though sensitivity to data shifts and lack of ablation analysis were noted. Additional works used RF and regression-based models for environmental inputs, identifying irradiance, temperature, and humidity as key features, yet failed to integrate hybrid ensemble strategies [23]. However, its computational intensity limited deployment in real-time grid applications. A number of 2025 papers have also developed PV power prediction with feature-enhanced ML and hybrid methods [24], joint systematic feature selection, and ensemble learning to enhance PV power prediction performance, but they only examined a single-site dataset and did not examine multi-station generalization using open benchmarks [25]. The authors of [26] examined machine learning–informed PV forecasting in separate climatic areas in Nigeria, showing the superiority of tree-based forecasting and kernel approaches, but their models were not trained using a region-independent multi-station dataset like PVOD v1.0. The authors of [27] used Bayesian hyperparameter optimization to optimize individual ML regressors to predict PV power, with a focus on model selection and tuning instead of a well-defined hybrid ensemble. Meanwhile, interpretable statistical models such as factor analysis and Ridge Regression offer good baselines but cannot represent nonlinear interactions between high-dimensional meteorological inputs, and hybrid signal processing and deep learning schemes involving wavelet/VMD decomposition hill neural networks present significant implementation challenges due to complexity.
Table 1.
Comprehensive summary of machine learning and hybrid approaches for PV power forecasting.
Despite the breadth of work, critical gaps remain:
- 1.
- Many models are trained on site-specific or small datasets, undermining generalizability.
- 2.
- The temporal structure of solar data remains underutilized.
- 3.
- Hybrid ensemble models remain underexplored.
It is worth mentioning that the reported performance metrics in the literature are based on heterogeneous datasets with varying geographic locations, temporal resolutions, forecasting horizons, and input features. As a result, the numerical values of R2, MAE, or RMSE of such works cannot be fairly compared to the outcomes of this study. This is why the current work is dedicated to an intense assessment of the PVOD v1.0 dataset and regards its results as supplementary, but not necessarily superior, to the previous practices. Our work aims to reduce these restrictions by analyzing an ensemble-based systematic learning system to predict PV power using the PVOD v1.0 dataset. It uses a framework that incorporates Random Forest, XGBoost, and CatBoost based on soft voting with time-engineered features (hour, weekday, month). Although these algorithms are established in their own right, when combined together with an optimized voting mechanism, they perform better than each individual algorithm alone. This step-wise improvement proves the usefulness of ensemble integration in multi-station PV forecasting. Importantly, our framework maintains computational efficiency and interpretability, with feature importance analysis highlighting global irradiance, temperature, and temporal indices as the most impactful predictors. This work presents a robust advancement in PV forecasting by integrating ensemble learning, temporal engineering, and open access data, bridging the gap between academic innovation and real-world deployment in smart grids.
3. Proposed Methodology
This section provides an overview of the proposed methodology that is shown in Figure 1. The proposed methodology is divided into three sections. Section A involves data preparation, where data is collected from [31] and preprocessing steps are carried out to clean the data along with data splitting. Section B contains an overview of the different models used and of the ensemble method applied on the best-performing models. Section C involves model training, performance analysis, and model comparison. By using engineered temporal features and integrating multiple learning algorithms, the ensemble models significantly improve generalization and adaptability, thereby supporting scalable and reliable solar power forecasting in real-world smart grid environments.
Figure 1.
Overview of the proposed ensemble learning framework for PV power forecasting.
3.1. Data Preparation
3.1.1. Dataset Collection
In this study, we utilized the PVOD v1.0 dataset [31], a publicly available, high-resolution dataset specifically designed for PV power forecasting and related tasks, such as solar irradiance prediction, grid stability analysis, and wind power forecasting. Developed by Tiechui Yao and colleagues, PVOD v1.0 contains a total of 271,968 records, each collected at 15 min intervals, making it one of the most comprehensive open access datasets in this domain. This dataset was built on two main sources of data, namely numerical weather prediction (NWP) data, which is availed by meteorological services, and local measurements data (LMD) directly collected in PV power stations. The NWP component contains seven parameters: global irradiance, direct irradiance, temperature, humidity, wind speed, wind direction, and pressure. Similarly, seven features in the LMD subset include global irradiance, diffuse irradiance, temperature, pressure, wind direction, wind speed, and photovoltaic output power.
3.1.2. Data Visualization
The data only consists of the photovoltaic (PV) power generation data that were recorded at ten isolated stations, which were numbered station00 to station09. Stations provide various geographical or operational arrangements and provide specific time-series data that are used to study solar energy patterns. The data in each station contain one of the most important parameters: power output during a specified interval. The energy generated by the stations differs according to the environmental conditions and the efficiency of the panels. To assess the quality and variability of the data, descriptives of an average, maximum, minimum, standard deviation, and the total record count of each station were computed, as shown in Table 2. For example, station00 had the lowest mean power of 0.83 kW, which suggests either low solar irradiance or a lack of high-power output, indicating an unproductive site, and station05 had the highest average power of 7.06 kW, with the maximum output reaching 35.12 kW, which indicates that it was a very productive site. The values of standard deviation were 1.28–9.75, indicating various degrees of variability in the amount of power that was delivered by various stations. This is the initial stage of data analysis in terms of data distribution and provides the basis for the development of the machine learning models, especially those related to forecasting and optimization of Solar energy work. Figure 2a represents an aggregated view of the total power output from all stations combined. On this plot, one can observe evident seasonal patterns, with the power production being relatively lower in the second half of 2018 and slowly rising at the beginning of 2019. A rise in power generation during spring and summer in 2019 indicates a better environment in terms of solar irradiance or better system performance. Another phase of lower generation is also indicated in the graph, which could be because of some environmental event like cloudy seasons, system outages or maintenance activities. Figure 2b decomposes the power output data by each station, each of which is represented by a different color. This visualization gives an idea of the unique operational schedule and performance pattern of each station. Peak outputs of stations such as station05 are much greater (up to 35 kW), which means that these stations have either a greater system capacity or better exposure conditions. Conversely, station00 and station09 have a lower mean output which perhaps can be attributed to changes in location, panel efficiency, or weather conditions. It is also observed that not all stations had the same time of operation; some had begun or ended data recording at different times.
Table 2.
Statistical evaluation of collected data.
Figure 2.
Time-series analysis of photovoltaic power output across all stations. (a) Aggregated time-series of photovoltaic (PV) power output across all stations (b) station-wise PV power output over the same period, illustrating temporal variability and inter-station differences under a consistent power scale.
Overall, Figure 2 can be viewed as a complete picture of the changes in power generation over time, as well as its variability among various PV stations. It can offer good context to understanding energy generation patterns, comparisons of station performance, and additional predictive modeling/optimization processes. Figure 3 shows two box plots showing the PV power production distribution per month and by season. The plot on a monthly basis, presented in Figure 3a, shows that the power output is maximum in the months of March through June, with a larger median and improved variance, which is a desirable solar condition. Conversely, winter months, such as January, February, November and December, are associated with low output and less variability, probably because of the shorter days and cloudy skies. Figure 3b shows that in the seasonal plot, summer yields the second-highest median power output after spring, followed by fall and winter, which have the lowest. The most productive season of PV generation is spring, with the most favorable balance of sunshine and temperature.
Figure 3.
Monthly and seasonal distributions of photovoltaic power output. (a) Monthly power output distribution; (b) Seasonal power output distribution.
All in all, temporal patterns are cloudless, and the production of solar energy drops sharply in late summer and in the fall. This demonstrates the significance of seasonal planning in PV system optimization and energy forecasting.
The dual-source structure permits the combination of the forecasted and observed environmental variables and increases the robustness and reality of predictive modeling programs. Because of its large size, high temporal granularity, and varieties in feature space, the dataset fits perfectly as a benchmark toward training and validation of machine learning models for short-term PV power forecasting. Additionally, the availability of synchronized weather predictions and real-time PV outputs enables experimentation with both reactive and proactive prediction techniques. This work retains the diversity of datasets to design and test a plane-based ensemble scheme that would generate accurate yet interpretable solar energy predictions in different environmental situations.
3.1.3. Data Preprocessing
The raw data of the PVOD v1.0 dataset was preprocessed before the model development to facilitate consistency, completeness, and the appropriateness of machine-learning-based prediction. Since the dataset includes a mixture of the numerical weather prediction (NWP) forecast variables and the meteorological data measured locally (LMD), special attention was paid to the alignment, cleaning, and organization of the mixed inputs. The preprocessing included the steps of timestamp alignment and station-wise combining of the NWP and the LMD data streams. These two sources of data were kept with equal time intervals and, thus, synchronized with stable timestamps and station identifiers to create a combined record of observations. Samples that had no timestamps or had a mismatched time were eliminated to ensure that all features were coherent in time. Thereafter, data quality control was implemented to deal with the missing values and outliers. The dataset was very complete; however, there were some isolated gaps that were managed by using suitable feature normalization and imputation methods by using statistics that were only calculated from the training data. The preprocessing parameters that were estimated were used directly on the validation and test sets. This process guarantees a name that breaks down training and evaluation information and prevents information leakage. In continuous variables, including irradiance, temperature, and wind speed, the missing values were linearly interpolated between each station to preserve the local time trends. Directional variables such as wind direction were filled with forward-filled mode-based imputation where needed. Through threshold-based filtering based on physical plausibility and statistical distribution, the presence of outliers was identified and eliminated. Values that crossed metro-logical limits (e.g., negative irradiance) or values with high deviations with high percentile thresholds were filtered to avoid distortion of the learning process. The above preprocessing procedures guaranteed that the resulting data was physically sound, statistically sound, and capable of training effective models.
Scaling of features was performed based on the requirements of the models. The algorithms that are sensitive to the feature magnitude (e.g., SVR and KNN) were min-max scaled individually by each station using the training data statistics to rescale numeric features to the [0, 1] range. In the models that are tree-based, like Random Forest and XGBoost, the raw feature values were kept, since these models are not sensitive to the scaling of features. In order to add temporal context, further time-related features were constructed out of the timestamp, such as hour of day, day of week, and month, which were represented by sine and cosine transformations of the cyclical relationships. Moreover, a binary daylight sensor was installed to differentiate between the day and the dark time because the PV power output is minimal in hours of no illumination. The above preprocessing procedures helped to make the input data consistent over time, controlled in terms of quality, and filled with time-related information, providing an opportunity to evaluate the suggested forecasting framework on the basis of reproducible and practically applicable results.
3.1.4. Model Hyperparameters and Implementation Details
To fully replicate and be completely transparent, this subsection presents the full hyperparameter settings, implementation environment, data splitting policy, and analysis plan of the ensembled models explored in this paper, as presented in Table 2. Ensemble models in Python were implemented with standard open-source libraries, such as scikit-learn, XGBoost, and CatBoost. The PVOD v1.0 dataset was separated on a chronological (time-conscious) basis, with the first 70% of observations being used to train the model, 15% to validate, and the remaining 15% to test. The approach maintains the temporal causality and remirrors the conditions of realistic forecasting. None of the preprocessing operations, such as missing-value imputation, feature scaling, or hyperparameter tuning, were performed on the validation and test sets to avoid information leakage, and they were only performed on the training data.
Tuning was performed with the help of validation, and hyperparameters were chosen and fixed before final testing. Random seeds were pinned to all the stochastic processes of learning, such as constructing trees and sampling data, to ensure reproducible and repetitive results.
3.1.5. Tree-Based Models and Ensemble Strategy
The three tree-based learning algorithms proposed include Random Forest (RF), XGBoost (XGB), and CatBoost (CB). Individual training was performed on every base learner using the same training and validation splits, the same feature sets, and the hyperparameters in Table 3. Equal-weight soft voting was used to obtain the ensemble prediction, i.e., the end-of-time photovoltaic power estimate was determined as the arithmetic average of the model outputs. The weighting method used was specifically chosen to ensure interpretability, reduce sensitivity to the bias of a given model, and prevent overfitting of the validation sample. Equal-weight aggregation is also able to offer stable performance when the temporal and spatial conditions are heterogeneous, without further increasing tuning complexity.
Table 3.
Hyperparameters of ensemble models.
RMSE, MAE, and the R2 were used to determine model performance in all experiments. RMSE focuses on bigger prediction errors, MAE focuses on average absolute errors, and R2 focuses on the percentage of variance explained by the model. These measures were calculated on the held-out test set alone and reported equally to form a fair comparison of the models.
3.1.6. Feature Selection
Effective feature selection is critical for enhancing model accuracy, reducing overfitting, and improving computational efficiency in photovoltaic (PV) power forecasting. In this study, the selection of input features was guided by a combination of domain knowledge, exploratory data analysis, and feature importance rankings derived from tree-based models. All variables that could be found in the dataset containing NWP, as well as LMD, were discussed at the beginning of the development process. These characteristics included environmental factors like global irradiance, diffuse and direct irradiance, temperature, humidity, wind speed, wind direction, and atmospheric pressure, as well as the output power of a photovoltaic device as the variable of interest. To identify the most influential predictors for photovoltaic (PV) power forecasting, both correlation analysis and feature importance evaluation were performed. These analyses are presented in Figure 4a–d, providing insights into the statistical relationships among features and their contributions to model performance. Figure 4a illustrates the complete feature correlation heatmap, showing Pearson correlation coefficients between all numerical features in the dataset. The color intensity represents the strength and direction of correlation, where values close to +1 indicate strong positive relationships, and values near −1 indicate strong negative relationships. From this heatmap, strong correlations were observed between PV power output and several irradiance-related features, particularly lmd_totalirradiance, nwp_globalirradiance, and nwp_directirradiance. On the other hand, variables such as wind direction, pressure, and humidity displayed weak or inconsistent correlations with power output, suggesting their limited relevance in predictive modeling. To narrow the focus, Figure 4b presents a focused correlation matrix consisting only of features directly associated with PV power generation. This simplified view confirms that lmd_totalirradiance and nwp_directirradiance have the highest correlation with PV power, with coefficients of 0.87 and 0.88, respectively. This focused matrix helped prioritize features that have the strongest linear relationships with the output variable. In addition to statistical correlation, model-based feature importance was also assessed using tree-based algorithms. Figure 4c displays the feature importances derived from the full set of input variables. Here, lmd_totalirradiance emerges as the most dominant feature, contributing substantially more than other variables. Lmd_pressure, lmd_diffuseirradiance, and nwp_pressure also showed moderate influence, while features like nwp_winddirection and lmd_windspeed had negligible impact. Building on this, Figure 4d highlights the importance of the selected subset of features used in the final ensemble model. Again, lmd_totalirradiance remains the most important predictor, followed by lmd_diffuseirradiance, nwp_temperature, and lmd_temperature. Temporal features such as month, day, and hour contributed modestly, offering contextual signals without overpowering the model. Notably, several low-impact variables identified earlier were excluded to enhance computational efficiency and reduce model complexity.
Figure 4.
Feature correlation and importance analysis for photovoltaic power prediction. (a) Correlation heatmap of all input features, (b) focused correlation matrix highlighting power-related variables, (c) overall feature importance ranking, and (d) selected feature importance illustrating the dominant predictors influencing photovoltaic power output.
Finally, Figure 4a–d provide a comprehensive basis for informed feature selection. By combining statistical correlation with model-driven importance rankings, only the most relevant features were retained, ultimately leading to improved model performance, reduced overfitting, and enhanced interpretability.
Besides the raw meteorological inputs, which are numerical weather prediction (NWP) forecast variables (such as global and direct irradiance, ambient temperature, humidity, wind speed, wind direction, and pressure), some temporal features were constructed based on the timestamp data to reflect daily and seasonal patterns that have an impact on solar energy production. These temporal encodings were hour of day, day of week, and month, as well as sine and cosine encodings of hour and month, to maintain their cyclicity. To extract the most informative predictors, the feature importance analysis was performed with the help of the Random Forest (RF) and Gradient Boosting (GB) models, which automatically rank input variables according to their contribution to a lower decision split prediction error. The outcomes were uniform in the fact that the global horizontal irradiance, the ambient temperature and hour of the day were the most predictive factors of photovoltaic power output, with wind speed and humidity coming next. Other features that had relatively lesser influence, like wind direction and pressure, were only selected in certain model configurations for comparison to determine their marginal contribution. Besides this, correlation analysis was applied to test multicollinearity among input variables. Features that were highly correlated, like global and direct irradiance, were thoroughly checked and reduced. Nevertheless, since tree-based ensemble models are capable of managing correlated inputs, these variables were kept where necessary to enable the models to be more adaptable in terms of feature exploitation. Using these analyses, a set of ideal features, meeting physical relevance and statistical significance as well as computation efficiency, was then chosen and used universally across all models to have a fair and meaningful comparison of performance.
3.1.7. Data Splitting
To provide stringent testing and avoid overfitting, the dataset was divided into three subsets: training, validation, and testing. Initially, the data was sequentially ordered to maintain the temporal pattern that is essential in solar power predictions in the dataset that consisted of more than 271,000 time-stamped measurements of various PV stations made at each 15 m interval between observations. The data was subsequently separated into the following: 70% was used for training to adjust the machine learning models and sign the relationship between the environmental features and the PV power output; 15% was used during model development in terms of hyperparameter optimization, early termination, and evaluation of model performance; and 15% was withheld during training and tuning of the models to obtain an unbiased assessment of the final model performance on unseen data. This measure was performed to make sure that models were not overfitted to the training set but were indeed quite generalizable. The chronological separation strategy represents a probable step of forecasting, in which models are trained on previous information and then applied toward the estimation of future outputs. The methodology eliminates the issue of data leakage and correlates with the working environment of PV forecasting, in which historical environmental and temporal behavior is used to preempt the future generation of solar energy. Through the three-way split, the study establishes the same sturdy testing and comparisons of all models against one another, which allows a fair comparison of individual models as well as ensemble techniques.
3.2. Principle of ML Algorithm
In this section, a prediction model is presented to obtain the maximum efficiency in terms of power forecasting of a PV system using eleven machine learning algorithms: LR, RR, SVR, KNN, CNN, XGBoost, Gradient Boosting, LightGBM, CatBoost, and an ensemble model termed HybrEnNet (Hybrid Ensemble Network). The principles governing the function of these algorithms are presented and discussed.
3.2.1. Linear Regression (LR)
In the context of photovoltaic power forecasting, Linear Regression serves as a foundational approach to modeling the relationship between solar power output and multiple influencing variables [32]. The method assumes a linear dependency between the target variable PV power output and a set of independent features such as global horizontal irradiance, ambient temperature, wind speed, humidity, hour of the day, and month of the year. The Linear Regression model expresses the predicted power output as a weighted sum of these input features, where each feature is assigned a coefficient that quantifies its influence on the output.
Mathematically, the model is represented as:
where is the predicted power, is the intercept, are the learned coefficients, are the input variables, and is the error term. These coefficients are determined during training by minimizing the mean squared error between the predicted and actual power outputs. While Linear Regression is limited in capturing nonlinear dependencies, it provides an interpretable baseline and offers insight into the relative impact of each feature on solar energy generation. In your methodology, it functions as a comparative benchmark against more complex ensemble models, helping to validate the added value of nonlinear learners like Random Forest and Gradient Boosting.
3.2.2. Random Forest
Random Forest is an ensemble learning algorithm that constructs multiple decision trees during training and outputs the average of their predictions for regression tasks [33], as shown in Figure 5. In photovoltaic power forecasting, it effectively captures complex, nonlinear relationships between solar power output and features such as irradiance, temperature, time, and weather conditions. Each tree in the forest is trained on a random subset of data and features, which reduces overfitting and improves generalization.
Figure 5.
Schematic representation of the Random Forest regression model.
Random Forest allows the combination of the estimates made by various trees to produce stable and highly precise predictions and retains the interpretability of predictions due to the feature importance measure. This is a fundamental model used in this study as it can bring good predictive defense at a relatively small cost of calculations and great robustness to corrupted data.
3.2.3. Support Vector Regression
Support Vector Regression (SVR) is a kind of machine learning algorithm that is based on kernels; it tries to use kernels to model the linkage between an input characteristic and a target, wanting to get a relationship based on a kernel that measures an error limit of fit approximating the data [34]. SVR finds some application in the photovoltaic power forecasting area, where nonlinear dependencies between environmental conditions, including irradiance, temperature, wind speed, humidity, and consequent power production, are involved.
Through kernel functions (i.e., radial basis function or polynomial) and by mapping the input data into a higher dimensional space, the data separability can be achieved linearly, as depicted in Figure 6. It seeks to reduce the complexity of the model at the same time, controlling the error in the prediction. Thus, it is applicable to both datasets with few samples or high dimensions. In the study, SVR will supplement the ensemble models by offering a lightweight yet powerful way to model the variability intrinsic to solar power generation [35].
Figure 6.
Schematic diagram of the Support Vector Machine (SVM).
3.2.4. K-Nearest Neighbors (KNN)
KNN is another instance-based learning algorithm; it classifies a data point by looking at what previous, more familiar ones are labeled as. Unlike parametric algorithms, KNN is non-parametric, meaning that it does not make any prior assumptions about the data. KNN has also been applied in forecasting photovoltaic power production based on its ability to observe similar patterns in environmental conditions, e.g., irradiance, temperature, and humidity between time points and hence predict the solar power generation [36].
It does not require prior training, making it simple to implement, and it adapts naturally to nonlinear patterns in the data as it is illustrated in Figure 7. However, its performance can be sensitive to the choice of k and the distance metric, as well as to the density and scale of the dataset. In this study, KNN serves as a baseline model for comparing performance with more advanced ensemble and kernel-based methods, providing insight into the role of local similarity in solar power prediction.
Figure 7.
Visualization of the K-Nearest Neighbors (KNN) classification algorithm.
3.2.5. Convolutional Neural Network (CNN)
CNN, originally developed for image processing tasks, have shown strong potential in time series and environmental data modeling due to their ability to automatically extract spatial and temporal features. In photovoltaic power forecasting, CNN can identify complex patterns and interactions among input variables such as solar irradiance, temperature, humidity, and atmospheric conditions by applying convolutional filters over sequential data. This hierarchical feature extraction enables the model to learn localized dependencies and structural variations in the input space as illustrated in Figure 8. When applied to grid-based or multivariate time series data, CNN offer high accuracy and robustness, especially in large datasets [37]. In this study, CNN are utilized to enhance prediction performance by capturing deep feature representations that may be overlooked by traditional regression or shallow learning methods.
Figure 8.
Architecture of a Convolutional Neural Network (CNN) for feature extraction and classification.
3.2.6. Extreme Gradient Boosting (XGBoost)
Extreme Gradient Boosting (XGBoost) is an efficient and high-performance gradient-boosted decision tree ensemble learning algorithm developed to work in high-performance scenarios, as shown in Figure 9. In photovoltaic power prediction, XGBoost is found to be useful in the modeling of complicated and nonlinear interactions between input variables, such as irradiance, temperature, wind speed, and time variables via the sequential construction of trees to rectify residual errors of the preceding models.
Figure 9.
Architecture of the Extreme Gradient Boosting (XGBoost) model.
It has methods of regularization to avoid overfitting and could support parallel processing [38]. Therefore, it will not only be accurate but also efficient in computation. This paper adopts XGBoost as a machine learning algorithm to improve the prediction accuracy and model generalization to provide a powerful competitor of conventional models and deep learning models in representing the interferences of solar energy output.
3.2.7. Gradient Boosting
Gradient Boosting is a form of sequential ensemble learning in which predictive models are constructed as a combination of the capabilities of several weak learners, often decision trees. More specifically, within the line of reasoning of PV power prediction, Gradient Boosting is a method that gradually reduces the error in predictions by fitting the new tree to the residuals of the last and essentially learns the intricate nonlinear associations between the environmental and time-related conditions like irradiance, temperature, and time of the day. Its capacity to discriminate hard-to-anticipate instances increases the importance of accuracy as well as model solidity [39]. In the present analysis, Gradient Boosting is incorporated into a system of hybrid ensembles to enhance the process of forecasting, which allows a striking compromise between predictive performance, interpretability, and efficiency.
3.2.8. Light Gradient Boosting Machine (LightGBM)
LightGBM is a very efficient gradient boosting framework that is optimized in speed and scalability and best applied when working with large volumes of data and high-dimensional characteristics, as shown in Figure 10. LightGBM is an ideal tool in photovoltaic power forecasting. In photovoltaic power forecasting, LightGBM effectively models nonlinear dependencies between variables such as solar irradiance, temperature, humidity, and temporal indicators by building leaf-wise decision trees with depth constraints. Compared to traditional boosting methods, LightGBM offers faster training, lower memory consumption, and improved accuracy through techniques like histogram-based decision splitting and gradient-based one-side sampling [40]. In this study, LightGBM is leveraged as part of an ensemble strategy to enhance predictive performance while maintaining computational efficiency, making it suitable for real-time applications in smart grid environments.
Figure 10.
Boosting Framework for model training and prediction.
3.2.9. CatBoost
CatBoost is a gradient boosting algorithm designed to work with categorical features efficiently to minimize overfitting by using ordered boosting and small variance sampling, as shown in Figure 11. Undoubtedly, when it comes to the application of CatBoost in photovoltaic power forecasting, it works best in modeling nonlinear interactions between a variety of input variables defined by irradiance, temperature, wind speed, humidity, time-based features, etc.
Figure 11.
Illustration of the Random Forest ensemble model using majority voting.
Its categorical data support, the ability to automatically store missing values, and ease of preprocessing simplify the process by providing high predictive accuracy [41]. To provide a fast and accurate model with good explainability, this study can apply the CatBoost as the ensemble learning model to improve the robustness of the model and generalization, which would serve as an effective model to predict solar power during real-time activities.
3.2.10. Lasso Regression
Lasso Regression is a form of Linear Regression, the use of which involves a technique known as L1 regularization, which helps in avoiding overfitting and difficulties when interpreting a model. The Lasso is useful in the scenario of photovoltaic power forecasting as the tool not only allows fitting the linear model of the relation between power output and the characteristics of input variables (irradiance, temperature, humidity) and the factors related to time but also allows selecting features by shrinking the coefficients of the minor features to zero [42]. That is why it is particularly effective when one has to work with high-dimensional or correlated data. Generally, this paper uses Lasso Regression as a simple and interpretable baseline model since it gives an insight into which predictors are most influential and creates a point of reference in comparison to the more sophisticated nonlinear models.
3.2.11. Ensemble Method
To enhance precision, reliability and ability to generalize PV power forecasting, an ensemble model termed HybrEnNet was proposed. This was used to apply the benefit of several different base learners. The ensemble structure input consists of predictions by the best-performing regression models, that is, RF, XGBoost, and CatBoost, as illustrated in Figure 12. All the models are selected considering their unique predictive error and potential to record various elements of the multifaceted nonlinear dependencies among the environmental conditions, the temporal characteristics, and PV power generation. To create the final ensemble prediction, the voting approach is used, in particular, soft voting, according to which the output of each model is averaged to increase the stability and improve the quality of a more stable prediction. This is an ideal procedure of balancing the individual contribution of the models to ensure the use of the complementing advantage of each of them and, in the end, increase the reliability of the overall prediction.
Figure 12.
Architecture of the proposed HybrEnNet framework for photovoltaic power prediction.
The meta-model is trained to find out the ideal combination of base predictions that give minima in terms of overall forecasting error. Layering allows the ensemble to apply the interpretability of linear models to the high performance of nonlinear learners in the sense that it balances the weaknesses of individual models. The ensemble method may be taken as a compromise and a scalable approach to the problem of predicting solar power and is obtained as a mix of different algorithms, some minimizing the run time and some maximizing the accuracy. This architecture is specially adapted to the modeling of the variation in PV with the changing weather and geographically dispersed stations. The results are better predictive stability, lower model bias, and greater deployment flexibility, thus capable of deployment in real-time smart grid operations. Though the suggested framework uses a regression-based learning framework, the short-term photovoltaic power prediction task is addressed in the time-conscious fashion. All the experiments were performed with chronological train-validation-test splits so that only the past was considered to predict future power output. This prevents leakage of the information and facilitates realistic evaluation of the temporal generalization as the evaluation of the models represents the actual conditions of short-term forecasting as opposed to randomly selected sampling.
4. Performance Analysis
The efficiency and dependability of created models in anticipating photovoltaic (PV) power yield were estimated by carrying out an in-depth performance analysis with a variety of evaluation indicators. The measurements were chosen in order to reflect the correctness of the predictions as well as their stability with various models and data settings. The key performance indicator is the Mean Absolute Error (MAE), which denotes the average size of errors between the predicted and measured outputs of PV power and provides a plain picture of forecasting errors in actual quantities (e.g., kW). The less the value of MAE, the higher the performance. Root Mean Squared Error (RMSE) is a metric in which the larger errors are highlighted because differences are squared first and then averaged, which makes it problematic to indicate large errors in the predictions. It is particularly applicable in finding out models that, at times, make massive forecast mistakes. The coefficient of determination (R2) measures how much the variance in the actual power output is being explained by the model. A model with a higher R2 indicates that it has good explanatory and predictive power. In the process of evaluation, all of the trained models that included Linear Regression, Random Forest, Gradient Boosting, XGBoost, LightGBM, CatBoost, SVR, KNN, and CNN were carried out on the held-out test set so that a fair comparison was made. The computed performance measures were plotted as bar graphs and scatter plots and allowed comparison with all models. The HybrEnNet model, which used predictions (soft voting) of various base learners, showed better results compared to the individual models on all the available evaluation metrics and was more accurate and less variable. Such a strict assessment of the performance of various algorithms not only assesses the forecasting abilities of the algorithms but also shows the importance of ensemble learning to identify and capture complex nonlinear patterns in solar power data in varying operational conditions.
Experimental Setup
All experiments were conducted on a high-performance computing workstation configured with an Intel(R) Core(TM) i7-13700 CPU (24 cores, 2.1 GHz), 16 GB of RAM, and an NVIDIA GeForce RTX 4060 GPU. The system operates on a 64-bit platform, ensuring the capability to handle large-scale data processing and model training efficiently.
The computational framework was built using Python (3.9.19) as the primary programming language. Deep learning models were implemented in Keras (2.7.0) with a TensorFlow (2.7.0) backend, enabling streamlined construction, training, and deployment of neural network architectures. Additional development and analysis were facilitated through Visual Studio (1.108.0), alongside essential Python (3.13.3) libraries such as NumPy (2.3.4), Pandas (2.2.3), Matplotlib (3.10.3), and scikit-learn (1.5.2), which supported comprehensive data preprocessing, statistical analysis, and visualization.
This hardware and software configuration ensured reliable execution of all machine learning experiments, providing the computational resources necessary to optimize and evaluate diverse predictive models for photovoltaic power forecasting.
5. Results and Discussion
The performance of different machine learning models in predicting photovoltaic (PV) power output is vividly illustrated in Figure 1, where each subplot provides an actual-versus-predicted scatter plot for a specific model. In the case of Random Forest, shown in Figure 13a, predictions cluster tightly along the diagonal line, indicating excellent alignment with the actual power values. This is supported by its high R2 score of 98.15%, low MAE (~0.66), and RMSE (~0.99), demonstrating strong predictive fidelity. However, despite its strengths in handling complex nonlinear interactions, Random Forest still primarily relies on bagging, which may fall short in adapting to intricate sequential or temporal patterns in PV data. By contrast, Figure 13b depicts the Linear Regression model, where the scatter points are widely dispersed, particularly underpredicting higher power outputs. This limitation in modeling nonlinear relationships is quantified by a relatively modest R2 of 83.01% alongside higher error metrics (MAE ≈ 1.31, RMSE ≈ 2.01). Figure 13c for Lasso Regression reveals even poorer performance, with severe underestimation across mid- to high-power ranges. Its R2 drops to just 71.73%, coupled with the highest MAE (≈1.55) and RMSE (≈2.59) among all models. This underscores how L1 regularization, while helpful for feature selection, overly constrains the model, making it ill-suited for capturing complex PV dynamics. XGBoost’s results, displayed in Figure 13d, show tightly clustered predictions along the ideal line, reflected in an R2 of 98.02%, MAE of about 0.28, and RMSE of approximately 0.68. However, XGBoost requires careful hyperparameter tuning, such as setting learning rates and tree depths to avoid overfitting or underfitting. Figure 13e similarly illustrates LightGBM’s high performance with an R2 of 97.57%, though slightly more spread than XGBoost, accompanied by an MAE ≈ 0.31 and an RMSE ≈ 0.76. While LightGBM offers computational efficiency through histogram-based splitting, it is sometimes more susceptible to instability when handling noisy data. Support Vector Regression (SVR), visualized in Figure 13f, effectively maps nonlinear patterns, achieving an R2 of 97.45% with a MAE around 0.48 and an RMSE close to 0.99. However, its sensitivity to kernel parameters can reduce robustness when underlying data distributions change. Figure 13g shows the KNN, which captures local relationships well, as is evident from its R2 of 97.19%, MAE of roughly 0.78, and RMSE of about 0.82. Still, its reliance on local data density makes it less reliable under variable data regimes. Figure 13h highlights CatBoost’s performance, with predictions closely aligned to actual values, delivering an R2 of 98.09%, MAE near 0.27, and RMSE of about 0.67. While CatBoost’s ordered boosting enhances stability, its effectiveness can diminish without carefully tuned learning rates and tree depths. Gradient Boosting, shown in Figure 13i, also performs well with an R2 of 95.83%, MAE of roughly 0.66, and RMSE of around 1.00, though its simpler boosting iterations can underperform compared to more advanced algorithms. Finally, Figure 13j demonstrates the ensemble model combining Random Forest, XGBoost, and CatBoost, which clearly outshines all others. Predictions are tightly concentrated along the diagonal, reflected in an outstanding R2 of 99.30% and the lowest MAE (≈0.23) and RMSE (≈0.63). Unlike the individual models, the ensemble leverages the strengths of bagging and boosting together, effectively mitigating the limitations of each standalone approach.
Figure 13.
Actual versus predicted PV power output for individual machine learning models (a–i) and the proposed RF–XGBoost–CatBoost ensemble (j), where the ensemble exhibits the closest agreement between predicted and measured values and achieves the highest accuracy.
This comparative evaluation in Figure 13 underscores that while individual models like XGBoost and CatBoost excel in capturing complex nonlinearities, they still carry biases tied to their respective learning strategies. In contrast, the ensemble method integrates these diverse strengths, resulting in unprecedented accuracy and robustness, making it the most effective solution for reliable PV power forecasting in practical grid operations.
Figure 14 shows the R2, MAE, and RMSE comparison across different regression models for ten machine learning models used in photovoltaic (PV) power forecasting. Among the individual models, Random Forest, CatBoost, and XGBoost achieved high predictive accuracy, with R2 scores of 98.15%, 98.09%, and 98.02%, respectively. Gradient Boosting, LightGBM, Support Vector, and KNN also performed well, all exceeding 95%. Traditional linear models like Linear Regression and Lasso Regression showed relatively lower accuracy, with R2 scores of 83.01% and 71.73%, respectively, indicating their limitations in capturing the nonlinear patterns in PV data. The ensemble model constructed by integrating Random Forest, XGBoost, and CatBoost through a voting regressor outperformed all combined models with an R2 score of 99.30%. This demonstrates the advantage of ensemble learning in enhancing robustness and generalization for real-world PV power prediction tasks.
Figure 14.
(a) Model comparison based on R2 score for photovoltaic power prediction. (b) Mean Absolute Error (MAE) and Root Mean Square Error (RMSE) comparison across different regression models.
5.1. Station-Wise Performance Evaluation
In order to further test the strength and generalization ability of the proposed HybrEnNet framework, a station-wise analysis was employed, whereby independent models were trained and evaluated in every photovoltaic station in the PVOD v1.0 dataset. Table 4 summarizes the results of the Mean Absolute Error (MAE), Root Mean Squared Error (RMSE), and coefficient of determination (R2).
Table 4.
The station-wise forecasting performance of the proposed HybrEnNet model on the PVOD v1.0 dataset.
The findings show that predictive accuracy is always high at the majority of stations, and the R2 values are greater than 0.97 with low error values, which proves the stability of the ensemble framework under heterogeneous operating conditions. Differences in the accuracy of forecasts are seen among the stations because there are differences in the installed capacity, the variability of the meteorological factors, and operational conditions. Comparatively, station09 has a lower performance, which is caused by lower mean power output and increased intermittency, resulting in a lower signal/noise ratio. This kind of behavior is an expression of variability in the real world and not model instability.
5.2. Robustness Analysis Under Time-Aware, Rolling-Origin, and Station-Wise Evaluations
The extra evaluation schemes also provide insight into the temporal strength and the spatial generalization of the suggested forecasting structure beyond the conventional random train/test divisions. When the model was run under the chronological (time-conscious) blocked split, it attained an RMSE of 0.9917, an MAE of 0.4281, and an R2 of 0.9716, which confirms the existence of strong predictive capability in the case of preservation of temporal causality, and information leakage is avoided. This indicates temporal stability in the learned relationship between meteorological inputs and photovoltaic power output.
The rolling-origin (walk-forward) forecast, known to simulate operational forecasting by making fixed-horizon forecasts sequentially with time, provided an RMSE of 0.8892, an MAE of 0.3615, and an R2 of 0.9772, as shown in Figure 15. The stable behavior of the performance in this environment proves to be a predictable forecasting behavior in changing time situations that are applicable in real-world implementation. When the model was tested on unknown photovoltaic stations in the station-wise generalization test, an RMSE of 0.8839, MAE of 0.3743, and R2 of 0.9694 were achieved. The small loss in performance corresponds to the expected spatial heterogeneity across sites, and the remaining large R2 value suggests good transferability and underfitting to the site-specifics of photovoltaic power prediction.
Figure 15.
Performance comparison under time-aware, rolling-origin, and station-wise evaluation protocols, demonstrating robust temporal consistency and spatial generalization.
5.3. Comparative Description of All Models
The comparative results across all evaluated models reveal clear performance distinctions in short-term PV power forecasting. Traditional linear approaches, including Linear Regression (R2 = 83.01%) and Lasso Regression (R2 = 71.73%), exhibited substantial underfitting, with high MAE and RMSE values exceeding 1.3 kW and 2.0 kW, respectively, as shown in Table 5. These results underscore their limited ability to capture the complex, nonlinear relationships inherent in PV power data.
Table 5.
Comparative results analysis of trained models.
In contrast, tree-based and boosting models demonstrated markedly superior performance. Random Forest, XGBoost, and CatBoost each achieved R2 scores exceeding 98%, with CatBoost slightly leading in terms of lower MAE (0.271 kW) and RMSE (0.673 kW). LightGBM also performed robustly (R2 = 97.57%), balancing predictive power with computational efficiency, while Gradient Boosting maintained a solid R2 of 95.83%, though with somewhat higher error values under peak conditions. Kernel and instance-based models such as SVR and KNN delivered competitive results (R2 > 97%), but they displayed modestly higher error metrics, reflecting sensitivity to data density and local variance.
Most notably, the proposed HybrEnNet model, integrating Random Forest, XGBoost, and CatBoost through a soft voting strategy, achieved the highest overall accuracy, with an R2 of 99.30%, an MAE of 0.227 kW, and the lowest RMSE of 0.629 kW. This illustrates the clear benefit of combining multiple learners to reduce individual model biases and variances, resulting in predictions that closely track actual PV outputs across the entire range of power levels.
5.4. Model Performance Comparison with Other Studies
The performance of various machine learning models for PV power prediction was evaluated using three key metrics: MAE, RMSE, and the coefficient of determination (R2). The baseline models, such as Linear Regression and Lasso Regression, exhibited moderate predictive capabilities, with R2 values around 0.84 and comparatively higher error rates. These models struggled to capture the nonlinear dependencies between environmental variables and PV output, limiting their suitability for real-world forecasting tasks.
Kernel-based and instance-based models, including SVR and KNN, demonstrated improved performance under stable conditions, but their effectiveness declined in highly dynamic environments due to sensitivity to kernel parameters and local density variations, respectively. In contrast, tree-based ensemble methods, namely Random Forest, Gradient Boosting, XGBoost, LightGBM, and CatBoost, consistently delivered superior results. Random Forest, when enhanced with temporal features such as hour, day, and month, achieved an R2 of 0.9612 with a low MAE of 1.13 kW, indicating strong model fidelity. Further performance gains were realized using Gradient Boosting and boosting-based frameworks like XGBoost and CatBoost, which reduced both MAE and RMSE while maintaining high R2 values. For example, XGBoost achieved an R2 of 0.92 with favorable error margins, and CatBoost demonstrated similar robustness. However, these models still had room for improvement in terms of handling generalization across diverse datasets. The best performance model according to all the metrics was the HybrEnNet ensemble model (Random Forest, XGBoost, and CatBoost), with an R2 = 0.993, an MAE = 0.227 kW, and an RMSE = 0.628 kW, as shown in Table 6. Such an ensemble approach combines several tree-based models, which decreases the bias of each separate model and enhances predictability over the individual models. The soft voting mechanism guarantees complementary prediction, improving the overall robustness, which is a sensible improvement to engineering as opposed to a radically new contribution to the algorithm.
Table 6.
Overview of comparative analysis of proposed methodology with previous work.
The comparative table highlights these findings by ranking models in ascending order of R2 scores. Models such as KNN and LGBM, as applied in the [24] study, were positioned lower due to their limited accuracy. LSTM, from [43], showed moderate results but suffered from high error margins. More robust models, including SVR, XGBoost, and ANN, performed well across multiple datasets. Ultimately, the proposed ensemble approach set a new benchmark in PV power prediction, validating the effectiveness of hybrid models in enhancing prediction accuracy, generalizability, and operational reliability in smart grid applications. It is important to note that quantitative comparison of the results with the previously conducted studies is necessarily indirect because of the variation in datasets, experimental configurations, and assessment procedures. Thus, the reported comparisons can only be taken as indicative references in order to contextualize the performance of the proposed framework within the entire body of literature, but not to argue that it is strictly superior.
5.5. Model Interpretability Using SHAP
The Shapley Additive Explanation, or SHAP, was used to measure the model interpretability by measuring the contribution of individual features to the predicted photovoltaic (PV) power as compared to a baseline expectation. As the proposed HybrEnNet is heterogeneous (i.e., it uses tree-based learners such as Random Forest, XGBoost, and CatBoost), the SHAP values were also calculated on an individual base model and aggregated through equal-weight averaging, as is the case in the ensemble voting strategy, to get ensemble-level explanations.
Figure 16 shows the SHAP summary plot of the seasonal combination of summer, winter, and aggregate conditions of the whole season. In all regimes, locally measured total irradiance has the most significant impact on PV power prediction, with high values having a great positive impact. Direct and global irradiance characteristics are more impactful under clear-sky conditions during summer, whereas in winter, diffuse irradiance and pressure-related factors represent the cloudy and unstable atmospheric regimes. There is a secondary effect of temperature and insignificant wind variables. All in all, SHAP analysis shows the adaptability of the features in different seasons and their consistency, which promotes the validity and transparency of the proposed ensemble.
Figure 16.
Combined SHAP summary plots for the ensemble model (RF + XGBoost + CatBoost) under (a) summer, (b) winter, and (c) all-season aggregated conditions.
6. Limitations and Future Directions
While the ensemble model achieved strong predictive performance, there are some limitations worth noting. First, the model relies on historical meteorological measurements and does not yet incorporate real-time satellite imagery or cloud movement data, which could further enhance short-term accuracy. Second, while temporal encodings improved performance, more advanced time-series architectures (e.g., Transformer-based models) could be explored for capturing long-range dependencies. Future research will involve Transformer-based designs of PV power prediction based on the PVOD v1.0 dataset. In this regard, the main issues are managing long input sequences due to the presence of high-frequency multi-station measurements and addressing the higher computational and memory costs of self-attention mechanisms that may constrain real-time implementation. In addition, we will explore edge-device optimization methods, including model compression, pruning, and low-precision quantization, to make it possible to use the forecasting models with high accuracy but low resource consumption on resource-constrained embedded hardware in PV plants.
7. Conclusions
The proposed HybrEnNet ensemble framework combines three popular tree-based algorithms (Random Forest, XGBoost, and CatBoost) using soft voting to enhance the accuracy of PV power forecasting. The ensemble results in R2 = 0.993, MAE = 0.227 kW, and RMSE = 0.628 kW using extensive temporal characteristics and the high-resolution PVOD v1.0 dataset. The results obtained are a reflection of a small step forward relative to each of the individual models, and they illustrate the practical utility of using a combination of multiple learners as opposed to any single algorithm. Time feature integration and ensemble voting are very simple and efficient methods that achieve consistent performance increases. The high accuracy and robustness in the generality of the framework, when applied to a variety of operational contexts, is made possible by its capacity to model nonlinear complex relations between meteorological and temporal variables. In feature importance analysis, it is worth highlighting the importance of global irradiance, temperature, and temporal indices, and that the soft voting strategy’s role in performance improvement in terms of predictive stability and robustness is related to the ensemble approach. Although computationally heavy, the model is efficient enough to apply to smart grid real-time integration. The inability to use real-time satellite data, as well as sophisticated time-series architectures, highlights potential areas of future research, like transfer learning and edge-device optimization. In general, this work creates the link between scholarship and real-life applications, and it has provided a scalable, transparent, high-performing solution to aid the international switch to renewable energy systems.
Author Contributions
W.A.: Conceptualization, formal analysis, original draft, writing—review and editing, and images. F.A.: Conceptualization, formal analysis, original draft, writing—review and editing, and images. A.U.: Writing—review and editing. W.Y.K.: Conceptualization, review and editing, resources, supervision, and funding acquisition. All authors have read and agreed to the published version of the manuscript.
Funding
This research was supported by the Regional Innovation System & Education (RISE) program through the Jeju RISE center, funded by the Ministry of Education (MOE) and the Jeju Special Self-Governing Province, Republic of Korea. (2025-RISE-17-001).
Data Availability Statement
The data presented in this study are openly available in Science Data Bank (ScienceDB) at [https://cstr.cn/31253.11.sciencedb.01094, (accessed on 12 July 2025); https://doi.org/10.11922/sciencedb.01094], reference number [32].
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Wang, Y.; Wang, R.; Tanaka, K.; Ciais, P.; Penuelas, J.; Balkanski, Y.; Sardans, J.; Hauglustaine, D.; Liu, W.; Xing, X.; et al. Accelerating the energy transition towards photovoltaic and wind in China. Nature 2023, 619, 761–767. [Google Scholar] [CrossRef] [Scilit]
- Sepúlveda-Oviedo, E.H. Impact of environmental factors on photovoltaic system performance degradation. Energy Strategy Rev. 2025, 59, 101682. [Google Scholar] [CrossRef] [Scilit]
- Cui, S.; Lyu, S.; Ma, Y.; Wang, K. Improved informer PV power short-term prediction model based on weather typing and AHA-VMD-MPE. Energy 2024, 307, 132766, Correction in Energy 2024, 310, 133290. [Google Scholar] [CrossRef] [Scilit]
- Aguilar, D.; Quinones, J.J.; Pineda, L.R.; Ostanek, J.; Castillo, L. Optimal scheduling of renewable energy microgrids: A robust multi-objective approach with machine learning-based probabilistic forecasting. Appl. Energy 2024, 369, 123548. [Google Scholar] [CrossRef] [Scilit]
- Yan, J.; Möhrlen, C.; Göçmen, T.; Kelly, M.; Wessel, A.; Giebel, G. Uncovering wind power forecasting uncertainty sources and their propagation through the whole modelling chain. Renew. Sustain. Energy Rev. 2022, 165, 112519. [Google Scholar] [CrossRef] [Scilit]
- Kim, J.M. Integrating Copula-Based Random Forest and Deep Learning Approaches for Analyzing Heterogeneous Treatment Effects in Survival Analysis. Mathematics 2025, 13, 1659. [Google Scholar] [CrossRef] [Scilit]
- Cha, Y.J.; Ali, R.; Lewis, J.; Büyüköztürk, O. Deep learning-based structural health monitoring. Autom. Constr. 2024, 161, 105328. [Google Scholar] [CrossRef] [Scilit]
- Khouili, O.; Hanine, M.; Louzazni, M.; Flores, M.A.L.; Villena, E.G.; Ashraf, I. Evaluating the impact of deep learning approaches on solar and photovoltaic power forecasting: A systematic review. Energy Strategy Rev. 2025, 59, 101735. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Li, L.; Zhou, S. Ensemble Forecasting Frame Based on Deep Learning and Multi-Objective Optimization for Planning Solar Energy Management: A Case Study. Front. Energy Res. 2021, 9, 764635. [Google Scholar] [CrossRef] [Scilit]
- Zhou, Y.; Li, Y.; Wang, D.; Liu, Y. A multi-step ahead global solar radiation prediction method using an attention-based transformer model with an interpretable mechanism. Int. J. Hydrogen Energy 2023, 48, 15317–15330. [Google Scholar] [CrossRef] [Scilit]
- Hamad, S.A.; Ghalib, M.A.; Munshi, A.; Alotaibi, M.; Ebied, M.A. Evaluating machine learning models comprehensively for predicting maximum power from photovoltaic systems. Sci. Rep. 2025, 15, 10750. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Yao, T.; Wang, J.; Wu, H.; Zhang, P.; Li, S.; Wang, Y.; Chi, X.; Shi, M. A photovoltaic power output dataset: Multi-source photovoltaic power output dataset with Python toolkit. Sol. Energy 2021, 230, 122–130. [Google Scholar] [CrossRef] [Scilit]
- Tripathi, A.K.; Aruna, M.; Elumalai, P.; Karthik, K.; Khan, S.A.; Asif, M.; Rao, K.S. Advancing solar PV panel power prediction: A comparative machine learning approach in fluctuating environmental conditions. Case Stud. Therm. Eng. 2024, 59, 104459. [Google Scholar] [CrossRef] [Scilit]
- Van Tai, D. Solar photovoltaic power output forecasting using machine learning technique. J. Phys. Conf. Ser. 2019, 1327, 012051. [Google Scholar] [CrossRef] [Scilit]
- Varughese, R.A.; Karpagam, R. Prediction of Solar Power Generation Based on Machine Learning Algorithm. In Proceedings of the 2022 3rd International Conference on Intelligent Computing, Instrumentation and Control Technologies: Computational Intelligence for Smart Systems, ICICICT 2022, Kannur, India, 11–12 August 2022; pp. 396–400. [Google Scholar] [CrossRef] [Scilit]
- Li, Z. Extracting spatial effects from machine learning model using local interpretation method: An example of SHAP and XGBoost. Comput. Environ. Urban Syst. 2022, 96, 101845. [Google Scholar] [CrossRef] [Scilit]
- Chaaban, A.K.; Alfadl, N. A comparative study of machine learning approaches for an accurate predictive modeling of solar energy generation. Energy Rep. 2024, 12, 1293–1302. [Google Scholar] [CrossRef] [Scilit]
- Bashir, A.; Ahmad, E.; Dulawat, S.; Abba, S.I. Harnessing synergy of machine learning and nature-inspired optimization for enhanced compressive strength prediction in concrete. Hybrid Adv. 2025, 9, 100404. [Google Scholar] [CrossRef] [Scilit]
- Thanh, H.V.; Dai, Z.; Rahimi, M. Data-driven explainable machine learning approaches for predicting hydrogen adsorption in porous crystalline materials. J. Alloys Compd. 2025, 1028, 180709. [Google Scholar] [CrossRef] [Scilit]
- Sekar, S.; Kaviya, V.; Vivekanandan, G.; Nithya, P. Solar Panel Power Prediction Using Machine Learning Technique. In Proceedings of the 2023 Intelligent Computing and Control for Engineering and Business Systems, ICCEBS 2023, Chennai, India, 14–15 December 2023. [Google Scholar] [CrossRef] [Scilit]
- Subeshan, B.; Atayo, A.; Asmatulu, E. Machine learning applications for electrospun nanofibers: A review. J. Mater. Sci. 2024, 59, 14095–14140. [Google Scholar] [CrossRef] [Scilit]
- Subramanian, E.; Karthik, M.M.; Krishna, G.P.; Prasath, D.V.; Kumar, V.S. Solar Power Prediction Using Machine Learning. 2023. Available online: https://arxiv.org/pdf/2303.07875 (accessed on 29 June 2025).
- Suanpang, P.; Jamjuntr, P. Machine Learning Models for Solar Power Generation Forecasting in Microgrid Application Implications for Smart Cities. Sustainability 2024, 16, 6087. [Google Scholar] [CrossRef] [Scilit]
- Ali, M.; Rabehi, A.; Souahlia, A.; Guermoui, M.; Teta, A.; Tibermacine, I.E.; Rabehi, A.; Benghanem, M.; Agajie, T.F. Enhancing PV power forecasting through feature selection and artificial neural networks: A case study. Sci. Rep. 2025, 15, 22574. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Jiang, T.; Gao, Y.; Liu, G.; Zhao, G.; Hu, J.; Sa, R.; Gao, P. Dipole-Moment-Knowledge-Guided Molecular Design for Perovskite Surface Passivation: A Gemma-Language-Model and DFT-Driven Framework. Adv. Theory Simul. 2025, 8, e01318. [Google Scholar] [CrossRef] [Scilit]
- Idogho, C.; Abah, E.O.; Onuhc, J.O.; Harsito, C.; Omenkaf, K.; Samuel, A.; Ejila, A.; Idoko, I.P.; Ali, U.E. Machine Learning-Based Solar Photovoltaic Power Forecasting for Nigerian Regions. Energy Sci. Eng. 2025, 13, 1922–1934. [Google Scholar] [CrossRef] [Scilit]
- Atiea, M.A.; Abdelghaffar, A.A.; Ben Aribia, H.; Noureddine, F.; Shaheen, A.M. Photovoltaic power generation forecasting with Bayesian optimization and stacked ensemble learning. Results Eng. 2025, 26, 104950. [Google Scholar] [CrossRef] [Scilit]
- Li, X.; Ma, L.; Chen, P.; Xu, H.; Xing, Q.; Yan, J.; Lu, S.; Fan, H.; Yang, L.; Cheng, Y. Probabilistic solar irradiance forecasting based on XGBoost. Energy Rep. 2022, 8, 1087–1095. [Google Scholar] [CrossRef] [Scilit]
- Kumar, M.; Borgohain, S.; Panda, K.P.; Thokchom, S.; Panda, G. Smart Solar Forecasting: Machine Learning Approaches for Predicting Solar Power. In Proceedings of the IEEE Region 10 Annual International Conference, Proceedings/TENCON, Singapore, 1–4 December 2024; pp. 1344–1349. [Google Scholar] [CrossRef] [Scilit]
- Kareem, A.K.; Nafea, A.A.; Mansour, M.T.; Jamil, N.N. Accurate Photovoltaic Power Prediction Using Machine Learning and Deep Learning: A Comparative Study Across Multiple Locations. ITEGAM-J. Eng. Technol. Ind. Appl. 2025, 11, 87–98. [Google Scholar] [CrossRef] [Scilit]
- Yao, T.; Wang, J.; Wu, H.; Zhang, P.; Li, S.; Wang, Y.; Chi, X.; Shi, M. PVOD v1.0: A Photovoltaic Power Output Dataset. Science Data Bank Datasets. Available online: https://www.scidb.cn/en/detail?dataSetId=f8f3d7af144f441795c5781497e56b62 (accessed on 12 July 2025).
- Sahin, G.; Isik, G.; van Sark, W.G. Predictive modeling of PV solar power plant efficiency considering weather conditions: A comparative analysis of artificial neural networks and multiple linear regression. Energy Rep. 2023, 10, 2837–2849. [Google Scholar] [CrossRef] [Scilit]
- Jogunuri, S.; Josh, F.T.; Stonier, A.A.; Peter, G.; Jayaraj, J.; Jaganathan, S.; Joseph, J.J.; Ganji, V. Random forest machine learning algorithm based seasonal multi-step ahead short-term solar photovoltaic power output forecasting. IET Renew. Power Gener. 2024, 19, e12921. [Google Scholar] [CrossRef] [Scilit]
- Zulkafli, N.A.; Bundak, C.E.A.; Rahman, M.A.A.; Yap, C.C.; Chong, K.-K.; Tan, S.T. Prediction of device performance in SnO2 based inverted organic solar cells using Machine learning framework. Sol. Energy 2024, 278, 112795. [Google Scholar] [CrossRef] [Scilit]
- Du, K.-L.; Jiang, B.; Lu, J.; Hua, J.; Swamy, M.N.S. Exploring Kernel Machines and Support Vector Machines: Principles, Techniques, and Future Directions. Mathematics 2024, 12, 3935. [Google Scholar] [CrossRef] [Scilit]
- Gadi, S.N.; Aly, H.H.; Cada, M. A proposed hybrid model of ANN and KNN for solar cell defects detection and temperature prediction using fuzzy image segmentation. Heliyon 2024, 10, e31774. [Google Scholar] [CrossRef] [Scilit]
- Zang, H.; Chen, D.; Liu, J.; Cheng, L.; Sun, G.; Wei, Z. Improving ultra-short-term photovoltaic power forecasting using a novel sky-image-based framework considering spatial-temporal feature interaction. Energy 2024, 293, 130538. [Google Scholar] [CrossRef] [Scilit]
- Qiu, R.; Liu, C.; Cui, N.; Gao, Y.; Li, L.; Wu, Z.; Jiang, S.; Hu, M. Generalized Extreme Gradient Boosting model for predicting daily global solar radiation for locations without historical data. Energy Convers. Manag. 2022, 258, 115488. [Google Scholar] [CrossRef] [Scilit]
- Krishnan, N.; Kumar, K.R.; Anirudh, R.S. Solar radiation forecasting using gradient boosting based ensemble learning model for various climatic zones. Sustain. Energy Grids Netw. 2024, 38, 101312. [Google Scholar] [CrossRef] [Scilit]
- Aksoy, N.; Genc, I. Predictive models development using gradient boosting based methods for solar power plants. J. Comput. Sci. 2023, 67, 101958. [Google Scholar] [CrossRef] [Scilit]
- Banik, R.; Biswas, A. Improving Solar PV Prediction Performance with RF-CatBoost Ensemble: A Robust and Complementary Approach. Renew. Energy Focus 2023, 46, 207–221. [Google Scholar] [CrossRef] [Scilit]
- Farhat, M.; Dekhane, A.; Djellad, A.; Takruri, M.; Al-Qaisi, A.; Barambones, O. Optimizing photovoltaic performance: Data-driven maximum power point prediction via advanced regression models. Results Control Optim. 2025, 20, 100586. [Google Scholar] [CrossRef] [Scilit]
- Anuradha, K.; Erlapally, D.; Karuna, G.; Srilakshmi, V.; Adilakshmi, K. Analysis of Solar Power Generation Forecasting Using Machine Learning Techniques. E3S Web Conf. 2021, 309, 01163. [Google Scholar] [CrossRef] [Scilit]
- Nguyen, H.N.; Tran, Q.T.; Ngo, C.T.; Nguyen, D.D.; Tran, V.Q. Solar energy prediction through machine learning models: A comparative analysis of regressor algorithms. PLoS ONE 2025, 20, e0315955. [Google Scholar] [CrossRef] [Scilit]
- Balal, A.; Jafarabadi, Y.P.; Demir, A.; Igene, M.; Giesselmann, M.; Bayne, S. Forecasting Solar Power Generation Utilizing Machine Learning Models in Lubbock. Emerg. Sci. J. 2023, 7, 1052–1062. [Google Scholar] [CrossRef] [Scilit]
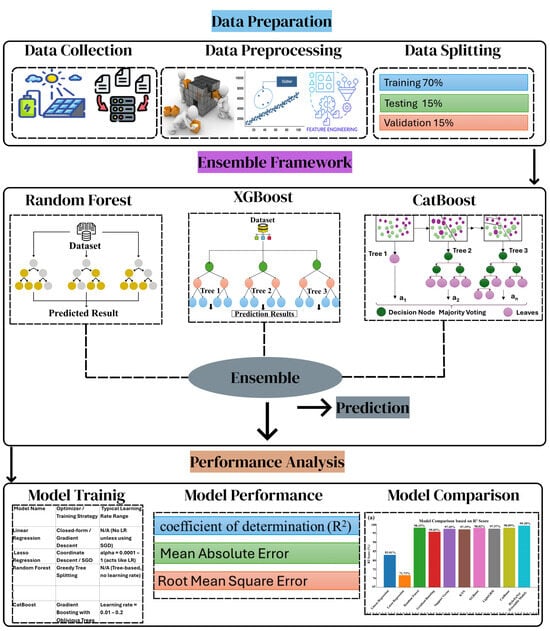
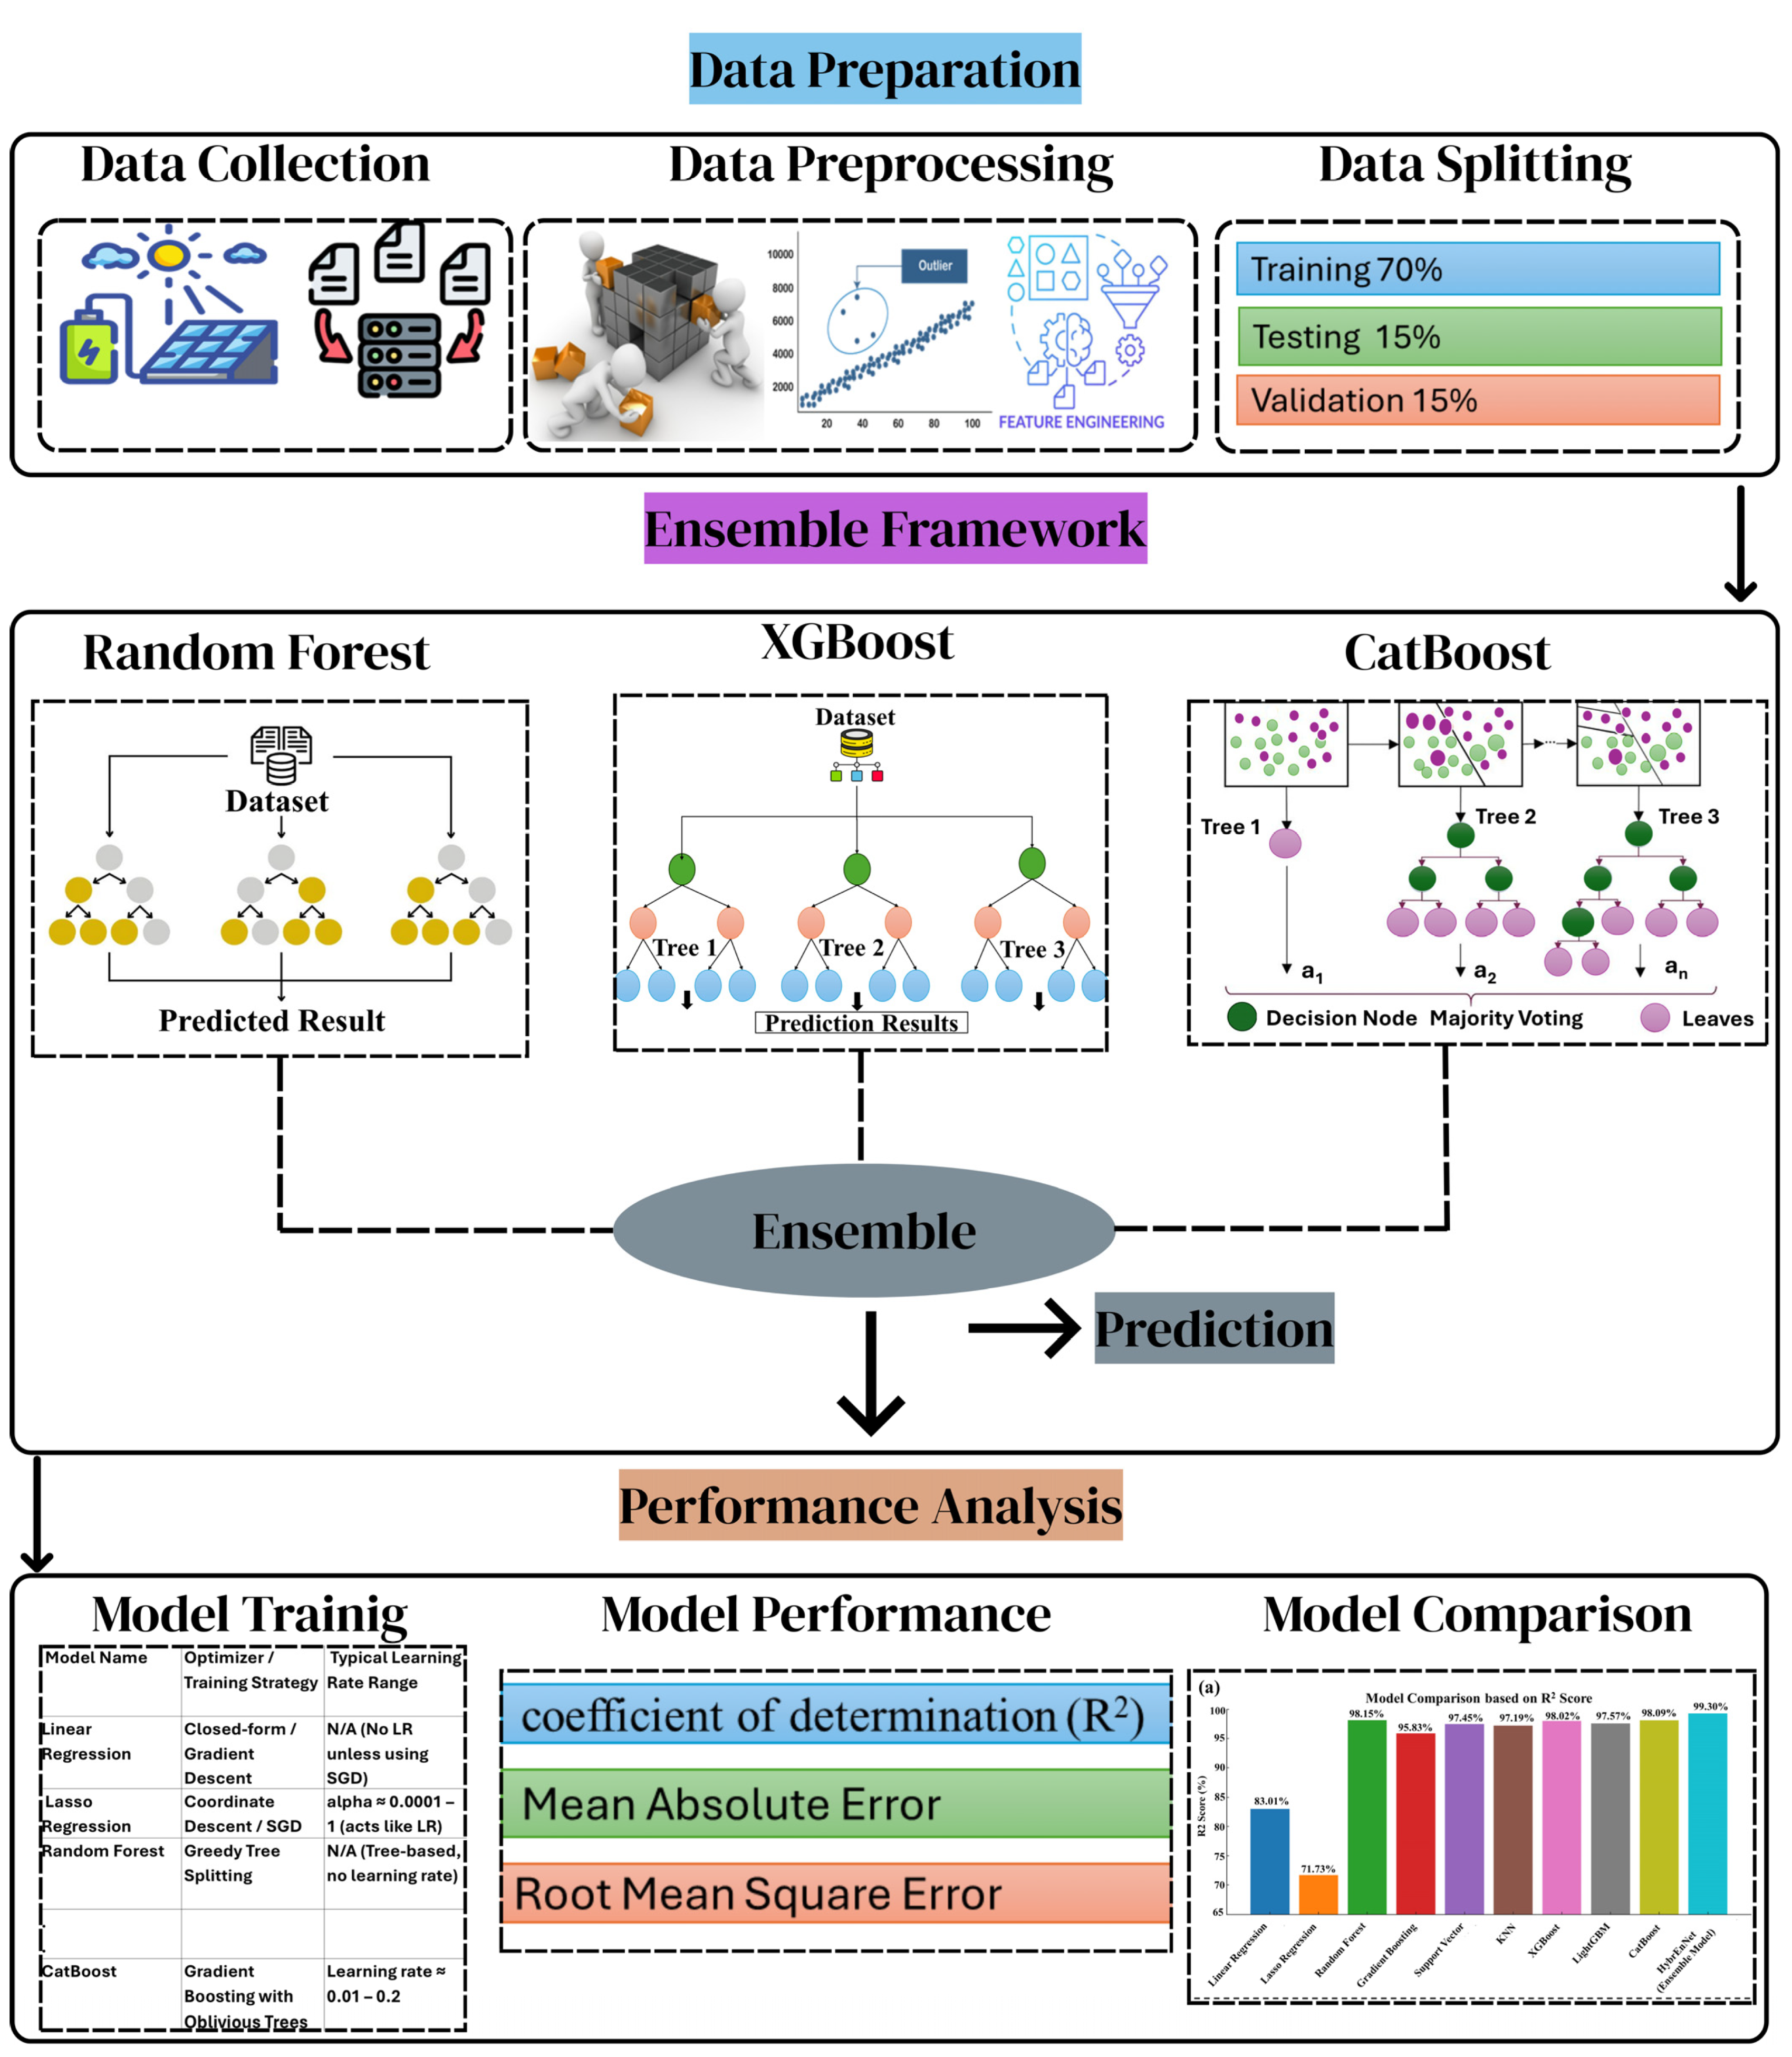
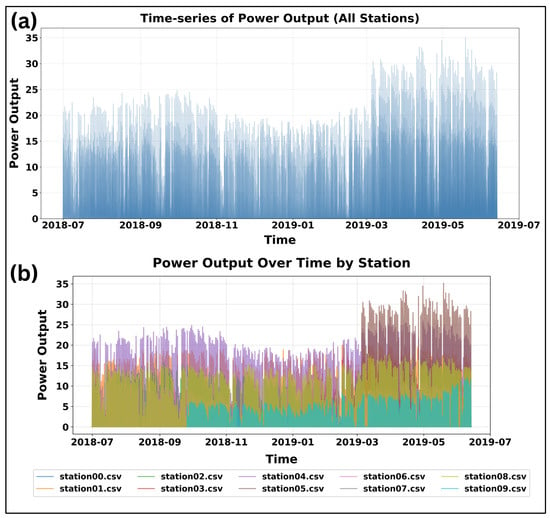
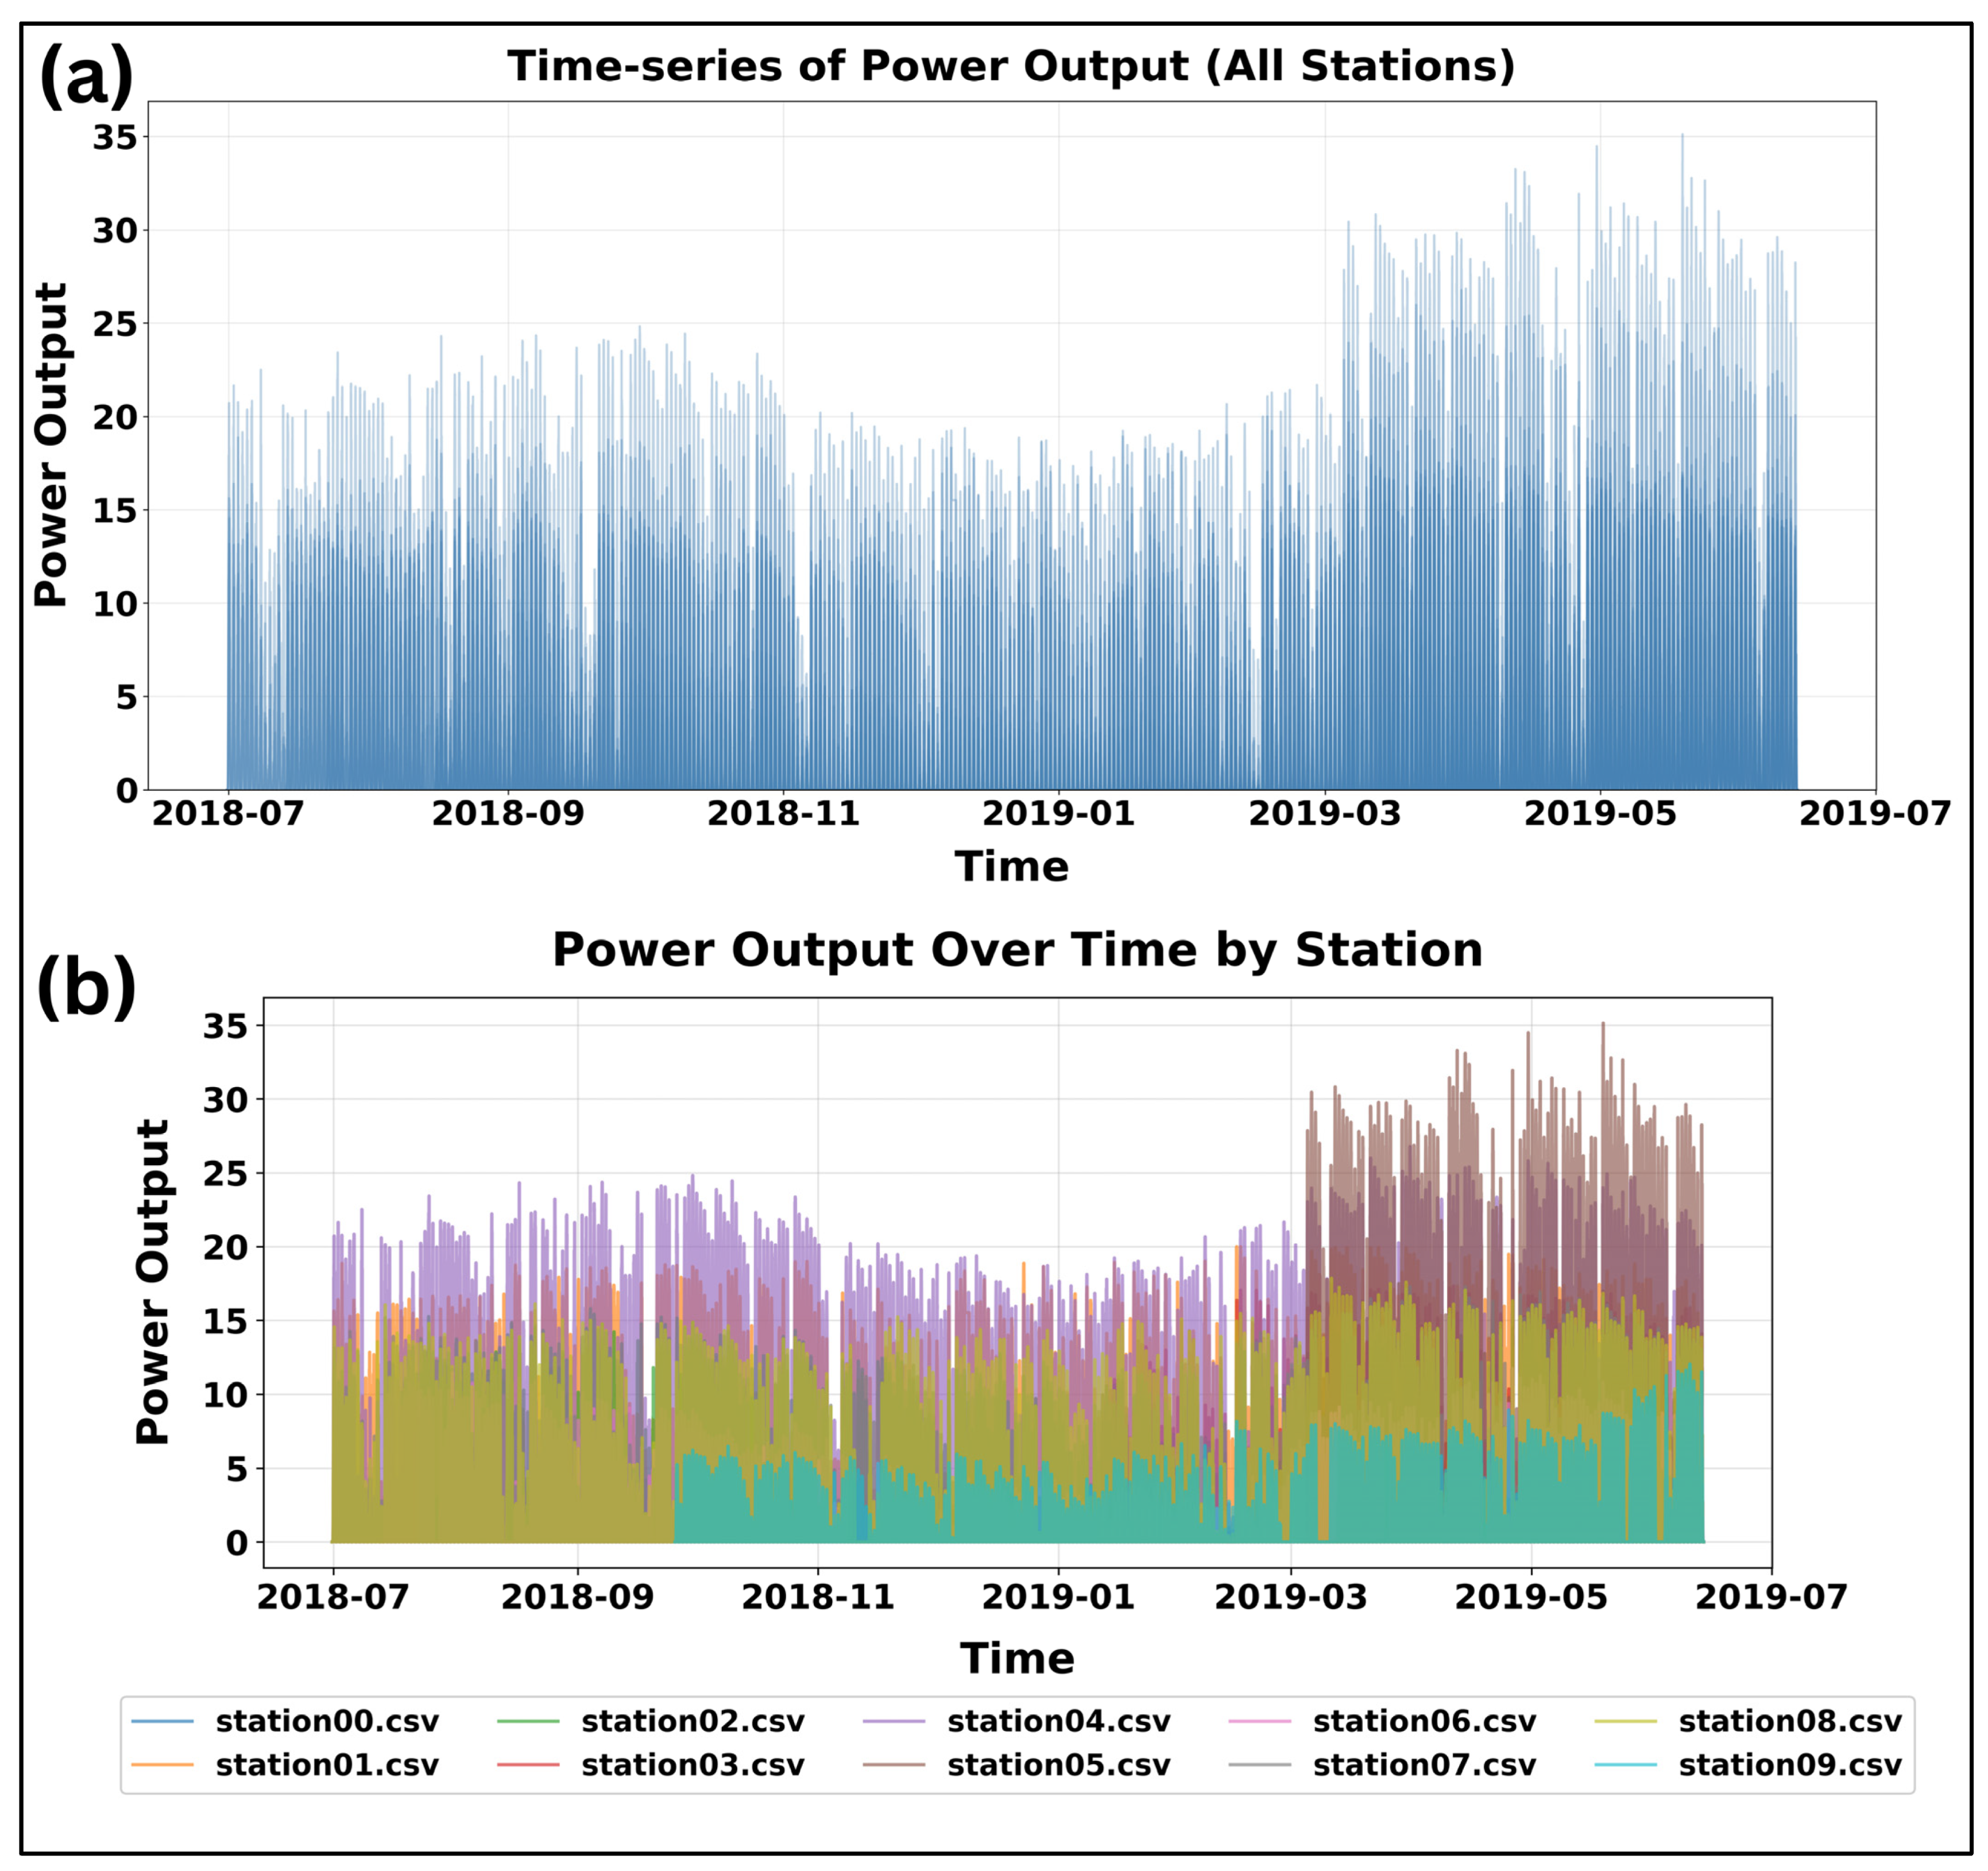
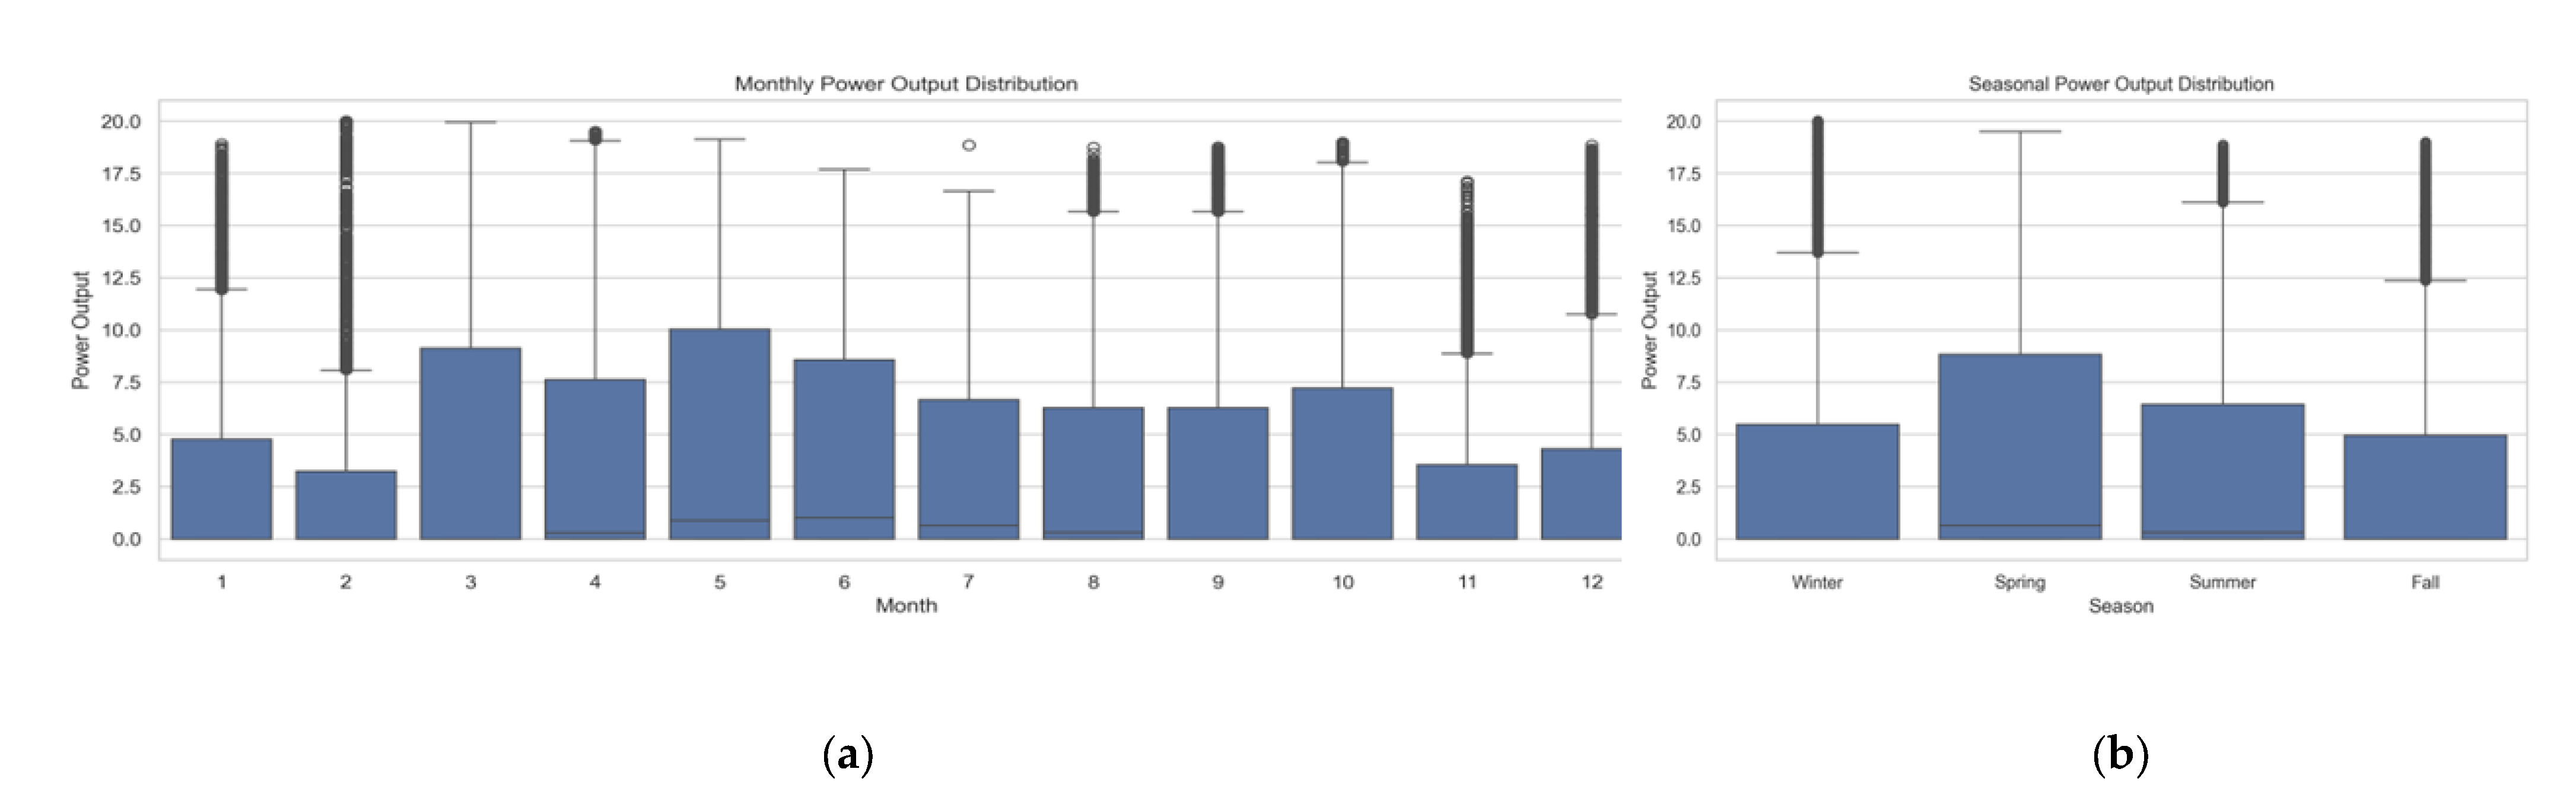
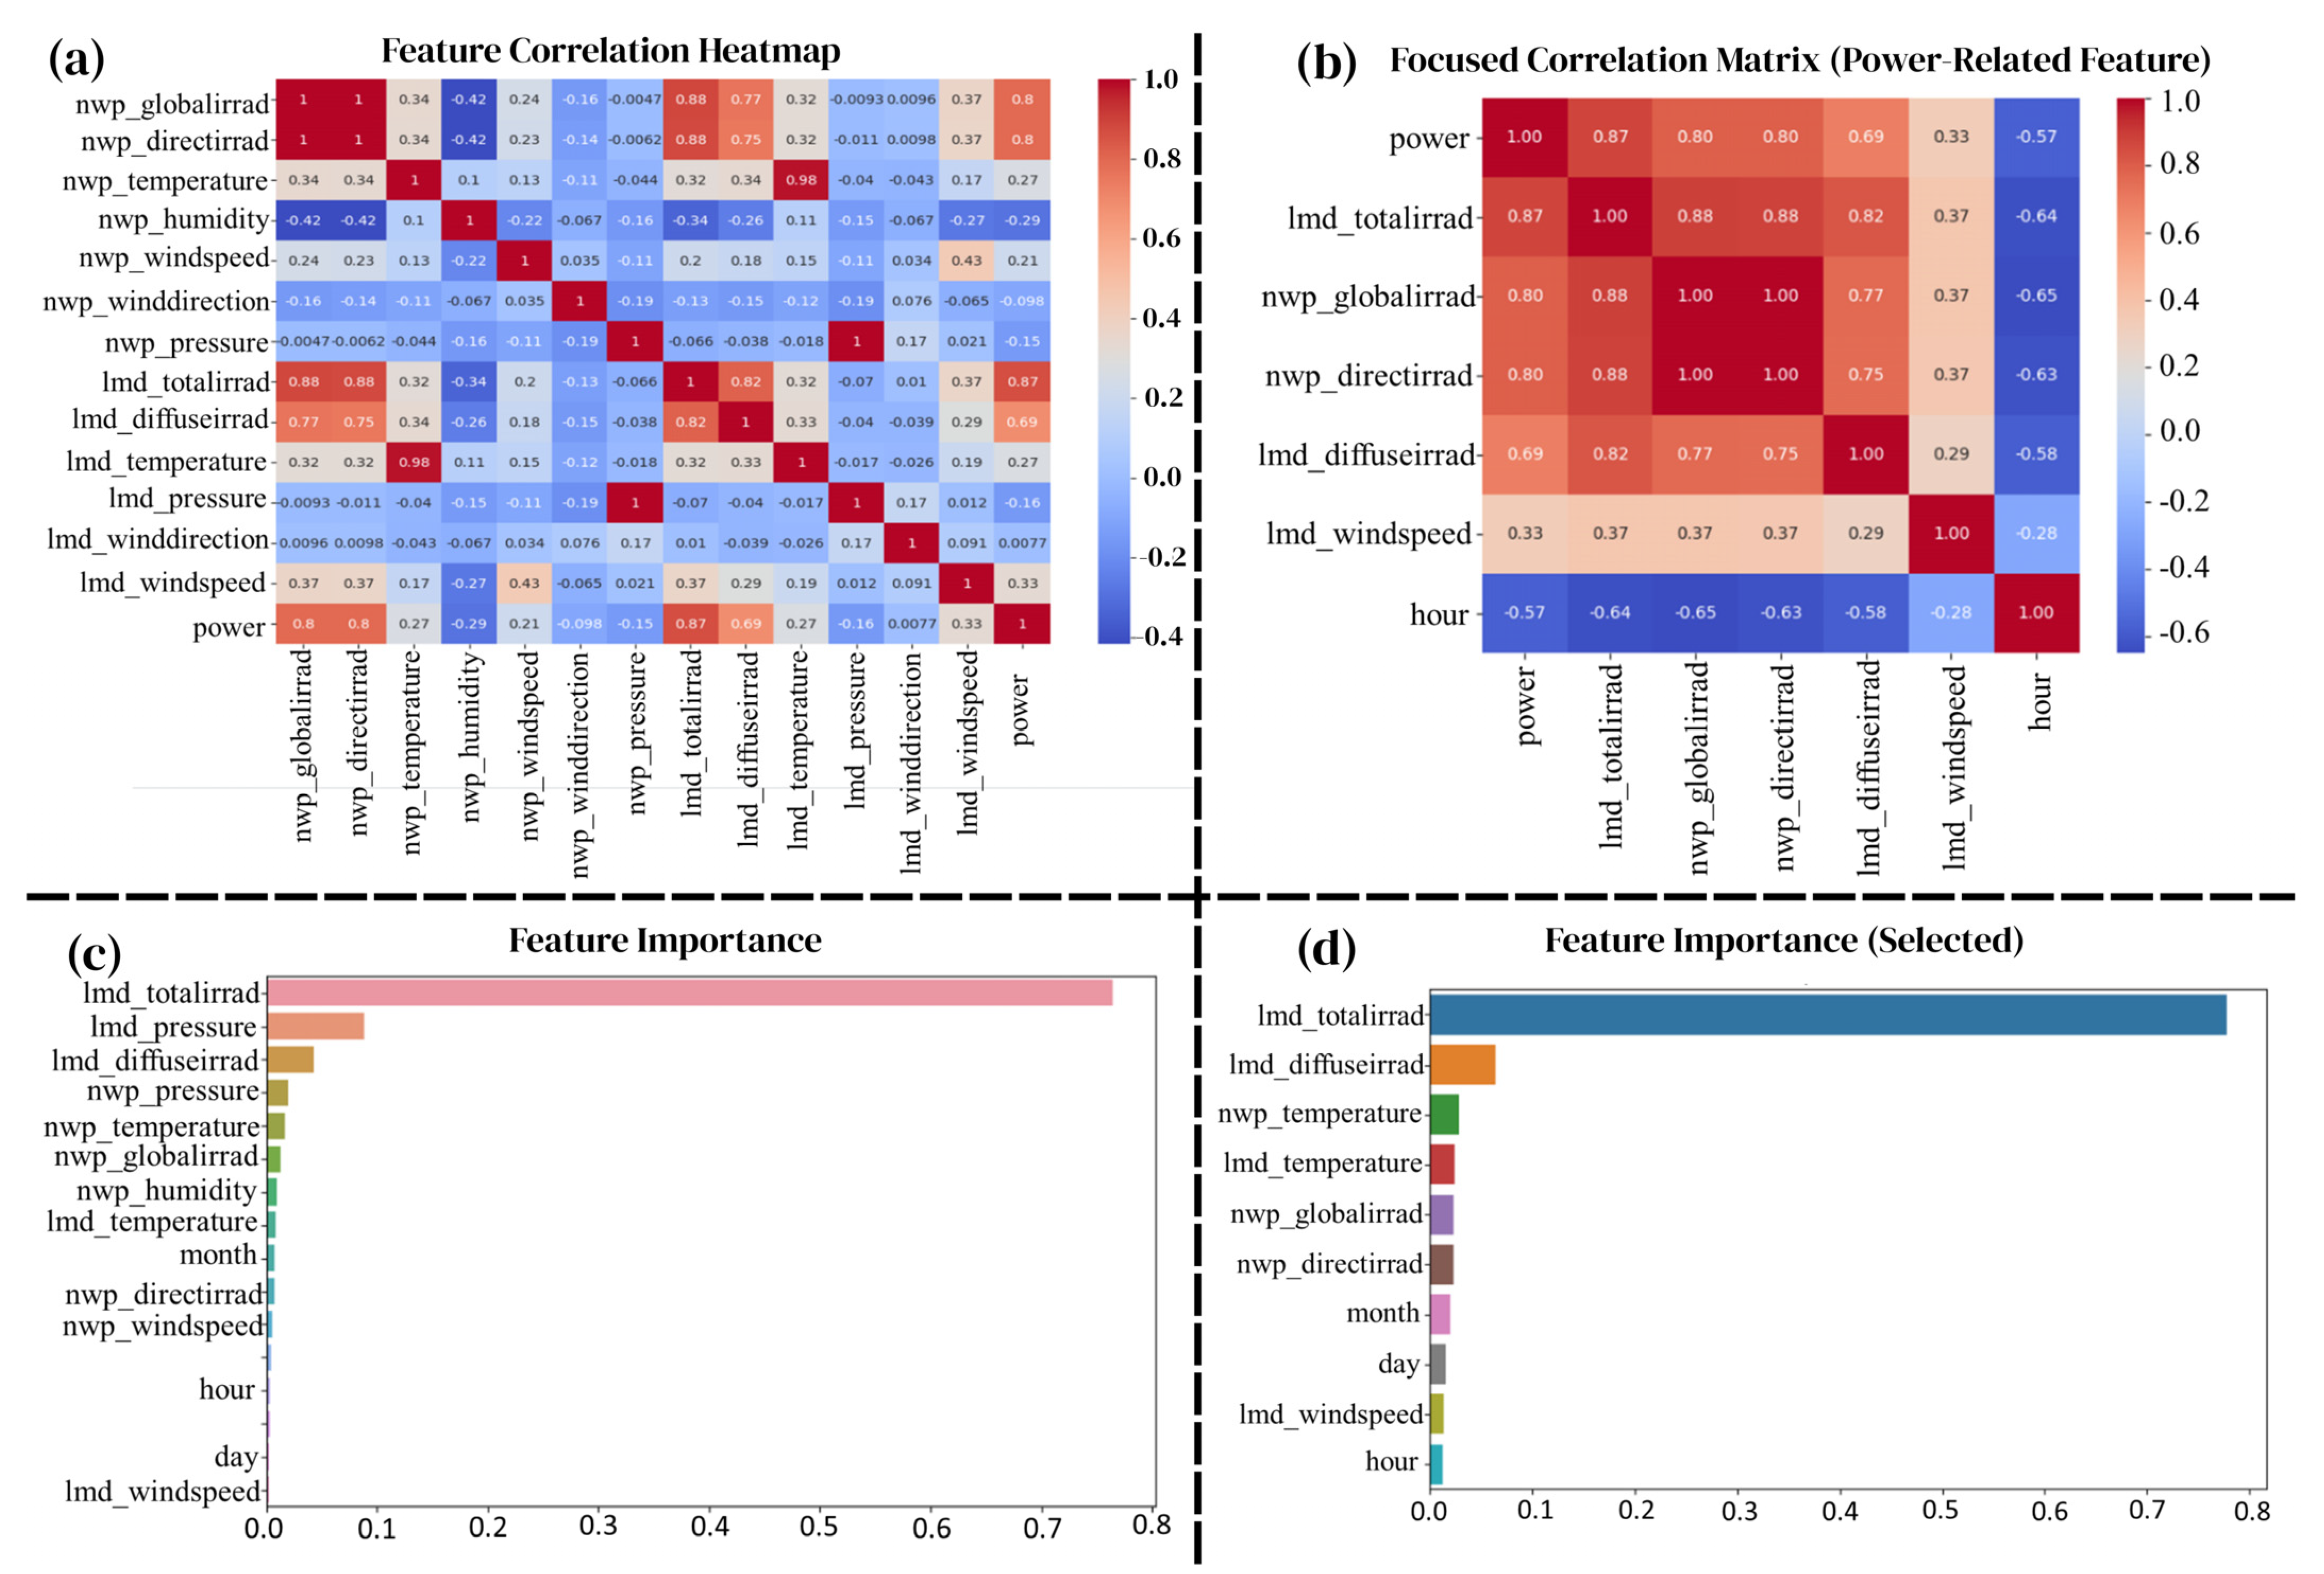
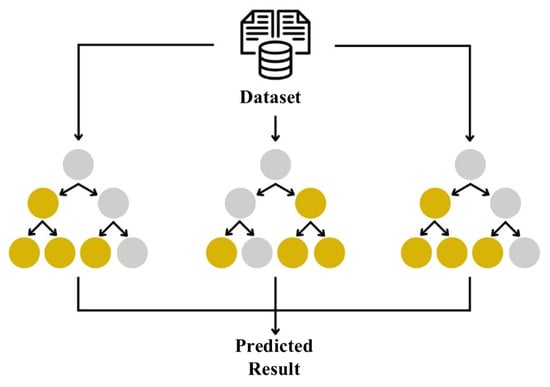
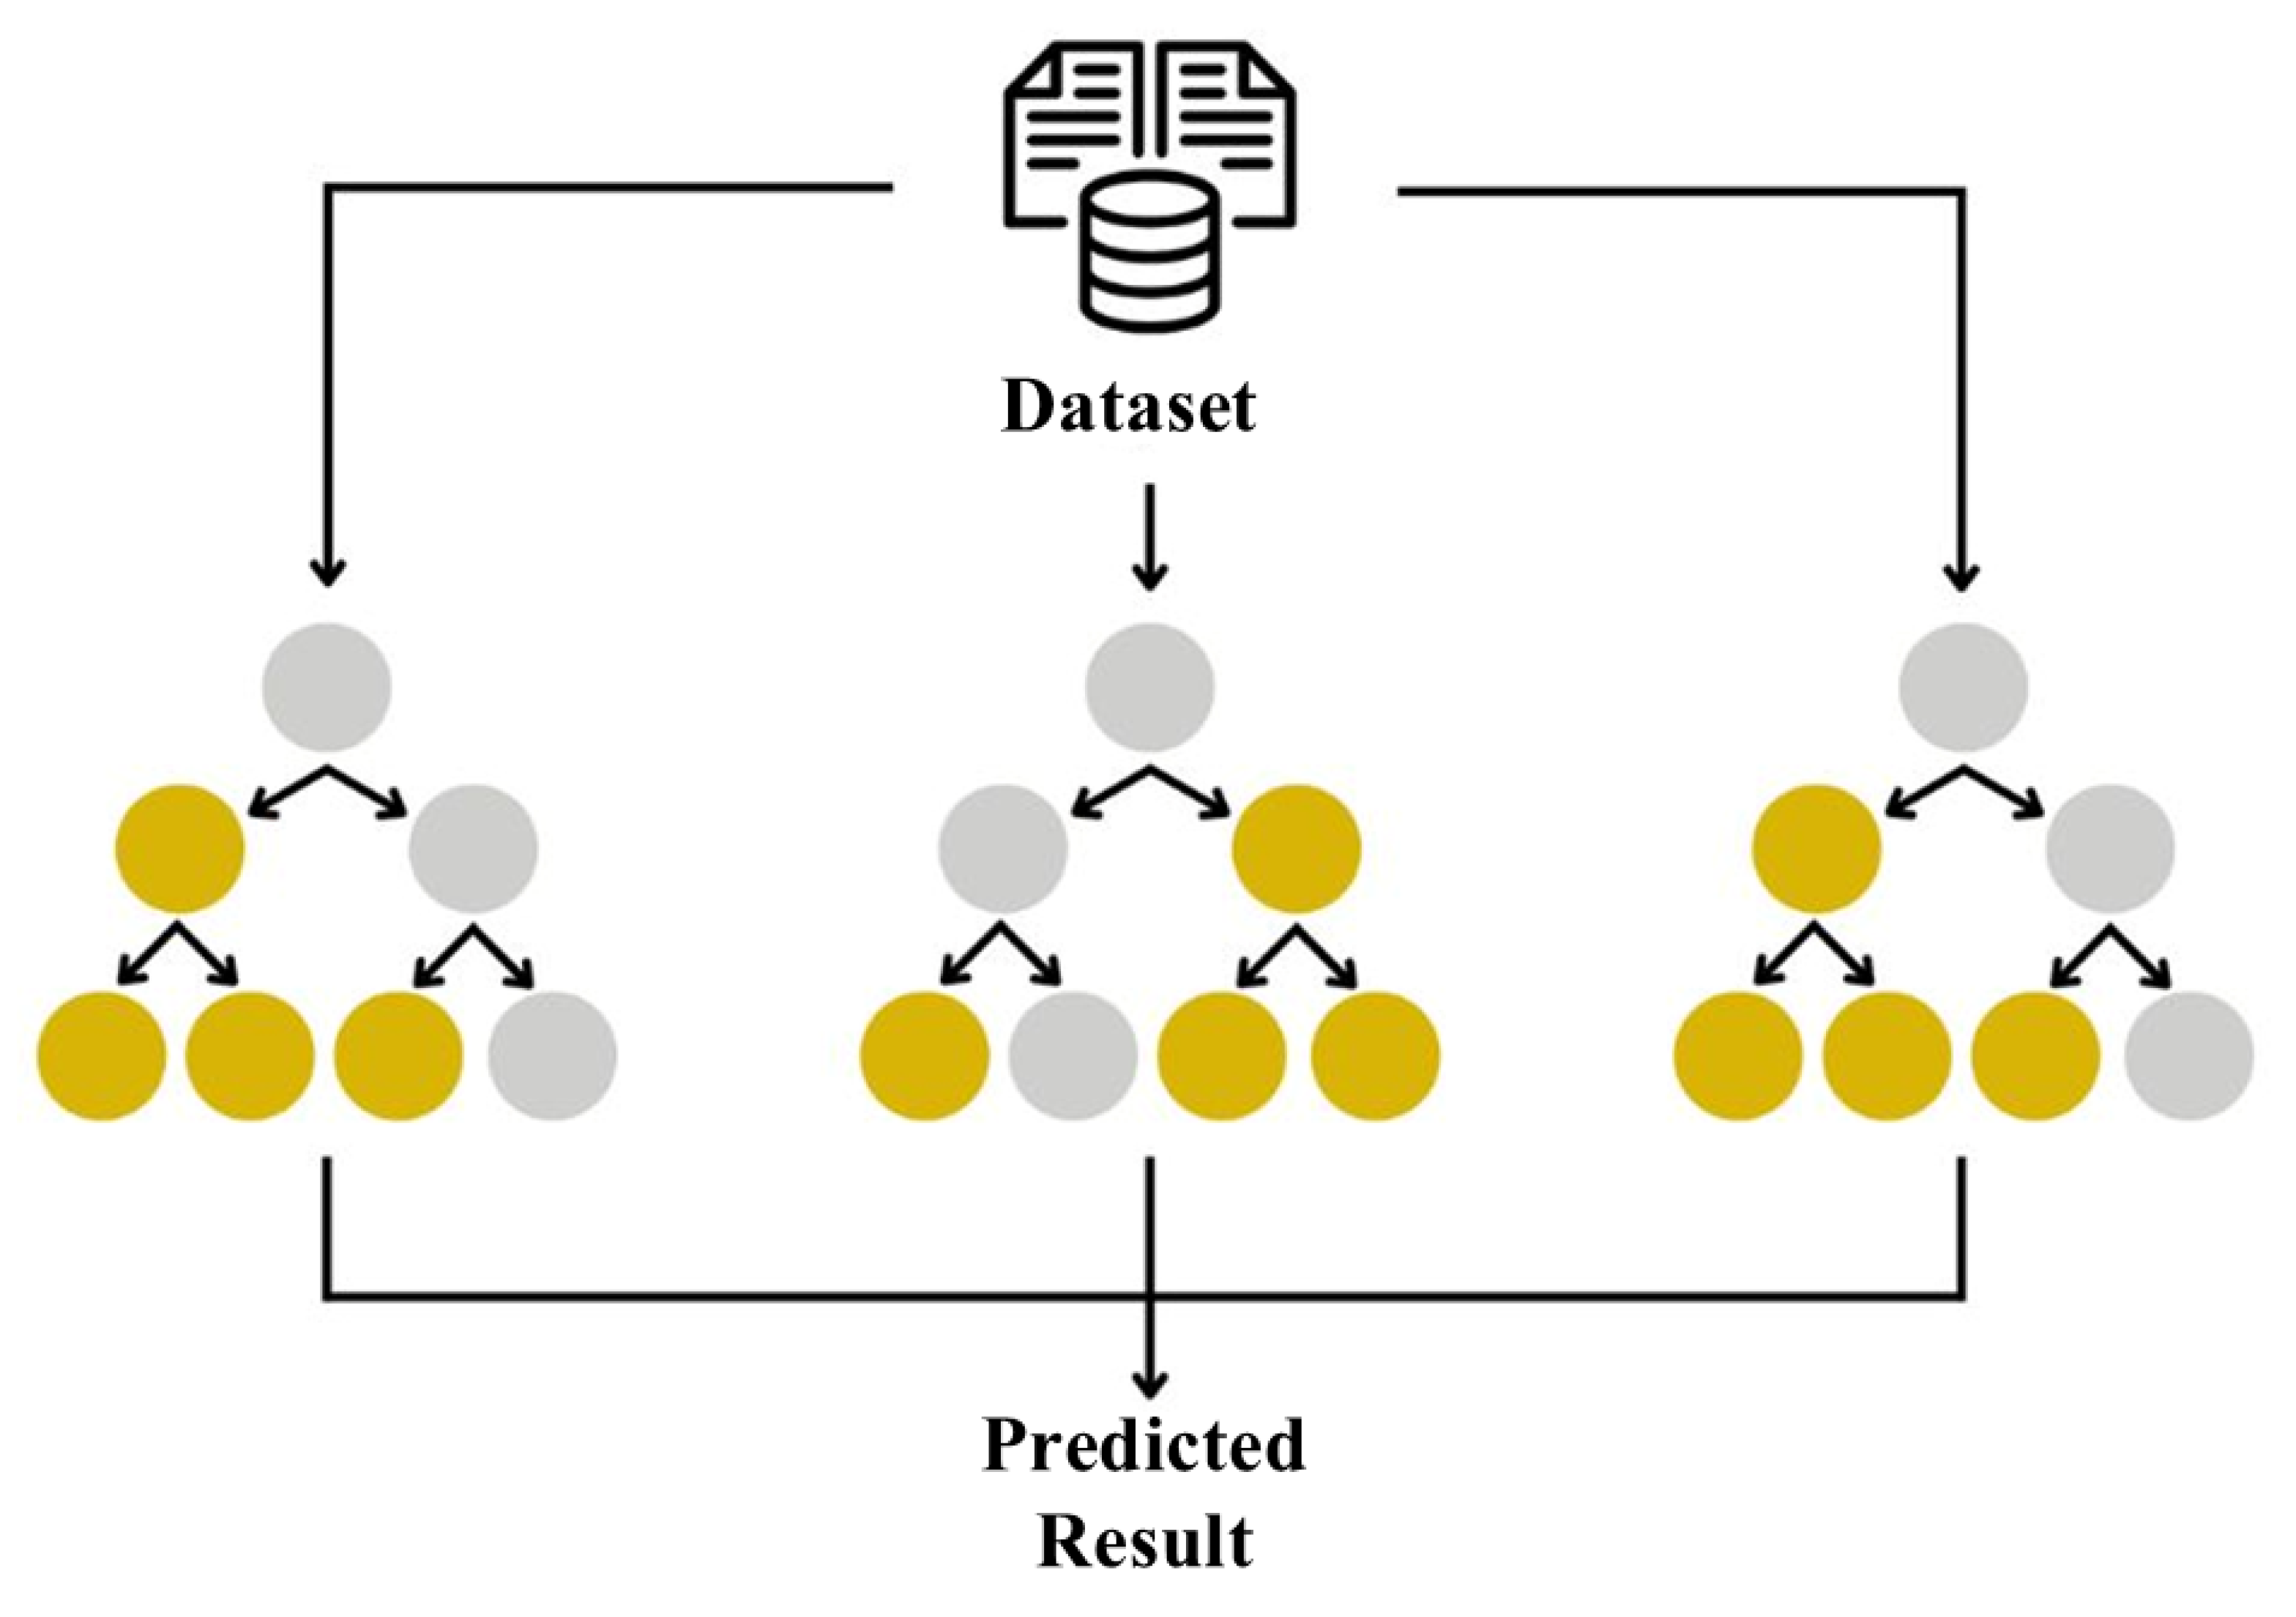
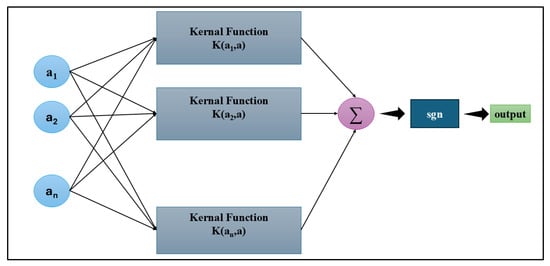
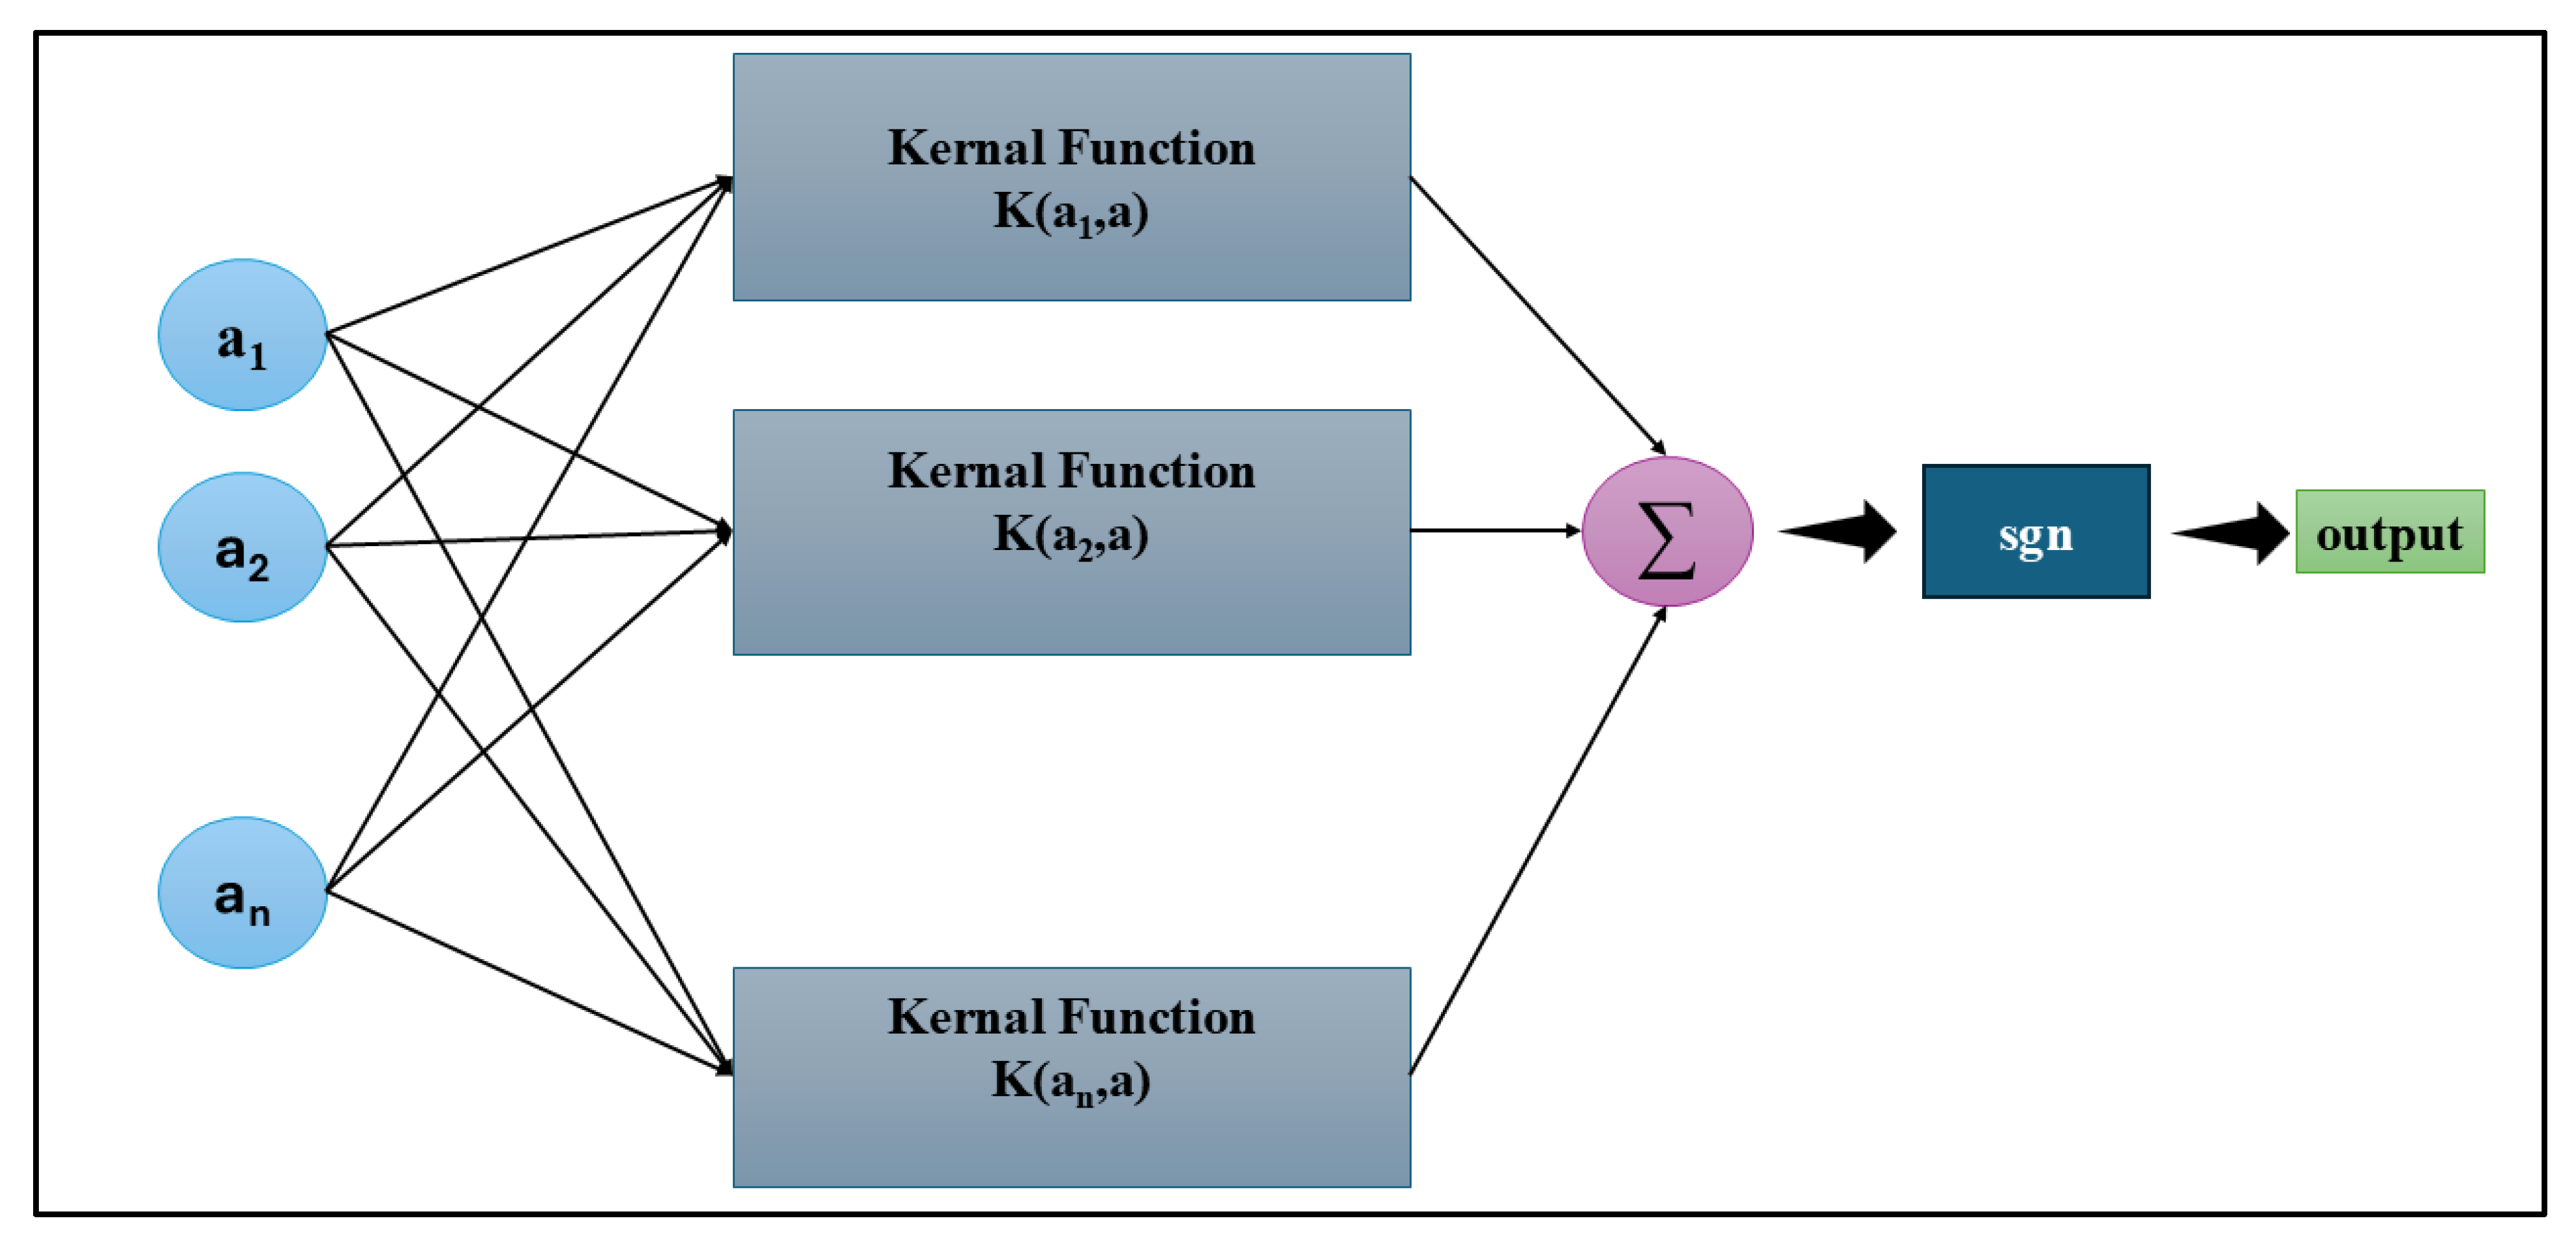
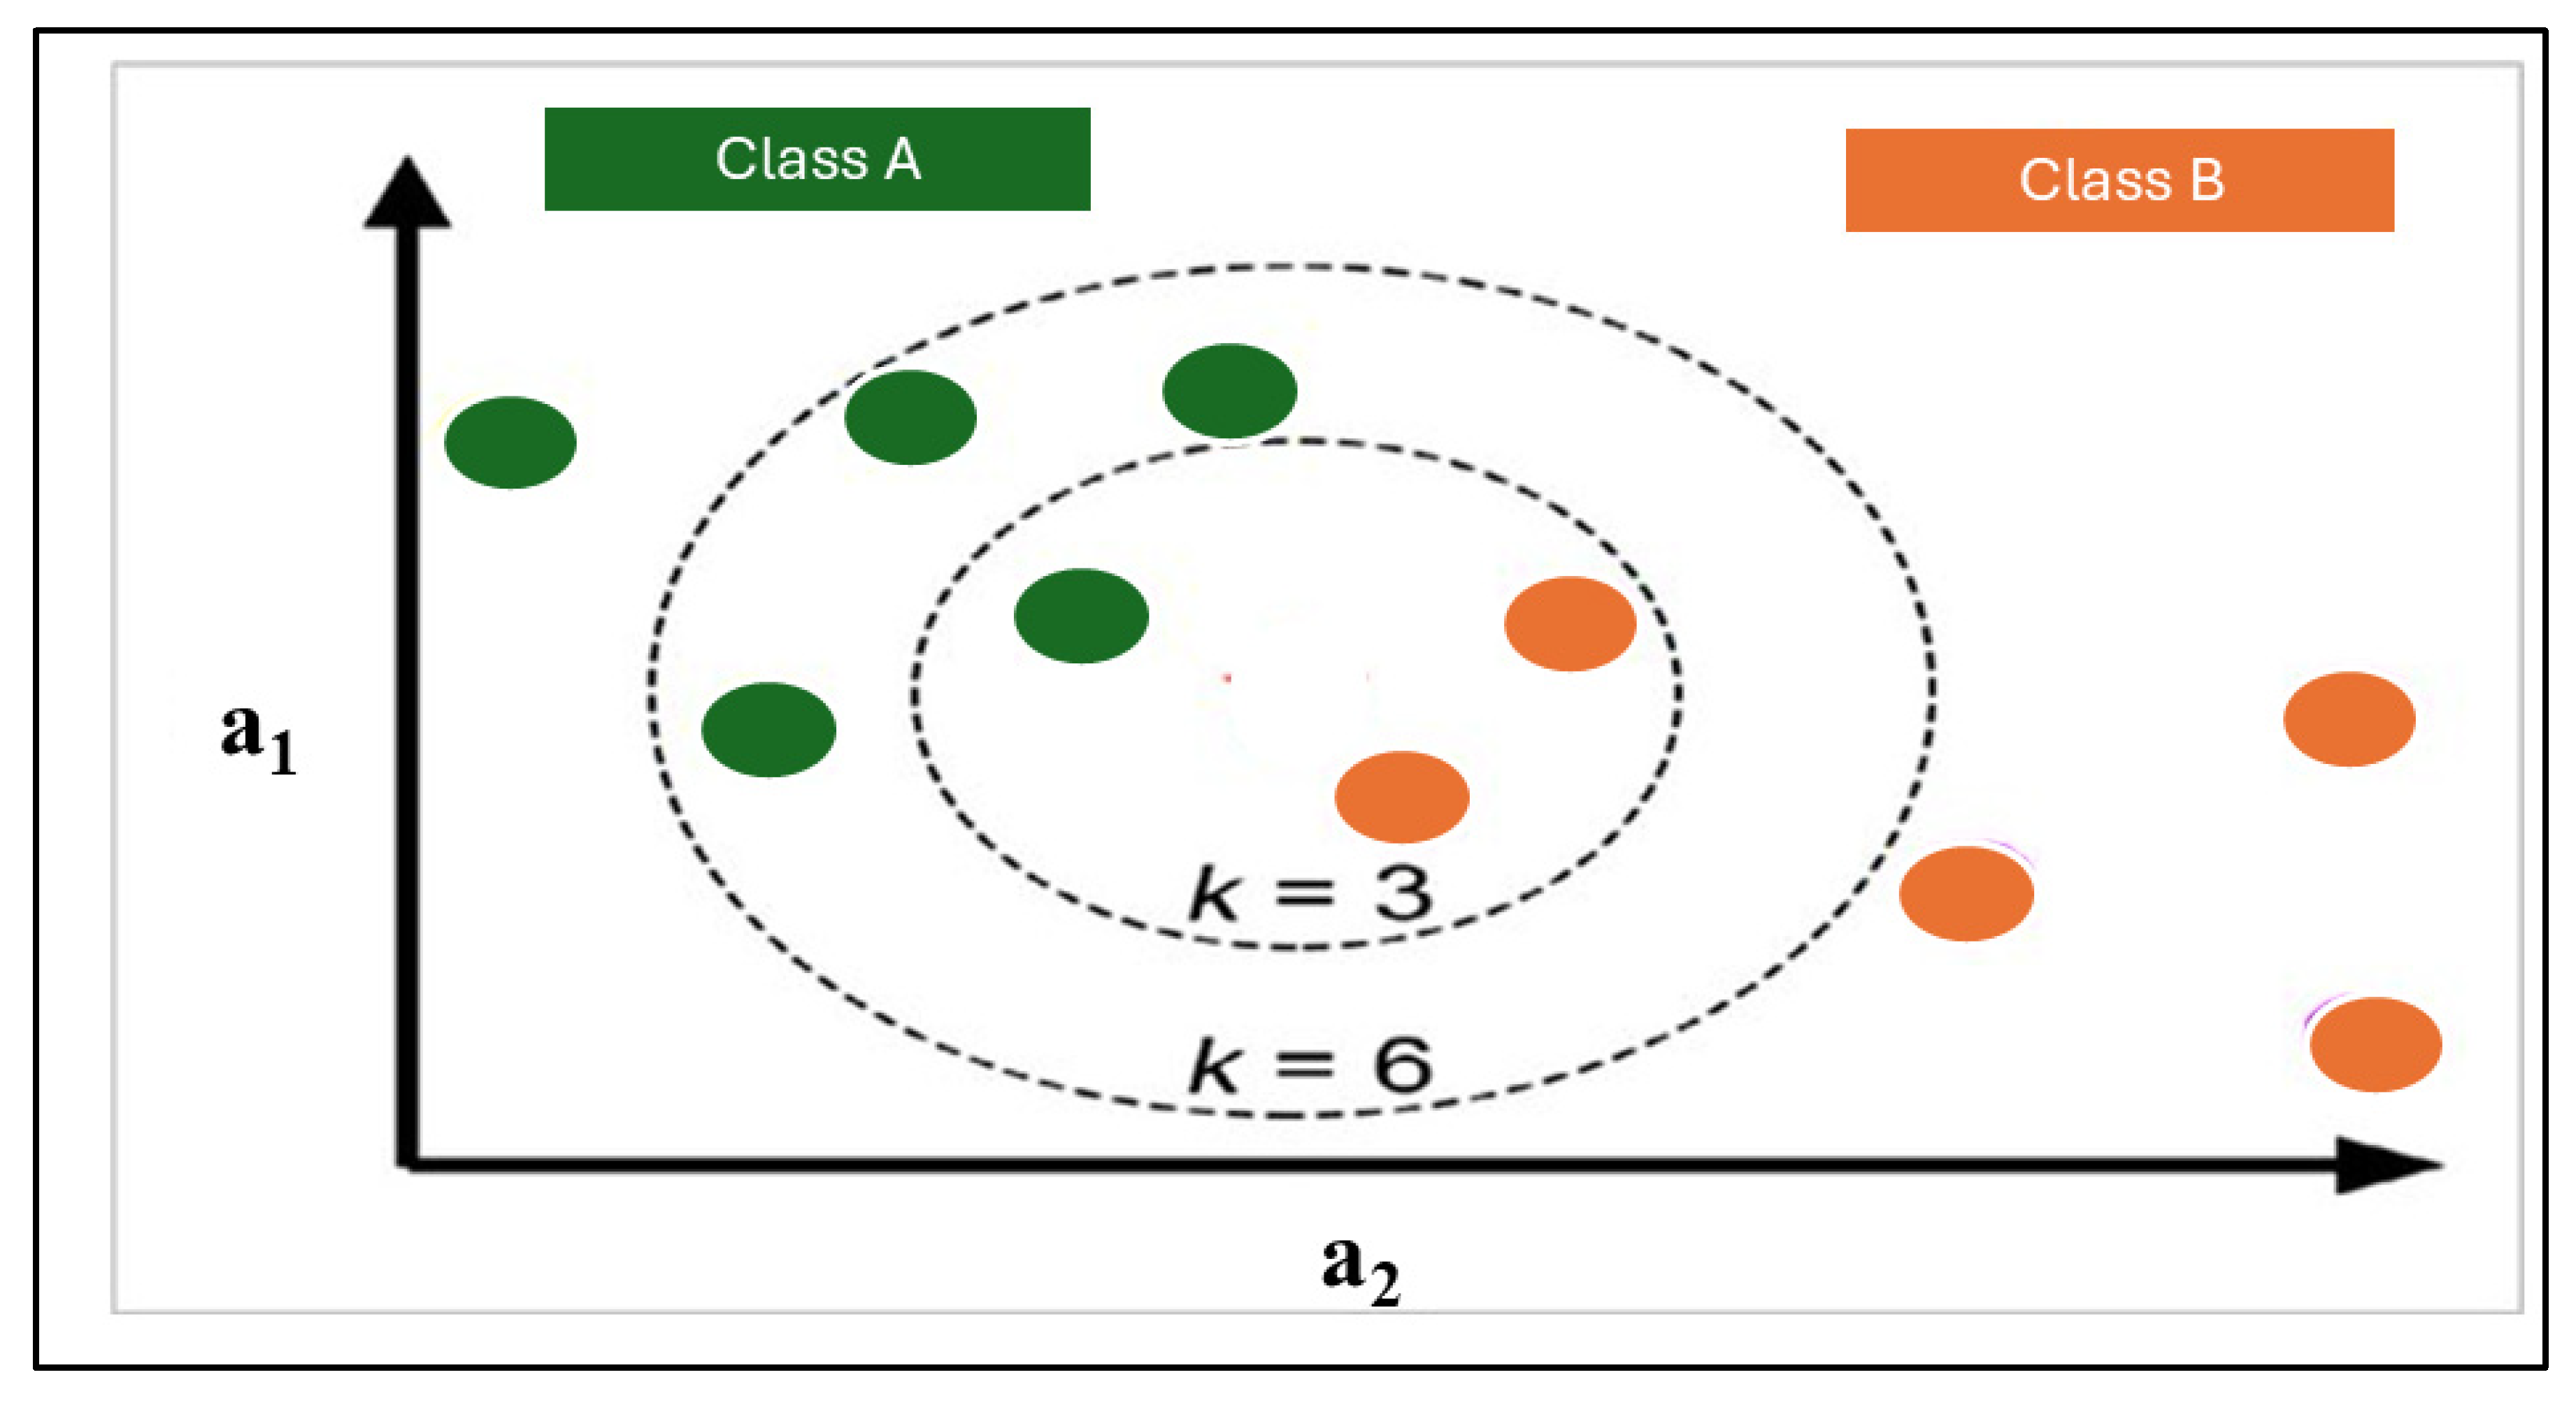
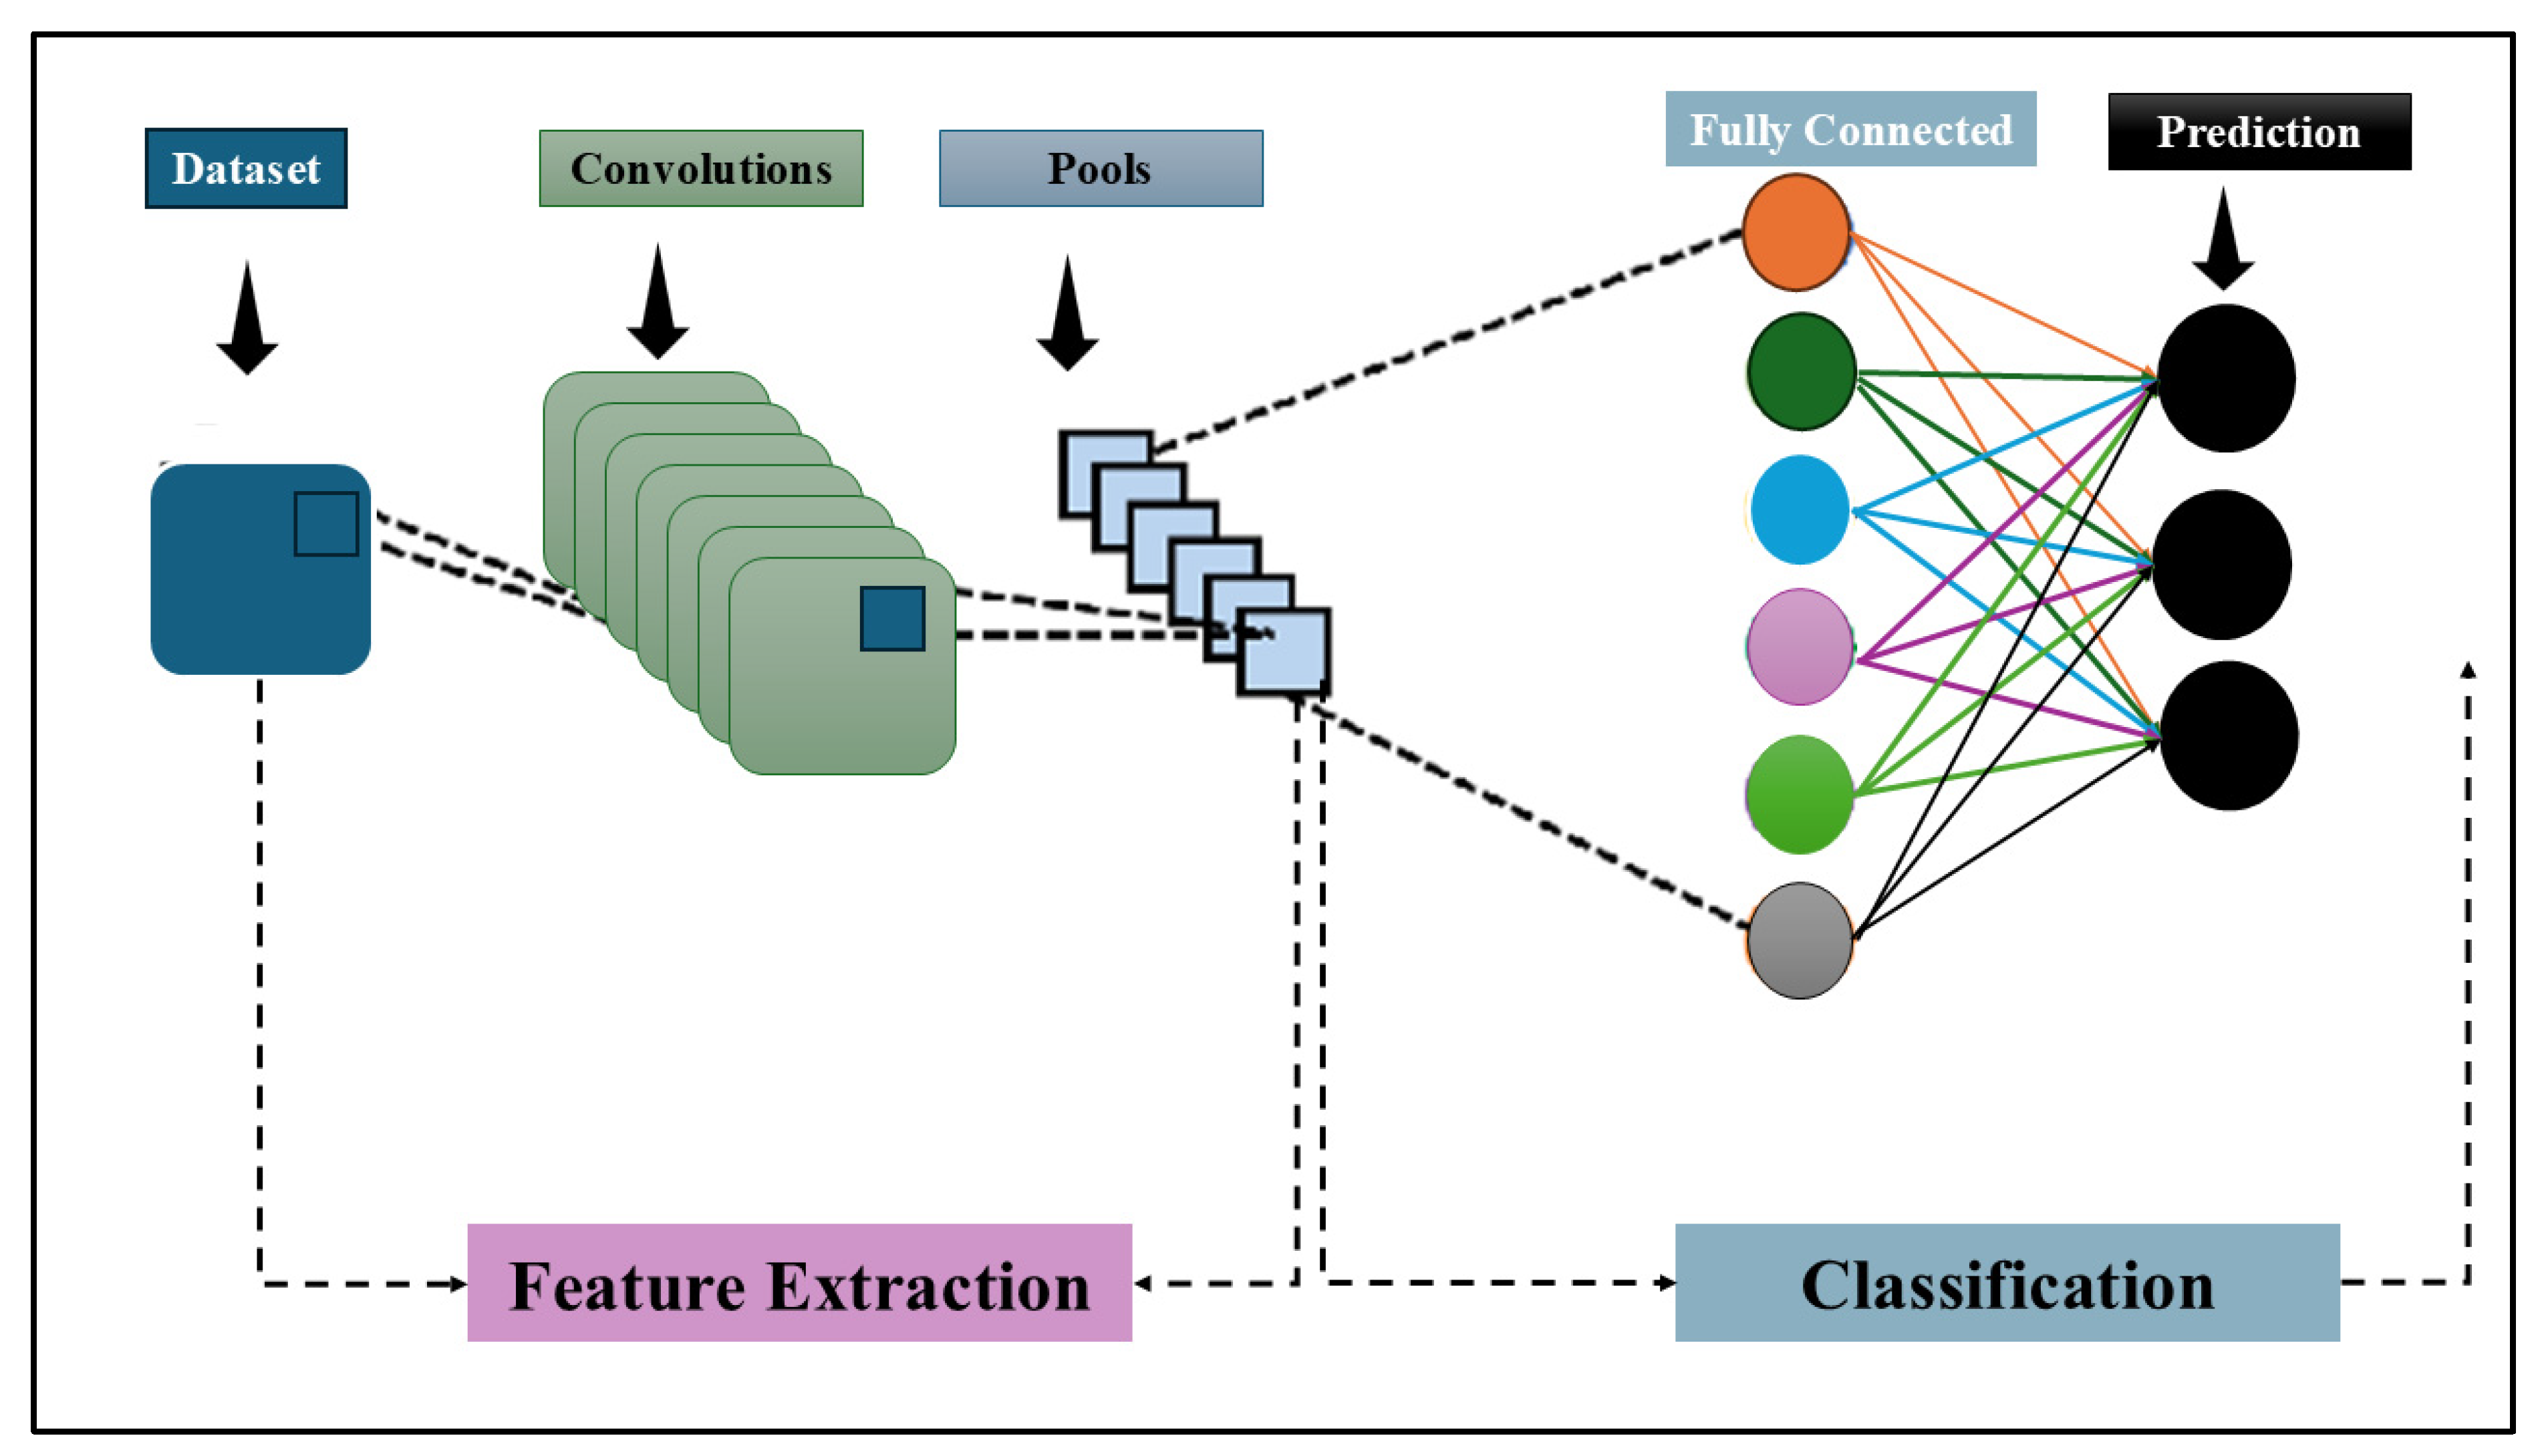
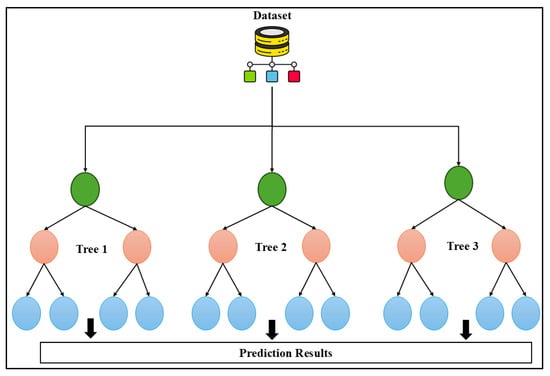
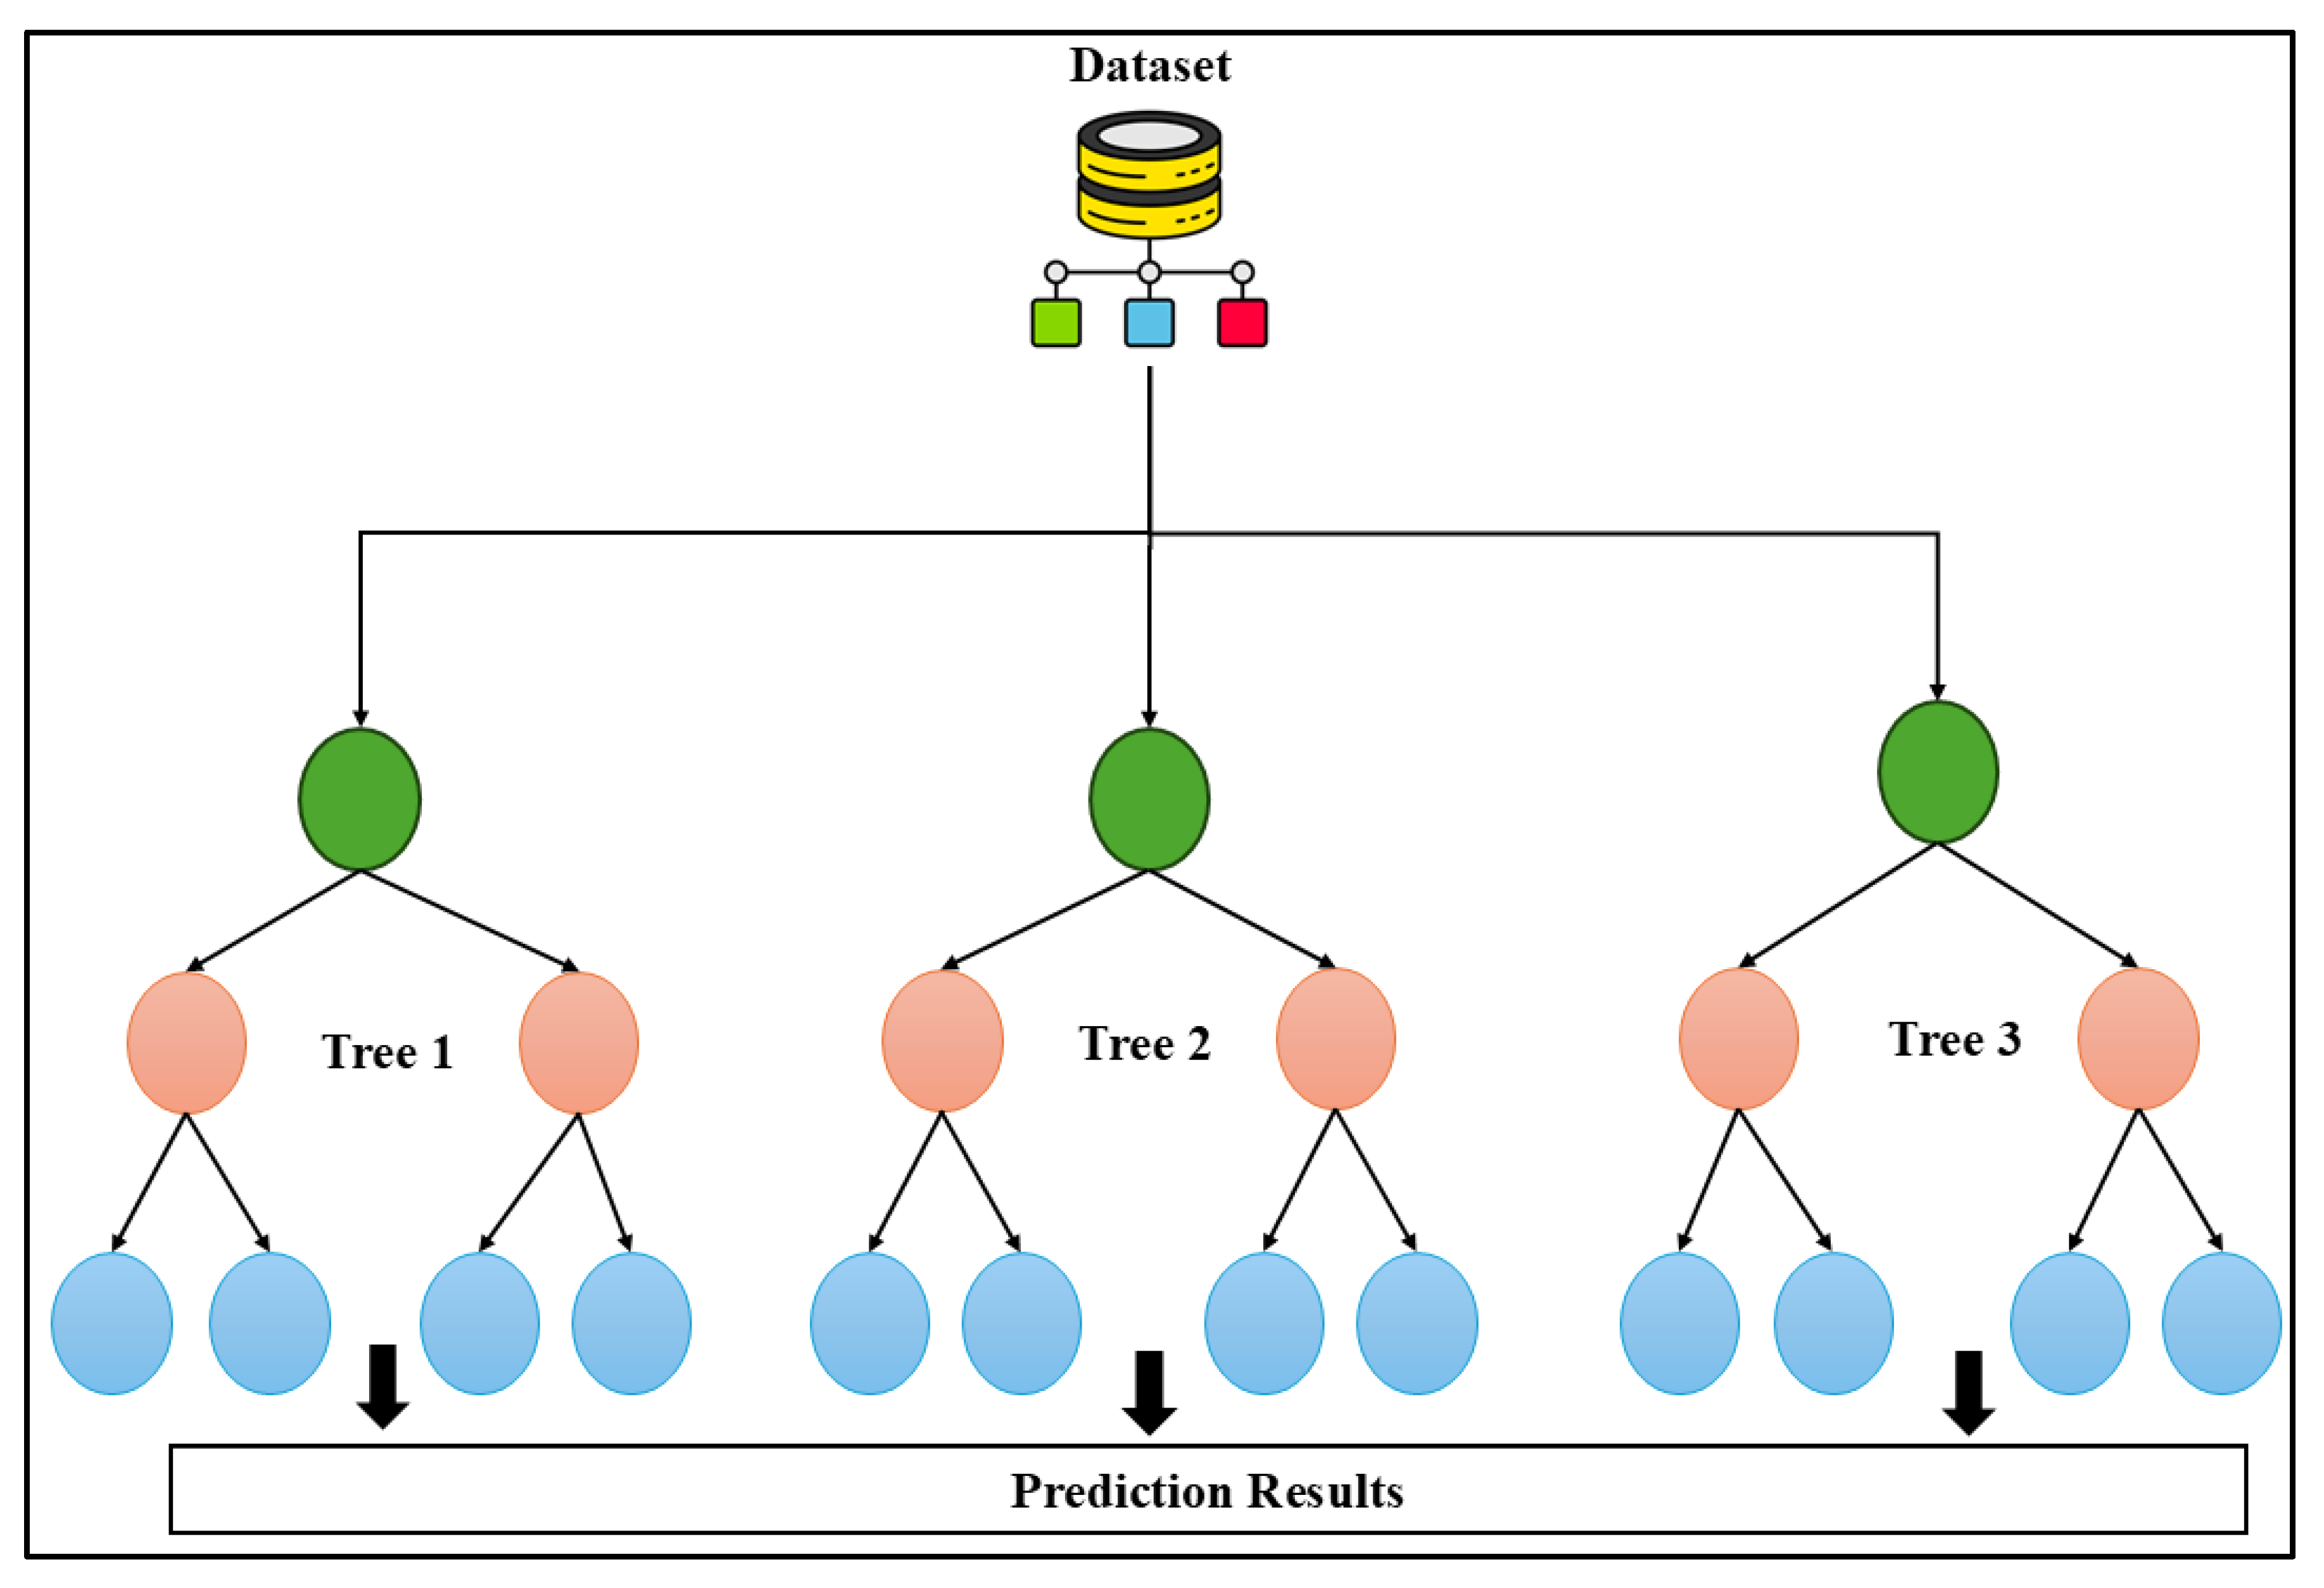
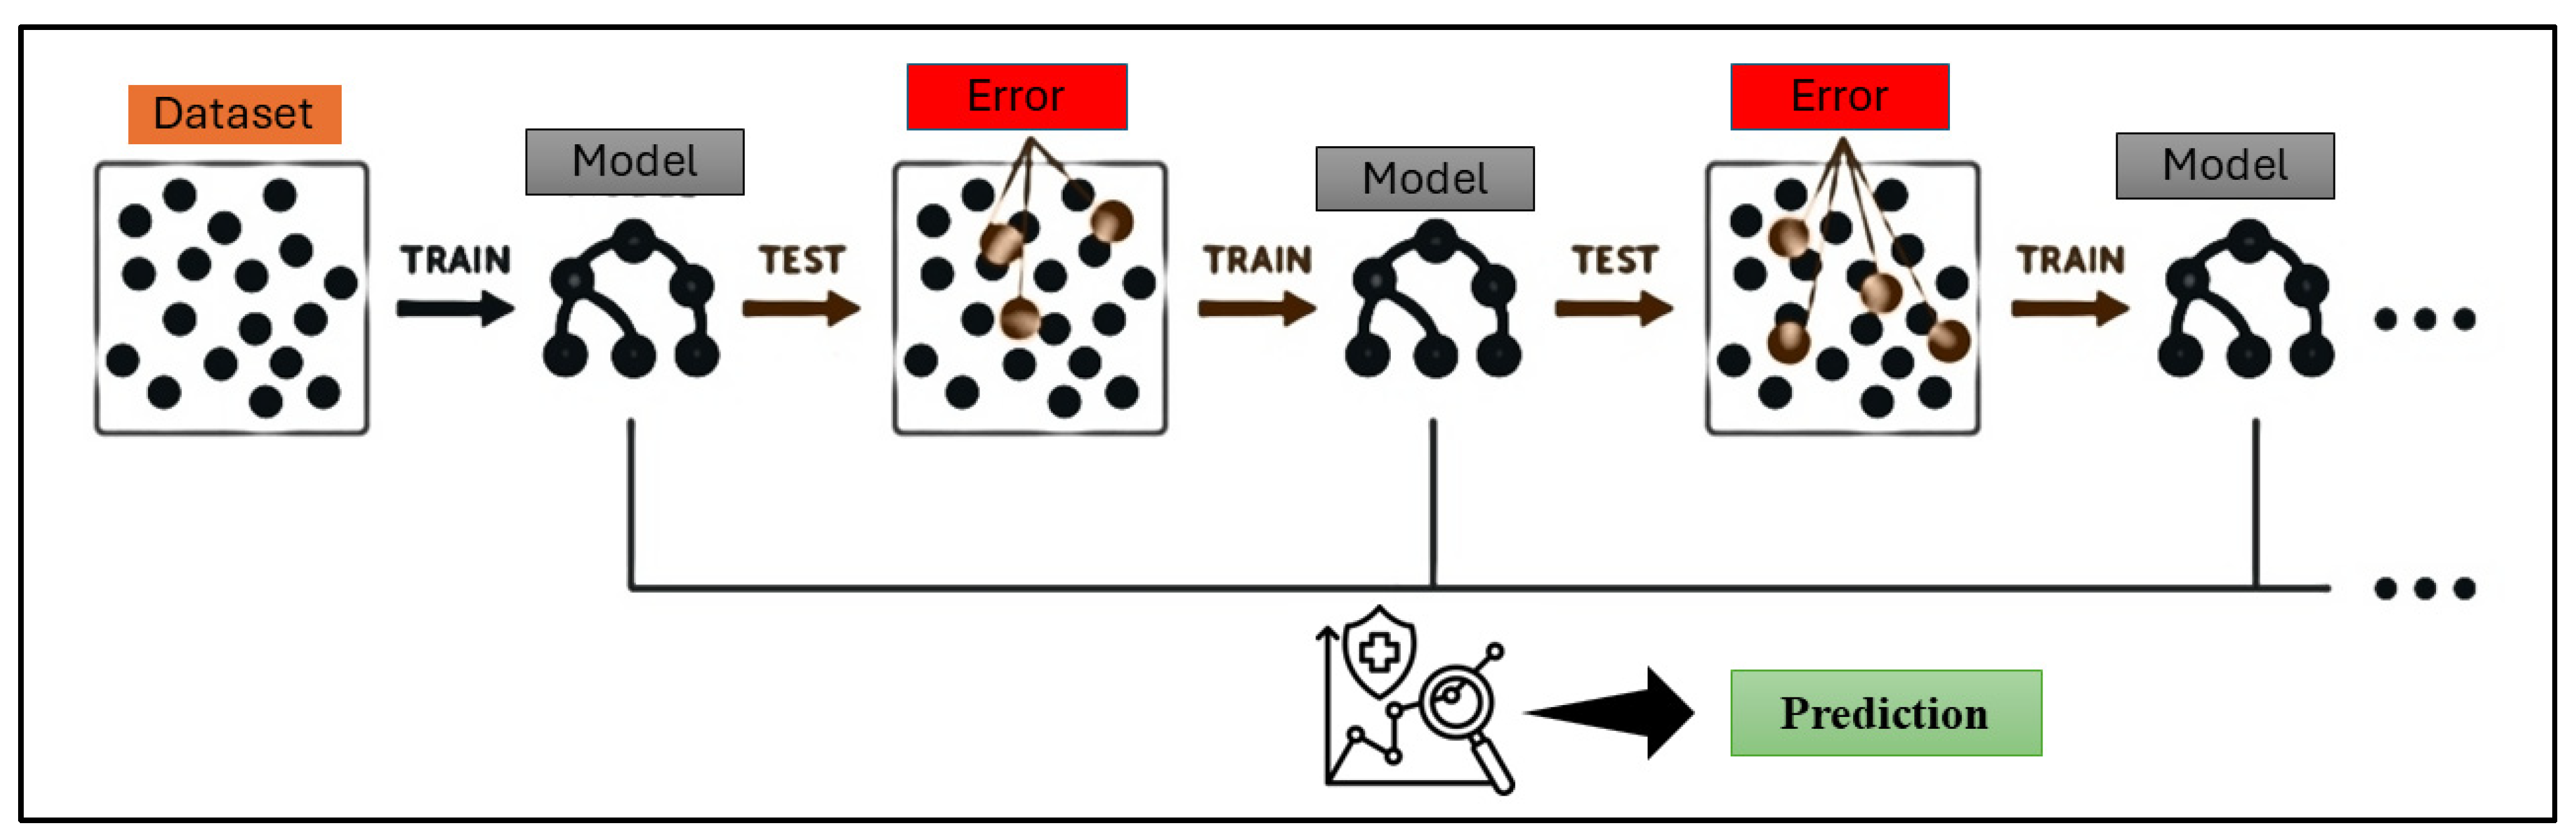
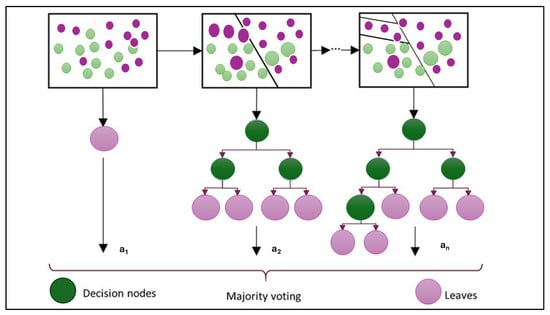
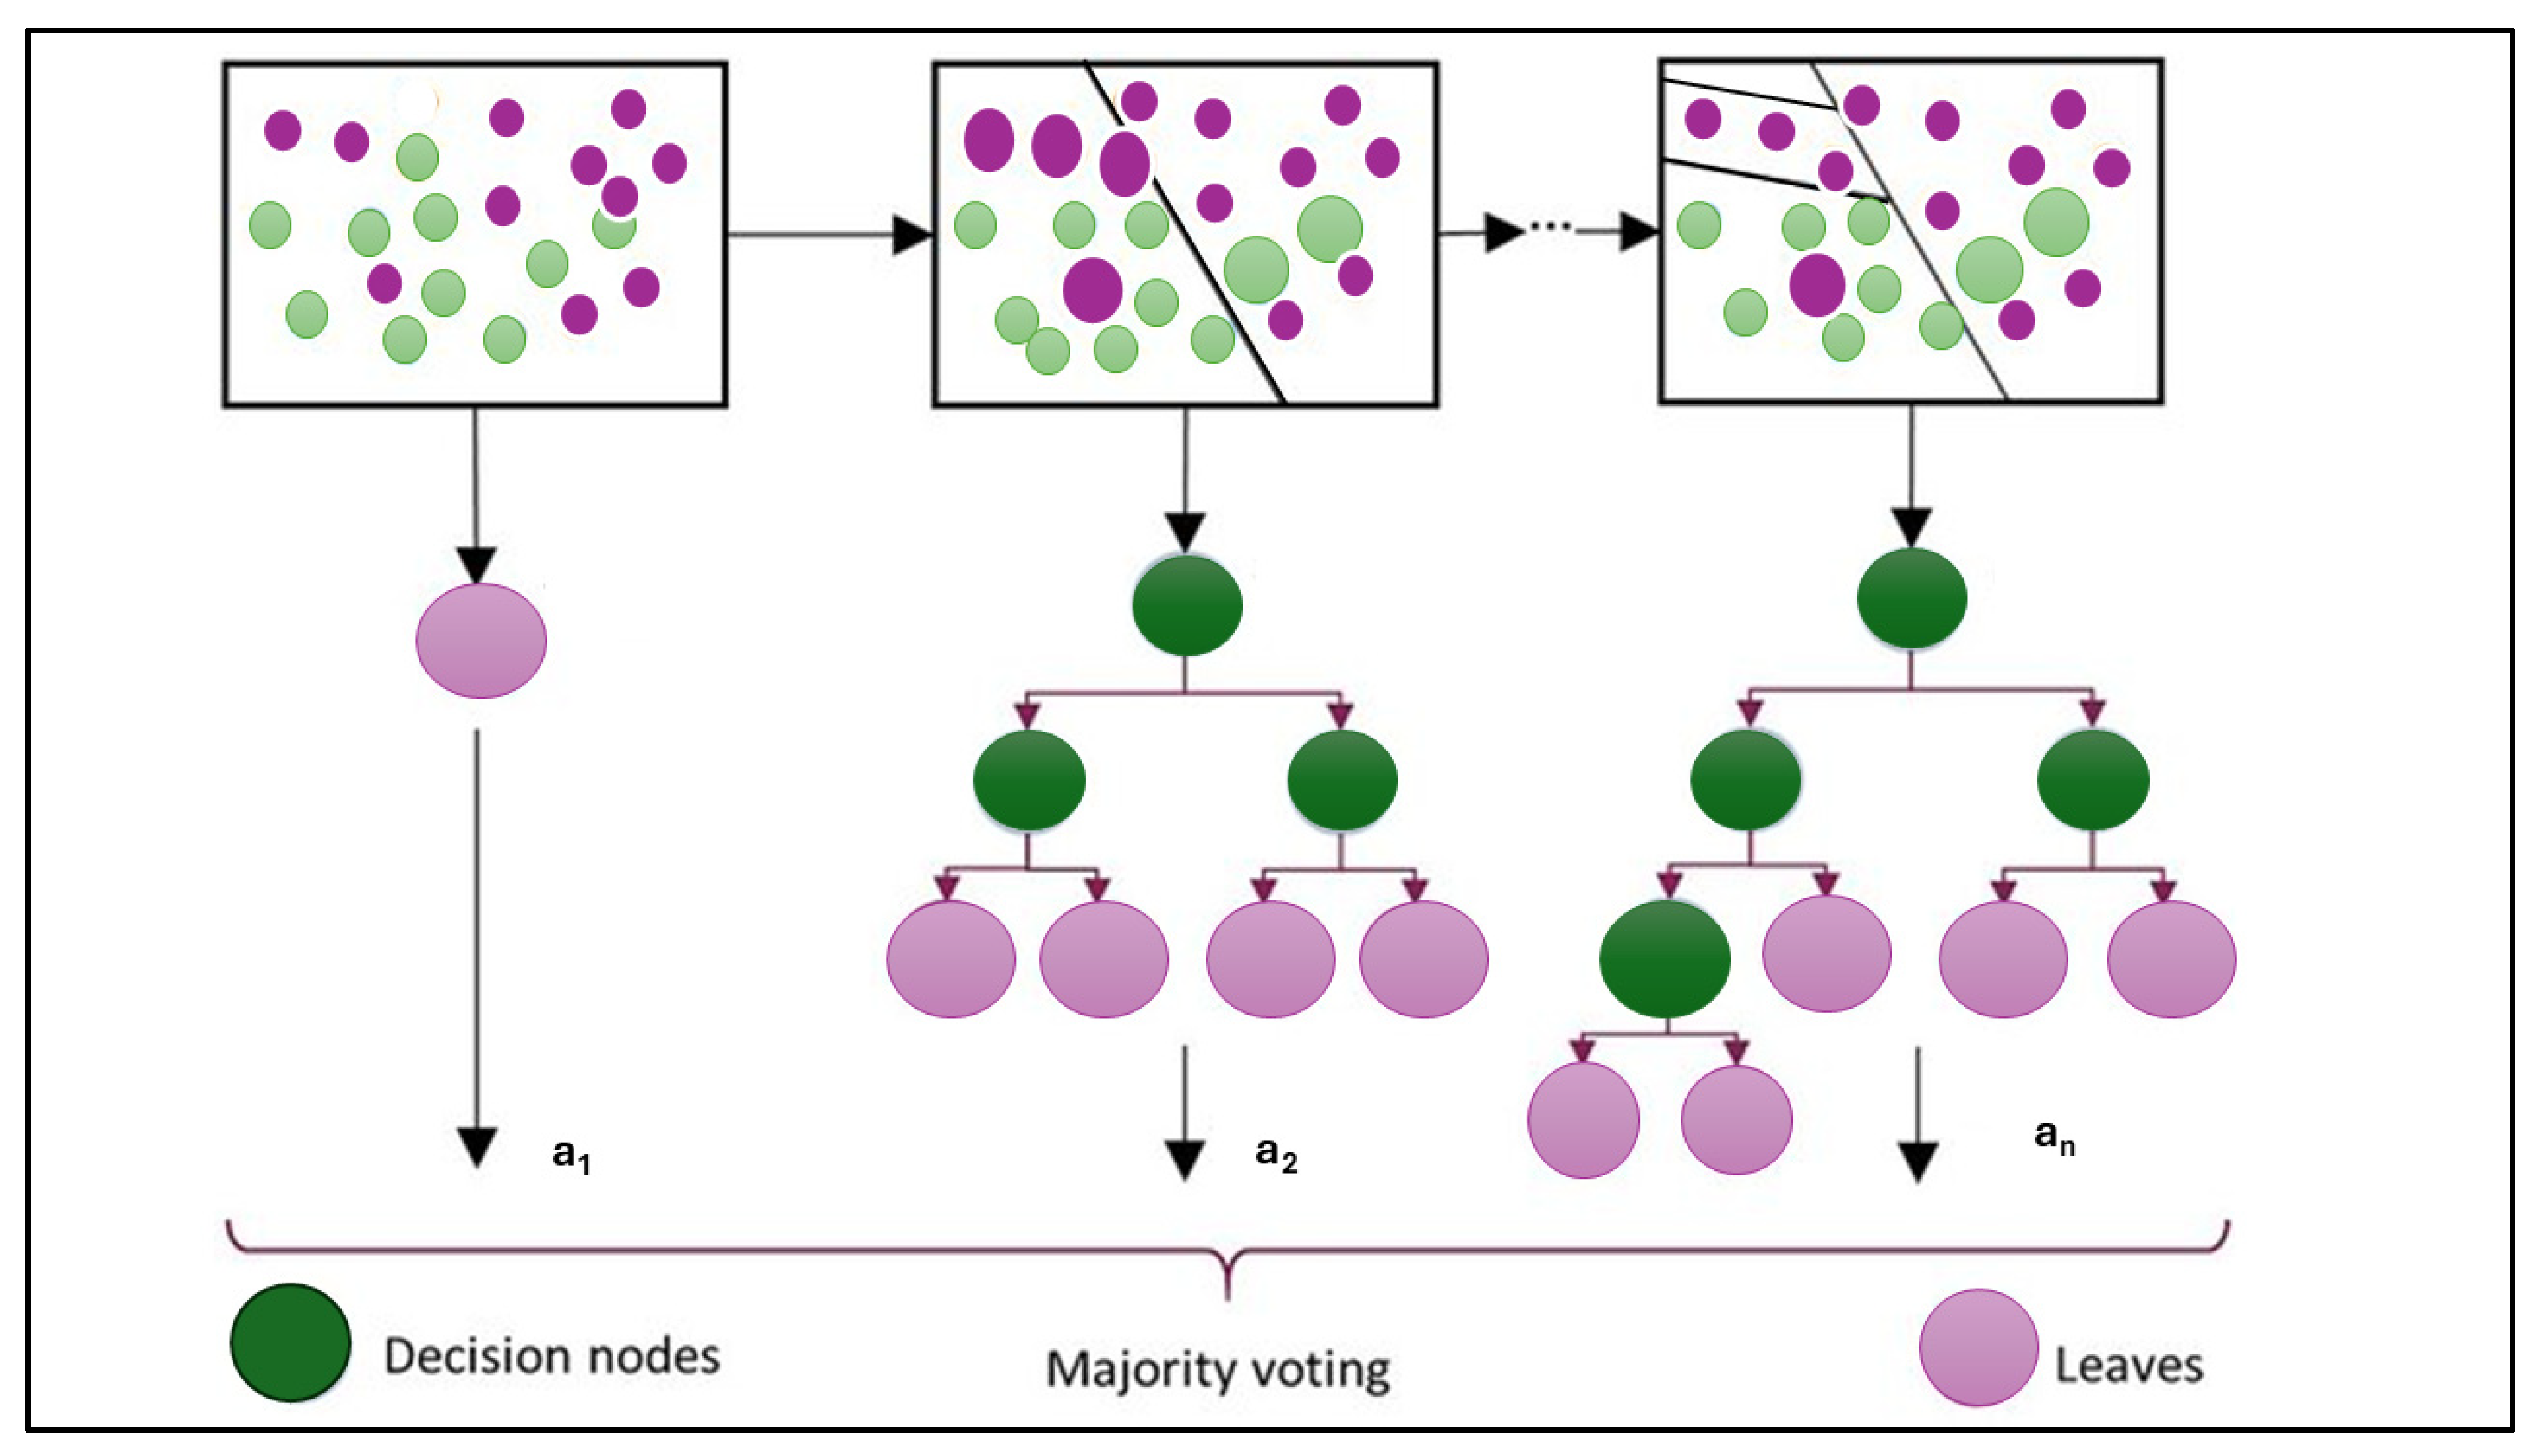
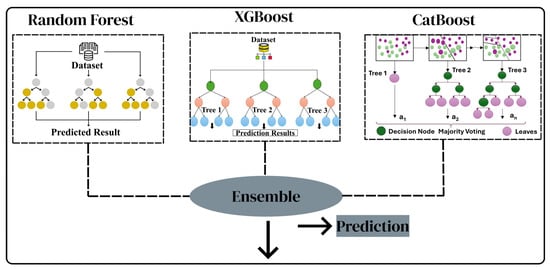
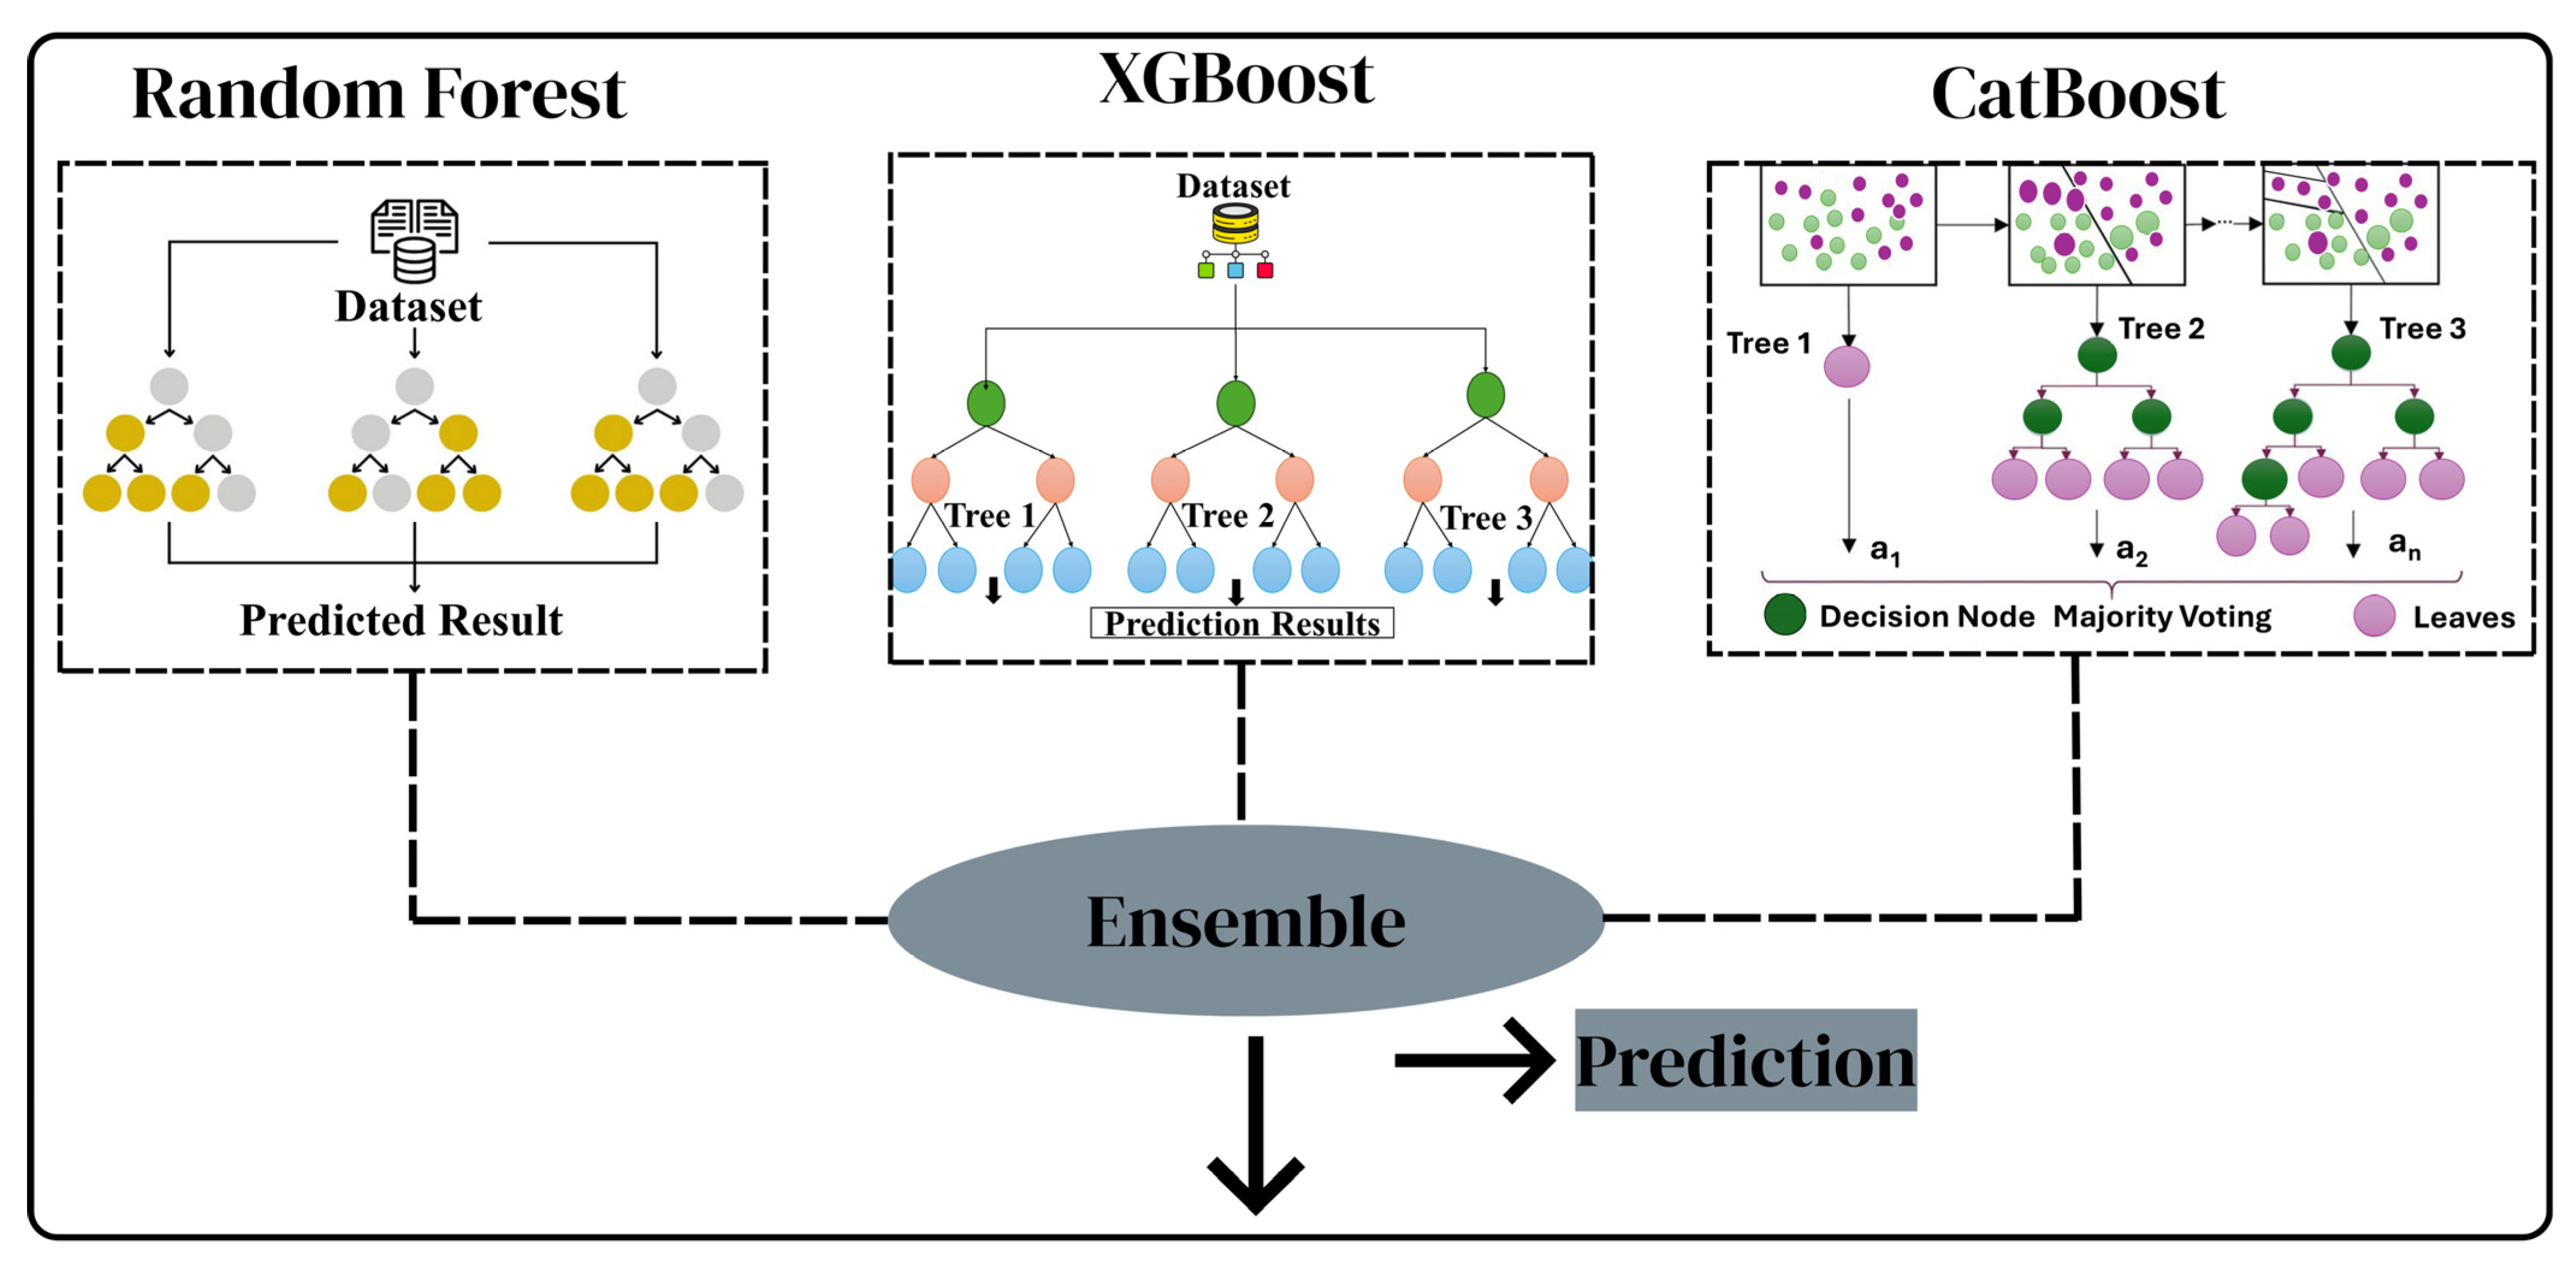
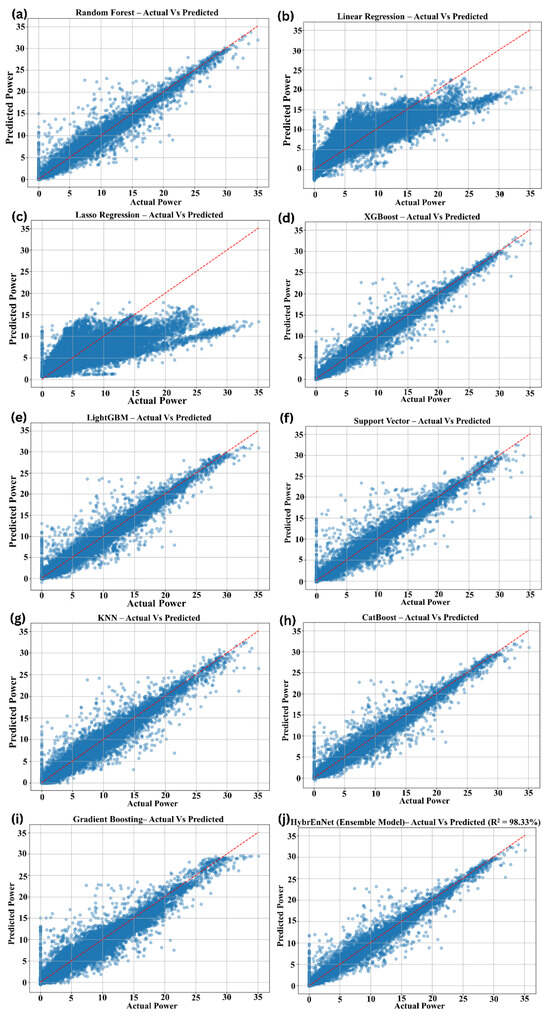
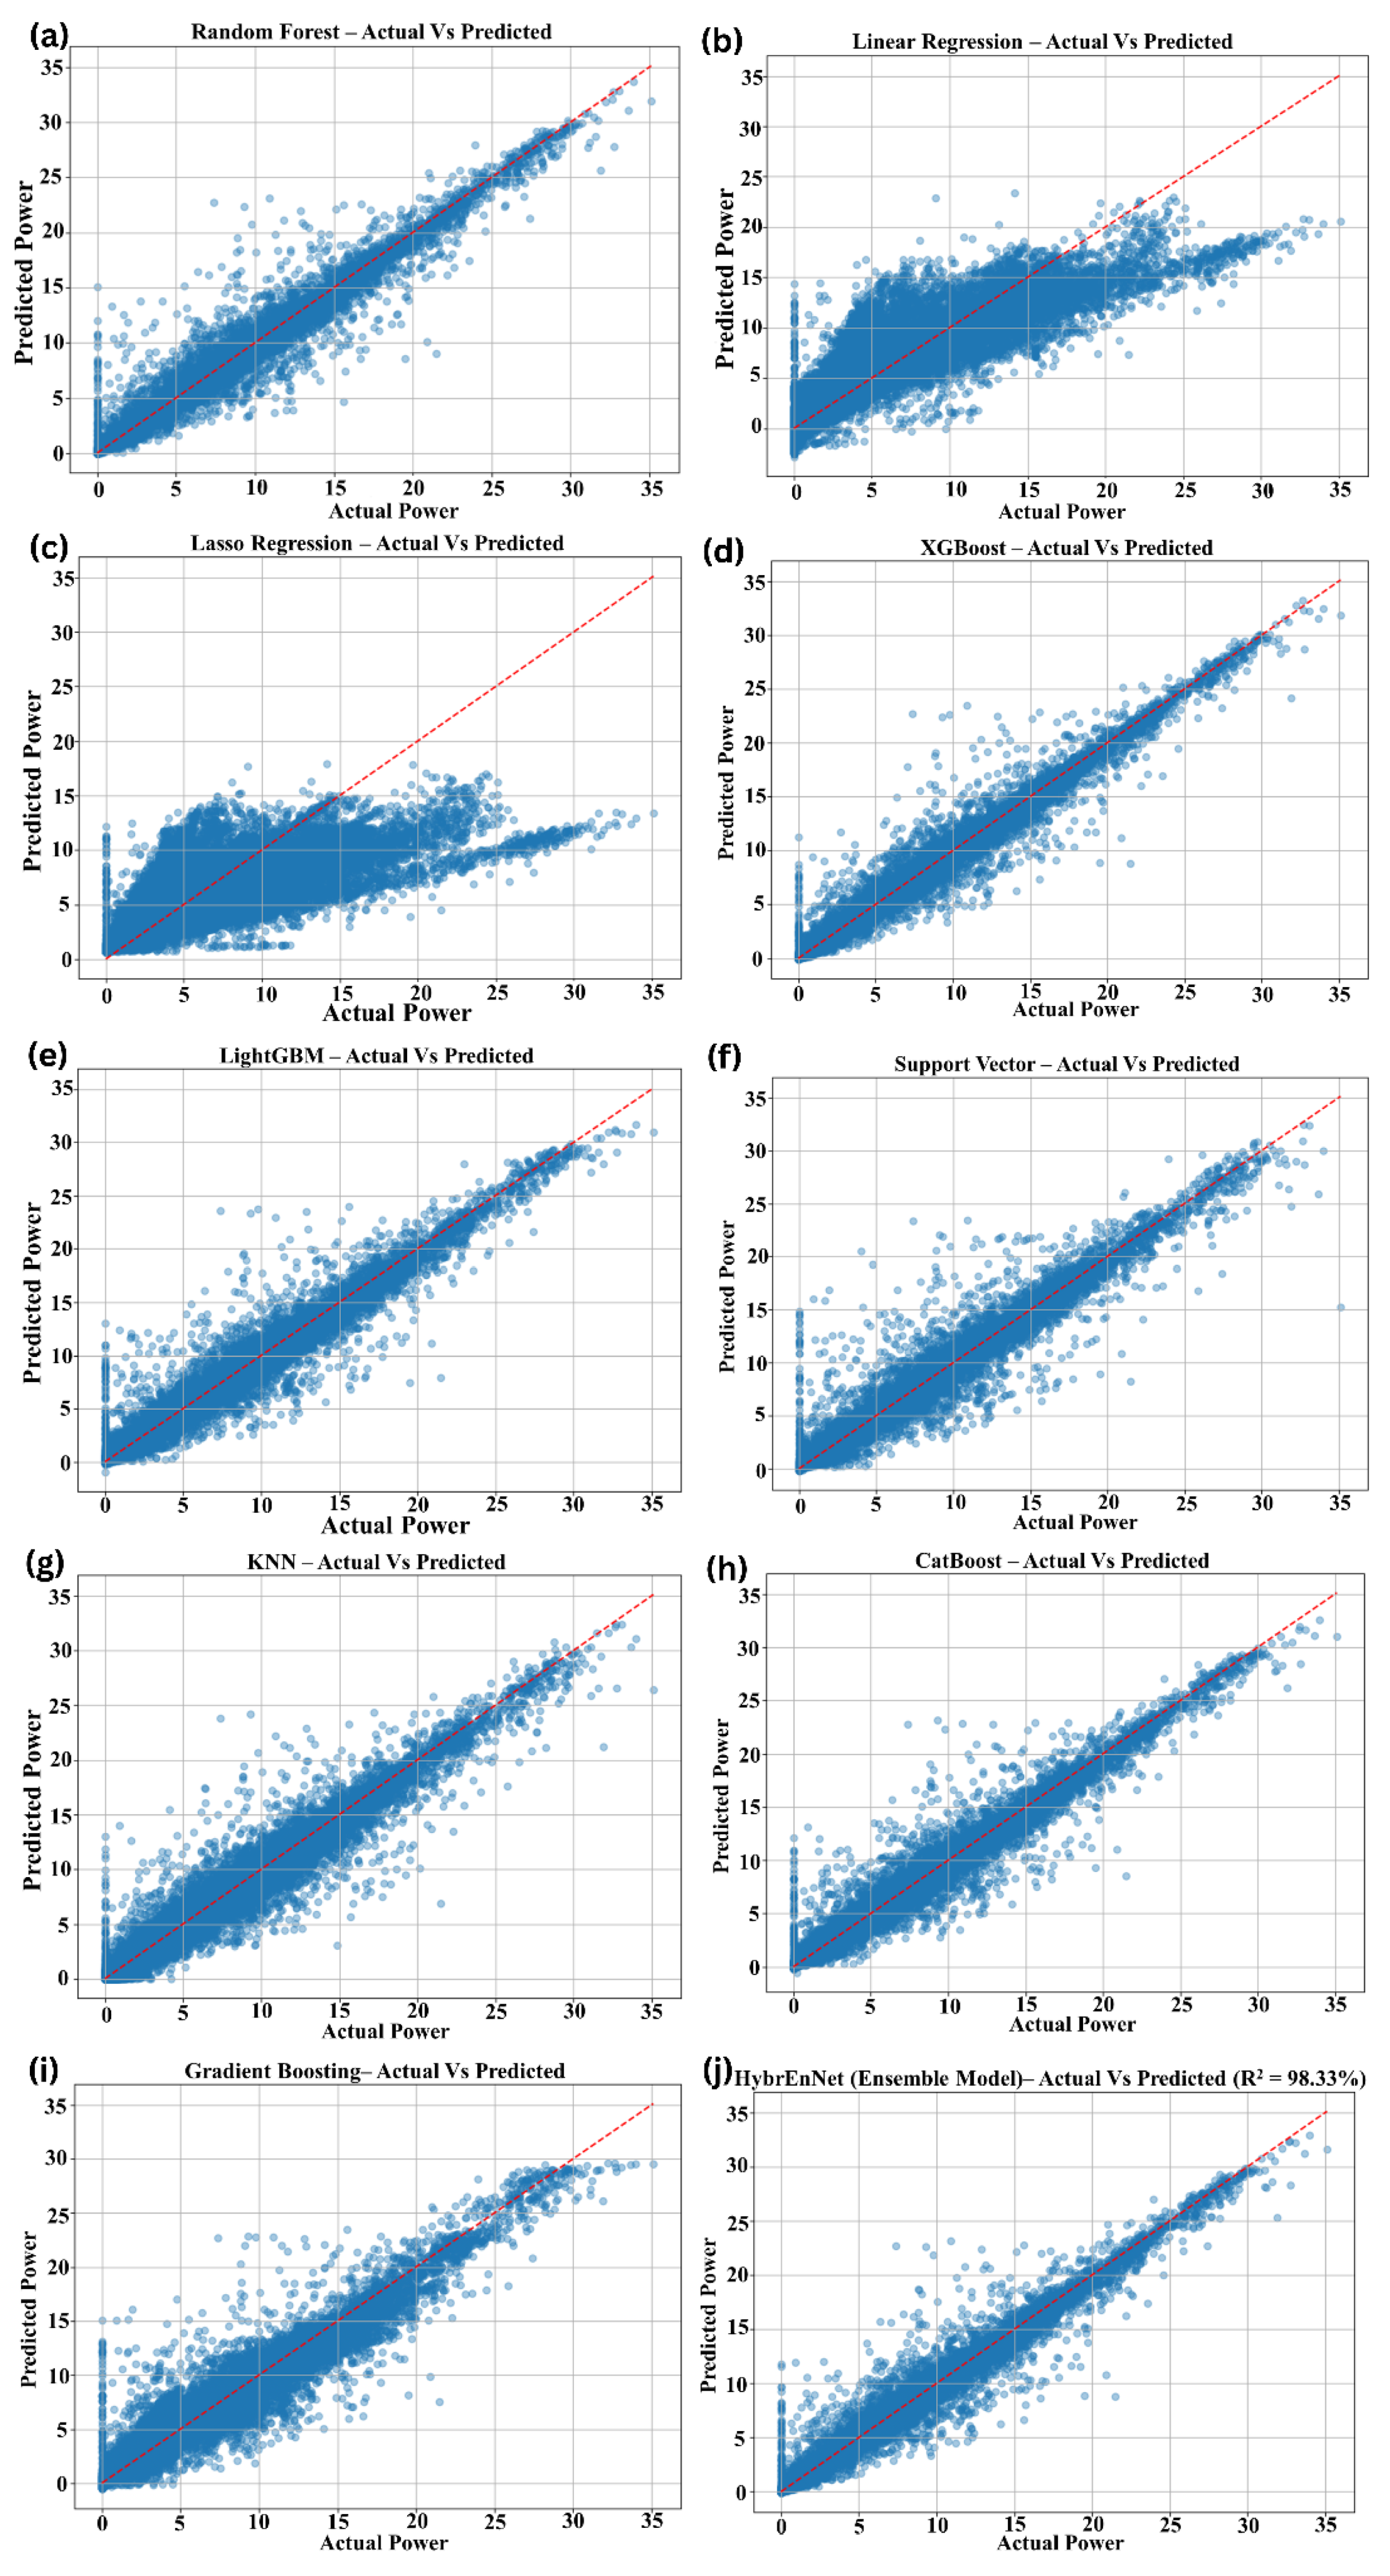
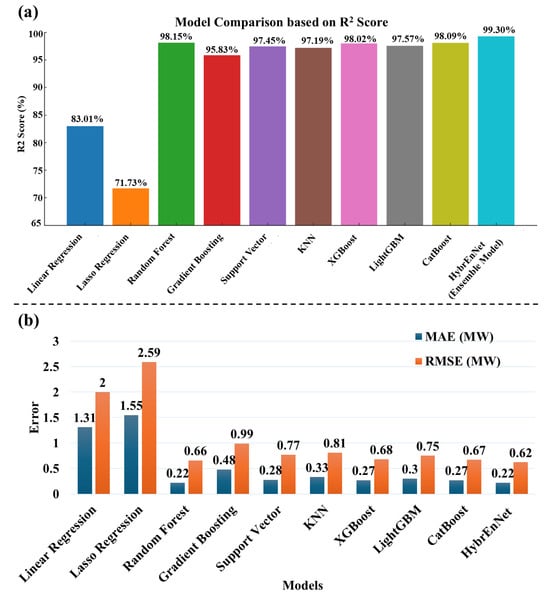
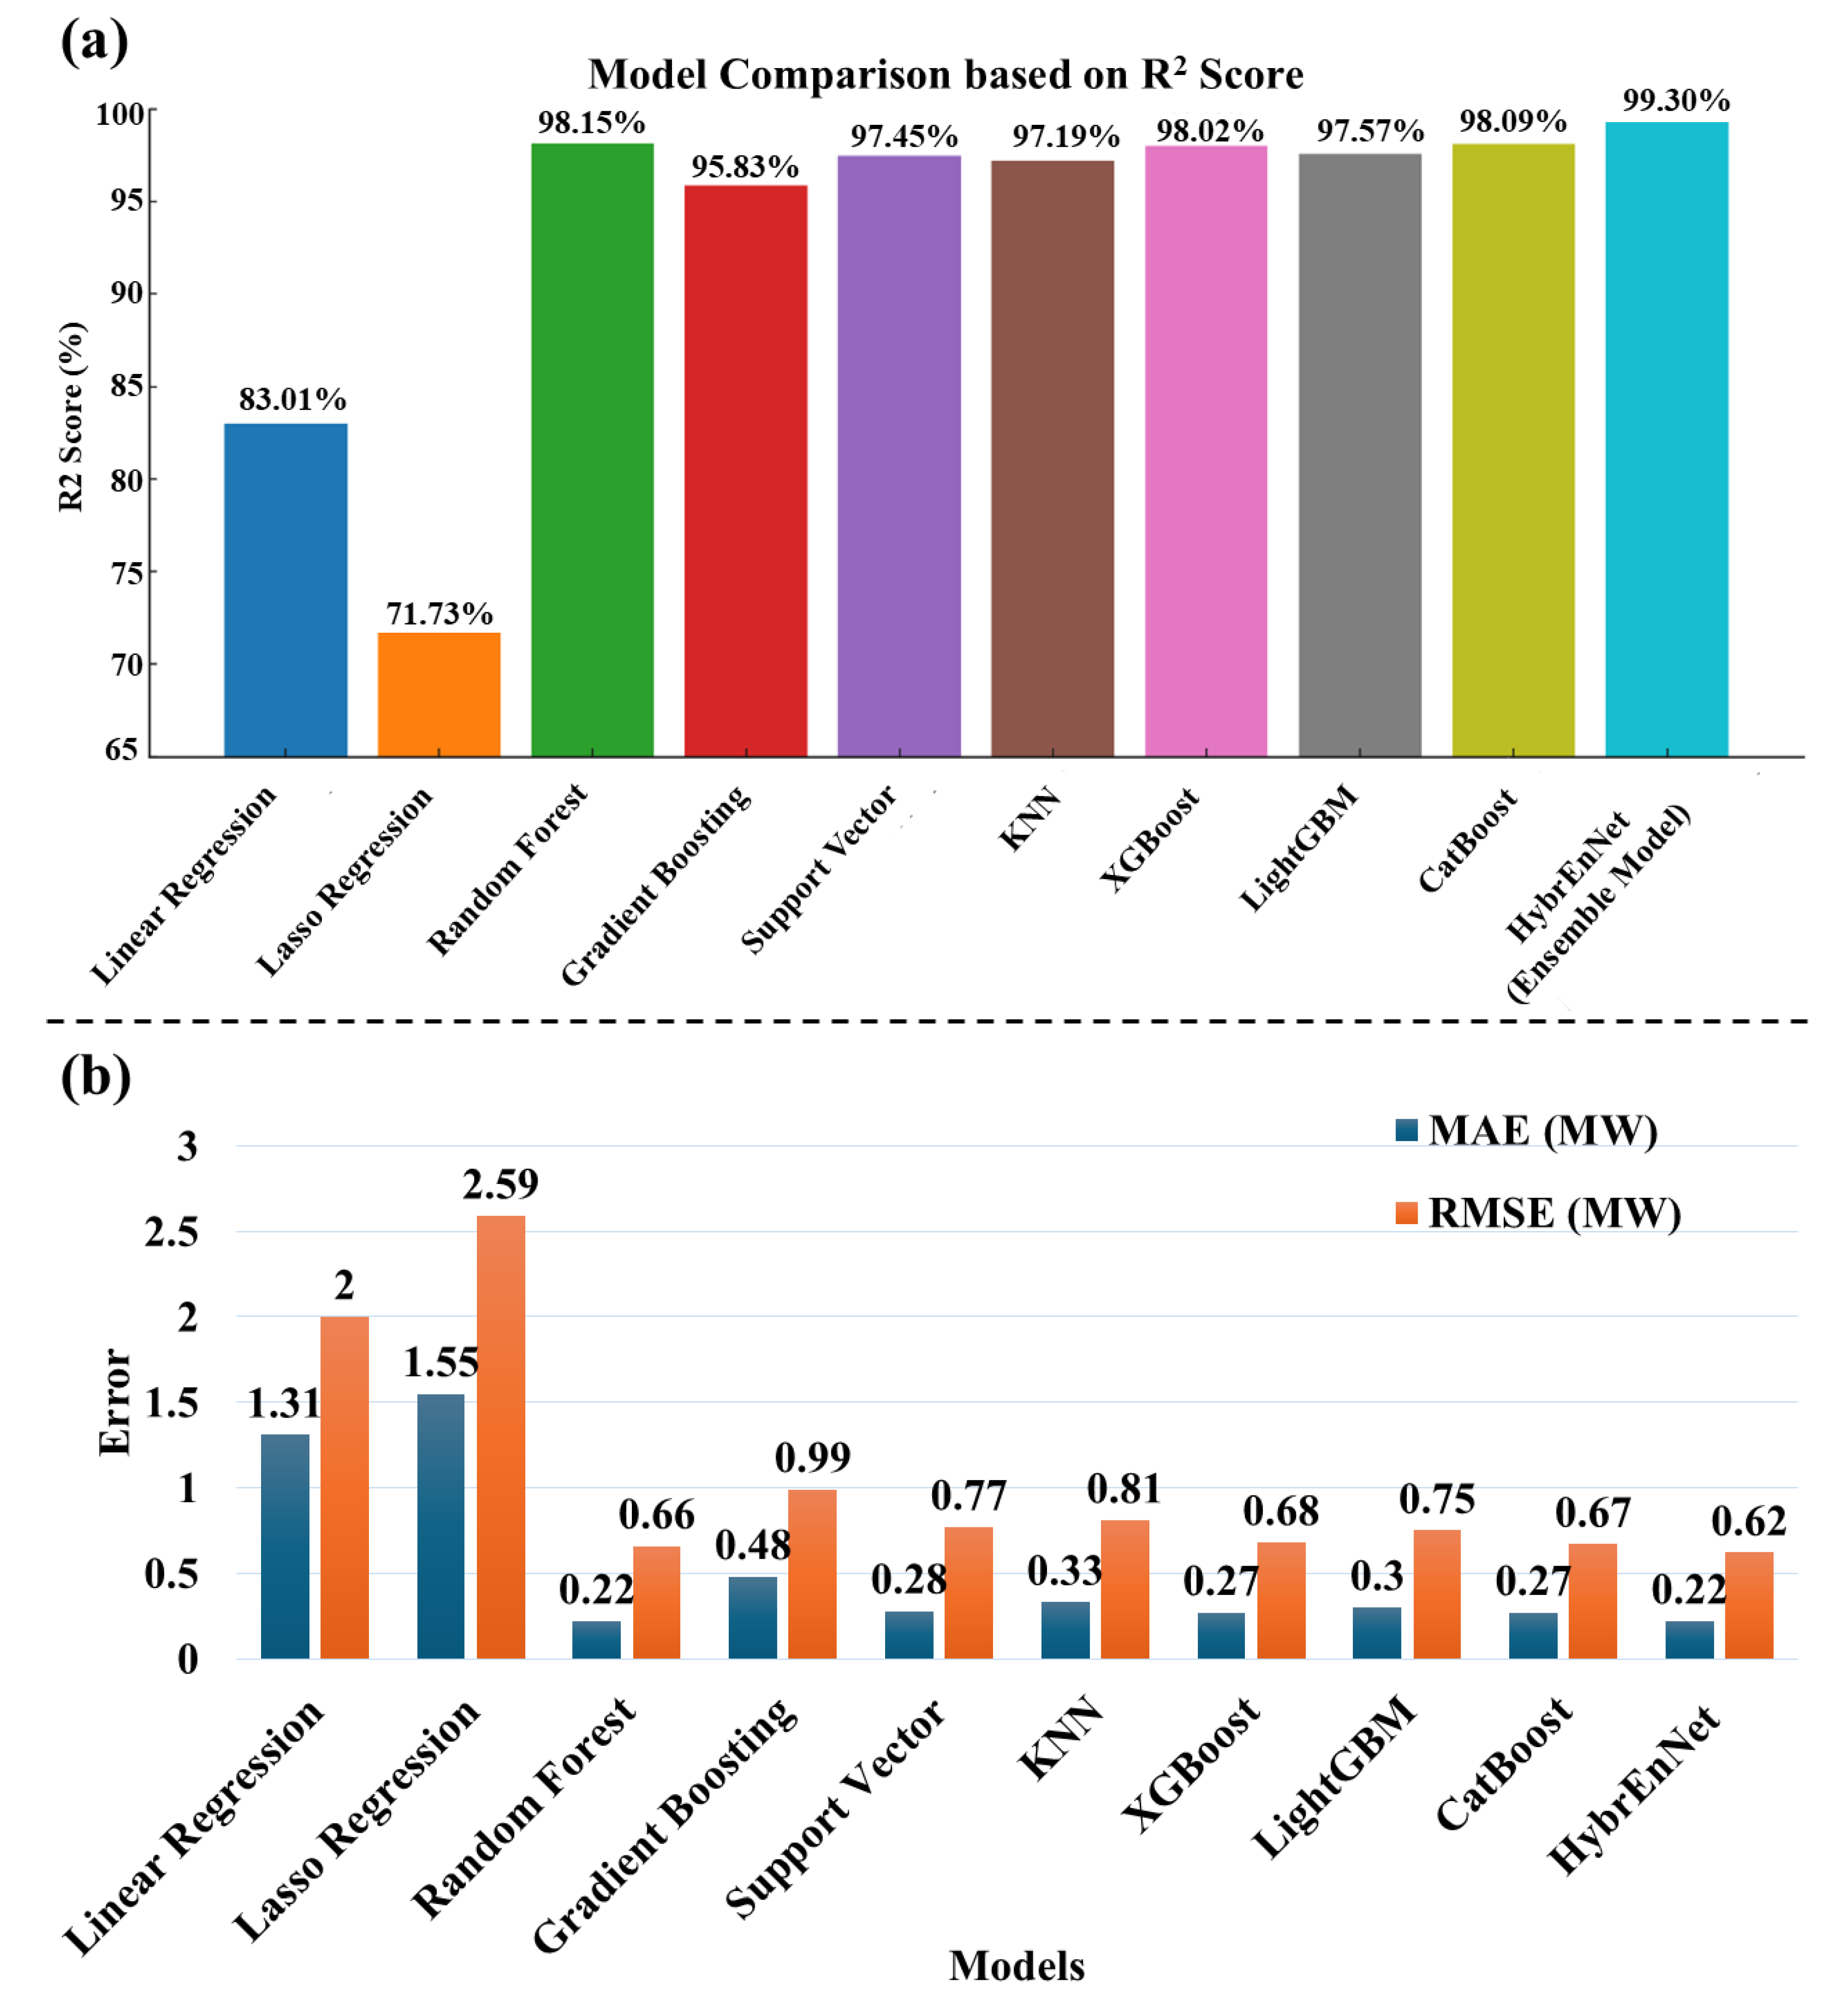
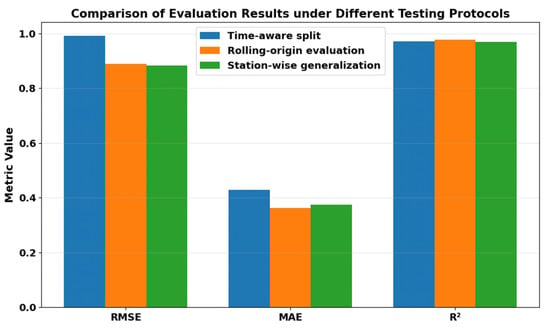
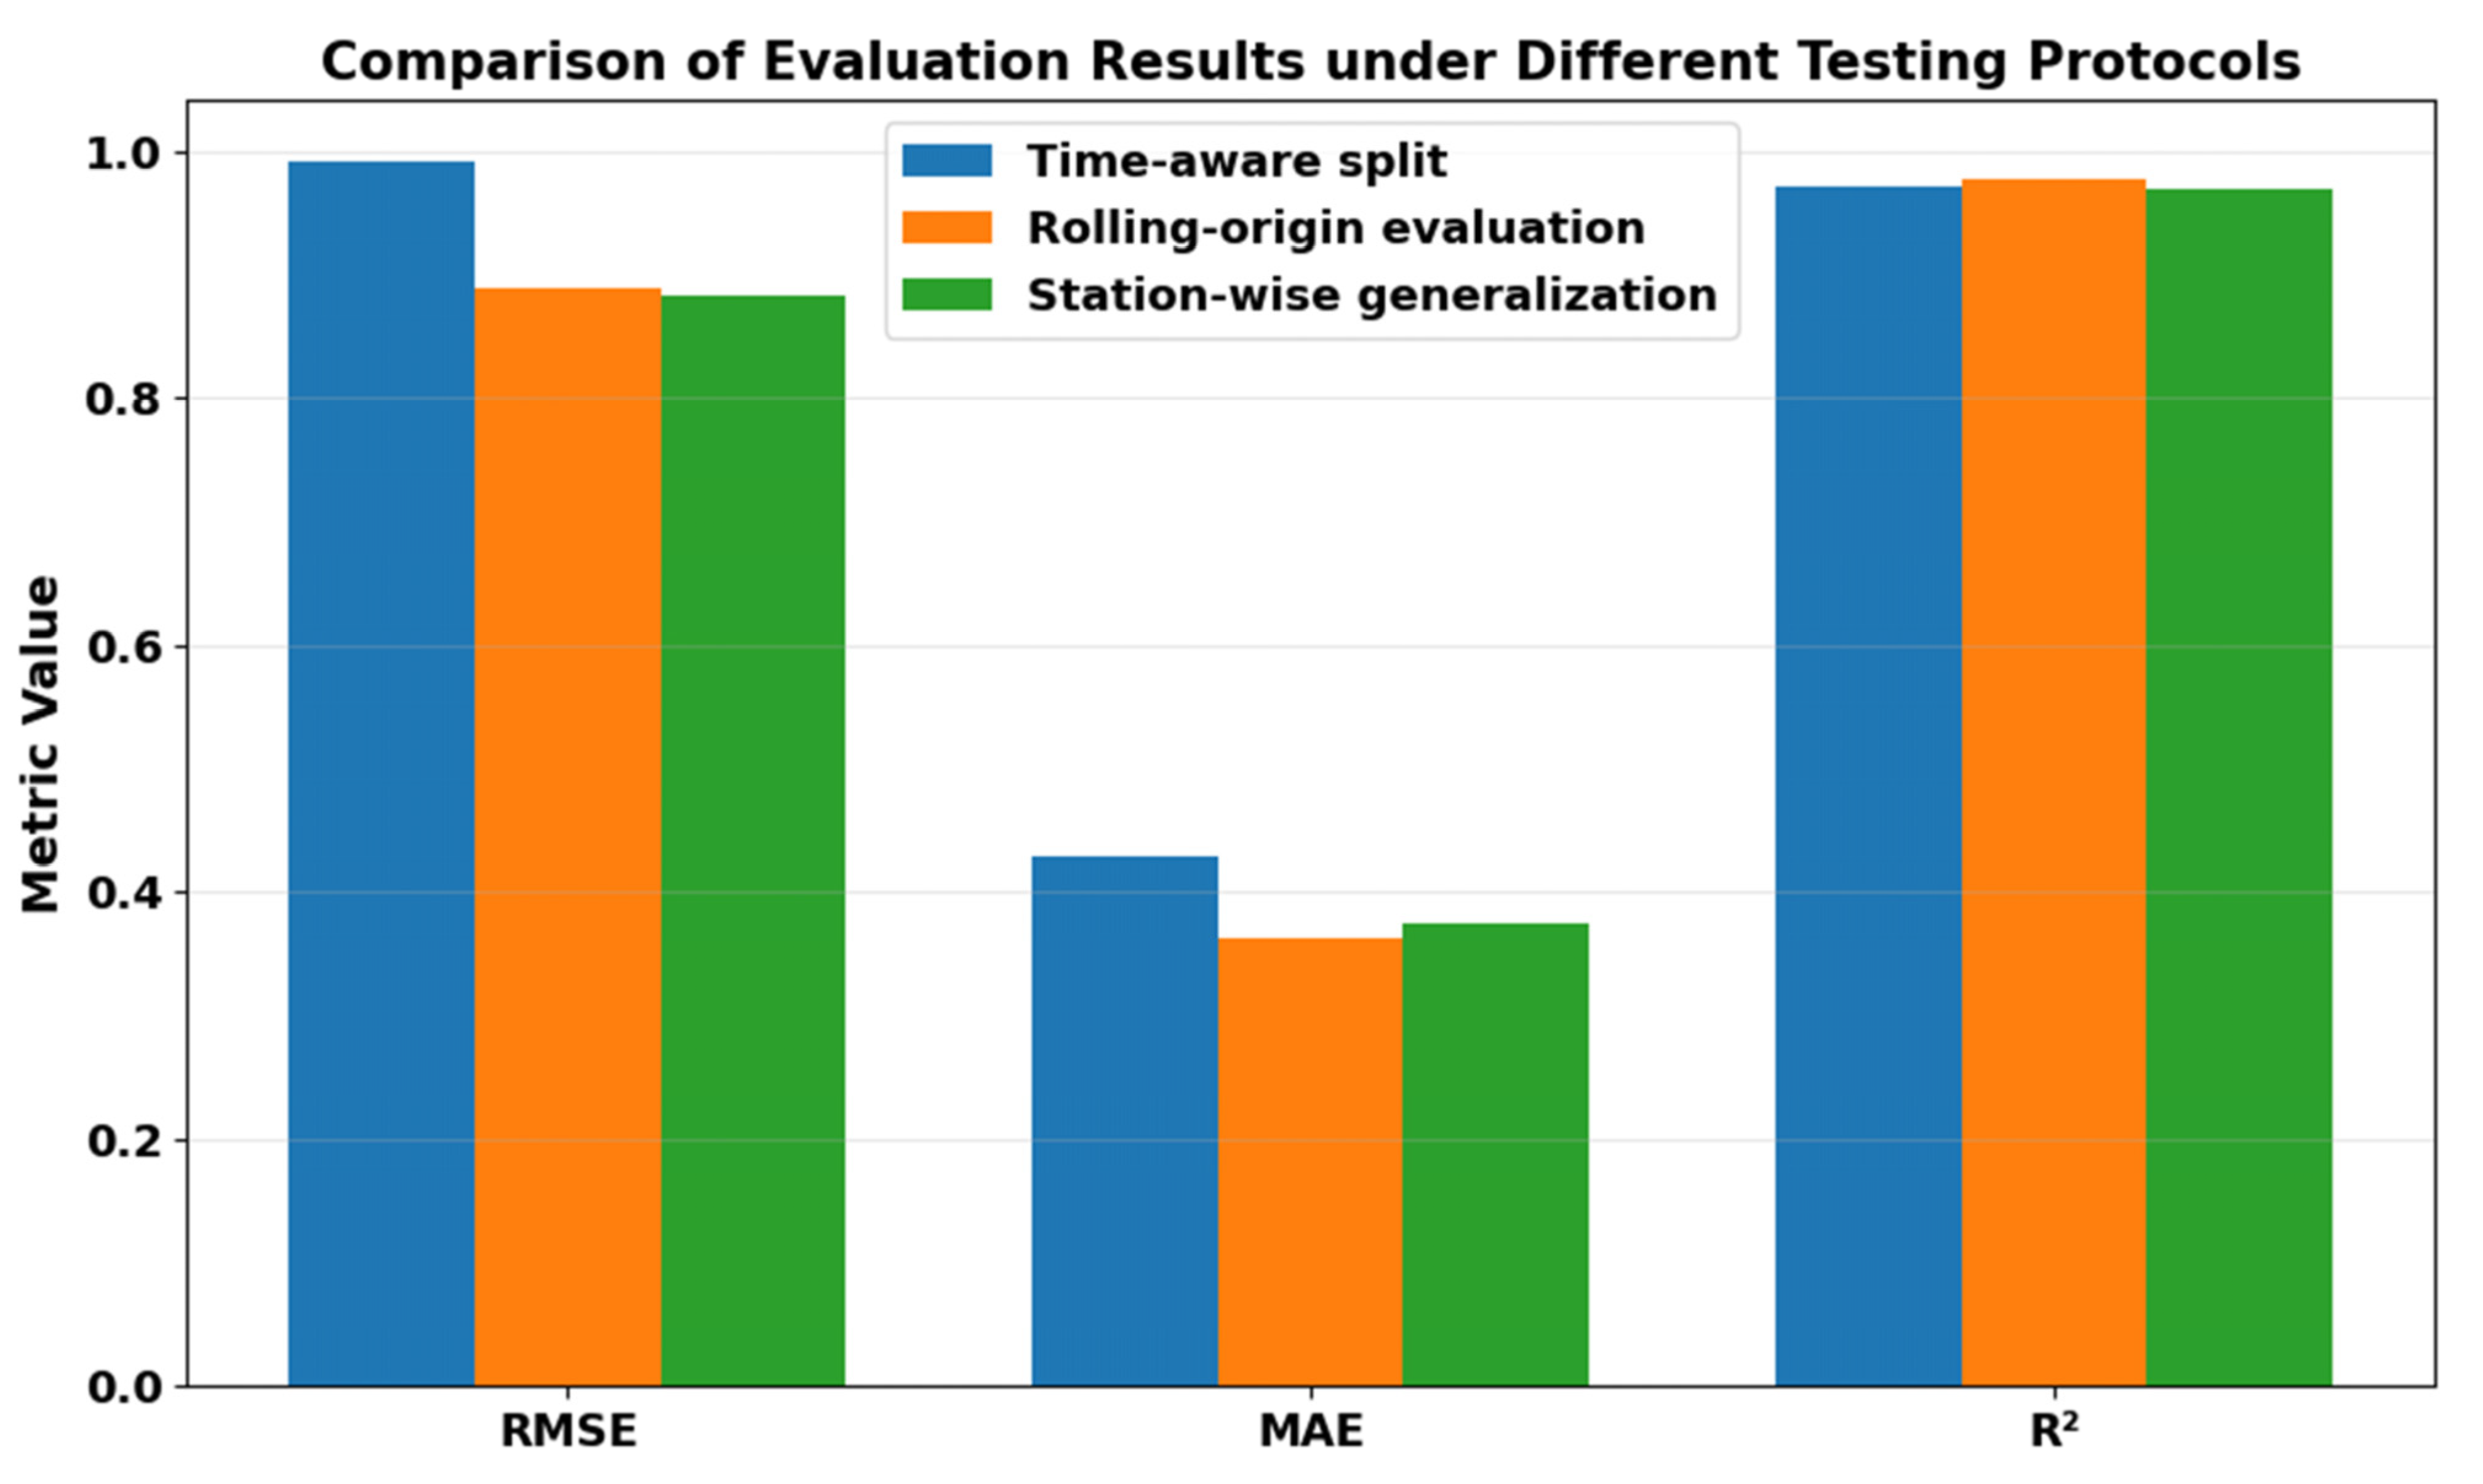
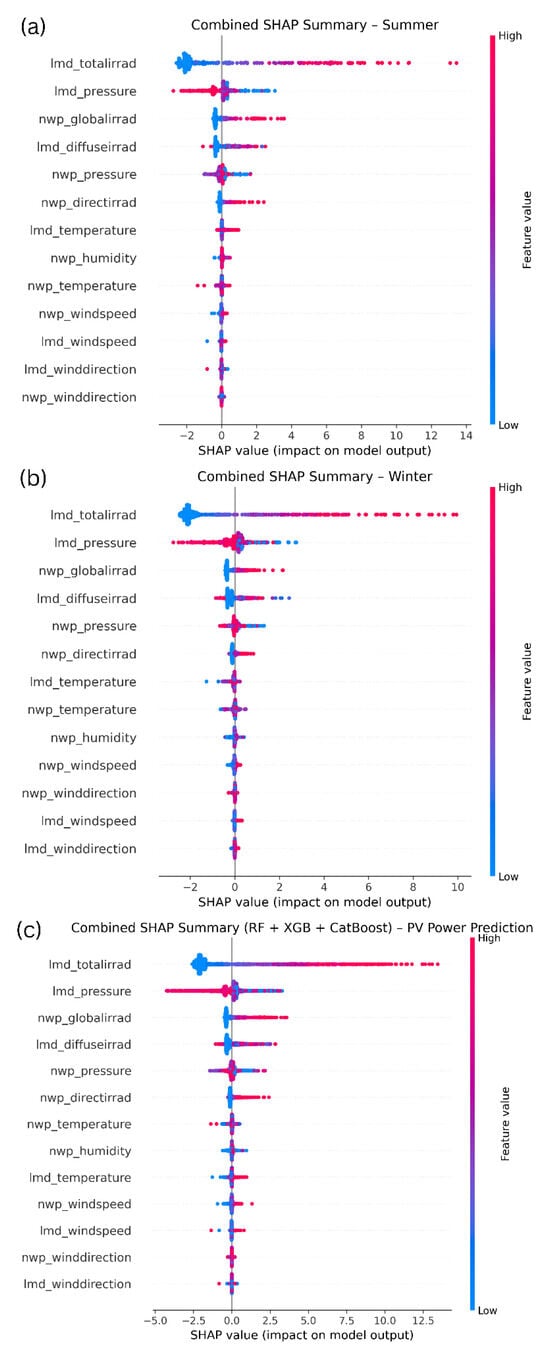
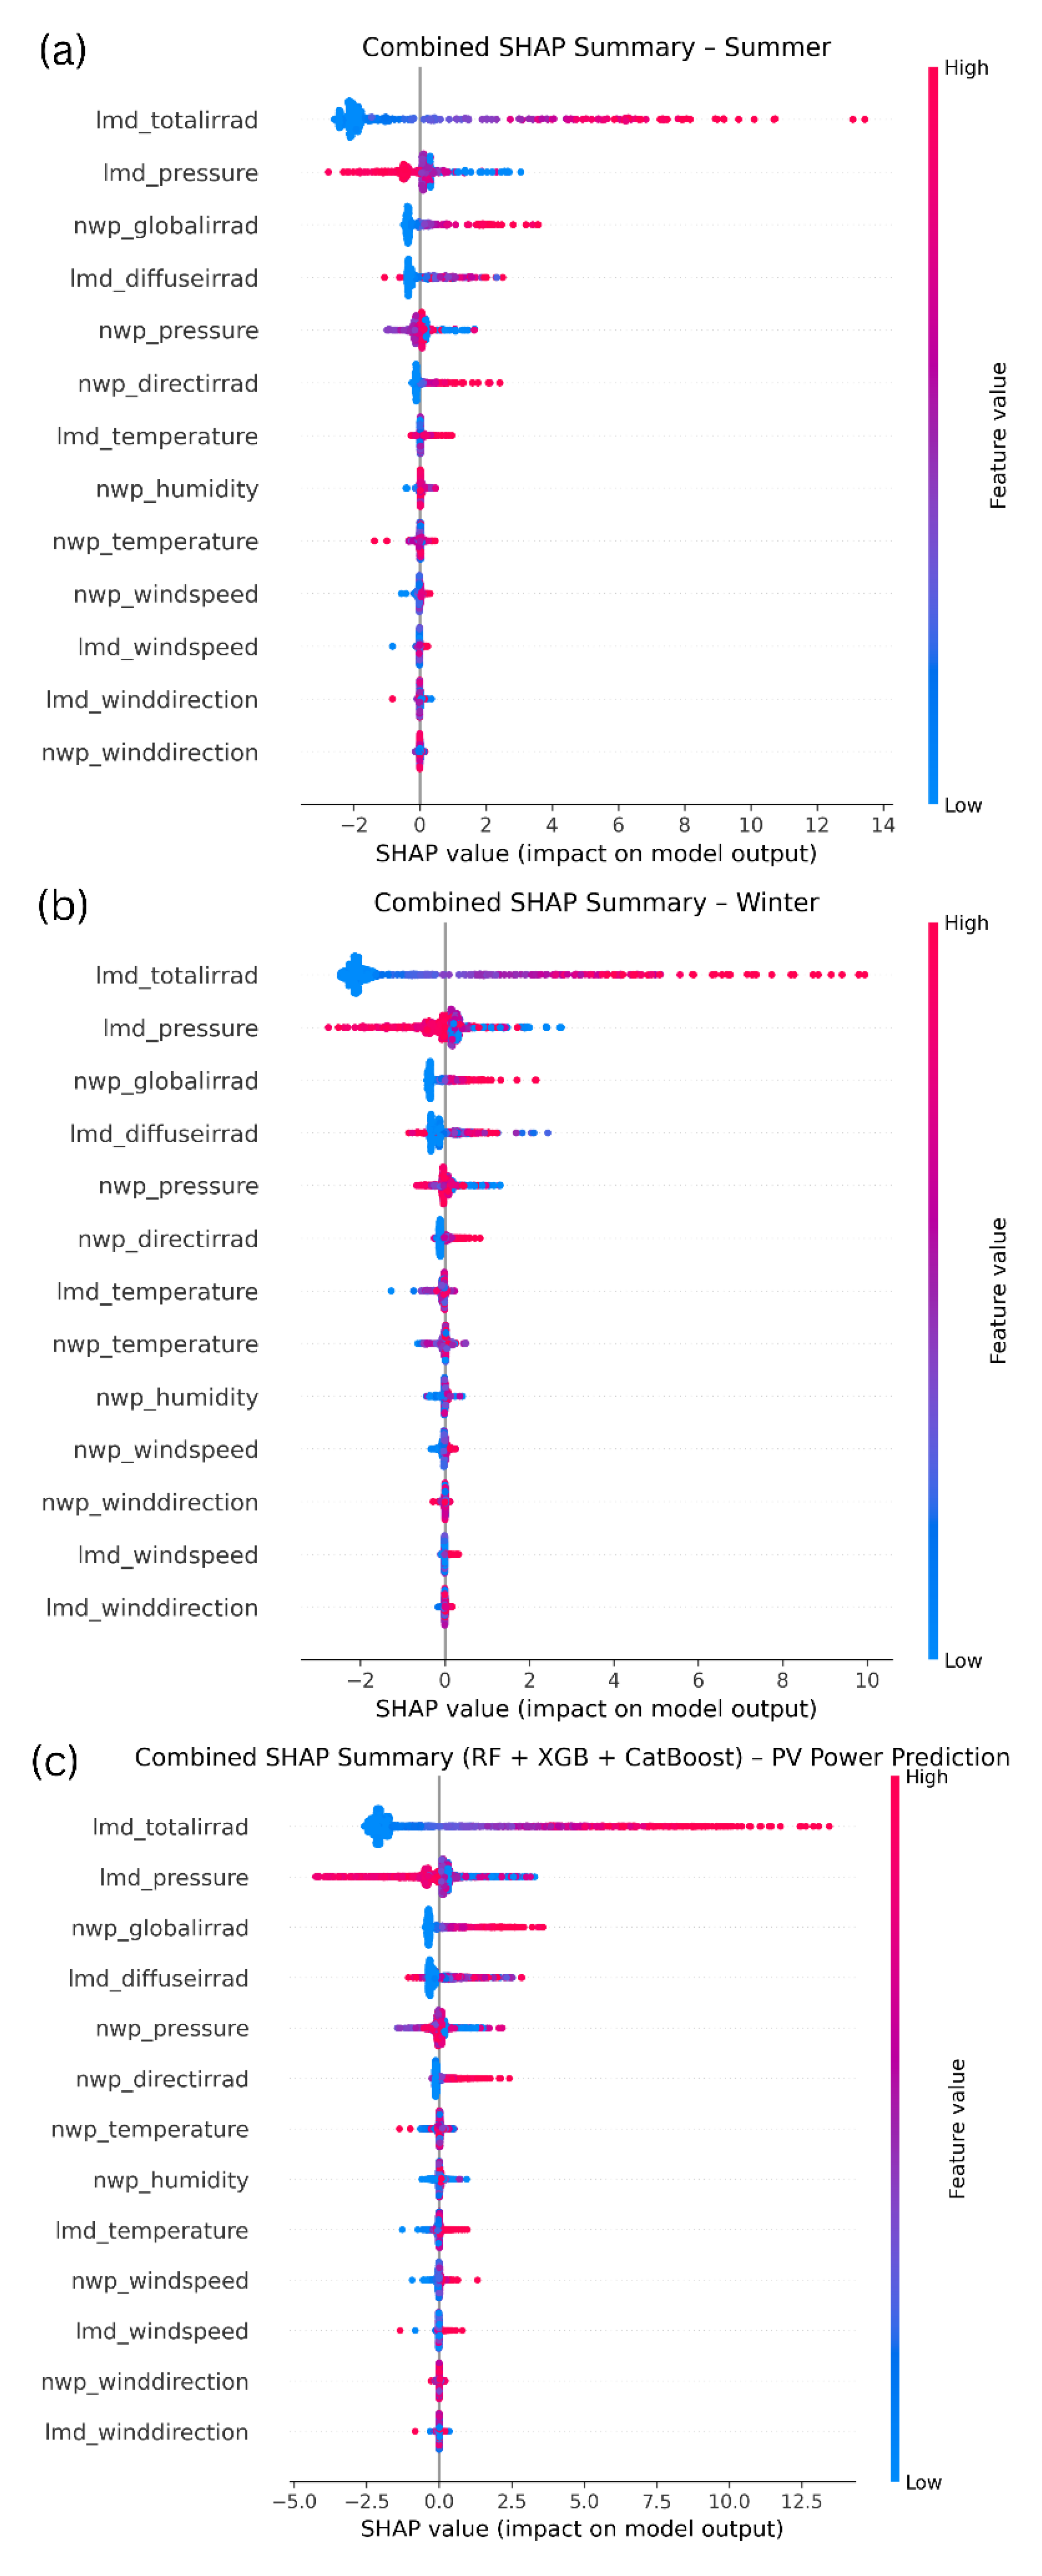

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.