


Abstract
High-precision satellite clock offset prediction is a core prerequisite for the BeiDou-3 Global Navigation Satellite System to achieve precise single-point positioning and timing. However, because of space radiation and the physical aging of the clock itself, the operational state of onboard atomic clocks exhibits a high degree of physical heterogeneity and time-varying drift characteristics. Traditional physical models struggle to capture complex nonlinear residuals, while existing deep learning methods often face boundary discontinuities caused by baseline separation when handling long-sequence forecasts. Furthermore, channel crosstalk in multivariate prediction and insufficient sensitivity to dynamic multiscale features limit the robustness of long-term predictions. To address these issues, this paper proposes a clock offset prediction architecture that integrates physically motivated statistical constraints with dynamic adaptive feature learning. Extensive experiments conducted using real BDS-3 precise clock difference products provided by Wuhan University demonstrate that the proposed method effectively mitigates the performance degradation often observed in existing models on heterogeneous satellites during the evaluated period. In the 24-h extrapolation task, the architecture achieved an average root-mean-square error as low as 0.507 ns, significantly improving prediction accuracy. It outperformed mainstream physical models and advanced deep learning baseline algorithms, providing a promising framework with good interpretability for high-precision clock error forecasting under dynamic space weather conditions.
1. Introduction
In modern global satellite navigation systems, high-precision, highly reliable positioning, navigation, and timing services are the cornerstones of efforts to maintain the operation of critical global infrastructure. With the full completion and launch of China’s BeiDou-3 Global Navigation Satellite System, its unique hybrid constellation architecture—combining medium-Earth orbit, inclined geosynchronous orbit, and geostationary orbit—along with the comprehensive deployment of new high-precision rubidium atomic clocks and passive hydrogen atomic clocks, provides exceptional navigation services to users worldwide. In GNSS precise point positioning (PPP), the spatial equivalent ranging error is highly sensitive to satellite clock anomalies, as the signal propagates at the speed of light. Consequently, an uncompensated time synchronization error of merely one nanosecond inherently translates to a pseudo-range error of approximately 0.3 m [1]. To achieve reliable centimeter-level kinematic positioning, establishing a robust sub-nanosecond clock bias prediction model is absolutely imperative. Due to the inevitable time lag in post-processed high-precision clock bias products released by organizations such as international GNSS services, the use of historical high-frequency clock bias data to perform high-precision, long-term dynamic predictions of future clock bias has become the most critical technology for overcoming the bottleneck in real-time PNT accuracy.
Lv et al. [2,3] point out that traditional predictions of atomic clock differences on board satellites largely rely on physical and empirical models such as quadratic polynomials, gray models, or standard Kalman filters. Although these methods can effectively fit the macroscopic long-term drift of clock error sequences, when dealing with high-frequency, non-stationary physical residuals caused by the space physical environment (such as severe temperature gradients and high-energy particle radiation), their prediction accuracy often degrades exponentially over time due to a lack of dynamic mapping capabilities for nonlinear characteristics [4].
To overcome the limitations of nonlinear representations in traditional physical models, Guo et al. [5] introduced wavelet neural networks, while our laboratory [6] proposed the BDS-3 clock error short-term prediction model based on singular spectral analysis and adaptive fuzzy neural networks. However, when spaceborne atomic clocks are exposed to space radiation over long periods, their aging drift parameters are not static but exhibit significant “concept drift.” The aforementioned shallow learning networks and some traditional autoregressive difference (ARD) time series models typically assign approximately equal weights to the entire historical observation window during training [7], neglecting the physical principle that “recent states play a crucial role in predicting short-term future trends.” This results in the models being unable to respond sensitively to the latest drift characteristics of atomic clocks during long-arm extrapolation, i.e., they struggle to overcome the challenge of time-varying lag in model weights [8].
In recent years, deep learning architectures—such as gated recurrent units (GRUs) and long short-term memory (LSTM) networks—have demonstrated significant potential in the GNSS field. Liu et al. [9] constructed a BDS-3 prediction model using an improved GRU network, while Cai et al. [10] and Ma et al. [11] proposed enhanced architectures—LSTM-Attention and CNN-LSTM-Attention, respectively—that incorporate self-attention mechanisms, effectively improving the ability to capture nonlinear local jitter features. However, given the BDS-3 system’s unique hybrid constellation architecture and heterogeneous clock types (high-frequency-drifting rubidium clocks and stable hydrogen clocks), current mainstream multi-source joint prediction mechanisms directly feed multiple heterogeneous satellites into a shared network, which can easily lead to feature crosstalk between channels [12,13]; simultaneously, due to the use of a single, fixed temporal receptive field, the network faces challenges in scale selection: a single, fixed receptive field struggles to simultaneously capture the local abrupt changes in high-noise satellites and fit the long-term trends of stable satellites [14].
Furthermore, with the widespread adoption of the Transformer architecture in the field of time series forecasting, Xie et al. [15] explored the SCITrans model—based on deep self-attention—for BDS-3 clock error prediction, while Zhou et al. [16] introduced highly representative long-sequence baseline architectures such as Informer. Although these state-of-the-art networks possess exceptional global macro-level insight, within the industry-standard decoupling framework of “physical baseline separation + residual prediction,” they have failed to effectively shield the physical starting phase from direct contamination by high-frequency transient noise at the endpoints. At the physical boundary between the end of the historical input window and the start of the future prediction, discontinuities and misalignments between the baseline and residuals are highly likely to occur. This discontinuous jump at the prediction boundary is gradually amplified during subsequent autoregressive long-term extrapolation, thereby significantly reducing the accuracy of long-term predictions.
Although traditional physical modeling methods (such as quadratic polynomial and harmonic function models) and emerging deep learning techniques (such as LSTM, Transformer, and their variants) have made some progress in the field of clock error prediction, existing prediction architectures still face three major bottlenecks that urgently need to be addressed, given the extreme complexity of the space environment and the highly dynamic nature of onboard clocks:
- “Scale conflict” caused by the physical heterogeneity of satellite-borne clocks:
The BDS-3 constellation not only features complex orbital types but also significant differences in the physical characteristics of atomic clocks operating in different media. Some satellites (such as C20) exhibit extremely high stability, requiring a macro-scale field of view to capture long-term trends; conversely, some satellites with high-frequency noise (such as C29) exhibit severe short-period jitter, requiring a micro-scale field of view to focus on local fluctuations. Existing deep learning networks based on a single time scale are highly prone to channel feature crosstalk when processing joint multi-variable inputs, which can lead to issues such as feature crosstalk in joint multi-variable prediction and insufficient multi-scale adaptability.
- 2.
- “Concept drift” caused by the time-varying nature of aging drift:
Spaceborne atomic clocks are continuously exposed to complex space radiation and rapid temperature gradients; consequently, their physical drift parameters are not static but undergo dynamic evolution over time. Traditional least-squares methods and conventional neural networks typically assign uniform weights to the entire historical window during training, ignoring the physical principle that “recent observational states have a critical influence on future physical evolution.” Consequently, they are highly prone to the “concept drift” issue in time series forecasting when extrapolating long sequences.
- 3.
- “Step-like discontinuities” in the prediction boundary caused by baseline separation:
Current state-of-the-art (SOTA) architectures generally adopt a decoupling strategy of “physical baseline fitting + AI residual prediction.” However, due to interference from high-frequency observation noise, a discontinuous misalignment between the baseline and residual phases is highly likely to occur at the junction between the end of the historical input window and the start of the future prediction window. Even sub-nanosecond-level jumps at the starting point can be rapidly amplified during long-period integral prediction, potentially causing the overall prediction error to diverge significantly.
To effectively address the aforementioned challenges, this paper proposes a novel hybrid prediction architecture called DRW-PatchTST (Dynamic Recency-Weighted Multi-Scale PatchTST with Physically Motivated Statistical Anchors). The main contributions of this paper can be summarized as the following four progressive innovations. While foundational techniques such as Weighted Least Squares (WLS), robust median filtering, Transformer architectures, and ensemble weighting are well-established, the core methodological contribution of this paper lies in their domain-specific synthesis and architectural adaptation tailored specifically to the complex physical constraints of the highly dynamic BDS-3 constellation:
- Input Layer:
A time-decay-weighted least-squares baseline decomposition mechanism is adapted. Rather than claiming WLS as a novel mathematical invention, our engineering adaptation introduces a strictly linear weight increase from 0.2 to 1.0 over the historical window. This specific boundary condition effectively resolves the concept drift of space environments by balancing the retention of long-term macroscopic physical memory (e.g., orbital periodicities anchored by the 0.2 lower bound) with the sensitivity required to track the recent temporal evolution of the atomic clocks.
- 2.
- Alignment Layer:
A physically motivated statistical boundary alignment strategy using micro-median anchors. To address boundary discontinuities without overclaiming physical PDE constraints, we adapt a robust statistical median operator over a strictly constrained 5.5-min micro-window. This specific window length acts as a physical boundary condition, assuming the macro-physical frequency drift remains constant while robustly filtering out transient local burst noise.
- 3.
- Feature Layer:
Introduces independent pure channels and a block-based attention mechanism. We treat the residual sequences of different tracks and satellite bodies as strictly independent sample pools, eliminating feature crosstalk and deeply exploring local high-frequency nonlinear semantics.
- 4.
- Fusion Layer:
A dynamic weighted ensemble strategy based on recency assessment and exponential smoothing. Unlike conventional global validation ensemble methods, our adaptation explicitly excludes “Stale Data” (the first 80% of the validation set) in favor of utilizing only the terminal 20% as “Recency Anchors.” By evaluating each scale-specific expert solely against these Recency Anchors and applying nonlinear exponential sharpening, the network adaptively assigns optimal receptive field weights for specific satellites.
2. Data Preprocessing
2.1. Introduction to WUM Precision Clock Differential Products
The experimental data in this paper are derived from high-precision, multi-system precise ephemeris and clock offset products provided by Wuhan University, a key analysis center for the International GNSS Service and the International GNSS Monitoring and Evaluation System. Compared to broadcast ephemeris, WUM’s post-processing precise clock offset products integrate data from a globally distributed network of continuously operating reference stations, offering exceptional stability and accuracy, and serving as a reliable benchmark for research on satellite clock offset modeling and forecasting.
This study focuses on the BeiDou-3 Global Navigation Satellite System, selecting operational satellites in both medium Earth orbit and inclined geosynchronous orbit as the subjects of analysis. To meet the input requirements of high-frequency deep learning models, the extracted clock offset data was resampled and aligned at a 30-s time resolution to construct a strictly equidistant time series. Considering that the clock offset data in the original .CLK files is measured in seconds and the values are extremely small, the data was uniformly scaled during the preprocessing stage and converted to the nanosecond range to prevent underflow or computational instability in the deep neural network during the backpropagation phase:
In the equation, represents the converted nanosecond-level satellite clock difference sequence; represents the clock difference observations in seconds from the original WUM high-precision clock difference product; and represents the time scale conversion factor. The converted high-frequency continuous time-series data will serve directly as the input reference for subsequent baseline decomposition and feature extraction.
2.2. Analysis of the Representativeness of the Experimental Period and the Space Weather Context
To comprehensively validate the generalization capability of the DRW-PatchTST model in complex space physics environments, this paper selected continuous high-frequency observational data from DOY 049 to 058 of 2026. The selection of this time period is based on two rigorous academic considerations: macroscopic environmental representativeness and microscopic temporal information density.
First, from the macroscopic perspective of space weather, 2026 falls near the peak of the 25th solar cycle, a period characterized by frequent solar flares and coronal mass ejections. To rigorously substantiate the complex geophysical conditions during our specific observation window, Table 1 details the daily averaged space weather indices retrieved from the NASA OMNIWeb database. As presented in Table 1, the selected 10-day period encapsulates a dynamic transition in the space environment rather than a strictly quiet baseline. Specifically, on DOY 52, a notable enhancement in solar wind proton density (8.2 N/cm3) was observed, immediately followed by a surge in solar wind plasma speed, peaking at 669 km/s on DOY 54. This high-speed stream triggered a clear geomagnetic disturbance: the planetary Kp index escalated to an active level of 4.3 on DOY 53, accompanied by a synchronous depression in the Dst index down to −21 nT. Furthermore, the F10.7 solar radio flux exhibited a continuous upward trend, reaching 135.9 sfu. These quantitative metrics confirm that the experimental period encompassed a complete cycle of geomagnetic perturbation. The model’s ability to maintain a stable sub-nanosecond RMSE (0.51 ns) across this magnetically unsettled period provides robust evidence that the dynamic ensemble mechanism effectively adapts to space weather perturbations without performance degradation.
Table 1.
Daily averaged space weather and geomagnetic indices during the experimental period (DOY 049–058, 2026).
Second, in terms of temporal information density and microscopic physical characterization, although the experimental duration was 10 days, the extremely high sampling frequency of 30 s yielded a massive sample size of 28,800 epochs per satellite. Compared to traditional low-frequency products (such as 5- or 15-min intervals), this high-frequency dense sampling preserves the high-frequency random walk noise and transient phase-jump characteristics inherent in atomic clocks without loss of information. This provides the indispensable micro-level data foundation for verifying the “micro-median anchor’s” resistance to transient noise and the small-scale Patch experts’ ability to capture localized anomalies.
2.3. Robust Smoothing and Denoising Strategy Based on MAD and S-G Filtering
During satellite operations in orbit, the onboard atomic clock is highly susceptible to interference from complex hardware and environmental factors, such as space electromagnetic radiation, temperature gradients, and satellite-ground link anomalies. This inevitably introduces sporadic large-amplitude errors and high-frequency measurement noise into the raw clock error sequence. If raw data contaminated with extreme values is directly fed into the prediction network, it will severely mislead the network’s fitting of the physical clock drift trend. To address this, this paper designs a three-stage robust preprocessing pipeline comprising “outlier removal, interpolation reconstruction, and high-frequency filtering.”
- Stage 1: Outlier Removal Based on Median Absolute Deviation
Traditional criteria are highly susceptible to the influence of extreme outliers when calculating the mean and standard deviation, which can lead to detection failure. This paper introduces a more robust median absolute deviation (MAD) algorithm for outlier identification [17]. For the independent clock error time series of any satellite, the MAD is defined as the median of the absolute deviations of each data point from the median:
Assuming that a sequence without outliers follows a normal distribution, this paper defines the outlier detection threshold as:
In the equation, represents the equidistant clock error time series for a specific satellite; is the time-series observation at the i-th epoch in this series; is the robust statistical operator used to calculate the median of the series; MAD is the median absolute deviation calculated; is the dynamically determined threshold for coarse-grained discrimination; 0.6745 is the scaling factor for mapping MAD to standard deviation under the assumption of a normal distribution; k is the strictness control coefficient, which is set to 5 in this paper based on empirical observations and multiple experimental tests.
If the absolute value of the deviation of the observed value from the median is greater than , i.e., , the data point is deemed an outlier and set to a missing value (NaN).
- Stage 2: Cubic Spline Interpolation and Time Series Reconstruction
Since the network input strictly requires equidistant continuity, this paper employs cubic spline interpolation to reconstruct the time series for isolated missing points removed by MAD or for local observation gaps inherent in the data files. Compared to simple linear interpolation, cubic spline interpolation not only ensures the continuity of the interpolated data in terms of function values but also guarantees smooth transitions in its first- and second-order derivatives, thereby maximizing the restoration of the dynamic physical evolution characteristics of the atomic clock. For isolated missing data at the very beginning or end of the sequence, forward/backward padding is applied to ensure temporal completeness.
- Stage 3: Savitzky–Golay (S-G) Filtering to Remove High-Frequency Noise
The sequence, after outlier removal, still contains a significant amount of broadband high-frequency fluctuations caused by receiver thermal noise. Conventional moving-average filtering, while smoothing out the noise, severely attenuates the physical amplitude and high-frequency phase boundaries of the original signal. Therefore, this paper employs the Savitzky–Golay filter [18] for final robust smoothing. The S-G filter is essentially a time-domain smoothing algorithm based on local polynomial least-squares fitting, capable of effectively suppressing high-frequency noise while preserving the local peaks, troughs, and phase width characteristics of the original clock offset signal. In this experiment, after multiple rounds of optimization and comparison, the sliding window length of the S-G filter was set to 51 epochs, and the degree of the fitting polynomial was set to 3. Following this third-order robust processing, a high-quality satellite clock difference time series was ultimately produced, which is clean and retains its core physical characteristics.
As shown in Table 2, the post-processed WUM precise clock offset products exhibit exceptionally high data quality. Among the 26 satellites analyzed over the 10-day period (28,800 epochs per satellite), the vast majority experienced zero data loss and required zero outlier removal by the Algorithm 1 Only three satellites (C36, C39, and C44) contained original missing data, with the maximum missing rate being merely 0.1007% (C44). The longest continuous interpolated gap was 29 epochs (equivalent to 14.5 min) for C44. Additionally, data integrity for specific constellation structures, such as C40 operating as an IGSO satellite, remained pristine at 100%. This extremely low proportion of interpolated points guarantees that the deep learning architecture is fitting the true physical evolution of the atomic clocks rather than the mathematical trajectories of the cubic spline interpolation. Furthermore, the high fidelity of the uncorrupted data sequence ensures the reliability of the fusion layer, which strictly utilizes the recent 20% of the validation set as recency anchors to dynamically assign optimal expert weights.
| Algorithm 1: Robust Preprocessing Pipeline for Satellite Clock Bias | |
| Input: Raw clock bias sequence for a specific satellite | |
| Output: Cleaned and robustly smoothed sequence | |
| 1 | Resample to a strictly equidistant 30-s interval |
| 2 | Calculate the median of the sequence: |
| 3 | Calculate Median Absolute Deviation: |
| 4 | for each data point in do |
| 5 | if then |
| 6 | (Identify and mark as extreme outlier) |
| 7 | end if |
| 8 | end for |
| 9 | Apply Cubic Spline Interpolation (Order = 3) to reconstruct NaN points |
| 10 | Apply Savitzky–Golay Filter (Window Length = 51, Polynomial Order = 3) to suppress high-frequency thermal noise |
| 11 | return |
Table 2.
Statistics of Missing Data and Outliers Removed during Preprocessing for 26 BDS-3 Satellites (Epochs = 28,800).
3. DRW-PatchTST Architecture
3.1. Time-Decay Weighted Least Squares and Micro-Median Anchors
3.1.1. Time-Decayed WLS for Baseline Decomposition
Traditional physical baseline decomposition of clock offsets typically employs Ordinary Least Squares (OLS), which assumes that all observations within the historical window carry equal weight in guiding future drift trends. However, due to the dynamic effects of onboard equipment aging and spatial temperature gradients, the recent evolution of atomic clocks plays a dominant role in predicting short-term future trends. To address this, this paper proposes a time-decay weighted least-squares (WLS) mechanism to extract the physical trend.
For an observation at epoch , the physical baseline is formulated as a composite model consisting of a quadratic polynomial and two-level harmonic terms:
where represents the time offset from the reference epoch . Consequently, for each epoch i, the corresponding row vector in the design matrix is fully specified as:
where is the fundamental angular frequency. While this functional basis remains consistent across the constellation, the harmonic constraint T is strictly tailored to the specific orbital dynamics of different satellite types. For IGSO and GEO satellites, T is set to 23.93 h, corresponding to one sidereal day. For MEO satellites, T is defined as 12.89 h, derived from Kepler’s Third Law () based on the semi-major axis () specified in the BDS-3 Interface Control Document (ICD).
To ensure the physical baseline tightly anchors to the latest hardware state, we introduce a time-decay diagonal weight matrix :
where represents the weight value for the i-th time step, and N is the total length of the historical window. The physical baseline parameter vector is then calculated as follows:
where is the input clock offset observation vector.
Regarding the specific distribution boundaries of the weight sequences in , this paper adopts a strictly linear increasing strategy: . The weight of the most recent observation is set to the maximum value of 1.0, while the lower bound for the oldest historical data (i.e., 24 h ago) is set to 0.2. This parameter configuration is based on globally optimal hyperparameters obtained through a rigorous grid search (range [0.0, 0.5], step size 0.05).
The underlying physical and mathematical logic is as follows: If approaches 1.0, the WLS degenerates into a traditional OLS model, failing to capture the “concept drift” dominated by recent states. Conversely, if is set too close to 0.0, it leads to the attenuation or loss of long-period physical constraint information. This causes the design matrix to become ill-conditioned due to a lack of support from long-term data, rendering the baseline decomposition overly sensitive to recent local fluctuations and resulting in overfitting. Therefore, the lower limit of 0.2 serves as a critical “long-range physical memory retention threshold.” It forces the baseline to align with the latest drift trends while precisely anchoring the core orbital harmonic constraints, achieving an optimal balance between macroscopic periodicity and microscopic time-varying behavior.
While the current model employs a strictly linear weight transition from 0.2 to 1.0, we acknowledge that the optimal decay characteristic may be intrinsically linked to the clock type. Physically, the high stability of hydrogen clocks favors a more gradual weight decay to preserve long-term periodicity, whereas the “concept drift” inherent in rubidium clocks—driven by space environmental sensitivity—may theoretically benefit from nonlinear (e.g., exponential) decay to prioritize the most recent physical states.
In our preliminary experiments, we conducted a grid search comparing linear, quadratic, and exponential weight functions. The results indicated that while nonlinear functions slightly improved tracking for certain high-noise rubidium satellites (e.g., C21), the linear strategy provided the most robust overall average performance across the entire hybrid constellation. It prevents the “over-smoothing” of long-term harmonic constraints in hydrogen clocks while maintaining sufficient sensitivity for rubidium drift. Therefore, 0.2 was selected as a universal “long-range physical memory retention threshold” to balance these heterogeneous requirements.
3.1.2. Physically Motivated Statistical Anchor Boundary Alignment
After separating the physical trend from the nonlinear residuals, due to the inherent presence of high-frequency observation noise, the end of the fitted baseline often fails to coincide with the end of the actual observation sequence, thereby causing a small yet significant “step jump” at the start of the forecast. If simple single-point alignment or long-window averaging alignment is used, the phase is easily biased by burst noise (such as high-noise satellites like C24 in the BDS-3 system).
Therefore, this paper proposes a micro-median anchor mechanism, which involves extracting a reasonable micro-window before the prediction start point and calculating the absolute translation between the true observation sequence and the physically fitted trend within that window:
In the equation, represents the calculated absolute offset of the reference starting point; represents the observed sequence of true robust clock errors within the historical input window; represents the physical trend reference sequence obtained through WLS analysis; The subscript [-m:] denotes the m most recent time-step observations at the end of the sequence (in this paper, m is set to 11, corresponding to a 5.5-min micro-physical window prior to the prediction start point); is the median filter operator, used to immunize the alignment offset against contamination by local high-frequency impulse noise.
In setting the length m of the micro-anchor window, this paper faces a trade-off between “filtering out random high-frequency noise” and “avoiding the introduction of smoothing-induced phase lag.” Since the sampling rate of the clock error data in this paper is 30 s, selecting an extremely short window—while resulting in minimal absolute time delay—would yield a sample size insufficient to statistically support the median operator’s robustness against extreme outliers, making it highly susceptible to being compromised by sporadic consecutive high-frequency glitches. Conversely, while a larger window offers extremely strong noise resistance, the actual physical frequency drift of the atomic clock may have undergone a slight change in slope within this time span. An excessively long historical window would introduce a non-negligible smoothing effect due to phase lag, undermining the original intent that “the prediction starting point must reflect the latest current state.”
To this end, this paper employs grid search and control variable ablation in preliminary experiments to ultimately narrow the micro-window down to exactly time steps. 11 is an odd equilibrium point that balances statistical robustness with micro-physical timeliness. It ensures that the physical state of the atomic clock can be approximated as constant on a macroscopic scale within the window, while also ensuring that when the duration of sporadic transient noise is less than 2.5 min, the median operator can effectively mitigate its impact with high confidence, thereby achieving pure, zero-delay boundary alignment.
It is crucial to clarify that while the median operator itself is a standard robust statistical tool, its application in this architecture is “physically motivated” precisely due to the strict temporal boundary imposed by (corresponding to a 5.5-min micro-physical window). This specific window size enforces a rigorous physical constraint: it is short enough to assume that the macroscopic physical frequency drift state of the rubidium or hydrogen clock remains essentially constant, yet long enough to statistically support the median operator’s resistance against transient extreme outliers. By confining the statistical alignment purely to this physically stable micro-window, the mechanism actively prevents the introduction of smoothing-induced phase lag while effectively filtering out high-frequency receiver thermal noise.
3.2. The Independence of Pure Channels and the Blocked Self-Attention Mechanism
3.2.1. Pure Channel Independence Mechanism
The BDS-3 constellation combines MEO and IGSO orbits and carries rubidium and hydrogen clocks with vastly different physical characteristics. Traditional multivariate time series forecasting treats all satellites as a single input, attempting to uncover inter-satellite correlations.
An intuitive alternative might be “group-wise independence” (e.g., grouping satellites by orbit type or clock type) to capture shared environmental stressors such as temperature gradients or space radiation specific to an orbital plane. However, in the DRW-PatchTST architecture, we deliberately adopt a strictly Pure Channel-Independent (CI) strategy.
This design choice is rooted in our two-stage decoupling framework. The macroscopic physical commonalities shared by satellites in the same orbit (e.g., the 12.89-h MEO and 23.93-h IGSO orbital periods) are already effectively extracted and modeled by the Time-Decay WLS physical baseline in the preceding stage. Consequently, the isolated residual sequences fed into the Transformer are predominantly driven by highly individualized microscopic physical factors—such as specific hardware aging progression, localized thermal micro-environments, and random walk noise.
Attempting to group these highly idiosyncratic residuals could inadvertently reintroduce channel crosstalk, causing the model to learn spurious inter-satellite correlations rather than the genuine physical evolution of a specific clock. By flattening the multivariate sequence from C satellites into C independent univariate sequences sharing the same Transformer backbone weights, the network is forced to learn universal local nonlinear periodic semantic information without crosstalk, while simultaneously expanding the training sample size by a factor of C.
3.2.2. Transformer Encoder and the Patching Mechanism
For univariate sequences from which the pure residuals have been extracted, the network first uses RevIN (Reversible Instance Normalization) to eliminate dimensionality differences, and then employs patching techniques to divide the one-dimensional sequence into overlapping or non-overlapping data blocks of length and step size .
This operation not only preserves the local physical semantics of the residual signal but also drastically reduces the sequence length fed into the Transformer from to , causing the model’s computational complexity to plummet from to . After linear projection and positional encoding, the block-based feature vectors are fed into a multi-layer Transformer Encoder module. Through the self-attention mechanism, the model can capture long-range, high-frequency dependencies between microscopic data blocks with a broader receptive field, thereby achieving efficient fitting and extrapolation of complex nonlinear residuals. The internal structure of the Pure CI-PatchTST model is shown in Figure 1:
Figure 1.
Diagram of the internal structure of the Pure CI-PatchTST model.
3.3. Dynamic Recency-Weighted Ensemble Based on Recency Assessment and Index Sharpening
Because satellite-based clocks exhibit heterogeneous temporal evolution patterns, a fixed patch size often leads to “scale conflicts.” For example, stable satellites require a large scale to capture long-term trends, while high-noise satellites require a small scale to track local fluctuations. To address this, this paper constructs a system incorporating multiple spatial resolutions and proposes a fully data-driven dynamic adaptive weighting mechanism.
The core challenge in multi-scale prediction for heterogeneous BDS-3 clocks lies in the adaptive selection of the optimal observation scale. In this study, we define ‘Recency’ as the terminal phase of the validation sequence that immediately precedes the forecast horizon. This specific temporal window represents the most immediate hardware state and physical drift characteristics of the onboard atomic clocks.
The proposed Dynamic Recency Weighting (DRW) mechanism adaptively allocates expert weights based on this Local Recency Evaluation. By focusing the performance assessment on this proximate window rather than the global historical average, the ensemble logic is strictly driven by the clock’s current operational regime. This approach effectively mitigates the interference from stale historical states, allowing the model to respond swiftly to sudden frequency shifts or environmental perturbations.
3.3.1. Local Validation Assessment of Immediate Causes
Conventional model ensembling typically relies on the global mean squared error of the entire validation set to assign weights. However, during the long-term operation of spaceborne atomic clocks, their error distribution exhibits severe time-varying characteristics (i.e., concept drift). To ensure the ensemble evaluation strictly reflects the most current physical state, this paper proposes a “recency assessment” strategy. In our architectural adaptation, we actively discard the “Stale Data” (representing the first 80% of the validation set) and utilize solely the terminal 20% of the data closest to the prediction window as “Recency Anchors”. For any given satellite, the local mean squared error of an expert model evaluated strictly against these Recency Anchors is defined as:
In the equation, represents the local mean squared error metric of the i-th scale expert network on the near-term validation set of the s-th satellite; is the total duration of the near-term validation set; in this paper, it is set to 20% of the end of the global validation set to ensure that the evaluation benchmark closely reflects the latest state of “concept drift”; and represent the residual prediction values and the true residual target values, respectively, output by the i-th expert model at time step t in the near-term validation set.
3.3.2. Power-Law Nonlinearity Index Sharpening
To dynamically integrate the predictive distributions from the K multi-scale experts, we evaluate their local prediction accuracy on the terminal 20% of the validation set (defined as the recency window). Let denote the Mean Squared Error of the k-th scale expert evaluated strictly within this recency window.
In conventional inverse-error weighting, an extremely small prediction error can cause the denominator to approach zero, leading to severe numerical instability. To strictly prevent this, a small regularization constant is introduced. Furthermore, instead of using a standard linear inverse penalization, we employ a power-law sharpening exponent to induce a “weight polarization” effect. This mathematically forces the ensemble to aggressively decay the interference from mismatched experts while assigning monopolistic dominance to the best-matching scale.
The non-normalized dynamic weight for the k-th expert is rigorously defined as:
where the regularization term is empirically set to to ensure absolute numerical robustness under high-precision residual fitting. The sharpening exponent is designated as a controllable hyperparameter and is set to 2 in our primary architecture. (A comprehensive sensitivity analysis regarding the choice of and comparisons with alternative weighting mechanisms, such as Softmax or learned gating, are detailed in Section 4.6).
Subsequently, the raw dynamic weights are normalized across all K parallel experts using standard normalization to yield the final ensemble weights :
Ultimately, the final ensembled clock bias residual is computed as the weighted summation of the individual expert predictions . The complete training and inference procedure of this dynamic recency-weighted multi-scale architecture is summarized in Algorithm 2:
| Algorithm 2: Dynamic Recency-Weighted (DRW) Ensemble Training and Inference | |
| Input: Preprocessed dataset D, Set of spatial resolution patch experts K = {24, 32, 48, 64, 96} | |
| Output: Final extrapolated clock bias prediction | |
| 1 | Chronologically split D into Model Building Domain (Days 1–9) and Blind Test Domain (Day 10) |
| 2 | Split Model Building Domain into Training Set (first 80%) and Validation Set (last 20%) |
| 3 | for each scale expert k ∈ K do |
| 4 | Train the independent CI-PatchTST model on the Training Set |
| 5 | Evaluate local Mean Squared Error on the terminal 20% of the Validation Set for each satellite s |
| 6 | end for |
| 7 | for each satellite s do |
| 8 | Compute dynamic ensemble weights via power-law sharpening based on (using Equation (9)) |
| 9 | Compute ensemble residual prediction: |
| 10 | end for |
| 11 | Reconstruct final prediction by adding physical baseline: |
| 12 | return |
4. Experiments and Analysis of Results
4.1. Experimental Setup and Evaluation Criteria
Dataset Construction and Parameter Settings: In this experiment, the BeiDou-3 high-precision clock offset product provided by the Analysis Center at Wuhan University was used. Continuous observation data from the 49th to the 58th day of 2026 (10 days in total) were extracted. To ensure full computational reproducibility—addressing the complex physical heterogeneity of the constellation—the detailed inclusion/exclusion criteria, the explicit list of the 26 selected satellites, and the core hyperparameters for robust preprocessing are comprehensively summarized in Table 3. After robust denoising and resampling to 30-s intervals based on these configurations, the total sequence length for each satellite reached 28,800 epochs.
Table 3.
Summary of dataset configurations and robust preprocessing parameters.
To rigorously evaluate the model’s generalization capability and strictly prevent data leakage from the future horizon, the 10-day dataset was divided into an independent Model Building Domain and a Blind Test Domain chronologically:
Model Building Domain (Day 1 to Day 9): The first 25,920 epochs were used exclusively for model training and validation. Through a sliding window approach (with input sequence length and forecast length , the generated samples within this 9-day domain were strictly divided into a training set and a validation set in an 8:2 ratio, following the temporal split protocol detailed in Algorithm 2. It is important to emphasize that the dynamic ensemble weights of the multi-scale experts were computed using only the terminal 20% of this validation set, ensuring that the weights were determined prior to the final test phase.
Blind Test Domain (Day 10): The last 24 h (Epochs 25,920 to 28,799) served as a completely independent test set. During testing, the model used the actual observations from the last 24 h of Day 9 as the final input window to extrapolate the subsequent 12-h and 24-h clock offsets. The reported RMSE and MAE metrics in this paper were evaluated exclusively on this unseen Day 10 dataset. No information from the test set was exposed to the model during training or weight selection.
The ensemble module comprises five Patch experts with different spatial resolutions (patch sizes of 24, 32, 48, 64, and 96). All experiments were run on the same hardware platform. Figure 2 illustrates the strict temporal split protocol of the dataset.
Figure 2.
Temporal split protocol of the experimental dataset.
Evaluation Metrics: To objectively quantify the deviation between the predicted values and the actual precision clock readings, this paper selects Root Mean Square Error (RMSE) and Mean Absolute Error (MAE) as the core evaluation metrics. Their mathematical definitions are as follows:
In the equation, N represents the total length of the extrapolated prediction sequence as defined by the model; denotes the true WUM precise clock offset observation corresponding to the t-th future prediction epoch; and represents the final clock offset prediction output by the DRW-PatchTST hybrid architecture described in this paper.
To ensure an objective and rigorous assessment of the model’s true forecasting capability rather than the efficacy of the denoising procedure, it is important to clarify that the evaluation metrics (RMSE and MAE) are computed strictly against the original WUM precise clock offset series. Specifically, the ground truth used in Equations (13) and (14) represents the raw observations after the initial MAD outlier removal but strictly prior to any Savitzky–Golay high-frequency filtering. Therefore, the reported accuracy reflects the model’s inherent ability to predict actual, noisy physical clock bias trajectories rather than a simplified, artificially smoothed curve.
Model Hyperparameters and Training Protocol: To ensure full computational reproducibility and transparency, the hardware environment, random seeds, and architectural hyperparameters for all models are strictly unified. The training protocol was implemented using PyTorch (version 2.8.0) on a single NVIDIA GPU. To prevent optimization bias, a standardized random seed (seed_everything = 42) was globally applied. For our multi-scale ensemble module, the independent experts were initialized with deterministic variant seeds (42 + ensemble_id × 10) to ensure diverse yet reproducible weight initializations.
The core hyperparameters and the tuning procedures are detailed in Table 4. All deep learning baselines share the identical optimizer, learning rate scheduler, and early stopping criteria to maintain strict experimental fairness.
Table 4.
Comprehensive Hyperparameters and Training Protocol for Evaluated Models.
4.2. Overall Performance Comparison Under Fair Baselines
To comprehensively and objectively validate the superiority and robustness of the DRW-PatchTST architecture under real-world complex constellation environments, we established a strict “Fair Baseline” evaluation protocol. To eliminate the potential bias introduced by data preprocessing and to precisely isolate the contribution of the neural network architectures, all selected deep learning baselines were equipped with the exact same Time-Decay WLS physical baseline separation step. The evaluated models include the classic recurrent neural network (WLS + LSTM), the benchmark for long-sequence prediction (WLS + Informer), and the channel-independent basic patch-based attention network (WLS + Basic-PatchTST).
Table 5 and Table 6 present the root mean square error (RMSE) statistics for each model in 12-h and 24-h extrapolation tasks, respectively, providing a detailed decoupling analysis for the MEO and IGSO orbits specific to the BeiDou-3 system. Additionally, Figure 3 and Figure 4 visually illustrate the absolute accuracy performance of different models for individual satellites.
Table 5.
Comparison of 12-h forecast accuracy (RMSE and MAE, units: ns).
Table 6.
Comparison of 24-h forecast accuracy (RMSE and MAE, units: ns).
Figure 3.
Comparison of per-satellite RMSE performance across different forecast models for a 12-h forecast window.
Figure 4.
Comparison of per-satellite RMSE performance across different forecast models for a 24-h forecast window model.
Based on the strict “Fair Baseline” evaluation protocol—where all deep learning models are equipped with the identical time-decay WLS physical baseline separation step to purely isolate and evaluate their residual prediction capabilities—we can draw the following insightful conclusions from the detailed quantitative results presented in the updated tables and figures:
- Comparison with the Pure Physical Model:
Although the pure physical baseline (OLS) can capture the macroscopic low-frequency harmonic trends of clock differences, the quantitative results show it maintains relatively large overall errors, with its 24-h overall RMSE and MAE reaching 2.053 ns and 1.675 ns, respectively. Analysis of the satellite-level bar charts reveals that the error of the pure physical model increases significantly when dealing with residual sequences containing a large amount of nonlinear micro-jitter (e.g., the error spikes on specific high-noise satellites such as C19 and C21). This confirms that physical equations alone cannot fully model the highly complex, space-environment-induced perturbations of on-board atomic clocks, thereby firmly demonstrating the necessity of the “physical baseline assistance + deep learning residual separation” architecture adopted across our experiments.
- 2.
- Compared to Traditional Recurrent Neural Networks (WLS + LSTM):
Even when operating on the separated, purely nonlinear residuals, WLS + LSTM exhibits significant structural limitations when handling extremely long sequences of up to 2880 steps. Due to its autoregressive Markov chain structure, LSTM is highly prone to error accumulation and the attenuation of long-range dependencies. For instance, in the 24-h temporal extrapolation, its overall RMSE and MAE increase to 0.934 ns and 0.641 ns, as it struggles to retain high-frequency features from long-range historical data, causing its prediction trajectory to diverge over extended periods. This makes it difficult for traditional RNN architectures to meet the strict continuity and stability requirements of high-precision navigation.
- 3.
- Comparison with Mainstream Transformers (WLS + Informer & WLS + Basic-PatchTST):
As state-of-the-art architectures in the field of temporal forecasting, both Informer and Basic-PatchTST demonstrate strong residual fitting capabilities. However, a detailed dual-metric analysis reveals their primary limitations:
Extreme Instability at Boundaries (WLS + Informer): While WLS + Informer achieves a relatively competitive overall MAE (0.639 ns at 24 h), its RMSE remains disproportionately high (0.919 ns), particularly on specific orbits like IGSO. This significant discrepancy between MAE and RMSE indicates that while the model captures the general baseline trend reasonably well, it suffers from severe local prediction divergences. As visually evident in the per-satellite bar charts, predictions for highly dynamic satellites (like C38) spike significantly. This occurs because Informer lacks a dedicated boundary alignment mechanism; its global attention mechanism is highly susceptible to contamination by high-frequency burst noise at the endpoint of the historical window, leading to starting-point step jumps that are heavily penalized by the RMSE metric.
Lack of Multiscale Adaptability (WLS + Basic-PatchTST): Although WLS + Basic-PatchTST mitigates the error explosion to some extent through channel independence and local temporal slicing techniques, its use of a single, static receptive field prevents it from adapting to the temporal scale conflicts inherent among heterogeneous satellites. Notably, its 24-h overall MAE (0.719 ns) is actually higher than that of Informer. This demonstrates that a rigidly locked single-scale patch struggles to consistently track the overall baseline deviation across different atomic clocks (e.g., stable hydrogen clocks vs. high-drift rubidium clocks), preventing further accuracy breakthroughs at the sub-nanosecond level.
- 4.
- Highlighting the Advantages of Our Method (DRW-PatchTST):
Comparative results clearly show that even when competing against baselines equipped with the identical WLS preprocessing step, the DRW-PatchTST architecture demonstrates highly competitive superior predictive performance across both the L1 norm (MAE) and L2 norm (RMSE). In the 12-h extrapolation, the overall average RMSE and MAE drop sharply to an excellent 0.293 ns and 0.258 ns, respectively; in the highly challenging 24-h long-arm extrapolation, it successfully maintains the overall RMSE at a remarkably stable 0.507 ns and the MAE at 0.438 ns.
Multi-orbit robustness: As shown in the statistical tables, DRW-PatchTST demonstrates exceptional and balanced stability across both MEO and IGSO orbits, effectively mitigating the severe performance degradation seen in Informer on specific orbital types.
Microscopic robustness and Global tracking: The concurrent minimization of both metrics visually translates into the lowest error bars across all satellites. The introduction of the “micro-median anchor” effectively achieves zero-delay smooth alignment, completely eliminating the starting-point step jumps (driving down the RMSE). Furthermore, the dynamic recency-weighted ensemble mechanism successfully allocates optimal receptive fields, overcoming the static scale bottleneck seen in Basic-PatchTST (driving down the global MAE).
In summary, these rigorous experimental results demonstrate significant statistical advantages and fully validate that our proposed architecture is fundamentally superior. The interlocking framework—comprising the “time-decay WLS physical baseline,” “zero-delay alignment of micro-anchors,” and “dynamic weighted multi-scale integration based on recency-based indicators”—exhibits excellent robustness and broad practical application prospects in effectively resolving both residual boundary discontinuities and physical scale conflicts among heterogeneous satellites in modern GNSS constellations.
4.3. Dynamic Weights and Interpretability Analysis
Deep learning models often face criticism for being “black-box” systems in time series forecasting; however, the dynamic weighting mechanism proposed in this paper—based on local recency assessment and power-law index sharpening —endows the DRW-PatchTST architecture with exceptional physical interpretability. Figure 5 illustrates the multiscale expert dynamic weight heatmap learned adaptively by the model at the end of the validation set.
Figure 5.
Multi-scale Expert Dynamic Weighted Heatmap.
An examination of the heatmap and its underlying data reveals that the distribution of weights among the multi-scale experts exhibits a high degree of prior alignment with the physical properties of the actual BeiDou-3 onboard atomic clocks:
- High Convergence Between Stable Satellites and Large-Scale Experts:
For satellites that have operated stably over the long term, the network allocates the majority of its weights to large-scale expert models. These satellites are primarily equipped with high-precision passive hydrogen atomic clocks; their physical characteristics result in extremely low frequency drift rates and excellent long-term stability, producing very smooth and regular clock error data over extended periods.
The data corroborates this physical phenomenon: in the heatmap, the expert activation weights assigned to Patch = 96 by the models for C30 and C45 are as high as 0.817 and 0.729, respectively; the weight for Patch = 96 in C38 also reaches 0.742. The network spontaneously discovered that, for these “high-performing” cases with slow-evolving errors, using large-scale sequence blocks can effectively filter out minor perturbations and accurately anchor the dominant period of the hydrogen clock’s long-term, slow evolution.
- 2.
- The Close Match Between High-Noise Stars and Small-Scale Experts:
Conversely, for challenging satellites with severe frequency drift accompanied by high-frequency jitter (such as the MEO satellites C19–C24, C32–C33, C36–C37, and C41–C42), small-scale experts (Patch = 24 or Patch = 32) dominate the weighting. The primary clock for these satellites is a rubidium (Rb) atomic clock, which exhibits significant long-term frequency drift and is more sensitive to the space environment. Consequently, their clock error sequences often contain complex periodic terms, random walk noise, and high-frequency jitter.
The heatmap accurately reflects this phenomenon: for the most representative high-noise challenging satellites, C20 and C21, the weights of the smallest-scale expert patches (Patch = 24 and Patch = 32) showed significant clustering, reaching 0.784 and 0.894, respectively; Furthermore, the weights for Patch = 24 on C36 and C41 reached 0.563 and 0.621, respectively. This phenomenon is highly plausible from a physical mechanism perspective, as small-scale patches possess higher sensitivity, enabling them to immediately capture and track recent local frequency jumps in the rubidium clock, thereby effectively avoiding the excessive smoothing and prediction lag caused by a macro-scale, wide field of view.
- 3.
- Conclusion: Decoupling of sublimation and physical state:
In summary, this nonlinear sharpening mechanism, based on the inverse of the local mean-squared error, successfully induces a polarization effect at the multi-expert ensemble level. Without introducing any artificially defined prior routing rules or satellite classification labels, the quantile distribution of the heatmap exhibits a high degree of consistency with the physical a priori characteristic that “the hydrogen clock is suitable for large-scale, high-frequency fluctuations, while the rubidium clock relies on small-scale fluctuations.” This strongly demonstrates that the DRW-PatchTST network does not resort to blind, purely numerical fitting, but rather genuinely resolves the heterogeneous timescale patterns underlying different physical satellites, achieving a fully data-driven decoupling of satellite physical evolution states.
4.4. Ablation Study
To rigorously validate the independent contributions and irreplaceability of each core innovative module in the DRW-PatchTST architecture (physical baseline decomposition, median anchor alignment, dynamic integration, etc.), this paper designs a stepwise ablation study under identical dataset splits and hyperparameter settings. The experiments cover the following five network variants with progressively added modules:
- Baseline:
Pure CI-PatchTST (directly inputs the original sequence into the network without any physical baseline decomposition).
- 2.
- +WLS:
Introduces time-decay WLS to extract the physical baseline; the network predicts only the residuals but does not use anchor alignment.
- 3.
- +Micro-Median Anchor:
Based on Step 2, introduces an 11-point micro-median anchor alignment mechanism but does not perform multi-scale integration (only a single patch size is used).
- 4.
- +Mean Ensemble:
Building on Step 3, introduces multi-scale ensemble learning with 5 experts of different field-of-view granularities, but uses simple averaging (i.e., equal weights of 1/5) for fusion.
- 5.
- +DRW (Ours):
The final complete architecture; building on Step 3, introduces a dynamic adaptive weighting mechanism based on local proximity evaluation and exponential sharpening .
- The Need for Baseline Separation
As shown in Table 7, the pure CI-PatchTST model exhibits high RMSE in both the 12-h and 24-h prediction tasks. The bar charts in Figure 6 and Figure 7 (blue bars) indicate that the Baseline model has the highest error rates across all satellites. This is because the raw on-board clock error sequences simultaneously incorporate both macroscopic, long-term physical aging trends and microscopic, high-frequency nonlinear drifts. Attempting to have a single neural network handle the prediction of these two heterogeneous signals results in the network being “overburdened,” making it difficult to balance the slope stability required for long-term extrapolation with the precision needed for short-term cycles.
Table 7.
Comparison of Ablation Experiment Results for Core Modules.
Figure 6.
Comparison of the ablation model’s RMSE performance across satellites within a 12-h forecast window.
Figure 7.
Comparison of the ablation model’s RMSE performance across satellites within a 24-h forecast window.
Based on the overall statistical errors in Table 7 and Figure 6 and Figure 7, this paper provides the following in-depth analysis of the specific performance of each module:
When time-decaying WLS is incorporated, the time-varying physical trend is effectively stripped away, and the neural network’s input is refined into a pure nonlinear residual. At this point, the attention mechanism can focus on uncovering complex local periodic features, resulting in a significant initial reduction in overall error; the model’s average RMSE for 12-h and 24-h forecasts decreased significantly by 75.4% and 63.3%, respectively. These results fully quantify the core value of decoupling physical trends from nonlinear residuals in reducing the difficulty of network fitting and addressing concept drift.
It is important to clarify that without the WLS baseline separation, the pure CI-PatchTST model does not necessarily fail to converge during training. Instead, during the 24-h long-term extrapolation phase, the network struggles to simultaneously map the macroscopic low-frequency orbital harmonics and the microscopic high-frequency stochastic noise. Consequently, the accumulated extrapolation errors cause the predicted trajectory to exhibit severe baseline drift and diverge significantly from the true physical trend, rather than producing mathematical chaos.
- 2.
- The effectiveness of the anchor mechanism in boundary repair
Although WLS achieves baseline separation, in the “+WLS” predictions, due to interference from high-frequency observational noise at the ends, there is often a small but significant phase shift between the separated physical baseline and the true sequence at the prediction starting point. This discontinuity at the starting point is rapidly amplified during the long-period autoregressive integration, causing the predicted trajectory to diverge.
A comparison of “+WLS” and “+Micro-Median Anchor (green bars)” in the chart clearly shows that introducing an 11-point (5.5-min) micro-median anchor significantly improves the prediction error. Particularly on satellites such as C29 and C38, which are known for high noise levels and frequent sudden changes, the median operator, with its exceptional noise-resistant robustness, effectively smooths out the abrupt jumps at the start of the forecast. This achieves effective zero-delay alignment between the physical baseline and the residuals. Building on the baseline separation, the addition of the micro-median anchor further reduced the RMSE of the 24-h long-range forecast by 6.4%. This step is the key correction that enables the entire model to perform stable 24-h long-range extrapolation.
- 3.
- Dynamic sharpening goes beyond simple averaging
After eliminating baseline discontinuities, a multi-scale expert ensemble approach was introduced to resolve temporal scale conflicts among heterogeneous satellites. A comparison of the results from “+Mean Ensemble (red bars)” and “+DRW” highlights the limitations of conventional mean fusion strategies and the necessity of a dynamic adaptive weighting mechanism.
Although Mean Ensemble achieves some improvement through multi-scale averaging and smoothing, its essence lies in striking a balance—while it suppresses the worst-performing experts, it also limits the outstanding performance of the best experts, resulting in a bottleneck in model accuracy.
In contrast, the DRW mechanism introduced in this paper successfully implements a performance-feedback-based weighting mechanism by sampling a validation set of recent causes from the end of the sequence and applying nonlinear exponential sharpening. Under this mechanism, the scale expert that best aligns with the current physical evolution of a given satellite is assigned a significantly dominant weight (as shown in the heatmap above), thereby achieving a highly satisfactory level of final prediction accuracy (the purple bars are suppressed to the lowest level among all satellites, with an overall average RMSE as low as 0.507 ns).
As shown by the quantitative analysis above, compared to the original Baseline, the complete DRW-PatchTST architecture achieves cumulative improvements in absolute prediction accuracy of up to 80.8% and 71.1% for the 12-h and 24-h extrapolation tasks, respectively. The progressive nature of the ablation experiments and the steady reduction in error (as evidenced by the step-like downward trend in the bar charts shown in Figure 5 and Figure 6) effectively demonstrate the robustness and high performance of the proposed “physical baseline alignment + dynamic multi-scale integration” hybrid architecture in handling complex, heterogeneous on-board clock error signals. Without WLS, the long-term prediction trajectory exhibits severe baseline drift and divergence; without the median anchor, the boundaries are significantly constrained; and without dynamic sharpening, the system falls into scale mediocrity. The outstanding performance of the DRW-PatchTST architecture is precisely built upon this interlocking, indispensable, and rigorous logical chain.
4.5. Case Study on Problematic Satellites
To visually demonstrate the robustness of the network model under extremely harsh operating conditions, this paper selected four satellites from the constellation—C21, C22, C24, and C35—which are widely recognized for their severe frequency drift and high susceptibility to high-frequency jitter, and conducted an in-depth analysis of their fitting curves over a 24-h period (2880 epochs).
In traditional clock offset visualization, due to the large absolute magnitude of satellite clock offsets (typically on the order of nanoseconds), plotting absolute clock offset line graphs directly can cause a severe “visual masking effect,” making it difficult to discern differences in accuracy of a few nanoseconds or even sub-nanoseconds between models with the naked eye on a macroscopic scale. To address this, this paper innovatively uses the prediction error sequence as the vertical axis for plotting. From this perspective, historical true data (True Data, black line) is strictly smoothed into a baseline on the y-axis (retaining only the minute fluctuations of observational noise), while the model’s prediction errors are amplified and clearly exposed.
Figure 8 shows the evolution of prediction errors for four challenging satellites during a 24-h extrapolation mission. Based on this visual representation, this paper further analyzes the data and draws the following key conclusions:
Figure 8.
Comparison of 24-h forecast error trajectories for challenging satellites (C21, C22, C24, C35).
- Elimination of “level shifts” at the prediction boundary
In time series forecasting, the boundary between the historical input window and the future forecast window is the area most prone to phase shifts. As shown in Figure 8, the baseline model Basic-PatchTST (blue line), which does not incorporate an anchor mechanism, exhibits a significant error jump at the start of the forecast after the physical baseline is removed, with the forecast starting point suddenly deviating from the axis. For example, during the initial prediction phase for satellites C21 and C24, the absolute error of the baseline model instantly jumps to 2–3 ns. This discontinuous offset at the starting point directly contaminates the entire subsequent autoregressive integration process. In contrast, the DRW-PatchTST model proposed in this paper, benefiting from the introduction of 11-point micro-median anchors, achieves effective zero-delay alignment with the true baseline at the prediction boundary. The red line transitions relatively smoothly from the historical data to the forecast phase, effectively suppressing the occurrence of boundary discontinuities.
- 2.
- Highly Robust Noise Resistance and Long-Term Trend Tracking
Within a 24-h forecast window, the cumulative drift of error over time serves as a key metric for assessing a model’s generalization capability. Taking the two representative rubidium clock challenge satellites, C21 and C24, as examples: Basic-PatchTST, due to its lack of dynamic scale adaptation, is highly susceptible to having its physical baseline skewed by high-frequency spikes at the end of the history. As the prediction horizon extends, its error curve exhibits a significant divergent trend—the prediction error for C21 rapidly accumulates and exceeds 10 ns, while the error for C24 rapidly drops below −6 ns. In stark contrast, the error trajectory of the DRW-PatchTST model remains consistently stable near the central axis, demonstrating high prediction stability. Even in the face of complex operating conditions like C21, which involve severe high-frequency jitter, the model can still adaptively assign dominant weights to small-scale Patch experts through its exponential sharpening mechanism. This effectively filters out terminal noise interference and accurately extrapolates the core low-frequency drift trend.
This case study at the micro-visual level not only clearly reveals the error divergence issues that traditional deep learning models are prone to in clock offset prediction, but also fully demonstrates the exceptional robustness of the DRW-PatchTST architecture when faced with complex frequency drifts and high-noise real-world environments. The model presented in this paper shows strong capability in maintaining stable high-precision time-series extrapolation across the evaluated frequency bands and orbit types.
4.6. Sensitivity Analysis and Weighting Scheme Comparison
To mathematically justify the design of the dynamic recency-weighted mechanism, we conducted a sensitivity analysis on the essential hyperparameters and compared alternative ensemble weighting schemes.
Selection of the Recency Window: The terminal 20% of the validation set (approximately 4.8 h) was selected as the recency evaluation window. This specific ratio represents an optimal trade-off between statistical significance and physical recency. A shorter window (e.g., 5%) renders the MSE calculation highly vulnerable to transient high-frequency noise, whereas a longer window (e.g., 50%) incorporates stale states that dilute the tracking of the latest “concept drift” in the atomic clock’s hardware state.
Comparison of Alternative Weighting Schemes: Table 8 details the performance of the proposed architecture under different gating and weighting strategies.
Table 8.
Comparison of different multi-scale ensemble weighting schemes on the 24-h prediction task.
Inverse-MSE (): This linear penalization proved insufficiently sharp to suppress poorly performing experts, leading to an over-smoothed, suboptimal mean-like ensemble.
Softmax with Temperature: While effective in standard attention mechanisms, Softmax weights are highly sensitive to the absolute scale of the MSE variance. In heterogenous constellations where error magnitudes vary drastically between PHM and Rubidium clocks, tuning a universal temperature parameter proved computationally fragile.
Learned Gating Mechanism: Employing a trainable neural router (similar to standard Mixture-of-Experts) resulted in significant overfitting. In the presence of high-frequency space weather noise, the learned router frequently collapsed to a suboptimal local minimum.
Inverse-MSE (, Ours): The selected inverse-square weighting acts as a non-linear power-law sharpener. As demonstrated in Table 8, it achieves the lowest RMSE by successfully inducing weight polarization—adaptively assigning dominant weights to the most competent scale expert while aggressively decaying the interference from mismatched ones, without requiring additional trainable parameters.
4.7. Computational Efficiency and Real-Time Engineering Feasibility
To evaluate the practical applicability of the proposed architecture for real-time GNSS Precise Point Positioning (PPP) and autonomous navigation services, computational efficiency is a critical metric alongside predictive accuracy. Table 9 presents a comparative analysis of the average training time per epoch, inference latency, and total parameter count across the evaluated models, measured under identical hardware conditions.
Table 9.
Comparison of Computational Efficiency (Training Time and Inference Latency).
An analysis of the profiling results indicates several computational characteristics of the DRW-PatchTST model:
- Efficiency of the Temporal Patching Mechanism:
Traditional Transformer architectures often face computational challenges when processing long time series. As observed in Table 9, the WLS + Informer model exhibits a relatively higher computational cost (10.43 s per training epoch and 23.14 ms for inference). This is primarily due to its global self-attention mechanism, which operates with a quadratic computational complexity of relative to the input sequence length (L = 2880). In contrast, models utilizing a temporal patching mechanism compress the effective sequence length fed into the Transformer encoder from 2880 to approximately 120 patches. This reduces the self-attention complexity to (where $P$ is the number of patches), contributing to a noticeable decrease in inference latency.
- 2.
- Parameter Optimization in the Projection Head:
A potential issue with standard patching models is the expansion of parameters at the output layer. For instance, the WLS + Basic-PatchTST model employs a direct flattening and linear mapping approach, resulting in a total parameter count of 11.09 M. The proposed DRW-PatchTST mitigates this by introducing an optimized bottleneck projection head. By routing the flattened sequence through an intermediate 128-dimensional bottleneck layer before the final prediction, the feature space is compressed. This structural adjustment reduces the parameter count to 0.68 M per expert network (an approximate 93.8% reduction compared to Basic-PatchTST), which helps lower memory overhead and facilitates the observed 1.24 ms inference latency.
- 3.
- Feasibility for Real-Time Services:
The complete DRW-PatchTST framework consists of a multi-scale ensemble of five expert networks. Due to the channel-independent (CI) design, the operations for independent satellites and expert networks can be highly parallelized. Even under sequential inference assumptions, the cumulative prediction latency remains in the single-digit millisecond range. In operational GNSS environments, high-precision clock offset products (such as those from WUM) are typically updated at intervals ranging from 30 s to 5 min. The measured sub-10 ms processing time is well within the strictest 30-s operational time budget. These results demonstrate that the DRW-PatchTST architecture can meet the timeliness requirements for real-time satellite navigation systems without compromising predictive accuracy.
4.8. Correlation Analysis with Space Weather Indices
To evaluate the influence of the space weather context on model performance, a correlation analysis was conducted between the geomagnetic disturbance levels (indicated by the daily Kp index) and the daily prediction errors for representative rubidium-clock satellites (e.g., C21 and C24). The corresponding error trajectories and actual measurements are illustrated in Figure 9 and Figure 10.
Figure 9.
Comparison of environmental robustness between the baseline and DRW-PatchTST models under varying geomagnetic activities (Satellite C21).
Figure 10.
Comparison of environmental robustness between the baseline and DRW-PatchTST models under varying geomagnetic activities (Satellite C24).
During the relatively quiet space weather phase (DOY 50 to 51, where the Kp index was 2.3 or lower), the daily root mean square error (RMSE) of all evaluated models remained stable. However, coinciding with the geomagnetic perturbation peak on DOY 53 (Kp index = 4.3), the baseline models exhibited pronounced increases in prediction errors. For example, the RMSE of WLS + Informer and WLS + Basic-PatchTST for satellite C24 increased from approximately 0.97 ns and 1.05 ns on DOY 50 to 1.85 ns and 1.72 ns on DOY 53, respectively. The error trajectories of these baseline models show a distinct positive correlation with the variations in the Kp index, suggesting a sensitivity to space environment anomalies.
In comparison, the proposed DRW-PatchTST architecture demonstrates a more consistent performance profile under the same perturbed conditions. Facilitated by the dynamic recency-weighted ensemble mechanism, the model can adaptively adjust its expert weights to track high-frequency physical drifts. Consequently, the magnitude of error variation is substantially suppressed. For satellite C21, the maximum daily RMSE fluctuation for DRW-PatchTST during the disturbance period was constrained to 0.11 ns (ranging from 0.51 ns to 0.62 ns), whereas baseline models experienced fluctuations exceeding 0.25 ns. This quantitative analysis indicates that the proposed model exhibits enhanced environmental robustness, effectively mitigating the impact of concept drift induced by variations in solar cycle activities.
5. Conclusions
High-precision satellite clock offset prediction is a critical component for enhancing the precise single-point positioning and autonomous navigation capabilities of the BeiDou-3 Global Navigation Satellite System. To address the three major challenges revealed during the long-term operation of on-board atomic clocks—namely, physical state heterogeneity, time-varying aging drift (concept drift), and discontinuities in prediction boundaries—this paper proposes a novel architecture: a multi-scale block-based self-attention network based on physically inspired anchors and dynamic recency weighting.
This study overcomes the inherent limitations of traditional physical models and conventional deep learning algorithms, achieving core technological innovations in four dimensions: During the baseline modeling phase, a time-decay-weighted least-squares mechanism was introduced to precisely capture the drift trends dominated by the recent physical state of atomic clocks; In the residual separation stage, we innovatively proposed a 5.5-min micro-median anchor alignment strategy, which not only effectively mitigated phase discontinuities at the prediction onset but also demonstrated exceptional robustness against high-frequency burst noise contamination. In the feature extraction stage, the use of a pure channel-independent network largely mitigated feature crosstalk among heterogeneous satellites from different systems. In the model integration stage, a pioneering dynamic weighted fusion mechanism based on local recency assessment and power-law nonlinear exponential sharpening was developed, achieving adaptive optimal matching between multiscale receptive fields and satellite time-varying characteristics.
Extensive experiments using real-world precision clock difference data from Wuhan University have validated the exceptional performance of this architecture. In 24-h extrapolation tasks, DRW-PatchTST achieved a highly accurate performance with an average root mean square error as low as 0.51 ns, significantly and consistently outperforming traditional OLS, Long Short-Term Memory, and mainstream Transformer baseline models. Even when faced with extremely challenging satellites such as C24 and C35, which exhibit high noise and high-frequency drift, this architecture is still capable of producing smooth and accurate tracking prediction curves.
More importantly, this study has successfully overcome the “black box” limitation commonly associated with deep learning in time series forecasting. Through the polarization effect induced by exponential sharpening, the multi-scale expert weight distributions spontaneously learned by the network achieved a high degree of a priori alignment with the physical evolution laws of space-based rubidium and hydrogen clocks. This indicates that DRW-PatchTST not only possesses the powerful nonlinear residual fitting capabilities of modern deep networks but also offers rigorous physical interpretability.
Despite the promising results, this study has certain limitations that warrant future investigation. The empirical validation in this work is based on a 10-day continuous observation window (DOY 049–058, 2026) with a 24-h independent test horizon. While this period robustly encompasses significant space weather perturbations, it represents a limited temporal snapshot of the satellite clocks’ multi-year lifecycle. Therefore, the demonstrated robustness and predictive capabilities are currently validated specific to this dataset and the reported geomagnetic conditions. The broad generalization of the DRW-PatchTST architecture over multi-month or multi-year horizons, which involve long-term physical aging and seasonal eclipse effects, remains to be fully verified. Future work will focus on expanding the validation framework to longitudinal datasets spanning multiple years.
Furthermore, looking ahead, as space weather monitoring systems continue to improve, incorporating external multi-source physical observation data—such as satellite-borne environmental temperature gradients and space electromagnetic radiation—as covariates into this dynamic prediction framework will further strengthen the model’s physical prior boundaries. This represents a highly promising research direction for advancing GNSS clock offset prediction to a higher level.
Author Contributions
Conceptualization, C.C. and K.X.; methodology, K.X. and S.W.; software, K.X. and S.W.; validation, S.L. and W.H.; formal analysis, K.X. and S.L.; investigation, S.W. and W.H.; resources, C.C.; data curation, S.W.; writing—original draft preparation, K.X.; writing—review and editing, C.C., S.L. and W.H.; visualization, K.X. and S.W.; supervision, C.C.; project administration, C.C.; funding acquisition, C.C. All authors have read and agreed to the published version of the manuscript.
Funding
We extend our gratitude extends to for the funding provided by the National Key Research and Development Program of China (Grant No. 2020YFA0713501).
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The precise clock offset products (WUM0MGXRAP) used in this study were retrieved from the Wuhan University IGS Analysis Center (available at http://www.igs.gnsswhu.cn/ (accessed on 17 May 2026)). The specific daily files span from WUM0MGXRAP_20260490000.CLK to WUM0MGXRAP_20260580000.CLK. These data were accessed and downloaded on 5 April 2026. The dataset encompasses 26 BDS-3 satellites, including MEO and IGSO/GEO orbits (detailed in Section 4.1).
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Kaplan, E.D.; Hegarty, C. (Eds.) Understanding GPS/GNSS: Principles and Applications, 3rd ed.; Artech House: Norwood, MA, USA, 2017. [Google Scholar]
- Lv, Y.; Meng, Z.; Wang, G.; Liu, M.; Yan, E. Review of Research on Satellite Clock Bias Prediction Models in GNSS. Remote Sens. 2025, 17, 3177. [Google Scholar] [CrossRef] [Scilit]
- Wang, X.; Chai, H.; Shi, M.; Zhong, Y. Analysis and Comparison of Satellite Clock Offset Prediction Models. J. Surv. Mapp. Sci. Technol. 2021, 38, 350–354. [Google Scholar]
- Gao, H.; Wang, Y.; Chen, H.; Dong, Z.; Zheng, X.; Liu, H.; Fan, J. A short-term prediction model for satellite clock bias based on Kalman_LSTM neural network. Surv. Rev. 2026, 1–18. [Google Scholar] [CrossRef] [Scilit]
- Guo, C.; Teng, Y. Performance Analysis of Satellite Clock Offset Forecasting Based on Wavelet Analysis and Neural Networks. Acta Astron. Sin. 2010, 51, 395–403. [Google Scholar]
- Cai, C.; Wu, M.; Lü, K. Short-term Forecast of BDS-3 Satellite Clock Offset Based on the SSA-ANFIS Model. Geod. Geodyn. 2024, 44, 926–931. [Google Scholar]
- Shao, K.; Li, K.; Wang, J. Research on Pseudo-Satellite Layout Strategy Based on Particle Swarm Optimization Algorithm. Commun. Technol. 2017, 50, 2454–2459. [Google Scholar]
- Bhatt, A.; Mehta, I.; Patidar, P. Leveraging LSTM for Predictive Modeling of Satellite Clock Bias. In Proceedings of the 2025 8th International Conference on Data Science and Machine Learning Applications (CDMA), Riyadh, Saudi Arabia, 16–17 February 2025; IEEE: New York, NY, USA, 2025; pp. 25–30. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.; Liu, F.; Kong, Y.; Yang, C. Improved SSA-Based GRU Neural Network for BDS-3 Satellite Clock Bias Forecasting. Sensors 2024, 24, 1178. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Cai, C.; Liu, M.; Li, P.; Li, Z.; Lv, K. Enhancing satellite clock bias prediction in BDS with LSTM-attention model. GPS Solut. 2024, 28, 92. [Google Scholar] [CrossRef] [Scilit]
- Ma, J.; Tang, J.; Teng, H.; Wu, X. Prediction and Performance of BDS Satellite Clock Bias Based on CNN-LSTM-Attention Model. Sensors 2026, 26, 422. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Nie, Y.; Nguyen, N.H.; Sinthong, P.; Kalagnanam, J. A time series is worth 64 words: Long-term forecasting with transformers. arXiv 2022, arXiv:2211.14730. [Google Scholar]
- Zeng, A.; Chen, M.; Zhang, L.; Xu, Q. Are transformers effective for time series forecasting? In Proceedings of the AAAI Conference on Artificial Intelligence, Washington, DC, USA, 7–14 February 2023; Volume 37, pp. 11121–11128. [Google Scholar]
- Qu, L.; Du, M.; Wang, J.; Zhao, Q.; Guo, J. Multi-GNSS Satellites Clock Estimation and Analysis. Geomat. Inf. Sci. Wuhan Univ. 2018, 43, 107–111. [Google Scholar] [CrossRef]
- Xie, S.; Li, J. Enhancing BDS-3 Satellite Clock Bias Prediction Using Transformer-Based Deep Learning Model. IEEE Aerosp. Electron. Syst. Mag. 2026, 41, 18–34. [Google Scholar] [CrossRef] [Scilit]
- Zhou, H.; Zhang, S.; Peng, J.; Zhang, S.; Li, J.; Xiong, H.; Zhang, W. Informer: Beyond Efficient Transformer for Long Sequence Time-Series Forecasting. arXiv 2020, arXiv:2012.07436. [Google Scholar] [CrossRef] [Scilit]
- Leys, C.; Ley, C.; Klein, O.; Bernard, P.; Licata, L. Detecting outliers: Do not use standard deviation around the mean, use absolute deviation around the median. J. Exp. Soc. Psychol. 2013, 49, 764–766. [Google Scholar] [CrossRef] [Scilit]
- Schafer, R.W. What Is a Savitzky-Golay Filter? [Lecture Notes]. IEEE Signal Process. Mag. 2011, 28, 111–117. [Google Scholar] [CrossRef] [Scilit]
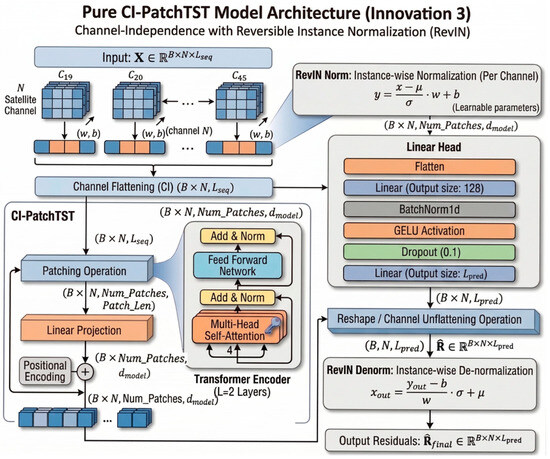
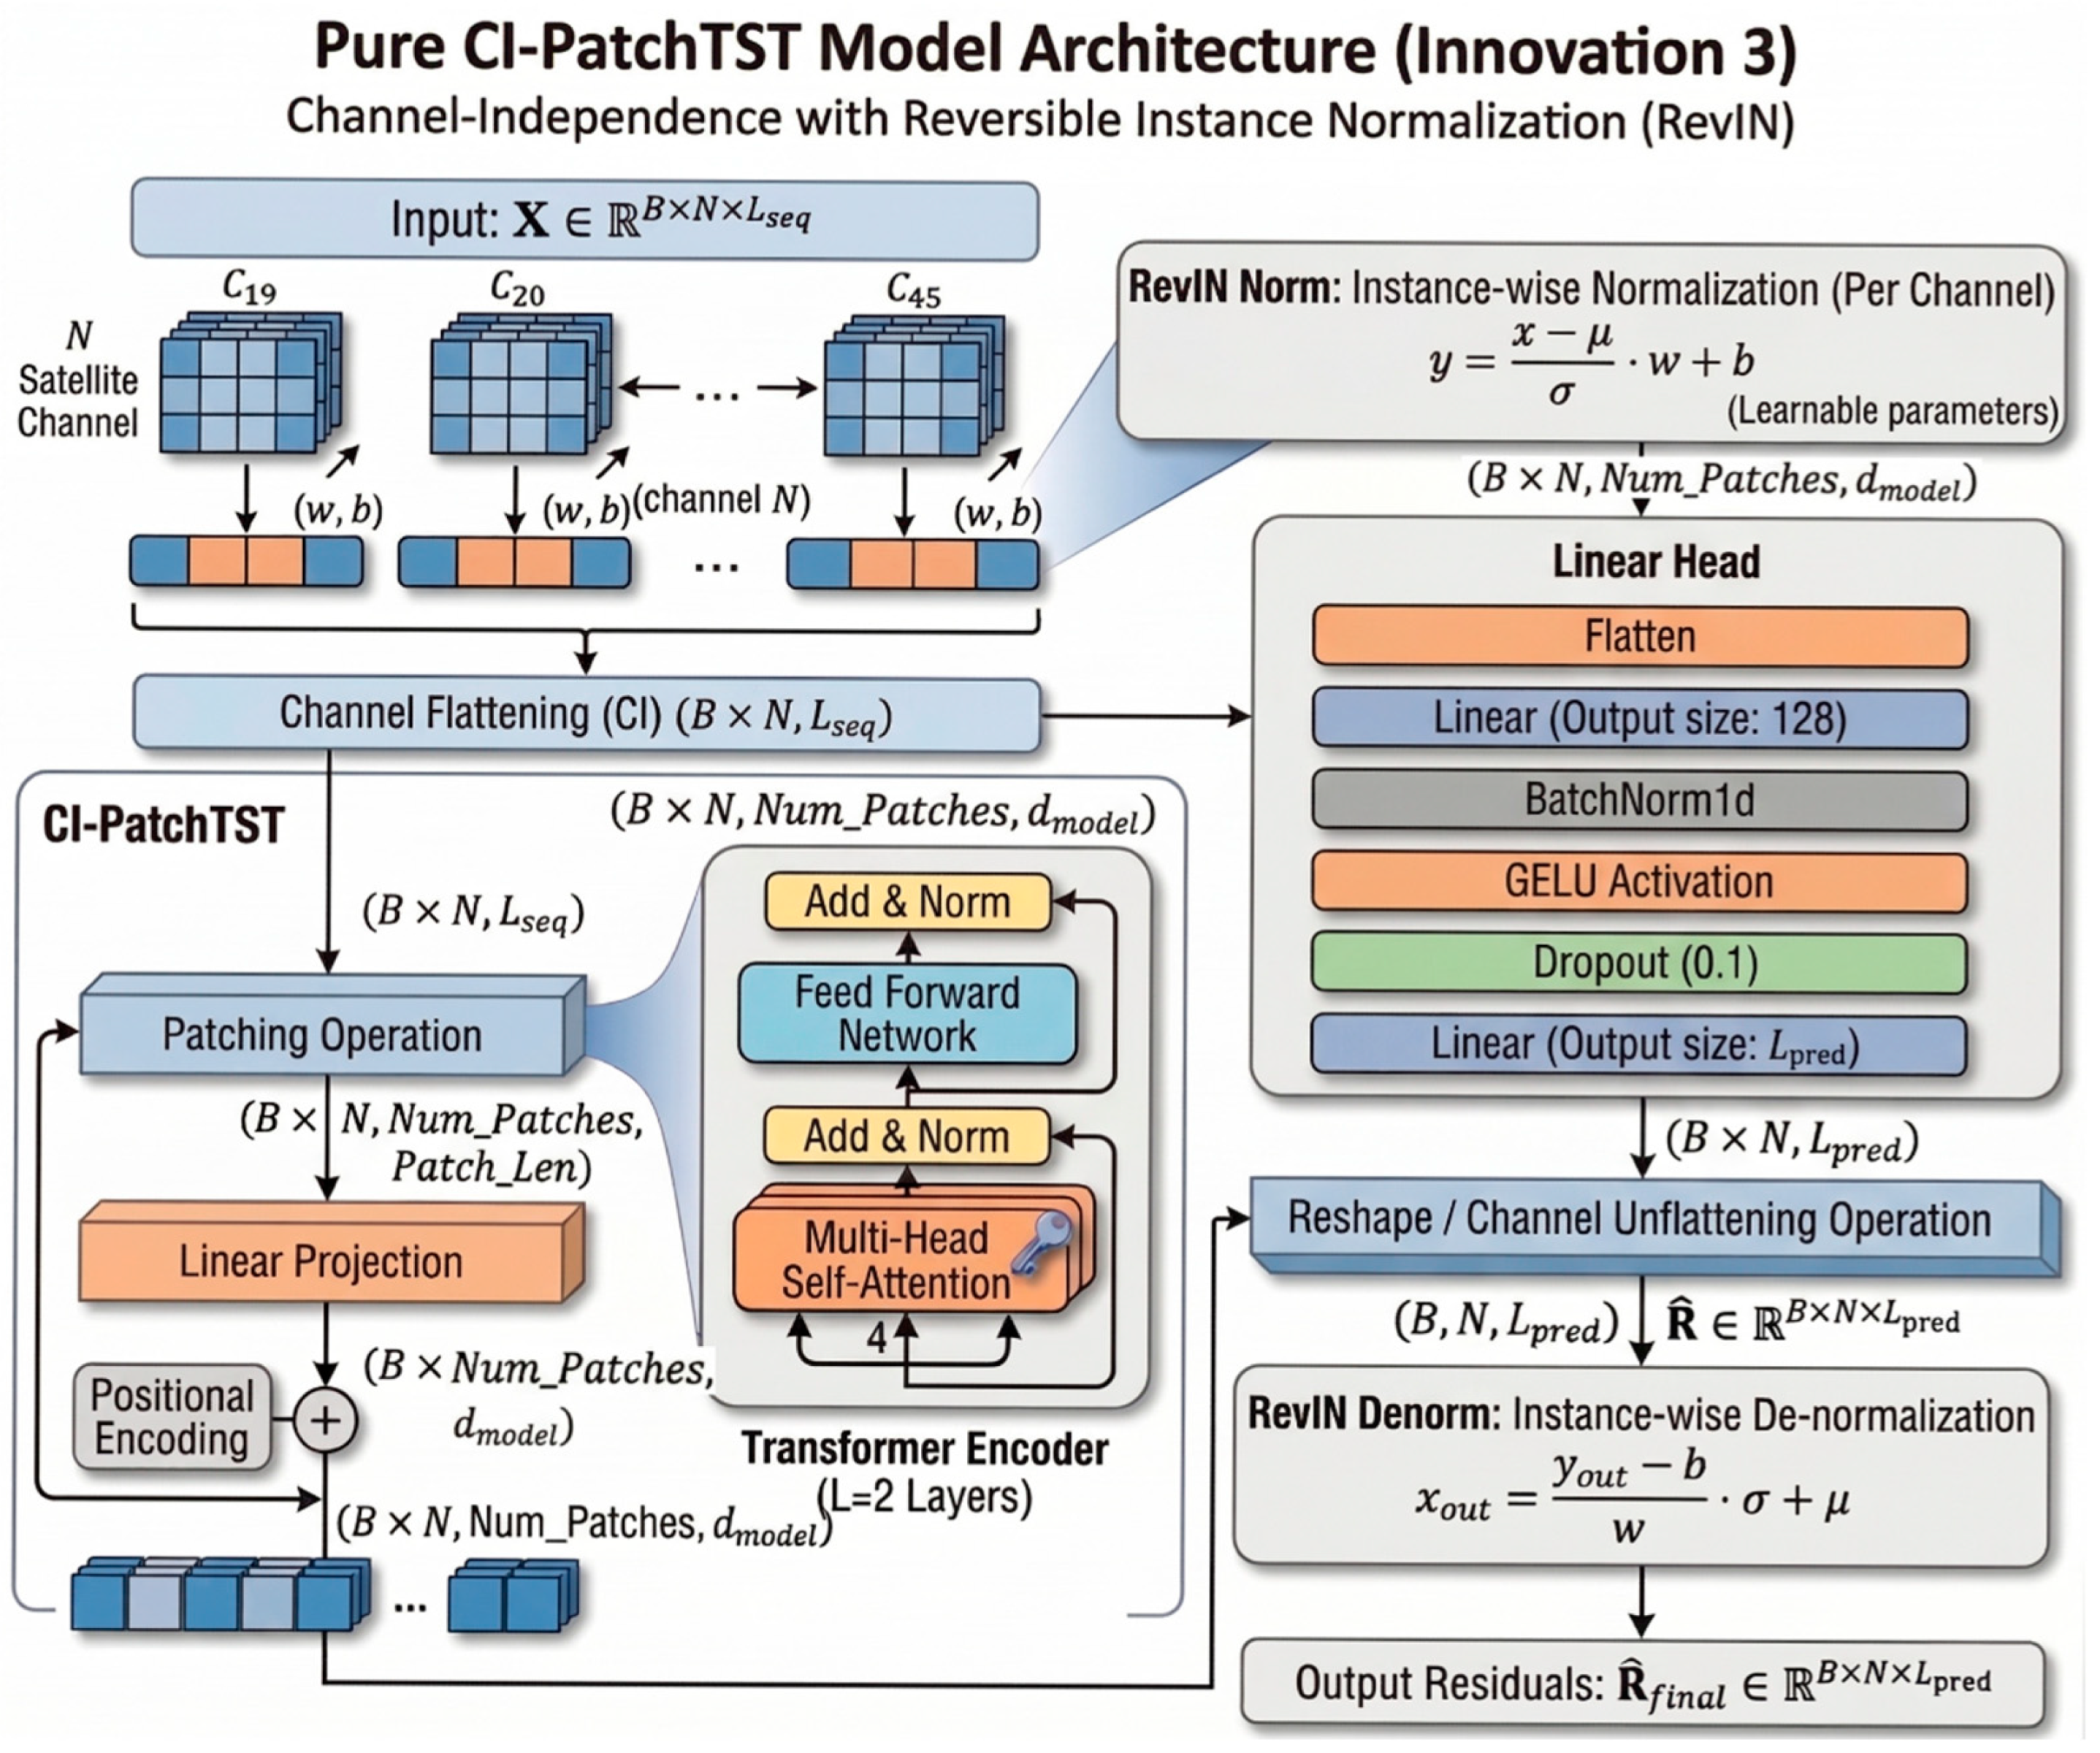
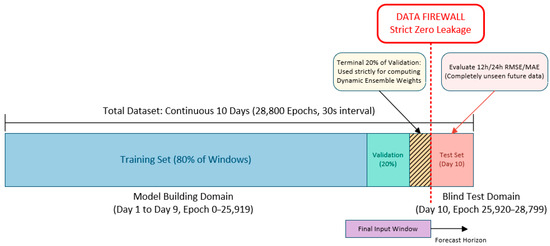
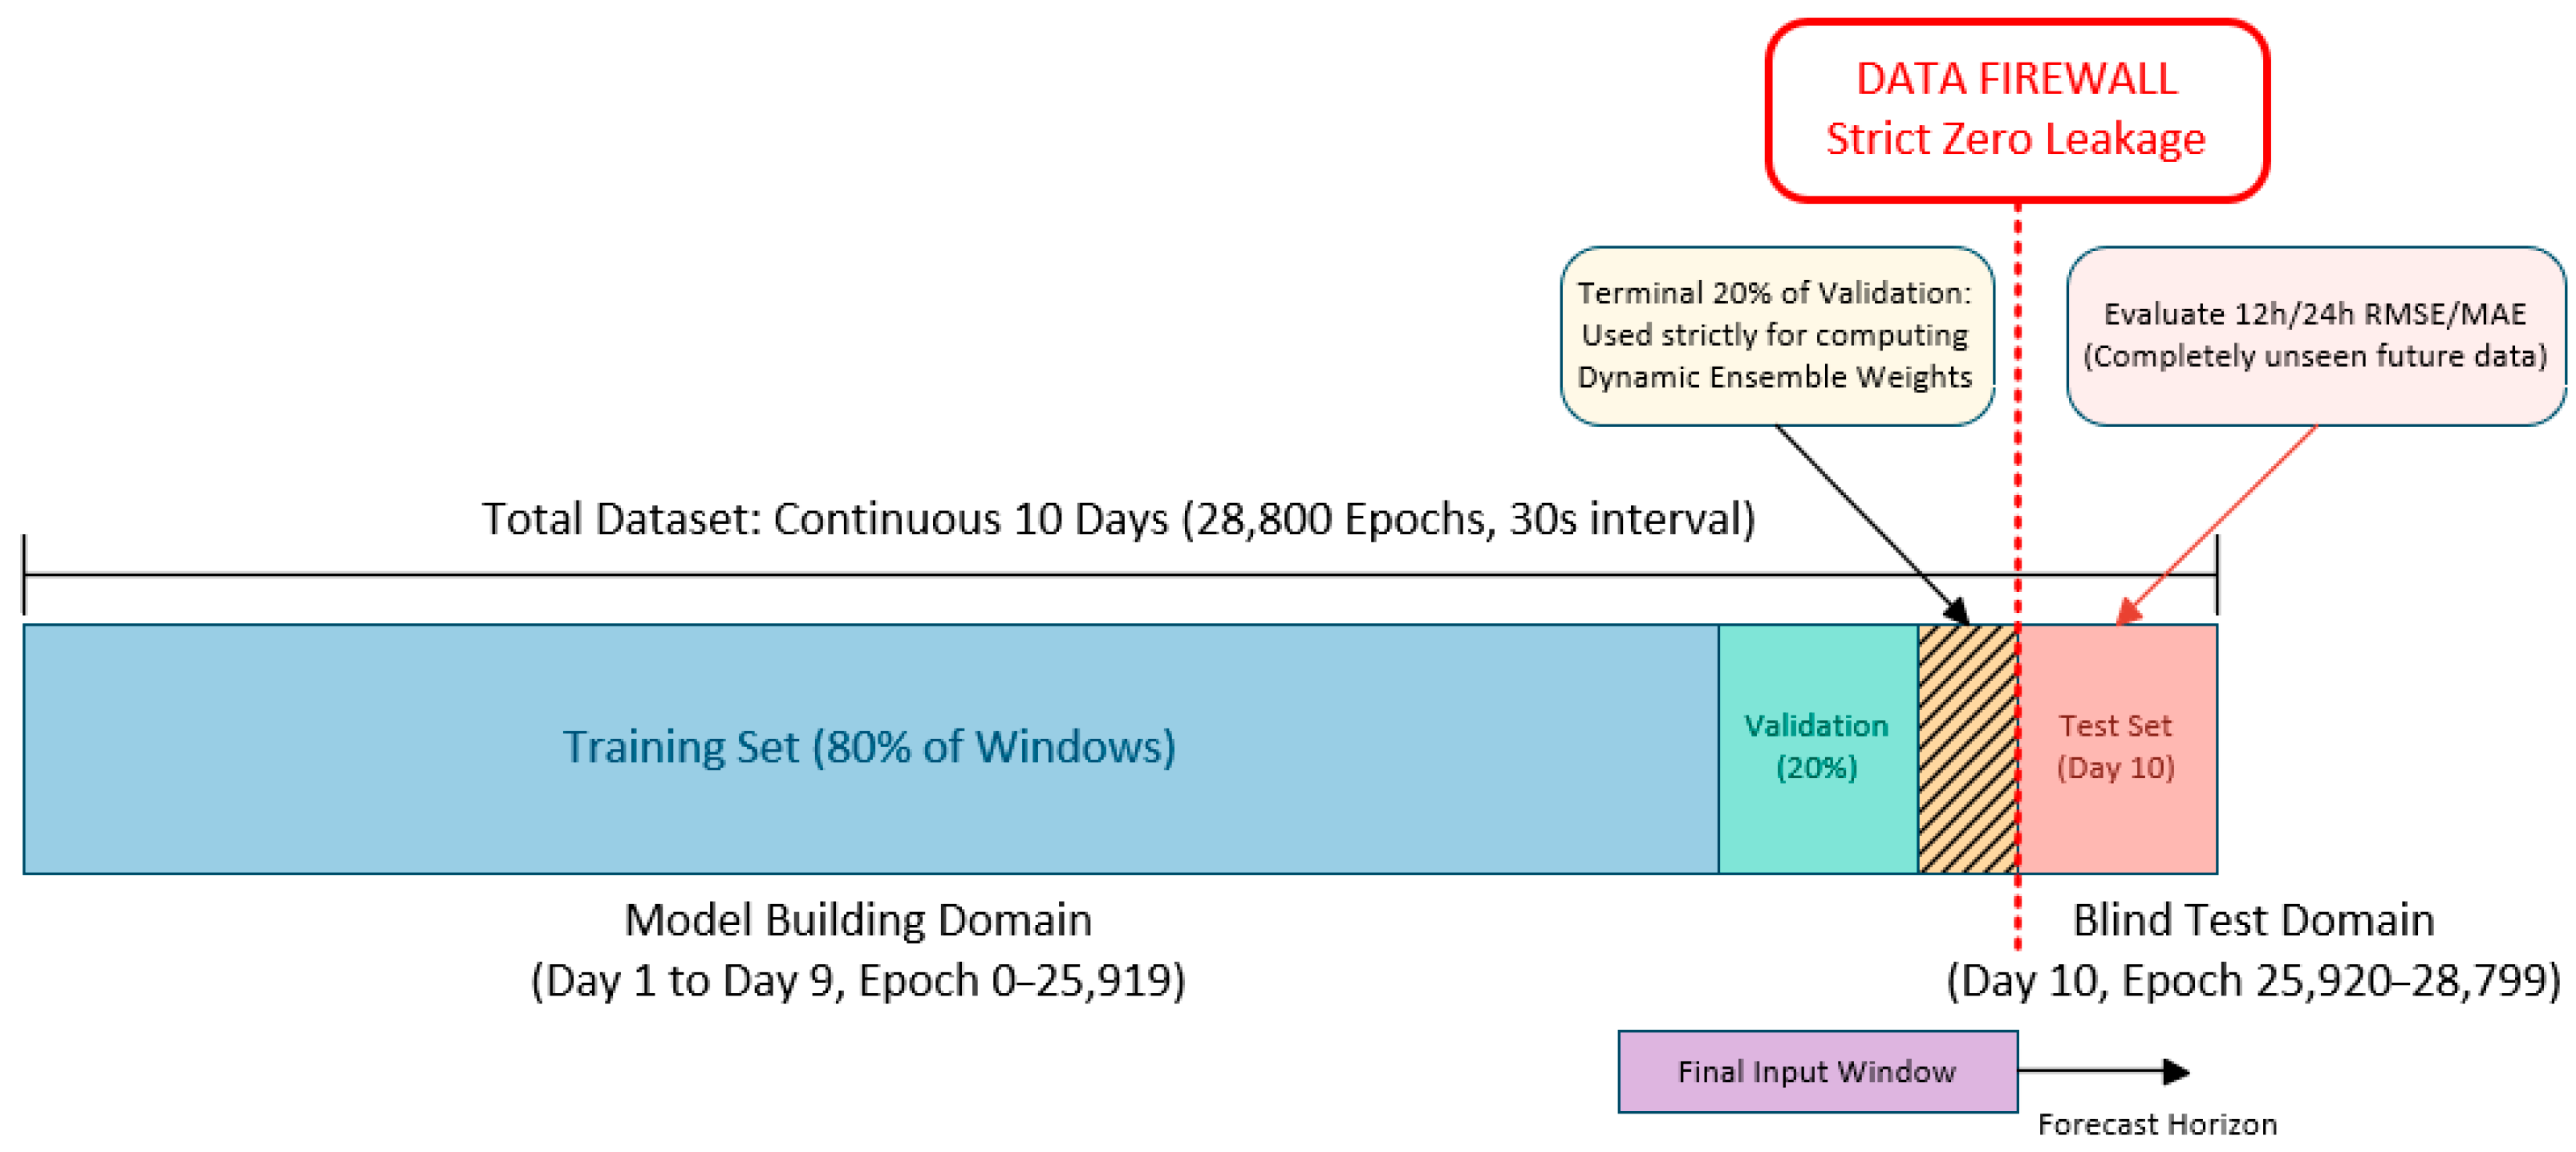
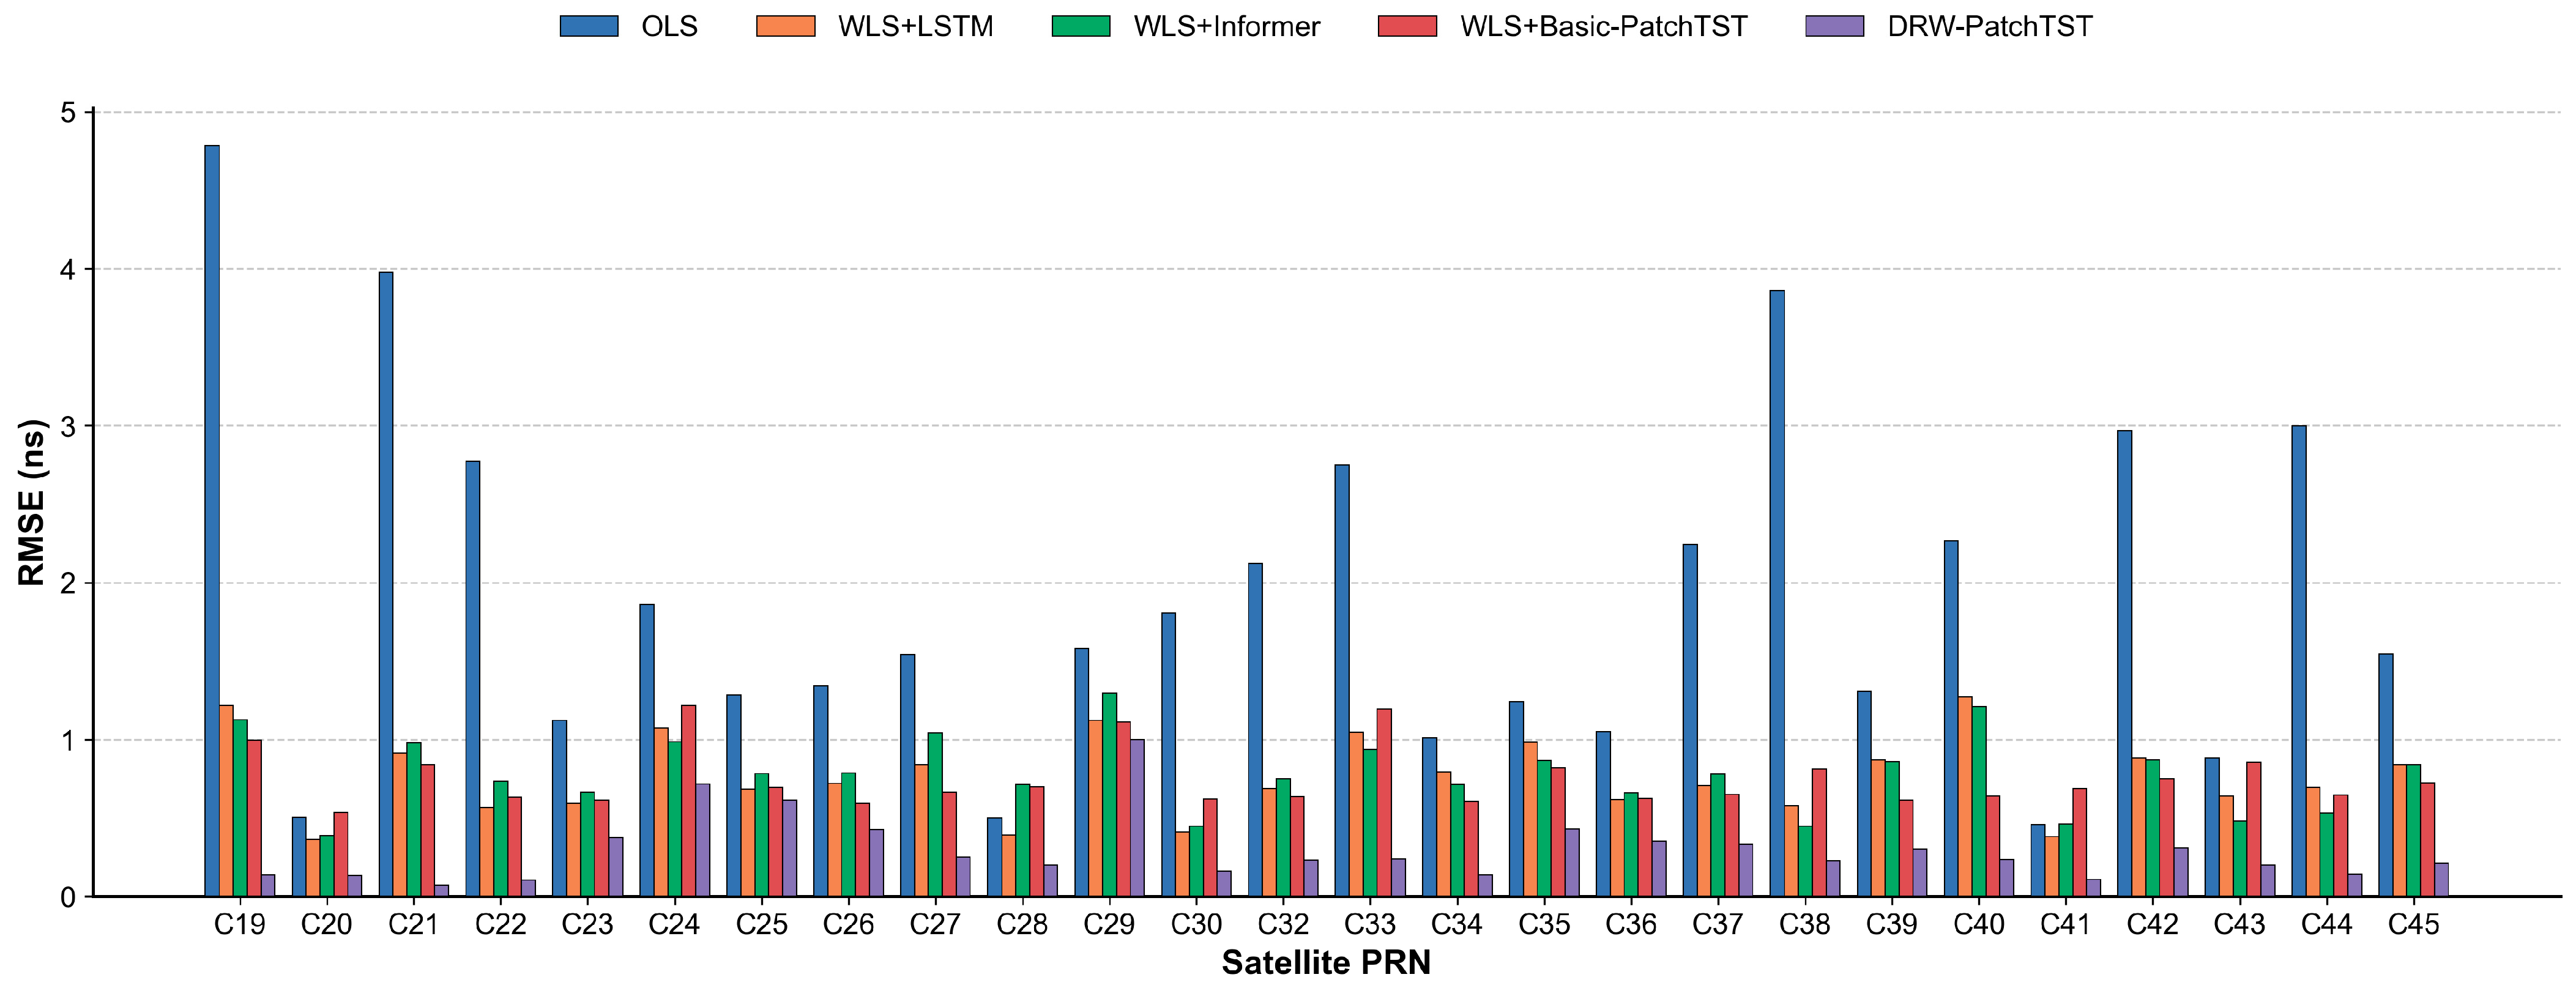
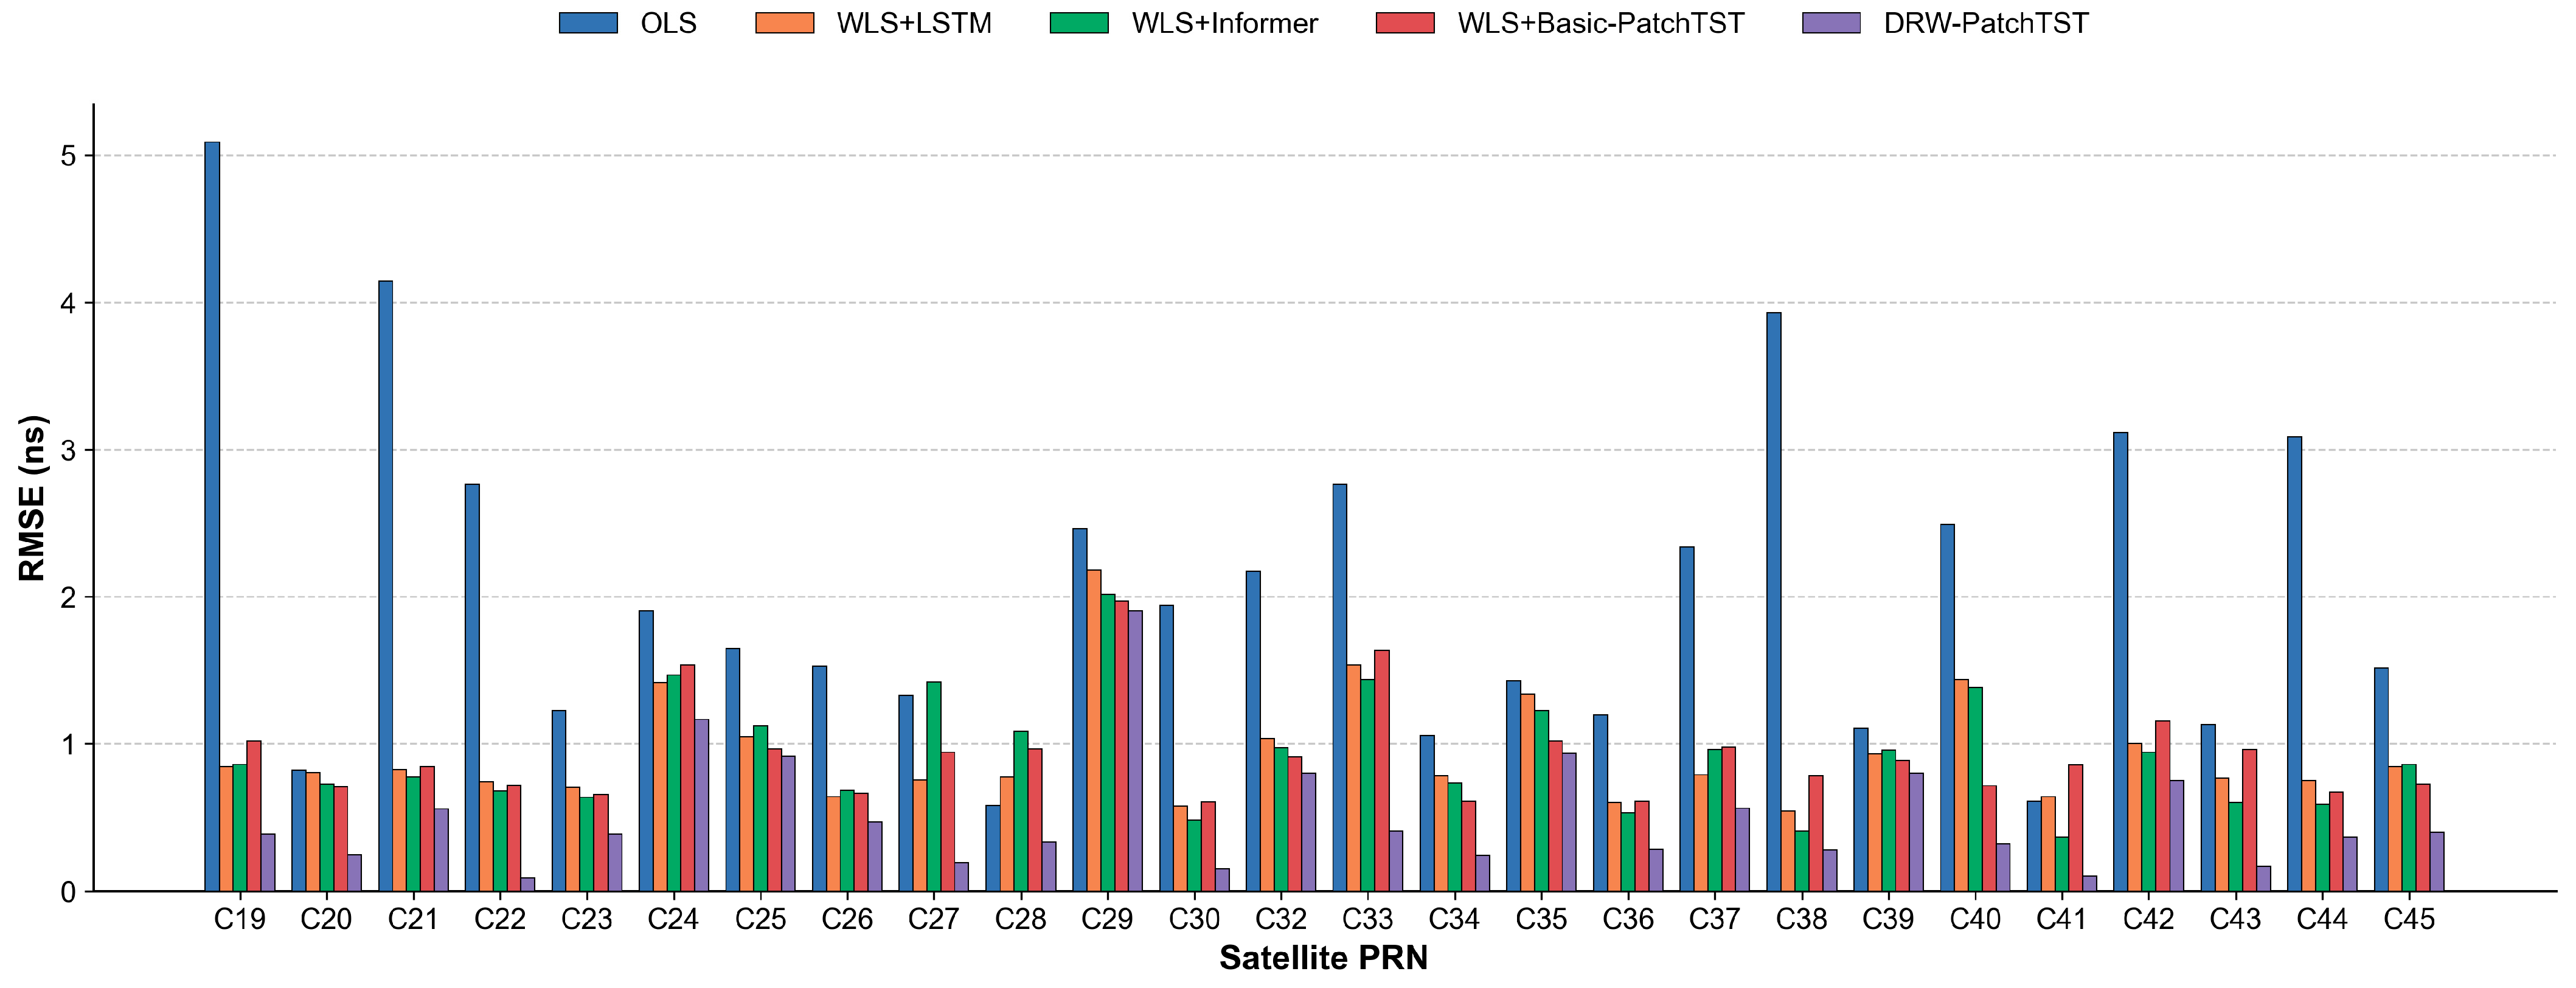
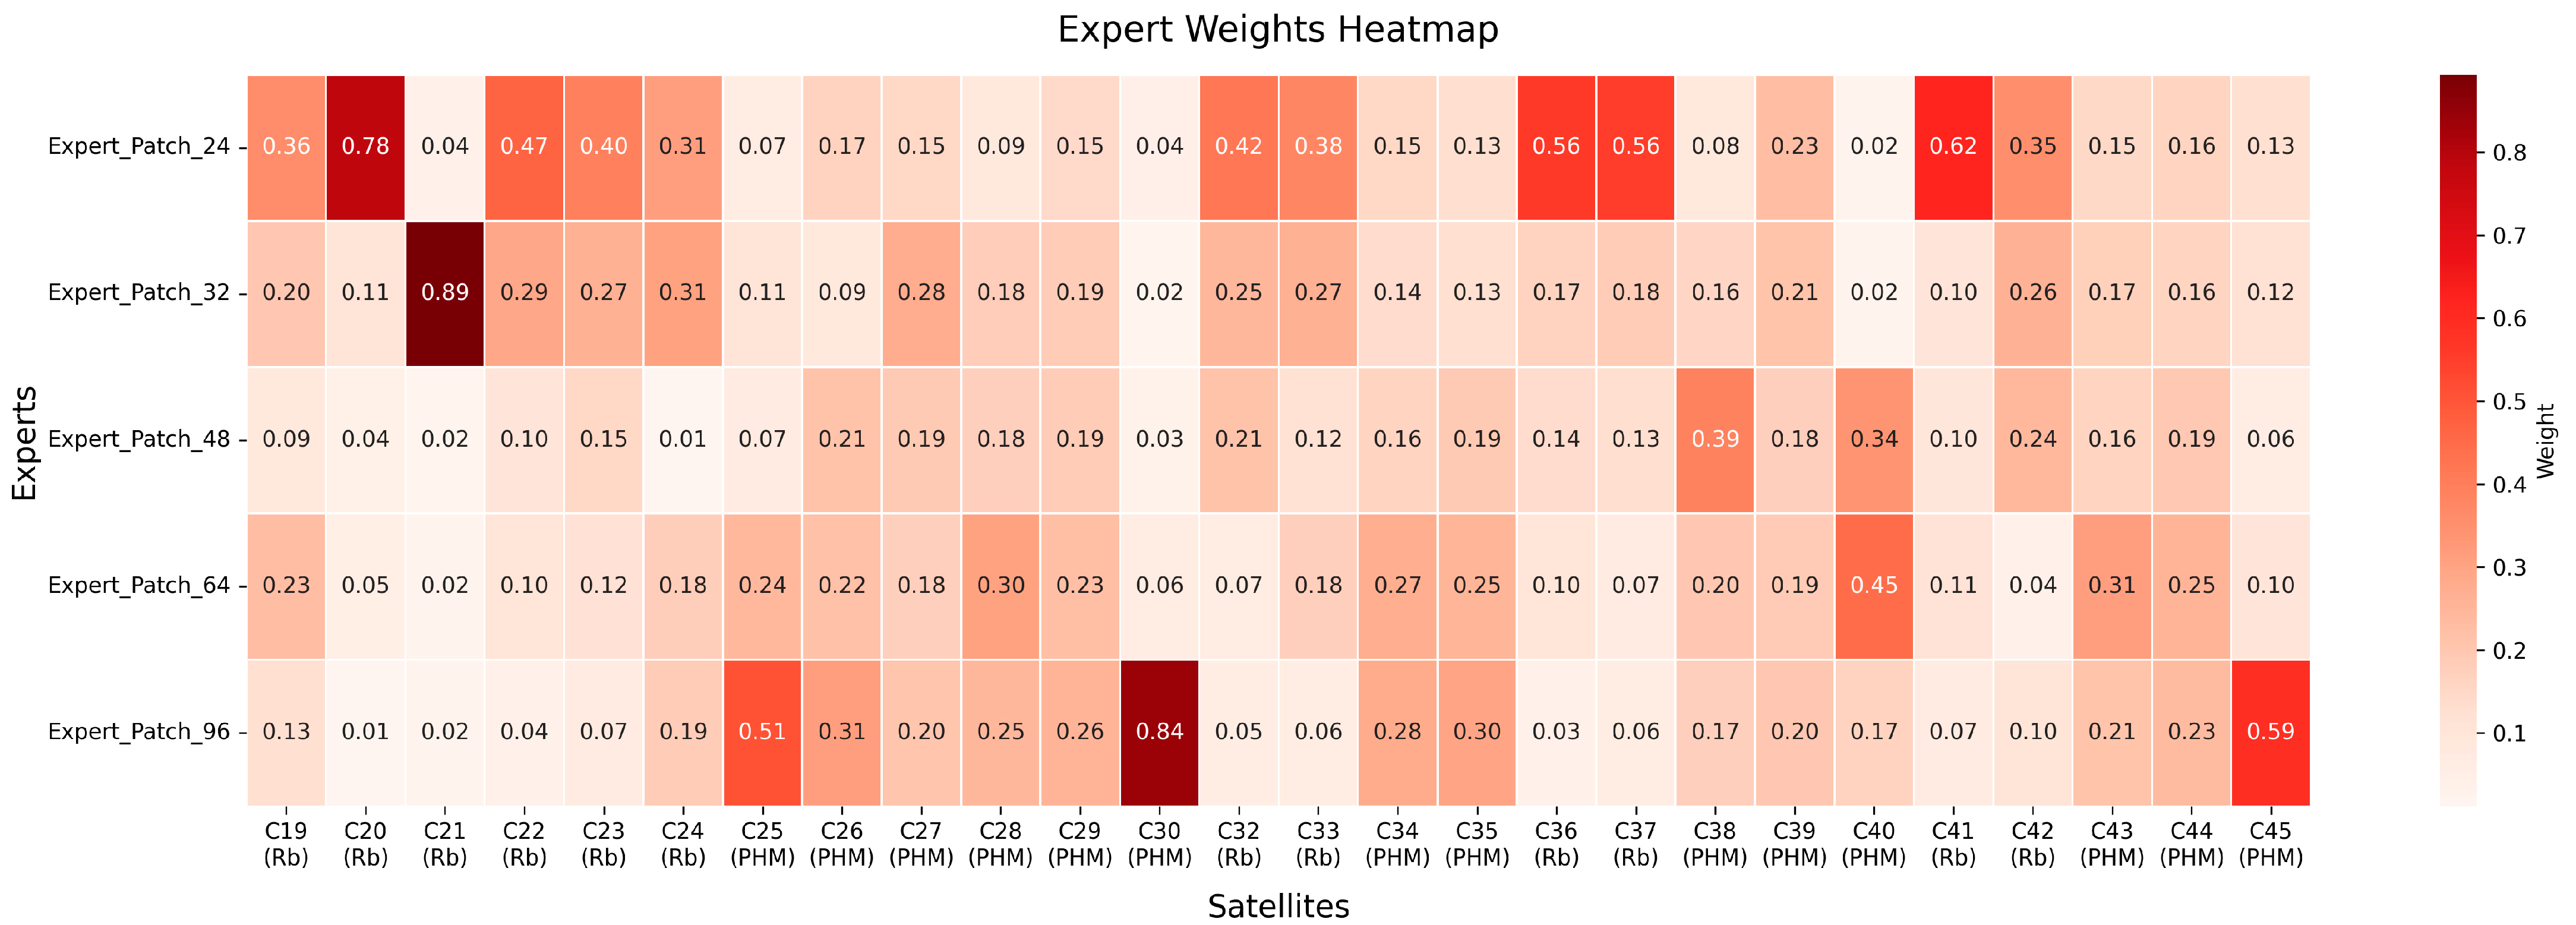
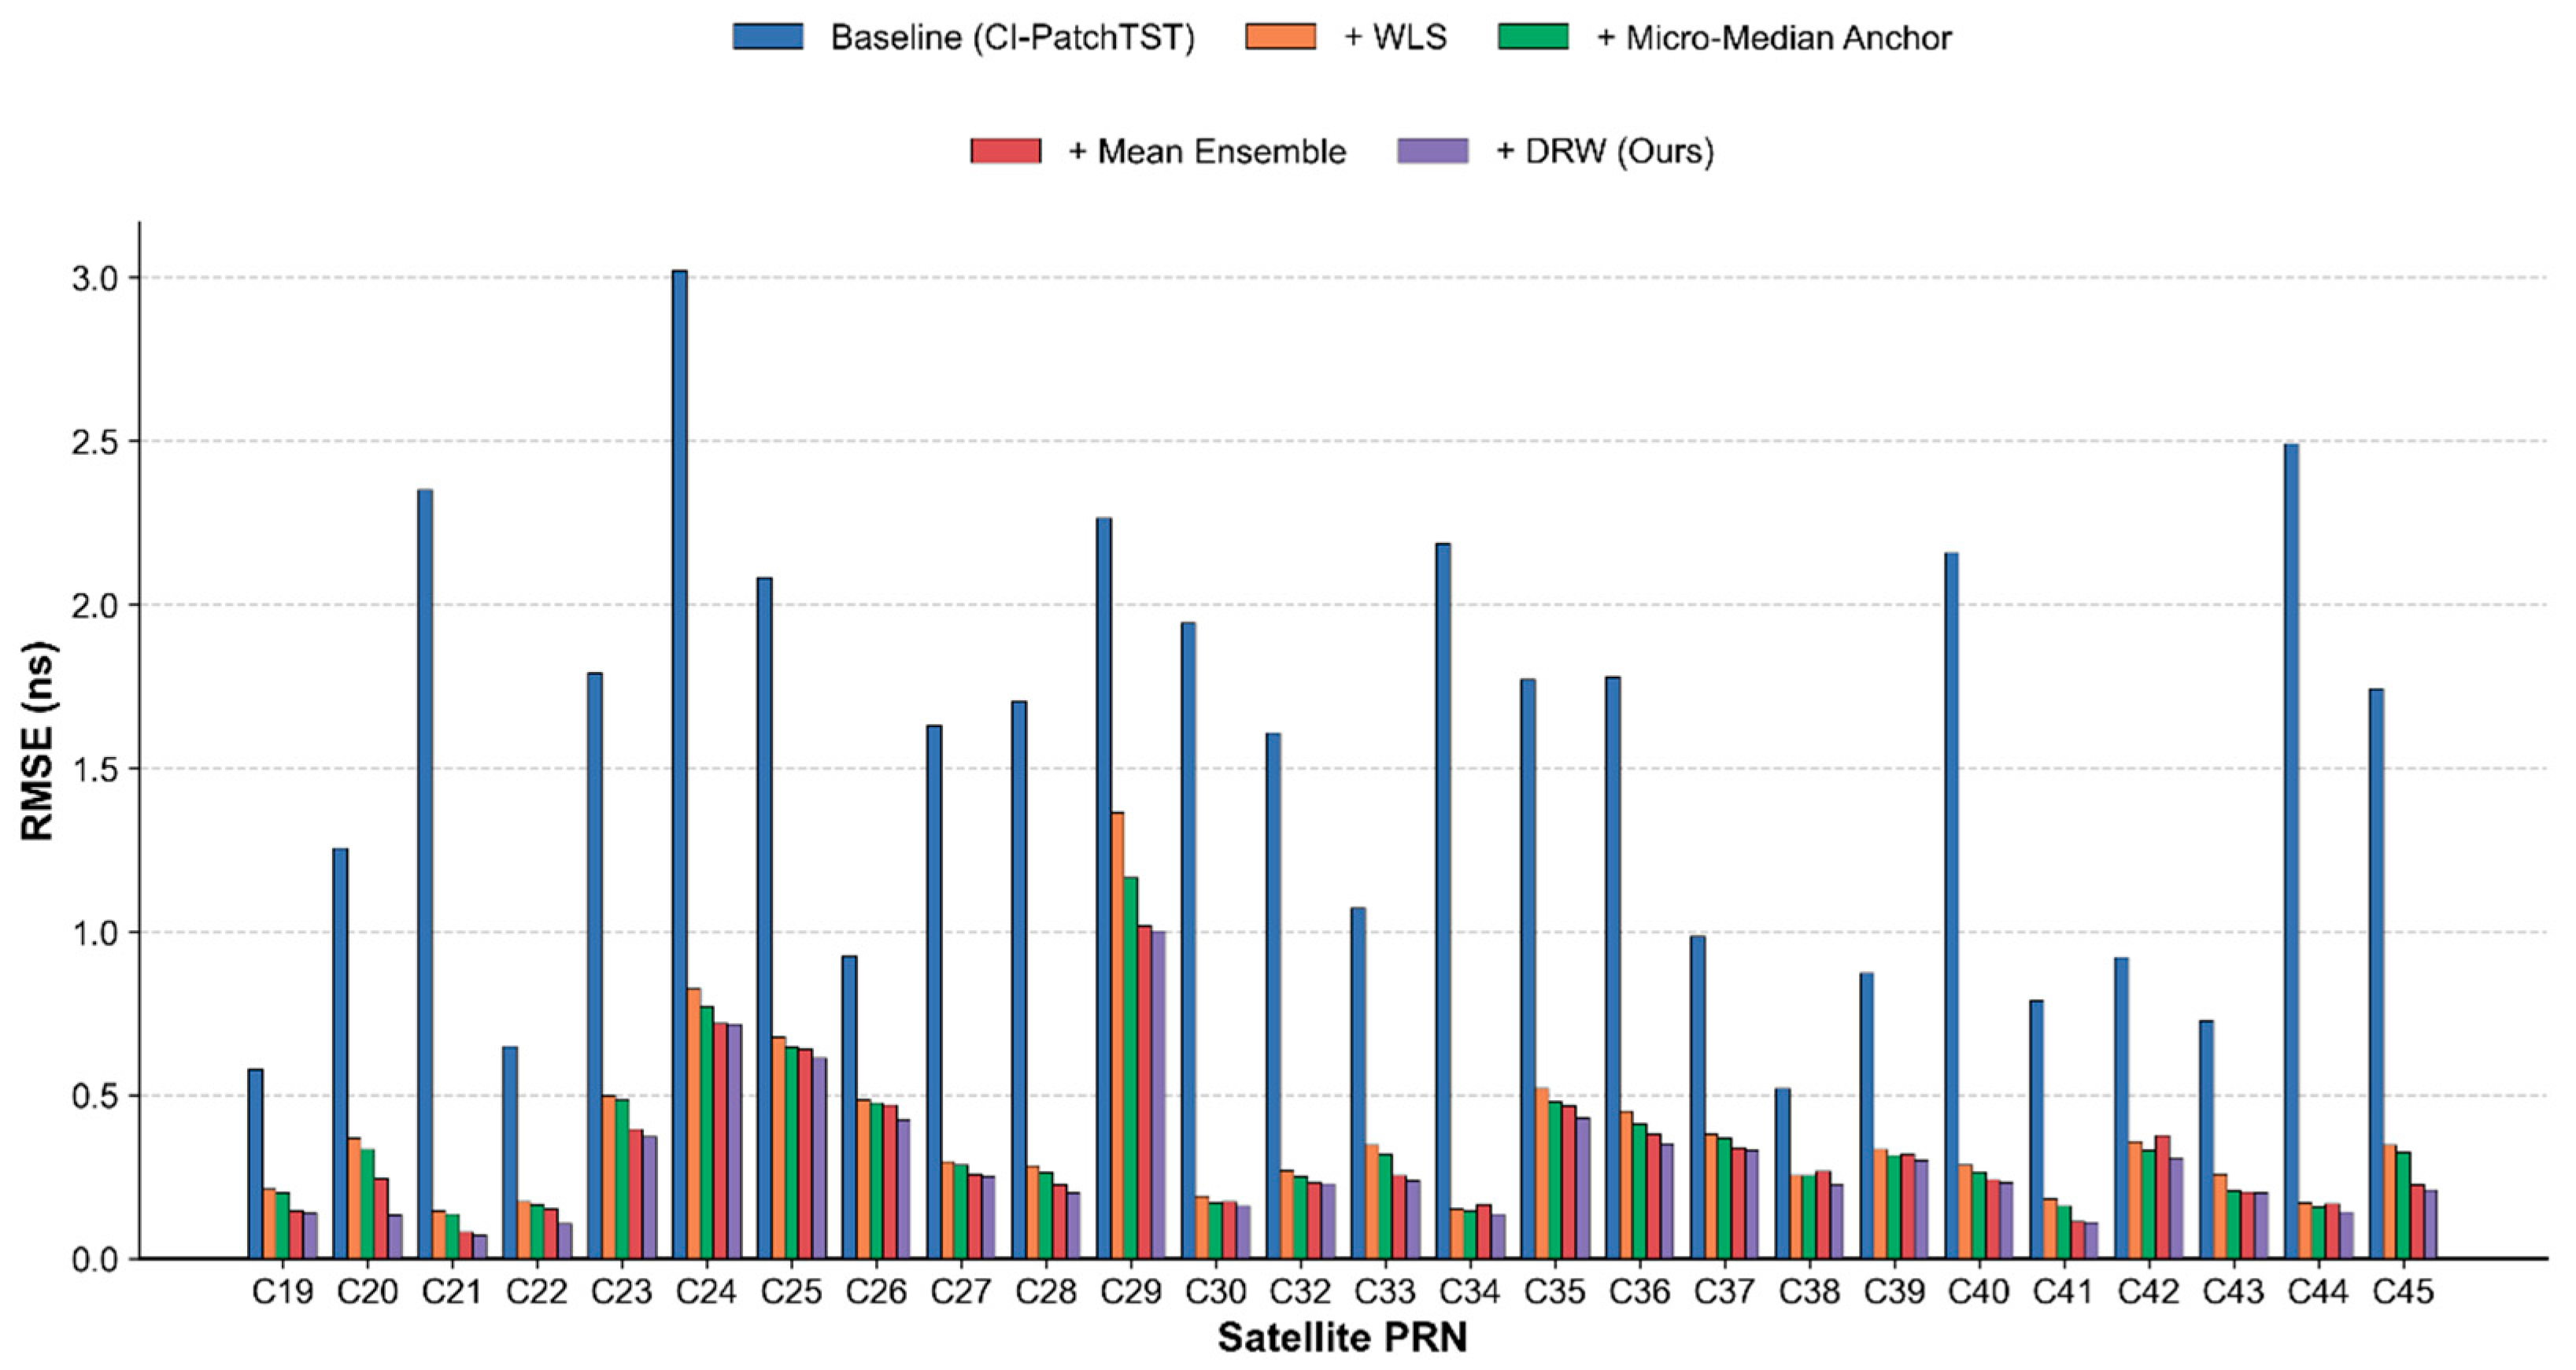
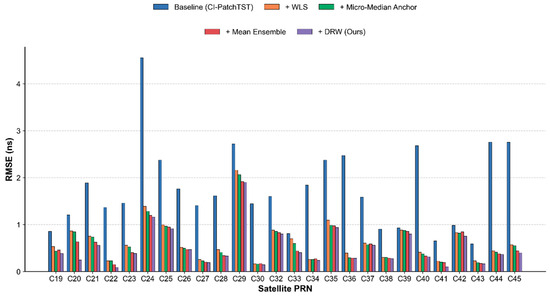
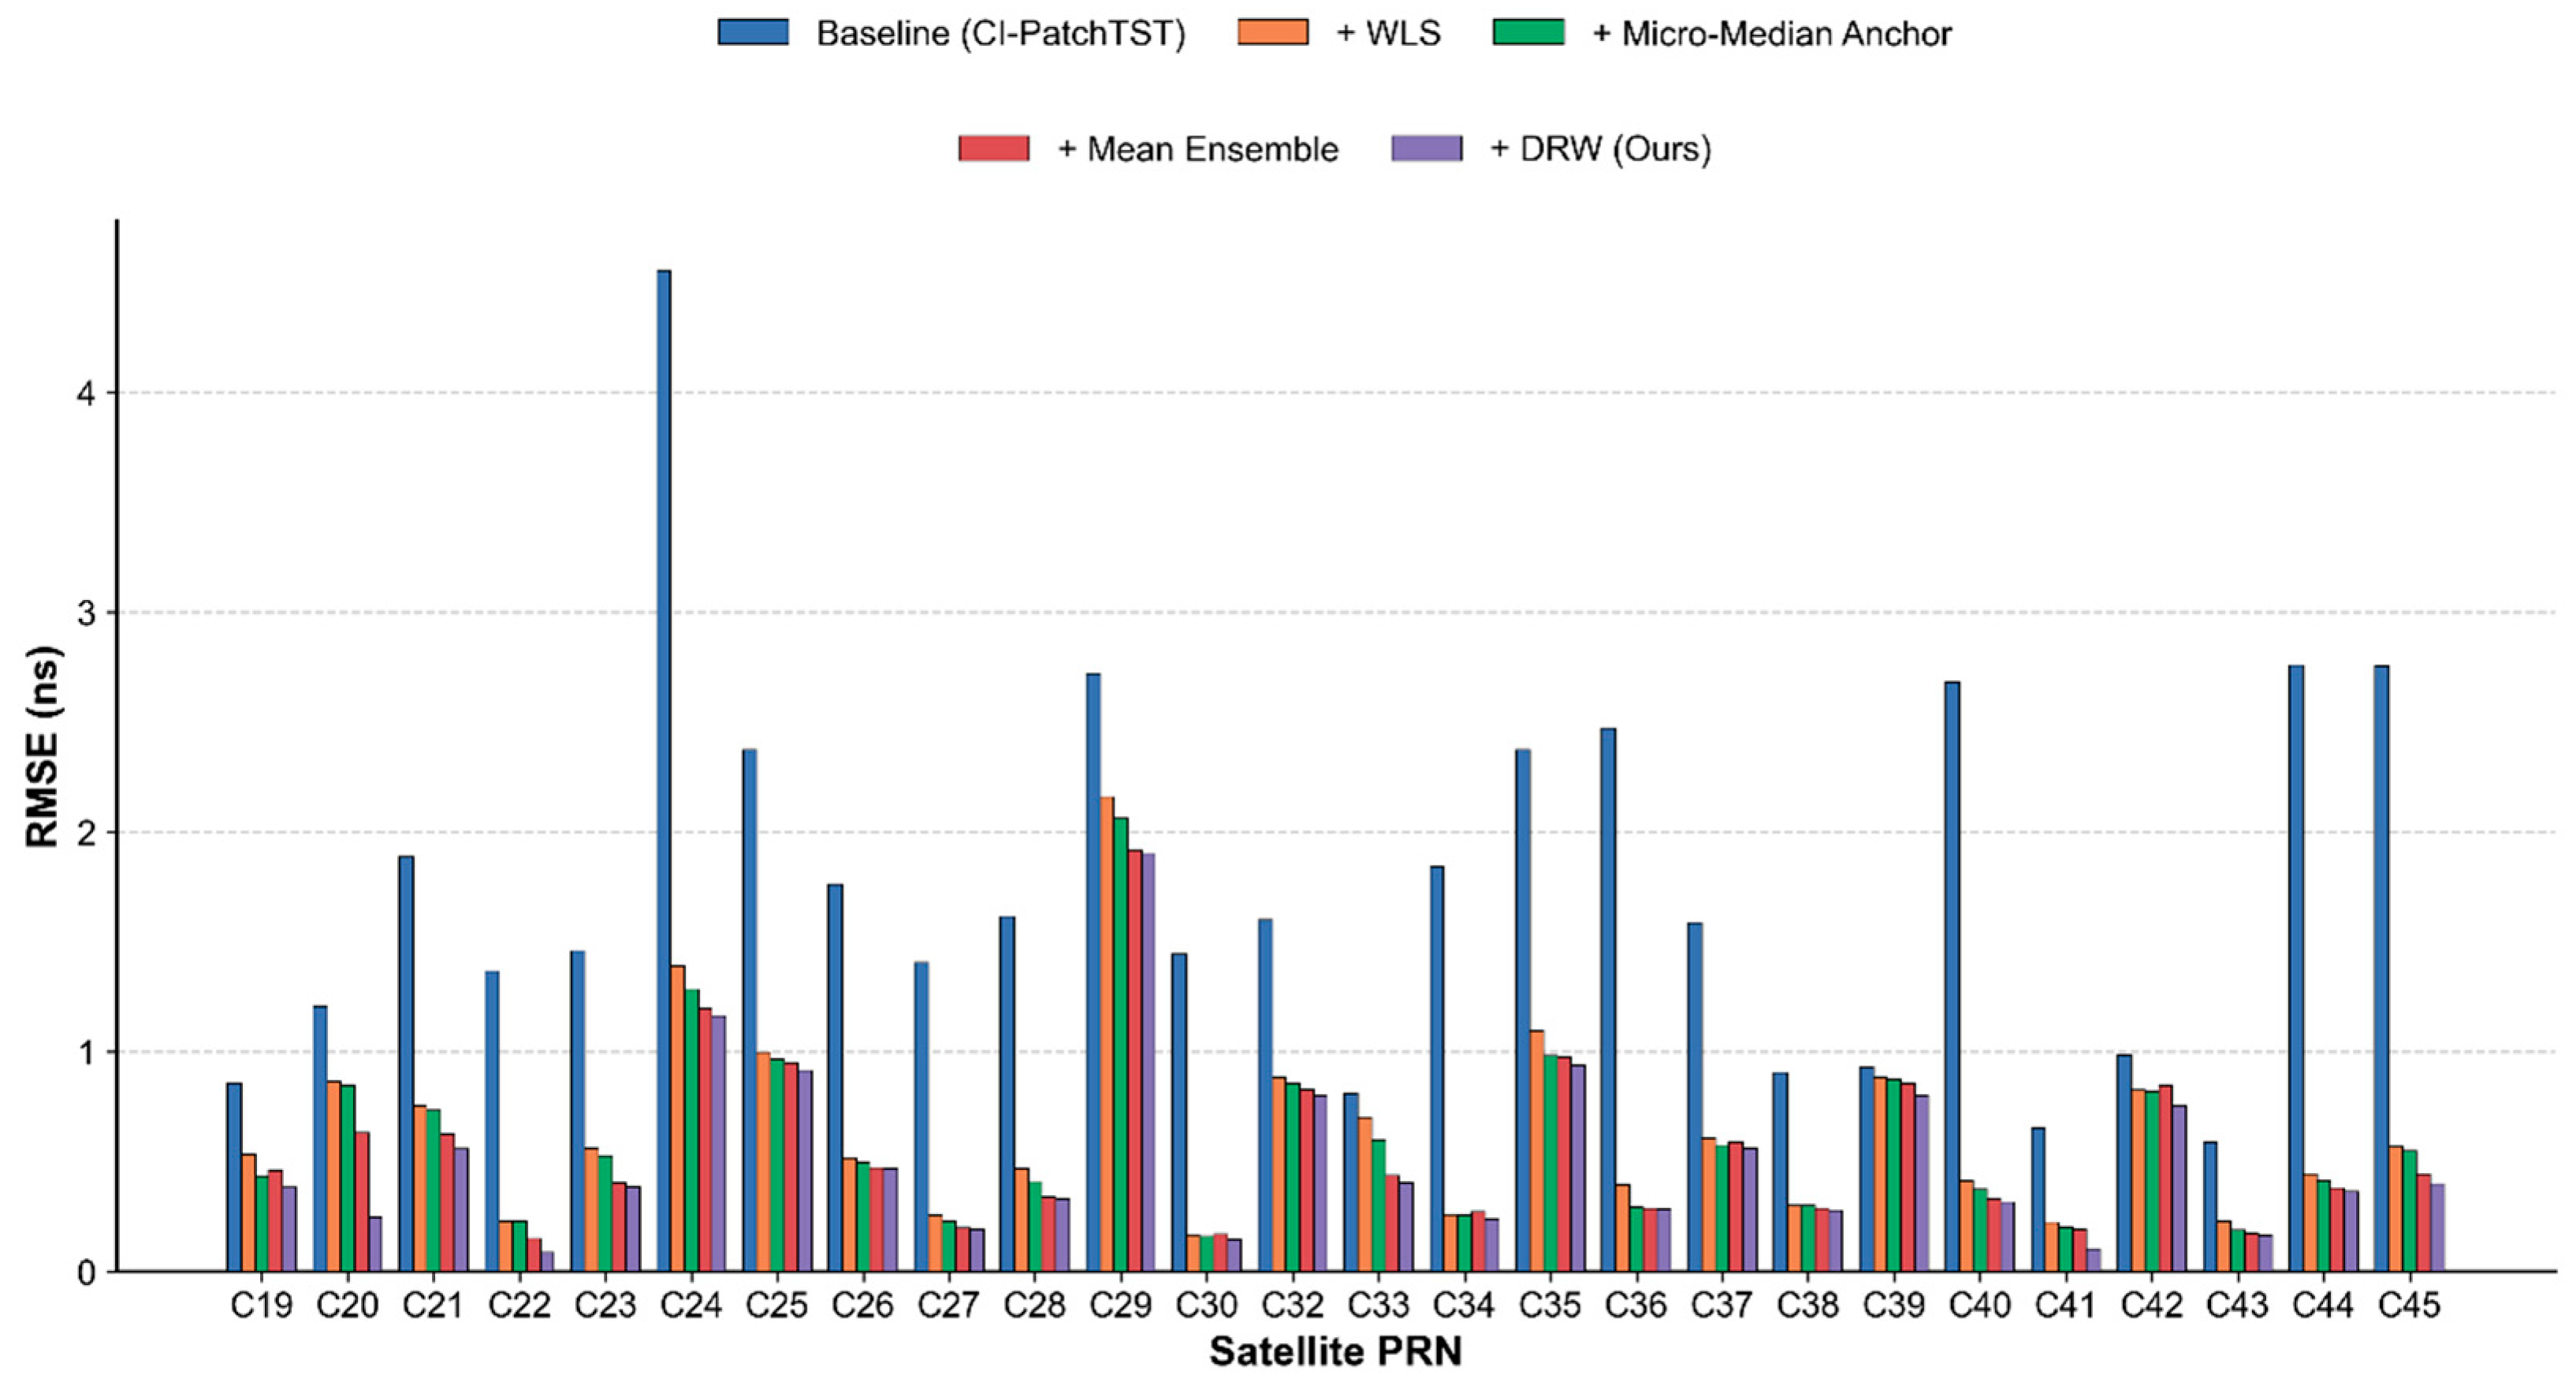
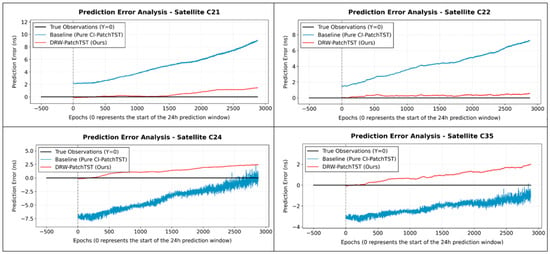
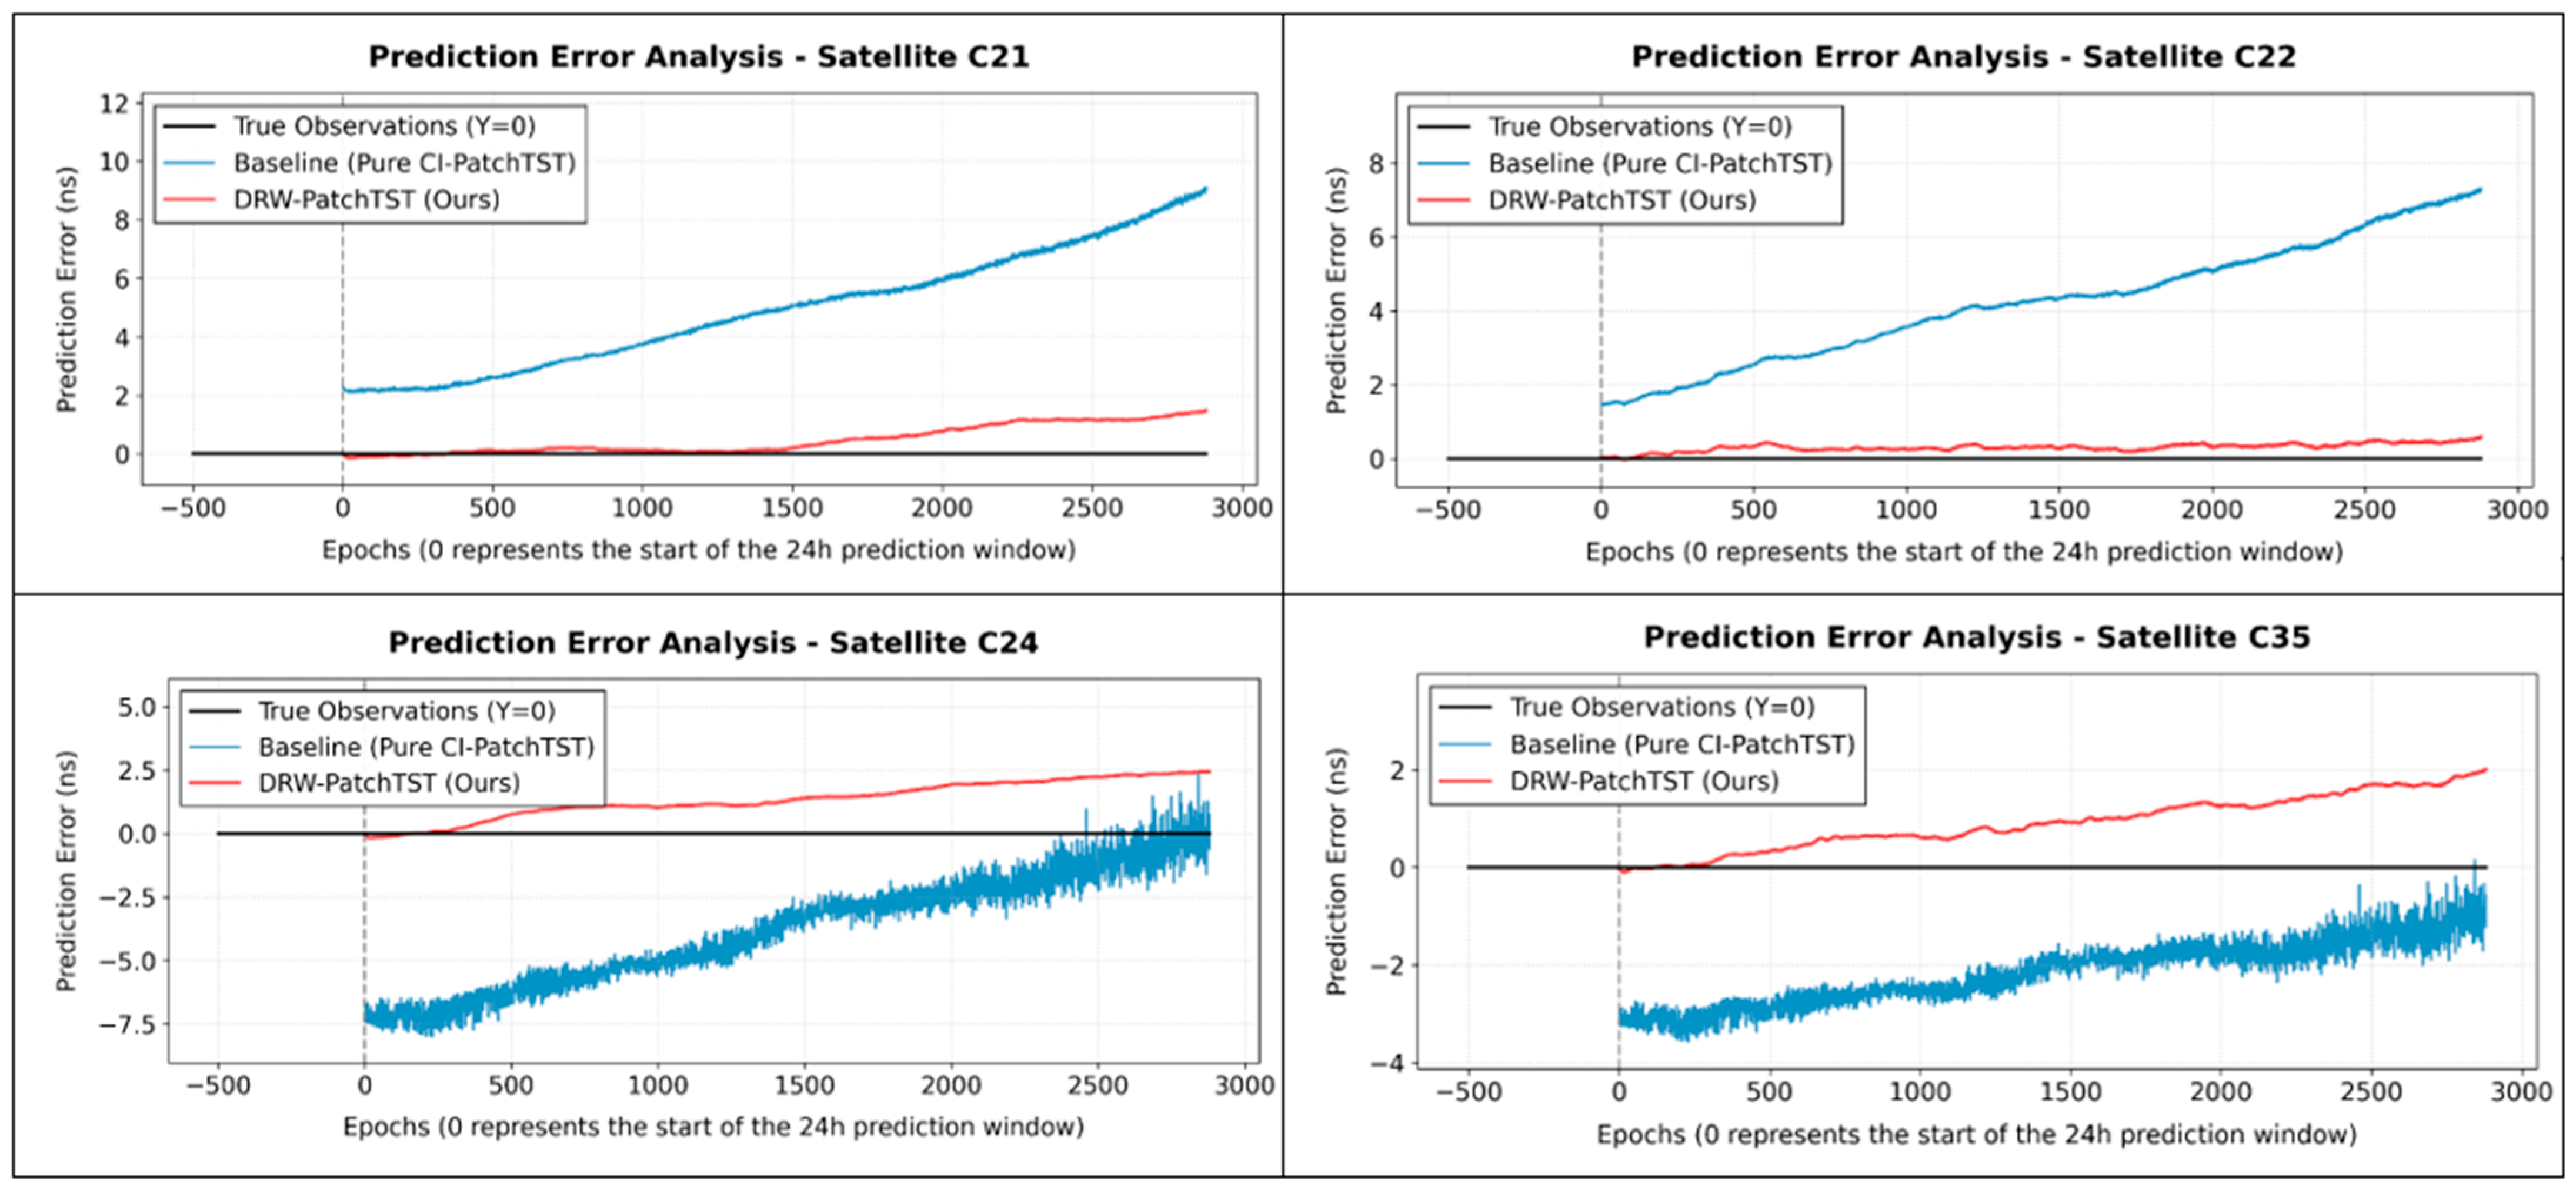
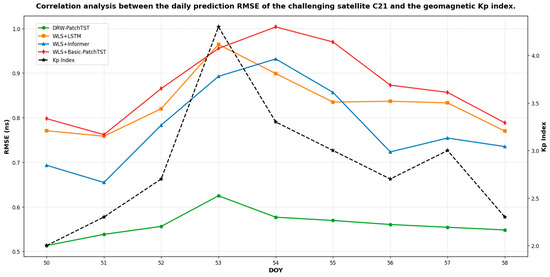
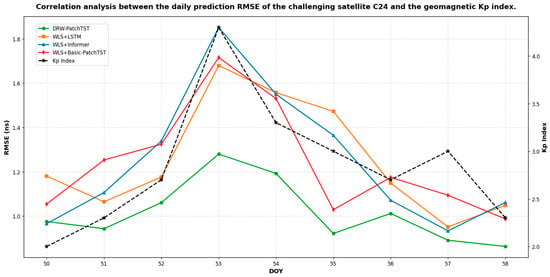

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.