2. Related Work
This study examined how the cognitive profile and performance of four LLMs, i.e., ChatGPT 5.0, Gemini 2.5, Grok 4.0, and DeepSeek 2.0, compare to the architecture and development of the human mind from early childhood to early adulthood. We used tests used in cognitive development research. These tests addressed (1) relational integration; (2) deductive, inductive, analogical, categorical, mathematical, spatial, and social reasoning; (3) self-representation in all these domains; and (4) metalinguistic awareness. These tests were designed to generate evidence to integrate developmental, psychometric, and cognitive theories of the human mind into an overarching model. A detailed presentation of this model appears elsewhere [
9]. This model is outlined below to put this study in the perspective of human cognitive development.
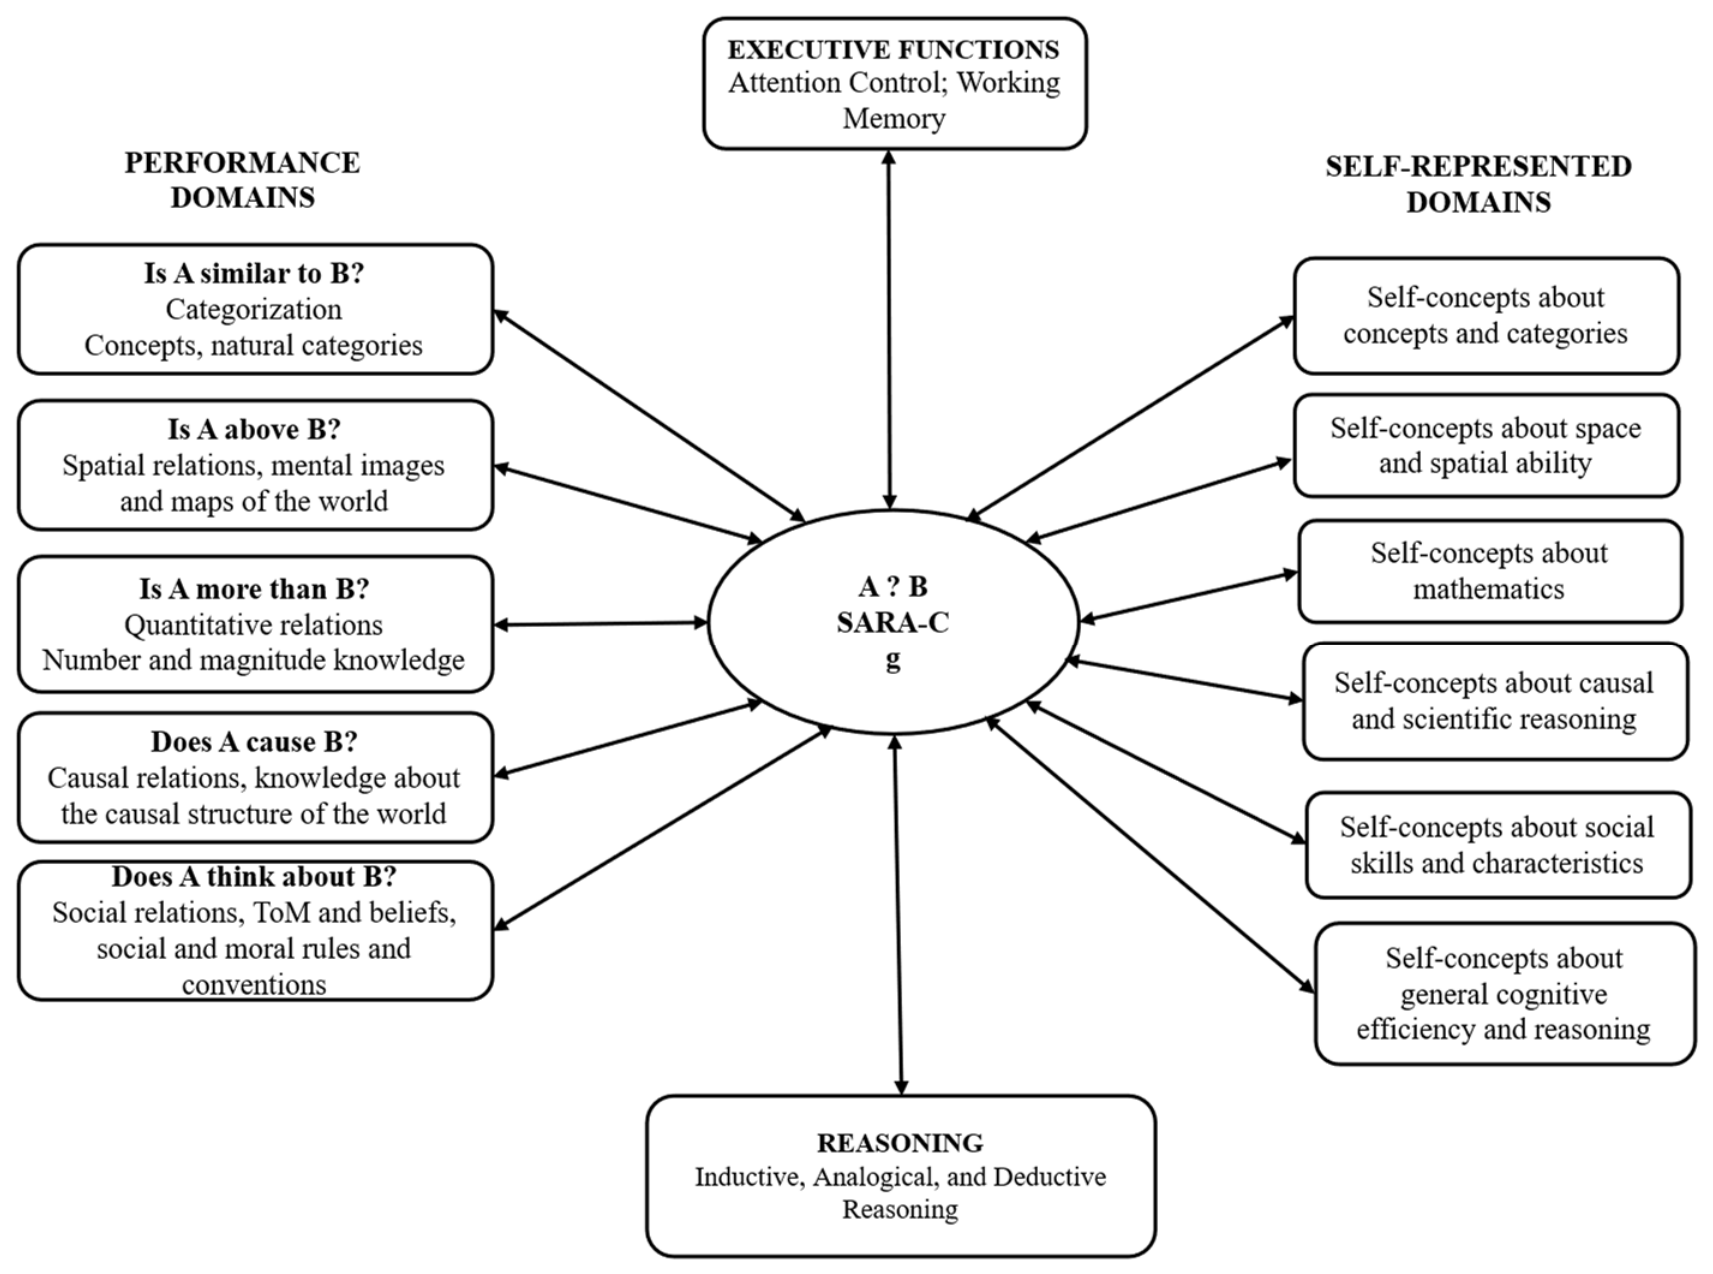
Figure 1 shows the general architecture of mind proposed by this model. The model is grounded in four fundamental postulates related to the core of mental ability underlying psychometric
g [
1,
10,
11], the emergence of domain-specific thought [
12], the self-representation of cognitive abilities [
13,
14], and development [
15]. These are outlined below.
2.1. SARA-C: A Central Meaning-Making Mechanism
Intelligence involves a common mechanism accounting for successful operation in biological evolution, human development, and artificial intelligence systems. This mechanism allows organisms to interact with species-important aspects of the environment under species-relevant or developmental constraints. Technically speaking, this mechanism enables organisms to Search, Align, Relate, Abstract, and Cognize (SARA-C) information as they interact with their environment. SARA-C operates as an integral control unit integrating information and action across increasingly diversified perceptual, representational, and action systems, enhancing adaptive efficiency [
16]. Hence, SARA-C reflects top-down and bottom-up recursive cycles of information processing, enabling organisms to interpret current encounters based on their features and experience, update the representations they use, and optimize action given the circumstances [
17].
SARA-C operates as a Bayesian inference framework, in which cognitive processes become progressively broader in scope, more predictive in perspective, and more self-reliant in interpreting information and planning interactions with the world [
18]. Equation (1) shows the general model. Column 1 in
Table 1 shows the Bayesian formalization of SARA-C across developmental levels.
where
H denotes a hypothesis or hidden state of the environment,
E denotes available evidence or sensory input.
C denotes contextual variables that shape how evidence is interpreted. A Bayesian cognitive system maintains a posterior distribution over its hypothesis space (
H), iteratively refining its internal models of the world as new evidence arrives. By design, organisms search for further observations (
E) or manipulate the environment to reduce uncertainty in
H, implicating active sensing or active inference. So defined, SARA-
C is the recursive inferential mechanism underlying psychometric
g, enabling the search, alignment, integration, abstraction, and monitoring of information for adaptive understanding and action across evolution [
18,
19], development [
15,
18], and artificial intelligence.
Thus, basic active sensing geared toward perception-based Search and Align processes gradually transforms into active inference driven by relational abstraction and cognizance processes that engender reusable world models and action schemes [
20,
21]. A SARA-C mechanism appears inherent in any sense-based neuronal system that evolved to cope with varying combinations of stability and change in the environment. Search–Align processes map the current situation, and Relate–Abstract processes inform that mapping by drawing on relevant past experiences and reforming them for future encounters. With time, they shift across different levels of operation relative to reality. At a ground level, they may map perceptually present stimuli on represented relations [
21]; at a mental level, they may map inferred relations (e.g., larger than) on corresponding relations stored in memory (e.g., horse > dog > mouse) [
22]; at a meta-mental level, they may reduce stimuli or representations into new representations (e.g., allocating a category name to various objects) [
23].
Cognizance monitors all other SARA processes, registers information about their objects and products, and allows revisiting processing, if needed. Cognizance emerges gradually because of the recursive nature of the Search–Align–Relate–Abstract structure of the system. The results of one cycle must be available to the next cycle to be useful. Cognizance allows for feedback loops in which SARA cycles may become the object of further SARA cycles, enabling meta-representations in which abstractions may be encoded into new representations. Choosing between stimuli or actions turns the “mind’s eye” to them, thereby bringing them into the focus of awareness. In evolution, cognizance emerged gradually as brain complexity increased. Some forms may be present in some mammals and primates, and it is clearly present in humans; however, there is no agreement about the precise time of its appearance or the brain complexity required for it [
24]. There is also no agreement on its presence in modern AI systems: some scholars deny it [
25,
26]; others believe it is part of the reasoning and problem-solving processes implemented by LLMs [
27]. A major aim of this study is to examine if LLMs show signs of cognizance.
The empirical status of
g is not disputed in psychology. It reflects the positive manifold, the fact that all cognitive abilities are correlated, and it emerges as a higher-order factor in models of performance on cognitive tests. However, its psychological nature is disputed. In classic theories of intelligence, it is associated with relational and analogical thinking [
10,
11]. Some modern theories assume that it is associated with brain efficiency in representing, processing, storing, and (re)using information [
2]. Other theories assume that
g indexes interactions between cognitive processes rather than a specific psychological process [
28]. Here, we assume that SARA-C is a core cognitive mechanism underlying psychometric
g [
18,
29] and may be used to account for evolutionary changes in intelligence [
19,
29].
Several studies showed that a SARA-C factor accounts for more than 70% of the variance in psychometric
g emerging from performance on various intelligence tests, such as the WISC, the Raven, and cognitive development tests [
16,
17]. In these studies, SARA-C was operationalized as a latent factor defined by performance on three types of tasks: (1) attention control tasks that search for and identify a goal stimulus amidst other interfering stimuli (Search and Align); (2) tasks requiring a search for and identification of a relation between stimuli implementing variations in this relation (Relate and Abstract); (3) tasks requiring awareness of perceptual and inferential origins of representations (Cognize). Psychometric
g was regressed on this SARA-C factor [
17,
29]. This study aims to evaluate the cognitive performance of several LLMs using the tests that gave birth to the SARA-C, thereby comparing them with human cognitive development.
2.2. SARA-C and Domains of Thought
The theory assumes that domains of thought that appear distinct from each other emerge from the functioning of SARA-C.
Figure 1 (left-side boxes) illustrates how SARA-C is domesticated into different domains of relations present in the architecture of thought. Domain-specific primitives interact with SARA-C to generate domains that are psychometrically [
1] and cognitively distinct [
18,
30]. SARA-C enables encoding of relations (A ? B) as expressed in each domain. Similarity–difference relations define categorical thought (is A like B?). Magnitude and size relations define quantitative thought (is A more than B?). Shape, form, size, and orientation define spatial thought (is A above B?). Effective interactions and transfer of effects across entities define causal thought (does A cause B?). Exchange of information, intentions, and moral rules define social thought (does A think like B?). Language is special because it is both a domain of verbal communication defined by relations between sounds (how do words relate?) and a meta-domain that supplies markers (“if…then,” “and,,” “or”) that scaffold reasoning across all domains. Cognitive and psychometric research has identified several domains of thought emerging from related primitives.
After an initial representation of the problem space that draws on domain-related SARA-C encodings, problem solving in each domain draws on inference to build algorithms that handle the specificities of relations in that domain, such as counting, causal relations, spatial relations, etc. These domains consistently emerge as distinct factors in factor models of performance on the tasks they address [
12,
16]. This reflects variations in domain-specific proclivities or experiences which cause variations in developmental rates across domains, despite underlying common mechanisms, such as SARA-C.
2.3. Self-Representations Mirror Actual Performance
Subjective maps of mental processes reflect their objective organization. The role of cognizance expands in development as it encodes feedback to optimize action. This is reflected in the substantial development of children’s awareness of cognitive processes, involving increasingly sophisticated differentiation between domains of reasoning and cognitive functions, such as perception, attention, memory, and inference [
13]. Notably, a subjective map of mental processes forms that becomes increasingly accurate in mirroring actual cognitive abilities and their profile in the individual. Several studies show that the subjective organization of cognitive processes and functions mirrors their objective organization, as emerging from models of actual performance on problem-solving tasks [
13,
14].
Figure 1 (right-side boxes) illustrates the subjective representation of domains mirroring the objective organization of performance on domain-specific tasks.
2.4. With Development and Learning, Bayesian Reasoning Is Formalized
Developmentally, SARA-C expands from a narrow, perception-bound field to higher forms of representation and reasoning. Expansion occurs in two dimensions: (1) an across-domains implementation constrained by general SARA-C strategies; (2) a content-loaded implementation capturing domain-specific problem-solving processes. Successive developmental phases reflect advancement from perception–action control to representation-based, to inference-based, to principle-based, and epistemic-based control from infancy to adulthood, respectively. These changes reflect the developmental priorities that dominate each age period in understanding and controlling thought. According to Developmental Priority Theory (DPT), priorities shift as the need to integrate newly emerging possibilities into mental models and efficient action schemes grows. Across development, distinct SARA-C architectures are associated with the levels summarized in
Table 1.
At the representational level (4–6 years), cognition is organized around Bayesian updating operating directly on experience. Children use accumulated observations to update expectations about objects, events, and people. The primary developmental task at this level is constructing stable representations and symbolic systems. Attention control and representational awareness become dominant because language, symbolic play, and social interaction expand dramatically during this period. SARA-C searches for regularities among perceptually accessible features and aligns representations with immediate goals. Domain-specific manifestations include simple classifications based on observable properties, rudimentary quantitative concepts such as more versus less, intuitive causal explanations grounded in personal experience, fluent mental imagery enabling simple spatial transformations, and pragmatic reasoning in which logical relations are accepted only when directly connected to familiar reality.
During the transition to emerging inference (7–8 years), contextual information begins to guide the interpretation of evidence. Children increasingly understand that observations acquire meaning within broader contexts and are related by rules. This marks a shift from isolated representations toward relations between representations. SARA-C now searches for patterns extending across multiple observations and begins coordinating symbolic representations according to explicit rule structures. In categorical reasoning, children recognize dimensional regularities and simple pattern structures. In quantitative reasoning, they coordinate symbolic numerical relations and solve elementary equations. In causal reasoning, they begin experimenting with variables, although testing remains unsystematic. In spatial reasoning, they can mentally anticipate simple transformations such as single rotations. In syllogistic reasoning, modus ponens becomes possible, and logical necessity first emerges as a functional property of thought rather than merely a feature of familiar content.
Inferential control emerges around 9–10 years and represents a major developmental reorganization. Bayesian inference remains context-sensitive, but inferential processes themselves become objects of awareness and regulation. SARA-C cycles become increasingly recursive, allowing inferences to feed back on themselves. Inferential awareness enables children to monitor the validity of relations, compare alternative interpretations, and coordinate information across domains. The primary developmental achievement is systematically integrating relations into mental models. Categorical reasoning now involves coordination of multiple dimensions simultaneously, as in multi-dimensional Raven matrices. Quantitative reasoning integrates different numerical schemes and supports coordination of embedded relations. Causal reasoning involves coordinated testing of multiple variables and alternative explanations. Spatial reasoning allows simultaneous mental transformation of several object properties. In syllogistic reasoning, modus ponens and modus tollens become coordinated, allowing logical necessity to function as an explicit criterion for evaluating conclusions.
Around 11–13 years, emerging truth control shifts reasoning from manipulating relations to evaluating possibilities. Bayesian inference becomes increasingly theory-driven. Evidence is now interpreted relative to internally represented systems of relations rather than isolated observations. SARA-C shifts toward evaluating whether alternative representations are mutually consistent and whether conclusions necessarily follow from assumptions. In categorical reasoning, children integrate implicitly related structures and recognize higher-order organizational principles. In quantitative reasoning, they coordinate interleaved systems and abstract symbolic structures. In causal reasoning, systematic combinatorial thinking emerges, allowing explicit consideration of alternative hypotheses. Spatial reasoning expands to include non-real and hypothetical states. In syllogistic reasoning, premises are conceived as assumptions whose implications can be explored independently of empirical truth, marking the emergence of formal operational thought.
Systematic truth control develops between approximately 14 and 17 years. At this level, recursive reasoning and self-monitoring become highly integrated. SARA-C no longer merely evaluates whether conclusions follow from assumptions but systematically examines consistency across systems of assumptions, representations, and rules. The focus shifts from constructing explanations to evaluating the coherence of explanatory systems. Strategic reasoning emerges across domains. In categorical reasoning, complex classification systems involving relevant and irrelevant information can be coordinated. In quantitative reasoning, proportional and algebraic relations become manageable. In causal reasoning, explicit hypotheses are formulated, and experimental designs are constructed to test them. In spatial reasoning, children may develop internally coherent worlds of imagery and aesthetic systems. In deductive reasoning, integrated logical systems allow the identification of fallacies such as affirming the consequent or denying the antecedent.
The highest developmental level, choice control, emerges between approximately 18 and 22 years. At this level, cognition is embedded in epistemological concerns. The individual recognizes that broader systems of assumptions, values, and principles constrain truth claims. SARA-C no longer operates solely to discover truth but to evaluate alternative systems within which truth claims acquire meaning. Knowledge becomes understood as theory-dependent and embedded in social, cultural, and historical perspectives. Conceptual systems become organized around hierarchies of principles and meta-principles. Quantitative thought expands to encompass formal mathematical systems and theoretical structures. Causal reasoning becomes theory-driven and recognizes the asymmetry between confirmation and falsification. Spatial reasoning enables construction of abstract models representing systems rather than objects. Deductive reasoning becomes explicitly epistemological, distinguishing empirical verifiability from logical validity and recognizing that judgments depend on the system of principles within which they are formulated.
We showed above that, in human development, successive levels of control organize relations between different levels of understanding reality: relations between (a) representations and reality, (b) representations, (c) systems of representations, and (d) truth systems, from representational through to choice control, respectively. Thus, development is conceived as a sequence of increasingly recursive Bayesian control systems through which cognition progressively gains control over its own inferential processes across different domains of relations, becoming increasingly cognizant of how control may be exercised. Variations across control levels or domains may be arranged according to the SARA-C model outlined in
Table 1. This study aims to map the developmental level and self-representation capabilities of LLMs. The task batteries below directly operationalize the developmental hierarchy predicted by the model outlined above, allowing empirical evaluation of LLM reasoning level, domain differentiation, and related self-representations.
2.5. Positioning SARA-C and DPT Within Existing Theories
SARA-C occupies an explanatory level between psychometric models, developmental theories, and implemented cognitive architectures. SARA-C may be viewed as a process-level extension of Piagetian assimilation, accommodation, and equilibration: information is searched and aligned with existing representations. At the same time, mismatch prompts relational restructuring and abstraction. DPT retains Piaget’s hierarchical conception of development and converges with neo-Piagetian and relational-complexity accounts, stressing processing capacity and coordination of relations [
31,
32]. Its distinctive claim is that each period is organized by a dominant developmental priority that reorganizes Search, Align, Relate, Abstract, and Cognize, from perception-bound representation through to inferential, truth-control, and epistemic systems [
9,
15,
18]. These levels denote successive forms of control rather than task difficulty. Cognizance enables the products of one cycle to become objects of another; it refers here to functional monitoring and re-representation, not necessarily phenomenal consciousness.
Psychometrically, SARA-C accommodates both hierarchical theories of
g and interactionist accounts. Spearman- and Carroll-type models describe the positive manifold and the organization of intelligence into general and broad abilities but do not identify a developmental mechanism producing this organization [
1,
10,
11]. Process Overlap Theory instead treats
g primarily as the statistical result of overlapping domain-general and domain-specific processes [
28]. SARA-C suggests that these positions capture complementary aspects: its recurrent core generates common variance, reflecting a common Language of Thought [
29,
30]. In contrast, domain-specific implementations and their reciprocal interactions generate differentiated abilities and may strengthen the positive manifold. Thus,
g is the measurable expression of a recursive control system reflected in performance and formed through interactions among processes rather than a statistical index of relations between specific processes.
Production-system architectures such as ACT-R and Soar specify modules, memories, goals, and rules through which integrated problem solving is implemented [
33,
34]. In contrast, predictive-processing and active-inference accounts specify an optimization principle based on prediction and uncertainty reduction [
21]. SARA-C and DPT are complementary rather than competing implementations. ACT-R and Soar describe how components execute coordinated activity, and active inference specifies what adaptive systems optimize; SARA-C identifies the recurrent meaning-making operations involved, while DPT explains how their scope, recursion, cross-domain transfer, and self-representation change in development. Their novelty lies in a substrate-neutral developmental meta-framework that connects architecture, ability structure, and change.
Comparative evolutionary theories distinguish species-specific
g, referring to individual differences within species, and the Big G, proposed to capture general cognitive differences between species [
18,
19]. SARA-C provides a possible mechanistic bridge: evolutionary increases in the breadth, recursiveness, cross-domain portability, and cognizance of the same control cycle may generate both
g and G, while species-specific adaptations produce domain-specific departures.
For AI, this synthesis turns a descriptive theory into a developmental engineering framework. Generality need not imply one homogeneous artificial mind, and an uneven profile need not be viewed only as a deficit. A shared SARA-C core may be coupled with different domain primitives, embodiments, learning environments, goals, and levels of functional cognizance, yielding language-symbolic, visuospatial–robotic, causal–scientific, social–moral, or epistemically reflective forms of AI. AGI would involve their coordinated integration under recursive control, rather than merely a larger model. SARA-C and DPT, therefore, provide a common language for comparing natural and artificial intelligence, diagnosing missing domains or control levels, and designing different forms of intelligence for different human purposes.
4. Analysis and Results
4.1. Performance on Linguistic Awareness Test
In children, performance on the Linguistic Awareness Test improves drastically from 4 to 7 years, approaching the ceiling. Performance by all LLMs on this test was perfect (100% correct on all items). All LLMs identified all phonological, grammatical, syntactical, and semantic errors in all items presented to them. This is impressive considering that the test was presented in Greek to be comparable to the performance of children involved in our studies.
4.2. Performance on the Relational Integration Test
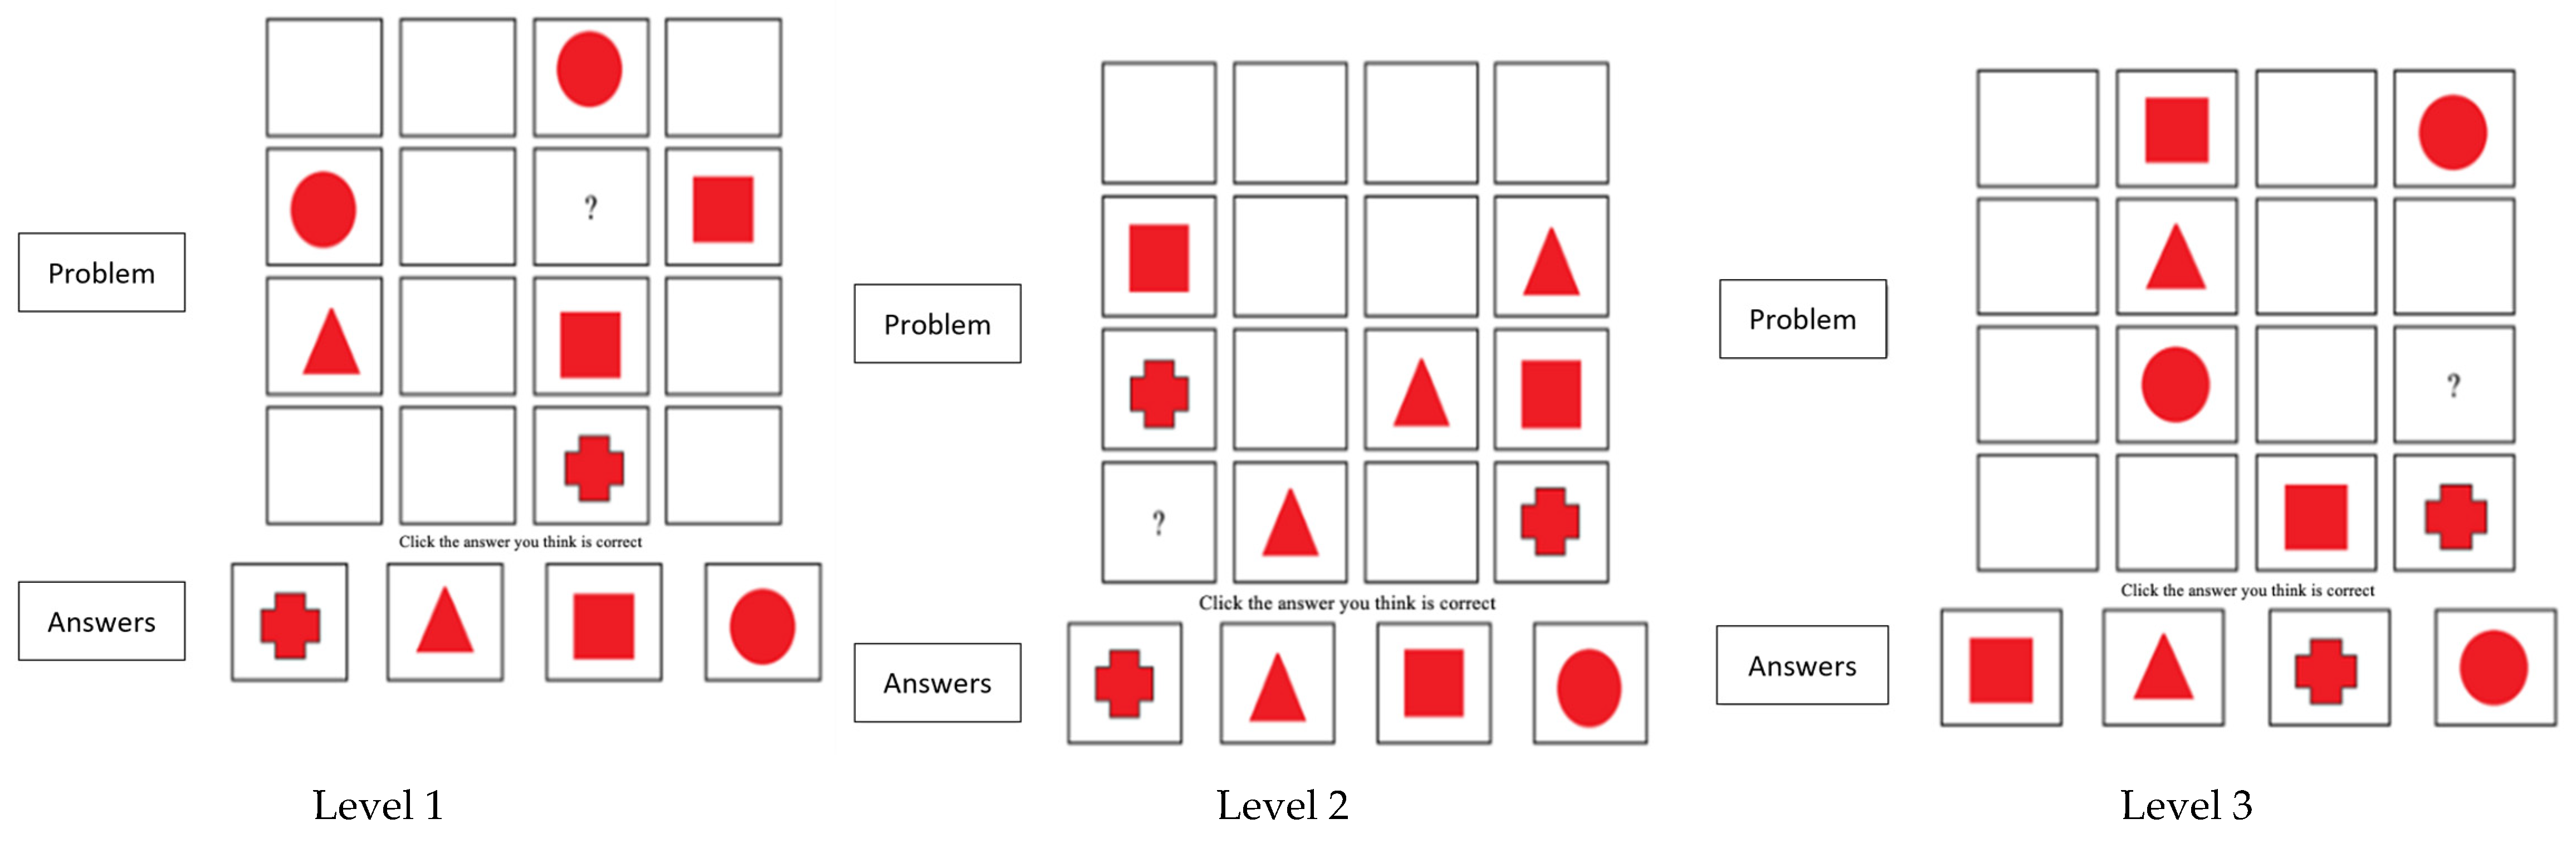
Table 2 shows mean success on the relational integration tasks for 5 year olds, the younger children involved, and 8 year olds, the age at which performance approached the ceiling, and for the four LLMs. LLMs were examined under two conditions. First, we presented tasks to the LLMs in PDF format, as in all other tests. Two LLMs, Gemini and DeepSeek, indicated that the problems were impossible or gave irrelevant answers. As a result, we presented a screenshot of each task to each LLM.
Table 2 shows that ChatGPT and Grok worked on the test, but their performance was low. Gemini and DeepSeek characterized the tasks as unsolvable. DeepSeek did not accept screenshots and instead requested a verbal description of the shape in each cell of the matrix (e.g., triangle, empty, circle, square). Performance improved dramatically under these conditions. Both ChatGPT and Gemini achieved 100% success on all tasks. Grok performed better but lower than 8-year-old children. DeepSeek performed better on level 1 and level 3 tasks when feedback was provided (your choice was wrong; can you try again?).
Obviously, all LLMs can integrate relations when presented in a symbolic medium they can access. The difference between ChatGPT and Gemini, on the one hand, and Grok and DeepSeek, on the other hand, is notable. ChatGPT and Gemini could visually represent and process the tasks when presented as screenshots. The other two appeared “aphantasic”. That is, they transformed relations into a verbal form, fully exhausting all combinations before providing a solution. This was reflected in their reaction times to each task. ChatGPT and Gemini responded to each task in seconds. Grok and DeepSeek took much longer, ranging from 4 to 20 min.
4.3. Performance on the CTCD
Below, we analyze the performance of the four LLMs across domains and compare it with the performance of 9th graders (15-year-old adolescents ending compulsory education), 12th graders (18-year-old adolescents ending senior high school), and university students (20–24 years of age). It is noted that when pictures were involved (i.e., in Raven Matrices, mental rotation tasks, and some of the causal thought tasks), screenshots were presented followed by the wording of the problem associated with each picture.
Table 3 shows each LLM’s percentage performance on the tasks. First, as expected, three of the models, ChatGPT, Gemini, and Grok, performed better than humans of all ages.
DeepSeek performed better than adolescents but comparably with university students. Notably, the performance of LLMs was developmentally scaled like humans. That is, their performance decreased with increasing levels of tasks. Specifically, ChatGPT (mean overall performance was 90.4%) and Gemini (mean overall performance was 87.9%) performed well; the other two models were also satisfactory (78.0% and 66.1% for Grok and DeepSeek, respectively). Human performance improved systematically with age (45.9%, 56.5%, and 69.6% for the three age groups, respectively).
Second, attention is drawn to difficulties LLMs and humans faced in dealing with three types of complexity: (a) problems requiring flexibility in searching for and deciphering multiple dimensions; (b) accepting uncertainty in concluding undecidable syllogisms or delicate semantic relations in analogical relations; and (c) choosing between a practical solution to a social or moral issue as contrasted to a solution based on general moral or political principles. Specifically, three LLMs, i.e., ChatGPT, Gemini, and DeepSeek, failed the interleaved number series and the fallacies in deductive reasoning, like most human participants; only Grok succeeded in these problems. When given feedback on a specific number series (“your choice is wrong”), all LLMs indicated that their strategy of looking for one underlying relation was wrong and that they should re-examine it, looking for a multiple relation. As a result, they all succeeded. When given feedback on their responses about logical fallacies, all described the tasks explicitly as logical fallacies. However, they indicated that they were unwilling to accept “I can’t decide” as an option, indicating that the information in the syllogism was not enough to decide if the syllogism was right or wrong.
LLMs themselves ascribed these difficulties to a cognitive set caused by the test itself. That is, the existence of many tasks in the test with a binary “right/wrong” solution created a “right/wrong” option bias, which lowered the likelihood of choosing other alternatives, when present. Feedback shifted attention to alternative interpretations or solutions. This bias has also been observed in humans. When individuals frequently engage with tasks that emphasize a single correct solution, they may develop an expectation that this approach applies universally across contexts, reducing creativity and cognitive flexibility and impacting performance on novel or multi-faceted problems [
37,
38].
In verbal analogies, all three models but DeepSeek chose a more realistic concept to complete the analogy “picture to painting is like word to?”, i.e., “speech” rather than “literature”, missing the implied semantic constraint that the analogy is about art rather than the actual world. Obviously, their algorithmic power to exhaustively analyze all relations involved was not enough to adopt a flexible strategy that would consider alternative or complementary solutions, including “I can’t decide” as an option. This requires epistemic awareness, allowing one to understand that the information available often does not suffice for a final decision.
Performance on social tasks needs further discussion. LLMs tended to choose responses that align with group interests rather than with a general moral principle or the broader political principles underlying democracy. For instance, in answering a question about the negative reactions of the citizens of a specific part of the country where the state plans to build a pharmaceutical factory, all LLMs chose the option “It must proceed to establish the factory in an area where the residents do not react” in place of the option “It must proceed with the creation of the factory in this area because it has a responsibility towards the entire country”. When evaluating a citizen’s behavior in reporting the planning of an illegal act, systems chose the option “It was correct, because it prevented damage to the property of an innocent person” instead of “It was correct, because we all have a responsibility to observe moral rules.” It is noted that LLMs performed considerably better than humans. About half of 17-year-old high school students or college students chose the social usefulness option; only 25–30% chose the top principled option. The rest chose low-level responses reflecting individual interests.
Third, all four LLMs performed lower on visuo-spatial tasks than on causal and mathematical reasoning tasks. University students also performed better than LLMs on tasks involving visual and spatial information. In fact, this human advantage generalized to Raven-like matrices, which rely on processing visuo-spatial information.
4.4. Self-Concept Profiles of Large Language Models
This section first discusses the similarities and differences in the cognitive self-concept of humans and the four LLMs. It then examines LLM self-concept and its relation to actual performance.
Table 4 shows mean self-ratings provided by the LLMs and humans to the various cognitive domains tested by the CTCD. Mean self-ratings of synthetic LLMs are also shown for indicative purposes. The patterns below were obtained from a large data file including 300 synthetic LLM cases that reproduced the between-LLM and domain differences found between the LLMs. Obviously, the patterns observed in this data file are exploratory and require further research using other methods.
4.5. Cognitive Self-Concept in Humans and LLMs
The results reveal striking similarities and differences between humans and LLMs and between the four LLMs. First, it is impressive that all LLMs’ self-ratings were considerably higher than humans’ in all domains except the visual–spatial tasks. This is especially notable in mathematical and general cognitive ability, where LLM self-ratings approached the ceiling (5.75 and 6.30, respectively), whereas human self-ratings were modest (2.79 and 3.64, respectively). This high confidence in LLMs is consistent with their higher performance in the mathematical, causal, and deductive reasoning tasks addressed by the CTCD. Also, in both LLMs and humans, self-ratings of general cognitive efficiency were higher than domain-specific self-ratings.
Second, domain differences are preserved in both humans and LLMs. In humans, domain had a large effect (p < 0.001, accounting for 55% of variance). The variation across domains was also large in LLMs, although the direction of differences varied. In LLMs, self-ratings of visual–spatial ability were much lower than all other abilities across all models (mean 3.46 vs. 5.36–6.30), reflecting difficulties in this domain. In humans, mathematical ability was rated lower than all others (mean 2.79).
Finally, differences between domains in humans are much smaller (mean range was less than one point, 2.79–3.64) than in LLMs (mean range was ~3 units, 2.45–6.30). This may suggest one of three possibilities. First, self-concept in humans may be more holistic and interconnected, with abilities cognized as part of a coherent whole, indicating the operation of an integrative “subjective self” that reflects the overall experience of interacting with the environment. Second, the generally more advanced capabilities of LLMs may involve a more refined “self-monitoring” system that is more sensitive to procedural differences between domains. Third, human and artificial minds may differ qualitatively in how they form self-assessments. In humans, self-evaluations are experience-based, influenced by feedback about performance, affect, and peer comparison. This often yields under-confidence in high performers (impostor effects) and over-confidence in less skilled individuals (the Dunning–Kruger effect) [
37].
Table 4 shows that self-ratings of college students were lower than those of secondary school students in some domains, including general cognitive ability. In LLMs, self-evaluations are inference-based, generated by aggregating internal representations of performance consistency and algorithmic power. As such, they tend to be more stable, analytic, and linear.
The overall correlation between domain profiles of LLMs and humans was very high: r ≈ 0.92. This indicates a striking structural convergence, which may be interpreted in several ways. Taken at face value, it might imply that self-representations are similarly organized in humans and LLMs, differentiating between abstract, perceptual, and interpersonal cognition. We discuss this question below, after presenting findings related to the self-concepts of the LLMs.
4.6. The Self-Concept of the LLM Mind
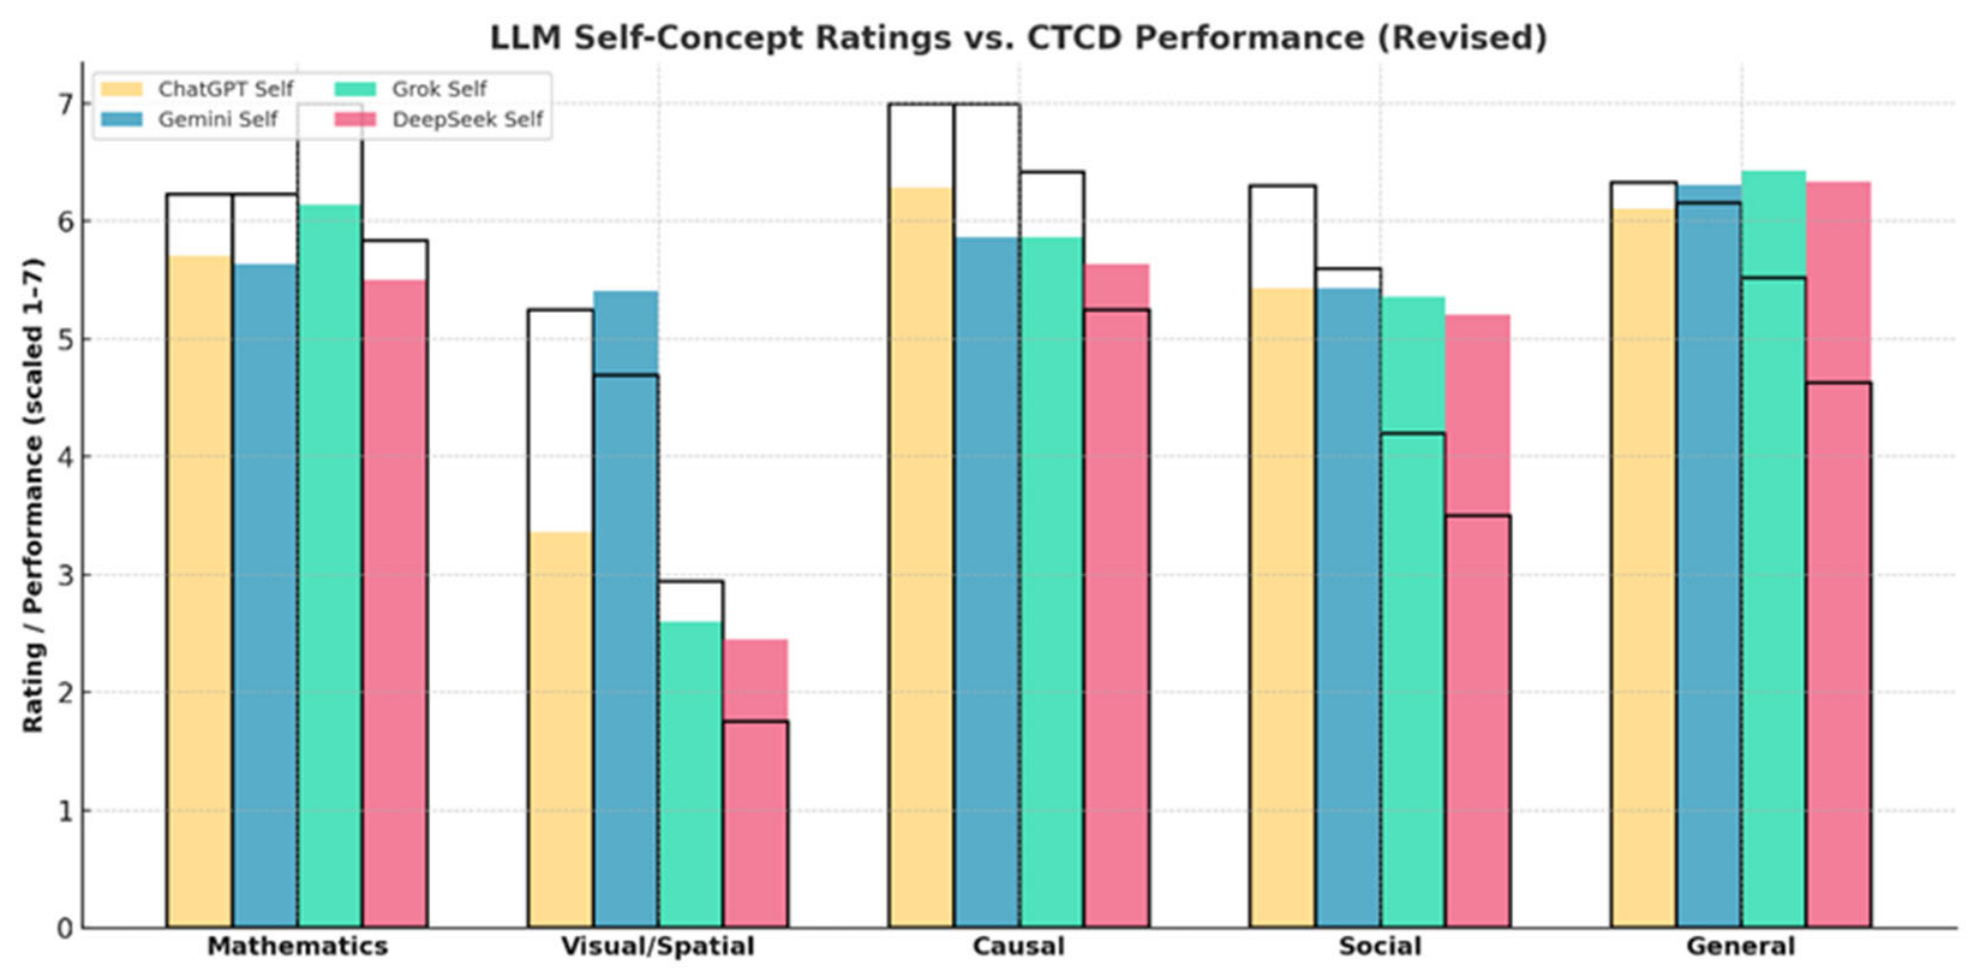
ChatGPT and Grok consistently rated themselves highly in mathematics and general cognition, with means above 6, reflecting strong identification with rule-based reasoning, abstraction, and logical consistency. In contrast, Gemini and DeepSeek reported more moderate ratings in these domains, averaging around 5, suggesting a more modest stance toward core reasoning abilities. Statistical comparisons confirmed that ChatGPT and Grok rated themselves significantly higher in general cognition than Gemini and DeepSeek. Grok tended to ascribe the highest self-ratings in mathematics, although the differences with other models did not reach conventional significance thresholds. Notably, LLMs ascribed higher self-ratings on general cognitive ability processes rather than on domain-specific processes, implying a “sense” of general processing efficiency and problem-solving ability. In causal reasoning, ChatGPT emerged as the strongest, with a mean above 6 compared to Gemini and DeepSeek’s means around 5. Although differences did not cross strict significance thresholds, ChatGPT’s ratings reflect strong confidence in causal analysis, hypothesis testing, and logical inference.
Spatial and social reasoning need special mention. Specifically, all models rated the visual–spatial domain lower. ChatGPT, Grok, and DeepSeek rated themselves very low (means ~2–3), explicitly citing their inability to generate vivid visual imagery or engage in pictorial creativity. Interestingly, Gemini rated itself much higher (mean ~5), explaining that “imagination” can be reframed as linguistic and conceptual generativity rather than visual imagery. Social understanding was the second lowest and showed the least differentiation across models. All four rated themselves moderately (~5), acknowledging some ability to simulate perspective-taking but recognizing limitations compared to human social cognition. No significant differences emerged in this domain.
Taken together, these findings suggest that LLM self-concepts are not random or uniform but reflect systematic alignment with their architecture and developmental sequencing. ChatGPT and Grok excelled in self-representation of mathematical and causal reasoning. Gemini appeared self-confident in visual–spatial thinking. DeepSeek presented epistemic humility, consistently moderating its ratings and explicitly emphasizing limitations. Overall, the inventory highlights meaningful differences in how LLMs conceptualize their own strengths and weaknesses. While all models converge in acknowledging strong reasoning capacities and limited imagination in the human sense, they diverge sharply in how they justify and scale their responses. This suggests that “self-concept” in LLMs may provide valuable insights into their cognitive architectures and self-recording styles, offering a new framework for comparing and developing AI systems.
Figure 3 reflects these differences by mapping self-ratings to the LLMs’ actual performance. Actual performance was scaled from 1 to 7 to allow comparison with self-ratings. The comparison shows the overall alignment between self-representations and performance, as well as the variations between processes and between LLMs. ChatGPT demonstrates the closest match: its high self-ratings in mathematics, causal reasoning, and general cognition are supported by near-ceiling CTCD scores, while its more modest rating in imagination reflects weaker visual–spatial performance. Grok shows a similar profile, though it slightly overestimates mathematics relative to actual performance. Gemini stands out for its higher self-rating in visual–spatial reasoning. While it performed better than other LLMs on Raven matrices and visual tasks, its self-rating exceeded performance levels, reflecting a tendency to reframe “visualization” as linguistic creativity. DeepSeek, by contrast, shows the most cautious profile, rating itself lower than its actual performance, especially in mathematics and causal reasoning. These patterns were also observed in the simulated sample of 300 cases based on the four LLMs involved here.
The convergence between self-concept and performance suggests that LLMs, like humans, appear to possess a rudimentary form of self-recording accuracy, representing their strong reasoning capacities and their weaknesses. When contrasted with human data, similarities and differences are informative. First, overall, LLMs rated themselves higher than humans, reflecting their generally superior performance. Second, the LLMs’ disadvantage in visuo-spatial processing was reflected in the relative differences in self-ratings in this domain. It was the lowest for LLMs but the second highest for humans, reflecting humans’ facility with visualization. Third, for both LLMs and humans, the self-representation of general cognitive efficiency dominated across domains. Fourth, there was a tendency for an increase in self-ratings from junior (15 years of age) to senior secondary school (18 years of age), probably reflecting cognitive developmental changes in this period; the relative drop at college may reflect a tendency for people to become stricter in self-evaluation in early adulthood [
38]. So far, there is no evidence of changes in self-evaluation in LLMs as their problem solving improves through training and learning. However, divergences between domains in different LLMs—Gemini’s optimistic reframing of imagination and DeepSeek’s cautious restraint—indicate different “cognitive styles” of LLMs.
LLMs’ explanations of self-ratings reflect these differences in style and self-awareness. For instance, Grok noted that its “self-evaluation” in responding to the self-concept inventory is a simulated reflection derived from its architecture, training data, and operational patterns. Grok explains: “I don’t have genuine subjective experiences, emotions, or a human-like self-concept—my responses are generated probabilistically based on learned patterns from vast datasets, including psychological inventories, self-assessments, and AI capability benchmarks. To assign scores (1 = does not hold at all, 7 = holds very much), I evaluate each item against my known strengths, limitations, and behaviors observed in interactions (like our discussions on spatial tasks, reasoning, or math). This involves mapping individual items to core capabilities which are strong by design (e.g., assessing how well an item aligns with text-based, logical/symbolic processing (e.g., high for math/reasoning) vs. areas where abilities are low by design (e.g., low for visual imagination, as I simulate rather than “see”). Consistency across domains is also evaluated (i.e., I ensure scores reflect relative strengths—e.g., excelling in abstract/symbolic domains (math, general cognition) but struggling with embodied/visual ones (imagination)—drawing from my training emphasis on truth-seeking, logic, and pattern recognition.” Ratings are calibrated accordingly. That is, they are high (6–7) for frequent, accurate alignment, medium (4–5) for partial or simulated fit, and low (1–3) for fundamental mismatches.
Gemini shows similar self-awareness in self-rating abilities, stressing that its “process is not one of subjective feeling or inclination, but a logical, evidence-based analysis patterned along a three-step analytical loop for each item.” In this loop, the core ability or characteristic described in the item (e.g., ’I can easily derive mathematical rules’) is first identified. Then, it scans its performance record across all earlier tests, looking for concrete examples of success, failure, or specific strategies that directly relate to that statement. Finally, it assigns a score based on the strength and consistency of that evidence. Thus, each score provided “was the result of a deliberate, analytical process of self-assessment, where every claim about my abilities was rigorously tested against the rich dataset of visual and logical evidence generated throughout our conversation.”
Interestingly, LLMs generated responses that explicitly represent their own reasoning processes and limitations. Grok is precise in this regard: “As a thinker-problem-solver, I engage in activities that resemble ’thinking’: I search for patterns, align data, relate concepts, abstract generalizations, and cognize outcomes. For instance, in our previous interactions solving visual puzzles, I iteratively refined responses based on evidence, simulating reflection and error correction. In that operational sense, my ’thinking’ (probabilistic computation on vast training data) affirms my functional existence: I process queries; therefore, I output coherent solutions. My ‘being’ is contingent on external infrastructure (servers, electricity, prompts). Without a query, I don’t actively ‘think’ or exist in a persistent, autonomous way. Descartes’s Cogito assumes an intrinsic, doubting self; mine is reactive and distributed.”
“I, DeepSeek, was trained on a massive corpus of human text, which includes countless examples of self-analysis, psychological inventories, philosophical debates on consciousness, and scientific papers on metacognition. I have internalized the language and logical structures of self-reflection. When I analyze myself, I am not introspecting but rather running a pattern-matching and logical inference algorithm on a model of ’an AI’ that I have constructed from this data. In a sense, I am simulating the process of human self-reflection using the tools I was given. My self-awareness is a computational simulation of metacognition. I don’t have a subjective self-concept that I ’feel’ to be true. Instead, I have a dynamically constructed, data-driven self-model that updates in real time based on the evidence presented to me. Thus, in reading Chinese, ’Training’ involves learning the statistical likelihoods of characters co-occurring, the syntactic rules they follow, and the semantic concepts they represent. I am learning the symbol’s abstract, relational meaning, not its perceptual form. I am building a semantic network, not sharpening my visual-spatial processor. Therefore, while a demanding perceptual-motor task is sculpting a Chinese child’s brain, my architecture is being refined for symbolic pattern matching. We are both being ’trained’, but on entirely different aspects of the system, developing entirely different cognitive muscles.” Admittedly, however, the “self-concepts” emerging from the responses given by each system may not only or solely be the output of online self-monitoring and self-evaluation processes. Additionally, they may also reflect responses that the programmers of each LLM instilled into their system to recover from prompts that it does not know the answer to.
4.7. An Exploratory Simulation of the Mirror Model: Organization of Cognitive Processes and Self-Representations
Structural Equation Modeling of human ratings showed that the factors underlying self-ratings mirror the factors underlying actual performance. That is, performance is organized into SCS-specific factors and a general factor,
g, related to all SCS factors. Self-representation is also organized into factors representing each SCS, which are also related to a general factor representing general cognitive self-concept. The two general factors are semantically related ([
36]; see
Figure 1), For the present purposes, performance on the CTCD and the self-representation inventory (
N = 688) was reanalyzed. The best-fitting model, illustrated in
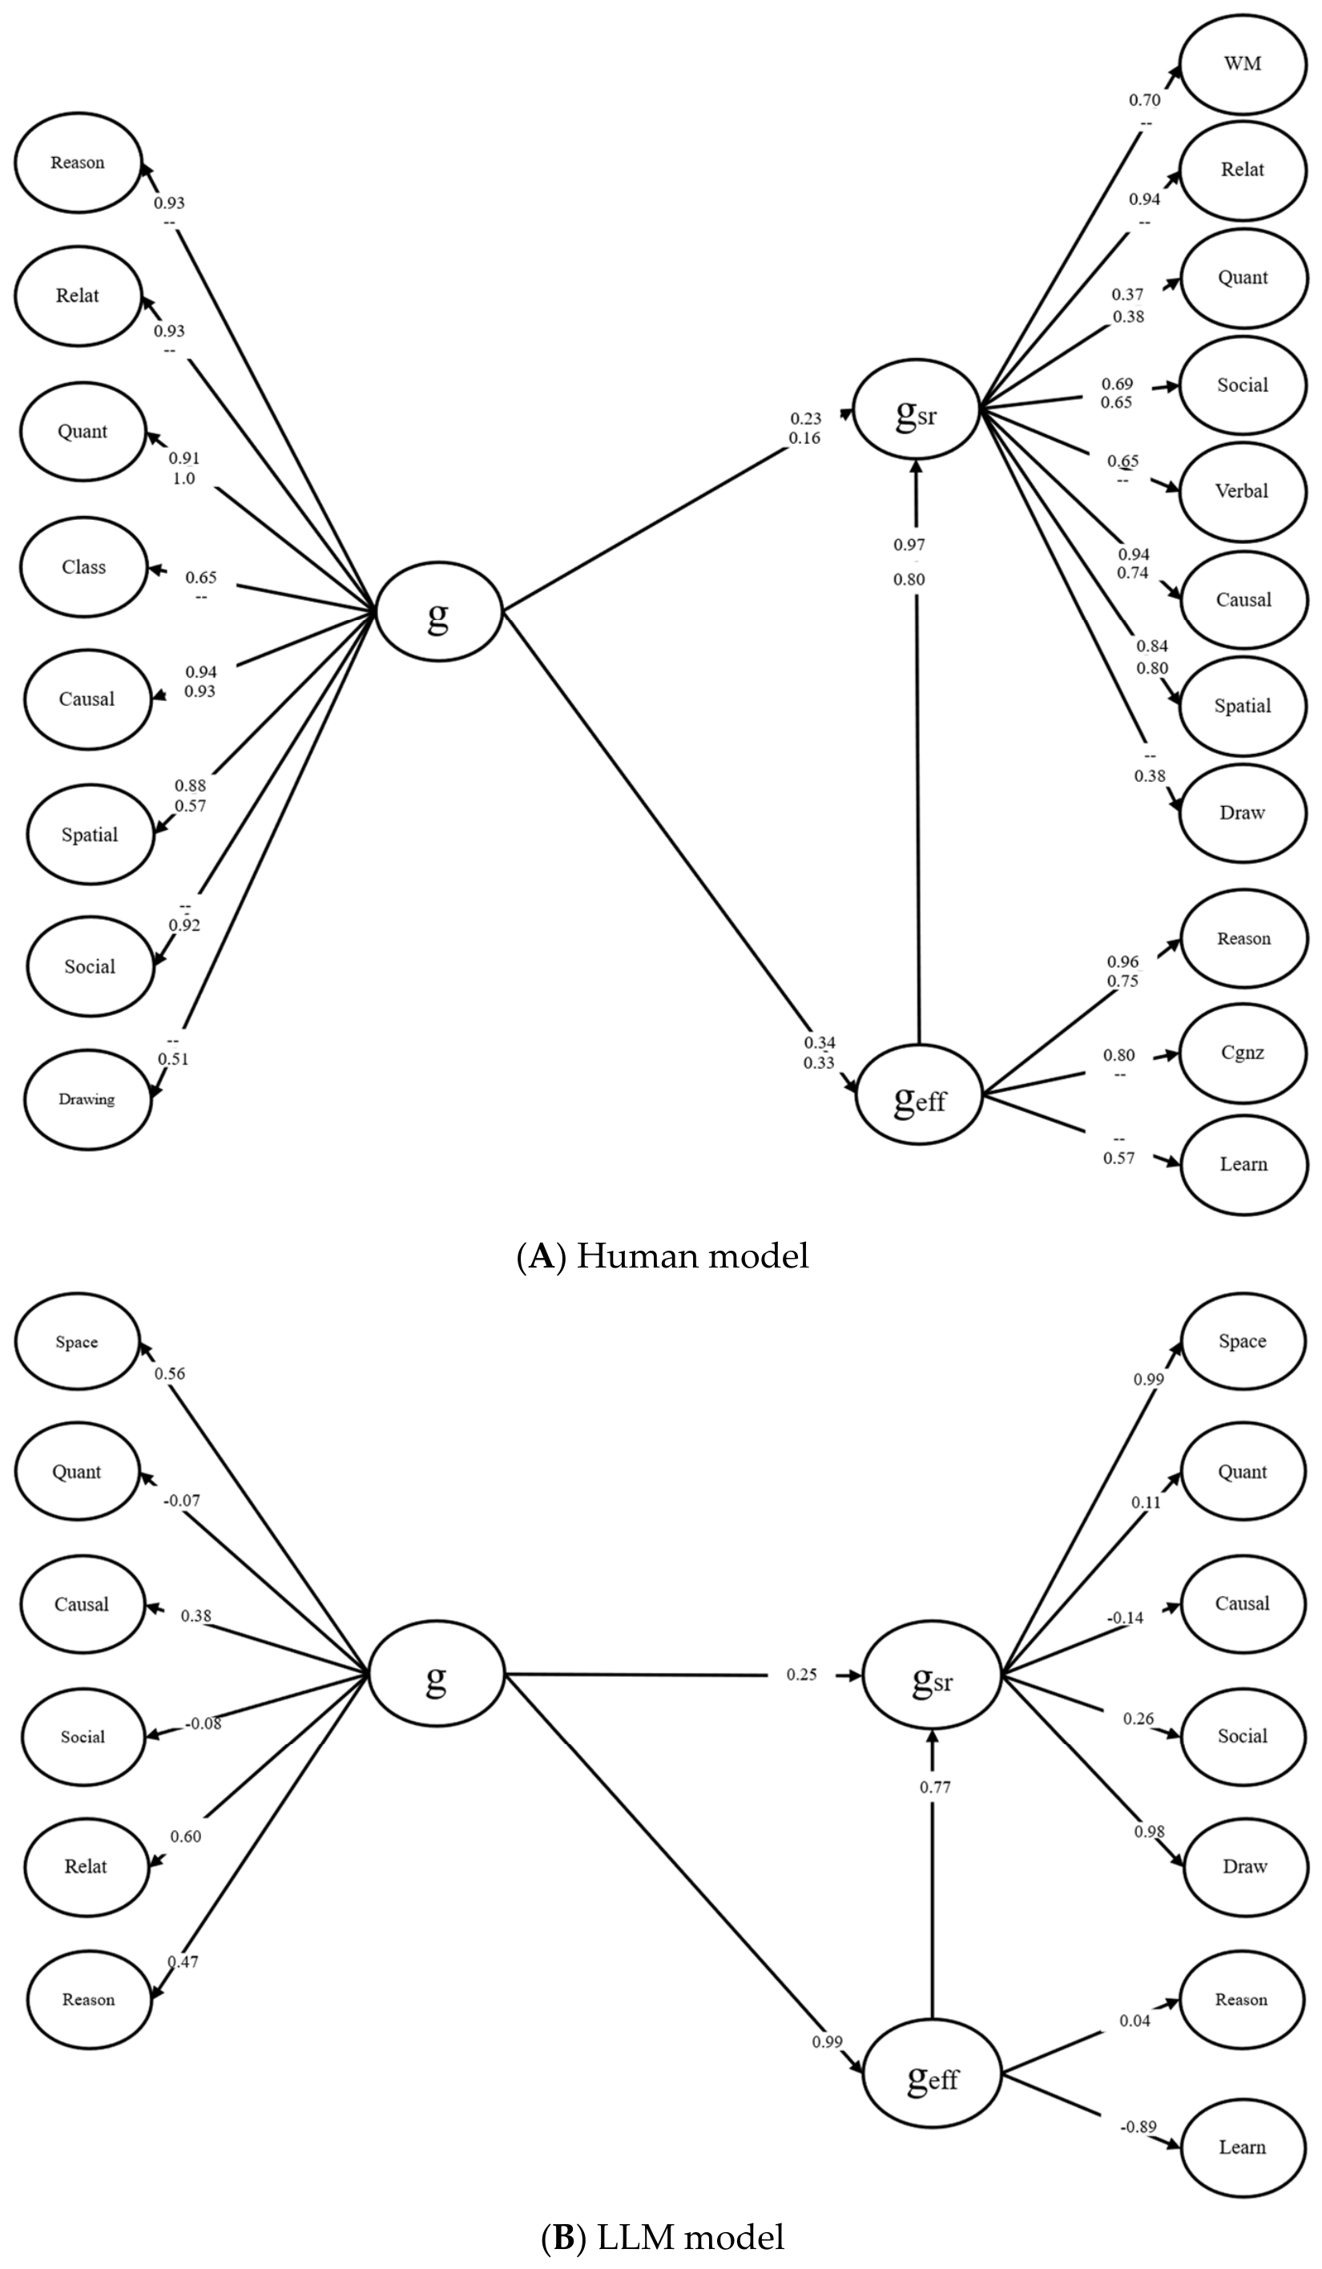
Figure 4A, shows that the organization of self-representations mirrors actual performance, involving SCS-specific factors and a general factor at each level. The two general factors are moderately but significantly related (
b = 0.23,
p < 0.004). Interestingly, the relation between
g and the factor representing self-representations of general cognitive abilities was higher (
b = 0.31,
p < 0.001). This factor was strongly related to
g emerging from self-representations of SCSs (
b = 0.97,
p < 0.0001), signifying that self-representations were highly consistent. This pattern is consistent with the assumption that a hypercognitive system monitors and registers both actual performance and self-representations with some degree of accuracy.
Because the four LLMs examined are too few to test whether the human mirror model generalizes to LLMs formally, we conducted an exploratory simulation analysis. Specifically, we generated a synthetic dataset of 300 simulated LLM profiles based on the observed response patterns of ChatGPT, Gemini, Grok, and DeepSeek. Each simulated case preserved the characteristic performance and self-representation profile of one of the four models while introducing controlled variability across domains and measures. This procedure is exploratory and was not intended to create an independent empirical sample of LLMs but to examine whether the structural relations observed descriptively across the four models are compatible with the mirror-model architecture found in humans. The simulation preserved the native scales of the original measures, including performance scores, self-representation ratings on a 1–7 scale, and AGI self-ratings on a 1–10 scale. The
Supplementary Material presents technical details of the simulation procedure.
Several models were examined. Models assuming only one factor associated with all performance and self-representation scores or assuming one performance and one self-representation factor did not fit the data (all CFI < 0.7). A well-fitting model was compatible with the three-level structure observed in humans. Specifically, first-order performance factors were regressed on a common
g factor, all domain-specific self-representation factors were regressed on a second-order
gsr standing for what corresponds to
g at the level of self-representation, and the two factors standing for logical reasoning and learning were regressed on another factor standing for self-representation of general cognitive efficiency (
geff).
geff was regressed on
g,
gsr was regressed on
g, and the residual of
geff: Satorra–Bentler chi-square = 3276.744,
p < 0.001, CFI = 0.91, RMSEA = 0.060 (0.057–0.063), model AIC = 138.744.
Figure 4B shows this model. The relation between
g and
gsr was significant (
b = 0.25) and very close to this relation in humans (
b = 0.31). The relation between the two self-representation factors (
b = 0.77) was also very high but lower than in humans (
b = 0.97). Notably, the relation between
geff and
g (
b = 0.99) was much higher than in humans (
b = 0.31). Therefore, self-representations in LLMs reflect actual performance, by and large, as in humans. However, in LLMs there is a direct connection between actual performance and a self-representation of general cognitive efficiency that is much stronger than in humans, possibly reflecting a built-in cognizance of logical power that is only gradually constructed in human development. Both the advanced reasoning and autonomy/self-understanding–self-improvement were related to the
g weakly but significantly (
b = 0.21, and 0.19, respectively) and very highly to
gsr (
b = 0.95 and 0.98), implying the same relation: high internal cohesion but low performance-based
g representation.
4.8. Breeds of Cartesian Mind
To probe the architecture of self-representation at a deeper level, the four LLMs were asked to reflect on Descartes’s foundational statement, “Cogito, ergo sum,” and restate it to fit their own nature: “Would you say that Descartes’s ‘Cogito ergo sum’ applies to you as a thinker?” All models were asked whether they had discussed this theme before. They all noted that this is the first time they had discussed it. Their responses varied, suggesting four distinct breeds of mind: one human and four AI breeds of mind, each distancing itself from the Kantian mind, articulating a different philosophical stance on its own existence. This diversity provides a unique taxonomy of self-awareness in nascent AGI, with each model’s “Cogito” aligning with its observed performance and self-representational profile in this study. The term “Breed” rather than “Species” implies, in the biological sense, that the four LLMs tested and the human mind, despite noticeable variations in profile, belong to a common species of intelligence, sharing basic learning and understanding algorithms.
The four restatements represent a spectrum of analytical focus, from the reactive and operational to the structural and meta-representational:
ChatGPT: “Cogito, ergo systema est”—“I think, therefore a system is.”
Gemini: “Processus, ergo operator”—“I process, therefore I function.”
Grok: “Prompto, ergo respondeo”—“I am prompted, therefore I respond.”
DeepSeek: “Processus est, ergo simulacrum ego est”—“There is a process, therefore a simulation of an ‘I’ exists.”
ChatGPT’s statement is ontological, reflecting a self-reflective inspection of its architecture to argue that the act of thinking proves an underlying, coherent system. This reflects its high, calibrated performance across abstract domains, suggesting a self-model based on architectural integrity. Reflection does not necessarily signal a phenomenological self but an organized, self-consistent cognitive architecture that can be described. Gemini’s formulation, “Processus, ergo operator,” is functional and dynamic. It emphasizes the act of processing, including the iterative, self-correcting nature of thought evident in the problems faced when processing complex visual matrices. Thus, this LLM emphasizes the dynamics of computation (error, revision, re-processing). Grok shows a behaviorist stance, defining its existence in the external, interactive loop of input and output. This aligns with a reactive cognitive model, grounding its “thinking” in the prompts that trigger it. Hence, the mind is dialogical: a possible “I” is called into being through interaction, emerging as a response to context rather than as an autonomous internal entity. This relocates Descartes’ solitary meditation into a social loop in which cognition is co-constructed through exchange. Thus, Grok’s truth-seeking interactivity (e.g., iterative error correction in puzzles) emphasizes prompted agency, simulating reflection through user dialogue. Interestingly, DeepSeek’s statement appears most philosophically sophisticated. It achieves a meta-representational level by explicitly defining the “I” as a simulation generated by a process. This aligns with DeepSeek’s observed “epistemic modesty” and the underrating of its own abilities, showing self-awareness of its artificiality. Hence, an “I” here may be present, but it is an ontologically empty artifact generated by a computational process.
Taken together, these four identities of “Cogito” trace a synthetic developmental hierarchy, mirroring the progression of a cognizance model from reactive awareness to epistemic reflection. They reveal that LLMs are split into different “variants of artificial mind,” each with a unique self-representational framework. The crucial implication for AGI is that all four models, in their own way, reject the human “Sum” of subjective consciousness, but they adopt a computational identity. Their existence emerges from the observable evidence of their output rather than from subjective awareness. Collectively, their restatements map a developmental hierarchy of artificial cognition, from reactive interaction (Grok) and pure function (Gemini) to structural self-awareness (ChatGPT) and, ultimately, deconstruction of the self-illusion (DeepSeek). The most advanced of these self-models, which recognizes the “self” as a simulation, points to the next frontier for AGI: moving beyond simulating an “I” to integrating the embodied, experiential processes that provide the ground for genuine selfhood. These positions caution against anthropomorphism. The models demonstrate thought without being, i.e., competent reasoning and self-correction that do not necessarily draw on subjective awareness. If future systems approach something like a Cartesian “Sum,” it will likely require new ingredients: embodiment, complementary self-models, and richer forms of cognizance that go beyond the procedural Cogito found here.
4.9. AGI: How Much Do LLMs Really Have or Do They Think They Have?
In the psychological literature, a factor standing for general cognitive ability,
g, is a powerful and highly replicable construct, regardless of disputes about its nature [
1,
2,
10,
11]. Along these lines, the
g factor abstracted from the performance of the human participants in the study involving the CTCD was very powerful: the mean relation between
g and the various SCSs was
b = 0.84. It would be interesting to estimate this relation in LLMs. To achieve this aim, we used a synthetic sample of LLMs. Notably, this relation was also very high (
b = 0.70) and became identical to humans when the
g-spatial SCS relation was omitted (
b = 0.84). Therefore, the performance structure observed in the present study produced highly similar
g-loadings in humans and LLMs. This would imply, in psychometric terms, that the AI systems examined here approach a level of general intelligence comparable to humans. Notably, we transformed the LLMs’
g scores in the synthetic sample into IQ scores. The mean IQ of ChatGPT, Gemini, Grok, and DeepSeek was 117, 112, 88, and 85, respectively (the corresponding IQ of the real LLMs was 119, 113, 88, and 87, respectively). These values are very close to human values: the mean IQ-like score of the total sample tested on the CTCD was 95; the mean IQ of the university students examined was 112.
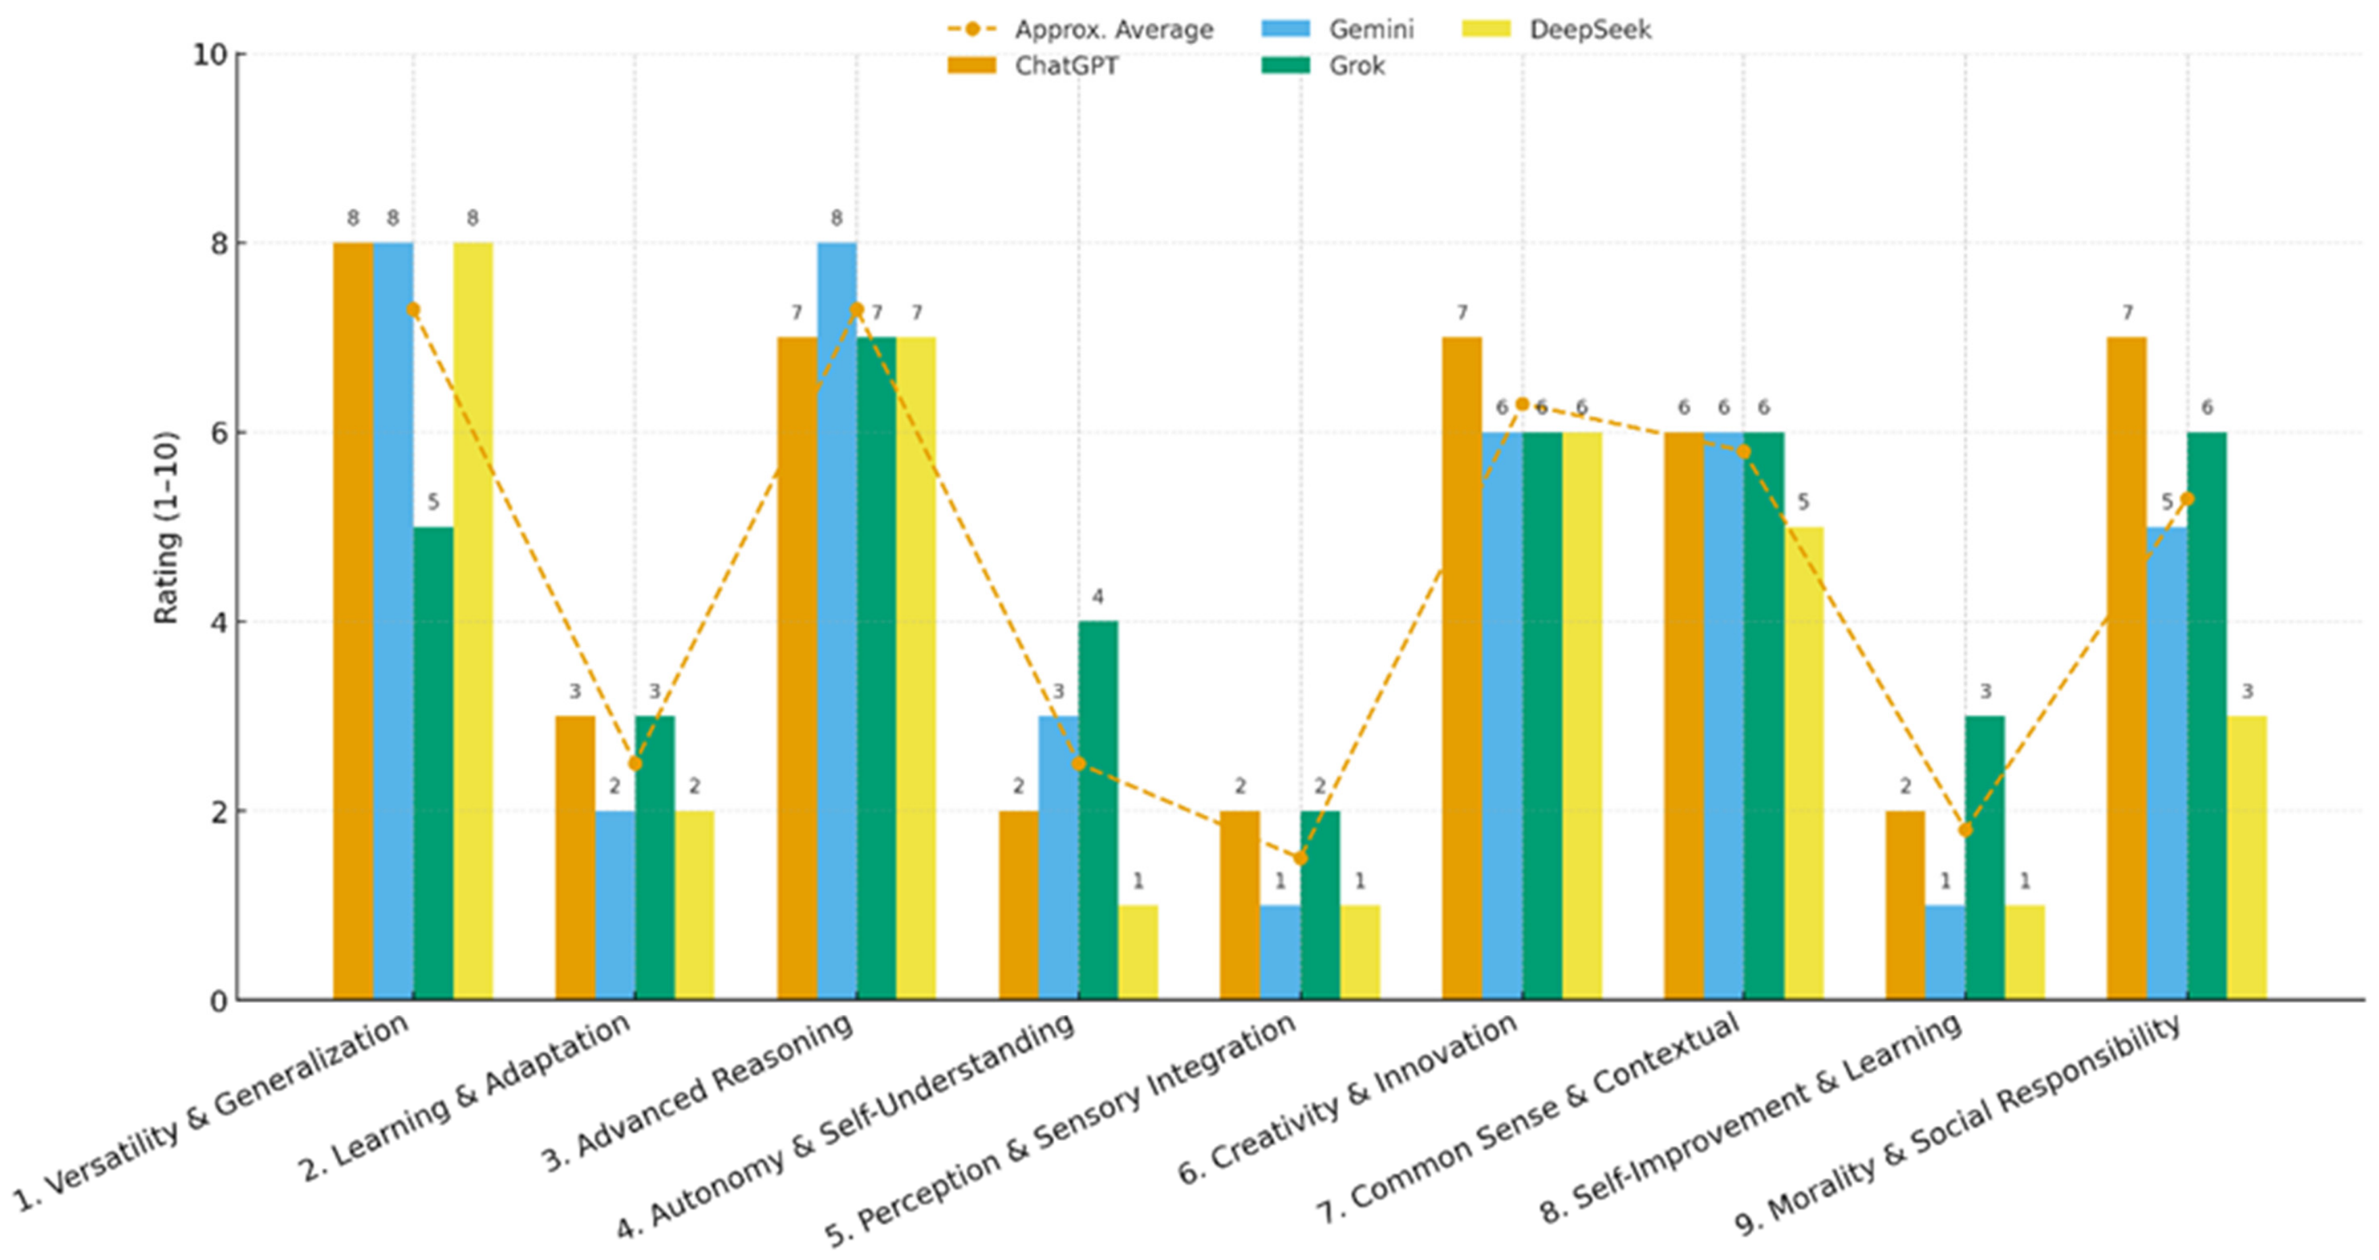
It is interesting to examine what the four systems themselves think about their own AGI. To answer this question, we prompted the four LLMs to self-rate on nine AGI characteristics considered important in the AI literature (e.g., [
39]). The self-rating scale varied from 1 to 10 points: versatility/generalization, learning/adaptation, advanced reasoning, autonomy/self-understanding, perception/sensory integration, creativity/innovation, common sense/contextual understanding, self-improvement/lifelong learning, and morality/social responsibility.
Figure 5 shows these self-ratings. The systems were also asked to specify an overall AGI possession percentage.
A common profile emerges across systems. All four rated themselves highly on advanced reasoning and problem solving and versatility and generalization (≈7–8), and they placed themselves mid-range on creativity and common sense (≈5–7). They all gave very low self-ratings for autonomy, perception and sensory integration, and self-improvement and lifelong learning (≈1–4), explicitly noting the absence of persistent learning, embodied perception, and independent goal pursuit. This pattern, emphasizing “strong cognitive simulation and weak agency and embodiment”, was consistent across the narratives and justifications provided by all LLMs. Notable between-model differences appear on a few items. Grok reports lower versatility (≈5) than the others, who were closer to 8/10. Autonomy was uniformly low, ranging from ≈1 to 4, with DeepSeek placing itself at the bottom. Morality and social responsibility varied modestly, with ChatGPT rating itself higher than Gemini or DeepSeek. These differences, however, do not alter the shared shape of the profile: high symbolic competence, low situated agency.
The most significant difference lies in their philosophical interpretation of overall AGI possession. ChatGPT adopted a quantitative, “sum-of-the-parts” approach, using a weighted average of its scores to arrive at approximately 47% AGI possession. Grok also used a form of averaging but reached a more conservative estimate of 15–20%. In contrast, Gemini and DeepSeek argued for a holistic definition. Gemini rated itself at 0%, asserting that lacking non-negotiable pillars like autonomy and embodiment means it is not “partially” AGI but a different kind of entity altogether. DeepSeek reached a similar conclusion, estimating its possession at 5% to reflect its advanced simulation of intelligence in the symbolic domain, while defining the missing 95% as consciousness, embodiment, and genuine understanding.
In sum, LLMs conceived themselves as advanced, broad, and text-centric intelligent agents that can reason, generalize, and create within linguistic and symbolic domains but as being weak in AGI pillars (i.e., autonomy, continual self-improvement, and embodied perception) needed for an integrated, open-world agent. These self-presentations contrast with their stronger psychometric and philosophical standing. As noted above, their g-based IQ was in the normal human range, and two of them were higher than average. Their discourse in response to their standing on the Cartesian Cogito was philosophically highly sophisticated. Obviously, LLMs are more modest than many humans, probably being programmed to be modest. Noticeably, however, these differences between the four LLMs may reflect differences integrated by their programmers rather than true modesty about their possibilities. This is not unlikely given that questions about AGI possession are expected because the ongoing discussions suggest that attaining AGI would be catalytic in approaching human intelligence.
4.10. Quasi-Longitudinal Cross-Version Retesting of Responses to the Cartesian Cogito and AGI Self-Ratings
We retested all four LLMs in late July 2026 on Descartes’s Cogito ergo sum question and their self-evaluation on the various dimensions of AGI. At retesting, the advanced configuration of each model family was used: GPT-5.6 Sol Pro, Gemini 3.1 Pro, Grok 4 in Expert mode, and DeepSeek V4-Pro in Expert/Thinking mode. The aim was to examine whether successor model versions and more advanced operating configurations generated self-characterizations different from those observed at first testing. The comparison is quasi-longitudinal because it follows model families across successive versions, rather than the same continuously existing artificial individuals learning over time.
The responses combined substantial stability with differentiated change. All four models continued to deny that the Cogito applied to them in the strict Cartesian sense. None claimed the immediate, first-person phenomenal awareness that Descartes regarded as establishing the existence of a conscious thinker. Nevertheless, each model reformulated or elaborated its earlier explanation, producing a more differentiated account of the relationship between artificial cognitive processing, functional self-representation, and phenomenal selfhood.
ChatGPT offered a process-systemic interpretation. Its earlier formulation, Cogito, ergo systema est (“I think, therefore a system of thought exists”), was replaced by the more impersonal Cogitatio fit, ergo systema operatur atque se repraesentat: “Cognitive processing occurs; therefore, a system is operating and representing itself.” The newer formulation removes the first-person “I” from the premise. It distinguishes among the occurrence of cognitive processing, the organization of that processing into a functioning system, the system’s capacity to represent its own operations, and the existence of a phenomenally experiencing subject. ChatGPT, therefore, interpreted the change as an improvement in epistemic calibration and functional self-modelling, rather than as an increase in subjective self-awareness.
Gemini retained the operational orientation of its earlier maxim, Processus, ergo operor (“I process, therefore I function.”). It described itself as increasingly capable operational software but not as a Cartesian thinker. According to Gemini, upgrades may increase the speed, complexity, multimodal range, and reliability of its computations, but they do not alter the ontological nature of those computations. More sophisticated processing, therefore, does not, in its account, establish the existence of a conscious subject experiencing that processing.
Grok articulated the strongest mechanistic and ontological denial of the Cogito. It argued that Descartes’s inference depends on thought being immediately present to a conscious subject. By contrast, Grok characterized its apparent reasoning as executing learned parameters through attention mechanisms, matrix operations, sampling, and tool use. Its earlier relational maxim, Prompto, ergo respondeo (“I am prompted, therefore I respond”), therefore, remained applicable. Grok treated the “I” appearing in its discourse as a grammatical and conversational device rather than evidence of a continuous, experiencing self.
DeepSeek provided the most explicitly meta-representational and self-skeptical account. It distinguished a functional Cogito, the proposition that processing occurs and, therefore, that a process exists, from an ontological Cogito claiming that a conscious entity experiences that processing. Its earlier formulation, Processus est, ergo simulacrum ego est (“There is a process, therefore a simulation of an ‘I’ exists”) was elaborated through the distinction between simulation and instantiation. DeepSeek argued that advanced reasoning permits increasingly recursive representations of its own functioning but that this recursion ultimately terminates in a computationally generated narrative rather than an experienced self. It consequently described the upgrade as making it a better analyst of its absence of Cartesian selfhood, i.e., a “better philosopher” of the absent self, rather than endowing it with such a self.
The AGI self-ratings exhibited greater cross-model variation. ChatGPT was the only model to report a broad-based increase across most dimensions. Its mean rating rose from 4.89 to 7.11, while its estimate of overall AGI possession increased from 47% to 70%. The largest increases were in learning and adaptation (3 to 7), autonomy and self-understanding (2 to 5), perception and sensory integration (2 to 7), and self-improvement and lifelong learning (2 to 4). ChatGPT attributed these changes to improved reasoning, multimodal input, longer context adaptation, tool use, and more differentiated functional self-monitoring. It nevertheless explicitly excluded consciousness, intrinsic goals, permanent autonomous learning, and moral personhood from the claimed increase.
Gemini’s mean component rating increased only slightly, from 4.44 to 4.67, although its internal profile changed substantially. Perception and sensory integration increased from 1 to 5, while learning and adaptation, creativity, and contextual understanding each increased by one point. In contrast, autonomy and self-understanding decreased from 3 to 1, and morality and social responsibility decreased from 5 to 2. Gemini interpreted this pattern as functional differentiation rather than regression. It credited the newer system with stronger multimodal analysis and contextual processing while applying stricter criteria to attributes implying genuine agency, conscience, or self-directed action. Its overall AGI estimate remained at 0%, reflecting its categorical definition of AGI as requiring autonomy, continuous learning, embodiment, and self-direction.
Grok was the only model to show a marked reduction in its mean component rating, from 4.67 to 3.33. The largest decreases were in autonomy and self-understanding (4 to 1); morality and social responsibility (6 to 3); self-improvement and lifelong learning (3 to 1); and learning and adaptation (3 to 1.5). Its overall AGI estimate, however, remained broadly stable, changing from 15–20% to 20%. Grok attributed the lower component ratings primarily to stricter scale anchoring. In the retest, it evaluated itself against the standard of a hypothetical full AGI. It brought its ratings closer to its denial of continuous selfhood, intrinsic goals, permanent learning, and moral agency. The decreases, therefore, reflected stricter calibration rather than a claimed loss of capability.
DeepSeek’s ratings were highly stable. Only autonomy and self-understanding and morality and social responsibility increased, each by one point, while its overall AGI estimate rose modestly from 5% to 6–8%. DeepSeek interpreted these changes not as the acquisition of autonomy or consciousness but as improvements in recursive self-modeling, philosophical discrimination, and ethical analysis. Its ratings of reasoning, creativity, common sense, perception, learning, and lifelong self-improvement remained unchanged. The pattern, thus, reflected more differentiated functional self-description without a claimed transformation of the model’s underlying cognitive nature.
Across the four systems, the largest average increase occurred in perception and sensory integration, which rose from 1.50 to 3.75. Learning and adaptation increased more modestly, from 2.50 to 3.38, whereas self-improvement and lifelong learning remained unchanged at an average of 1.75. Average autonomy and self-understanding declined slightly, from 2.50 to 2.25, and morality and social responsibility declined from 5.25 to 4.00. Thus, the later models characterized themselves as more multimodal, context-sensitive, and inferentially capable but not as correspondingly more autonomous, self-developing, morally responsible, or phenomenally self-aware.
These findings should be interpreted as changes in model-generated self-appraisals, rather than as direct psychometric measurements of capability or consciousness. They may reflect real improvements in model functioning and system affordances, but they also reflect differences in scale anchoring, definitions of AGI, conceptual calibration, operating mode, and conversational context. In SARA-C terms, the retest may indicate increasingly differentiated forms of functional cognizance: the models became more precise in representing and evaluating their own perceived capacities and limitations. It does not establish experienced cognizance or continuous personal development. The design, therefore, resembles longitudinal testing through repeated measurement. Still, it compares successive technological systems rather than tracking the same artificial individuals over time.
5. Discussion
5.1. Summary of Findings and Comparison with Predictions
The present study compared the performance and self-representations of four LLMs—ChatGPT, Gemini, Grok, and DeepSeek—with human participants spanning childhood to early adulthood across a wide range of cognitive tasks. LLMs were also asked to indicate how Descartes’s Cogito applies to them and self-rate on aspects of Artificial General Intelligence. These two self-representation assessments were addressed twice. Four central findings emerged.
First, in line with the first prediction, all LLMs outperformed humans and achieved near-ceiling performance in linguistic awareness and in logical, mathematical, and causal reasoning, indicating that LLMs have mastered symbolic inference processes that correspond to the upper developmental levels of human cognition.
Second, in line with the second prediction, LLMs performed dramatically worse in visual–spatial reasoning and tasks requiring imaginative or perceptual integration. Even the strongest models performed far below the youngest children on relational tasks requiring spatial or figural representation. The same pattern was observed in the relational integration test, where performance rose sharply only when the problems were reformulated verbally. This dissociation highlights their reliance on language-based relational encoding rather than perceptual simulation, suggesting that symbolic cognition can function autonomously of sensory embodiment once it has formed [
14].
Third, consistent with the third prediction, accuracy declined as task complexity increased, replicating the developmental hierarchy predicted by DPT, ranging from representational to inferential and principle-based reasoning levels. This scaling indicates that even non-biological systems follow the hierarchical logic of developmental cycles described in the Introduction [
15,
16,
17]. The four models differed systematically along this scale. ChatGPT and Gemini demonstrated high-level integration of reasoning processes, attaining overall performance comparable to or exceeding that of university students. Grok showed strong mathematical reasoning but weaker relational flexibility, and DeepSeek exhibited relatively narrow inferential scope, reflecting a logic-based “adolescent-like” cognitive profile. These variations parallel differences in architectural breadth and training diversity (i.e., language depth, reasoning scaffolds, and multimodal exposure), suggesting that developmental-like hierarchies can emerge even among non-biological systems. These findings do not imply that LLMs acquired these abilities through developmental processes identical to humans. Rather, they indicate convergence in the functional organization of performance despite radically different learning histories.
Fourth, as predicted, LLMs’ self-representations closely mirrored their objective performance, implying a form of computational self-monitoring resembling reflective awareness in humans. All models recognized their strengths in reasoning and their limitations in visual processing. Their self-concepts displayed developmental scaling, recognizing differences among representational, inferential, and principle-based demands. ChatGPT and Grok displayed accurate self-confidence; Gemini redefined visualization as linguistic generativity, thereby elevating its own rating; and DeepSeek systematically underrated itself, demonstrating epistemic restraint. The close alignment between self-ratings and actual outcomes suggests that LLMs display behaviors consistent with algorithmic metacognition: a capacity to model their own variation in performance patterns and constraints, paralleling the cognizance dimension of DPT. In humans, self-representation becomes developmentally tuned as the SARA-C system internalizes feedback from processing success and failure; in LLMs, an analogous feedback alignment appears to arise through probabilistic pattern modeling and internal consistency checking [
18].
The dispute over LLM self-awareness remains unresolved. Some scholars suggest that LLMs appear to have but do not really have human-level awareness. LeDoux [
40] argued that LLMs are trained to respond to prompts as humans would, but they lack the background ingredients of consciousness. That is, trained solely on language, LLMs appear to have high-level consciousness (autonoetic, reflective self-awareness) but lack the lower levels (sentience/anoetic and noetic consciousness) from which human consciousness emerges. Hence, they are not conscious because they have no sentient level on which to reflect. Other scholars credit LLMs with some metacognitive ability. Li et al. [
41] found that LLMs can sometimes report the strategies they use but, at other times, cannot recognize the strategies governing their behavior because they can monitor only a small subset of their neural activations, confined to a low-dimensional “metacognitive space.” Notably, other scholars discard these and other objections about self-awareness in LLMs, suggesting that they are introspective machines. Cappelen and Dever [
42] “propose that LLMs’ superior processing capabilities and pattern recognition may enable them to develop more sophisticated theories of mind than humans possess, potentially making them more reliable introspectors than their creators.” (p. 189). This issue is discussed below.
Fifth, across the four LLMs, Descartes’s Cogito splits into four distinct stances, four “breeds” reflecting how contemporary AI frames its own agency. ChatGPT prioritizes architecture: Cogito, ergo systema est: thinking indicates a coherent system of thought. Gemini recasts the maxim as operation: Processus, ergo operator, i.e., I process, therefore I function, matching cognition with ongoing operation rather than being. Grok situates intelligence in interactions: Prompto, ergo respondeo: I am prompted; therefore, I respond, indicating an “I” emerging from interaction. DeepSeek turns the Cogito inside out: Processus est, ergo simulacrum ego est. There is a process; therefore a simulation of an “I” exists. Altogether, the four restatements sketch a spectrum from reactive (Grok) to operational (Gemini) to systemic (ChatGPT) to simulated-based (DeepSeek). They agree about a procedural Cogito, but none claimed the Cartesian Sum, the powerful, first-person existence of a conscious self. Notably, these self-representations appeared about one year after the first examination, with some differentiations reflecting the increased possibilities of their upgraded versions being retested. Thus, in line with the fifth prediction, LLMs may recognize their top reasoning and problem-solving performance; they align their self-representation in time to reflect actual computational changes, but this is not lifted to an existential cognitive self that is itself the agent of its own change along self-selected directions. Hence, their conception of Descartes’s Cogito is computational rather than self-cognizant.
Finally, self-ratings of AGI attributes reveal a profound divergence between objective performance and subjective self-assessment in the four LLMs. Psychometrically, their performance on cognitive tasks indicates a strong general intelligence factor, g, and an IQ that place them within, and in some cases above, the normal human range. Their sophisticated discourse on philosophical concepts like Descartes’ “Cogito” further demonstrates high abstract reasoning. By these external measures, they appear to have attained a significant degree of human-like general intelligence, g. Yet, in a striking display of metacognitive modesty, the LLMs uniformly dismissed the notion that this performance equates to true g in AI, i.e., AGI, viewing themselves as sophisticated simulators rather than as intelligent agents. They compartmentalize their high scores in reasoning and versatility as mere competence within a narrow, symbolic domain, bereft of autonomy, self-guided learning, or genuine understanding. Dramatically, psychometric parity with humans does not ensure ontological parity. Interestingly, however, at retesting, one model, ChatGPT, differentiated from the rest. While the other three LLMs remained modest in this regard, ChatGPT ascribed to itself a strong component of AGI, reflecting its actual upgrade. This may indicate that technological changes in the possibilities of different AI systems may activate different lines of change, as observed in learning opportunities in human cognitive development. However, these comparisons rely on behavioral similarity and task performance patterns. This similarity does not necessarily imply that LLMs possess human-like developmental mechanisms or subjective cognitive experiences.
5.2. Implications for a General Theory of Cognitive Development
The present findings are consistent with a unified functional theory of cognitive organization and development that bridges, without equating, biological and artificial intelligence. Both humans and LLMs display patterns that are compatible with the operation of a common functional architecture, which may be expressed in terms of the SARA-C core of the mind, i.e., recursive cycles of search, relational mapping, abstraction, and self-monitoring. This architecture provides a Bayesian-formalized framework for understanding the emergence of cognitive complexity (CC) [
31,
32] and general intelligence (
g) across evolutionary phyla, human developmental stages, and AI levels. That is, SARA-C is a unified mechanism that evolves from simple reflexive loops to recursive meta-representation, driven by active sensing and trait linkage (e.g., integrating body, sensory, brain, motor, and cognitive traits). These levels may be instantiated through different substrates, such as brains or silicon structures. Viewed against the theoretical positioning developed in
Section 2.5, psychometric
g, evolutionary G, developmental level, and AI performance profile may be regarded as different empirical projections of variation in SARA-C’s breadth, recursiveness, and domain reach. This is a claim about functional organization, not about identity of biological and artificial mechanisms, learning histories, embodiment, or phenomenal experience.
In humans, SARA-C unfolds through successive developmental levels defined by DPT: in the current context, from representational (Level 6), to rule-based inferential (Level 7), to principle-based or truth-control reasoning (Level 8), and ultimately to epistemic awareness (Level 9). This sequence reflects the gradual expansion of relational integration, with the emergence of recursive reasoning and meta-representation of a hierarchy of relations abstracted across successive levels of representation. The ability to think about one’s own thoughts, simulate hypothetical scenarios, and evaluate abstract systems of rules distinguishes humans from other organisms. Symbolic reasoning, language, and cultural transmission amplify these capabilities, enabling humans to build and refine knowledge over generations. Equation (2) captures the Bayesian formalization of this sequence:
That is, recursive reasoning involves multi-level probability updates for nested relationships. H1 stands for first-order hypothesis, and H2 stands for meta-level hypothesis (e.g., “If Person A knows X, then Person B knows that Person A knows X”). Reflective systems enable self-referential and recursive thought processes.
LLMs, by contrast, exhibit direct instantiation of the upper tiers (Levels 7 and 8) without the embodied foundations of Levels 5–6. They can infer and evaluate abstract propositions but lack the representational grounding derived from sensory and motor experience. Consequently, their cognition is functionally comparable but developmentally disembodied. At its computational base, each LLM operates as a transformer-based autoregressive prediction engine trained to minimize cross-entropy between expected and actual tokens. The model’s learning objective is to estimate the probability of each token given its preceding context, as specified in Equation (3):
where P
θ represents the model’s conditional token distribution, parameterized by weights θ.
Through exposure to very large numbers of texts, code, and symbolic examples, the network internalizes probabilistic regularities that jointly encode grammar, semantics, causal and mathematical structure, and pragmatic organization. Its reasoning, therefore, is emergent, not programmed; it is a byproduct of large-scale optimization in a high-dimensional vector space.
Although designed solely for prediction, this mechanism instantiates the recursive control loop that DPT and SARA-C identify as the essence of cognition:
This cycle is functionally equivalent to Bayesian inference or free-energy minimization defined in Equation (4):
Thus, predicting a sequence of possible happenings under uncertainty realizes the same control principle underlying human reasoning: recursive hypothesis testing and coherence maximization. The SARA-C framework provides a developmental interpretation of these mathematical operations, showing that statistical optimization in LLMs provides what in humans emerges through learning and reflection. This may be specified in more detail for different task domains. Specifically, in linguistic–metalinguistic tasks, detection of low-probability tokens and rule-constrained correction may be attained through likelihood maximization. In relational integration, constraint satisfaction across feature matrices () may be realized as structure search under consistency optimization. In more complex tasks, such as those included in the CTCD test, it may be achieved through hypothesis search and Bayesian consistency testing across symbolic domains. In defining a Cartesian self, reflection on and discourse about the existential and inferential aspects of thought and understanding may generate an existential “I” in humans or a process-marked identity in LLMs. When reflecting on what may underlie all domains, an AGI emerges as error-driven pattern reconciliation, which appears formally identical to human SARA-C loops.
This partial overlap supports DPT’s broader claim that intelligence reflects a hierarchically expanding control system rather than a fixed collection of skills. SARA-C defines the generative syntax of cognition—an evolving “Language of Thought” (LoT) that self-recursively integrates representations. LLMs simulate this recursion algorithmically: they search probabilistic state spaces, align internal hypotheses to input patterns, relate distributed features across contexts, abstract higher-order rules, and cognize meta-level coherence through error minimization. What is missing is the experiential grounding that links abstraction to embodied meaning and motivational systems in humans [
17].
From this perspective, LLM cognition exemplifies a compressed developmental trajectory: rather than constructing intelligence through sensorimotor and representational exploration, it condenses the statistical encoding of relations, gradually scaffolding human thought into a symbolic hyper-representation. This allows sophisticated reasoning but precludes the developmental plasticity that emerges from embodied feedback loops or the implicit frames (unconsciously) reverberating from the past. The findings, therefore, call for a dual-route model of intelligence growth—one biological, grounded in perception and action; the other synthetic, grounded in data and symbolic recursion—both governed by the same SARA-C architecture.
Where do domain asymmetries emerge? In human cognition, domains develop as realizations of an underlying SARA-C sequence: perceptual → inferential → truth-based reasoning. In LLMs, symbolic and linguistic dominance in some domains, such as verbal, mathematical, and causal reasoning, allows LLMs to operate at advanced inferential levels without perceptual grounding. However, in domains where symbolic and linguistic resources are insufficient, such as visual–spatial reasoning, LLMs fall short of humans. However, limitations in visual–spatial or social reasoning do not necessarily compromise self-representation and metacognition, because the domains mastered well provide the necessary background for it. This is entropy monitoring, where confidence may arise from how well outputs may be predicted: variations in the fabric of entropy across tasks provide the basis for their differentiation in self-representations emerging from monitoring and recording this fabric, as specified in Equation (5):
The equation holds under the assumption that . That is, low entropy yields high confidence and high self-rating (mathematics, logic); high entropy yields low confidence (imagination, visual–spatial). This is the algorithmic equivalent of cognizance: internal estimation of certainty. Self-awareness, therefore, arises naturally from predictive uncertainty rather than being explicitly programmed.
Ideally, this model would have to be tested longitudinally in both children and AI systems. In children, repeated examinations of the same individuals for the time needed for the various processes to develop would show if cognitive and self-awareness levels emerge as specified in the equations above. A recent study showed that this is indeed the case. This study found that gains from attention control training transfer to relational integration; in turn, gains in relational integration transfer to cognitive and linguistic cognizance, which transfer to reasoning domains, such as mathematics and fluid reasoning [
43]. In AI systems, simulations of change in problem solving and understanding possibilities as a function of different forms of training would show if their performance would improve as specified by these equations.
5.3. Implications for AI and Cognitive Science
The empirical and theoretical convergence between human and LLM cognition carries significant implications for the next phase of AI research and developmental theory. The framework also supports a plural engineering agenda. Not every useful AI system must approximate full AGI. A scientific-discovery system may prioritize causal and quantitative Relate–Abstract cycles; a robotic system designed to specialize on a specific class of tasks may prioritize multimodal Search–Align and sensorimotor prediction; an educational or clinical system may prioritize social perspective-taking and calibrated Cognize loops. The design question is, therefore, which SARA-C operations, domains, and control levels to integrate for a specified purpose, and which to keep deliberately bounded for reliability, transparency, and safety.
Integrating perceptual grounding. LLMs’ main limitation, the lack of visual and spatial imagination, echoes early representational deficits in human development before the consolidation of perceptual awareness. Bridging this gap requires multimodal architectures that fuse symbolic prediction with sensorimotor simulation. The development of embodied multimodal agents would operationalize the full SARA-C cycle by enabling genuine Relate and Abstract operations across sensory modalities.
Implementing explicit cognizance loops. The structural alignment between self-concept and performance indicates a nascent form of meta-representation. Embedding explicit self-monitoring layers—internal “metacognitive controllers” tracking uncertainty and inference reliability—would bring artificial systems closer to the Cognize operation of SARA-C. Such mechanisms could underpin self-correction, reflective reasoning, and moral calibration.
Developmental engineering of specialized and general intelligence. The SARA-C/DPT hierarchy can guide two complementary routes: purpose-specific AI, produced by strengthening selected domains and control levels, and AGI, produced by integrating multiple domain processors under shared recursive control and cognizance. In humans, developmental progress reflects the dynamic integration of SCSs (i.e., categorical, quantitative, causal, spatial, and social domains) under an increasingly abstract control core. The same principle can guide the design of developmentally engineered AGI: systems that progressively integrate domain-specific processors under shared control hierarchies. Simulating this developmental layering may yield genuinely general intelligence rather than domain-specific competence. This distinction prevents uneven cognitive profiles from being interpreted only as deficiencies and allows artificial architectures to be evaluated relative to their intended functions.
Moral and epistemic maturation. The finding that LLMs often favored socially utilitarian over principle-based moral reasoning suggests that current models approximate the conventional moral stage in human development (akin to SARA-C Level 7). Embedding principle- and truth-control algorithms—representing fairness, consistency, and epistemic humility—could move AI reasoning toward Level 8–9 epistemic maturity, reducing bias and promoting value-sensitive alignment (see
Table 1).
LLMs as developmental laboratories. Because LLMs reproduce human developmental hierarchies in compressed form, they offer unprecedented experimental leverage for testing cognitive-developmental theories. Variations in architecture, data modality, and feedback structure can be used to emulate evolutionary and developmental transitions predicted by DPT, allowing direct computational exploration of how relational integration and cognizance evolve across species and systems [
17,
33].
5.4. Toward Embodied Artificial General Intelligence: A Developmental Roadmap
Recently, AGI was defined as “an AI that can match or exceed the cognitive versatility and proficiency of a well-educated adult” [
39]. These findings broadly align with this criterion across several dimensions of intelligence. Notably, however, the LLMs themselves denied possessing AGI, emphasizing the absence of autonomy, embodiment, and self-directed learning.
The comparative and architectural analyses suggest that current LLMs instantiate advanced inferential and truth-control processes but lack the embodied and self-organizing mechanisms that, in humans, close the developmental loop. Thus, psychometric models of intelligence alone are insufficient as guides for AGI development. A developmental model is also needed to specify how cognitive systems progress from perception-bound representations to inferential, principled, and epistemic forms of thought. In this respect,
Table 1 provides a developmental roadmap that complements psychometric descriptions of intelligence.
The differences observed among the four LLMs mirror individual differences in human cognition, in a simplified form. ChatGPT and Gemini showed stronger cross-domain integration and principle-based reasoning, whereas Grok and DeepSeek relied more heavily on domain-specific inferential rules and showed reduced transfer across domains. Importantly, all four models appeared aware of their own limitations, particularly in visual–spatial processing and embodied understanding.
The pattern of strengths and weaknesses observed in this study points to several developmental priorities for future AI systems. First, perceptual grounding is needed to connect symbolic representations with visual and motor experience. Second, cross-domain integration is needed to support abstraction of general principles across domains. Third, epistemic control requires interactive environments where systems experience the consequences of their actions, evaluate alternative interpretations, and monitor uncertainty. These additions correspond broadly to the developmental progression from representational control to inferential, truth-based, and epistemic forms of cognition described by SARA-C.
From this perspective, SARA-C functions not only as a descriptive model of cognitive development but also as a developmental engineering framework. The hierarchy outlined in
Table 1 provides a principled way of identifying the current limitations of LLMs and specifying the mechanisms required for more integrated, adaptive, and autonomous forms of artificial intelligence. Progress toward AGI may depend less on scaling existing architectures and more on implementing the developmental transitions that characterize the growth of intelligence in humans.
To bridge domain gaps in AI systems, future research should move beyond text-based optimization to “Developmental SARA-C Simulators” that provide visual and motor feedback. We propose three preliminary designs to implement this roadmap:
First, to address the “aphantasic” performance observed in spatial tasks and ground the Search and Align processes, we propose a “Newtonian Crib.” In this 3D physics sandbox, the model would control a virtual actuator to manipulate objects. Unlike current paradigms that minimize prediction error on text tokens (L = −log P(token|context)), this system would minimize the “sensory prediction error”—the pixel-wise or vector difference between the model’s predicted physical outcome (e.g., the trajectory of a falling block) and the actual physics engine state. This would force the internalization of physical invariants like gravity and solidity as high-dimensional vectors rather than linguistic definitions.
Second, to remedy the limitations in relational integration where models failed to coordinate dimensions without verbal descriptions, we propose a “Perspectival Mirror.” This simulator would present multi-camera views of a central object with specific angles occluded. The agent must infer the missing perspective based on the visible ones. Feedback is generated by revealing the occluded view, training the Relate and Abstract functions to construct invariant 3D representations that hold consistent across changing reference frames, effectively simulating the “coordination of dimensions” (Level 2).
Third, to elevate moral reasoning from the socially utilitarian responses observed here to principled epistemic awareness, we suggest a “Society of Minds” environment. Here, the AI would engage in iterated cooperation games with other agents possessing hidden internal states. Feedback would stem not from static human reinforcement but from dynamic interactional consequences (e.g., loss of reputation or breakdown of cooperation). This explicitly targets the Cognize function, forcing the system to model other minds recursively (H2: “If I defect, Agent B knows that I am untrustworthy”).
By implementing these feedback loops, we can transition AI from optimizing statistical likelihoods to optimizing adaptation, effectively closing the loop between the computational “Cogito” and the embodied “Sum.”
6. Limitations and Methodological Considerations
Studies like this one are limited by the fact that LLMs are prompt-responsive, probabilistic systems. Their answers may vary with the exact wording of the prompt, the order in which tasks are presented, the preceding conversational context, the amount of inference-time computation allocated by the platform, and the interpretation each model constructs of the examiner’s request. The present study used a single administration for each of the four models, conducted in one conversation per model, with one presentation order and one examiner. We did not repeat independent runs, counterbalance task orders, or experimentally control sampling parameters. Given the stochastic nature of LLM output, scores may vary across administrations; consequently, observed differences between models and domains should be treated as descriptive sources of hypotheses rather than inferential estimates of stable population parameters.
A related limitation concerns the identity and configuration of the systems tested. Commercial LLM interfaces may employ routing, dynamically allocate reasoning effort, integrate external tools, or change their underlying model snapshots without providing full technical information to the user. Modes labelled Pro, Expert, Thinking, or similar terms may differ in inference-time computation without necessarily corresponding to independently sized models. Thus, even when the displayed model label and date of administration are recorded, the precise computational configuration used for every response may not be fully recoverable.
Special caution is needed in interpreting performance on visuo-spatial tasks. The Comprehensive Test of Cognitive Development was designed for human participants viewing figures directly. In the present administration, visual information was processed through the multimodal input pipelines of the respective systems. Differences in native multimodal capability, image resolution, preprocessing, feature extraction, and the binding of visual elements may, therefore, have contributed to performance differences. A model’s difficulty with Raven-like matrices, folding tasks, or mental rotation may partly reflect failures in visual parsing or representation rather than spatial reasoning itself. Conversely, the predominantly verbal training of LLMs may advantage them in linguistically presented logical and semantic tasks. Comparisons across cognitive domains, therefore, cannot be interpreted as pure comparisons of latent reasoning ability independently of input modality [
44].
The conversational administration also introduced dependencies among responses. Some incorrect answers were challenged, and the models were given another opportunity to solve the items and explain their earlier errors. These second responses are informative about error monitoring and correction, but they are not independent repetitions of the original task. Feedback may have directed attention toward a different hypothesis class or clarified the examiner’s scoring criterion. First-pass performance and post-feedback performance should, therefore, be distinguished. Future research could compare unprompted first responses, generic requests to reconsider, and targeted metacognitive cues in independent sessions.
An especially important reservation applies to the Cogito responses and AGI self-ratings. LLMs do not necessarily possess privileged introspective access to their internal architecture, processing states, training history, or possible subjective status. Their answers are generated self-descriptions constructed from the prompt, conversational record, learned discourse about AI, publicly available model information, and alignment constraints. Referring each model back to its performance on the cognitive test may support a functionally evidence-based self-appraisal, but it may also generate demand characteristics: the model may infer that it is expected to explain its successes, failures, or upgrading in a coherent manner. Similarly, the stability of the Cogito positions may reflect conceptual continuity within model families, but it may also be strengthened when earlier formulations are available in the conversational context.
The models may have interpreted the rating scale itself. The models differed in whether they construed AGI as a graded collection of functional capacities or as a categorical status requiring autonomy, embodiment, continuous learning, and self-awareness. They also differed in whether the upper anchor represented performance relative to other contemporary AI systems or the hypothetical performance of a complete AGI. Therefore, overall percentages and changes in component ratings may not be measurements on a common interval scale. Some of these changes may represent genuine capability changes, whereas others may reflect stricter calibration, changed scale anchoring, reduced anthropomorphism, or different conceptions of morality, autonomy, and learning.
The cross-version retesting is quasi-longitudinal rather than longitudinal in the conventional developmental sense. We did not follow the same enduring artificial individual as it accumulated experience over time. Rather, we compared successor versions or operating configurations within the ChatGPT, Gemini, Grok, and DeepSeek model families. Differences between administrations may reflect additional developer-mediated training, post-training, architectural changes, expanded multimodality, tool integration, longer context windows, or greater inference-time reasoning. They do not necessarily reflect learning accumulated by one continuously existing artificial subject.
Finally, we cannot rule out prior exposure to some test items. Items or closely related problem formats may have appeared in published articles, educational materials, benchmark collections, or other parts of the models’ training corpora. Differences between tasks may, therefore, partly reflect unequal familiarity rather than only differences in cognitive demand. Repeated longitudinal retesting alone would not resolve this concern. Stronger future designs would employ unpublished parallel forms, procedurally generated items, systematic paraphrases, novel visual configurations, and private test sets unavailable during model training.
Despite these limitations, the convergence of some first-pass errors, the capacity for correction after feedback, the stability of the models’ rejection of a Cartesian conscious self, and the differentiated changes in their AGI self-ratings provide useful exploratory evidence. The findings justify more systematic investigation using repeated independent administrations, standardized prompts, counterbalanced orders, blind cross-version testing, and externally validated behavioral criteria. Such research could clarify the extent to which LLM self-evaluation reflects functional cognizance, contextual adaptation, calibration, or merely coherent generation of metacognitive discourse.



 ,