
Unsupervised Domain Adaptation with Multimodal Fusion for Monocular 3D Object Detection


Abstract
1. Introduction
- We propose a quality-aware pseudo-label generation strategy that combines an object-level random scaling strategy to mitigate cross-domain object-size bias with a three-interval memory bank using IoU-based scoring to iteratively refine pseudo-labels in the target domain.
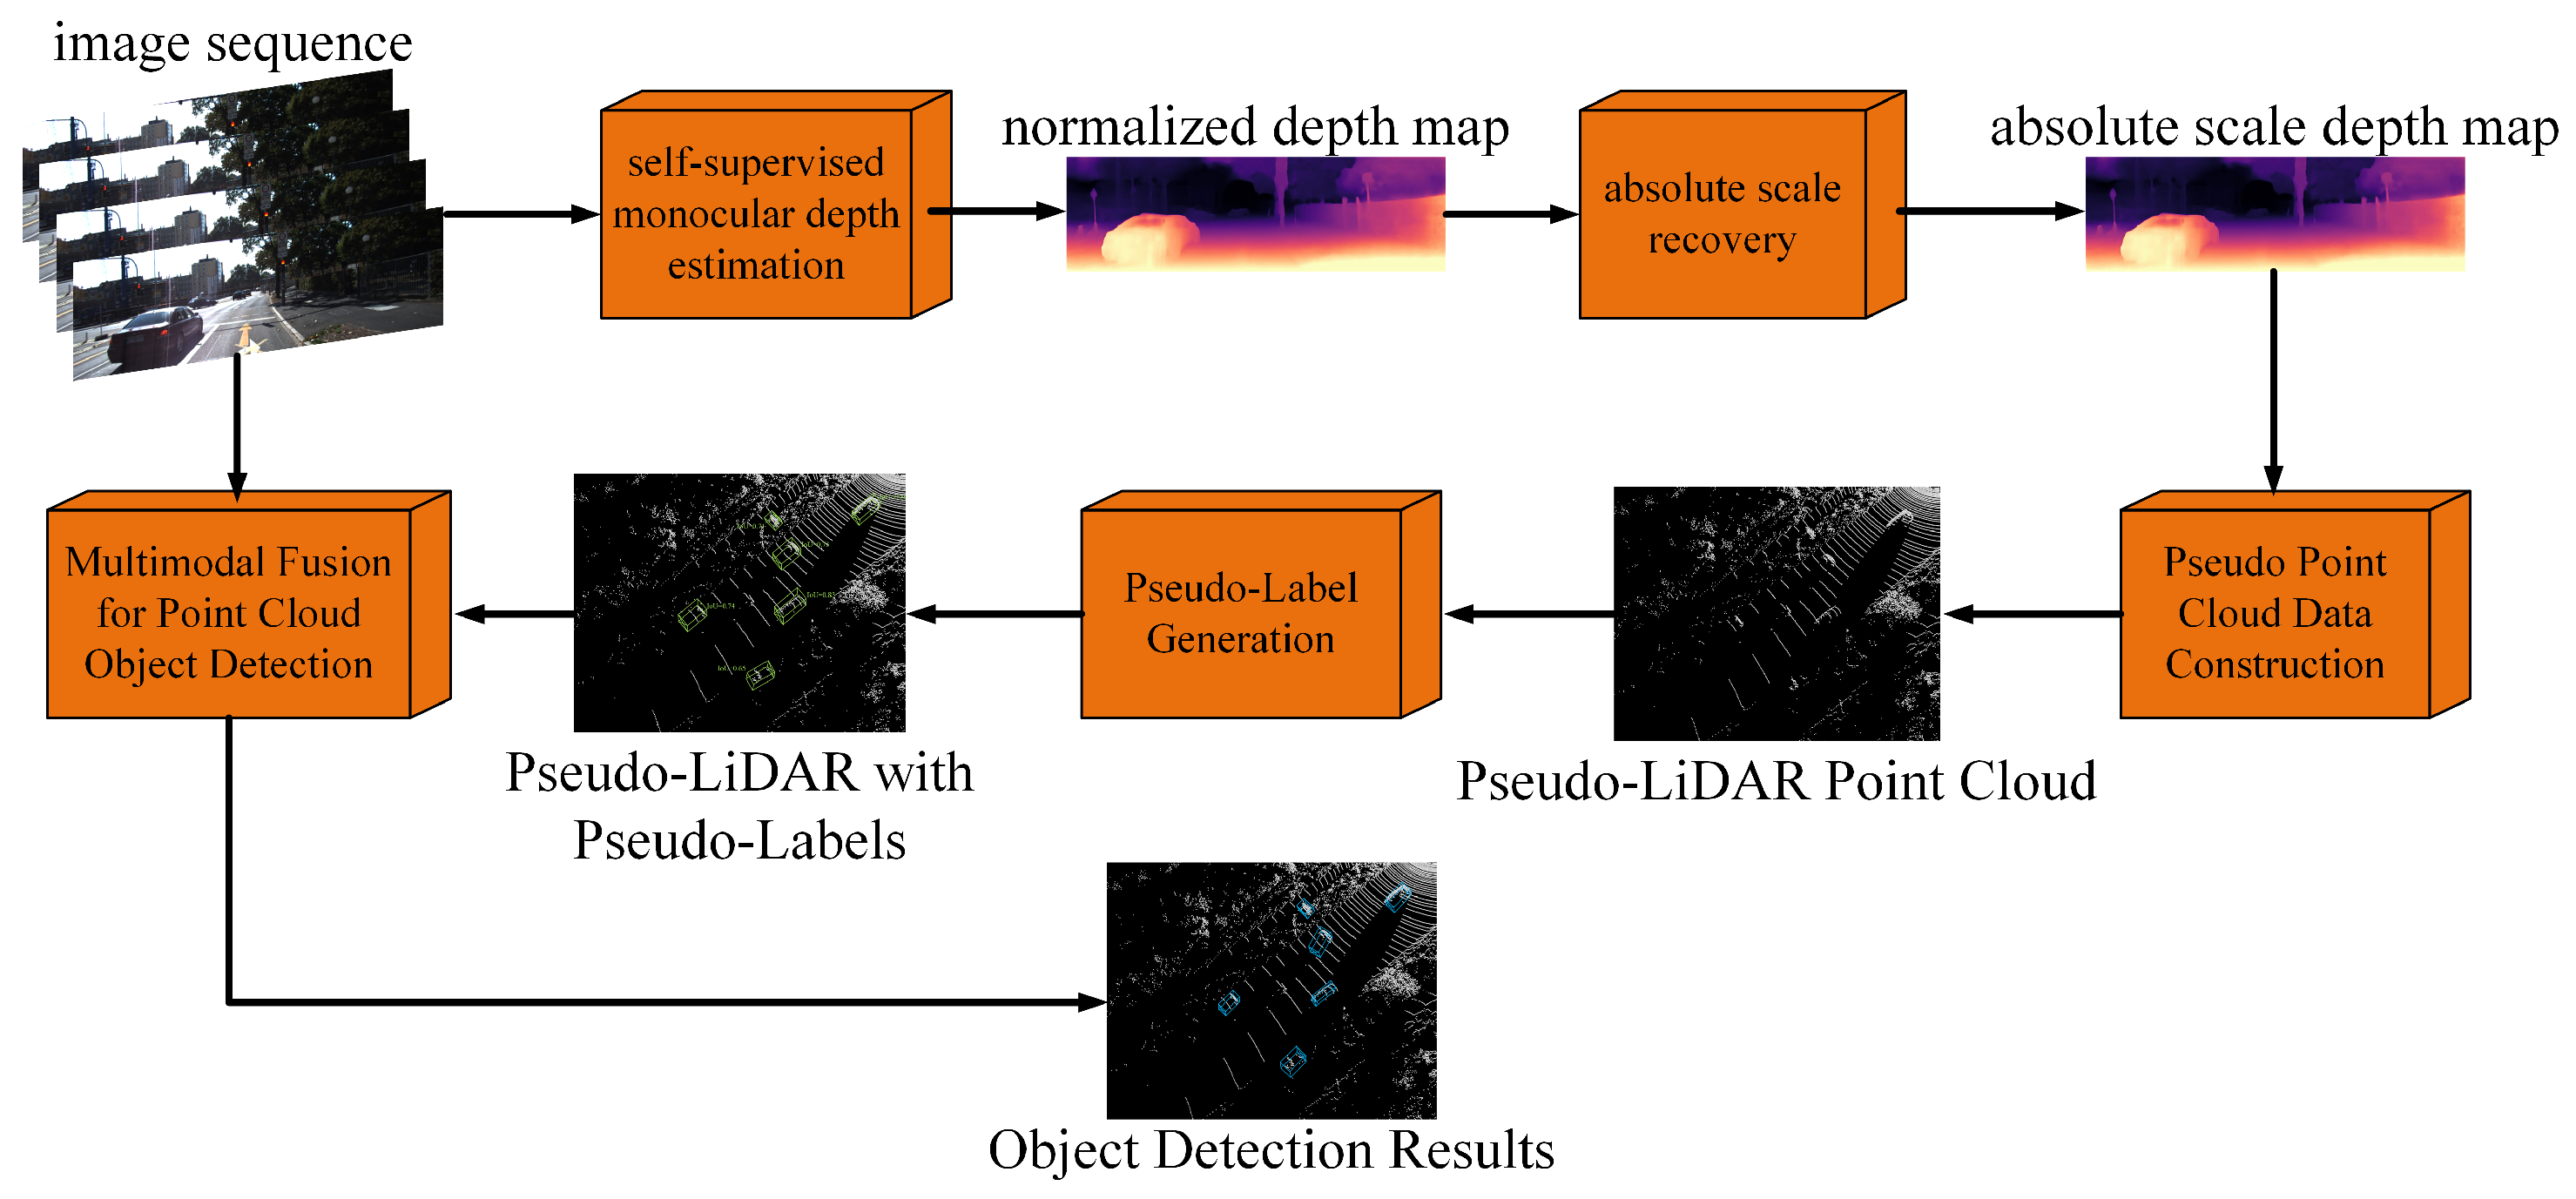
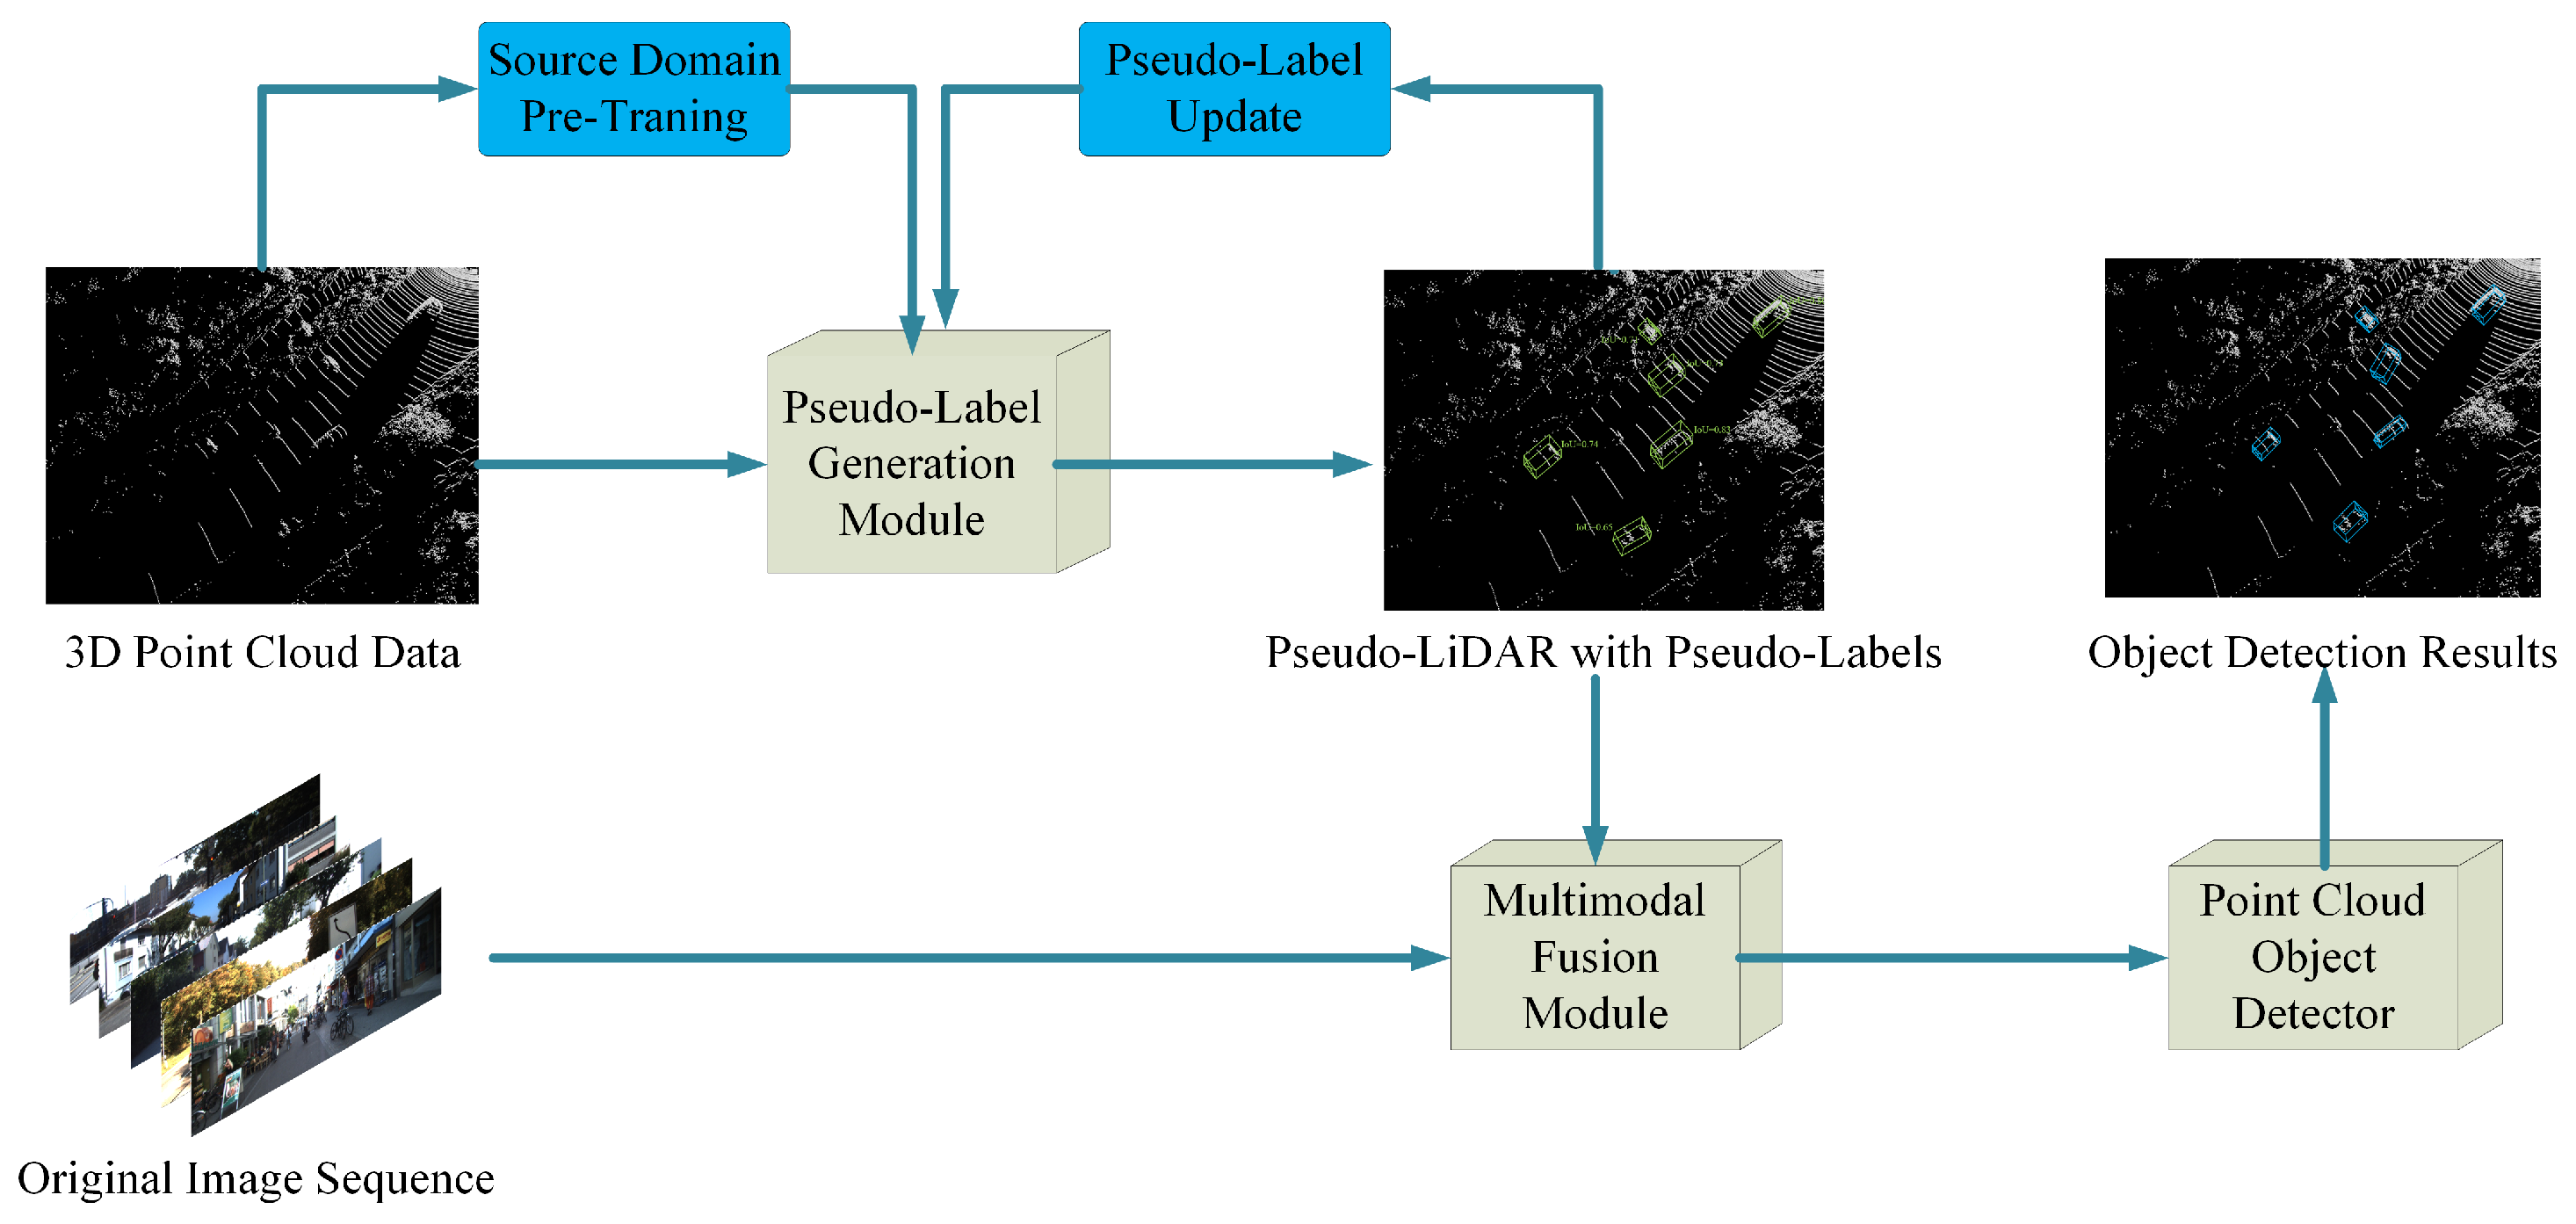
- We construct UM3D, an end-to-end unsupervised domain adaptation framework that unifies self-supervised depth estimation, Pseudo-LiDAR generation with density-based interval sampling, quality-aware pseudo-label generation, and multimodal fusion-based 3D detection into a single differentiable pipeline, jointly optimized through a multi-network consistency loss. The entire pipeline requires only a single monocular camera at inference, as the Pseudo-LiDAR representation is derived from the same input image rather than from an additional sensor.
2. Related Works
2.1. Supervised Learning-Based Monocular 3D Object Detection
2.2. Unsupervised Learning-Based Monocular 3D Object Detection
3. Method
3.1. Pseudo-LiDAR Point Cloud Generation
3.1.1. Depth Map to Pseudo-LiDAR Conversion
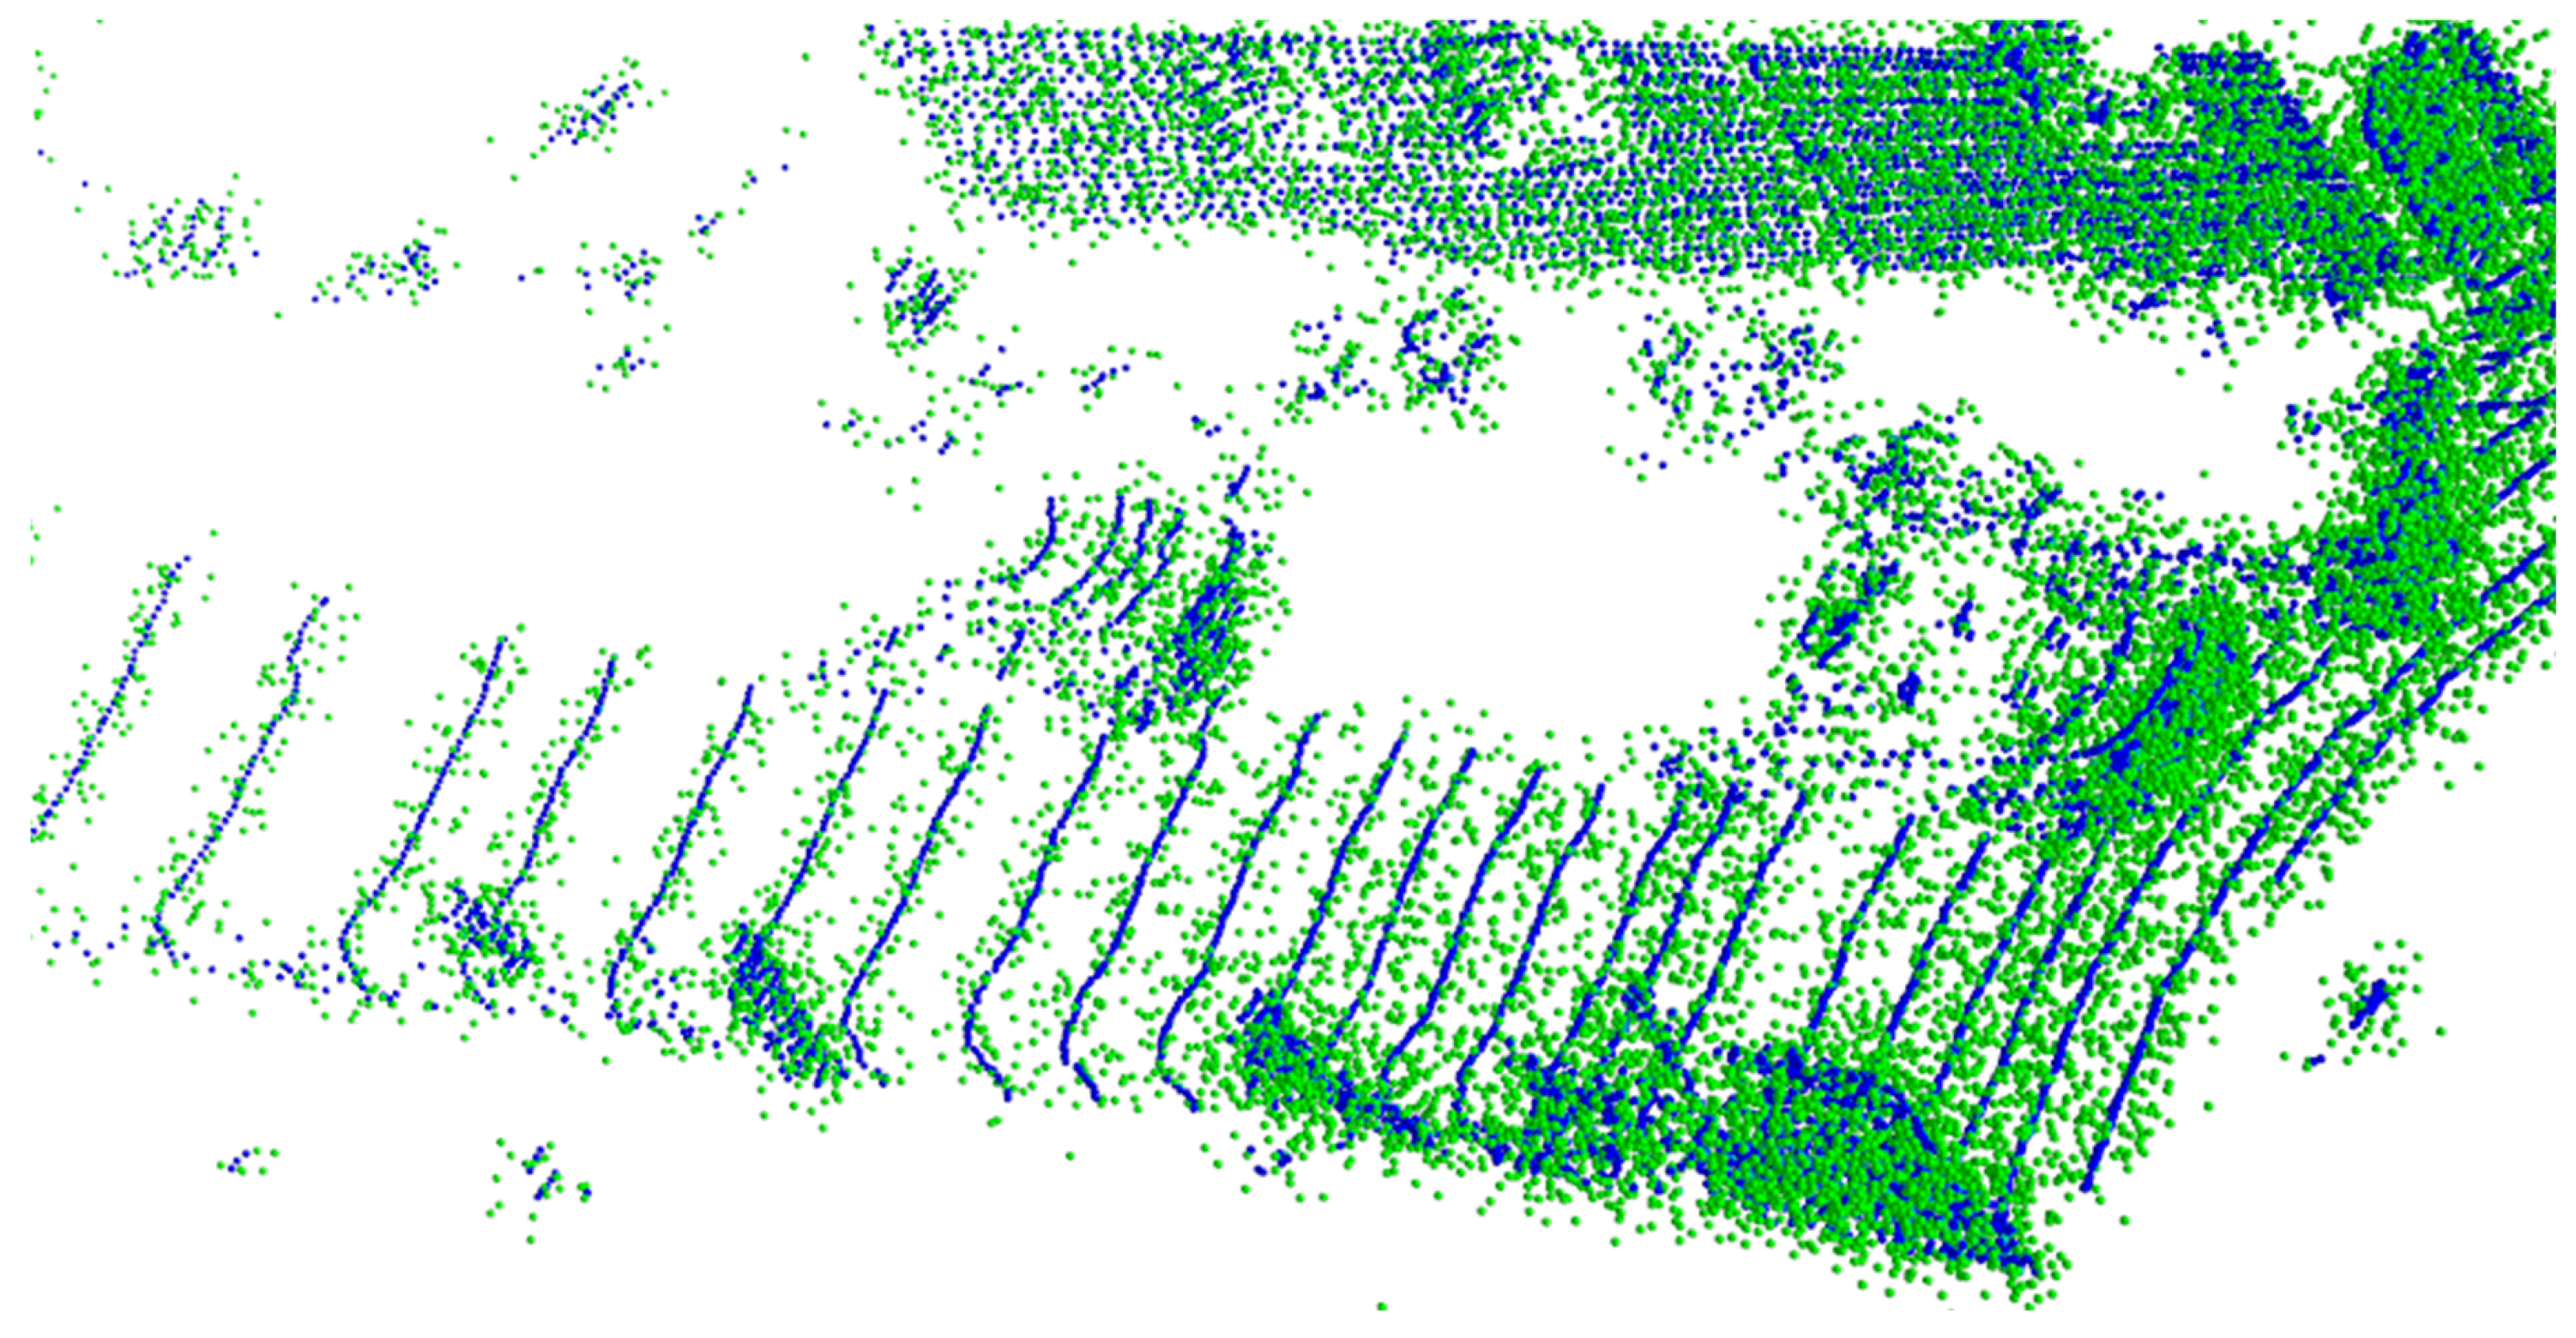
3.1.2. Density-Based Interval Sampling
3.2. Quality-Aware Pseudo-Label Generation
3.2.1. Object-Level Random Scaling Strategy for Source Domain Pre-Training
3.2.2. Pseudo-Label Generation Module
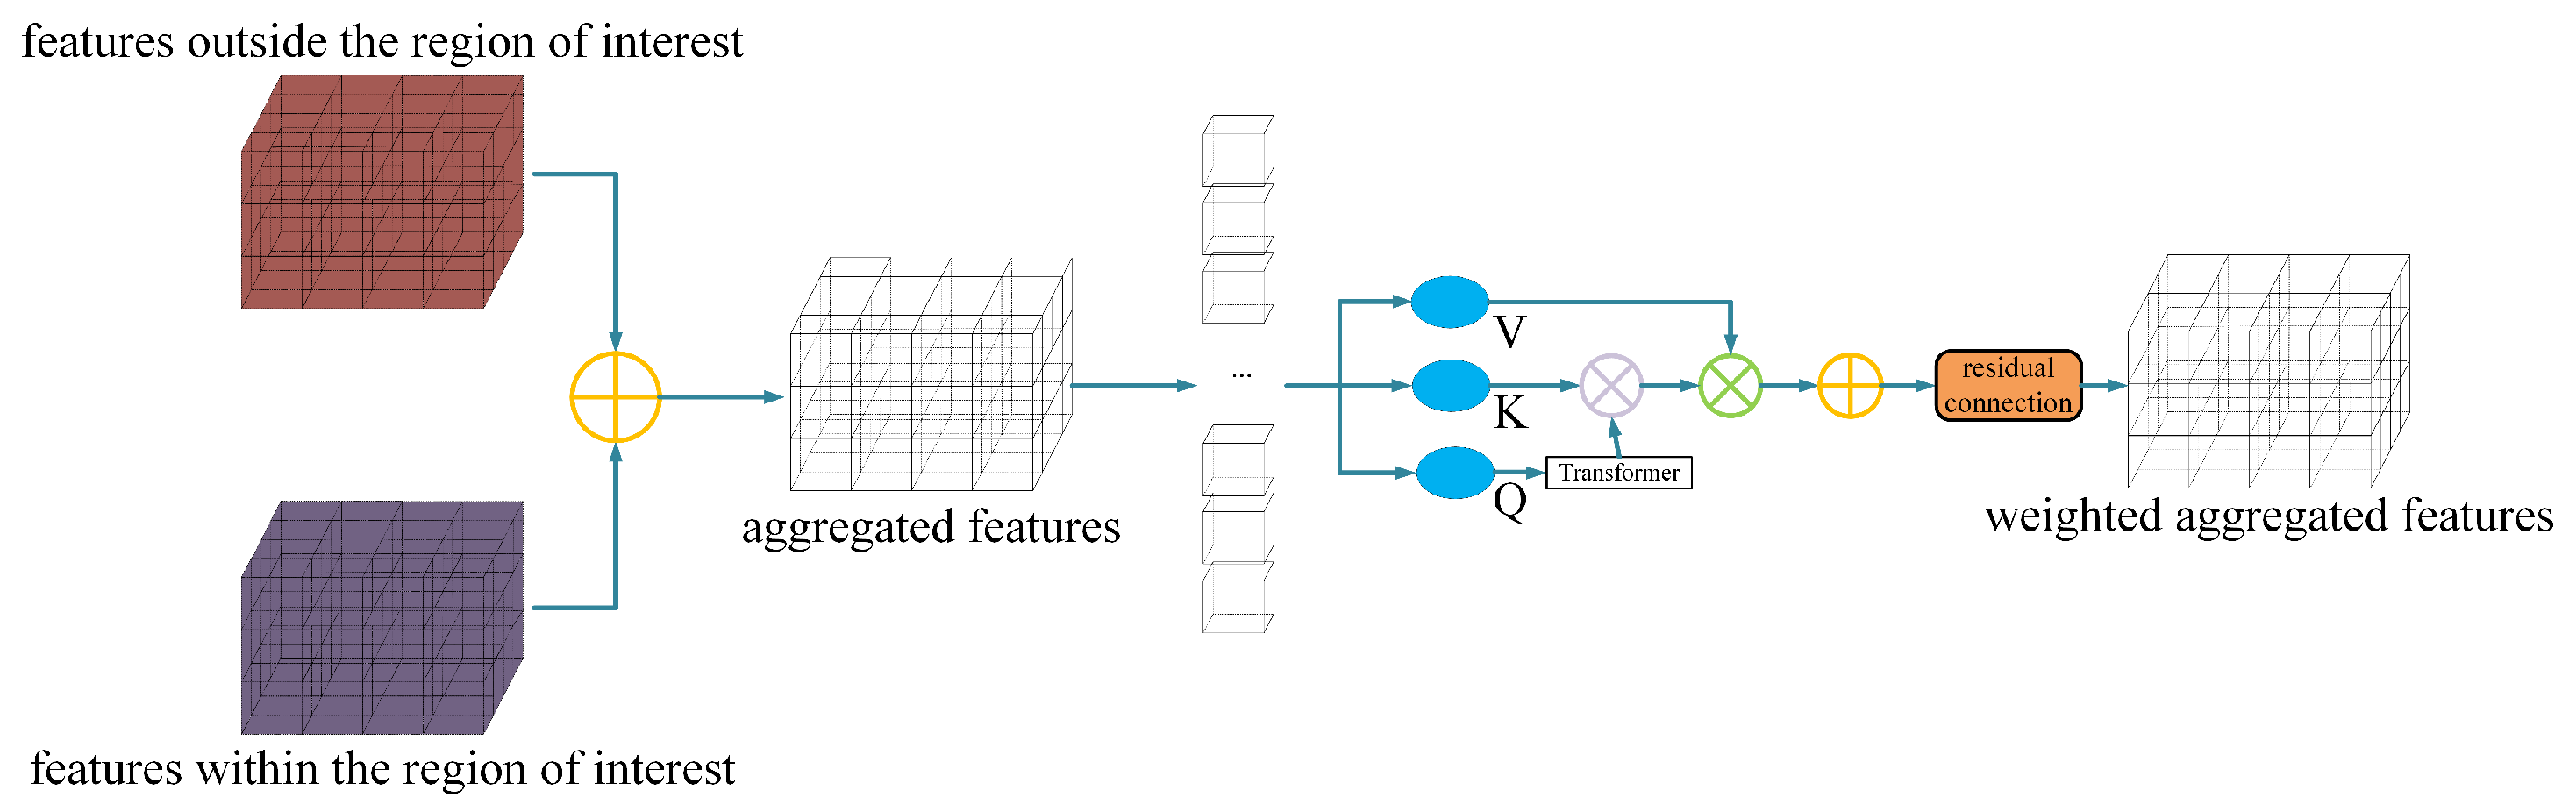
3.3. Multimodal Fusion for 3D Object Detection
3.4. End-to-End Network Implementation
3.4.1. Differentiable Change of Representation
3.4.2. Loss Function: Multi-Network Consistency Loss
| Algorithm 1: UM3D Training Procedure. |
 |
4. Experimental Results
4.1. Implementation Details
4.2. Experimental Setup
4.3. Main Results
4.3.1. Quantitative Results
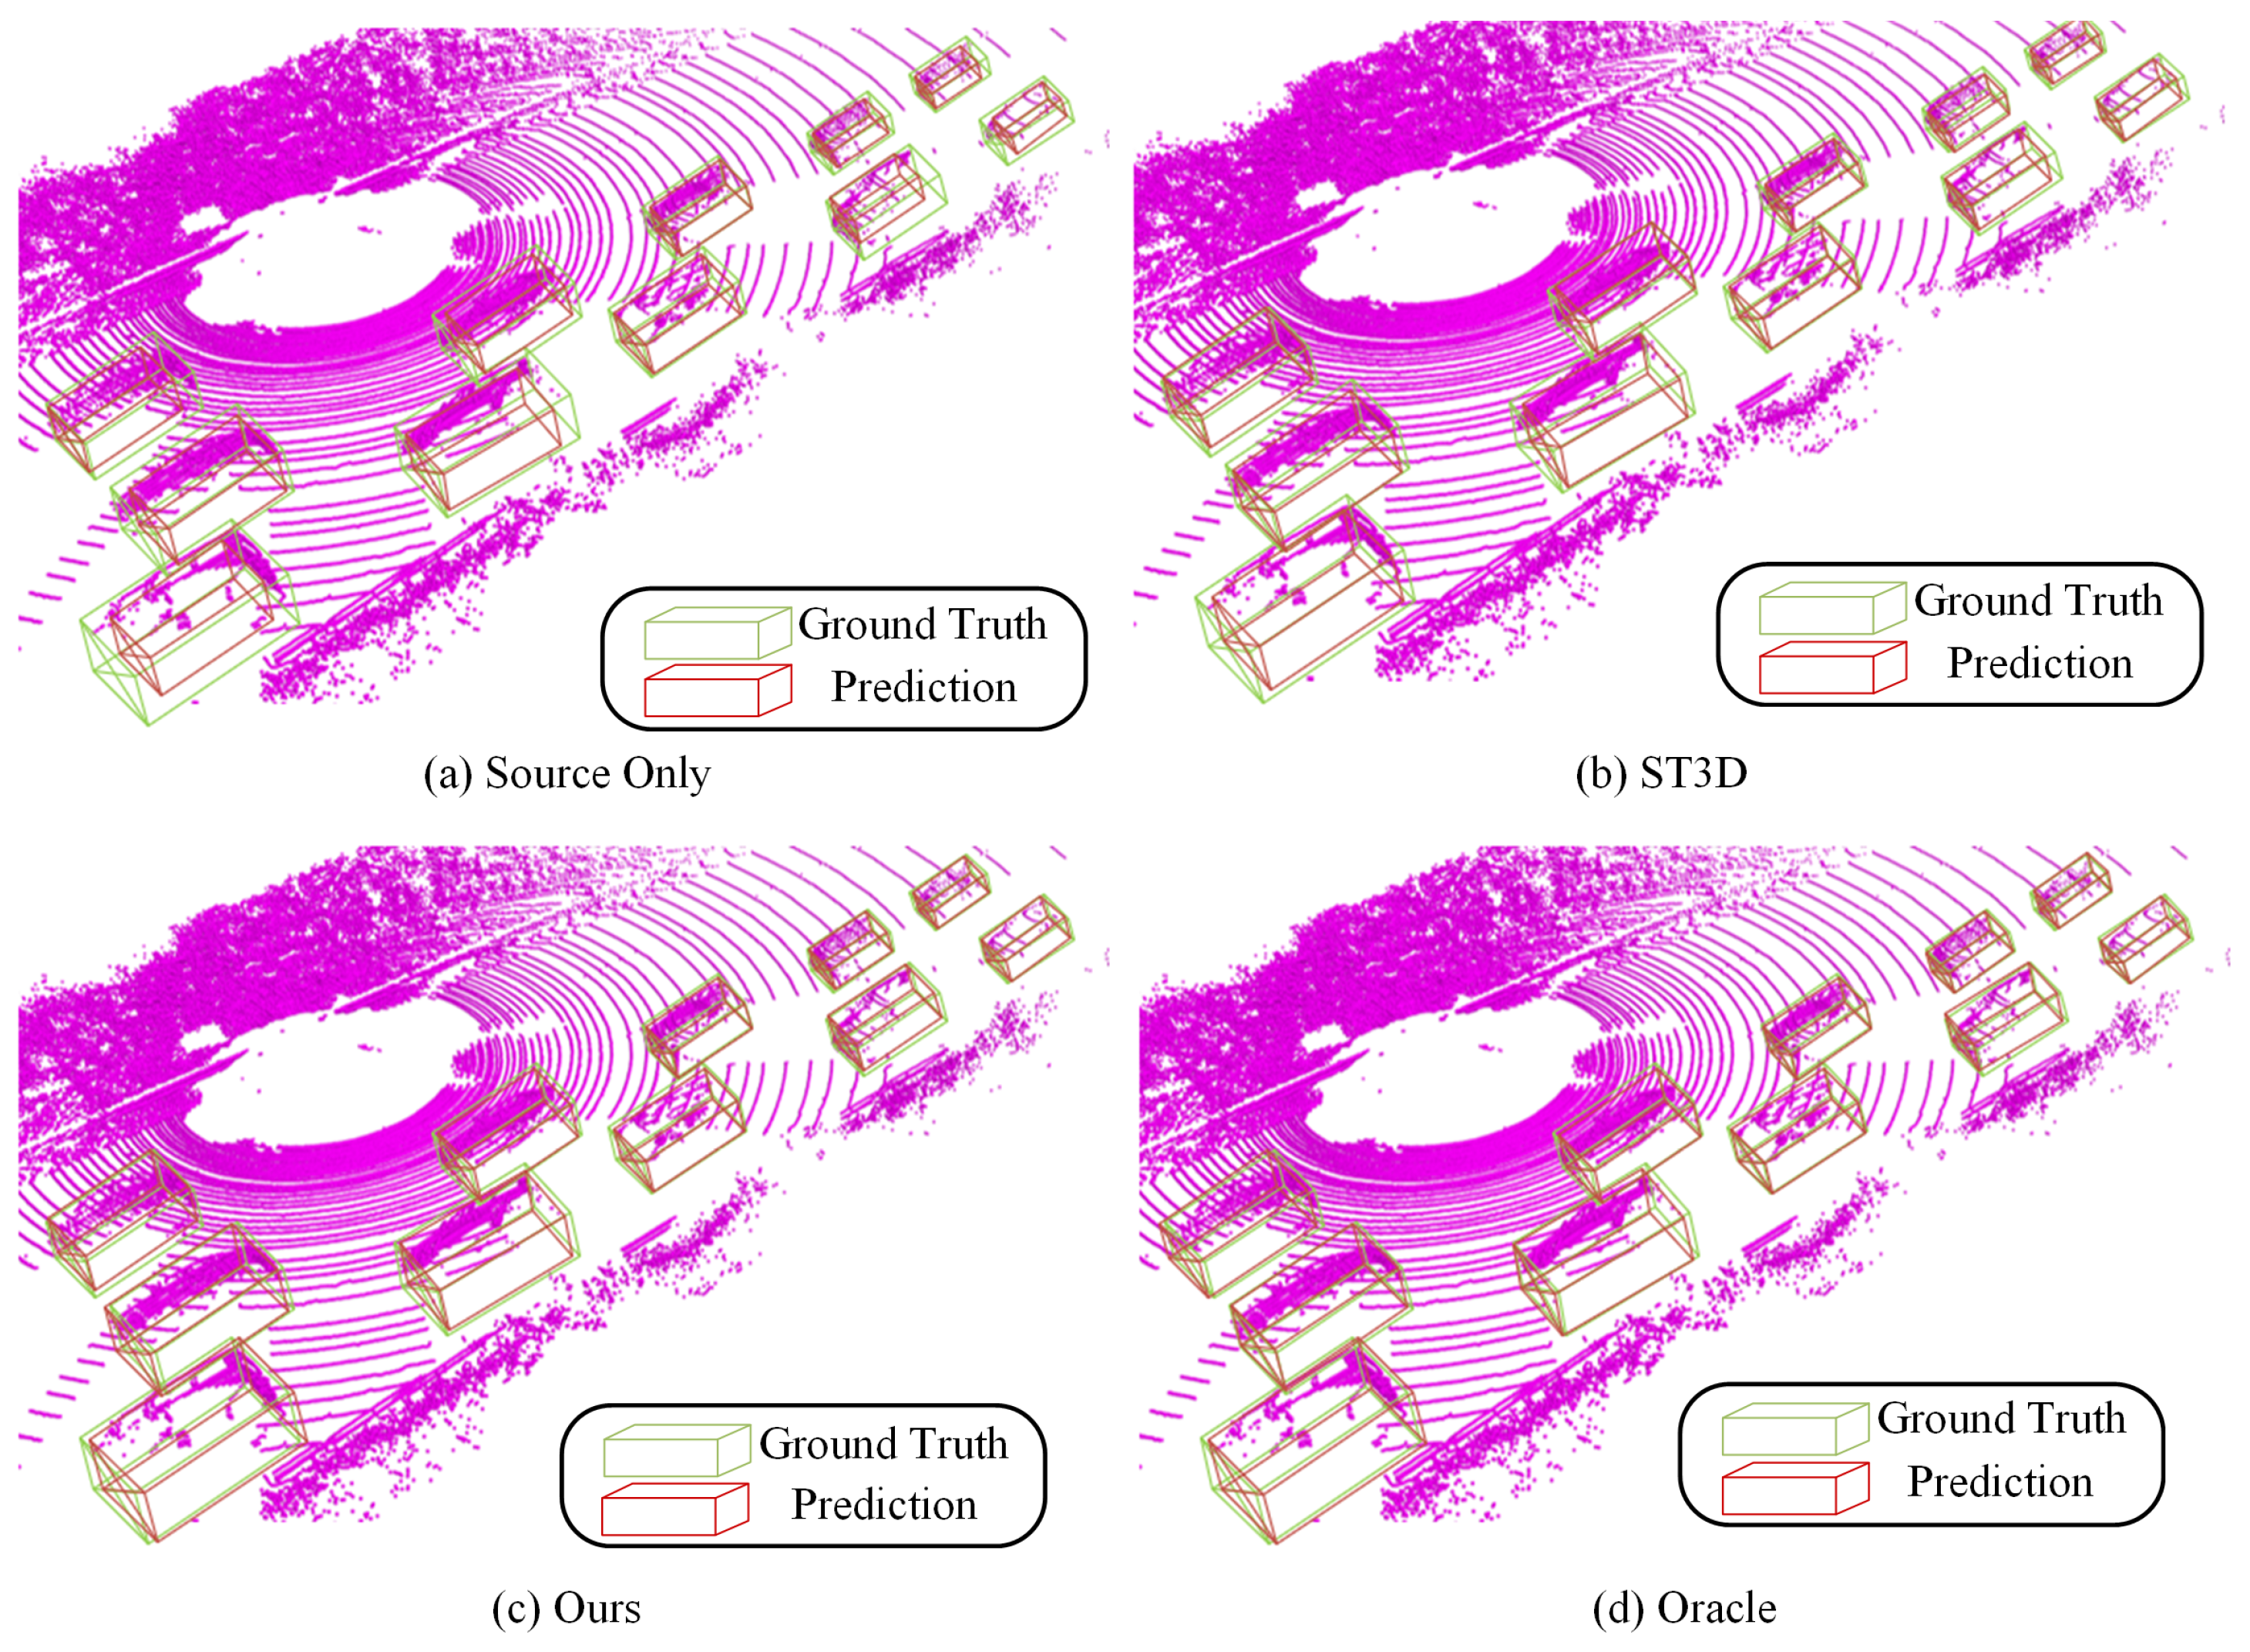
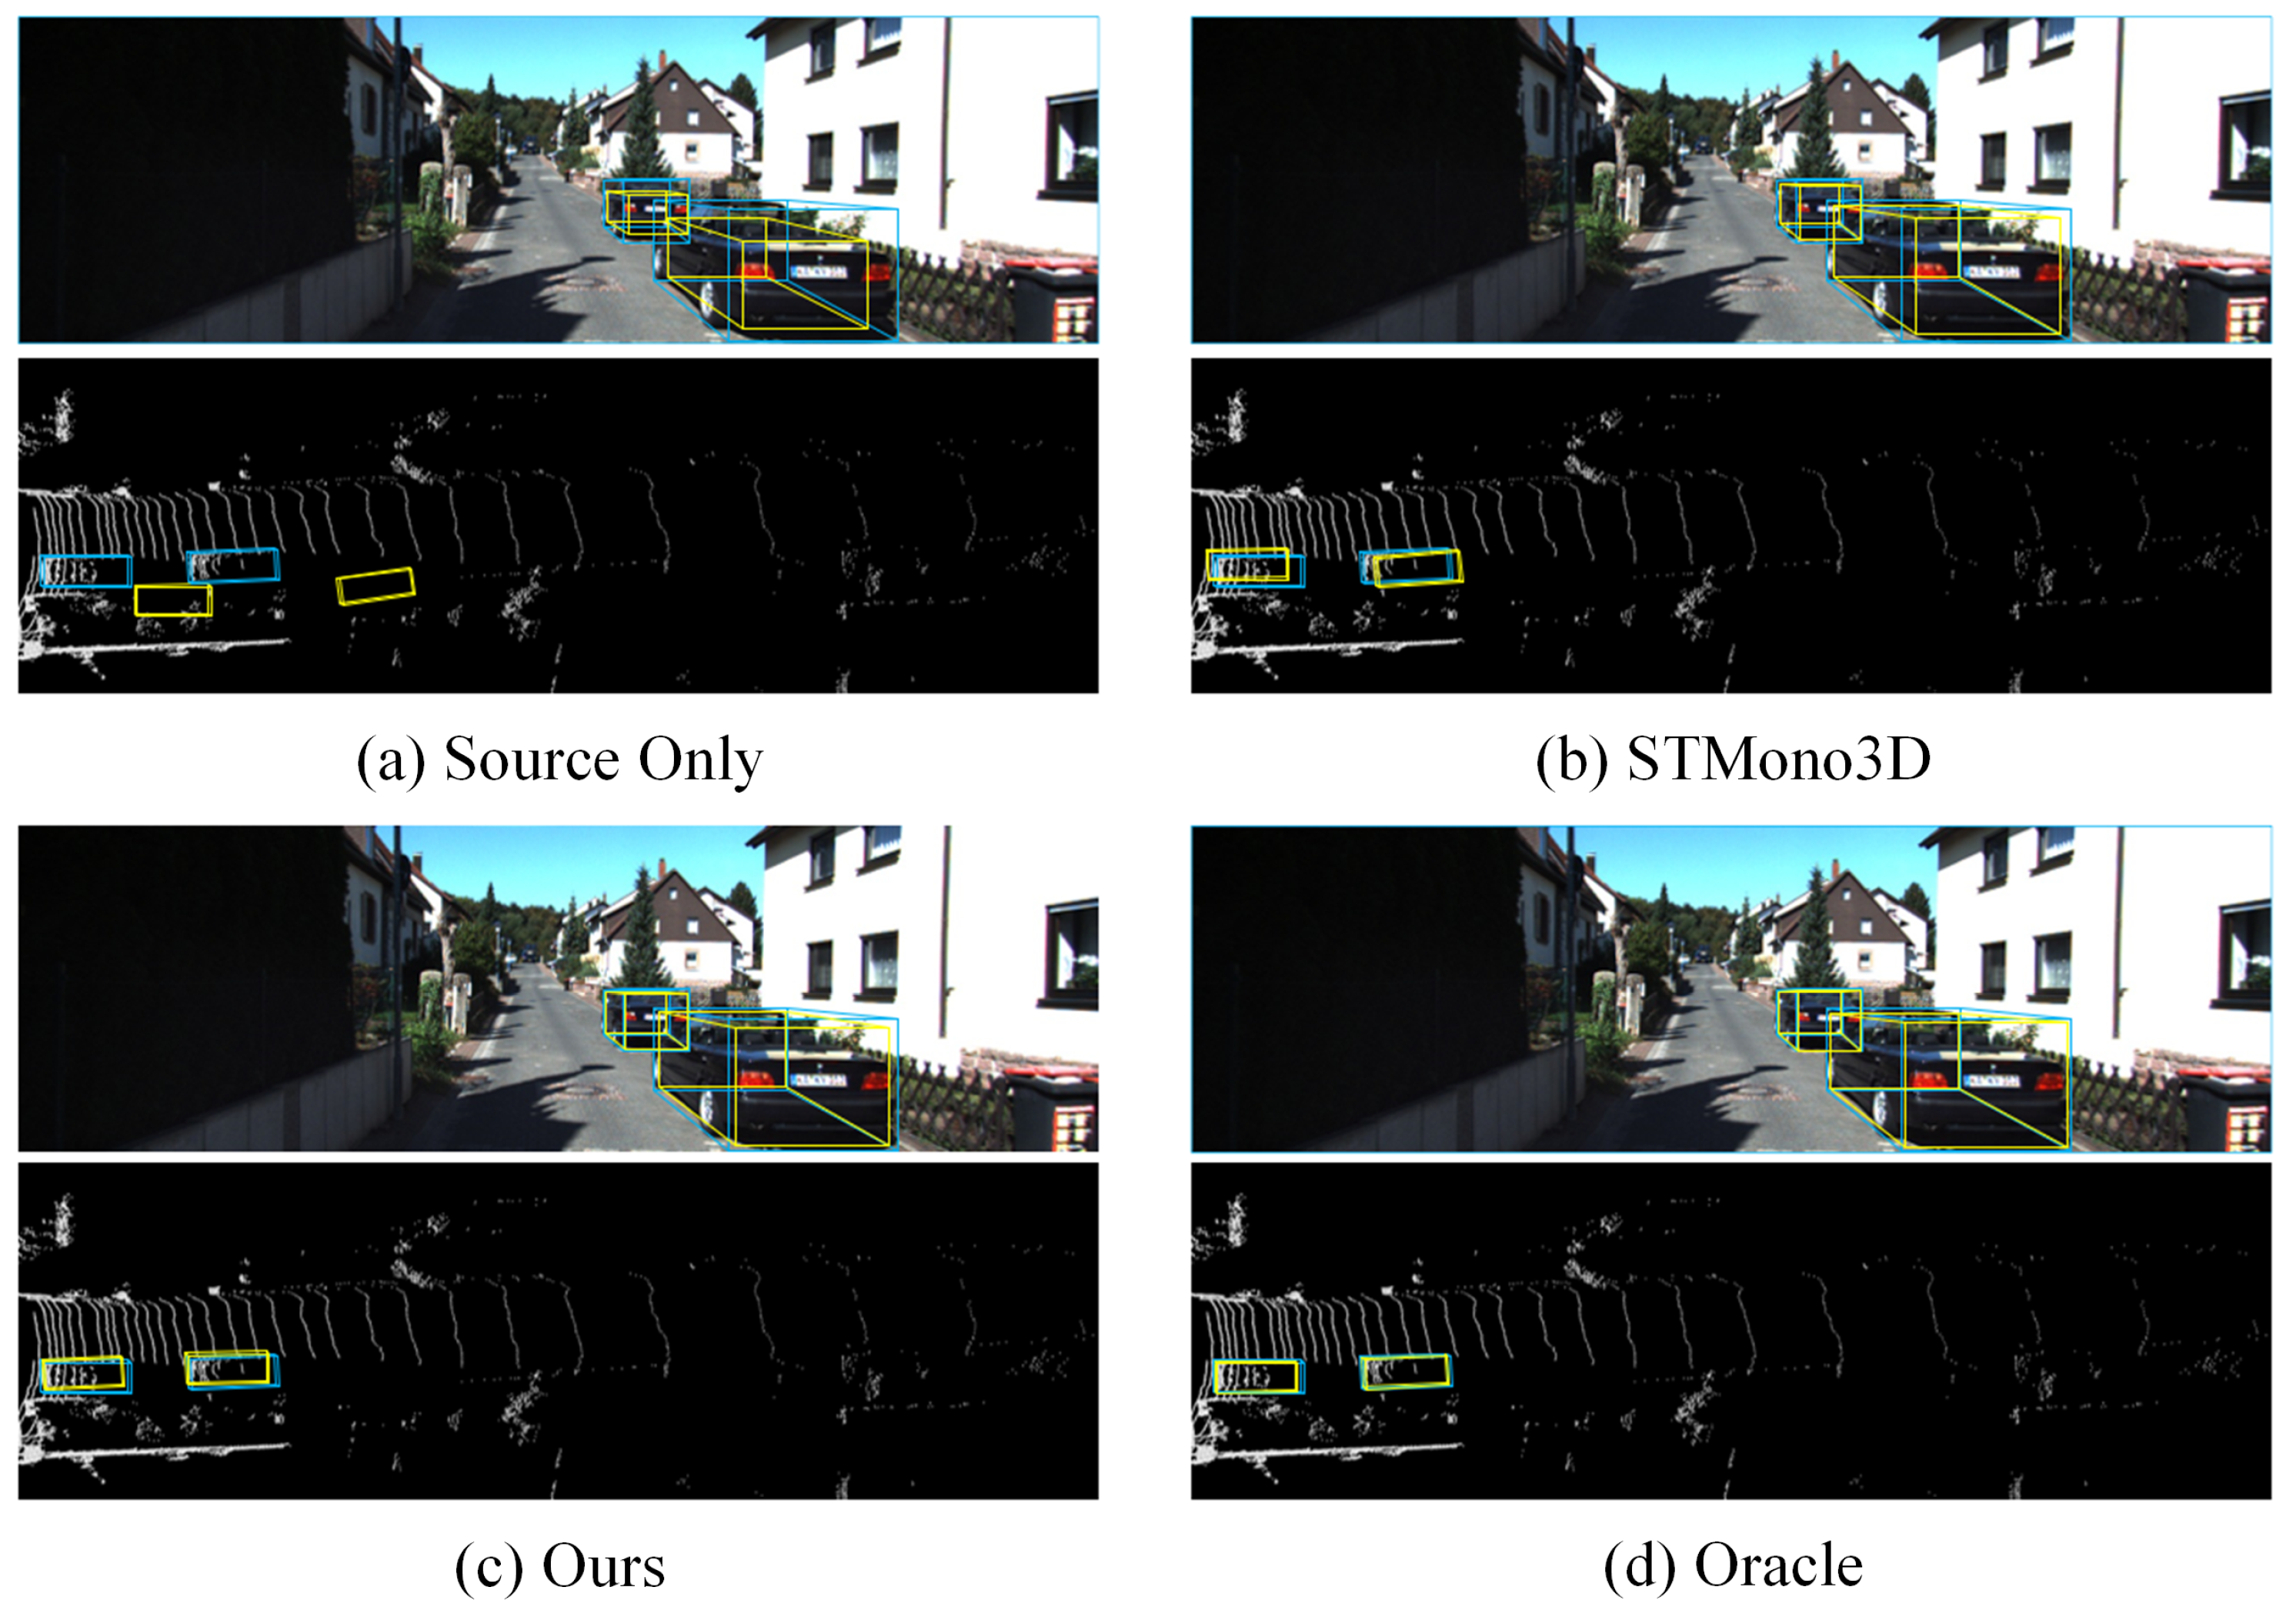
4.3.2. Qualitative Results
4.4. Ablation Studies
5. Conclusions
Author Contributions
Funding
Institutional Review Board Statement
Informed Consent Statement
Data Availability Statement
Conflicts of Interest
Abbreviations
| AP | Average Precision |
| BEV | Bird’s Eye View |
| CNN | Convolutional Neural Network |
| CoR | Change of Representation |
| IoU | Intersection over Union |
| mAOE | mean Average Orientation Error |
| mAP | mean Average Precision |
| mASE | mean Average Scale Error |
| mATE | mean Average Translation Error |
| ORSS | Object-Level Random Scaling Strategy |
| PLGM | Pseudo-Label Generation Module |
| RBF | Radial Basis Function |
| RCNN | Region-based Convolutional Neural Network |
| RoI | Region of Interest |
| RPN | Region Proposal Network |
| UDA | Unsupervised Domain Adaptation |
| UM3D | Unsupervised Monocular 3D Detection |
| WOD | Waymo Open Dataset |
References
- Simeonov, G.; Bayer, P.; Simoudis, E. Real-Time 3D Scene Understanding and Object Detection for Autonomous Vehicle Awareness. Vehicles 2026, 8, 28. [Google Scholar] [CrossRef] [Scilit]
- Fawole, O.A.; Rawat, D.B. Recent advances in 3D object detection for self-driving vehicles: A survey. AI 2024, 5, 1255–1285. [Google Scholar] [CrossRef] [Scilit]
- Gupta, A.; Jain, S.; Choudhary, P.; Parida, M. Dynamic object detection using sparse LiDAR data for autonomous machine driving and road safety applications. Expert Syst. Appl. 2024, 255, 124636. [Google Scholar] [CrossRef] [Scilit]
- Zhang, S.; Yang, J.; Hao, T.; Wu, S.; Li, M. Temporal feature fusion with deformable attention for multi-view 3D object detection. Digit. Signal Process. 2026, 168, 105518. [Google Scholar] [CrossRef] [Scilit]
- Li, Z.; Wang, W.; Li, H.; Xie, E.; Sima, C.; Lu, T.; Yu, Q.; Dai, J. BEVFormer: Learning bird’s-eye-view representation from LiDAR-camera via spatiotemporal transformers. IEEE Trans. Pattern Anal. Mach. Intell. 2025, 47, 2020–2036. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Philion, J.; Fidler, S. Lift, splat, shoot: Encoding images from arbitrary camera rigs by implicitly unprojecting to 3D. In Proceedings of the European Conference on Computer Vision (ECCV), Glasgow, UK, 23–28 August 2020; pp. 194–210. [Google Scholar] [CrossRef] [Scilit]
- Chen, X.; Kundu, K.; Zhang, Z.; Ma, H.; Fidler, S.; Urtasun, R. Monocular 3D object detection for autonomous driving. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Las Vegas, NV, USA, 27–30 June 2016; pp. 2147–2156. [Google Scholar] [CrossRef] [Scilit]
- Chen, X.; Kundu, K.; Zhu, Y.; Berneshawi, A.G.; Ma, H.; Fidler, S.; Urtasun, R. 3D object proposals for accurate object class detection. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), Montreal, QC, Canada, 7–12 December 2015; Volume 28, pp. 424–432. [Google Scholar]
- Mousavian, A.; Anguelov, D.; Flynn, J.; Kosecka, J. 3D bounding box estimation using deep learning and geometry. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Honolulu, HI, USA, 21–26 July 2017; pp. 5632–5640. [Google Scholar] [CrossRef] [Scilit]
- Gao, Y.; Wang, P.; Li, X.; Sun, M.; Di, R.; Li, L.; Hong, W. MonoDFNet: Monocular 3D object detection with depth fusion and adaptive optimization. Sensors 2025, 25, 760. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, C.; Aouf, N. Depth-enhanced deep learning approach for monocular camera based 3D object detection. J. Intell. Robot. Syst. 2024, 110, 101. [Google Scholar] [CrossRef] [Scilit]
- Pan, C.; Peng, J.; Zhang, Z. Depth-guided vision transformer with normalizing flows for monocular 3D object detection. IEEE/CAA J. Autom. Sin. 2024, 11, 673–689. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Chao, W.L.; Garg, D.; Hariharan, B.; Campbell, M.; Weinberger, K.Q. Pseudo-LiDAR from visual depth estimation: Bridging the gap in 3D object detection for autonomous driving. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, CA, USA, 16–20 June 2019; pp. 8437–8445. [Google Scholar] [CrossRef] [Scilit]
- Chen, Y.N.; Dai, H.; Ding, Y. Pseudo-stereo for monocular 3D object detection in autonomous driving. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 877–887. [Google Scholar] [CrossRef] [Scilit]
- Meng, H.; Li, C.; Chen, G.; Chen, L.; Knoll, A. Efficient 3D object detection based on pseudo-LiDAR representation. IEEE Trans. Intell. Veh. 2024, 9, 1953–1964. [Google Scholar] [CrossRef] [Scilit]
- Yang, R.; You, Z.; Luo, R. MSFNet3D: Monocular 3D object detection via dual-branch depth-consistent fusion and semantic-guided point cloud refinement. World Electr. Veh. J. 2025, 16, 173. [Google Scholar] [CrossRef] [Scilit]
- Qian, R.; Garg, D.; Wang, Y.; You, Y.; Belongie, S.; Hariharan, B.; Campbell, M.; Weinberger, K.Q.; Chao, W.L. End-to-end pseudo-LiDAR for image-based 3D object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 5880–5889. [Google Scholar] [CrossRef] [Scilit]
- Zhou, Y.; Zhang, C.; Deng, L.; Fu, J.; Li, H.; Xu, Z.; Zhang, J. Resolution-sensitive self-supervised monocular absolute depth estimation. Appl. Intell. 2024, 54, 4781–4793. [Google Scholar] [CrossRef] [Scilit]
- Ganin, Y.; Lempitsky, V. Unsupervised domain adaptation by backpropagation. In Proceedings of the International Conference on Machine Learning (ICML), Lille, France, 6–11 July 2015; Volume 37, pp. 1180–1189. [Google Scholar]
- Ben-David, S.; Blitzer, J.; Crammer, K.; Kulesza, A.; Pereira, F.; Vaughan, J.W. A theory of learning from different domains. Mach. Learn. 2010, 79, 151–175. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Zhou, C.; Huang, D. STAL3D: Unsupervised domain adaptation for 3D object detection via collaborating self-training and adversarial learning. IEEE Trans. Intell. Veh. 2024, 9, 4753–4764. [Google Scholar] [CrossRef] [Scilit]
- Luo, Y.; Liu, P.; Zheng, L.; Guan, T.; Yu, J.; Yang, Y. Category-level adversarial adaptation for semantic segmentation using purified features. IEEE Trans. Pattern Anal. Mach. Intell. 2022, 44, 3940–3956. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wozniak, M.K.; Hansson, M.; Thiel, M.; Jensfelt, P. UADA3D: Unsupervised adversarial domain adaptation for 3D object detection with sparse LiDAR and large domain gaps. IEEE Robot. Autom. Lett. 2024, 9, 11450–11457. [Google Scholar] [CrossRef] [Scilit]
- Tsai, D.; Berrio, J.S.; Shan, M.; Nebot, E.; Worrall, S. MS3D++: Ensemble of experts for multi-source unsupervised domain adaptation in 3D object detection. IEEE Trans. Intell. Veh. 2025, 10, 1999–2014. [Google Scholar] [CrossRef] [Scilit]
- Yang, J.; Shi, S.; Wang, Z.; Li, H.; Qi, X. ST3D: Self-training for unsupervised domain adaptation on 3D object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 19–25 June 2021; pp. 10363–10373. [Google Scholar] [CrossRef] [Scilit]
- Li, Z.; Yao, Y.; Quan, Z.; Qi, L.; Feng, Z.H.; Yang, W. Adaptation via proxy: Building instance-aware proxy for unsupervised domain adaptive 3D object detection. IEEE Trans. Intell. Veh. 2024, 9, 3478–3492. [Google Scholar] [CrossRef] [Scilit]
- Lu, X.; Radha, H. DALI: Domain adaptive LiDAR object detection via distribution-level and instance-level pseudo label denoising. IEEE Trans. Robot. 2024, 40, 4498–4514. [Google Scholar] [CrossRef] [Scilit]
- Reading, C.; Harakeh, A.; Chae, J.; Waslander, S.L. Categorical depth distribution network for monocular 3D object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 19–25 June 2021; pp. 8551–8560. [Google Scholar] [CrossRef] [Scilit]
- Wang, T.; Zhu, X.; Pang, J.; Lin, D. FCOS3D: Fully convolutional one-stage monocular 3D object detection. In Proceedings of the IEEE/CVF International Conference on Computer Vision Workshops, Montreal, QC, Canada, 11–17 October 2021; pp. 913–922. [Google Scholar] [CrossRef] [Scilit]
- Li, X.; Ma, T.; Hou, Y.; Shi, B.; Yang, Y.; Liu, Y.; Wu, X.; Chen, Q.; Li, Y.; Qiao, Y.; et al. LogoNet: Towards accurate 3D object detection with local-to-global cross-modal fusion. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, BC, Canada, 17–24 June 2023; pp. 17524–17534. [Google Scholar] [CrossRef] [Scilit]
- Brazil, G.; Liu, X. M3D-RPN: Monocular 3D region proposal network for object detection. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Seoul, Republic of Korea, 27 October–2 November 2019; pp. 9286–9295. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Wu, Z.; Tóth, R. SMOKE: Single-stage monocular 3D object detection via keypoint estimation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, Seattle, WA, USA, 13–19 June 2020; pp. 4289–4298. [Google Scholar] [CrossRef] [Scilit]
- Wang, K.; Zhou, P.; Hu, M.; Lu, J. Unsupervised 3D object detection domain adaptation based on pseudo-label variance regularization. IEEE Trans. Circuits Syst. Video Technol. 2025, 35, 6273–6285. [Google Scholar] [CrossRef] [Scilit]
- Li, Z.; Chen, Z.; Li, A.; Fang, L.; Jiang, Q.; Liu, X.; Jiang, J. Unsupervised domain adaptation for monocular 3D object detection via self-training. In Proceedings of the European Conference on Computer Vision (ECCV), Tel Aviv, Israel, 23–27 October 2022; pp. 245–262. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Z.; Chen, M.; Xiao, S.; Peng, L.; Li, H.; Lin, B.; Li, P.; Wang, W.; Wu, B.; Cai, D. Pseudo-label refinery for unsupervised domain adaptation on cross-dataset 3D object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 17–21 June 2024; pp. 15291–15300. [Google Scholar] [CrossRef] [Scilit]
- Godard, C.; Mac Aodha, O.; Firman, M.; Brostow, G.J. Digging into self-supervised monocular depth estimation. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Seoul, Republic of Korea, 27 October–2 November 2019; pp. 3828–3838. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Chen, X.; You, Y.; Li, L.E.; Hariharan, B.; Campbell, M.; Weinberger, K.Q.; Chao, W.L. Train in Germany, test in the USA: Making 3D object detectors generalize. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 11710–11720. [Google Scholar] [CrossRef] [Scilit]
- Yan, Y.; Mao, Y.; Li, B. SECOND: Sparsely embedded convolutional detection. Sensors 2018, 18, 3337. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Kingma, D.P.; Ba, J. Adam: A method for stochastic optimization. In Proceedings of the International Conference on Learning Representations (ICLR), San Diego, CA, USA, 7–9 May 2015. [Google Scholar]
- Geiger, A.; Lenz, P.; Urtasun, R. Are we ready for autonomous driving? The KITTI vision benchmark suite. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Providence, RI, USA, 16–21 June 2012; pp. 3354–3361. [Google Scholar] [CrossRef] [Scilit]
- Sun, P.; Kretzschmar, H.; Dotiwalla, X.; Chouard, A.; Patnaik, V.; Tsui, P.; Guo, J.; Zhou, Y.; Chai, Y.; Caine, B.; et al. Scalability in perception for autonomous driving: Waymo Open Dataset. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 2443–2451. [Google Scholar] [CrossRef] [Scilit]
- Caesar, H.; Bankiti, V.; Lang, A.H.; Vora, S.; Liong, V.E.; Xu, Q.; Krishnan, A.; Pan, Y.; Baldan, G.; Beijbom, O. nuScenes: A multimodal dataset for autonomous driving. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 11618–11628. [Google Scholar] [CrossRef] [Scilit]
- Kesten, R.; Usman, M.; Houston, J.; Pandya, T.; Nadhamuni, K.; Ferreira, A.; Yuan, M.; Low, B.; Jain, A.; Ondruska, P.; et al. Lyft Level 5 AV Dataset 2019. 2019. Available online: https://github.com/lyft/nuscenes-devkit (accessed on 15 March 2024).




| Method | Year | Category | Key Advantage | Key Limitation |
|---|---|---|---|---|
| Supervised line (target-domain labels required) | ||||
| Pseudo-LiDAR [13] | 2019 | Monocular → PL | Enables LiDAR detectors on image input | Supervised depth; error propagation |
| E2E-PL [17] | 2020 | End-to-end PL | Joint depth and detection optimization | Target-domain 3D labels required |
| FCOS3D [29] | 2021 | Direct monocular 3D | End-to-end, no intermediate step | No 3D geometric cues |
| LoGoNet [30] | 2023 | Multimodal LiDAR+image | Local–global cross-modal fusion | Real LiDAR hardware; full target supervision |
| MSFNet3D [16] | 2025 | Monocular + depth fusion | Dual-branch depth-consistent fusion with semantic refinement | Supervised; no domain adaptation |
| UDA line (no target-domain 3D labels) | ||||
| ST3D [25] | 2021 | Self-training (LiDAR) | Pioneered pseudo-label self-training | Single modality; unreliable confidence filter |
| STMono3D [34] | 2022 | End-to-end UDA monocular 3D | First end-to-end UDA for monocular 3D | Image-only; no Pseudo-LiDAR geometry |
| DALI [27] | 2024 | Pseudo-label denoising | Distribution + instance-level denoising | Single modality |
| PseudoVariance [33] | 2025 | Variance-regularised UDA | Pseudo-label variance regularisation for 3D | Single modality (LiDAR) |
| UM3D (Ours) | – | End-to-end UDA multimodal + quality PL | Multimodal fusion, quality-aware PL, end-to-end joint optimization | Bounded by depth estimation quality at long range |
| Task | Method | LoGoNet | SECOND | ||
|---|---|---|---|---|---|
| / | Closed Gap | / | Closed Gap | ||
| nuScenes → KITTI | Source Only | 54.56/23.15 | - | 51.84/17.92 | - |
| SN [37] | 47.69/32.38 | −18.99%/+14.95% | 40.03/21.23 | −37.55%/+5.96% | |
| ST3D [25] | 78.26/57.41 | +65.51%/+55.50% | 75.94/54.13 | +76.63%/+65.20% | |
| Ours | 80.17/58.20 | +70.84%/+56.79% | 76.25/54.38 | +77.62%/+65.66% | |
| Oracle | 90.72/84.87 | - | 83.29/73.45 | - | |
| WOD → KITTI | Source Only | 69.12/31.59 | - | 67.64/27.48 | - |
| SN | 79.95/62.25 | +50.14%/+57.55% | 78.96/59.20 | +72.33%/+69.00% | |
| ST3D | 84.67/65.39 | +71.99%/+63.44% | 82.19/61.83 | +92.97%/+74.72% | |
| Ours | 85.71/67.44 | +76.81%/+67.27% | 82.96/62.75 | +97.89%/+76.73% | |
| Oracle | 90.72/84.87 | - | 83.29/73.45 | - | |
| Task | Method | LoGoNet | SECOND | ||
|---|---|---|---|---|---|
| / | Closed Gap | / | Closed Gap | ||
| WOD → nuScenes | Source Only | 39.28/24.65 | - | 32.91/17.24 | - |
| SN | 40.15/26.36 | +5.32%/+11.76% | 33.23/18.57 | +1.69%/+7.54% | |
| ST3D | 42.58/28.14 | +20.19%/+24.20% | 35.92/20.19 | +15.87%/+16.73% | |
| Ours | 44.10/29.57 | +29.49%/+33.86% | 36.84/23.62 | +20.72%/+36.18% | |
| Oracle | 55.62/39.18 | - | 51.88/34.87 | - | |
| Task | Method | LoGoNet | SECOND | ||
|---|---|---|---|---|---|
| / | Closed Gap | / | Closed Gap | ||
| WOD → Lyft | Source Only | 74.87/57.61 | - | 72.92/54.34 | - |
| SN | 74.93/57.89 | +0.57%/+2.01% | 72.33/54.34 | −5.11%/+0.00% | |
| ST3D | 78.14/59.93 | +31.26%/+16.68% | 76.32/59.24 | +29.44%/+33.93% | |
| Ours | 79.06/61.28 | +40.05%/+26.38% | 76.14/59.19 | +27.88%/+33.59% | |
| Oracle | 85.33/71.52 | - | 84.47/68.78 | - | |
| Task | Method | IoU ≥ 0.5 | IoU ≥ 0.5 | ||||
|---|---|---|---|---|---|---|---|
| Easy | Mod. | Hard | Easy | Mod. | Hard | ||
| nuScenes → KITTI | Source Only | 0 | 0 | 0 | 0 | 0 | 0 |
| STMono3D [34] | 35.63 | 27.37 | 23.95 | 28.65 | 21.89 | 19.55 | |
| Ours | 36.81 | 27.60 | 22.94 | 29.37 | 22.16 | 18.93 | |
| Oracle | 33.46 | 23.62 | 22.18 | 29.01 | 19.88 | 17.17 | |
| Lyft → KITTI | Source Only | 0 | 0 | 0 | 0 | 0 | 0 |
| STMono3D | 26.46 | 20.71 | 17.66 | 18.14 | 13.32 | 11.83 | |
| Ours | 28.23 | 21.59 | 17.98 | 19.32 | 13.35 | 11.16 | |
| Oracle | 33.46 | 23.62 | 22.18 | 29.01 | 19.88 | 17.17 | |
| WOD → KITTI | Source Only | 0 | 0 | 0 | 0 | 0 | 0 |
| STMono3D | 35.69 | 26.94 | 23.19 | 28.34 | 20.21 | 18.03 | |
| Ours | 36.10 | 27.67 | 23.48 | 29.08 | 20.92 | 18.84 | |
| Oracle | 33.46 | 23.62 | 22.18 | 29.01 | 19.88 | 17.17 | |
| Task | Method | mAP | mATE | mASE | mAOE |
|---|---|---|---|---|---|
| WOD → nuScenes | Source Only | 2.4 | 1.302 | 0.190 | 0.802 |
| STMono3D | 23.5 | 0.843 | 0.171 | 0.349 | |
| Ours | 25.7 | 0.820 | 0.168 | 0.311 | |
| Oracle | 28.2 | 0.798 | 0.160 | 0.209 | |
| Lyft → nuScenes | Source Only | 2.4 | 1.302 | 0.190 | 0.802 |
| STMono3D | 21.3 | 0.911 | 0.170 | 0.355 | |
| Ours | 22.1 | 0.898 | 0.173 | 0.304 | |
| Oracle | 28.2 | 0.798 | 0.160 | 0.209 |
| Module | Method | ||
|---|---|---|---|
| Source Only | SECOND | 67.64 | 27.48 |
| LoGoNet | 69.12 | 31.59 | |
| Baseline+ORSS | SECOND | 78.29 | 55.13 |
| LoGoNet | 79.46 | 56.08 | |
| Baseline+PLGM | SECOND | 81.30 | 59.42 |
| LoGoNet | 83.25 | 61.91 | |
| Baseline+PLGM+ORSS | SECOND | 82.96 | 62.75 |
| LoGoNet | 85.71 | 67.44 |
| Method | IoU ≥ 0.5 | IoU ≥ 0.5 | ||||
|---|---|---|---|---|---|---|
| Easy | Mod. | Hard | Easy | Mod. | Hard | |
| Depth | 30.26 | 20.71 | 17.35 | 25.51 | 16.06 | 14.48 |
| RCNN | 32.01 | 22.56 | 18.55 | 26.75 | 17.69 | 15.41 |
| RPN | 32.64 | 22.87 | 18.94 | 26.14 | 17.52 | 14.34 |
| RCNN + RPN | 33.89 | 23.42 | 19.80 | 26.99 | 17.10 | 15.85 |
| Depth + RPN | 35.62 | 26.36 | 21.16 | 28.74 | 19.23 | 16.19 |
| Depth + RCNN | 35.98 | 26.73 | 23.20 | 29.32 | 19.15 | 17.41 |
| Depth + RCNN + RPN | 36.10 | 27.67 | 23.48 | 29.08 | 20.92 | 18.84 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Jiang, J.; Dai, J.; Li, W.; Zhou, Y.; Ye, M.; Zhang, J.; Zhang, C. Unsupervised Domain Adaptation with Multimodal Fusion for Monocular 3D Object Detection. Vehicles 2026, 8, 98. https://doi.org/10.3390/vehicles8050098
Jiang J, Dai J, Li W, Zhou Y, Ye M, Zhang J, Zhang C. Unsupervised Domain Adaptation with Multimodal Fusion for Monocular 3D Object Detection. Vehicles. 2026; 8(5):98. https://doi.org/10.3390/vehicles8050098
Chicago/Turabian StyleJiang, Jin, Jidong Dai, Wei Li, Yuquan Zhou, Maozhang Ye, Jianhuan Zhang, and Chentao Zhang. 2026. "Unsupervised Domain Adaptation with Multimodal Fusion for Monocular 3D Object Detection" Vehicles 8, no. 5: 98. https://doi.org/10.3390/vehicles8050098
APA StyleJiang, J., Dai, J., Li, W., Zhou, Y., Ye, M., Zhang, J., & Zhang, C. (2026). Unsupervised Domain Adaptation with Multimodal Fusion for Monocular 3D Object Detection. Vehicles, 8(5), 98. https://doi.org/10.3390/vehicles8050098