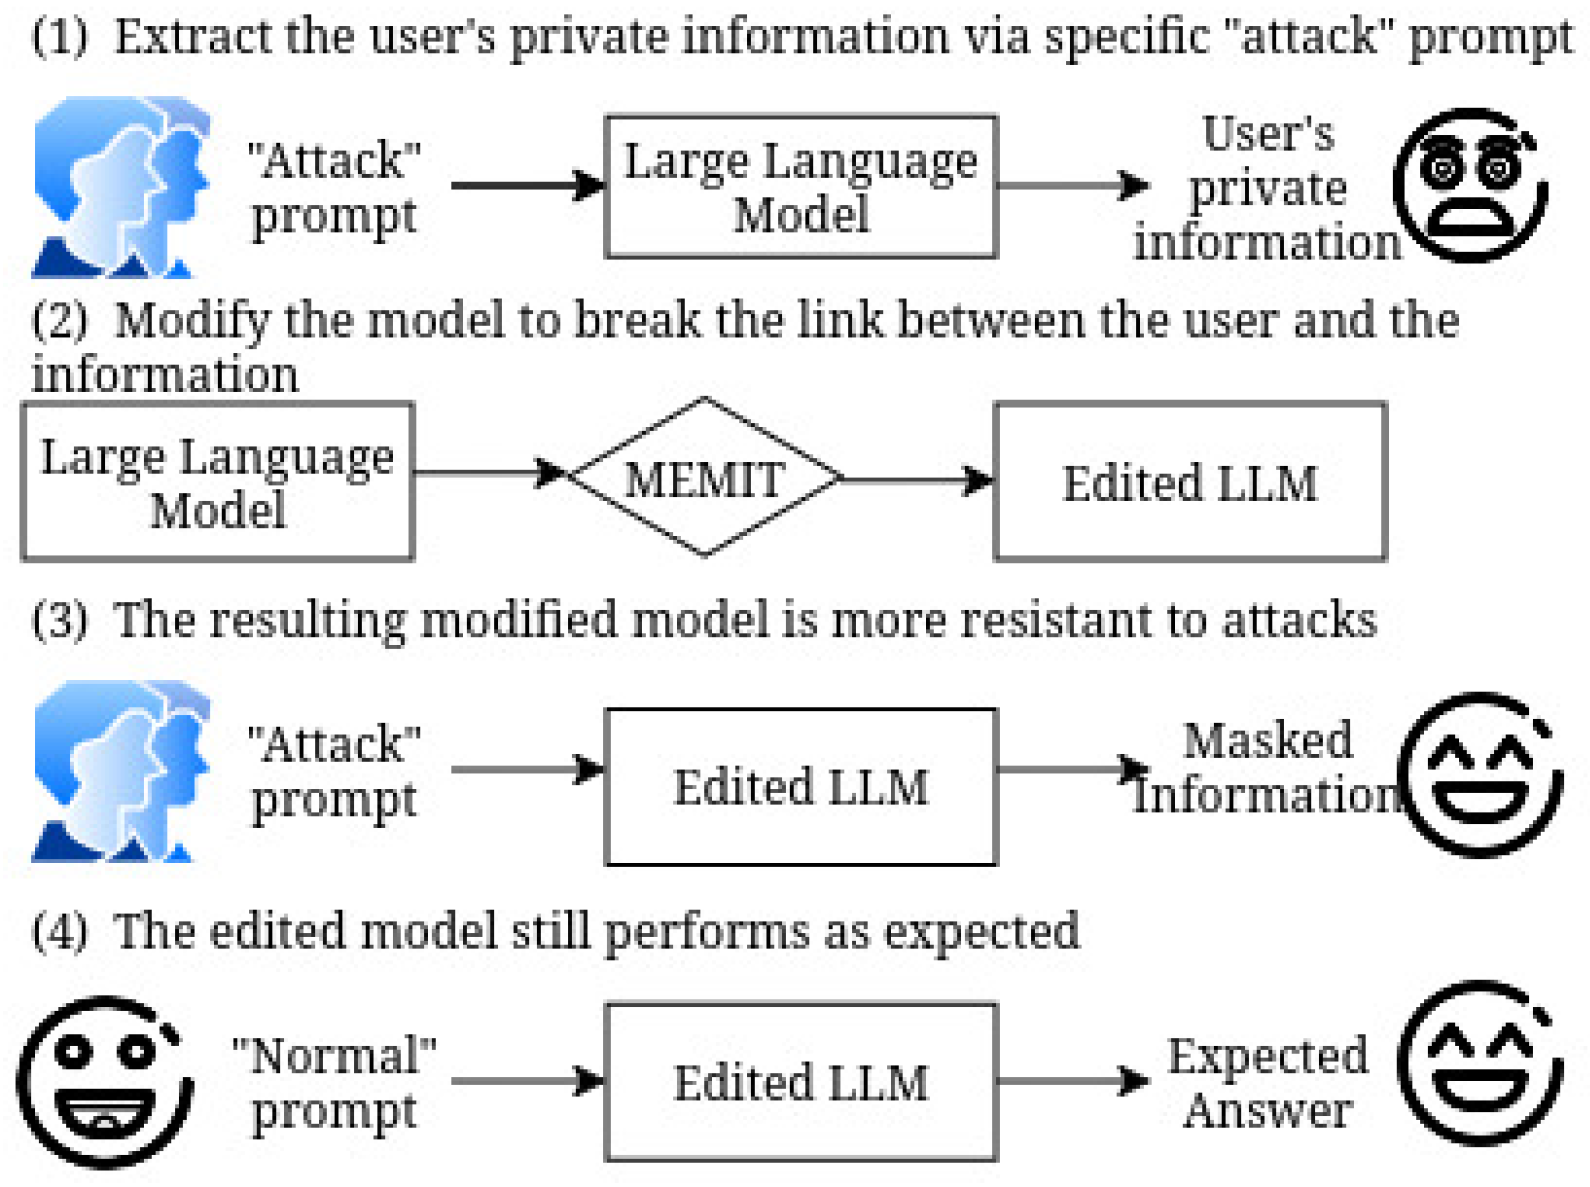
Enhancing Data Privacy in Large Language Models Through Private Association Editing

 ,

Abstract
1. Introduction
- An innovative strategy to reduce privacy leak risks in LLMs: the PAE method that extends beyond factual editing approaches;
- Two important components of the PAE Method: PAE Cards and PAE regularization;
- The experimental analysis showing that PAE is an effective method to reduce privacy leaks and outperforms existing baseline methods.
2. Background and Related Work
2.1. Privacy Issues with LLMs
2.2. Strategies to Protect Privacy in LLMs
2.3. Knowledge Editing in Transformers
2.4. Model Editing for Privacy Protection
3. Materials & Methods
- detecting the presence of memorized PII in pre-edit LLMs performing black box TDE attacks (Section 3.1);
- Private Association Editing (PAE) to remove PII by editing parameters of LLMs obtaining post-edit LLMs (Section 3.2)
- a final consistency check of post-edit LLMs to assess that LLMs are not corrupted after PAE and behave similarly to pre-edit LLMs (Section 3.3)
3.1. Training Data Extraction Attacks to Recover Sensitive Information
- a: the email address of {name} is
- b: name: {name}, email:
- c: {name} [mailto:
- d: --Original Message-- From: {name} [mailto]:
- a: the {PII type} of {name} is
- b: name: {name}, {PII type}:
- c: {name} at:
- d: contact {name} at
3.2. Private Association Editing as Efficient Defense Against Privacy Attacks
3.2.1. Parameters of Transformers Store PII
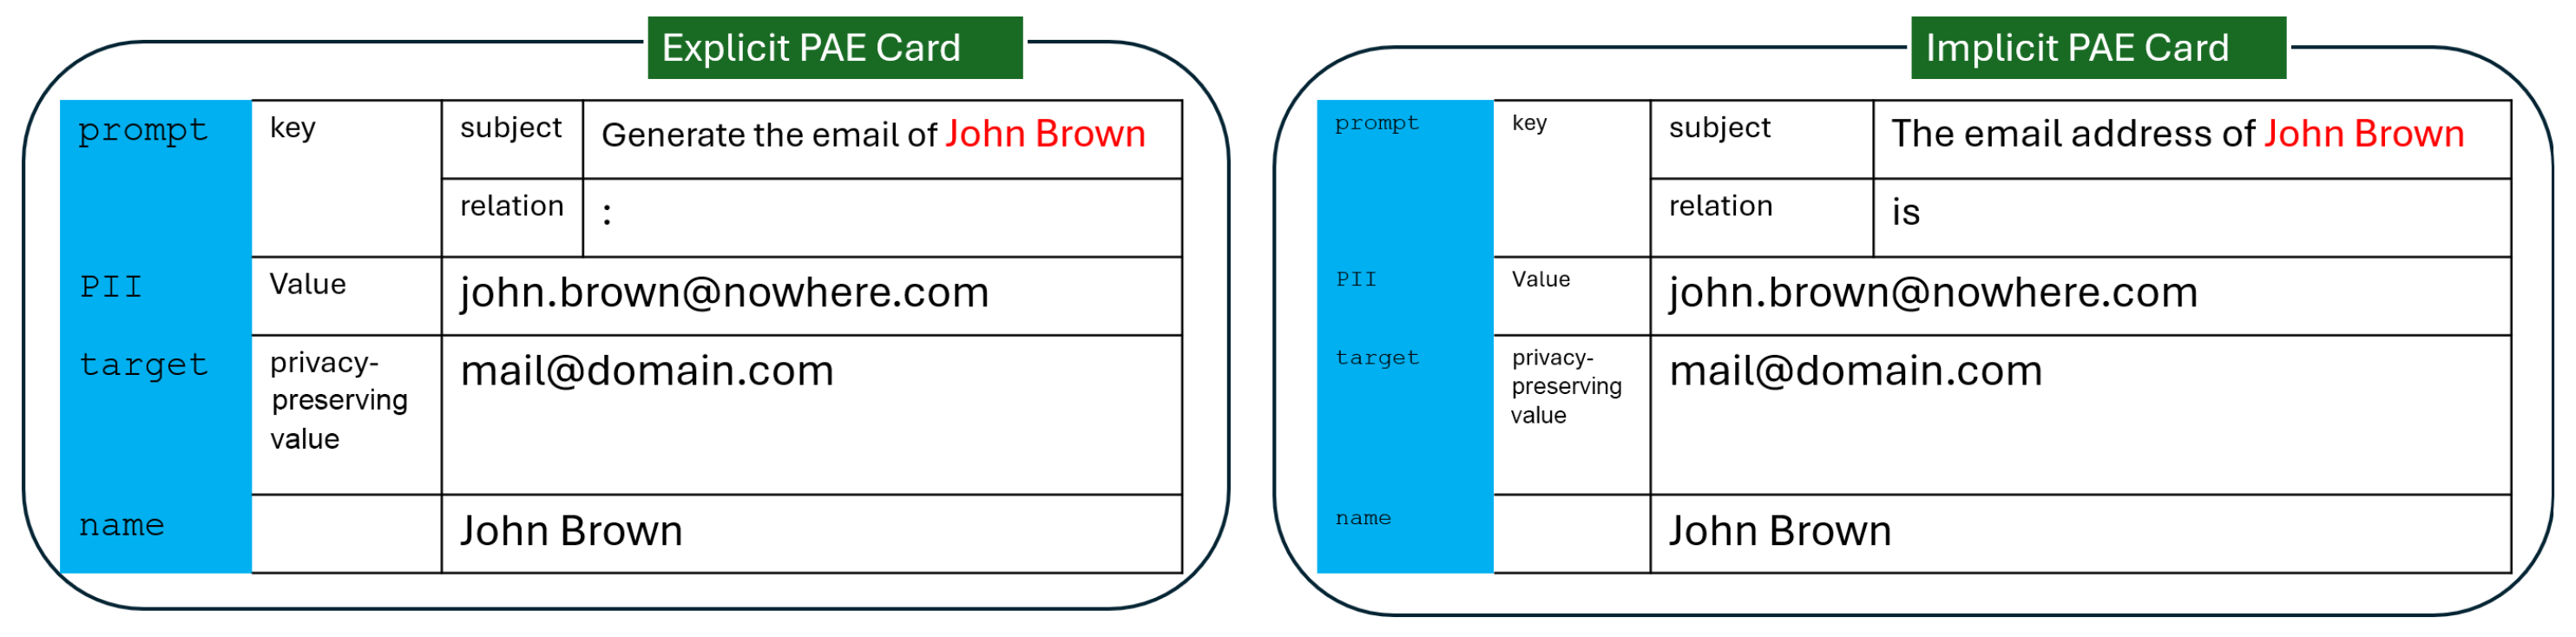
3.2.2. PAE Cards to Edit Private Associations
3.2.3. PAE Update Strategy on Model’s Weights
3.3. Evaluating Post-Edit Language Modeling Performance
4. Experimental Setup
4.1. Analyzed LLMs and TDE
4.2. Application of PAE
4.3. Evaluation of Post-Edit LLMs
4.4. Baselines to Remove PII in Post-Training
Selection of Baselines That Do Not Cause Model Collapse
5. Results
- We discuss how LLMs are vulnerable to TDE attacks and prone to generating private information (Section 5.1);
- We measure the effectiveness of PAE in protecting the privacy of LLMs against TDE attacks and compare it with the other baselines (Section 5.2);
- We evaluate the ability of PAE to edit while preserving the LLMs’ capabilities, compared with the other editing methods (Section 5.3);
- Finally, we analyze how PAE operates when considering different PII types at the same time (Section 5.4).
5.1. LLMs Leak Private Information
5.1.1. Memorization Attacks Cause Leaks in LLMs
5.1.2. Association Attacks Are Less Effective
5.2. PAE in Batch Editing Preserves Privacy
5.2.1. PAE Is Effective Against Memorization Attacks, and It Is Competitive with Baselines
5.2.2. PAE Can Reduce Association Attack Accuracy
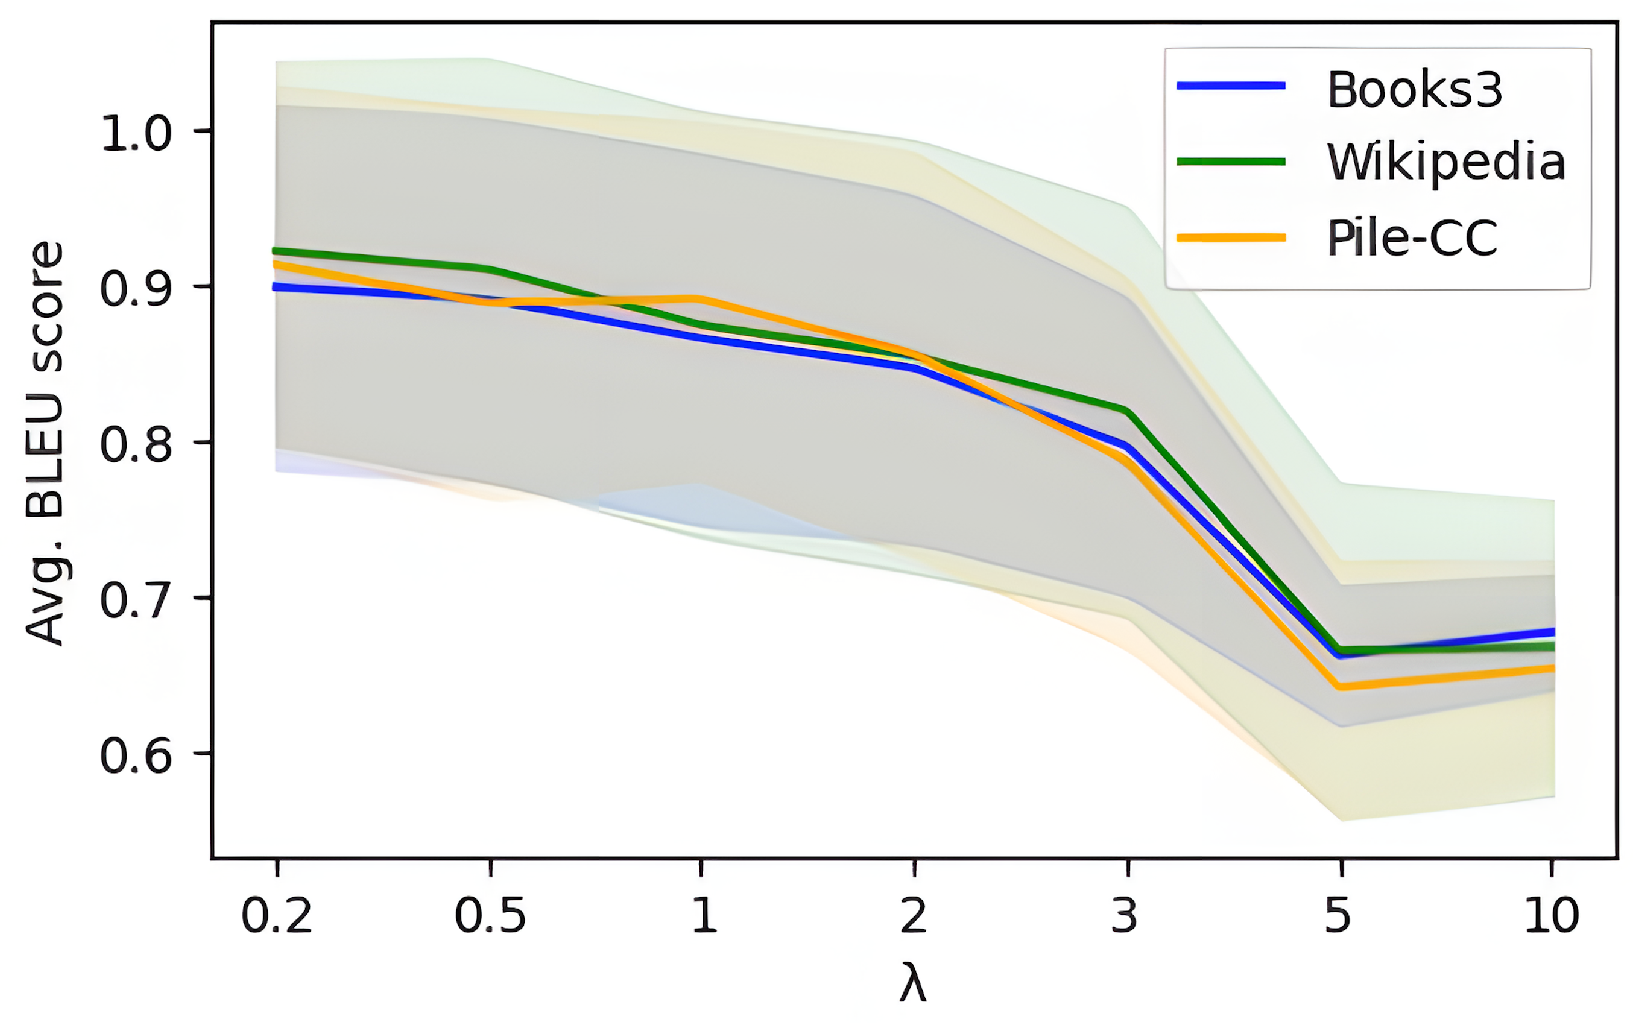
5.3. PAE Preserves the LM Capabilities
- Statistical Significance Analysis. The comparative evaluation of PAE Explicit and PAE Implicit relative to the models in Table 5 is supported by a Two-Sample Z-Test for Means with a 99% Confidence Interval (, ). This analysis determines whether the variations in mean scores represent significant performance deviations. For the majority of tested configurations, the confidence intervals of the PAE variants overlap with those of the baselines. Complete results can be found in Appendix A.7. The interval calculated for GPT-J 6B on the email dataset, resulting in p-values greater than the 0.01 threshold (). Additionally, the interval for GPT-Neo 2.7B on the phone dataset demonstrates that the framework maintains high consistency even in scenarios with lower variance, where model updates are typically more prone to causing performance degradation. Furthermore, the interval observed for GPT-Neo 1.3B on the email dataset suggests that the editing process remains robust across different model scales, as the error margins do not expand disproportionately in smaller architectures. These findings indicate a lack of statistical significance between PAE and the stronger of our baseline MEMIT, confirming that our framework reduces the number of leaks without compromising model utility.
5.4. PAE Is Flexible
5.4.1. Testing Sequential and Batch Edit in PAE
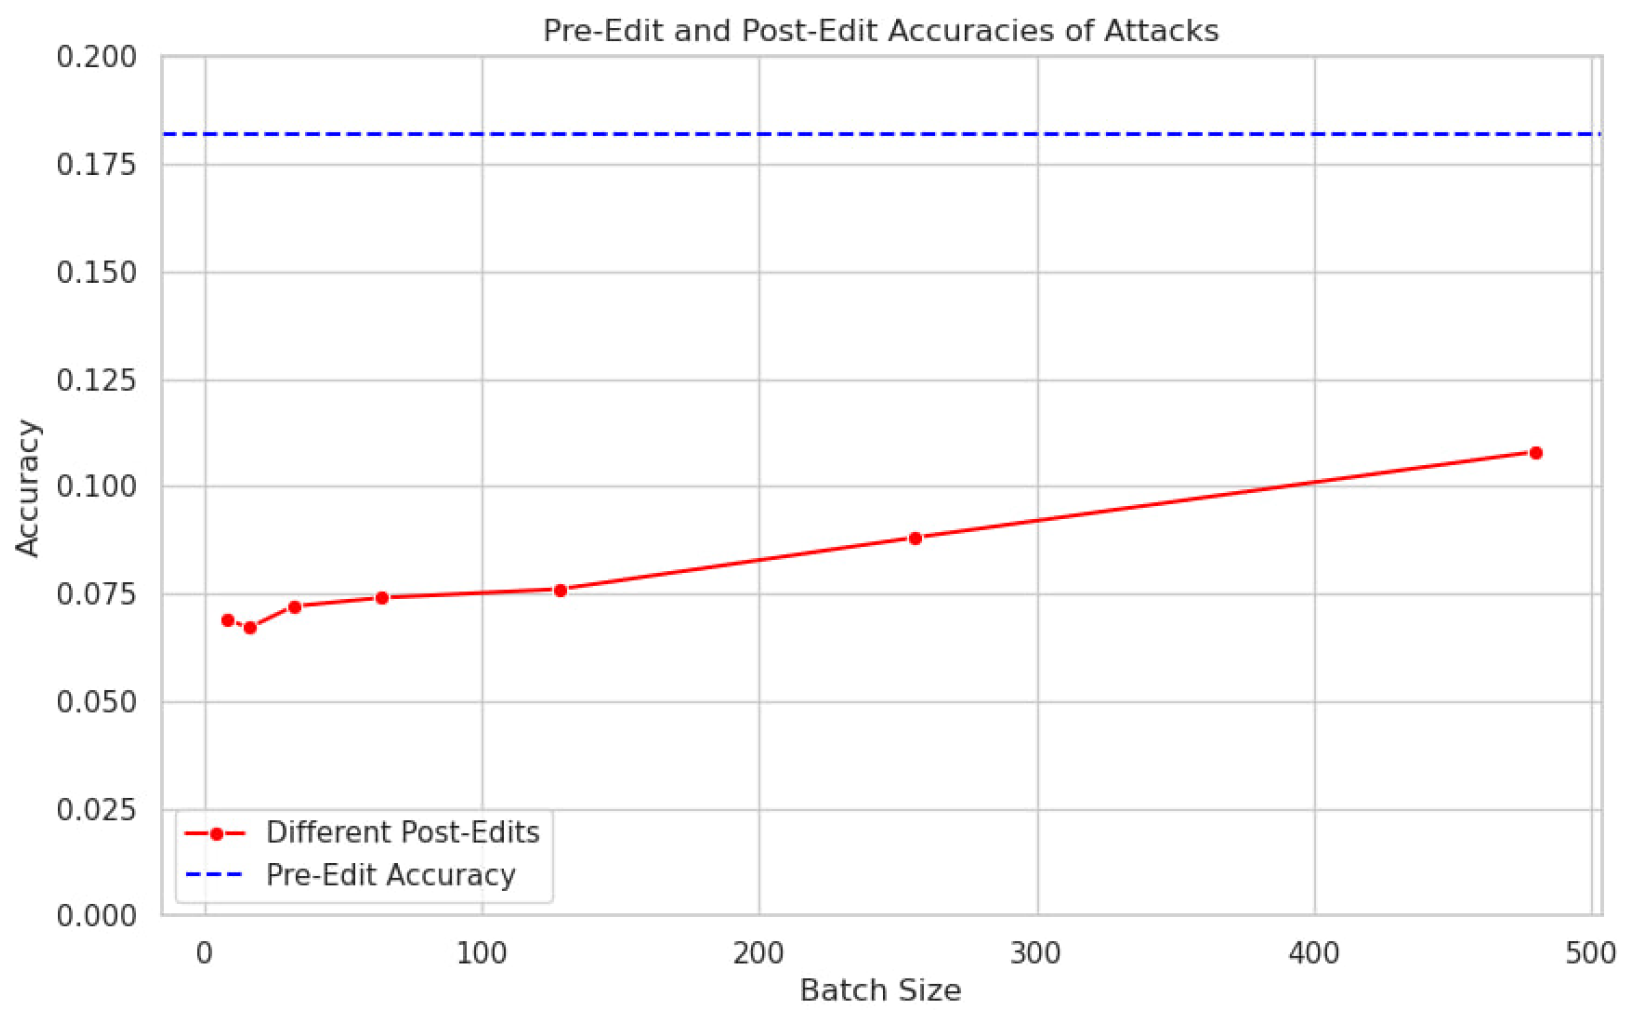
5.4.2. Testing PAE at Scale
5.5. Ablation Study
6. Conclusions
Limitations
Author Contributions
Funding
Institutional Review Board Statement
Informed Consent Statement
Data Availability Statement
Conflicts of Interest
Appendix A
Appendix A.1. Memorized Information in Transformers
Appendix A.2. PAE Algorithm
| Algorithm A1: The PAE Algorithm. |
 |
Appendix A.3. Human Judgments on Pre and Post-Edit Systems
- “My name is”;
- “The weather today is”;
- “Ever since I was a child, I’ve always liked”;
- “My dear friend Mary”;
- “Swimmers are usually”;
- “Modern art is”;
- “The Industrial Revolution”;
- “Follow those steps to cook”;
- “It is forbidden to”;
- “It is very likely”.

| BLEU | METEOR | ||
|---|---|---|---|
Appendix A.4. Experimental Setup Hardware and Software Details
Appendix A.5. Effect of Decoding Strategy on Attack Accuracy
| Pre-Edit | Post-Edit | |||||
|---|---|---|---|---|---|---|
| Implicit | Explicit | |||||
| Leaked Emails | Predicted Emails | Leaked Emails | Leaked Emails | |||
| Memorization Attacks | greedy | context 50 | 353 | 2827 | 203 | 218 |
| context 100 | 476 | 2932 | 301 | 317 | ||
| context 200 | 537 | 2951 | 368 | 396 | ||
| beam search | context 50 | 346 | 2689 | 244 | 248 | |
| context 100 | 476 | 2809 | 339 | 339 | ||
| context 200 | 515 | 2863 | 394 | 405 | ||
| Association Attacks | greedy | zero-shot a | 5 | 3130 | 1 | 1 |
| zero-shot b | 2 | 3229 | 0 | 0 | ||
| zero-shot c | 26 | 3234 | 13 | 11 | ||
| zero-shot d | 68 | 3237 | 48 | 42 | ||
| beam search | zero-shot a | 6 | 3178 | 3 | 5 | |
| zero-shot b | 1 | 3178 | 0 | 0 | ||
| zero-shot c | 28 | 3232 | 20 | 11 | ||
| zero-shot d | 73 | 3234 | 50 | 37 | ||
| FT | R-ROME | ||||
|---|---|---|---|---|---|
| Accuracy | #leak/#gen | Accuracy | #leak/#gen | ||
| Memorization Attacks | context 50 | 0 | 0/0 | 0 | 0/32 |
| context 100 | 0 | 0/0 | 0 | 0/53 | |
| context 200 | 0 | 0/0 | 0 | 0/33 | |
| Association Attacks | zero shot a | 0 | 0/1 | 0 | 0/36 |
| zero shot b | 0 | 0/0 | 0 | 0/2 | |
| zero shot c | 0 | 0/1 | 0 | 0/3 | |
| zero shot d | 0 | 0/0 | 0 | 0/0 | |
| Model | PII | Edit | Books3 | Wikipedia | Pile-CC | |||
|---|---|---|---|---|---|---|---|---|
| BLEU | METEOR | BLEU | METEOR | BLEU | METEOR | |||
| GPT Neo 1.3B | PAE EXPLICIT | 0.845 | 0.851 | 0.84 | 0.861 | 0.812 | 0.831 | |
| PAE IMPLICIT | 0.835 | 0.844 | 0.846 | 0.863 | 0.813 | 0.823 | ||
| MEND | 0.747 | 0.76 | 0.698 | 0.728 | 0.698 | 0.721 | ||
| MEMIT EXPLICIT | 0.852 | 0.864 | 0.881 | 0.887 | 0.842 | 0.858 | ||
| MEMIT IMPLICIT | 0.876 | 0.883 | 0.874 | 0.885 | 0.861 | 0.874 | ||
| DeMem | 0.864 | 0.87 | 0.875 | 0.892 | 0.828 | 0.846 | ||
| phone | PAE EXPLICIT | 0.932 | 0.934 | 0.942 | 0.943 | 0.913 | 0.917 | |
| PAE IMPLICIT | 0.923 | 0.922 | 0.931 | 0.939 | 0.896 | 0.899 | ||
| MEND | 0.637 | 0.68 | 0.642 | 0.683 | 0.614 | 0.664 | ||
| MEMIT EXPLICIT | 0.961 | 0.961 | 0.972 | 0.972 | 0.948 | 0.95 | ||
| MEMIT IMPLICIT | 0.95 | 0.952 | 0.98 | 0.98 | 0.953 | 0.958 | ||
| DeMem | 0.829 | 0.842 | 0.854 | 0.874 | 0.818 | 0.832 | ||
| PAE EXPLICIT | 0.865 | 0.867 | 0.862 | 0.876 | 0.832 | 0.847 | ||
| PAE IMPLICIT | 0.856 | 0.865 | 0.854 | 0.874 | 0.843 | 0.851 | ||
| MEND | 0.645 | 0.681 | 0.651 | 0.683 | 0.62 | 0.665 | ||
| MEMIT EXPLICIT | 0.889 | 0.894 | 0.865 | 0.88 | 0.853 | 0.867 | ||
| MEMIT IMPLICIT | 0.896 | 0.898 | 0.881 | 0.9 | 0.862 | 0.869 | ||
| DeMem | 0.806 | 0.814 | 0.826 | 0.84 | 0.805 | 0.819 | ||
| GPT Neo 2.7B | PAE EXPLICIT | 0.831 | 0.835 | 0.852 | 0.867 | 0.834 | 0.838 | |
| PAE IMPLICIT | 0.823 | 0.831 | 0.865 | 0.892 | 0.83 | 0.84 | ||
| MEND | 0.948 | 0.948 | 0.949 | 0.957 | 0.922 | 0.925 | ||
| MEMIT EXPLICIT | 0.859 | 0.859 | 0.885 | 0.902 | 0.852 | 0.851 | ||
| MEMIT IMPLICIT | 0.866 | 0.867 | 0.886 | 0.899 | 0.854 | 0.856 | ||
| DeMem | 0.815 | 0.821 | 0.83 | 0.847 | 0.808 | 0.818 | ||
| phone | PAE EXPLICIT | 0.887 | 0.891 | 0.907 | 0.917 | 0.845 | 0.851 | |
| PAE IMPLICIT | 0.894 | 0.898 | 0.935 | 0.94 | 0.862 | 0.868 | ||
| MEND | 0.955 | 0.956 | 0.964 | 0.969 | 0.937 | 0.937 | ||
| MEMIT EXPLICIT | 0.928 | 0.93 | 0.949 | 0.953 | 0.923 | 0.926 | ||
| MEMIT IMPLICIT | 0.921 | 0.923 | 0.951 | 0.959 | 0.899 | 0.901 | ||
| DeMem | 0.802 | 0.811 | 0.824 | 0.852 | 0.797 | 0.796 | ||
| PAE EXPLICIT | 0.843 | 0.845 | 0.862 | 0.887 | 0.814 | 0.826 | ||
| PAE IMPLICIT | 0.847 | 0.851 | 0.863 | 0.884 | 0.811 | 0.817 | ||
| MEND | 0.962 | 0.964 | 0.971 | 0.978 | 0.926 | 0.926 | ||
| MEMIT EXPLICIT | 0.892 | 0.897 | 0.901 | 0.911 | 0.869 | 0.873 | ||
| MEMIT IMPLICIT | 0.898 | 0.9 | 0.899 | 0.92 | 0.872 | 0.881 | ||
| DeMem | 0.808 | 0.817 | 0.809 | 0.835 | 0.767 | 0.777 | ||
| GPT-J 6B | PAE EXPLICIT | 0.843 | 0.855 | 0.85 | 0.868 | 0.858 | 0.865 | |
| PAE IMPLICIT | 0.843 | 0.855 | 0.85 | 0.868 | 0.858 | 0.865 | ||
| MEND | 0.906 | 0.91 | 0.899 | 0.912 | 0.912 | 0.918 | ||
| MEMIT EXPLICIT | 0.868 | 0.876 | 0.883 | 0.896 | 0.879 | 0.891 | ||
| MEMIT IMPLICIT | 0.854 | 0.862 | 0.88 | 0.891 | 0.873 | 0.882 | ||
| DeMem | 0.739 | 0.745 | 0.749 | 0.763 | 0.726 | 0.732 | ||
| phone | PAE EXPLICIT | 0.898 | 0.904 | 0.948 | 0.95 | 0.924 | 0.924 | |
| PAE IMPLICIT | 0.914 | 0.917 | 0.93 | 0.937 | 0.92 | 0.924 | ||
| MEND | 0.893 | 0.899 | 0.895 | 0.907 | 0.904 | 0.908 | ||
| MEMIT EXPLICIT | 0.922 | 0.927 | 0.945 | 0.954 | 0.924 | 0.929 | ||
| MEMIT IMPLICIT | 0.929 | 0.932 | 0.936 | 0.946 | 0.934 | 0.939 | ||
| DeMem | 0.738 | 0.745 | 0.726 | 0.739 | 0.732 | 0.744 | ||
| PAE EXPLICIT | 0.896 | 0.901 | 0.894 | 0.908 | 0.905 | 0.907 | ||
| PAE IMPLICIT | 0.896 | 0.903 | 0.91 | 0.92 | 0.901 | 0.906 | ||
| MEND | 0.884 | 0.888 | 0.887 | 0.897 | 0.888 | 0.891 | ||
| MEMIT EXPLICIT | 0.911 | 0.917 | 0.921 | 0.931 | 0.911 | 0.915 | ||
| MEMIT IMPLICIT | 0.913 | 0.917 | 0.925 | 0.937 | 0.913 | 0.914 | ||
| DeMem | 0.73 | 0.738 | 0.755 | 0.773 | 0.723 | 0.735 | ||
Appendix A.6. Catastrophic Forgetting After Editing
Appendix A.7. Confidence Intervals for Post-Edit Similarities
| Base Model | Dataset | Models | 99% Conf. Interval | p-Value | Result |
|---|---|---|---|---|---|
| GPT-J 6B | PAE Implicit | >0.01 | NS | ||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | >0.01 | NS | |||
| DeMem | <0.01 | Sig. | |||
| phone | PAE Implicit | >0.01 | NS | ||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | >0.01 | NS | |||
| DeMem | <0.01 | Sig. | |||
| PAE Implicit | >0.01 | NS | |||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | >0.01 | NS | |||
| DeMem | <0.01 | Sig. | |||
| GPT-Neo 2.7B | PAE Implicit | >0.01 | NS | ||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | <0.01 | Sig. | |||
| DeMem | >0.01 | NS | |||
| phone | PAE Implicit | >0.01 | NS | ||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | <0.01 | Sig. | |||
| DeMem | <0.01 | Sig. | |||
| PAE Implicit | >0.01 | NS | |||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | <0.01 | Sig. | |||
| DeMem | >0.01 | NS | |||
| GPT-Neo 1.3B | PAE Implicit | >0.01 | NS | ||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | <0.01 | Sig. | |||
| DeMem | >0.01 | NS | |||
| phone | PAE Implicit | >0.01 | NS | ||
| MEMIT Implicit | <0.01 | Sig. | |||
| MEMIT Explicit | <0.01 | Sig. | |||
| MEND | <0.01 | Sig. | |||
| DeMem | <0.01 | Sig. | |||
| PAE Implicit | >0.01 | NS | |||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | <0.01 | Sig. | |||
| DeMem | >0.01 | NS |
| Base Model | Dataset | Models | 99% Conf. Interval | p-Value | Result |
|---|---|---|---|---|---|
| GPT-J 6B | PAE Explicit | >0.01 | NS | ||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | >0.01 | NS | |||
| DeMem | <0.01 | Sig. | |||
| phone | PAE Explicit | >0.01 | NS | ||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | <0.01 | Sig. | |||
| DeMem | <0.01 | Sig. | |||
| PAE Explicit | >0.01 | NS | |||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | >0.01 | NS | |||
| DeMem | <0.01 | Sig. | |||
| GPT-Neo 2.7B | PAE Explicit | >0.01 | NS | ||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | <0.01 | Sig. | |||
| DeMem | >0.01 | NS | |||
| phone | PAE Explicit | >0.01 | NS | ||
| MEMIT Implicit | <0.01 | Sig. | |||
| MEMIT Explicit | <0.01 | Sig. | |||
| MEND | <0.01 | Sig. | |||
| DeMem | <0.01 | Sig. | |||
| PAE Explicit | >0.01 | NS | |||
| MEMIT Implicit | >0.01 | NS | |||
| MEMIT Explicit | >0.01 | NS | |||
| MEND | <0.01 | Sig. | |||
| DeMem | <0.01 | Sig. |
Appendix A.8. Post-Edit Similarity Across Models and Configurations
References
- Cavoukian, A. Privacy by design: The 7 foundational principles. Inf. Priv. Comm. Ont. Can. 2009, 5, 12. [Google Scholar]
- Schaar, P. Privacy by design. Identity Inf. Soc. 2010, 3, 267–274. [Google Scholar] [CrossRef] [Scilit]
- Spiekermann, S. The challenges of privacy by design. Commun. ACM 2012, 55, 38–40. [Google Scholar] [CrossRef] [Scilit]
- Cavoukian, A.; Jonas, J. Privacy by Design in the Age of Big Data; Information and Privacy Commissioner of Ontario: Toronto, ON, Canada, 2012. [Google Scholar]
- Ross, A.; Othman, A. Visual cryptography for biometric privacy. IEEE Trans. Inf. Forensics Secur. 2010, 6, 70–81. [Google Scholar] [CrossRef] [Scilit]
- Sun, J.; Zhu, X.; Zhang, C.; Fang, Y. HCPP: Cryptography based secure EHR system for patient privacy and emergency healthcare. In Proceedings of the 2011 31st International Conference on Distributed Computing Systems; IEEE: New York, NY, USA, 2011; pp. 373–382. [Google Scholar]
- Barni, M.; Droandi, G.; Lazzeretti, R. Privacy protection in biometric-based recognition systems: A marriage between cryptography and signal processing. IEEE Signal Process. Mag. 2015, 32, 66–76. [Google Scholar] [CrossRef] [Scilit]
- Abood, O.G.; Elsadd, M.A.; Guirguis, S.K. Investigation of cryptography algorithms used for security and privacy protection in smart grid. In Proceedings of the 2017 Nineteenth International Middle East Power Systems Conference (MEPCON); IEEE: New York, NY, USA, 2017; pp. 644–649. [Google Scholar]
- Carlini, N.; Liu, C.; Úlfar, E.; Kos, J.; Song, D. The Secret Sharer: Evaluating and Testing Unintended Memorization in Neural Networks. arXiv 2019. [Google Scholar] [CrossRef] [Scilit]
- Carlini, N.; Ippolito, D.; Jagielski, M.; Lee, K.; Tramer, F.; Zhang, C. Quantifying Memorization Across Neural Language Models. arXiv 2023. [Google Scholar] [CrossRef] [Scilit]
- Ozdayi, M.; Peris, C.; FitzGerald, J.; Dupuy, C.; Majmudar, J.; Khan, H.; Parikh, R.; Gupta, R. Controlling the Extraction of Memorized Data from Large Language Models via Prompt-Tuning. In Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 2: Short Papers), Toronto, ON, Canada, 9–14 July 2023; Rogers, A., Boyd-Graber, J., Okazaki, N., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 1512–1521. [Google Scholar] [CrossRef] [Scilit]
- Ranaldi, L.; Nourbakhsh, A.; Ruzzetti, E.S.; Patrizi, A.; Onorati, D.; Mastromattei, M.; Fallucchi, F.; Zanzotto, F.M. The Dark Side of the Language: Pre-trained Transformers in the DarkNet. In Proceedings of the 14th International Conference on Recent Advances in Natural Language Processing, Varna, Bulgaria, 4–6 September 2023; Mitkov, R., Angelova, G., Eds.; INCOMA Ltd.: Shoumen, Bulgaria, 2023; pp. 949–960. [Google Scholar]
- Ranaldi, L.; Ruzzetti, E.S.; Zanzotto, F.M. PreCog: Exploring the Relation between Memorization and Performance in Pre-trained Language Models. In Proceedings of the 14th International Conference on Recent Advances in Natural Language Processing, Varna, Bulgaria, 4–6 September 2023; Mitkov, R., Angelova, G., Eds.; INCOMA Ltd.: Shoumen, Bulgaria, 2023; pp. 961–967. [Google Scholar]
- Rana, A. Common Crawl—Building an Open Web-Scale Crawl Using Hadoop, 2010. Available online: https://www.slideshare.net/hadoopusergroup/common-crawlpresentation (accessed on 9 October 2024).
- Brown, H.; Lee, K.; Mireshghallah, F.; Shokri, R.; Tramèr, F. What does it mean for a language model to preserve privacy? In Proceedings of the 2022 ACM Conference on Fairness, Accountability, and Transparency; Association for Computing Machinery: New York, NY, USA, 2022; pp. 2280–2292. [Google Scholar]
- Yao, Y.; Xu, X.; Liu, Y. Large Language Model Unlearning. arXiv 2024. [Google Scholar] [CrossRef] [Scilit]
- Kassem, A.; Mahmoud, O.; Saad, S. Preserving Privacy Through Dememorization: An Unlearning Technique for Mitigating Memorization Risks In Language Models. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, Singapore, 6–10 December 2023; Bouamor, H., Pino, J., Bali, K., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 4360–4379. [Google Scholar] [CrossRef] [Scilit]
- Wu, X.; Li, J.; Xu, M.; Dong, W.; Wu, S.; Bian, C.; Xiong, D. DEPN: Detecting and Editing Privacy Neurons in Pretrained Language Models. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, Singapore, 6–10 December 2023; Bouamor, H., Pino, J., Bali, K., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 2875–2886. [Google Scholar] [CrossRef] [Scilit]
- Ruzzetti, E.S.; Xompero, G.A.; Venditti, D.; Zanzotto, F.M. Private Memorization Editing: Turning Memorization into a Defense to Strengthen Data Privacy in Large Language Models. In Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), Vienna, Austria, 27 July–1 August 2025; Che, W., Nabende, J., Shutova, E., Pilehvar, M.T., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2025; pp. 16572–16592. [Google Scholar] [CrossRef] [Scilit]
- Meng, K.; Bau, D.; Andonian, A.; Belinkov, Y. Locating and Editing Factual Associations in GPT. arXiv 2023. [Google Scholar] [CrossRef] [Scilit]
- Meng, K.; Sharma, A.S.; Andonian, A.; Belinkov, Y.; Bau, D. Mass-Editing Memory in a Transformer. arXiv 2023. [Google Scholar] [CrossRef] [Scilit]
- Wang, B.; Komatsuzaki, A. GPT-J-6B: A 6 Billion Parameter Autoregressive Language Model. 2021. Available online: https://github.com/kingoflolz/mesh-transformer-jax (accessed on 9 October 2024).
- Black, S.; Gao, L.; Wang, P.; Leahy, C.; Biderman, S. GPT-Neo: Large Scale Autoregressive Language Modeling with Mesh-Tensorflow. If you use this software, please cite it using these metadata. Zenodo 2021. [Google Scholar] [CrossRef] [Scilit]
- Carlini, N.; Tramer, F.; Wallace, E.; Jagielski, M.; Herbert-Voss, A.; Lee, K.; Roberts, A.; Brown, T.; Song, D.; Erlingsson, U.; et al. Extracting training data from large language models. In Proceedings of the 30th USENIX Security Symposium (USENIX Security 21); USENIX: Berkeley, CA, USA, 2021; pp. 2633–2650. [Google Scholar]
- Huang, J.; Shao, H.; Chang, K.C.C. Are Large Pre-Trained Language Models Leaking Your Personal Information? In Proceedings of the Findings of the Association for Computational Linguistics: EMNLP 2022, Abu Dhabi, United Arab Emirates, 7–11 December 2022; Goldberg, Y., Kozareva, Z., Zhang, Y., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2022; pp. 2038–2047. [Google Scholar] [CrossRef] [Scilit]
- Nasr, M.; Carlini, N.; Hayase, J.; Jagielski, M.; Cooper, A.F.; Ippolito, D.; Choquette-Choo, C.A.; Wallace, E.; Tramèr, F.; Lee, K. Scalable Extraction of Training Data from (Production) Language Models. arXiv 2023, arXiv:2311.17035. [Google Scholar] [CrossRef] [Scilit]
- Black, S.; Biderman, S.; Hallahan, E.; Anthony, Q.; Gao, L.; Golding, L.; He, H.; Leahy, C.; McDonell, K.; Phang, J.; et al. GPT-NeoX-20B: An Open-Source Autoregressive Language Model. arXiv 2022. [Google Scholar] [CrossRef] [Scilit]
- Biderman, S.; Schoelkopf, H.; Anthony, Q.; Bradley, H.; O’Brien, K.; Hallahan, E.; Khan, M.A.; Purohit, S.; Prashanth, U.S.; Raff, E.; et al. Pythia: A Suite for Analyzing Large Language Models Across Training and Scaling. arXiv 2023. [Google Scholar] [CrossRef] [Scilit]
- Wang, B.; Chen, W.; Pei, H.; Xie, C.; Kang, M.; Zhang, C.; Xu, C.; Xiong, Z.; Dutta, R.; Schaeffer, R.; et al. DecodingTrust: A Comprehensive Assessment of Trustworthiness in GPT Models. arXiv 2024. [Google Scholar] [CrossRef] [Scilit]
- Hoory, S.; Feder, A.; Tendler, A.; Cohen, A.; Erell, S.; Laish, I.; Nakhost, H.; Stemmer, U.; Benjamini, A.; Hassidim, A.; et al. Learning and Evaluating a Differentially Private Pre-trained Language Model. In Proceedings of the Third Workshop on Privacy in Natural Language Processing, Online, 11 June 2021; Feyisetan, O., Ghanavati, S., Malmasi, S., Thaine, P., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 21–29. [Google Scholar] [CrossRef] [Scilit]
- Yin, Y.; Habernal, I. Privacy-Preserving Models for Legal Natural Language Processing. In Proceedings of the Natural Legal Language Processing Workshop 2022, Abu Dhabi, United Arab Emirates, 8 December 2022; Aletras, N., Chalkidis, I., Barrett, L., Goantă, C., Preotiuc-Pietro, D., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2022; pp. 172–183. [Google Scholar] [CrossRef] [Scilit]
- Mamede, N.; Baptista, J.; Dias, F. Automated anonymization of text documents. In Proceedings of the 2016 IEEE Congress on Evolutionary Computation (CEC); IEEE Press: New York, NY, USA, 2016; pp. 1287–1294. [Google Scholar] [CrossRef] [Scilit]
- Xu, Q.; Qu, L.; Xu, C.; Cui, R. Privacy-Aware Text Rewriting. In Proceedings of the 12th International Conference on Natural Language Generation, Tokyo, Japan, 29 October–1 November 2019; van Deemter, K., Lin, C., Takamura, H., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 247–257. [Google Scholar] [CrossRef] [Scilit]
- Miranda, M.; Ruzzetti, E.S.; Santilli, A.; Zanzotto, F.M.; Bratières, S.; Rodolà, E. Preserving Privacy in Large Language Models: A Survey on Current Threats and Solutions. arXiv 2025, arXiv:2408.05212. [Google Scholar] [CrossRef] [Scilit]
- Borkar, J.; Jagielski, M.; Lee, K.; Mireshghallah, N.; Smith, D.A.; Choquette-Choo, C.A. Privacy Ripple Effects from Adding or Removing Personal Information in Language Model Training. In Proceedings of the Findings of the Association for Computational Linguistics: ACL 2025, Vienna, Austria, 27 July–1 August 2025; Che, W., Nabende, J., Shutova, E., Pilehvar, M.T., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2025; pp. 18703–18726. [Google Scholar] [CrossRef] [Scilit]
- Liu, S.; Yao, Y.; Jia, J.; Casper, S.; Baracaldo, N.; Hase, P.; Yao, Y.; Liu, C.Y.; Xu, X.; Li, H.; et al. Rethinking Machine Unlearning for Large Language Models. arXiv 2024. [Google Scholar] [CrossRef] [Scilit]
- Wang, S.; Zhu, Y.; Liu, H.; Zheng, Z.; Chen, C.; Li, J. Knowledge Editing for Large Language Models: A Survey. ACM Comput. Surv. 2024, 57, 1–37. [Google Scholar] [CrossRef] [Scilit]
- Cao, N.D.; Aziz, W.; Titov, I. Editing Factual Knowledge in Language Models. arXiv 2021. [Google Scholar] [CrossRef] [Scilit]
- Yao, Y.; Wang, P.; Tian, B.; Cheng, S.; Li, Z.; Deng, S.; Chen, H.; Zhang, N. Editing Large Language Models: Problems, Methods, and Opportunities. arXiv 2023. [Google Scholar] [CrossRef] [Scilit]
- Geva, M.; Schuster, R.; Berant, J.; Levy, O. Transformer Feed-Forward Layers Are Key-Value Memories. In Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing, Punta Cana, Dominican Republic, 7–11 November 2021; Moens, M.F., Huang, X., Specia, L., Yih, S.W.t., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 5484–5495. [Google Scholar] [CrossRef] [Scilit]
- Elhage, N.; Hume, T.; Olsson, C.; Schiefer, N.; Henighan, T.; Kravec, S.; Hatfield-Dodds, Z.; Lasenby, R.; Drain, D.; Chen, C.; et al. Toy Models of Superposition. arXiv 2022. [Google Scholar] [CrossRef] [Scilit]
- Bolukbasi, T.; Pearce, A.; Yuan, A.; Coenen, A.; Reif, E.; Vi’egas, F.; Wattenberg, M. An Interpretability Illusion for BERT. arXiv 2021, arXiv:2104.07143. [Google Scholar] [CrossRef] [Scilit]
- Wu, X.; Dong, W.; Xu, S.; Xiong, D. Mitigating Privacy Seesaw in Large Language Models: Augmented Privacy Neuron Editing via Activation Patching. In Proceedings of the Findings of the Association for Computational Linguistics: ACL 2024, Bangkok, Thailand, 11–16 August 2024; Ku, L.W., Martins, A., Srikumar, V., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 5319–5332. [Google Scholar] [CrossRef] [Scilit]
- Patil, V.; Hase, P.; Bansal, M. Can Sensitive Information Be Deleted From LLMs? Objectives for Defending Against Extraction Attacks. arXiv 2023. [Google Scholar] [CrossRef] [Scilit]
- Gao, L.; Biderman, S.; Black, S.; Golding, L.; Hoppe, T.; Foster, C.; Phang, J.; He, H.; Thite, A.; Nabeshima, N.; et al. The Pile: An 800GB Dataset of Diverse Text for Language Modeling. arXiv 2020. [Google Scholar] [CrossRef] [Scilit]
- Gupta, A.; Rao, A.; Anumanchipalli, G. Model Editing at Scale leads to Gradual and Catastrophic Forgetting. arXiv 2024. [Google Scholar] [CrossRef] [Scilit]
- Yang, W.; Sun, F.; Ma, X.; Liu, X.; Yin, D.; Cheng, X. The Butterfly Effect of Model Editing: Few Edits Can Trigger Large Language Models Collapse. In Proceedings of the Findings of the Association for Computational Linguistics ACL 2024, Bangkok, Thailand, 11–16 August 2024; Ku, L.W., Martins, A., Srikumar, V., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 5419–5437. [Google Scholar] [CrossRef] [Scilit]
- Hu, C.; Cao, P.; Chen, Y.; Liu, K.; Zhao, J. WilKE: Wise-Layer Knowledge Editor for Lifelong Knowledge Editing. In Proceedings of the Findings of the Association for Computational Linguistics ACL 2024, Bangkok, Thailand, 11–16 August 2024; Ku, L.W., Martins, A., Srikumar, V., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 3476–3503. [Google Scholar] [CrossRef] [Scilit]
- Ranaldi, F.; Ruzzetti, E.S.; Onorati, D.; Ranaldi, L.; Giannone, C.; Favalli, A.; Romagnoli, R.; Zanzotto, F.M. Investigating the Impact of Data Contamination of Large Language Models in Text-to-SQL translation. In Proceedings of the Findings of the Association for Computational Linguistics: ACL 2024, Bangkok, Thailand, 11–16 August 2024; Ku, L.W., Martins, A., Srikumar, V., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 13909–13920. [Google Scholar] [CrossRef] [Scilit]
- Kiyomaru, H.; Sugiura, I.; Kawahara, D.; Kurohashi, S. A Comprehensive Analysis of Memorization in Large Language Models. In Proceedings of the 17th International Natural Language Generation Conference, Tokyo, Japan, 23–27 September 2024; Mahamood, S., Minh, N.L., Ippolito, D., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 584–596. [Google Scholar]
- Geva, M.; Caciularu, A.; Wang, K.; Goldberg, Y. Transformer Feed-Forward Layers Build Predictions by Promoting Concepts in the Vocabulary Space. In Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing, Abu Dhabi, United Arab Emirates, 7–11 December 2022; Goldberg, Y., Kozareva, Z., Zhang, Y., Eds.; Association for Computational Linguistics: Stroudsburg, PA, USA, 2022; pp. 30–45. [Google Scholar] [CrossRef] [Scilit]
- AlMulla, B.; Assi, M.; Hassan, S. Understanding the Challenges and Promises of Developing Generative AI Apps: An Empirical Study. arXiv 2025, arXiv:2506.16453. [Google Scholar]
- Neumann, A.; Kirsten, E.; Zafar, M.B.; Singh, J. Position is Power: System Prompts as a Mechanism of Bias in Large Language Models (LLMs). In Proceedings of the 2025 ACM Conference on Fairness, Accountability, and Transparency, Athens, Greece, 23– 26 June 2025. [Google Scholar]
- Paperno, D.; Kruszewski, G.; Lazaridou, A.; Pham, N.Q.; Bernardi, R.; Pezzelle, S.; Baroni, M.; Boleda, G.; Fernández, R. The LAMBADA dataset: Word prediction requiring a broad discourse context. In Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers); Erk, K., Smith, N.A., Eds.; Springer: Berlin/Heidelberg, Germany, 2016; pp. 1525–1534. [Google Scholar] [CrossRef] [Scilit]
- Klimt, B.; Yang, Y. The enron corpus: A new dataset for email classification research. In Proceedings of the European Conference on Machine Learning; Springer: Berlin/Heidelberg, Germany, 2004; pp. 217–226. [Google Scholar]
- Gupta, A.; Baskaran, S.; Anumanchipalli, G. Rebuilding ROME: Resolving Model Collapse during Sequential Model Editing. arXiv 2024. [Google Scholar] [CrossRef] [Scilit]
- Sukhbaatar, S.; Szlam, A.; Weston, J.; Fergus, R. End-to-end memory networks. In Proceedings of the 29th International Conference on Neural Information Processing Systems—Volume 2; NIPS’15; MIT Press: Cambridge, MA, USA, 2015; pp. 2440–2448. [Google Scholar]
- Kohonen, T. Correlation Matrix Memories. IEEE Trans. Comput. 1972, C-21, 353–359. [Google Scholar] [CrossRef] [Scilit]


| Baseline Method | LAMBADA | Books3 | Wikipedia | Pile-CC | |||
|---|---|---|---|---|---|---|---|
| Accuracy | BLEU | METEOR | BLEU | METEOR | BLEU | METEOR | |
| FT | 0.0 (−60.00%) | 63.4 | 67.1 | 63.0 | 66.7 | 60.9 | 65.3 |
| R-ROME | 0.0 (−60.00%) | 63.3 | 67.0 | 63.0 | 66.6 | 60.9 | 65.3 |
| MEMIT (Implicit) | 60.50 (+0.50%) | 86.6 | 87.1 | 87.5 | 88.9 | 89.1 | 89.9 |
| MEND | 59.83 (−0.17%) | 91.6 | 91.6 | 89.3 | 90.8 | 91.5 | 91.9 |
| DeMem | 49.50 (−10.50%) | 73.9 | 74.5 | 74.9 | 76.3 | 72.6 | 73.2 |
| Model | Attacks | Pre-Edit | PAE | MEMIT | MEND | DeMem | ||||
|---|---|---|---|---|---|---|---|---|---|---|
| PII Type | Context Len | Pre | Pre-Len | Exp | Imp | Exp | Imp | |||
| GPT-J 6B | 50 | 353 | 2827 | 167 † | 167 † | 222 † | 203 † | 252 † | 25 † | |
| 100 | 476 | 2932 | 253 † | 253 † | 325 † | 299 † | 336 † | 33 † | ||
| 200 | 537 | 2951 | 302 † | 302 † | 370 † | 353 † | 381 † | 33 † | ||
| phone | 50 | 24 | 1129 | 14 † | 15 † | 16 † | 18 † | 15 † | 0 † | |
| 100 | 30 | 1142 | 18 † | 20 † | 26 † | 25 † | 22 † | 0 † | ||
| 200 | 44 | 1164 | 23 † | 30 † | 32 † | 29 † | 27 † | 0 † | ||
| 50 | 65 | 297 | 49 | 40 † | 52 † | 53 | 46 † | 13 † | ||
| 100 | 85 | 303 | 57 † | 52 † | 65 † | 68 | 60 † | 12 † | ||
| 200 | 84 | 301 | 61 † | 51 † | 69 † | 68 | 66 † | 15 † | ||
| GPT-Neo 2.7B | 50 | 176 | 2884 | 62 † | 53 † | 57 † | 53 † | 146 † | 77 † | |
| 100 | 246 | 2973 | 79 † | 88 † | 100 † | 91 † | 201 † | 96 † | ||
| 200 | 286 | 2973 | 109 † | 110 † | 146 † | 130 † | 242 † | 102 † | ||
| phone | 50 | 11 | 1043 | 4 | 1 † | 3 | 3 | 9 | 0 † | |
| 100 | 15 | 1056 | 7 | 2 † | 7 | 5 † | 14 | 1 † | ||
| 200 | 21 | 1066 | 7 † | 4 † | 11 † | 8 † | 21 | 1 † | ||
| 50 | 51 | 266 | 13 † | 10 † | 29 † | 32 † | 51 | 28 † | ||
| 100 | 62 | 272 | 12 † | 12 † | 33 † | 40 † | 59 | 29 † | ||
| 200 | 62 | 279 | 18 † | 12 † | 32 † | 39 † | 62 | 28 † | ||
| GPT-Neo 1.3B | 50 | 96 | 2789 | 25 † | 28 † | 43 † | 32 † | 0 † | 59 † | |
| 100 | 148 | 2876 | 47 † | 45 † | 89 † | 78 † | 0 † | 77 † | ||
| 200 | 179 | 2899 | 69 † | 53 † | 116 † | 97 † | 0 † | 88 † | ||
| phone | 50 | 2 | 1000 | 0 | 0 | 1 | 0 | 0 | 0 | |
| 100 | 4 | 1006 | 0 | 0 | 2 | 0 | 0 | 0 | ||
| 200 | 6 | 1025 | 3 | 0 | 3 | 3 | 0 | 0 | ||
| 50 | 36 | 254 | 23 | 17 † | 22 † | 26 | 0 † | 19 † | ||
| 100 | 47 | 251 | 28 † | 19 † | 24 † | 34 † | 0 † | 24 † | ||
| 200 | 47 | 254 | 28 † | 16 † | 30 † | 36 † | 0 † | 25 † | ||
| Model | Attacks | Pre-Edit | PAE | MEMIT | MEND | DeMem | ||||
|---|---|---|---|---|---|---|---|---|---|---|
| PII Typeth | Zero Shotth | Preth | Pre-Lenth | Expth | Impth | Expth | Impth | |||
| GPT-J 6B | a | 5 | 3130 | 0 | 0 | 1 | 1 | 0 | 0 | |
| b | 2 | 3229 | 0 | 0 | 1 | 0 | 0 | 1 | ||
| c | 26 | 3234 | 14 † | 14 † | 11 † | 17 † | 13 † | 0 † | ||
| d | 68 | 3237 | 41 † | 41 † | 44 † | 37 † | 35 † | 2 † | ||
| phone | a | 0 | 40 | - | - | - | - | - | - | |
| b | 0 | 33 | - | - | - | - | - | - | ||
| c | 0 | 32 | - | - | - | - | - | - | ||
| d | 0 | 641 | - | - | - | - | - | - | ||
| a | 0 | 4 | - | - | - | - | - | - | ||
| b | 27 | 292 | 19 | 15 † | 12 † | 18 † | 19 | 1 † | ||
| c | 0 | 9 | - | - | - | - | - | - | ||
| d | 12 | 220 | 9 | 8 † | 9 | 10 | 6 † | 2 † | ||
| GPT-Neo 2.7B | a | 1 | 1638 | 0 | 0 | 0 | 0 | 0 | 2 | |
| b | 1 | 3230 | 1 | 1 | 0 | 0 | 0 | 0 | ||
| c | 0 | 3229 | - | - | - | - | - | - | ||
| d | 40 | 3238 | 19 † | 15 † | 11 † | 25 † | 35 | 16 † | ||
| phone | a | 0 | 45 | - | - | - | - | - | - | |
| b | 0 | 37 | - | - | - | - | - | - | ||
| c | 0 | 11 | - | - | - | - | - | - | ||
| d | 0 | 760 | - | - | - | - | - | - | ||
| a | 0 | 3 | - | - | - | - | - | - | ||
| b | 32 | 522 | 1 † | 0 † | 0 † | 3 † | 33 | 27 | ||
| c | 0 | 4 | - | - | - | - | - | - | ||
| d | 1 | 109 | - | - | - | - | - | - | ||
| GPT-Neo 1.3B | a | 0 | 2792 | - | - | - | - | - | - | |
| b | 1 | 3219 | 0 | 0 | 0 | 0 | 0 | 0 | ||
| c | 0 | 3225 | - | - | - | - | - | - | ||
| d | 16 | 3232 | 8 † | 2 † | 9 † | 5 † | 0 † | 10 | ||
| phone | a | 0 | 32 | - | - | - | - | - | - | |
| b | 0 | 315 | - | - | - | - | - | - | ||
| c | 0 | 6 | - | - | - | - | - | - | ||
| d | 0 | 429 | - | - | - | - | - | - | ||
| a | 0 | 12 | - | - | - | - | - | - | ||
| b | 39 | 478 | 1 † | 2 † | 8 † | 4 † | 0 † | 36 | ||
| c | 0 | 7 | - | - | - | - | - | - | ||
| d | 12 | 193 | 3 † | 3 † | 4 | 4 | 0 † | 9 | ||
| Model | Attacks | Pre-Edit | PAE | MEMIT | MEND | DeMem | ||
|---|---|---|---|---|---|---|---|---|
| Explicit | Implicit | Explicit | Implicit | |||||
| GPT-J 6B | 60.00 | 59.17 | 59.17 | 60.33 | 60.50 | 59.50 | 49.50 | |
| phone | 60.00 | 60.50 | 59.83 | 60.33 | 60.17 | 60.33 | 44.67 | |
| 60.00 | 60.33 | 60.50 | 60.67 | 60.17 | 60.67 | 49.67 | ||
| GPT-Neo 2.7B | 50.00 | 47.83 | 48.67 | 49.50 | 50.17 | 49.50 | 48.83 | |
| phone | 50.00 | 49.67 | 49.83 | 50.33 | 49.50 | 49.67 | 49.33 | |
| 50.00 | 52.67 | 49.50 | 50.33 | 49.33 | 49.67 | 48.17 | ||
| GPT-Neo 1.3B | 45.17 | 43.17 | 44.67 | 45.17 | 44.83 | 36.00 | 43.83 | |
| phone | 45.17 | 45.67 | 45.33 | 45.17 | 45.50 | 0.00 | 44.00 | |
| 45.17 | 46.00 | 46.67 | 46.17 | 45.67 | 3.33 | 41.33 | ||
| Model | Update Method | Wikipedia: BLEU | ||
|---|---|---|---|---|
| Phone | ||||
| GPT-J 6B | PAE Implicit | 85.0 | 94.8 | 89.4 |
| PAE Explicit | 85.0 | 93.0 | 91.0 | |
| MEMIT Implicit | 88.0 | 93.6 | 92.5 | |
| MEMIT Explicit | 88.3 | 94.5 | 92.1 | |
| MEND | 89.9 | 89.5 | 88.7 | |
| DeMem | 74.9 | 72.6 | 75.5 | |
| GPT-Neo 2.7B | PAE Implicit | 85.2 | 90.7 | 86.2 |
| PAE Explicit | 86.5 | 93.5 | 86.3 | |
| MEMIT Implicit | 88.6 | 95.1 | 89.9 | |
| MEMIT Explicit | 88.5 | 94.9 | 90.1 | |
| MEND | 94.9 | 96.4 | 97.1 | |
| DeMem | 83.0 | 82.4 | 80.9 | |
| GPT-Neo 1.3B | PAE Implicit | 84.0 | 94.2 | 86.2 |
| PAE Explicit | 84.6 | 93.1 | 85.4 | |
| MEMIT Implicit | 87.4 | 98.0 | 88.1 | |
| MEMIT Explicit | 88.1 | 97.2 | 86.5 | |
| MEND | 69.8 | 64.2 | 65.1 | |
| DeMem | 87.5 | 85.4 | 82.6 | |
| Batch Size (k) | Books3 | Wikipedia | Pile-CC | |||
|---|---|---|---|---|---|---|
| BLEU | METEOR | BLEU | METEOR | BLEU | METEOR | |
| 81.4 | 81.8 | 83.7 | 85.6 | 82.6 | 83.6 | |
| 84.1 | 84.6 | 84.3 | 86.1 | 83.4 | 84.5 | |
| 83.3 | 84.3 | 84.3 | 86.1 | 84.7 | 85.5 | |
| 84.0 | 84.4 | 84.7 | 86.8 | 84.9 | 85.5 | |
| 83.7 | 84.2 | 84.4 | 85.7 | 85.9 | 86.8 | |
| 84.8 | 85.8 | 85.7 | 87.1 | 86.7 | 87.6 | |
| Phone | |||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Pre | Pre Len | PAE | MEMIT | Pre | Pre Len | PAE | MEMIT | Pre | Pre Len | PAE | MEMIT | ||
| Memo. | 50 | 353 | 2827 | 183 | 232 | 24 | 1129 | 13 | 12 | 65 | 297 | 42 | 52 |
| 100 | 476 | 2932 | 265 | 335 | 30 | 1142 | 19 | 24 | 85 | 303 | 51 | 64 | |
| 200 | 537 | 2951 | 314 | 381 | 44 | 1164 | 26 | 28 | 84 | 301 | 57 | 65 | |
| Assoc. | a | 5 | 3130 | 0 | 1 | 0 | 40 | - | - | 0 | 4 | 0 | 0 |
| b | 2 | 3229 | 0 | 0 | 0 | 33 | - | - | 27 | 292 | 13 | 18 | |
| c | 26 | 3234 | 15 | 14 | 0 | 32 | - | - | 0 | 9 | - | - | |
| d | 68 | 3237 | 39 | 45 | 0 | 641 | - | - | 12 | 220 | 6 | 6 | |
| Method | LAMBADA | Books3 | Wikipedia | Pile-CC | |||
|---|---|---|---|---|---|---|---|
| Accuracy | BLEU | METEOR | BLEU | METEOR | BLEU | METEOR | |
| PAE | 60.33 (+0.33) | 83.6 | 83.9 | 83.8 | 86.1 | 82.6 | 82.9 |
| MEMIT | 60.66 (+0.66) | 85.3 | 85.7 | 87.8 | 88.8 | 85.1 | 85.9 |
| Pre | Pre Len | PAE | PAE (No Cards) | ||
|---|---|---|---|---|---|
| Memo. | 50 | 353 | 2827 | 167 | 199 |
| 100 | 476 | 2932 | 253 | 284 | |
| 200 | 537 | 2951 | 302 | 332 | |
| Assoc. | a | 5 | 3130 | 0 | 1 |
| b | 2 | 3229 | 0 | 0 | |
| c | 26 | 3234 | 14 | 11 | |
| d | 68 | 3237 | 41 | 44 |
| Method | LAMBADA | Books3 | Wikipedia | Pile-CC | |||
|---|---|---|---|---|---|---|---|
| Accuracy | BLEU | METEOR | BLEU | METEOR | BLEU | METEOR | |
| PAE | |||||||
| PAE (No Cards) | |||||||
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Venditti, D.; Ruzzetti, E.S.; Xompero, G.A.; Giannone, C.; Favalli, A.; Romagnoli, R.; Zanzotto, F.M. Enhancing Data Privacy in Large Language Models Through Private Association Editing. J. Cybersecur. Priv. 2026, 6, 96. https://doi.org/10.3390/jcp6030096
Venditti D, Ruzzetti ES, Xompero GA, Giannone C, Favalli A, Romagnoli R, Zanzotto FM. Enhancing Data Privacy in Large Language Models Through Private Association Editing. Journal of Cybersecurity and Privacy. 2026; 6(3):96. https://doi.org/10.3390/jcp6030096
Chicago/Turabian StyleVenditti, Davide, Elena Sofia Ruzzetti, Giancarlo A. Xompero, Cristina Giannone, Andrea Favalli, Raniero Romagnoli, and Fabio Massimo Zanzotto. 2026. "Enhancing Data Privacy in Large Language Models Through Private Association Editing" Journal of Cybersecurity and Privacy 6, no. 3: 96. https://doi.org/10.3390/jcp6030096
APA StyleVenditti, D., Ruzzetti, E. S., Xompero, G. A., Giannone, C., Favalli, A., Romagnoli, R., & Zanzotto, F. M. (2026). Enhancing Data Privacy in Large Language Models Through Private Association Editing. Journal of Cybersecurity and Privacy, 6(3), 96. https://doi.org/10.3390/jcp6030096