1. Introduction
Transformer self-attention provides content-dependent access to earlier tokens, but the key–value (KV) cache required for autoregressive inference grows with sequence length and with the number of globally attending KV heads [
1,
2]. Efficient attention research has reduced arithmetic and memory traffic through grouped-query attention, streaming policies, and input/output-aware kernels [
2,
3,
4]. These approaches generally preserve, share, compress, or approximate token-to-token attention. A different question is whether some global-attention functions can be localized and whether identified semantic functions can be handed to explicit computation over a structured linguistic state.
The motivation is functional rather than purely compressive. Predicate–argument structure identifies events and their participants, semantic dependency graphs permit multiple relations per mention, and vector-symbolic binding preserves which filler occupies which role [
5,
6,
7]. Such a structure can support exact operations that are difficult to inspect in an unrestricted latent memory: read the patient of a selected event, follow a coreference relation, or distinguish a supporting proof from a contradicting proof. The unresolved architectural issue is whether typed graph computation can coexist with a physical reduction of the global token state and whether any removed attention functionality can be attributed to that graph path.
Our previous Primitive-Augmented Transformer with Event-Role side state (PAT-ER) established that typed event-role registers can be attached to a pretrained decoder with bounded, zero-initialized modulation [
8]. PAT-ER retained dense causal attention at every layer and used 1024-token contexts. The present study asks two separate questions: which selected global KV heads can be physically localized while preserving language-model quality at a true 8192-token context, and whether a typed graph path can provide independently testable event-role computation within the same exported model.
Initial experiments showed why the replacement unit matters. Removing 12 of 24 complete global-attention layers preserved controlled typed execution but increased 8192-token perplexity by 34.22%, with the positions 4096–8191 bucket increasing by 74.74%. Sparse token caches, fixed kernel bases, and dynamic low-rank residual states did not repair the loss. These negative findings indicate that semantic and lexical/discourse functions coexist within layers. They motivate the head-group quotient used here: retain globally attending groups whose token-level context is indispensable, localize redundant groups, and supply narrowly scoped graph reads only to groups with identified semantic programs.
This article addresses four research questions:
RQ1. Can a physically exported, static head-group decomposition preserve perplexity on complete 8192-token sequences?
RQ2. Does the typed graph path preserve controlled event-role behavior beyond ordinary localization or an untyped memory with matched capacity?
RQ3. What fraction of global KV groups can be removed before the 8192-token language-model contract fails?
RQ4. Do independently evaluated natural-carrier graphs and deterministic evidence decisions support a bounded path from natural text to the typed computation?
The principal contributions are:
C1. A three-mode functional taxonomy and static export that removes full-history KV storage from selected heads while retaining compact global and local projections;
C2. An interaction-aware selection procedure combining 384 single-head audits, all 6903 pairs among 118 candidates, measured triples, and constrained mixed-integer subset selection;
C3. An 8192-token Q10–Q30 localization frontier, including a 470-document paired non-inferiority evaluation, static reload verification, and two fresh adaptation/selection campaigns within the frozen 118-head inventory;
C4. An event-scoped typed graph path evaluated separately through typed, untyped, wrong-role, wrong-event, random, and zero interventions, together with a selective natural-carrier evaluation.
Contributions C1–C3 address RQ1 and RQ3; C4 addresses RQ2 and RQ4.
Section 8 returns to each question explicitly and states the remaining unresolved work. The primary Q25 checkpoint localizes 96 of 384 heads. Only 15 execute graph programs; the other 81 are local-only. Ordinary perplexity evaluation disables graph reads and therefore establishes localization tolerance, not graph necessity. The corrected matched-capacity analysis likewise does not demonstrate transfer of a removed attention capability to the graph path.
The remainder of the article is organized as follows.
Section 2 positions the work against efficient attention, head pruning, and structured semantic computation.
Section 3 defines the backbone, carrier, three exported modes, causal audit, selection procedure, export, and evaluation protocol.
Section 4 presents the functional decision framework and use cases.
Section 5 reports language-model, semantic, replication, runtime, and natural-carrier results.
Section 6,
Section 7 and
Section 8 discuss interpretation, limitations, and conclusions.
2. Related Work
2.1. Efficient Attention and Head-Level Functional Variation
Multi-head attention was introduced to allow several content-dependent projections to operate in parallel [
1]. Grouped-query attention shares a KV head among several query heads, reducing inference-state size while maintaining several KV groups [
2]. Cost-aware GQA design has further shown that appropriate head and group allocations depend on context length [
9]. The present backbone uses standard multi-head attention (MHA), with 16 query heads and 16 KV heads in a one-to-one mapping. We retain the term “KV group” for the exported decision unit because the implementation operates on one KV head and its associated query/output slice; in this experiment, each group contains exactly one query head. Accordingly, “KV head” denotes the physical MHA head and “KV group” denotes the selection/export unit; the two coincide numerically in this backbone. The method name is written consistently as
Strata-
HeadQuotient, and exported modes are written as
GLOBAL,
LOCAL, and
LOCAL_GRAPH.
Head-ablation studies have shown substantial heterogeneity. Michel et al. found that many heads could be removed at inference without large task degradation, although important heads remained [
10]. Voita et al. identified specialized translation heads and used stochastic gates to prune less important heads [
11]. These results establish redundancy and specialization, but neither typed semantic substitution nor exact physical graph execution follows from importance scores alone. In the present work, each candidate group is evaluated under local-only, typed, untyped, wrong-role, wrong-event, random, and graph-zero interventions. Pairwise interactions are then included because individually safe removals need not be jointly safe.
StreamingLLM demonstrates that retaining selected token states can stabilize windowed generation [
4], while FlashAttention shows that algorithmic memory savings do not automatically imply wall-clock improvements unless data movement is considered [
3]. Recent peer-reviewed KV-compression work spans latent KV representations and post-training conversion [
12], adaptive grouping and resource allocation [
9], token-cluster selection [
13], layer-adaptive quantization [
14], task-aware layer budgets [
15], and two-stage permanent-eviction plus sparse-attention policies [
16]. These methods compress KV dimensions, precision, groups, or retained tokens.
Strata-
HeadQuotient instead statically converts selected full-history heads to local heads and attaches exact typed programs to a smaller final-layer subset; it is complementary to, rather than a direct replacement for, those compression dimensions.
Table 1 provides quantitative positioning and a qualitative mechanism comparison. The reported data come from different backbones, tasks, hardware, and context protocols and are therefore not treated as a head-to-head ranking. The same-backbone dense and intervention controls remain the basis for the empirical claims in this article.
The comparison exposes distinct design axes rather than a single efficiency ranking. MHA2MLA and TaDA reduce representation size or precision; ClusterAttn, DynamicKV, and RocketKV reduce the retained token set; Cost-Optimal GQA changes group allocation.
Strata-
HeadQuotient changes the temporal scope of a statically selected head and adds a typed semantic interface to a smaller subset. The methods may therefore be composable, but cross-paper numerical superiority cannot be inferred from
Table 1.
2.2. Semantic Roles, Dependency Graphs, and Typed Binding
PropBank represents predicate-specific argument roles and has expanded across genres, languages, and semantic resources [
5]; FrameNet organizes lexical units around frames and frame elements [
17]; and Universal Dependencies (UD) supplies cross-lingual morphology and basic syntactic relations [
18]. Direct semantic dependency parsing supports graph outputs that are not constrained to one syntactic head per token [
6], while second-order parsers explicitly model interactions between semantic edges [
19]. These foundations motivate the minimal carrier used by
Strata-
HeadQuotient: it preserves only surface relations required for exact frame-conditioned role derivation, rather than requiring a complete UD tree at inference.
Vector symbolic architectures provide distributed mechanisms for binding fillers to roles and for composing symbolic structures [
7]. In
Strata-
HeadQuotient, an orthogonal role basis and exact unbinding preserve the distinction between, for example, the agent and patient of the same event. This distinction is evaluated causally: an untyped collapse has the same graph capacity but removes role addresses, and a wrong-role intervention supplies a valid filler under the wrong role.
2.3. Structured Evidence and Selective Prediction
ProofWriter and FOLIO demonstrate the value of explicit proof annotations and executable logical structure for evaluating language reasoning [
20,
21]. The proposed model applies a narrower deterministic mechanism: once support and contradiction proof facts are supplied, the decision is a fixed mapping to
ANSWER,
REJECT,
NOT_SURE, or
IDK. This does not estimate universal truth and does not replace calibration of the upstream natural compiler.
2.4. Relation to PAT-ER
Table 1 compares
Strata-
HeadQuotient with external KV-efficiency methods; PAT-ER is instead the direct architectural precursor and is therefore described here rather than in a second comparison table. PAT-ER retained dense attention in every layer, used additive event-role and primitive registers, and evaluated 1024-token contexts [
8]. The present work uses executable predicate-graph programs, changes the physical temporal scope of selected heads, evaluates complete 8192-token sequences, and exports a model in which 96/384 heads no longer retain full-history KV. Inherited elements are the motivation for explicit event-role state, bounded attachment, and typed-versus-untyped interventions. The representation, localization objective, context length, selection procedure, and physical export are new; no PAT-ER prose, figures, or experimental tables are reused.
3. Materials and Methods
3.1. Dense Reference Model and Corpora
The dense reference is a controlled multilingual decoder with the architecture in
Table 2. It uses standard MHA, not grouped-query attention: every query head has its own KV head. The dense checkpoint contains 554,281,986 parameters and the Q25 export 554,281,987. The 8192-position embedding table was initialized by periodic copying of a trained 4096-position absolute table; all rows then remained trainable during continuation.
The frozen continuation budget was 100,007,936 tokens sampled from a 500-million-token multilingual Wikipedia corpus (snapshot 1 November 2023) containing 688,774 documents and equal 100-million-token pools for Arabic, Chinese, English, German, and Spanish. Training used eight NVIDIA L40 GPUs, one 8192-token sequence per GPU, no gradient accumulation, AdamW with learning rate of , and , weight decay of 0.1, and 2% warmup followed by cosine decay, gradient-norm clipping at 1.0, bfloat16 arithmetic, distributed data parallelism, and 1526 optimizer steps. The held-out corpus contains five million tokens, one million per language, across 6653 documents. Token files, metadata, configurations, and checkpoints were hash-locked before frontier evaluation. This token budget is small relative to the 554M-parameter model and is treated as a limitation on backbone maturity.
The original frontier used eight complete 8192-token confirmation windows (indices 112–119), with diagnostic windows 96–103 and interaction window 110 kept separate. After a methodological review identified the small confirmation sample, the already frozen Q25 checkpoint was evaluated on a larger post-review set. The set contains one complete 8192-token window from each of the 470 unique held-out documents, selected by deterministic document hash without model outputs: 20 Arabic, 300 Chinese, and 50 each for English, German, and Spanish. The unequal support reflects the number of eligible long documents and is handled by reporting both aggregate and per-language results. This evaluation covers 3,850,240 input tokens and 3,849,770 next-token targets. Statistical inference uses paired document-level differences; adjacent tokens are not treated as independent bootstrap units.
Controlled semantic data are partitioned by non-overlapping generator indices (
Table 3). Cases are balanced across
READ_EVENT_ARG0,
READ_EVENT_ARG1,
READ_EVENT_ARG2,
READ_EVENT_TIME, and
READ_EVENT_LOCATION. Each case provides eight same-type answer candidates, a correct answer, and a matched counterfactual answer. The post-review confirmation set had not been used for adapter training, head auditing, interaction measurement, program assignment, or threshold selection.
The natural external carrier set contains 2000 examples. A separate, once-opened evidence-policy set contains 800 hash-locked cases.
3.2. Natural Semantic Carrier and Exact Closure
The natural compiler maps a completed segment to a compact surface-semantic carrier rather than a complete dependency tree. Carrier nodes include predicates, mentions, entities, clauses, gaps, coordination groups, times, and locations. Carrier edges include subject and object realization, clausal complements, relative gaps, coordination sharing, nominal arguments, case evidence, and voice. The carrier is intentionally not the final role graph. Frozen lexical valency signatures and construction rules map surface realization to canonical roles:
where
B is a carrier hypothesis and
G is a canonical typed graph. The executor rejects ill-typed programs. The carrier compiler exposes relation-level prediction sets and marks a fact authoritative only when event, relation, and argument hypotheses agree and a frame/valency proof is valid. Non-authoritative facts are not injected.
This quotient was motivated empirically: the gold carrier retained 4731 semantic edges from 50,459 UD arcs while preserving canonical execution at 0.996584. Thus, 90.62% of surface-syntax arc decisions were removed from the semantic intermediate without changing the frozen semantic result on the supported set. The carrier retains only dependencies that participate in the frozen execution. The natural parser, valency stack, and role lattice are frozen during the head-replacement campaign.
The external-v3 carrier set was selected deterministically from UD v2.18 English-CHILDES, English-LinES, and English-ParTUT after the development contract was frozen.
Table 4 gives the exact composition. Selection first excluded every source corpus used by the carrier-development environments, then rejected document, normalized-text, and surface-template overlap; it prioritized unseen predicate lemmas, multi-event cases, and construction-family balance. The final set contains 580 multi-event examples and 1057 examples whose predicate lemma was absent from carrier training. Its targets are deterministic projections of the source UD annotations followed by the frozen lexical and construction rules; they were not independently re-annotated or manually adjudicated for this experiment. Accordingly, the evaluation measures transfer from independently unused treebanks under the same conversion scheme, not agreement with a new human semantic annotation.
3.3. Event-Scoped Graph Programs
For current anchor
and group-specific program
, the graph path returns only the program result:
Programs read one role or construction address from one selected event. Unrelated events cannot enter the read. Each graph-enabled group has at most two programs during adaptation and a hard static assignment at export. The graph read is fused by a bounded relative residual read (BRR):
where
is a proof-derived reliability term. Graph projections and gates are zero initialized, so graph attachment begins as the exact dense function, following the identity-safe residual principle used in zero-initialized networks [
22]. Invalid, disputed, unsupported, or low-reliability reads are exactly zero.
Table 5 gives an illustrative input and the exact addresses exposed to a graph-enabled head. It is an explanatory example, not an additional evaluation case. A local head sees only its 1024-token window. A global head retains ordinary full-history token KV. A local-plus-graph head has the same local window and may additionally receive only the result of its assigned event-scoped program.
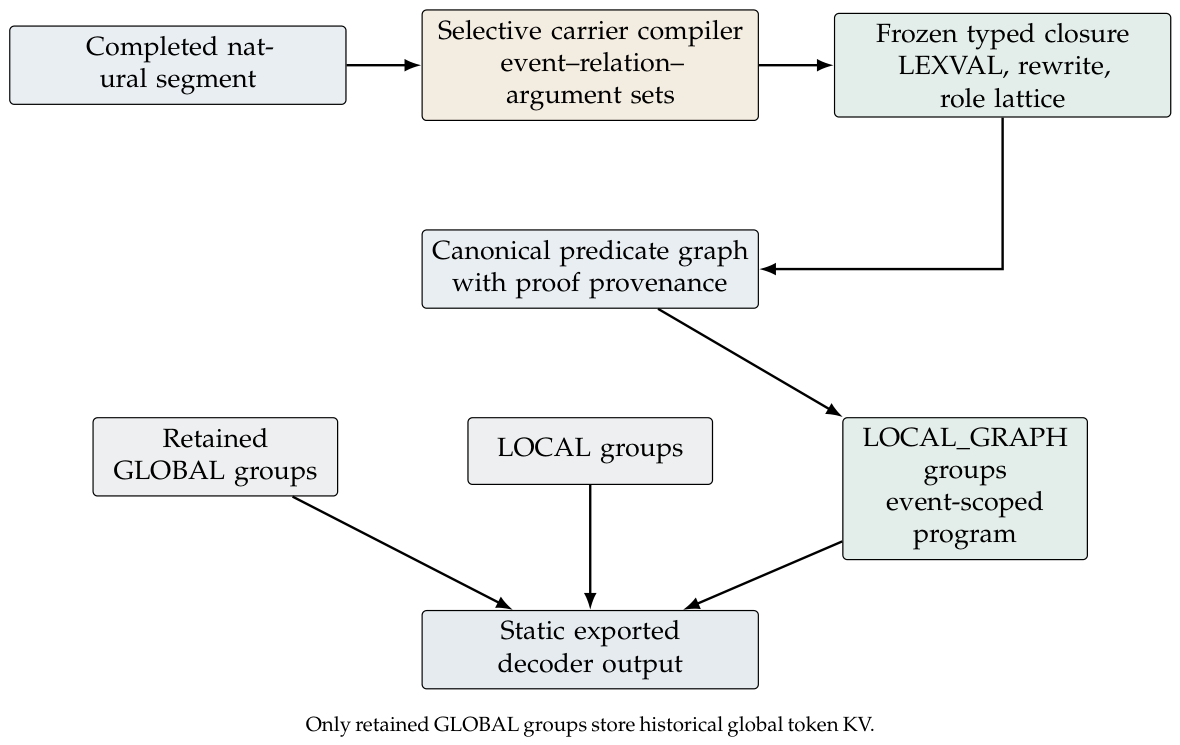
Figure 1 summarizes the complete boundary: natural-carrier compilation and exact semantic closure occur before the statically exported model-core modes, and compiler runtime is accounted for separately.
3.4. Functional KV-Group Taxonomy
For layer
ℓ and KV group
g, one exported mode is active:
At export,
z is one-hot.
GLOBAL retains full causal history;
LOCAL keeps only a 1024-token local window; and
LOCAL_GRAPH combines the same local window with Equation (
2).
Table 6 gives the reproducible decision rule. This functional taxonomy avoids calling every localized group a semantic group.
3.5. Causal Group Audit
The dense model has global KV groups. Every group was evaluated under five replacements: ablation, local-only, local-plus-typed graph, local-plus-untyped graph, and local-plus-wrong-role graph. The audit recorded late-context perplexity cost, controlled semantic cost, typed recovery, wrong-event sensitivity, depth, functional cluster, and estimated runtime cost. A group entered the replacement candidate pool only if the individual audit supported localization; 118 groups passed this screening.
Group effects are non-additive. For candidate groups
i and
j, we measured
where
C contains language-model and semantic replacement costs. All
candidate pairs and 128 high-interaction triples were evaluated. This interaction graph prevents independent ranking from selecting a jointly destructive set.
3.6. Constrained Subset Selection and Graph-Path Adaptation
For binary replacement variable
, the selector minimizes a linearized signed quadratic objective:
The node cost was
. Pairwise aggregate and late-NLL interactions were scaled by 0.739698 and 0.527571, respectively, estimated against 128 measured triples; positive semantic interaction again received a weight of 20. Each localized layer incurred a 0.005 compactness cost. The constraints enforced the exact head budget and limited Q25 to ten localized layers. Every localized layer required at least two selected heads, layer 23 required at least ten selected heads, each of the five graph programs required at least two eligible readers, and every measured functional cluster retained at least one representative. Selection used SciPy’s mixed-integer linear programming interface with HiGHS branch-and-bound, a 900 s time limit, and a requested relative gap of 0.30. For Q25, the solver returned a feasible tested configuration with an 11.16% mixed-integer gap. We do not claim that Q25 is unique or globally optimal.
Graph-path adaptation used ordinary causal language-model loss plus controlled intervention losses, without matching dense hidden states or dense outputs. For correct answer
y, counterfactual
, correct graph
G, and wrong graph
, the margin loss was
The scoped adapter loss was the mean of correct-graph and wrong-role cross-entropies plus
and a 0.01 sparsity/coverage/unsupported-program regularizer. The adapter was trained for 1200 steps with batch size of 32 using AdamW, a learning rate of
, a weight decay of
, and gradient clipping at 1.0. Wrong-event, random, and zero graphs were held as evaluation interventions rather than added to this scoped loss. Static export used 32 stabilization steps at a learning rate of
, a weight decay of zero, and gradient clipping at 1.0, updating only packed local projection rows. All frontier budgets were evaluated sequentially: Q10 (39 groups), Q20 (77), Q25 (96), and Q30 (115). Q40 was not opened after Q30 failed.
3.7. Static Physical Export
After selection, global, local, and graph-local groups were packed into contiguous per-layer projections. Training gates and inactive global K/V slices were removed. Historical token KV is allocated only for GLOBAL groups. Program outputs are cached per segment/event and routed by a parameter-free static table. Export validation reloads the checkpoint and checks the number and identity of localized groups, retained global groups, affected layers, and graph program assignments.
At Q25, 96 groups across ten layers were localized. Of these, 81 are LOCAL and 15 are LOCAL_GRAPH. All graph-enabled groups are in the final decoder layer (zero-based layer 23), because the scoped graph-adapter campaign fixed graph computation to that layer before subset selection; the experiment did not search graph-adapter depth. The graph-enabled groups execute five program types; repeated program counts across groups are 15 for Arg0, 7 for Arg1, 3 for Arg2, 3 for time, and 2 for location because a group may support up to two active programs before hard export. Ten compacted layers contain no original dense QKV module object; retained global groups in those layers are represented by compact global projections.
3.8. Evaluation Metrics and Statistical Analysis
Language-model quality is reported as candidate-to-dense perplexity ratio, both aggregate and in position buckets 0–2047, 2048–4095, and 4096–8191. For the 470-document post-review confirmation, we compute paired Q25-minus-dense negative-log-likelihood (NLL) for every document and form percentile 95% confidence intervals from 10,000 document bootstrap resamples. Exponentiating the paired NLL interval yields the PPL-ratio interval. Non-inferiority is supported when the interval’s upper bound is below the pre-specified ratio 1.03. Language-specific intervals use the same document-level procedure. Graph reads are disabled for both models in this LM evaluation. Thus, this test evaluates the global-to-local quotient and cannot establish graph necessity for perplexity.
Controlled execution is exact-match accuracy over 2000 cases. Exact counts and two-sided 95% Clopper–Pearson intervals are reported for the untouched post-review set. Because each case has eight candidates, uniform chance accuracy is 0.125. The principal causal quantity is the answer-margin change relative to graph zero. A marginal localization effect additionally subtracts a matched H0 dense-plus-graph effect. The corrected H0 retains all token attention but activates exactly the same selected graph heads and program table as the corresponding Q25 export. This capacity matching repairs an earlier comparison in which H0 used all 16 graph heads while Q25 used 14 or 15. Marginal intervals use 1000 paired bootstrap resamples and are diagnostic rather than final confirmation statistics.
Runtime uses synchronized CUDA measurements on an NVIDIA L40 GPU with PyTorch 2.5.1, CUDA 12.4, and bfloat16 model weights. The original qualification paired full-sequence 8192-token forwards. A subsequent serving profile used an inference-only preallocated cache: retained heads store KV to the maximum sequence length, whereas localized heads use a 1024-token circular buffer. Prefill and 32-token autoregressive decode were timed separately after one warm-up and over three repeats at batch sizes 1, 4, 8, and 16. Before timing, cached and full-sequence paths were compared under the same mathematical SDPA backend on a held-out prefix. Their top-token predictions were identical; maximum absolute logit differences were 0.0625 for dense and 0.078125 for Q25, and maximum probability differences were 0.00154 and 0.00212, respectively. Thus, the BF16 paths are numerically, not bitwise, equivalent. All model-core timings exclude synchronous natural-carrier compilation.
3.9. Fresh Q25 Replication Audits
Two additional Q25 campaigns used new graph-adapter initializations and random seeds (20260777 and 20260791), disjoint language-model diagnostic and interaction windows, and disjoint controlled-semantic index regions. The 118-head candidate pool was kept fixed from the original single-head pre-screen; these runs therefore test fresh adaptation, interaction measurement, joint selection, and export within a frozen candidate inventory rather than independent rediscovery of that inventory. Each campaign re-evaluated all 118 candidate node costs, all 6903 pair interactions, and 128 triples, solved a fresh 96-head mixed-integer selection, exported a physical checkpoint, and ran the same model-core evaluations. Because Q25 was already the declared frontier, the campaigns did not repeat Q10–Q30 selection.
The corrected matched-capacity H0 analysis was treated as a strict attribution check. When that check failed, the larger 470-document and 2000-case evaluations were run only as post-failure characterization of whether localization and the typed path reproduced; they were not used to convert a failed attribution gate into a pass. Document-bootstrap intervals quantify evaluation variability, while differences among the three campaigns characterize selection and adaptation variability under the fixed candidate pool. The pre-specified promotion criteria and evaluation material are summarized in
Table 7.
4. Functional Framework and Use-Case Analysis
4.1. Decision Procedure for a KV Group
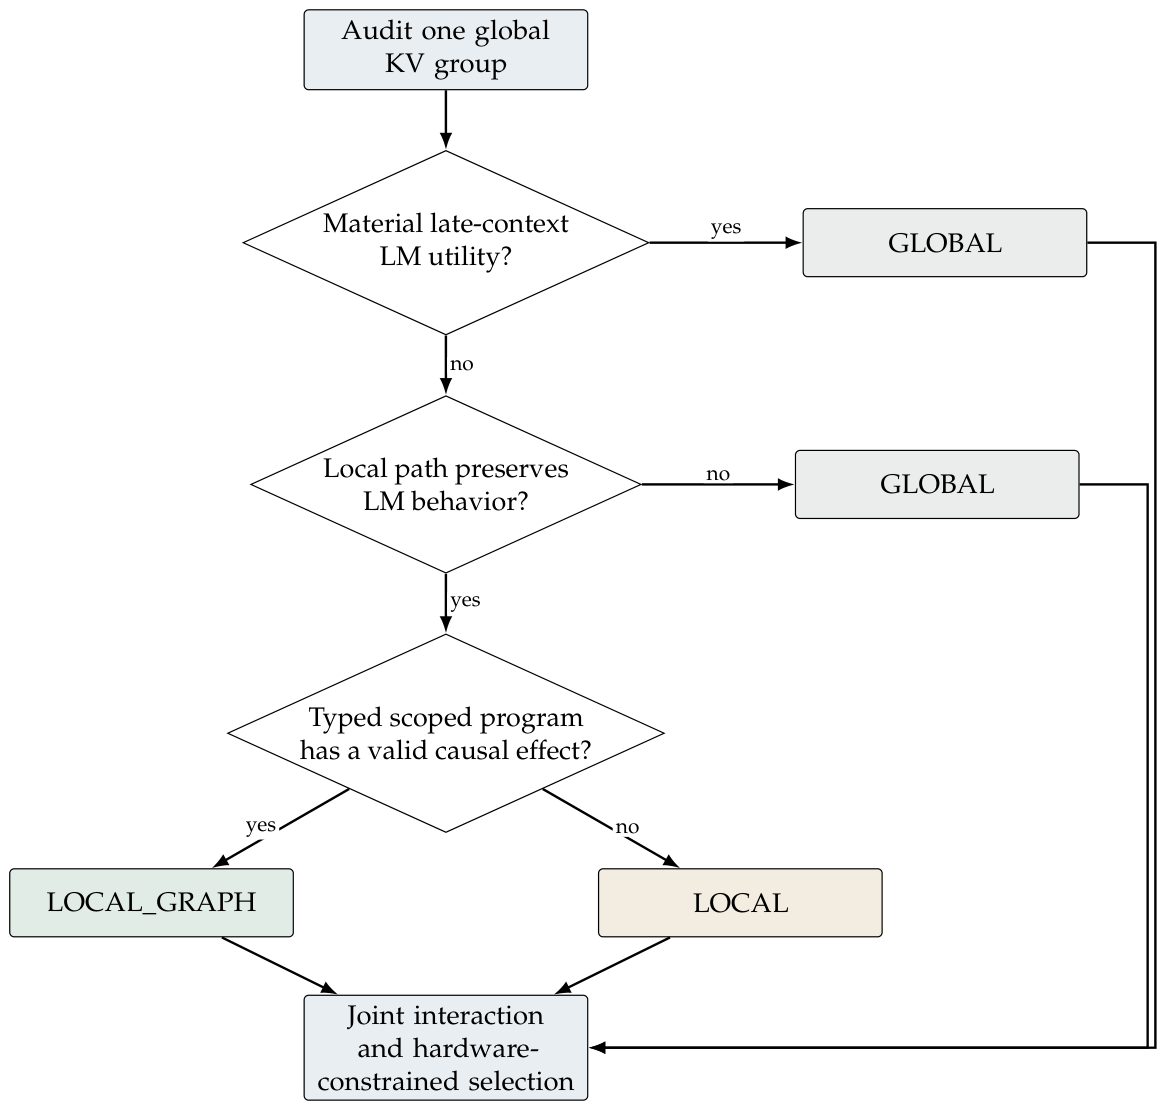
Figure 2 summarizes the selection logic. A group with material late-context perplexity utility remains global. A group without such utility is tested locally. Typed graph assignment is permitted only when an event-scoped program is identified and the correct graph recovers a relation-sensitive margin without corresponding recovery from wrong-event or random graphs. The final decision is joint: cluster retention and pairwise interactions can override an individually favorable assignment.
4.2. Typed Program Use Cases
The graph programs are intentionally narrow. Participant programs retrieve one frame-relative filler: Arg0commonly denotes an agent-like role, Arg1a patient/theme-like role, and Arg2a recipient or other frame-specific third core role. These labels are addresses within a lexical frame, not universal thematic definitions. Time and location programs retrieve typed adjunct values attached to the selected event. The event anchor is part of the query, so the same mention participating in two events does not authorize migration between them.
For natural input, the compiler first predicts event, relation, and argument jointly. A fact is authoritative only if all corresponding prediction sets are singletons and the exact semantic proof is valid. This supports selective use rather than forced graph completion. In the external-v3 evaluation, the main unresolved errors were wrong carrier relation and multi-event ambiguity, which is consistent with the use case targeted by event-scoped programs.
4.3. Intended Task and Deployment Boundary
The tested use case is long-context document language modeling with precompiled or asynchronously compiled event-role structure. The graph path supports bounded participant, time, location, and evidence-state queries when a carrier fact is authoritative. It is not a general replacement for retrieval-augmented generation, unrestricted question answering, or a safety-critical control loop. The model-core localization result remains valid without natural graph input because graph reads are disabled in ordinary PPL evaluation. Conversely, the semantic result requires a valid carrier and exact program address. Synchronous natural compilation is too slow for a production-efficiency claim in the tested implementation.
4.4. Deterministic Evidence-State Decisions
The evidence controller operates after structured facts are available. For claim
q, let
indicate at least one valid support proof and
at least one valid contradiction proof. The decision is
Structural disagreement and unsupported frames may also force
IDK before Equation (
8) is applied. This is deterministic execution over a supplied evidence graph. It is not a claim that the model knows whether a statement is true in the world.
5. Results
5.1. Dense Coexistence and Matched Q10 Controls
The H0 attachment retained every global group and initialized graph projections and gates to zero. Logits, hidden states, perplexity, and position-bucket losses were identical to the dense baseline before adaptation. This established that the graph interface could be attached without perturbing the reference function.
At Q10, the functional selector localized 39/384 groups and preserved aggregate perplexity at 0.9999× dense. Matched random removal of 39 groups produced 1.0466× perplexity; independent importance-only removal produced 1.3798×. Thus, preserving perplexity was not a generic consequence of removing a small number of heads. The importance-only failure also illustrates that independent local scores can choose a destructive combination when interactions are ignored.
5.2. Replacement Frontier
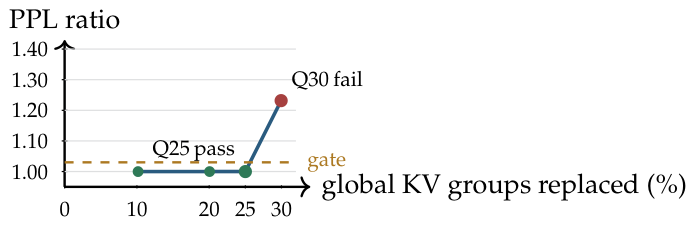
Table 8 and
Figure 3 show the pre-specified frontier on the original fixed eight-window confirmation. Q10, Q20, and Q25 preserved aggregate and late-context perplexity on that material. Q30 failed abruptly, with an aggregate ratio of 1.2317 and late ratio of 1.3781. Typed execution remained high at Q30, so the failure is attributable to language-model information in the additional global groups rather than collapse of the typed executor. The larger 470-document Q25 confirmation is reported separately and supersedes the original Q25 point estimate for the final language-model claim.
5.3. 8192-Token Language-Model Quality
Table 9 reports the expanded Q25 confirmation. Mean dense NLL was 4.916463 (PPL 136.519) and mean Q25 NLL was 4.917926 (PPL 136.719). The paired PPL ratio was 1.001463, and the upper 95% document-bootstrap bound, 1.001611, remained well below the 1.03 non-inferiority margin. Every position bucket and language-specific upper bound also remained within its gate. Because graph reads were disabled, these values establish LM preservation by the mixed global-to-local quotient, not by the graph program itself.
Table 10 consolidates the three exported modes and graph interventions. The ordinary-text evaluator invokes the exported model with
graph_enabled=false. Typed, untyped, and graph-zero variants were evaluated on the separate semantic task, not as different ordinary-text PPL models. No evidence from
Table 9 can therefore be used to claim that graph reads are necessary for ordinary PPL preservation.
Qualitatively, the ablations assign different responsibilities to the exported modes. The dense reference tests unrestricted historical token access. Q25 ordinary LM combines retained GLOBAL heads with LOCAL and graph-disabled LOCAL_GRAPH heads, thereby isolating the global-to-local quotient. The typed, untyped, wrong-role, and graph-zero conditions keep the same exported head map and vary only the semantic representation, thereby isolating the graph interface. Consequently, the PPL result supports localization, whereas the typed–untyped and wrong-role contrasts support role-sensitive graph computation. Neither result is used as evidence for the other.
5.4. Typed Graph Computation and Matched-Capacity Reanalysis
On the untouched confirmation split, the typed graph achieved 1998/2000 exact executions (0.999), while the matched untyped graph achieved 374/2000 (0.187), a difference of 0.812 (
Table 11). Wrong-role execution was zero and selected the counterfactual wrong target in 1999/2000 cases, demonstrating role-address sensitivity. Wrong-event and random conditions matched graph zero exactly at 267/2000 (0.1335), close to the 0.125 uniform-candidate chance baseline. Their accuracy is therefore a retained-model floor, not a graph benefit. These interventions establish that the typed path is causally operative relative to zero, untyped, and wrong-role conditions.
Correct typed graphs increased the untouched-set answer margin over graph zero by 0.2098. Methodological review subsequently identified that the original H0 comparator activated all 16 final-layer graph heads, whereas the Q25 export activated 15. A corrected comparator retained all token-attention heads globally while activating exactly the Q25-selected graph heads and program table. Under this matched capacity, the original campaign’s marginal correct-graph effect was (95% paired-bootstrap interval to ). The two fresh campaigns produced ( to ) and ( to ). Every interval includes zero. The data therefore support a typed path that changes controlled behavior, but they do not establish that this path recovered a capability lost when the selected attention heads were localized.
5.5. Depth Concentration of the Typed Path
All 15
LOCAL_GRAPH heads occur in layer 23, while the 81 local-only heads are distributed over layers 2, 4, 5, and 17–22. Disabling the layer-23 graph read produces the graph-zero semantic condition in
Table 11. However, because the scoped adapter was fixed to layer 23 before joint selection, this concentration is not evidence that optimization discovered the final layer as uniquely best. No matched relocation experiment was performed. The supported description is therefore a final-layer semantic controller combined with localization at nine earlier layers.
5.6. Fresh Selection and Adaptation Results
Table 12 reports the original campaign and two fresh campaigns. Both fresh solves selected 96 heads but used 14 rather than 15 graph-enabled heads. Their selected-set Jaccard similarities were 0.901 and 0.939 relative to the original set and 0.864 to each other. The expanded PPL upper bounds remained below 1.03 in every run, typed execution remained above 0.99, the typed–untyped difference exceeded 0.80, and no invalid program occurred. Full-sequence throughput ranged from 0.953× to 0.984× dense. Thus, Q25 localization and the separate typed-path behavior reproduced across fresh adaptation, interaction audit, subset selection, and export. The corrected matched-capacity attribution check failed in every campaign because each confidence interval included zero; this negative result is reported alongside, rather than hidden by, the reproducible component metrics.
5.7. Physical Export and Model-Core Efficiency
Reload verification found exactly 96 localized groups and 288 retained global groups. The affected layers were 2, 4, 5, and 17–23 (zero-based indexing). Historical global KV state is therefore 75% of dense, corresponding to a dense-to-Q25 ratio of 1.3333. The graph routing table used 80 buffer bytes and two parameter bytes after compaction.
At 8192 tokens and bfloat16 KV storage, dense attention requires 805,306,368 token-KV bytes. Q25 retains 603,979,776 bytes for 288 full-history heads and 25,165,824 bytes for the 1024-token windows of 96 localized heads, totaling 629,145,600 bytes before graph state and implementation buffers. The resulting token-KV ratio is 0.78125, a 21.875% reduction. Thus, “25%” refers specifically to the number of heads no longer retaining full history, not to total KV-cache bytes.
Model-core full-sequence throughput was 71,892 tokens/s for Q25 and 73,034 tokens/s for dense in the frozen confirmation, a ratio of 0.9844. Peak allocated memory was 1,488,253,440 bytes versus 1,488,563,200 bytes, a ratio of 0.99979. Consequently, the original qualification supports 25% fewer full-history KV heads, 21.875% fewer token-KV bytes before graph state, and near-dense full-sequence model-core throughput.
The physical export and model-core runtime results are summarized in
Table 13.
Table 14 reports the separate cached-serving profile. With an 8160-token prefix and 32 decoded tokens, the measured persistent KV ratio was exactly 0.78125 at every batch size. Q25 decode throughput was 1.003× dense at batch 1 and increased to 1.237× at batch 16; prefill ranged from 0.926× to 1.018×. Peak allocated memory ratios ranged from 0.922 at batch 1 to 0.834 at batch 16. These results establish an implementation-specific cached-decode benefit for this model core, especially under batching. They do not include carrier compilation, scheduler overhead, networking, or production request variability.
5.8. External Natural-Carrier Evaluation
The frozen natural-carrier compiler was evaluated once on the 2000 external-v3 examples described in
Table 4, none of which was used for Q25 frontier selection (
Table 15). Raw canonical execution was 1821/2000 (0.9105). Relation-level authority increased execution among accepted facts to 0.9827 at 0.7973 fact coverage, with a wrong-authority rate of 0.0173 and carrier-edge macro-F1 of 0.9210. No invalid programs occurred. This result supports selective transfer to three unused English UD treebanks under the frozen conversion scheme, but it is separate from Q25’s model-core LM evaluation and does not constitute independently adjudicated semantic gold.
The associated 256-case frozen natural graph retrieval evaluation obtained 256/256 typed answers, 127/256 untyped answers, 2/256 under wrong role, 12/256 under wrong event and graph zero, and 0/256 under random carrier. Because this retrieval evaluation used the frozen natural semantic stack packaged before Q25 frontier selection, it is reported as evidence for compiler/executor transfer rather than as an end-to-end latency claim for Q25.
5.9. Deterministic Evidence-Policy Verification
On the once-opened 800-case hash-locked evidence set, Equation (
8) achieved 1.000 macro decision accuracy, 1.000 accuracy for each of the four decisions, 1.000 proof correctness, 1.000 paired-identical agreement, and zero invalid proof/programs. The set contained 200 support-only, 200 contradiction-only, and 100 cases each for conflicting evidence, absent required evidence, structural disagreement, and unresolved structure.
This experiment evaluates the policy given structured proof facts. It does not evaluate extraction of all proofs from unrestricted natural text, factual correctness of a source, or universal truth-aware confidence. An incorrect authoritative carrier fact can still produce a deterministically incorrect decision.
5.10. Claim–Evidence Summary
Table 16 separates the supported claims from tests that failed or remain outside the study. This distinction is central because localization, typed graph behavior, and complete-system efficiency are evaluated by different experiments.
5.11. Negative and Boundary Results
Table 17 summarizes the experiments that delimit the final design. They are included because they prevent the positive Q25 result from being interpreted as evidence for whole-layer or generic compressed-memory replacement.
6. Discussion
6.1. The Replacement Unit Is Functional, Not Layer-Wide
The principal result is the contrast between whole-layer failure and head-group success. Complete attention layers combined semantic, lexical, quotation, numeric, stylistic, and discourse functions. A predicate graph represented the first category well but could not reconstruct the rest. Head-level auditing retained groups with distributed lexical utility and removed only a jointly compatible subset. The Q25/Q30 discontinuity further shows that substitutability is not a smooth magnitude-pruning property.
The result should also not be reduced to ordinary independent pruning. Random and importance-only Q10 controls degraded perplexity, and the untouched typed/untyped semantic difference was 0.812. At the same time, 81 of the 96 localized heads were local-only, all 15 graph-enabled heads were constrained to the final layer, and ordinary PPL was evaluated with graph reads disabled. The correct interpretation is therefore a mixed quotient: interaction-aware localization preserves ordinary LM behavior, while a smaller final-layer graph path preserves controlled typed behavior. The experiment neither identifies all 96 localized heads as semantic nor shows that graph reads cause the observed PPL preservation.
6.2. Why Event-Scoped Programs Matter
Broad graph cross-attention allows unrelated events to influence a query and can assign authority to a graph simply because its embedding is similar. Event-scoped programs instead expose a typed address and one result set. Relative to graph zero, correct graphs altered controlled answers while wrong-event and random graphs had null effects. The wrong-role intervention is stronger: moving a valid filler to the wrong role reverses the target margin, showing that role identity, rather than the presence of a related entity vector, controls the read. The corrected dense-capacity comparison nevertheless shows no detectable additional marginal effect caused by localization; event scoping is therefore supported as an operative typed interface, not as demonstrated transfer from the removed heads.
6.3. Scientific and Systems Implications
Scientifically, Q25 demonstrates that a nontrivial fraction of full-history token memory can be quotiented into local computation while remaining non-inferior to dense attention under the 3% 8192-token PPL margin. Separately, exact graph operations preserve controlled event-role behavior for the designated semantic heads. The static export makes the localization claim structural: full-history KV is not allocated for localized heads. The tested Q30 subset is a counterexample to extrapolating the passing Q25 configuration, although it is not a proof that no 30% subset can pass.
System conclusions are narrower. The number of full-history KV heads decreases by 25%, but 1024-token local windows reduce token-KV bytes by 21.875% before graph state rather than 25%. Peak allocation was unchanged in the full-sequence benchmark because parameters, local buffers, activations, and compact graph machinery dominated that measured peak. The separate cached profile showed near-parity batch-1 decode and higher batched decode throughput with lower measured peak allocation, but only for one inference-only implementation and workload. The natural compiler is substantially slower than dense inference when run synchronously. A practical deployment would require asynchronous document compilation, cached carriers, or a much faster selective compiler. Those complete-system engineering possibilities were not established by the present experiment.
6.4. Natural Compilation and Evidence Control
External-v3 supports a selective natural path at 98.27% authoritative execution and 79.73% coverage. This is evidence of useful natural compilation, not universal parsing. The remaining wrong-authority rate of 1.73% is material in high-stakes use. The graph-off fallback is therefore part of the method, not an optional convenience.
The four-way evidence controller demonstrates deterministic differentiation between support, contradiction, conflict, and absence. Unlike verbal confidence, the decision can be traced to proof availability. Its reliability nevertheless remains conditional on the source evidence, carrier compilation, and supported rule inventory. Human review and domain-specific verification remain necessary where incorrect structured facts can cause harm.
7. Limitations
The original Q25 result followed a large adaptive search comprising 384 single-head audits, 6903 pair interventions, 128 triple checks, program assignment, a mixed-integer solve, and four frontier stages. Two fresh campaigns used new graph-adapter seeds, disjoint diagnostic and interaction material, complete new interaction audits, fresh mixed-integer selections, and physical exports. They reproduced Q25 PPL non-inferiority and typed-path behavior with different selected subsets. However, the 118-head candidate pre-screen remained fixed. The two campaigns therefore replicate graph adaptation, interaction measurement, constrained selection, and export within that inventory; they do not repeat discovery from all 384 heads. The corrected matched-capacity attribution check failed in all three campaigns. Document bootstrap intervals quantify evaluation uncertainty, not all variation from backbone training or candidate-pool discovery.
The study uses one approximately 554-million-parameter controlled decoder, standard 16-head MHA, and one 8192-token context. Its 100M-token continuation budget is low relative to model size, so head redundancy may differ in a more mature pretrained model. Neither the 25% fraction nor the selected head map should be extrapolated to larger models, GQA backbones, more extensively trained checkpoints, or longer contexts. The expanded LM result covers 470 documents, but its language support is unequal and the Arabic estimate is based on 20 eligible long documents.
Ordinary-text PPL was evaluated with graph reads disabled. Consequently, this experiment establishes that interaction-aware localization preserves LM quality and that a typed graph path separately preserves controlled semantics; it does not establish that typed graph reads are necessary for PPL preservation. The matched-capacity intervals further fail to establish that localization transferred an attention capability to the graph path. Graph programs were restricted to the final decoder layer before subset selection. Their layer-23 concentration is therefore a design constraint, not a discovered optimum; no conclusion about optimal graph depth is supported.
The mixed-integer selector returned a feasible Q25 solution with an 11.16% optimality gap. Q25 is therefore a demonstrated passing configuration, not a global optimum. Q30 failure establishes only that the tested 115-head subset failed; it does not rule out every possible 30% subset. The final semantic confirmation is independent of semantic training and interaction data, but the graph-program inventory and thresholds arose from earlier development stages.
Natural-carrier evaluation is bounded to 2000 English examples from 15 documents in three unused UD treebanks and to the supported conversion inventory. Its targets were produced from source UD annotations by the same frozen deterministic conversion and were not independently human-adjudicated. Thus, multilingual evidence in this paper concerns LM perplexity, whereas the external semantic evaluation is English-only and conversion-derived. A separately adjudicated natural semantic set remains future work; no post-submission annotation was introduced into this revision. The compiler is selective and leaves about 20% of facts non-authoritative. Its synchronous runtime is not production-competitive. The evidence-policy evaluation conditions on structured proof facts and primarily verifies deterministic implementation consistency; it cannot establish natural proof extraction, broad factual reliability, or universal awareness of missing knowledge.
Peak allocation did not materially decrease in the original full-sequence qualification, and its model-core throughput was 1.6% below dense. The separate cached profile measured lower peak allocation and faster batched decode, but it used one L40 GPU, one fixed 32-token continuation, identical prompts within each batch, and an inference-only research cache rather than a production server. The 25% figure concerns heads that no longer retain full history; after 1024-token local windows are included, token-KV bytes decrease by 21.875% before graph state and implementation buffers. Synchronous compiler-inclusive throughput is approximately 0.19× dense, so complete-system acceleration is not supported. Maximum production concurrency, floating-point operation counts, scheduler effects, and complete-system latency remain unqualified. All runtime findings are hardware- and implementation-dependent.
Finally, the semantic carrier and role lattice use supervised linguistic resources. This work does not demonstrate label-free semantic-role induction. Morphologically rich and low-resource languages may require dedicated preprocessing and lexical resources, which were not evaluated independently in this study.
8. Conclusions
Strata-HeadQuotient changes full-history token access at the level of causally selected heads rather than complete layers. In a 24-layer MHA decoder with 384 KV heads, a static export localized 96 heads: 81 became local-only and 15 received final-layer, event-scoped typed predicate-graph programs. On 470 document-disjoint complete 8192-token windows, the Q25/dense PPL ratio was 1.00146 (95% CI 1.00131–1.00161), satisfying the pre-specified 1.03 non-inferiority margin. The model retained 98.44% of dense full-sequence core throughput, used 25% fewer full-history KV heads, and used 21.875% fewer token-KV bytes before graph state. A separate cached profile showed near-parity decode at batch 1 and 1.178–1.237× dense decode throughput at batches 4–16 after an 8160-token prefix. On an untouched controlled set, typed execution reached 1998/2000 versus 374/2000 for an untyped graph. The tested Q30 subset failed.
8.1. Answers to the Research Questions
RQ1 (C1–C3). Yes, within the tested configuration. The physically exported Q25 decomposition preserved 8192-token perplexity for the tested 554M MHA backbone: its dense-relative PPL ratio was 1.00146, with a 95% upper bound of 1.00161 against the pre-specified 1.03 non-inferiority margin.
RQ2 (C4). Yes for controlled role-sensitive behavior, but not as demonstrated transfer from localized heads. Typed execution reached 1998/2000 versus 374/2000 for the capacity-matched untyped graph, and wrong-role execution was 0/2000. However, every corrected matched-capacity marginal graph-effect interval included zero; the study therefore does not show that graph programs caused the PPL result or recovered a capability removed by localization.
RQ3 (C2–C3). The demonstrated frontier is 25%, not a proven global maximum. Q25 passed the full protocol, whereas the tested Q30 subset failed with an aggregate PPL ratio of 1.2317. The solver gap and finite subset search do not rule out every alternative 30% configuration.
RQ4 (C4). Yes, selectively and under the frozen conversion inventory. External-v3 authoritative carrier execution reached 98.27% at 79.73% coverage, and the registered evidence policy deterministically separated support, contradiction, conflict, and absence. The carrier targets were English and conversion-derived rather than independently adjudicated semantic gold, so this result does not establish unrestricted natural semantic understanding.
8.2. Unresolved Questions and Future Work
The study leaves six issues unresolved: independent candidate discovery from all heads; graph-adapter placement at matched decoder depths; transfer to a mature GQA or second backbone; independently adjudicated multilingual semantic evaluation; asynchronous carrier compilation and complete serving latency; and contexts beyond 8192 tokens. These are not implied by the present results. Future work should address them separately under the same static-export, causal-control, and non-inferiority requirements.
Supplementary Materials
The following supporting information can be downloaded at:
https://www.mdpi.com/article/10.3390/make8090269/s1, Eight supporting files accompany the manuscript. File S1 contains the complete static Q25 mode and program assignment. File S2 contains frozen Q25/Q30 frontier metrics and artifact hashes. File S3 contains the natural-carrier evaluation. File S4 contains the hash-locked evidence-policy evaluation. File S5 contains the frozen multilingual held-out corpus metadata. File S6 contains the 470-document post-review PPL confirmation, the untouched semantic confirmation, architecture metadata, persistent token-KV accounting, per-document losses, and bootstrap results. File S7 contains the cached prefill/decode profile and numerical-equivalence checks. File S8 contains the original and fresh Q25 replication summary, selected-set overlaps, checkpoint hashes, and corrected matched-capacity intervals. The filenames and checksums are listed in the project README and
Appendix A.
Author Contributions
Conceptualization, N.K. and M.M.; methodology, N.K.; software, N.K.; validation, N.K. and M.M.; formal analysis, N.K.; investigation, N.K.; data curation, N.K.; writing—original draft preparation, N.K.; writing—review and editing, N.K. and M.M.; visualization, N.K.; supervision, M.M.; project administration, M.M.; funding acquisition, M.M. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by the Ministry of Science and Higher Education of the Republic of Kazakhstan, grant number BR24993001, “Creation of a large language model (LLM) to maintain the implementation of Kazakh language and increase the technological progress”.
Institutional Review Board Statement
Not applicable. The study did not involve human participants or animals. It used public text corpora, synthetic controlled cases, and previously prepared linguistic annotations.
Informed Consent Statement
Not applicable.
Data Availability Statement
The compact analytical reproducibility package is publicly available in the immutable STRATA-HeadQuotient Q25 v1.2.0 release at
https://huggingface.co/datasets/nur-dev/strata-headquotient-q25/tree/v1.2.0 (Hub commit
de7d91302c249f65fcb4f8304fc13d7b32ff0bec; accessed 21 July 2026). It contains the complete group classifications, 6903 original pair interactions, reported metrics, classification rules, two fresh Q25 campaign summaries, the corrected matched-capacity analysis, verification scripts,
supplementary tables, and SHA-256 checksums. The dense reference, three physical Q25 checkpoints, tokenizer, static assignments, event-scoped adapters, complete fresh interaction audits, exact evaluation token bundles, cached-decode implementation and profile, pinned environment, transitive source snapshot, and one-command verification/evaluation scripts are public in the linked immutable model release at
https://huggingface.co/nur-dev/strata-headquotient-q25/tree/v1.2.0 (Hub commit
60b2ea8dc02c1b847faf3770105fecb2e9a74d7d; accessed 21 July 2026). The evaluation token material retains the upstream Wikipedia licensing terms documented in that release; third-party source corpora are otherwise not duplicated.
Acknowledgments
The authors acknowledge computational support provided by Al-Farabi Kazakh National University. OpenAI ChatGPT and Codex using GPT-5 (accessed through 3 September 2026) were used for code scaffolding, experimental-plan review, implementation assistance, consistency and artifact audits, manuscript organization, and LaTeX formatting. The tools did not act as authors or approve experimental conclusions. The authors inspected code changes, executed the experiments, verified outputs against frozen manifests and source files, checked cited sources, and take full responsibility for the study design, results, interpretations, and manuscript.
Conflicts of Interest
The authors declare no conflicts of interest. The funders had no role in the design of the study; in the collection, analyses, or interpretation of data; in the writing of the manuscript; or in the decision to publish the results.
Abbreviations
The following abbreviations are used in this manuscript:
| BRR | Bounded relative residual read |
| GQA | Grouped-query attention |
| KV | Key–value |
| LM | Language model |
| MHA | Multi-head attention |
| PPL | Perplexity |
| TPR | Tensor product representation |
| UD | Universal dependencies |
Appendix A. Reproducibility Manifest
Table A1.
Principal SHA-256 identifiers.
Table A1.
Principal SHA-256 identifiers.
| Artifact | SHA-256 |
|---|
| Dense reference checkpoint | 10e8559713ef1d951c604605f8f3666a027a25a341363d0c17006f628cc38c1f |
| Q25 exported checkpoint | 51120c7ecca5234a4e7cee424c199582e444eb04e434a2d7f08263e3ccc74a90 |
| Q25 confirmation result | a2ed2b19139c3bdc37f7995f084cfd3d3900eaac13931f09f4a122783c49fc65 |
| Post-review 470-document confirmation | ce61c391567909891f972535a0f376b9250e6b9111a7a2c30ed3ee81f8e65e20 |
| Q25 selection plan | cdb8f17ae11322d276b68b96873398257a8936ebb20a007749d4811bce6039e1 |
| Held-out token corpus | a3988865234579662bf1fda5b486f08d3f5b1e8be02a7c249f9892af3d0ff61f |
| Training token corpus | 0d0494869aa61a04e12d95dc2bfce6beb684dc9d787da42b9445a458a49bc2c4 |
| External-v3 target set | 9a455e1cee6e819ff80ceff72d2664be8c98a1eec6be95911efa3cdc74754f91 |
| Hash-locked evidence test | d00bd33339182d80f54ebc29093985448a08ab32d213be7be779540def18fd94 |
| Supplementary Q25 group map | 5d64414e334f1c9a5535e67f8373cd76f3b1d2b837624dd1d511a4f2486ebc8c |
| Cached decode profile | fec2e25194ef49faa5a5d99fabc9c836f9407075c321a16bfc6ef807f1460654 |
| Q25 replication summary | 00aa763a46ce1572821239bec2721fcd5e4946d09992b36079adb87b1b511c73 |
Appendix B. Q25 Layer Distribution
Table A2.
Localized Q25 groups by zero-based layer index.
Table A2.
Localized Q25 groups by zero-based layer index.
| Layer | 2 | 4 | 5 | 17 | 18 | 19 | 20 | 21 | 22 | 23 | Total |
|---|
| Localized groups | 6 | 10 | 12 | 2 | 12 | 7 | 7 | 10 | 15 | 15 | 96 |
| Graph-enabled | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 15 | 15 |
| Local-only | 6 | 10 | 12 | 2 | 12 | 7 | 7 | 10 | 15 | 0 | 81 |
References
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, L.; Polosukhin, I. Attention Is All You Need. In Advances in Neural Information Processing Systems 30; Curran Associates: Red Hook, NY, USA, 2017; pp. 5998–6008. [Google Scholar]
- Ainslie, J.; Lee-Thorp, J.; de Jong, M.; Zemlyanskiy, Y.; Lebron, F.; Sanghai, S. GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, Singapore, 6–10 December 2023; pp. 4895–4901. [Google Scholar] [CrossRef] [Scilit]
- Dao, T.; Fu, D.Y.; Ermon, S.; Rudra, A.; Ré, C. FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness. In Advances in Neural Information Processing Systems 35; Curran Associates: Red Hook, NY, USA, 2022; pp. 16344–16359. [Google Scholar]
- Xiao, G.; Tian, Y.; Chen, B.; Han, S.; Lewis, M. Efficient Streaming Language Models with Attention Sinks. In Proceedings of the 12th International Conference on Learning Representations, Vienna, Austria, 7–11 May 2024. [Google Scholar]
- Pradhan, S.; Bonn, J.; Myers, S.; Conger, K.; O’Gorman, T.; Gung, J.; Wright-Bettner, K.; Palmer, M. PropBank Comes of Age—Larger, Smarter, and More Diverse. In Proceedings of the 11th Joint Conference on Lexical and Computational Semantics, Seattle, WA, USA, 14–15 July 2022; pp. 278–288. [Google Scholar] [CrossRef] [Scilit]
- Dozat, T.; Manning, C.D. Simpler but More Accurate Semantic Dependency Parsing. In Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics, Volume 2: Short Papers, Melbourne, Australia, 15–20 July 2018; pp. 484–490. [Google Scholar] [CrossRef] [Scilit]
- Schlegel, K.; Neubert, P.; Protzel, P. A Comparison of Vector Symbolic Architectures. Artif. Intell. Rev. 2022, 55, 4523–4555. [Google Scholar] [CrossRef] [Scilit]
- Kadyrbek, N.; Mansurova, M. Primitive-Augmented Transformers with Event-Role Side State: Architecture Evidence, Warm-Started Modulation, and Decoupled Tool Interfaces. Mach. Learn. Knowl. Extr. 2026, 8, 201. [Google Scholar] [CrossRef] [Scilit]
- Chen, Y.; Wu, Y.; Song, C.; Thai, Z.L.; Shen, X.; Han, X.; Liu, Z.; Sun, M. Cost-Optimal Grouped-Query Attention for Long-Context Modeling. In Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, Suzhou, China, 4–9 November 2025; pp. 5360–5376. [Google Scholar] [CrossRef] [Scilit]
- Michel, P.; Levy, O.; Neubig, G. Are Sixteen Heads Really Better than One? In Advances in Neural Information Processing Systems 32; Curran Associates: Red Hook, NY, USA, 2019; pp. 14014–14024. [Google Scholar]
- Voita, E.; Talbot, D.; Moiseev, F.; Sennrich, R.; Titov, I. Analyzing Multi-Head Self-Attention: Specialized Heads Do the Heavy Lifting, the Rest Can Be Pruned. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics, Florence, Italy, 28 July–2 August 2019; pp. 5797–5808. [Google Scholar] [CrossRef] [Scilit]
- Ji, T.; Guo, B.; Wu, Y.; Guo, Q.; Shen, L.; Chen, Z.; Qiu, X.; Zhang, Q.; Gui, T. Towards Economical Inference: Enabling DeepSeek’s Multi-Head Latent Attention in Any Transformer-Based LLMs. In Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), Vienna, Austria, 27 July–1 August 2025; pp. 33313–33328. [Google Scholar] [CrossRef] [Scilit]
- Zhang, M.; Sun, H.; Wang, J.; Li, S.; Ning, W.; Qi, Q.; Zhuang, Z.; Liao, J. ClusterAttn: KV Cache Compression under Intrinsic Attention Clustering. In Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), Vienna, Austria, 27 July–1 August 2025; pp. 14451–14473. [Google Scholar] [CrossRef] [Scilit]
- Joshi, V.; Brahma, P.P.; Liu, Z.; Barsoum, E. TaDA: Training-Free Recipe for Decoding with Adaptive KV Cache Compression and Mean-Centering. In Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 6: Industry Track), Vienna, Austria, 27 July–1 August 2025; pp. 1435–1443. [Google Scholar] [CrossRef] [Scilit]
- Zhou, X.; Wang, W.; Zeng, M.; Guo, J.; Liu, X.; Shen, L.; Zhang, M.; Ding, L. DynamicKV: Task-Aware Adaptive KV Cache Compression for Long Context LLMs. In Proceedings of the Association for Computational Linguistics: EMNLP 2025, Suzhou, China, 4–9 November 2025; pp. 8042–8057. [Google Scholar] [CrossRef] [Scilit]
- Behnam, P.; Fu, Y.; Zhao, R.; Tsai, P.-A.; Yu, Z.; Tumanov, A. RocketKV: Accelerating Long-Context LLM Inference via Two-Stage KV Cache Compression. Proc. Mach. Learn. Res. 2025, 267, 3358–3392. [Google Scholar]
- Boas, H.C.; Ruppenhofer, J.; Baker, C.F. FrameNet at 25. Int. J. Lexicogr. 2024, 37, 263–284. [Google Scholar] [CrossRef] [Scilit]
- Nivre, J.; de Marneffe, M.-C.; Ginter, F.; Hajič, J.; Manning, C.D.; Pyysalo, S.; Schuster, S.; Tyers, F.; Zeman, D. Universal Dependencies v2: An Evergrowing Multilingual Treebank Collection. In Proceedings of the Twelfth Language Resources and Evaluation Conference, Marseille, France, 11–16 May 2020; pp. 4034–4043. [Google Scholar]
- Wang, X.; Huang, J.; Tu, K. Second-Order Semantic Dependency Parsing with End-to-End Neural Networks. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics, Florence, Italy, 28 July–2 August 2019; pp. 4609–4618. [Google Scholar] [CrossRef] [Scilit]
- Tafjord, O.; Dalvi, B.; Clark, P. ProofWriter: Generating Implications, Proofs, and Abductive Statements over Natural Language. In Proceedings of the Association for Computational Linguistics: ACL-IJCNLP 2021, Online, 1–6 August 2021; pp. 3621–3634. [Google Scholar] [CrossRef] [Scilit]
- Han, S.; Schoelkopf, H.; Zhao, Y.; Qi, Z.; Riddell, M.; Zhou, W.; Coady, J.; Peng, D.; Qiao, Y.; Benson, L.; et al. FOLIO: Natural Language Reasoning with First-Order Logic. In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, Miami, FL, USA, 12–16 November 2024; pp. 22017–22031. [Google Scholar] [CrossRef] [Scilit]
- Bachlechner, T.; Majumder, B.P.; Mao, H.; Cottrell, G.; McAuley, J. ReZero Is All You Need: Fast Convergence at Large Depth. Proc. Mach. Learn. Res. 2021, 161, 1352–1361. [Google Scholar]
Figure 1.
End-to-end architecture and the boundary between the frozen natural semantic compiler and the head-level model-core quotient. Carrier-compiler runtime is reported separately from model-core runtime.
Figure 1.
End-to-end architecture and the boundary between the frozen natural semantic compiler and the head-level model-core quotient. Carrier-compiler runtime is reported separately from model-core runtime.
Figure 2.
Decision procedure for functional group assignment. Individual audits generate candidates; the final static assignment is chosen jointly because group interactions are non-additive.
Figure 2.
Decision procedure for functional group assignment. Individual audits generate candidates; the final static assignment is chosen jointly because group interactions are non-additive.
Figure 3.
Observed aggregate 8192-token perplexity frontier on the original fixed windows. The sharp change between the tested Q25 and Q30 subsets bounds the demonstrated quotient to 25% for this checkpoint and protocol; it does not prove that every possible 30% subset fails.
Figure 3.
Observed aggregate 8192-token perplexity frontier on the original fixed windows. The sharp change between the tested Q25 and Q30 subsets bounds the demonstrated quotient to 25% for this checkpoint and protocol; it does not prove that every possible 30% subset fails.
Table 1.
Quantitative positioning and qualitative distinctions relative to recent peer-reviewed KV-efficiency methods. Values for prior work are those reported by the cited authors and were not reproduced in this study.
Table 1.
Quantitative positioning and qualitative distinctions relative to recent peer-reviewed KV-efficiency methods. Values for prior work are those reported by the cited authors and were not reproduced in this study.
| Method | Mechanism | Source-Reported Scope/Result | Qualitative Distinction |
|---|
| MHA2MLA [12] | Low-rank latent KV after MHA conversion | 92.19% KV reduction for Llama2-7B with a 1% LongBench drop | Compresses representation rank; it does not assign explicit local or typed functions to physical heads. |
| Cost-Optimal GQA [9] | Context-dependent KV/query-head allocation | More than 50% memory and FLOP reduction versus the compared Llama-3 GQA configuration | Designs group geometry; this work instead post hoc localizes selected heads in an MHA checkpoint. |
| ClusterAttn [13] | Prompt-token selection by attention clusters | 10–65% memory reduction; 12–23% lower latency in the authors’ settings | Dynamically retains selected historical tokens; this work uses a static head mode and a fixed local window. |
| TaDA [14] | Layer-adaptive KV quantization | Retains 27% of the 16-bit KV footprint with comparable reported accuracy | Reduces precision without changing the semantic interpretation or temporal scope of a head. |
| DynamicKV [15] | Task-aware layer-specific token budgets | At 0.9% cache, reported 11% improvement over compared methods on Needle-in-a-Haystack | Adapts cache size to task/layer; this work exports one static mode per head. |
| RocketKV [16] | Permanent eviction followed by top-k sparse attention | Up to 400× compression and 3.7× speedup with negligible reported task loss | Approximates token attention at decode; this work preserves selected global heads and separately executes typed programs. |
| This work | Static global-to-local head localization plus a separate typed path | 21.875% token-KV reduction before graph buffers; PPL ratio 1.00146 (95% CI 1.00131–1.00161) | Tests functional head modes, physical export, and typed interventions; it does not claim the largest cache reduction. |
Table 2.
Dense reference and Q25 architecture. The KV-group sharing ratio is one because the tested backbone uses standard MHA.
Table 2.
Dense reference and Q25 architecture. The KV-group sharing ratio is one because the tested backbone uses standard MHA.
| Component | Value | Component | Value |
|---|
| Decoder layers | 24 | Vocabulary | 48,029 |
| Model width | 1024 | Context length | 8192 |
| Query heads/layer | 16 | KV heads/layer | 16 |
| Query heads/KV head | 1 | Head dimension | 64 |
| Dense feed-forward width | 4704 | Local window | 1024 |
| Position encoding | Learned absolute | Normalization | RMSNorm |
| Feed-forward activation | SwiGLU | Dropout | 0 |
| Dense parameters | 554,281,986 | Q25 parameters | 554,281,987 |
| Weight precision | bfloat16 | Segment size | 256 |
Table 3.
Controlled semantic split boundaries and uses.
Table 3.
Controlled semantic split boundaries and uses.
| Split | Indices | Cases | Purpose |
|---|
| Graph-adapter train | 0–1999 | 2000 | Scoped graph-adapter training |
| Diagnostic control | 2048–4047 | 2000 | Program assignment and frontier diagnostics; first 256 also used for interaction audit |
| Post-review confirmation | 8192–10,191 | 2000 | Final untouched typed, untyped, wrong-role, wrong-event, random, and zero evaluation |
Table 4.
Composition and source licensing of the external-v3 natural-carrier evaluation. All examples are in English.
Table 4.
Composition and source licensing of the external-v3 natural-carrier evaluation. All examples are in English.
| UD v2.18 Treebank | Examples | Share | Source License |
|---|
| English-CHILDES | 1154 | 57.7% | CC BY-SA 4.0 |
| English-LinES | 613 | 30.7% | CC BY-NC-SA 4.0 |
| English-ParTUT | 233 | 11.7% | CC BY-NC-SA 4.0 |
| Total | 2000 | 100% | 15 source documents; no text is redistributed in the article package |
Table 5.
Worked example of event-scoped typed access and the three exported modes.
Table 5.
Worked example of event-scoped typed access and the three exported modes.
| Element | Illustrative Value |
|---|
| Completed text | “Mira gave Leo the report. Leo filed the report later.” |
| Canonical events | and |
| Typed facts | ; ; ; ; ; |
| Scoped read | READ_EVENT_ARG2 returns Leo; the same program addressed to is invalid because the selected frame has no Arg2 filler |
| GLOBAL | Reads full-history token KV through ordinary causal attention |
| LOCAL | Reads only the most recent 1024-token window |
| LOCAL_GRAPH | Uses the same local window and one statically assigned typed result such as READ_EVENT_ARG2 |
Table 6.
Functional taxonomy of exported KV-group modes.
Table 6.
Functional taxonomy of exported KV-group modes.
| Mode | Historical State | Admission Rule | Exported Computation |
|---|
| GLOBAL | Full token KV | High late-context utility or low graph substitutability | Compact global projection and historical KV cache |
| LOCAL | Window KV only | Low joint replacement cost; no identified graph program | Local attention; no historical global KV |
| LOCAL_GRAPH | Window KV plus typed result | Strong typed effect, valid event scope, null control effects | Local attention and a hard event-scoped program; no historical global KV |
Table 7.
Pre-specified Q25 promotion criteria and evaluated material. The post-review confirmation enlarges the sample without changing the frozen model or 3% margin.
Table 7.
Pre-specified Q25 promotion criteria and evaluated material. The post-review confirmation enlarges the sample without changing the frozen model or 3% margin.
| Category | Criterion | Gate | Evaluation Material |
|---|
| Replacement | Global KV groups | ≥25% | Reloaded static checkpoint and group map |
| Aggregate LM | 8192-token PPL ratio | ≤1.03 | 470 document-disjoint 8192-token windows; upper 95% bound also tested |
| Late LM | Positions 4096–8191 PPL ratio | ≤1.05 | Same windows, position-bucket loss and document bootstrap |
| Languages | Every PPL ratio | ≤1.05 | Arabic, Chinese, English, German, and Spanish document subsets |
| Typed causality | Accuracy; typed–untyped | ≥0.95; ≥0.20 | 2000 untouched matched graph-program cases |
| Null controls | Wrong-event/random gain | Near zero | Paired interventions and bootstrap intervals |
| Efficiency | Throughput; peak allocation | ≥0.95×; ≤1.00× | Paired synchronized model-core benchmark |
| Validity | Invalid programs | 0 | Exact typed executor |
Table 8.
Static full-history-KV localization frontier on the original eight-window evaluation. Runtime is the full-sequence model-core throughput relative to dense. Q30 is a failed diagnostic checkpoint.
Table 8.
Static full-history-KV localization frontier on the original eight-window evaluation. Runtime is the full-sequence model-core throughput relative to dense. Q30 is a failed diagnostic checkpoint.
| Stage | Groups | Fraction | Graph Groups | PPL Ratio | 4096–8191 Ratio | Throughput |
|---|
| Q10 | 39 | 10.16% | 13 | 0.999909 | 0.999708 | 1.0252× |
| Q20 | 77 | 20.05% | 15 | 1.000037 | 0.999470 | 1.0339× |
| Q25 | 96 | 25.00% | 15 | 0.999939 | 0.999389 | 0.9844× |
| Q30 | 115 | 29.95% | 15 | 1.231682 | 1.378070 | 0.9393× |
Table 9.
Expanded Q25 8192-token perplexity ratios relative to dense attention. Intervals are paired 95% document-bootstrap intervals; n is the number of documents.
Table 9.
Expanded Q25 8192-token perplexity ratios relative to dense attention. Intervals are paired 95% document-bootstrap intervals; n is the number of documents.
| Slice | n | Ratio | 95% CI |
|---|
| Aggregate | 470 | 1.001463 | (1.001315, 1.001611) |
| Positions 0–2047 | 470 | 1.000426 | (1.000296, 1.000556) |
| Positions 2048–4095 | 470 | 1.001417 | (1.001209, 1.001624) |
| Positions 4096–8191 | 470 | 1.002006 | (1.001772, 1.002237) |
| Arabic | 20 | 1.000795 | (0.999749, 1.001707) |
| Chinese | 300 | 1.001546 | (1.001371, 1.001736) |
| English | 50 | 1.001290 | (1.000772, 1.001840) |
| German | 50 | 1.001624 | (1.001213, 1.002084) |
| Spanish | 50 | 1.001246 | (1.000978, 1.001515) |
Table 10.
Consolidated mode and intervention ablation. A dash denotes that the metric was not evaluated for that configuration; “identical” denotes the same graph-disabled LM path, not an additional fitted result.
Table 10.
Consolidated mode and intervention ablation. A dash denotes that the metric was not evaluated for that configuration; “identical” denotes the same graph-disabled LM path, not an additional fitted result.
| Configuration | Exported Head Modes | Graph Input | LM PPL Ratio | Semantic Exact Accuracy |
|---|
| Dense reference | 384 GLOBAL | Disabled | 1.000000 | – |
| Q25 ordinary LM | 288 GLOBAL; 81 LOCAL; 15 LOCAL_GRAPH | Disabled | 1.001463 (1.001315, 1.001611) | – |
| Q25 typed | Same Q25 export | Correct typed | – | 0.9990 (1998/2000) |
| Q25 untyped | Same Q25 export | Capacity-matched untyped | Identical LM path if disabled | 0.1870 (374/2000) |
| Q25 wrong role | Same Q25 export | Typed filler at wrong role | – | 0.0000 (0/2000) |
| Q25 graph zero | Same Q25 export | Zero | Identical to ordinary LM by construction | 0.1335 (267/2000) |
| Localized without graph | 288 GLOBAL; 96 LOCAL | Absent | Identical to Q25 ordinary LM path | No graph-supported prediction |
| Dense plus zero-safe graph | 384 GLOBAL | Zero | Exactly dense at initialization | – |
Table 11.
Q25 controlled graph interventions on the untouched 2000-case confirmation. Confidence intervals are exact two-sided 95% Clopper–Pearson intervals.
Table 11.
Q25 controlled graph interventions on the untouched 2000-case confirmation. Confidence intervals are exact two-sided 95% Clopper–Pearson intervals.
| Condition | Correct | Accuracy | 95% CI |
|---|
| Correct typed graph | 1998/2000 | 0.9990 | (0.9964, 0.9999) |
| Untyped graph | 374/2000 | 0.1870 | (0.1701, 0.2048) |
| Wrong role | 0/2000 | 0.0000 | (0.0000, 0.0018) |
| Wrong event | 267/2000 | 0.1335 | (0.1189, 0.1492) |
| Random graph | 267/2000 | 0.1335 | (0.1189, 0.1492) |
| Graph zero | 267/2000 | 0.1335 | (0.1189, 0.1492) |
Table 12.
Original and fresh Q25 campaigns. PPL intervals use the 470-document post-failure characterization for fresh runs. “Marginal typed effect” compares Q25 with a dense-attention H0 having exactly the same graph-head/program capacity; all intervals include zero.
Table 12.
Original and fresh Q25 campaigns. PPL intervals use the 470-document post-failure characterization for fresh runs. “Marginal typed effect” compares Q25 with a dense-attention H0 having exactly the same graph-head/program capacity; all intervals include zero.
| Metric | Original | Fresh Seed 20260777 | Fresh Seed 20260791 |
|---|
| Localized heads | 96 | 96 | 96 |
| Graph-enabled heads | 15 | 14 | 14 |
| Expanded PPL ratio | 1.001463 | 1.001305 | 1.001412 |
| Expanded PPL 95% upper bound | 1.001611 | 1.001452 | 1.001554 |
| Expanded typed execution | 0.9990 | 0.9935 | 0.9940 |
| Expanded untyped execution | 0.1870 | 0.1910 | 0.1920 |
| Diagnostic core throughput | 0.9844× | 0.9528× | 0.9781× |
| Marginal typed effect | | | |
| Marginal-effect 95% CI | | | |
| Strict attribution check | Not passed | Not passed | Not passed |
Table 13.
Q25 physical and runtime results. Compiler-inclusive throughput is reported to preserve the distinction between model-core and complete-system performance.
Table 13.
Q25 physical and runtime results. Compiler-inclusive throughput is reported to preserve the distinction between model-core and complete-system performance.
| Metric | Dense | Q25 | Interpretation |
|---|
| Full-history KV heads retained | 384 | 288 | 25% fewer full-history heads |
| Full-history token-KV bytes | 805,306,368 | 603,979,776 | 0.750× dense |
| Local-window token-KV bytes | 0 | 25,165,824 | 1024-token windows for localized heads |
| Total token-KV bytes † | 805,306,368 | 629,145,600 | 0.78125× dense; 21.875% reduction |
| Full-sequence core throughput | 73,034 tok/s | 71,892 tok/s | 0.9844× dense |
| Peak allocated memory | 1.489 GB | 1.488 GB | 0.99979×; operationally unchanged |
| Compiler-inclusive throughput | 1.000× | approx. 0.19× | Synchronous natural serving not qualified |
| Invalid typed programs | – | 0 | Exact executor rejected no evaluated program |
Table 14.
Cached model-core profile after an 8160-token prefix and 32 autoregressive decode steps. Ratios are Q25/dense except for peak allocation, where a lower value uses less device memory.
Table 14.
Cached model-core profile after an 8160-token prefix and 32 autoregressive decode steps. Ratios are Q25/dense except for peak allocation, where a lower value uses less device memory.
| Batch | Dense Decode | Q25 Decode | Decode Ratio | Prefill Ratio | KV Ratio | Peak Ratio |
|---|
| |
Tokens/s
| | | | |
|---|
| 1 | 142.15 | 142.52 | 1.003 | 0.926 | 0.78125 | 0.922 |
| 4 | 401.95 | 473.67 | 1.178 | 1.018 | 0.78125 | 0.863 |
| 8 | 558.87 | 681.12 | 1.219 | 1.015 | 0.78125 | 0.845 |
| 16 | 682.04 | 843.54 | 1.237 | 0.994 | 0.78125 | 0.834 |
Table 15.
External-v3 natural-carrier and graph-retrieval results.
Table 15.
External-v3 natural-carrier and graph-retrieval results.
| Metric | Result | Cases or Scope |
|---|
| Raw carrier execution | 0.9105 | 2000 natural examples |
| Authoritative execution | 0.9827 | Accepted relation-level facts |
| Authoritative coverage | 0.7973 | Fraction accepted |
| Wrong-authority rate | 0.0173 | Accepted facts |
| Carrier-edge macro-F1 | 0.9210 | Carrier relation inventory |
| Invalid programs | 0 | Full natural set |
| Typed retrieval | 1.0000 | 256/256; exact 95% CI (0.9857, 1.0000) |
| Untyped retrieval | 0.4961 | 127/256; exact 95% CI (0.4332, 0.5590) |
| Wrong role | 0.0078 | 2/256; exact 95% CI (0.0009, 0.0279) |
| Wrong event/graph zero | 0.0469 | 12/256; exact 95% CI (0.0245, 0.0804) |
| Random carrier | 0.0000 | 0/256; exact 95% CI (0.0000, 0.0143) |
Table 16.
Main claims, direct evidence, and boundaries.
Table 16.
Main claims, direct evidence, and boundaries.
| Claim | Direct Evidence | Supported Boundary |
|---|
| Q25 preserves 8192-token LM quality | 470 paired document windows; PPL ratio 1.00146, upper 95% bound 1.00161 | Supported for the tested 554M MHA backbone and Q25 export |
| Typed graph path is role sensitive | 1998/2000 typed versus 374/2000 untyped; wrong-role 0/2000 | Supported on the untouched controlled semantic set |
| Graph path replaced a localized-head capability | Corrected matched-capacity marginal intervals include zero in all three campaigns | Not established |
| Q25 is the optimum localization fraction | Q25 passed and one tested Q30 subset failed; solver gap 11.16% | Not established; Q25 is a demonstrated tested configuration |
| Persistent KV state is reduced | 25% fewer full-history heads; 21.875% fewer token-KV bytes before graph buffers | Supported for the measured 8192-token cache geometry |
| Complete natural system is faster | Synchronous compiler-inclusive throughput approximately 0.19× dense | Not supported |
| Result transfers to GQA, larger models, or longer contexts | One 554M MHA backbone at 8192 tokens | Not evaluated |
Table 17.
Negative results that bound the supported architecture. Ratios are candidate perplexity divided by dense perplexity.
Table 17.
Negative results that bound the supported architecture. Ratios are candidate perplexity divided by dense perplexity.
| Formulation | Key Result | Implication |
|---|
| Whole-layer graph-only R12 | 8192-token aggregate 1.3422; positions 4096–8191 ratio 1.7474 | Predicate graphs alone are not sufficient statistics for token prediction |
| Sparse residual tokens, | Oracle aggregate 1.3146; positions 4096–8191 ratio 1.6797 | Missing information is not concentrated in a small token subset |
| Fixed-basis kernel state | Max residual , but cross-window/language overlap 0.7053/0.6980 | Residual is locally low rank but its basis is nonstationary |
| Dynamic low-rank oracle | Best rank-32 aggregate 1.3745; positions 4096–8191 ratio 1.7531 | One bounded adaptive residual state does not recover the removed computation |
| Q30 head quotient | Aggregate 1.2317; positions 4096–8191 ratio 1.3781 | The observed head-level frontier is 25%, not 30% |
| Synchronous natural compiler | Approximately 0.19× dense throughput | Complete-system serving efficiency is not established |
| Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |