1. Introduction
The rapid growth of the scientific literature has increased the need for scalable methods to organize, explore, and synthesize research texts. Extracting semantic structure from large collections of scientific abstracts supports knowledge discovery, trend analysis, and efficient literature navigation. Large language models (LLMs) provide contextual representations capable of capturing latent semantic patterns, enabling tasks such as topic extraction, clustering, and semantic similarity analysis [
1].
Despite their potential, existing approaches often rely on full model fine-tuning [
2] or task-specific supervision, which can be resource-intensive and may not generalize well to exploratory analysis. In addition, scientific texts exhibit domain-specific terminology and stylistic diversity that challenge generic representation methods, leading to fragmented or noisy semantic spaces.
Soft prompt tuning [
3] provides an efficient alternative by learning lightweight embeddings that steer LLM representations without modifying the underlying model parameters. When applied to the scientific literature, soft prompts can encode both general language patterns and domain-specific terminology, enabling the model to capture meaningful semantic structure in an unsupervised manner. Furthermore, compositional or hierarchical prompt [
4] representations allow the integration of multiple levels of semantic information, supporting flexible downstream analyses such as clustering, topic discovery, and semantic normalization.
In this work, we propose a soft-prompt-based framework for the unsupervised analysis of scientific abstracts. Our approach leverages domain-aware embeddings and contrastive alignment objectives to produce consistent semantic representations across diverse corpora. The proposed method enables the effective semantic organization and exploratory analysis of the scientific literature without requiring task-specific labels or full model fine-tuning, providing a scalable and flexible tool for knowledge discovery in large textual datasets.
2. Related Work
LLMs have shown remarkable capability in capturing semantic patterns across diverse textual domains. Jiang et al. [
5] introduce FedPSF-LLM, a framework that combines prompt selection and dynamic weighting to improve model performance under non-IID data distributions, highlighting the potential of prompt-based adaptation for distributed textual representations. Wang et al. [
6] propose RoFed-LLM, integrating adaptive mechanisms for robust LLM training in distributed settings, while Djuhera et al. [
7] study resilient LLM embedding transmission over noisy communication channels. These works illustrate the utility of parameter-efficient tuning and prompts for controlling LLM behavior in decentralized environments.
In recommendation systems, LLMs combined with prompt or adapter mechanisms have been used to integrate textual and sequential information. Yuan et al. [
8] present FELLAS, using an LLM to provide sequence- and item-level representations, while applying sequence perturbation for privacy. Feng et al. [
9] propose T-GCN-LLM, a multi-topic graph convolutional approach incorporating textual item features. Qiang Wang et al. [
10] introduce FedITD, demonstrating privacy-preserving LLM adaptation for insider threat detection through local prompt and adapter tuning. Collectively, these studies show that LLM-based representations, guided by task-specific prompts or adapters, can encode structured knowledge from heterogeneous text sources.
LLMs have also been applied to domain-specific scientific and healthcare tasks. Priya et al. [
11] highlight diagnostic support using LLMs, incorporating multimodal data integration and privacy-preserving mechanisms. Habchi et al. [
12] review deep learning models, including LLMs, for cancer detection, emphasizing transfer and reinforcement learning to address limited labeled data. Other works explore NLP-based assessments in mental health [
13] and e-learning reviews [
14], demonstrating that LLMs can extract meaningful insights from distributed or sensitive scientific corpora.
Several studies address domain-specific NLP tasks with prompt or representation learning. Zaidani et al. [
15] examine dialect text classification using LLMs. North et al. [
16] survey transformer-based methods for lexical simplification, highlighting the role of prompt-based learning. Chen et al. [
17] propose AdaptForever, combining elastic and mutual learning to preserve knowledge across sequential NLP tasks with adapter tuning. Alkaoud [
18] develops semantic question similarity methods using embeddings, and Amin et al. [
19] describe few-shot transformer models for automated essay scoring.
Beyond application-specific studies, surveys and conceptual works outline broader LLM design and usage. Lou et al. [
20] review instruction-following capabilities of LLMs, while Kumar [
21] presents architectures, frameworks, and cross-domain applications. Pternea et al. [
22] propose a taxonomy of interactions between reinforcement learning and LLMs, and Du et al. [
23] explore distributed foundation models for multi-modal learning under computational constraints. These studies highlight the growing importance of structured representations, prompt design, and parameter-efficient adaptation for large-scale LLM deployment.
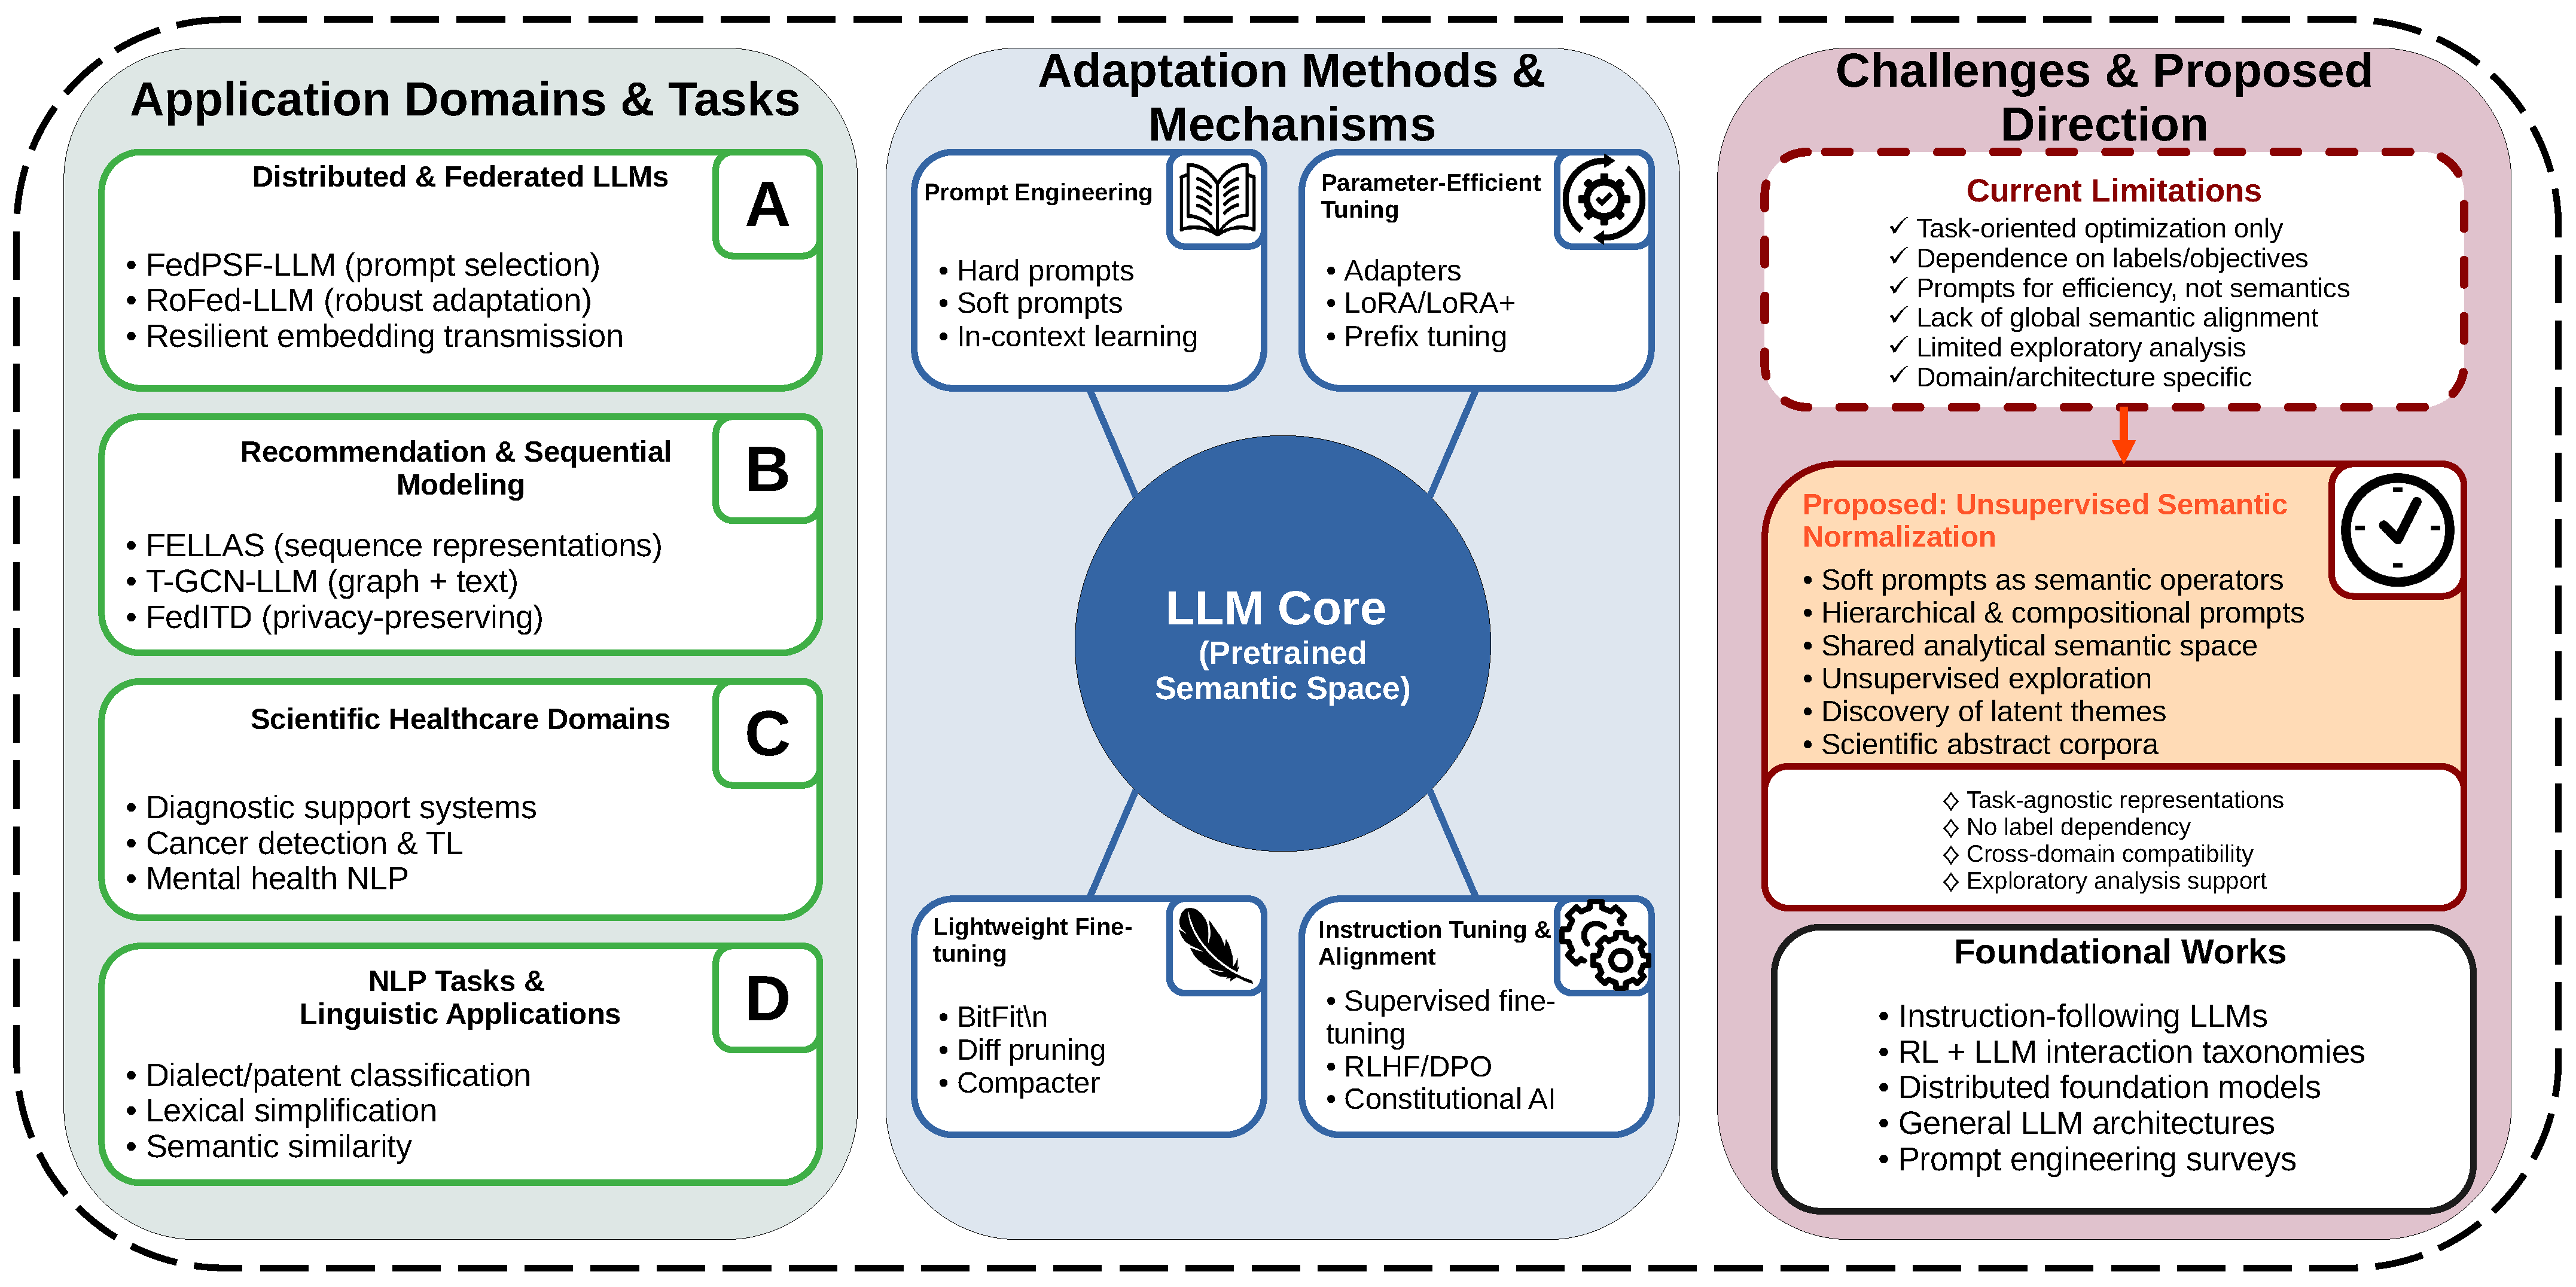
Existing approaches predominantly focus on task-oriented optimization, such as supervised prediction, recommendation, or domain-specific adaptation, treating prompts and adapters primarily as mechanisms for efficiency or local tuning. However, these methods provide limited support for the unsupervised exploratory analysis of the scientific literature, where the objective is to discover latent semantic structures, thematic relationships, and domain-specific patterns without predefined labels. Moreover, current techniques rarely consider prompts as hierarchical or compositional semantic operators capable of shaping a consistent analytical space across diverse scientific corpora. This gap motivates our approach, which leverages soft prompt tuning for unsupervised semantic normalization and the exploratory analysis of scientific abstracts. The research landscape outlined above is conceptually organized in
Figure 1, illustrating the progression from task-specific adaptations to the semantic challenges addressed by our approach.
3. Method
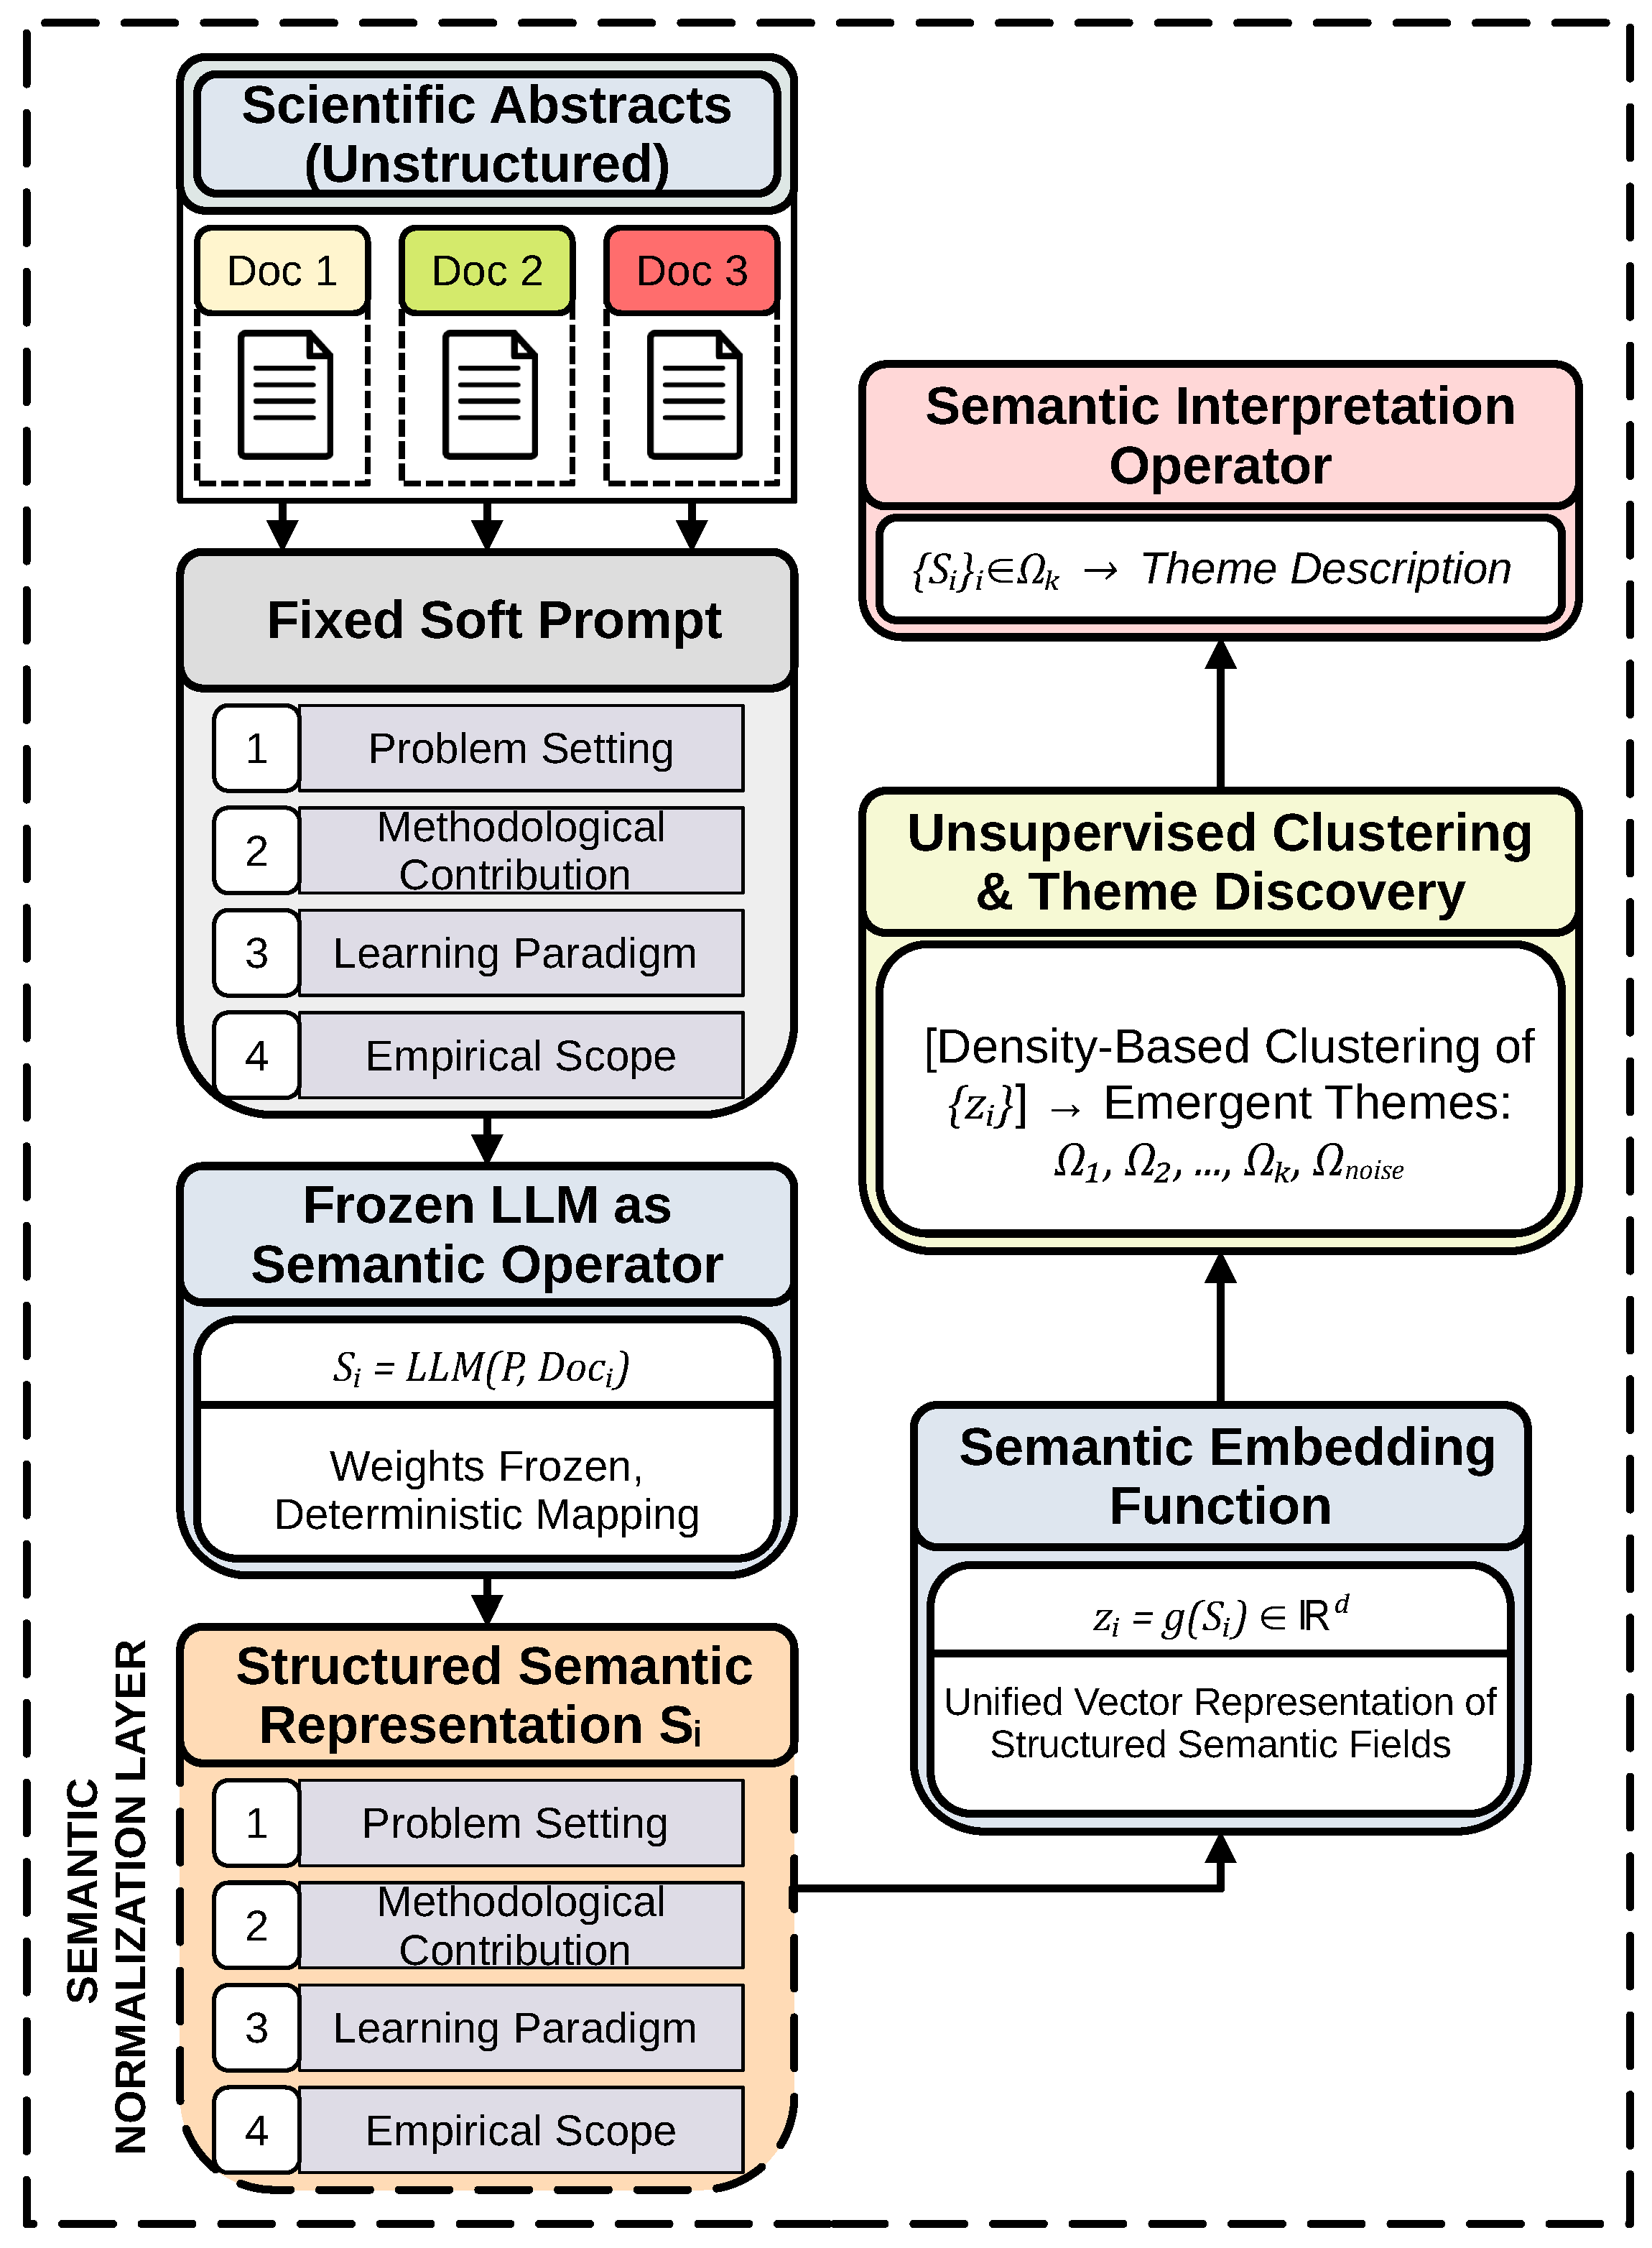
This section describes a prompt-driven semantic analysis framework for the large-scale unsupervised understanding of the scientific literature. The framework treats a pretrained LLM as a fixed conditional inference operator and relies on structured prompting rather than gradient-based adaptation. The central premise is that scientific abstracts can be projected into a normalized semantic representation that admits principled geometric analysis in a continuous embedding space.
Figure 2 shows a diagram of the proposed soft-prompt-based semantic analysis framework.
3.1. Problem Formulation
Let
denote a corpus of
N scientific abstracts, where
is the space of natural language documents over a finite vocabulary. Each abstract
is assumed to be generated from an underlying latent semantic configuration that encodes multiple conceptual attributes.
Formally, let
denote an unobserved semantic variable associated with
, where
represents latent factors corresponding to problem formulation, modeling paradigm, methodological contribution, and empirical scope, respectively. The observable text
can be interpreted as a stochastic realization drawn from a conditional distribution
which introduces lexical and stylistic variability that may obscure the underlying conceptual structure.
The goal is to recover a latent thematic organization of the corpus in the absence of supervision. Specifically, the objective is to infer a partition
such that each subset
corresponds to a coherent research theme characterized by shared structure in the latent space
.
Equivalently, the problem may be expressed as identifying a surjective assignment function
where
indicates that abstract
belongs to theme
. The number of themes
K is not fixed a priori and is treated as an emergent property of the corpus geometry. No labeled data, predefined taxonomy, or supervised objective is assumed; thus,
must be inferred solely from structural regularities induced by semantic similarity [
24] among
.
The problem can therefore be interpreted as unsupervised recovery of latent semantic clusters under unknown and potentially non-uniform theme distributions.
3.2. LLM as a Fixed Conditional Semantic Operator
Let
denote a pretrained autoregressive language model conditioned on a fixed prompt
. The prompt
is treated as a structured conditioning variable that encodes (i) an analytical perspective, (ii) a constrained output schema, (iii) an implicit abstraction level. Formally, the prompt defines a conditional distribution
where
is an abstract and
denotes the frozen model parameters.
Given an abstract
, a structured semantic representation is obtained via conditional generation:
where
denotes the subset of outputs that satisfy the schema imposed by
. In practice, low-temperature decoding [
25] is employed so that
approximates a deterministic operator.
The representation space
is constrained to structured tuples
where each component corresponds to a semantically grounded dimension of scientific discourse. Specifically,
encodes the formal or conceptual problem formulation,
captures the learning or modeling paradigm,
represents the principal methodological contribution, and
describes the empirical or application context.
The prompt
is fixed for all
and no parameter update is performed, i.e.,
where
denotes the pretrained parameters. Consequently, the mapping
is purely induced by conditioning and not by corpus-specific optimization [
26]. This design ensures that
functions as a semantic projection operator rather than an adaptive learner. The abstraction properties of the mapping are therefore attributable to prompt-induced structural constraints and to the pretrained knowledge encoded in
, rather than to supervised fine-tuning on the target corpus.
3.3. Semantic Normalization as Invariance Induction
Scientific abstracts exhibit substantial lexical, syntactic, and stylistic variability. Such variability may arise from author preferences, subfield conventions, or narrative structure, and is often orthogonal to the underlying conceptual contribution.
The structured mapping
is interpreted as a semantic normalization operator that induces invariance to surface-level linguistic variation. Formally, consider two abstracts
and
describing conceptually similar contributions but expressed using different terminology. Let
denote a lexical or surface-level dissimilarity measure and
a semantic distance in representation space. The normalization hypothesis assumes that
whenever
and
share the same conceptual structure.
Under this interpretation, soft prompting [
27,
28] functions as a structured information bottleneck: it suppresses stylistic degrees of freedom while preserving high-level semantic attributes relevant for thematic organization. This abstraction step is critical for ensuring that downstream clustering reflects research content rather than writing style.
3.4. Embedding-Induced Semantic Geometry
Each structured representation
is mapped to a continuous vector space through a pretrained embedding function
where
denotes the embedding dimensionality. The mapping
g is fixed and independent of the corpus
.
To ensure comparability of magnitudes and to align cosine similarity with Euclidean geometry [
29], embeddings are optionally normalized as follows:
Under this normalization, cosine similarity reduces to an inner product,
and Euclidean distance satisfies
The collection
induces a metric space
with pairwise distance matrix
This metric defines a geometric structure in which local neighborhoods
approximate sets of semantically related scientific contributions.
Under the semantic normalization assumption, the embedding map approximates a Lipschitz continuous transformation [
30] with respect to latent semantic variables
, i.e.,
for some constant
, implying that proximity in latent conceptual space is preserved in
. Consequently, regions of high point density in embedding space correspond to subsets of abstracts sharing similar problem formulations, modeling paradigms, methodological principles, or empirical contexts.
The embedding stage therefore realizes a mapping from a discrete textual domain to a continuous geometric manifold , where thematic structure can be characterized using metric, topological, and density-based operators. This geometric representation enables unsupervised recovery of latent themes through analysis of spatial concentration and connectivity patterns.
3.5. Density-Based Unsupervised Theme Discovery
Given , theme discovery is formulated as a density-based clustering problem. Rather than assuming spherical clusters or a fixed number of partitions, the framework assumes that research themes manifest as regions of varying density in embedding space.
Let
denote a local density estimate in
. Clustering aims to recover connected high-density components:
where
represents a dense region corresponding to a latent research theme;
captures low-density points interpreted as outliers, interdisciplinary works, or emerging directions.
Density-based clustering [
31] accommodates clusters with non-convex geometry and heterogeneous scale, properties that are consistent with the structure of scientific research landscapes. Large, established subfields typically correspond to extensive high-density regions, whereas niche or emerging topics form smaller but coherent clusters.
3.6. Semantic Decoding and Theme Interpretation
Clusters in embedding space are geometric objects and are not inherently interpretable. To map geometric structure back to human-readable scientific concepts, a semantic interpretation operator is introduced.
For each cluster
, the set of structured representations
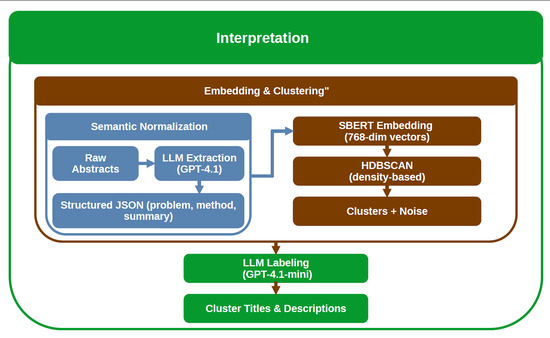
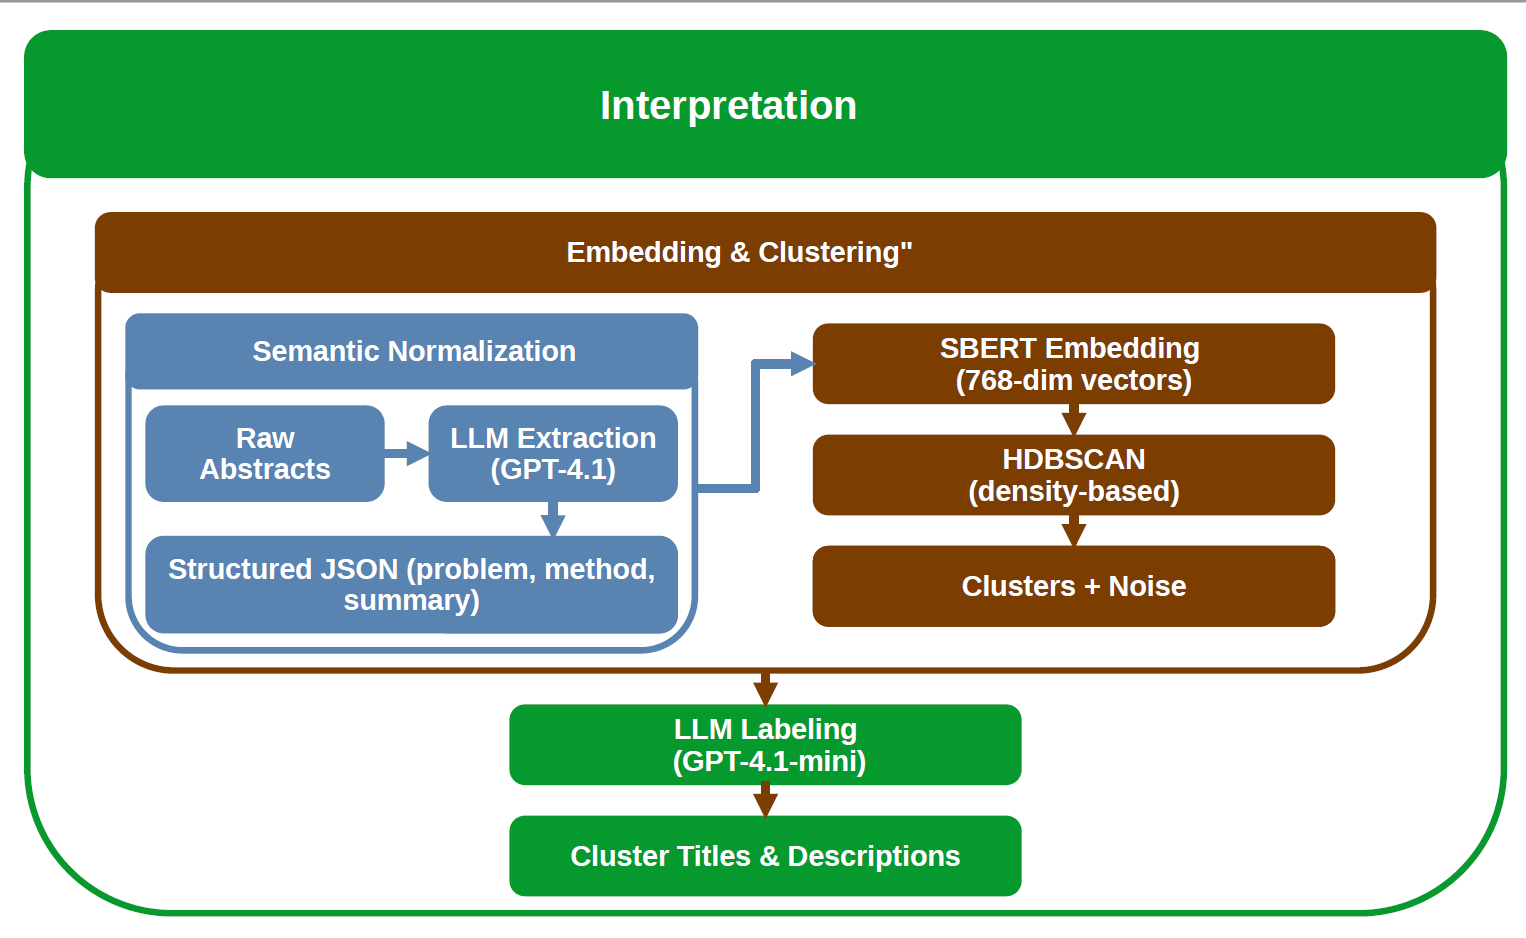
is aggregated and provided to an LLM-based decoder conditioned on a fixed interpretative prompt. The decoder produces a concise thematic label, descriptive title, and short narrative summarizing the shared research direction.
This step can be interpreted as a semantic compression operator
where
is a low-dimensional textual summary of the cluster’s conceptual core.
4. Experiments
4.1. Dataset and Motivation
In this study, we analyze the abstracts of papers accepted to the International Conference on Machine Learning [
32] (ICML) 2025. ICML is widely regarded as one of the flagship venues in machine learning research, covering a broad spectrum of topics ranging from theoretical foundations and optimization to large-scale systems and applications. As such, the ICML corpus provides a representative snapshot of contemporary research directions and emerging trends in the machine learning community.
We focus on abstracts rather than full papers for three reasons. First, abstracts are the primary medium through which research contributions are communicated and indexed in large-scale scholarly databases. Second, abstracts provide a concise yet structured summary of problem settings, methodological contributions, and empirical scope, making them suitable for scalable automated analysis. Third, restricting the analysis to abstracts allows for uniform processing across a large number of papers without introducing confounding factors related to paper length or section organization.
4.2. LLM-Based Structured Paper Analysis
Each paper abstract was processed using the LLM via a structured soft prompting pipeline designed to emulate the evaluation perspective of an ICML reviewer. The LLM employed in this step was gpt-4.1-mini, with deterministic sampling (temperature set to 0.0). The pipeline followed a multi-level prompting strategy:

Formally, for each paper abstract
, the model produces a structured JSON object
where
denotes the fixed system, instruction, and schema prompts shown above. The output
contains normalized fields such as problem setting, method class, core contribution summary, and a one-sentence summary.
This approach serves two key purposes:
- 1.
It reduces unstructured natural language into a consistent semantic representation across all papers, mitigating stylistic and lexical variability.
- 2.
It injects domain knowledge through prompt design, guiding the model to emphasize aspects salient for conference-level evaluation rather than superficial text features.
4.3. Secondary Normalization via Prompt Refinement
Although the first-stage LLM extraction yields structured JSON representations, minor stylistic variability and paraphrasing effects remain across papers. Since the downstream embedding step operates on concatenated semantic fields, even small inconsistencies in phrasing may introduce unwanted variance in the vector space.
To address this, we applied a second-stage normalization procedure. In this stage, the LLM receives the previously generated JSON representation and is instructed to re-extract a reduced and strictly standardized subset of attributes under a more constrained schema. The goal of this step is normalization rather than information extraction: no new semantic content is introduced, and only lexical and structural consistency is enforced.
4.3.1. Model and Decoding Configuration
The secondary normalization stage uses the same base LLM as the primary extraction stage, namely
GPT-4.1 [
33] (OpenAI API, January 2025 snapshot), to avoid distributional inconsistencies introduced by heterogeneous generators. Decoding was performed using deterministic generation to enforce reproducibility and suppress the stylistic variability introduced by stochastic sampling. Greedy decoding [
34] was obtained by setting the temperature to
and top_p = 1.0, ensuring that token selection followed the maximum likelihood path without probabilistic truncation of the distribution. Frequency and presence penalties were fixed at zero to prevent artificial lexical diversification, since the objective of the normalization stage is canonicalization rather than variation. The generation length was limited to max_tokens = 256, which is sufficient to cover all normalized schema fields while constraining unnecessary paraphrastic expansion.
Under this configuration, the normalization step behaves as a deterministic operator
so identical structured inputs yield identical normalized outputs. Consequently, observed differences in clustering quality cannot be attributed to sampling randomness but instead reflect structural changes introduced by schema-constrained semantic normalization.
Greedy decoding was intentionally used because the task requires canonicalization rather than generative diversity. Under these settings, repeated runs produced identical outputs for identical inputs, ensuring stable normalization.
A representative second-stage prompt is shown below:

Formally, the refinement step is defined as
where
denotes the normalization prompt and
represents the fixed decoding configuration specified above.
The resulting normalized fields are concatenated to form the semantic text
which serves as input to the embedding model.
4.3.2. Alternative Model Robustness Check
To assess whether the observed normalization effect is tied to a language model or instead arises from the schema-constrained transformation itself, we repeated the secondary normalization stage using an alternative instruction-tuned model (
Llama-3-70B-Instruct [
35]) while keeping the prompt, decoding configuration, embedding model, clustering algorithm, and evaluation pipeline unchanged. This controlled substitution isolates the generator as the only varying component of the pipeline.
Let
and
denote normalization operators induced by two different models. If clustering improvements were driven primarily by model-specific stylistic preferences, the resulting embedding distributions would diverge, leading to measurable degradation or instability in cluster validity indices. Instead, embeddings obtained from normalized texts generated by both models produced nearly identical clustering outcomes (
Section 4.4), with differences confined to
for the silhouette coefficient and
for the Davies–Bouldin index.
Given that these deviations are substantially smaller than the performance gap observed between raw and normalized representations, the normalization process can be interpreted as approximately model-invariant,
with respect to downstream embedding geometry. This indicates that the improvement originates from enforcing a shared semantic schema that reduces non-semantic variance, rather than from stylistic biases or latent preferences of a specific LLM.
4.3.3. Rationale for Model Allocation Across Stages
Different stages of the pipeline impose requirements. The primary extraction stage prioritizes semantic recall [
36] and structured parsing from heterogeneous abstracts, while the secondary stage performs constrained canonicalization under a fixed schema. Using the same LLM with deterministic decoding ensures semantic consistency between stages while preventing additional variability introduced by stochastic generation or model mismatch. The embedding stage is intentionally decoupled from the normalization model, ensuring that clustering results depend on the normalized representation rather than on generator-specific embedding alignment.
This two-stage prompting strategy can therefore be interpreted as a form of controlled semantic denoising [
37]: the first stage extracts structured meaning from natural language text, and the second stage enforces schema alignment and lexical regularity. Empirically, this reduces phrasing variability and stabilizes embedding geometry without introducing additional semantic bias.
4.4. Semantic Text Construction and Embedding
For each paper i, a compact semantic text was constructed by concatenating three normalized fields: the formal problem formulation, the structured description of the core methodological contribution, and the one-sentence summary. Let denote the resulting text sequence after preprocessing (lowercasing preserved, no stop-word removal applied, maximum length truncated to 512 tokens to match model constraints).
Dense vector representations were computed using the
sentence-transformers/all-mpnet-base-v2 model from the Sentence-Transformers library (v2.2.2) implemented in PyTorch (v2.1). This model belongs to the SBERT (Sentence-BERT) [
38,
39] family and was selected due to its strong empirical performance on semantic textual similarity benchmarks and its suitability for sentence- and paragraph-level representations. The encoder produces fixed-length embeddings of dimensionality
.
Inference was performed in evaluation mode with gradient computation disabled. Default tokenizer settings were used, and no task-specific fine-tuning was applied in order to preserve model generality and avoid corpus-specific adaptation.
In addition to standalone SBERT-based embeddings, we also employed the BERTopic [
40] framework for topic-aware document representations. BERTopic leverages transformer-based sentence embeddings as an initial semantic space and combines them with dimensionality reduction and density-based clustering to induce coherent topic structures.
Within this pipeline, SBERT embeddings serve as the underlying semantic encoder, after which dimensionality reduction and clustering are applied to construct topic representations. This approach enables the extraction of semantically coherent topic groupings while preserving contextual information captured by the transformer-based embeddings.
4.5. Unsupervised Clustering
Clustering was performed using the
hdbscan [
41] Python package (v0.8.33). HDBSCAN was chosen due to its ability to detect clusters of varying density, its robustness to noise, and its non-parametric determination of the number of clusters.
Pairwise distances were computed using Euclidean distance on normalized embeddings:
The
eom (excess of mass) cluster selection [
42] method favors clusters with higher stability over hierarchical persistence, which improves the interpretability of dense regions in the embedding space.
No manual reassignment or merging of clusters was performed after algorithm execution. The algorithm produced labels
where
K was inferred automatically and
denoted noise points corresponding to low-density or weakly connected papers.
To complement embeddings-based clustering [
43], an analogous pipeline was applied to TF-IDF representations of the same abstracts:
where
is the semantic text constructed from the abstract. Pairwise distances were computed using the cosine metric, which better captures similarity in high-dimensional sparse spaces.
To systematically explore the hyperparameter space
, a multi-objective optimization using NSGA-II [
44] was performed. The objectives were to maximize the silhouette score [
45]
S and minimize the Davies–Bouldin index [
46]
, computed on clustered points:
where
X denotes the embedding or TF-IDF matrix [
47]. The NSGA-II algorithm produced a set of Pareto-optimal solutions [
48] representing the trade-off between cluster cohesion and separation.
From the Pareto front, a single “best” configuration was selected using a knee-point criterion, corresponding to a compromise where improvements in silhouette would lead to disproportionate increases in DB, or equivalently where the ratio
is minimized to chose hyperparameters with compact, well-separated clusters with meaningful coverage of the dataset.
4.6. Cluster-Level Topic Assignment via LLMs
To generate interpretable semantic labels for each discovered cluster, we employed the large language model GPT-4.1-mini [
49] with
temperature = 0.0 and
max_tokens = 500. For every cluster, the model received as input the titles and one-sentence summaries of the papers assigned to that cluster. The LLM was instructed to output a short title (3–6 words), a long descriptive title (1 sentence), and a brief description (2–3 sentences) characterizing the research trend represented by the cluster.
The system prompt used for all clusters was placed in a highlighted box to clarify the instructions provided to the model:

For each cluster, the user prompt consisted of a formatted list of the papers in that cluster, for example:

The model responses were parsed as JSON [
50] and stored in
cluster_summaries.json, with each cluster entry containing its short title, long title, and description. This procedure ensures reproducibility, explicit specification of the model and prompt, and a direct link between discovered clusters and interpretable semantic labels.
These LLM-generated labels were used solely for visualization and interpretability, such as annotating t-SNE [
51] plots, and do not influence the clustering process itself. The actual clusters were determined independently using either semantic embeddings or TF-IDF representations.
4.6.1. Independence of Interpretation from Normalization
The LLM used for cluster labeling is the same model family as employed in the normalization stages (
GPT-4.1-mini) [
52]; however, the labeling procedure operates strictly post hoc and does not participate in representation construction, embedding generation, clustering, or hyperparameter optimization. Formally, clustering produces assignments
where
denotes the HDBSCAN operator applied to embeddings
. The labeling stage is subsequently defined as an interpretation mapping
which depends only on already fixed cluster memberships. Consequently, cluster structure is invariant to the labeling model,
ensuring that interpretation cannot influence clustering outcomes.
4.6.2. Alternative Interpretation Strategy
To test whether cluster interpretation depends on the specific LLM used for labeling, we introduced an independent non-LLM interpretation baseline [
53] derived directly from cluster content. For each cluster
, lexical descriptors were constructed using TF-IDF statistics computed over the
original raw abstracts, thereby removing any influence of semantic normalization or LLM-generated intermediate representations.
Let
denote the vocabulary restricted to documents assigned to cluster
k. For each term
, a cluster salience score was defined as
which estimates the expected lexical importance of the term within the cluster. The highest-scoring terms were used to construct keyword-based topic descriptors representing an entirely model-independent interpretation layer.
Agreement between LLM-generated labels and TF-IDF descriptors was evaluated by measuring semantic overlap [
54] between keyword sets extracted from both representations. Across clusters, the majority of high-salience terms identified by TF-IDF appeared explicitly or implicitly in LLM-generated titles and descriptions, indicating consistent thematic characterization. Importantly, because TF-IDF labeling operates directly on raw abstracts and does not use normalized semantic text, embeddings, or LLM outputs, the interpretation process forms an independent observational probe of cluster structure.
Formally, letting
and
denote labels obtained from the LLM and lexical baseline respectively, both can be viewed as functions of fixed cluster memberships,
with no dependence on the normalization operator. The observed agreement therefore indicates that semantic interpretations arise from intrinsic structure in the clustered data rather than from a closed-loop interaction between normalization and labeling prompts. This supports the claim that LLM-based labeling acts purely as a post hoc interpretability mechanism and does not introduce narrative bias into the analytical pipeline.
4.7. Visualization
Finally, the high-dimensional embedding space was projected into two dimensions using t-SNE for visualization purposes. Cluster assignments and LLM-generated cluster labels were overlaid on the projection. For each cluster, a convex hull was drawn to illustrate its spatial extent in the projected space, providing an intuitive depiction of thematic regions and their overlap.
5. Results and Analysis
5.1. Thematic Landscape of Machine Learning Research
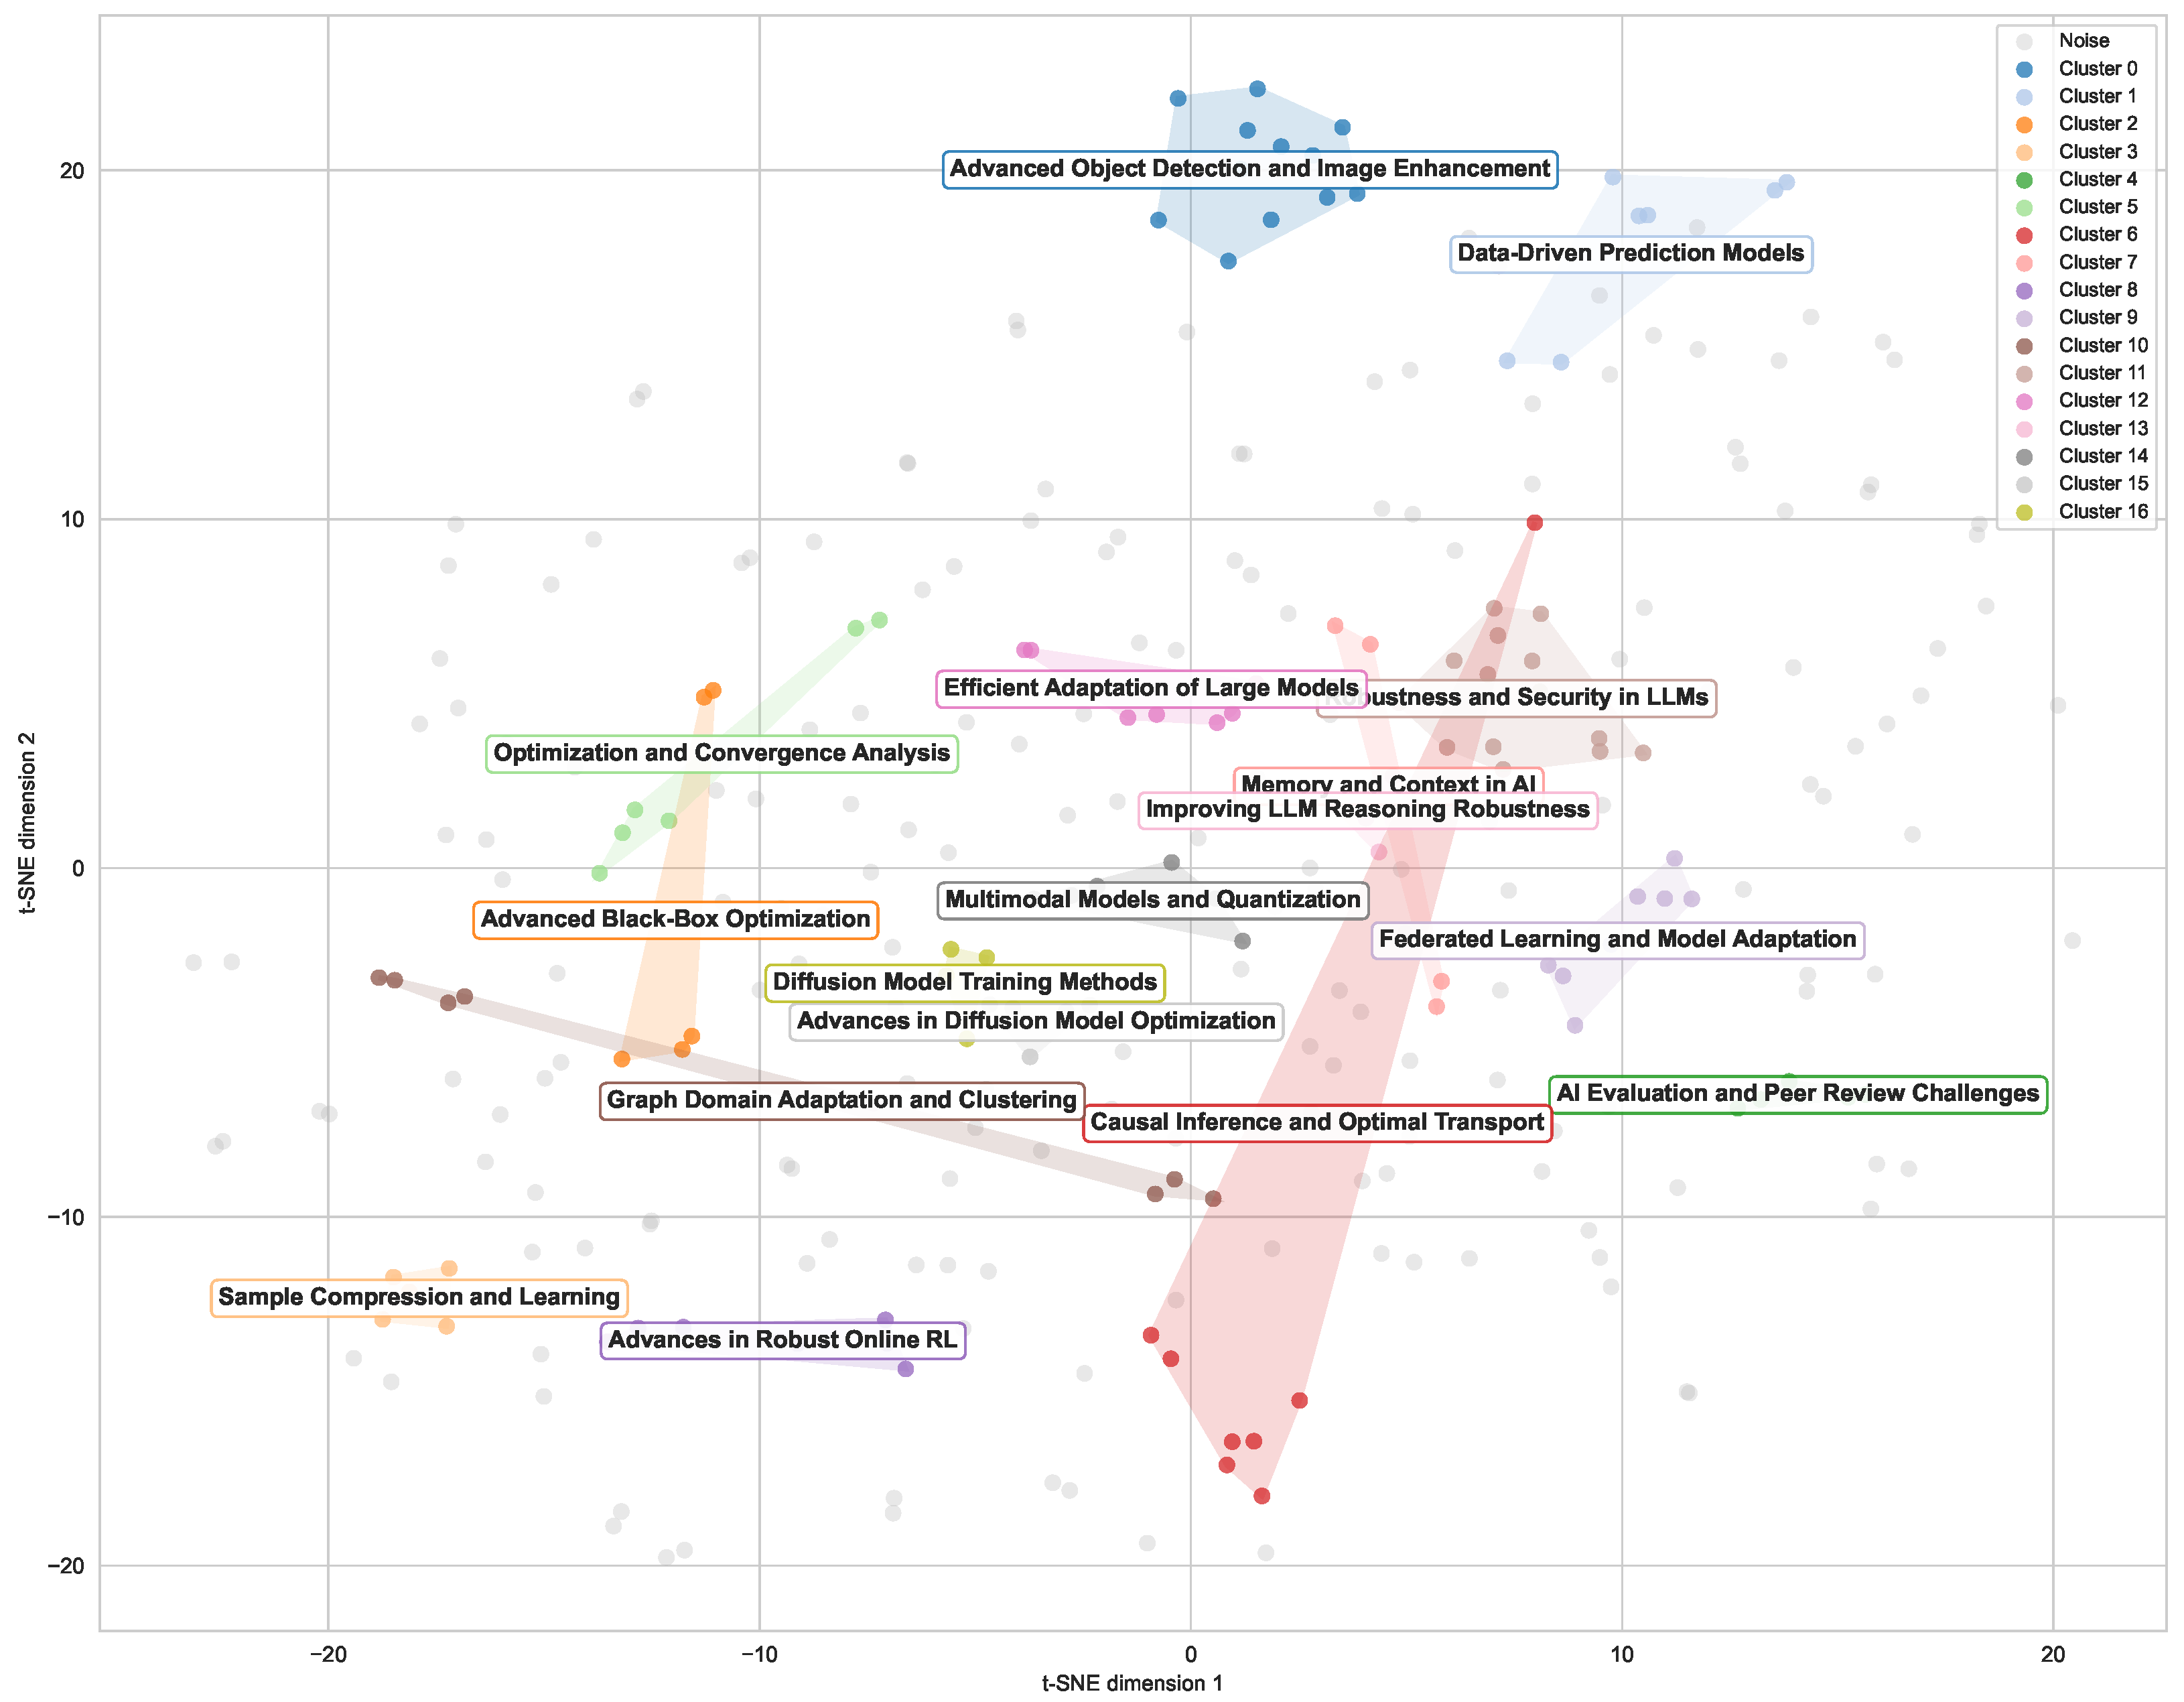
Figure 3 visualizes the semantic embedding space of ICML 2025 abstracts using t-SNE, with HDBSCAN-derived clusters representing coherent research themes across theoretical, methodological, and applied directions. One prominent theme concerns sample compression and learning (Cluster 3) [
55], highlighting advances in ensemble methods, boosting, and sparse recovery techniques that improve learning efficiency and robustness, particularly in multiclass and high-dimensional settings. Closely related are studies on optimization dynamics and convergence (Cluster 5) and black box optimization [
56] (Cluster 2), which provide theoretical insights into gradient-based methods, stochastic approximation, and meta-learning strategies for high-dimensional or combinatorial problems.
In the domain of sequential decision-making, robust online reinforcement learning [
57] (Cluster 8) addresses stability, safety, and convergence under uncertainty, combining actor–critic methods, risk-sensitive learning, and adversarial training to ensure a reliable policy performance across variable environments. Parallel to this, causal inference and robust learning [
58] (Cluster 6) leverage optimal transport and ensemble frameworks to generalize causal effects, tighten bounds, and mitigate confounding bias without requiring strict data partitioning, offering robust decision-making under distributional shifts.
Large language and multimodal models form another major research axis. Clusters focused on memory and contextual understanding [
59] (Cluster 7) and improving LLM reasoning robustness (Cluster 13) investigate mechanisms for isolating memorization, token-level contrastive learning, reflective self-correction, and intermediate representation comprehension. These approaches aim to enhance interpretability, generalization, and multi-step reasoning in both LLMs and vision–language systems. Complementary to this, clusters on the efficient adaptation of large models (Cluster 12) and federated learning [
60] and model personalization (Cluster 9) explore parameter-efficient fine-tuning, pruning, quantization, and prompt-based adaptation in distributed settings, emphasizing computational scalability and data privacy.
Generative modeling constitutes a further thematic direction. Diffusion model optimization [
61] and training (Clusters 15 and 16) focus on preference alignment, score-based training, distillation, and the theoretical analysis of generalization, highlighting strategies to improve the efficiency, interpretability, and control of generative outputs. Similarly, multimodal model generalization and quantization [
62] (Cluster 14) addresses video diffusion, causal generation, and adaptive quantization to optimize alignment and reduce computational cost in multi-modal systems.
Applied methodologies in object detection and image enhancement (Cluster 0), graph representation and domain adaptation (Cluster 10), and data-driven predictive modeling (Cluster 1) demonstrate the integration of deep learning with practical problem-solving, spanning vision, graph-structured data, and domain-specific prediction tasks. AI evaluation and peer review challenges (Cluster 4) emphasize methodological rigor, metric limitations, and systemic challenges, underscoring the importance of reliable evaluation in both research reproducibility and benchmark design.
5.2. TF-IDF Clustering and Controlled Comparison of Semantic Normalization
To evaluate the role of representation choice and to directly test the hypothesis that semantic normalization reduces linguistic and stylistic variability, we conducted a set of complementary clustering experiments using identical datasets and evaluation procedures. The analysis included both a classical lexical baseline based on TF-IDF representations and a controlled comparison between embeddings computed from raw abstracts and embeddings derived from semantically normalized text.
As a non-semantic reference, clustering was first performed on TF-IDF representations of the ICML 2025 abstracts. Each semantic text
was converted into a sparse vector
where
after removing extremely rare and overly frequent terms (min_df = 3,
max_df = 0.9) and considering both unigram [
63] and bigram [
64] features. Cosine distance was employed due to its suitability for sparse high-dimensional spaces. Clustering was performed using HDBSCAN, while hyperparameters
were optimized via NSGA-II to simultaneously maximize the silhouette score
S and minimize the Davies–Bouldin index
,
resulting in a Pareto front of 50 candidate solutions.
The knee-point solution [
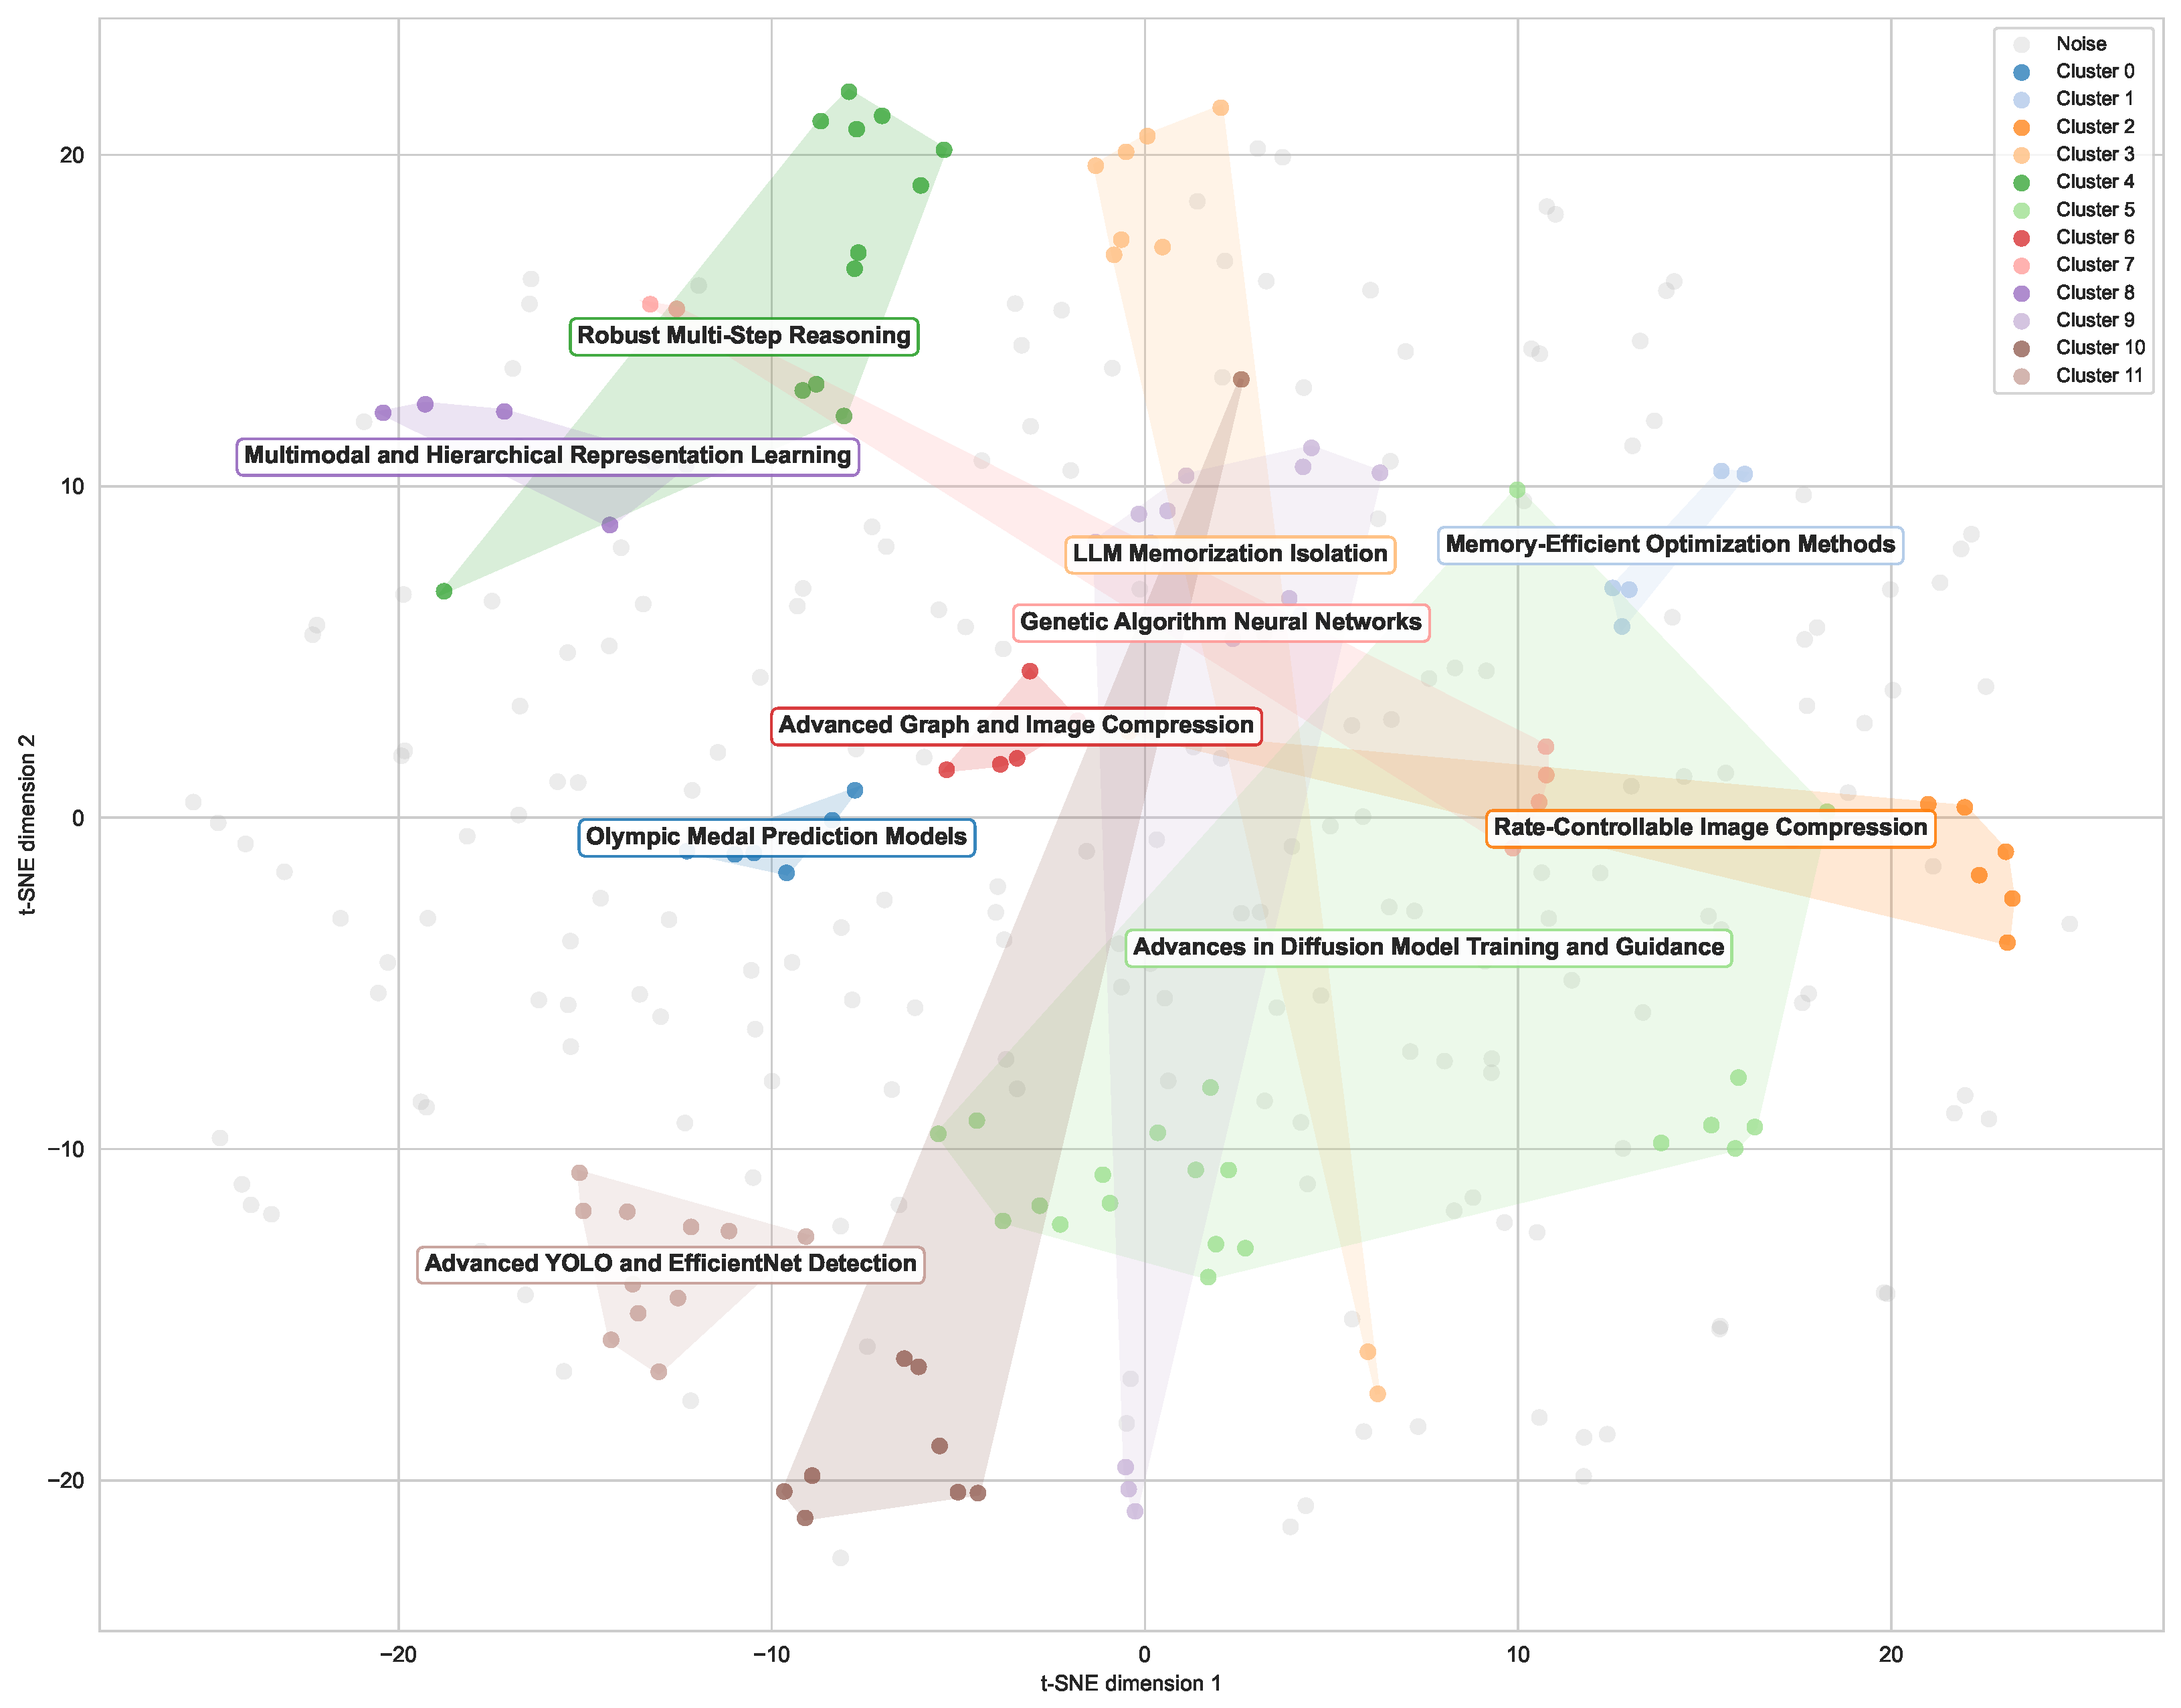
65] produced 12 clusters with sizes ranging from five to 21 papers. The discovered groups corresponded to recognizable research themes such as diffusion model optimization, large model adaptation and federated learning, and LLM memorization analysis, indicating that lexical statistics alone can partially recover topical structure. A two-dimensional projection of TF-IDF clusters obtained using t-SNE is presented in
Figure 4.
Quantitative evaluation indicates that embeddings derived from semantically normalized text produce systematically more compact and better-separated clusters than embeddings computed from raw abstracts. Let
denote embeddings of raw abstracts and
embeddings obtained after semantic normalization. For a clustering assignment
, cluster compactness can be expressed through the expected intra-cluster dispersion
where
is the centroid of cluster
. Semantic normalization reduces lexical and stylistic variability that does not correspond to conceptual differences, which empirically results in a contraction of intra-cluster variance [
66],
while preserving semantic relations between documents. At the same time, inter-cluster separation [
67],
remains stable or increases slightly, indicating improved discriminability between thematic groups. This combination increases the effective signal-to-noise ratio of the embedding space and stabilizes density estimation, which is particularly important for density-based clustering algorithms such as HDBSCAN.
These geometric changes are reflected in standard cluster validity indices. The silhouette coefficient,
where
and
denote mean intra- and nearest-cluster distances, increases when normalized embeddings are used, indicating improved local neighborhood consistency. Similarly, the Davies–Bouldin index,
decreases due to reduced cluster dispersion
relative to centroid separation.
Empirically, the TF-IDF configuration achieved and , whereas embeddings-based clustering produced and . When comparing embeddings computed from raw and normalized text under identical clustering settings, normalized embeddings consistently yielded higher silhouette values and lower Davies–Bouldin scores. This indicates that semantic normalization contributes independently to clustering quality by reducing non-semantic variance rather than merely benefiting from the embedding model itself.
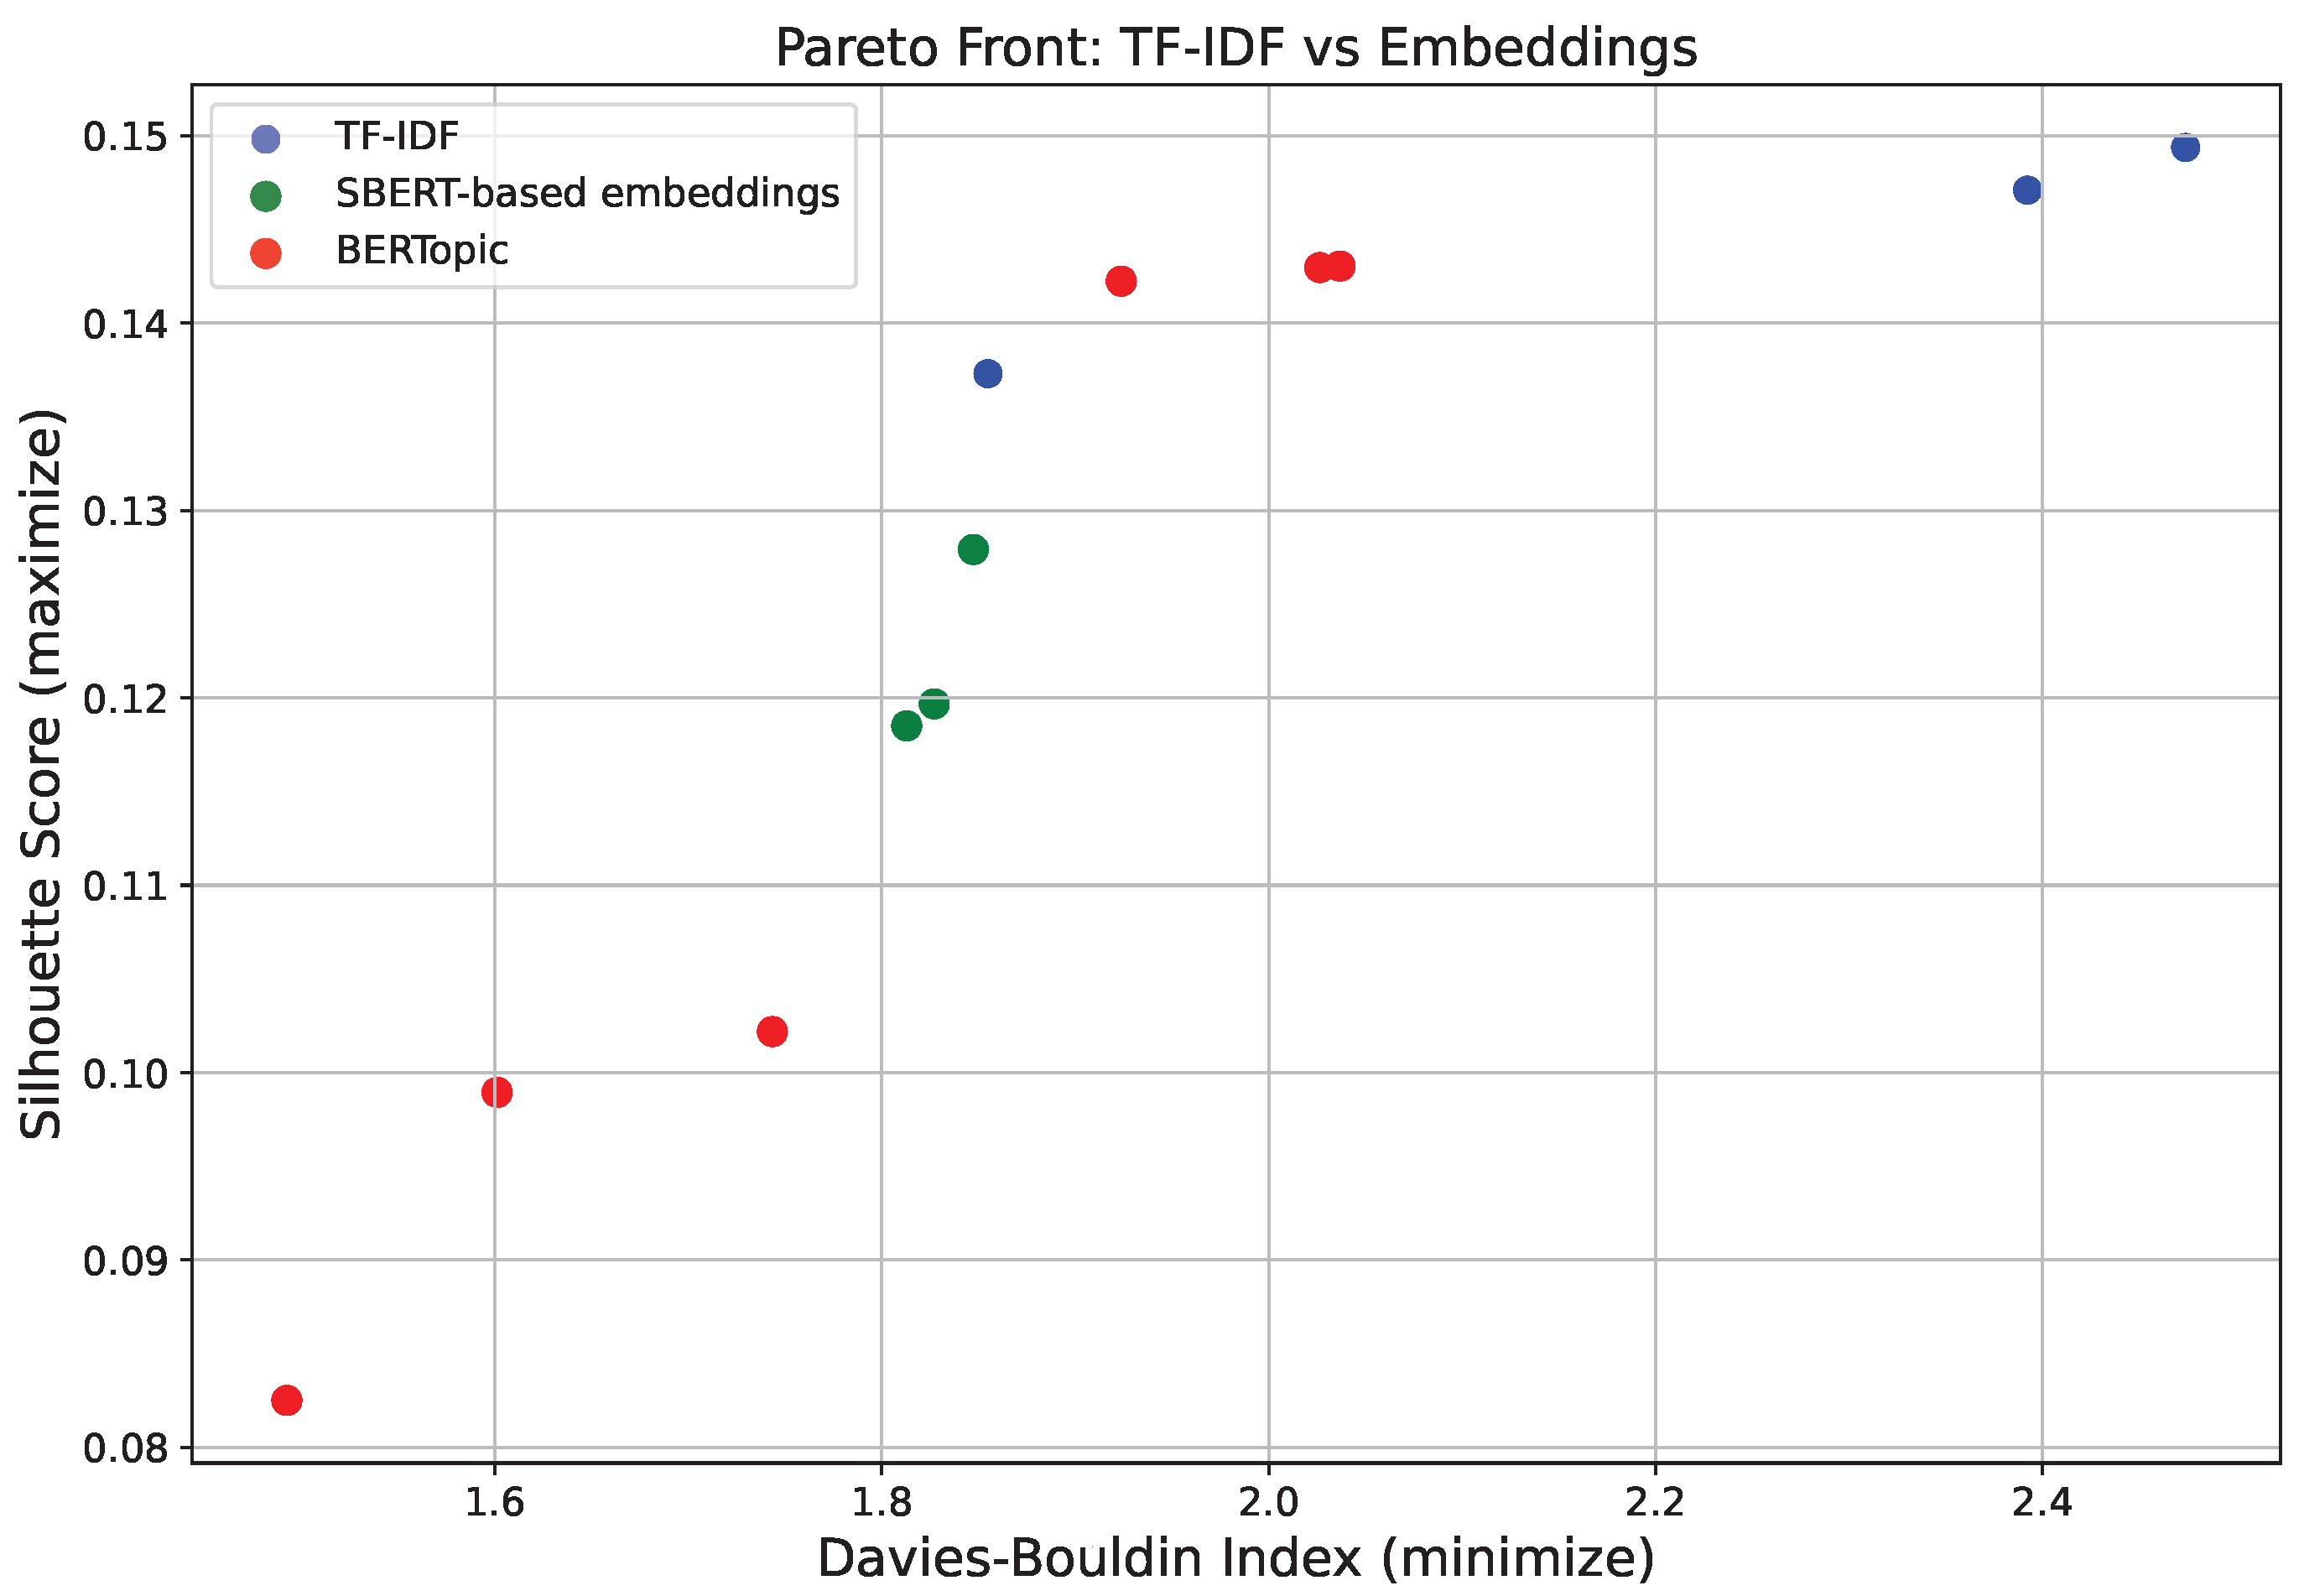
The Pareto fronts obtained during hyperparameter optimization for both TF-IDF and embedding-based representations are shown in
Figure 5. The distributions illustrate the trade-off between cluster cohesion and separation across configurations, with optimal solutions selected using the knee-point criterion balancing silhouette maximization and Davies–Bouldin minimization.
5.3. Clustering Analysis of ACL 2025 Papers
For further evaluation of the clustering approach on a different source of data, the model was applied to the corpus of ACL 2025 papers. Unlike the ICML-like corpus, ACL exhibits a pronounced applied focus within natural language processing, with a strong presence of works on LLM evaluation, multilinguality, and alignment, providing a useful test for the generalizability of the embedding-based representation. Clustering using HDBSCAN with parameters (also obtained using NSGA II) min_cluster_size = 2
and min_samples = 3 produced eight interpretable clusters. One cluster grouped papers related to mathematical reasoning, backdoor attacks, the interpretability of in-context learning, cross-lingual factual inconsistencies, robustness to incorrect multiple-choice options, and the comparative evaluation of LLM-as-a-judge, reflecting an emphasis on model reasoning and reliability. Another cluster included works on data-efficient evaluation, planning with language models, garden path effects, and evaluations of Portuguese and Sinhala language models, capturing the focus on model assessment across linguistic and cognitive scenarios. A separate cluster contained papers dedicated to benchmarks such as GUIDEbench, BIG-Bench Extra Hard, GUESSARENA, and CFBench, illustrating the benchmark-driven evaluation direction. Additional clusters highlighted research on reward modeling and alignment, efficiency and knowledge boundaries, faithfulness in rationale generation and retrieval-augmented reasoning, tool-augmented LLM agents, and social aspects including bias and fairness.
Quantitative evaluation revealed a silhouette score of and a Davies–Bouldin index of for the ACL 2025 clustering. Comparing this with the ICML abstracts, the lower Davies–Bouldin index indicates more compact and better-separated clusters, suggesting that semantic embeddings capture conceptual similarity more effectively than raw TF-IDF vectors. The ACL corpus is characterized by high thematic coherence, with respect to evaluation and alignment topics, which naturally reduces inter-cluster distances and affects silhouette measurements.
6. Discussion
The structured LLM-based semantic normalization pipeline projects abstracts into a continuous embedding space where latent conceptual variables, including problem formulation, methodological contributions, and empirical context, are explicitly represented. Two-stage prompting, comprising initial extraction followed by refinement, reduces lexical variability and enforces schema consistency, producing embeddings suitable for density-based clustering with HDBSCAN, which detects non-convex, variable-density clusters without a predefined number of topics.
Soft prompting functions as a semantic normalization mechanism rather than model adaptation, with fixed prompts and structured output schemas constraining LLMs to emphasize conceptual content over linguistic form [
68]. The resulting embedding space exhibits a coherent geometric structure reflecting shared research problems and methodological patterns, enabling the unsupervised identification of both established and emerging themes.
The two-stage procedure implicitly encodes an abstraction hierarchy: the first stage captures broad semantic context, while the second enforces schema-level consistency, stabilizing downstream embeddings [
69]. Cluster interpretation is performed separately using LLMs to generate concise textual summaries, preserving unsupervised structure while producing human-readable analysis. At scale, this framework enables the corpus-level mapping of thematic landscapes, trend detection, and structural organization across large scientific venues [
70].
Comparison between embedding-based and TF-IDF-based clustering on the ICML 2025 corpus demonstrates higher silhouette scores and lower Davies–Bouldin indices for embeddings, indicating that dense semantic vectors better preserve conceptual similarity across abstracts. Clusters correspond to coherent research themes including sample-efficient learning, optimization dynamics, sequential decision-making, large language and multimodal model adaptation, generative modeling, and applied problem domains such as computer vision and graph learning. LLM-assisted cluster labeling provides structured textual summaries, facilitating interpretability without influencing cluster formation.
Application to ACL 2025 abstracts confirms cross-domain generalization. Clusters correspond to evaluation and benchmarking, multilinguality, reward modeling, tool-augmented LLM agents, and alignment and fairness research. Quantitative metrics show that embeddings generate compact and well-separated clusters, suggesting that latent semantic variables are preserved across corpora with differing topical and editorial characteristics. High-density clusters reflect established research directions, whereas low-density points capture niche, interdisciplinary, or emerging topics.
The limitations of the current approach include the dependence on the quality of the structured prompt [
71] and pretrained model knowledge. Domain-specific terminology or novel methodologies not well represented in the LLM’s training data may reduce embedding fidelity. Additionally, HDBSCAN identifies clusters based on density, which may be sensitive to high-dimensional scaling and does not capture hierarchical topic structure explicitly.
Future work can address these limitations by integrating multi-model embeddings, including both domain-specific LLMs and scientific knowledge graphs, to enhance the representation of underrepresented concepts. Temporal embeddings could capture the evolution of research trends, and hierarchical or graph-based clustering could recover nested thematic structures. Incorporating uncertainty quantification for embeddings and cluster assignments may provide confidence estimates for thematic labels, supporting downstream meta-analyses or recommendation systems.
7. Conclusions
This study demonstrates that structured LLM-based semantic normalization combined with embedding-based clustering produces coherent representations of scientific abstracts across distinct venues. For ICML 2025, embeddings captured conceptual similarity among problem formulations, methodological contributions, and empirical contexts, generating clusters that aligned with theoretical, methodological, and applied research themes. Compared to TF-IDF representations, embeddings yielded higher silhouette scores and lower Davies–Bouldin indices, indicating more compact and well-separated clusters. Applying the same pipeline to ACL 2025 abstracts reproduced interpretable clusters in evaluation, alignment, and multilinguality, suggesting generalizability across domains with differing topical focus and stylistic conventions.
The two-stage prompting strategy reduced lexical and stylistic variability, enforcing schema consistency without model adaptation, and facilitated the clustering of both large, well-established topics and smaller, emerging areas. Cluster interpretation via LLMs produced concise thematic summaries, separating geometric discovery from semantic explanation while preserving unsupervised structure.
The limitations include the reliance on a single embedding model, potential sensitivity to prompt design, and the partial dependence on abstracts rather than full papers, which may omit detailed methodological nuances. Future work could explore multi-model embeddings, cross-lingual corpora, the integration of full-text analysis, and hierarchical clustering to capture multi-level thematic structure. Scaling to multi-year or cross-conference datasets may enable automated mapping of research evolution and the identification of nascent scientific directions.
Author Contributions
Conceptualization, I.M. and V.T.; methodology, I.M. and D.M.; software, I.M. and V.N.; validation, A.G. and A.B.; formal analysis, I.M.; investigation, V.T. and V.N.; resources, A.B.; data curation, V.N.; writing—original draft preparation, I.M.; writing—review and editing, V.T. and A.G.; visualization, D.M.; supervision, V.T.; project administration, V.T. and D.M.; funding acquisition, A.B. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The data supporting the findings of this study are available from the corresponding author upon reasonable request.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Jin, Z.; Chen, Y.; Adauto, F.G.; Liu, J.; Zhang, J.; Michael, J.; Schölkopf, B.; Diab, M. Analyzing the role of semantic representations in the era of large language models. In Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers), Mexico City, Mexico, 16–21 June 2024; pp. 3781–3798. [Google Scholar]
- Wu, X.K.; Chen, M.; Li, W.; Wang, R.; Lu, L.; Liu, J.; Hwang, K.; Hao, Y.; Pan, Y.; Meng, Q.; et al. Llm fine-tuning: Concepts, opportunities, and challenges. Big Data Cogn. Comput. 2025, 9, 87. [Google Scholar] [CrossRef] [Scilit]
- Wu, J.; Yu, T.; Wang, R.; Song, Z.; Zhang, R.; Zhao, H.; Lu, C.; Li, S.; Henao, R. Infoprompt: Information-theoretic soft prompt tuning for natural language understanding. Adv. Neural Inf. Process. Syst. 2023, 36, 61060–61084. [Google Scholar]
- Wang, Y.; Jiang, X.; Cheng, D.; Li, D.; Zhao, C. Learning hierarchical prompt with structured linguistic knowledge for vision-language models. In Proceedings of the AAAI Conference on Artificial Intelligence, Vancouver, QC, Canada, 20–27 February 2024; Volume 38, pp. 5749–5757. [Google Scholar]
- Jiang, Y.; Li, Z.; Song, B. Fine-tuning large language models in federated learning with fairness-aware prompt selection. Neural Netw. 2026, 194, 108160. [Google Scholar] [CrossRef] [Scilit]
- Wang, H.; Yin, Z.; Chen, B.; Zeng, Y.; Yan, X.; Zhou, C.; Li, A. ROFED-LLM: Robust Federated Learning for Large Language Models in Adversarial Wireless Environments. IEEE Trans. Netw. Sci. Eng. 2026, 13, 1084–1096. [Google Scholar] [CrossRef] [Scilit]
- Djuhera, A.; Andrei, V.C.; Li, X.; Mönich, U.J.; Boche, H.; Saad, W.M. R-SFLLM: Jamming Resilient Framework for Split Federated Learning With Large Language Models. IEEE Trans. Inf. Forensics Secur. 2025, 20, 8296–8311. [Google Scholar] [CrossRef] [Scilit]
- Yuan, W.; Yang, C.; Ye, G.; Chen, T.; Nguyen, Q.V.H.; Yin, H. FELLAS: Enhancing Federated Sequential Recommendation with LLM as External Services. ACM Trans. Inf. Syst. 2025, 43, 144. [Google Scholar] [CrossRef] [Scilit]
- Feng, S.; Lang, Z.; He, J.; Zhang, H.; Chen, W.; Cao, J. A group recommendation method based on automatically integrating members’ preferences via taking advantages of LLM. Inf. Sci. 2025, 709, 122067. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.Q.; Wang, H.; El Saddik, A.E. FedITD: A Federated Parameter-Efficient Tuning with Pre-Trained Large Language Models and Transfer Learning Framework for Insider Threat Detection. IEEE Access 2024, 12, 160396–160417. [Google Scholar] [CrossRef] [Scilit]
- Priya, N.M.; Alla, A.; Phani Praveen, S.; Balagoni, Y.; Tirumalasetti, N.R.; Shariff, V.; Ummadisetti, G.N. Revolutionizing Healthcare With Large Language Models: Advancements, Challenges, And Future Prospects In Ai-Driven Diagnostics And Decision Support. J. Theor. Appl. Inf. Technol. 2025, 103, 3638–3662. [Google Scholar]
- Habchi, Y.; Kheddar, H.; Himeur, Y.; Belouchrani, A.; Serpedin, E.; Khelifi, F.; Chowdhury, M.E. Advanced deep learning and large language models: Comprehensive insights for cancer detection. Image Vis. Comput. 2025, 157, 105495. [Google Scholar] [CrossRef] [Scilit]
- Azad, M.S.; Leeon, S.I.; Khan, R.A.; Mohammed, N.; Momen, S. SAD: Self-assessment of depression for Bangladeshi university students using machine learning and NLP. Array 2025, 25, 100372. [Google Scholar] [CrossRef] [Scilit]
- Kong, L.; Koh, D.; Antonenko, P. Evaluating User Experience in E-Learning Platforms: An NLP-Enhanced Analysis of Duolingo Reviews. Int. J. -Hum.-Comput. Interact. 2025, 41, 9700–9713. [Google Scholar] [CrossRef] [Scilit]
- Zaidani, H.; Koulali, R.; Maizate, A.; Ouzzif, M. Augmentation and Classification of Requests in Moroccan Dialect to Improve Quality of Public Service: A Comparative Study of Algorithms. Future Internet 2025, 17, 176. [Google Scholar] [CrossRef] [Scilit]
- North, K.; Ranasinghe, T.; Shardlow, M.; Zampieri, M. Deep learning approaches to lexical simplification: A survey. J. Intell. Inf. Syst. 2025, 63, 111–134. [Google Scholar] [CrossRef] [Scilit]
- Chen, K.; Peng, C.; He, X.; Sun, J.; Liu, X.; Qin, X.; Zhong, Y. AdaptForever: Elastic and Mutual Learning for Continuous NLP Task Mastery. Comput. Mater. Contin. 2025, 82, 4003–4019. [Google Scholar] [CrossRef] [Scilit]
- Alkaoud, M. FArSS: Fast and Efficient Semantic Question Similarity in Arabic. IEEE Access 2025, 13, 10944–10953. [Google Scholar] [CrossRef] [Scilit]
- Amin, T.; Tanoli, Z.U.R.; Aadil, F.; Awan, K.M.; Lim, S. Enhancing Essay Scoring: An Analytical and Holistic Approach With Few-Shot Transformer-Based Models. IEEE Access 2025, 13, 12483–12501. [Google Scholar] [CrossRef] [Scilit]
- Lou, R.; Zhang, K.; Yin, W. Large Language Model Instruction Following: A Survey of Progresses and Challenges. Comput. Linguist. 2024, 50, 1053–1095. [Google Scholar] [CrossRef] [Scilit]
- Kumar, P. Large language models (LLMs): Survey, technical frameworks, and future challenges. Artif. Intell. Rev. 2024, 57, 260. [Google Scholar] [CrossRef] [Scilit]
- Pternea, M.; Singh, P.; Chakraborty, A.; Oruganti, Y.D.; Milletari, M.; Bapat, S.; Jiang, K. The RL/LLM Taxonomy Tree: Reviewing Synergies between Reinforcement Learning and Large Language Models. J. Artif. Intell. Res. 2024, 80, 1525–1573. [Google Scholar] [CrossRef] [Scilit]
- Du, J.; Lin, T.; Jiang, C.; Yang, Q.; Bader, F.; Han, Z. Distributed Foundation Models for Multi-Modal Learning in 6G Wireless Networks. IEEE Wirel. Commun. 2024, 31, 20–30. [Google Scholar] [CrossRef] [Scilit]
- Kandola, J.; Cristianini, N.; Shawe-taylor, J. Learning semantic similarity. Adv. Neural Inf. Process. Syst. 2002, 15. [Google Scholar]
- Shi, C.; Yang, H.; Cai, D.; Zhang, Z.; Wang, Y.; Yang, Y.; Lam, W. A thorough examination of decoding methods in the era of llms. In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, Miami, FL, USA, 12–16 November 2024; pp. 8601–8629. [Google Scholar]
- Yu, P.; Mallia, A.; Petri, M. Improved learned sparse retrieval with corpus-specific vocabularies. In European Conference on Information Retrieval; Springer: Berlin/Heidelberg, Germany, 2024; pp. 181–194. [Google Scholar]
- Zhao, M.; Schütze, H. Discrete and soft prompting for multilingual models. In Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing, Punta Cana, Dominican Republic, 7–11 November 2021; pp. 8547–8555. [Google Scholar]
- Chien, J.T.; Chen, M.Y.; Lee, C.h.; Xue, J.H. Meta soft prompting and learning. APSIPA Trans. Signal Inf. Process. 2024, 13, 3251–3262. [Google Scholar] [CrossRef] [Scilit]
- Shamrai, M.; Hamolia, V. Deep Language Geometry: Constructing a Metric Space from LLM Weights. In Proceedings of the 15th International Conference on Recent Advances in Natural Language Processing-Natural Language Processing in the Generative AI Era, Varna, Bulgaria, 8–10 September 2025; pp. 1127–1136. [Google Scholar]
- Kumabe, S.; Yoshida, Y. Lipschitz continuous algorithms for graph problems. In 2023 IEEE 64th Annual Symposium on Foundations of Computer Science (FOCS); IEEE: New York, NY, USA, 2023; pp. 762–797. [Google Scholar]
- Fahim, A. A varied density-based clustering algorithm. J. Comput. Sci. 2023, 66, 101925. [Google Scholar] [CrossRef] [Scilit]
- Singh, A.; Thakur, N.; Sharma, A. A review of supervised machine learning algorithms. In 2016 3rd International Conference on Computing for Sustainable Global Development (INDIACom); IEEE: New York, NY, USA, 2016; pp. 1310–1315. [Google Scholar]
- Fachada, N.; Fernandes, D.; Fernandes, C.M.; Ferreira-Saraiva, B.D.; Matos-Carvalho, J.P. Gpt-4.1 sets the standard in automated experiment design using novel python libraries. Future Internet 2025, 17, 412. [Google Scholar] [CrossRef] [Scilit]
- Song, Y.; Wang, G.; Li, S.; Lin, B.Y. The good, the bad, and the greedy: Evaluation of llms should not ignore non-determinism. In Proceedings of the 2025 Conference of the Nations of the Americas Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers), Albuquerque, New Mexico, 29 April–4 May 2025; pp. 4195–4206. [Google Scholar]
- Hairan, B.; Şahman, M.A. Compressing Large Language Models for SQL Injection Detection: A Case Study on Deep Seek-Coder and Meta-llama-3-70b-instruct. In 2025 38th Conference of Open Innovations Association (FRUCT); IEEE: New York, NY, USA, 2025; pp. 90–96. [Google Scholar]
- Hu, J.; Xia, W.; Zhang, X.; Fu, C.; Wu, W.; Huan, Z.; Li, A.; Tang, Z.; Zhou, J. Enhancing sequential recommendation via llm-based semantic embedding learning. In Proceedings of the Companion Proceedings of the ACM Web Conference 2024, Singapore, 13–17 May 2024; pp. 103–111. [Google Scholar]
- Wang, S.; Zheng, Z.; Sui, Y.; Xiong, H. Unleashing the power of large language model for denoising recommendation. In Proceedings of the ACM on Web Conference 2025, Sydney, Australia, 28 April 2025; pp. 252–263. [Google Scholar]
- Reimers, N.; Gurevych, I. Sentence-bert: Sentence embeddings using siamese bert-networks. In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP), Hong Kong, China, 3–7 November 2019; pp. 3982–3992. [Google Scholar]
- Chu, Y.; Cao, H.; Diao, Y.; Lin, H. Refined SBERT: Representing sentence BERT in manifold space. Neurocomputing 2023, 555, 126453. [Google Scholar] [CrossRef] [Scilit]
- Grootendorst, M. BERTopic: Neural topic modeling with a class-based TF-IDF procedure. arXiv 2022, arXiv:2203.05794. [Google Scholar]
- Stewart, G.; Al-Khassaweneh, M. An implementation of the HDBSCAN* clustering algorithm. Appl. Sci. 2022, 12, 2405. [Google Scholar] [CrossRef] [Scilit]
- Chan, Y.B.; Hall, P. Using evidence of mixed populations to select variables for clustering very high-dimensional data. J. Am. Stat. Assoc. 2010, 105, 798–809. [Google Scholar] [CrossRef] [Scilit]
- Rashed, A.; Kutlu, M.; Darwish, K.; Elsayed, T.; Bayrak, C. Embeddings-based clustering for target specific stances: The case of a polarized turkey. In Proceedings of the International AAAI Conference on Web and Social Media, Virtually, 7–10 June 2021; Volume 15, pp. 537–548. [Google Scholar]
- Deb, K.; Pratap, A.; Agarwal, S.; Meyarivan, T. A fast and elitist multiobjective genetic algorithm: NSGA-II. IEEE Trans. Evol. Comput. 2002, 6, 182–197. [Google Scholar] [CrossRef] [Scilit]
- Shahapure, K.R.; Nicholas, C. Cluster quality analysis using silhouette score. In 2020 IEEE 7th International Conference on Data Science and Advanced Analytics (DSAA); IEEE: New York, NY, USA, 2020; pp. 747–748. [Google Scholar]
- Xiao, J.; Lu, J.; Li, X. Davies Bouldin Index based hierarchical initialization K-means. Intell. Data Anal. 2017, 21, 1327–1338. [Google Scholar] [CrossRef] [Scilit]
- Bafna, P.; Pramod, D.; Vaidya, A. Document clustering: TF-IDF approach. In 2016 International Conference on Electrical, Electronics, and Optimization Techniques (ICEEOT); IEEE: New York, NY, USA, 2016; pp. 61–66. [Google Scholar]
- Deb, K.; Gupta, H. Searching for robust Pareto-optimal solutions in multi-objective optimization. In International Conference on Evolutionary Multi-Criterion Optimization; Springer: Berlin/Heidelberg, Germany, 2005; pp. 150–164. [Google Scholar]
- Waga, A.; Benhlima, S.; Bekri, A.; Saber, F.Z.; Abdouni, J.; Mzili, T.; Regragui, A. Waypoint-guided trajectory planning for mobile robots using GPT-4.1 mini and ensemble learning-based action prediction. Array 2026, 29, 100636. [Google Scholar] [CrossRef] [Scilit]
- Pezoa, F.; Reutter, J.L.; Suarez, F.; Ugarte, M.; Vrgoč, D. Foundations of JSON schema. In Proceedings of the 25th International Conference on World Wide Web, Montreal, QC, Canada, 11–15 April 2016; pp. 263–273. [Google Scholar]
- Van der Maaten, L.; Hinton, G. Visualizing data using t-SNE. J. Mach. Learn. Res. 2008, 9, 2579–2605. [Google Scholar]
- Domínguez-Díaz, A.; De-Marcos, L.; Prado-Sánchez, V.P.; Rodriguez, D.; Martínez-Herráiz, J.J. Classifying illicit dark web content through zero-shot prompting: An empirical study with GPT models. Inf. Process. Manag. 2026, 63, 104476. [Google Scholar] [CrossRef] [Scilit]
- Ford, J.; Zhao, X.; Schumacher, D.; Rios, A. Charting the future: Using chart question-answering for scalable evaluation of LLM-driven data visualizations. In Proceedings of the 31st International Conference on Computational Linguistics, Abu Dhabi, United Arab Emirates, 19–24 January 2025; pp. 7497–7510. [Google Scholar]
- Bansal, N.; Akter, M.; Santu, S.K.K. Semantic overlap summarization among multiple alternative narratives: An exploratory study. In Proceedings of the 29th International Conference on Computational Linguistics, Gyeongju, Republic of Korea, 12–17 October 2022; pp. 6195–6207. [Google Scholar]
- Ben-David, S.; Bie, A.; Canonne, C.L.; Kamath, G.; Singhal, V. Private distribution learning with public data: The view from sample compression. Adv. Neural Inf. Process. Syst. 2023, 36, 7184–7215. [Google Scholar]
- Golovin, D.; Solnik, B.; Moitra, S.; Kochanski, G.; Karro, J.; Sculley, D. Google vizier: A service for black-box optimization. In Proceedings of the 23rd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, Halifax, NS, Canada, 13–17 August 2017; pp. 1487–1495. [Google Scholar]
- Chaudhari, S.; Aggarwal, P.; Murahari, V.; Rajpurohit, T.; Kalyan, A.; Narasimhan, K.; Deshpande, A.; Castro da Silva, B. Rlhf deciphered: A critical analysis of reinforcement learning from human feedback for llms. ACM Comput. Surv. 2025, 58, 1–37. [Google Scholar] [CrossRef] [Scilit]
- Deng, Z.; Tian, H.; Zheng, X.; Zeng, D.D. Deep causal learning: Representation, discovery and inference. ACM Comput. Surv. 2025, 58, 1–36. [Google Scholar] [CrossRef] [Scilit]
- Hatalis, K.; Christou, D.; Myers, J.; Jones, S.; Lambert, K.; Amos-Binks, A.; Dannenhauer, Z.; Dannenhauer, D. Memory matters: The need to improve long-term memory in llm-agents. In Proceedings of the AAAI Symposium Series, Singapore, 17–19 July2023; Volume 2, pp. 277–280. [Google Scholar]
- Ye, M.; Fang, X.; Du, B.; Yuen, P.C.; Tao, D. Heterogeneous federated learning: State-of-the-art and research challenges. ACM Comput. Surv. 2023, 56, 1–44. [Google Scholar] [CrossRef] [Scilit]
- Liang, R.; Yang, B.; Yu, Z.; Guo, B.; Cao, X.; Debbah, M.; Poor, H.V.; Yuen, C. DiffSG: A generative solver for network optimization with diffusion model. IEEE Commun. Mag. 2025, 63, 16–24. [Google Scholar] [CrossRef] [Scilit]
- Yang, H.; Yang, X.; Gong, N.Z.; Chen, Y. Hero: Hessian-enhanced robust optimization for unifying and improving generalization and quantization performance. In Proceedings of the 59th ACM/IEEE Design Automation Conference, San Francisco, CA, USA, 10–14 July 2022; pp. 25–30. [Google Scholar]
- Yang, X.; Liu, W.; Bailey, J.; Tao, D.; Liu, W. Bigram and unigram based text attack via adaptive monotonic heuristic search. In Proceedings of the AAAI Conference on Artificial Intelligence, Virtually, 2–9 February 2021; Volume 35, pp. 706–714. [Google Scholar]
- Garg, M. UBIS: Unigram bigram importance score for feature selection from short text. Expert Syst. Appl. 2022, 195, 116563. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X.; Tian, Y.; Jin, Y. A knee point-driven evolutionary algorithm for many-objective optimization. IEEE Trans. Evol. Comput. 2014, 19, 761–776. [Google Scholar] [CrossRef] [Scilit]
- Eldridge, S.M.; Ukoumunne, O.C.; Carlin, J.B. The intra-cluster correlation coefficient in cluster randomized trials: A review of definitions. Int. Stat. Rev. 2009, 77, 378–394. [Google Scholar] [CrossRef] [Scilit]
- Li, K.; Cao, X.; Ge, X.; Wang, F.; Lu, X.; Shi, M.; Yin, R.; Mi, Z.; Chang, S. Meta-heuristic optimization-based two-stage residential load pattern clustering approach considering intra-cluster compactness and inter-cluster separation. IEEE Trans. Ind. Appl. 2020, 56, 3375–3384. [Google Scholar]
- Zhao, C.; Wang, Y.; Jiang, X.; Shen, Y.; Song, K.; Li, D.; Miao, D. Learning domain invariant prompt for vision-language models. IEEE Trans. Image Process. 2024, 33, 1348–1360. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Su, H.; Shi, W.; Kasai, J.; Wang, Y.; Hu, Y.; Ostendorf, M.; Yih, W.t.; Smith, N.A.; Zettlemoyer, L.; Yu, T. One embedder, any task: Instruction-finetuned text embeddings. In Proceedings of the Findings of the Association for Computational Linguistics: ACL 2023, Toronto, ON, Canada, 9–14 July 2023; pp. 1102–1121. [Google Scholar]
- Hsiao, W.C.; Wang, H.C. Cross-domain corpus selection for cold-start context. J. Inf. Sci. 2024, 01655515241263283. [Google Scholar] [CrossRef] [Scilit]
- Zhong, W.; Gao, Y.; Ding, N.; Qin, Y.; Liu, Z.; Zhou, M.; Wang, J.; Yin, J.; Duan, N. ProQA: Structural prompt-based pre-training for unified question answering. In Proceedings of the 2022 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Seattle, WA, USA, 10–15 July 2022; pp. 4230–4243. [Google Scholar]
| Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |



 ,