Article

The Value of Numbers in Clinical Text Classification

1
Advanced Environmental Research Institute, West University of Timisoara, 300223 Timisoara, Romania
2
School of Computer Science & Informatics, Cardiff University, Cardiff CF10 4AG, UK
*
Author to whom correspondence should be addressed.
Mach. Learn. Knowl. Extr. 2023, 5(3), 746-762; https://doi.org/10.3390/make5030040
Submission received: 9 June 2023 / Revised: 30 June 2023 / Accepted: 5 July 2023 / Published: 7 July 2023

Abstract

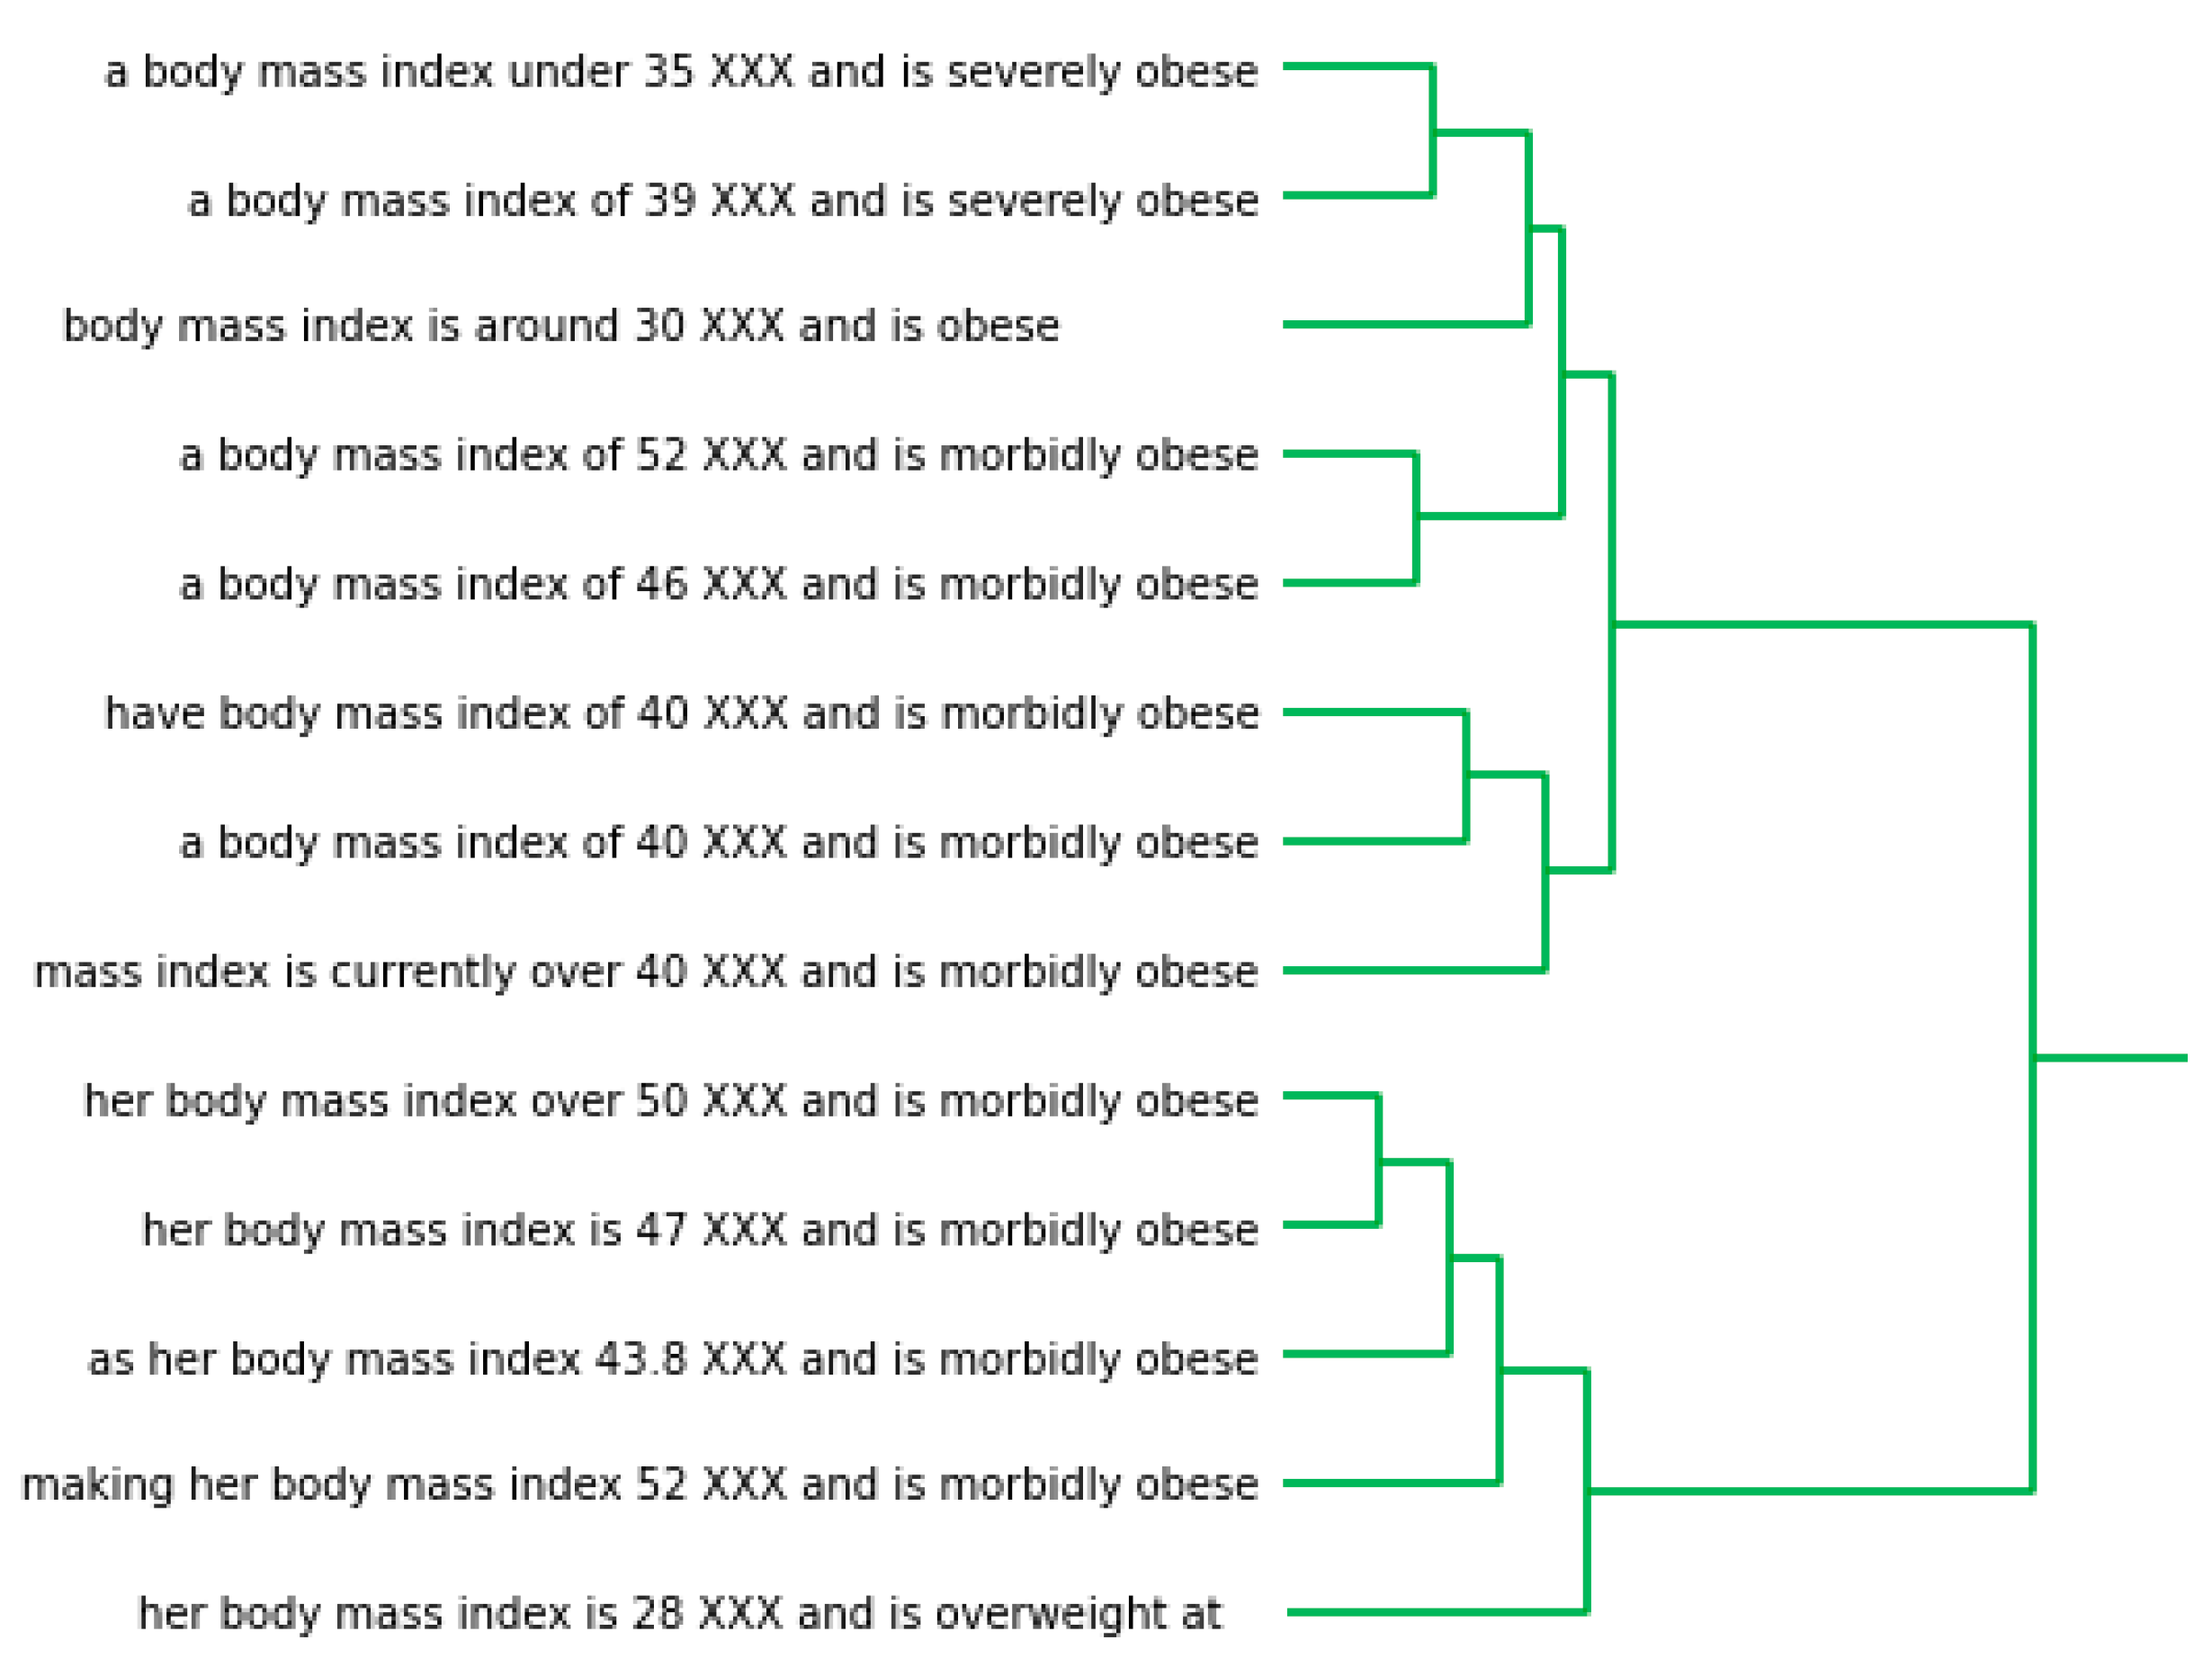
Clinical text often includes numbers of various types and formats. However, most current text classification approaches do not take advantage of these numbers. This study aims to demonstrate that using numbers as features can significantly improve the performance of text classification models. This study also demonstrates the feasibility of extracting such features from clinical text. Unsupervised learning was used to identify patterns of number usage in clinical text. These patterns were analyzed manually and converted into pattern-matching rules. Information extraction was used to incorporate numbers as features into a document representation model. We evaluated text classification models trained on such representation. Our experiments were performed with two document representation models (vector space model and word embedding model) and two classification models (support vector machines and neural networks). The results showed that even a handful of numerical features can significantly improve text classification performance. We conclude that commonly used document representations do not represent numbers in a way that machine learning algorithms can effectively utilize them as features. Although we demonstrated that traditional information extraction can be effective in converting numbers into features, further community-wide research is required to systematically incorporate number representation into the word embedding process.
Keywords: natural language processing; text classification; feature engineering; machine learning natural language processing; text classification; feature engineering; machine learning