1. Introduction
Object detection models may experience substantial performance degradation when the input distribution at deployment differs from that used during fine-tuning. In this study, we focus on a specific input-representation distribution shift in which detectors fine-tuned on grayscale-derived images are subsequently evaluated or deployed on RGB inputs. For three-channel grayscale inputs, the RGB channels are identical (R = G = B), so the input varies only along the equal-channel intensity direction and contains no independent chromatic variation. In contrast, RGB inputs introduce additional chromatic variations across the three channels. Although the semantic content of the images may remain unchanged, this change in input-channel statistics can alter the behavior of the feature extraction process and compromise model robustness under deployment-time distribution shift.
Such a setting can arise in practical vision systems in which grayscale and RGB image representations coexist. For example, in industrial inspection, legacy models trained on grayscale images may need to process RGB inputs after grayscale cameras are replaced by color cameras. In medical imaging, X-ray and CT images are intrinsically grayscale, while color-coded and color-derived representations are increasingly used in medical image processing and visualization, creating analogous grayscale-to-color representation shifts. In these scenarios, computational resources and real-time constraints on edge devices often necessitate the deployment of lightweight end-to-end detectors such as YOLO, making it difficult to directly adopt large vision models for cross-modal adaptation [
1].
Experimental results reveal a pronounced asymmetry in this modality adaptation process: models trained on RGB data generally retain satisfactory performance when applied to grayscale inputs, whereas models trained on grayscale data suffer from severe performance degradation when applied to RGB inputs, along with substantial variability across different training runs. This modality shift between grayscale and RGB primarily manifests as a mismatch in chromatic channel information, referred to as the chromatic mismatch problem. Importantly, this asymmetry cannot be fully explained by the conventional assumption that grayscale training lacks chromatic information, indicating the presence of deeper underlying mechanisms.
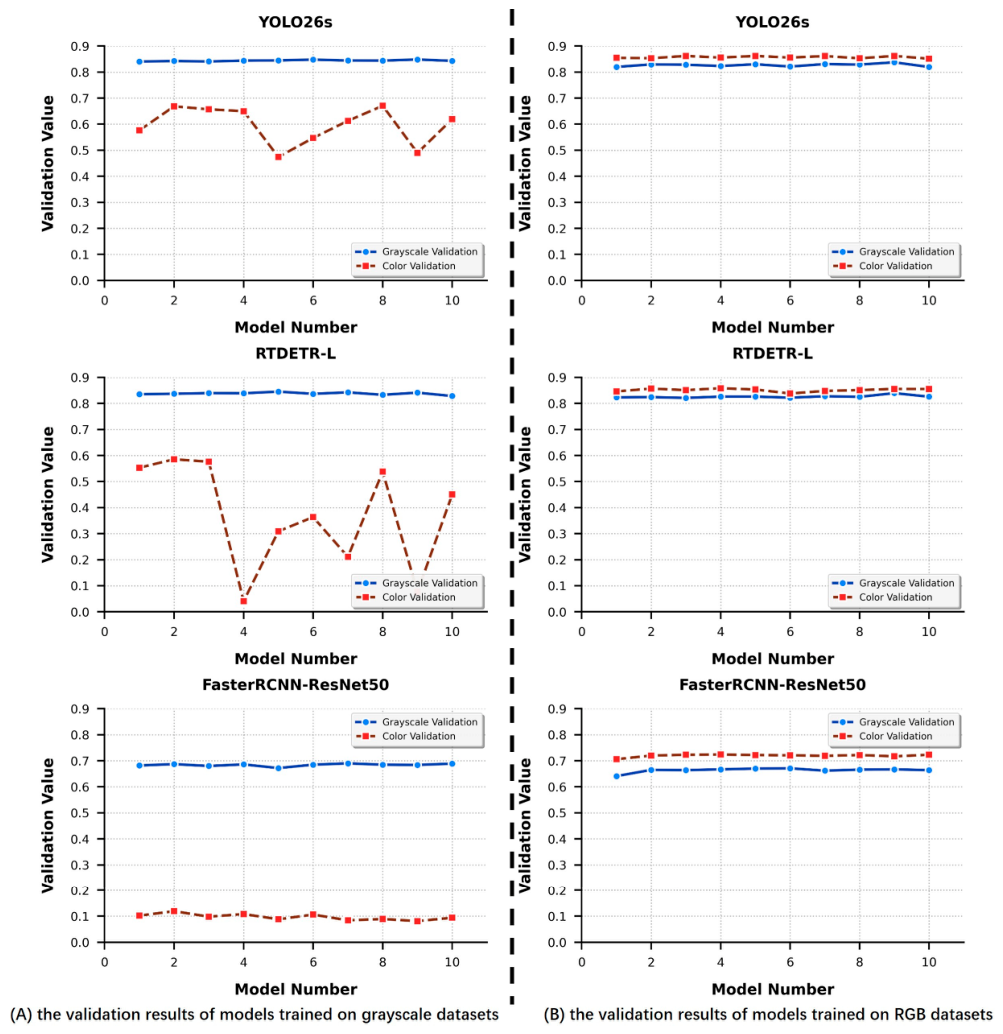
Figure 1 illustrates comparative results using three detectors: YOLO26s [
2], RTDETR-L [
3], and Faster R-CNN [
4]. Subfigure (A) shows the validation results of models fine-tuned from pretrained parameters on a grayscale dataset (hereafter “grayscale models”), while subfigure (B) shows the results of models fine-tuned from pretrained parameters on an RGB dataset (hereafter “RGB models”). In both subfigures, red curves indicate performance on RGB validation images, and blue curves indicate performance on grayscale validation images. Each model was trained and validated 10 times; the
x-axis represents the N-th training-validation run, and the
y-axis shows the mAP@0.5 (mAP50) metric. As shown, the RGB models in (B) generalize reasonably well to grayscale images, whereas the grayscale models in (A) consistently exhibit substantial performance degradation under cross-modality evaluation. Notably, YOLO26s and RTDETR-L display pronounced fluctuations in performance across different training runs.
For the aforementioned chromatic mismatch problem, existing studies commonly attribute its cause to a discrepancy between training and deployment conditions. Specifically, open-source models are typically trained on datasets containing only a limited proportion of grayscale images, resulting in weak task specificity for grayscale scenarios. Conversely, models trained on grayscale images are unable to learn chromatic features present in RGB images, leading to more severe degradation in cross-domain performance.
To address the limitations of existing models in handling chromatic mismatch, prior studies have explored approaches based on color invariance or color augmentation [
5,
6], aiming to develop deep representations that are independent of color, thereby enhancing robustness to color variations. Lengyel et al. [
7] introduced color-equivariant convolutional operations, sharing parameters across hue transformations to preserve discriminative information while improving color robustness. Yang et al. [
8] further leveraged a group convolution framework to construct network architectures that are equivariant to changes in hue, saturation, and brightness.
These studies effectively improve model robustness under chromatic mismatch scenarios, but the proposed enhancements primarily target color models and do not account for the pronounced fluctuations observed in the grayscale models of
Figure 1A. To elucidate the mechanisms underlying these phenomena, this study analyzes the channel-wise processing of chromatic information in the first layer of relevant models, revealing the process by which variance collapse occurs during grayscale training and clarifying its relationship to performance degradation under chromatic mismatch. Based on this analysis, we define a parameter for quantifying the chromatic sensitivity of convolutional kernels—
ColorScore and propose a kernel-level
chromatic sensitivity regularization method. This approach allows control over the channel bias between chromatic and luminance components during training, effectively mitigating cross-color-domain instability and enhancing model performance under chromatic mismatch conditions. The primary contributions of this work are as follows:
Analysis of RGB detection mismatch mechanism. By examining the chromatic information processing in the first layer (layer 0) of YOLO models, we reveal the core mechanism by which training on grayscale samples induces variance collapse, ultimately leading to RGB detection mismatch.
Chromatic-Sensitivity Regularization. Building on the RGB detection mismatch analysis, we propose a kernel-level regularization method that adjusts the chromatic sensitivity of the first layer by modulating the ratio between color-channel kernels and luminance-channel kernels. This effectively mitigates the impact of variance collapse. Experiments demonstrate that this approach is also effective for CNN models with first-layer structures similar to YOLO, indicating its potential to enhance robustness of model training across diverse input samples. Furthermore, in contrast to earlier color-invariance methods, our method does not impose a predefined color-transformation symmetry while preserving the original detector architecture. The regularization is applied only during training, introduces no additional learnable parameters, and incurs only marginal additional inference-time computational cost.
ColorScore metric for chromatic sensitivity. We introduce a ColorScore parameter to quantify the chromatic sensitivity of convolutional kernels. This metric allows analysis of whether a kernel preferentially extracts chromatic or luminance information.
3. Analysis of the Chromatic Mismatch Problem
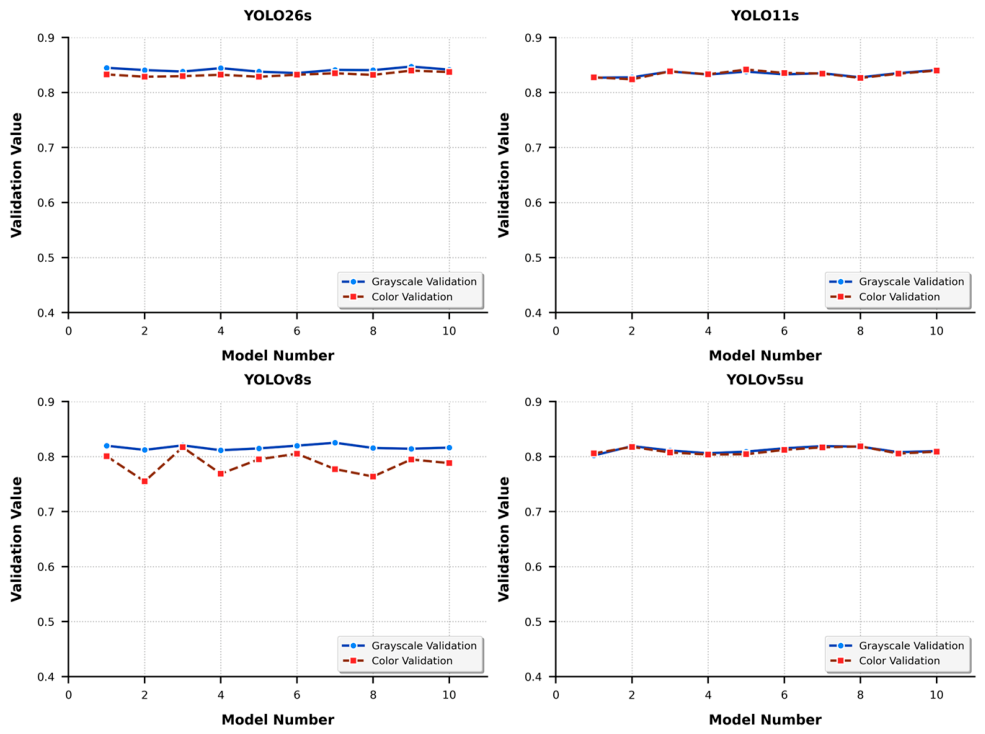
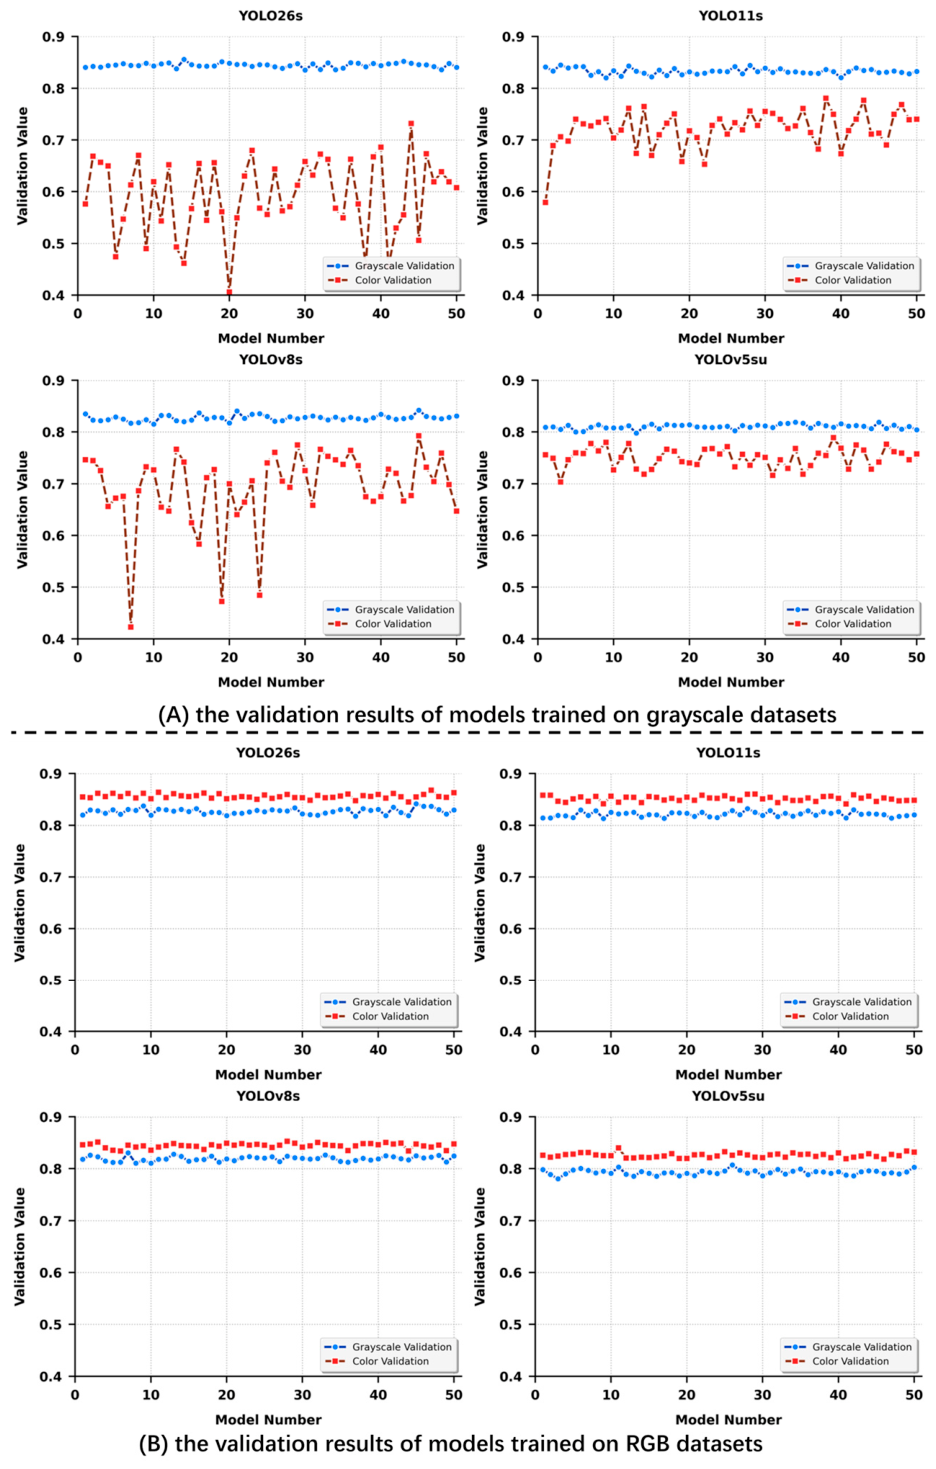
Figure 2 illustrates the chromatic mismatch scenarios for four models: YOLOv5su [
31], YOLOv8s [
32], YOLO11s [
33], and YOLO26s. All models are first fine-tuned on grayscale and RGB training datasets, respectively, and then evaluated on both grayscale and RGB test datasets. Each fine-tuning process is conducted for 100 epochs using the AdamW optimizer, with an initial learning rate of 5 × 10
−4 and a batch size of 32. The dataset used is PASCAL VOC2007, along with its corresponding converted grayscale version.
The reason for selecting this dataset is that the focus of this study is to reveal the intrinsic mechanism underlying RGB detection degradation caused by grayscale training, namely variance collapse, rather than to optimize performance for a specific application scenario. As a standard benchmark for RGB object detection, PASCAL VOC2007 can be converted into a grayscale version while preserving identical semantic content, thereby isolating color information as the only varying factor. This enables a clearer observation of the variance collapse phenomenon and its impact on detection performance. The variance collapse mechanism revealed in this work originates from the weight degradation process of convolutional kernels in the first layer (layer 0) under grayscale training. Since this process is independent of specific image content, the findings obtained on a general-purpose dataset provide a solid theoretical basis for transferability to real-world scenarios such as medical imaging and industrial inspection.
In this study, the RGB images in PASCAL VOC2007 were converted to grayscale using an equal-weight transformation:
where
IR0,
IG0, and
IB0 denote the pixel intensities of the three channels in the original RGB image. The resulting scalar grayscale intensity was then represented as three identical input channels when supplied to the detector, such that
Igray =
IR =
IG =
IB.
As shown in
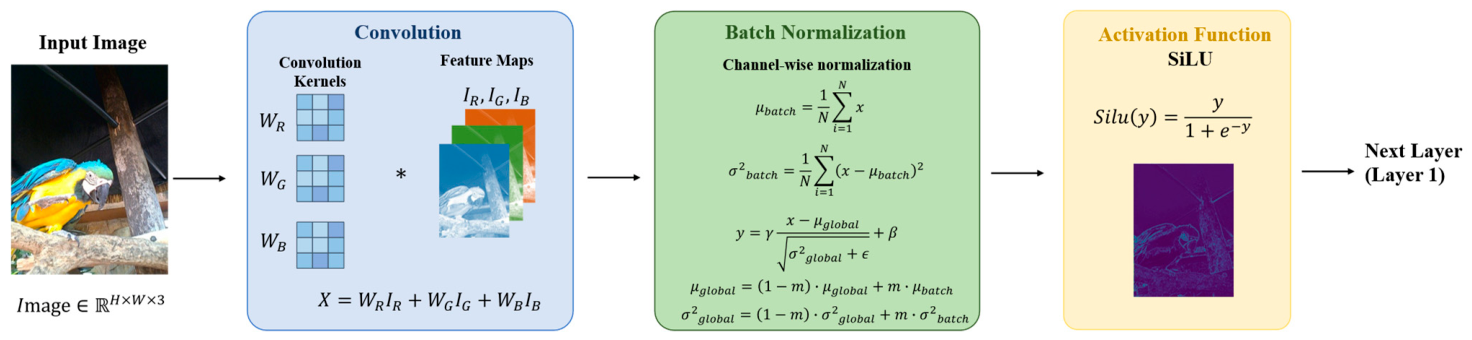
Figure 2, compared with the performance degradation observed when RGB models are validated on grayscale images in region (B), the degradation is substantially more severe when grayscale models are validated on RGB images in region (A), accompanied by significant fluctuations across different training runs. This clearly indicates deficiencies in the models’ handling of chromatic information. From an architectural perspective, the first stage of such processing corresponds to the initial layer (layer 0) of the model, as illustrated in
Figure 3.
Let the convolutional kernels of layer 0 be denoted as
W = (
WR,
WG,
WB), where
WR,
WG,
WB ∈ ℝ
K×K correspond to the convolutional kernel parameters for the three input channels, and
K is the kernel size. Consider an input sample
Image = (
IR,
IG,
IB), where
IR,
IG,
IB represent the data in the red, green, and blue channels, respectively. We regard the equal-channel direction in RGB space as a symmetric geometric reference. Accordingly, in this study, the intensity component
L is defined using an equal-weight average as:
Then we have:
where
r +
g +
b = 0, and
r,
g, and
b denote the chromatic residual components along the respective RGB axes. This zero-sum relation follows directly from the equal-weight definition of
L and decomposes the RGB space into a one-dimensional equal-channel intensity component and a two-dimensional chromatic residual subspace. It therefore provides an explicit geometric separation between intensity and chromatic variation. The convolutional output
X can then be written as:
Let
Wsum =
WR +
WG +
WB. The
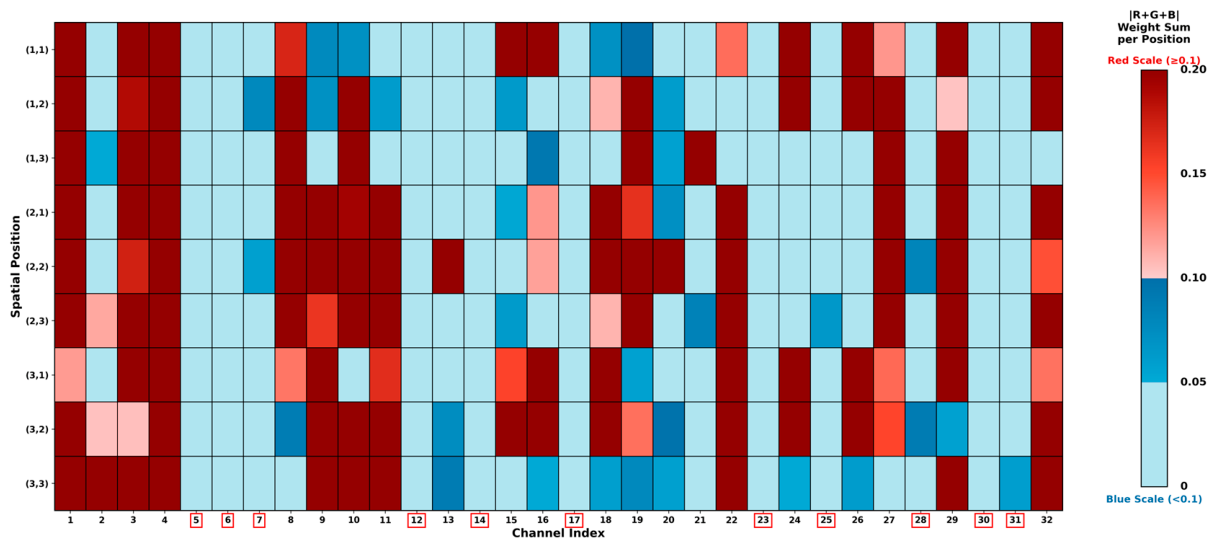
Wsum values of the convolutional kernels in the first layer (layer 0) of the YOLO26s model were computed, and their absolute values are listed in
Figure 4. It can be observed that some channels exhibit very small weight magnitudes, with channels 5, 6, 12, 14, 17, 23, and 30 having weights below 0.05. Channels 7, 25, and 31 also have overall weights below 0.1. Similar computations of
Wsum for the first layer of the other three models reveal the presence of comparable channels.
According to Equation (4), these channels show relative insensitivity to the L component of the input RGB image. In this study, such convolutional kernels are referred to as chromatic filters, and the channels in which they reside are referred to as chromatic channels. These channels primarily process the chromatic information present in the input image.
For the grayscale training samples described above, the detector input satisfies
Igray =
IR =
IG =
IB, the inputs in Equation (4) satisfy
r =
g =
b = 0. It should be emphasized that the particular weighting used to compute the scalar grayscale intensity affects only the value of
Igray; it does not affect this equal-channel condition as long as the resulting grayscale intensity is represented identically across the three model input channels. Equation (4) therefore reduces to:
At this stage, due to the influence of the kernel weight coefficients, the outputs of the chromatic filters become significantly reduced, which in turn affects the Batch Normalization (BN) layer according to the following variance update formulation:
Here, and denote the global variance parameter of the channel output and the variance of the current batch, respectively.
During grayscale model training, the convolutional outputs of chromatic channels decrease, leading to smaller values of
μbatch and
. After multiple updates, the global variance
correspondingly diminishes substantially.
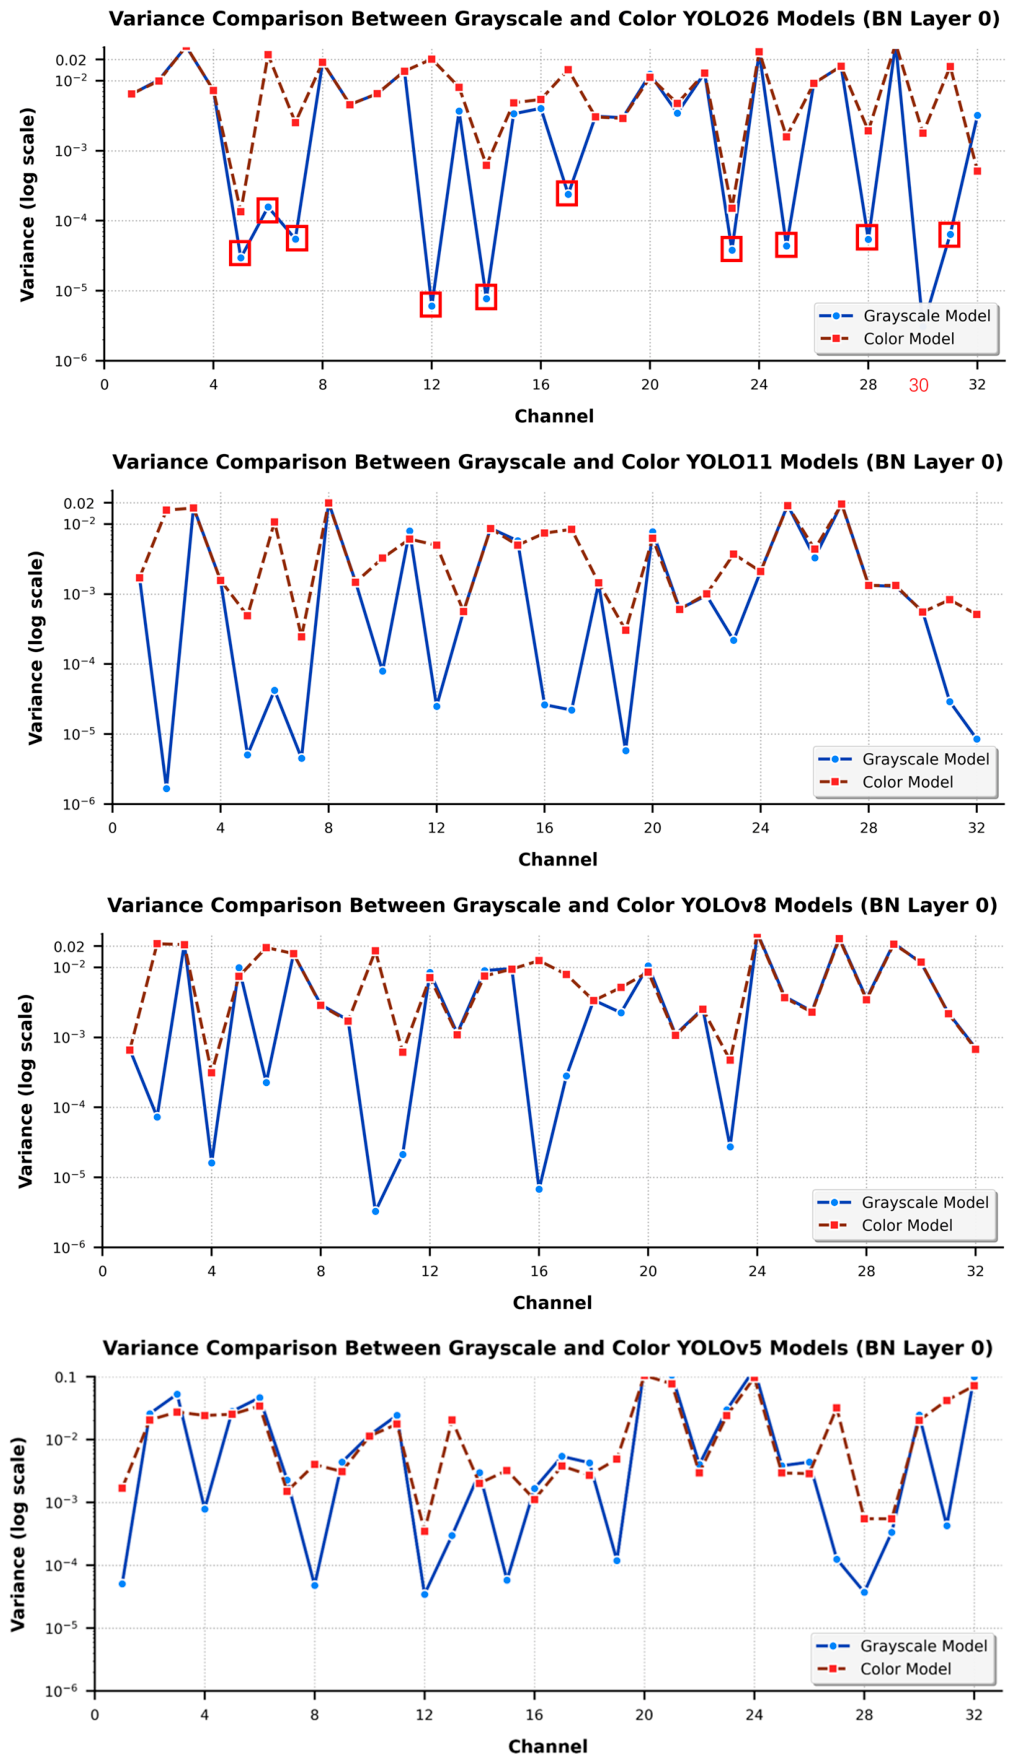
Figure 5 illustrates the BN variance parameters of each channel in the first layer for both grayscale and RGB models trained using four YOLO variants. In the figure, the red curves represent the RGB models, while the blue curves represent the grayscale models; the horizontal axis denotes the channel index, and the vertical axis denotes the variance value.
It can be observed that, in grayscale models, the BN variance of certain channels decreases by orders of magnitude compared with that of RGB models. This phenomenon is referred to as
chromatic variance collapse. A comparison between
Figure 4 and
Figure 5 shows that the channel indices exhibiting variance collapse in the YOLO26 model strongly correlate with the chromatic channel indices identified in
Figure 4, which is consistent with the aforementioned theoretical analysis.
The output of the first layer (layer 0) of YOLO models is given by Equation (9).
The analysis suggests that, during grayscale-model training, the reduced activations of chromatic channels may not only be accompanied by variance collapse as the network adapts to the grayscale input distribution but may also increase the sensitivity of the corresponding convolutional-kernel optimization to stochastic perturbations. This may in turn induce trade-offs in the optimization of other parameters as the model converges. When RGB information is subsequently introduced, the collapsed variance in the denominator of Equation (9) can amplify these perturbations in chromatic channels, potentially leading to a substantial performance decline when the grayscale-trained model is evaluated on RGB inputs.
Moreover, owing to the stochastic nature of deep learning optimization, the detailed pattern of variance collapse may vary slightly across independently trained models despite an overall consistent tendency. For the YOLO11s model, the number of variance-collapsed channels in grayscale-trained runs ranged from 10 to 12. Furthermore, models with 11–12 variance-collapsed channels exhibited lower mAP50 under RGB validation than models with 10 such channels. This observation is consistent with the possibility that variations in the extent of variance collapse contribute to the pronounced performance dispersion across independently trained models. Nevertheless, the run-to-run variation in model performance cannot be attributed solely to variance collapse, because it may also be affected by multiple downstream factors, including deeper network optimization, normalization, nonlinear transformations, feature fusion, and the detection head.
In contrast, for the scenario where RGB models are validated on grayscale datasets, the chromatic channels are not affected by insufficient information during training. During validation, since the input grayscale images lack chromatic information, the chromatic channels contribute little to the detection results, leading to reduced performance; however, the absence of variance collapse prevents the occurrence of large performance fluctuations.
5. Experiments
Regularized training was conducted on two datasets. The first was the general-purpose PASCAL VOC 2007 dataset and its grayscale counterpart. The models were trained for 100 epochs using AdamW, with an initial learning rate of 5 × 10
−4, a batch size of 32, and
λr =
λs = 0.3. The second experiment used a subset of the domain-specific CBIS-DDSM mammography dataset [
34] and a separately sourced set of algorithmically colorized CT/X-ray images [
35]. The latter, which consists of algorithmically colorized data, was employed as a controlled stress test of color-representation shifts, rather than as evidence of native clinical RGB imaging. For this experiment, the models were trained for 50 epochs using SGD, with an initial learning rate of 0.001, a batch size of 32, and
λr =
λs = 0.7. For PASCAL VOC2007, both regularization coefficients were set to
λr =
λs = 0.3. For the medical-imaging experiments, both were set to
λr =
λs = 0.7. This selection serves a dual purpose: it avoids over-regularization that could impair detection accuracy, while guaranteeing convergence of the regularized models across different epoch settings in our experiments. All experiments were initialized from pretrained weights and evaluated under a grayscale-training-to-color-input protocol. Specifically, the models were trained using grayscale inputs and evaluated using the corresponding color-representation inputs specified for each experimental setting. Each model is trained and evaluated at least 10 times.
5.1. Effectiveness of Chromatic Sensitivity Regularization
Figure 7 presents the validation results of four YOLO grayscale models with regularization applied under the setting
M = 3. The red curves correspond to validation on RGB data, while the blue curves correspond to validation on grayscale data. Here, the horizontal axis represents the
N-th run and the vertical axis denotes the mAP50 performance.
A comparison between
Figure 2A and
Figure 7 shows that the proposed regularization method significantly improves the detection performance of grayscale models on RGB samples. Moreover, the severe performance fluctuations observed across different training runs are effectively eliminated.
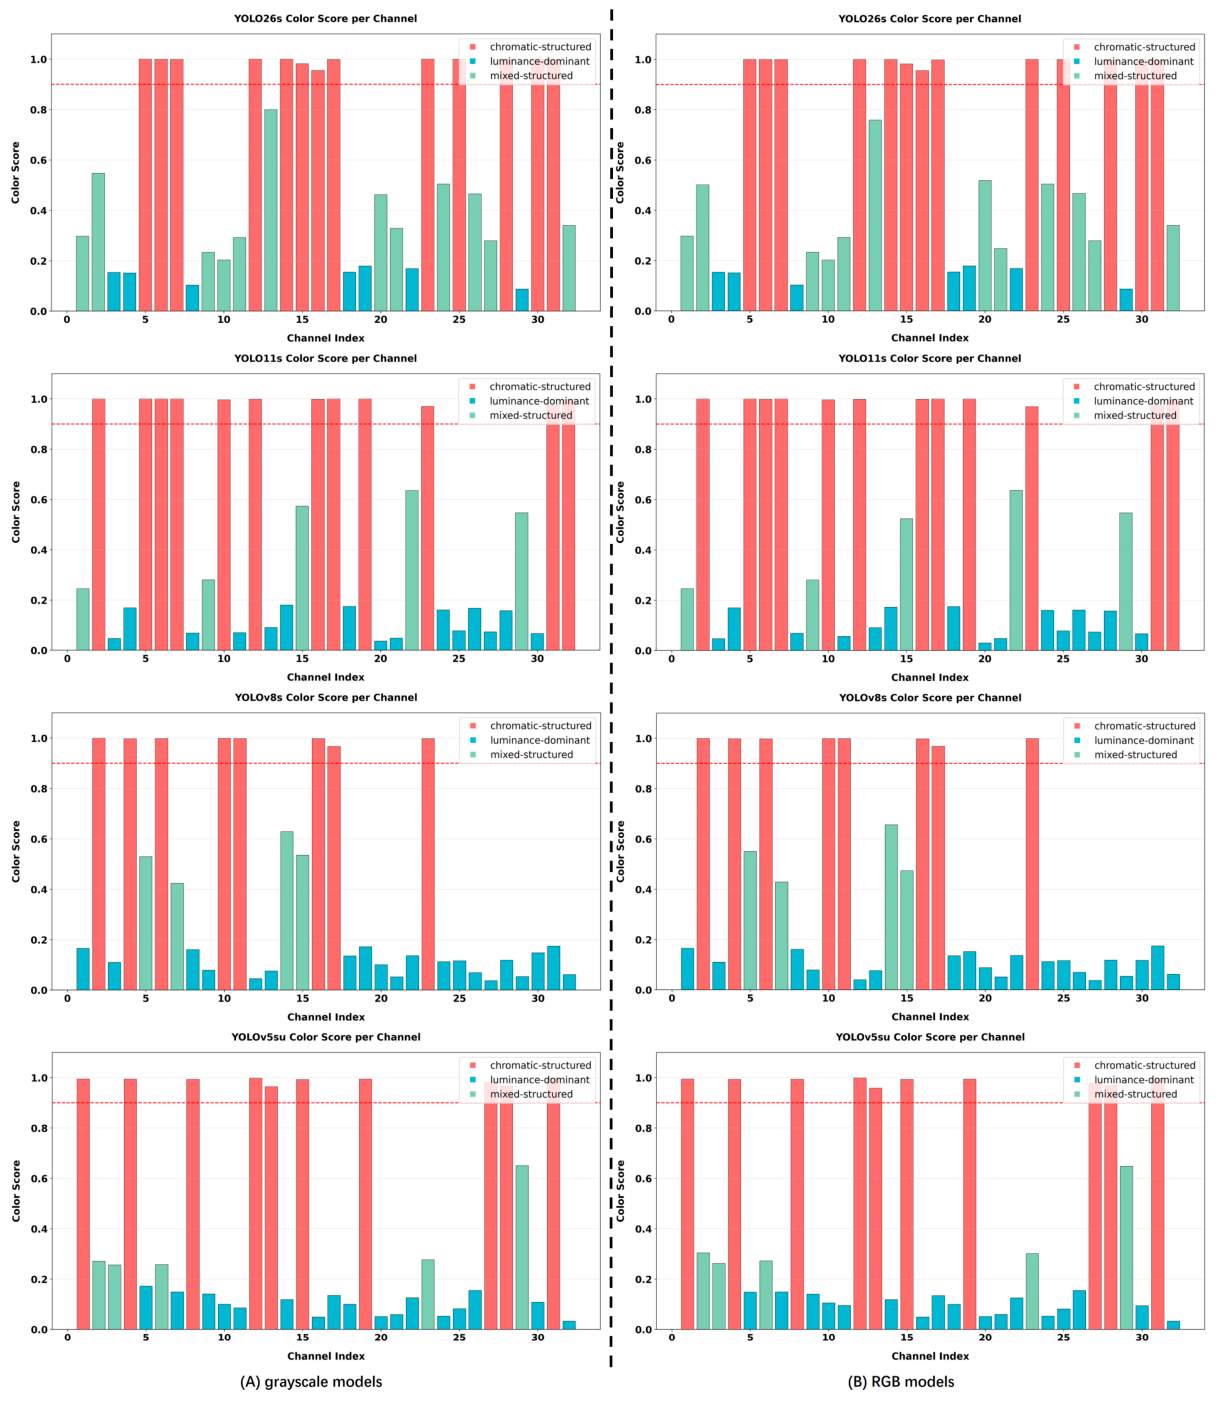
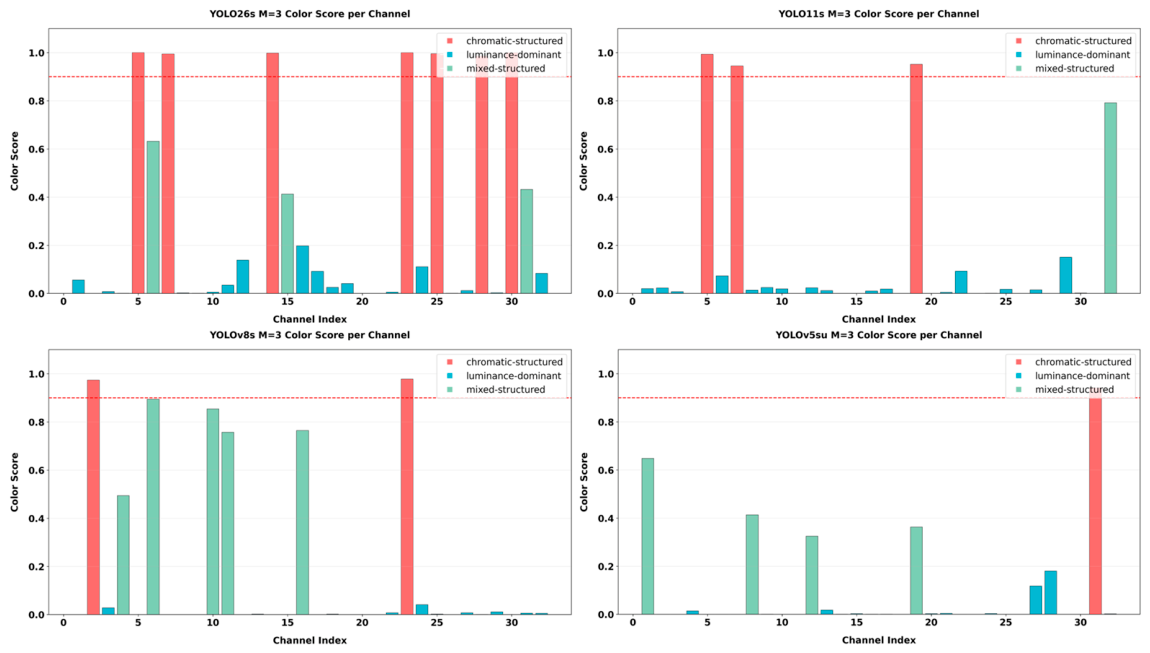
Figure 8 shows the ColorScore values of the first-layer channels for the four YOLO grayscale models with regularization applied under
M = 3. The horizontal axis represents the channel index of layer 0, and the vertical axis denotes the ColorScore values. Compared with the left panel of
Figure 6, it is evident that the number of chromatic channels has decreased significantly, and the functional differentiation among channels is more pronounced. This demonstrates the effectiveness of chromatic sensitivity regularization in regulating channel allocation during model training.
To further evaluate the effectiveness of the chromatic-sensitivity regularization and determine whether its improvement depends on object scale, we used YOLO11s as a representative model and evaluated three variants on the VOC2007 dataset: the grayscale-trained YOLO11s model, the RGB-trained YOLO11s model, and the regularized YOLO11s model with
M = 3. The evaluation was conducted separately for small, medium, and large objects. The results are presented in
Table 1.
As shown in
Table 1, the grayscale-trained baseline model (YOLO11s-GVOC) exhibited substantial performance degradation across all three object-size groups when evaluated under the RGB setting. After applying the proposed regularization (YOLO11s-M3), the mAP50 increased from 0.379 to 0.506 for small objects, from 0.507 to 0.664 for medium objects, and from 0.782 to 0.886 for large objects, corresponding to absolute improvements of 0.127, 0.157, and 0.104, respectively. These results indicate that the performance recovery is not limited to medium or large objects; small objects also benefit substantially from the proposed regularization.
Compared with the RGB-trained YOLO11s-VOC model, YOLO11s-M3 achieved comparable performance across all object scales. In particular, its mAP50 for small objects was slightly higher (0.506 vs. 0.481), while the differences for medium and large objects were only 0.020 and 0.017, respectively. These results suggest that the proposed regularization largely restores the scale-wise detection capability lost under the grayscale-to-RGB distribution shift, rather than improving the overall mAP50 through gains concentrated in a particular object-size group.
5.2. Comparative Experiments
Table 2 summarizes the comparative results of the proposed regularization method and representative existing approaches on a general-purpose object-detection dataset and a CBIS-DDSM-based medical imaging setting. YOLO11s-M3 denotes the proposed regularization method with
M = 3. CIConv is a color-invariant convolutional method, whereas CEConv is a color-equivariant convolutional method.
On the general-purpose object-detection dataset, the grayscale-trained models obtained using the proposed method, CIConv, and CEConv did not exhibit a substantial decrease in mAP50 under color validation relative to grayscale validation. In particular, CIConv and CEConv achieved marginally higher mAP50 values under color validation than under grayscale validation. Given the small magnitude of these differences, they are more appropriately interpreted as run-to-run variation in the training and evaluation process than as evidence of a systematic benefit of color validation. Nevertheless, both CIConv and CEConv achieved lower overall detection performance than YOLO11s-M3 on PASCAL VOC 2007. In particular, CEConv attained substantially lower mAP50 on PASCAL VOC 2007 than the other methods. This is likely attributable to the fact that CEConv was originally designed for image classification rather than object detection and was applied here without task-specific architectural adaptation or hyperparameter optimization. To ensure a controlled comparison, all methods—including CEConv—were trained using identical hyperparameters and the same training budget. Under this protocol, the performance gap on the multi-class, higher-complexity PASCAL VOC 2007 benchmark is larger than on the simpler single-class CBIS-DDSM setting, where CEConv performed comparably to the other methods.
In the CBIS-DDSM-based medical imaging setting, all three approaches showed performance degradation when evaluated using color-representation inputs relative to grayscale validation. However, the proposed method exhibited a numerically smaller decrease in mAP50 than both CIConv and CEConv. Specifically, YOLO11s-M3 decreased from 0.727 to 0.544, whereas CIConv decreased from 0.711 to 0.223, and CEConv decreased from 0.713 to 0.462. These results suggest that the proposed regularization provides improved robustness to the evaluated grayscale-to-color representation shift under this experimental protocol.
5.3. Generalization of Chromatic Sensitivity Regularization
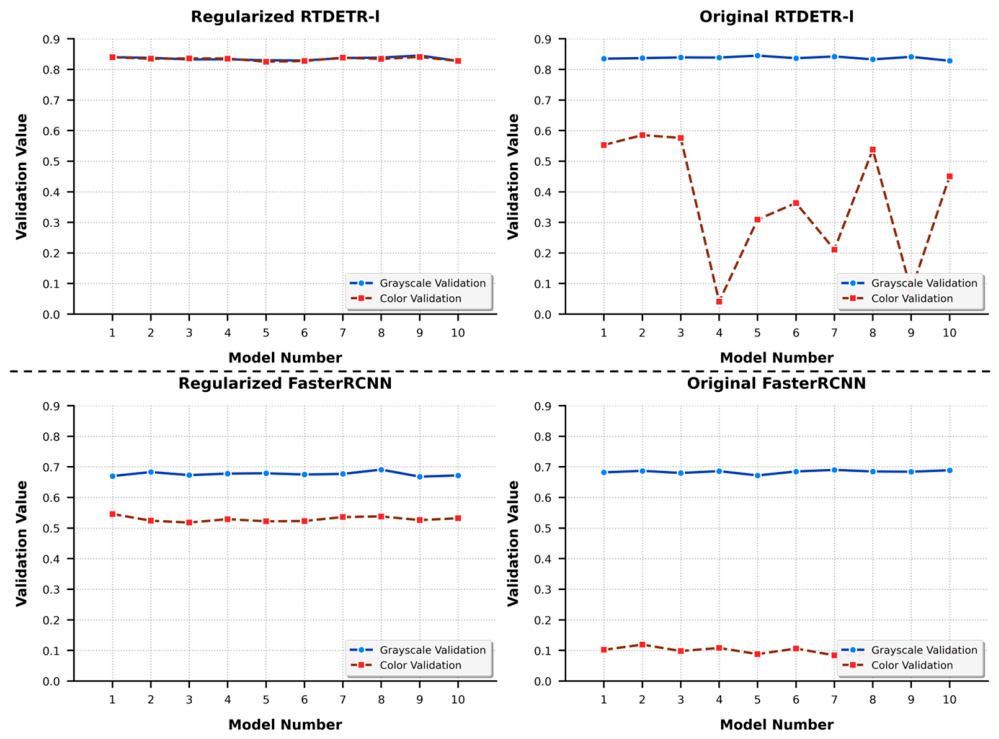
To evaluate the generality of the proposed regularization, we further considered RT-DETR-L and Faster R-CNN. Although their first-stage architectures differ from those of the YOLO family, both models contain a learnable convolutional layer that directly projects the three-channel RGB input into feature channels. Therefore, the same ColorScore formulation and regularization terms can be applied to this first input-projection layer without modifying the subsequent network architecture. For RT-DETR-L, the regularization was applied to the first convolution in the HGNetv2 stem (stem1.conv). For Faster R-CNN, the same ColorScore computation and regularization terms were applied to the first input convolution of the ResNet-50 backbone.
Figure 9 shows the experimental results under the setting
M = 3. It can be observed that grayscale models trained with the proposed regularization exhibit significantly improved performance and stability when validated on RGB data compared with non-regularized models. This confirms the effectiveness of the method for models employing similar backbone architectures.
5.4. Analysis of the Chromatic Sensitivity Regularization Parameter M
To investigate the effect of different
M values on the regularization results, four grayscale-trained models were evaluated under a range of
M settings. The results are summarized in
Table 3, where each reported value represents the mean over ten validation runs.
Inspection of the pretrained first-layer weights of the four YOLO backbones showed that their initial total ColorScore values were all approximately centered around 15. We therefore used M = 15 as a common reference target to facilitate a unified comparison across architectures. Consistent with this observation, the initial values of Lr were relatively small when M = 15. For example, in the 100-epoch YOLO11s setting, the initial Lr was 0.494, while the corresponding value for YOLOv5su was 2.68, with YOLOv8s and YOLO26s showing similarly low initial values. Based on this reference, M = 3, 6, and 8 impose lower total ColorScore targets, whereas M = 18 and 24 impose higher targets.
When the separation loss sufficiently polarizes the channel-wise ColorScore values toward 0 or 1, the lower-M, settings can be interpreted approximately as encouraging fewer highly chromatic-sensitive channels, whereas the higher-M settings encourage more such channels.
Table 3 shows that for YOLOv5su, YOLO11s, and YOLO26s, grayscale models with
M = 3, 6 or 8 exhibit significantly improved RGB detection performance. To further assess whether the RGB-validation improvements were robust across repeated training runs, we conducted two-sided paired t-tests between each regularized configuration and its corresponding baseline model. For YOLO11s, the mean improvements in RGB-validation mAP50 were 0.1286 (95% CI: [0.0958, 0.1614]) for M3, 0.1273 (95% CI: [0.0928, 0.1617]) for M6, and 0.1195 (95% CI: [0.0881, 0.1509]) for M8. All three improvements were statistically significant: M3,
t(9) = 8.875,
p < 0.001,
Cohen’s d = 2.81; M6,
t(9) = 8.365,
p < 0.001,
Cohen’s d = 2.65; and M8,
t(11) = 8.375,
p < 0.001,
Cohen’s d = 2.42. Similar paired comparisons were conducted for the remaining three backbones. For YOLOv5su and YOLO26s, the RGB-validation improvements were statistically significant under all tested
M settings (all
p < 0.001,
Cohen’s d ≥ 1.54). For YOLOv8s, the improvement under M3 was statistically significant (
t(11) = 4.313,
p < 0.001,
Cohen’s d = 1.24), whereas under M6 and M8 the mean differences were negative and not significant (M6:
t(9) = −0.315,
Cohen’s d = −0.10; M8:
t(12) = −0.550,
Cohen’s d = −0.15), indicating that the regularization did not produce consistent improvements for this backbone. It should be noted that the baseline models were trained and validated 50 times. Among the regularized configurations, YOLO11s-M8, YOLOv8s-M3, and YOLOv8s-M8 were trained and validated 12, 12, and 13 times, respectively, whereas the remaining regularized configurations were trained and validated 10 times. Accordingly, the paired comparisons involved 10, 12, or 13 paired observations, corresponding to 9, 11, or 12 degrees of freedom, respectively.
The results for YOLOv8s differ slightly: although its baseline
M is also approximately 15, the model contains 8 chromatic channels (as shown in
Figure 6). Therefore, when
M = 6 or 8, the actual number of chromatic channels does not decrease effectively, limiting the impact of the regularization.
When M is set to 18 or 24, the RGB detection performance of all four models shows a general decline. This indicates that further increasing the number of chromatic channels does not improve the model’s utilization of color information in RGB images, and may in fact interfere with the extraction of luminance information.
For color models, experiments were conducted using two extreme strategies,
M = 3 and
M = 24, with results summarized in
Table 4. It can be observed that introducing chromatic sensitivity regularization results in only a minor decline in grayscale validation performance compared with the baseline models (approximately 2%∼3% mAP50), indicating that the proposed regularization does not compromise the original capabilities of RGB models.
Furthermore, even under M = 3, the detection performance of color models in the RGB space remains largely unchanged. This suggests that the models retain strong capability to leverage color information even when chromatic channels are suppressed. The precise mechanisms underlying this phenomenon require further investigation.
5.5. Ablation Study
As shown in
Table 5, the ablation results indicate that
ratio is the primary factor contributing to improved chromatic robustness of the model. In contrast,
sep helps enhance the stability of model performance by reducing variability across training runs. However, when used independently,
sep does not improve RGB detection performance; instead, it may lead to performance degradation due to overly strong channel disentanglement constraints. When the two loss terms are jointly applied,
sep plays a complementary regularization role, further refining channel specialization and enabling the model to achieve optimal overall performance.
Finally, the proposed chromatic-sensitivity regularization is lightweight and introduces only a small additional computational overhead during training. Taking YOLO11s as an example, the detailed overhead analysis is reported in
Table 6.
As shown in
Table 6, the proposed regularization method does not introduce additional learnable parameters and incurs only a small training-time computational and memory overhead relative to the baseline model. Because the regularization terms are applied only during training and do not modify the inference architecture, the method introduces no additional computational cost during inference.
6. Conclusions
This paper systematically investigated the chromatic mismatch phenomenon in YOLO models when training data is converted from RGB to grayscale. We analyzed the relationship between the chromatic sensitivity of channel-wise convolutional filters and variance collapse in Batch Normalization layers and proposed a chromatic sensitivity regularization method based on the ColorScore metric to control channel allocation within the model.
Experimental results demonstrate that, with the proposed chromatic sensitivity regularization, the mean absolute mAP50 gap between grayscale and RGB evaluation is reduced from 0.140 to 0.014, while also effectively eliminating performance fluctuations across different training runs.
Because the proposed regularization is defined in the physical RGB input space, it is applied to the first learnable input-projection layer. After this layer, subsequent feature channels no longer correspond directly to the physical R, G, and B axes; instead, they form learned and progressively abstract feature coordinates that may jointly encode color, spatial structure, texture, and semantic information. Consequently, the equal-channel direction and the RGB chromatic subspace on which the regularization is based no longer have a unique or directly interpretable definition in subsequent layers. We therefore recommend applying the proposed regularization to the first input-projection layer rather than directly extending the same formulation to deeper network layers.
The proposed method is also effective for additional detector architectures, including the Transformer-based RT-DETR-L and the CNN-based Faster R-CNN. Overall, this approach improves the robustness of model training with respect to data distribution shifts and provides a useful reference for CNN-based object detection in real-world scenarios where grayscale training and RGB deployment coexist, such as medical imaging, industrial inspection, and infrared surveillance. We note that the medical-imaging evidence in this study is based on algorithmically colorized CT/X-ray representations and a mammography subset (CBIS-DDSM), rather than native clinical RGB acquisition. The supplementary medical experiment should therefore be interpreted as a controlled stress test of robustness to grayscale-to-color image-representation shifts, not as validation on a paired native grayscale/RGB clinical dataset.