Article

CFANet: The Cross-Modal Fusion Attention Network for Indoor RGB-D Semantic Segmentation

1
School of Mechanical and Automotive Engineering, Shanghai University of Engineering Science, Shanghai 201620, China
2
College of Materials and Energy, South China Agricultural University, Guangzhou 510642, China
*
Author to whom correspondence should be addressed.
J. Imaging 2025, 11(6), 177; https://doi.org/10.3390/jimaging11060177

Submission received: 17 April 2025 / Revised: 22 May 2025 / Accepted: 23 May 2025 / Published: 27 May 2025
(This article belongs to the Section Computer Vision and Pattern Recognition)

Abstract

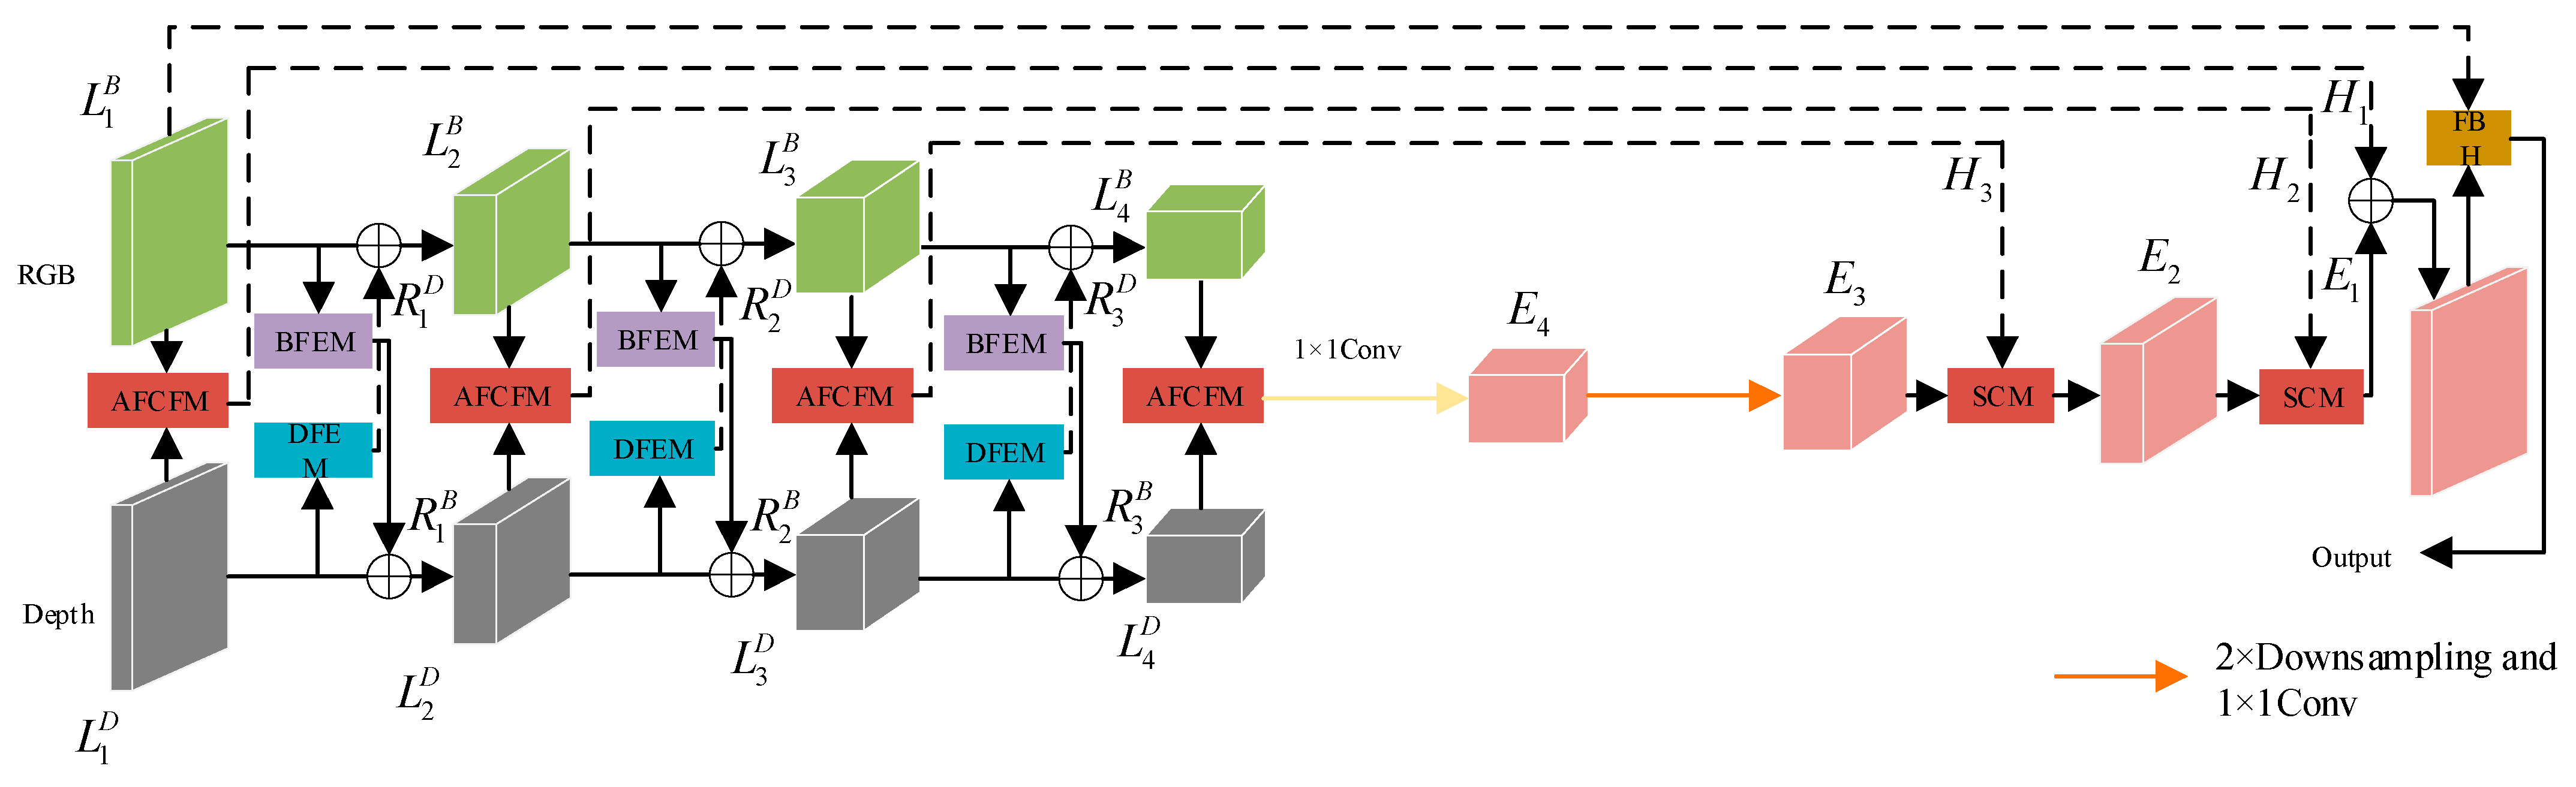
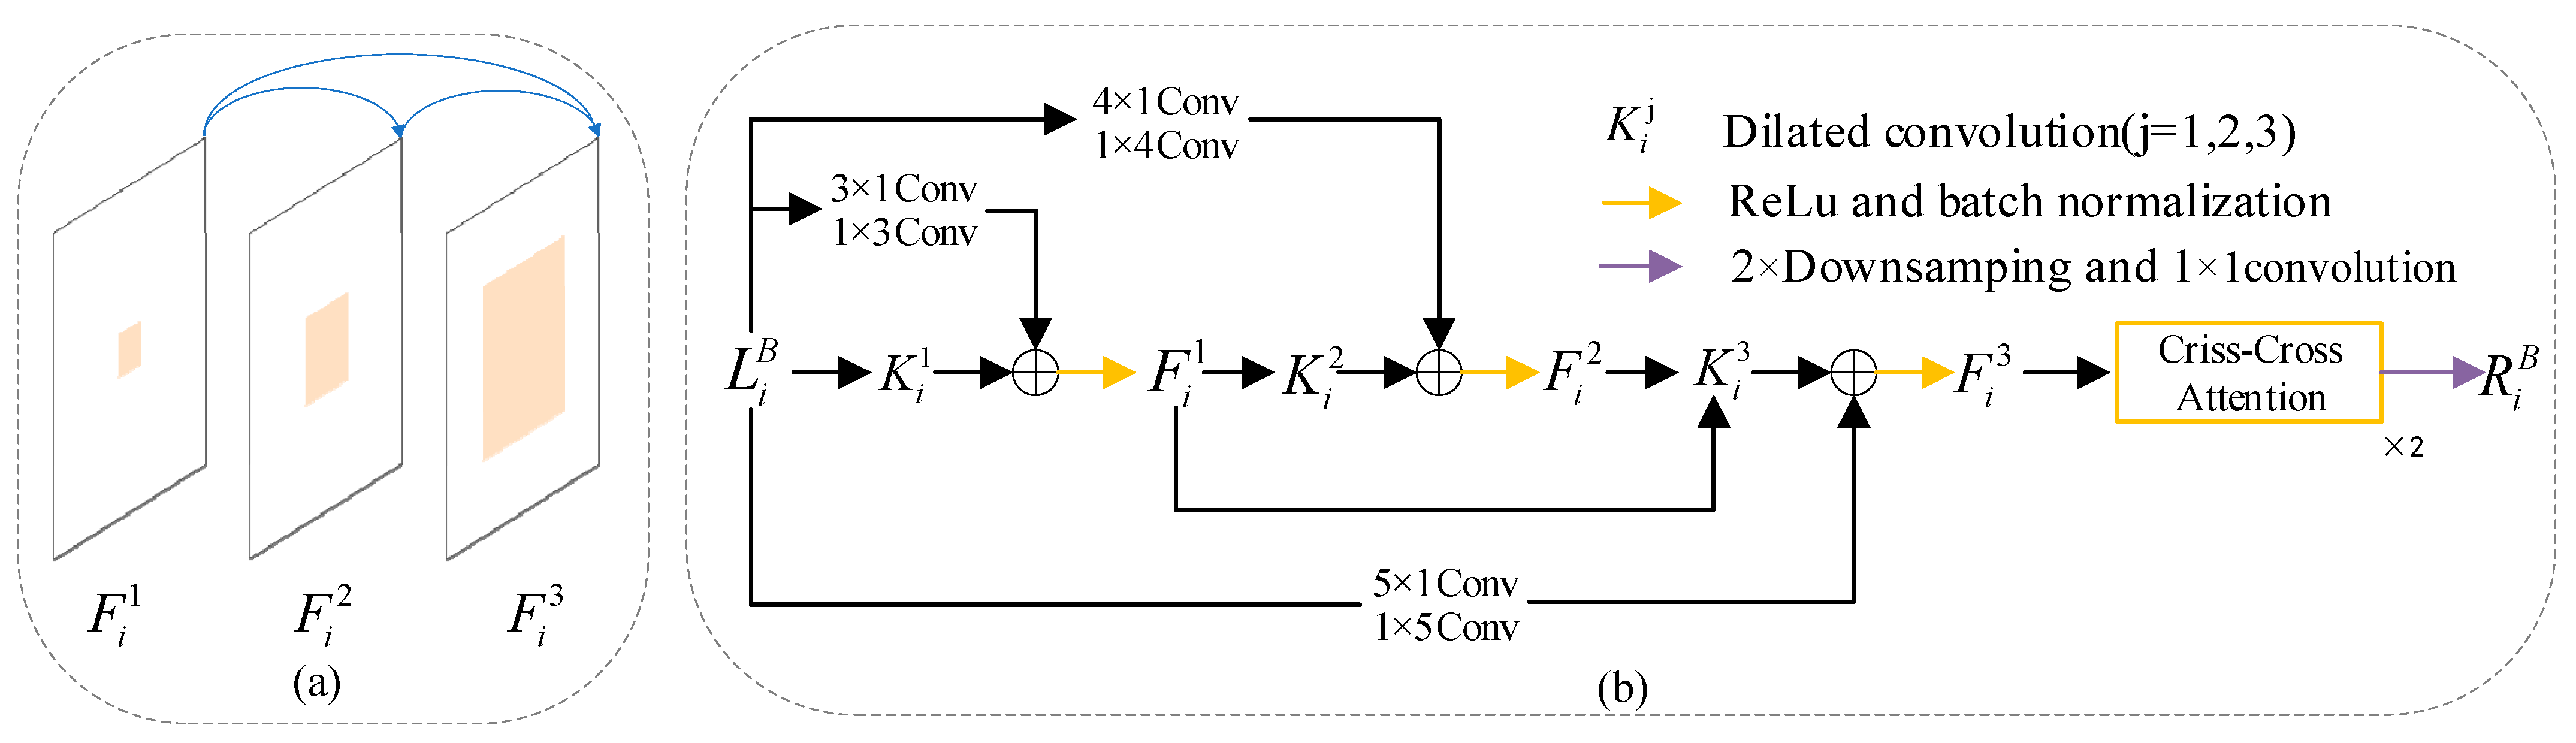
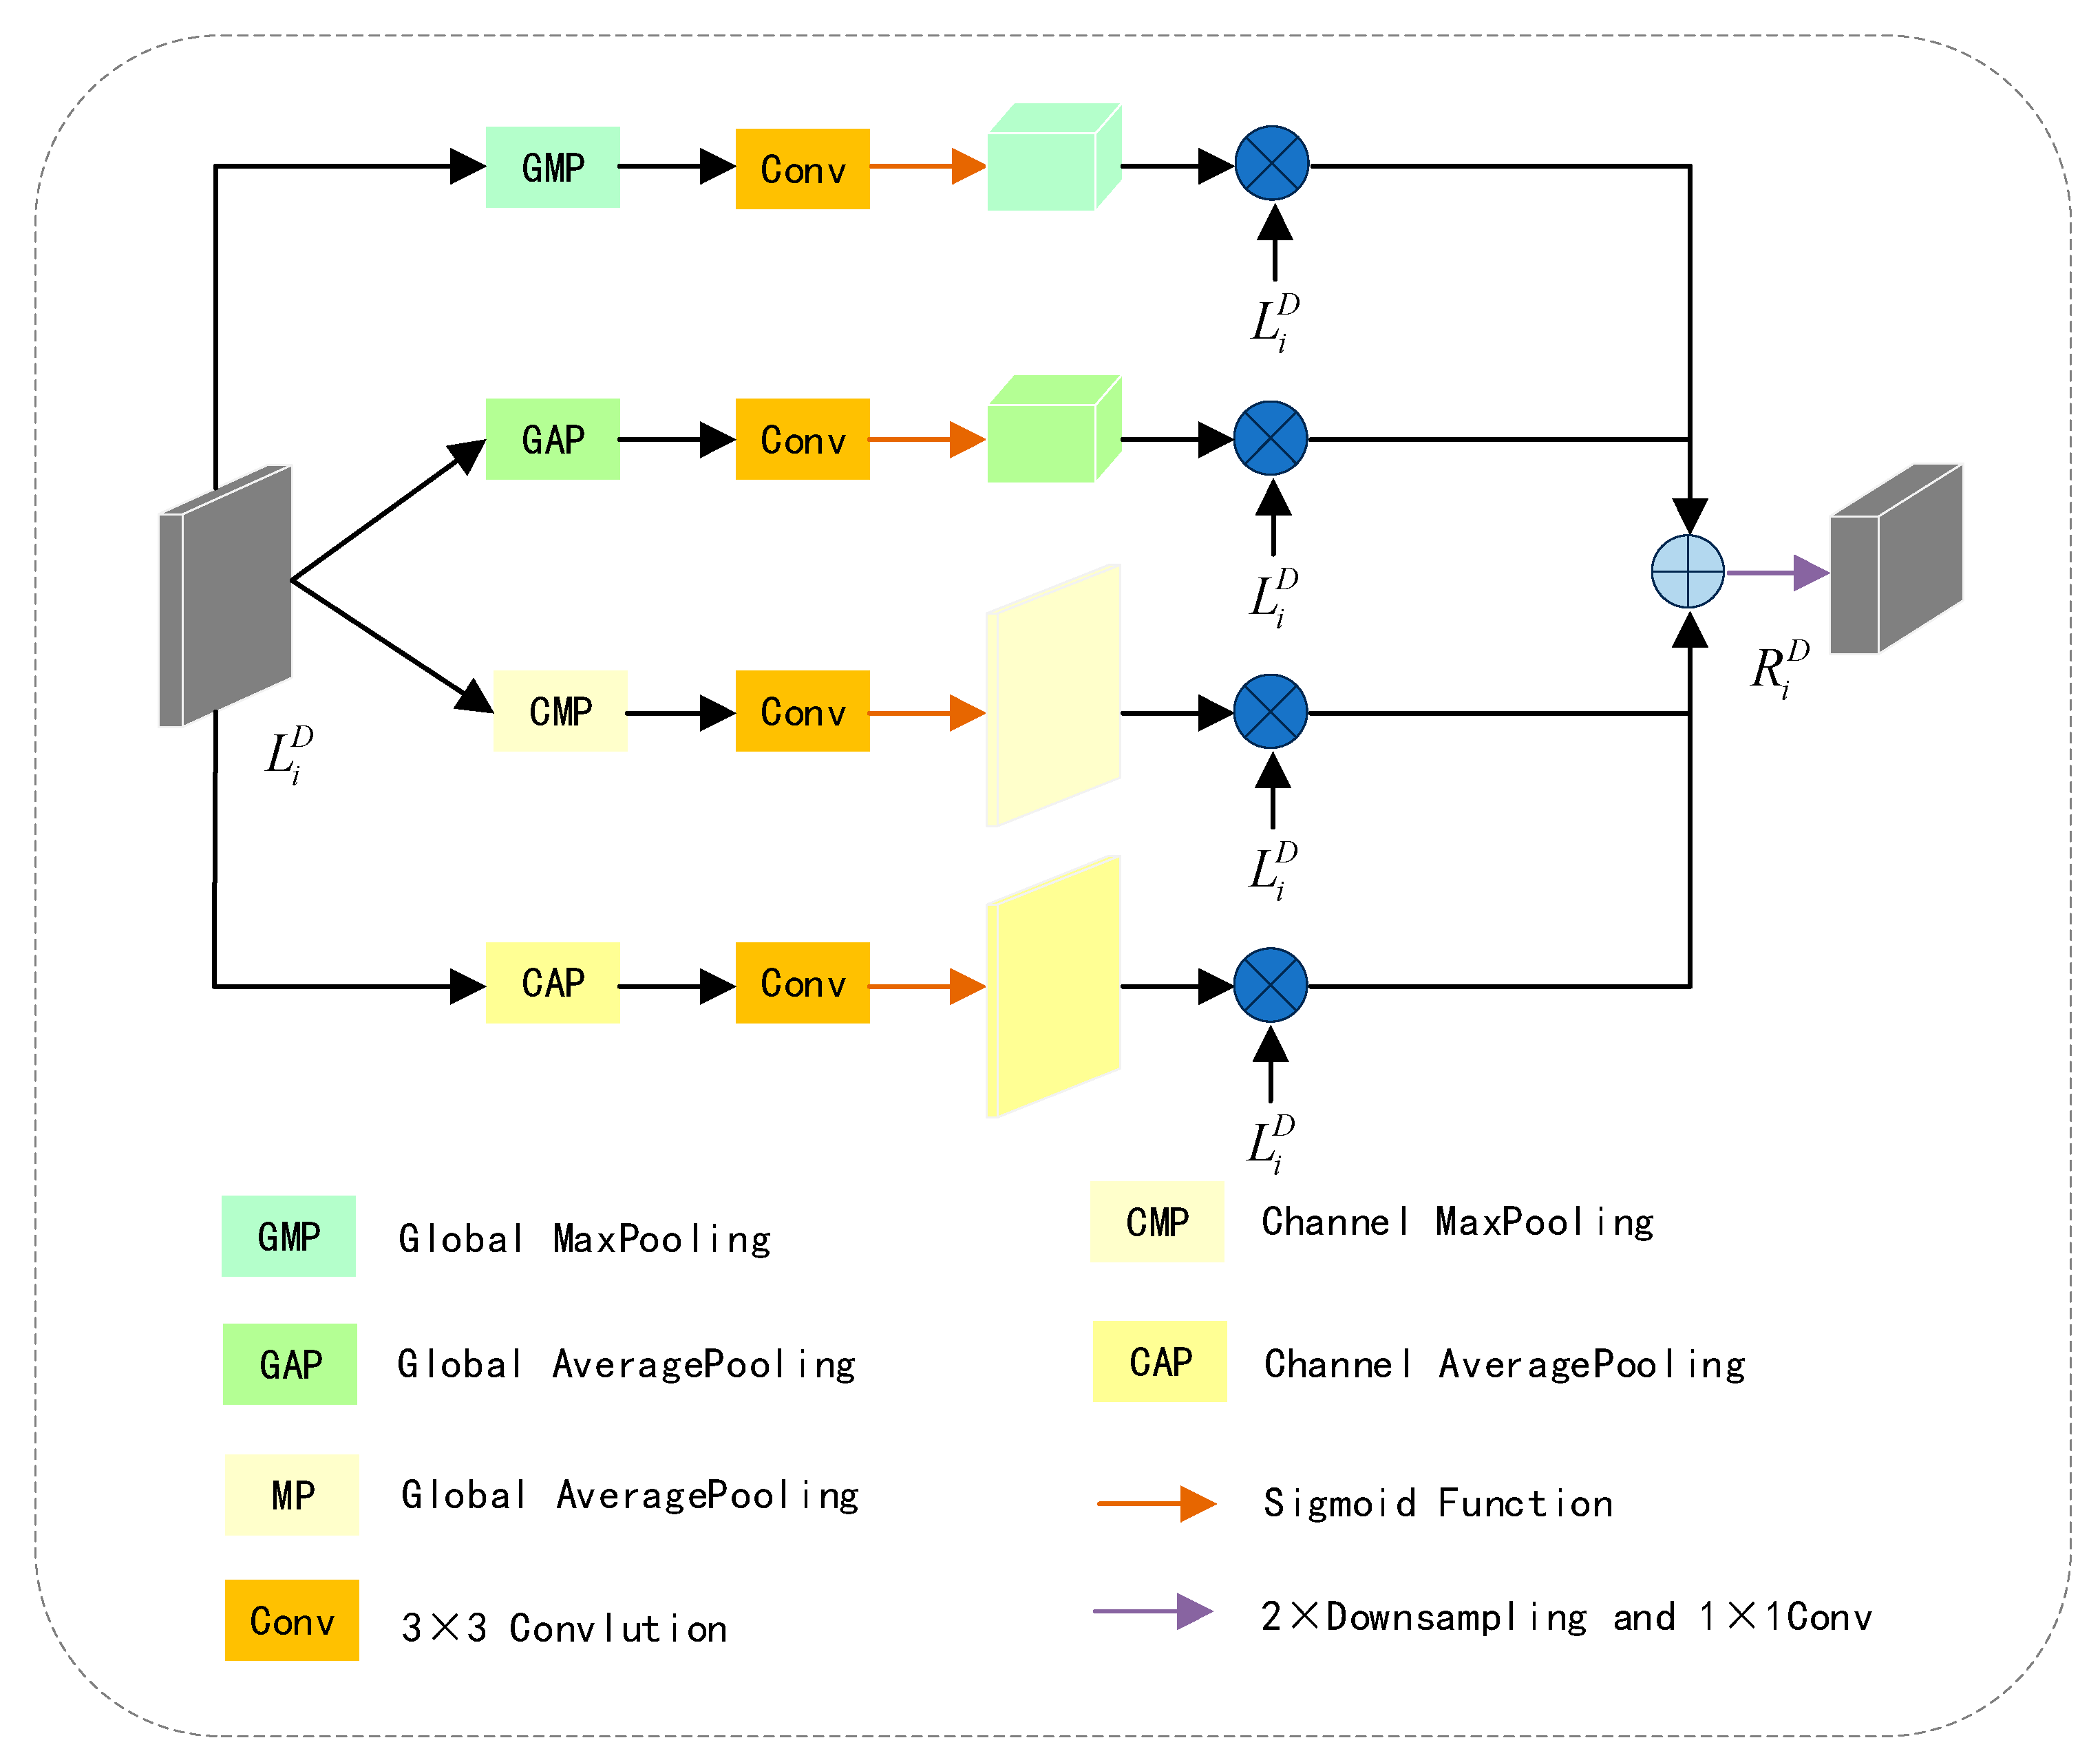
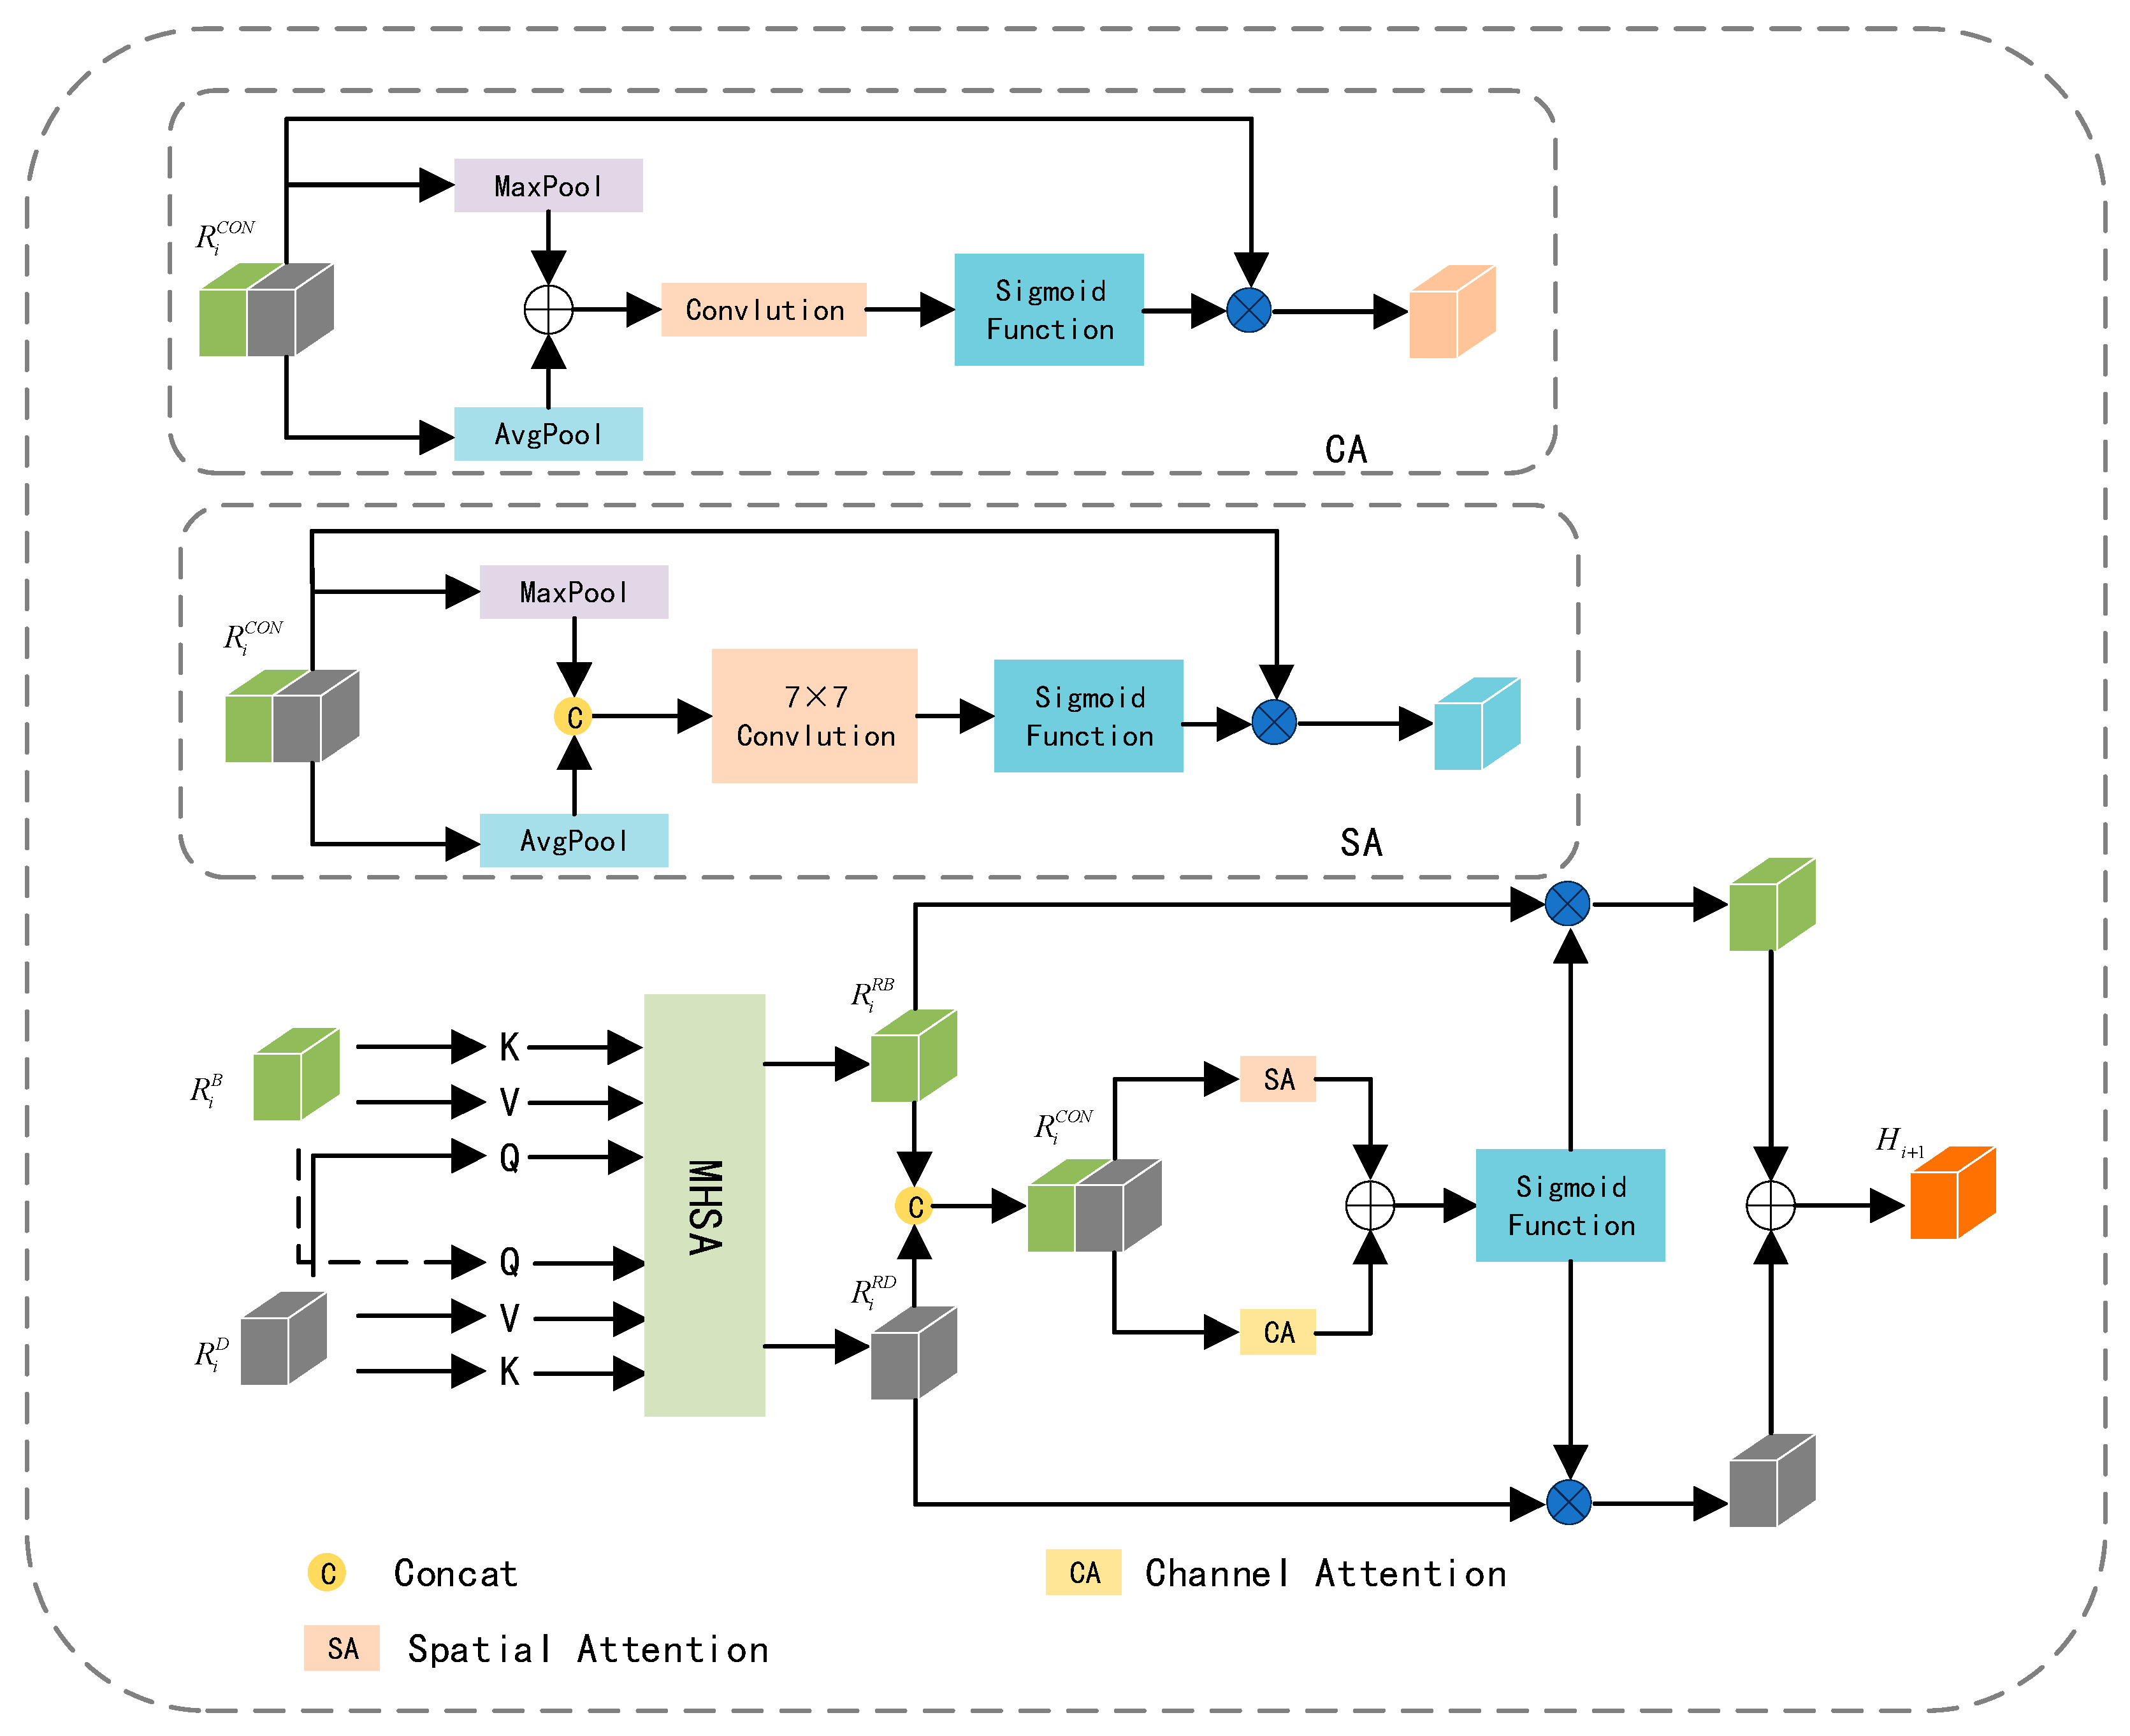
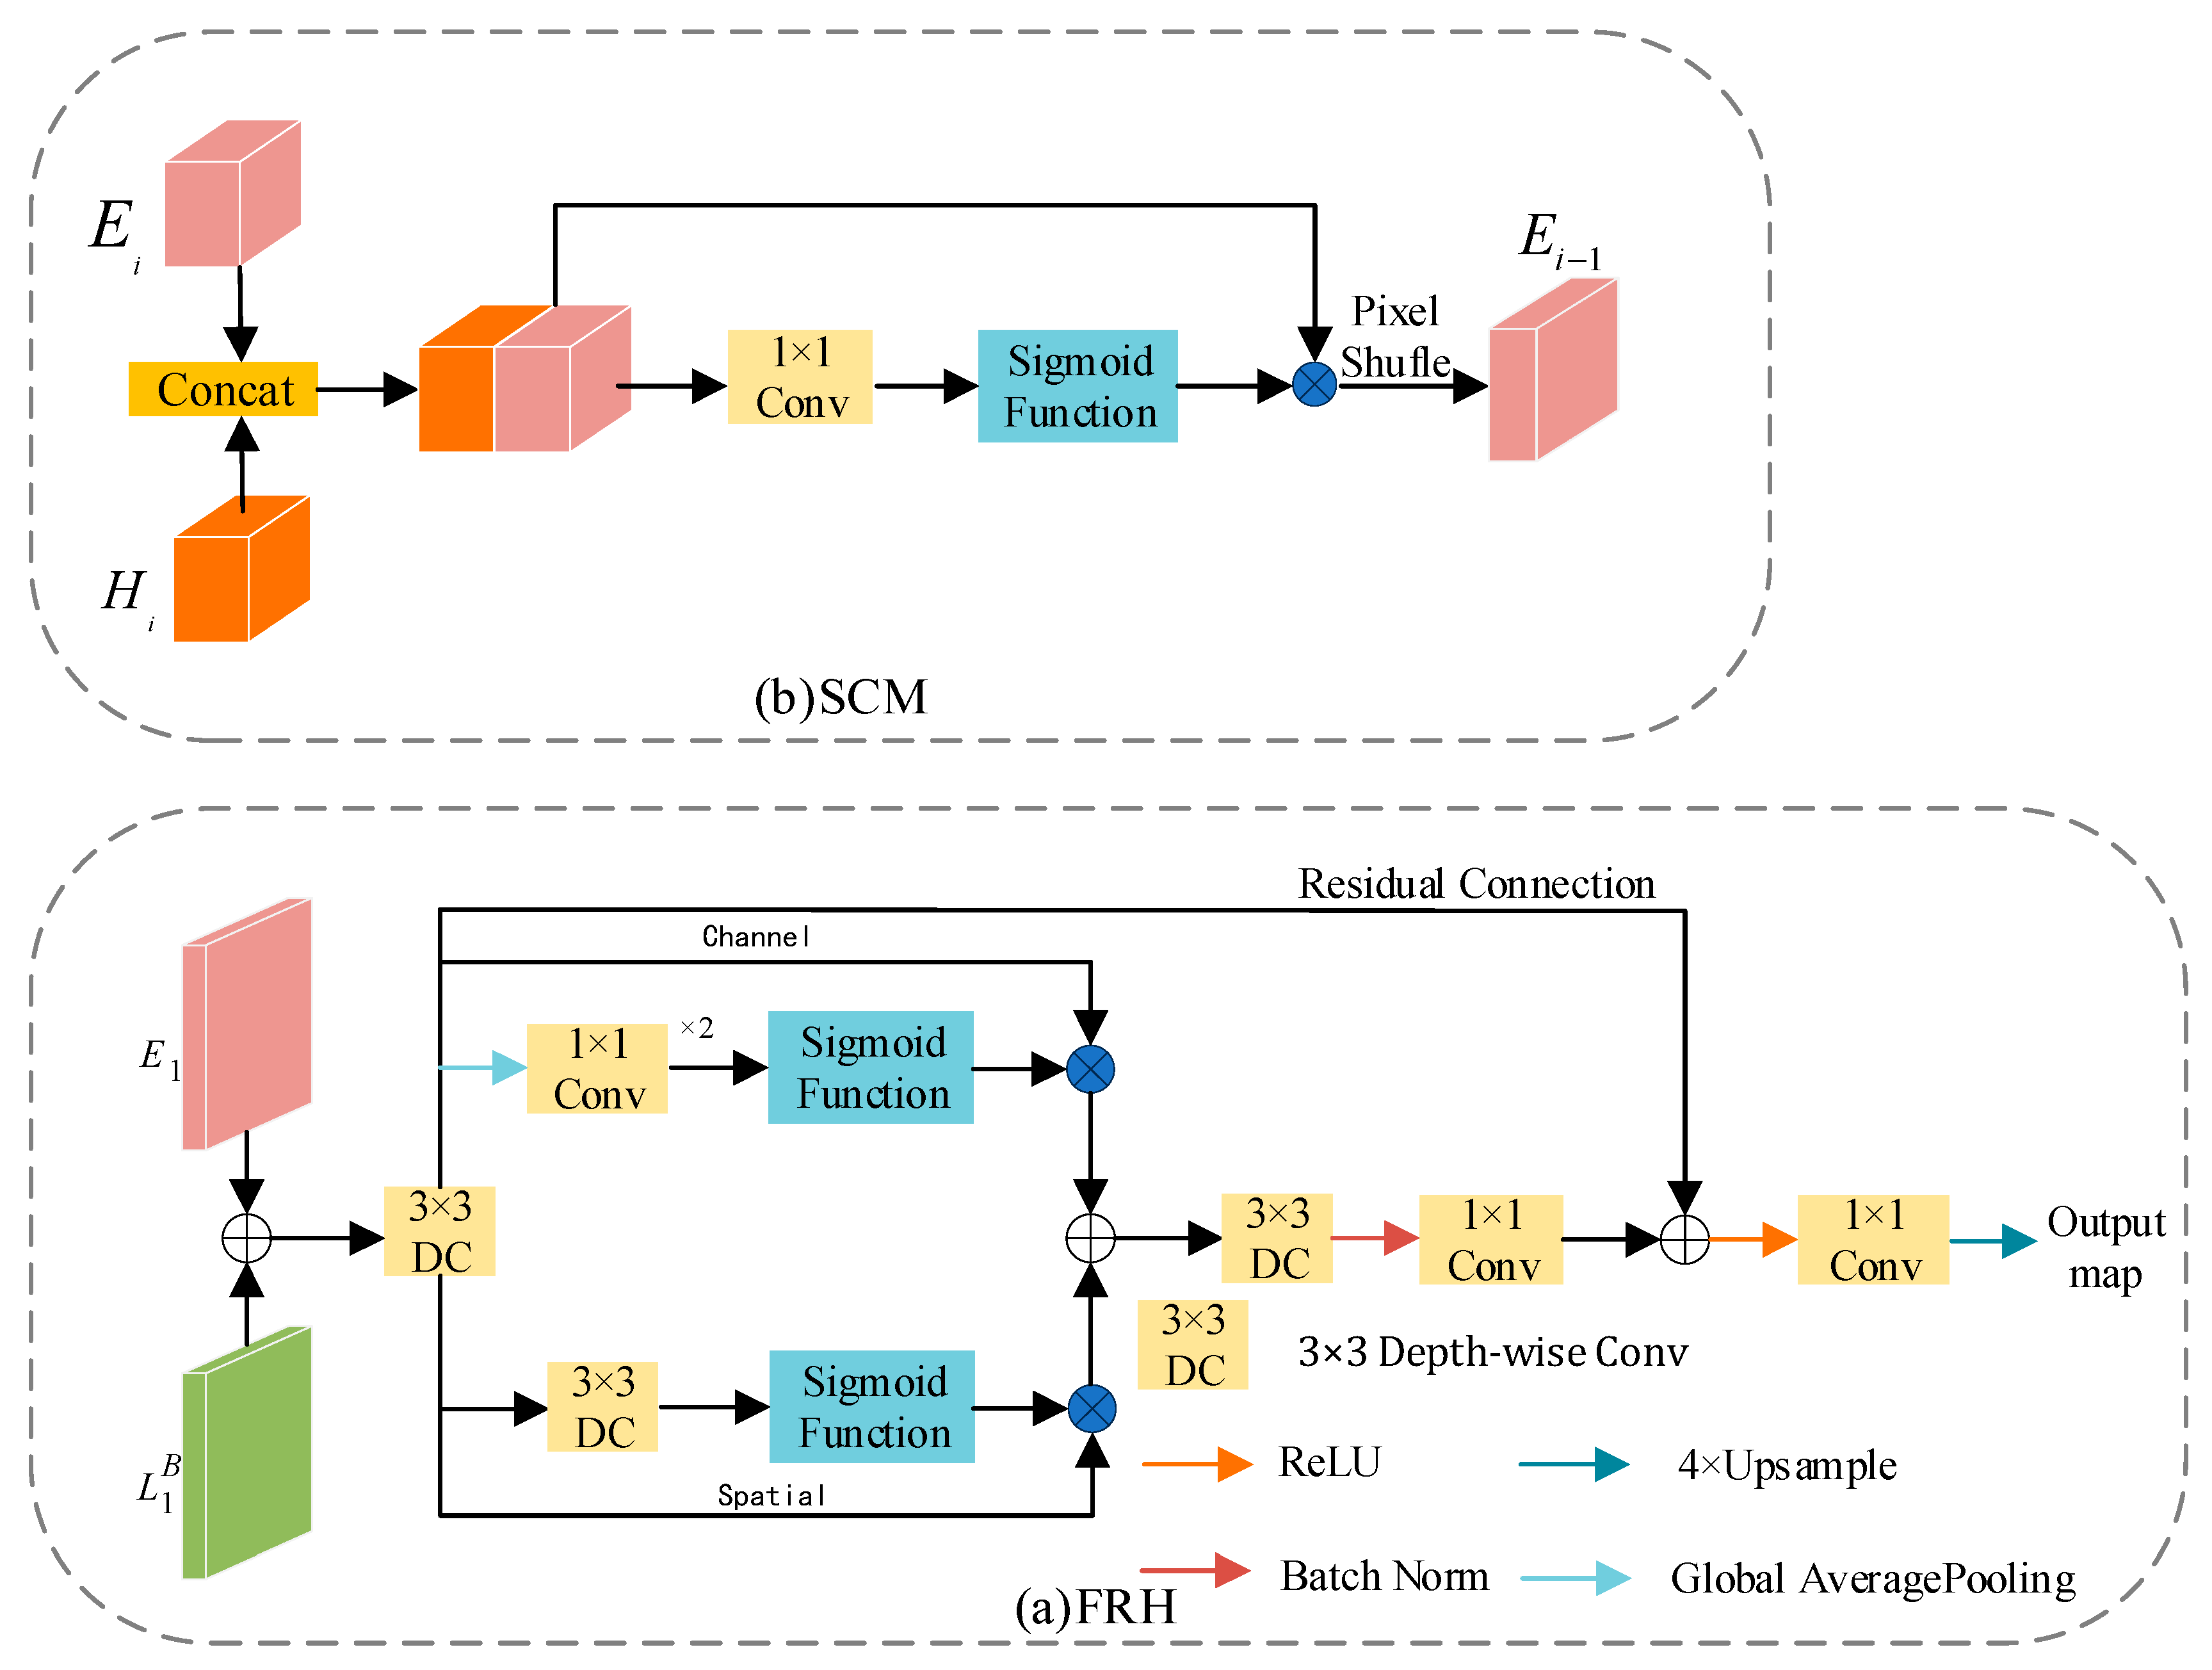
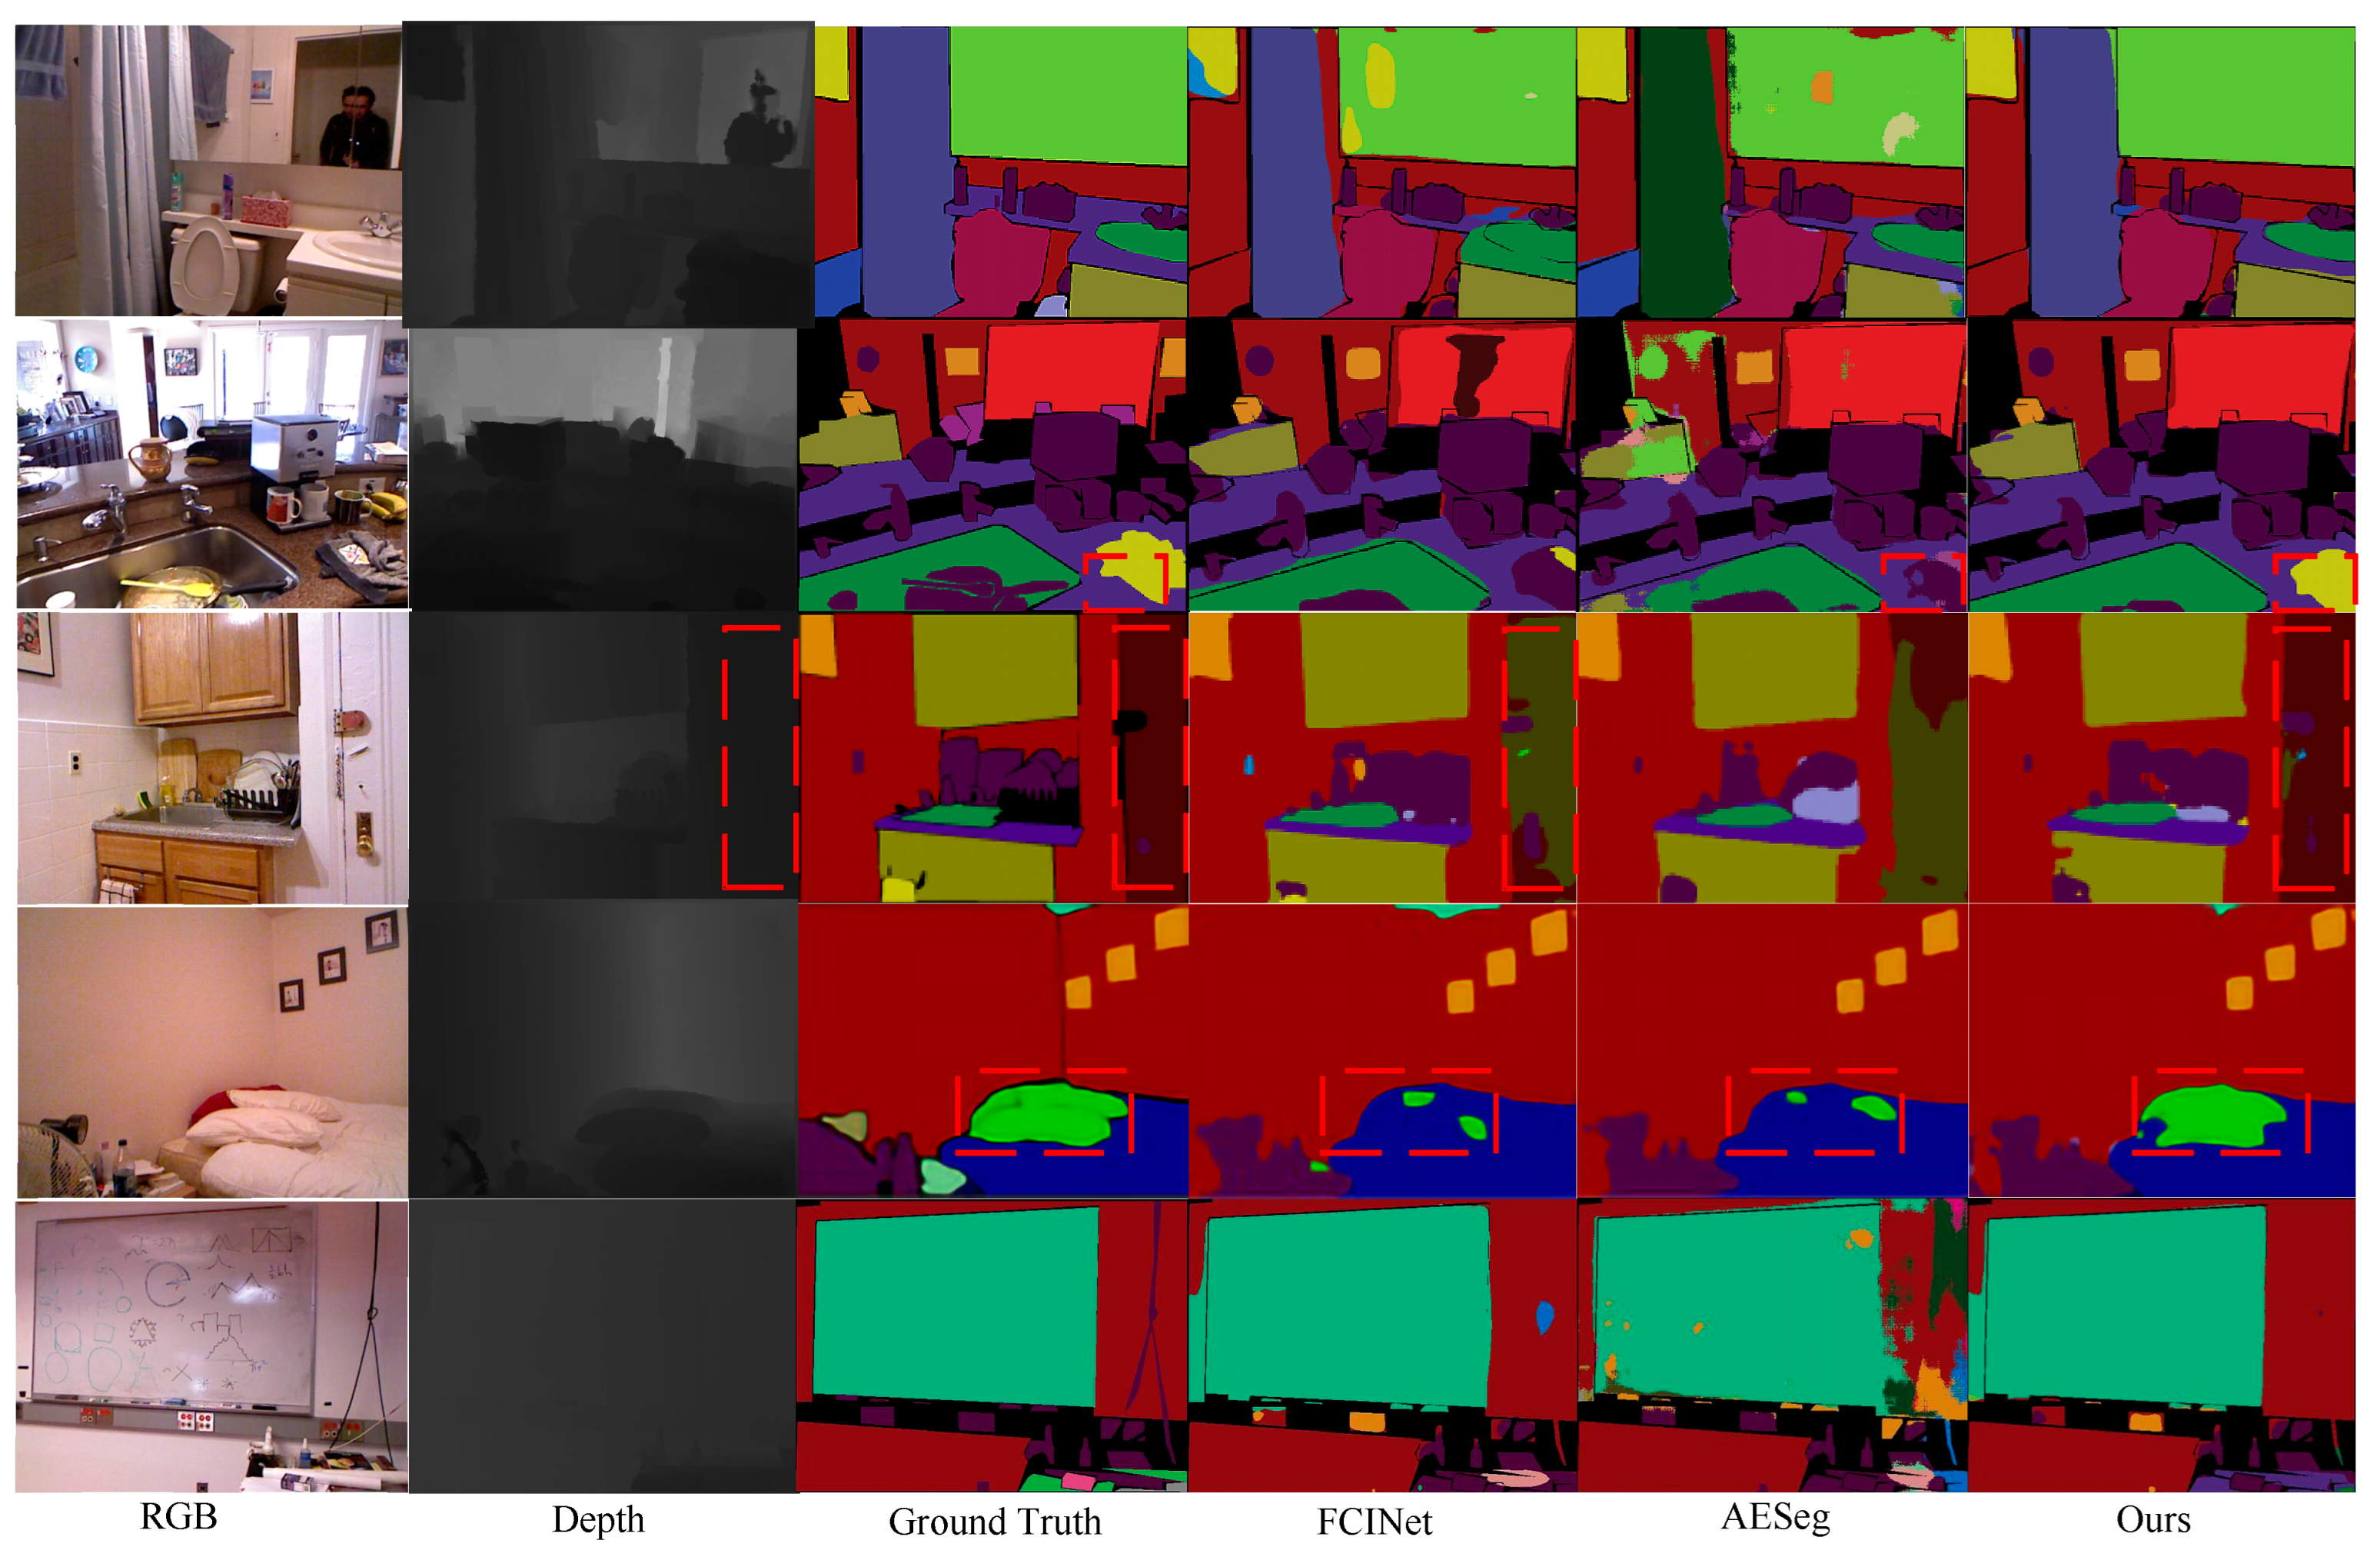
Indoor image semantic segmentation technology is applied to fields such as smart homes and indoor security. The challenges faced by semantic segmentation techniques using RGB images and depth maps as data sources include the semantic gap between RGB images and depth maps and the loss of detailed information. To address these issues, a multi-head self-attention mechanism is adopted to adaptively align features of the two modalities and perform feature fusion in both spatial and channel dimensions. Appropriate feature extraction methods are designed according to the different characteristics of RGB images and depth maps. For RGB images, asymmetric convolution is introduced to capture features in the horizontal and vertical directions, enhance short-range information dependence, mitigate the gridding effect of dilated convolution, and introduce criss-cross attention to obtain contextual information from global dependency relationships. On the depth map, a strategy of extracting significant unimodal features from the channel and spatial dimensions is used. A lightweight skip connection module is designed to fuse low-level and high-level features. In addition, since the first layer contains the richest detailed information and the last layer contains rich semantic information, a feature refinement head is designed to fuse the two. The method achieves an mIoU of 53.86% and 51.85% on the NYUDv2 and SUN-RGBD datasets, which is superior to mainstream methods.
Keywords: cross-modal fusion; RGB-D; feature extraction; feature interaction cross-modal fusion; RGB-D; feature extraction; feature interaction