


Abstract
Functional time series (FTS) modeling has emerged as a powerful framework for capturing complex temporal dependencies using the functional autoregressive models FAR(p, m) and FARX(p, m, τ). These functional models characterize the evolution of functional observations by incorporating ‘p’ lagged functional responses, ‘m’ truncated dimensions from functional principal component analysis (FPCA), and τ number of scalar covariates with optimal parameter selection guided by the minimization of the functional final prediction error fFPE(p, m). The aim of this study is to propose a computationally efficient FAR model that can integrate a number of functional covariates to achieve a high predictive accuracy in terms of standard out-of-sample accuracy measures. To this end, an integrated functional autoregressive model FAR is developed, where X denotes the exogenous information, this being a lagged or modeled functional profile within the FAR(p, m) framework, and ‘’ represents a vector of optimal dimensions for a number of functional covariates. The theoretical contributions are twofold: first, deriving the distribution of the modified functional final prediction error, denoted as fFPE; second, using this derivation to establish formal criteria for optimal model selection. To empirically investigate the predictive performance of the proposed model, hourly temperature data from the NASA POWER project are considered, and day-ahead out-of-sample forecasts over a full annual cycle are computed. The forecasting performance of the proposed model is assessed against state-of-the-art models using different error summary metrics. The results show that functional models consistently outperform traditional time series and neural network-based approaches, with FAR achieving superior predictive accuracy compared to FAR(p, m) and FARX(p, m, τ), thereby underscoring the efficacy of incorporating functional exogenous information in FTS modeling.
Keywords:
functional autoregressive models; forecasting; functional final prediction error; functional principal component analysis; ARIMA; temperature MSC:
62M10; 62R10; 46-11; 62J05
1. Introduction
Climate patterns exhibit intricate variability, driven by complex interactions between atmospheric, oceanic, and terrestrial systems. Understanding these patterns is crucial for predicting extreme weather events, assessing climate change impacts, and developing effective mitigation strategies. Among the many climatic variables, temperature plays a pivotal role, serving as a primary driver of atmospheric circulation, precipitation dynamics, and weather extremes [1]. It is a fundamental variable in meteorology, shaping the intricate patterns of weather systems and influencing atmospheric circulation. As key drivers of energy exchange within the Earth’s climate system, temperature variations dictate the formation of storms, heatwaves, and cold spells, making them crucial parameters for understanding and predicting complex weather structures. Moreover, long-term temperature trends serve as vital indicators of environmental changes, including global warming and shifts in regional climate regimes. Accurate modeling and forecasting of temperature are essential for climate resilience, disaster preparedness, and sustainable environmental policies [2,3].
To accurately forecast air temperature, researchers used different methods that vary in complexity, methodology, and performance. For example, ref. [4] used linear regression to model the daily maximum temperature data with geopotential thickness forecasts as a covariate for the site in Nashville, Tennessee. The study reveals that forecasting accuracy of daily maximum temperature is high for warmer air, whereas in the winter season, the forecasting accuracy tends to decrease. Although this method improves daily maximum temperature modeling, it has limitations, including dependence on geopotential thickness forecasts, seasonal effects, and other environmental factors. In the context of producing long-horizon predictive densities, which are crucial for pricing weather derivatives, the daily average temperature data are modeled by various authors [5,6]. For pricing temperature derivatives, the Chicago Mercantile Exchange (CME) defines the daily average temperature underlying its contracts as the mean of the daily high and low temperatures. In an evaluation using daily average temperature data from the United States of America, ref. [7] proposed an Extreme Value Theory (EVT) approach that outperformed classical models such as AR, generalized autoreggresive hetroskedasticity (GARCH), and standard regression.
Based on 62 years of historical time series (TS) data from Zhengzhou, China, ref. [8] modeled the daily average temperature using a mean-reverting Ornstein–Uhlenbeck process to provide accurate pricing for weather derivatives. Recent advances in nonlinear and complex time series modeling include Markov switching bilinear models for higher-order spectral analysis and threshold-based stochastic volatility frameworks which are capable of capturing asymmetric dynamics and regime changes [9,10]. Heatwaves significantly impact society and hence are referred to as highlighting the importance of modeling temperature. Ref. [11] evaluated the Regional Atmospheric Modelling System (RAMS) for predicting maximum and minimum summer temperatures in the Valencia Region from 2007 to 2010. The results show that the model predicts maximum temperatures well, with small errors of about 2 °C. The impact of global warming based on daily minimum and maximum temperature data from Coimbra in Portugal is assessed by [12] using the Hadley Centre model and a neural network. The results suggest that the two-layer neural network outperforms the competitors. Ref. [13] used the Abductory Induction Mechanism (AIM) as a modeling tool for temperature forecasting within a machine learning framework. Using daily maximum temperature data from the city of Dhahran in Saudi Arabia, the model was validated, achieving 97% accuracy within a range of ±3 °C, and hence provides better predictions than other traditional models. A novel abductive network model is developed by [14] to forecast a day-ahead and hour-ahead temperature data. The aforementioned model was trained using 5 years of hourly data and tested for the next whole year, for which the mean absolute errors (MAEs) of day-ahead and hour-ahead forecasts were 1.68 °F and 1.05 °F, respectively. Multiple linear regression and three artificial neural networks—feed-forward backpropagation (FFBP), radial basis function (RBF), and generalized regression neural network (GRNN)—have also been applied to model daily minimum, average, and maximum temperatures [15]. These models are evaluated against the geographical location of Turkey’s most important areas for agricultural production—the Geyve and Sakarya basins—which are located in the southeast of the Marmara region. The study reveals that the three ANN models outperform the classical benchmark.
A comparative study of data-intelligent models, namely a generalized regression neural network (GRNN), multivariate adaptive regression splines (MARSs), random forest (RF), and extreme learning machines (ELMs), is presented by [16], in which longitude, latitude, altitude, and periodicity are used as covariates rather than traditional atmospheric features such as humidity, precipitation, etc. These models were implemented at eleven different sites in Madhya Pradesh, central India, and the results show that the GRNN works more effectively for modeling air temperature, particularly in data-sparse regions where only geographic and topographic factors are utilized for temperature forecasting. One can also read [17] for an in-depth review of air temperature modeling using machine learning and neural network models, respectively. A systematic literature review (from 2019 to 2024) in connection with modeling and forecasting daily temperature is also given in Table 1.
Table 1.
Summary of literature review.
Accurate day-ahead temperature forecasts are essential for energy, agriculture, and public health, as they help optimize resource management and reduce climate-related risks. Traditional methods often struggle to capture the continuous and complex nature of temperature variations. To overcome this deficiency, this research work contributes an effort to model and forecast the daily temperature curves using functional data analysis (FDA). To this end, a novel functional autoregressive model FAR is developed and the distribution of the modified functional final prediction error fFPE is derived for optimal model selection.
The rest of the article is structured as follows. Section 2 provides an introduction to functional data analysis along with the fundamental tools necessary for its implementation. Section 3 presents the development of a new functional model, including discussions on classical and functional competitors. An empirical application of the proposed methodology is provided in Section 4, where the results are analyzed in detail. Finally, Section 5 concludes the study.
2. Functional Data Analysis
FDA offers a strong and promising framework for treating complex and high-dimensional datasets. Within FDA, data are represented as smooth curves or functions rather than discrete points or vectors [36]. This technique contrasts with traditional approaches that often concentrate on summary statistics or discrete observations. There are diverse applications of FDA in various disciplines such as medicine, finance, neuroscience, economics, environmental studies, and quality control [37,38]. A systematic review about the applications of the FDA in various fields for the period from 1995 to 2010 is given by [39]. A recent study [40] involves forecasting crude oil prices using derivative information in a multivariate empirical mode decomposition (MEMD) model within the FDA framework, which results in better performance as compared with traditional time series models. An application of the FDA to analyze the behavioral patterns of the Colombian stock market, specifically the effects of COVID-19 and the aftermath of the Ukraine war, is conducted by [41]. Ref. [42] employed the FDA approach to predict age-specific brain cancer mortality trends for planning public health policies and resource allocation. FDA has also significantly contributed to numerical weather prediction. For example, it is utilized to create point and interval forecasts for drought time series patterns [43]. They developed a reliable predictive method for predicting drought intervals. Based on the FDA technique, ref. [44] illustrated the temporal changes of rainfall to assist in forecasting the future and to achieve a clear understanding of rainfall patterns. Ref. [45] implemented the FDA framework to forecast temperature and precipitation under various climate change scenarios. Ref. [46] performed FPCA to model the structure of rainfall. A functional autoregressive model of the first order, FAR(1), is explored to forecast hourly air temperature up to 24 h ahead, where the traditional time series model ARIMA served as the competitor, and the results suggest that FAR(1) is superior. Online auction prices and traffic volume are also predicted under the FDA framework by [47,48,49], respectively. Due to substantial fluctuations, ref. [50] indicates a non-linear and complex structure in electricity consumption, demand, and prices. Refs. [51,52,53] applied the FDA to estimate and forecast electricity consumption and demand, respectively. Hour-ahead electricity demand forecasting strategies are implemented using non-parametric FDA [54,55,56,57], and the results significantly outperform those obtained from the classical seasonal ARIMA (SARIMA) models.
2.1. Preliminaries
Let denote a stationary functional time series of observations, where t represents the time index and υ the argument in the continuous domain of each function. Each is assumed to belong to the Hilbert space with the inner product . Thus, each is square-integrable, satisfying , and all random functions are defined on a common probability space . For p > 0, we write if . Since the series is not necessarily centered, we define the mean function , and the covariance operator of the centered functions as:
or equivalently via its kernel representation
with
Equation (1) expresses the covariance operator C as an integral operator with kernel , while Equation (2) defines this kernel as the covariance between the functional observations at points υ and γ. For a more detailed discussion of covariance operators in functional time series, the reader is referred to [58].
2.2. Basis Function System
In the FDA framework, a basis function system (BFS) plays a crucial role in converting discrete data into a functional object, enabling a more compact representation without losing essential information. Various types of basis function systems exist, including polynomial, B-spline, and Fourier basis functions (FBFs), each suitable for different data structures. Among these, FBF, which consist of sine and cosine waves with increasing frequency, are particularly effective for modeling periodic data. FBFs are especially useful for cyclical environmental data, such as temperature, wind speed, and atmospheric pressure, where seasonal and diurnal variations play a crucial role. The sinusoidal components of the FBF effectively capture periodic fluctuations, providing a smooth and continuous representation of temperature profiles. A Fourier basis function is defined as
where j denotes the Fourier frequency index and is the fundamental frequency function, typically defined as , . Using M Fourier basis functions, the functional observation at time t can be approximated as
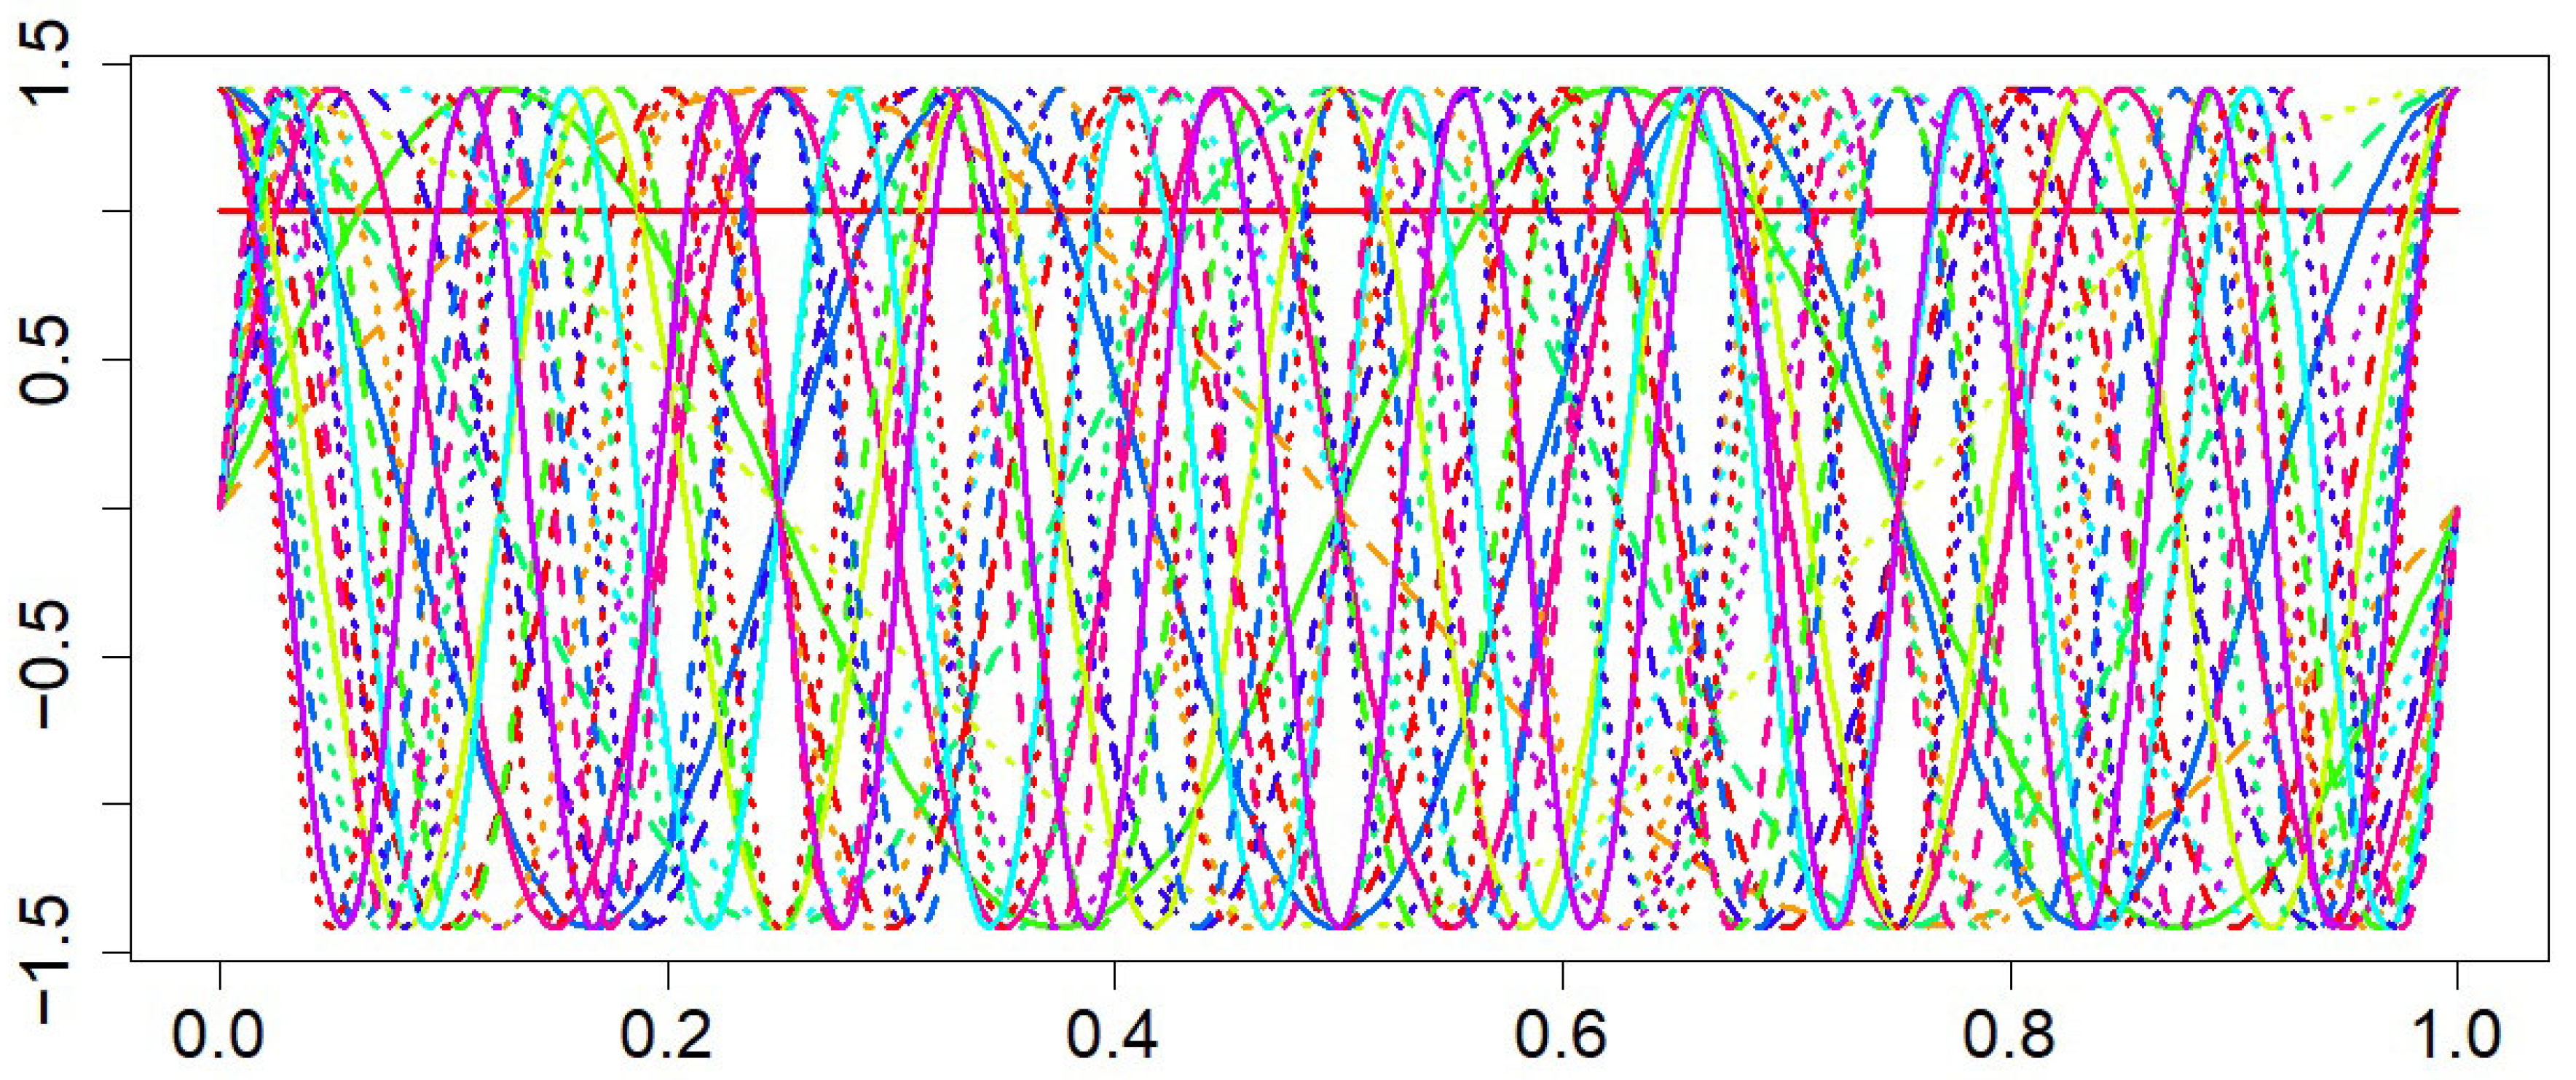
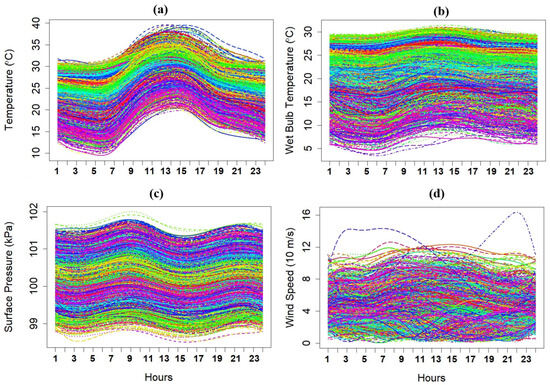
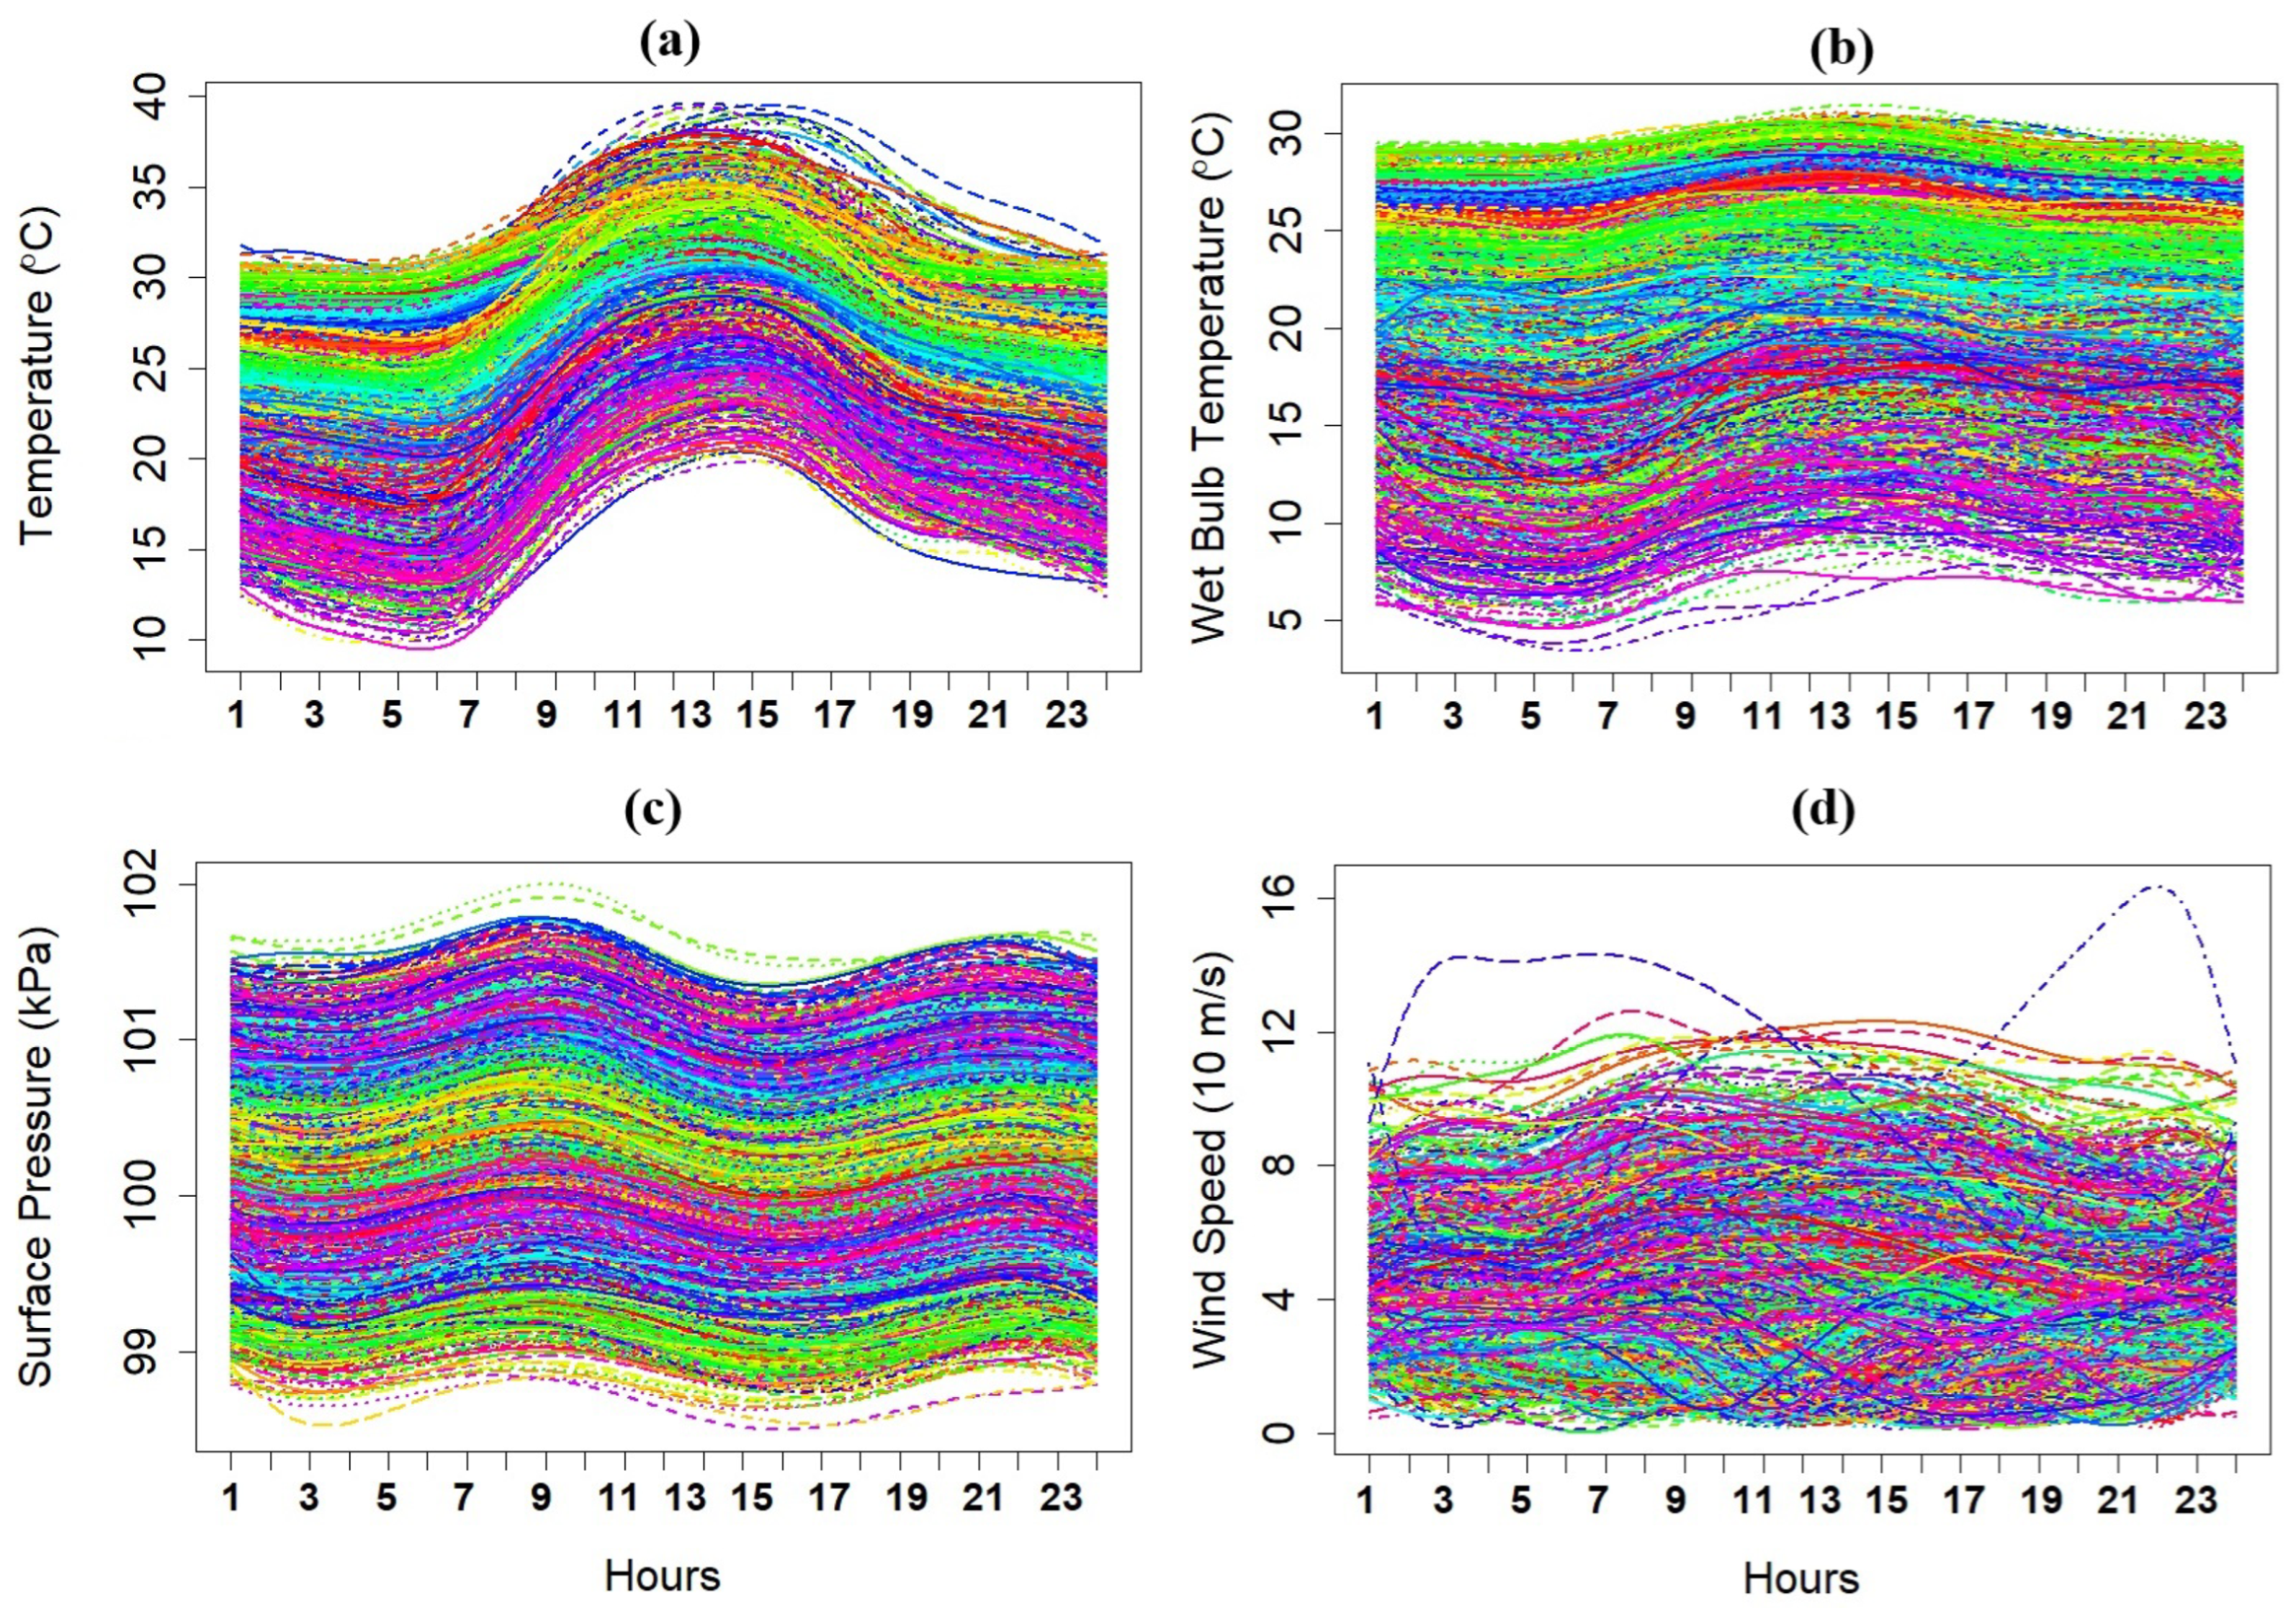
where are time-varying Fourier coefficients and form the Fourier basis function system. An example of functional data, based on M = 20 FBFs represented in Figure 1, for the years 2019 to 2024 reflects 2192 daily temperature curves in Figure 2. The is known as the functional time series (FTS) where one can investigate the major source of variation among different temperature curves.
Figure 1.
The Fourier basis functions using M = 20.
Figure 2.
Functional data representation of (a) response variable; (b) first exogenous variable; (c) second exogenous variable; (d) third exogenous variable, under study using Fourier basis functions.
2.3. Functional Principal Component Analysis (FPCA)
Suppose we observe an FTS, , consisting of n curves, where . The mean function is defined as . The mean-centered curves are then given by
Let denote the jth FPC. Each mean-centered curve can be projected onto in the Hilbert space . The corresponding FPC score is defined as
The FPCs satisfy the normalization condition ensuring the identifiability of the scores. The covariance operator of the mean-centered process is defined as . According to Mercer’s theorem, C admits the spectral decomposition
where are the eigenvalues in decreasing order and are the corresponding orthonormal eigenfunctions [59]. Using the Karhunen–Loève expansion, each functional observation can be expressed as
where and . For dimension reduction, we retain the first m FPCs and obtain the approximation [60,61]
where the third term in the above expression accounts for the variability not explained by the first m functional principal components and has zero mean and finite variance [62]. In practice, the mean function and covariance kernel are estimated as
Let and denote the eigenvalues and eigenfunctions of . The reconstructed FTS is then given by
where .
3. Functional Time Series Modeling
An FTS captures nonlinear dependencies while preserving smooth temporal structures, making it particularly suitable for modeling complex dynamic processes. This section discusses the existing methodologies and the new developed approach which can effectively handle such dependencies. Despite its statistical relevance and mathematical appeal, functional time series modeling has practical limitations. Few user-friendly software packages exist, with notable exceptions being the far [63] and ftsa [64] packages in R version 4.5.0 (2025-04-11 ucrt). The lack of dedicated tools often requires manual implementation, limiting its use to academicians. This article aims to bridge this gap by introducing a prediction algorithm.
3.1. Functional Autoregressive Models
An autoregressive (AR) model is a well-known linear model where the response variable is regressed over its lagged values plus a noise term [65,66]. If the response observations are functions defined over a continuous domain (rather than scalar or vector values), the autoregressive model is referred to as an FAR model. An FAR process and its theoretical properties are described in a Hilbert space framework, which is one of the best techniques for modeling the complex nature of FTS [67]. In traditional univariate and multivariate time series analysis, reliable predictions rely on recursive methods like the Durbin–Levinson algorithm and the innovations algorithm [68], which systematically update predictions based on past observations. Prediction equations for general stationary FTS can be derived explicitly. However, their practical implementation is challenging due to the infinite-dimensional nature of functional data. As a result, most of the research in this area is limited to FAR(1) models primarily due to the computational and theoretical challenges of estimating higher-order FAR(p) models, as functional time series are infinite-dimensional and more complex models require substantial data and computation for reliable parameter estimation. Mathematically, the FAR(1) model [69] is given in Equation (13) as
where is the functional mean curve, is the first lagged functional variable, is i.i.d. in such that , and ϕ is the linear operator bounded over mapping such that Equation (13) has a unique solution. If the FAR(1) approach is infeasible, the multiple testing procedure ensures a better fit to the data and can be used to determine the optimal order p [70]. A more general FAR(p) process is given by Equation (14), in which the kernel function yields a test statistic following an approximate chi-square distribution, with the degrees of freedom based on the number of FPCs being
where are the linear operators of corresponding p-lagged functional variables . Another approach for FAR(p, m) based on multivariate time series and FPCA, in which a VAR model is used with FPC scores. To implement the VAR model, an automatic procedure is suggested for selecting the optimal lag order (p) and dimension (m) by minimizing the final functional prediction error (fFPE) given in Equation (15).
where the first part is the product of a penalty term and the trace of an estimated covariance matrix of the residuals from a VAR model fitted to the FPC scores. n is the sample size in the penalty term. The second term represents the sum of eigenvalues associated with ignored principal components. The values of m and p, which minimize the fFPE, are the optimal values that are used in FAR(p, m). The predictive performance of FAR(p, m) is also increased by incorporating the τ number scalar covariates, namely the model FARX(p, m, τ) given as in Equation (16)
where are coeffcients of scalar covariates. Hence, the optimal orders p and m for Equation (16) are obtained by minimizing the fFPE, adjusted for degrees of freedom for scalar covariates as
For detailed discussions about Equations (13)–(17) and their applications to real data, one can consult [18,52,58] and the references therein.
3.2. Building Model
To enhance the forecasting accuracy of the FARX(p, m, τ) model, this work introduces a novel functional model, denoted as FAR. This model incorporates , where each g represents the optimum dimensions of corresponding functional exogenous variables, extending the standard framework. Additionally, a modified version of fFPE(p, m), is derived, leading to the formulation of fFPE for improved model selection.
Suppose a functional stationary response and functional exogenous variables are given and the goal is to derive an empirical . Then Equation (17) can be written as a FAR given as
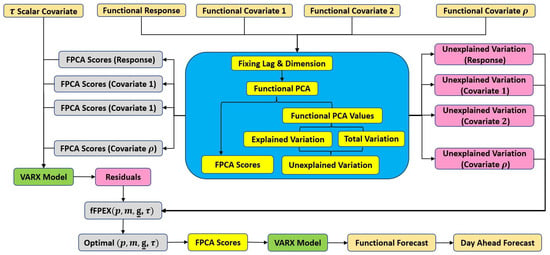
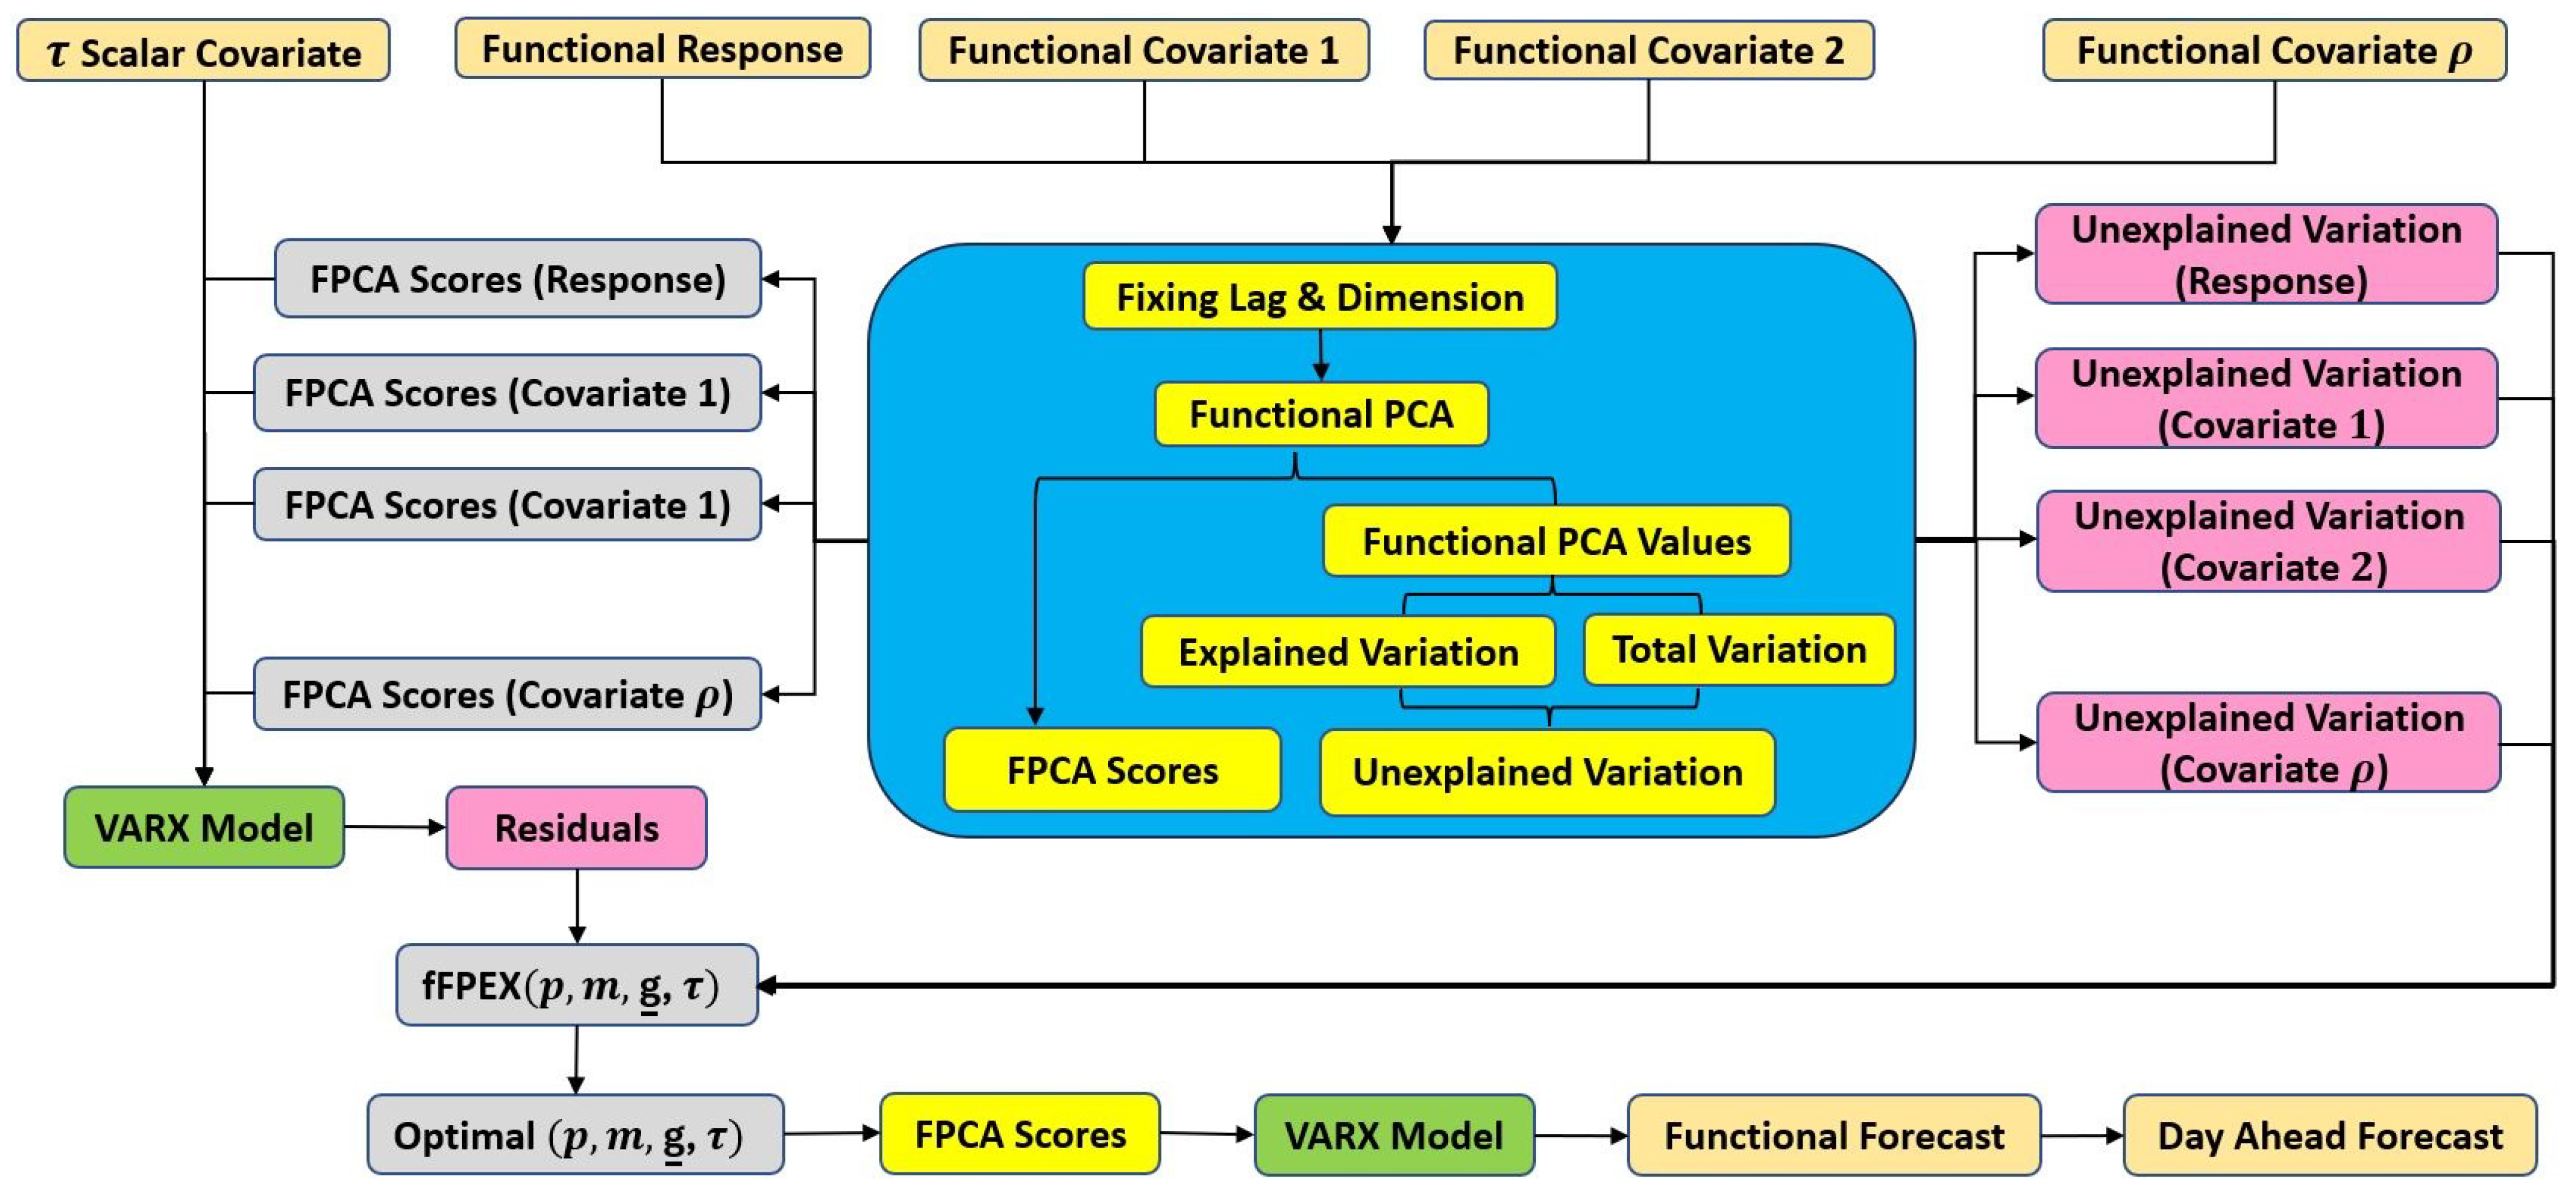
where are the functional operators of the ρ functional covariates of the above model. The rest of the notations are same as discussed in Section 3.1. In this work, we estimate the Equation (18) model using the FPCA approach. This method ensures both accurate model estimation and computational efficiency, as the first few FPCs capture most of the variation in the endogenous and exogenous functional variables. In this context, the identification step involves selecting the optimal dimensions m and lag order p for an endogenous functional variable and a set of optimal dimensions for a ρ number of exogenous functional variables. To achieve this, the following steps are employed for selecting and τ while a flowchart is given in Figure 3.
Figure 3.
Framework for the proposed functional model.
- 1.
- Based on the algorithm in Section 3.3, fix the dimension m of the functional endogenous variable. Using FPCA based on m dimensions, the estimated FPC scores are obtained for each of such that we have vectors of j-variate-estimated FPC scores where t = 1, 2, 3, …, k and j = 1, 2, 3, …, m.
- 2.
- Fix the dimensions for a ρ number of functional exogenous variables and obtain the estimated FPC scores for each of the .and so on,Such that we have vectors of -variate-estimated FPC scores, respectively.and so on,
- 3.
- If the number of scalar exogenous variables τ is sufficiently large, then it is better to use their functional form instead of their scalar form. That is, fix the dimensions τ using the same algorithm as described in Section 3.3. Using FPCA based on τ dimensions, the estimated FPC scores are obtained for , such that we have vectors of j-variate-estimated FPC scores where t = 1, 2, 3, …, k and j = 1, 2, 3, …, τ.
- 4.
- The first and second derivatives of functional data capture essential dynamic features, such as trends and curvature, making them valuable predictors for improving the accuracy and interpretability of functional response models. Therefore, using the same idea as discussed earlier, one can also use the derivatives of functional variables as predictors.
- 5.
- Once all vectors of estimated FPC scores from all functional and scalar exogenous variables are obtained, combine them into a single vector as follows: .
- 6.
- Next, fix the lag order p and using the estimated vector of FPC scores of endogenous variable obtained in Step (1) and the from Step (5), fit an appropriate multivariate model, for example the VAR model with an exogenous variable (VARX), given aswhere Γ is a matrix of coefficients of and is a white noise process. Then obtain a one-step-ahead forecast for as
- 7.
- In the last step, the is reverted to a functional object using the KL theorem and a one-step-ahead forecast in a functional form is obtained as
3.3. Selection of Optimal Orders by
The performance of FAR(p, m) clearly depends on the optimal selection of the order parameters p and m representing the lag and appropriate number of FPCs, respectively. Past studies suggest some techniques to get these optimal values for the FAR models. For example, the value of m was suggested by [70], based on multistage hypothesis testing. Also, a mechanical and automated technique is suggested for getting an optimum p and m based on minimizing the mean squared error (MSE) as proposed by [58], and called ffPE(p, m) in Equations (15) and (17), as discussed in Section 3.1. In this section, we demonstrate a modified ffPE(p, m) called fFPE, which is minimized for the selection of optimal parameter values where . We begin by analyzing the MSE. Since the eigenfunctions are orthogonal and the FPCs are uncorrelated, we can partition the MSE as follows:
Here, the usual Euclidean norm of vectors is represented by . In the above equation, the first term represents the finite-dimensional MSE for the approximation based on the truncated score vectors. Essentially, it quantifies the error within the selected subspace of dimension m. This finite-dimensional space contains the most significant components (typically derived from the eigenfunctions of the functional data), allowing us to approximate using a lower-dimensional projection. The second term captures the information loss due to truncation at dimension m. Here, represents the eigenvalues associated with the components beyond m. By truncating at m, we exclude components with eigenvalues which means losing some functional information, as these components are no longer part of the approximation. The third term captures the information loss due to truncation at dimension based on ρ number of functional covariates. Here l is the index of the functional covariate ranging from 1 to ρ, while r indexes the higher-order terms beyond the optimal dimension . captures the information loss due to truncating the functional covariate at its dimension and corresponds to the eigenvalue of the principal component of that covariate, quantifying the variance it explains. Summing over all components beyond accounts for the total information lost due to dimension reduction, analogous to for the response. Hence, the third term represents the cumulative contribution of the truncated higher-order components of the functional covariates beyond the selected optimal dimensions . Assuming the stationarity of the process is a -variate , where , has the following form:
where Γ is a matrix of coefficients of and is a white noise process such that
where
is the least squares estimator of , is the difference between the estimator and the true parameter vector scaled by and , and . The asymptotic distribution suggests that as , this scaled difference converges to a normal distribution with a zero mean and a covariance structure-determined Kronecker product of and . Suppose that the are estimated from an independent training sample . It follows then that
The first term is the intrinsic noise variance from the white noise process and second term is obtained from the estimation error, which is expressed compactly using the Kronecker product (⊗) and vector notation represents the past values in the autoregressive component, and combined from a reduced dimension from functional covariates and scalar exogenous variables. The independence of and yields that
represents the overall variance–covariance structure for the autoregressive, functional exogenous, and scalar terms. By using Equation (20), the last term can be approximated as
Using the above results, Equation (21) can be written as
Replacing by ,
Using the above results, Equation (19) can be written as
In practice, the population-level quantities in the second and third terms are not observable and are therefore replaced by their corresponding empirical estimates. Thus, the orders and τ are simultaneously selected by minimizing the functional final perdition error criterion generalized for exogenous covariates as
The implementation of the criterion renders the proposed forecasting framework fully automated, eliminating reliance on arbitrary tuning parameter specification. Notably, the determination of the optima dimension are now sample-adaptive and explicitly dependent on the observed sample size n. The empirical results presented in Section 4 confirm the strong practical efficacy of this approach.
3.4. Competitive Models
The traditional time series model, like the AutoRegressive Integrated Moving Average (ARIMA), the neural network autoregressive model (NNAR), and two functional autoregressive models FAR(p, m) and FARX(p, m, τ) in Equations (14) and (16), as described in Section 3.1, are studied as benchmarks to compare the forecasting accuracy of the proposed functional models.
3.4.1. Autoregressive Integrated Moving Average Model
ARIMA is one of the most commonly applied time series models for forecasting a univariate time series. ARIMA is the extended form of the simple ARMA model, which is a tool that extrapolates the signal into the future to generate forecasts by separating signal from noise. It comprises three parametric parts known as the order of AR, MA, and the number of differences needed for a time series to be stationary; i.e., p, q, and d, respectively. Mathematically, it can be written as
where is the stochastic part obtained from partitioning the , q is an integrated difference to achieve a stationarity, B is the backward shift operator, is the white noise term, α is an intercept term, and and are the parameters of the AR and MA parts, respectively, which are estimated using the maximum likelihood estimation method.
3.4.2. Neural Network Autoregressive Model
Artificial neural networks (ANNs) allow complex nonlinear relationships between the response variable and its predictors. The strength of the NNAR model comes from the parallel processing of data, which eliminates the need for classical assumptions. As a result, the network model may be easily chosen based on the characteristics of the data. ANN includes three types of layers, namely input, output, and one or more hidden layer(s) with an activation function that determines the relationship (represented by a sigmoid) between the input () and output () of a node and network. The mathematical form of the NNAR model is
where and are the biases on the nodes, and (, ,) are the connection weights between the layers of the model, is the activation function of the hidden layer, d is the number of input nodes, q is the number of hidden nodes, and . Furthermore, the sigmoid is based on the logistic function given as .
4. Application to Real Data
4.1. Study Area
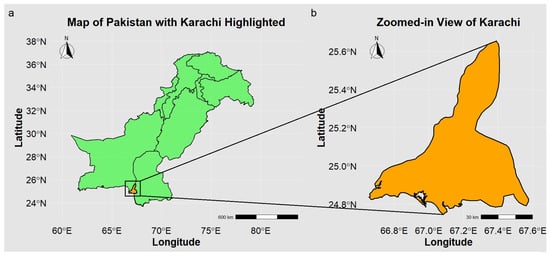
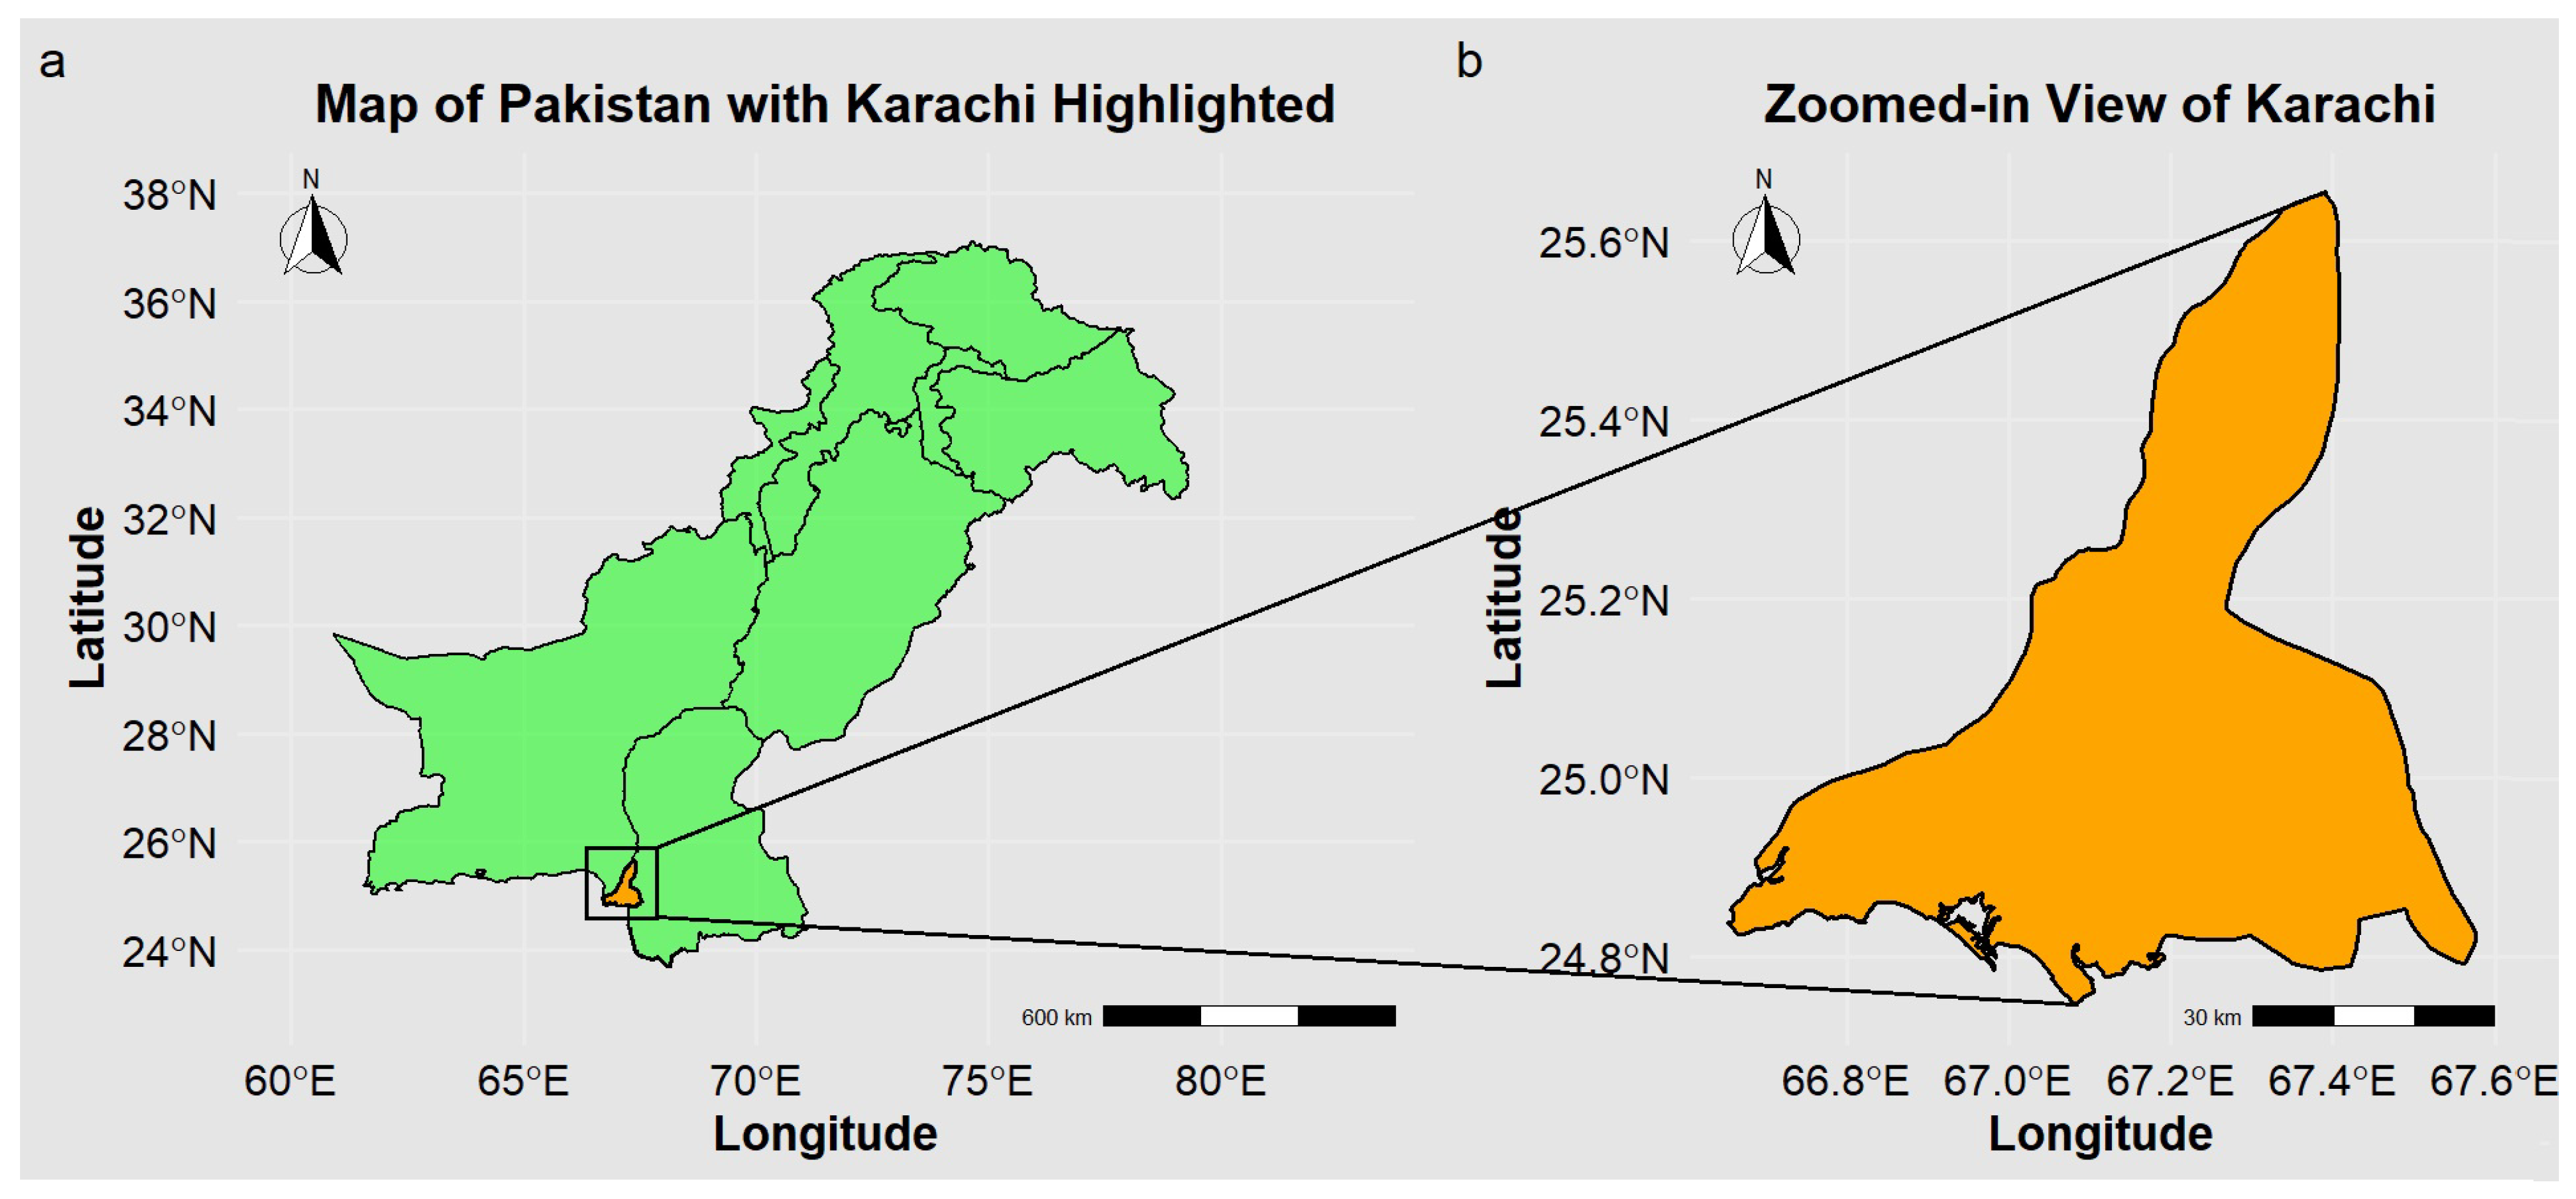
For the empirical investigation of the proposed FAR model, an hourly temperature time series (in °C) for the site Karachi, Pakistan (Latitude: 24.8607° N, Longitude: 67.0011° E), is considered (Figure 4). The data used in this study span the period from 1 January 2019 to 31 December 2024 and were collected from the NASA POWER data access portal (https://power.larc.nasa.gov/data-access-viewer/ (accessed on 14 January 2025)).
Figure 4.
Spatial location of the study area, (a) map of Pakistan with Karachi highlighted; (b) zoomed-in view of Karachi.
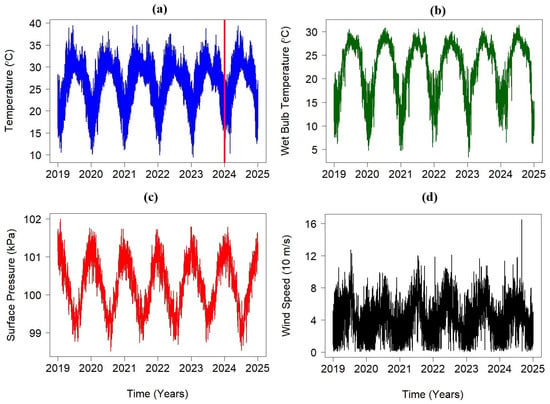
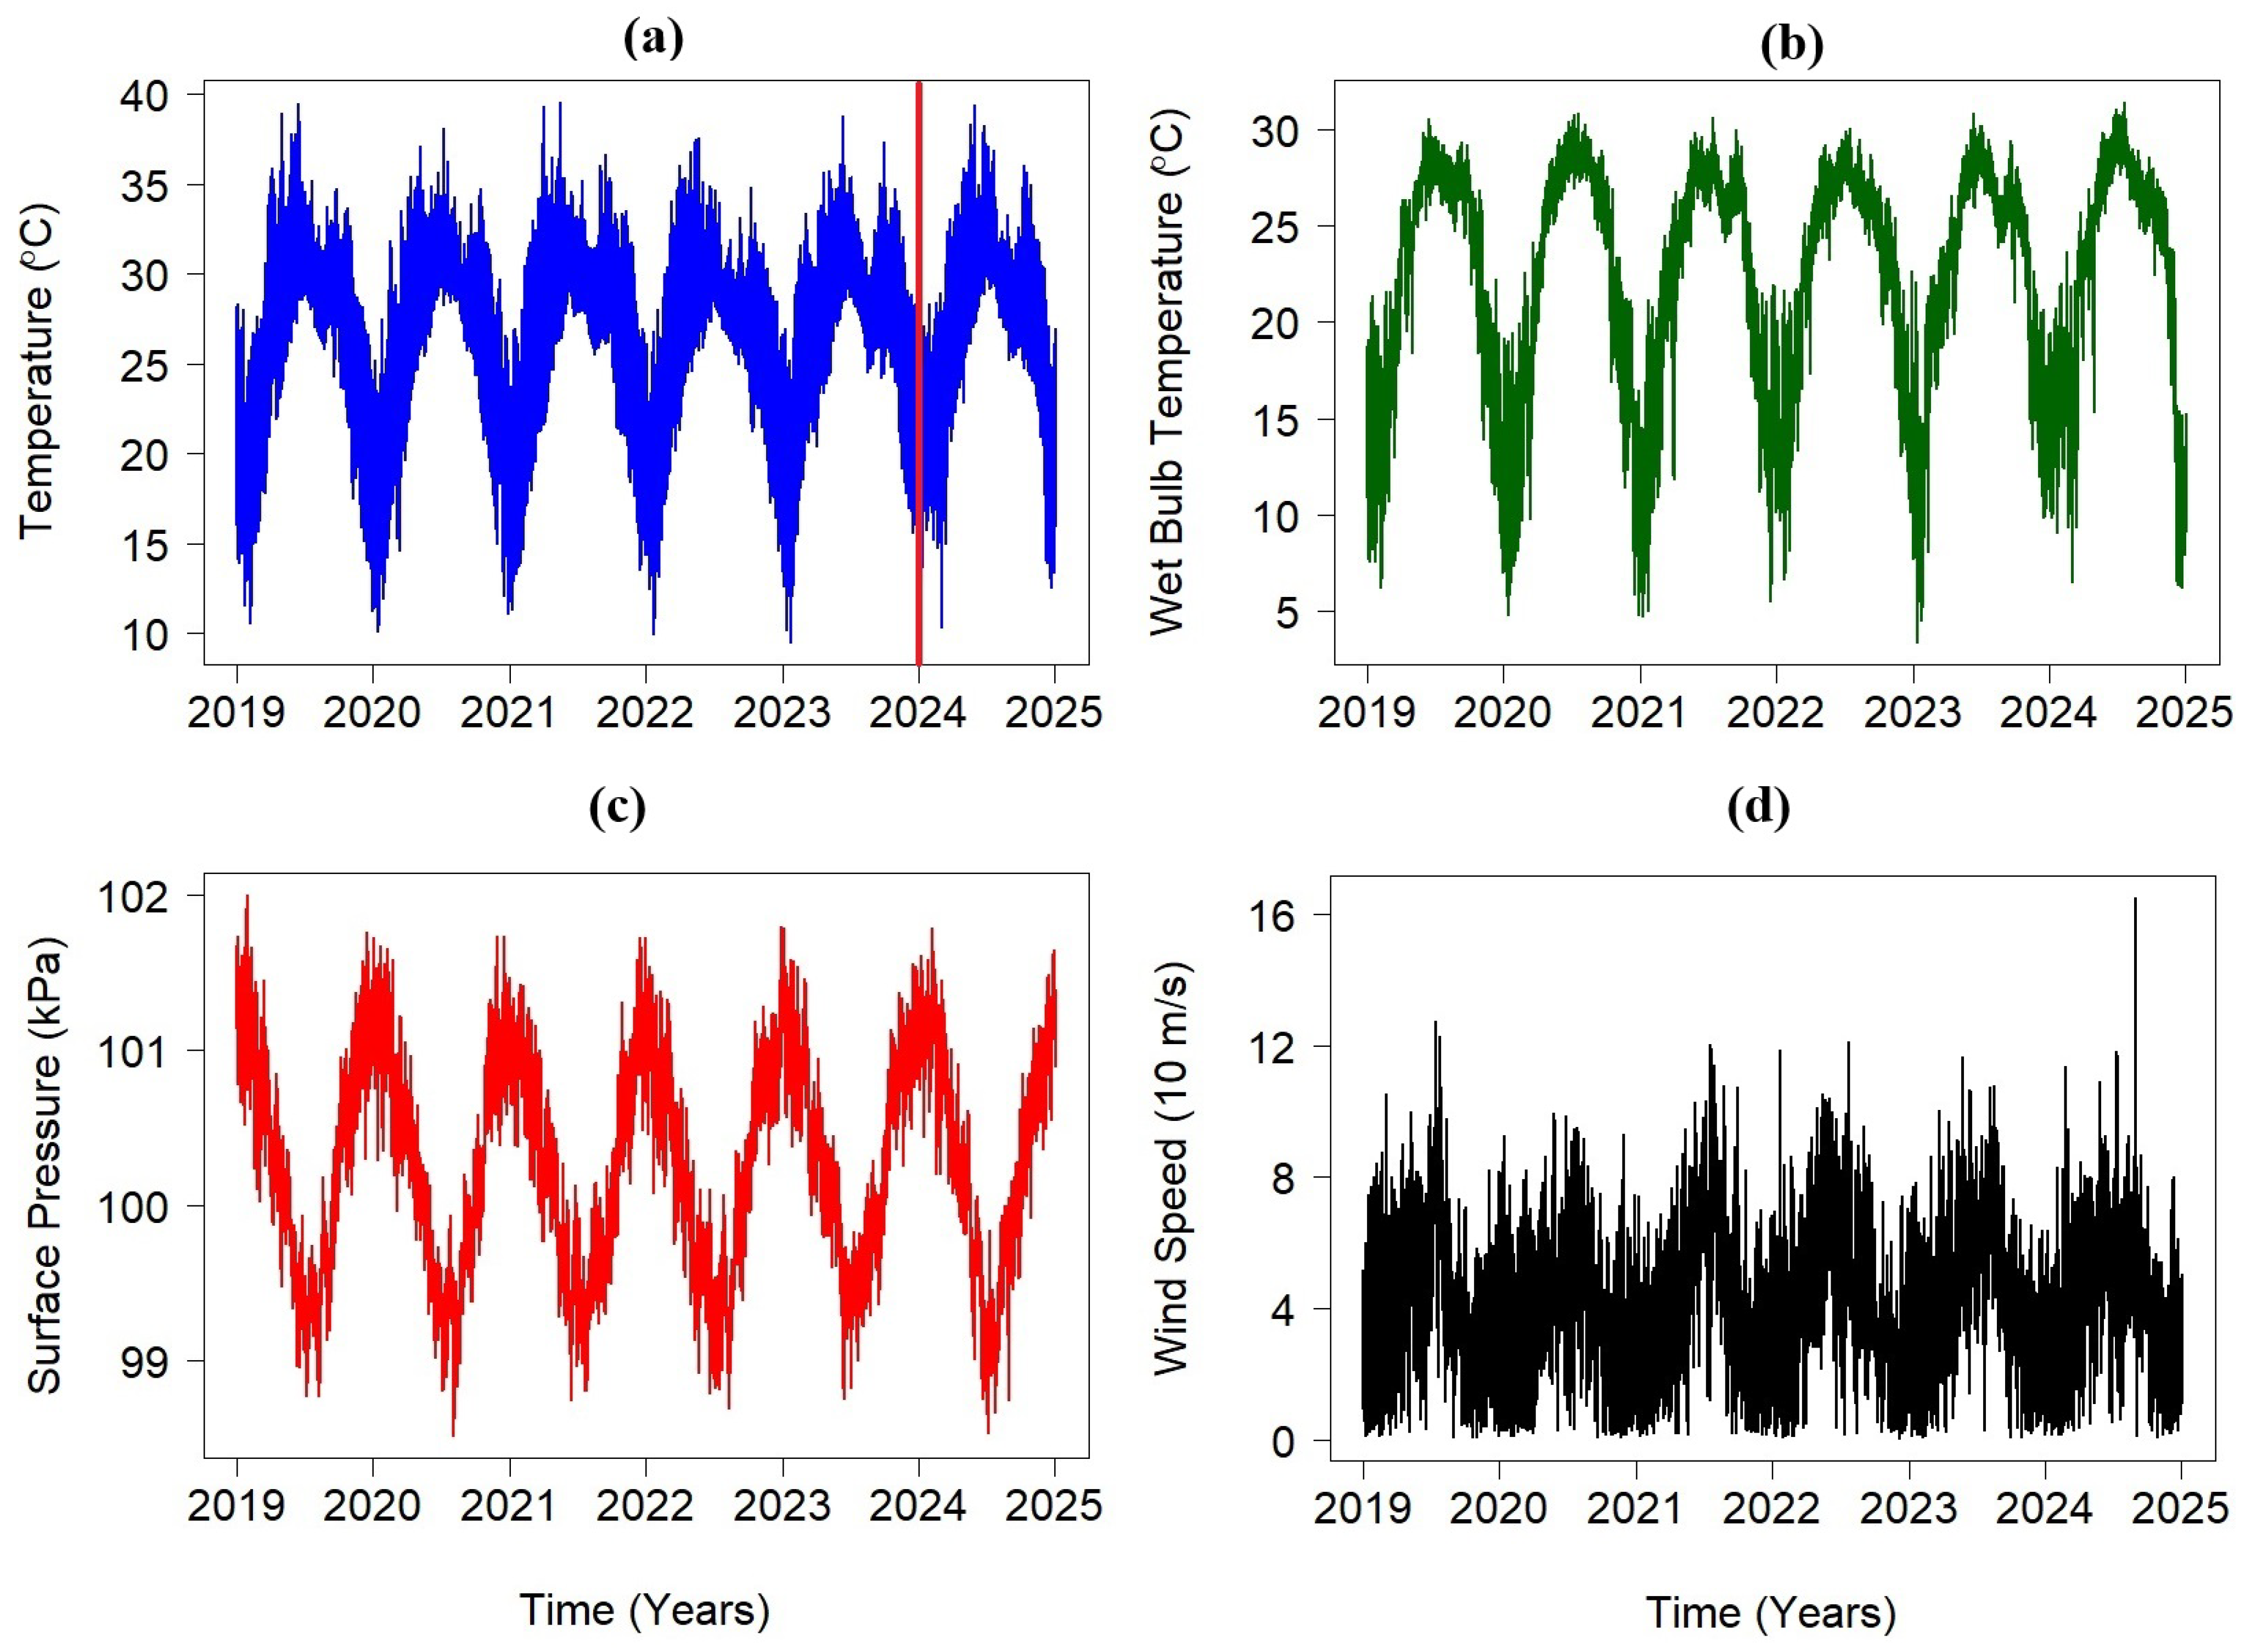
In addition, exogenous variables such as wet-bulb temperature (°C), wind speed (10 m/s), and surface pressure (kPa) are also collected for the same location. The times series data for each variable consists of 52,632 hourly observations for 2192 days. The descriptive summaries for the these variables are given in Table 2.
Table 2.
Descriptive Summaries of Endogenous and Exogenous Variables.
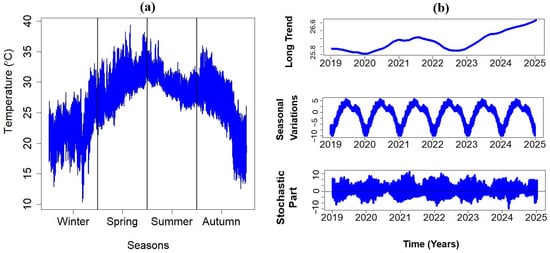
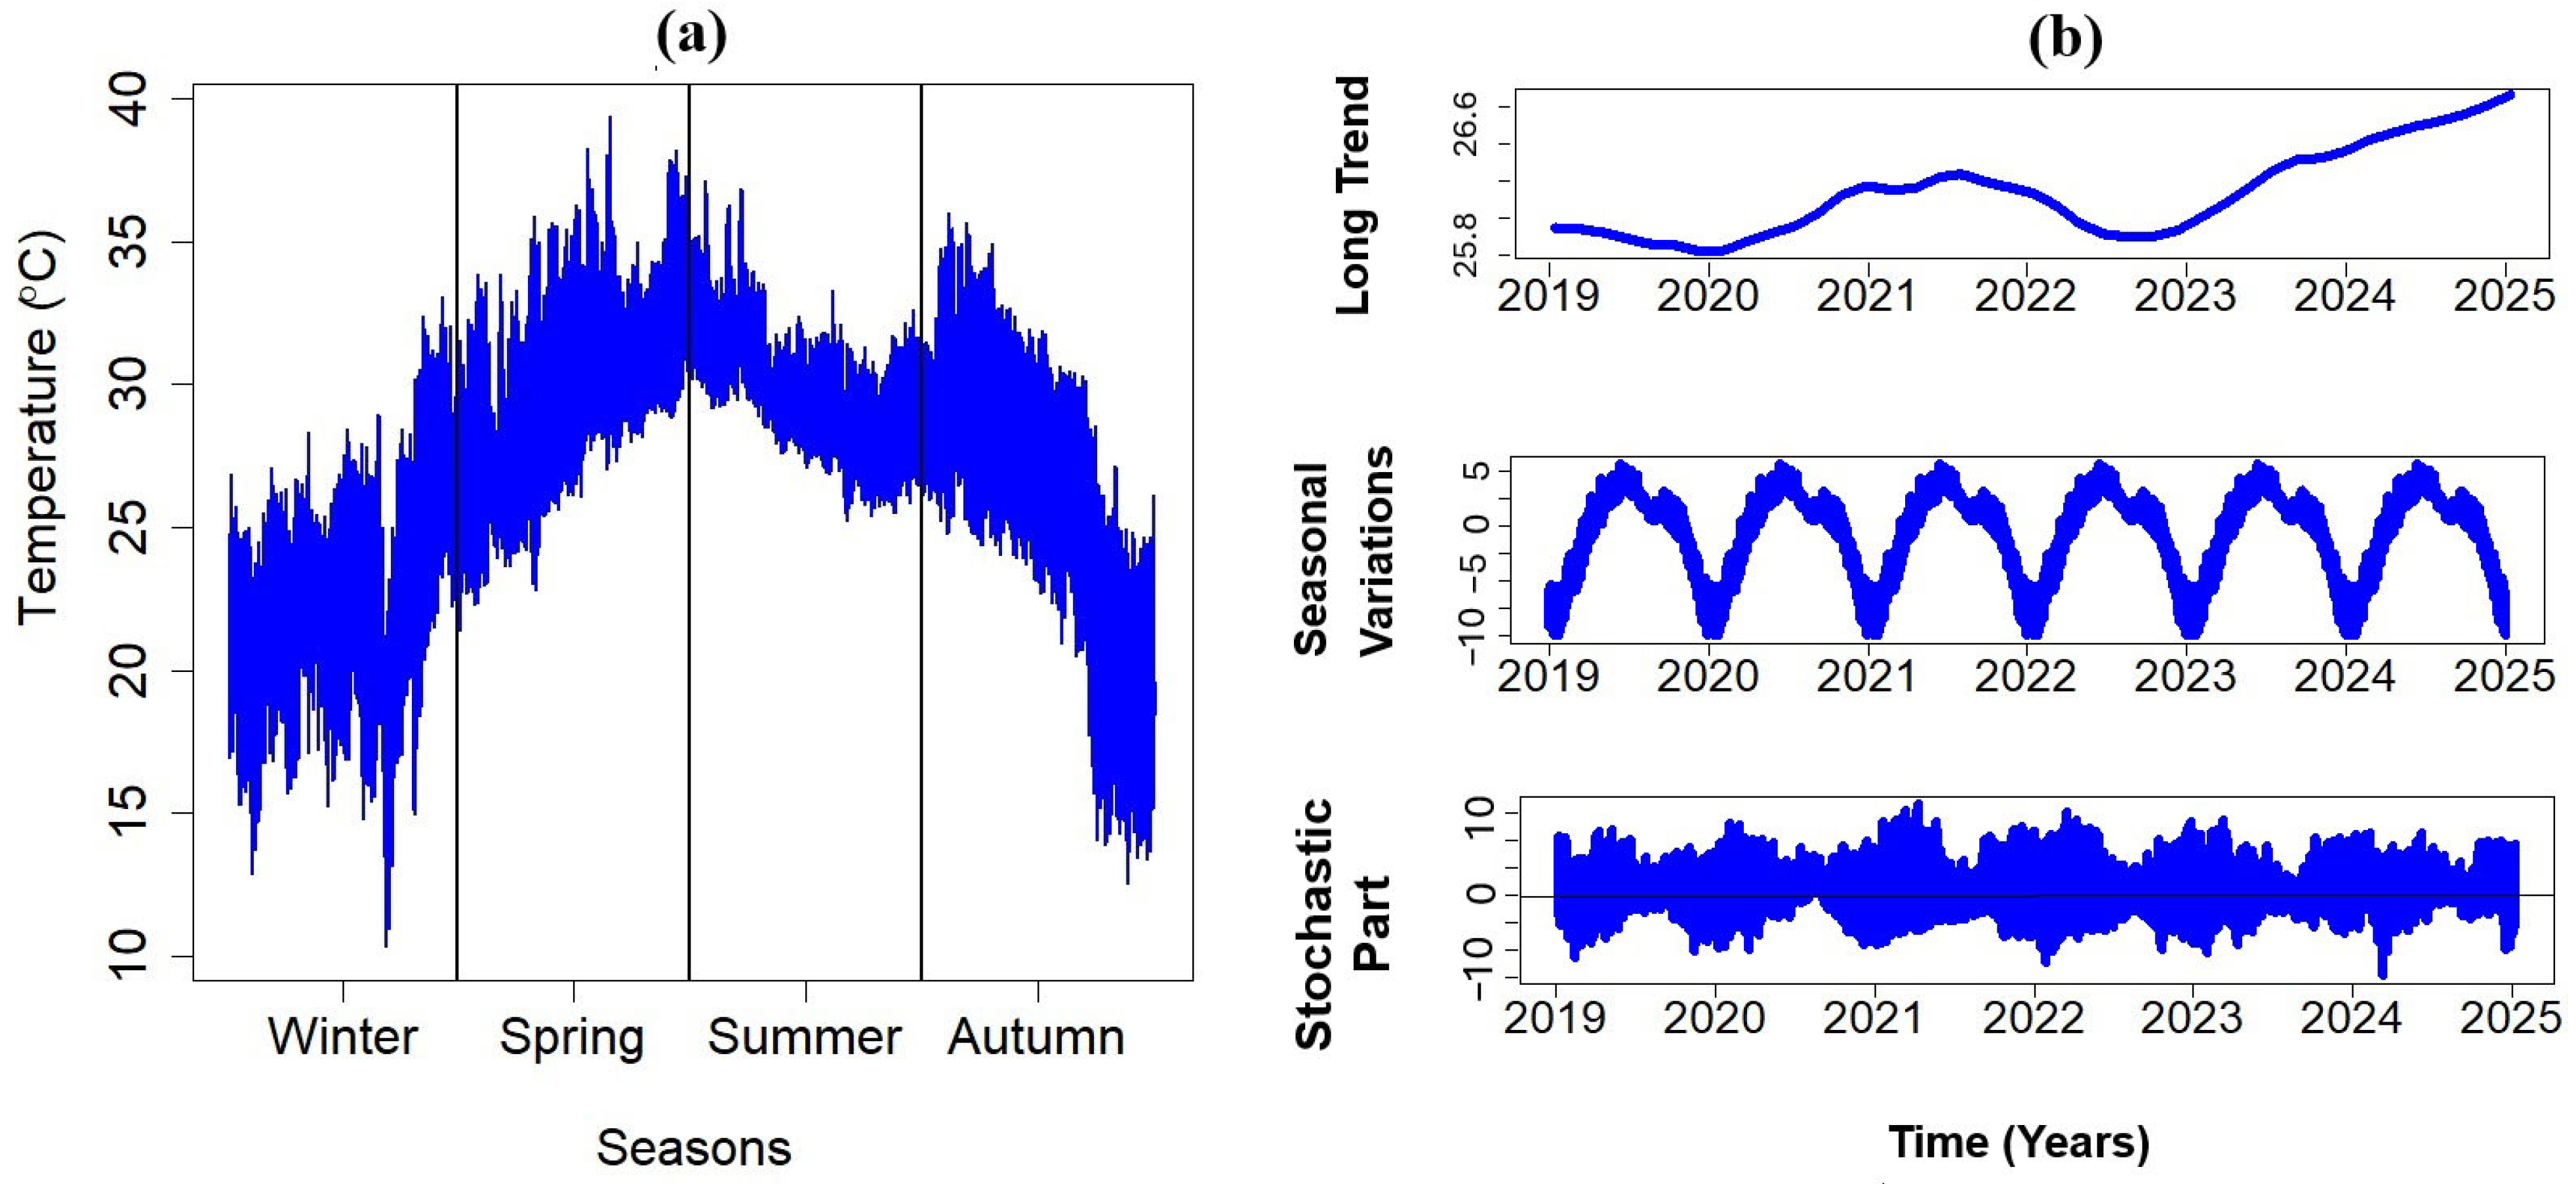
Figure 5 depicts the nature of variations for response and the three exogenous variables. The time series plot of the temperature data over six years clearly distinguish the training set (43,848) used for modeling and estimation from the testing set (8784), which corresponds to out-of-sample forecasts. Since 2024 is a leap year, a total of 366 day-ahead forecasts are generated using the expanding window modeling technique. The hourly temperature data also exhibits seasonal variation. Figure 6a illustrates seasonal variations across different seasons in 2024, showing that winter and autumn experience significant fluctuations in temperature as compared to the other three seasons.
Figure 5.
Time series plots of (a) endogenous variable indicating training and testing data partition; (b) first exogenous variable; (c) second exogenous variable; (d) third exogenous variable.
Figure 6.
(a) Seasonal variations within an year; (b) long-trend, yearly, and seasonal variations for the whole dataset.
4.2. Data-Driven Modeling Procedure
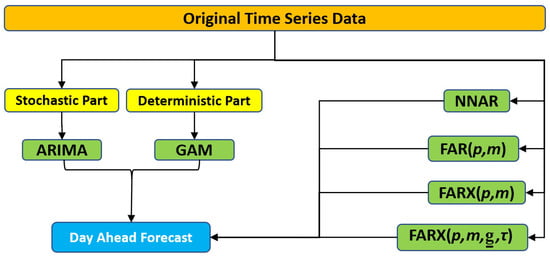
Figure 7 clearly illustrates the step-by-step data-driven modeling procedure that is used to implement the proposed and competitive models, beginning with data preprocessing.
Figure 7.
Flowchart of data-driven modeling procedure.
Extreme values in the times series of responses, as well as in the explanatory variables, pose challenges for estimation and forecasting. Identifying and adjusting these values improves prediction accuracy. This study applies the Shifting Filter on time series (SFT), an extension of [71], which operates on a rolling window instead of the entire series. Each of the original time series is divided into segments, where N is the total number of observations and r is the window width. Values deviating beyond 2.58 (based on a 99% confidence interval from a normal distribution) times the sample standard deviation σ from the mean are flagged as extreme [72]. The process iterates across all segments for all series as follows:
where is the temperature (°C) at time t, is the sample mean, and is the standard deviation. The replacement rule can be mathematically defined as
Extreme values are replaced with the median () of the respective window for improved forecasting stability.
Once are obtained for each TS, we move towards the data-driven framework as indicated in Figure 7, which includes the application of the traditional time series model ARIMA, a machine learning model NNAR, and three FAR models. Consider to be a filtered temperature time series where and . Due to significant seasonal variations (), long trends (), and year effects (), as represented in Figure 6b, we partitioned into deterministic () and stochastic () parts, such that the first term is estimated via a generalized additive model (GAM) and the second term is modeled by ARIMA. Finally, the results are combined () for the day-ahead final forecast; that is, . Additionally, models like NNAR and FAR can capture non-linearity directly without decomposing , as they performed even better in handling complex patterns.
Order Identification and Estimation
For different variables used in the study, order identification is crucial for ensuring accurate time series modeling and forecasting. The optimal orders required for the implementation of the models in Figure 7 are estimated and given in Table 3.
Table 3.
Optimal orders for various models.
The optimal orders for all models are selected based on the model selection criteria: for ARIMA, using AIC/BIC; for neural networks via cross-validation; and for FAR(p, m), FARX(p, m, τ) and FAR, the respective fFPE’s in Equations (15), (17) and (22) are minimized to determine the right functional orders, which optimizes the dependency structure in FTS, enhancing predictive performance. Thus, based on Table 3, the estimated time series models are ARIMA(3, 0, 2), NNAR(32, 16), and the three FAR models FAR(6, 14), FARX(6, 14, 3), FAR, respectively.
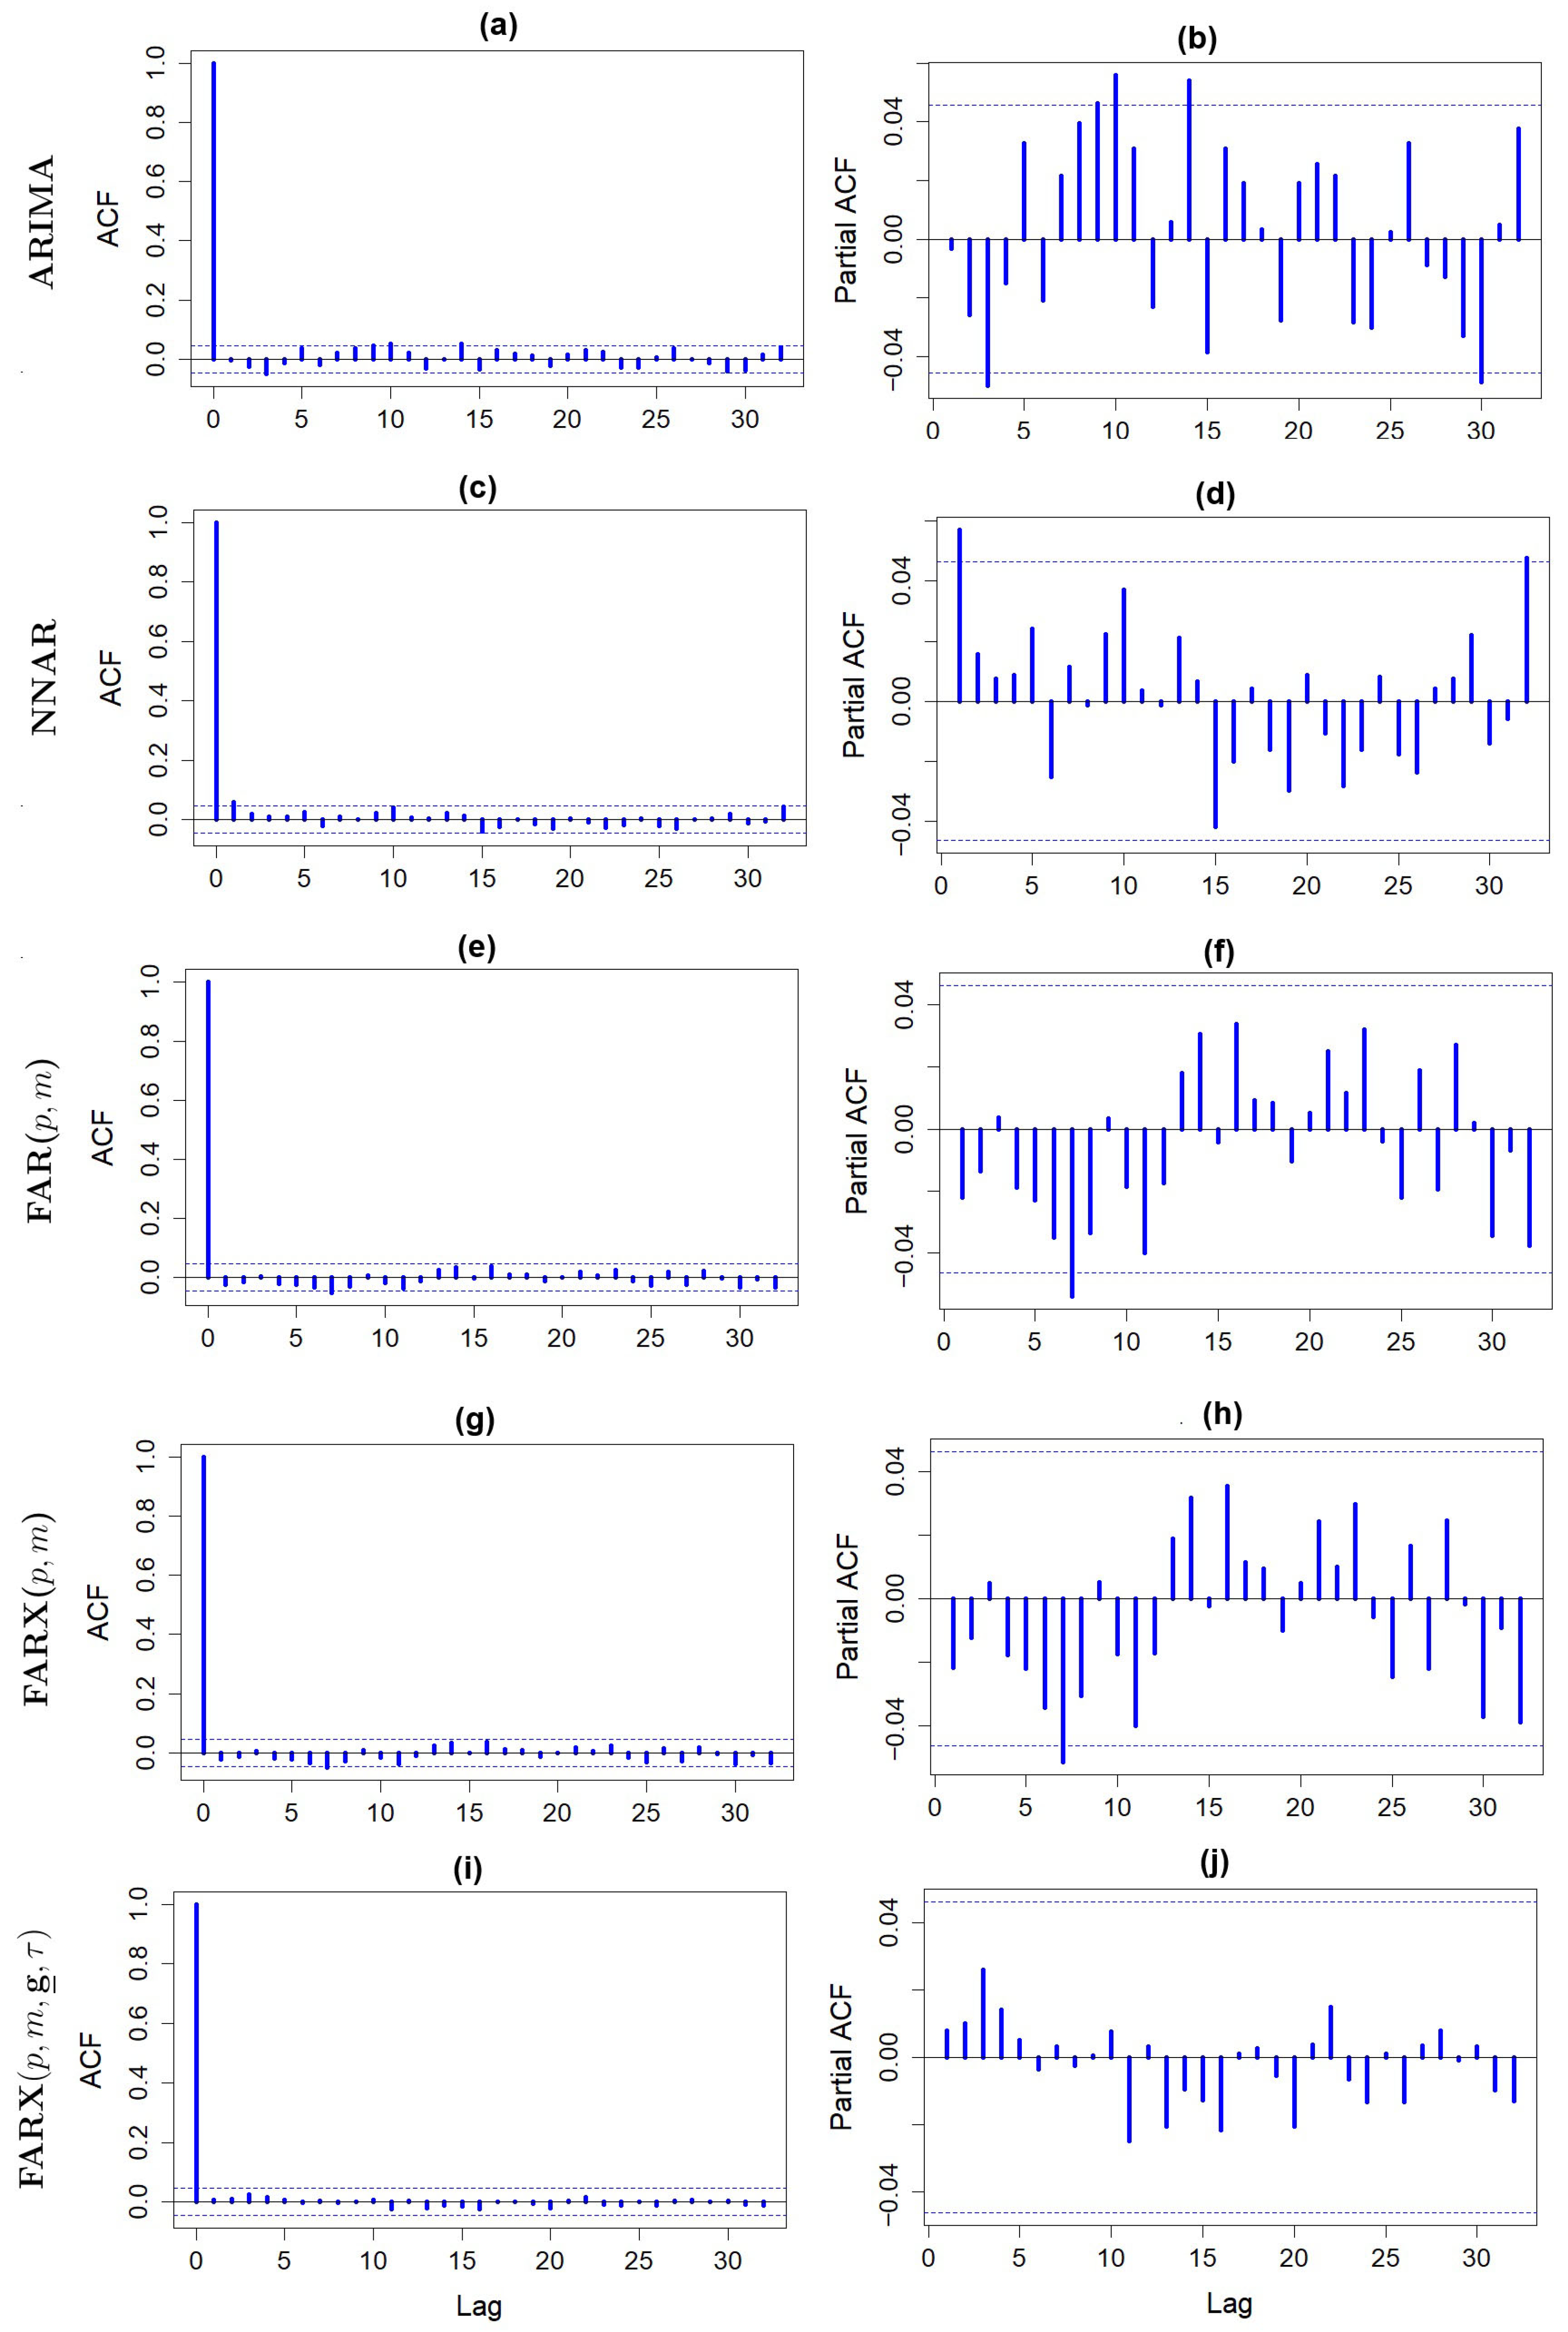
To evaluate the residual behavior of the selected models, the autocorrelation function (ACF) and partial ACF (PACF) plots are depicted in Figure 8. Overall, the final estimated residuals appear to be largely whitened, indicating that the fitted models can be regarded as adequate. Since the fitted models exhibit satisfactory diagnostic behavior, we now proceed to the out-of-sample forecasting analysis.
4.3. Out-of-Sample Forecasting
Out-of-sample forecasting evaluates a model’s predictive performance on unobserved data beyond the estimation period. This approach helps assess the generalization and robustness of the model in real-world applications. To validate the accuracy of the forecasting models, different performance measures are used. In particular, the forecasting accuracy of a model is determined by the mean absolute error (MAE), root mean squared error (RMSE), mean absolute percentage error (MAPE) and mean absolute scaled error (MASE) for number of out-of-sample forecasts used for accuracy evaluation, which are given as
Using the proposed and competitor models, day-ahead out-of-sample forecasts are obtained for the complete leap year 2024. A univariate hourly time series dataset of temperature is used to get ARIMA(3, 0, 2) and NNAR(32, 16) while the daily temperature curves are used to estimate the three FAR models.
The results for various models are summarized in Table 4 by means of RMSE, MAE, MAPE and MASE. From the results we can see that the NNAR outperforms the classical ARIMA by producing relatively small RMSE (0.9720) and MAPE (2.7928). While the FAR and FARX models provide considerable improvement in forecasting in comparison with ARIMA and NNAR, the proposed FAR ensures superior performance within the class of functional models. It achieves the lowest RMSE (0.2942) and MAE (0.2004), indicating improved forecasting accuracy. Additionally, the significant reduction in MAPE (0.8213) highlights lower prediction errors, while the MASE (0.3188) is also the lowest among all models, showcasing its robustness. These findings confirm that FAR provides more accurate day-ahead temperature forecasts while minimizing overall errors, which is a major advancement in climate data analysis.
Table 4.
One-day-ahead out-of-sample temperature forecasting performance for various models.
To assess the significance of the differences between the accuracy metrics given in Table 4, we applied the Diebold and Mariano (DM) [73] test, which is a standard statistical method for comparing forecast accuracy across models. It evaluates whether differences in accuracy measures between forecast pairs are statistically significant and the null hypothesis states no difference in accuracy. Table 5 consists of findings of the DM test, amd contains the p-values, using which we test the null hypothesis that the forecasting accuracies of the model in the row and the model in the column are the same against the alternative hypothesis that the forecasting accuracy of the model in the column is greater than the model in the row.
Table 5.
p-values from the Diebold–Mariano test, where the null hypothesis assumes equal predictive accuracy between models, while the alternative suggests the column model outperforms the row model.
Figure 8.
ACF and PACF plots for all models under study, (a) ACF for ARIMA; (b) PACF for ARIMA; (c) ACF for NNAR; (d) PACF for NNAR; (e) ACF for FAR(p, m); (f) PACF for FAR(p, m); (g) ACF for FAR(p, m, τ); (h) PACF for FAR(p, m, τ); (i) ACF for FAR; (j) PACF for FAR.
This table indicates that the functional models produce statistically more significant results than ARIMA and NNAR. Among the functional models, the proposed FAR outperforms the other functional models, demonstrating its statistical significance for temperature forecasting.
To evaluate the performance of our proposed functional model, we compute the same accuracy measures for different seasons of the year as well as for each month, and the results are listed in Table 6 and Table 7, respectively. The study site goes through four different seasons and the daily temperature curves are considerably different resulting in different forecasting accuracy errors. For example, looking at Table 6, which lists the one-day-ahead out-of-sample forecasting errors for different seasons, one can notice that the errors vary through all seasons. More precisely, looking at the MAE values, one can see that in summer, the value is 0.1550 for the FAR model, which is the lowest value as compared to other seasons and compared to the other models. Although the forecasting accuracies of all the models are high, the three FAR approaches have relatively better performance, especially the proposed FAR model. The error metrics of all models are relatively small in autumn, but large in winter. For instance, the FAR(6, 14) and FARX(6, 14, 3) produce MAPE values of 1.2031 and 1.1875 in autumn, but 3.4099 and 3.4241 in winter, respectively. On the other hand, the benchmark models ARIMA(3, 0, 2) and NNAR(32, 16) produces fairly large MAPE values. The results indicate that the proposed model performs better in summer and autumn compared to winter and spring. This can be attributed to the relatively smoother and more stable temperature patterns during these seasons, whereas winter and spring exhibit rapid fluctuations due to complex atmospheric interactions.
Table 6.
Accuracy measures for one-day-ahead out-of-sample temperature forecasts for different seasons based on various models.
Table 7.
One-day-ahead out-of-sample temperature forecasts: month-specific forecasting errors.
Table 7 lists the monthly forecasting accuracy for the models used in this study. The results suggest that the forecasting errors are lower in June, September and November compared to the other months of the year. The lowest errors are observed in the month of June, whereas the higher errors correspond to the month of March. Comparing the forecasting accuracies of different models, it is evident that the functional models perform relatively better than ARIMA and NNAR. Among the functional models, the FAR gives better results than FAR(6, 14) and FARX(6, 14, 3). The lowest MAPE produced by our proposed functional model is 0.4081 for June, whereas the value of 1.4048, produced for February, is the highest MAPE value.
Finally, Table 8 provides a comparison of the models for each hour of the day. The results are attributed to the one-day-ahead out-of-sample forecasts for a whole year. That is, the accuracy measures are obtained for the first hour based on all first hours for a complete cycle in 2024 (366 days), and so forth. This table indicates that daily temperature curves are more stable in the second-to-sixth and eighteenth-to-twenty-first hours of the day than they are in the first, seventh, thirteenth, and the twenty-fourth hour. The forecasting errors for the thirteenth and fourteenth hours are comparatively lower than in the first and last hour of the day. Additionally, higher prediction errors around dawn are observed, likely caused by abrupt temperature transitions and lower signal-to-noise ratios at these times, which increase the difficulty of accurate short-term forecasting. The results suggest that our proposed functional model FAR is more efficient at capturing the non-linear trends and performs significantly better compared to the traditional ARIMA and NNAR within the class of functional models. Hence, the inclusion of a number of exogenous variables enhances the capability of FAR(6, 14) and FARX(6, 14, 3).
Table 8.
Hour-specific one-day-ahead out-of-sample forecasting errors for temperature.
To summarize the work, one can see from Table 4, Table 5, Table 6, Table 7 and Table 8 that the proposed approach is efficient, producing significantly lower error metrics than the other competitors, which indicates better predictive power for modeling and forecasting the daily temperature curves and hence demonstrates the usefulness of our estimation framework. Moreover, the forecasting results show that the functional forecasting approach is superior to the classical ARIMA and NNAR methods.
4.4. Computational Complexity
Finally, we compare the average computational time in seconds for the five models as given in Table 9. For the functional models, authors wrote their own code and the necessary programming is carried out in R which is a statistical computing language and all the computations have been performed using an Intel(R)-Core(TM) i7-4770 CPU running at 3.40 GHz. For deterministic part, the library gam is used while for ARIMA and NNAR, the library forecast is used. For the applications of functional models the libraries fda and vars. The documentation provided by the packages includes in-depth details on the particular algorithms utilized in the estimation process.
Table 9.
Average time in seconds for one-day-ahead forecast of temperature data.
Table 9 presents the average computation time in seconds for one-day-ahead temperature forecasting across various models. ARIMA exhibits the lowest execution time (0.33 s), serving as the baseline. The functional models, particularly FARX(), show increased computational cost, with a maximum time of 2.17 s. This rise reflects the added complexity due to functional and exogenous components. However, such models provide improved predictive performance, justifying the additional time.
5. Conclusions
Accurate modeling and forecasting of daily temperature curves are essential for many practical applications, such as weather forecasting, agriculture, energy management, coastal activities, engineering, and climate analysis. However, due to the complex and non-linear patterns in weather data, the forecasting problem is a challenging task. To address this issue, a novel functional autoregressive model, namely FAR, is proposed to accommodate any number of functional and scalar covariates. The optimum orders used for different parts of the proposed model are estimated by minimizing a modified functional final prediction error called fFPE. To evaluate the performance of the proposed methodology, the daily temperature curve data obtained from NASA POWER for Karachi in Pakistan is used, and one-day-ahead out-of-sample forecasts are obtained for a complete year. For comparison purposes, forecasts are also obtained using the classical ARIMA and NNAR models, as well as two functional models, namely FAR(p, m) and FARX(p, m). The forecasting performance of the different models is assessed through different accuracy measures, including the RMSE, MAE, MAPE, and MASE.
The study findings suggest that the proposed functional model FAR is efficient at forecasting daily temperature curves by producing considerably lower forecasting errors compared to the competitors. Both of the functional models, FAR(p, m) and FARX(p, m), perform relatively better than ARIMA and NNAR. Among the functional models, our proposed model, taking into consideration several functional and scalar exogenous variables, produces the best forecasting results. The proposed model effectively captures functional temperature dynamics, particularly for short-term horizons; however, it may be less accurate under extreme or abrupt climatic events. Future work could incorporate additional high-frequency exogenous variables and explore hybrid approaches with deep learning to further enhance predictive performance. Additionally, the model should be evaluated across regions with diverse climatic patterns, such as continental or tropical climates, to assess its robustness and generalizability beyond Karachi.
Author Contributions
Conceptualization, I.S. and M.U.; methodology, I.S. and M.U.; software, M.U. and S.A.; validation, S.A. and S.M.A.; formal analysis, I.S. and M.U.; investigation, S.A. and S.M.A.; resources, S.A. and S.M.A.; data curation, M.U. and S.M.A.; writing—original draft preparation, I.S.; writing—review and editing, S.A. and S.M.A.; visualization, M.U. and S.M.A.; supervision, I.S.; project administration, I.S. and S.A.; funding acquisition, S.M.A. All authors have read and agreed to the published version of the manuscript.
Funding
This research work was funded by Umm Al-Qura University, Saudi Arabia, under grant number: 26UQU4310037GSSR03.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data used in this study were collected from the NASA POWER data access portal (https://power.larc.nasa.gov/data-access-viewer/), accessed on 14 January 2025.
Acknowledgments
The authors extend their appreciation to Umm Al-Qura University, Saudi Arabia, for funding this research work through grant number: 26UQU4310037GSSR03.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Tajfar, E.; Bateni, S.M.; Margulis, S.A.; Gentine, P.; Auligne, T. Estimation of turbulent heat fluxes via assimilation of air temperature and specific humidity into an atmospheric boundary layer model. J. Hydrometeorol. 2020, 21, 205–225. [Google Scholar] [CrossRef] [Scilit]
- Valipour, M.; Bateni, S.M.; Gholami Sefidkouhi, M.A.; Raeini-Sarjaz, M.; Singh, V.P. Complexity of forces driving trend of reference evapotranspiration and signals of climate change. Atmosphere 2020, 11, 1081. [Google Scholar] [CrossRef] [Scilit]
- Cifuentes, J.; Marulanda, G.; Bello, A.; Reneses, J. Air temperature forecasting using machine learning techniques: A review. Energies 2020, 13, 4215. [Google Scholar] [CrossRef] [Scilit]
- Massie, D.R.; Rose, M.A. Predicting daily maximum temperatures using linear regression and Eta geopotential thickness forecasts. Weather Forecast 1997, 12, 799–807. [Google Scholar] [CrossRef] [Scilit]
- Campbell, S.D.; Diebold, F.X. Weather forecasting for weather derivatives. J. Am. Stat. Assoc. 2005, 100, 6–16. [Google Scholar] [CrossRef] [Scilit]
- Svec, J.; Stevenson, M. Modelling and forecasting temperature based weather derivatives. Glob. Financ. J. 2007, 18, 185–204. [Google Scholar] [CrossRef] [Scilit]
- Dupuis, D.J. Forecasting temperature to price CME temperature derivatives. Int. J. Forecast. 2011, 27, 602–618. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.; Li, P.; Li, L.; Huang, C.; Liu, M. Modeling and forecasting average temperature for weather derivative pricing. Adv. Meteorol. 2015, 2015, 837293. [Google Scholar] [CrossRef] [Scilit]
- Cavicchioli, M.; Ghezal, A.; Zemmouri, I. (Bi)spectral analysis of Markov switching bilinear time series. Stat. Methods Appl. 2025, 1–30. [Google Scholar] [CrossRef] [Scilit]
- Alraddadi, R. The logTG-SV model: A threshold-based volatility framework with logarithmic shocks for exchange rate dynamics. AIMS Math. 2025, 10, 19495–19511. [Google Scholar] [CrossRef] [Scilit]
- Gomez, I.; Estrela, M.J.; Caselles, V. Operational forecasting of daily summer maximum and minimum temperatures in the Valencia Region. Nat. Hazards 2014, 70, 1055–1076. [Google Scholar] [CrossRef] [Scilit]
- Trigo, R.M.; Palutikof, J.P. Simulation of daily temperatures for climate change scenarios over Portugal: A neural network model approach. Clim. Res. 1999, 13, 45–59. [Google Scholar] [CrossRef] [Scilit]
- Abdel-Aal, R.E.; Elhadidy, M.A. Modeling and forecasting the daily maximum temperature using abductive machine learning. Weather Forecast 1995, 10, 310–325. [Google Scholar] [CrossRef] [Scilit]
- Abdel-Aal, R.E. Hourly temperature forecasting using abductive networks. Eng. Appl. Artif. Intell. 2004, 17, 543–556. [Google Scholar] [CrossRef] [Scilit]
- Ustaoglu, B.; Cigizoglu, H.K.; Karaca, M. Forecast of daily mean, maximum and minimum temperature time series by three artificial neural network methods. Meteorol. Appl. 2008, 15, 431–445. [Google Scholar] [CrossRef] [Scilit]
- Sanikhani, H.; Deo, R.C.; Samui, P.; Kisi, O.; Mert, C.; Mirabbasi, R.; Gavili, S.; Yaseen, Z.M. Survey of different data-intelligent modeling strategies for forecasting air temperature using geographic information as model predictors. Comput. Electron. Agric. 2018, 152, 242–260. [Google Scholar] [CrossRef] [Scilit]
- Tran, T.T.K.; Bateni, S.M.; Ki, S.J.; Vosoughifar, H. A review of neural networks for air temperature forecasting. Water 2021, 13, 1294. [Google Scholar] [CrossRef] [Scilit]
- Shah, I.; Mubassir, P.; Ali, S.; Albalawi, O. A functional autoregressive approach for modeling and forecasting short-term air temperature. Front. Environ. Sci. 2024, 12, 1411237. [Google Scholar] [CrossRef] [Scilit]
- Selmy, H.A.; Mohamed, H.K.; Medhat, W. A predictive analytics framework for sensor data using time series and deep learning techniques. Neural Comput. Appl. 2024, 36, 6119–6132. [Google Scholar] [CrossRef] [Scilit]
- Alexander, V.O.; Ali, M.I. Enhancing Time Series Data Predictions: A Survey of Augmentation Techniques and Model Performance. In Proceedings of the 2024 Australasian Computer Science Week (ACSW 2024); Association for Computing Machinery: New York, NY, USA, 2024. [Google Scholar] [CrossRef] [Scilit]
- Uluocak, I.; Bilgili, M. Daily air temperature forecasting using LSTM-CNN and GRU-CNN models. Acta Geophys. 2024, 72, 2107–2126. [Google Scholar] [CrossRef] [Scilit]
- An, H.; Li, Q.; Lv, X.; Li, G.; Qian, Q.; Zhou, G.; Nie, G.; Zhang, L.; Zhu, L. Forecasting daily extreme temperatures in Chinese representative cities using artificial intelligence models. Weather. Clim. Extrem. 2023, 42, 100621. [Google Scholar] [CrossRef] [Scilit]
- Sen, A.; Mazumder, A.R.; Dutta, D.; Sen, U.; Syam, P.; Dhar, S. Comparative evaluation of metaheuristic algorithms for hyperparameter selection in short-term weather forecasting. arXiv 2023, arXiv:2309.02600. [Google Scholar] [CrossRef] [Scilit]
- Toharudin, T.; Pontoh, R.S.; Caraka, R.E.; Zahroh, S.; Lee, Y.; Chen, R.C. Employing long short-term memory and Facebook prophet model in air temperature forecasting. Commun. Stat.-Simul. Comput. 2023, 52, 279–290. [Google Scholar] [CrossRef] [Scilit]
- Elshewey, A.M.; Shams, M.Y.; Elhady, A.M.; Shohieb, S.M.; Abdelhamid, A.A.; Ibrahim, A.; Tarek, Z. A Novel WD-SARIMAX model for temperature forecasting using daily delhi climate dataset. Sustainability 2022, 15, 757. [Google Scholar] [CrossRef] [Scilit]
- Gong, B.; Langguth, M.; Ji, Y.; Mozaffari, A.; Stadtler, S.; Mache, K.; Schultz, M.G. Temperature forecasting by deep learning methods. Geosci. Model Dev. 2022, 15, 8931–8956. [Google Scholar] [CrossRef] [Scilit]
- Shin, K.-H.; Jung, J.-W.; Chang, K.-H.; Kim, K.; Jung, W.-S.; Lee, D.-I.; You, C.-H. Dynamical prediction of two meteorological factors using the deep neural network and the long short-term memory (II). J. Korean Phys. Soc. 2022, 80, 1081–1097. [Google Scholar] [CrossRef] [Scilit]
- Alomar, M.K.; Khaleel, F.; Aljumaily, M.M.; Masood, A.; Razali, S.F.M.; AlSaadi, M.A.; Al-Ansari, N.; Hameed, M.M. Data-driven models for atmospheric air temperature forecasting at a continental climate region. PLoS ONE 2022, 17, e0277079. [Google Scholar] [CrossRef] [Scilit]
- Haque, E.; Tabassum, S.; Hossain, E. A comparative analysis of deep neural networks for hourly temperature forecasting. IEEE Access 2021, 9, 160646–160660. [Google Scholar] [CrossRef] [Scilit]
- Wang, H.; Pathan, M.S.; Lee, Y.H.; Dev, S. Day-ahead forecasts of air temperature. In 2021 IEEE USNC-URSI Radio Science Meeting (Joint with AP-S Symposium); IEEE: New York, NY, USA, 2021; pp. 94–95. [Google Scholar] [CrossRef] [Scilit]
- Lee, S.; Lee, Y.-S.; Son, Y. Forecasting daily temperatures with different time interval data using deep neural networks. Appl. Sci. 2020, 10, 1609. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Z.; Dong, Y. Temperature Forecasting via Convolutional Recurrent Neural Networks Based on Time-Series Data. Complexity 2020, 2020, 3536572. [Google Scholar] [CrossRef] [Scilit]
- Shin, J.-Y.; Kim, K.R.; Ha, J.-C. Seasonal forecasting of daily mean air temperatures using a coupled global climate model and machine learning algorithm for field-scale agricultural management. Agric. For. Meteorol. 2020, 281, 107858. [Google Scholar] [CrossRef] [Scilit]
- Wanishsakpong, W.; Owusu, B.E. Optimal time series model for forecasting monthly temperature in the southwestern region of Thailand. Model. Earth Syst. Environ. 2020, 6, 525–532. [Google Scholar] [CrossRef] [Scilit]
- Zahroh, S.; Hidayat, Y.; Pontoh, R.S.; Santoso, A.; Sukono, F.; Bon, A.T. Modeling and forecasting daily temperature in Bandung. In Proceedings of the International Conference on Industrial Engineering and Operations Management, Riyadh, Saudi Arabia, 26–28 November 2019; pp. 406–412. [Google Scholar]
- Ramsay, J.O.; Silverman, B.W. Applied Functional Data Analysis: Methods and Case Studies; Springer: Berlin/Heidelberg, Germany, 2002. [Google Scholar] [CrossRef] [Scilit]
- Uzair, M.; Shah, I.; Ali, S. An adaptive strategy for wind speed forecasting under functional data horizon: A way towards enhancing clean energy. IEEE Access 2024, 12, 68730–68746. [Google Scholar] [CrossRef] [Scilit]
- Naeem, N.; Ali, S.; Shah, I. Functional EWMA control chart for phase II profile monitoring. J. Stat. Comput. Simul. 2025, 95, 96–116. [Google Scholar] [CrossRef] [Scilit]
- Ullah, S.; Finch, C.F. Applications of functional data analysis: A systematic review. BMC Med. Res. Methodol. 2013, 13, 43. [Google Scholar] [CrossRef] [Scilit]
- Tao, Z.; Wang, M.; Liu, J.; Wang, P. A Functional Data Analysis Framework Incorporating Derivative Information and Mixed-Frequency Data for Predictive Modeling of Crude Oil Price. IEEE Trans. Ind. Inform. 2025, 21, 3226–3235. [Google Scholar] [CrossRef] [Scilit]
- Rodríguez Cuadro, D.; Pérez-Plaza, S.; Castaño-Martínez, A.; Fernández-Palacín, F. A Study of the Colombian Stock Market with Multivariate Functional Data Analysis (FDA). Mathematics 2025, 13, 858. [Google Scholar] [CrossRef] [Scilit]
- Pokhrel, K.P.; Tsokos, C.P. Forecasting age-specific brain cancer mortality rates using functional data analysis models. Adv. Epidemiol. 2015, 2015, 721592. [Google Scholar] [CrossRef] [Scilit]
- Beyaztas, U.; Yaseen, Z.M. Drought interval simulation using functional data analysis. J. Hydrol. 2019, 579, 124141. [Google Scholar] [CrossRef] [Scilit]
- Hael, M.A.; Yongsheng, Y.; Saleh, B.I. Visualization of rainfall data using functional data analysis. SN Appl. Sci. 2020, 2, 461. [Google Scholar] [CrossRef] [Scilit]
- Ghumman, A.R.; Haider, H.; Shafiquzamman, M. Functional data analysis of models for predicting temperature and precipitation under climate change scenarios. J. Water Clim. Change 2020, 11, 1748–1765. [Google Scholar] [CrossRef] [Scilit]
- Hael, M.A. Modeling of rainfall variability using functional principal component method: A case study of Taiz region, Yemen. Model. Earth Syst. Environ. 2021, 7, 17–27. [Google Scholar] [CrossRef] [Scilit]
- Wang, S.; Jank, W.; Shmueli, G. Explaining and forecasting online auction prices and their dynamics using functional data analysis. J. Bus. Econ. Stat. 2008, 26, 144–160. [Google Scholar] [CrossRef] [Scilit]
- Wagner-Muns, I.M.; Guardiola, I.G.; Samaranayke, V.A.; Kayani, W.I. A functional data analysis approach to traffic volume forecasting. IEEE Trans. Intell. Transp. Syst. 2017, 19, 878–888. [Google Scholar] [CrossRef] [Scilit]
- Shah, I.; Muhammad, I.; Ali, S.; Ahmed, S.; Almazah, M.M.A.; Al-Rezami, A.Y. Forecasting day-ahead traffic flow using functional time series approach. Mathematics 2022, 10, 4279. [Google Scholar] [CrossRef] [Scilit]
- Liebl, D. Modeling and forecasting electricity spot prices: A functional data perspective. Ann. Appl. Stat. 2013, 12, 1562–1592. [Google Scholar] [CrossRef] [Scilit]
- Lisi, F.; Shah, I. Forecasting next-day electricity demand and prices based on functional models. Energy Syst. 2020, 11, 947–979. [Google Scholar] [CrossRef] [Scilit]
- Jan, F.; Shah, I.; Ali, S. Short-Term Electricity Prices Forecasting Using Functional Time Series Analysis. Energies 2022, 15, 3423. [Google Scholar] [CrossRef] [Scilit]
- Shah, I.; Jan, F.; Ali, S. Functional data approach for short-term electricity demand forecasting. Math. Probl. Eng. 2022, 2022, 6709779. [Google Scholar] [CrossRef] [Scilit]
- Chen, Y.; Koch, T.; Lim, K.G.; Xu, X.; Zakiyeva, N. A review study of functional autoregressive models with application to energy forecasting. Wiley Interdiscip. Rev. Comput. Stat. 2021, 13, e1525. [Google Scholar] [CrossRef] [Scilit]
- Frois Caldeira, J.; Gupta, R.; Suleman, M.T.; Torrent, H.S. Forecasting the term structure of interest rates of the BRICS: Evidence from a nonparametric functional data analysis. Emerg. Mark. Financ. Trade 2021, 57, 4312–4329. [Google Scholar] [CrossRef] [Scilit]
- Vilar, J.M.; Cao, R.; Aneiros, G. Forecasting next-day electricity demand and price using nonparametric functional methods. Int. J. Electr. Power Energy Syst. 2012, 39, 48–55. [Google Scholar] [CrossRef] [Scilit]
- Curceac, S.; Ternynck, C.; Ouarda, T.B.M.J.; Chebana, F.; Niang, S.D. Short-term air temperature forecasting using nonparametric functional data analysis and SARMA models. Environ. Model. Softw. 2019, 111, 394–408. [Google Scholar] [CrossRef] [Scilit]
- Aue, A.; Norinho, D.D.; Hörmann, S. On the prediction of stationary functional time series. J. Am. Stat. Assoc. 2015, 110, 378–392. [Google Scholar] [CrossRef] [Scilit]
- Karhunen, K. Under linear methods in probability theory. Ann. Acad. Sci. Fenn. Ser. A. I. Math.-Phys. 1947, 37, 3–79. [Google Scholar]
- Shang, H.L. A survey of functional principal component analysis. AStA Adv. Stat. Anal. 2014, 98, 121–142. [Google Scholar] [CrossRef] [Scilit]
- Hall, P.; Hosseini-Nasab, M. On properties of functional principal components analysis. J. R. Stat. Soc. Ser. B Stat. Methodol. 2006, 68, 109–126. [Google Scholar] [CrossRef] [Scilit]
- Hörmann, S.; Kokoszka, P. Weakly dependent functional data. Ann. Stat. 2010, 38, 1845–1884. [Google Scholar] [CrossRef] [Scilit]
- Damon, J.; Guillas, S. far: Modelization for Functional AutoRegressive Processes. 2024. Available online: https://CRAN.R-project.org/package=far (accessed on 14 January 2025).
- Hyndman, R.J.; Shang, H.L. ftsa: Functional Time Series Analysis. 2025. Available online: https://CRAN.R-project.org/package=ftsa (accessed on 14 January 2025).
- Dickey, D.A.; Fuller, W.A. Distribution of the estimators for autoregressive time series with a unit root. J. Am. Stat. Assoc. 1979, 74, 427–431. [Google Scholar] [CrossRef] [Scilit]
- Dickey, D.A.; Fuller, W.A. Likelihood ratio statistics for autoregressive time series with a unit root. Econometrica 1981, 49, 1057–1072. [Google Scholar] [CrossRef] [Scilit]
- Hörmann, S.; Kokoszka, P. Functional time series. In Handbook of Statistics; Elsevier: Amsterdam, The Netherlands, 2012; Volume 30, pp. 157–186. [Google Scholar] [CrossRef] [Scilit]
- Brockwell, P.J.; Davis, R.A. Time Series: Theory and Methods; Springer: Berlin/Heidelberg, Germany, 1991. [Google Scholar] [CrossRef] [Scilit]
- Bosq, D. Linear Processes in Function Spaces: Theory and Applications; Springer: Berlin/Heidelberg, Germany, 2000. [Google Scholar] [CrossRef] [Scilit]
- Kokoszka, P.; Reimherr, M. Determining the order of the functional autoregressive model. J. Time Ser. Anal. 2013, 34, 116–129. [Google Scholar] [CrossRef] [Scilit]
- Borovkova, S.; Permana, F.J. Modelling electricity prices by the potential jump-diffusion. In Stochastic Finance; Springer: Berlin/Heidelberg, Germany, 2006; pp. 239–263. [Google Scholar] [CrossRef] [Scilit]
- Shah, I.; Akbar, S.; Saba, T.; Ali, S.; Rehman, A. Short-term forecasting for the electricity spot prices with extreme values treatment. IEEE Access 2021, 9, 105451–105462. [Google Scholar] [CrossRef] [Scilit]
- Diebold, F.X.; Mariano, R.S. Comparing predictive accuracy. J. Bus. Econ. Stat. 2002, 20, 134–144. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.