


Abstract
In lifetime testing, reliably assessing the life performance index of the Weibull distribution under Type I interval-censored data is a critical task. Although maximum likelihood estimation (MLE) is a conventional approach for parameter estimation, closed-form solutions are unavailable for this data type. To address this limitation, four least-squares estimation methods based on data transformation are developed. The proposed estimations can provide closed-form solutions for the Weibull distribution and life performance index. The asymptotic unbiasedness and normality of the proposed estimators are rigorously established. Their effectiveness is further supported by simulation studies. Moreover, the practical relevance of the methods is illustrated with two real-data applications.
Keywords:
Weibull distribution; least-squares estimation; life performance index; Type-I interval-censored data; data transformation MSC:
62F10
1. Introduction
In manufacturing, a product’s quality is a critical attribute that attracts considerable attention from both producers and consumers [1]. To assess the product’s quality, the process capability index (PCI) is a simple but widely adopted tool in process capability analysis [2]. Over the years, numerous PCIs have been proposed, among which the life performance index, denoted by is specifically designed to assess the lifetime performance of electronic components [3]. Because product lifetime is a larger-the-better type of quality characteristic, only the lower specification limit is incorporated in . Due to inherent constraints and the asymmetric nature, lifetime data often deviate from normality. Weibull distribution is a particularly important asymmetric distribution in this context, and it has been extensively applied to implement reliability and lifetime analysis. The flexibility of the Weibull distribution in shaping the probability density function (PDF) and its convenient mathematical representation render the Weibull distribution especially effective for modeling lifetime data [4,5,6].
In addition to the lifetime distribution, the method of data collection represents a crucial aspect of lifetime analysis. Owing to constraints of cost, time, and feasibility, it is often impractical to record the exact failure times of items during testing, resulting in observations that are censored in nature [7]. Censoring schemes are thus a common practice in data collection (see Balakrishnan et al. [8], Chapter 1, P.2), with Type I and Type II censoring being the most widely used and conceptually straightforward approaches (see, e.g., [9,10,11,12,13]). Under Type I censoring, exact failure times are observed only up to a prespecified time point, after which subsequent failures are not recorded. In contrast to Type I censoring, Type II censoring terminates the experiment after a prespecified number of failures have occurred. Both Type I and Type II schemes share the feature of continuous monitoring of failure times. However, in certain life-testing scenarios, exact failure times cannot be continuously observed; instead, only the number of failures within predetermined time intervals can be counted. This data collection method is known as the interval-censoring scheme, resulting in interval-censored data. The termination time of such experiments can further give rise to Type I and Type II interval censoring. In Type I interval-censoring, all units are inspected simultaneously at prespecified times (including the termination time), and only the number of failures within consecutive intervals is recorded, instead of the exact failure times, primarily for administrative convenience. The interval-censoring scheme has become increasingly prevalent across engineering [14], biostatistics [15,16], economics [17], and related fields; therefore, it is adopted in the present study.
The life performance index is widely recognized as a numerical measure of process performance and potential, and it has been extensively investigated under different distributional assumptions and censoring schemes [18,19,20,21]. Within the framework of Type I interval censoring, a substantial body of research has explored its applications in diverse fields. These include the design and evaluation of sampling plans [22,23,24,25], system reliability analysis [26,27], model selection [28], hypothesis testing for the mean [29], survival analysis [15], and regression modeling [30,31]. Such studies highlight both the versatility of and the methodological challenges that arise when handling interval-censored data.
Apart from these applications, parameter estimation with Type I interval-censored data has also attracted considerable attention. The classical method MLE has been widely applied in many studies. Recent studies have focused on improving the efficiency of the MLE method. Considering the lower efficiency of MLE with an interval-censoring scheme, Tan [32] proposed a new approach to the Weibull distribution with interval data to improve the efficiency for the MLE problem. Similarly, Wang et al. [33] presented a novel expectation-maximization (EM) algorithm to find the maximum likelihood estimators for interval-censored data. This algorithm is robust to initialization and straightforward to implement. Intuitively, the aforementioned studies do not consider prior information. For this, Ganjali and Baghfalaki [34] constructed a Bayesian method to infer the unemployment duration data. Xu and Wang [35] derived a conjugate prior for the homogeneous gamma process and developed efficient posterior sampling algorithms, significantly improving computational efficiency and estimation accuracy for degradation inference. Furthermore, it extends the conjugate framework to heterogeneous gamma processes and proposes a novel online algorithm that enables recursive parameter updates and effective multi-system remaining useful life prediction. However, the above studies mainly focus on the data with a known distribution. In practice, the distribution of data is usually not fully known. Therefore, nonparametric approaches can be employed to solve the problem. For example, Zeng et al. [36] provided a nonparametric MLE for semiparametric transformation models with interval-censored data; the method converges stably with the existence of time-dependent covariates. The above studies mainly focus on improving efficiency rather than data processing. For this reason, the conditional imputation method [37] and iterative single-point imputation [38] are proposed to address the issues of missing data, improving the performance of censored data, and parameter estimation. Additionally, several studies have compared the efficiency of the MLE and found that it outperforms the naive likelihood estimator [39]. Furthermore, the MLE is usually closer to the best estimator and more robust compared to the minimum distance estimation, ad hoc approach, and imputation method [40].
Although existing studies provide valuable insights, most focus primarily on improving the performance and applications of MLE. Importantly, none of these methods admits closed-form solutions. To provide closed-form solutions, iterative numerical procedures are required, which increase computational complexity, are time-consuming, and are often sensitive to initial values. Consequently, developing a reliable and straightforward parameter estimation method that enables the derivation of closed-form solutions is crucial. In this study, we employ data transformation to construct least-squares estimation (LSE) methods. By converting the PDF into the cumulative distribution function (CDF), a regression framework is established, enabling the application of LSE for parameter estimation and yielding closed-form solutions. Moreover, we derive the statistical properties of the LSE estimators, including asymptotic unbiasedness and normality. Furthermore, we propose an extension of the LSE along with two bias-corrected estimation methods, which not only preserve closed-form solutions but also enhance estimation performance.
The remainder of this paper is organized as follows. Section 2 reviews the life performance index and the MLE method for the Weibull distribution based on Type I interval-censored data. Section 3 presents the proposed LSE methods for the Weibull distribution under Type I interval-censoring, including bias-corrected extensions and their large-sample properties. Section 4 evaluates and compares the performance of the MLE and the proposed methods using Monte Carlo simulations with the absolute bias and mean squared error (MSE) as evaluation metrics. In Section 5, two real-world examples are presented to illustrate the practical applications of the proposed parameter estimation methods. Finally, concluding remarks are provided in Section 6.
2. The Life Performance Index for the Weibull Distribution
Suppose that random variable T follows a Weibull distribution with the shape parameter and scale parameter . Denoted it by . The PDF and CDF of are given by
and
respectively. To obtain a reliable life performance index, following Wu and Lin [41], the Weibull data are first transformed into an exponential distribution. Specifically, let ; then follows an exponential distribution with scale parameter . Defining , the PDF and CDF of are given by
and
respectively. The mean and the standard deviation of the variable are and , respectively. The life performance index , designed to evaluate larger-the-better quality characteristics, can be defined and presented by
where denotes the known lower specification limit (LSL) of variable , with being the corresponding LSL of variable . In this study, is defined as a known constant and does not require estimation. In practice, however, the process parameters are typically unknown and must be estimated. To this end, the conventional MLE method is introduced as follows.
Suppose units are placed on a life test simultaneously at the initial time; without loss of generality, denote it by . The units are inspected at prespecified times , where represents the scheduled termination time of the life test. Let denote the numbers of units that fail within the intervals (0 (, respectively. Define as the cumulative number of failures observed up to the i-th intervals, such that for . At the final inspection time , units remain surviving, which are then treated as censored observations. Accordingly, the likelihood function under Type I interval-censoring is given by
where (). The MLE of , denoted as (), is obtained by maximizing the log-likelihood function. The term MLE is used to denote the maximum likelihood estimation and the maximum likelihood estimate hereafter. Unfortunately, does not admit closed-form solutions and must be computed using numerical methods, which poses challenges for practical implementation. By substituting with in Equation (5), the MLE of the life performance index is expressed as
3. Proposed Estimation Methods
3.1. Least-Squares Estimation Methods
Suppose the random variable and define . Then, , where denotes the uniform distribution on the interval . In the case of complete samples, let be independent and identically distributed (i.i.d), and define for . It follows that . Furthermore, let the vector denote the order statistics from , where the i-th element is . Consequently, follows a Beta distribution with shape parameters and , i.e., for . The mean of , also referred to as the mean rank, is given by
When the data collected is subject to the Type I interval-censoring scheme, the exact failure times of individual units are unobservable. Nevertheless, the probability of failure prior to can be expressed as
Furthermore, if units fail earlier than , it follows that lies between the survival times of the and units. Denote the failure times of the and units by and , respectively. Accordingly, we obtain the following expression:
To estimate the values of the cumulative distribution function , we employ the cumulative mean rank, expressed as:
Equation (10) can be rewritten as
To facilitate a straightforward estimation of the parameters in Equation (12), we can use the midpoint of the interval for the approximation:
Furthermore, by applying the logarithm twice to Equation (13), we obtain
where , , and , . The estimators and of the regression parameters and are given by
and
where . The term LSE is used to denote the least-squares estimation, and the least-squares estimate hereafter. The LSEs of the parameters and are given by
and
respectively. Replacing with in Equation (5), the LSE of the life performance index is given b
As m increases, the probability of sample-free observation intervals also rises, which reduces the estimation efficiency of the LSE method. To improve estimation performance, a method that applies LSE after removing intervals with no observations is defined as PLSE. The corresponding parameter is denoted by . Consequently, the PLSE of is given by
We further examined the large-sample properties of the proposed estimators, from which the following results are established.
Theorem 1.
Let be i.i.d. random variables from , and let denote predetermined time points. Suppose that units fail earlier than . Then, the parameter estimators in Equations (17) and (18) satisfy
Theorem 2.
The parameter estimators in Equations (17) and (18) satisfy
Then, and are consistent estimators of the parameters and and possess asymptotic normality. Similarly, the improved estimators and exhibit the same properties. The proofs of Theorems 1 and 2 are provided in the Appendix A.
3.2. Bias-Corrected Least-Squares Estimation Methods
Although the estimators and are consistent, they may exhibit bias in finite samples. To enhance their performance, bias correction is implemented using Efron’s [42] bootstrap resampling method. The idea of this method is to generate pseudo-samples from the original data to estimate the bias of the estimator and then subtract the estimated bias from the original estimator to obtain the bias-corrected estimator.
Specifically, let , , denote a Type I interval-censored sample drawn from . The LSE method is applied to estimate parameters and the resulting LSE is denoted by . pseudo-samples can be generated from the distribution based on repetitions of same size. In each repetition, the LSEs of and are estimated using the generated pseudo-sample and the resulting LSE is denoted by , where , is a large positive integer. Correspondingly, the life performance index based on the bootstrap samples can be expressed as , where and .
Thus, the bootstrap estimate of the bias can be obtained as follows:
In this paper, we consider the expected values of and to be
Accordingly, the bias-corrected least squares estimators of and are given by:
The algorithm for implementing the bias-corrected LSE is presented as follows:
- Based on the Type-I interval-censored sample , , the LSE is obtained based on this sample.
- Generate a pseudo-sample of size n from the Weibull distribution with shape parameter and scale parameter .
- Transform the generated pseudo-sample into a Type I interval-censored sample based on , denoted as a Type-I interval pseudo-sample.
- Compute the LSEs of k, , and using this Type-I interval pseudo-sample.
- Repeat Step 2 to Step 4 times to obtain two sets of size estimators, i.e., and
- Calculate the and according to the Equation (22).
- Using Equation (22), the bias-corrected LSEs of k, and are computed as , and .
Similarly, by replacing the LSE method in the above steps with the PLSE method, we obtain the bias-corrected PLSE estimators, denoted by , and . For the sake of brevity, the details are omitted here.
4. Simulation Study
This section presents numerical simulations designed to evaluate the performance of the proposed LSEs. First, we compare the efficiency of MLE with that of the LSE and PLSE. Next, to assess the impact of the bias-correction procedure, we report the simulation results obtained from the bias-corrected versions of the LSE and PLSE. All simulations are conducted using 10,000 Monte Carlo replications. The comparisons are based on two criteria: the absolute bias () and the mean squared error (MSE), whose mathematical formulations are provided below.
and
where denotes and corresponding to , with representing the true parameters and for . Here, stands for the estimators of , including the MLE, LSE, PLSE, and the bias-corrected versions of LSE and PLSE. The data for the experimental design are randomly generated from the Weibull distribution with parameter settings . Following Hu and Gui [18], and Wu and Lin [41], the sample sizes are set to , with a lower specification limit of and interval numbers . The corresponding inspection time points for each case are summarized in Table 1. The code of the proposed method can be found at https://github.com/Zhengcheng11/Code-of-the-LSE-and-PLSE (accessed on 19 December 2025).
Table 1.
Observation time in different groups.
The simulation results are presented in Table 2, Table 3, Table 4, Table 5 and Table 6. Table 2, Table 3 and Table 4 report the results for the MLE, LSE, and PLSE, whereas Table 5 and Table 6 present the outcomes for the bias-corrected LSE and bias-corrected PLSE. Since the estimates of are typically below 0.01, the and MSE values are multiplied by 100 and 10,000, respectively, for ease of comparison. In Table 2, Table 3, Table 4, Table 5 and Table 6, they are reported as and , respectively.
Table 2.
Type I interval-censored with .
Table 3.
Type I interval-censored with .
Table 4.
Type I interval-censored with .
Table 5.
Type I interval-censored with for the bias-corrected LSE and bias-corrected PLSE.
Table 6.
Type I interval-censored with for bias-corrected LSE and bias-corrected PLSE.
We first compare the results of the MLE, LSE, and PLSE. Based on the simulation outcomes, the following observations can be made:
- The and MSE of all three methods decrease toward zero as the sample size increases.
- For parameter , both and increase with increasing .
- For the parameter , the of all three methods decreases as increases.
- For estimating , the LSE performs best when or . When , the PLSE yields the best performance for , whereas the MLE is optimal for and . For estimating , the MLE is the most accurate in most cases.
- When , the LSE outperforms the MLE for estimating . However, as either m or increases, the of MLE becomes superior to that of the LSE for . Although the PLSE shows smaller values than the LSE when , its overall performance remains less effective than the LSE.
- For the life performance index , the MSEs computed using the LSE are the smallest when or , whereas the PLSE yields the lowest MSE when . Similarly, the values among the three methods exhibit patterns consistent with those of the MSEs.
- In the scenario of Case 4, when and , or , the values of corresponding to the MLE are extremely high. This is primarily attributable to computational issues or suboptimal choices of initial values, a limitation that can be mitigated by adopting the EM algorithm. Essentially, this problem arises because the MLE does not have a closed-form solution, whereas the proposed method is endowed with an explicit solution. Therefore, the results derived from the proposed method will not be affected by initial values, unlike those from the MLE.
It can be observed that the LSE performs optimally in terms of simplicity and efficiency when . However, as either or increases, the accuracy of both the LSE and PLSE deteriorates. Consequently, bias-corrected versions of the LSE and PLSE were applied for and , with the corresponding results presented in Table 5 and Table 6, respectively. Based on the results presented in Table 1, Table 2, Table 3, Table 4, Table 5 and Table 6, the following additional conclusions can be drawn:
- The bias-corrected methods are more effective than the uncorrected counterparts. Among the three parameters, significant improvements are observed for and , whereas the improvement for is less pronounced.
- When comparing the original and bias-corrected methods, bootstrap-based correction is particularly effective for PLSE.
- Compared with the MLE, the LSE should be used when , while the bias-corrected PLSE is recommended for or .
In summary, when the number of inspections is small, and no bias correction is applied, the LSE or PLSE is recommended to estimate the parameters , , and the life performance index . These methods are more computationally convenient than MLE and can provide closed-form solutions. However, as the sample size increases, the performance of MLE can be improved due to large-sample theory. The choice between LSE and PLSE depends primarily on the presence of sample-free observation intervals. When bias correction is applied, the bias-corrected PLSE outperforms all other estimation methods. Additionally, for readers interested in exploring other parameter settings, the code for the proposed method can be found at https://github.com/Zhengcheng11/Code-of-the-LSE-and-PLSE (accessed on 19 December 2025).
5. Real Data Analysis
5.1. Example of Ball Bearing Failure Data
An example involving ball bearing failure data is considered to illustrate the application of the proposed method. The dataset was originally reported by Caroni [43], and also discussed by Wu and Lin [41]. It contains the failure times (in number of cycles) of n = 25 ball bearings subjected to an automatic lifetime test. The data are as follows:
0.1788, 0.2892, 0.3300, 0.4152, 0.4212, 0.4560, 0.4848, 0.5184, 0.5196, 0.5412, 0.5556, 0.6780, 0.6780, 0.6780, 0.6864, 0.6864, 0.6888, 0.8412, 0.9312, 0.9864, 1.0512, 1.0584, 1.2792, 1.2804, 1.7340.
As noted by Wu and Lin [41], these data can be appropriately modeled using a Weibull distribution. To implement the methods proposed in this study, and considering with the inspection times = , and , then converting the complete sample into a Type-I interval-censored sample, as presented in Table 7.
Table 7.
The Type-I interval censored data of ball bearing failures data.
Based on the data in Table 7 and considering the LSL L = 0.05, the resulting estimates are as follows:
- MLE: 2.0988, 0.8263, and 0.9253;
- LSE: 1.8475, 0.8447, and 0.9317;
- PLSE: 2.2231, 0.8131, and 0.9208;
- Bias-corrected LSE: 2.0477, 0.8460, and 0.9310;
- Bias-corrected PLSE: 2.4433, 0.8152, and 0.9182.
For the results obtained from LSE, MLE, and PLSE, the PLSE produces the largest estimate of , while its estimates of and are the smallest. Moreover, the LSE and PLSE methods give opposite conclusions regarding the parameters: the LSE suggests relatively lower estimates for and higher estimates for and . After applying bias correction, the estimates of and increase, whereas the estimate of decreases a little bit compared to the uncorrected values.
Based on , the probability that the lifetime exceeds the lower specification limit can be estimated as 0.9280. Similarly, using , , and , the corresponding probabilities of are 0.9340, 0.9239, 0.9333, and 0.9215, respectively.
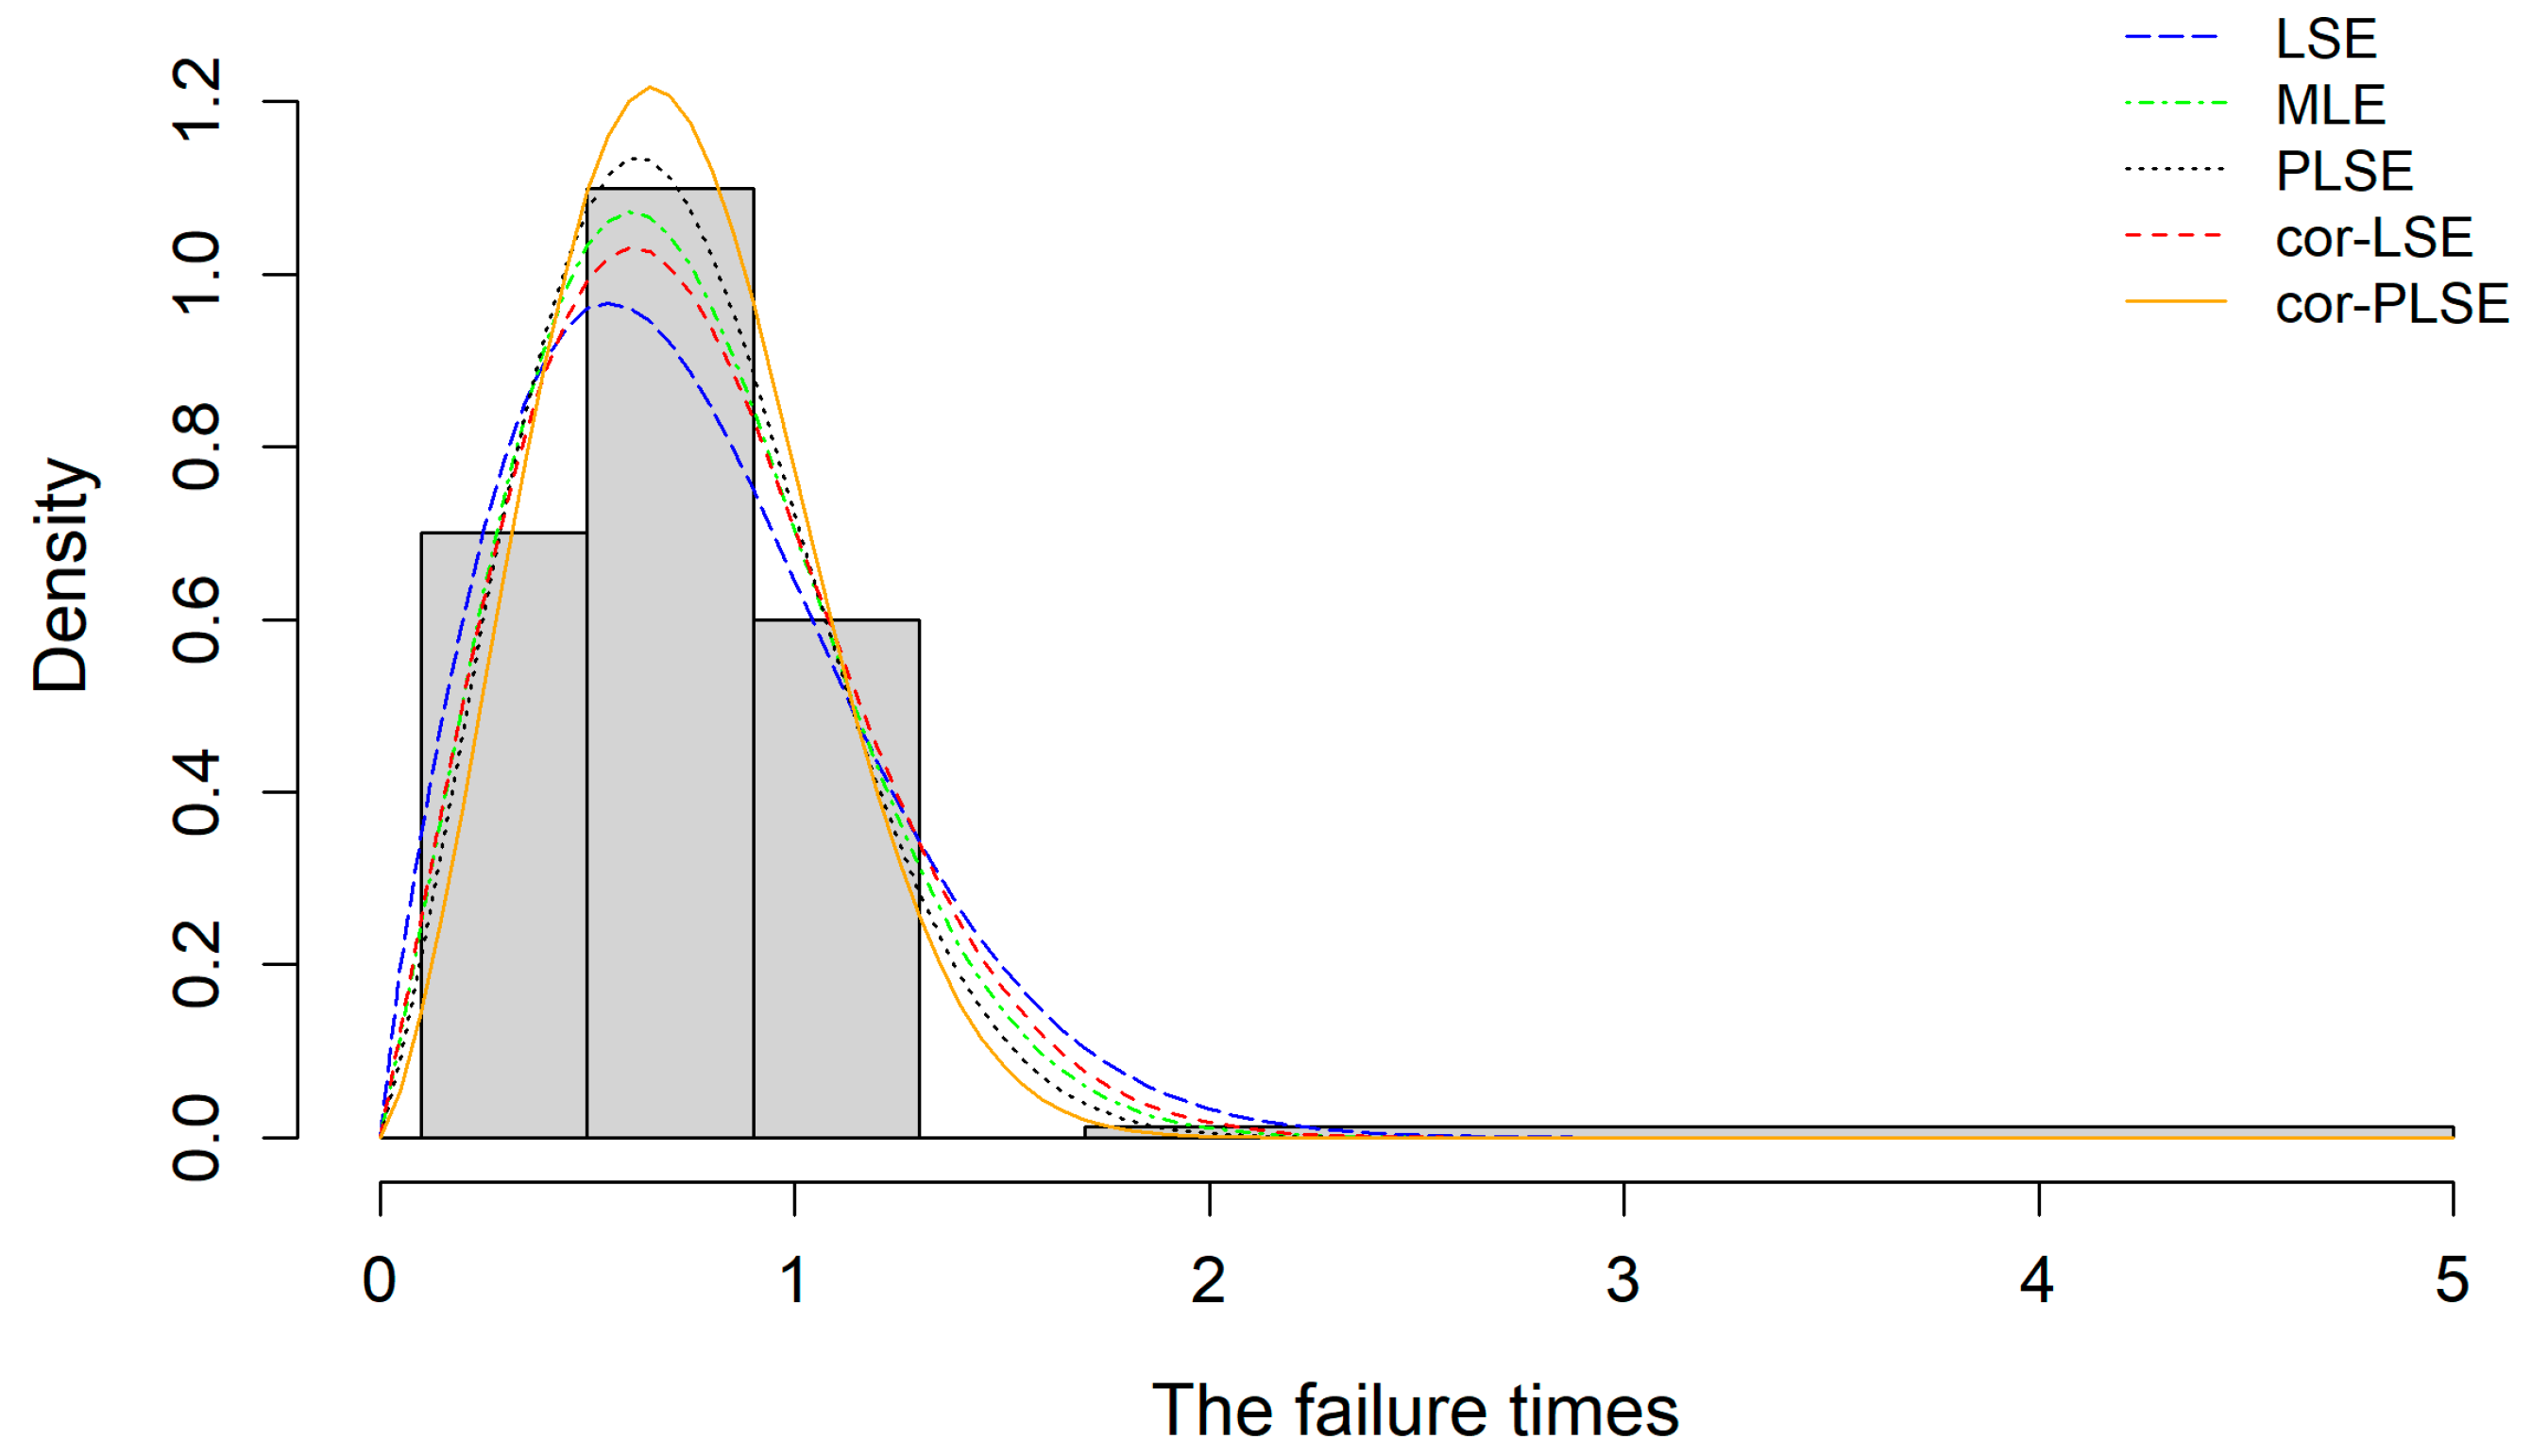
In addition, Figure 1 presents the fitted PDF for this dataset. The figure indicates that the performance of the estimation methods is generally similar, with the PLSE and bias-corrected PLSE providing fits that more accurately reflect the observed data. These observations are consistent with the conclusions reported in Section 4.
Figure 1.
Graph of the fitted PDF for ball bearing failures data.
5.2. Example of New Drug-Induced Leukemia Remission Times
In this subsection, the proposed method is applied to a published dataset in [44] to illustrate the procedures. The dataset comprises remission times observed in leukemia patients treated with a new drug. The 22 remission times are as follows (in days):
47, 56, 58, 64, 77, 79, 89, 128, 131, 142, 144, 149, 163, 166, 175, 176, 184, 184, 188, 190, 191, 204.
As stated in [44], both the Kolmogorov-Smirnov test statistic and its corresponding p-value results indicate that the Weibull distribution provides an excellent fit for this data. We employ the Weibull distribution to model this dataset. To illustrate the application of the proposed method, we set and examine time points 90, 130, 170, and 210. The complete sample is transformed into a Type I interval-censored dataset sample, with results presented in Table 8.
Table 8.
The Type I interval-censored data of remission times.
Based on the data in Table 8 and considering the LSL L = 0.05, the resulting estimates are as follows:
- MLE: 2.9180, 149.3540 and 1.0000;
- LSE: 2.4811, 145.6516 and 0.9999;
- PLSE: 2.4811, 145.6516, and 0.9999;
- Bias-corrected LSE: 2.5370, 144.1888, and 1.0000.
- Bias-corrected PLSE: 2.6422, 144.9373, and 1.0000.
For the results obtained from LSE, MLE, and PLSE, the MLE produces the largest estimates of and , as well as the highest value of (1.0000). In contrast, LSE and PLSE produce identical parameter estimates across all three metrics , , and , with their values of and being lower than those from MLE, and their value slightly reduced to 0.9999. Following bias correction, the estimates of for both bias-corrected LSE and bias-corrected PLSE increase compared to their uncorrected counterparts (LSE and PLSE), whereas the estimates of exhibit a slight decrease. Notably, the bias correction restores the value of back to 1.00 for both corrected methods, aligning it with the MLE result for this metric.
Based on , the probability that the lifetime exceeds the lower specification limit can be estimated as 1.00. Similarly, using , , and , the corresponding probabilities are 0.9999, 0.9999, 1.0000, and 1.0000, respectively.
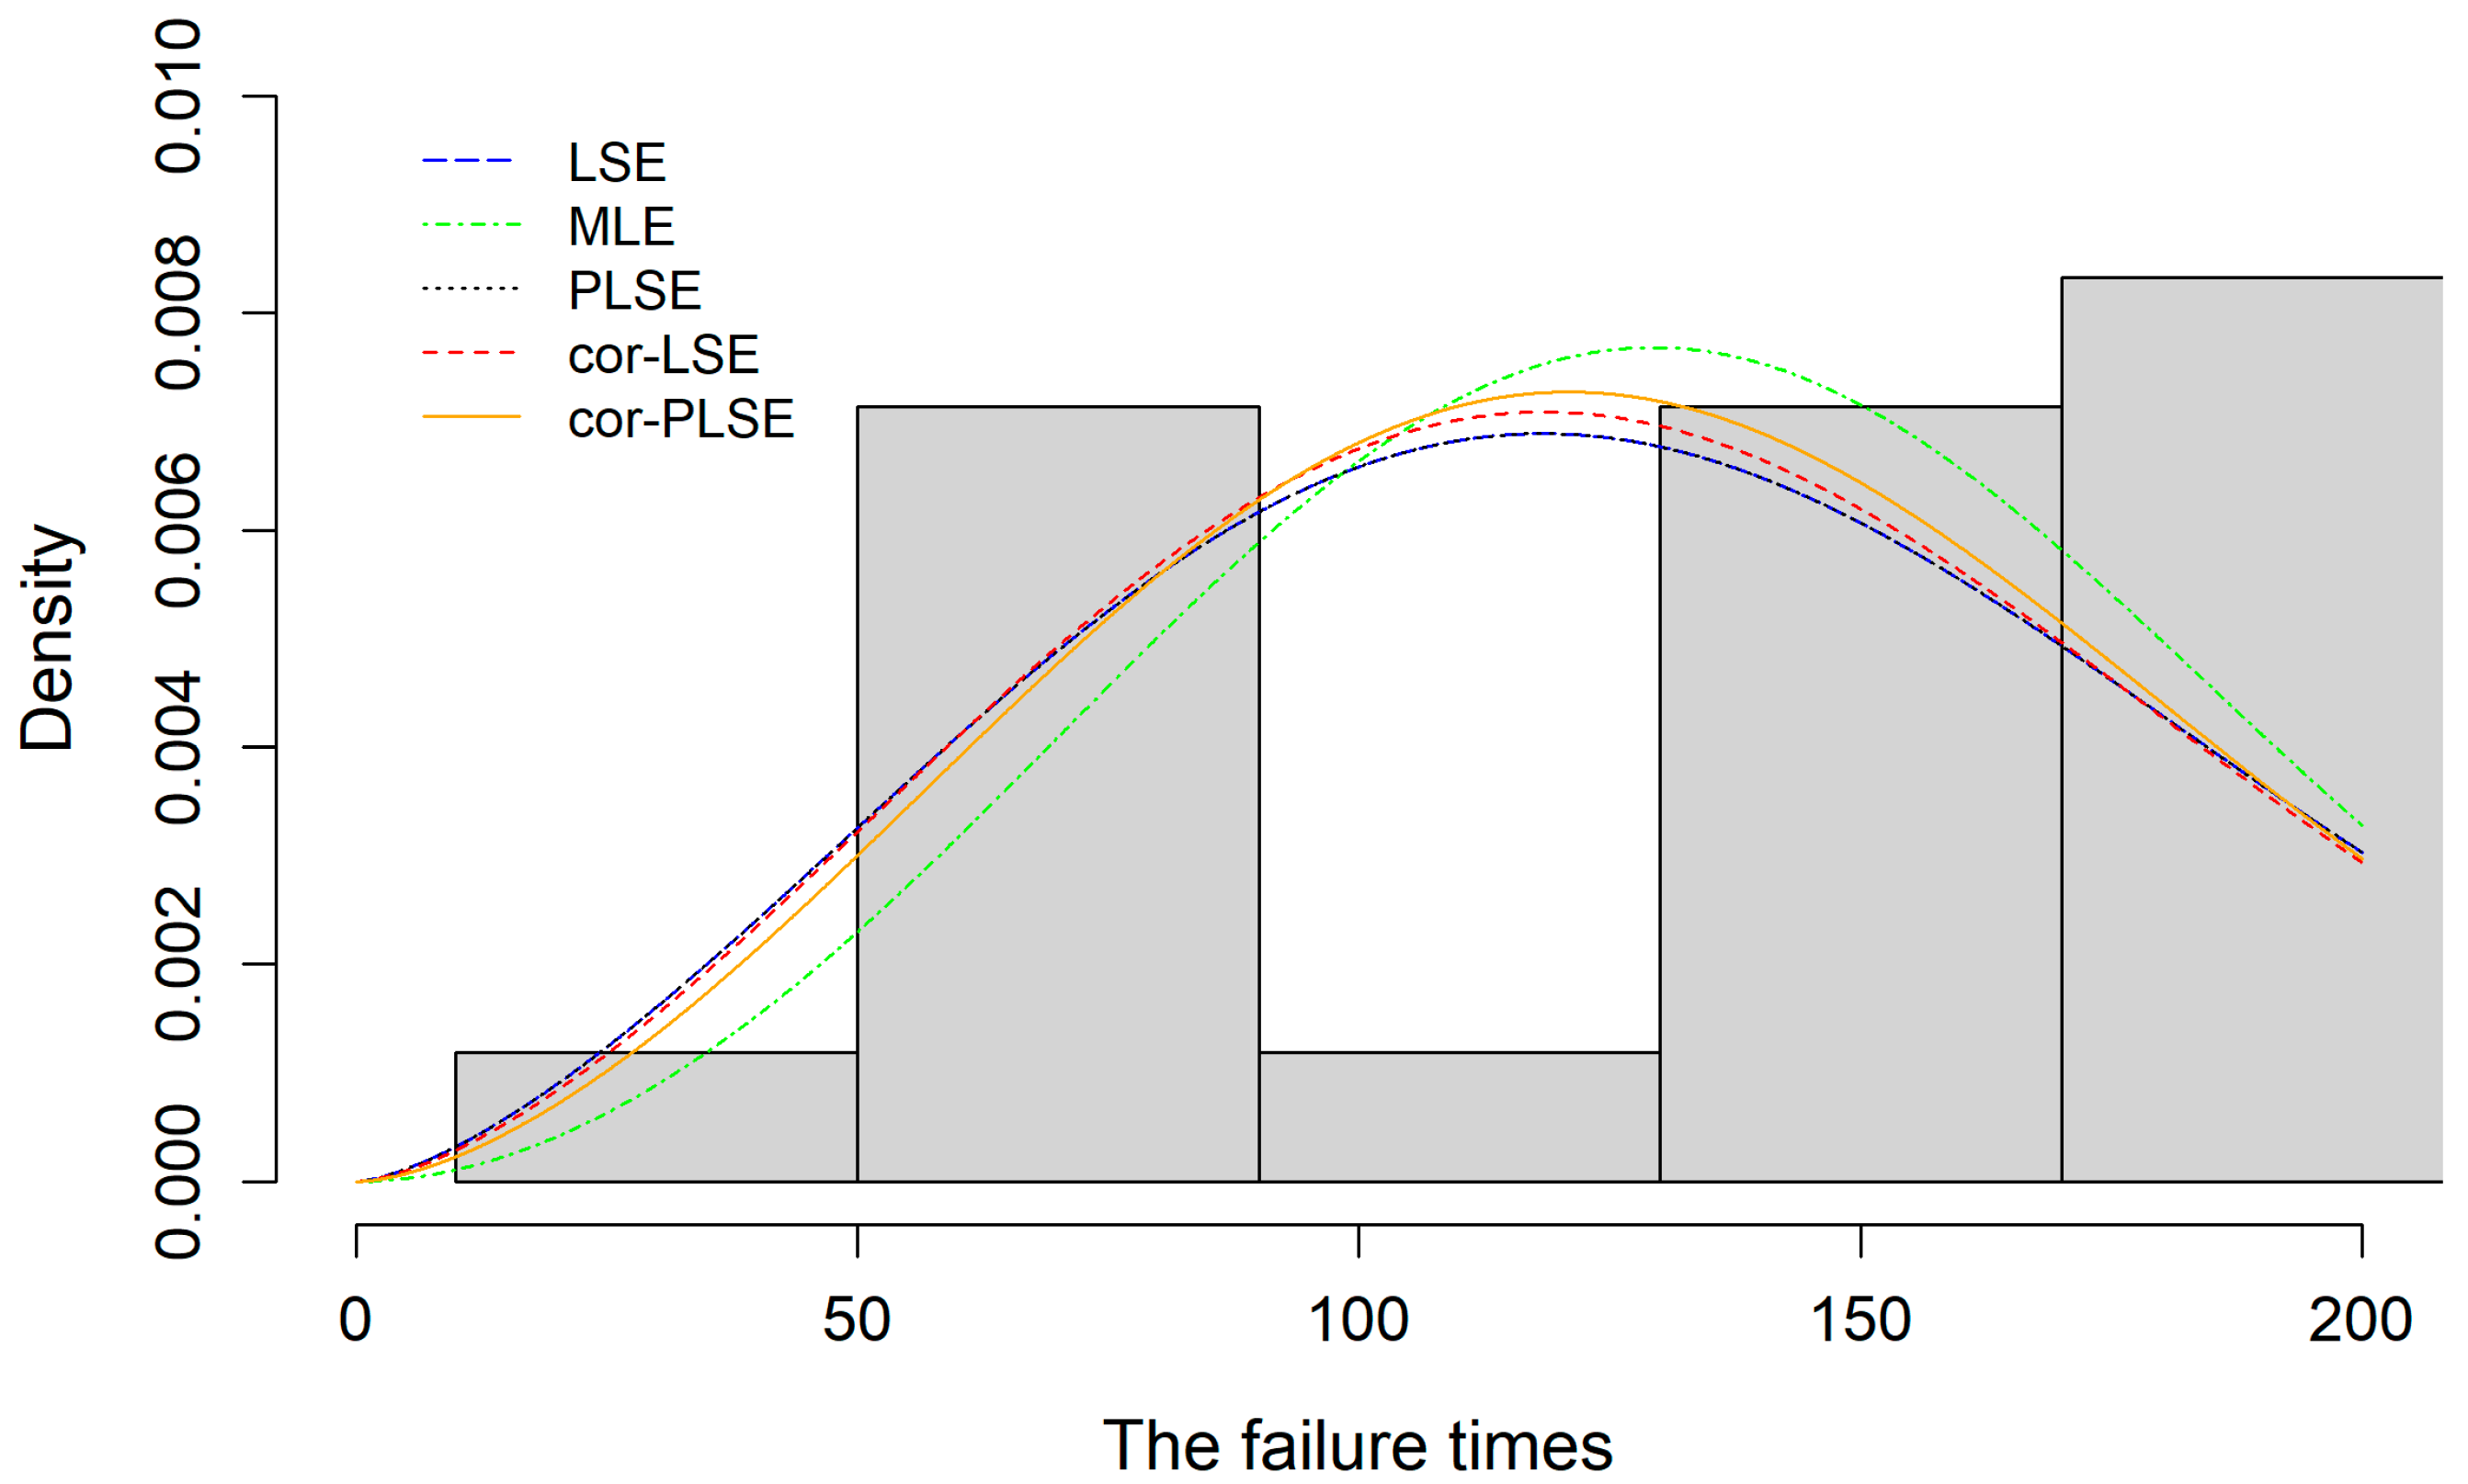
In addition, Figure 2 presents the fitted PDF for this dataset. The figure indicates that the performance of the estimation methods is generally similar, with the bias-corrected LSE and bias-corrected PLSE providing fits that more accurately reflect the observed data.
Figure 2.
Graph of the fitted PDF for ball remission times data.
6. Conclusions
In this paper, we proposed four LSE methods to estimate the life performance index and the parameters of the Weibull distribution based on Type I interval-censored data. The proposed methods can provide closed-form solutions, offering clear advantages over widely used alternative approaches. The performance of the MLE and the proposed LSE methods was evaluated through simulation studies, using and MSE as comparison criteria. The results indicated that, without bias correction, the LSE and PLSE perform competitively. When bias correction is incorporated, the bias-corrected PLSE outperforms all other methods. It should be noted that an excessive number of intervals without observations may lead to an overestimation of the life performance index by the MLE or LSE methods, while PLSE will underestimate the life performance index. It is suggested not to use short time intervals for the proposed methods. Finally, two real data examples involving ball bearing failures and new drug-induced leukemia remission times were used to illustrate the proposed estimation methods. The analysis demonstrated that the LSE method provides reasonable and reliable parameter estimates.
A major challenge in parameter inference lies in obtaining the exact sampling distributions of the estimators. Alternative computational approaches may help alleviate difficulties arising from the unknown distributions of the model parameters. At the same time, the efficiency of the LSE decreases when the intervals are obtained without direct observations. In addition, in Equation (13), we use the “midpoint” of the interval to estimate the parameters, but this approach may lead to systematic bias in the estimators for biased distributions. Therefore, it is essential to explore strategies for improving the proposed methods and to investigate more robust estimation schemes based on enhanced experimental designs for the interval-censoring scheme. These issues remain open and will be addressed in future research.
Author Contributions
Conceptualization, investigation, writing, review and editing, and project administration: Z.M.; Conceptualization, investigation, writing: Y.L.; methodology, investigation, and funding acquisition: J.-Y.C.; validation, investigation, review and editing: T.-R.T. All authors have read and agreed to the published version of the manuscript.
Funding
Chiang’s work was supported by the Fundamental Research Funds for the Central Universities No. JBK2201058; Tsai’s work was supported by the National Science and Technology Council, Taiwan, grant number NSTC 114-2221-E-032-030-MY2.
Data Availability Statement
All data generated or analyzed during this study are included in this article.
Conflicts of Interest
The authors declare no potential conflicts of interest with respect to the research, authorship, and/or publication of this article.
Appendix A. The Proof of Theorem 1 and Theorem 2
In what follows, we first prove some auxiliary lemmas and then provide the proofs of Theorems 1 and 2.
Lemma A1.
Let X be random variable with the CDF F. Define that random variable , then, , where is the uniform distribution between 0 and 1.
Lemma A2.
are the order statistics from . Then, and the PDF is given by
where is the Gamma function.
Suppose that are i.i.d samples from distribution . are predetermined time points. Same to Section 3.1, assuming that units fail before , it means that is between the survival time of sample and the survival time of sample.
Lemma A3.
Let , then,
Proof.
Suppose samples fail at time . Hence
where is the indicative function. Then, when , it can be given that
Because are the i.i.d samples from . According to Khinchin’s law of large numbers, the above equation can be converted to
□
Lemma A4.
Let . . Then,
where
Proof.
Let , then
It is known that are i.i.d. Given , based on Equation (A2), we can obtain
where is the i-th element of , is the i-th element of , then
When , then,
where . Hence.
then . According to the central limit theorem, then
□
Lemma A5.
Let , ,
Proof.
and , then
□
Appendix A.1. The Proof of Theorem 1
According to Equation (15), it can be found that
According to Lemma A3, it can be found that
Consistency of parameter estimators is proved. Similarly,
According to Lemma A3,
Consistency of parameter estimators is proved.
Appendix A.2. The Proof of Theorem 2
According to Equations (15), (17) and (18), we have
where , are continuous functions independent of n. Expand and in a first-order Taylor expansion at , then
where is a value between and . According to Theorem 1, it can be found that
so
From Lemma A3 and Lemma A4, we have . Let
where
By Lemma A5, we have
So,
where . Similarly,
By Lemma A3 and Lemma A5, we have
So,
According to Lemma A4, . Hence,
According to Theorem 2, the estimations of asymptotic variance of and can also be obtained. Firstly, obtain the estimators of , and , i.e., , and . We have
where
Hence, the estimators of asymptotic variances of and are
References
- Zacharias, M. The importance of quality control for the success of a company. Asian J. Logist. Manag. 2022, 1, 99–106. [Google Scholar] [CrossRef] [Scilit]
- Tian, W.; Zhao, Y.; Li, S.; Ning, W. Empirical likelihood-type methods for confidence intervals of the process capability index Cpm. Commun. Stat.-Simul. Comput. 2025; pp. 1–20, Online ahead print. [CrossRef] [Scilit]
- Tong, L.I.; Chen, K.S.; Chen, H.T. Statistical testing for assessing the performance of lifetime index of electronic components with exponential distribution. Int. J. Qual. Reliab. Manag. 2002, 19, 812–824. [Google Scholar] [CrossRef] [Scilit]
- Wang, T.C.; Wu, C.W.; Shu, M.H. A variables-type multiple-dependent-state sampling plan based on the lifetime performance index under a Weibull distribution. Ann. Oper. Res. 2022, 311, 381–399. [Google Scholar] [CrossRef] [Scilit]
- Jafari, A.A.; Bafekri, S. Inferences on the performance index of Weibull distribution based on k-record values. J. Comput. Appl. Math. 2021, 382, 113060. [Google Scholar] [CrossRef] [Scilit]
- Rasay, H.; Naderkhani, F.; Golmohammadi, A.M. Designing variable sampling plans based on lifetime performance index under failure censoring reliability tests. Qual. Eng. 2020, 32, 354–370. [Google Scholar] [CrossRef] [Scilit]
- Gijbels, I. Censored data. Wiley Interdiscip. Rev. Comput. Stat. 2010, 2, 178–188. [Google Scholar] [CrossRef] [Scilit]
- Balakrishnan, N.; Ling, M.H.; So, H.Y. Accelerated life testing of one-shot devices: Data collection and analysis. In One-Shot Device Testing Data; John Wiley & Sons: Hoboken, NJ, USA, 2021; Chapter 1; p. 2. [Google Scholar]
- Prentice, R.L. Linear rank tests with right censored data. Biometrika 1978, 65, 167–179. [Google Scholar] [CrossRef]
- Nassar, M.N.; Okasha, H.; Albassam, M. E-Bayesian estimation and associated properties of simple step-stress model for exponential distribution based on type-II censoring. Qual. Reliab. Eng. Int. 2021, 37, 997–1016. [Google Scholar] [CrossRef] [Scilit]
- Starling, J.K.; Mastrangelo, C.; Choe, Y. Improving Weibull distribution estimation for generalized Type I censored data using modified SMOTE. Reliab. Eng. Syst. Saf. 2021, 211, 107505. [Google Scholar] [CrossRef] [Scilit]
- Tanış, C.; Saraçoğlu, B.; Kuş, C.; Pekgör, A.; Karakaya, K. Transmuted lower record type Fréchet distribution with lifetime regression analysis based on type I-censored data. J. Stat. Theory Appl. 2021, 20, 86–96. [Google Scholar] [CrossRef] [Scilit]
- Chen, T.; Wang, L. Linear Bayes estimator of the extreme value distribution based on type II censored samples. Commun. Stat.-Simul. Comput. 2023, 52, 4532–4544. [Google Scholar] [CrossRef] [Scilit]
- Johnen, M.; Schmitz, C.; Kateri, M.; Kamps, U. Fitting lifetime distributions to interval censored cyclic-aging data of lithium-ion batteries. Comput. Ind. Eng. 2020, 143, 106418. [Google Scholar] [CrossRef] [Scilit]
- Singh, R.S.; Totawattage, D.P. The statistical analysis of interval-censored failure time data with applications. Open J. Stat. 2013, 3, 155–166. [Google Scholar] [CrossRef]
- Shen, H.; Cook, R.J. Analysis of interval-censored recurrent event processes subject to resolution. Biom. J. 2015, 57, 725–742. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Li, S.; Nadolnyak, D.; Hartarska, V. Agricultural land conversion: Impacts of economic and natural risk factors in a coastal area. Land Use Policy 2019, 80, 380–390. [Google Scholar] [CrossRef] [Scilit]
- Hu, X.; Gui, W. Assessing the lifetime performance index with Lomax distribution based on progressive type I interval censored sample. J. Appl. Stat. 2020, 47, 1757–1775. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wu, S.F.; Wu, Y.C.; Wu, C.H.; Chang, W.-T. Experimental design for the lifetime performance Index of Weibull products based on the progressive type I interval censored sample. Symmetry 2021, 13, 1691. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Gui, W. Statistical inference for the lifetime performance index of products with Pareto distribution on basis of general progressive type II censored sample. Commun. Stat.-Theory Methods 2021, 50, 3790–3808. [Google Scholar] [CrossRef] [Scilit]
- Wu, S.F.; Liu, T.H.; Lai, Y.H.; Chang, W.-T. A study on the experimental design for the lifetime performance index of Rayleigh lifetime distribution under progressive type I interval censoring. Mathematics 2022, 10, 517. [Google Scholar] [CrossRef] [Scilit]
- Lu, W.; Tsai, T.R. Interval censored sampling plans for the log-logistic lifetime distribution. J. Appl. Stat. 2009, 36, 521–536. [Google Scholar] [CrossRef] [Scilit]
- Lu, W.; Tsai, T.R. Interval censored sampling plans for the gamma lifetime model. Eur. J. Oper. Res. 2009, 192, 116–124. [Google Scholar] [CrossRef] [Scilit]
- Chen, L.S.; Yang, M.C.; Liang, T.C. Bayesian sampling plans for exponential distributions with interval censored samples. Nav. Res. Logist. 2015, 62, 604–616. [Google Scholar] [CrossRef] [Scilit]
- Yang, M.C.; Chen, L.S.; Liang, T. A Bayesian approach for selecting the best exponential population with interval censored samples. Commun. Stat.-Theory Methods 2014, 43, 2357–2369. [Google Scholar] [CrossRef] [Scilit]
- Tsai, T.R.; Ng, H.K.T.; Pham, H.; Lio, Y.; Chiang, J.Y. Reliability inference for VGA adapter from dual suppliers based on contaminated type-I interval-censored data. Qual. Reliab. Eng. Int. 2019, 35, 2297–2313. [Google Scholar] [CrossRef] [Scilit]
- Zhuang, L.; Xu, A.; Pang, J. Product reliability analysis based on heavily censored interval data with batch effects. Reliab. Eng. Syst. Saf. 2021, 212, 107622. [Google Scholar] [CrossRef] [Scilit]
- Tsai, T.R.; Wu, S.H.; Shen, Y. Model selection methods for reliability assessment based on interval-censored field failure samples. Int. J. Reliab. Qual. Saf. Eng. 2020, 27, 2050018. [Google Scholar] [CrossRef] [Scilit]
- Chen, L.S. Locally best tests for exponential distributions with interval-censored data. J. Stat. Comput. Simul. 2014, 84, 1946–1959. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.; Shen, Y. A semiparametric regression cure model for interval-censored data. J. Am. Stat. Assoc. 2009, 104, 1168–1178. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhang, Z.; Zhao, Y. Empirical likelihood for linear transformation models with interval-censored failure time data. J. Multivar. Anal. 2013, 116, 398–409. [Google Scholar] [CrossRef] [Scilit]
- Tan, Z. A new approach to MLE of Weibull distribution with interval data. Reliab. Eng. Syst. Saf. 2009, 94, 394–403. [Google Scholar] [CrossRef] [Scilit]
- Wang, L.; McMahan, C.S.; Hudgens, M.G.; Qureshi, Z.P. A flexible, computationally efficient method for fitting the proportional hazards model to interval-censored data. Biometrics 2016, 72, 222–231. [Google Scholar] [CrossRef] [Scilit]
- Ganjali, M.; Baghfalaki, T. Bayesian analysis of unemployment duration data in the presence of right and interval censoring. J. Reliab. Stat. Stud. 2012, 17–32. [Google Scholar]
- Xu, A.; Wang, W. Recursive Bayesian prediction of remaining useful life for gamma degradation process under conjugate priors. Scand. J. Stat. 2025; Online ahead of print.
- Zeng, D.; Mao, L.; Lin, D.Y. Maximum likelihood estimation for semiparametric transformation models with interval-censored data. Biometrika 2016, 103, 253–271. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Kong, D.; Cui, L. The analysis of mixed interval-censored and complete data. Commun. Stat.–Simul. Comput. 2017, 46, 145–163. [Google Scholar] [CrossRef] [Scilit]
- Kong, D.; Huang, J.; Balakrishnan, N.; Cui, L. Stochastic quantile-filling augmentation algorithm to censored and accurate reliability data. Comput. Ind. Eng. 2017, 108, 27–38. [Google Scholar] [CrossRef] [Scilit]
- Hudgens, M.G.; Li, C.; Fine, J.P. Parametric likelihood inference for interval censored competing risks data. Biometrics 2014, 70, 1–9. [Google Scholar] [CrossRef] [Scilit]
- Xiao, X.; Mukherjee, A.; Xie, M. Estimation procedures for grouped data—A comparative study. J. Appl. Stat. 2016, 43, 2110–2130. [Google Scholar] [CrossRef] [Scilit]
- Wu, S.F.; Lin, M.J. Computational testing algorithmic procedure of assessment for lifetime performance index of products with Weibull distribution under progressive type I interval censoring. J. Comput. Appl. Math. 2017, 311, 364–374. [Google Scholar] [CrossRef] [Scilit]
- Efron, B. Computers and the theory of statistics: Thinking the unthinkable. SIAM Rev. 1979, 21, 460–480. [Google Scholar] [CrossRef] [Scilit]
- Caroni, C. The correct “ball bearings” data. Lifetime Data Anal. 2002, 8, 395–399. [Google Scholar] [CrossRef] [Scilit]
- Jia, X.; Wang, D.; Jiang, P.; Guo, B. Inference on the reliability of Weibull distribution with multiply Type-I censored data. Reliab. Eng. Syst. Saf. 2016, 150, 171–181. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.