1. Introduction
In recent years, global climate change has increased the frequency and intensity of extreme weather events, making urban pluvial flooding a major challenge for urban resilience and emergency management [
1]. Due to its localised characteristics and rapid evolution, urban flooding can severely affect transportation systems, infrastructure operations, and emergency response activities. Among various flood-related information, water depth provides a direct indicator of inundation severity and supports flood impact assessment, road accessibility analysis, and emergency decision-making [
2,
3,
4]. Therefore, obtaining timely and accurate street-scale water-depth information after flood events is essential for improving disaster response capabilities.
However, acquiring fine-grained water-depth observations during short-duration flooding events remains challenging. Conventional monitoring systems, such as hydrological stations and sensor networks, usually provide limited spatial coverage and may not capture rapidly changing local inundation conditions [
2,
5,
6]. To address this limitation, researchers have explored alternative data sources, particularly image-based approaches, for flood-depth estimation [
2,
7,
8]. Existing image-based methods mainly rely on supervised learning, geometric measurement, or reference-object reasoning [
4,
9]. Although these approaches have achieved promising results, their application in complex post-disaster environments remains challenging due to variations in observation conditions, the need for scenario-specific information, and uncertainties in interpreting visual flood evidence.
The rapid development of social media platforms has provided new opportunities for disaster monitoring and emergency response. Crowdsourced data, particularly image–text records shared by affected individuals, can provide timely and near-ground observations of disaster situations [
10,
11,
12]. Previous studies have demonstrated the potential of social media data for disaster-related applications, including affected-area identification, location recognition, damage assessment, and situational awareness [
13,
14,
15]. Compared with traditional monitoring systems, crowdsourced records can capture detailed local conditions that are difficult to obtain through fixed observation networks [
5,
16]. For urban flooding, images can provide direct visual evidence of water surfaces, roads, and submerged objects, while accompanying texts may contain complementary information, such as locations, timestamps, numerical depths, and relative water-level descriptions [
17].
Nevertheless, extracting quantitative water-depth information from crowdsourced multimodal data remains challenging. Visual observations usually require identifying appropriate reference objects and establishing relationships between visible submerged parts and water depth. Furthermore, textual descriptions often contain implicit expressions, multiple values, temporal variations, and spatial ambiguity, which makes direct depth extraction difficult. Existing studies have shown that geolocated social media data contain semantic and spatial uncertainties [
18,
19,
20], while multimodal information may involve differences in quality and potential conflicts [
21]. Therefore, image and text should not be simply regarded as equivalent observations; instead, their complementary roles and reliability should be carefully considered when integrating crowdsourced multimodal information.
To address these challenges, this study develops an image-led framework for estimating street-scale urban flood depth from crowdsourced image–text records. Unlike approaches that directly generate depth values from images or combine image and text as equivalent observations, the proposed framework first converts visual observations into structured depth evidence from reference objects and then treats textual depth information as conditional auxiliary evidence. The image module identifies reference objects and submerged parts that are assigned to depth classes based on explicit knowledge relationships. The text module combines rule-based extraction with semantic review to assess whether textual depth cues are quantifiable. Text is incorporated into the final estimate only when predefined directional and image–text discrepancy conditions are satisfied. The methodology therefore focuses on controlling cross-modal inconsistency rather than assuming that multimodal fusion necessarily improves depth estimation.
The main contributions of this study are summarised as follows:
- •
We propose an image-led framework for urban flood-depth estimation from crowdsourced image–text data. The framework treats images as the primary source of depth evidence and integrates textual information only as conditional auxiliary evidence, thereby avoiding direct equivalence between the two modalities.
- •
We develop a structured depth-evidence construction strategy based on reference-object reasoning and text quantifiability assessment. The image module identifies reference objects and submerged parts and maps them to depth values through explicit knowledge relationships, while the text module combines rule-based extraction and semantic review to identify quantifiable depth cues from complex disaster descriptions.
- •
We design a conditional image–text fusion strategy to control textual participation under cross-modal inconsistency. Textual evidence is incorporated only when quantifiability, directional, and image–text discrepancy conditions are satisfied, limiting the influence of temporally or spatially inconsistent descriptions on the final depth estimate.
3. Materials and Methods
3.1. Construction and Analysis of the Crowdsourced Multimodal Dataset
Images related to urban flooding and their accompanying text published on Weibo [
55] are used as the primary data source to construct a crowdsourced multimodal dataset for image-based depth quantification, text-based depth extraction, and image–text fusion evaluation. Data were collected mainly between 23 July and 1 August 2025, with Beijing as the principal study area. Retrieval was controlled using keywords including Beijing rainstorm, urban flooding, and road inundation. More than 17,558 public Weibo posts were collected, yielding 29,122 traceable single-image records, with additional image samples extracted from Weibo videos. The 29,122 traceable images constituted the initial candidate pool rather than the final experimental dataset. The initial image pool was first subjected to automatic flood/non-flood screening to remove irrelevant images. The remaining candidates were then manually reviewed to exclude residual irrelevant images and duplicate records. After this two-stage screening process, 1283 images were retained and manually annotated for the subsequent image-based experiments. The annotated image dataset was further divided into training, validation, and test subsets, with 193 images retained as the fixed test set for comparison among the image-based methods. After image screening, the accompanying texts paired with the retained image records were further screened for the text-based experiment. Texts unrelated to water-depth descriptions and duplicate text records were removed. Among the remaining records, 239 cleaned text samples containing annotatable depth information were retained and manually assigned text reference depths for the text-extraction experiment. Image reference depth was manually assigned from the relative relationship between visible reference-object parts and the water surface, with primary reference to the correspondence of human body parts and vehicle components under different inundation conditions [
42,
43]. Text reference depth was annotated solely from the accompanying text without using image information. All depth values were recorded in centimetres. Two annotators independently reviewed the samples, and disagreements were resolved through joint review. Because the image reference depths were inferred from visible scene evidence rather than field measurements, they should be interpreted as scene-based reference estimates rather than centimetre-level in situ observations. Image and text reference depths were annotated independently to avoid cross-modal information leakage. Relative-part descriptions from both modalities were converted using the same object-part and depth mapping to maintain a common depth representation.
The training and validation subsets were used for model training and parameter selection of the supervised ResNet-50 [
56] and ViT-B/16 [
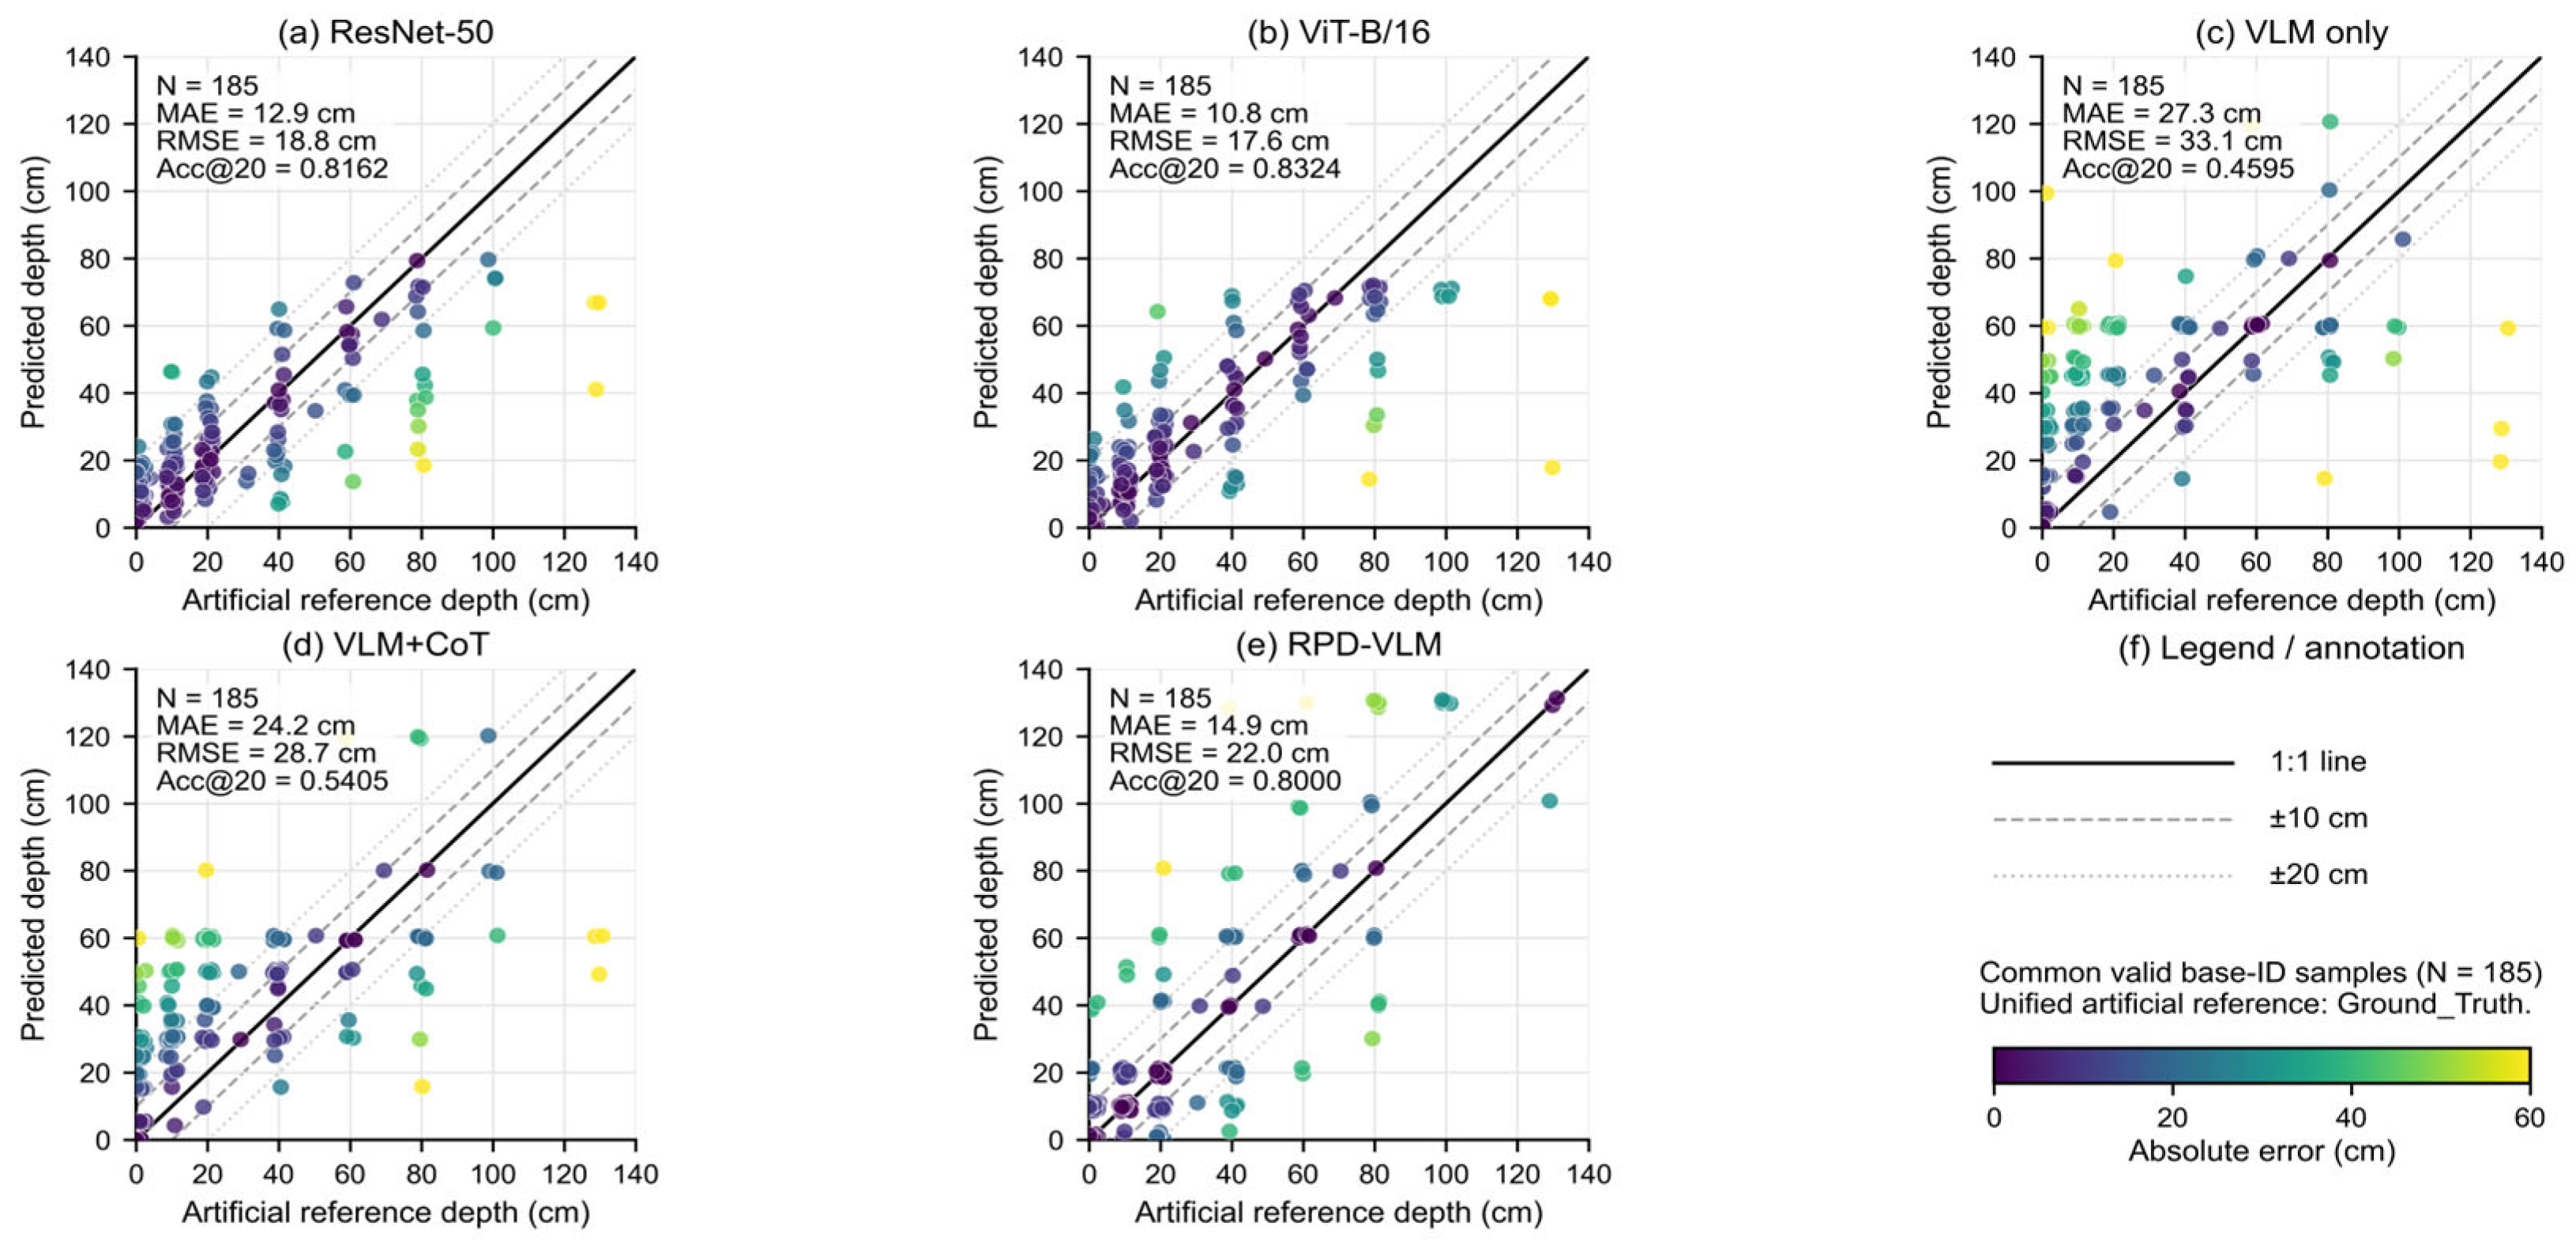
57] models. The fixed test set of 193 images was used to compare the supervised models, direct vision–language model inference, and the proposed vision–language framework for the depth based on reference objects (RPD-VLM).
Table 1 summarises the sample size, inclusion criteria, and corresponding section for each evaluation set.
The image-depth, text-extraction, image–text fusion, and ablation experiments used different task-specific evaluation sets. In particular, the 193-image test set was used to compare image-based methods, whereas the 202-sample fusion set consisted of paired image–text records for which an image-based prediction, a text-based prediction, and an image reference depth were all available. Therefore, these sample sets represent different experimental tasks rather than successive stages of a single filtering process.
Table 1 summarises the sample size, inclusion criteria, and corresponding role of each experimental set.
The depth-estimation experiments were conducted at level of individual records, and precise sample-level georeferencing was not used as an input or evaluation criterion in the current experiments. The geographic scope was controlled by event- and location-related retrieval terms, whereas the positional accuracy of individual social media records was not independently evaluated.
3.2. Overall Framework
As shown in
Figure 1, the overall study workflow comprises five stages: (1) crowdsourced multimodal dataset construction; (2) image-based depth-evidence construction using RPD-VLM; (3) textual depth-evidence extraction and quantifiability assessment using RPD-VLM-T; (4) image-led conditional fusion using RPD-VLM-Fusion; and (5) experimental evaluation and comparison. After dataset construction, the image and text pathways operate in parallel to produce image-based depth evidence
and textual depth evidence (
), respectively. These outputs are combined only at the subsequent conditional-fusion stage. The experimental evaluation separately examines textual extraction, fusion strategies, and image-based depth estimation, including supervised and direct-VLM baselines. Precise geographic coordinates are not estimated in the current framework; location cues, when available from platform metadata or textual place names, require independent geocoding and positional validation before downstream spatial analysis.
The image module is the primary source of depth information. It uses a vision–language model (VLM) to identify the principal flooded area, candidate reference objects, and their spatial relationships with the water surface, and then generates image-based depth through reference-object knowledge mapping. The text module provides candidate auxiliary evidence. It first applies rules to parse explicit values, ranges, and common relative part descriptions, and then performs semantic review for complex text involving negation, multiple numbers, temporal change, spatial reporting, or colloquial expressions. Its outputs include text-based depth, text quantifiability, expression type, and evidence span. The fusion module calculates the image–text discrepancy on a common depth scale and determines whether text participates in the final estimate according to its quantifiability and a continuously decaying weight.
3.3. Construction of Image-Based Depth Evidence Through Reference-Object Knowledge Mapping
This image-based procedure constitutes the RPD-VLM framework introduced in
Section 3.1. The image module converts crowdsourced flood images into structured evidence containing a reference object, submerged part, and water-depth value. The model first identifies the principal flooded area and candidate reference objects and then assesses the relative relationship between key object parts and the water surface. A reference-object knowledge base subsequently maps the object type and submerged part to a discrete depth class and its representative depth.
Image interpretation follows a two-stage procedure. The first stage locates the principal flooded area and identifies candidate reference objects. The second stage assesses the object–water relationship and submerged part within the candidate set. Qwen3-VL-8B-Instruct [
58] is used to identify candidate reference objects and interpret object–water relationships, but does not directly generate the final depth value. A retrieval-augmented knowledge context is introduced between the two stages of image interpretation. After the first-stage detection, the identified reference-object types are normalised to predefined categories. The detected object categories are then used as retrieval keys to query a structured reference-object knowledge base. Only knowledge entries associated with the detected object types are retrieved, including candidate object parts, corresponding depth classes, and representative depth values. The retrieved entries are inserted into the second-stage prompt as contextual constraints for interpreting the object–water relationship and selecting the corresponding submerged-part key. The retrieved context does not directly provide the final depth estimate. Instead, after the VLM identifies the reference-object type and submerged part, the final image-based depth is assigned through the explicit object-part depth mapping described below. If no valid pair of reference objects can be established, no deterministic image-based depth is returned.
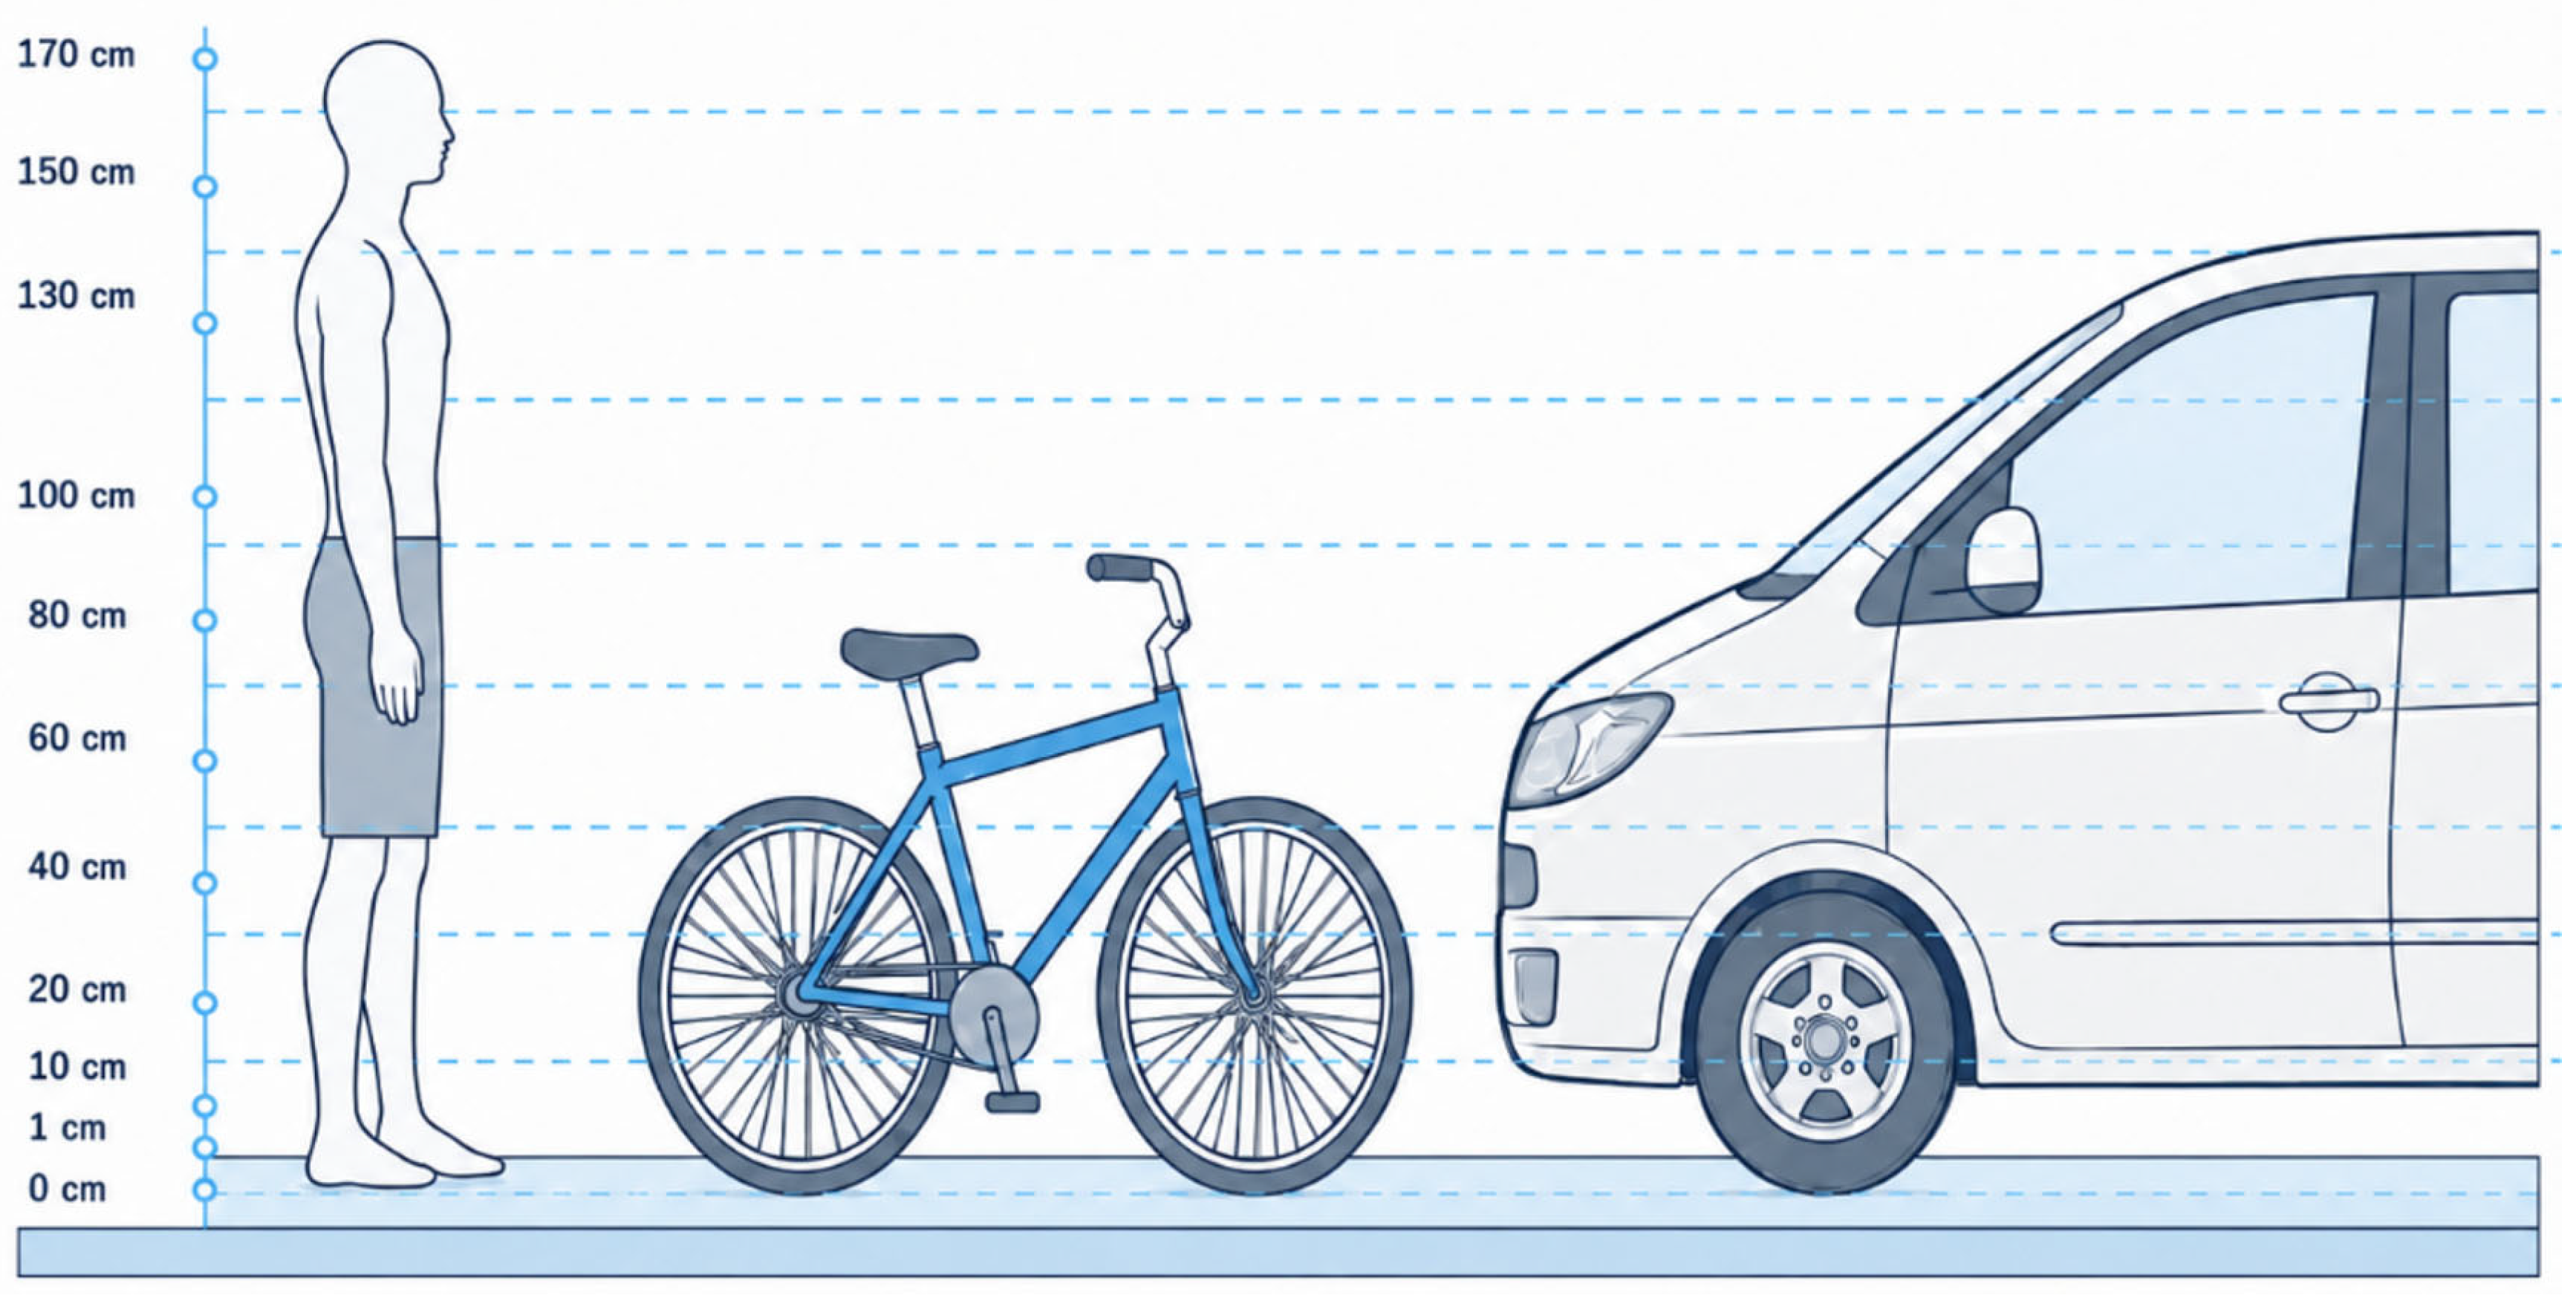
For depth quantification, this study follows the multi-reference-object classification scheme described in [
51], mapping key parts of common urban objects, including people, non-motorised vehicles, and motor vehicles, to a common set of depth classes. The knowledge base is grounded in typical elevations of key human body parts and incorporates corresponding component-height relationships for bicycles, motorcycles, cars, and buses. It defines mapping from reference-object type and submerged part to depth class and representative depth, as illustrated in
Figure 2.
Let the type and submerged part of candidate reference object i be denoted by
and
, respectively. Its depth class is:
The corresponding representative depth is:
where
maps the reference-object type and part to a depth class,
maps the depth class to a representative depth, and
is measured in centimetres.
When multiple valid reference objects occur in the same image, only candidates located within the principal flooded area, with a clear object–water relationship and visible key parts, are retained. Let
denote the set of valid candidates in the principal flooded area. The candidate with the largest mapped depth is selected:
The image-based depth is defined as:
This selection rule reduces the influence of shallow margins, local puddles, and areas outside the principal inundated zone. Before mapping, reference-object types and submerged parts are standardised to the categories defined in the knowledge base.
To examine how uncertainty associated with reference-object dimensions and the object-part depth mapping may propagate to the final numerical estimate, a scenario-based proportional sensitivity analysis was conducted. The perturbation magnitude of ±10% was selected following the sensitivity setting adopted in the previous reference-object-based flood-depth study [
51]. This provides a moderate and symmetric scenario for evaluating the response of the estimates while maintaining methodological comparability with the previous study.
The ±10% perturbation was applied to both the representative depth levels and the final RPD-VLM estimates according to the following equation:
where
D denotes the depth value being perturbed. For the depth-level bound analysis,
D represents a representative depth level defined in
Figure 2. For the performance-propagation analysis,
D represents the final RPD-VLM image-depth estimate for each sample. Reference-object recognition, submerged-part interpretation, manually assigned reference depths, and sample composition were kept unchanged. MAE, RMSE, MedAE, Acc@10, and Acc@20 were recalculated on the same common valid subset of 185 samples used for the main image-based comparison. Consequently, the 0% condition reproduces the baseline results reported in
Section 4.3.1. The ±10% setting represents a controlled sensitivity scenario rather than an empirically estimated confidence interval for actual human or vehicle dimensions.
3.4. Extraction and Quantifiability Assessment of Depth Evidence from Social Media Text
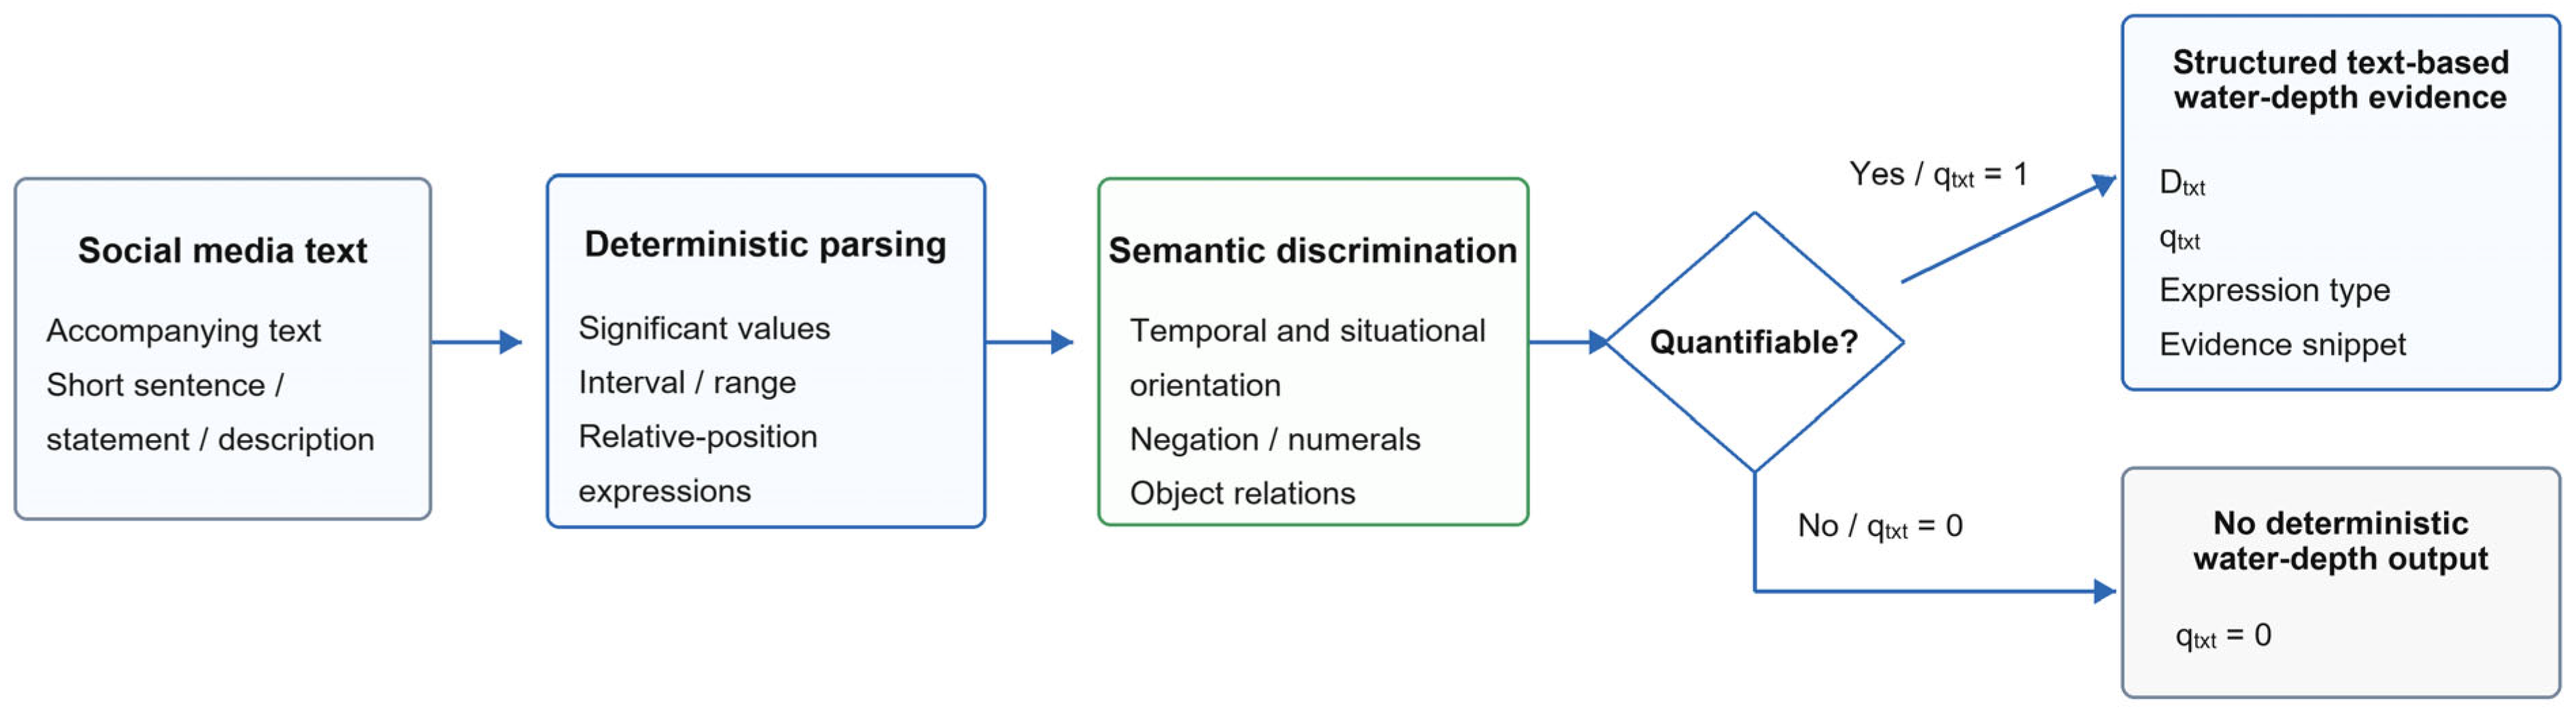
The text module identifies quantifiable water-depth cues in the accompanying social media text and determines whether they can form an explicit text-based depth result, as shown in
Figure 3. The output fields include text-based depth
, text quantifiability
, expression type, and evidence span.
Text-based depth evidence includes explicit values, interval expressions, and relative part descriptions. For explicit values, the rule layer identifies the numerical value and unit and converts them to centimetres:
where
is the numerical value in the text,
is the unit, and
is the unit-normalisation function.
For interval expressions with explicit lower and upper bounds, the midpoint is used:
where a and b are the lower and upper bounds, respectively. Vague degree expressions without identifiable bounds are not forced into deterministic depth values.
For relative part descriptions, such as water reaching the ankle or covering half of a tyre, the reference-object type
and part relationship
are first identified and then converted to a representative depth using the same knowledge mapping as the image module. This shared mapping places relative-part evidence from the two modalities on the same depth scale before image–text discrepancy calculation:
These results only form candidate text-based depths and do not indicate that the text is aligned with the time, location, or inundated area shown in the image.
Text containing multiple numbers, negation, temporal change, spatial reporting, range comparisons, or descriptions of a non-current scene is marked as complex and triggers semantic review. The semantic interpretation module uses the original text together with the rule-based candidate to determine whether the text refers to an explicit inundation state and whether the candidate should be retained, revised, or rejected.
The final text-based depth is defined as:
where
is the rule-based result,
is the semantic-review result, and
indicates that the text module does not output a deterministic depth. This process yields
and its quantifiability state
. A value of
= 1 indicates only that the text can be quantified; it does not establish consistency with the image scene. Text participation in the final estimate is determined subsequently by the directional constraint and image–text discrepancy control.
3.5. Image-Led Depth-Evidence Fusion Accounting for Textual Uncertainty
The fusion stage retains image-based depth as the primary estimate and treats text-based depth as candidate auxiliary evidence. The manually assigned reference depth is used only for experimental evaluation and does not enter the calculation of text participation or weight.
The discrepancy between image-based and text-based depth is defined as:
Text participation first requires = 1. Subject to this condition, text is allowed to provide a downward correction only when < ; otherwise, the image-based estimate is retained. This asymmetric rule is a conservative fusion constraint rather than a physical assumption that textual reports systematically underestimate water depth. Social media text may either under- or overstate the local inundation state because of temporal or spatial mismatch and subjective reporting. The constraint therefore prevents text from increasing the image-based estimate when cross-modal correspondence cannot be established.
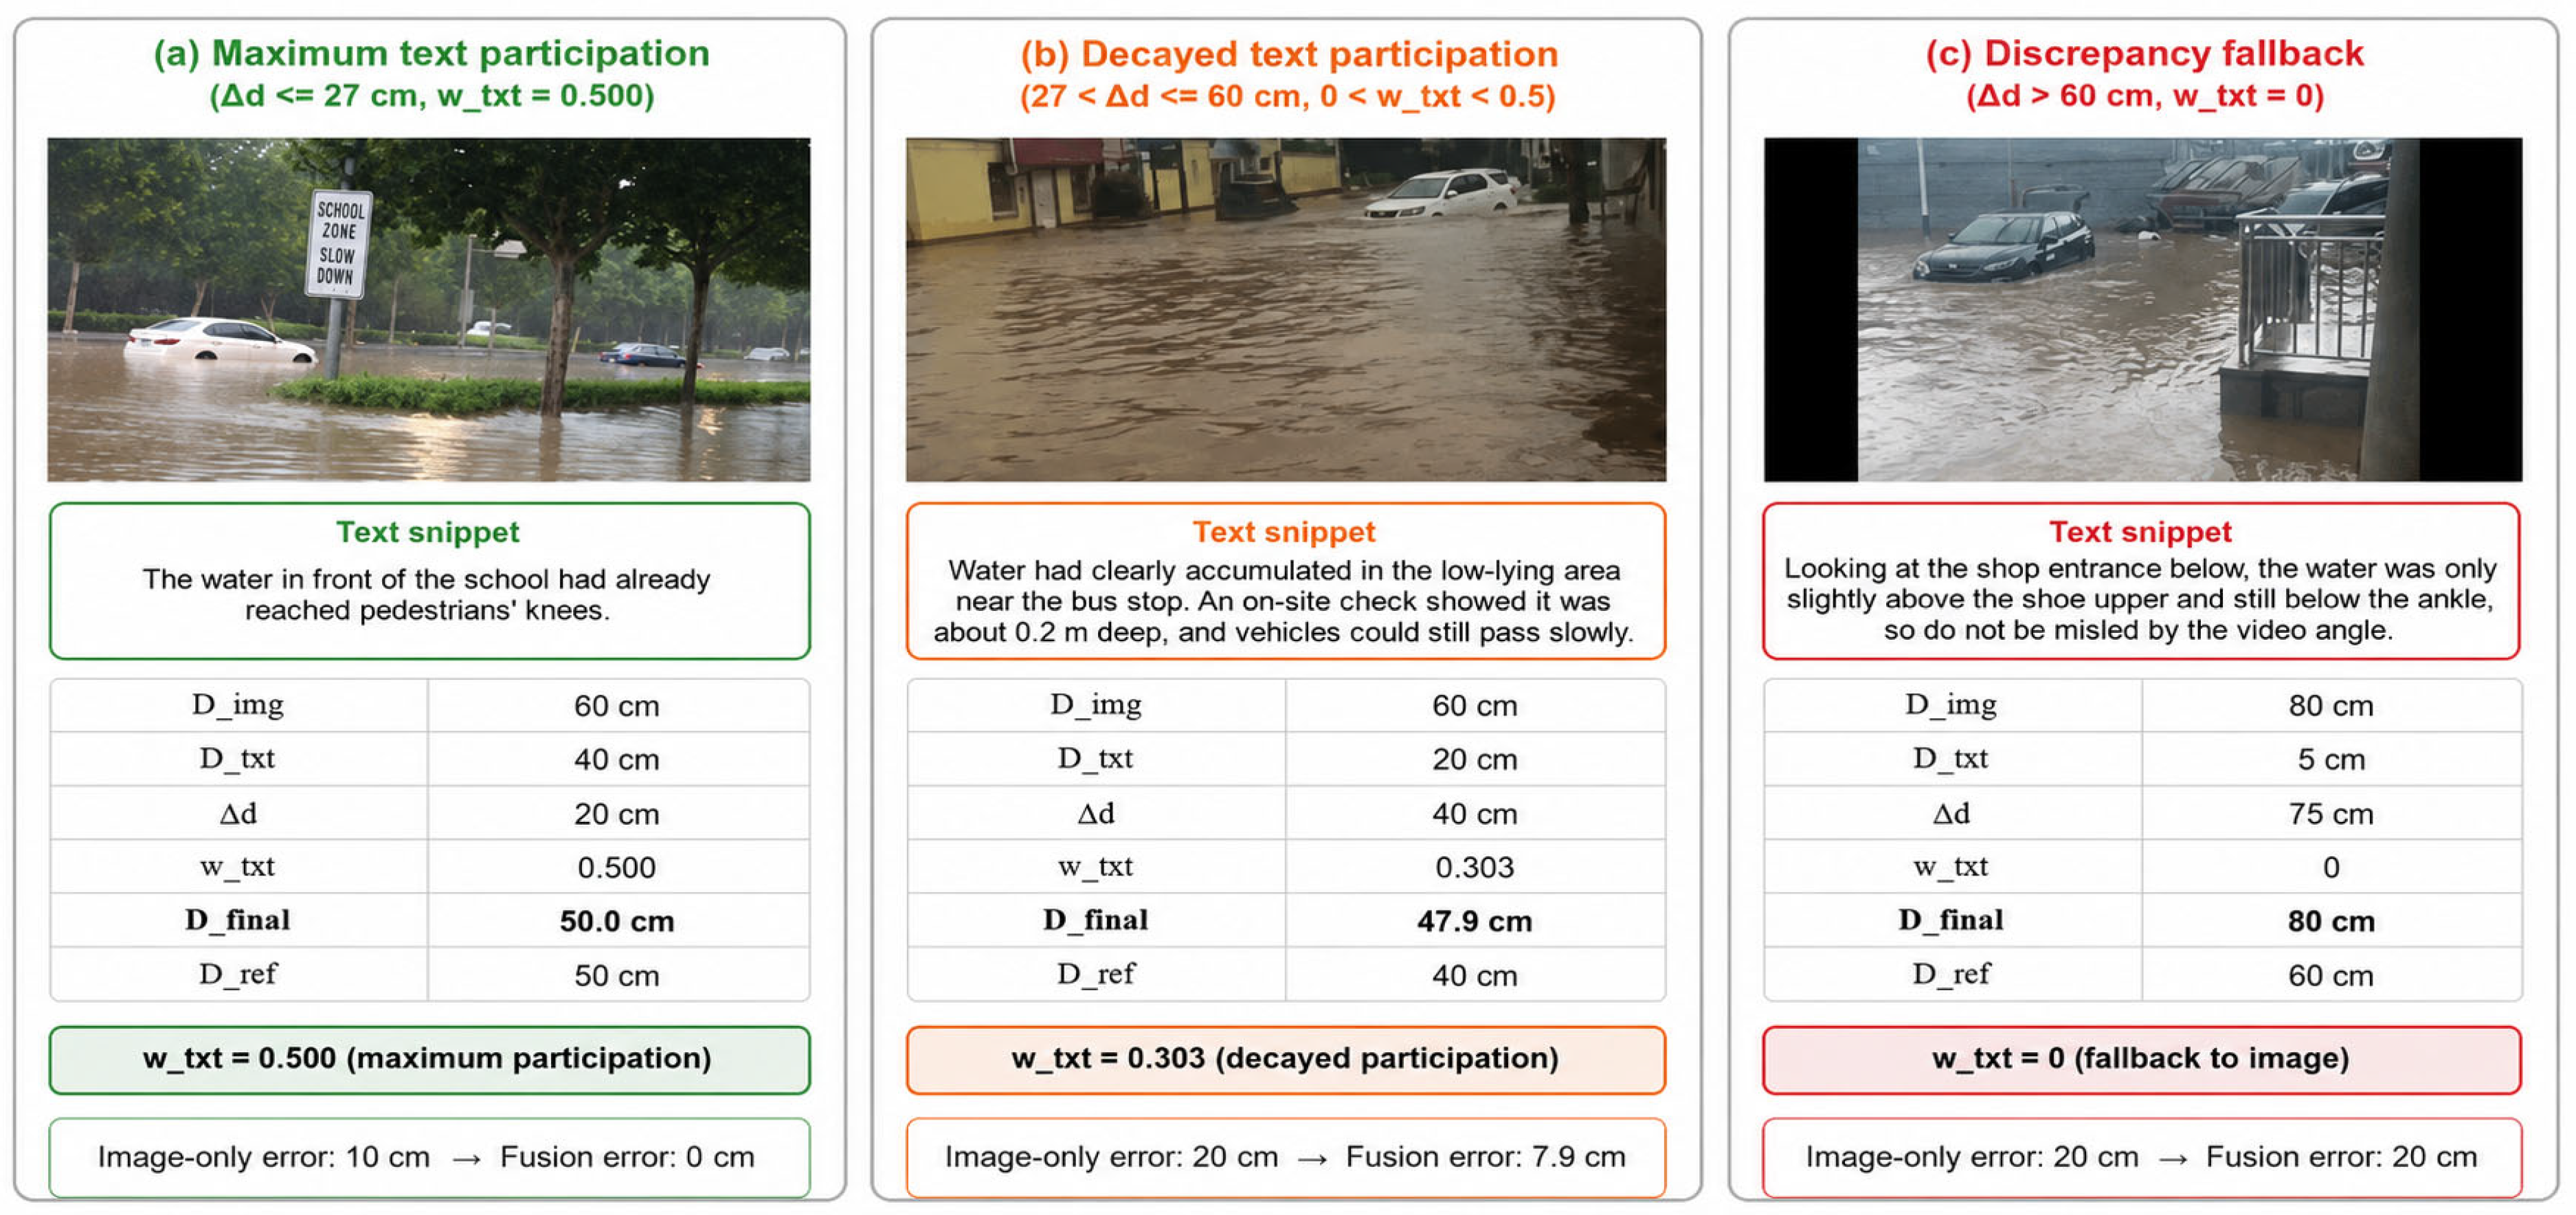
When the quantifiability and directional conditions are satisfied, the text weight decays continuously with the image–text discrepancy. With a maximum text weight of 0.5, the weight is defined as:
The final depth estimate is:
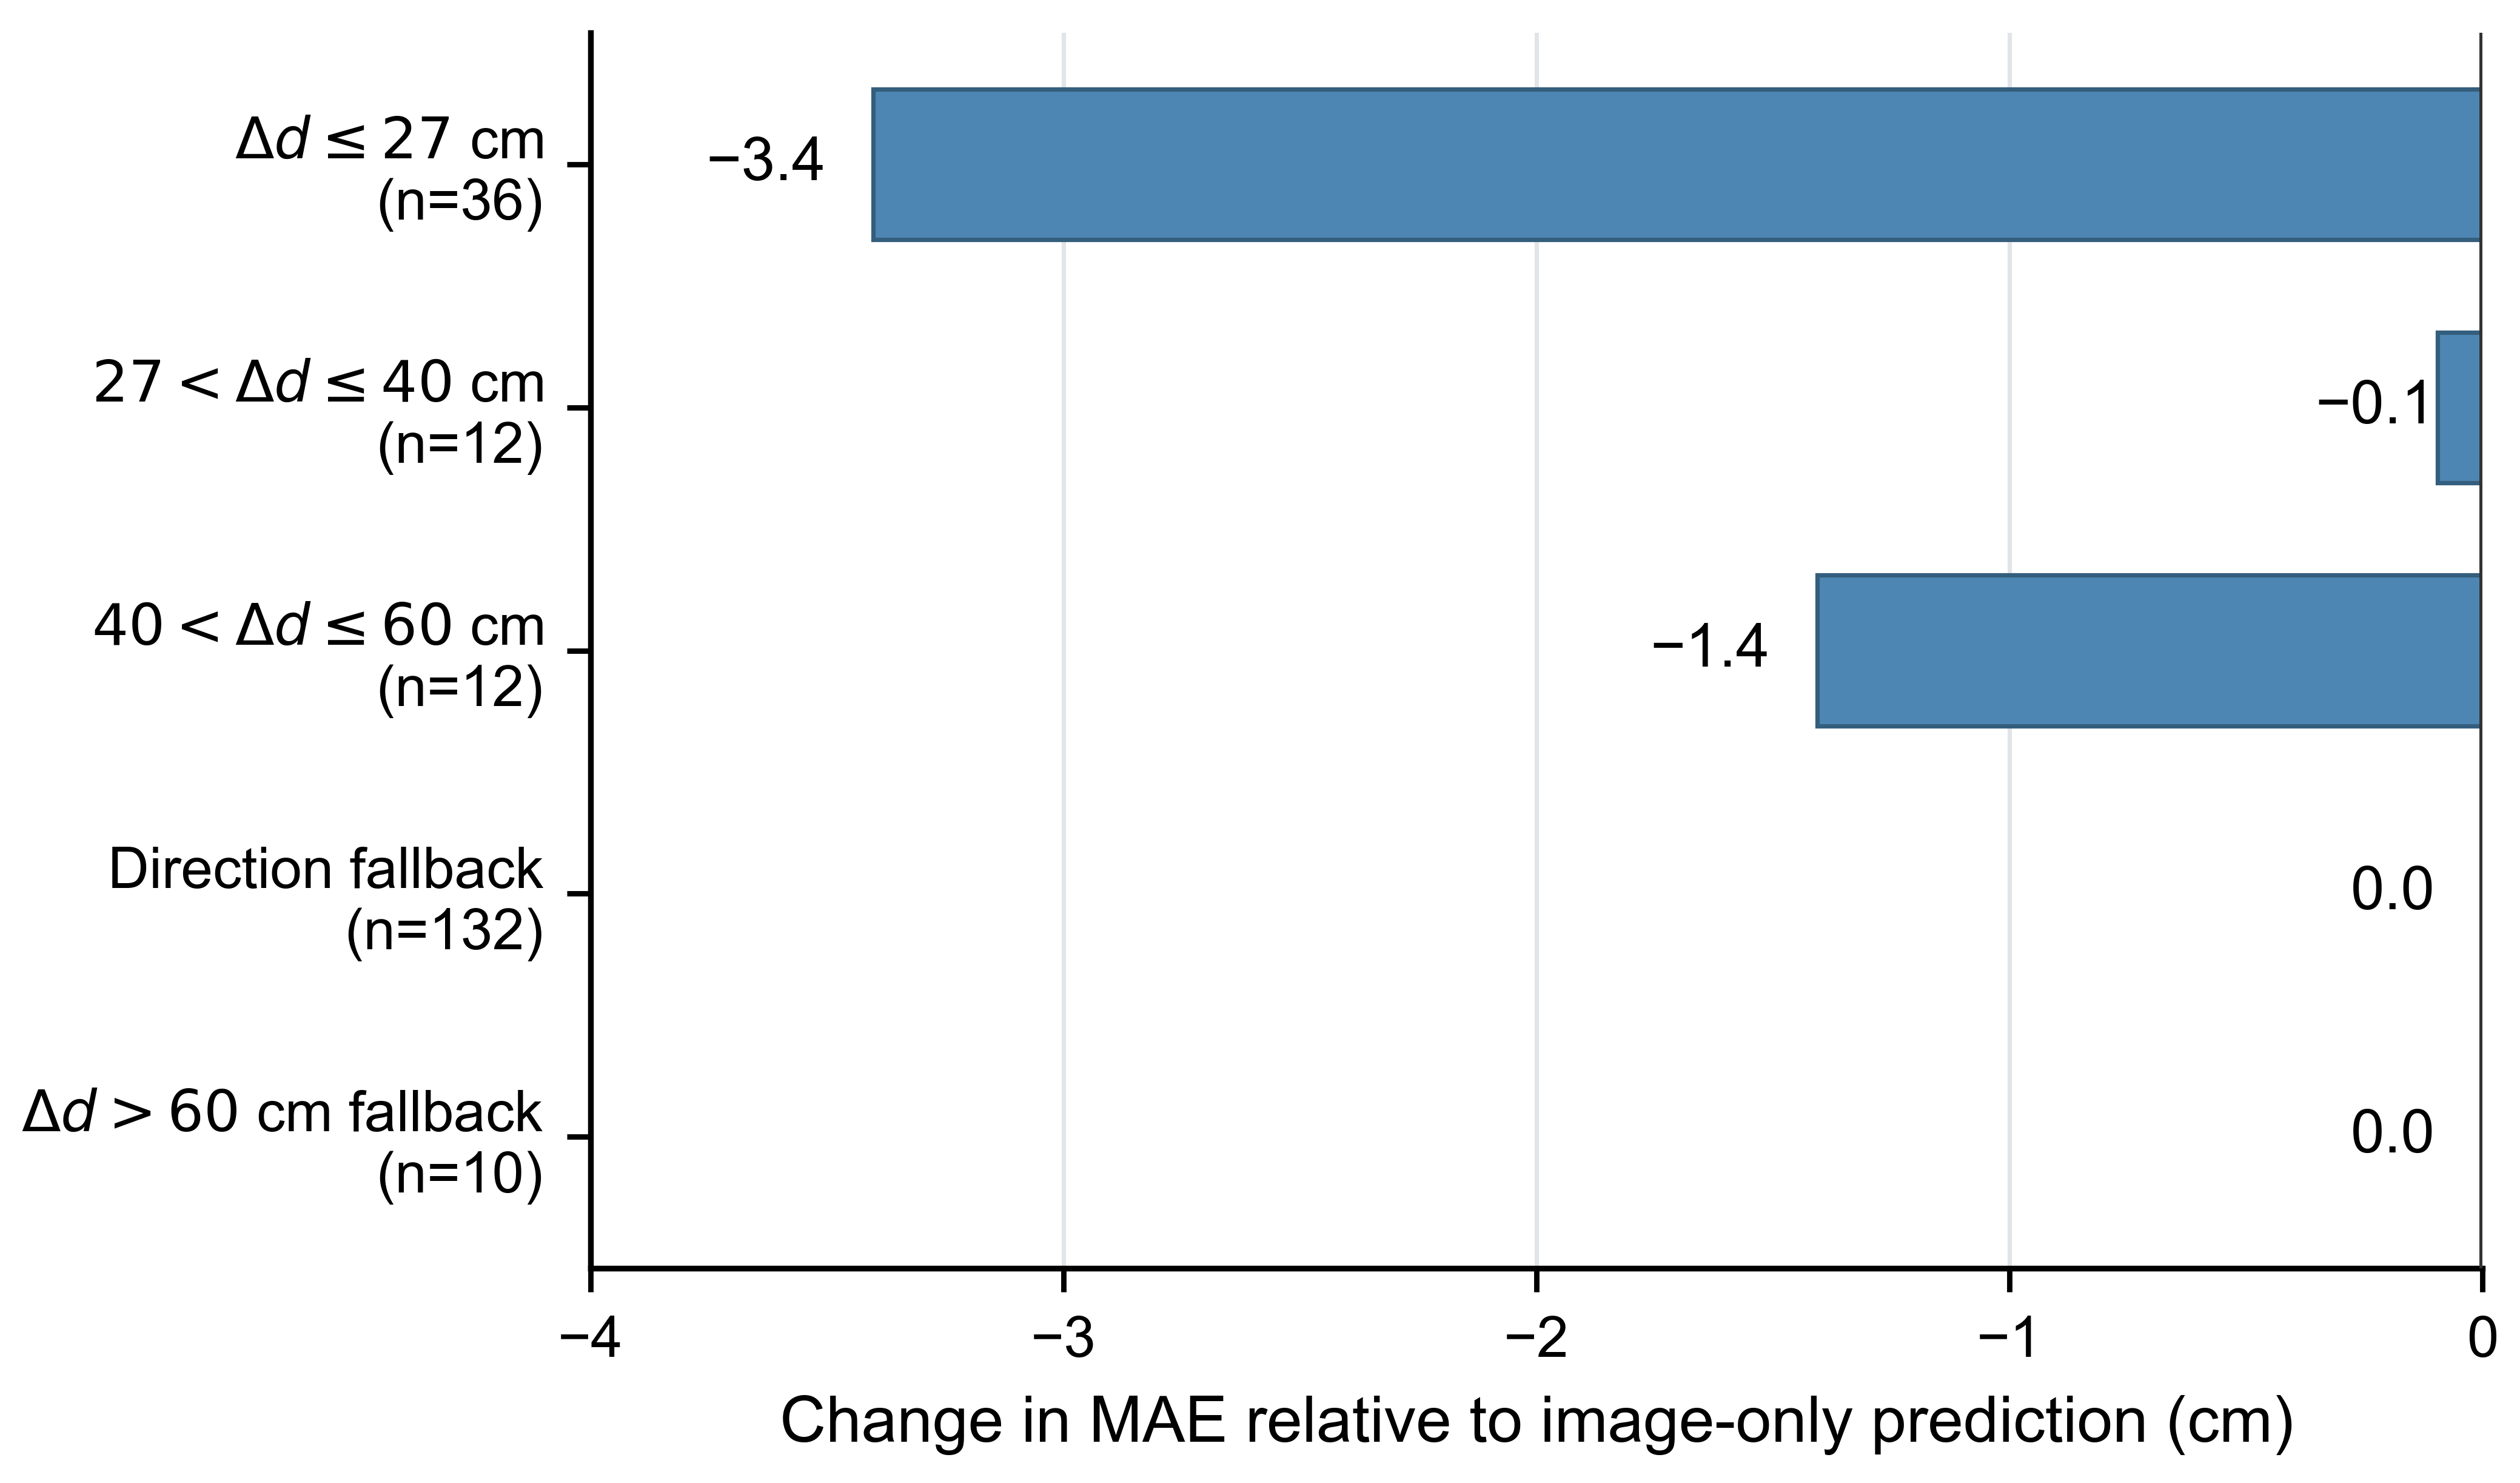
When the text is not quantifiable, the directional constraint is not satisfied, or the image–text discrepancy exceeds 60 cm, = 0 and the final result equals . When the discrepancy does not exceed 27 cm, text participates with the maximum weight. Between 27 and 60 cm, the text weight decreases linearly as the discrepancy increases.
3.6. Experimental Design and Evaluation Metrics
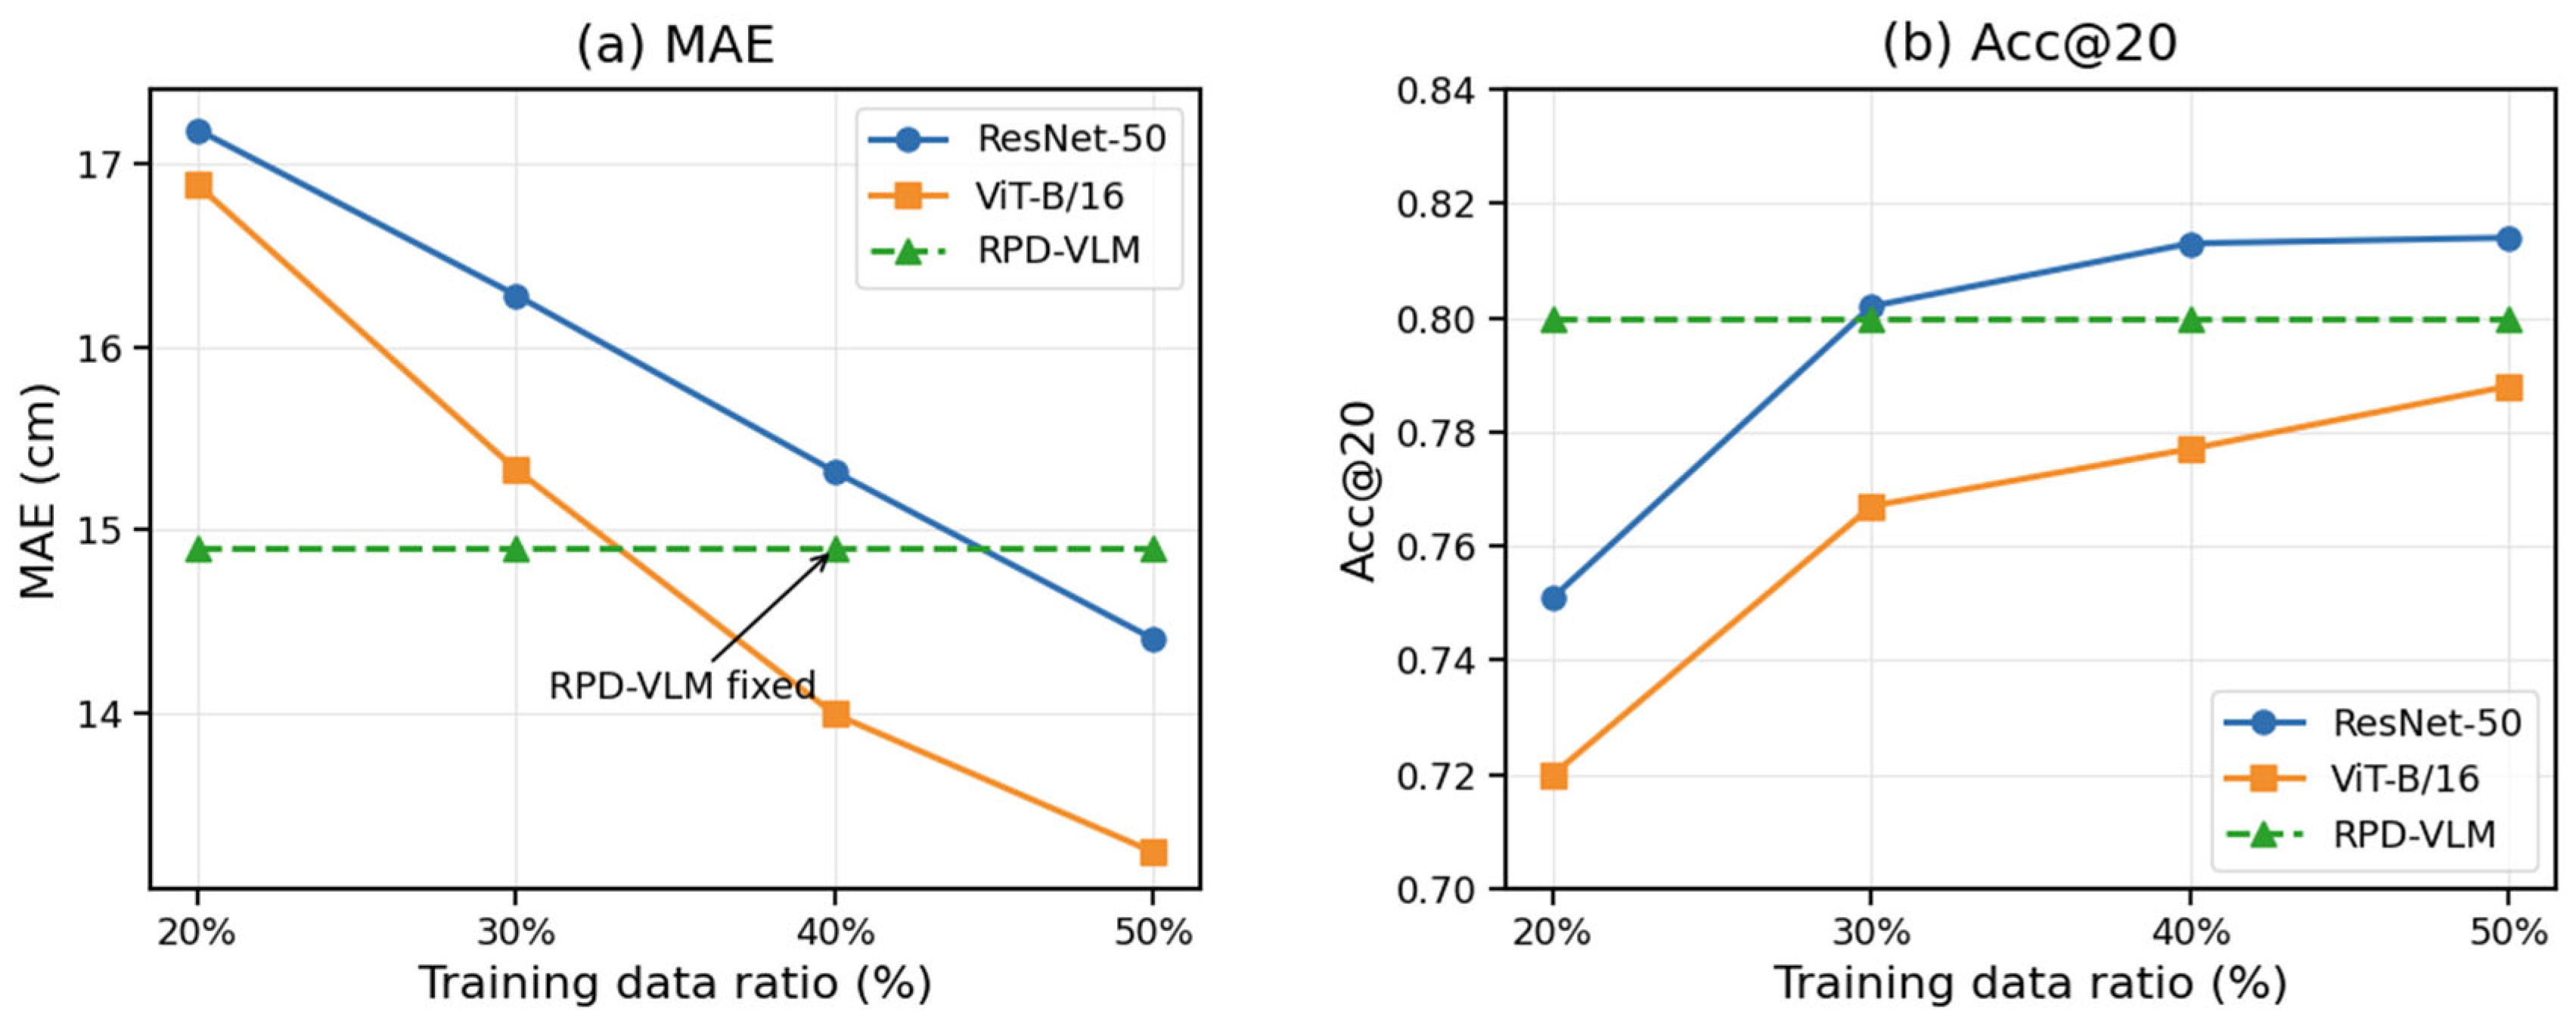
The experiments comprise three main tasks: textual depth-evidence extraction, image–text fusion, and image-based depth estimation. Textual depth extraction is first evaluated, followed by analysis of the conditions under which textual evidence participates in image–text fusion. The image-based depth method is then compared with supervised and direct-VLM baselines on the unified image test set. Additional analyses examine performance under different training-data proportions, depth ranges, and scene types, together with ablation experiments and representative cases. The framework does not assume a general preference for methods without task-specific supervised training. Supervised models are included as performance baselines, whereas RPD-VLM is investigated as a VLM-based inference pathway that does not require task-specific end-to-end depth-regression training.
The sample sets and corresponding inclusion criteria are summarised in
Table 1. Because the text-extraction, image–text fusion, image-based depth estimation, and ablation experiments use different task-specific sample sets, methods are compared only within the same evaluation set. Text-extraction methods are evaluated against the text reference depth, whereas image-based depth estimation and image–text fusion are evaluated against the image reference depth. The fusion experiment uses samples for which an image-based prediction, a text-based prediction, and an image reference depth are all available. The image-depth comparison uses the unified image test set, with error metrics calculated on the common valid subset when direct comparison among methods is required. Coverage and extraction counts are calculated over the corresponding task-specific sample pool.
For continuous depth estimation, mean absolute error (MAE), root mean square error (RMSE), and median absolute error (MedAE) are used to quantify the difference between predicted and reference depths. Acc@10 and Acc@20 denote the proportions of samples with absolute errors no greater than 10 cm and 20 cm, respectively, whereas Out@30 and Out@50 denote the proportions with absolute errors greater than 30 cm and 50 cm. The text-extraction experiment additionally reports the number of successful extractions and extraction coverage. For paired comparisons between RPD-VLM and the baseline methods, statistical uncertainty was assessed using paired bootstrap resampling on the common valid subset. For each comparison, the 185 paired samples were resampled with replacement 10,000 times while preserving the correspondence between the predictions of the two methods and the same reference depth. Differences in MAE, RMSE, and Acc@20 were calculated for each resample. The 2.5th and 97.5th percentiles of the bootstrap distribution were used to form the 95% confidence interval (CI). A difference was considered statistically stable when the corresponding 95% CI did not include zero.
5. Discussion
5.1. Conditions of Applicability
The method is not intended for all images of urban surface water. It targets crowdsourced flood image–text records containing interpretable reference objects and clear relations between those objects and the water surface. RPD-VLM converts an unstructured image into image-based depth evidence containing the reference-object type, submerged part, and knowledge-mapping relation, thereby retaining an intermediate interpretation path. It is not positioned as a replacement for a fully supervised depth-regression model. Instead, it provides a structured process for constructing candidate depth evidence without relying on end-to-end depth-regression training on the current task, particularly when disaster records need to be organised or the basis of an estimate needs to be reviewed.
With respect to image conditions, the method is more applicable to roads, streets, and parking-area entrances containing common reference objects such as pedestrians, vehicles, kerbs, or barriers. Spatial relations between these objects and the water surface are generally more interpretable. In blurred images, images captured from a high angle, scenes with unclear flood boundaries, occluded reference objects, or invisible key parts, the available image cues are insufficient and the output should be treated as a candidate estimate requiring further verification.
The text module has stricter conditions of applicability. Social media text may describe a historical water level, a nearby location, overall event severity, or a subjective impression and therefore cannot be equated directly with the local depth shown in the current image. Text participates in candidate correction only when it is quantifiable, satisfies the image-led directional condition, and remains within the controlled image–text difference range.
The method can support rapid screening of crowdsourced flood information, organisation of candidate depths before manual review, and mapping analyses that require an explicit evidence path. Samples involving deep water, severe occlusion, no stable reference object, or temporal or spatial inconsistency between image and text still require verification using field inspection, surveillance video, water gauges, or sensor observations.
The comparative results are consistent with previous studies showing that supervised image-based models can achieve strong flood-depth estimation performance when task-specific annotations are available [
34,
35,
36], whereas direct numerical generation from large multimodal models remains sensitive to prompting and output constraints [
50]. In the present experiments, ViT-B/16 achieved lower error than RPD-VLM, while the structured reference-object pathway yielded lower errors than direct VLM depth generation on the current common valid subset. This positions RPD-VLM as a structured alternative to direct VLM inference rather than as a replacement for supervised regression.
5.2. Error Sources and Uncertainty
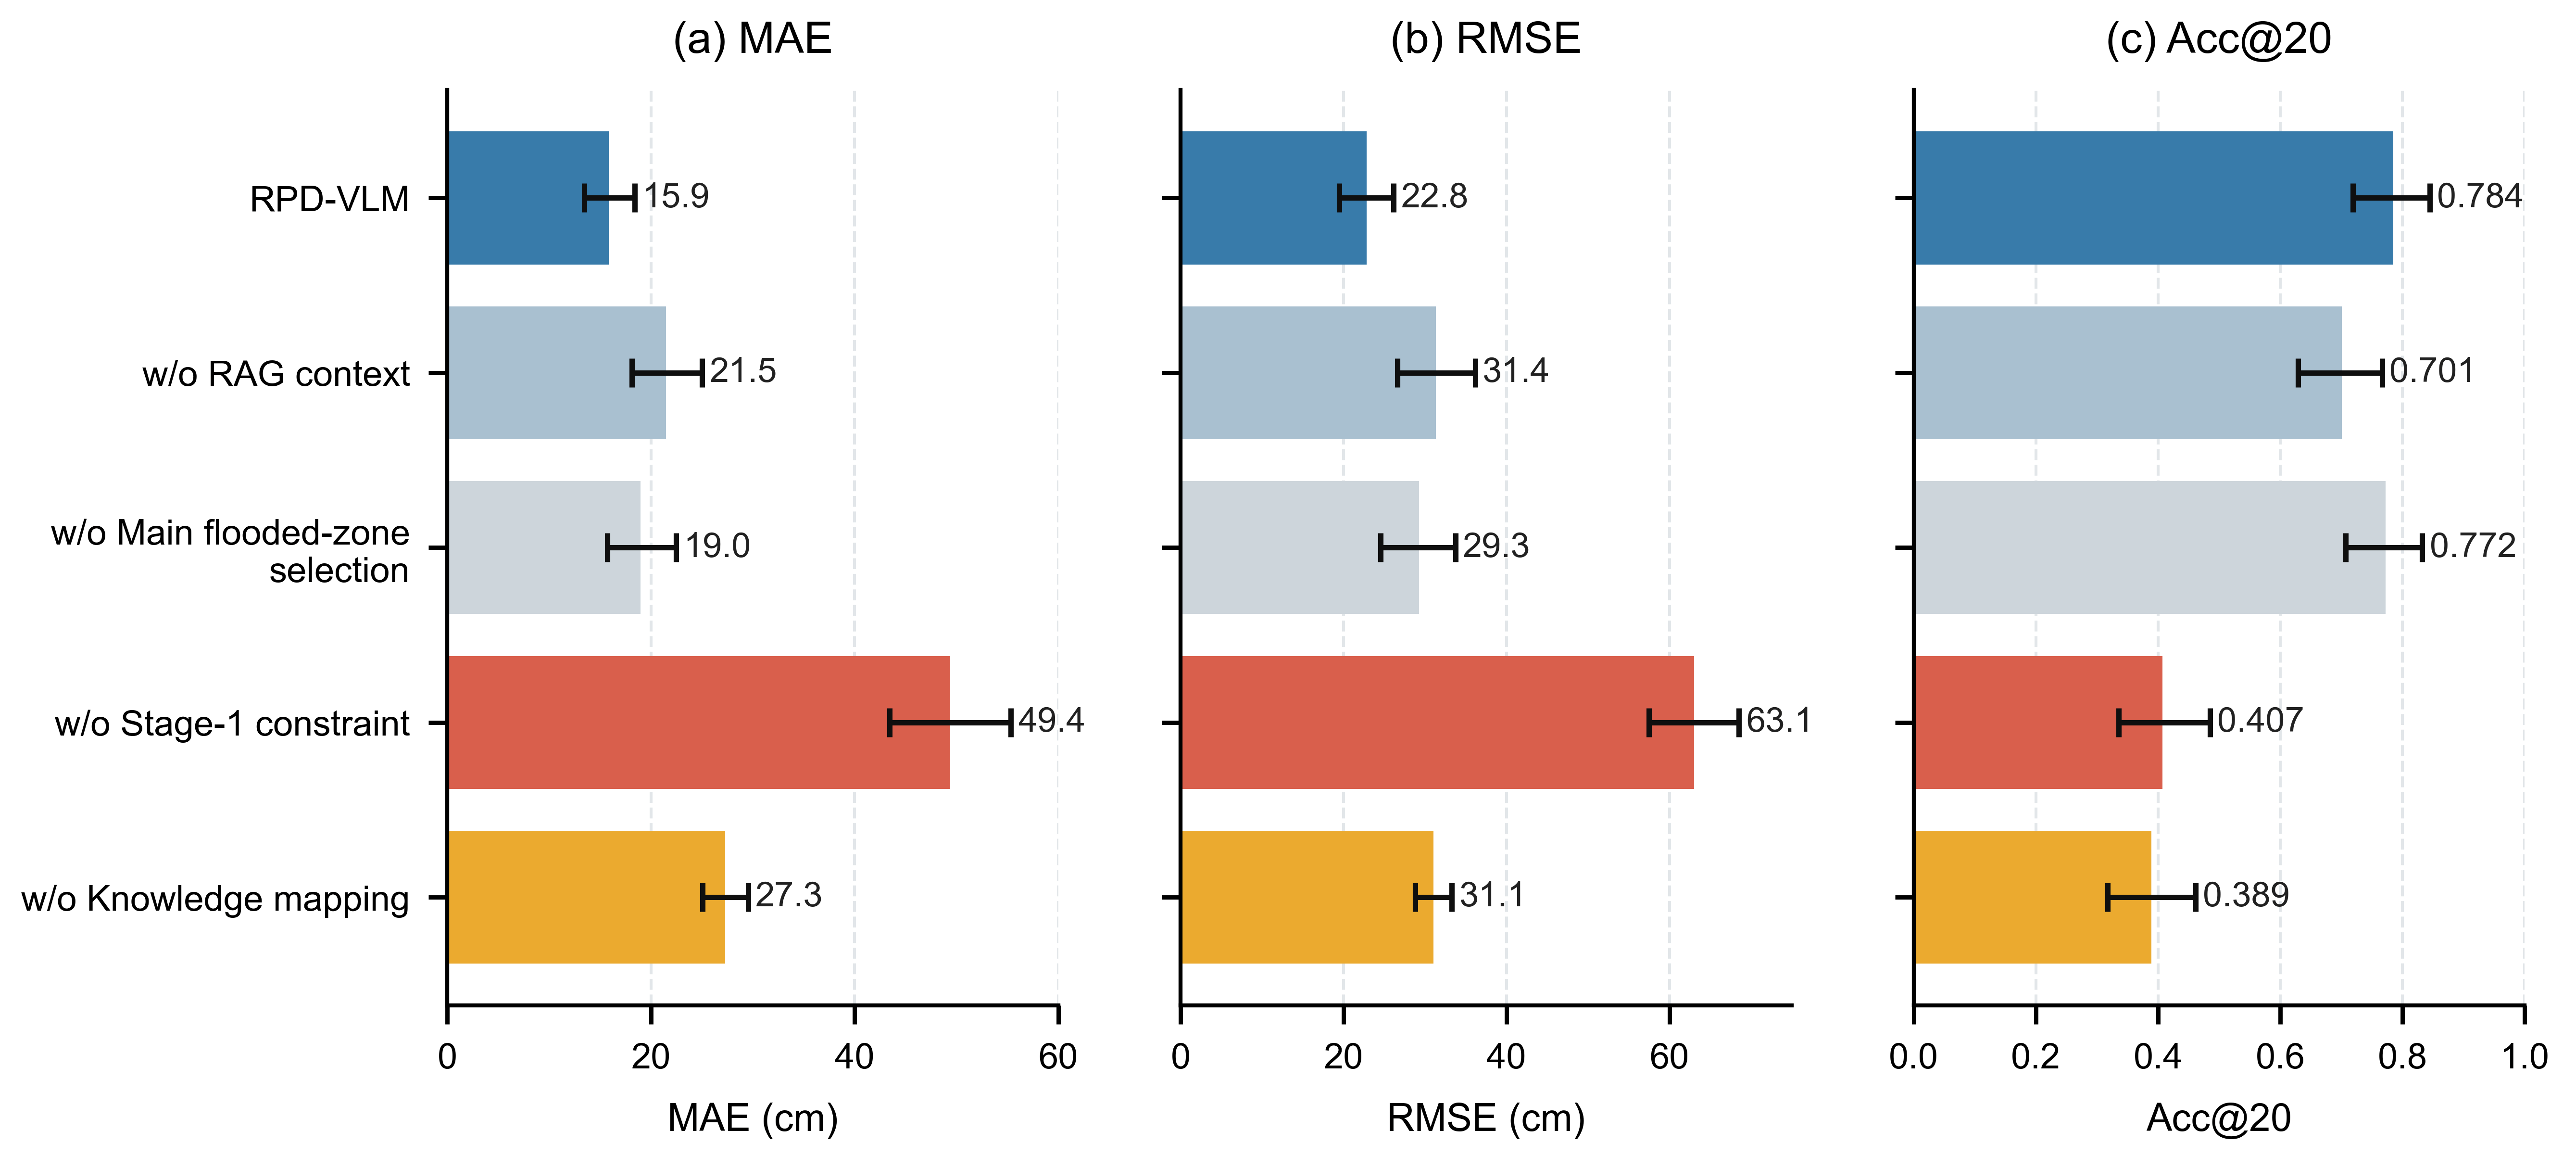
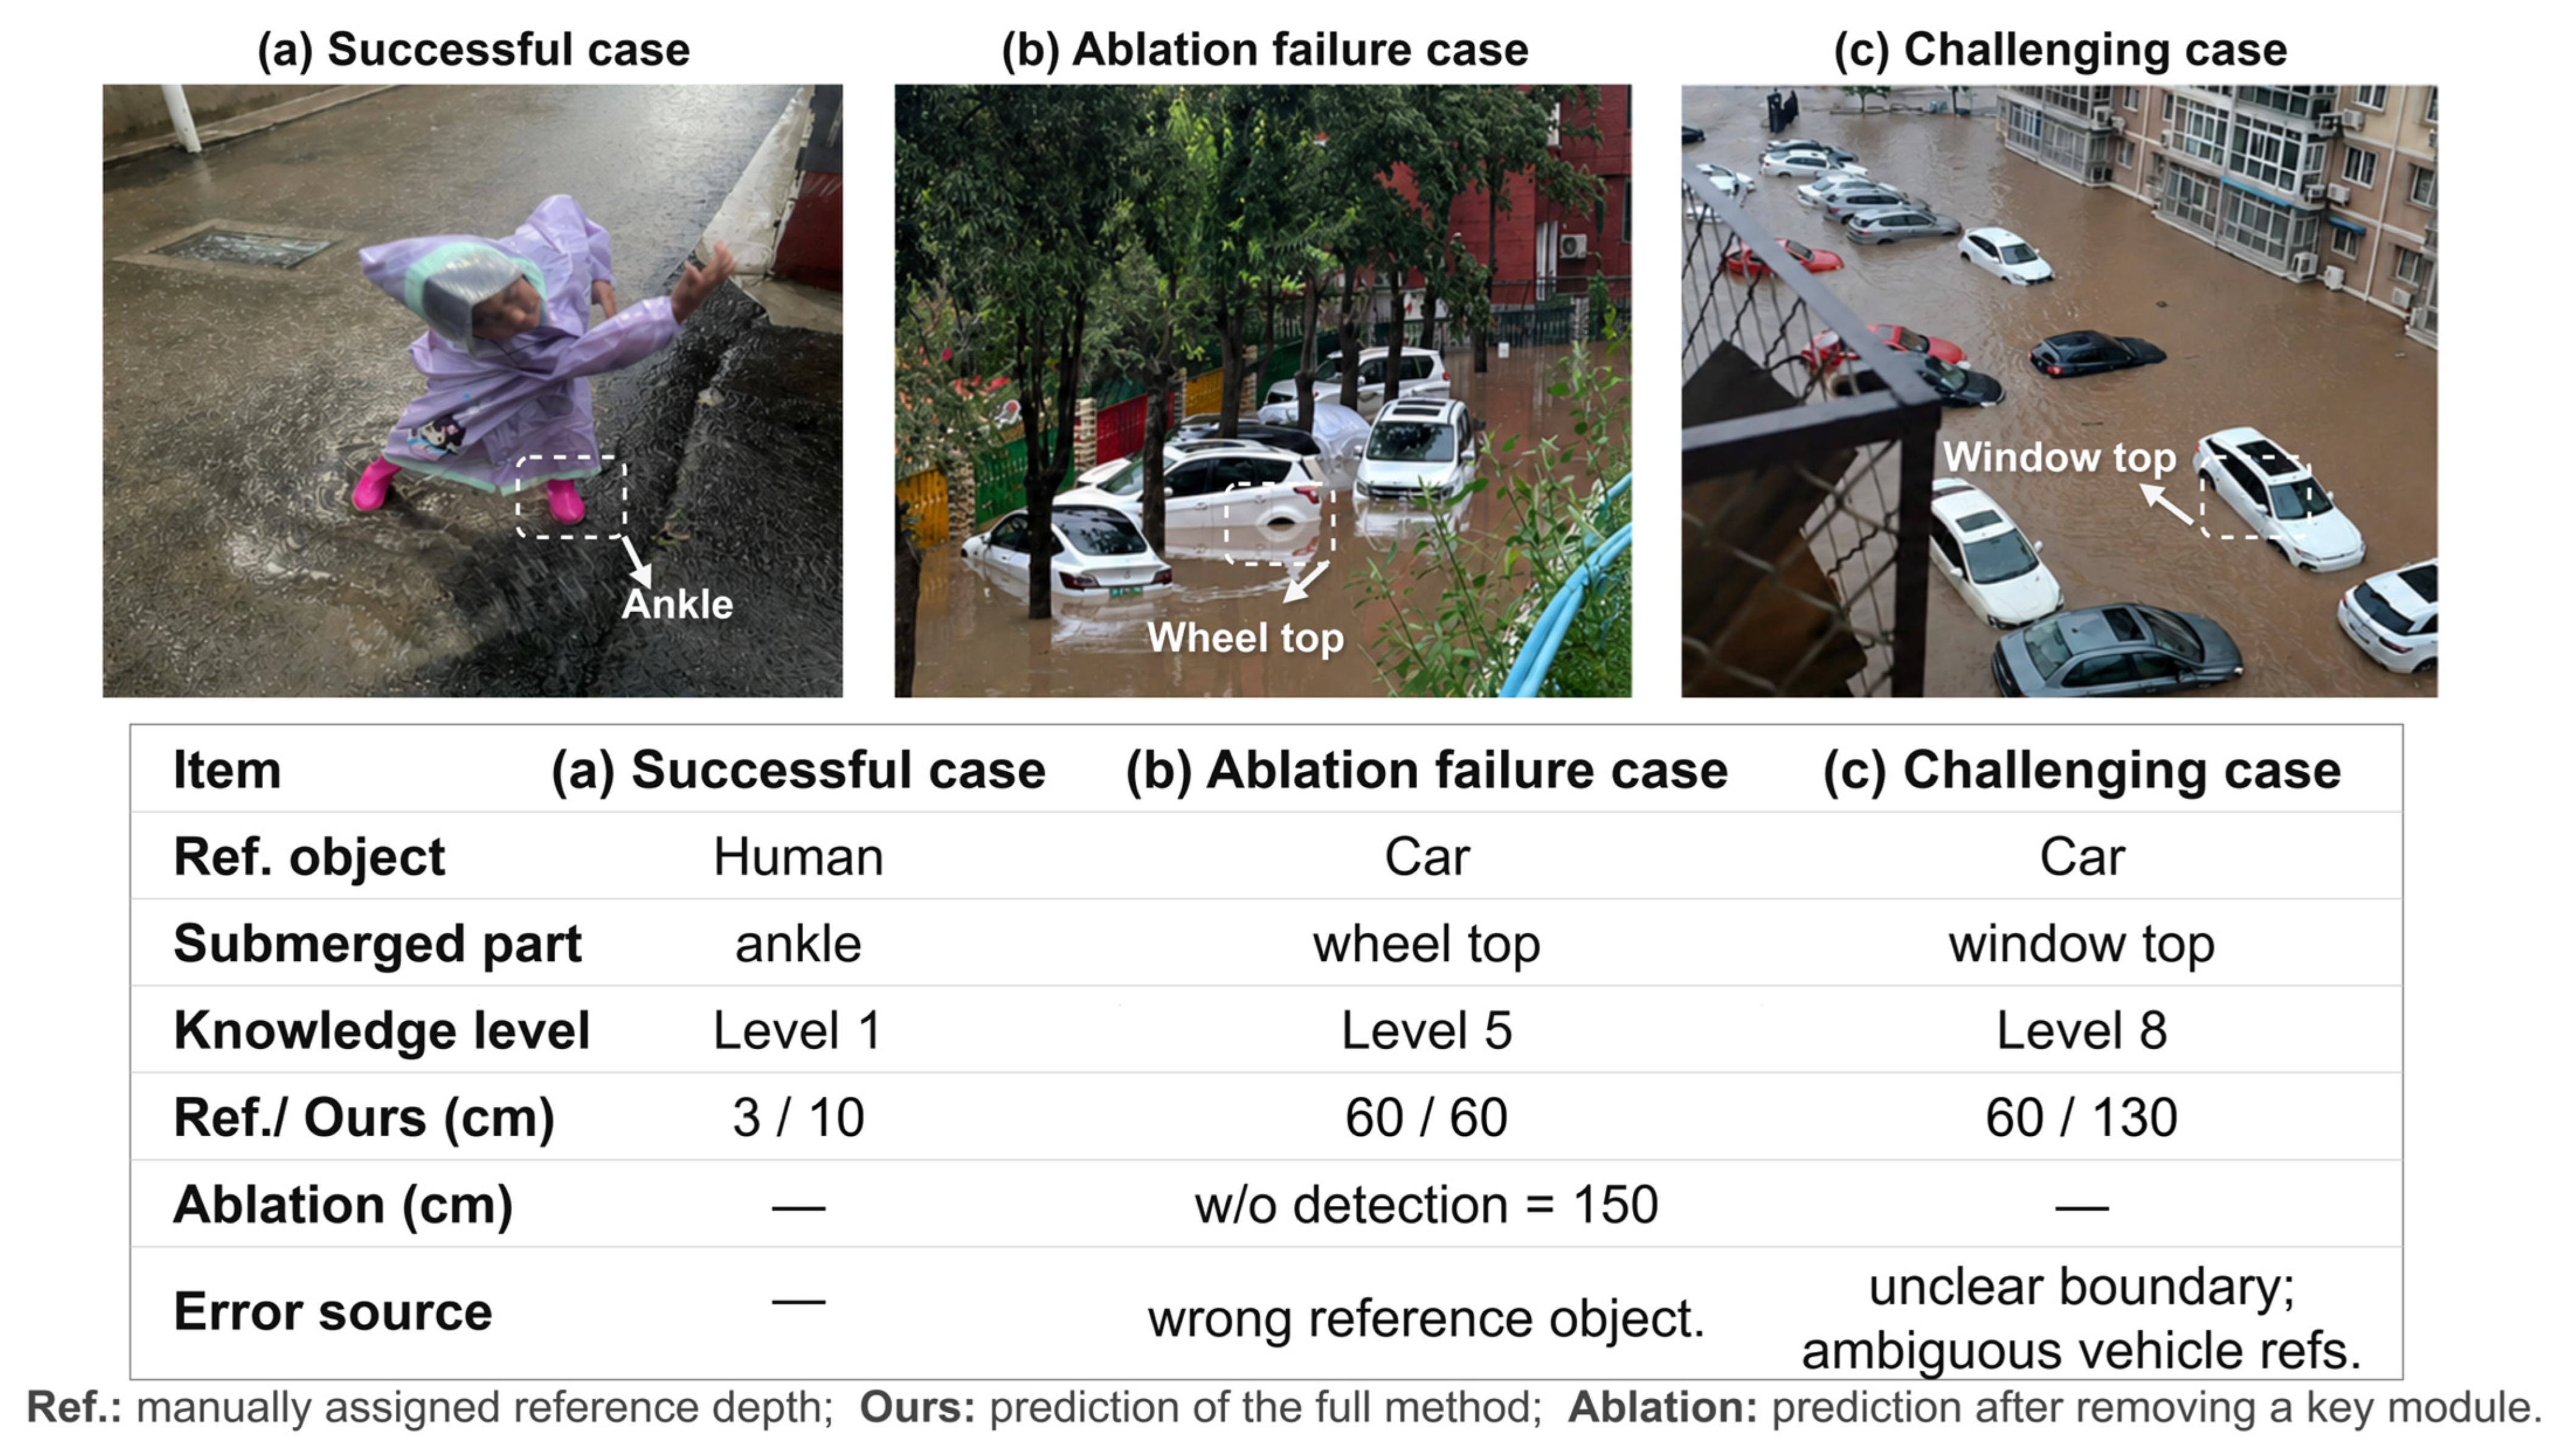
The first source of error lies in the construction of image-based depth evidence. RPD-VLM depends on reference-object recognition, submerged-part assessment, and knowledge mapping, and uncertainty at any stage propagates to the final depth estimate. If the model selects an object outside the main flooded area or uses a reference object at a shallow margin to represent the principal inundation, the estimate may depart from the manually assigned reference depth. On the common valid subset, removal of the candidate-reference-object constraint is associated with a larger increase in error, indicating that object selection and object–water interpretation are important error sources.
A second source of uncertainty arises from the reference-object depth mapping. Variations in human body proportions, tyre diameters, vehicle ground clearance, and component heights may cause the physical depth corresponding to the same semantic part to differ from its representative value. The discrete depth classes also cannot fully represent within-class variation.
Under the ±10% scenario, the maximum deviation across the representative depth levels was 17.0 cm, while the MAE on the 185 common valid samples ranged from 13.7 to 17.4 cm. These results represent scenario-based mapping sensitivity rather than a confidence interval for actual object dimensions or a total uncertainty bound. Other uncertainties, including object selection, submerged-part interpretation, imaging conditions, and manually assigned reference depths, are not included.
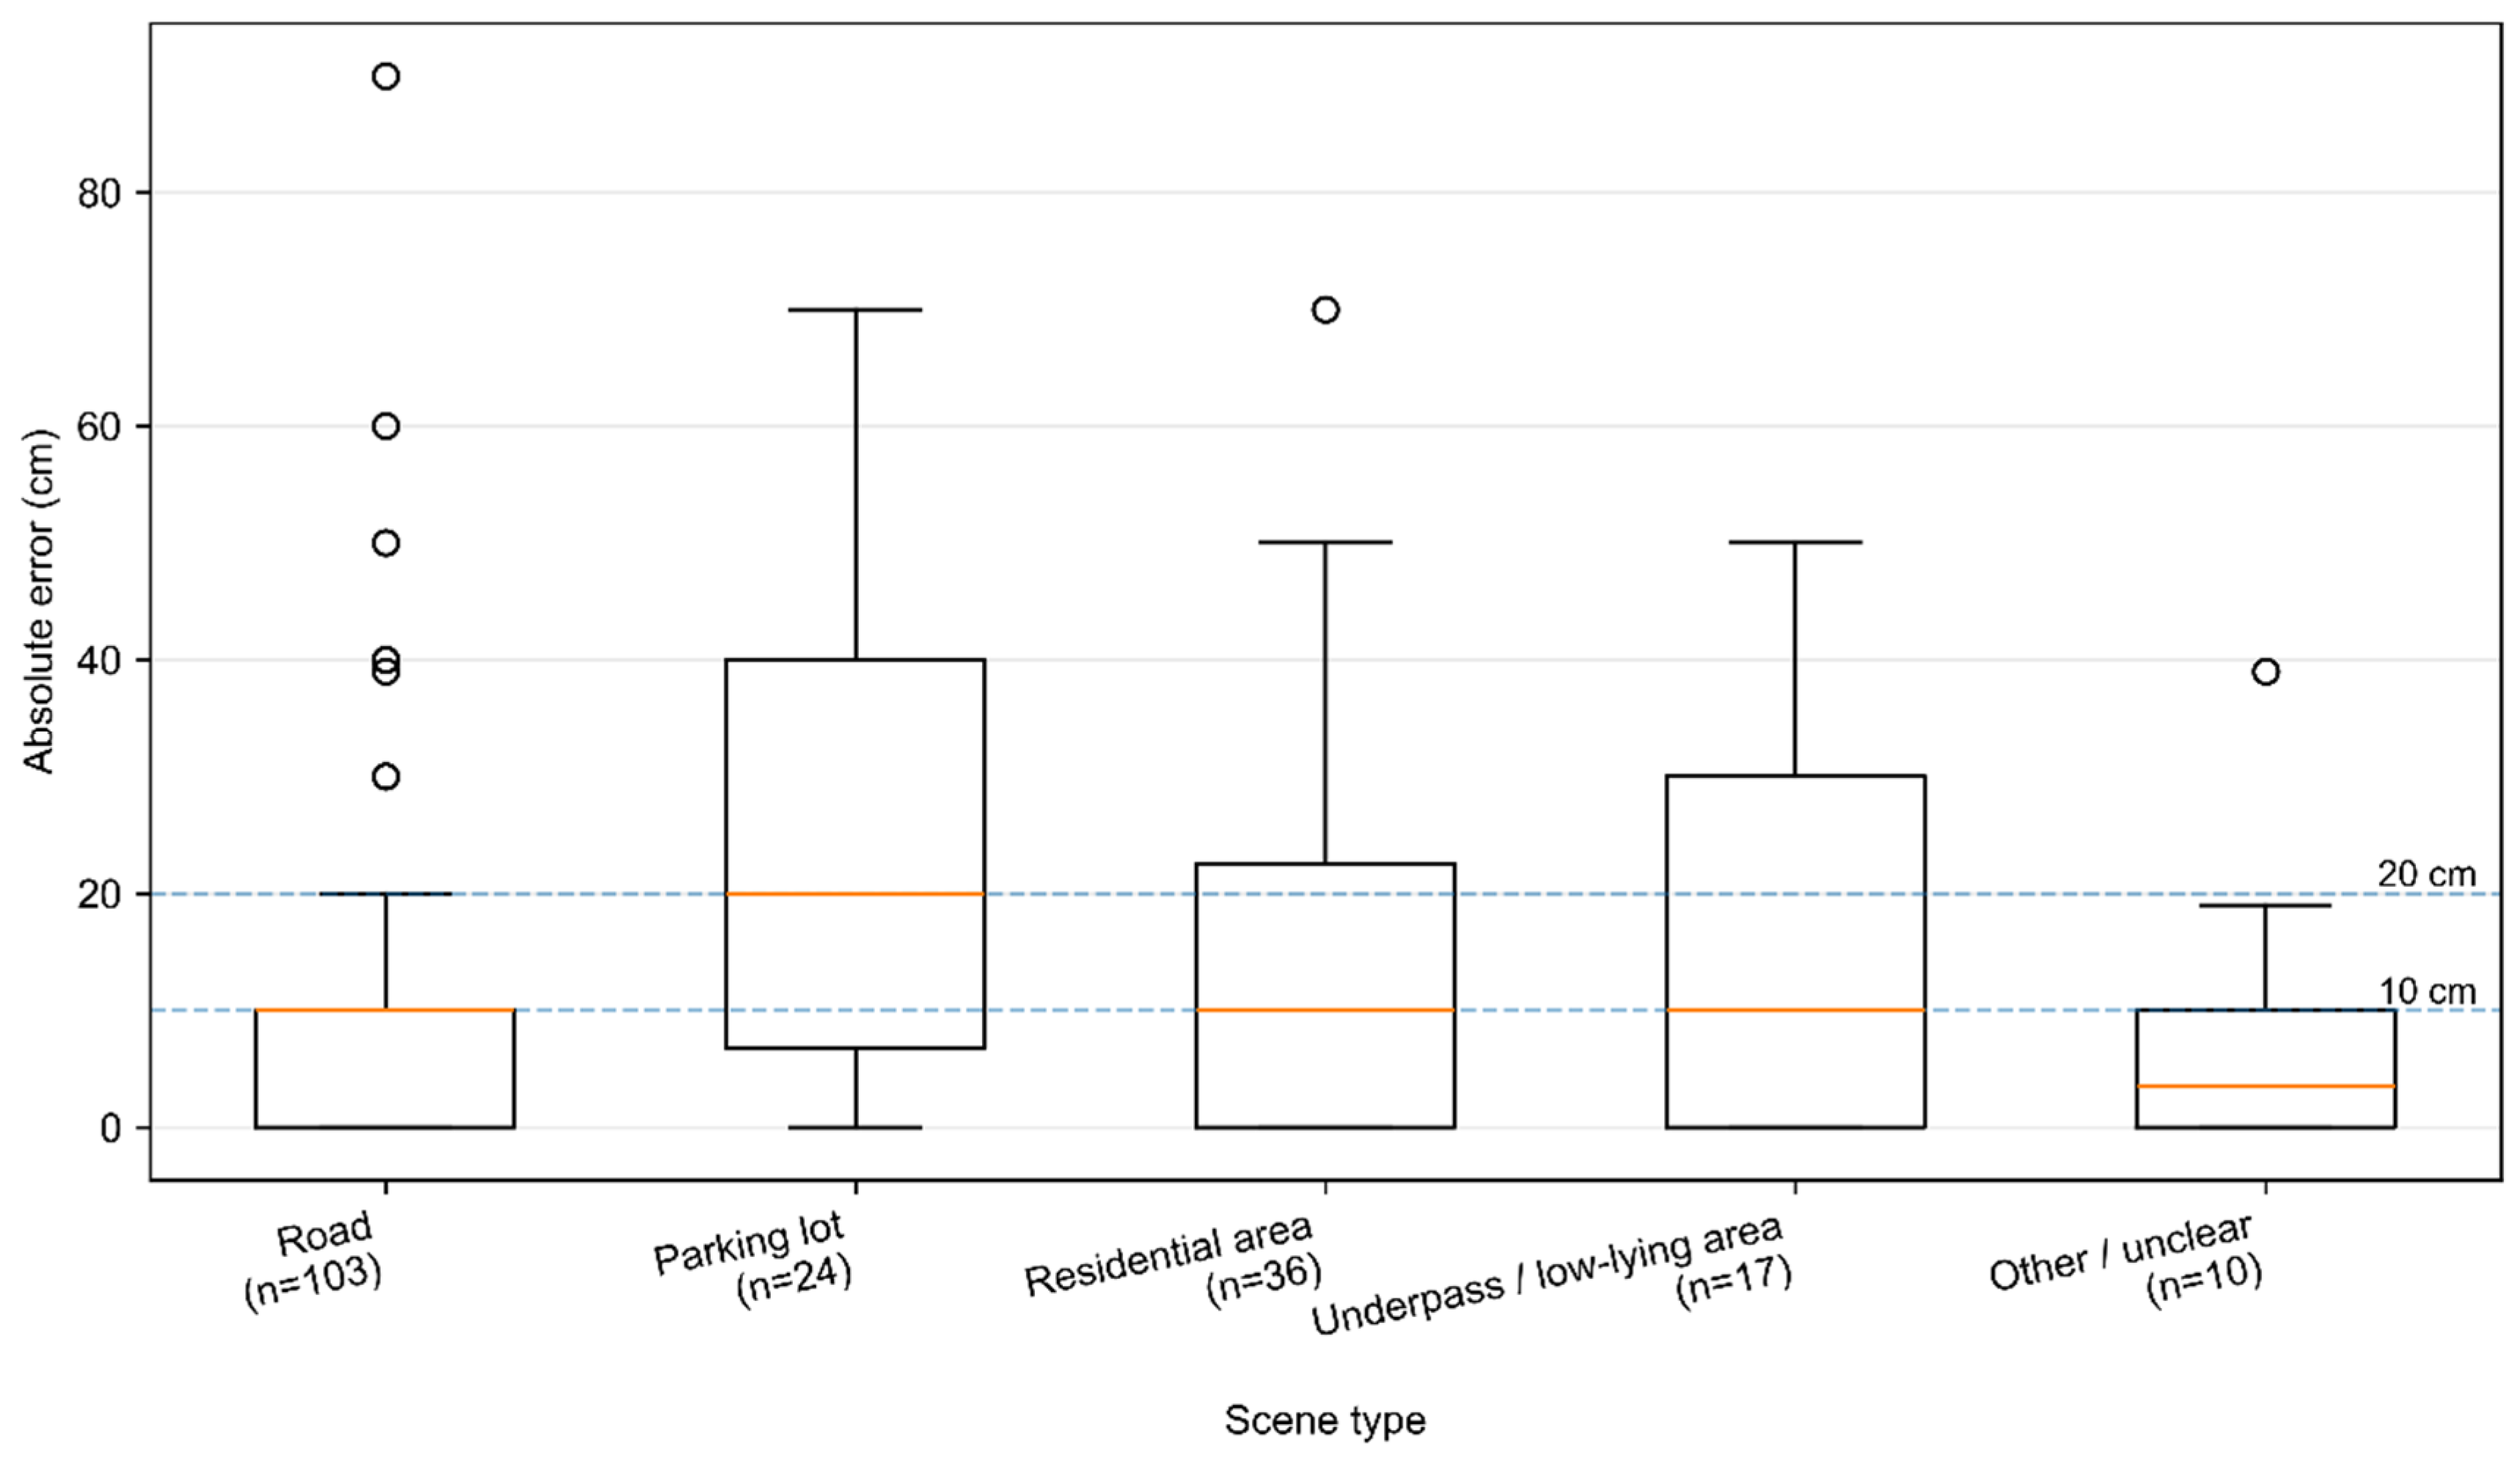
A third source of error concerns the imaging conditions and spatial structure of crowdsourced scenes. Social media images generally lack standardised camera distance, camera height, and viewpoint information, and may be affected by rain, mist, low illumination, compression artefacts, or motion blur. Reflections from the water surface, unclear road–water boundaries, and vehicle occlusion reduce the interpretability of object–water relations. Among the larger scene categories, road scenes have a comparatively stable error distribution, whereas parking areas, bridges, culverts, and low-lying scenes more often contain multiple vehicles, occlusion, and unclear water boundaries.
Textual uncertainty is another source of error in image–text fusion. Even an explicit numerical value or relative-part expression may not correspond to the image acquisition time or the main flooded area in the image. Text may refer to a nearby intersection, a historical maximum, a local deepest point, or the poster’s subjective assessment of severity. Unconditional text participation is associated with higher error on the current fusion set. Text is therefore used as auxiliary evidence only when the quantifiability, directional, and image–text difference conditions are satisfied.
This finding also complements previous multimodal flood-depth studies that jointly exploit image and textual information, by showing that, in the present crowdsourced dataset, textual participation is beneficial only under restricted conditions and should not be assumed to provide a uniform gain.
In this framework, RPD-VLM-T is used to extract candidate depth evidence from accompanying text, whereas RPD-VLM-Fusion determines whether that evidence should modify the image-based estimate under the predefined quantifiability, directional, and image–text discrepancy conditions. This differs from multimodal approaches that jointly optimise image and text within a unified model, because textual evidence is evaluated separately before being allowed to participate in the final estimate.
The manually assigned reference depths also contain uncertainty. Crowdsourced data usually lack in situ water gauges or synchronous sensor measurements, and the reference depths are mainly determined from visible reference objects, scene context, and annotation rules. The reported errors are therefore more appropriate for comparing methods under a common manual reference benchmark than for representing absolute physical error relative to in situ depth. Future work can combine field observations, camera geometry, instance segmentation, and depth estimation to evaluate uncertainty in reference-object interpretation and scale conversion more directly.
5.3. Application Value and Future Work
The method does not use a single image as a substitute for an in situ water-gauge observation. Instead, it converts fragmented image–text records into comparable and traceable structured depth-evidence units. The image module retains the reference-object type, submerged part, and image-based depth evidence; the text module retains the textual depth evidence and quantifiability status; and the fusion module records whether text participates and the difference between the image and text predictions. These fields provide an evidence path for subsequent filtering, review, and aggregation.
Within a flood event, structured depth evidence with temporal and locational cues can be aggregated by road, community, or reported flood location to help identify repeatedly affected places and compare relative depths across records. Records with clear image evidence and text satisfying the participation conditions may support situational assessment. Records for which text does not participate, the reference object is unstable, or the image–text difference is large should be reviewed manually using the retained intermediate fields.
The spatiotemporal distribution of crowdsourced records is influenced by platform-user density, event attention, camera location, and posting behaviour and does not represent the actual spatial distribution of urban flooding. The location of a record may derive from a platform tag, a textual place name, or manual interpretation, each with uncertain positional accuracy and temporal correspondence. Precise georeferencing should therefore be regarded as a separate uncertainty source from depth estimation. The current experiments evaluate water depth at the record level and do not infer or validate exact geographic coordinates for every social media record. Consequently, the resulting depth estimates should not be interpreted directly as georeferenced flood-depth measurements or as a complete flood-depth map. For downstream spatial aggregation, location cues would require independent geocoding and positional validation before being associated with specific roads, communities, or inundated areas. Images from the same location may also represent different stages of inundation. The results are therefore more appropriately treated as candidate depth evidence and relative depth cues within a specified time window. Future spatial analyses should account for this sampling bias by incorporating population or platform-user density, applying spatial stratification or density-based weighting, and comparing crowdsourced observations with independent monitoring data where available.
RPD-VLM, RPD-VLM-T, and RPD-VLM-Fusion can serve as front-end evidence-construction modules for processing crowdsourced flood information and can be used together with field inspection, fixed cameras, water-level monitoring, rainfall data, or hydrodynamic models. Their role is to provide structured input for subsequent filtering and manual verification, not to replace field measurement or independently produce precise water-depth maps. Future work will focus on validating crowdsourced depth estimates against synchronous field observations, refining the reference-object depth mapping to account for variations in reference-object dimensions, improving georeferencing using textual locations and external geographic information, and evaluating the framework across different flood events and cities.
6. Conclusions
This study developed an image-led framework for urban street-scale flood-depth estimation from crowdsourced image and text data. The framework constructs structured depth evidence separately from images and accompanying text, with image-derived evidence retained as the primary source and text used only as conditional auxiliary evidence. Rather than directly combining the two modalities, the proposed fusion strategy controls textual participation using quantifiability, directional, and image–text discrepancy conditions, thereby limiting the influence of cross-modal inconsistency on the final depth estimate. The proposed method first extracts image-based depth evidence by recognizing reference objects, identifying submerged parts, and establishing object-part depth relationships through knowledge mapping. Compared with direct depth inference from vision–language models, this evidence-based strategy provides a more interpretable approach for transforming visual flood observations into depth estimates. Additionally, textual information from social media is analyzed through rule-based extraction and semantic verification to identify explicit values, range descriptions, and relative water-level expressions. The extracted textual information is incorporated as conditional auxiliary evidence under quantifiability, directional, and image–text discrepancy constraints, considering the potential inconsistency between image and text observations caused by differences in location, time, and flooding conditions.
Experimental results show that the proposed framework can construct structured water-depth evidence from crowdsourced image–text records and reduce the instability of direct VLM depth generation. Conditional text participation provides limited auxiliary correction under the specified constraints but should not be interpreted as a general accuracy gain from multimodal fusion. Because the reference depths are scene-based manual estimates rather than in situ measurements, the resulting depths are more appropriately used as auxiliary evidence for post-disaster situational assessment and subsequent manual verification. Future studies will further evaluate the framework using field measurements, sensor observations, cross-city flood events, and more detailed geometric constraints.