Ego-Motion-Aware Temporal Fusion in BEV Space for Multi-Modal 3D Object Detection


Abstract
1. Introduction
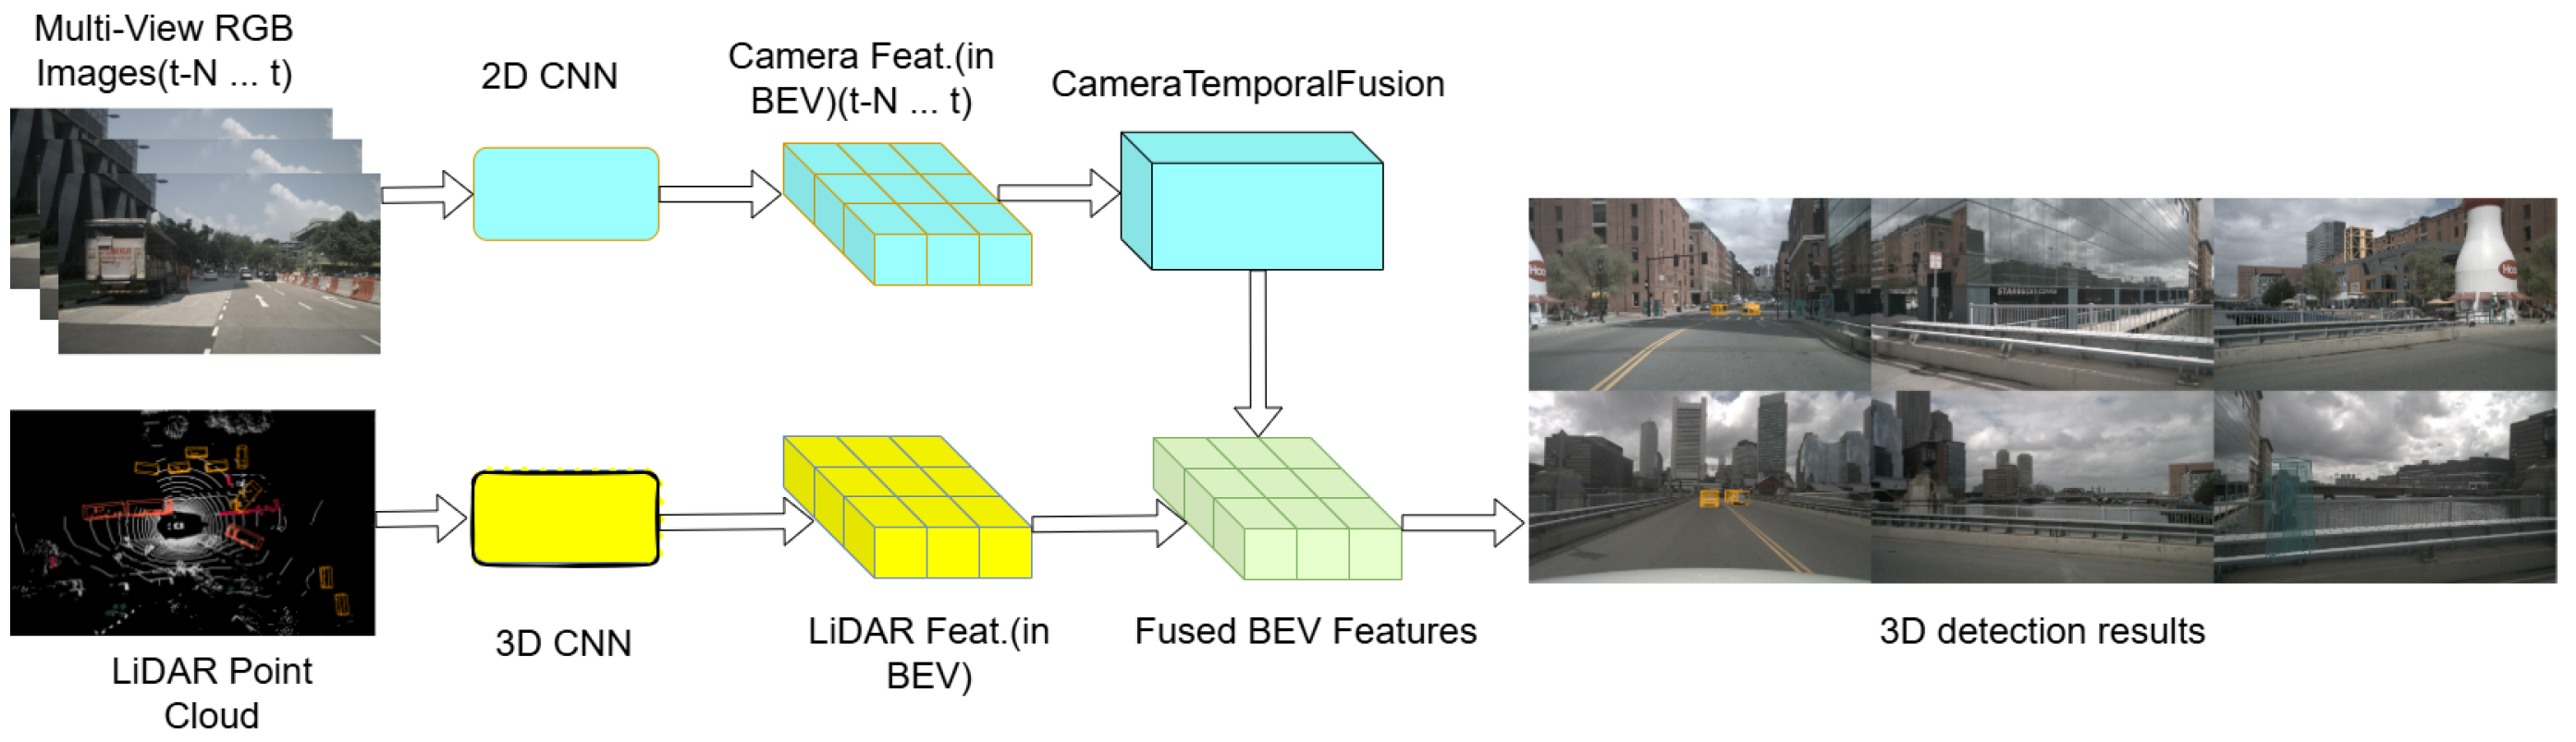
- We propose CamT-BEV, a camera-temporal-enhanced BEV fusion framework specifically designed to enhance camera-side representations for multi-modal 3D object detection.
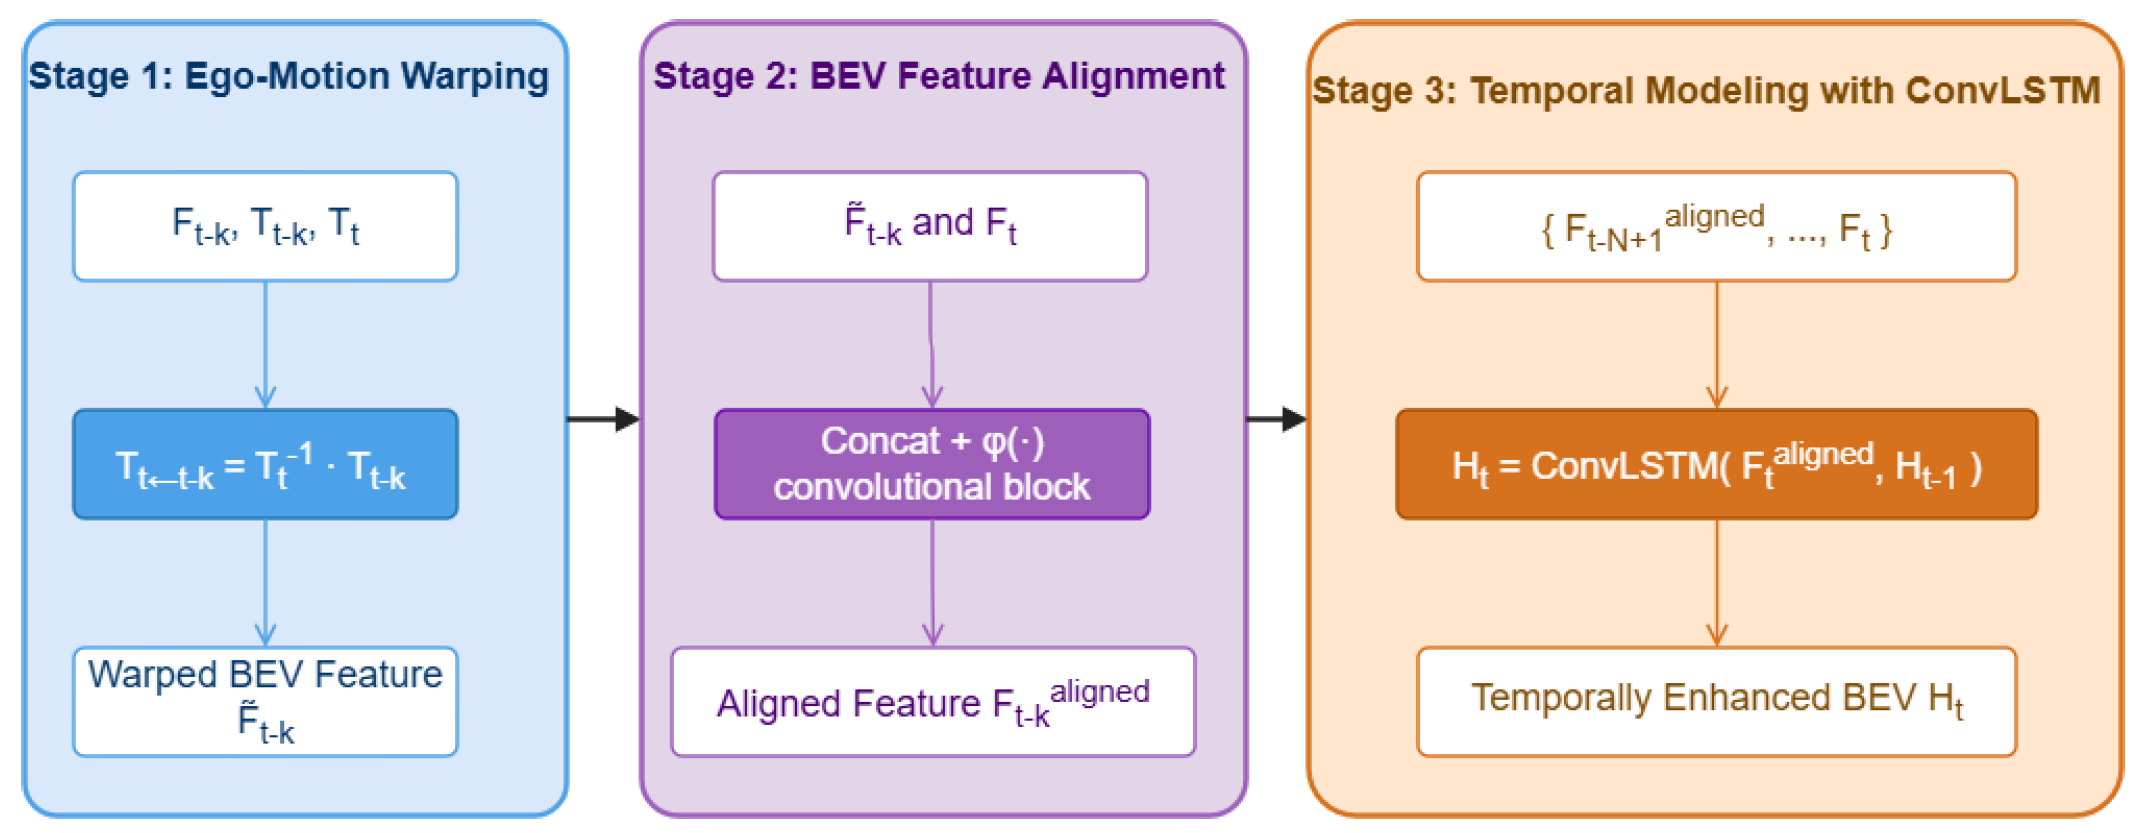
- We design the CameraTemporalFusion module for CamT-BEV, which combines ego-motion-based alignment with ConvLSTM temporal encoding for efficient multi-frame camera feature aggregation.
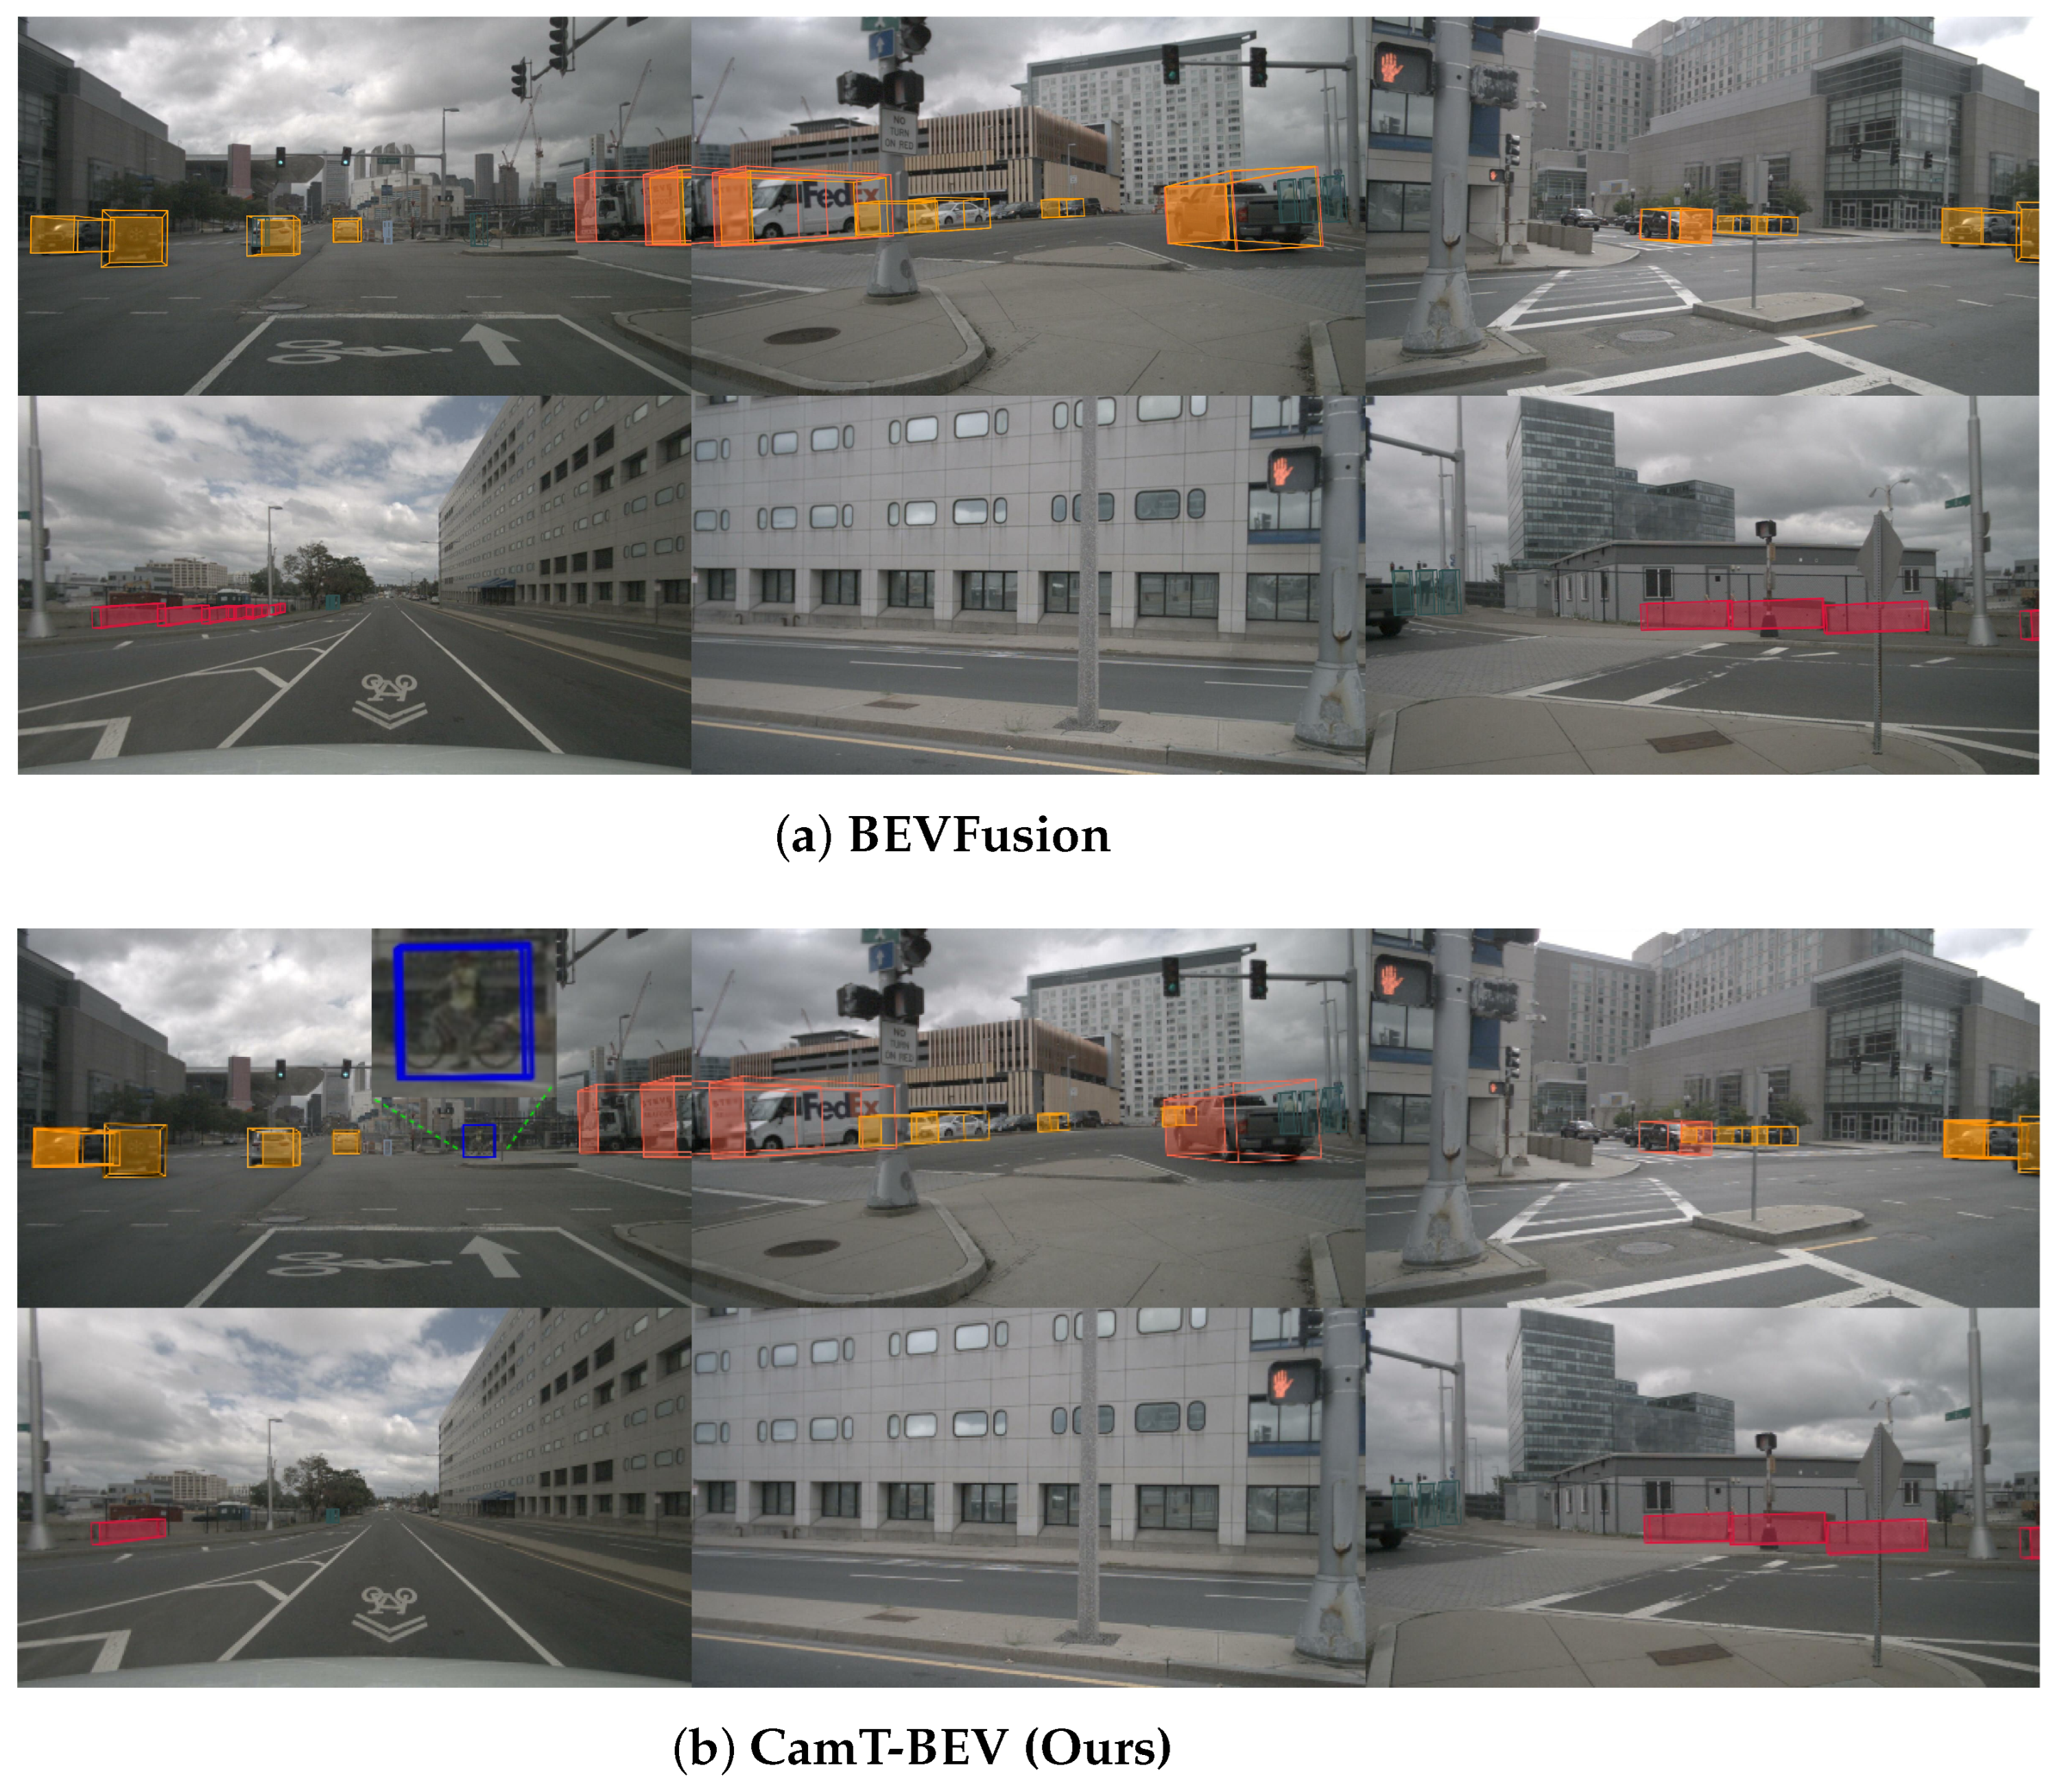
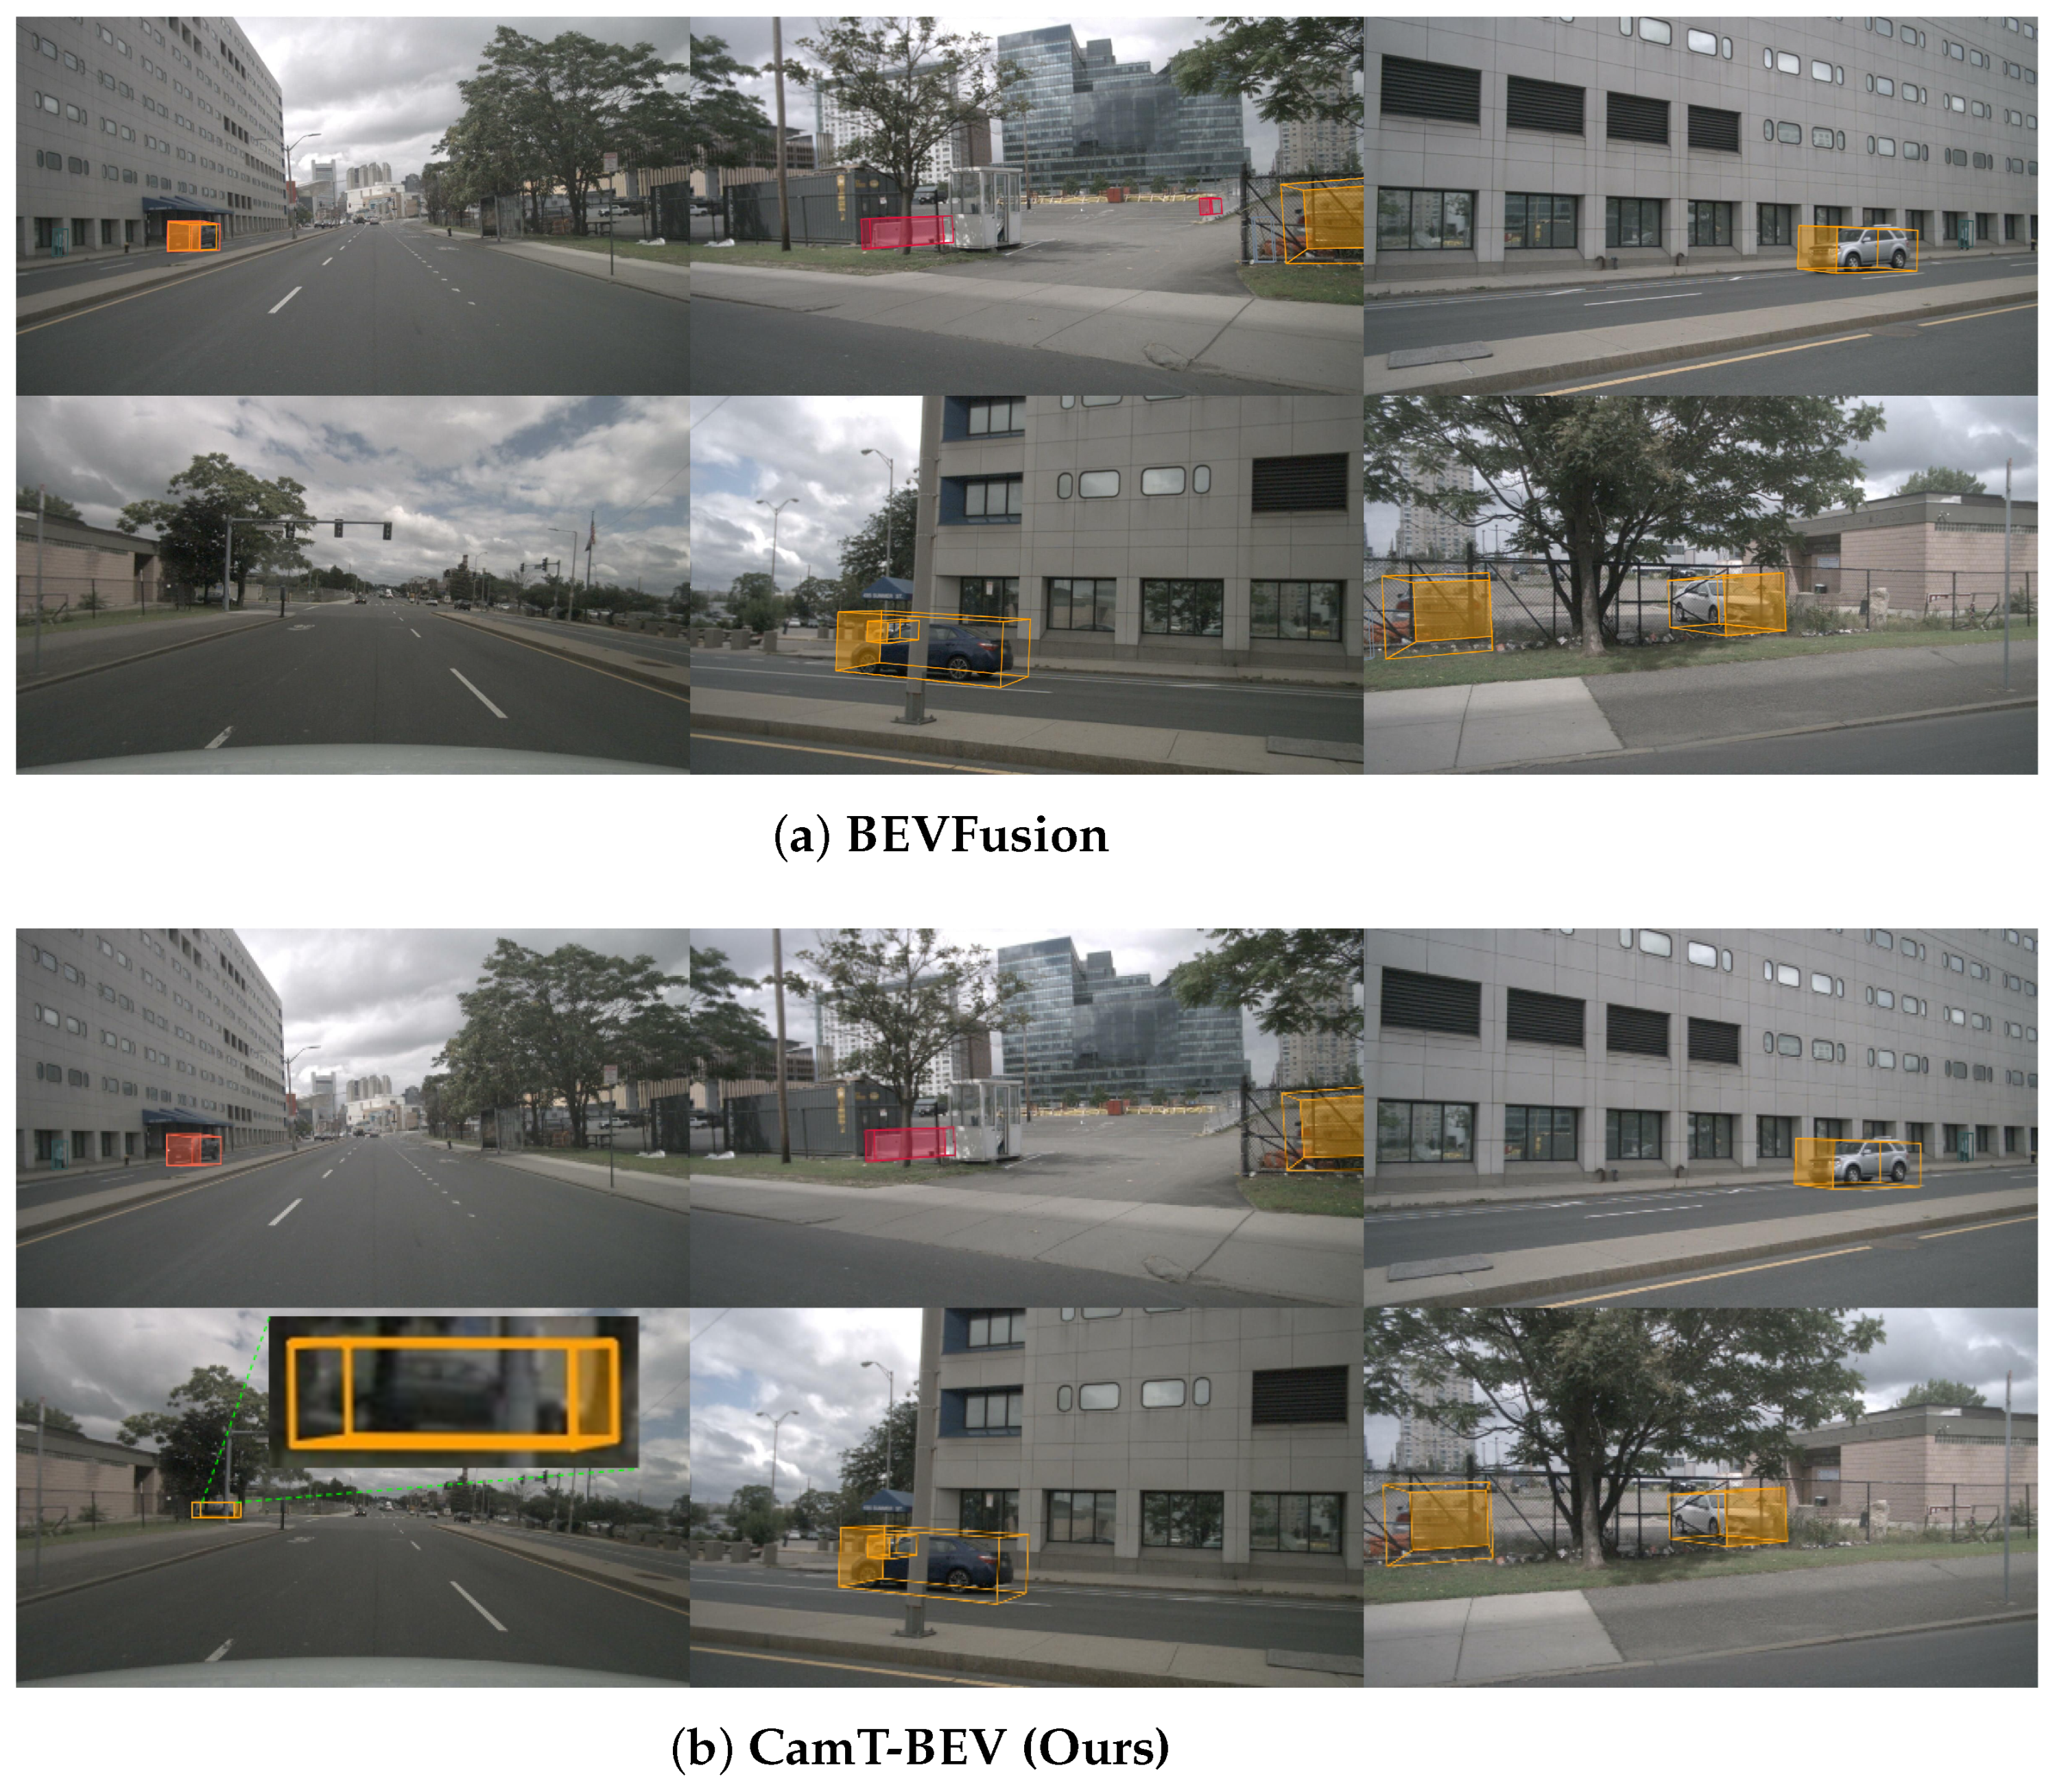
- We conduct extensive experiments on nuScenes, demonstrating that CamT-BEV achieves superior performance over BEVFusion (yielding +0.0154 NDS and +0.0302 mAP improvements), with significant gains on challenging object categories while maintaining an identical memory footprint.
- We provide comprehensive analyses validating the effectiveness of CamT-BEV’s camera-temporal fusion for robust 3D object detection in autonomous driving scenarios.
2. Related Work
2.1. 3D Object Detection
2.2. Multi-Modal Sensor Fusion
2.3. Temporal Modeling and 4D Perception
3. Proposed Method
3.1. CamT-BEV
3.2. CameraTemporalFusion
3.2.1. Ego-Motion-Based BEV Warping
3.2.2. BEV Feature Alignment
3.2.3. Temporal Modeling with ConvLSTM
3.3. Motivation and Design Rationale for Camera-Side Temporal Fusion
4. Experiment and Analysis
4.1. Hardware and Software Environment
4.2. Network and Input Configuration
4.3. Temporal Module Settings
4.4. Normalization and Training Hyperparameters
4.5. Dataset and Evaluation Indicators
4.6. Comparison and Analysis of Results
4.7. Ablation Experiment
4.8. Visualization of Test Results
4.9. Discussion and Limitations
5. Conclusions
Author Contributions
Funding
Data Availability Statement
Acknowledgments
Conflicts of Interest
References
- Liu, Z.; Tang, H.; Amini, A.; Yang, X.; Mao, H.; Rus, D.L.; Han, S. BEVFusion: Multi-Task Multi-Sensor Fusion with Unified Bird’s-Eye View Representation. In Proceedings of the IEEE International Conference on Robotics and Automation (ICRA), London, UK, 29 May–2 June 2023; pp. 2774–2781. [Google Scholar]
- Bai, X.; Hu, Z.; Zhu, X.; Huang, Q.; Chen, Y.; Fu, H.; Tai, C.L. TransFusion: Robust LiDAR-Camera Fusion for 3D Object Detection with Transformers. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2022; pp. 1090–1099. [Google Scholar]
- Contreras, M.; Jain, A.; Bhatt, N.P.; Banerjee, A.; Hashemi, E. A survey on 3D object detection in real time for autonomous driving. Front. Robot. AI 2024, 11, 1212070. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Lang, A.H.; Vora, S.; Caesar, H.; Zhou, L.; Yang, J.; Beijbom, O. PointPillars: Fast Encoders for Object Detection from Point Clouds. In Proceedings of the 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, CA, USA, 15–20 June 2019; pp. 12689–12697. [Google Scholar] [CrossRef] [Scilit]
- Yin, T.; Zhou, X.; Krahenbuhl, P. Center-Based 3D Object Detection and Tracking. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2021; pp. 11784–11793. [Google Scholar]
- Zhao, K.; Gou, Z.; Liu, H. Edge-assisted adaptive offloading algorithm for 3D object detection tasks. PLoS ONE 2026, 21, 0345876. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Liang, D.; Zhou, X.; Xu, W.; Zhu, X.; Zou, Z.; Ye, X.; Tan, X.; Bai, X. Pointmamba: A simple state space model for point cloud analysis. Adv. Neural Inf. Process. Syst. 2024, 37, 32653–32677. [Google Scholar] [CrossRef] [Scilit]
- Li, Z.; Wang, W.; Li, H.; Xie, E.; Sima, C.; Lu, T.; Yu, Q.; Dai, J. BEVFormer: Learning Bird’s-Eye-View Representation from LiDAR-Camera via Spatiotemporal Transformers. IEEE Trans. Pattern Anal. Mach. Intell. 2025, 47, 2020–2036. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Peng, S.; Genova, K.; Jiang, C.; Tagliasacchi, A.; Pollefeys, M.; Funkhouser, T. OpenScene: 3D Scene Understanding with Open Vocabularies. In Proceedings of the 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, BC, Canada, 17–24 June 2023; pp. 815–824. [Google Scholar] [CrossRef] [Scilit]
- Sima, C.; Renz, K.; Chitta, K.; Chen, L.; Zhang, H.; Xie, C.; Beißwenger, J.; Luo, P.; Geiger, A.; Li, H. Drivelm: Driving with graph visual question answering. In Proceedings of the European Conference on Computer Vision; Springer: Berlin/Heidelberg, Germany, 2024; pp. 256–274. [Google Scholar]
- Ye, L. Exploring The Current State of Multimodal Alignment and Fusion. In Proceedings of the ITM Web of Conferences; EDP Sciences: Les Ulis, France, 2025; Volume 78, p. 04036. [Google Scholar]
- Jiao, T.; Chen, Y.; Feng, X.; Guo, C.; Song, J. Semantic-Enhanced Bidirectional Multimodal Fusion for 3D Object Detection Under Adverse Weather. Appl. Sci. 2026, 16, 2943. [Google Scholar] [CrossRef] [Scilit]
- Yang, Z.; Chen, J.; Miao, Z.; Li, W.; Zhu, X.; Zhang, L. Deepinteraction: 3d object detection via modality interaction. Adv. Neural Inf. Process. Syst. 2022, 35, 1992–2005. [Google Scholar] [CrossRef] [Scilit]
- Sun, J.; Chen, K.; He, X.; Liu, X.; Li, K.; Peng, C. Unitrans: Unified parameter-efficient transfer learning and multimodal alignment for large multimodal foundation model. Comput. Mater. Contin. 2025, 83, 219–238. [Google Scholar] [CrossRef] [Scilit]
- Huang, J.; Huang, G. BEVDet4D: Exploit Temporal Cues in Multi-Camera 3D Object Detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 1012–1021. [Google Scholar]
- Ma, J.; Chen, X.; Huang, J.; Xu, J.; Luo, Z.; Xu, J.; Gu, W.; Ai, R.; Wang, H. Cam4DOcc: Benchmark for Camera-Only 4D Occupancy Forecasting in Autonomous Driving Applications. In Proceedings of the 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16–22 June 2024; pp. 21486–21495. [Google Scholar] [CrossRef] [Scilit]
- Zeng, Y.; Ma, C. LIFT: Learning 4D LiDAR-Image Fusion Transformer for 3D Object Detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 17151–17160. [Google Scholar]
- Caesar, H.; Bankiti, V.; Lang, A.H.; Vora, S.; Liong, V.E.; Xu, Q.; Krishnan, A.; Pan, Y.; Baldan, G.; Beijbom, O. nuScenes: A Multimodal Dataset for Autonomous Driving. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 11618–11628. [Google Scholar]
- Dong, Y.; Kang, C.; Zhang, J.; Zhu, Z.; Wang, Y.; Yang, X.; Su, H.; Wei, X.; Zhu, J. Benchmarking Robustness of 3D Object Detection to Common Corruptions in Autonomous Driving. In Proceedings of the 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, BC, Canada, 17–24 June 2023; pp. 1022–1032. [Google Scholar] [CrossRef] [Scilit]
- Zhu, X.; Ma, Y.; Wang, T.; Xu, Y.; Shi, J.; Lin, D. Ssn: Shape signature networks for multi-class object detection from point clouds. In Proceedings of the European Conference on Computer Vision; Springer: Berlin/Heidelberg, Germany, 2020; pp. 581–597. [Google Scholar]
- Wang, T.; Xinge, Z.; Pang, J.; Lin, D. Probabilistic and geometric depth: Detecting objects in perspective. In Proceedings of the Conference on Robot Learning; PMLR: New York, NY, USA, 2022; pp. 1475–1485. [Google Scholar]
- Vora, S.; Lang, A.H.; Helou, B.; Beijbom, O. PointPainting: Sequential Fusion for 3D Object Detection. In Proceedings of the 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 13–19 June 2020; pp. 4603–4611. [Google Scholar] [CrossRef] [Scilit]
- Yoo, J.H.; Kim, Y.; Kim, J.; Choi, J.W. 3d-cvf: Generating joint camera and lidar features using cross-view spatial feature fusion for 3d object detection. In Proceedings of the European Conference on Computer Vision; Springer: Berlin/Heidelberg, Germany, 2020; pp. 720–736. [Google Scholar]
- Yin, J.; Shen, J.; Chen, R.; Li, W.; Yang, R.; Frossard, P.; Wang, W. IS-Fusion: Instance-Scene Collaborative Fusion for Multimodal 3D Object Detection. In Proceedings of the 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16–22 June 2024; pp. 14905–14915. [Google Scholar] [CrossRef] [Scilit]



| METHOD | Sensors | NDS↑ | mAP↑ | mATE↓ | mASE↓ | mAOE↓ | mAVE↓ | mAAE↓ |
|---|---|---|---|---|---|---|---|---|
| Pointpillars [4] | LiDAR | 0.49078 | 0.34327 | 0.4239 | 0.2844 | 0.5293 | 0.3773 | 0.1936 |
| SSN [20] | LiDAR | 0.49761 | 0.35167 | 0.42438 | 0.28495 | 0.49674 | 0.38269 | 0.19396 |
| BEVFormer [8] | Camera | 0.5690 | 0.4810 | 0.5820 | 0.2560 | 0.3750 | 0.3780 | 0.1260 |
| PGD [21] | Camera | 0.39335 | 0.31736 | 0.7636 | 0.2668 | 0.4572 | 1.2849 | 0.1658 |
| PointPainting [22] | LiDAR+Camera | 0.5810 | 0.4640 | 0.3877 | 0.2712 | 0.4958 | 0.2466 | 0.1114 |
| 3D-CVF [23] | LiDAR+Camera | 0.4978 | 0.4217 | 0.3001 | 0.2455 | 0.4576 | 0.2795 | 0.12225 |
| IS-Fusion [24] | LiDAR+Camera | 0.6849 | 0.6647 | 0.2922 | 0.2708 | 0.3180 | 0.3873 | 0.2060 |
| BEVFusion [1] | LiDAR+Camera | 0.2830 | 0.2523 | 0.3535 | 0.2967 | 0.1880 | ||
| CamT-BEV | LiDAR+Camera | 0.2830 | 0.2559 | 0.3558 | 0.2918 | 0.1842 |
| Category | Distance (m) | Pointpillars | SSN | BEVFormer | PGD | PointPainting | 3D-CVF | BEVFusion | CamT-BEV |
|---|---|---|---|---|---|---|---|---|---|
| Car | 0.5 | 0.530 | 0.681 | 0.362 | 0.204 | 0.664 | 0.742 | 0.7932 | 0.8059 |
| 1.0 | 0.696 | 0.799 | 0.645 | 0.487 | 0.790 | 0.839 | 0.8872 | 0.8947 | |
| 2.0 | 0.741 | 0.840 | 0.817 | 0.718 | 0.822 | 0.863 | 0.9164 | 0.9238 | |
| 4.0 | 0.769 | 0.856 | 0.883 | 0.834 | 0.841 | 0.875 | 0.9274 | 0.9341 | |
| Bicycle | 0.5 | 0.050 | 0.104 | 0.165 | 0.097 | 0.195 | 0.275 | 0.4273 | 0.5439 |
| 1.0 | 0.120 | 0.125 | 0.370 | 0.262 | 0.244 | 0.303 | 0.4599 | 0.5840 | |
| 2.0 | 0.130 | 0.129 | 0.519 | 0.404 | 0.258 | 0.317 | 0.4623 | 0.5932 | |
| 4.0 | 0.160 | 0.133 | 0.576 | 0.491 | 0.265 | 0.322 | 0.4689 | 0.6076 | |
| Pedestrian | 0.5 | 0.499 | 0.686 | 0.162 | 0.116 | 0.642 | 0.720 | 0.8474 | 0.8596 |
| 1.0 | 0.589 | 0.702 | 0.461 | 0.350 | 0.722 | 0.735 | 0.8592 | 0.8714 | |
| 2.0 | 0.633 | 0.718 | 0.721 | 0.580 | 0.769 | 0.748 | 0.8697 | 0.8811 | |
| 4.0 | 0.668 | 0.744 | 0.832 | 0.719 | 0.796 | 0.766 | 0.8803 | 0.8907 | |
| Truck | 0.5 | 0.097 | 0.162 | 0.102 | 0.050 | 0.207 | 0.289 | 0.4204 | 0.4194 |
| 1.0 | 0.222 | 0.339 | 0.316 | 0.204 | 0.353 | 0.450 | 0.5937 | 0.6048 | |
| 2.0 | 0.290 | 0.427 | 0.520 | 0.397 | 0.425 | 0.521 | 0.6714 | 0.6845 | |
| 4.0 | 0.312 | 0.450 | 0.632 | 0.543 | 0.447 | 0.540 | 0.7069 | 0.7229 | |
| Construction vehicle | 0.5 | 0.000 | 0.001 | 0.003 | 0.000 | 0.018 | 0.009 | 0.0530 | 0.0527 |
| 1.0 | 0.012 | 0.061 | 0.080 | 0.030 | 0.113 | 0.101 | 0.2166 | 0.2245 | |
| 2.0 | 0.059 | 0.150 | 0.316 | 0.166 | 0.230 | 0.227 | 0.3426 | 0.3808 | |
| 4.0 | 0.094 | 0.179 | 0.517 | 0.341 | 0.270 | 0.298 | 0.4802 | 0.5082 | |
| Bus | 0.5 | 0.074 | 0.197 | 0.049 | 0.033 | 0.147 | 0.284 | 0.4740 | 0.5266 |
| 1.0 | 0.280 | 0.419 | 0.239 | 0.186 | 0.362 | 0.515 | 0.7263 | 0.7615 | |
| 2.0 | 0.371 | 0.518 | 0.491 | 0.369 | 0.452 | 0.567 | 0.8472 | 0.8805 | |
| 4.0 | 0.403 | 0.544 | 0.648 | 0.553 | 0.486 | 0.587 | 0.8790 | 0.8998 | |
| Trailer | 0.5 | 0.004 | 0.071 | 0.021 | 0.000 | 0.040 | 0.164 | 0.1316 | 0.1073 |
| 1.0 | 0.106 | 0.301 | 0.205 | 0.085 | 0.286 | 0.464 | 0.4203 | 0.4089 | |
| 2.0 | 0.353 | 0.484 | 0.584 | 0.375 | 0.531 | 0.646 | 0.5798 | 0.5867 | |
| 4.0 | 0.471 | 0.537 | 0.772 | 0.602 | 0.633 | 0.709 | 0.6705 | 0.6849 | |
| Barrier | 0.5 | 0.091 | 0.257 | 0.365 | 0.268 | 0.407 | 0.495 | 0.5675 | 0.6044 |
| 1.0 | 0.383 | 0.507 | 0.614 | 0.544 | 0.613 | 0.670 | 0.6699 | 0.7014 | |
| 2.0 | 0.506 | 0.623 | 0.738 | 0.690 | 0.675 | 0.724 | 0.7125 | 0.7417 | |
| 4.0 | 0.574 | 0.661 | 0.781 | 0.742 | 0.713 | 0.747 | 0.7279 | 0.7547 | |
| Motorcycle | 0.5 | 0.171 | 0.308 | 0.165 | 0.113 | 0.325 | 0.460 | 0.5822 | 0.6173 |
| 1.0 | 0.285 | 0.376 | 0.427 | 0.339 | 0.433 | 0.521 | 0.7051 | 0.7565 | |
| 2.0 | 0.313 | 0.392 | 0.617 | 0.524 | 0.447 | 0.532 | 0.7214 | 0.7732 | |
| 4.0 | 0.327 | 0.396 | 0.708 | 0.612 | 0.457 | 0.535 | 0.7310 | 0.7870 | |
| Traffic cone | 0.5 | 0.210 | 0.440 | 0.449 | 0.326 | 0.555 | 0.609 | 0.7462 | 0.7641 |
| 1.0 | 0.289 | 0.457 | 0.698 | 0.581 | 0.608 | 0.619 | 0.7594 | 0.7754 | |
| 2.0 | 0.334 | 0.480 | 0.810 | 0.726 | 0.640 | 0.630 | 0.7784 | 0.7934 | |
| 4.0 | 0.399 | 0.535 | 0.855 | 0.788 | 0.693 | 0.659 | 0.8095 | 0.8166 |
| Method | Ego-Warp | FeatureAlign | ConvLSTM | NDS | mAP |
|---|---|---|---|---|---|
| A: BEVFusion Baseline | — | — | — | 0.6817 | 0.6384 |
| B: +History w/o ego-warp | × | √ | √ | 0.6742 | 0.6392 |
| C: ego-warp only | √ | × | × | 0.6808 | 0.6474 |
| D: ego-warp + FeatureAlign | √ | √ | × | 0.6809 | 0.6467 |
| E: w/o FeatureAlign | × | × | √ | 0.6892 | 0.6549 |
| F: CamT-BEV (Ours) | √ | √ | √ |
| METHOD | Params (M) | Weight Size (MB) | Peak VRAM (GB) | Latency (ms) | FPS (4060Ti) | FPS (H100) |
|---|---|---|---|---|---|---|
| BEVFusion | 40.80 | 475 | 4.89 | 321.08 | 3.1145 | 6.9 |
| CamT-BEV | 41.26 | 475 | 4.89 | 325.33 | 3.0738 | 6.9 |
| Improvement | +0.46 | 0.00 | 0.00 | +4.25 | 0.00 |
| METHOD | NDS | mAP | Car | Bicycle | Pedes | Truck | Con.V | Bus | Trailer | Barrier | Motor | Tra.C |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| BEVFusion () | 0.6817 | 0.6381 | 0.8811 | 0.4546 | 0.8642 | 0.5981 | 0.2731 | 0.7316 | 0.4506 | 0.6695 | 0.6849 | 0.7734 |
| CamT-BEV () | 0.6860 | 0.6493 | 0.8868 | 0.5171 | 0.8714 | 0.5999 | 0.2669 | 0.7359 | 0.4393 | 0.6835 | 0.7089 | 0.7830 |
| CamT-BEV () | 0.6971 | 0.6683 | 0.8896 | 0.5822 | 0.8757 | 0.6079 | 0.2916 | 0.7671 | 0.4470 | 0.7006 | 0.7335 | 0.7874 |
| Improvement ( vs. ) | +0.0154 | +0.0302 | +0.0085 | +0.1276 | +0.0115 | +0.0098 | +0.0185 | +0.0355 | −0.0036 | +0.0311 | +0.0486 | +0.0140 |
| METHOD | NDS | mAP | Car | Bicycle | Pedes | Truck | Con.V | Bus | Trailer | Barrier | Motor | Tra.C |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| BEVFusion | 0.6765 | 0.6296 | 0.8717 | 0.4415 | 0.8563 | 0.5916 | 0.2726 | 0.7247 | 0.4432 | 0.6642 | 0.6662 | 0.7645 |
| CamT-BEV | 0.6933 | 0.6623 | 0.8816 | 0.5761 | 0.8693 | 0.6040 | 0.2900 | 0.7592 | 0.4464 | 0.6968 | 0.7191 | 0.7806 |
| Improvement | +0.0168 | +0.0327 | +0.0099 | +0.1346 | +0.0130 | +0.0124 | +0.0174 | +0.0345 | +0.0032 | +0.0326 | +0.0529 | +0.0161 |
| METHOD | NDS | mAP | Car | Bicycle | Pedes | Truck | Con.V | Bus | Trailer | Barrier | Motor | Tra.C |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| BEVFusion | 0.6737 | 0.6254 | 0.8615 | 0.4379 | 0.8536 | 0.5836 | 0.2628 | 0.7150 | 0.4383 | 0.6754 | 0.6561 | 0.7704 |
| CamT-BEV | 0.6909 | 0.6578 | 0.8762 | 0.5659 | 0.8671 | 0.6034 | 0.2793 | 0.7507 | 0.4454 | 0.7001 | 0.7055 | 0.7845 |
| Improvement | +0.0172 | +0.0324 | +0.0147 | +0.1280 | +0.0135 | +0.0198 | +0.0165 | +0.0357 | +0.0071 | +0.0247 | +0.0494 | +0.0141 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Zhang, N.; Guerra, E.; Grau, A. Ego-Motion-Aware Temporal Fusion in BEV Space for Multi-Modal 3D Object Detection. Electronics 2026, 15, 4200. https://doi.org/10.3390/electronics15184200
Zhang N, Guerra E, Grau A. Ego-Motion-Aware Temporal Fusion in BEV Space for Multi-Modal 3D Object Detection. Electronics. 2026; 15(18):4200. https://doi.org/10.3390/electronics15184200
Chicago/Turabian StyleZhang, Na, Edmundo Guerra, and Antoni Grau. 2026. "Ego-Motion-Aware Temporal Fusion in BEV Space for Multi-Modal 3D Object Detection" Electronics 15, no. 18: 4200. https://doi.org/10.3390/electronics15184200
APA StyleZhang, N., Guerra, E., & Grau, A. (2026). Ego-Motion-Aware Temporal Fusion in BEV Space for Multi-Modal 3D Object Detection. Electronics, 15(18), 4200. https://doi.org/10.3390/electronics15184200