


Abstract
The core driver of enterprise operations is data, making data lineage crucial for data management. It not only tracks data flow but also links data sources, workflows, applications, and decision-making, improving efficiency and governance. However, current data lineage parsing methods face challenges like high costs, long development cycles, and poor generalization, especially for non-SQL scripts. In this paper, we introduce an innovative approach leveraging pre-trained large language models (LLMs) to overcome these bottlenecks in data lineage parsing. LLMs are employed across the entire parsing pipeline, encompassing prompt construction, lineage extraction, and result standardization. Specifically, this study developed a few-shot prompting method incorporating error cases to optimize parsing performance across various types of scripts. Additionally, a collaborative Chain of Thought (CoT) and multi-expert prompting framework was designed to further enhance parsing accuracy at the operator level. The proposed approach was empirically validated using LLMs of different parameter scales on datasets comprising multiple script types (SQL, Python, Shell, Flume, etc.). The experimental results show that LLMs with 10 billion and 100 billion parameters achieved over 95% accuracy in table-level lineage parsing when utilizing the newly designed prompts. Furthermore, 100-billion-parameter LLMs exhibited substantial accuracy improvements at the operator level. Our method reinforces the feasibility and practicality in advancing data lineage parsing methodologies.
1. Introduction
With the rapid and pervasive advancement of digitalization across industries, enterprise operations have increasingly relied on crucial, competitive data assets. The exponential growth in data generation across various domains necessitates its transformation into structured data assets through processing and analysis, underscoring the critical role of data lineage in operational efficiency and governance. Data lineage, the focus of our research, refers to the detailed trail that data follow as they navigate through an array of systems and processes. It serves as an indispensable cornerstone for accurately discerning data origin, maintaining high-quality data, and enabling comprehensive auditing. In the domain of data lineage parsing, numerous research efforts have been dedicated to developing innovative solutions. For instance, Michael Backes et al. introduced the LIME framework, a pioneering solution for tracking data flow across multiple entities, which set a benchmark for data lineage research [1]. Similarly, Mingjie Tang et al. proposed the SAC system, a groundbreaking approach for data lineage tracking on distributed computing platforms such as Spark, which has been widely adopted in big data ecosystems [2]. These contributions have laid a solid foundation for contemporary data lineage solutions, which can be broadly categorized into embedded and parsed lineage acquisition techniques.
Embedded lineage acquisition involves integrating plug-ins or hooks into the underlying architecture of computation engines or databases to automatically capture data lineage during execution. This approach leverages the inherent capabilities of modern data processing frameworks to seamlessly extract lineage information without significant overhead [3]. For example, the Spark big data processing framework, renowned for its scalability and performance, allows the seamless deployment of external plug-ins to effectively capture lineage information during task execution. A notable case in point is the DataHub-based metadata lineage management solution, which ingests extensive datasets into a database and maintains direct upstream/downstream table correlations in memory. This architecture enables efficient lineage retrieval through the recursive traversal of dependent tables, facilitating the rapid construction of a comprehensive lineage tree. Such solutions are particularly advantageous in environments where real-time lineage tracking is essential for operational decision-making and compliance. Conversely, parsed lineage acquisition delves into metadata, system logs, and other key information sources to extract implicit lineage relationships that are not explicitly captured during execution. This approach often involves sophisticated algorithms and tools to reconstruct lineage logic from disparate data sources [4]. Solutions based on Neo4j graph databases, for instance, enable lineage modifications via RESTful APIs, allowing specialized algorithms to process lineage parsing independently. Additionally, by deeply analyzing Spark’s event logs, it is possible to reconstruct lineage logic for task execution, providing valuable insights into data flow and dependencies. These techniques are particularly useful in scenarios where embedded lineage acquisition is not feasible or historical lineage reconstruction is required.
While these solutions offer improved accuracy and update efficiency, they still present considerable challenges. Firstly, they entail high costs and lengthy development cycles for customization. Enterprises with specific business requirements often require extensive system modifications, involving a deep understanding of intricate business logic, restructuring, and significant architectural adjustments [5]. These modifications inevitably escalate costs and extend the development timeline, making it difficult for organizations to achieve timely implementation [6]. Additionally, ongoing adjustments necessitated by evolving business demand further prolong the implementation cycle, potentially resulting in lost market opportunities and reduced competitive advantage. Secondly, existing approaches suffer from limited generalization capabilities, particularly when dealing with diverse scripting environments. While SQL, with its well-structured syntax, is relatively straightforward to parse, non-SQL languages such as Python and Shell pose substantial challenges due to their flexibility and complexity. Scripts in these languages often incorporate complex logical structures, nested function calls, and dynamic runtime behaviors, requiring precise syntactic understanding and adaptability. The inability of current tools to effectively handle these variations significantly restricts their applicability across diverse scripting environments, limiting their utility in modern data ecosystems [7].
In recent years, the field of artificial intelligence has witnessed a surge in the adoption of large language models (LLMs), which have demonstrated promising potential for addressing the challenges of data lineage parsing. LLMs, with their ability to process and generate human-like text, have shown remarkable capabilities to understand and infer complex relationships within data. Particularly in the context of few-shot prompting, pre-trained LLMs exhibit exceptional proficiency in discerning intricate correlations and data flow pathways under conditions of limited information. By leveraging advanced prompt engineering techniques—such as structured querying, guided inference, and scientific prompting—LLMs can generate more human-aligned outputs, bridging the gap between machine-generated and human-interpretable lineage information [8]. The incorporation of methodologies such as Chain of Thought (CoT) has further enhanced the logical inference capabilities of LLMs, proving beneficial for complex task decomposition in AI agent scenarios [9]. For example, in the GSM8K dataset, CoT-based prompting with only eight examples yielded superior results compared to full dataset fine-tuning [10], reinforcing the effectiveness of CoT techniques in reasoning tasks. Moreover, CoT improves the interpretability of model outputs by offering step-by-step inferences, enhancing credibility in lineage parsing and making the results more transparent and actionable [11]. Various refinements, such as Least-to-Most [12], Self-Consistency [13], and Diverse prompting [14], have been proposed to strengthen LLM inference performance, further expanding their applicability in data lineage parsing.
In this paper, we introduce an innovative approach leveraging pre-trained LLMs for data lineage parsing, systematically addressing the limitations of existing methodologies. Through comparative analytics, empirical research, and advanced modeling techniques, we aim to reduce customization costs, expedite development cycles, and enhance the generalizability of parsing solutions. Notably, this approach is designed to tackle the inherent complexities of non-SQL script parsing, thereby advancing data management frameworks and enabling more robust and scalable lineage tracking. The findings offer valuable insights for industry practitioners, including data engineers and governance teams, by providing efficient, scalable tools to enhance workflow automation and improve data governance practices. Furthermore, this research contributes novel interdisciplinary perspectives at the intersection of artificial intelligence and data management, fostering technological advancements in enterprise data governance. The proposed methodology and experimental results provide a valuable reference for researchers and practitioners in data lineage parsing and optimized data management, ultimately driving improvements in enterprise data governance and the broader technological landscape. By addressing the challenges of high customization costs, limited generalization, and complex script parsing, this study paves the way for more efficient and effective data lineage solutions and enables organizations to harness the full potential of their data assets in an increasingly digital world.
2. Related Work
2.1. Concepts and Applications of Data Lineage
In the era of big data, applications are designed to transform raw data into valuable insights through a series of sophisticated transformation processes [15]. These processes are critical for extracting meaningful information from vast and unstructured datasets. During this conversion, data sequentially undergoes essential steps such as cleaning, integration, decomposition, and in-depth analysis. Raw data from upstream sources is processed and refined to evolve into application-specific, on-demand datasets. This transformation forms a structured data processing chain, like a human lineage tree, which meticulously records the entire lifecycle of data from its generation to processing and conversion. This structured process is referred to as data lineage [16]. Data lineage, therefore, serves as a comprehensive map that traces the journey of data through various stages, ensuring that its origins, transformations, and final usages are well-documented and transparent.
In the context of data governance, data lineage plays a crucial role in documenting relationships between data assets. It captures the origin, transmission, transformation, and derivation [17] of data resources while ensuring transparency and traceability. By maintaining a historical and factual perspective, data lineage establishes a structured data transmission chain that enhances both credibility and traceability. This is particularly important in environments where data integrity and accountability are paramount, such as in regulatory compliance and audit scenarios. Data lineage provides a clear and unambiguous record of how data has been manipulated, which is essential for verifying the accuracy and reliability of data-driven decisions.
The vast applications span multiple domains to address specific challenges. In the energy sector, for instance, data lineage facilitates data asset valuation by evaluating lineage relationships between tables and fields during data import, export, and processing across data warehouses. This approach enables the development of asset valuation models for power grids using predefined assessment indexes and weights [18]. By understanding the lineage of data, energy companies can better assess the value of their data assets and make informed decisions about data management and utilization.
In civil aviation, dynamic lineage monitoring allows the real-time visualization of data sources, processing workflows, and data flows, thereby enabling the continuous tracking and monitoring of aviation data through dynamic architecture-level data lineage maps [19]. This capability is crucial for ensuring the safety and efficiency of aviation operations as it allows for the real-time identification and resolution of data-related issues. By providing a clear view of how data flow through the system, dynamic lineage monitoring helps aviation authorities maintain high standards of data quality and reliability.
In financial and security regulation, metadata lineage graphs support regulatory compliance by constructing real-time data tracking systems that facilitate impact analysis and traceability assessments for regulatory reporting [20]. Financial institutions are often required to demonstrate the provenance and integrity of their data to regulatory bodies, and data lineage provides the necessary framework. By enabling real-time track and impact analysis, metadata lineage graphs help financial institutions meet regulatory requirements more efficiently and effectively.
2.2. Large Language Models (LLMs)
AI research has focused on large language models (LLMs), which significantly improve performance and generalization in multiple domains. By integrating extensive datasets, sophisticated algorithms, and advanced computing power, LLMs enhance a wide range of downstream applications. These models achieve remarkable results through pre-training and fine-tuning [21], making them instrumental in tasks such as natural language processing, computer vision, and content generation. With the rapid advancement of deep learning, pre-trained LLMs have demonstrated substantial potential across various applications. Through training on large-scale datasets, these models acquire rich feature representations and optimize end-to-end learning techniques in order to facilitate accurate predictions, even with limited data [22].
LLMs offer exceptional adaptability by deeply understanding and dynamically responding to complex environments [23]. This adaptability is particularly valuable in scenarios where traditional models struggle to generalize across diverse datasets or tasks. Several recent studies highlight the growing applications of LLMs in various fields. In sentiment analysis and data augmentation, Shichen Li et al. introduced a cross-domain sentiment analysis method based on LLMs and data augmentation to mitigate data scarcity and improve domain-specific learning [24]. This approach leverages the generalization capabilities of LLMs to enhance sentiment analysis in domains where labeled data are limited.
In autonomous task planning, Long Qin et al. developed AutoPlan, an LLM-powered framework designed for complex task planning and execution [25]. AutoPlan demonstrates how LLMs can be used to automate and optimize complex workflows, reducing the need for manual intervention and improving efficiency. In automatic code repair, Pengyu Xu et al. proposed an LLM-driven solution to enhance traditional code understanding and patch generation methodologies [26]. This approach leverages the natural language understanding capabilities of LLMs to improve the accuracy and efficiency of code repair, making it a valuable tool for software development and maintenance.
For data lineage parsing, researchers and practitioners employ a variety of approaches, including zero-shot and few-shot prompting, as well as fine-tuned and refined-tuned training [26]. While fine-tuning requires manually labeled datasets and hyperparameter optimization to improve prediction accuracy, zero-shot and few-shot prompting techniques enable LLMs to generalize across different script types with minimal adjustments. The latter approaches reduce computational costs and streamline deployment while maintaining broad, cross-domain applicability. This is particularly important in data lineage parsing, where the ability to generalize across different scripting languages and environments is crucial for effective lineage tracking.
We investigate the methodology and effectiveness of LLM-based data lineage parsing across various script types and granularities using few-shot prompting. By addressing key limitations in existing approaches—such as inadequate support for multiple scripting languages and insufficient operator-level lineage tracking—this research advances the field of data governance and lineage analysis. The findings of this study have the potential to significantly improve the accuracy, efficiency, and scalability of data lineage parsing, making it a valuable tool for organizations seeking to enhance their data governance practices.
3. A Large Language Model-Based Approach to Data Lineage Parsing
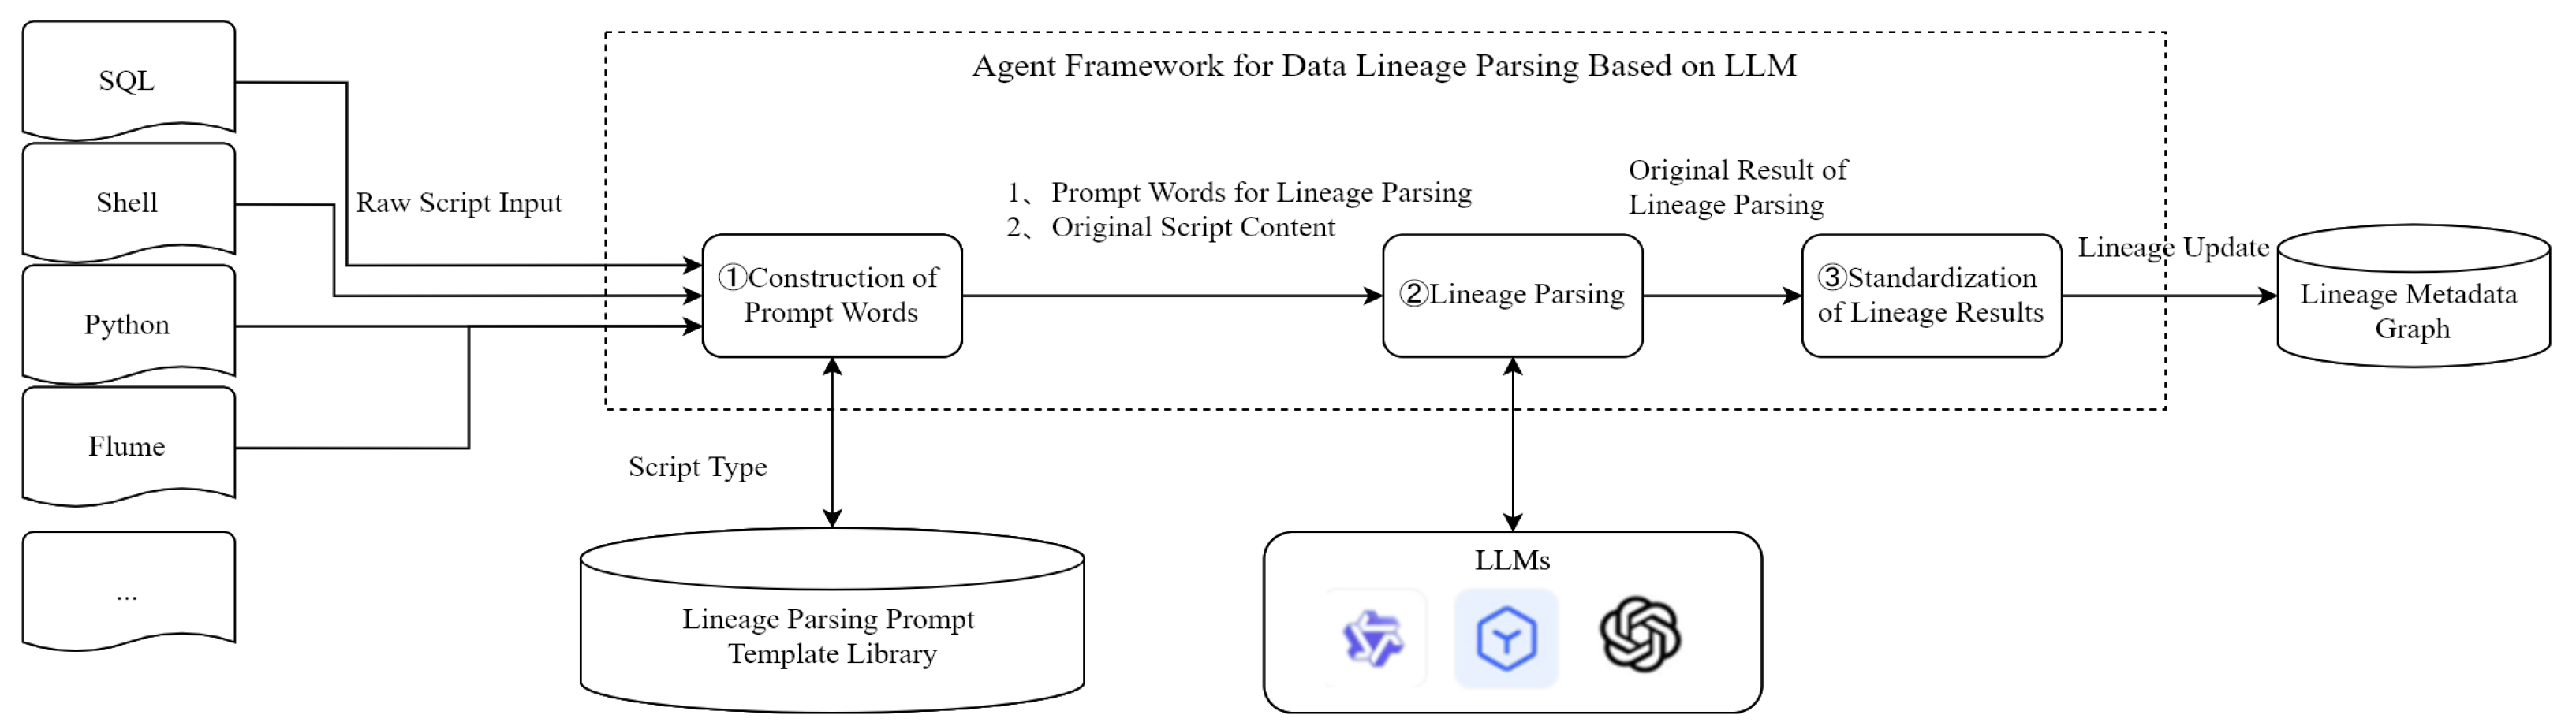
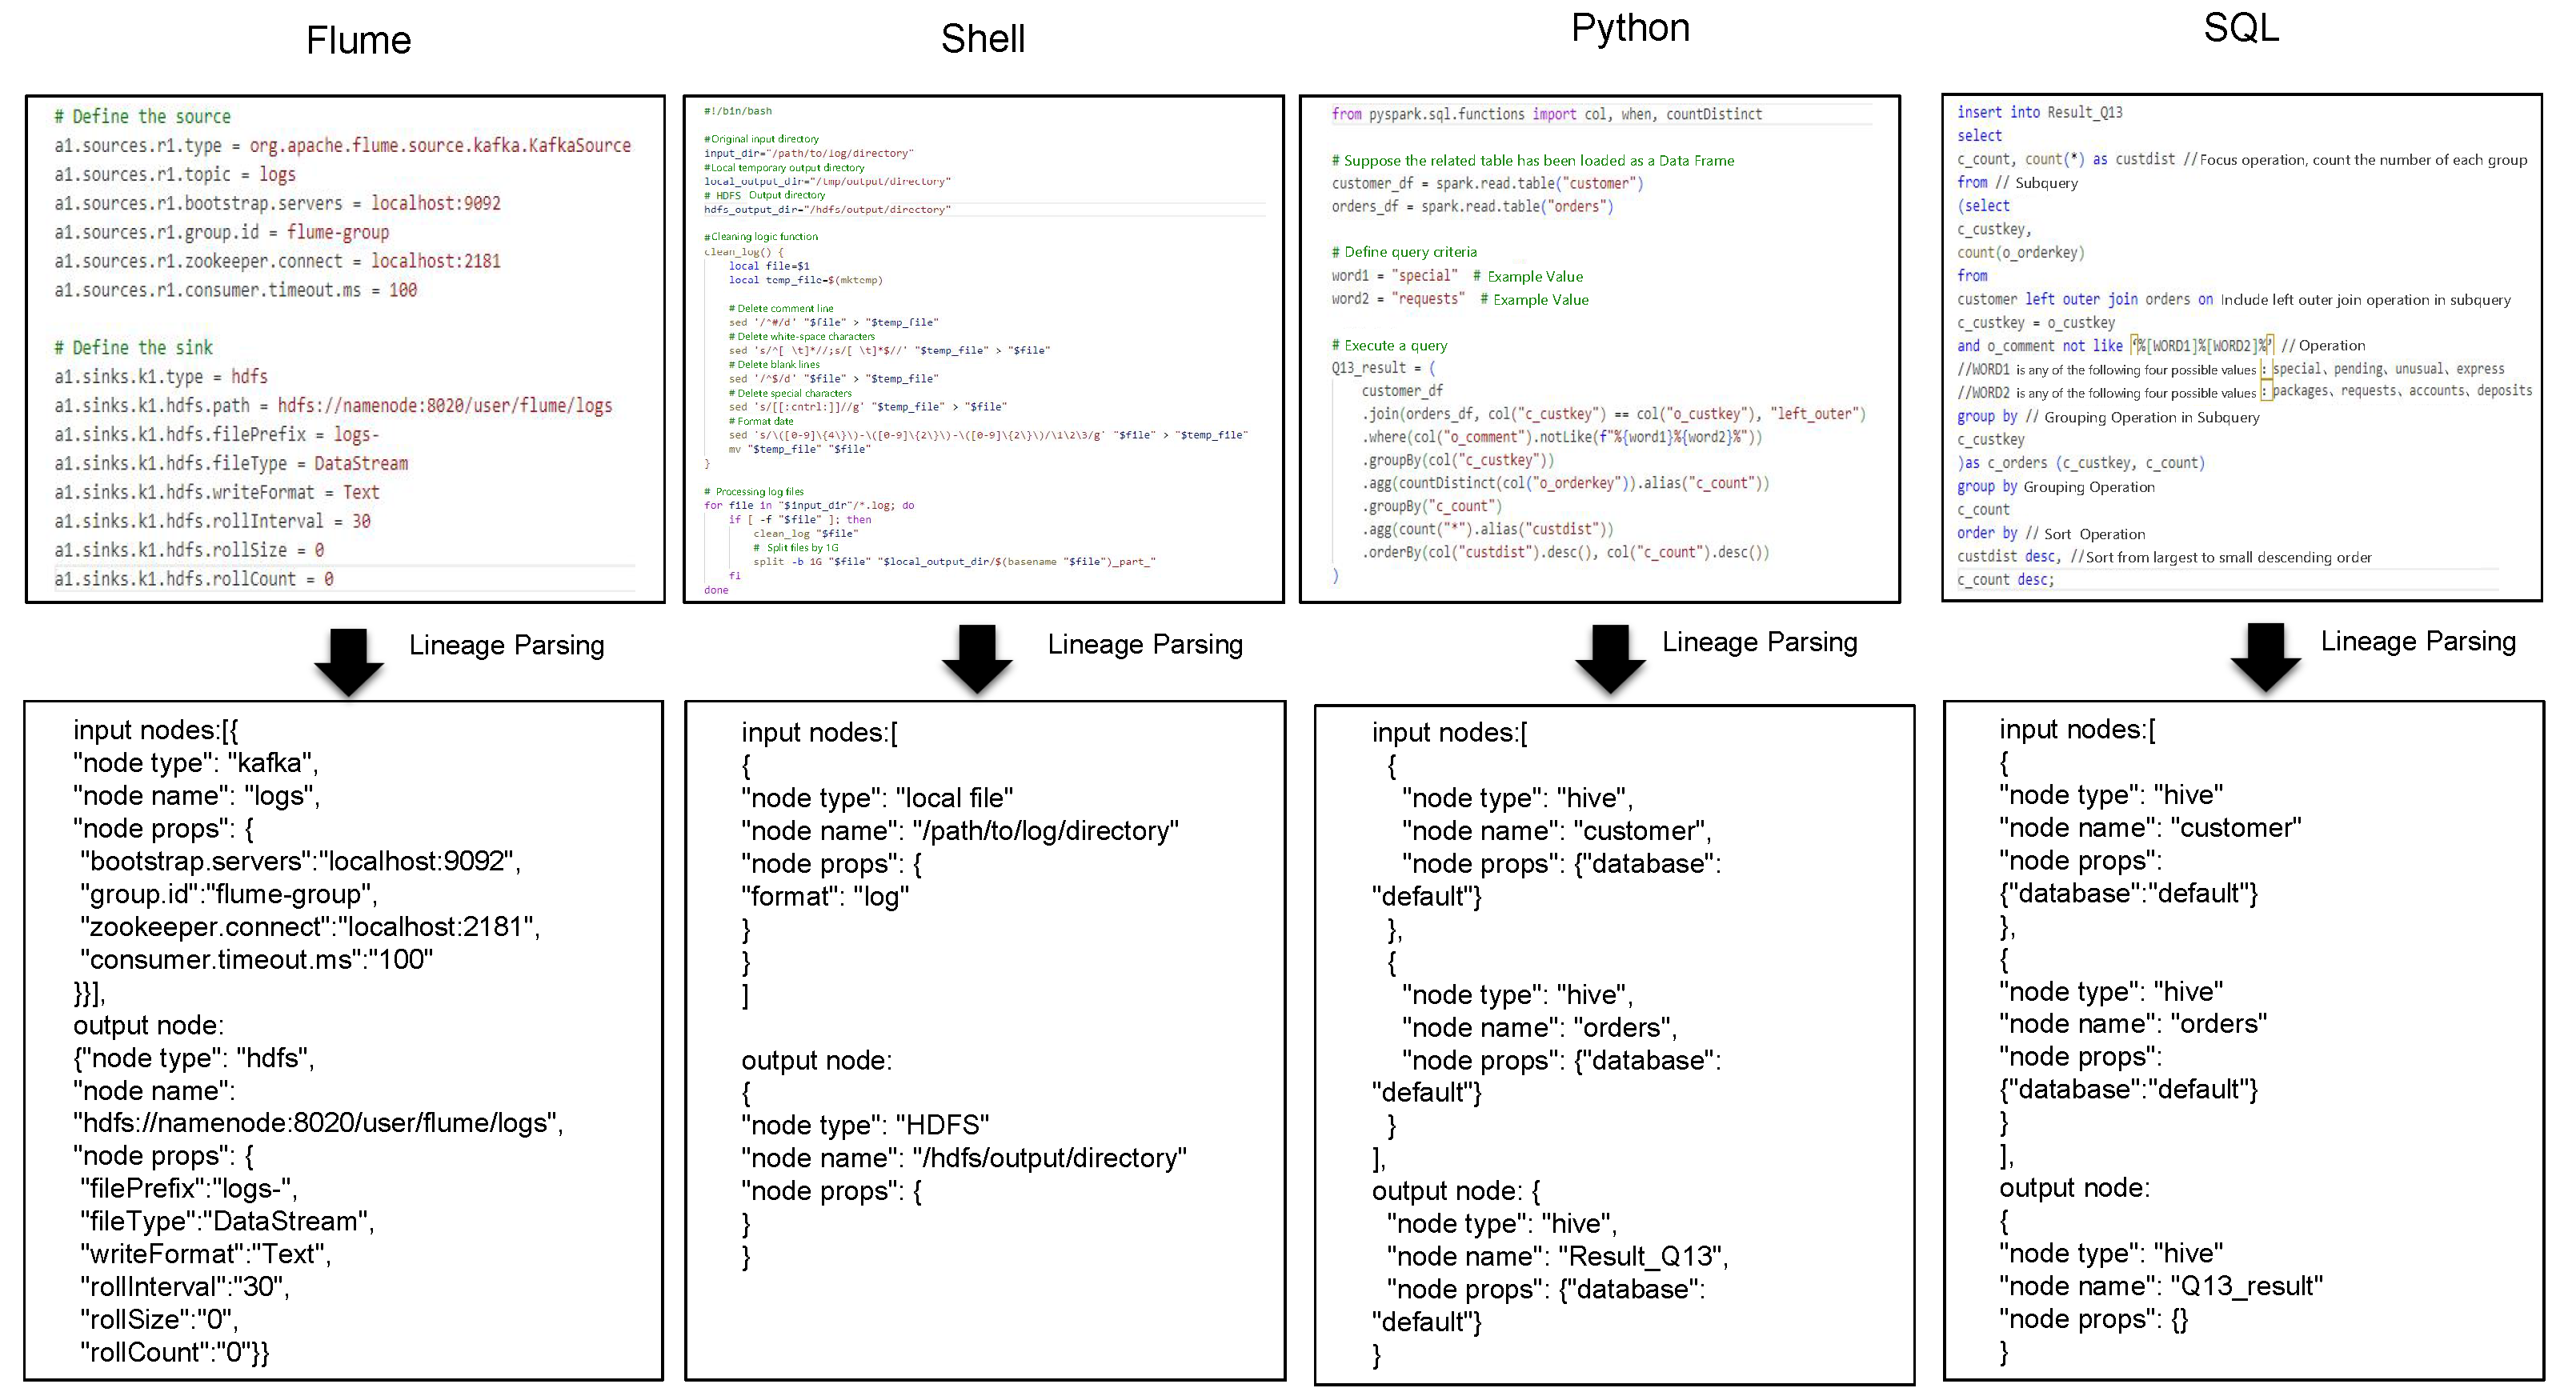
The LLM-based data lineage parsing process consists of three main stages: prompt construction, lineage parsing, and result standardization. The overall process is illustrated in Figure 1.
Figure 1.
The overall process of data lineage parsing based on LLM.
- 1.
- Prompt construction: In this stage, the system first identifies the type of task script provided by the user, including SQL scripts, Shell scripts, Python code, and Flume scripts, among others. Since each script type possesses distinct syntactic and semantic structures, predefined prompts are employed to guide the LLM in accurately interpreting and processing the input. A prompt serves as an instruction that informs the LLM on how to analyze a given script. When a specific task script is received, the system generates an appropriate input I.The function f determines the appropriate prompt based on the script type (T) and its content (C).
- 2.
- Lineage parsing: The generated input I is then fed into a pre-trained LLM , an AI system equipped with advanced natural language processing capabilities to discern complex linguistic patterns and extract relevant information. The primary objective of LLM in this stage is to conduct a comprehensive analysis of the input I, identifying data entities, their relationships, and the interconnections established through a sequence of operations. The LLM then produces a response answer A that delineates the lineage relationships between data elements, including but not limited to source tables, target tables, field mappings, and transformation logic.
- 3.
- Result standardization: After the generates response answer A, a post-processing step is applied to refine the output. This involves filtering out extraneous explanatory content and structuring the extracted data lineage information into a standardized JSON format. This standardized representation facilitates seamless data exchange and interoperability across various systems.g represents the lineage standardization functions and denotes the final standardized lineage results.
4. Prompt Design
4.1. Few-Shot Prompting with Error Cases
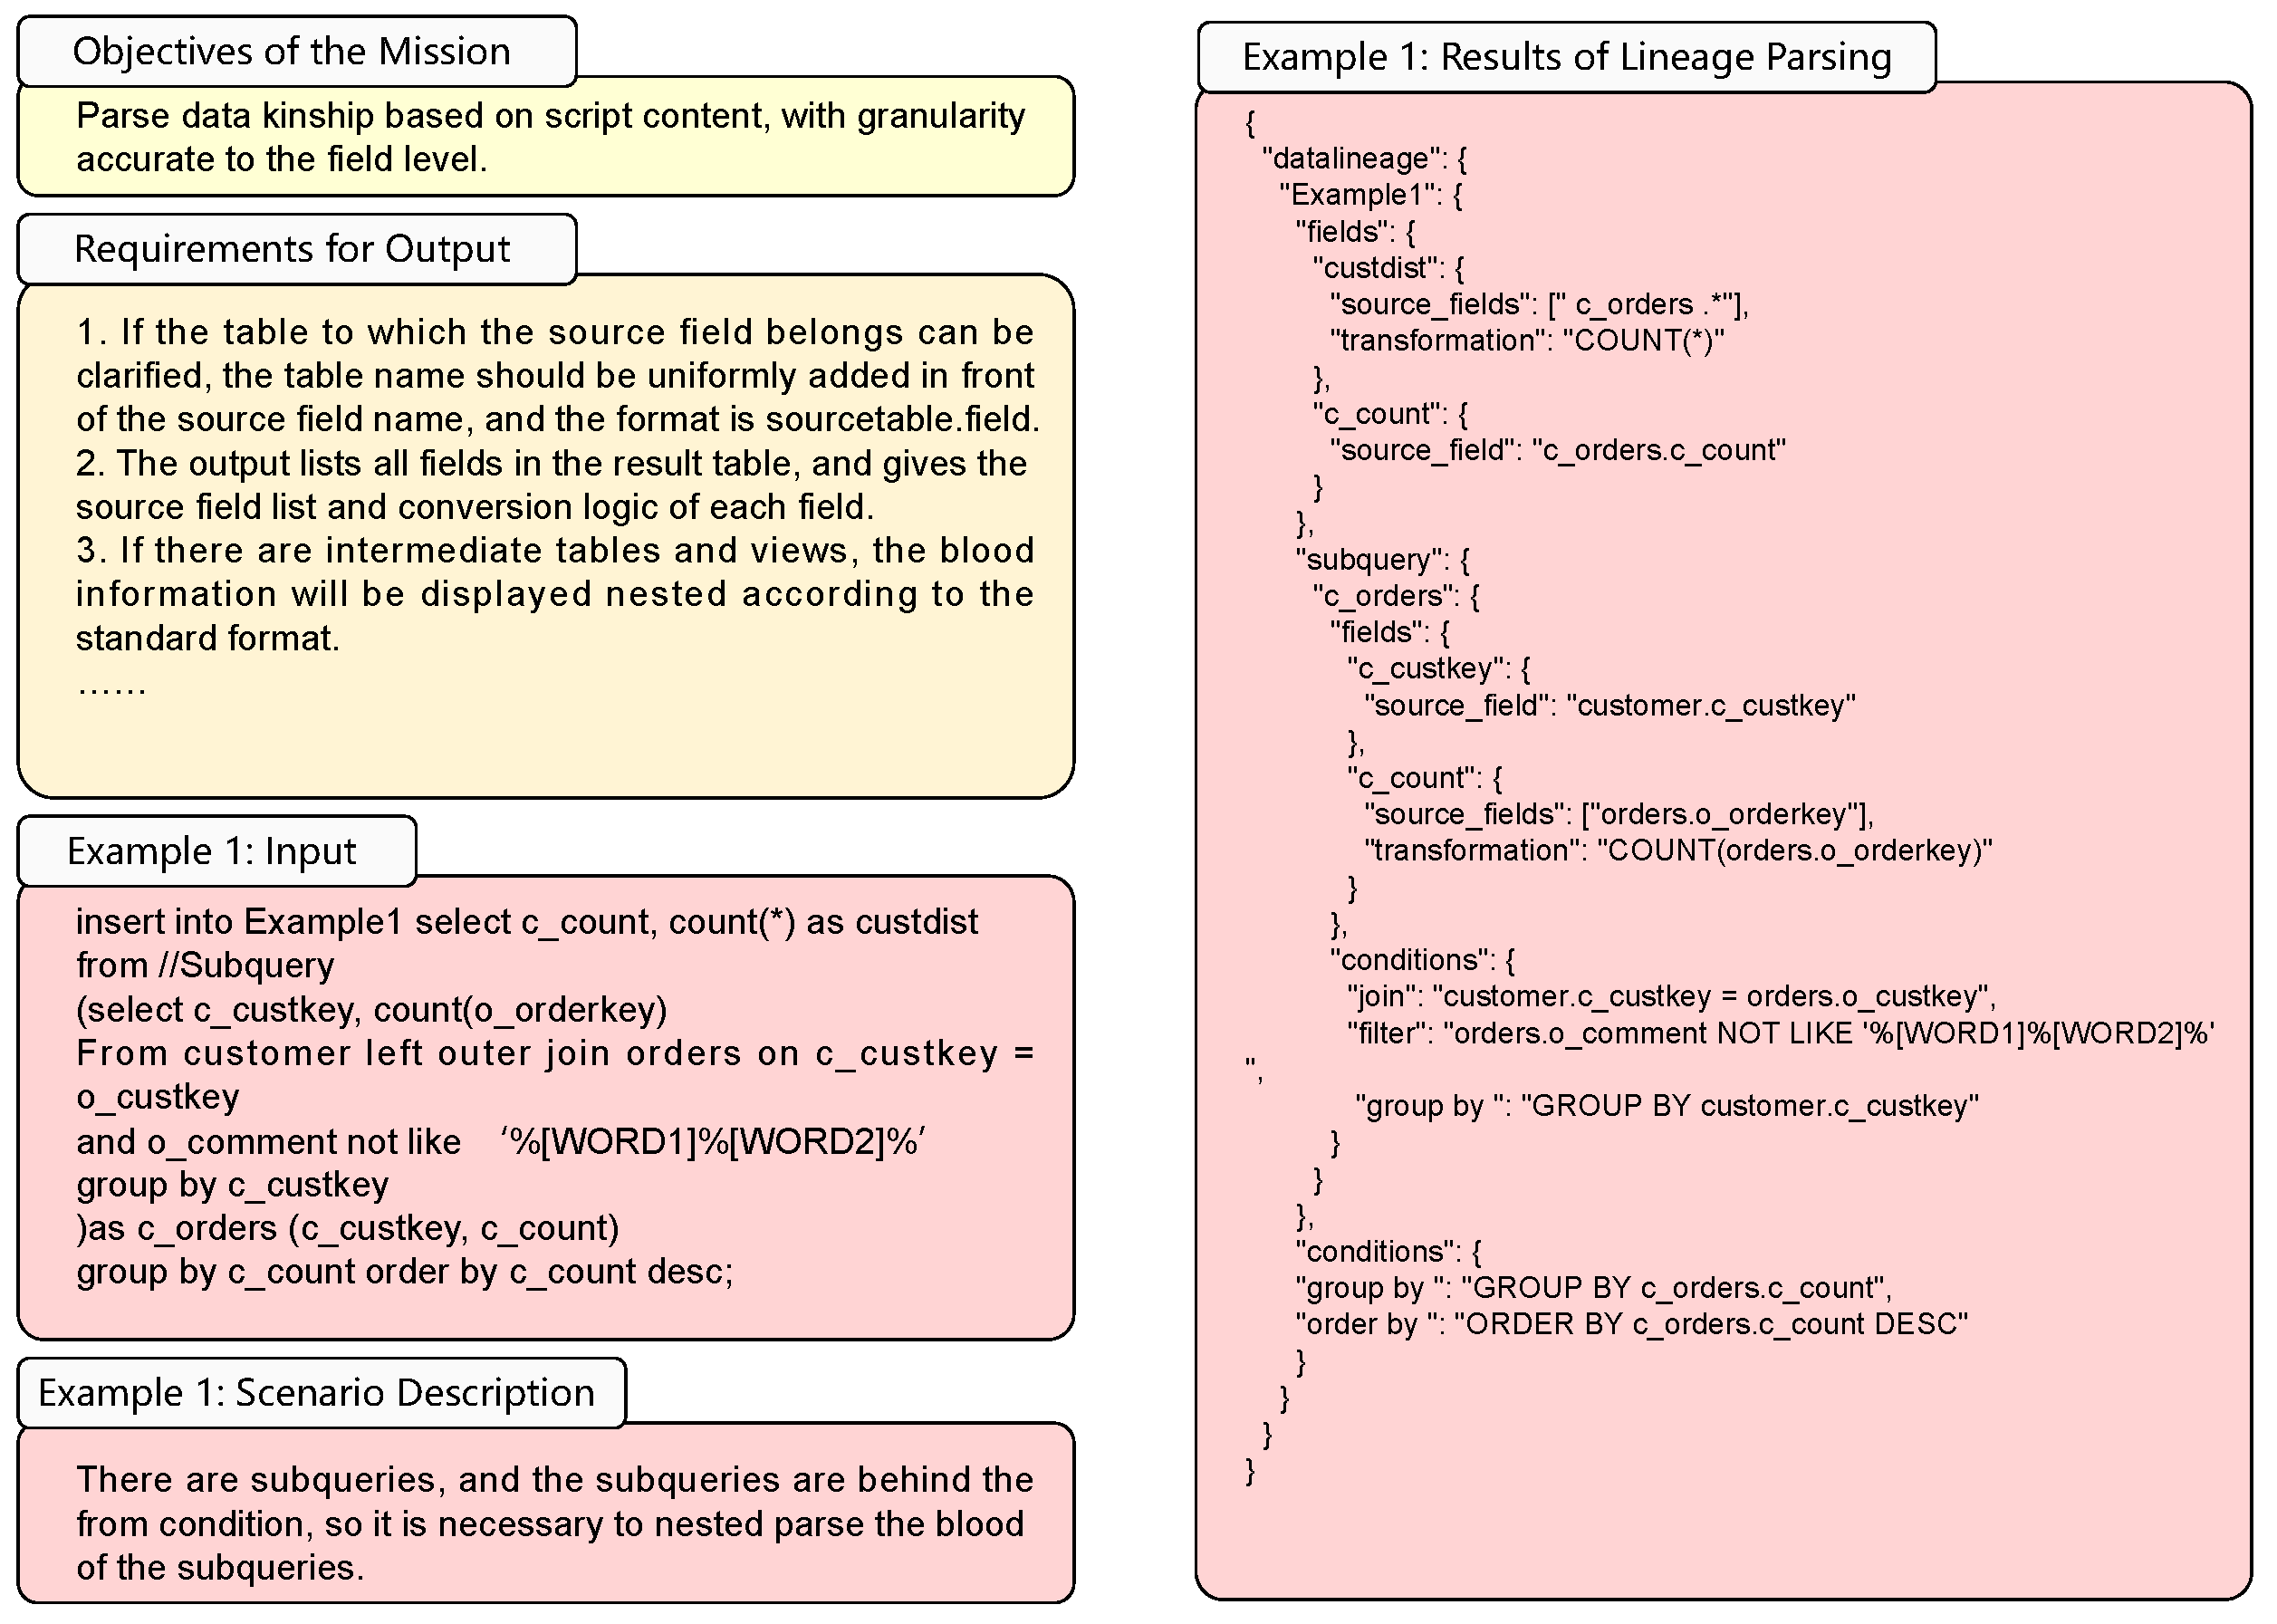
In the preliminary exploratory experiments, we found that few-shot prompting with error cases for different types of scripts could obtain more consistent lineage parsing results than zero-shot prompting and few-shot prompting. Therefore, before the batch experiment, relatively high complexity case scripts were selected for different scenarios, and a few input/output cases could be added to get the parsing results more in line with the expectation by adjusting the prompts several times. In addition, the points for the LLMs illusions and errors were highlighted in such cases. The prompts mainly included the task objectives, output requirements, and case scripts (including the original scripts, scenario characteristic descriptions, and lineage parsing results of the cases), as shown in Figure 2 below.
Figure 2.
Few-shot prompting with error cases.
The task definition established the core objective and the level of granularity required for lineage parsing. The output specification determined the expected format of the results and delineated parsing strategies for some specific scenarios, such as handling subqueries. Finally, 0 to N typical cases were provided, encompassing the original script, scenario characteristics, and expected lineage parsing output. The scenario characteristic descriptions emphasized LLM illusions and errors observed in the exploratory experiments, offering corrected examples to enhance parsing accuracy.
4.2. Chain-of-Thought and Multi-Expert Collaboration
While few-shot prompting with error cases demonstrated strong performance at the table-level granularity of lineage parsing, there remained significant room for improvement at the operator level. To address this problem, this study integrated expert prompting [27], Chain of Thought (CoT) prompting [28], and multi-expert prompting [29], adapting them to the characteristics of data lineage analysis. Thus, a novel collaborative approach is proposed that combines structured reasoning through CoT with multi-expert collaboration, enhancing LLM performance for operator-level lineage parsing.
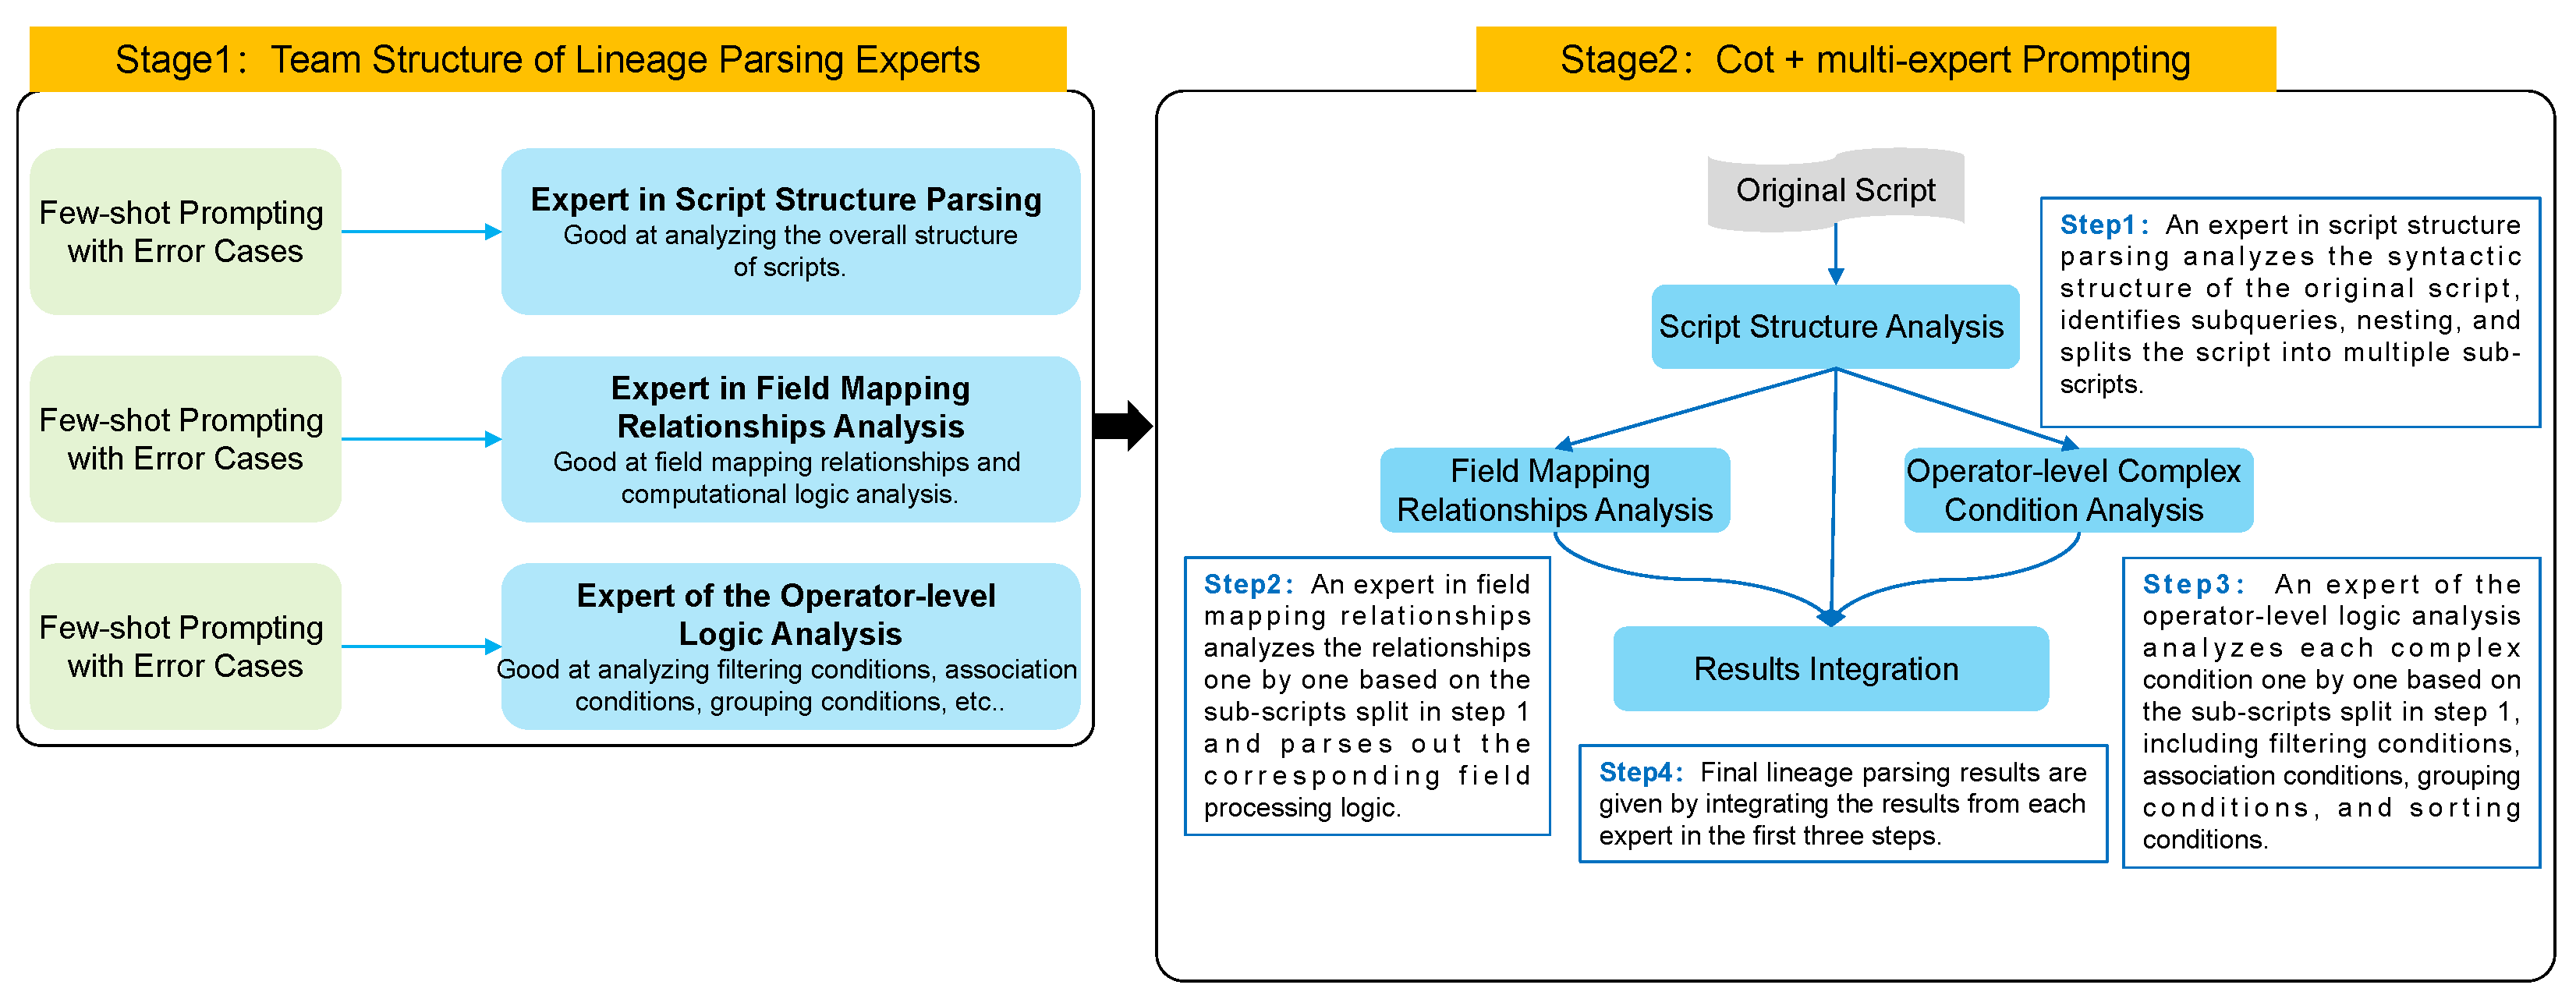
The collaborative CoT and multi-expert prompting framework consists of two primary stages: expert generation and expert collaboration with result aggregation. In the first phase, the LLM generates three specialized experts based on predefined instructions. In the second phase, these experts sequentially analyze and parse lineage information, with their outputs aggregated into a final result. The process is illustrated in Figure 3.
Figure 3.
Collaborative CoT and multi-expert prompting framework.
During the first stage, the LLM is instructed to generate three experts, denoted as {(E1, D1), (E2, D2), (E3, D3)}, each responsible for distinct tasks: script structure parsing, field mapping relationship analysis, and operator-level logic analysis. This process is formally defined as
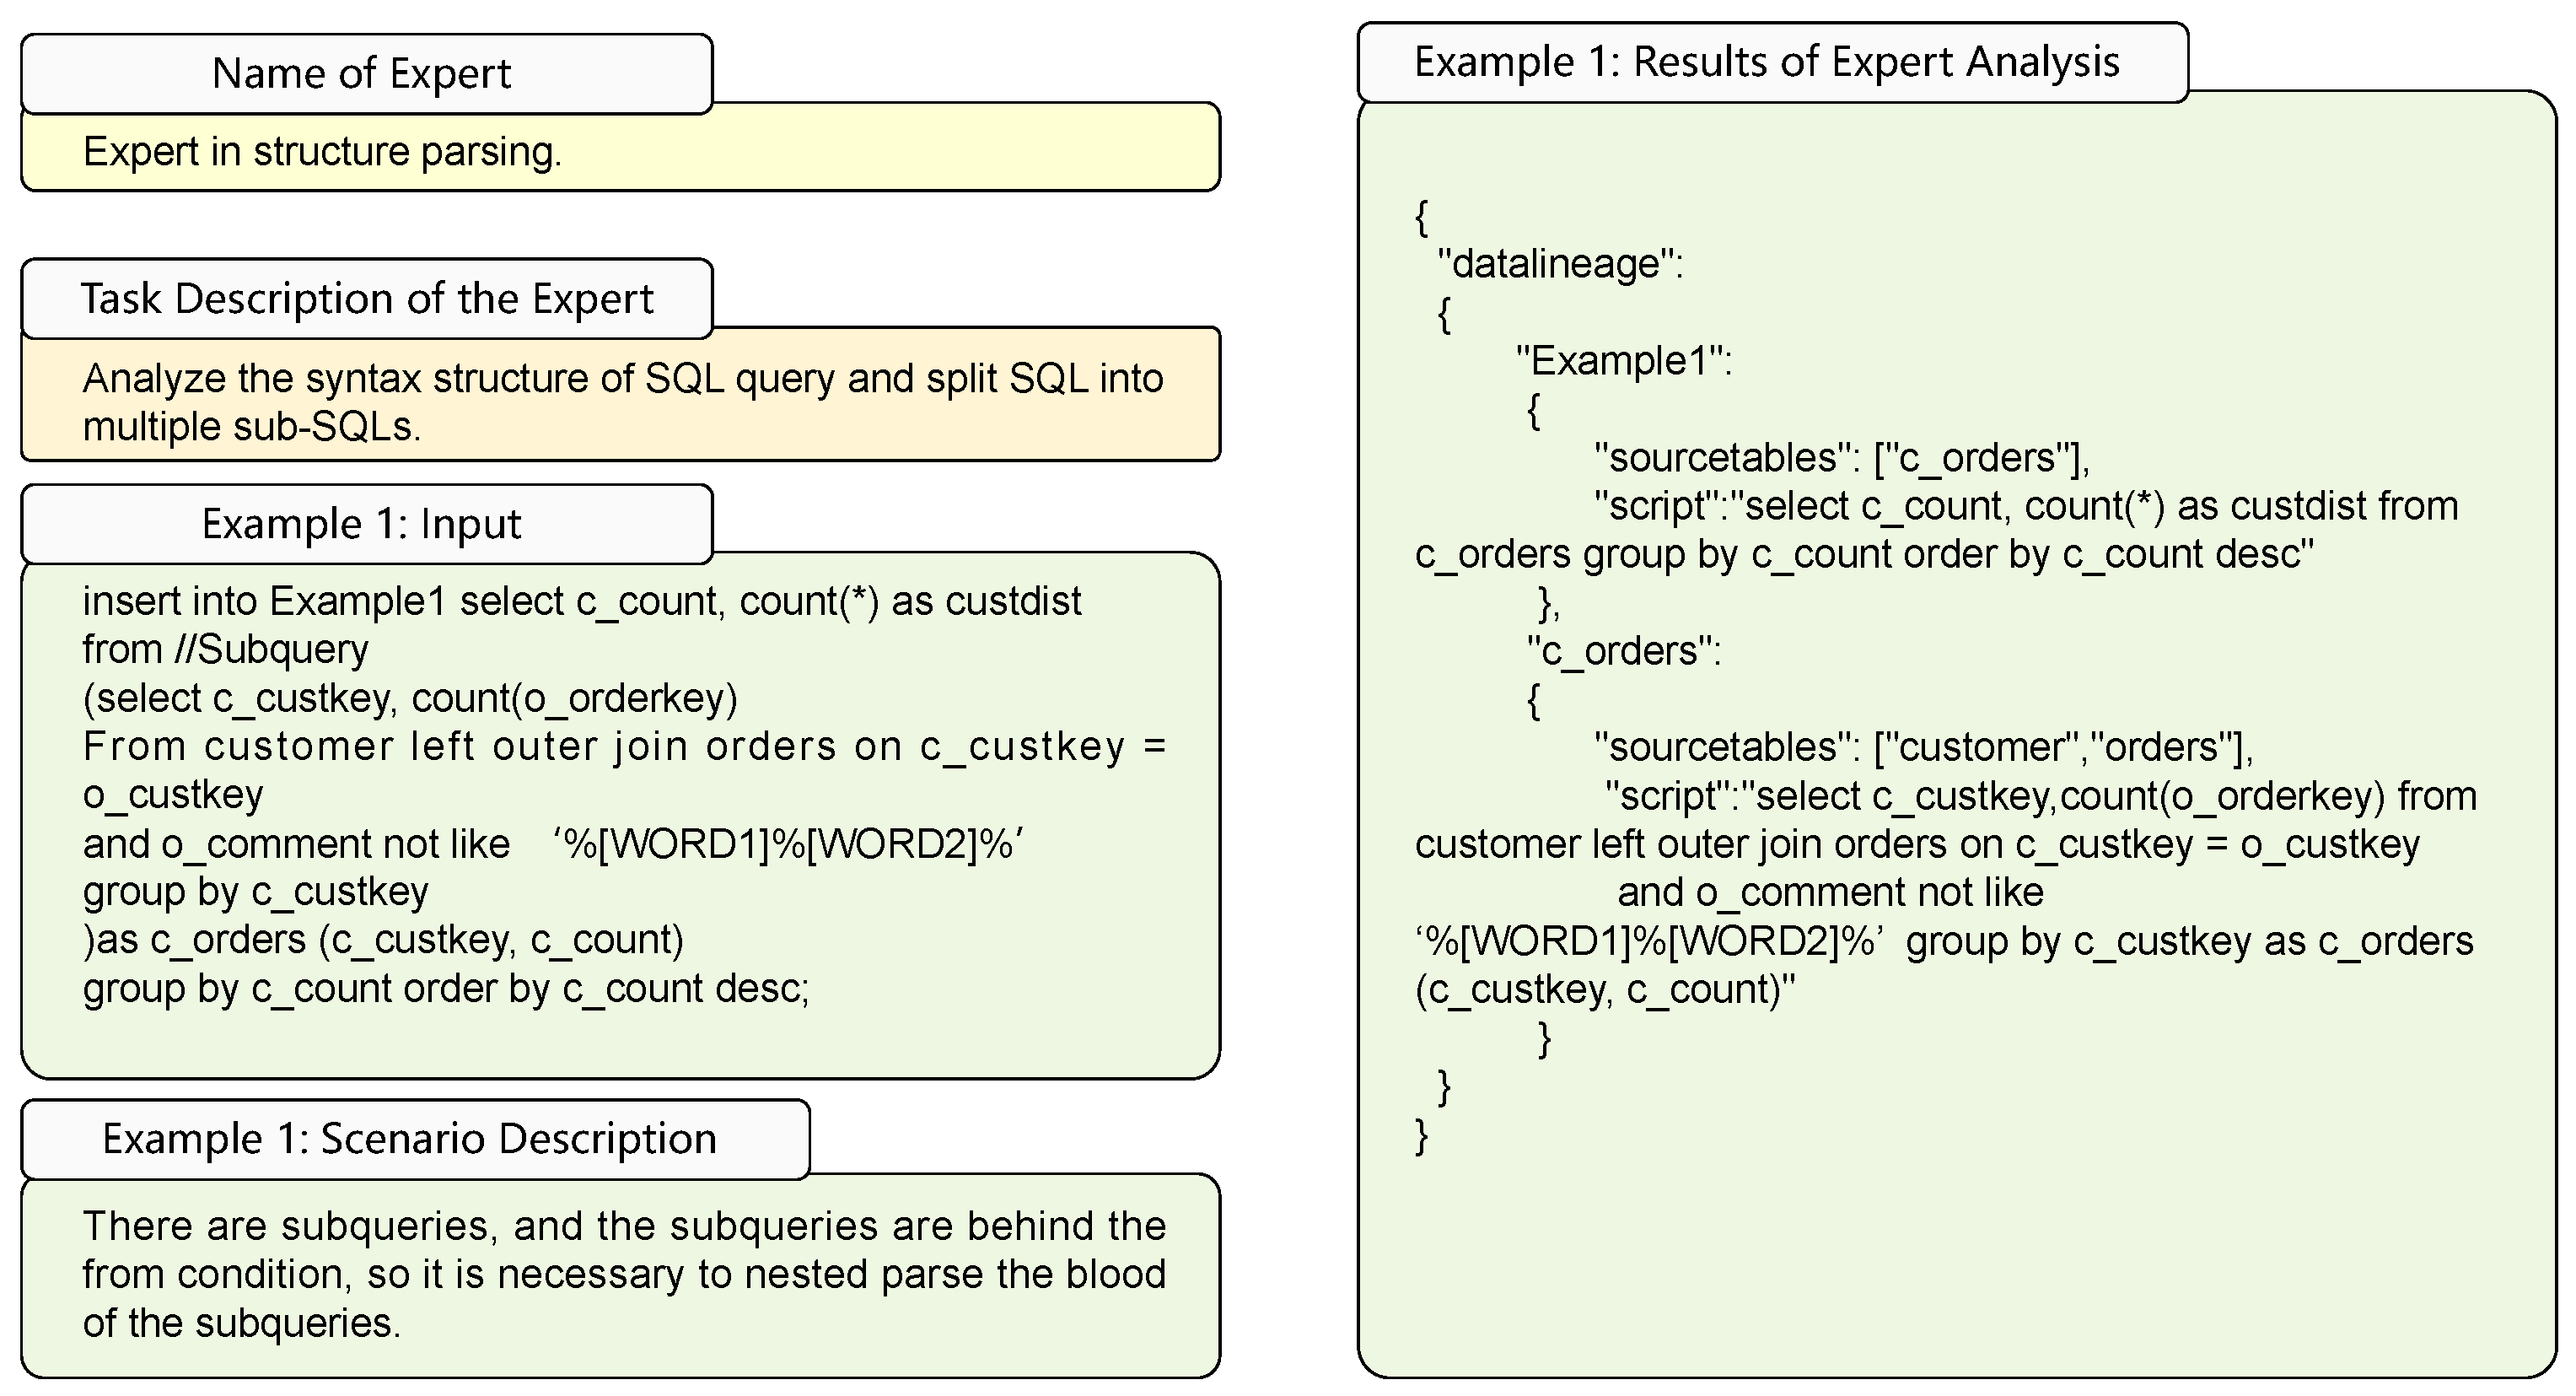
where represents the i-th expert and denotes the corresponding task description. includes generation instructions specifying the expert’s name, task definition, and few-shot prompting examples designed to optimize expert performance in specific subtasks. A sample expert prompt is depicted in Figure 4.
Figure 4.
Expert prompting sample.
In the second stage, Chain of Thought (CoT) instructions guide the large language model (LLM) to invoke multiple experts in a specified sequence for the stepwise parsing of data lineage. The intermediate results are aggregated into a final lineage analysis outcome, as formalized in Equation (5). Here, denotes the CoT prompts that orchestrate multi-expert collaboration and result aggregation, C represents the raw script content, and signifies the lineage parsing result under multi-expert coordination.
The execution of the CoT-based multi-expert collaboration method is autonomously performed step-by-step by the LLM without requiring multiple interactions. To provide an intuitive understanding of the collaborative workflow, the process is decomposed into four sequential steps, each explained below.
Step 1: The script structure parsing expert analyzes the syntactic structure of the raw script to identify subqueries and nested structures and decompose the script into multiple subscripts, as shown in Equation (6). Here, denotes the prompt for invoking Expert 1, C is the original script, and represents the i-th decomposed subscript.
Step 2: The field mapping relationship analysis expert processes each subscript from Step 1 to derive field-level mapping relationships and processing logic. This generates a collection of procedural lineage parsing results {} for n subscripts. The parsing of each subscript is formalized in Equation (7), where is the prompt for Expert 2, and denotes the i-th subscript decomposed by Expert 1.
Step 3: The operator-level logical analysis expert examines complex conditions within each subscript from Step 1, including filter conditions (e.g., those involving subqueries), join conditions, grouping conditions, and sorting conditions. This produces a collection {} of lineage parsing results for n subscripts, as formalized in Equation (8). Here, is the prompt for Expert 3 and refers to the i-th subscript from Expert 1.
Step 4: The outcomes from the preceding three steps are fused to generate the final lineage parsing result. Field mapping relationships, operator-level computational logic, and other metadata are grouped and aggregated by table/subquery, as shown in Equation (9). denotes the prompt for aggregating expert outputs, while and represent the consolidated results from Expert 2 and Expert 3, respectively.
5. Evaluation
5.1. Datasets and Evaluation Criteria
The characteristics of the data, features of the model, and business scenarios were fully taken into account and targeted strategies were formulated to ensure that there were no misjudgments in the overall experimental results. In terms of dataset selection, this paper study chose a total of five types of scripts, including SQL scripts, Python scripts, Shell scripts, and Flume configuration scripts. Regarding scenario design, this study comprehensively considered two methods: industry standards (TPC-H) and custom rules, and used large language models for synthetic expansion. TPC-H serves as a benchmark testing suite for decision support systems (DSSs), developed by the Transaction Processing Performance Council (TPC) and designed to simulate complex decision-making environments and assess the performance of database management systems (DBMSs) in executing queries and generating reports. The customized scenarios defined the input and output data sources, as well as the data processing logic. Once the scenarios were selected, the test dataset was expanded using synthetic data generated by LLMs. The datasets are presented in Table 1, with a comprehensive description of use cases provided in Appendix A.
Table 1.
Data lineage parsing of the test dataset.
The accuracy metric was used to evaluate the effectiveness of the lineage parsing by LLMs, calculated as follows:
5.2. Model Parameters
The experiments in this study did not involve the private deployment of LLMs. Instead, we directly invoked the SaaS service APIs provided by cloud service providers for LLMs, thus eliminating the need to prepare dedicated computational resources for LLMs.
The models involved in the experiments of this study are all publicly available models. In order to ensure the consistency of the model names being cited, this paper standardizes the naming criteria for the models: Model Name-Version Number-Parameter Scale. For example, Llama-3.1-405B indicates that the model name is Llama, the version number is 3.1, and the parameter scale is 405 billion.
The experiment employed four LLMs: Qwen-2-7B-Instruct (Qwen-2-7b), Llama-3.1-8B-Instruct (Llama-3.1-8b), Qwen-2-72b-instruct-gptq-int4 (Qwen-2-72b), and Llama-3.1-405B-Instruct (Llama-3.1-405b). The context length was fixed at 10K and the temperature parameter was set at 0.1. The details of these models are summarized in Table 2.
Table 2.
Experimental LLM configurations.
5.3. Compared Methods
This study employed zero-shot, one-shot, and few-shot prompting as baseline comparisons to assess improvements in lineage parsing performance. The few-shot prompting with error cases and collaborative CoT and multi-expert prompting framework were evaluated for their efficacy. In addition, to compare the performance of the LLM-based method proposed in this paper with that of traditional lineage parsing methods, an additional lineage parsing method based on the fusion of abstract syntax trees and metadata [7] was included as a comparison baseline. However, this baseline was only applicable to SQL scripts and Python scripts. The baselines of all experiments are listed in Table 3.
Table 3.
List of experimental baselines.
5.4. Results Analysis
5.4.1. Table-Level Lineage Parsing
Table-level lineage parsing captured input and output table-related information, such as table names, catalog names, and extended attributes, while ignoring mapping relationships, subqueries, and filtering conditions. The experimental framework is illustrated in Figure 5.
Figure 5.
Framework of the proposed DRL scheduling method based on PPO.
The statistical results of table-level lineage parsing are presented in Table 4 below.
Table 4.
Experimental results of table-level lineage parsing of four types of scripts.
The findings indicated that Qwen-2-72b and Llama-3.1-405B achieved over 90% accuracy in table-level lineage parsing across all four script types, even with zero-shot prompting. The one-shot and few-shot prompting techniques yielded marginal accuracy improvements of approximately 0–3%. The proposed method of few-shot with error cases enhanced accuracy by approximately 2–4% compared to the most effective baseline (B3). Specifically, Qwen-2-72b surpassed 95% accuracy across all script types, while Llama-3.1-405B achieved over 97% accuracy. The traditional data lineage parsing method based on abstract syntax trees (AST) achieved an accuracy rate of over 99% in scenarios involving SQL scripts and Python scripts, which still gives it an advantage over the LLM-based method proposed in this paper. However, it is incapable of parsing Flume scripts, Shell scripts, and others. Therefore, in terms of scenario coverage, it is slightly inferior to the method proposed in this paper.
Conversely, Llama-3.1-8B and Qwen-2-7B demonstrated poor parsing performance, with an accuracy below 50% in most cases. The primary sources of error included the misinterpretation of script content, resulting in extraneous nodes within lineage graphs, and incorrect formatting that deviated from predefined templates. Despite incremental improvements using one-shot and few-shot prompting, the overall performance of these models remained suboptimal. Consequently, further operator-level lineage experiments excluded small-scale LLMs such as Llama-3.1-8B and Qwen-2-7B.
5.4.2. Operator-Level Lineage Parsing
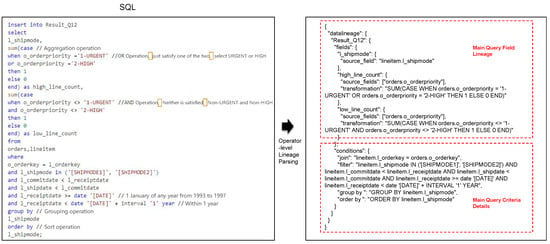
Operator-level lineage parsing extended beyond table-level parsing to include mapping relationships between fields, aggregation and mathematical computations, and detailed information such as subqueries, filtering conditions, grouping, and sorting. An example of SQL-script operator-level lineage parsing using few-shot prompting is illustrated in Figure 6.
Figure 6.
Sample results for operator-level lineage parsing.
The statistical results are summarized in Table 5 for Python and SQL script operator-level lineage parsing across different baselines.
Table 5.
Experimental results of operator-level lineage parsing.
The experimental results indicated that Qwen-2-72b achieved an accuracy below 85% across all baselines, including zero-shot, one-shot, few-shot, and few-shot with error cases. However, the proposed multi-expert with CoT significantly improved accuracy, exceeding 90% for Python and 85% for SQL, representing improvements of 5% and 10% compared to the B4 baseline, respectively. Llama-3.1-405B consistently outperformed other models, achieving nearly 90% accuracy with zero-shot prompting. The progressive improvements from B2 to B4 further increased accuracy to approximately 95%. Notably, the multi-expert with CoT approach enhanced lineage parsing accuracy to over 97% for both script types.
Taking the Llama-3.1-405B model as an example, when compared with the traditional lineage parsing method based on abstract syntax trees (AST), it can be observed that for Python scripts, the accuracy rate of the method proposed in this paper was about 1.5% lower than that of the traditional method. However, for SQL scripts, the method proposed in this paper was slightly higher than the traditional method. From the analysis of error cases, it was found that there were a small number of SQL dialects in the experimental cases. The traditional method, which did not extend its parsing rules to cover SQL dialects, failed to parse these cases. In contrast, the LLM-based method proposed in this paper still correctly parsed a significant proportion of the SQL dialect cases, resulting in an overall accuracy rate that was slightly higher than that of the traditional method.
5.4.3. Ablation Analysis
To investigate the impact of prompt strategies such as sample size, negative samples, Chain of Thought (COT), and multi-expert mechanisms on performance, additional baselines were added to the previous ones, as shown in Table 6 below.
Table 6.
Ablation study baseline experiments.
Additional operator-level lineage experiments with baselines were conducted for the Llama-3.1-405B large model, and the results are shown in Table 7 below.
Table 7.
Comparison of baseline operator-level lineage parsing results.
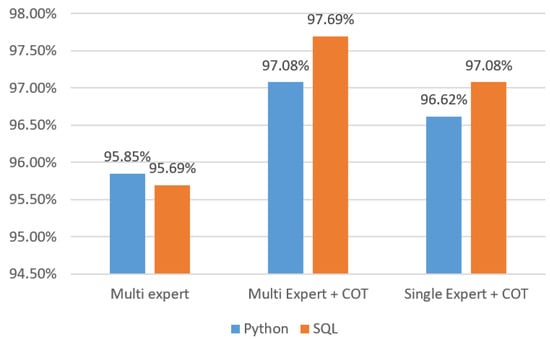
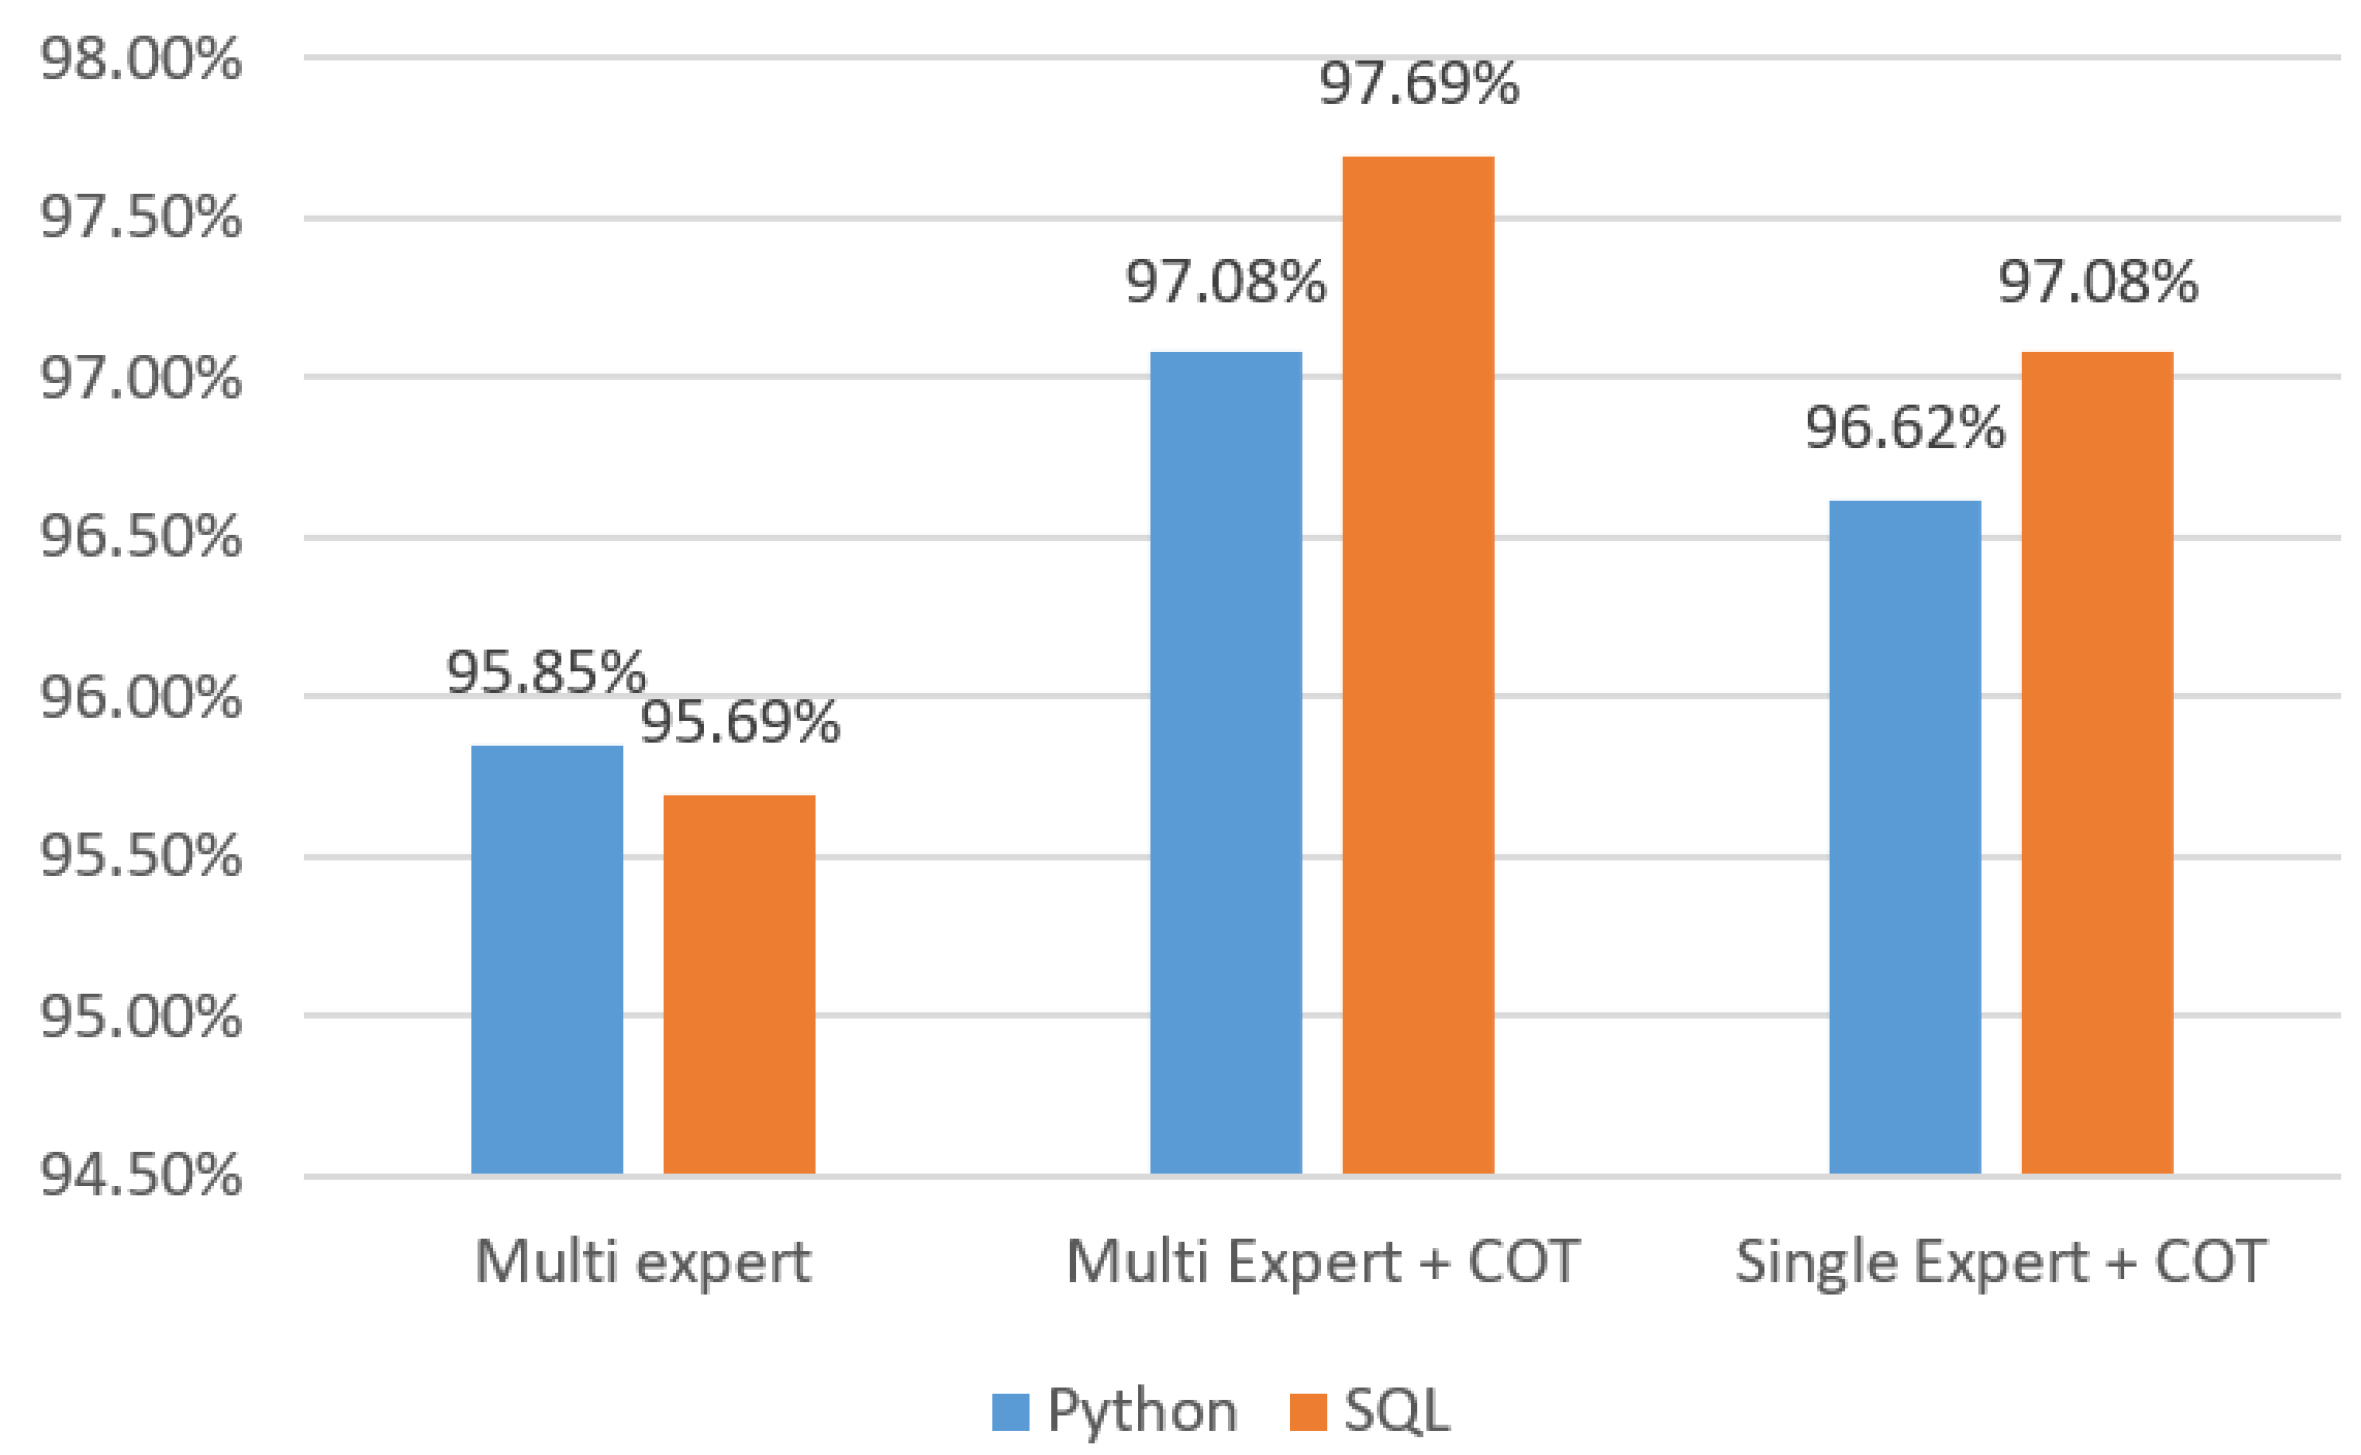
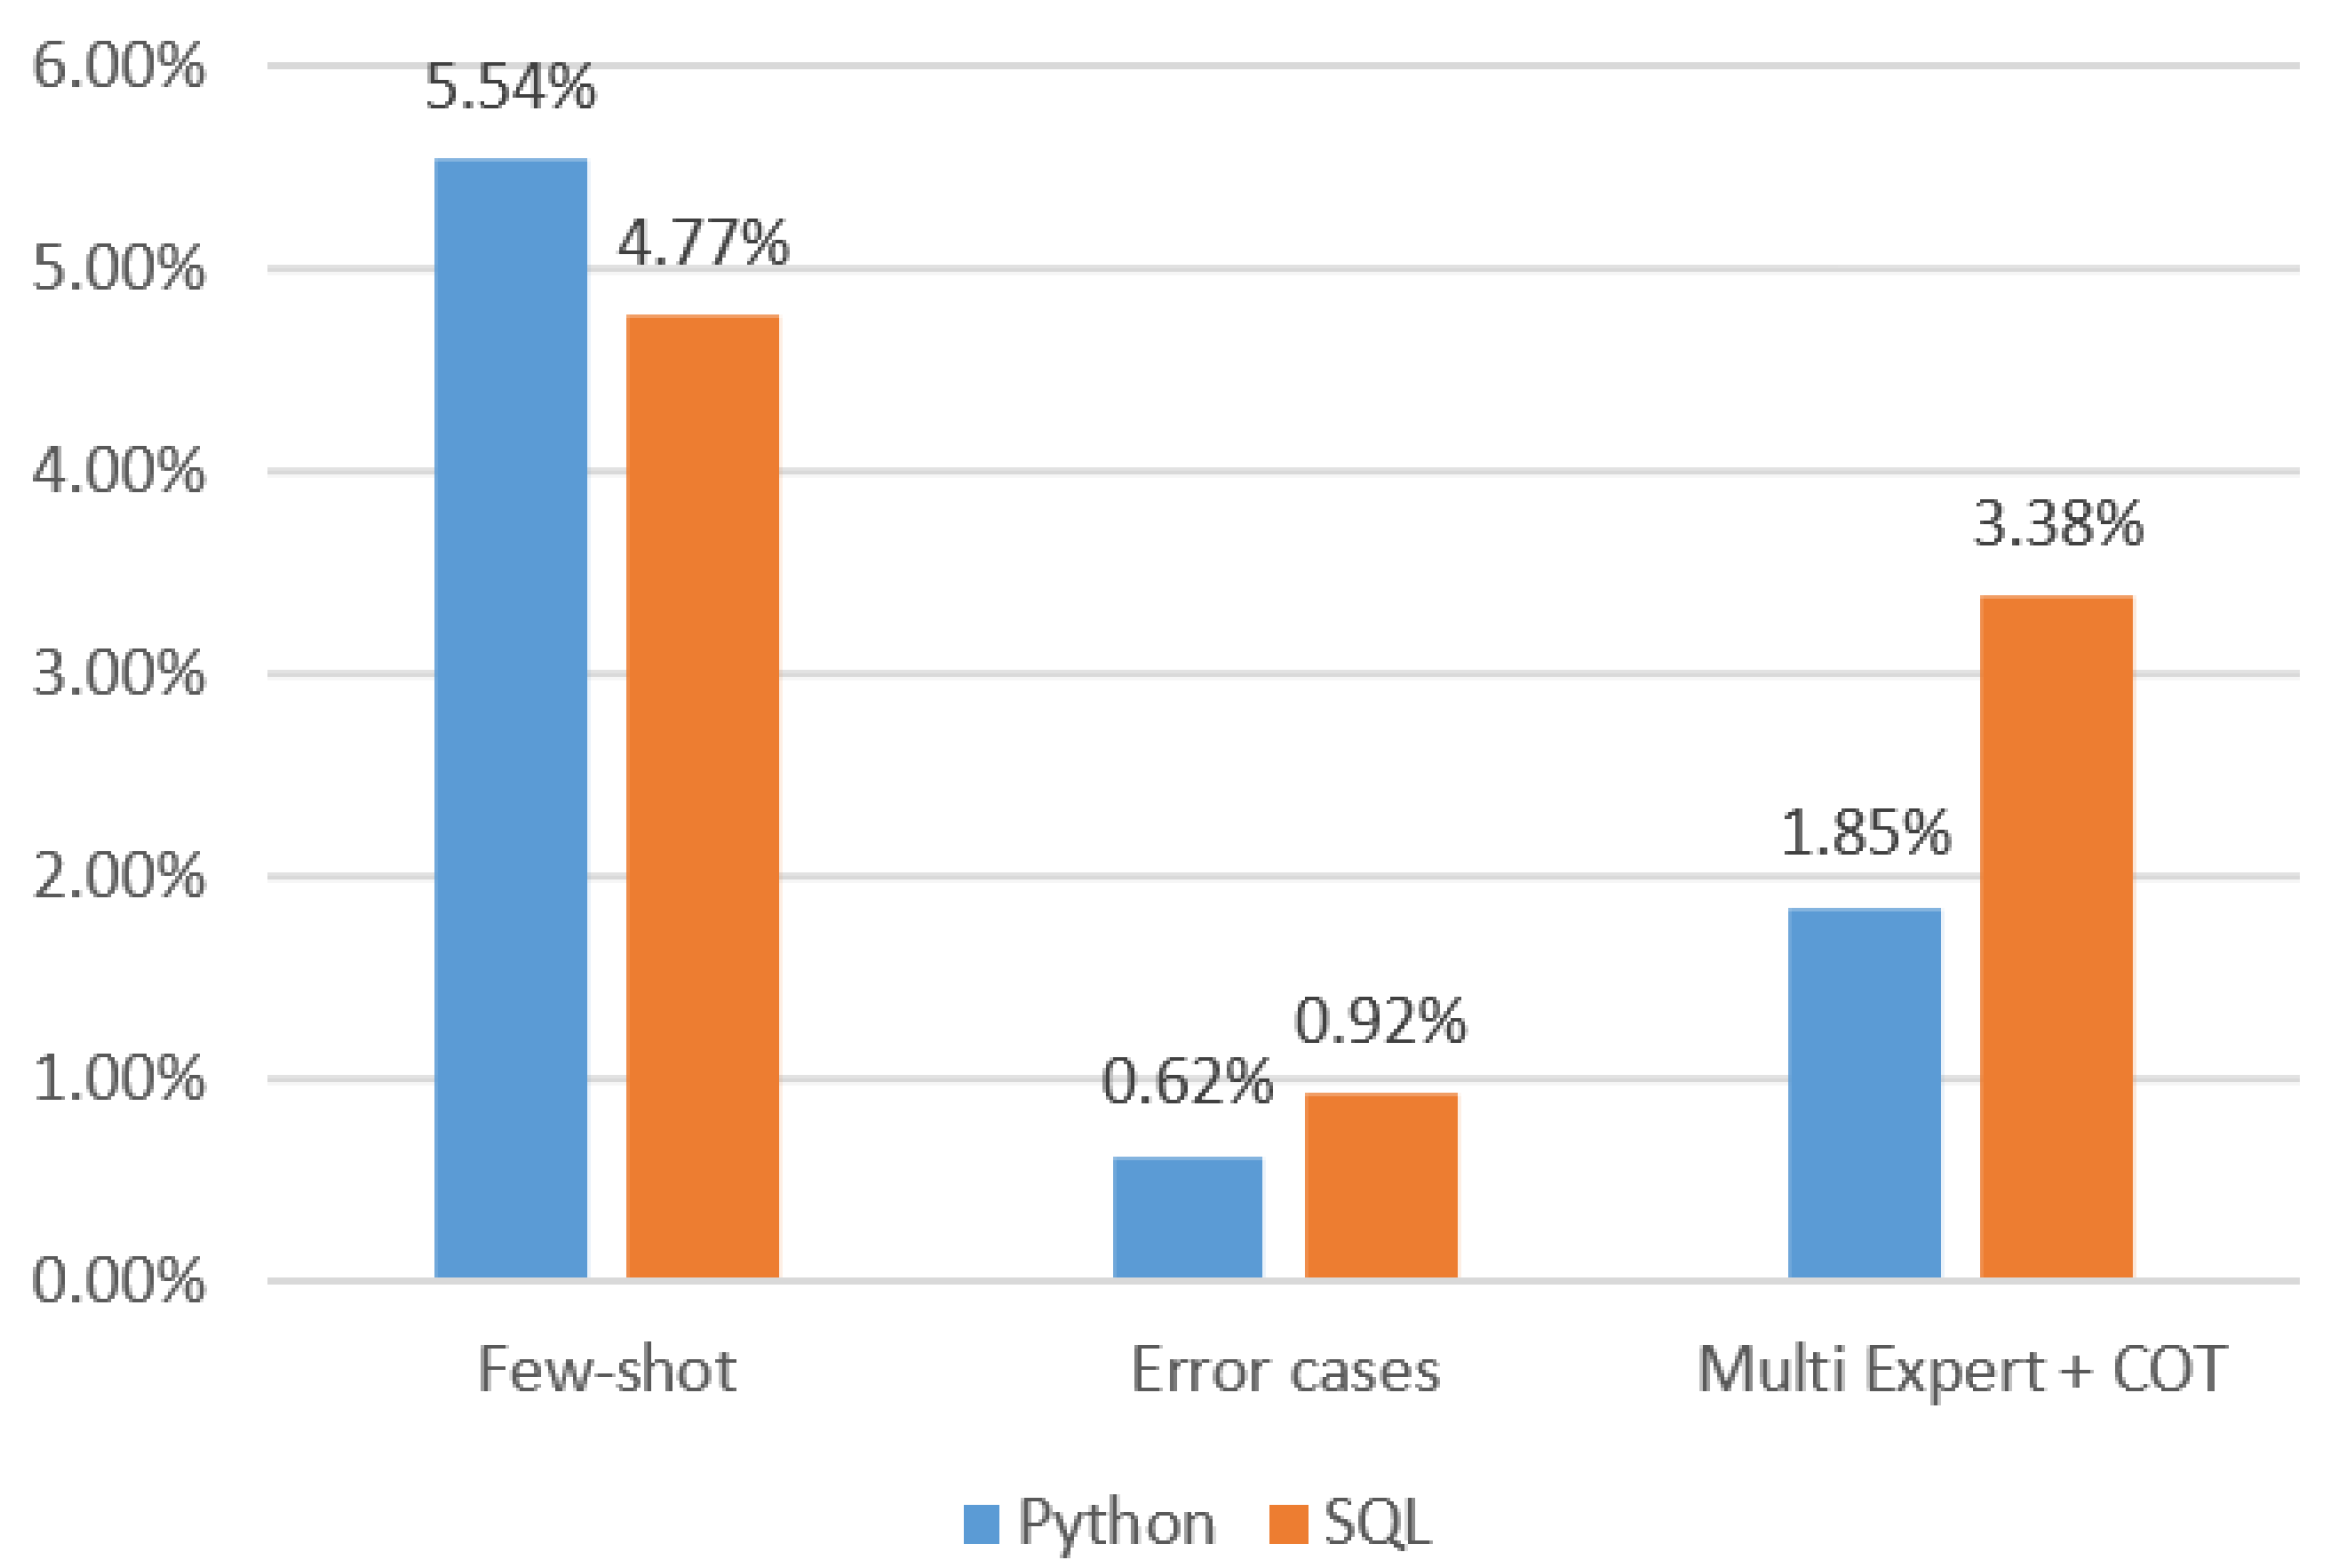
By comparing the parsing results of the baselines, it can be seen that in the SQL scenario, removing the multi-expert and COT led to a decrease of 0.62% and 2.0% in the accuracy rate of operator-level lineage parsing, respectively. In the Python scenario, removing the multi-expert and COT resulted in a decrease of 0.46% and 1.23% in the accuracy rate of lineage parsing, respectively, as shown in Figure 7 below. The ablation comparison in both scenarios indicated that COT had a greater impact on the accuracy of lineage parsing than multi-expert. Comparing baseline B5 and B4 revealed that removing both multi-expert and COT simultaneously resulted in a more significant decrease in accuracy: 3.38% for SQL and 1.85% for Python. These decreases were greater than the sum of the individual decreases when each strategy was removed separately (SQL: 2.0% + 0.62% = 2.62%, Python: 1.23% + 0.46% = 1.69%). This suggests that using both multi-expert and COT prompt strategies together is more effective than using them individually (1 + 1 > 2).
Figure 7.
Multi-Expert vs. CoT Ablation Comparative Analysis.
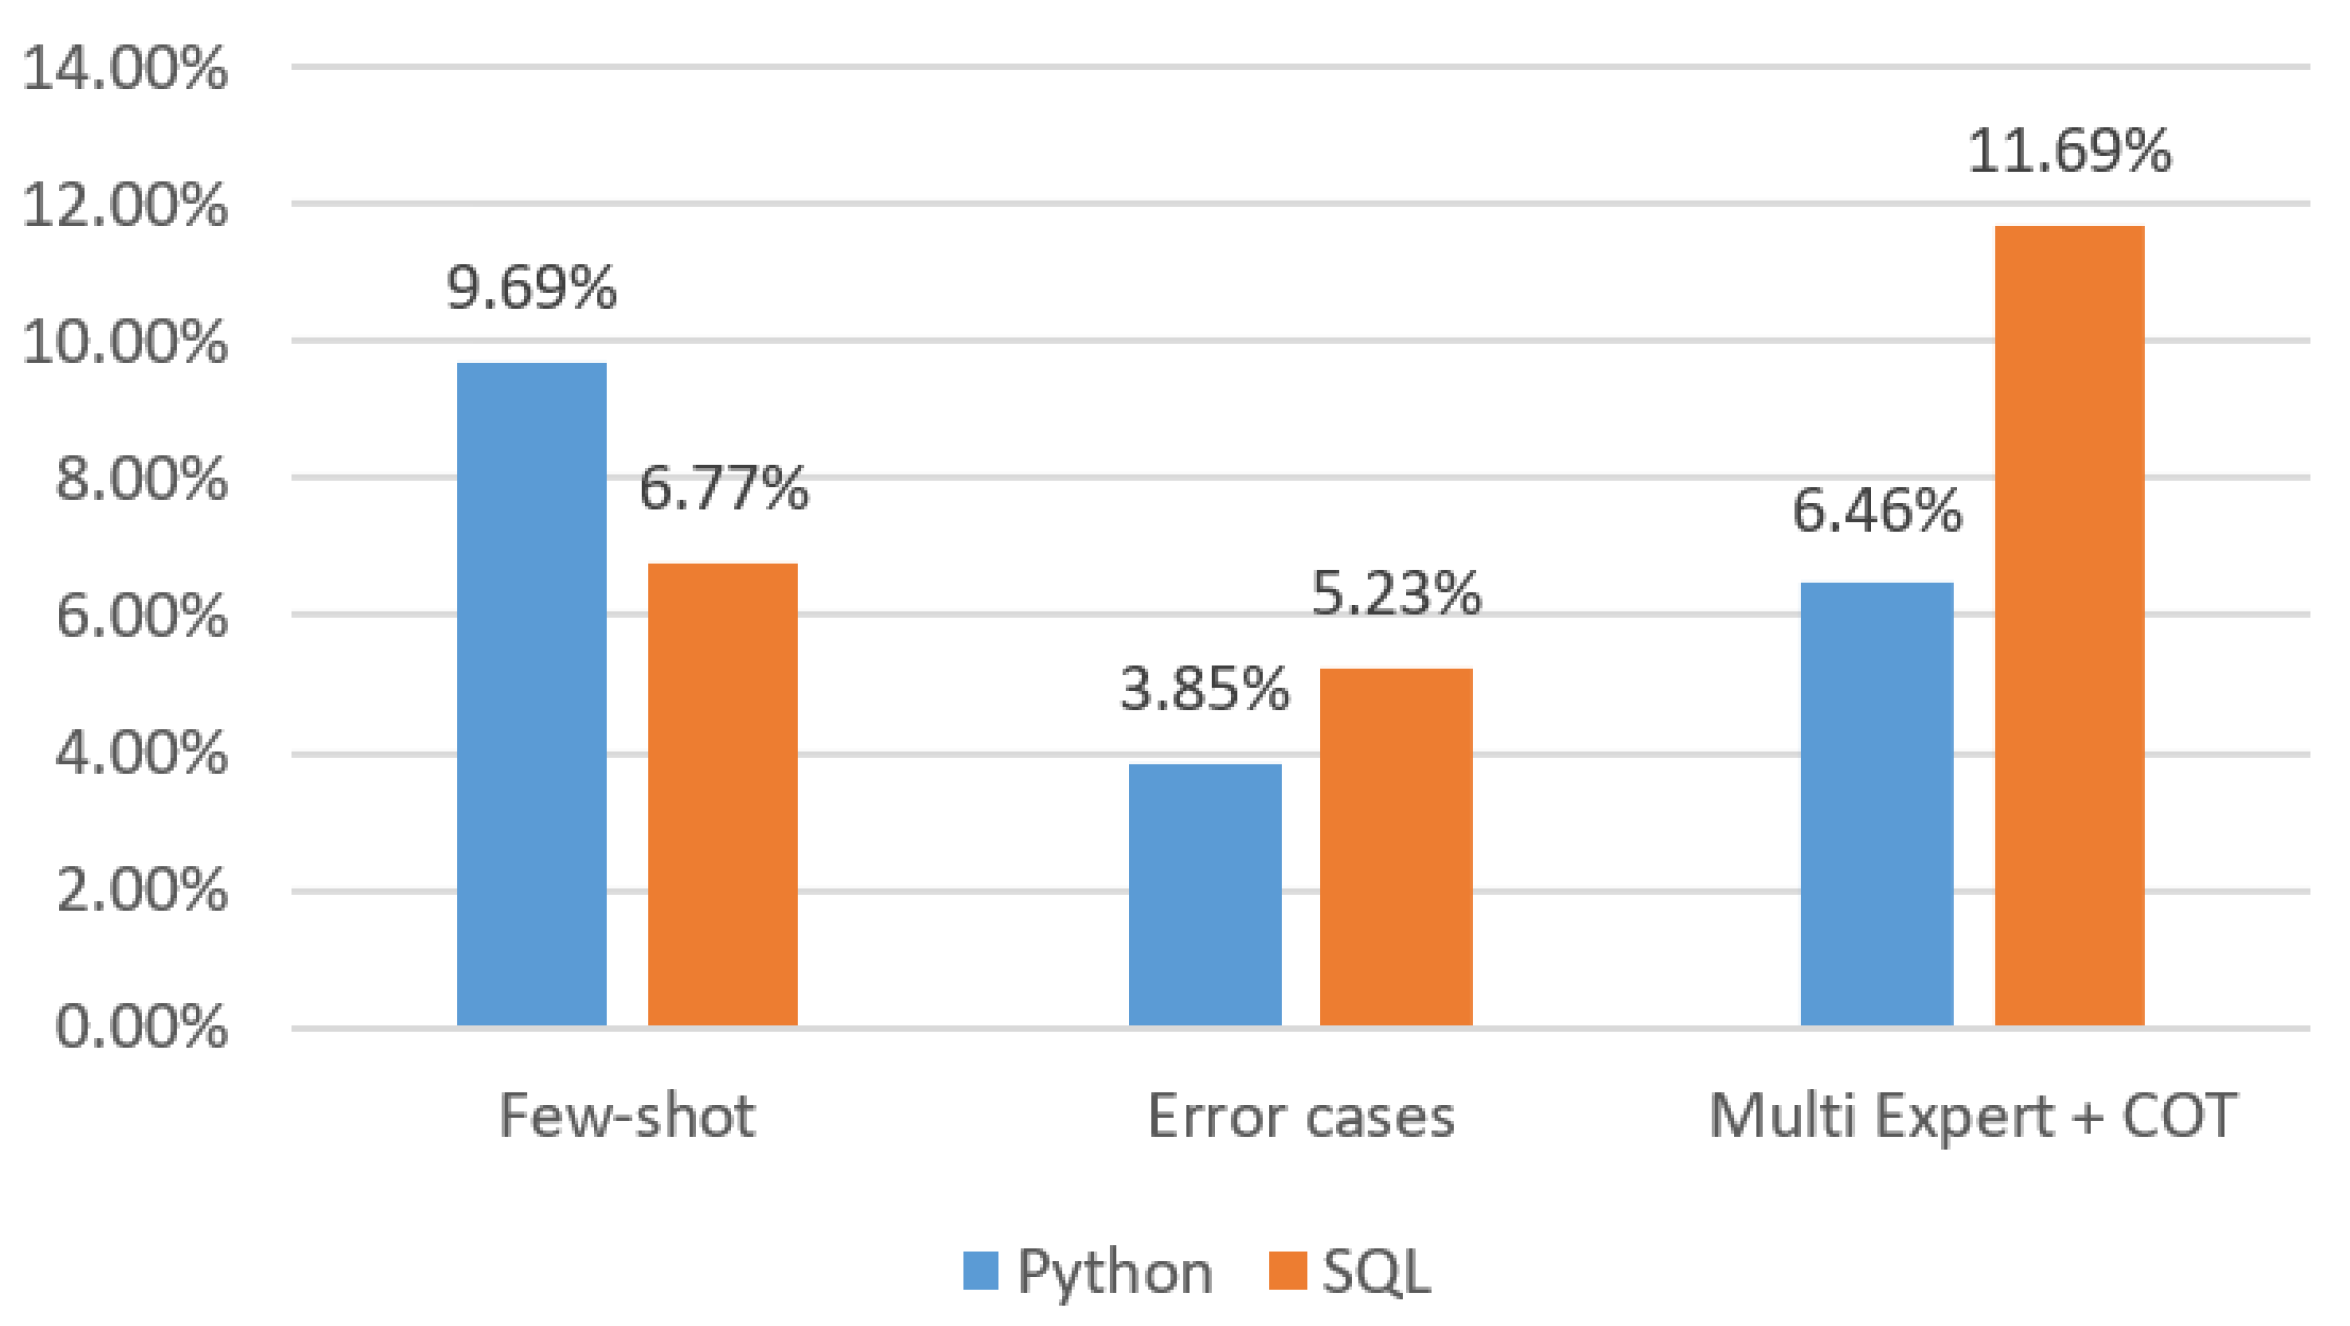
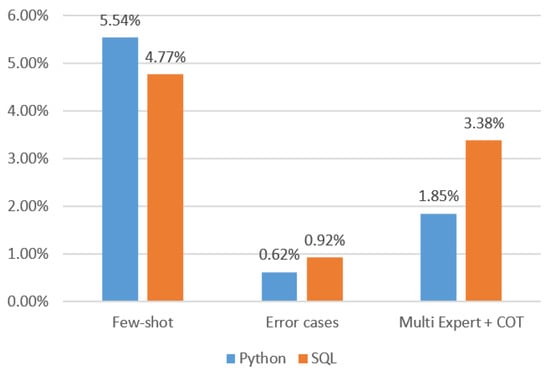
In addition, by analyzing Table 5 and comparing the accuracy rates of the baselines in pairs such as B3 and B1, B4 and B3, and B5 and B4, we could approximately determine the individual improvement rates brought by the prompt strategies of few-shot, error cases, and multi-expert + COT. The relevant data are shown in Figure 8 and Figure 9.
Figure 8.
Accuracy improvement achieved by employing various prompting strategies (Qwen-2-72b).
Figure 9.
Accuracy improvement achieved by employing various prompting strategies (Llama-3.1-405B).
As can be seen from Figure 8, for Qwen-2-72b, the mainstream few-shot prompting strategy in the industry significantly contributed to the improvement of accuracy. The multi-expert + COT method proposed in this paper achieved the greatest improvement in the SQL scenario, but its contribution in the Python scenario was lower than that of few-shot. In both scenarios, the improvement rate of the negative sample strategy was relatively small.
From Figure 9, it can be observed that for the large model Llama-3.1-405B with hundreds of billions of parameters, few-shot remained the most effective strategy for improvement. The multi-expert + COT strategy proposed in this paper had a slightly lower improvement rate than the former, and the improvement rate of the negative sample strategy was also small.
5.5. Discussion
Data in the telecommunications industry are characterized by their large scale, high real-time requirements, and complex and diverse business scenarios. A vast amount of data are generated daily, including network operation and maintenance data, user call and data traffic information, and business package data, among others. In the scenario of network operation and maintenance data management for telecommunications operators, various types of script are used in collaboration to process data from different sources. Similarly, in user behavior data analysis, different types of script are employed to mine and analyze user data related to calls, data traffic, and text messages.
The experimental results demonstrate that the proposed approach effectively addresses the key challenges associated with current data lineage parsing methods, namely, high customization costs, lengthy development cycles, and limited generalization, particularly demonstrating significant application value and broad prospects in the telecommunications operator industry.
First, the LLM-based lineage parsing framework significantly enhances the generalizability of parsing solutions across both SQL and non-SQL scripts. At the table-level granularity, open-source LLMs such as Qwen-2-72b and Llama-3.1-405B achieve over 95% parsing accuracy across multiple script types, including Shell, Flume, Python, and SQL. In contrast, smaller models such as Qwen-2-7B and Llama-3.1-8B perform poorly, with an average accuracy below 50%, even after multiple rounds of prompt optimization. Consequently, LLMs with more than 10 billion parameters are recommended for practical implementation.
Second, the proposed LLM-based approach relies solely on prompt engineering, eliminating the need for additional training, parameter fine-tuning, or customized code development. Minor prompt optimizations can be applied to adapt to new business scenarios, reducing development cycles and computational resource consumption compared to traditional lineage parsing solutions and fine-tuned LLM-based applications.
Additionally, the proposed method enhances the depth of lineage parsing without necessitating complex, deep customization. While Qwen-2-72b achieves suboptimal results for operator-level lineage parsing, with accuracy below 85%, the multi-expert with CoT approach improves accuracy beyond 90% for Python and 85% for SQL. Meanwhile, Llama-3.1-405B performs well across all baselines, achieving nearly 90% accuracy with zero-shot prompting. With the application of multi-expert with CoT, lineage parsing accuracy exceeds 97%. Compared with traditional lineage parsing methods, the method proposed in this paper achieved accuracy in table-level lineage that is close to that of traditional methods. However, it outperforms traditional methods when dealing with scenarios involving SQL dialects and multiple types of scripts.
From the results of the ablation analysis, it is evident that the currently well-developed few-shot prompting strategies have a significant impact on lineage accuracy and are indispensable. The multi-expert + COT prompting strategy proposed in this paper can notably improve lineage accuracy, with more pronounced effects observed in models with smaller parameter scales. Among the combined strategies, the COT strategy appears to be more important than the multi-expert strategy. Additionally, incorporating negative samples into the prompts can slightly enhance the final accuracy of lineage parsing.
In summary, the results indicate that LLMs, particularly those with large parameter scales, offer a highly effective and scalable solution for data lineage parsing. The multi-expert with CoT approach further enhances accuracy and interpretability, demonstrating substantial potential for improving enterprise data management and governance frameworks.
6. Conclusions
This study demonstrated the feasibility of employing a large language model (LLM)-based approach for data lineage parsing across various data processing script types through advanced prompt engineering techniques. This research comprehensively evaluated parsing performance under multiple dimensions, including LLM parameter scales, script types, different prompting methods, and varying levels of lineage granularity. By systematically analyzing these factors, this study provides a nuanced understanding of the capabilities and limitations of LLMs in the context of data lineage parsing. Furthermore, this research introduces significant enhancements to traditional LLM prompting methods, such as few-shot prompting and expert prompting, by incorporating innovative strategies like few-shot prompting with error cases and collaborative Chain-of-Thought (CoT) and multi-expert prompting. The effectiveness of these enhancements has been rigorously validated through empirical experimentation, demonstrating their potential to improve the accuracy and reliability of data lineage parsing.
The findings of this study offer valuable insights into the application of LLMs for data lineage parsing, particularly in scenarios involving multi-type, script-based lineage parsing and operator-level lineage tracking. The results underscore the potential of LLMs to enhance accuracy, efficiency, and adaptability in data lineage management, making them a powerful tool for organizations seeking to improve their data governance practices. By leveraging the generalization capabilities of LLMs, this research highlights how complex data lineage tasks can be streamlined, reducing the need for extensive manual intervention and enabling more scalable and efficient data management solutions.
However, despite the promising results, several challenges remain, particularly in handling complex stored procedures. Even large-scale LLMs, such as those with 100 billion parameters, exhibit various errors when parsing stored procedures. These errors often arise because stored procedures frequently depend on external scripts, and LLMs may generate speculative parsing results in the absence of explicit script content. This limitation underscores the need for further research to address the complexities associated with stored procedures and develop more robust parsing methodologies. Due to time and resource constraints, this study did not extensively explore lineage parsing for stored procedures, leaving this as an important area for future investigation.
In the future, we should focus on the deeper integration of AI Agent and Retrieval-Augmented Generation (RAG) techniques to enhance the accuracy and reliability of lineage extraction and interpretation. AI agents, with their ability to autonomously perform complex tasks, could be leveraged to dynamically retrieve and integrate relevant information from external sources, thereby improving the context-awareness and precision of LLM-based lineage parsing. Similarly, RAG techniques, which combine retrieval mechanisms with generative models, could be employed to augment an LLM’s knowledge base, enabling it to generate more accurate and contextually relevant lineage information. By integrating these advanced techniques, future research could address the current limitations and further advance the state of the art in data lineage parsing.
In conclusion, this study provides a foundational framework for leveraging LLMs in data lineage parsing, demonstrating their potential to transform data governance practices. Our contributions offer valuable guidance for researchers and practitioners in the field, highlighting both the opportunities and challenges associated with LLM-based approaches. Along with the continued exploration of stored procedure parsing, further advancements in AI agent and RAG integration will be critical for realizing the full potential of LLMs in data lineage management. This research contributes to the growing body of knowledge at the intersection of artificial intelligence and data governance, paving the way of more efficient, accurate, and scalable data lineage solutions in the future.
Author Contributions
Conceptualization, Z.L.; Methodology, W.G.; Investigation, Y.G.; Writing—original draft, D.Y.; Writing—review & editing, L.K. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by the Key Research and Development Project of Shanxi Province (202102070301019), and the special fund for Science and Technology Innovation Teams of Shanxi Province (no. 202304051001035).
Data Availability Statement
Data are contained within the article.
Conflicts of Interest
Authors Zhangti Li, Wenbin Guo, Yabing Gao and Di Yang was employed by the company China Unicom Software Research Institute. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.
Appendix A. Test Dataset Scenarios and Generation Methods Used in Experiments
| Test Case Type | Description |
| SQL Script Test Cases | A subset of the industry-standard TPC-H test case library was selected, comprising 13 typical scenarios (Q1, Q2, Q5, Q6, Q8) used as templates. These templates were synthesized into 50 variants, each using a large language model, resulting in a total of 650 test cases. |
| Python Script Test Cases | The aforementioned TPC-H SQL scripts were converted into Python scripts. Using a large language model, 50 variants were synthesized for each scenario, yielding a total of 650 Python test cases. |
| Shell Script Test Cases | Generated using a large language model, these scripts randomly selected output sources from nine data types (local files, HDFS, Hive, Kafka, Oracle, MySQL, PostgreSQL, HBase, and Elasticsearch). Data cleaning logic, such as date formatting, the removal of whitespace characters, the deletion of empty lines, and function transformations, was randomly incorporated. A total of 500 test cases were generated. |
| Flume Script Test Cases | Generated using a large language model, these scripts feature six source types (taildir, avro, syslog, kafka, thrift, exec) and five sink types (hdfs, hive, hbase, kafka, avro). Attributes such as file directories and IP addresses were randomly generated, resulting in a total of 500 test cases. |
References
- Backes, M.; Grimm, N.; Kate, A. Data Lineage in Malicious Environments. IEEE Trans. Dependable Secur. Comput. 2016, 1, 178–191. [Google Scholar] [CrossRef] [Scilit]
- Tang, M.; Shao, S.; Yang, W.; Liang, Y.; Hyun, D. SAC: A System for Big Data Lineage Tracking. In Proceedings of the 2019 IEEE 35th International Conference on Data Engineering (ICDE), Macao, China, 8–11 April 2019. [Google Scholar]
- Bao, X.; Lv, Z.; Wu, B. Enhancing large language models with RAG for Visual Language Navigation in Continuous Environments. Electronics 2025, 14, 909. [Google Scholar] [CrossRef] [Scilit]
- Ding, R.; Zhou, B. Enhancing Domain-Specific Knowledge Graph Reasoning via Metapath-Based Large Model Prompt Learning. Electronics 2025, 14, 1012. [Google Scholar] [CrossRef] [Scilit]
- Phani, A.; Rath, B. Reproducibility Report for ACM SIGMOD 2021 Paper: “LIMA: Fine-grained Lineage Tracing and Reuse in Machine Learning Systems”. In Proceedings of the 2021 International Conference on Management of Data, Online, China, 20–25 June 2021. [Google Scholar]
- De Oliveira, W.; Braga, R.; David, J.M.N.; Stroele, V.; Campos, F.; Castro, G. Visionary: A framework for analysis and visualization of provenance data. Knowl. Inf. Syst. 2022, 64, 381–413. [Google Scholar] [CrossRef] [Scilit]
- Tan, Z.; Haihong, E.; Song, M. A Column-Level Data Lineage Processing System Based on Hive. In Proceedings of the ICBDT 2020: 2020 3rd International Conference on Big Data Technologies, Qingdao, China, 18–20 September 2020. [Google Scholar]
- Liu, P.; Yuan, W.; Fu, J.; Jiang, Z.; Hayashi, H.; Neubig, G. Pre-train, Prompt, and Predict: A Systematic Survey of Prompting Methods in Natural Language Processing. ACM Comput. Surv. 2023, 55, 1.1–1.35. [Google Scholar] [CrossRef] [Scilit]
- Wei, J.; Wang, X.; Schuurmans, D.; Bosma, M.; Chi, E.; Le, Q.; Zhou, D. Chain of Thought Prompting Elicits Reasoning in Large Language Models. arXiv 2022, arXiv:2201.11903. [Google Scholar]
- Fu, Y.; Peng, H.; Sabharwal, A.; Clark, P.; Khot, T. Complexity-Based Prompting for Multi-Step Reasoning. arXiv 2023, arXiv:2210.00720. [Google Scholar]
- Creswell, A.; Shanahan, M.; Higgins, I. Selection-Inference: Exploiting Large Language Models for Interpretable Logical Reasoning. arXiv 2022, arXiv:2205.09712. [Google Scholar]
- Zhou, D.; Schärli, N.; Hou, L.; Wei, J.; Scales, N.; Wang, X.; Schuurmans, D.; Cui, C.; Bousquet, O.; Le, Q.; et al. Least-to-Most Prompting Enables Complex Reasoning in Large Language Models. arXiv 2023, arXiv:2205.10625. [Google Scholar]
- Wang, X.; Wei, J.; Schuurmans, D.; Le, Q.; Chi, E.; Narang, S.; Chowdhery, A.; Zhou, D. Self-Consistency Improves Chain of Thought Reasoning in Language Models. arXiv 2022, arXiv:2203.11171. [Google Scholar]
- Zhang, Z.; Zhang, A.; Li, M.; Smola, A. Automatic Chain of Thought Prompting in Large Language Models. arXiv 2022, arXiv:2210.03493. [Google Scholar]
- Gao, M.; Jin, C.; Wang, X.; Tian, X.X.; Zhou, A.Y. A Survey on Data Lineage Management Techniques. Chin. J. Comput. 2010, 33, 373–389. [Google Scholar] [CrossRef] [Scilit]
- Buneman, P.; Tan, W.C. Data Provenance: What next? In Proceedings of the International Conference on Management of Data, Amsterdam, The Netherlands, 30 June–5 July 2019.
- Shi, L.; Sun, L.; Wang, Y. A Survey on Data Provenance Security. Appl. Res. Comput. 2017, 34, 1–7. [Google Scholar]
- Zhu, Q. Evaluation of the Value of Data Assets in Power Grid Enterprises Based on Data Lineage Analysis. Inf. Comput. 2023, 35, 91–93. [Google Scholar]
- Ran, Y.; Cheng, S.; Gan, G.; Gao, M.; Yao, J.; Qiao, Y. Research and Application of Dynamic Data Lineage Monitoring Scheme in Civil Aviation. China Informatiz. 2024, 52–54. [Google Scholar]
- Wang, Z.; Zhao, Z.; Yue, F.; Shu, G.; Fang, X. Research on Metadata Lineage Graph for Regulatory Reporting Data Governance. China Financ. Comput. 2023, 58–62. [Google Scholar]
- Liu, X.; Bi, C. Data Governance of Artificial Intelligence Large Models. Inf. Secur. Commun. Priv. 2024, 45–55. [Google Scholar]
- Shu, W.; Li, R.; Sun, T.; Huang, X.; Qiu, X. Large Language Models: Principles, Implementation and Development. J. Comput. Res. Dev. 2024, 61, 351–361. [Google Scholar]
- Wang, W.; Tan, N.; Huang, K.; Zhang, Y.; Zheng, W.; Sun, F. A Survey on Embodied Intelligence Systems Based on Large Models. Acta Autom. Sin. 2025, 1–18. [Google Scholar]
- Li, S.; Wang, Z.; Zhou, G. Cross-Domain Attribute-Level Sentiment Analysis Driven by Large Language Models. J. Softw. 2025, 1–16. [Google Scholar]
- Qin, L.; Wu, W.; Liu, D.; Hu, Y.; Yin, Q.; Liu, D.; Wang, F. A Framework for Autonomous Planning and Processing of Complex Tasks Based on Large Language Models. Acta Autom. Sin. 2024, 50, 862–872. [Google Scholar]
- Xu, P.; Kuang, B.; Su, S.; Fu, A. A Survey on Automatic Code Repair Based on Large Language Models. J. Comput. Res. Dev. 2025, 1–19. [Google Scholar]
- Xu, B.; Yang, A.; Lin, J.; Wang, Q.; Zhou, C.; Zhang, Y.; Mao, Z. ExpertPrompting: Instructing Large Language Models to be Distinguished Experts. arXiv 2023, arXiv:2305.14688. [Google Scholar]
- Huang, J.; Gu, S.S.; Hou, L.; Wu, Y.; Wang, X.; Yu, H.; Han, J. Large Language Models Can Self-Improve. arXiv 2022, arXiv:2210.11610. [Google Scholar]
- Long, D.X.; Yen, D.N.; Luu, A.T.; Kawaguchi, K.; Kan, M.Y.; Chen, N.F. Multi-expert Prompting Improves Reliability, Safety, and Usefulness of Large Language Models. arXiv 2024, arXiv:2411.00492. [Google Scholar]


Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).