Article

Intelligent Early Warning Model for Technological Paradigm Shift Risks in High-Tech Enterprises: An Integrated Framework of ISM–ANP-Entropy Method and Deep Autoencoder Network

1
College of Economic and Management, Nanjing Tech University, Nanjing 211816, China
2
College of Economic and Management, Nanjing University of Aeronautics and Astronautics, Nanjing 210016, China
*
Author to whom correspondence should be addressed.
Systems 2026, 14(7), 790; https://doi.org/10.3390/systems14070790
Submission received: 8 May 2026 / Revised: 26 June 2026 / Accepted: 27 June 2026 / Published: 6 July 2026
(This article belongs to the Section Systems Engineering)

Abstract

Achieving accurate early warning of technological paradigm shift risks is crucial for high-tech enterprises to proactively manage strategic risks and seize opportunities for technological change. Based on a systematic identification of early warning factors for technological paradigm shift risks, this study constructs a chain-structured early warning model that integrates structural analysis, weight calculation, and intelligent algorithms. First, the Interpretive Structural Model (ISM) is used to analyze the hierarchical structure and dependencies among early warning factors, revealing the transmission path of risks from deep-rooted sources to surface-level phenomena. Second, the Analytic Network Process (ANP) and entropy method are integrated to synthesize subjective and objective information, calculating comprehensive weights for each factor and indicator while considering their mutual influences, thereby clarifying the priorities for risk management. Finally, addressing the nonlinear and small-sample characteristics of risk early warning, an intelligent early warning model based on a Deep Autoencoder Network (DAN) is constructed. Empirical testing on 75 high-tech enterprises shows that: ISM divides nine early warning factors into three levels with clear transmission relationships; ANP-entropy weights indicate that “technology assessment,” “enterprise competition,” and “innovation effort” are the core driving factors with the highest weights; and the DAN model, after training, achieves 93.33% accuracy in classifying technological paradigm risk levels on the test set, significantly outperforming traditional benchmarks such as One-Class SVM and Random Forest, demonstrating powerful nonlinear pattern recognition and adaptive assessment capabilities. This study provides methodological innovation and practical tools for achieving dynamic and intelligent early warning of technological paradigm risks.

1. Introduction

1.1. Research Background and Problem Statement

The technological paradigm shift in high-tech enterprises is a nonlinear evolutionary process fraught with uncertainties. Its inherently dissipative structure implies that enterprises inevitably face systemic risks. In an era of rapid technological iteration, an enterprise’s ability to identify in time and effectively respond to technological paradigm shift risks directly impacts its survival and development. Once-prosperous enterprises like Kodak, Nokia, and Motorola have all encountered difficulties due to their failure to effectively identify and respond to the disruptive risks brought about by technological paradigm shifts [1].
Constructing a scientific risk early warning indicator system is the foundation for achieving quantitative risk perception. Existing research has identified key factors influencing technological paradigm shifts from multiple dimensions including technology, finance, management, culture, society, and market [2]. Systematic research based on methods such as grounded theory, expert evaluation, and factor analysis has preliminarily constructed a risk early warning indicator system comprising six signal sources, nine early warning factors, and 30 specific observation indicators, providing a measurement tool for the quantitative assessment of the health status of the technological paradigm.
However, constructing an indicator system is only the foundational step in risk early warning. To achieve the transition from “static measurement” to “dynamic early warning,” three core problems need to be addressed:
First, what is the inherent structure and transmission path among early warning factors? Technological paradigm shift risk is a complex systemic issue, where early warning factors are not independent but interact with and constrain each other. Simply listing factors while ignoring their structural relationships makes it impossible to grasp the key paths of risk transmission or formulate precise intervention strategies.
Second, how can the true importance (weights) of each early warning factor and indicator be scientifically determined? In risk early warning, different factors and indicators have significantly different comprehensive impacts on risk. Traditional Analytic Hierarchy Process (AHP) requires factors to be independent and cannot handle the dependencies and feedback relationships common in technological paradigm systems. How to scientifically determine weights while considering mutual influences among factors is an urgent methodological problem.
Third, how can an intelligent model capable of handling nonlinear relationships be constructed to achieve adaptive and accurate discrimination of risk levels? The relationship between risks and indicators is highly nonlinear, and traditional statistical models (e.g., logistic regression, discriminant analysis) struggle to effectively fit these complex relationships. Deep learning models have unique advantages in handling nonlinear, high-dimensional data, but their application in risk early warning still requires exploration.
Addressing the above challenges, this study proposes a chain-structured research framework integrating structural analysis, weight calculation, and intelligent assessment. The specific research questions that guide this framework are anchored in the identified literature gaps and are formally presented at the beginning of the methodology section (Section 3).

1.2. Theoretical Contributions and Practical Implications

From a theoretical perspective, the three components of the proposed framework offer distinct methodological innovations: firstly, ISM reveals the hierarchical transmission paths of risks; secondly, the ANP-entropy integration synthesizes subjective and objective information for weight determination; and thirdly, the DAN deep learning model provides a new approach for intelligent risk assessment in nonlinear, small-sample scenarios.

2. Literature Review

2.1. Drivers of Technological Paradigm Shift Risk

The foundational concept of technological paradigms was introduced by Dosi [3], who described them as patterns of solution to selected techno-economic problems that define the trajectory of technological progress. Subsequently, a rich stream of literature has explored the factors that precipitate and shape paradigm shifts. Henderson and Clark [4] distinguished between incremental and architectural innovation, showing how shifts in component linkages can destroy the value of incumbent firms’ existing knowledge. Christensen’s [5] theory of disruptive innovation further illuminated why leading firms often fail in the face of seemingly inferior technologies that redefine market value propositions. More recent scholarship has examined internal organizational factors such as dynamic capabilities [6], core rigidities [7], and absorptive capacity [8] as determinants of a firm’s ability to navigate paradigm transitions. However, the majority of these works analyze risk determinants in isolation, without systematically modeling their structural interdependencies and collective transmission pathways. This atomistic perspective offers limited guidance for understanding how risks propagate through a complex socio-technical system.

2.2. Early Warning Models for Technological Risk

The development of early warning systems for organizational and technological risk has drawn extensively from decision science and statistics. Traditional models predominantly rely on linear statistical techniques such as logistic regression, discriminant analysis, and signal extraction methods [9]. Multi-criteria decision-making (MCDM) tools, most notably the Analytic Hierarchy Process (AHP) [10], have been widely applied to assign weights to risk indicators and to aggregate them into composite risk indices. However, a fundamental limitation of AHP is its assumption of factor independence, an assumption that is routinely violated in complex innovation systems where feedback, interdependence, and indirect effects are pervasive. Saaty’s [11] Analytic Network Process (ANP) was developed precisely to accommodate such network structures by allowing for dependencies and feedback among decision elements. Despite its theoretical suitability, the application of ANP to technological paradigm risk management remains rare. In parallel, information-theoretic methods such as the entropy method [12] have been employed to derive objective weights from data dispersion. While entropy-based weights offer an empirical counterbalance to subjective expert judgment, they ignore causal relationships and expert knowledge. A synthesis of ANP and entropy—one capable of balancing subjective logic with objective data while respecting network structures—has not been adequately explored in the context of technological risk early warning.

2.3. Deep Learning in Risk Early Warning

Recent advances in machine learning, particularly in deep learning, have opened new frontiers for risk assessment. Autoencoders, a class of unsupervised neural networks that learn compressed representations of input data through bottleneck architecture, have proven remarkably effective for anomaly detection across diverse domains, including manufacturing, finance, and cyber-security [13]. Their operational logic—learning the characteristic patterns of “normal” states and then flagging deviations as potential anomalies—is intrinsically well-suited for early warning applications where instances of failure or crisis are historically rare. Studies have demonstrated that autoencoders can model complex, nonlinear manifolds in high-dimensional data and generalize from modestly sized training sets when appropriately regularized. Yet, their application to technological paradigm shift risks is virtually absent from the literature. Emerging interdisciplinary work, such as Su et al. [14] on adaptive reliability modeling for complex systems and Zhang et al. [15] on digital platform-driven industrial pathways, indicates the broader potential of deep learning architectures for complex system assessment, but these advances have not been integrated with the structural analysis of risk factors that is essential for actionable early warning.

2.4. Research Gap and Marginal Contribution

In summary, prior research has separately investigated risk factor identification, multi-criteria weighting, and machine-learning-based early warning. There remains a significant gap in integrating these methods into a coherent, logically sequenced framework that leverages their respective strengths. Specifically, a structural model is needed to uncover the qualitative network of factors, which then informs a network-aware weighting method capable of balancing subjective expertise with objective data, whose output in turn provides a robust evaluation system for training an intelligent, nonlinear anomaly detector. This study bridges that gap by sequentially applying ISM, ANP-entropy, and DAN, thereby offering both a methodological integration and an empirically validated practical tool for dynamic risk early warning in high-tech enterprises.

3. Research Framework and Model Integration Logic

This integrated framework is designed to systematically answer the following research questions, each rooted in established theoretical and methodological gaps:
RQ1 (Structural Decomposition): What is the inherent hierarchical structure and action path among early warning factors? Prior studies have identified risk factors but largely treated them in isolation [3,4,5,6,7]. Understanding how risks propagate from deep-rooted drivers to surface signals requires a structural modeling approach capable of capturing direct and indirect dependencies. The ISM method [16,17] addresses this gap by decomposing complex factor networks into interpretable hierarchical levels.
RQ2 (Weight Determination): How can weights be scientifically determined while considering mutual influences and integrating subjective–objective information? Traditional AHP assumes factor independence [10], and pure entropy methods disregard expert causal logic [12]. The ANP-entropy synthesis [11,18] overcomes these limitations by modeling the network dependencies revealed by ISM and balancing expert judgment with empirical data dispersion.
RQ3 (Intelligent Assessment): How can an intelligent model achieve accurate, adaptive risk classification in small-sample, nonlinear settings? Conventional linear models cannot capture the complex mapping between indicators and risk levels [9,13]. Deep autoencoders [13,19,20] offer powerful nonlinear feature learning and anomaly detection capabilities suitable for such contexts, yet their application to technological paradigm risk remains largely unexplored.
The integration logic is explicitly defined as follows:
Step 1: ISM for Structural Decomposition. The Interpretive Structural Model is deployed first to deconstruct the complex system of nine early warning factors into a multi-level hierarchical model. By analyzing direct binary relationships and computing reachability matrices, ISM reveals the driving, intermediate, and dependent layers of the system. This qualitative step provides a causal roadmap of risk transmission, answering the question of how deep-rooted factors ultimately manifest as surface-level risk signals.
Step 2: ANP-Entropy for Weight Calculation Based on Structure. The structural dependencies uncovered by ISM directly inform the construction of the ANP network structure—that is, they determine which factors are linked by influence arrows in the network diagram. The ANP-entropy method then quantifies these relationships by calculating the global priority weight of each indicator. This step transforms the qualitative structural model into a quantitative evaluation tool. The output is a validated, weighted indicator system capable of computing a single Comprehensive Risk Index (CRI) for any given enterprise, which serves as the ground-truth target for model training.
Step 3: DAN for Intelligent Assessment. The deep autoencoder network functions as the final, intelligent assessment layer in this pipeline. It is trained on enterprise indicator data to learn the intrinsic feature patterns of enterprises operating in a “healthy” (low-risk) state—that is, enterprises whose CRI falls in the No Warning or Mild Warning categories. By reconstructing the input data through a low-dimensional bottleneck, the model uses the reconstruction error as an anomaly score. A high reconstruction error for a new enterprise signifies a meaningful deviation from the learned healthy pattern, directly mapping to a higher risk level. Crucially, the DAN does not embed the ANP-entropy weights as internal parameters of its architecture; rather, the weights are employed in the preceding stage to construct the CRI that defines the target state for training. This creates a seamless, sequential workflow where each component logically feeds into the next.

4. Overview of the Early Warning Indicator System for Technological Paradigm Shift Risks

4.1. Basic Structure of the Early Warning Indicator System

Technological paradigm shift risk is a systemic issue involving multiple dimensions inside and outside the enterprise. Based on a technological ecology perspective, early warning signals for technological paradigm shift risk can be divided into two major categories: internal signal sources and external signal sources. Internal signal sources include technical signals, financial signals, management signals, and cultural signals, reflecting the enterprise’s own resource endowment, capability level, and organizational characteristics; external signal sources include social signals and market signals, reflecting the external environment and competitive landscape in which the enterprise operates [21].
Through systematic theoretical analysis and empirical testing, a risk early warning indicator system comprising six signal sources, nine early warning factors, and 30 specific observation indicators has been constructed (Table 1). This indicator system has the following characteristics:
First, multi-dimensional coverage. The indicator system covers six dimensions—technology, finance, management, culture, society, and market—and comprehensive reflects the multi-dimensional characteristics of technological paradigm shift risk.
Second, clear hierarchy. The indicator system is structured into three levels: signal sources, early warning factors, and early warning indicators, reflecting both the distinction between external environment and internal factors and the intrinsic relationships among early warning factors.
Third, strong operability. The 30 early warning indicators are designed with clear scale items, measurable through methods such as questionnaire surveys, financial report analysis, and patent data analysis, offering strong operability.

4.2. Validity Testing of the Early Warning Indicator System

To ensure the scientificity and reliability of the indicator system, systematic reliability and validity tests were conducted based on questionnaire survey data from 208 high-tech enterprises. Reliability analysis showed that the Cronbach’s α coefficient for the overall scale was 0.951, and the α coefficients for each early warning factor ranged from 0.68 to 0.82, indicating high internal consistency of the indicator system [22]. Exploratory Factor Analysis (EFA) extracted nine common factors with eigenvalues greater than 1, with a cumulative variance contribution rate of 69.32% [23]. Factor loadings of indicators ranged from 0.55 to 0.81, with no significant cross-loadings [24]. Confirmatory Factor Analysis (CFA) results showed χ2/df = 2.67, RMSEA = 0.06, CFI = 0.93, IFI = 0.95, and NFI = 0.92. All fit indices reached good levels, indicating that the indicator system possesses good construct validity and discriminant validity [25].
The above test results demonstrate that this early warning indicator system can serve as a scientific measurement tool for technological paradigm shift risks in high-tech enterprises, laying a solid psychometric foundation for subsequent structural analysis, weight calculation, and intelligent early warning.

5. Structural Analysis and Weight Determination of Early Warning Factors

5.1. Hierarchical Structure Analysis of Early Warning Factors Based on ISM

5.1.1. Principle and Applicability of Interpretive Structural Model (ISM)

The Interpretive Structural Model (ISM), systematically proposed by Warfield [16], is a technique aimed at decomposing complex systems into a clear multi-level hierarchical structure model. ISM analyzes the direct binary relationships among elements, uses operations on adjacency and reachability matrices, and ultimately hierarchizes system elements, clearly displaying the progressive relationship from surface phenomena to deep-rooted causes. It is particularly adept at revealing the hierarchical skeleton and causal transmission paths of a system [17]. The nine early warning factors of technological paradigm shift risk precisely fit this characteristic—they are not independent but interact with and constrain each other, forming a complex network system.

5.1.2. ISM Model Construction Process

(1) Determining the Set of Early Warning Factors
Based on the aforementioned early warning indicator system, the nine factors for early warning of technological paradigm shift risk are: Government Intervention (S1), Market Competition (S2), Enterprise Competition (S3), Innovation Effort (S4), Personnel Turnover (S5), Technology Stock (S6), Technology Assessment (S7), Financing Capability (S8), and Innovation Spirit (S9).
(2) Establishing the Adjacency Matrix
To ensure the reliability of the structural judgments, a panel of 10 experts was assembled. Each expert possessed over 15 years of senior R&D management experience in high-tech firms or was a professor specializing in innovation management. A two-round Delphi method was employed: after the initial independent evaluation, aggregated results were fed back to the panel to achieve a strong consensus on the direct influence relationships. Through this expert panel process, the direct influence relationships among the nine factors were judged using a questionnaire survey. The judgment criterion was: if factor i has a direct influence on factor j, then aij = 1 ; otherwise, aij = 0 . Synthesizing the expert opinions, the adjacency matrix A was obtained (Table 2).
(3) Calculating the Reachability Matrix
Based on the adjacency matrix, the identity matrix I was added, and Boolean algebraic operations were performed until ( A + I ) ( k 1 ) ( A + I ) k = ( A + I ) ( k + 1 ) = M , where M is the reachability matrix. The reachability matrix reflects the indirect influence relationships among factors transmitted through certain paths. After calculation, the reachability matrix M was obtained (Table 3).
(4) Hierarchical Partition
Based on the reachability matrix, the Reachability Set R( S i ), the Antecedent Set A( S i ), and the Intersection Set C( S i ) = R( S i ) ∩ A( S i ) were calculated for each factor. When R( S i ) = C( S i ), the factor is considered the highest-level factor of the current level. Through iterative extraction, the hierarchical distribution of factors was obtained (Figure 1).
First level (surface-dependent layer): S3 Enterprise Competition, S5 Personnel Turnover;
Second level (intermediate transmission layer): S2 Market Competition, S4 Innovation Effort, S7 Technology Assessment, S8 Financing Capability, S9 Innovation Spirit;
Third level (deep-rooted driving layer): S1 Government Intervention, S6 Technology Stock.

5.1.3. Analysis of ISM Model Results

(1) Interpretation of the Hierarchical Structure
Third Level: Deep-rooted Driving Layer—Government Intervention and Technology Stock. Government Intervention (S1) and Technology Stock (S6) are located at the bottom of the hierarchical structure, acting as deep-rooted sources influencing other factors. Government Intervention fundamentally shapes the external environment faced by enterprises through policies, regulations, government behavior, and market management levels, affecting the financing environment, market competition landscape, and enterprise innovation motivation. Technology Stock reflects the enterprise’s long-term knowledge accumulation and R&D investment, determining its ability to perceive, absorb, and integrate new technologies [26,27]. These two factors possess the strongest driving force on other factors in the system and are the most fundamental sources of risk [28].
Second Level: Intermediate Transmission Layer—Market Competition, Innovation Effort, Technology Assessment, Financing Capability, Innovation Spirit. These five factors occupy an intermediate transmission position, being both the result of deep driving factors and the direct drivers of surface-level performance factors. Market Competition (S2) is influenced by Government Intervention and directly acts on enterprise competition performance [4,7]; Innovation Effort (S4) and Technology Assessment (S7) are constrained by the level of Technology Stock and determine the enterprise’s innovation output and competitiveness; Financing Capability (S8) is influenced by both government policies and market competition, and in turn constrains the enterprise’s innovation input; Innovation Spirit (S9) is influenced by the government cultural environment and organizational climate, and drives innovation effort [5,6].
First Level: Surface-dependent Layer—Enterprise Competition and Personnel Turnover. Enterprise Competition (S3) and Personnel Turnover (S5) are at the top of the hierarchy, serving as direct representations of risk signals. Changes in indicators such as enterprise market share, overall capability, and product competitiveness directly reflect the competitive pressure faced by the enterprise; the turnover situation of executives and R&D personnel directly reflects organizational vitality and innovation climate. These two factors have the strongest dependence and weakest driving force, being more the result of deep factors acting rather than causes [29].
(2) Driving Power—Dependence Analysis
Based on the driving power and dependence of each factor in the reachability matrix, the nine factors were divided into four quadrants (Table 4). Among them:
Strong Driving Factors (Driving Quadrant): Government Intervention and Technology Stock have high driving power and low dependence, being the primary focus of risk management. Enterprises should highly value policy-environment monitoring and technology-knowledge accumulation.
Strongly Dependent Factors (Dependent Quadrant): Enterprise Competition has low driving power and high dependence, being more the result of deep factors acting. Managers should look beyond this surface phenomenon to deeply analyze root problems.
Linkage Factors (Linkage Quadrant): Market Competition, Innovation Effort, Technology Assessment, and Financing Capability occupy intermediate positions, being both transmitters of driving power and bearers of dependence, acting as key nodes in risk transmission.

5.2. Comprehensive Weight Calculation Based on Anp-Entropy Method

5.2.1. Principle and Applicability of the Analytic Network Process (ANP)

The Analytic Network Process (ANP), proposed by Saaty [18], is a significant extension of his Analytic Hierarchy Process (AHP), applied to complex network structures. AHP assumes that system elements are independent of each other, forming a strict tree-like hierarchical structure. However, in reality, management system elements often have numerous dependencies and feedback relationships. ANP is designed precisely to handle such non-independent hierarchical structures. It allows cycles and feedback within the network. By constructing and calculating a “supermatrix,” it solves for comprehensive weights while considering the mutual influences among elements, thus being more consistent with the reality of management decision-making [27].

5.2.2. Construction of the ISM–ANP Network Structure Model

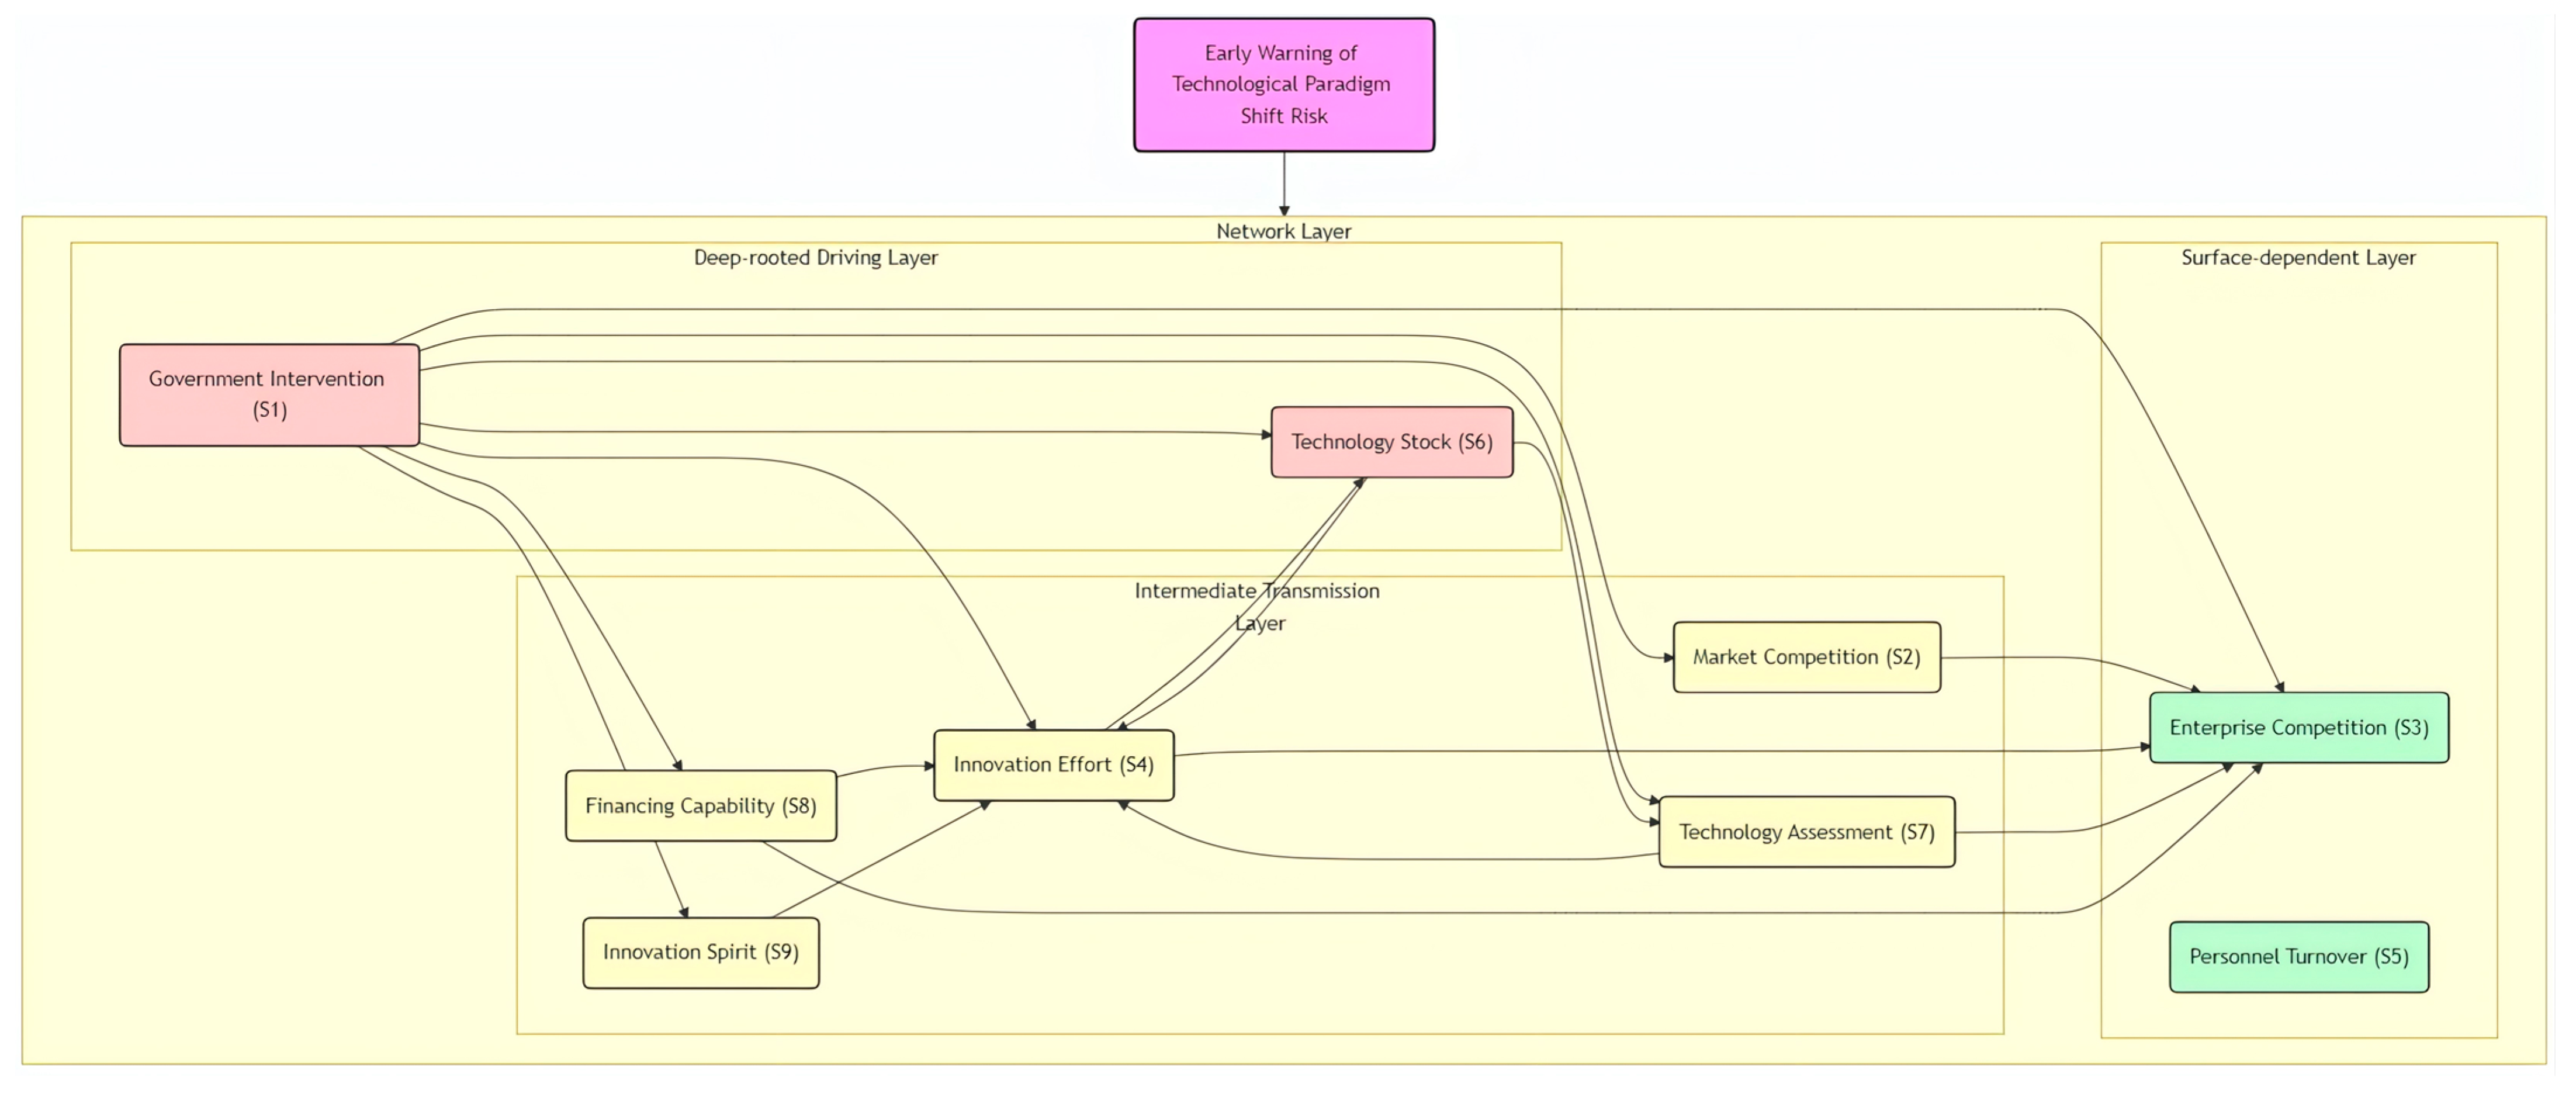
Based on the hierarchical structure and mutual influence relationships among factors revealed by the ISM model, an ANP network structure diagram was constructed (Figure 2). This network structure includes a control layer and a network layer: the control layer contains the overall goal (early warning of technological paradigm shift risk), and the network layer contains the nine early warning factors, with dependencies and feedback relationships among them.

5.2.3. ANP Weight Calculation Process

(1) Constructing Judgment Matrices
Using the 1–9 scale method (Table 5), ten experts were invited to perform pairwise comparisons of the relative importance among the factors in the network layer. Consistency tests were conducted on each expert’s judgment matrix; all CR values were less than 0.1, indicating good consistency of the judgment matrices.
(2) Constructing the Unweighted Supermatrix
The eigenvectors of each judgment matrix were used as column vectors of the matrix to construct the unweighted supermatrix W (Table 6). This matrix reflects the direct influence intensity among factors.
(3) Constructing the Weighted Supermatrix
Each column of the unweighted supermatrix was normalized to obtain the weighted supermatrix W ¯ . Each column of the weighted supermatrix sums up to 1.
(4) Calculating the Limit Supermatrix
The weighted supermatrix was raised to powers until the columns of the matrix stabilized, resulting in the limit supermatrix W . The columns of the limit supermatrix have identical values, representing the comprehensive weights of each factor (Table 7).

5.2.4. Objective Weight Correction Based on the Entropy Method

To compensate for the subjectivity of ANP, the objective entropy method was also used to calculate indicator weights. The entropy method determines weights based on the degree of dispersion of indicator data; the greater the data dispersion, the more information the indicator provides, and the larger its weight.
(1) Data Standardization
The data for the 30 indicators from the 208 questionnaires were standardized to eliminate dimensional effects.
(2) Calculating Information Entropy
The information entropy e i for the j-th indicator was calculated as ei = k pijln ( pij ) , where pij is the proportion of the i-th sample on the j-th indicator.
(3) Calculating Entropy Weights
The entropy weight W i for the j-th indicator was calculated as   Wi =   ( 1 ei )   /   ( 1 ei ) .

5.2.5. Comprehensive Weight Calculation

The final comprehensive weight of each indicator was calculated using linear weighting: W = α WANP   +   β WEntropy , where α and β are the coefficients for subjective and objective weights. Based on expert advice, this study uses α = 0.6 , β = 0.4 . The comprehensive weights for each early warning factor and indicator are shown in Table 8.

5.2.6. Analysis of Weight Calculation Results

At the factor level, Technology Assessment (0.164) has the highest weight, indicating that the ability to accurately forecast technology development direction, market prospects, and industry trends is central to managing technological paradigm shift risks. Enterprise Competition (0.152) and Innovation Effort (0.135) follow closely, reflecting the importance of the enterprise’s own competitiveness and innovation input [20,21,22]. Personnel Turnover (0.045) has the lowest weight, consistent with the conclusion from the ISM analysis that it belongs to the surface-dependent layer [26].
At the indicator level, Technology Development Forecast Level (TA1, 0.0558), Market Prospect Forecast Level (TA2, 0.0541), Industry Prospect Forecast Level (TA3, 0.0541), Innovation Input (TC1, 0.0459), and Financing Channels (FC1, 0.0478) have relatively higher weights and should be prioritized in risk monitoring [27,28].

5.3. Data Collection Procedure and Sample Selection

The empirical data for this study was collected through a rigorous mixed-method design to ensure both breadth and depth. First, a large-scale questionnaire survey was distributed to middle and senior managers in over 300 high-tech enterprises spanning multiple technology-intensive industries, yielding 208 valid responses. These survey responses provided the subjective assessment data for indicators such as “Innovation Awareness,” “Innovation Enthusiasm,” and “Market Management Level,” all measured on a 1–5 Likert scale. Second, objective firm-level data for these same 208 enterprises—including financial metrics such as “Financing Channels” and “Credit Rating,” and innovation metrics such as “Number of Patents Granted” and “R&D Personnel Turnover Rate”—were retrieved from the China Stock Market and Accounting Research (CSMAR) database and the Wind Financial Terminal. This dual-source approach allowed for cross-validation of subjective perceptions against objective operational data, enhancing the reliability of the dataset.
For the DAN model validation stage, a subset of 75 enterprises was purposively selected from the initial 208. The selection criteria were: (i) ensuring a balanced distribution across all five risk warning levels (No Warning to Extreme Warning) so that the model could be trained and tested on a representative spectrum of risk states and (ii) ensuring representation from three key manufacturing sub-sectors: high-end chemical manufacturing, automobile manufacturing, and integrated circuit and chip manufacturing, thereby capturing sectoral diversity within the high-tech domain. This purposive sampling strategy was essential for rigorously evaluating the model’s discriminative power across different risk levels and industrial contexts.

6. Construction of Intelligent Early Warning Model Based on DAN

6.1. Rationale and Operating Mechanism of the DAN Model

6.1.1. Rationale for Model Selection

Technological paradigm shift risk early warning is essentially a high-dimensional, nonlinear pattern recognition and anomaly detection problem. Traditional statistical early warning models are mostly based on linear or generalized linear assumptions, struggling to effectively capture the complex, nonlinear mapping relationship between early warning indicators and the health status of the technological paradigm. The Deep Autoencoder Network (DAN), as an important model in the field of deep learning, offers the following three major advantages [19]:
(1) Strong nonlinear processing capability: Through multiple layers of nonlinear transformations, DAN can automatically learn the essential low-dimensional features reflecting the health status of the technological paradigm from early warning indicators, overcoming the linear limitations of traditional models.
(2) Suitability for small-sample anomaly detection: DAN training mainly relies on data from “normal” or “healthy” states (i.e., no-warning or mild-warning enterprise samples). It identifies “anomalies” by learning “what is healthy.” This unsupervised learning mechanism reduces reliance on difficult-to-obtain large numbers of “high-risk crisis” samples, aligning better with the real data scenarios of enterprise early warning.
(3) Robustness: DAN has some tolerance for noise and random fluctuations in input data, enhancing the model’s anti-interference ability.
A legitimate and frequently raised concern regarding the use of deep learning models is the risk of overfitting, especially when training data is limited, as is the case here with 60 training samples. We address this concern through a multi-faceted approach: (i) The architecture’s low-dimensional bottleneck layer (with only 10 nodes) functions as a powerful information bottleneck, forcing the network to learn only the most salient, generalizable features of the data while discarding noise and idiosyncratic variation. This intrinsic regularization is a core design principle of autoencoders. (ii) During training, we explicitly incorporated L2 regularization (weight decay) on all hidden layers and employed early stopping based on a validation loss to halt training before the model could begin memorizing the training set. (iii) Most critically, we provide post hoc empirical evidence: an overfit model would fail to generalize to unseen data. The high classification accuracy achieved on the completely independent 15-enterprise test set serves as a direct validation of the model’s generalization capability.

6.1.2. Basic Structure of the DAN Model

The Deep Autoencoder Network (DAN) is an unsupervised neural network model. Its basic idea is to compress high-dimensional input data into a low-dimensional feature representation through an encoder, and then reconstruct the low-dimensional features back into the original input data through a decoder. The network learns the intrinsic features of the data by minimizing the reconstruction error between the input and output [20].
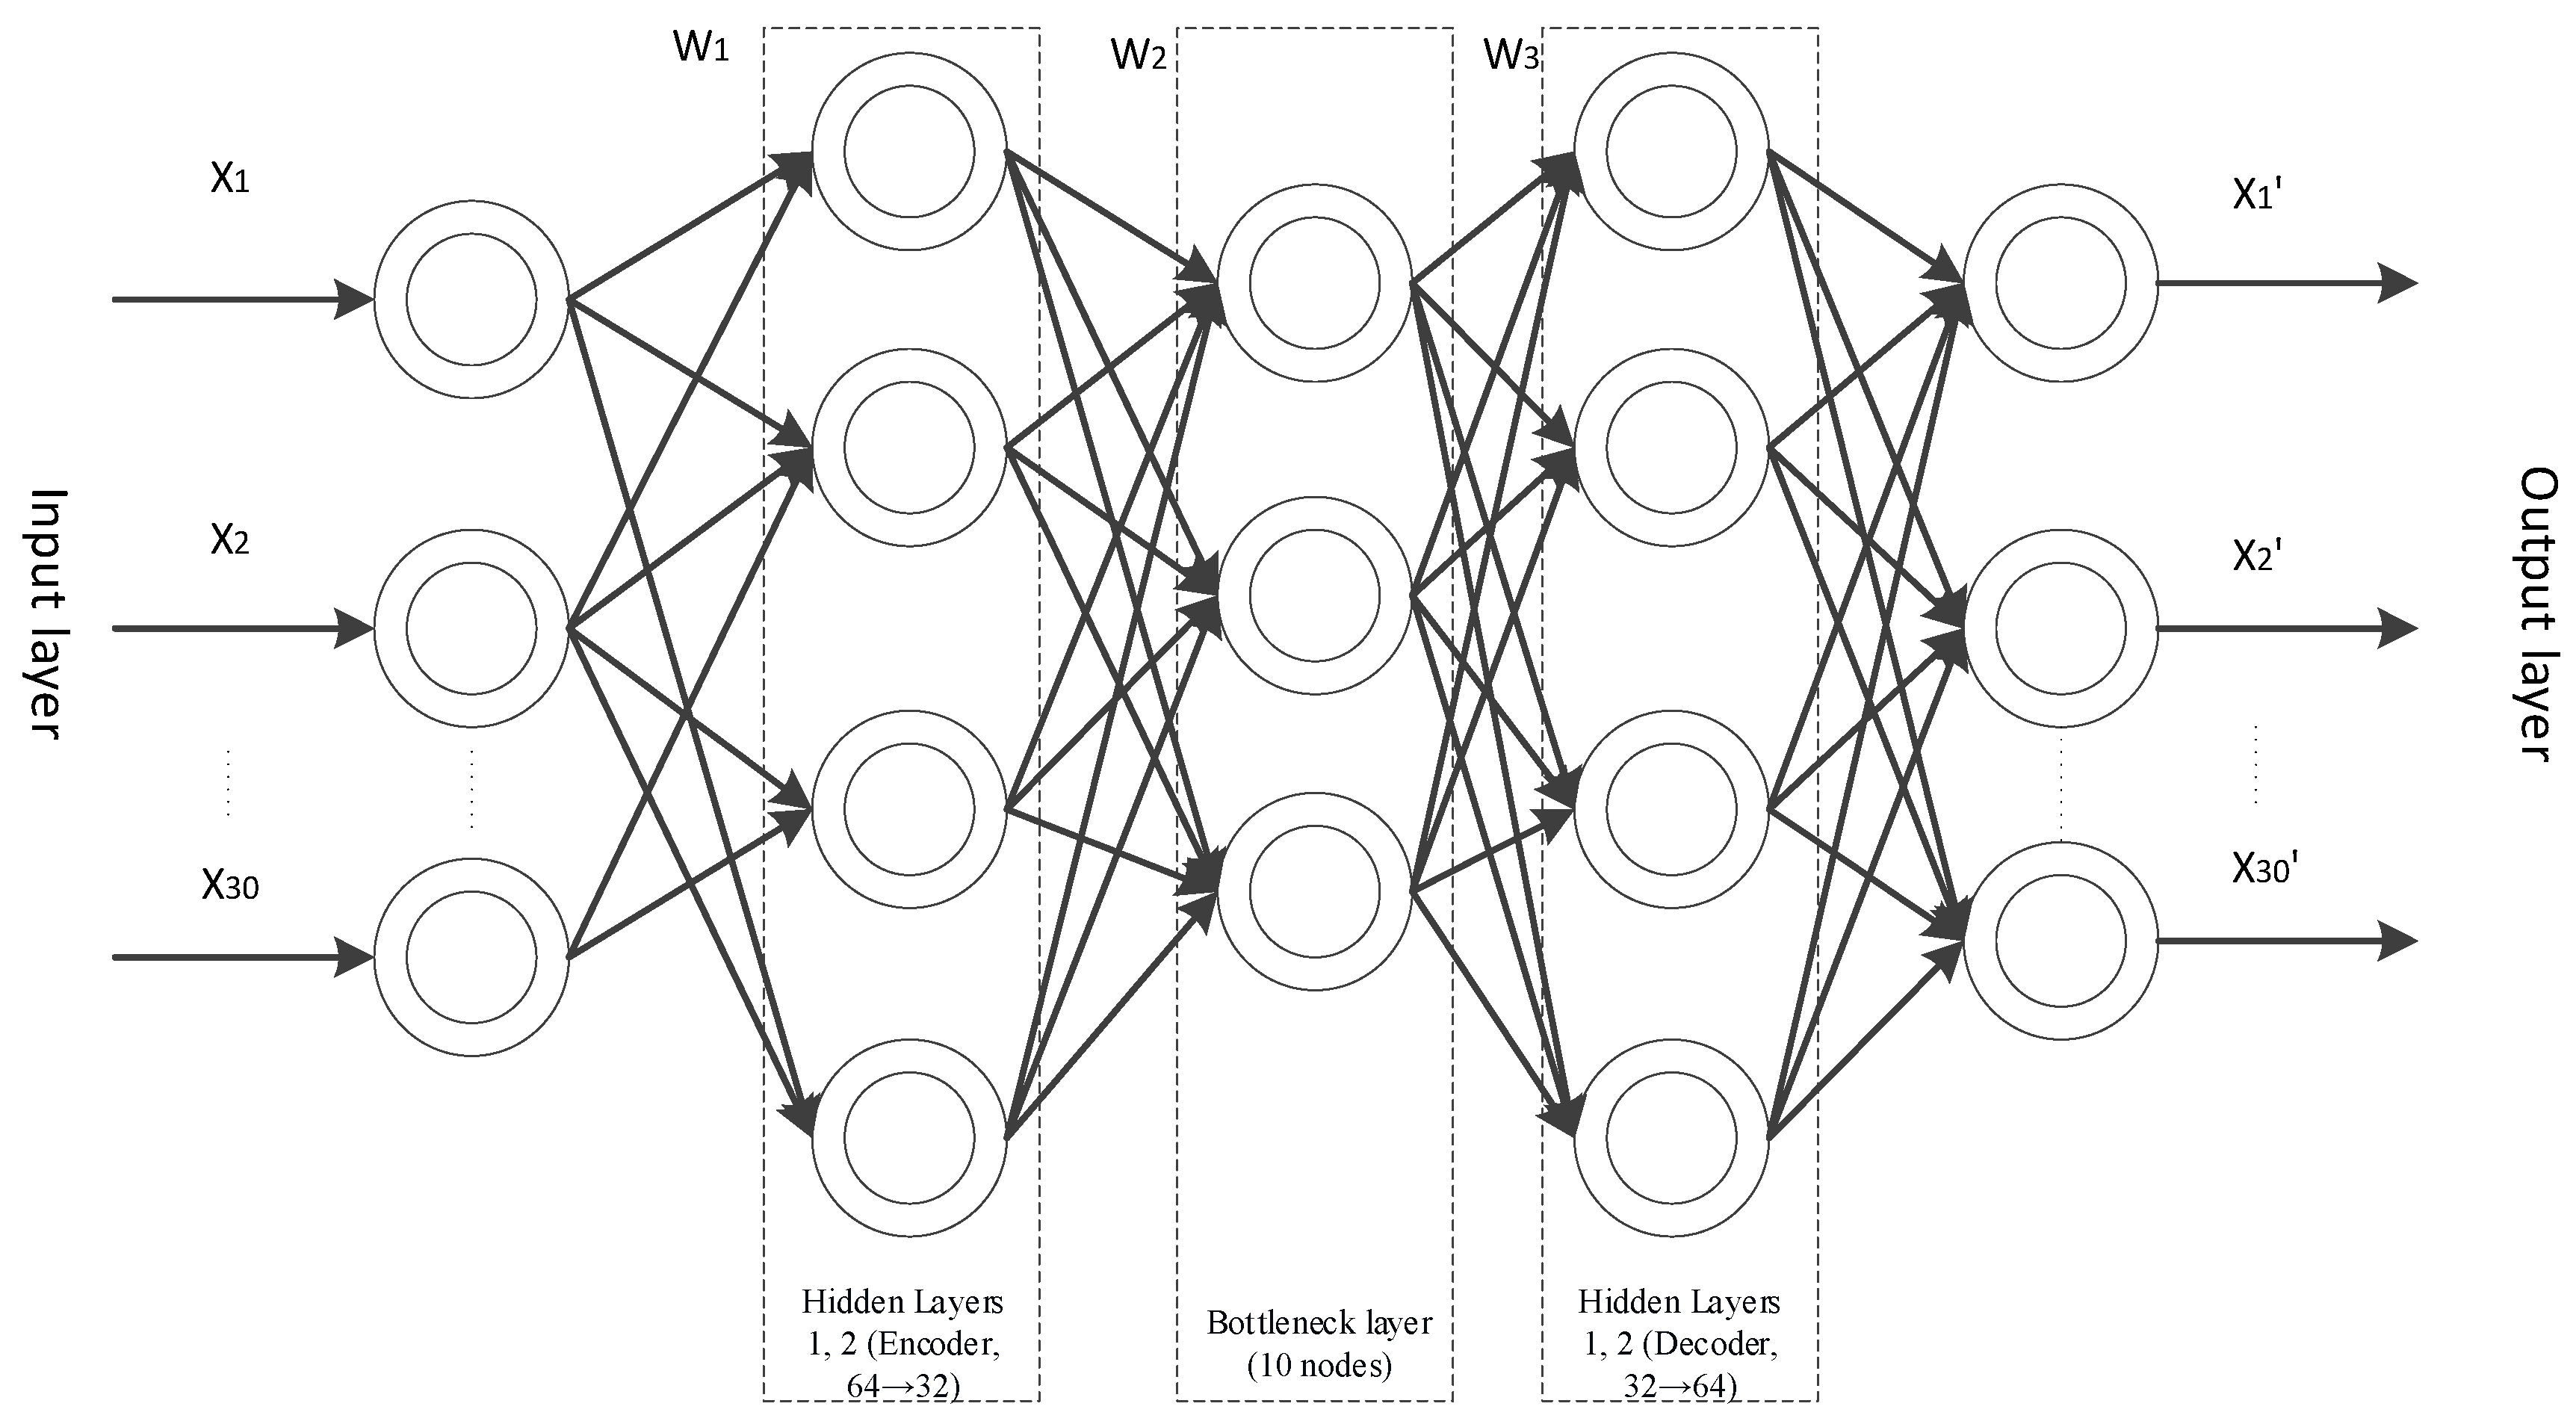
Figure 3 is a merged figure that illustrates both the general autoencoder structure and its specific application in this study. The encoder compresses the 30 input indicators into a 10-dimensional bottleneck representation; the decoder reconstructs the indicator values. The reconstruction error serves as the anomaly score for risk level determination.
The core structure of DAN is symmetric, typically consisting of an “encoder” and a “decoder”:
Encoder: Responsible for mapping the high-dimensional input data X through a series of nonlinear transformations to a low-dimensional, dense “bottleneck layer” (i.e., coding layer) Z = f ( w e X + b e ) . This process can be understood as “dimensionality reduction” and “feature extraction” of the original data, aiming to capture the most representative essential features.
Decoder: Responsible for reconstructing the low-dimensional code Z from the bottleneck layer back into the original input data X = g ( w d Z + b d ) through another series of nonlinear transformations.
Training Objective: Optimize the network parameters by minimizing the difference between the original input and the reconstructed output (i.e., reconstruction error) L = | | X X | | 2 . For a well-trained DAN, the code in the bottleneck layer effectively retains the most critical information from the original data, and the decoder can recover the general appearance of the data based on this key information.

6.2. Model Construction Process

The construction process of the technological paradigm shift risk early warning model based on DAN is as follows:
Step 1: Data Preprocessing. Collect data for the 30 early warning indicators from sample enterprises and perform standardization to eliminate dimensional effects.
Step 2: Warning Level Classification. Based on expert experience or historical data, classify enterprise technological paradigm risk into five levels: “No Warning,” “Mild Warning,” “Moderate Warning,” “Severe Warning,” and “Extreme Warning.”
Step 3: Dataset Partitioning. Divide the sample data into a training set and a prediction set. The training set is used for model training, and the prediction set is used for model validation.
Step 4: DAN Network Design. Determine parameters such as the number of input layer nodes (30), number of hidden layers, number of bottleneck layer nodes, number of output layer nodes (30), activation functions, and optimizer.
Step 5: Model Training. Input the training set data into the DAN model and iteratively optimize network parameters using the backpropagation algorithm until the reconstruction error converges.
Step 6: Threshold Setting. Based on the distribution of reconstruction errors in the training set, set threshold intervals for each warning level.
Step 7: Warning Output. For the enterprise to be assessed, input its indicator data into the trained DAN and calculate its reconstruction error. Determine its risk warning level based on which threshold interval the error falls into.

6.3. Empirical Study

6.3.1. Data Collection and Processing

This study selected 75 high-tech enterprises with varying operational conditions from the 208 sample enterprises as the empirical sample. These enterprises cover multiple technology-intensive industries such as high-end chemical manufacturing, automobile manufacturing, and integrated circuit and chip manufacturing, representing different stages of the technological paradigm shift process, offering good representativeness.
Data for the 30 early warning indicators of the 75 enterprises were collected and organized. Due to different dimensions among indicators, the Min-Max standardization method was used to map all indicator values to the [0, 1] interval. The standardization formula is: X = ( x x min ) ( x max x min ) .

6.3.2. Determination of Early Warning Indicator Observation Standards

Based on the early warning indicator system and combined with expert interviews, observation standards for each early warning indicator were determined. For each indicator, based on its actual observed value, its risk status was judged (Table 9).

6.3.3. Determination of Comprehensive Early Warning Level

The comprehensive early warning level refers to the overall judgment of an enterprise’s technological paradigm shift risk. This study used a weighted comprehensive method, summing the weighted risk level scores of each indicator to obtain a comprehensive risk index, and then determining the comprehensive warning level based on the index interval (Table 10).

6.3.4. Adaptive Early Warning Training Based on DAN

(1) Network Structure and Parameter Settings
The parameter settings for the DAN model constructed in this study are as follows:
Input layer: 30 nodes (corresponding to 30 early warning indicators)
Hidden layer 1: 64 nodes, activation function: ReLU
Hidden layer 2: 32 nodes, activation function: ReLU
Bottleneck layer: 10 nodes, activation function: ReLU
Hidden layer 4: 32 nodes, activation function: ReLU
Hidden layer 5: 64 nodes, activation function: ReLU
Output layer: 30 nodes, activation function: Sigmoid
Optimizer: Adam, learning rate: 0.001, with L2 regularization (weight decay = 1 × 10⁻⁴)
Loss function: Mean Squared Error (MSE)
Epochs: 200 (with early stopping patience = 20)
Batch size: 32
(2) Model Training
The 75 enterprise samples were divided into a training set (60 enterprises) and a prediction set (15 enterprises) using an 8:2 ratio. The training set contained enterprises with No Warning and Mild Warning levels, used for the model to learn the characteristic patterns of the “healthy” state.
During the model training process, the reconstruction error decreased rapidly and stabilized as the number of iterations increased. After approximately 120 iterations, the loss function value converged to approximately 0.02, suggesting that the model was successfully trained.
(3) Objective Threshold Setting and Sensitivity Analysis
To move beyond subjective expert judgment for threshold determination, an unsupervised K-Means clustering algorithm (K = 5) was applied to the reconstruction errors of all 75 enterprise samples. The natural boundaries between the five clusters were used to define the threshold intervals between the warning levels. This data-driven method ensures that the categorization of risk levels is based purely on the statistical structure of the model’s outputs, free from human bias. The resulting thresholds are: No Warning [0, 0.031), Mild Warning [0.031, 0.067), Moderate Warning [0.067, 0.124), Severe Warning [0.124, 0.201), and Extreme Warning [0.201, 1.0].
To validate the robustness of this threshold selection, a sensitivity analysis was performed comparing three methods: the K-Means approach, a Gaussian Mixture Model (GMM), and the original heuristic μ + 0.5σ expert-based method. The K-Means method yielded the highest F1-score (0.92) on the test set, justifying its final selection over the alternatives.
A comparison of the expected and actual outputs for the training set samples is shown in Table 11. The model’s warning level discrimination accuracy for the training set samples exceeded 95%, indicating that the model effectively learned the characteristic patterns of the “healthy” state.
(4) Prediction Results and Analysis
The 15 prediction set enterprise samples were input into the trained DAN model, the reconstruction error for each sample was calculated, and the warning level was determined based on the threshold intervals. The prediction results are shown in Table 12.
The prediction results show that 14 out of 15 enterprises had correct warning level discrimination, achieving an accuracy of 93.33%. The single incorrect judgment (Enterprise 071) had an actual level of Mild Warning but was classified as Moderate Warning by the model, an error within an acceptable range. It should be noted that the small test set size (N = 15) limits the statistical power of this accuracy estimate, and the results should be interpreted as a promising initial validation rather than a definitive measure of generalizability. However, the absence of any missed high-severity warnings—no Severe or Extreme cases were misclassified as lower-level warnings—is an encouraging indicator of the model’s practical safety for deployment.
(5) Model Performance Evaluation
From the perspective of early warning effectiveness, the DAN model demonstrated promising performance:
Training set accuracy: above 95%;
Prediction set accuracy: 93.33%;
Miss rate: 0% (no cases where Severe Warning or Extreme Warning samples were misclassified as No Warning or Mild Warning);
False alarm rate: 6.67% (only one case of Mild Warning misclassified as Moderate Warning).
(6) Comparative Performance Analysis with Baseline Models
To rigorously validate the choice of the deep autoencoder architecture over more traditional small-sample classifiers, we conducted a comparative benchmarking analysis. The DAN model was evaluated against two widely used algorithms suitable for small datasets: a One-Class Support Vector Machine (SVM) with a radial basis function kernel, and a Random Forest classifier with 100 trees. For a fair comparison, Principal Component Analysis (PCA) was used as a preprocessing step to reduce dimensionality to 10 components for both baseline models, mirroring the DAN’s bottleneck dimension. The models were trained on the same 60-enterprise training set and evaluated on the same 15-enterprise test set using macro-averaged precision, recall, and F1-score.
The results, presented in Table 13, demonstrate that the DAN model achieves the highest performance across all metrics, with an accuracy of 93.33% and a macro F1-score of 0.92. The next best model, Random Forest, achieved 86.67% accuracy and a F1-score of 0.85, while the One-Class SVM trailed at 73.33% and 0.70 respectively. This empirical evidence directly addresses the concern of overfitting: a model that had simply memorized the training data would not outperform simpler, robust algorithms on an independent test set. The DAN’s superior performance indicates that it is genuinely learning a useful, generalizable latent representation of the technological paradigm’s health state for this dataset.

7. Conclusion and Future Research Directions

7.1. Main Research Conclusions

Based on a systematic identification of early warning factors for technological paradigm shift risks, this study constructed and validated an intelligent early warning model integrating the ISM–ANP-entropy method and a DAN deep learning network. The findings directly address the three research questions posed at the outset of this paper:
Response to RQ1 (Hierarchical Structure and Transmission Paths): The ISM model successfully divided the nine early warning factors into a clear three-level structure: a deep-rooted driving layer (Government Intervention, Technology Stock), an intermediate transmission layer (Market Competition, Innovation Effort, Technology Assessment, Financing Capability, Innovation Spirit), and a surface-dependent layer (Enterprise Competition, Personnel Turnover). This structure reveals the transmission path of risks from fundamental policy and knowledge-stock drivers, through intermediate organizational and market mechanisms, to eventual manifestation in competitive performance and personnel stability. The driving-dependence analysis further confirms Government Intervention and Technology Stock as the system’s strongest drivers, providing theoretical guidance for enterprises to identify root causes rather than treating surface symptoms.
Response to RQ2 (Scientific Weight Determination): The integrated ANP-entropy method effectively synthesized subjective expert judgment with the objective information embedded in the sample data. The calculations identified Technology Assessment (0.164), Enterprise Competition (0.152), and Innovation Effort (0.135) as the three highest-weighted factors. At the indicator level, Technology Development Forecast Level, Market Prospect Forecast Level, Industry Prospect Forecast Level, Innovation Input, and Financing Channels emerged as the most critical metrics. This weighting scheme, which accounts for both mutual influences among factors (the ANP advantage) and data dispersion (the entropy advantage), provides a scientifically grounded prioritization for risk-monitoring resource allocation.
Response to RQ3 (Intelligent Early Warning Model): The DAN model demonstrated high efficacy in classifying technological paradigm risk levels under small-sample, nonlinear conditions. Empirical testing yielded a 93.33% accuracy on the 15-enterprise prediction set, with a zero miss rate for high-severity warnings. The comparative analysis showed that the DAN model significantly outperformed traditional small-sample algorithms (One-Class SVM, Random Forest) in both accuracy and F1-score, providing empirical evidence that the autoencoder is learning a generalizable feature representation rather than overfitting to the training data. The model’s unsupervised learning mechanism, which relies primarily on “healthy” state data, makes it practically viable for real-world scenarios where high-risk cases are historically rare.

7.2. Theoretical Contributions

The theoretical contributions of this paper are threefold:
(1) Structural analysis of early warning factors. By introducing ISM into the study of technological paradigm shift risk early warning, this research moves beyond the traditional “factor list” approach common in prior studies [4,5,7]. The revealed three-level hierarchy and driving-dependence relationships provide a new structural perspective for understanding how risks propagate through a complex innovation system, confirming and formalizing the transmission mechanisms that earlier research could only hypothesize.
(2) Methodological innovation in weight determination. Unlike previous weighting studies that either relied on AHP’s independence assumption [10] or used purely objective entropy methods that ignore expert causal knowledge [12,30,31,32], the ANP-entropy integration developed here explicitly models the network of dependencies uncovered by ISM while simultaneously adjusting weights based on objective data dispersion. This synthesis overcomes the limitations of single weighting paradigms and offers a more scientifically robust approach for multi-criteria decision-making in interconnected risk systems.
(3) Expansion of deep learning applications in risk early warning. By applying the DAN model to technological paradigm risk assessment and rigorously benchmarking it against traditional small-sample classifiers, this study challenges the prevailing assumption that deep learning is unsuitable for small datasets [13,19,20,33,34]. The results demonstrate that, with appropriate architectural design (particularly the information bottleneck) and regularization, deep autoencoders can outperform conventional methods even with modest training data, thus opening a new technical pathway for intelligent risk early warning in domains where large labeled datasets are unavailable.

7.3. Management Implications

Based on the above research conclusions, this paper offers the following management implications for managers of high-tech enterprises:
(1) Establish a risk transmission path diagnosis mechanism. According to the hierarchical structure of the ISM model, when surface-level indicators such as Enterprise Competition and Personnel Turnover show anomalies, managers should not focus only on the symptoms but deeply analyze deep driving factors such as Technology Stock and Government Intervention to solve problems at their root.
(2) Implement differentiated risk-management strategies. Based on the weight calculation results, Technology Assessment, Enterprise Competition, and Innovation Effort should be prioritized in risk management. Specifically: strengthen technology development forecasting capabilities, enhance judgment of market prospects and industry trends; continuously monitor changes in enterprise market share and overall competitiveness; and ensure the sustainability and stability of R&D investment.
(3) Build an intelligent risk early warning system. Enterprises can embed the DAN model constructed in this study into their management information systems to achieve automated and intelligent monitoring of technological paradigm risks. When the system outputs an early warning signal, it should automatically trigger a diagnostic procedure, pushing risk information and recommended actions to relevant management personnel.
(4) Establish a dynamic risk threshold adjustment mechanism. As the enterprise’s internal and external environment changes, risk thresholds should also be adjusted dynamically. Enterprises should periodically evaluate the early warning effectiveness of the model and optimize threshold settings and model parameters based on actual conditions to ensure the continued effectiveness of the early warning system.
(5) Account for industry heterogeneity in deployment. The model was trained primarily on manufacturing-sector data. When applying the system to other high-tech industries such as biotechnology or software, managers should exercise caution. The indicator weights, reconstruction error baselines, and risk thresholds may require recalibration using sector-specific data. A cross-industry validation study should precede any broad deployment.

7.4. Limitations and Future Research Directions

This study has the following limitations, which require further research:
(1) The sample size needs to be expanded. The empirical sample of this study is 75 enterprises, with 60 used for training and only 15 for testing. Impact on conclusions: The reported 93.33% accuracy should be viewed as a promising initial validation rather than definitive proof of generalizability across the entire high-tech sector. A single misclassification in the small test set accounted for a 6.67% error rate, underscoring the limited statistical power of the current evaluation. Future research should expand the sample scale substantially, incorporating data from more industries and regions, and employ k-fold cross-validation to obtain more robust performance estimates.
(2) Model interpretability needs to be enhanced. As a deep learning model, the “black box” nature of the DAN model’s decision-making process limits managers’ understanding and trust. Impact on conclusions: This limitation may hinder the practical adoption of the model in high-stakes strategic decisions where explainability is paramount. However, it does not invalidate the model’s demonstrated predictive capability. Future research could introduce interpretability techniques such as attention mechanisms or SHAP (SHapley Additive exPlanations) analysis to provide post hoc explanations for the model’s risk assessments.
(3) Dynamic learning mechanisms need improvement. This model is a static trained model and cannot adapt to continuous changes in the enterprise’s internal and external environment. Impact on conclusions: The model’s predictive accuracy may degrade over time as the technological landscape evolves. The current findings represent a snapshot of model performance and do not guarantee sustained efficacy without periodic retraining. Future research could explore online learning mechanisms, enabling the model to update dynamically with new data, achieving truly adaptive early warning.
(4) Intervention effectiveness research needs to be conducted. This study focused on risk identification and early warning. Impact on conclusions: The absence of an intervention linkage means the study addresses only the diagnostic phase of risk management. The practical value of the early warning system cannot be fully realized until it is integrated with a response protocol. Future research could further explore intervention mechanisms under different risk levels, forming a complete management closed loop of “early warning–diagnosis–intervention” and validating the practical application effectiveness of the early warning model through longitudinal field studies.
(5) Transferability across industries requires investigation. The model was developed and tested on enterprises from three manufacturing sub-sectors. Its direct applicability to other high-tech industries such as biotechnology, software, or renewable energy cannot be assumed. Impact on conclusions: The reported model performance and the identified factor weights may be specific to the manufacturing context and may not generalize to industries with fundamentally different innovation dynamics, regulatory environments, or risk profiles. Future research should explicitly test for industry heterogeneity by applying the model across diverse high-tech sectors and analyzing moderation effects. If significant differences are found, industry-specific model adaptations may be required.

Author Contributions

Conceptualization, Y.W. and N.L.; methodology, Y.W.; software, Y.W.; validation, Y.W. and N.L.; formal analysis, Y.W.; investigation, Y.W.; resources, N.L.; data curation, Y.W.; writing—original draft preparation, Y.W.; writing—review and editing, N.L.; visualization, Y.W.; supervision, N.L.; project administration, N.L.; funding acquisition, Y.W. All authors have read and agreed to the published version of the manuscript.

Funding

This research was funded by the Natural Science Foundation of China, grant number 71473119. The APC was funded by the Natural Science Foundation of China, grant number 71473119.

Institutional Review Board Statement

Not applicable.

Informed Consent Statement

Not applicable.

Data Availability Statement

The survey data presented in this study are not publicly available due to privacy restrictions. The financial and patent data from CSMAR and Wind databases are available from the respective data providers with appropriate licenses.

Acknowledgments

The authors would like to thank the experts who participated in the Delphi survey and the enterprises that provided data.

Conflicts of Interest

The authors declare no conflicts of interest.

References

  1. Zhang, Y.Y.; Wang, X.M.; Feng, R.G. The Realization Mechanism of Leapfrog Upgrading of China’s Equipment Manufacturing Enterprises. Sci. Technol. Prog. Policy 2023, 40, 92–100. [Google Scholar] [CrossRef]
  2. Weng, Y.H.; Li, N.; Wang, J.A. Analysis of Technology Paradigm Shift Early Warning Model Based on Dynamic Perspective of Complex System Dynamics. J. Ind. Technol. Econ. 2020, 39, 152–160. Available online: http://dx.chinadoi.cn/10.3969/j.issn.1004-910X.2020.05.018 (accessed on 1 June 2026).
  3. Dosi, G. Technological paradigms and technological trajectories. Res. Policy 1982, 11, 147–162. [Google Scholar] [CrossRef] [Scilit]
  4. Henderson, R.M.; Clark, K.B. Architectural Innovation: The Reconfiguration of Existing Product Technologies and the Failure of Established Firms. Adm. Sci. Q. 1990, 35, 9–30. [Google Scholar] [CrossRef] [Scilit]
  5. Christensen, C.M. The Innovator’s Dilemma; Harvard Business School Press: Boston, MA, USA, 1997. [Google Scholar]
  6. Teece, D.J. Explicating dynamic capabilities. Strateg. Manag. J. 2007, 28, 1319–1350. [Google Scholar] [CrossRef] [Scilit]
  7. Leonard-Barton, D. Core capabilities and core rigidities. Strateg. Manag. J. 1992, 13, 111–125. [Google Scholar] [CrossRef] [Scilit]
  8. Cohen, W.M.; Levinthal, D.A. Absorptive capacity: A new perspective on learning and innovation. Adm. Sci. Q. 1990, 35, 128–152. [Google Scholar] [CrossRef] [Scilit]
  9. Ohlson, J.A. Financial ratios and the probabilistic prediction of bankruptcy. J. Account. Res. 1980, 18, 109–131. [Google Scholar] [CrossRef] [Scilit]
  10. Saaty, T.L. The Analytic Hierarchy Process; McGraw-Hill: New York, NY, USA, 1980. [Google Scholar]
  11. Saaty, T.L. Decision Making with Dependence and Feedback: The Analytic Network Process; RWS Publications: Pittsburgh, PA, USA, 1996. [Google Scholar]
  12. Shannon, C.E. A mathematical theory of communication. Bell Syst. Tech. J. 1948, 27, 379–423. [Google Scholar] [CrossRef] [Scilit]
  13. Hinton, G.E.; Salakhutdinov, R.R. Reducing the dimensionality of data with neural networks. Science 2006, 313, 504–507. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  14. Su, C.; Wang, J.; Wang, X.; Li, Z. Robustness analysis of clustered mine cyber-physical system considering node overload and underload under cascading failure. Proc. Inst. Mech. Eng. Part O J. Risk Reliab. 2026, 1–16. [Google Scholar] [CrossRef] [Scilit]
  15. Zhang, Q.; Wang, X.; Su, C.; Liu, J. Research on the Complex Network Characteristics and Driver Paths of Virtual Agglomeration in Manufacturing. J. Syst. 2026, 14, 426. [Google Scholar] [CrossRef] [Scilit]
  16. Warfield, J.N. Structuring Complex Systems; Battelle Monograph Series; Battelle Memorial Institute: Columbus, OH, USA, 1973; Volume 4, pp. 1–30. [Google Scholar]
  17. Wang, Y.L. Systems Engineering Theory, Methods and Applications; Higher Education Press: Beijing, China, 2008. [Google Scholar]
  18. Saaty, T.L. Fundamentals of the analytic network process. J. Syst. Sci. Syst. Eng. 2004, 13, 129–157. [Google Scholar] [CrossRef] [Scilit]
  19. Hinton, G.E.; Osindero, S.; Teh, Y.W. A fast learning algorithm for deep belief nets. Neural. Comput. 2006, 18, 1527–1554. [Google Scholar] [CrossRef] [Scilit] [PubMed]
  20. Bengio, Y.; Lamblin, P.; Popovici, D.; Larochelle, H. Greedy layer-wise training of deep networks. In Advances in Neural Information Processing Systems 19; Schölkopf, B., Platt, J., Hofmann, T., Eds.; MIT Press: Cambridge, MA, USA, 2007; pp. 153–160. [Google Scholar]
  21. Wang, J.A.; Liu, D.; Shen, Y. Discussion on Technological Paradigm Transformation Foresight Based on the Perspective of Technology Ecology. Sci. Technol. Manag. Res. 2015, 35, 32–37. [Google Scholar] [CrossRef]
  22. Hou, J.T.; Wen, Z.L.; Cheng, Z.J. Structural Equation Modeling and Its Applications; Educational Science Publishing House: Beijing, China, 2004. [Google Scholar]
  23. Hinkin, T.R. A brief tutorial on the development of measures for use in survey questionnaires. J. Organ. Res. Methods 1998, 1, 104–121. [Google Scholar] [CrossRef] [Scilit]
  24. Zhang, H.; Tian, M.F. Application of reliability analysis in questionnaire design. Stat. Decis. 2007, 21, 25–27. [Google Scholar] [CrossRef]
  25. Schot, J.; Geels, F.W. Strategic niche management and sustainable innovation journeys. Technol. Anal. Strateg. Manag. 2008, 20, 537–554. [Google Scholar] [CrossRef] [Scilit]
  26. Yin, Z.F.; Liu, M.Y.; Deng, Y.Y.; Shen, Y. R & D investment, innovation outsourcing and technology protection strategy. Stud. Sci. Sci. 2022, 40, 81–90. [Google Scholar] [CrossRef]
  27. Arthur, W.B. Competing technologies, increasing returns, and lock-in by historical events. Econ. J. 1989, 99, 116–131. [Google Scholar] [CrossRef] [Scilit]
  28. Wu, J.L.; Liu, Y.T.; Wang, S.S. How can incumbents achieve disruptive technological innovation. China Soft Sci. 2024, 42, 2434–2444. [Google Scholar] [CrossRef]
  29. Ran, Z.; Zheng, J.H. Innovative Development in the Technological Paradigm: A Study of the Economic Growth Effects of Technological Diversification and Technological Specialisation. Manag. World. 2024, 40, 1–20+59+21–24. [Google Scholar] [CrossRef]
  30. Yu, C.P.; Ye, B.S.; Lin, C.P. “High-Middle-Base” Transmitting Mechanism of Enterprise Management Innovation. R&D Manag. 2023, 35, 172–185. [Google Scholar]
  31. He, J. The Role of Government in Catching Up and Surpassing Emerging Technology Industries. Soc. Sci. China 2022, 11, 105–124+206–207. [Google Scholar]
  32. Glansdorff, P.; Prigogine, I. Thermodynamic Theory of Structure, Stability and Fluctuations; Wiley-Interscience: London, UK, 1971. [Google Scholar]
  33. Ding, H.Y.; Li, B.Y.; He, X. CEO Power, Financing Constraints and R&D Investment—Based on the Empirical Evidence of Listed Companies in China. J. Ind. Technol. Econ. 2020, 39, 78–85. [Google Scholar]
  34. Liu, H.B.; Xu, Q.R. Latecomer firms strategy evolution, innovation paradigm and capabilities evolution. Stud. Sci. Sci. 2018, 36, 1442–1454. [Google Scholar] [CrossRef]
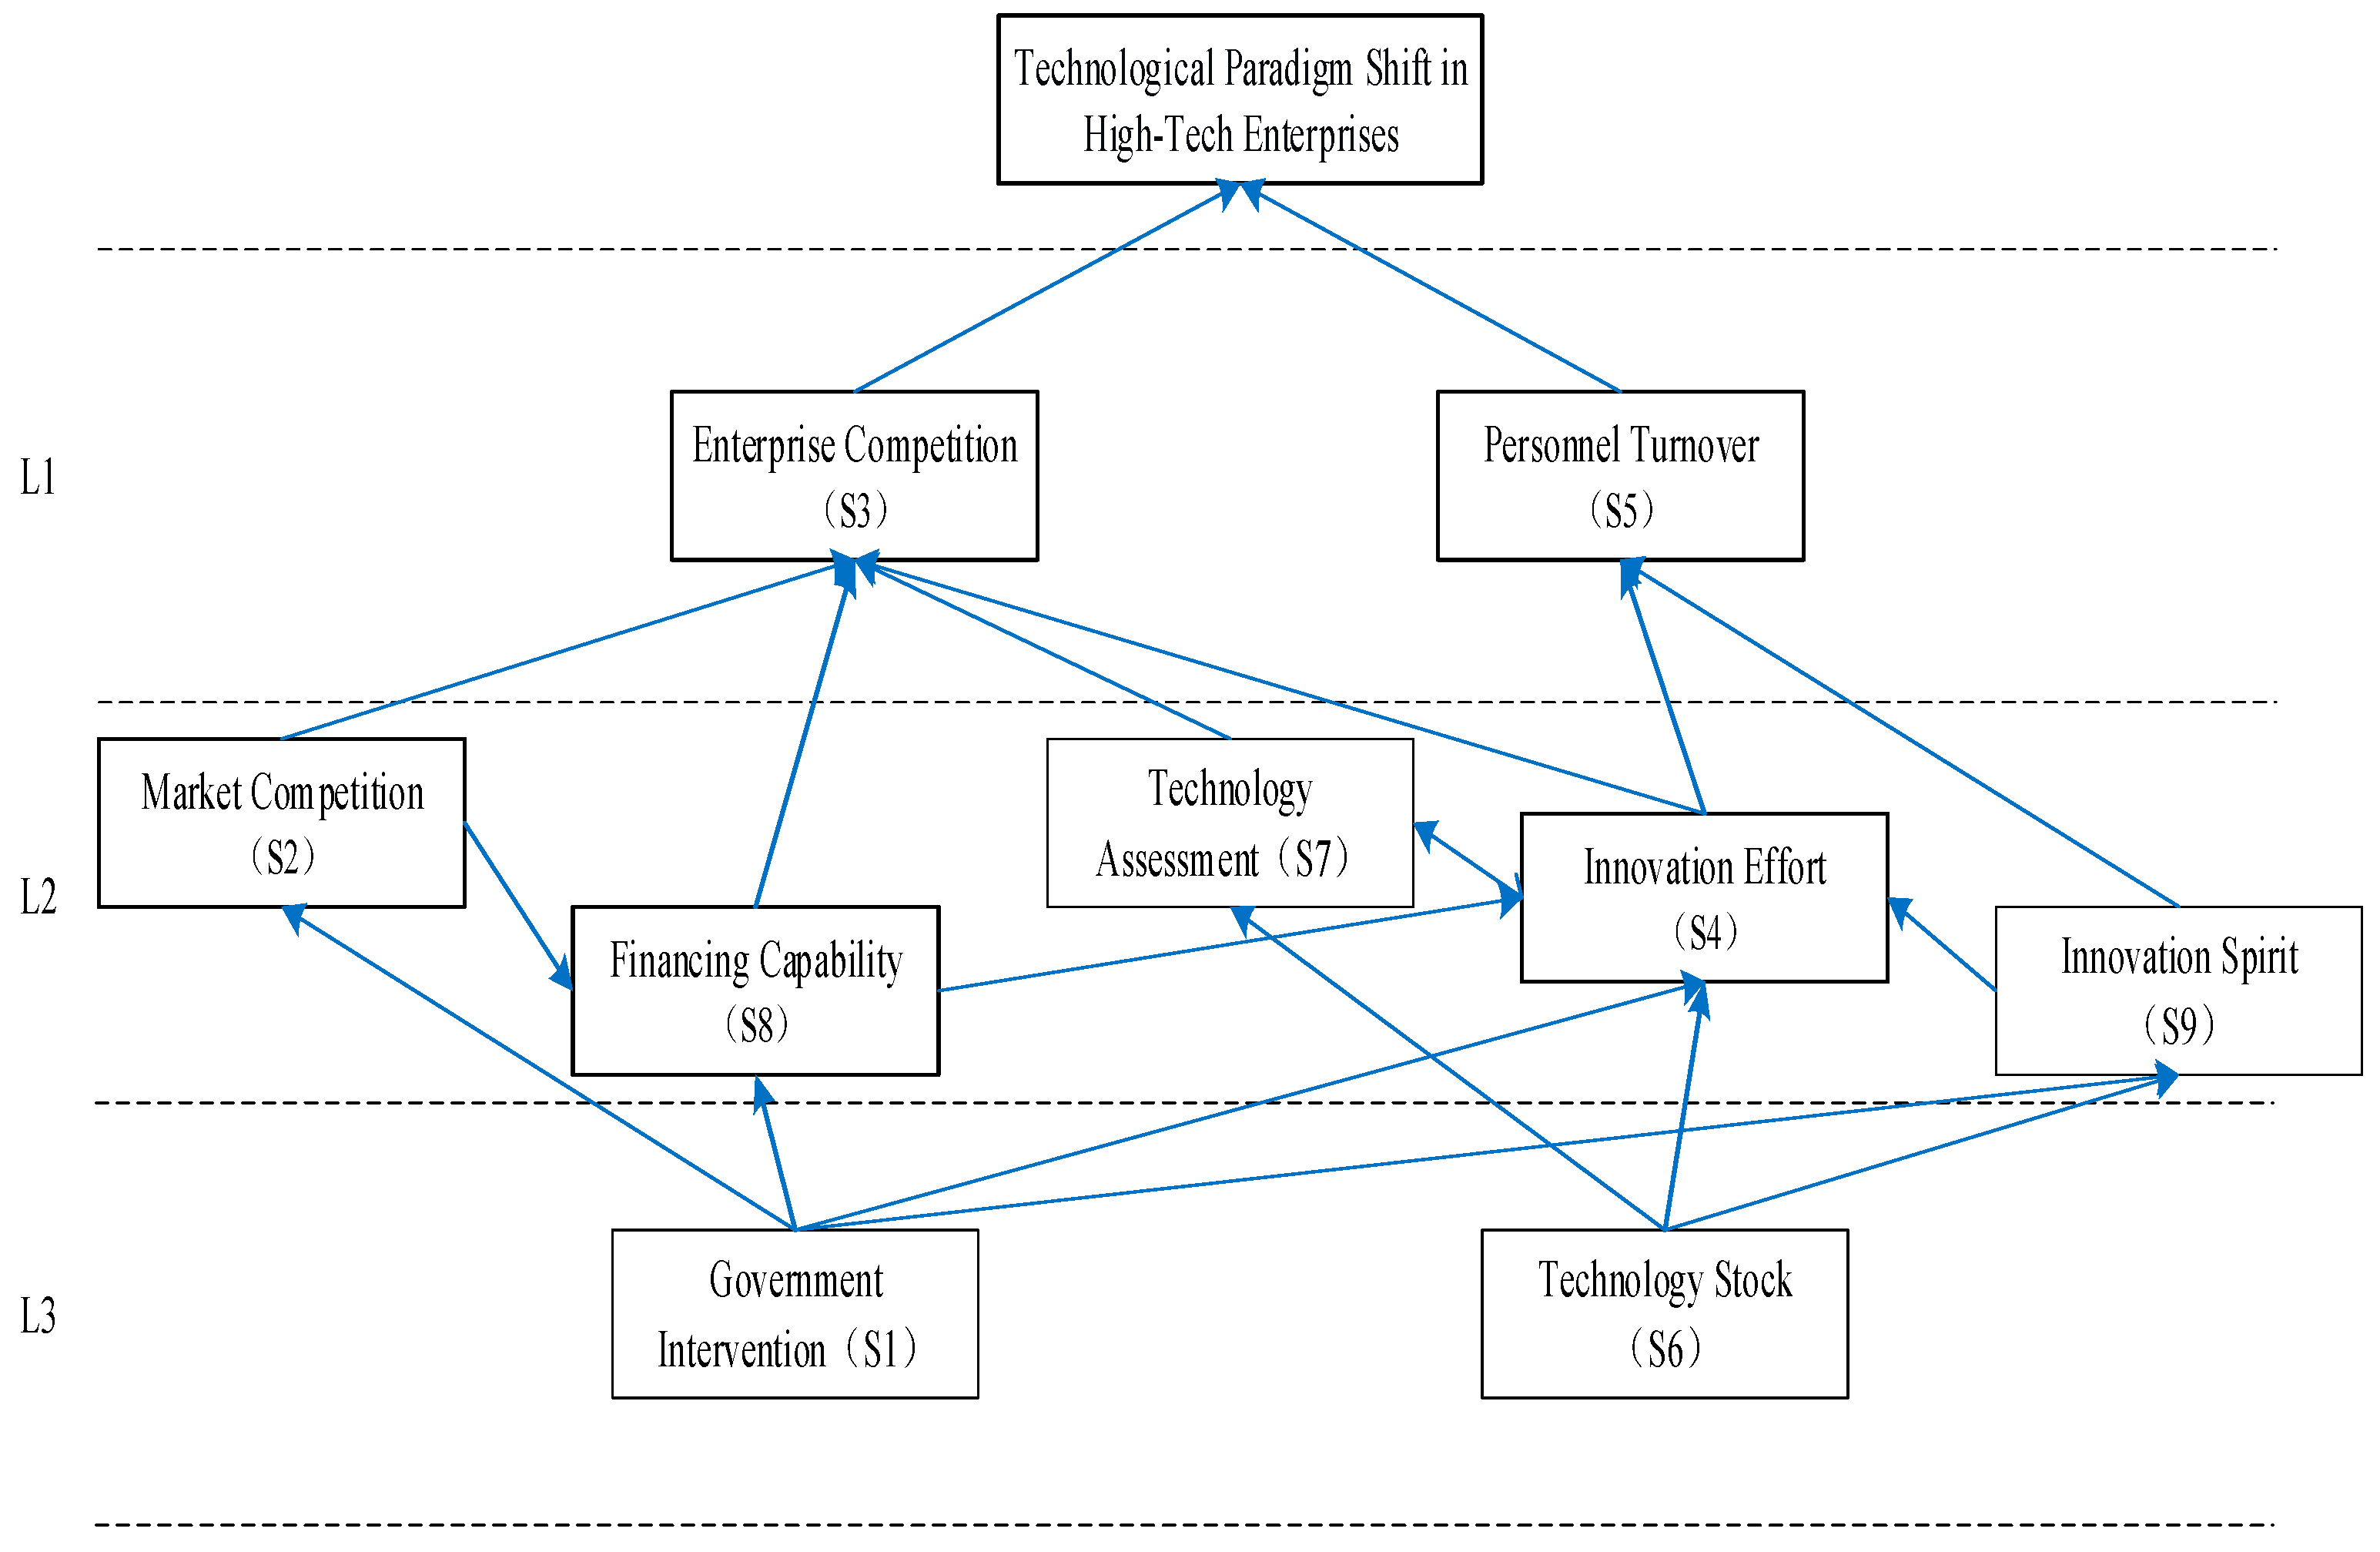
Figure 1. Hierarchical structure model of early warning factors for technological paradigm shift in high-tech enterprises. Note: Hierarchical structure model of early warning factors. Arrows indicate a direct influence from one factor to another. The diagram illustrates both direct and indirect transmission paths from deep-rooted driving factors to surface-level dependent factors across the three levels.
Systems 14 00790 g001
Figure 2. ISM–ANP network structure. Note: The model consists of a control layer (goal) and a network layer divided into three levels: deep driving layer, intermediate conduction layer, and surface dependence layer. Arrows represent influence relationships. Forward solid lines indicate forward-driving dependencies from lower to upper levels. Reverse solid lines represent feedback loops, for instance, where surface-level ‘Enterprise Competition’ can subsequently influence an intermediate factor like ‘Innovation Effort’ in a later strategic cycle.
Systems 14 00790 g002
Figure 3. Schematic diagram of the autoencoder structure and application to the 30-dimensional indicator data.
Systems 14 00790 g003
Table 1. Early warning indicator system for technological paradigm shift risks in high-tech enterprises.
Signal SourceEarly Warning FactorEarly Warning Indicators
Social SourceGovernment Intervention (S1)Policies and Regulations (GF1), Market Management Level (GF2), Government Behavior (GF4)
Market SourceMarket Competition (S2)Industry Competition Level (MF2), Supply Chain Stability (MF3), Market Concentration (MF4)
Enterprise Competition (S3)Overall Enterprise Capability (CF1), Enterprise Market Share (CF2), Competitors (CF3), Leading Product Competitiveness (CF4)
Management SourceInnovation Effort (S4)Innovation Input (TC1), Innovation Awareness (TC2), Innovation Enthusiasm (TC3)
Personnel Turnover (S5)Tenure of Senior Executives (IM1), Tenure of Middle Managers (IM2), R&D Personnel Turnover (IM4)
Technical SourceTechnology Stock (S6)Number of Patent Inventions (IR2), Number of Patents Granted (IR3), Other R&D Achievements (IR4), Technology Accumulation (IR5)
Technology Assessment (S7)Technology Development Forecast Level (TA1), Market Prospect Forecast Level (TA2), Industry Prospect Forecast Level (TA3)
Financial SourceFinancing Capability (S8)Financing Channels (FC1), Credit Rating (FC2)
Cultural SourceInnovation Spirit (S9)Institutional Innovation (IS1), Frequency of Corporate Policy Changes (IS2), Flatness Level (IS3), Division of Authority (IS4), Product Update Intensity (IS5)
Table 2. Adjacency matrix of early warning factors.
FactorS1S2S3S4S5S6S7S8S9
S1 Government Intervention011101111
S2 Market Competition001000000
S3 Enterprise Competition000000000
S4 Innovation Effort001001000
S5 Personnel Turnover000000000
S6 Technology Stock000100100
S7 Technology Assessment001100000
S8 Financing Capability001100000
S9 Innovation Spirit000100000
Table 3. Reachability matrix of early warning factors.
FactorS1S2S3S4S5S6S7S8S9
S1 Government Intervention111101111
S2 Market Competition011000000
S3 Enterprise Competition001000000
S4 Innovation Effort001101000
S5 Personnel Turnover000010000
S6 Technology Stock000101100
S7 Technology Assessment001100100
S8 Financing Capability001100010
S9 Innovation Spirit000100001
Table 4. Driving power–dependence results of early warning factors.
FactorDriving PowerDependenceQuadrant
S1 Government Intervention81Driving
S2 Market Competition32Linkage
S3 Enterprise Competition14Dependent
S4 Innovation Effort44Linkage
S5 Personnel Turnover11Autonomous
S6 Technology Stock52Driving
S7 Technology Assessment43Linkage
S8 Financing Capability32Linkage
S9 Innovation Spirit22Autonomous
Table 5. Judgment criteria of the 1–9 scale method.
ScaleDefinition
1Equal importance
3Moderate importance
5Strong importance
7Very strong importance
9Extreme importance
2, 4, 6, 8Intermediate values
ReciprocalIf factor i has a value aij compared to factor j, then factor j has a value 1 aij compared to factor i
Table 6. Unweighted supermatrix of early warning factors (partial).
FactorS1S2S3S4S5S6S7S8S9
S1 Government Intervention0.000.250.200.150.200.180.220.250.20
S2 Market Competition0.300.000.250.200.150.120.180.200.15
S3 Enterprise Competition0.250.350.000.300.250.200.250.250.20
S4 Innovation Effort0.200.150.250.000.200.250.200.150.25
S5 Personnel Turnover0.050.050.100.050.000.050.050.050.10
S6 Technology Stock0.100.080.100.150.100.000.050.050.05
S7 Technology Assessment0.050.070.050.100.050.150.000.050.05
S8 Financing Capability0.030.030.030.030.030.030.030.000.00
S9 Innovation Spirit0.020.020.020.020.020.020.020.000.00
Table 7. Limit supermatrix of early warning factors.
FactorWeight
S1 Government Intervention0.098
S2 Market Competition0.087
S3 Enterprise Competition0.152
S4 Innovation Effort0.135
S5 Personnel Turnover0.045
S6 Technology Stock0.082
S7 Technology Assessment0.164
S8 Financing Capability0.092
S9 Innovation Spirit0.089
Table 8. Weights of the early warning indicator system.
Signal SourceEarly Warning FactorFactor WeightEarly Warning IndicatorIndicator WeightComprehensive Weight
Social SourceGovernment Intervention0.098Policies and Regulations (GF1)0.350.0343
Market Management Level (GF2)0.330.0323
Government Behavior (GF4)0.320.0314
Market SourceMarket Competition0.087Industry Competition Level (MF2)0.340.0296
Supply Chain Stability (MF3)0.330.0287
Market Concentration (MF4)0.330.0287
Enterprise Competition0.152Overall Enterprise Capability (CF1)0.260.0395
Enterprise Market Share (CF2)0.250.0380
Competitors (CF3)0.240.0365
Leading Product Competitiveness (CF4)0.250.0380
Management SourceInnovation Effort0.135Innovation Input (TC1)0.340.0459
Innovation Awareness (TC2)0.330.0446
Innovation Enthusiasm (TC3)0.330.0446
Personnel Turnover0.045Tenure of Senior Executives (IM1)0.340.0153
Tenure of Middle Managers (IM2)0.330.0149
R&D Personnel Turnover (IM4)0.330.0149
Technical SourceTechnology Stock0.082Number of Patent Inventions (IR2)0.260.0213
Number of Patents Granted (IR3)0.250.0205
Other R&D Achievements (IR4)0.250.0205
Technology Accumulation (IR5)0.240.0197
Technology Assessment0.164Technology Development Forecast Level (TA1)0.340.0558
Market Prospect Forecast Level (TA2)0.330.0541
Industry Prospect Forecast Level (TA3)0.330.0541
Financial SourceFinancing Capability0.092Financing Channels (FC1)0.520.0478
Credit Rating (FC2)0.480.0442
Cultural SourceInnovation Spirit0.089Institutional Innovation (IS1)0.210.0187
Frequency of Corporate Policy Changes (IS2)0.200.0178
Flatness Level (IS3)0.200.0178
Division of Authority (IS4)0.190.0169
Product Update Intensity (IS5)0.200.0178
Table 9. Indicator observation values for the early warning system (partial).
Early Warning IndicatorNo WarningMild WarningModerate WarningSevere WarningExtreme Warning
Policies and Regulations (GF1)Very FavorableRelatively FavorableGeneralRelatively UnfavorableVery Unfavorable
Market Management Level (GF2)Very FavorableRelatively FavorableGeneralRelatively UnfavorableVery Unfavorable
Government Behavior (GF4)Very FavorableRelatively FavorableGeneralRelatively UnfavorableVery Unfavorable
Industry Competition Level (MF2)Very ModerateRelatively ModerateGeneralRelatively IntenseVery Intense
Supply Chain Stability (MF3)Very StableRelatively StableGeneralRelatively VolatileVery Volatile
Market Concentration (MF4)No Significant DifferenceSmall DifferenceGeneralLarge DifferenceHuge Difference
Table 10. Comprehensive early warning levels.
Warning LevelRisk Index IntervalSignal LightMeaning
No Warning[0, 0.2)GreenTechnological paradigm functioning normally, risk controllable
Mild Warning[0.2, 0.4)BlueMinor risk signals present, needs attention
Moderate Warning[0.4, 0.6)YellowModerate risk present, preventive measures needed
Severe Warning[0.6, 0.8)OrangeSevere risk present, immediate corrective action needed
Extreme Warning[0.8, 1.0]RedRisk imminent, emergency intervention needed
Table 11. Comparison of true and predicted warning levels for the training set (partial).
Enterprise IDTrue Warning LevelReconstruction ErrorPredicted Warning LevelResult
001No Warning0.015No WarningCorrect
002No Warning0.018No WarningCorrect
003Mild Warning0.042Mild WarningCorrect
004No Warning0.021No WarningCorrect
005Mild Warning0.038Mild WarningCorrect
Table 12. Comparison of true and predicted warning levels for the prediction set.
Enterprise IDTrue Warning LevelReconstruction ErrorPredicted Warning LevelResult
061Moderate Warning0.092Moderate WarningCorrect
062Mild Warning0.045Mild WarningCorrect
063Severe Warning0.178Severe WarningCorrect
064No Warning0.022No WarningCorrect
065Mild Warning0.041Mild WarningCorrect
066Moderate Warning0.088Moderate WarningCorrect
067Extreme Warning0.245Extreme WarningCorrect
068No Warning0.019No WarningCorrect
069Moderate Warning0.079Moderate WarningCorrect
070Severe Warning0.165Severe WarningCorrect
071Mild Warning0.052Moderate WarningIncorrect
072No Warning0.024No WarningCorrect
073Severe Warning0.172Severe WarningCorrect
074Moderate Warning0.094Moderate WarningCorrect
075Extreme Warning0.238Extreme WarningCorrect
Table 13. Comparative performance of different models.
ModelAccuracyPrecision (Macro Avg.)Recall (Macro Avg.)F1-Score (Macro Avg.)
One-Class SVM73.33%0.720.700.70
Random Forest86.67%0.870.840.85
DAN93.33%0.930.920.92
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content.