1. Introduction
In mechanical and mechatronic system development, testing aims to verify the system’s functional and physical behavior. Test cases provide the essential structure on which testing is conducted. A test case specifies the test objective and the boundary conditions under which verification is performed.
Table 1 shows an excerpt from a test case used to validate the volume flow of a coolant pump. The test targets define the desired result as a volume flow of minimum 5 L/min within a 5% tolerance (
Table 1 left), as well as the conditions under which this target must be achieved (
Table 1 right). If additional sets of conditions need to be evaluated, such as verifying the pump’s operability at higher temperatures, a separate test case is created for each condition set. As test definition progresses, test cases are extended by test methods, test processes, and criticality assessments into a comprehensive test plan. Therefore, in the test-case definition, the coverage of all boundary conditions for one test target is important as all relevant conditions for the later conducted tests must already be specified in the test cases [
1,
2,
3].
A structured test-case definition is especially relevant for technical systems that merge subsystems of the mechanical, electronic, and software domains, so-called cyber-physical systems (CPSs) [
4]. Future CPSs are becoming increasingly interconnected, not only in software but across all domains. From energy supply and sensing to actuation, energy conversion, and protection, developers must capture, manage, and verify numerous highly integrated and increasingly complex system functions. The involvement of strong interactions across physical and software domains in CPSs makes it essential to interpret boundary conditions consistently across these domains. Thus, the testing and therefore test-case definition effort increases significantly as functional interactions and boundary conditions must be covered across multiple domains [
5,
6,
7].
In industrial practice, a manual test-case definition remains common practice and is both time- and cost-intensive [
8,
9,
10]. With rising system complexity and pressure to reduce time-to-market, this challenge grows further—for example, creating all test cases for a new car model (Audi: ~600,000 requirements) from the ground up would require about 24,000 person-days [
11,
12].
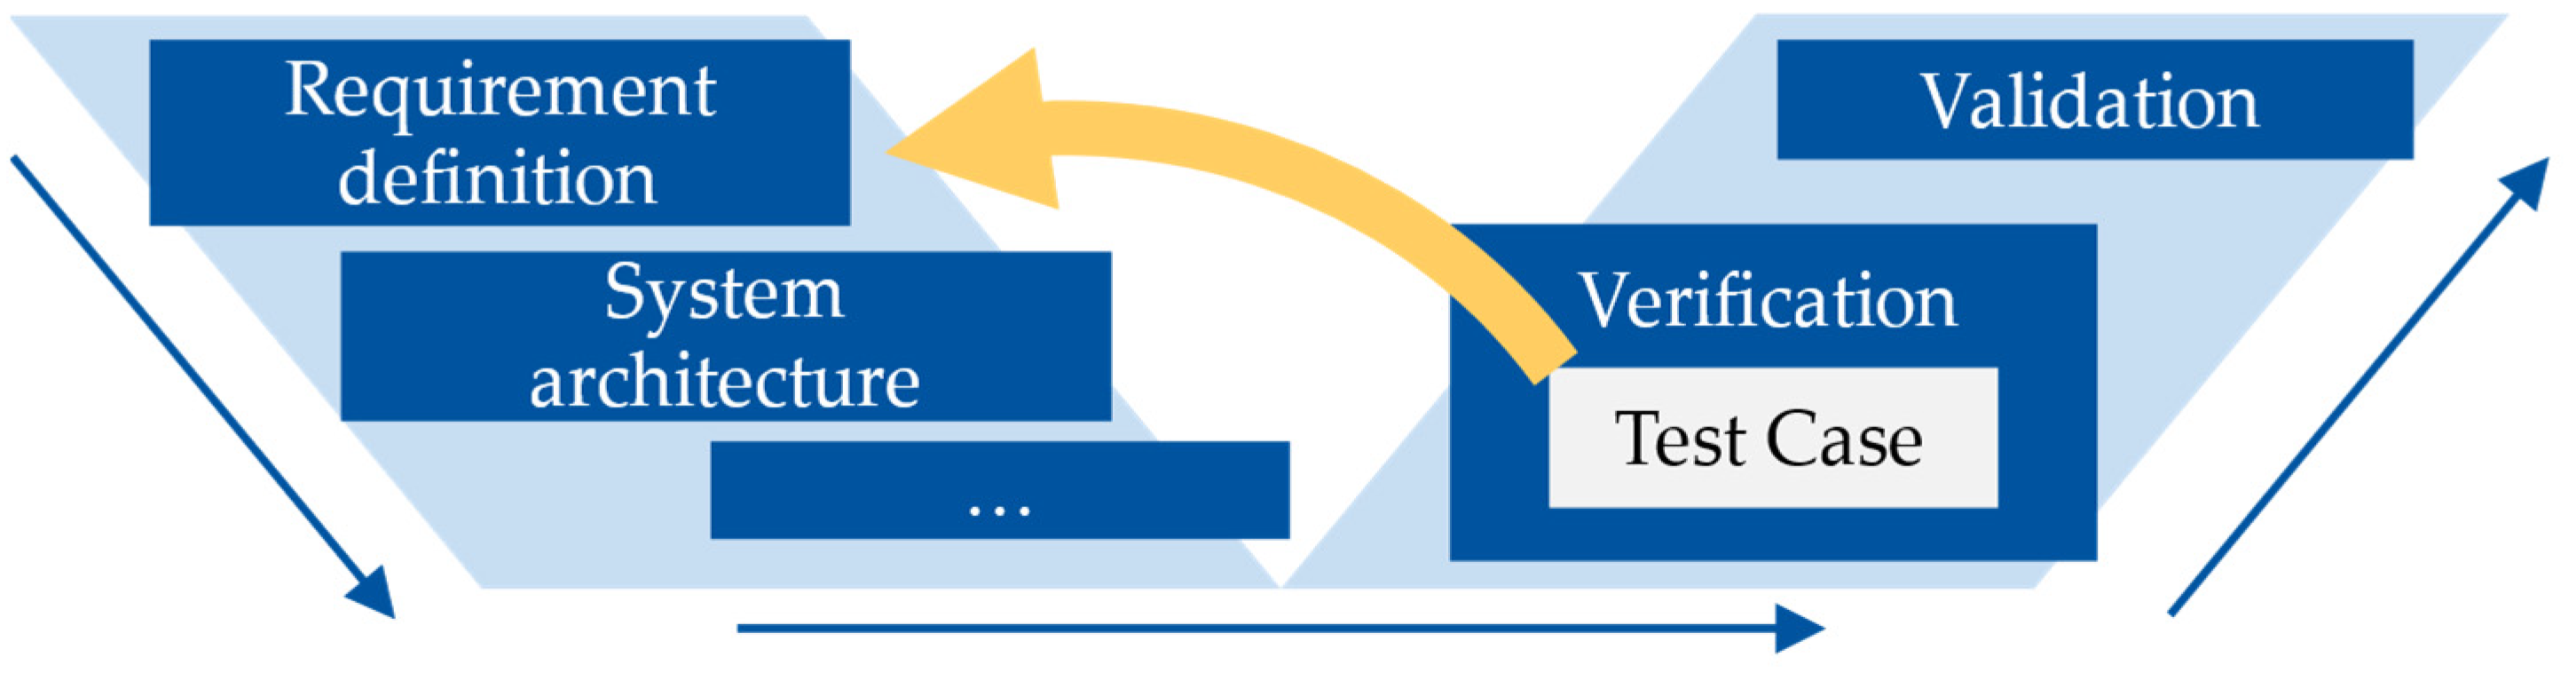
To reduce manual effort and therefore contribute to time-to-market, the test-case definition process should be automated. One suitable information basis for the automation process is requirement specification. When following the design process according to VDI 2206 (
Figure 1), requirements are available at the beginning of the development process and define what a system should be capable of and under which conditions it must achieve this capability. A requirement-based test-case definition therefore enables early consideration of test cases. To confirm that the system behaves as intended, the testing should always verify the system against its requirements. A requirement-based test-case definition also provides the necessary traceability to show which requirements are covered and which requirements are verified by which test [
4,
13,
14]. In safety-critical domains, complete documentation of this requirement-based testing process is mandated by standards such as ISO 26262 for automotive engineering [
15].
The key challenge in requirement-based test-case definition lies in the fact that requirements are written in natural language and are therefore not directly machine-readable. This is precisely where modern large language models (LLMs) open up new possibilities: models such as GPT-4o, Claude Sonnet, or DeepSeek V3 are capable of semantically analyzing unstructured natural-language text, recognizing causal and structural dependencies in the information provided, and generating structured outputs [
16,
17,
18,
19]. This capability opens up the possibility of performing causal and semantic analysis of natural-language requirements and deriving test cases from that analysis (Requirement-to-Test) [
20,
21,
22]. However, most current Requirement-to-Test approaches focus on the definition of test cases for systems from the control and software domains. An application of Requirement-to-Test for CPSs including boundary conditions resulting from complex physical interdependencies is missing to this day.
This paper investigates methodological approaches that leverage LLMs to identify complex boundary conditions for CPS test-case definition through detailed analysis of requirements. For this purpose, three approaches are compared: a direct method where the LLM freely defines test cases based on provided requirements (Approach 1,
Section 4.1), a stepwise approach that includes a taxonomy-guided structured requirement interdependency mapping prior to test-case generation (Approach 2,
Section 4.3), and a variant where this stepwise approach is supported by adding a Model-Based Systems Engineering (MBSE) system model as context information via Graph RAG (Approach 3,
Section 4.5). These approaches are evaluated as a proof of concept on the basis of manually constructed test cases and test cases derived from ISO 9906.
2. State of Research
To assess the state of research for requirement-based test-case definition via LLMs in CPSs, three main areas must be covered. First, LLM technology and standards for LLM output evaluation are introduced. Second, the current state-of-the-art of automated test-case generation from requirements (Requirement-to-Test) and existing taxonomies for requirement interdependency mapping are presented. Last, an introduction to MBSE is given, as MBSE system models will be used as system context information in the third approach.
2.1. Large Language Models
Modern LLMs based on the transformer architecture [
23,
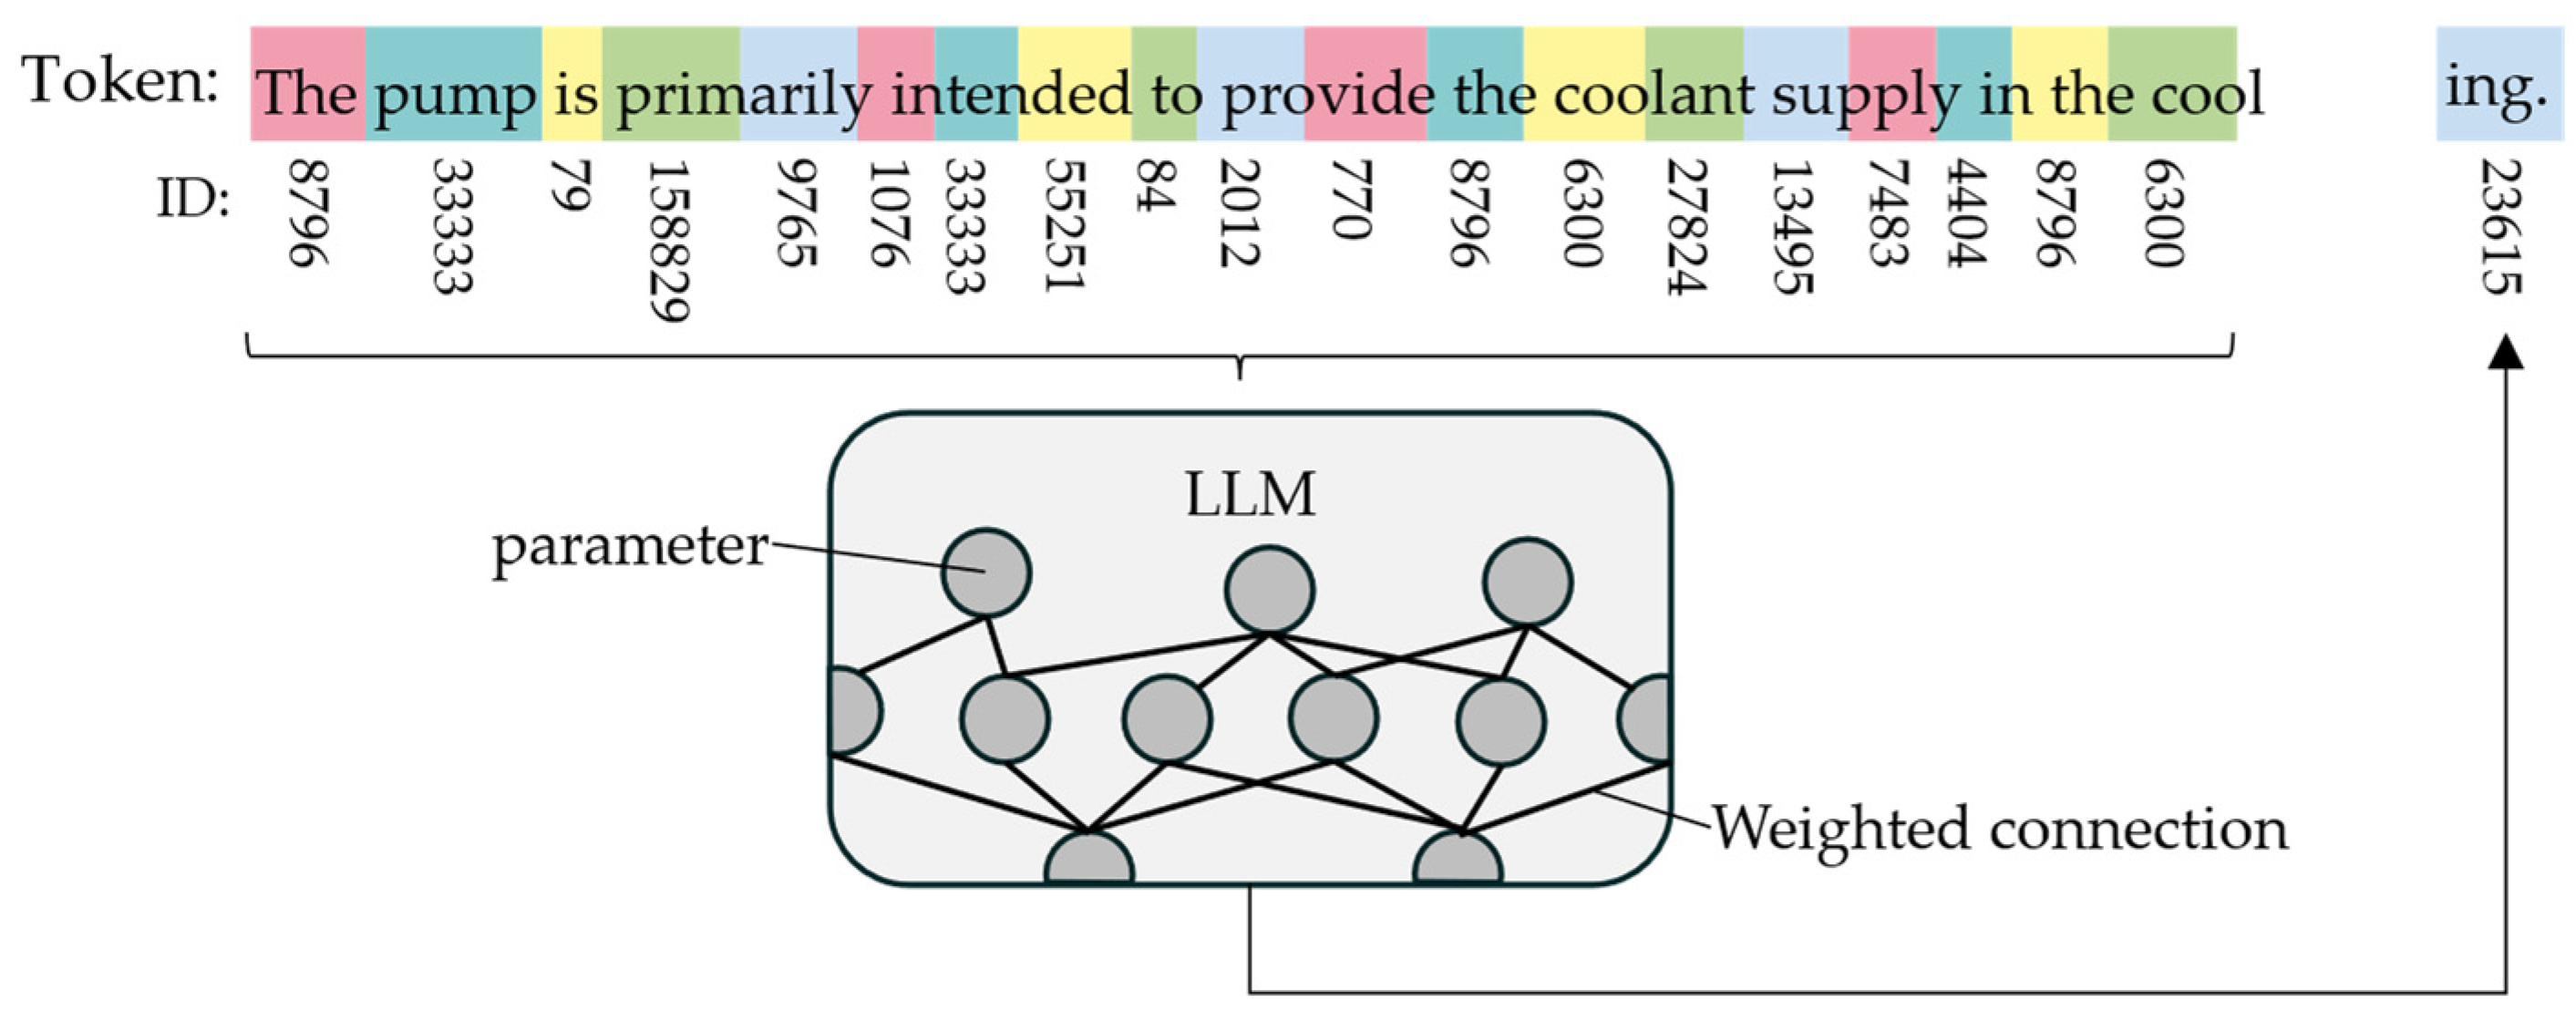
24], such as GPT-4, Claude Sonnet, and DeepSeek V3, generate text probabilistically by predicting the most likely next token [
23,
25,
26] (see
Figure 2 right). Tokens represent the smallest language units that are numerically encoded and processed (see
Figure 2 top) [
27]. In an LLM, the next-token prediction emerges from the interaction of billions of learned parameters, numerical values whose weighted connections determine how strongly previous token patterns influence the model’s probabilistic output (see
Figure 2 bottom). During training, these parameters are adjusted to minimize prediction errors, enabling the model to learn linguistic patterns and semantic relationships. LLMs are trained on trillions of tokens from diverse sources to adjust billions of parameters [
24,
25,
28]. LLMs vary greatly in size, from small models like DistilBERT with 66 million parameters to large ones such as GPT-3 with 175 billion, and GPT-4, DeepSeek V3 or Claude 3 with as many as 671 billion parameters [
24,
29,
30]. Larger models generally achieve better language understanding, context depth, and generalization [
31,
32,
33].
Apart from the adjustment of the models’ internal parameters, which is very computing- and therefore cost-intensive, there are several methods to adjust the behavior of LLMs. Most notably are the adjustment of the model temperature, Few-Shot Learning and Retrieval Augmented Generation (RAG) [
26,
34,
35,
36].
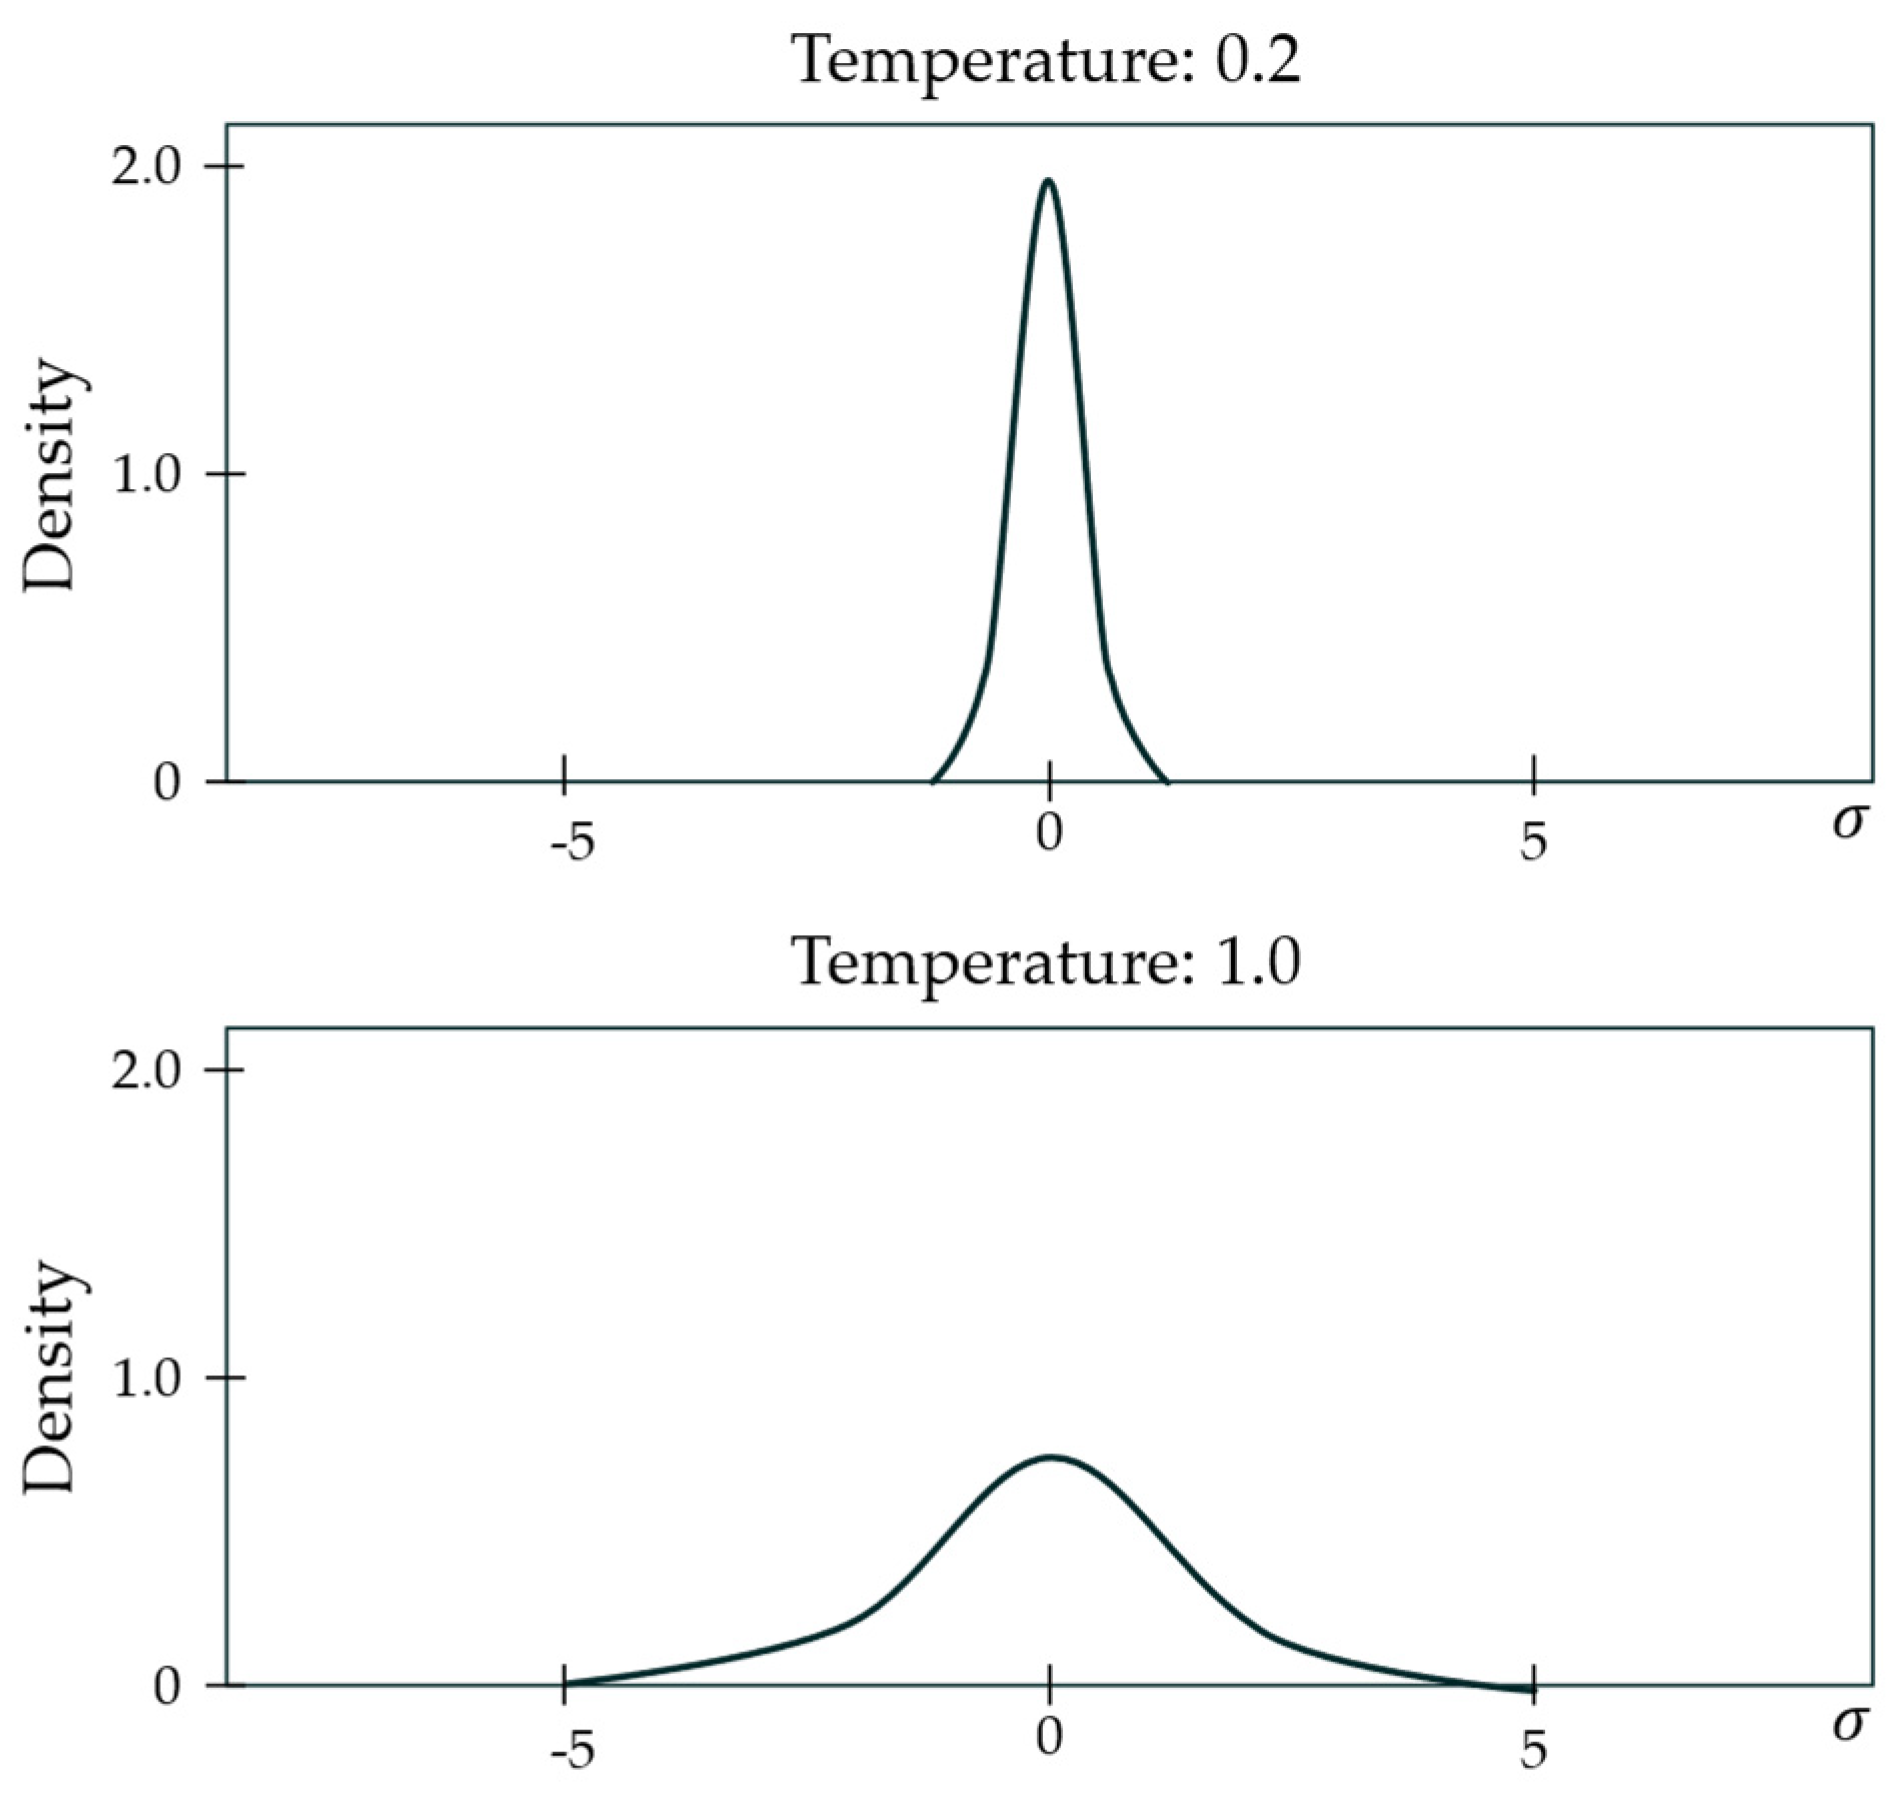
The temperature parameter controls the randomness of the next predicted token, and therefore the randomness or creativity of the generated text. Low temperatures (T < 1) sharpen the probability distribution and yield more deterministic outputs (see
Figure 3 top), while higher temperatures (T > 1) flatten the distribution (see
Figure 3 bottom) and produce more diverse and creative, but less predictable, text. Temperature thus acts as a central decoding parameter balancing precision and variability in generated outputs [
35,
37,
38,
39].
Additional to adjusting the model temperature, the input context can heavily influence the system’s output [
32,
33]. Few-Shot Learning and RAG are methods that add information to the provided input prompt and therefore have major influence on the output.
Few-Shot Learning enables LLMs to perform tasks by providing a small number of representative examples directly within the prompt. A few input–output pairs illustrate the desired output pattern, allowing the model to interpret the underlying structure and apply it to new outputs. Through in-context learning, LLMs generalize task behavior from minimal demonstration examples. Few-Shot prompts can significantly improve output consistency, task adherence, and domain specificity, especially for classification, formatting, or reasoning tasks [
26,
34,
41]. These capabilities can be useful when complex reasoning tasks and structured outputs will be used for subsequent algorithm-based processing. Both are relevant in the following test-case generation approaches.
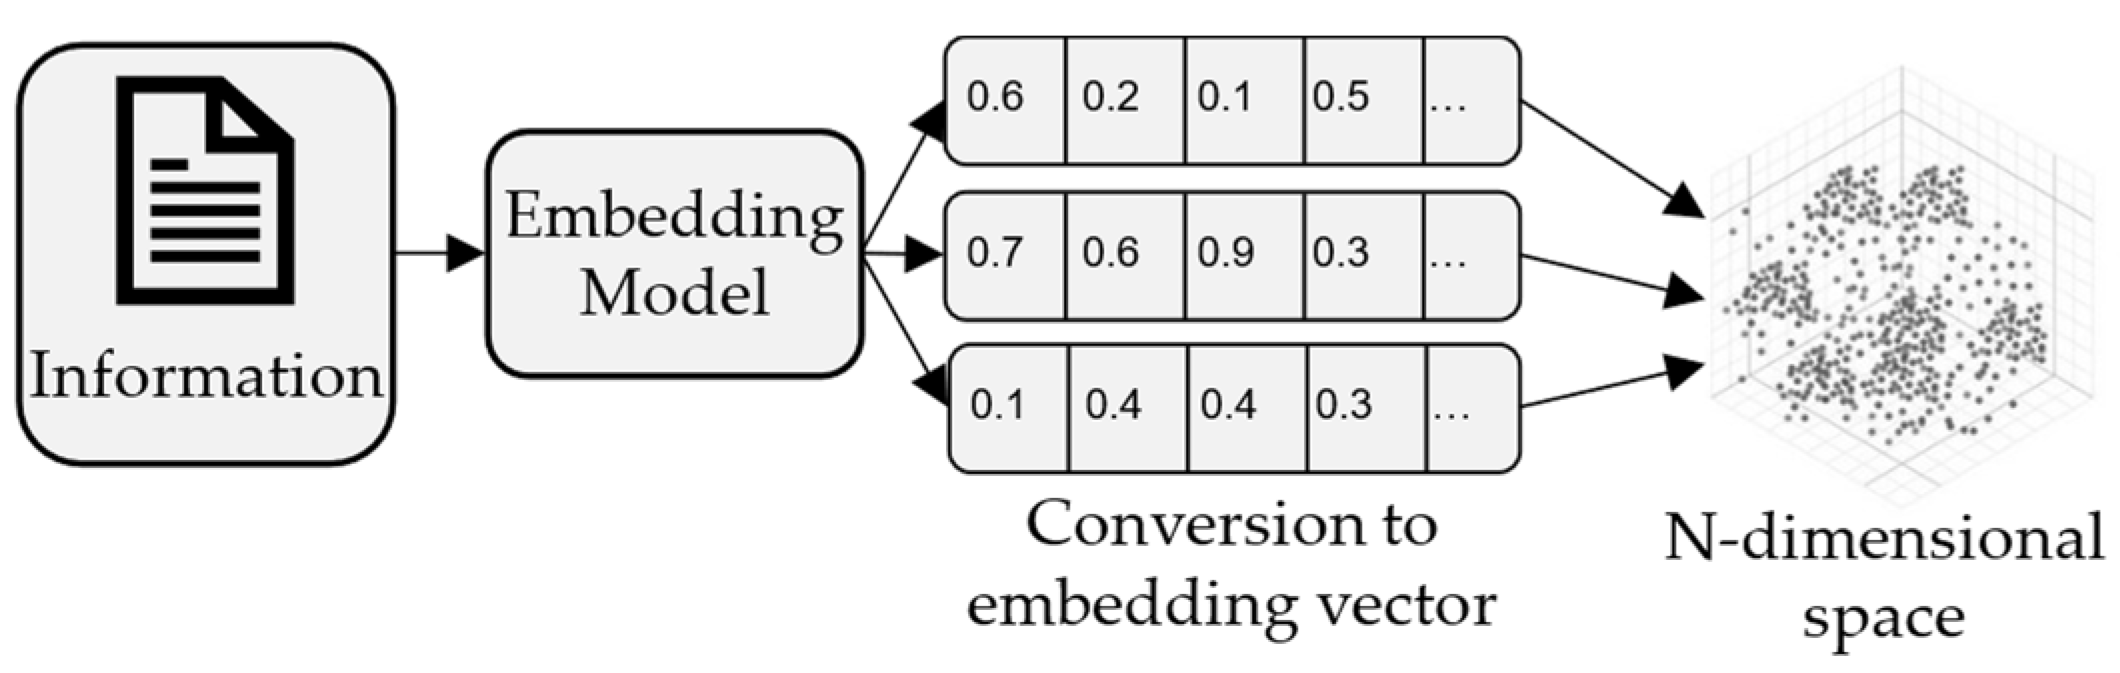
RAG enhances LLM performance by supplementing the model’s internal knowledge with relevant external information. Before generating an answer, relevant information from an external knowledge base is identified and injected into the prompt as context information. This retrieval step relies on semantic similarity search, in which texts are converted into vector embeddings using an embedding model (see
Figure 4 second block from the left ). Embeddings are a high-dimensional vector used as a mathematical representation of the information’s semantic content. These embeddings are positioned within a vector space, where spatial proximity corresponds to semantic similarity (see
Figure 4 right side) [
36,
42,
43].
When a user query is issued, it is likewise embedded, and the system searches this vector space for semantically related entries, typically using cosine similarity to measure the closeness between vectors. As a result, the retrieval algorithm can locate conceptually relevant passages even when they do not share explicit keywords, making semantic search significantly more robust than traditional lexical retrieval. By grounding the generation process in retrieved, contextually relevant evidence, RAG reduces hallucinations, improves factual accuracy, and enables LLMs to perform effectively in knowledge-intensive tasks such as question answering, scientific analysis, or domain-specific decision support [
36,
42,
43].
In the following work, this RAG technology will be used to provide suitable context information about the system as well as suitable Few-Shot examples to the LLM. Based on the semantic similarity search, the relevant information can be extracted, reducing unnecessary noise in the input context of the LLM, providing only the information that is needed.
2.2. Evaluation Metrics
To evaluate the LLM outputs, a confusion matrix is used—a method originating from medical diagnostics to assess classification performance. It categorizes results based on true positive (TP), false positive (FP), false negative (FN), and true negative (TN) results and is now a standard tool for evaluating AI systems in classification and information extraction tasks.
Table 2 shows the meaning of these values in terms of AI research [
44].
Based on these four fundamental values, standardized metrics commonly used in AI research—precision and recall—can be calculated. These metrics permit a detailed assessment of model performance.
Table 3 summarizes their formulas, meanings, and intuitive interpretations. Precision describes the proportion of correctly identified positive cases among all cases predicted as positive, indicating how reliable the positive predictions are. Recall, in contrast, measures how many of the actual positive cases are successfully detected, reflecting the completeness of the detection. In this work, these metrics will be used in assessing the approaches’ output quality to quantify the value given to the test-case generation of each approach [
44].
2.3. Requirement-to-Test Approaches
Automated test-case generation from requirements (Requirement-to-Test), as pursued in this work, builds on foundational research that is already established in the field of computer science. Significant progress in Requirement-to-Test is largely concentrated on the software domain.
Early work on Requirement-to-Test for software systems applies classic Natural-Language Processing (NLP) methods to derive test cases directly from textual requirements [
22,
45,
46]. Despite notable advances, traditional NLP approaches face clear limitations in practice. These approaches are often domain-specific, difficult to adapt to new contexts, and struggle with linguistic variability, ambiguity, and contextual meaning. Moreover, they typically require extensive manual preprocessing, such as annotation or rule definition, which limits scalability [
22,
45,
46]. These approaches operate on the requirement text alone and assume that individual requirements can be mapped directly to the corresponding test cases.
With the evolution from classic NLP techniques to LLMs, recent work on Requirement-to-Test has focused on LLM-based processes. It is observed that LLMs can generate high-quality test cases from clearly structured software requirements. These requirements follow an explicit input–response schema, describing how a system must react to a defined input in a single requirement [
20,
47]. One comparative study evaluated several LLMs, including GPT-3.5, GPT-4, and Claude, for their ability to derive software test cases from technical requirements and found that more capable models such as GPT-4 produced a higher number of relevant and better-structured test cases [
20,
47]. Work by Schäfer et al. [
20,
47] on software unit-test generation further shows that LLMs can produce functional and meaningful tests by combining source code, function signatures, comments, and usage examples as input and that, under these conditions, they outperform traditional approaches in terms of coverage. Compared to traditional NLP techniques and classical unit-test generators, modern and larger LLMs achieve better results [
20,
22,
47].
Studies in control electronics show similar potential: LLMs can produce logically consistent tests for discrete, rule-based behaviors when inputs are well-defined and standardized [
11,
21,
47]. Lebioda et al. [
21] explored an end-to-end pipeline in which a powerful LLM, such as GPT-4, generates executable simulation code and corresponding test cases from free-form, use-case-based requirements; this worked well for simple, clearly structured reactions to environmental conditions but produced semantically incorrect simulation logic for ambiguous or highly interdependent requirements. A related study showed that LLMs can derive syntactically valid and logically consistent test cases for programmable logic controllers from technical system descriptions, yet often miss critical verification steps and rare edge cases, underlining the need for structured workflows and domain expertise in industrial settings [
20,
21,
48].
The approach’s performance drops significantly when requirements become ambiguous or interdependent, showing the relevance for requirement interdependency analysis. Also, without a structured process and domain-specific context knowledge, the models struggle with requirement complexity [
20,
21,
48].
Current work does not utilize system information as context in the process. Even advanced approaches such as processes translating requirements to discrete software models and later generating test cases from these are limited to simple, clearly structured scenarios and fail when physical constraints or complex system interactions must be considered [
21].
Overall, the current state of the art for Requirement-to-Test is largely confined to the software and control electronics domain, where systems follow predominantly discrete logic. Requirements are often expressed as an explicit description of a wanted response to a given input. Research on automated test-case generation for mechatronic systems, especially incorporating mechanical and physical boundary conditions, remains largely unaddressed. It is observed that the effectiveness of current Requirement-to-Test approaches is strongly limited by the ability to interpret implicit information about systems’ behavior and strongly depend on requirements describing discrete sequences. As a result, current methods typically reformulate individual requirements into test cases without adequately addressing complex physical boundary conditions. However, LLMs show great capabilities for Requirement-to-Test, with the test quality rising with the growth of the LLM models.
2.4. Approaches to Interdependency Analysis of Requirements
In Approach 2, a taxonomy for requirement interdependency mapping is introduced. Therefore, the state of the art for requirement interdependency analysis must be considered. Early approaches before the introduction of NLP processes systematically identify and manage interactions between requirements. Even without the use of NLP-based methods, dependencies among requirements are systematically identified and classified by establishing structured relation frameworks [
49,
50]. The objective of these approaches is the early detection and effective management of requirement interactions [
50,
51,
52].
With advancing NLP capabilities, automation in requirement interdependency analysis has increased across diverse use cases such as contradiction detection [
53,
54,
55,
56,
57], visual or model representations, mostly in UML [
58,
59,
60], and legal and regulatory requirement alignment [
61,
62,
63]. Overall, this work shows a clear trend toward data-driven, context-aware automation—but it remains largely focused on software engineering and is used for other purposes than test-case generation, leaving notable gaps for mechanical engineering applications in this field. Software requirements typically specify explicit, discrete input–response relations, with interdependencies mainly arising from defined sequences. In contrast, mechanical systems are governed by continuous physical processes that are often implicitly described or distributed across multiple requirements. Consequently, dependencies are more context-dependent, and requirement mapping must account for physical interrelations that are less explicit than in discrete software systems.
2.5. Model-Based Systems Engineering (MBSE)
MBSE is an engineering approach used to master the increasing complexity of CPSs. Instead of relying on separate, document-based development artifacts, MBSE introduces a centralized system model in which all subsystems and their interactions are represented consistently. This system model forms a single point of truth (SPOT) for all development parameters and relationships. MBSE facilitates efficient, standardized virtual modeling of CPSs, improving interdisciplinary communication, traceability, and reusability. To achieve this, MBSE system models gather all engineering information in a parametrized architecture and integrate simulation models for virtual verification [
64,
65,
66,
67,
68,
69].
For MBSE system models, SysML is commonly used as the modeling language with various established tools and methodologies supporting its application [
70]. The motego methodology stands out through a strict function-oriented approach that decomposes system behavior down to elementary functions, following Koller’s principles [
71,
72]. Functional interfaces are expressed using material, energy, and signal flows to ensure interdisciplinary consistency [
71]. Unlike most other MBSE approaches, motego establishes fully parametric, quantitative links between functional and solution levels, ensuring consistent propagation of changes [
72]. Furthermore, the method integrates simulation and domain models (e.g., FEM, fatigue, and MBS) directly into system elements to support virtual verification and optimization [
73,
74,
75,
76]. Together, the motego method uniquely specifies a modeling environment that defines all levels of the product’s architecture and models parameterized interfaces between system functions and subsystems [
72,
77]. These advantages result in the motego method being used in the model as system context in the third approach, as the methodology enables the creation of a deeply structured and strongly interconnected system model, allowing the LLM to be provided with the most comprehensive and detailed system knowledge as contextual information.
3. Research Concept
While AI-based test-case derivation has been explored extensively in software and electronics engineering, there is little to no research on its application for CPS with a special focus on the inclusion of all necessary physical boundary conditions resulting from the implicit interdependencies of the mechanical domain. So far, it remains unclear how LLMs can reliably identify and represent physical boundary conditions from natural-language requirements for use in test-case generation. To address this research gap, this paper investigates the following research question (RQ):
RQ. How can LLMs be used to extract relevant information from natural-language requirements for test cases with boundary conditions that cover complex physical interdependencies of CPSs?
In the state of research, it was shown that the effectiveness of LLMs depends not only on model size and capability but also on the input information and a well-defined methodological workflow. To extract relevant information from natural-language requirements for test cases with complex boundary conditions that can be leveraged for automated test-case generation, such a methodological workflow for the semantic analysis of natural-language requirements of CPSs is discussed. This methodology is based on the fact that requirements mutually influence each other. An example of this is that if a coolant pump’s volume flow output is to be tested, requirements specifying the coolant type, maximum power usage and others must be considered as well. The identification of interdependencies between requirements could lead to the identification of boundary conditions. Therefore, the main hypothesis is as follows.
Main hypothesis.
It is possible to identify complex boundary conditions for test cases through an analysis of interdependencies between natural-language requirements using LLMs and MBSE system models as system context.
Since LLMs operate probabilistically and rely heavily on context, their effectiveness depends on structured input design and contextual grounding. Therefore, the three hypotheses below address these issues.
H1. Aggregating multiple LLM outputs can compensate for the non-deterministic behavior of LLMs, improving consistency.
H2. A provision of predefined relationship types describing the possible test-relevant influences between requirements enables the LLM to extract deeper boundary conditions in test-case generation.
As discussed, the effectiveness of the LLM is influenced by both the methodological workflow and the input information. To assess the impact of the input information for test-case generation with complex boundary conditions, system context is provided to the LLM. MBSE system models offer a comprehensive knowledge base by integrating and interlinking all development information within a single point of truth and explicitly representing cause–effect relationships. This structured knowledge base can serve as contextual input for the LLM, enabling a deeper understanding of the system and improved identification of physical interactions and therefore complex boundary conditions. The third hypothesis can therefore be formulated as follows.
H3. Integrating MBSE system models as contextual information about system behavior can increase the reliability of the analysis.
4. Materials, Methods and Results
The test-case generation process in this paper is structured around the main hypothesis of test-case generation through interdependency analysis of requirements.
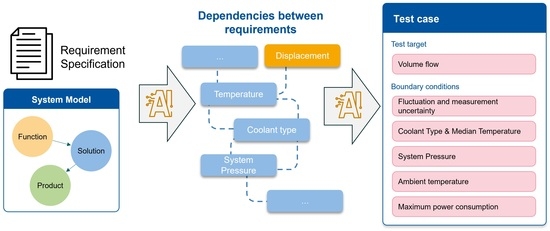
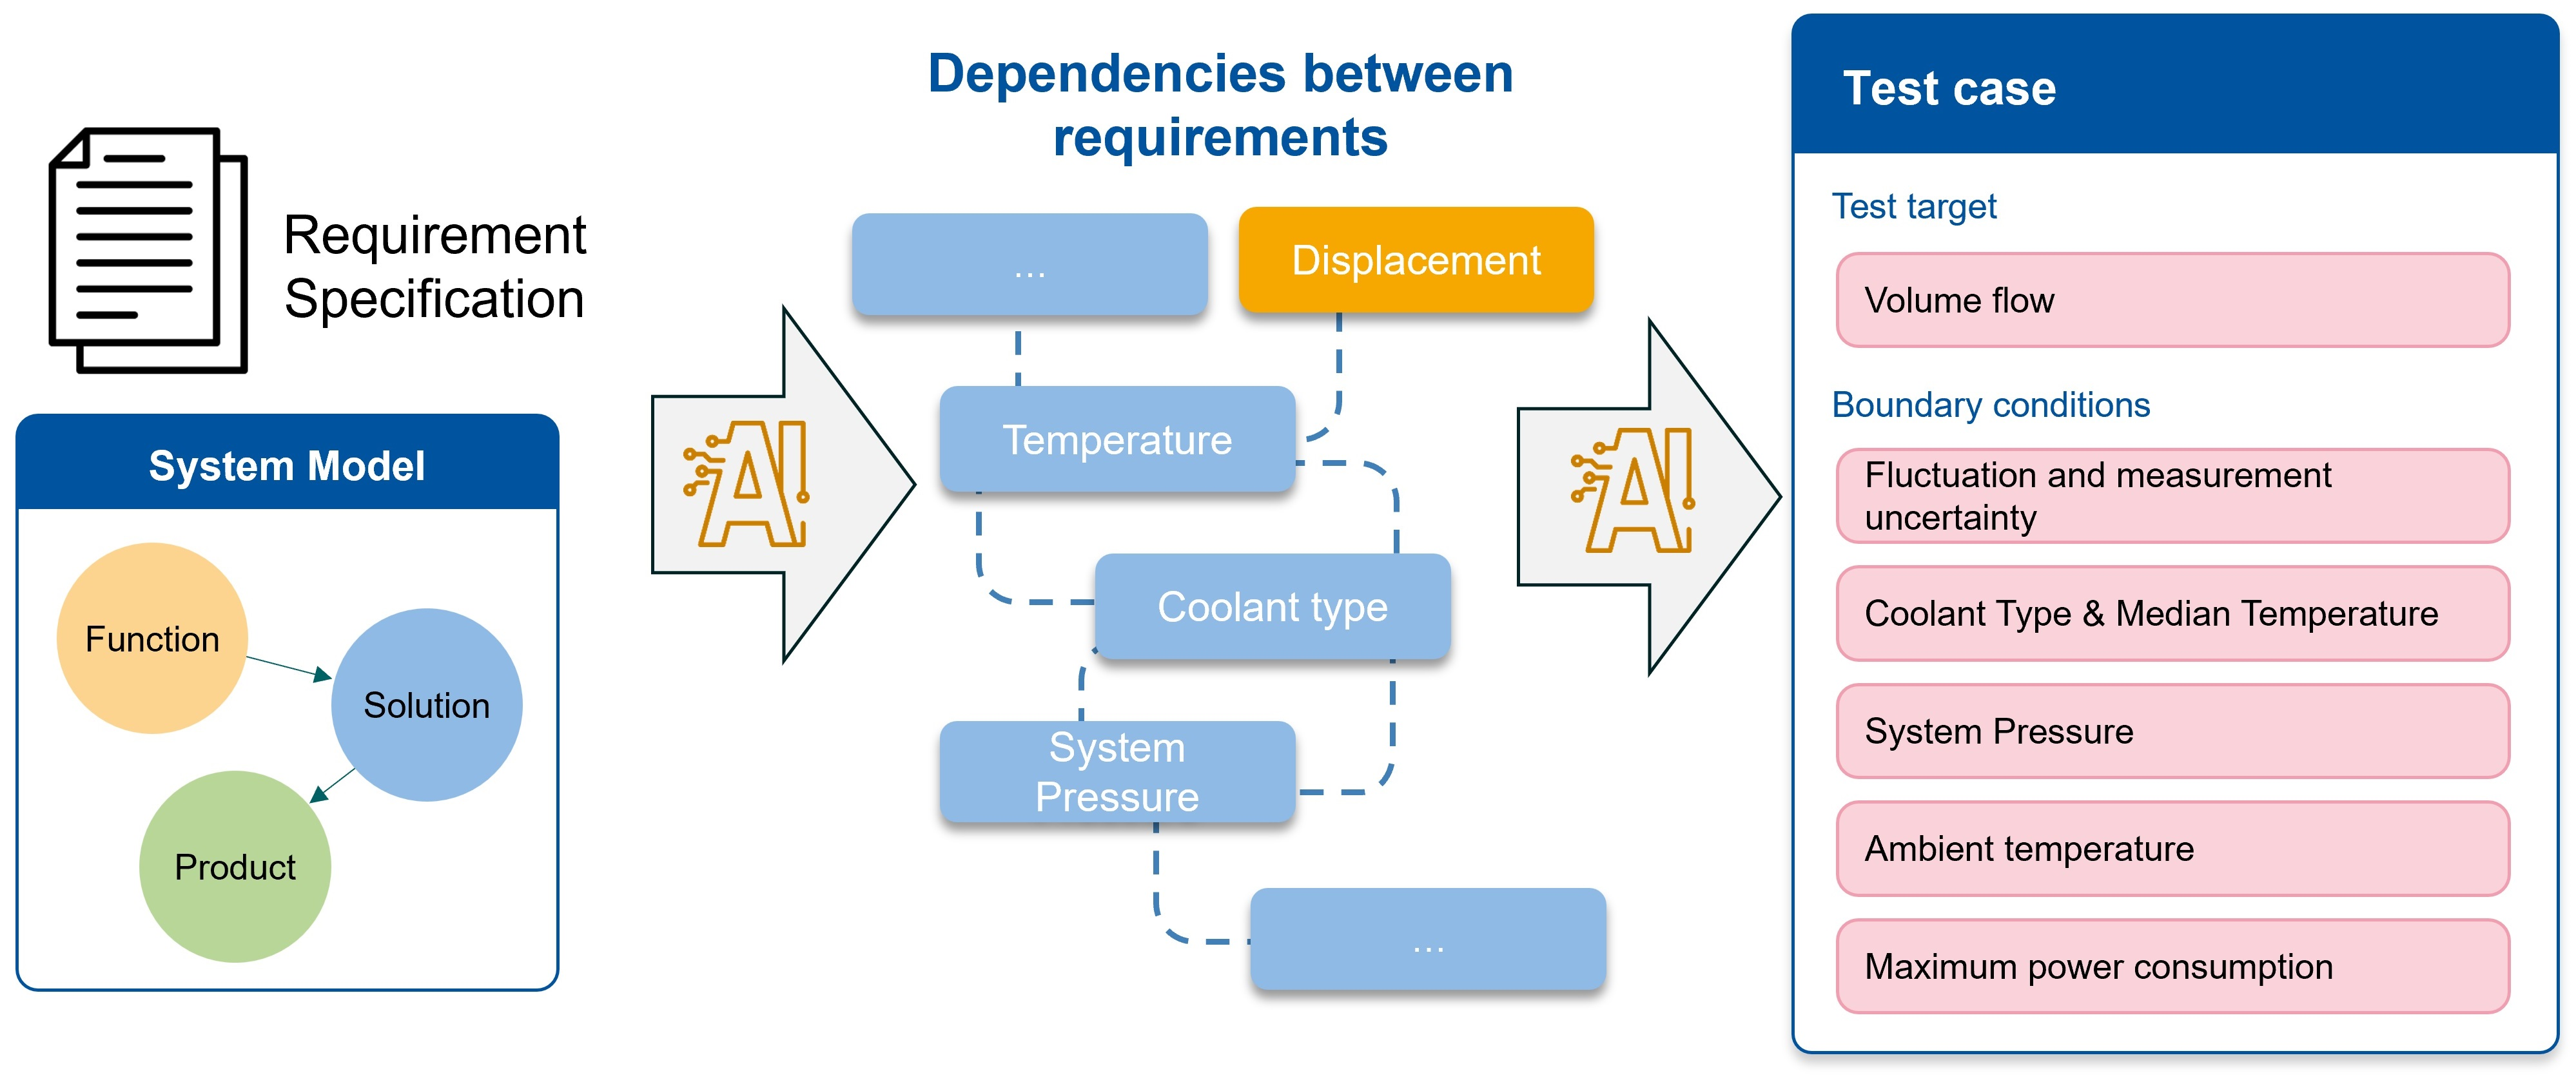
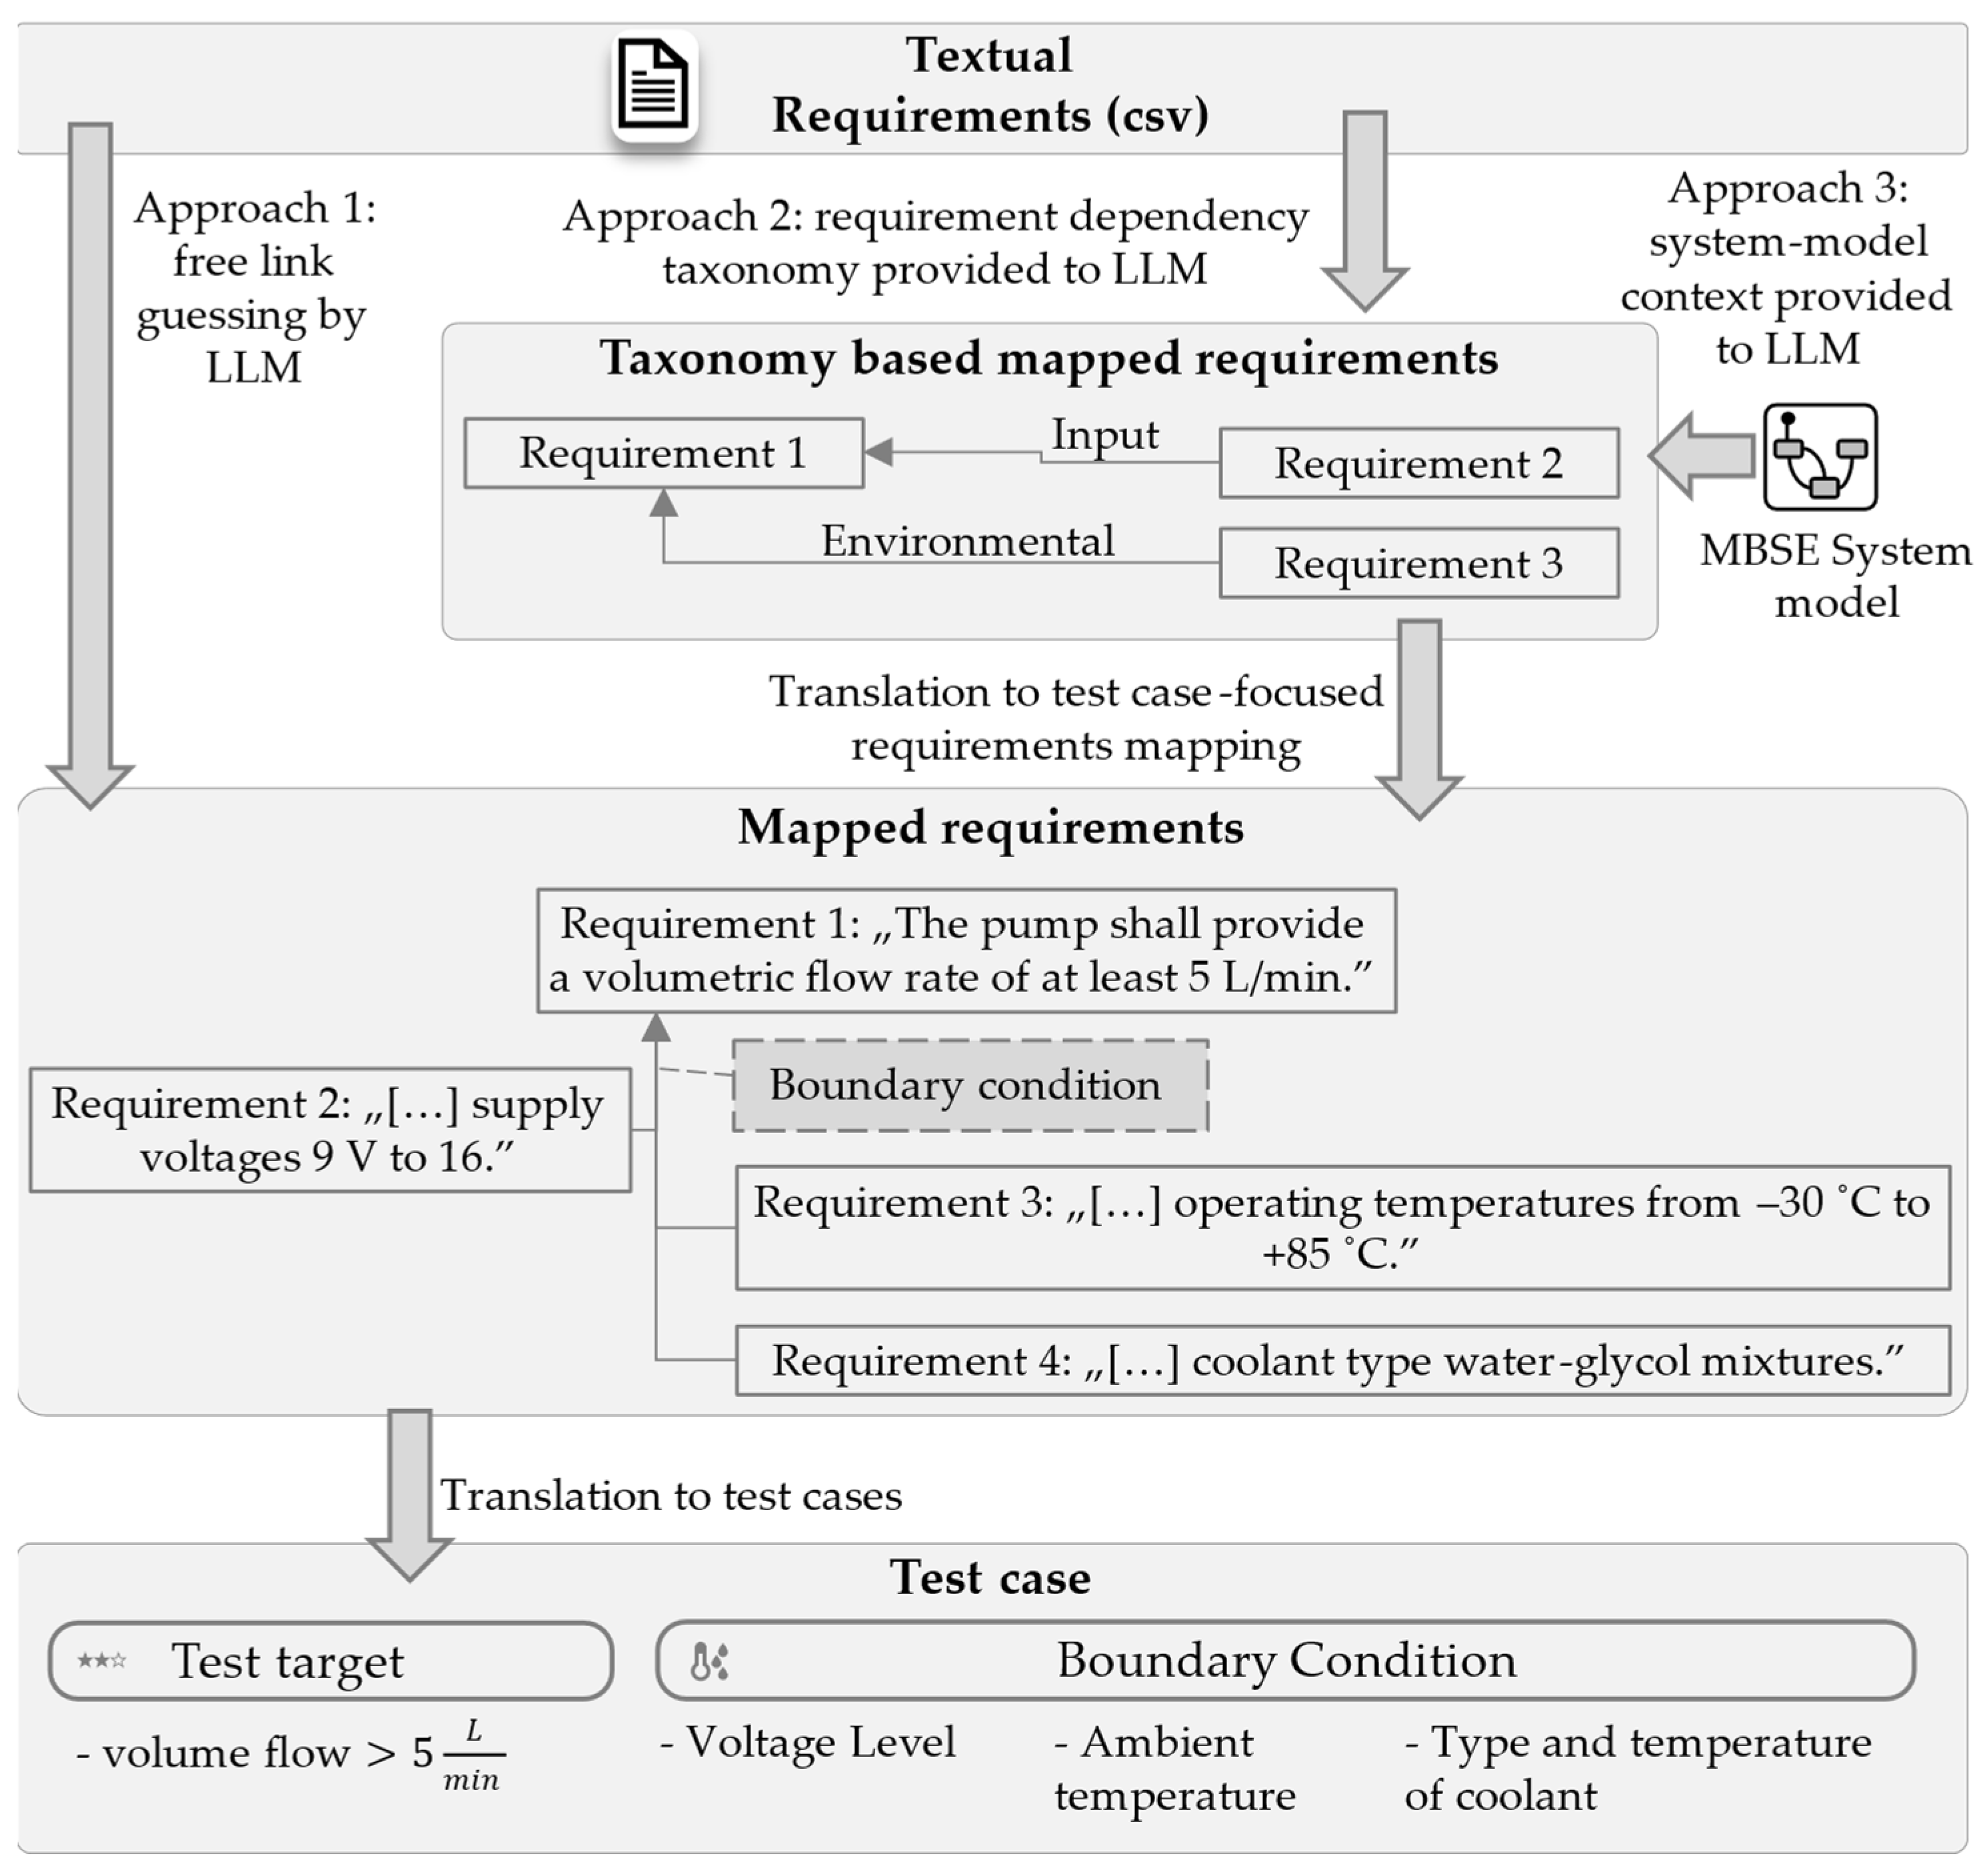
Figure 5 visualizes this process based on the example test case of a volume flow test of a coolant pump. During the process, requirements are mapped against each other in terms of their relative relevance for test-case definition, following the ISO 29119 concepts of test conditions and test targets (see
Figure 5 “Mapped requirements”). The requirements are analyzed to determine if they constitute a boundary condition for a requirement to be tested or if they extend its test target. From these identified dependent requirements, test cases can be extracted.
To achieve this state, three successive approaches are compared, each addressing one of the hypotheses (H1, H2, and H3) and building on the results of the previous one (see
Figure 5 top). Approach 1 lets the LLM guess the requirement mapping freely with little guidance. Approach 1 furthermore extends this state-of-the-art approach by testing an aggregation of multiple LLM outputs to increase consistency (H1). Approach 2 introduces a taxonomy for predefined relationship types describing the possible test-relevant influences between requirements to integrate a well-defined methodological workflow (H2). Approach 3 builds on the taxonomy of Approach 2 by adding system information from an MBSE system model to test the impact of advanced system knowledge in the LLM input to the requirement mapping process (H3). The following
Section 4.1,
Section 4.2,
Section 4.3,
Section 4.4,
Section 4.5 and
Section 4.6 address these three approaches in successive order.
The LLM used for the following approaches is the GPT-4o model by OpenAI, which was integrated via the OpenAI API. GPT-4o represents one of the latest generations of OpenAI’s multimodal models, capable of processing text, images, and audio within a unified architecture. It combines the reasoning strength of GPT-4 with significantly faster response times and reduced computational cost, making it well suited for research and real-time applications [
24].
The reference object for evaluation is a coolant pump with ~100 natural-language requirements and an accompanying MBSE system model. For evaluation, the outputs are compared against two standard-based reference test-case sets for the same system, manually constructed by technical experts: (i) system tests in line with ISO 29119 and (ii) performance tests as stated in ISO 9906. Each reference test case is linked to its originating requirement and thus defines a set of requirement–test links to be rediscovered by the proposed process. This derivation was performed by a technical expert and therefore does not guarantee completeness with respect to all possible valid tests, and we must clarify that TPs, FPs and the resulting precision and recall are defined strictly with respect to this fixed reference suite and are used to compare the three process variants rather than as absolute coverage measures. Performance is measured using TP, FP, and FN counts and the derived metrics precision and recall (for further details, check
Section 2.2). The optimum reference for evaluation is 71 TPs. For every evaluation, 5 executions are performed with 15 aggregated runs per execution. Afterwards, the arithmetic mean is defined. Precision and recall are defined strictly with respect to the fixed reference set and are used to compare the three process variants rather than absolute coverage measures. Generated links that do not match any reference case are counted as false positives, even if they may represent additional valid tests, which makes our precision estimates conservative.
4.1. Approach 1: Free Interdependency Guessing by LLM
In this approach, the LLM is allowed to decide autonomously which requirements have test-relevant relationships with each other, i.e., which act as target conditions and which must hold simultaneously as boundary conditions. The model receives the natural-language requirements of the coolant pump together with a set of Few-Shot examples that illustrate how a test case groups requirements into targets and boundary conditions. The prompt to the LLM instructs the model to compare all requirements, propose sets that must be verified together in a single test case, and label each requirement accordingly. The prompt was defined as follows (abridged):
“[…]Compare all the following requirements with each other and create relationships between the requirements based on the relationship types given below. […] Possible relationship types are:
Target Condition (when validating the new requirement also requires validating the existing requirement), formatted as A-TestTarget->B, meaning requirement B represents a test target that needs to be simultaneously considered during testing for requirement A.
Boundary Condition (when the existing requirement imposes a boundary condition for validating the new requirement), formatted as A-BoundaryCondition->B, meaning requirement B acts as a boundary condition during testing for requirement A.
[…]”
A structured output formatted as a JSON file was given (as well as an example for the structured output).
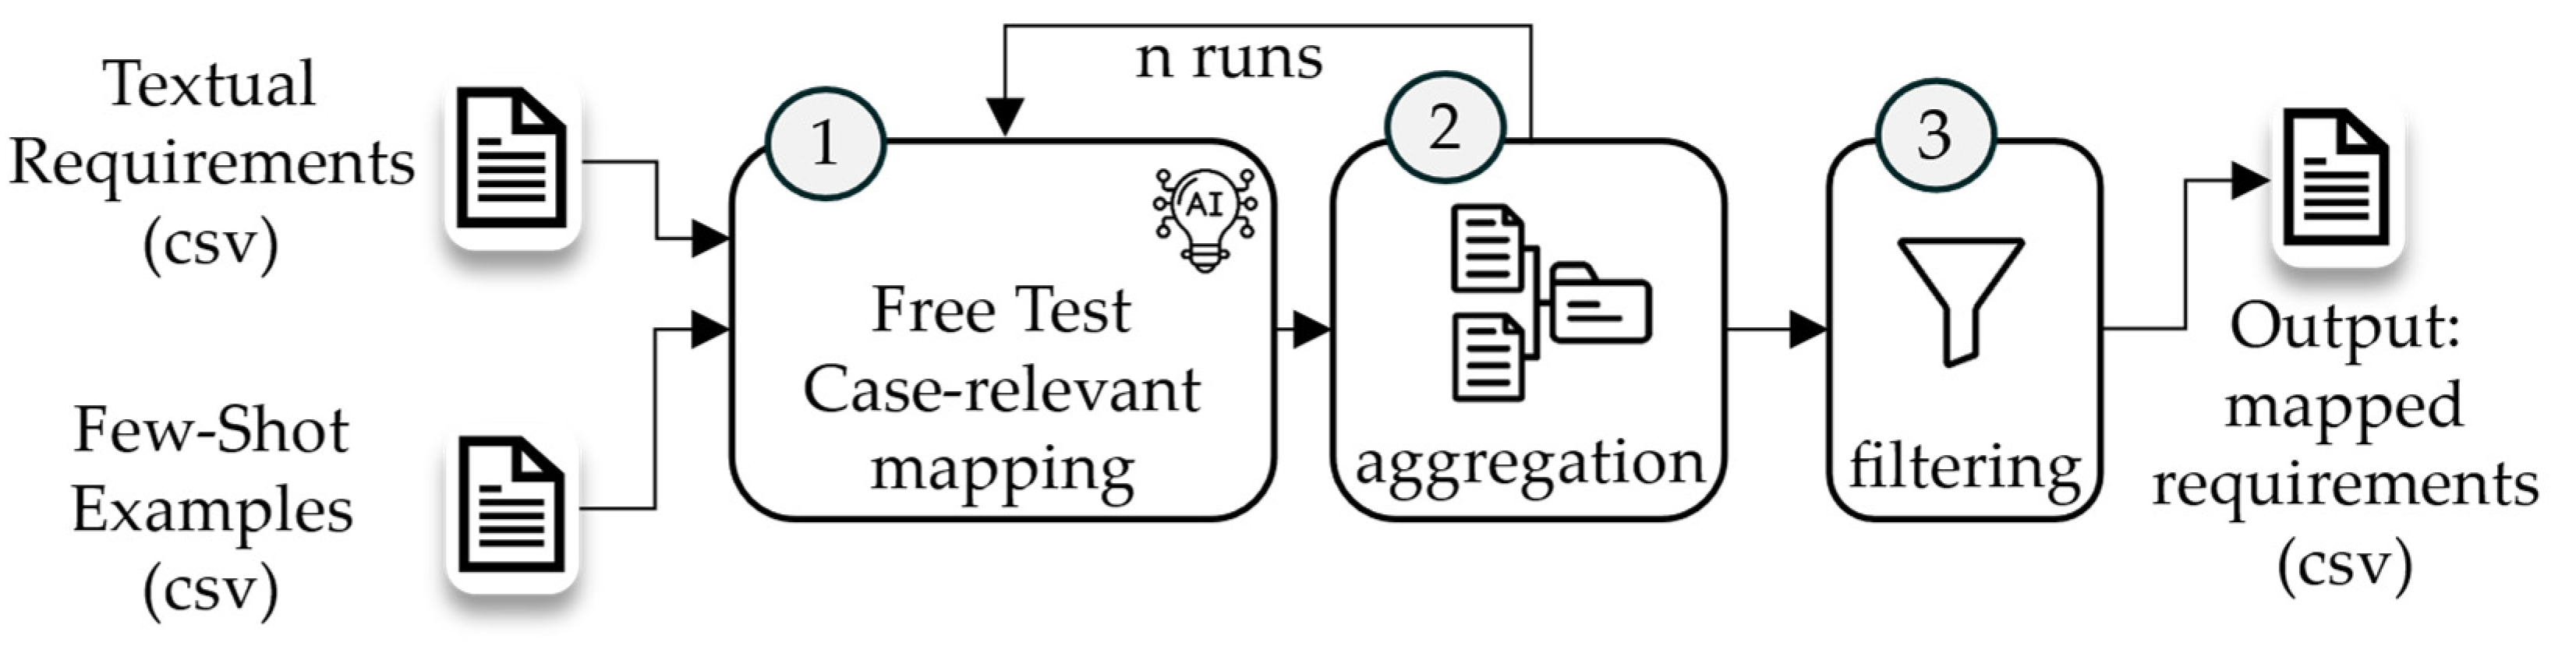
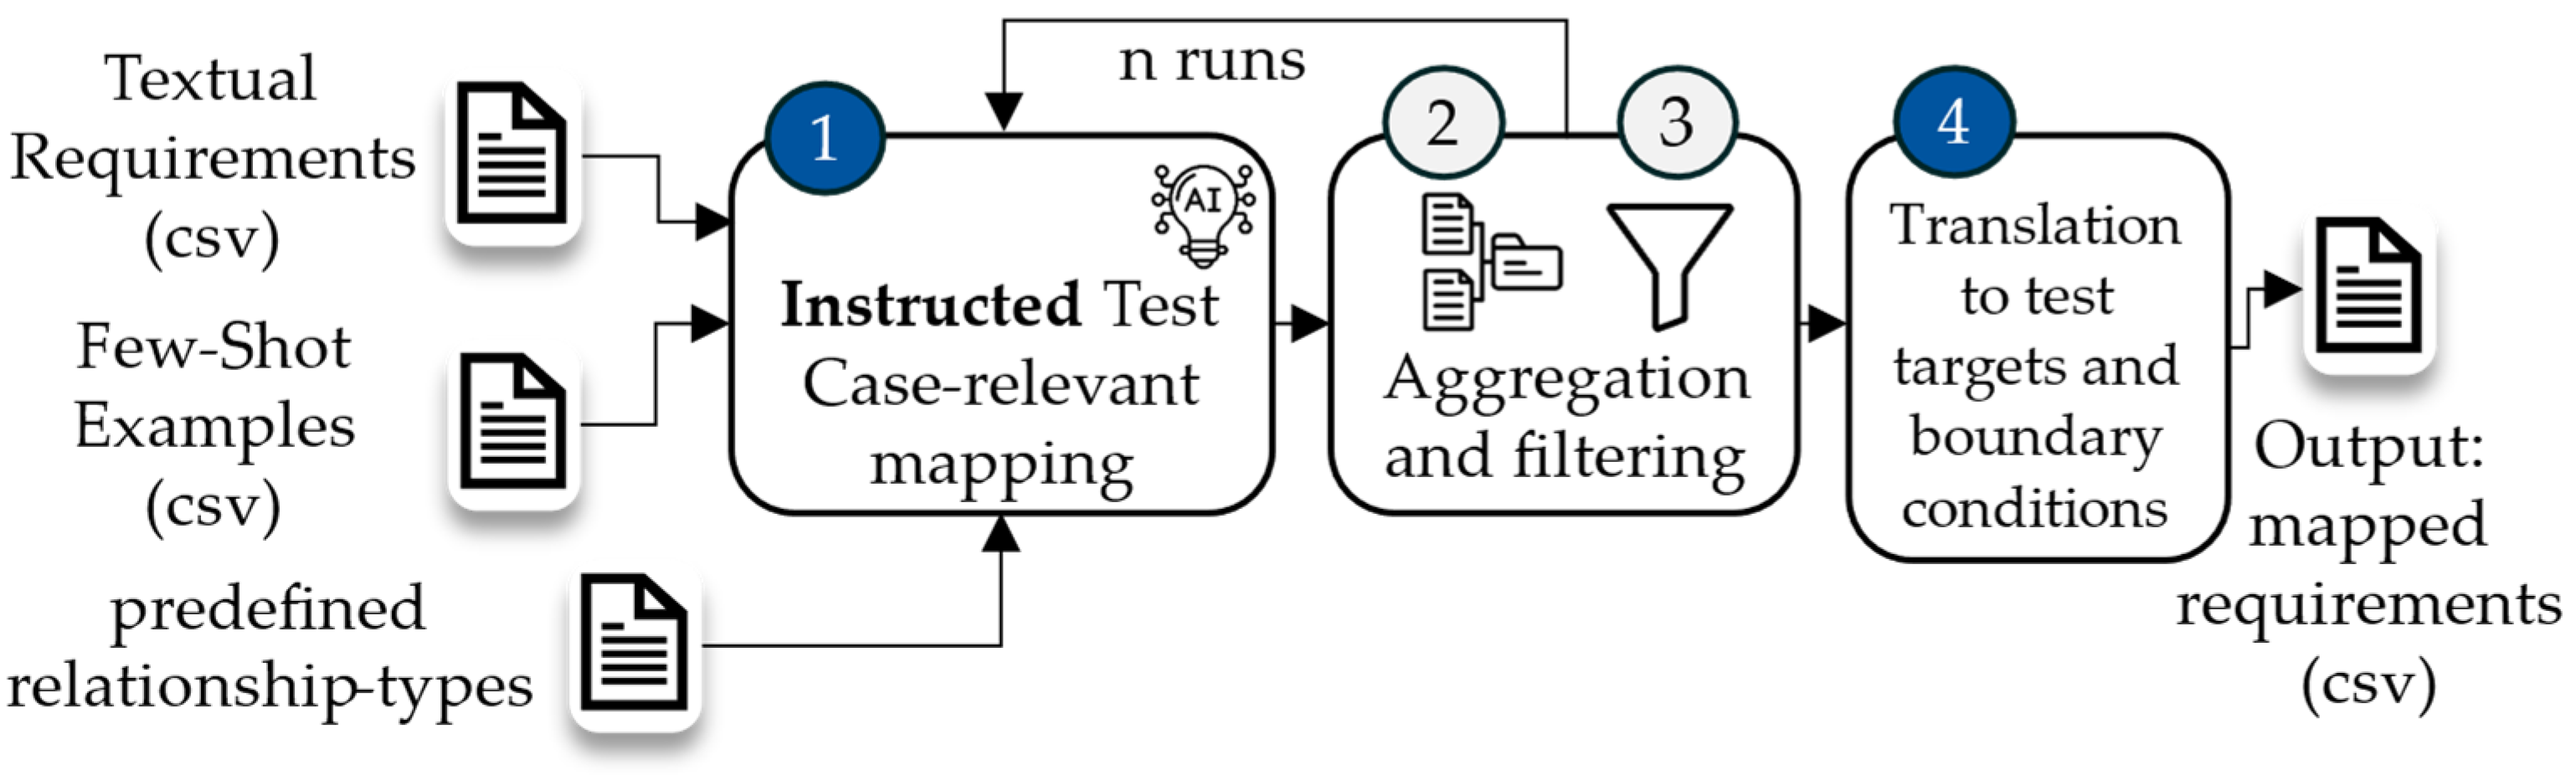
GPT-4o with a temperature of 0.1 was used to keep phrasing largely deterministic while preserving limited exploratory variation in requirement interdependency discovery. The workflow proceeds in three phases as shown in
Figure 6.
First, the LLM generates the desired requirement mapping (
Figure 6, number 1). Here, the aforementioned prompt is loaded and extended by a set of Few-Shot examples as well as the requirements to analyze. Second, the generation is repeated multiple times and the outputs are merged in a Neo4j graph (
Figure 6, number 2). By consolidating repeated generations in a Neo4j graph, multiple LLM outputs can be aggregated. Therefore, for every proposed requirement interdependency (e.g., “Req A ↔ Req B in Test X”) a consensus confidence is calculated which is defined as the proportion of runs in which the same interdependency reappears. Third, a consensus filter passes only those dependencies whose confidence exceeds a defined threshold, thereby suppressing volatile, one-off suggestions and yielding a more robust basis for subsequent test-case derivation (
Figure 6, number 3).
4.2. Results After Approach 1 Evaluation: Aggregation Improves Coverage, but Not Precision
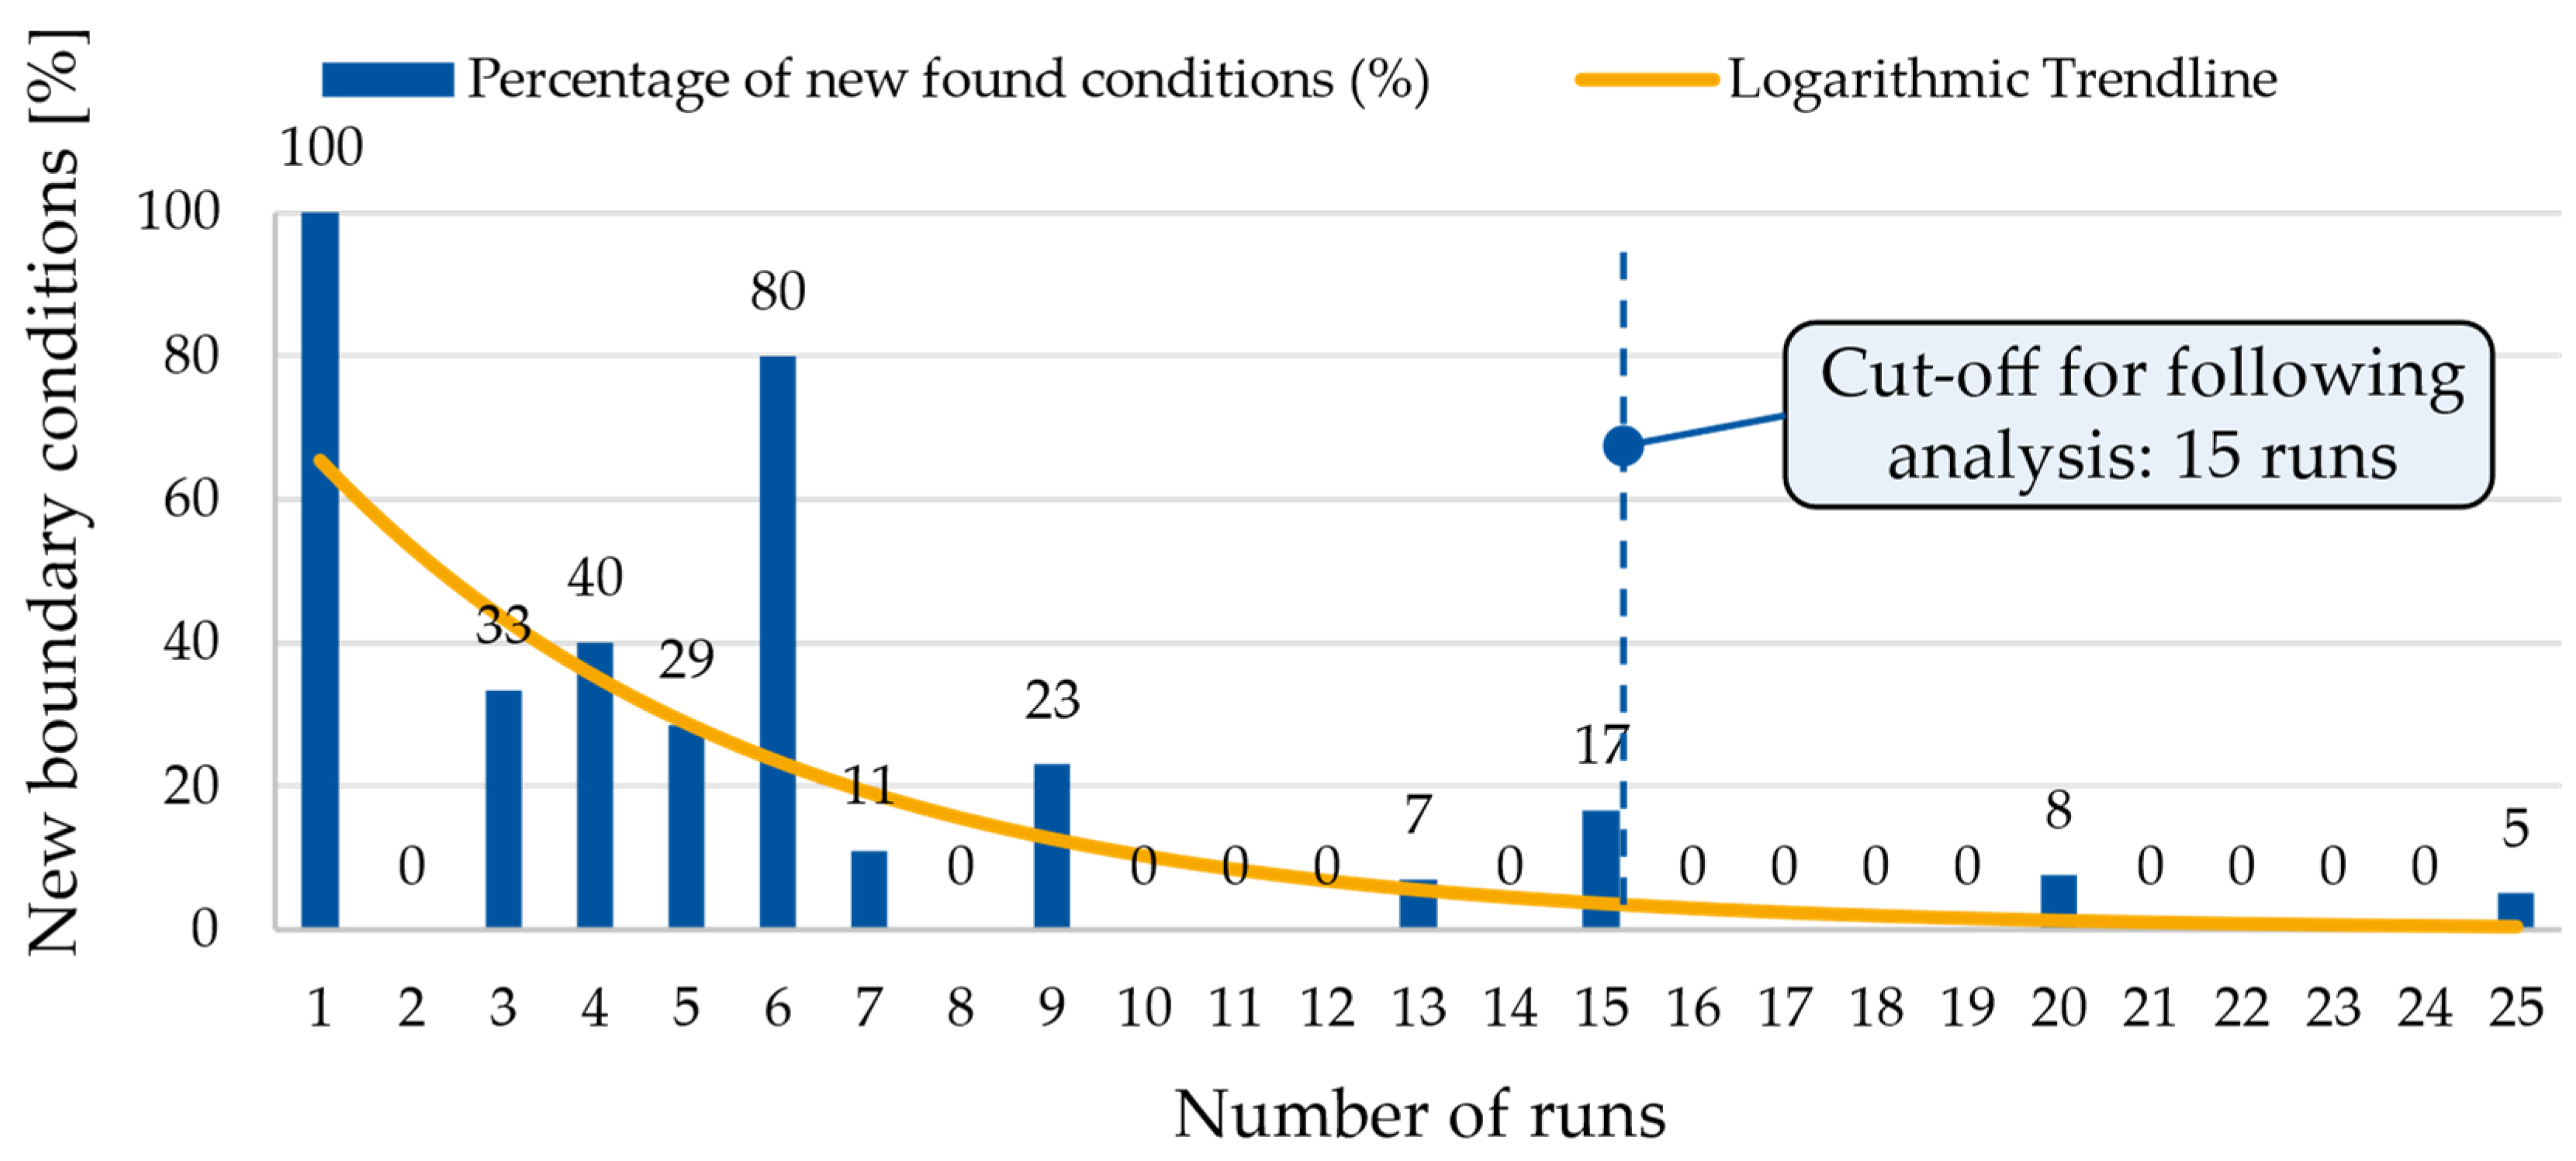
To select a suitable number of repetitions, an analysis of the discovery rate of newly appearing boundary conditions over 25 runs is conducted (see
Figure 7). The curve exhibits saturation: after approximately 15 runs, an additional run contributes on average only about 2% new boundary conditions found. Therefore, a fix cut-off of 15 consecutive runs per workflow execution is set for the following analysis.
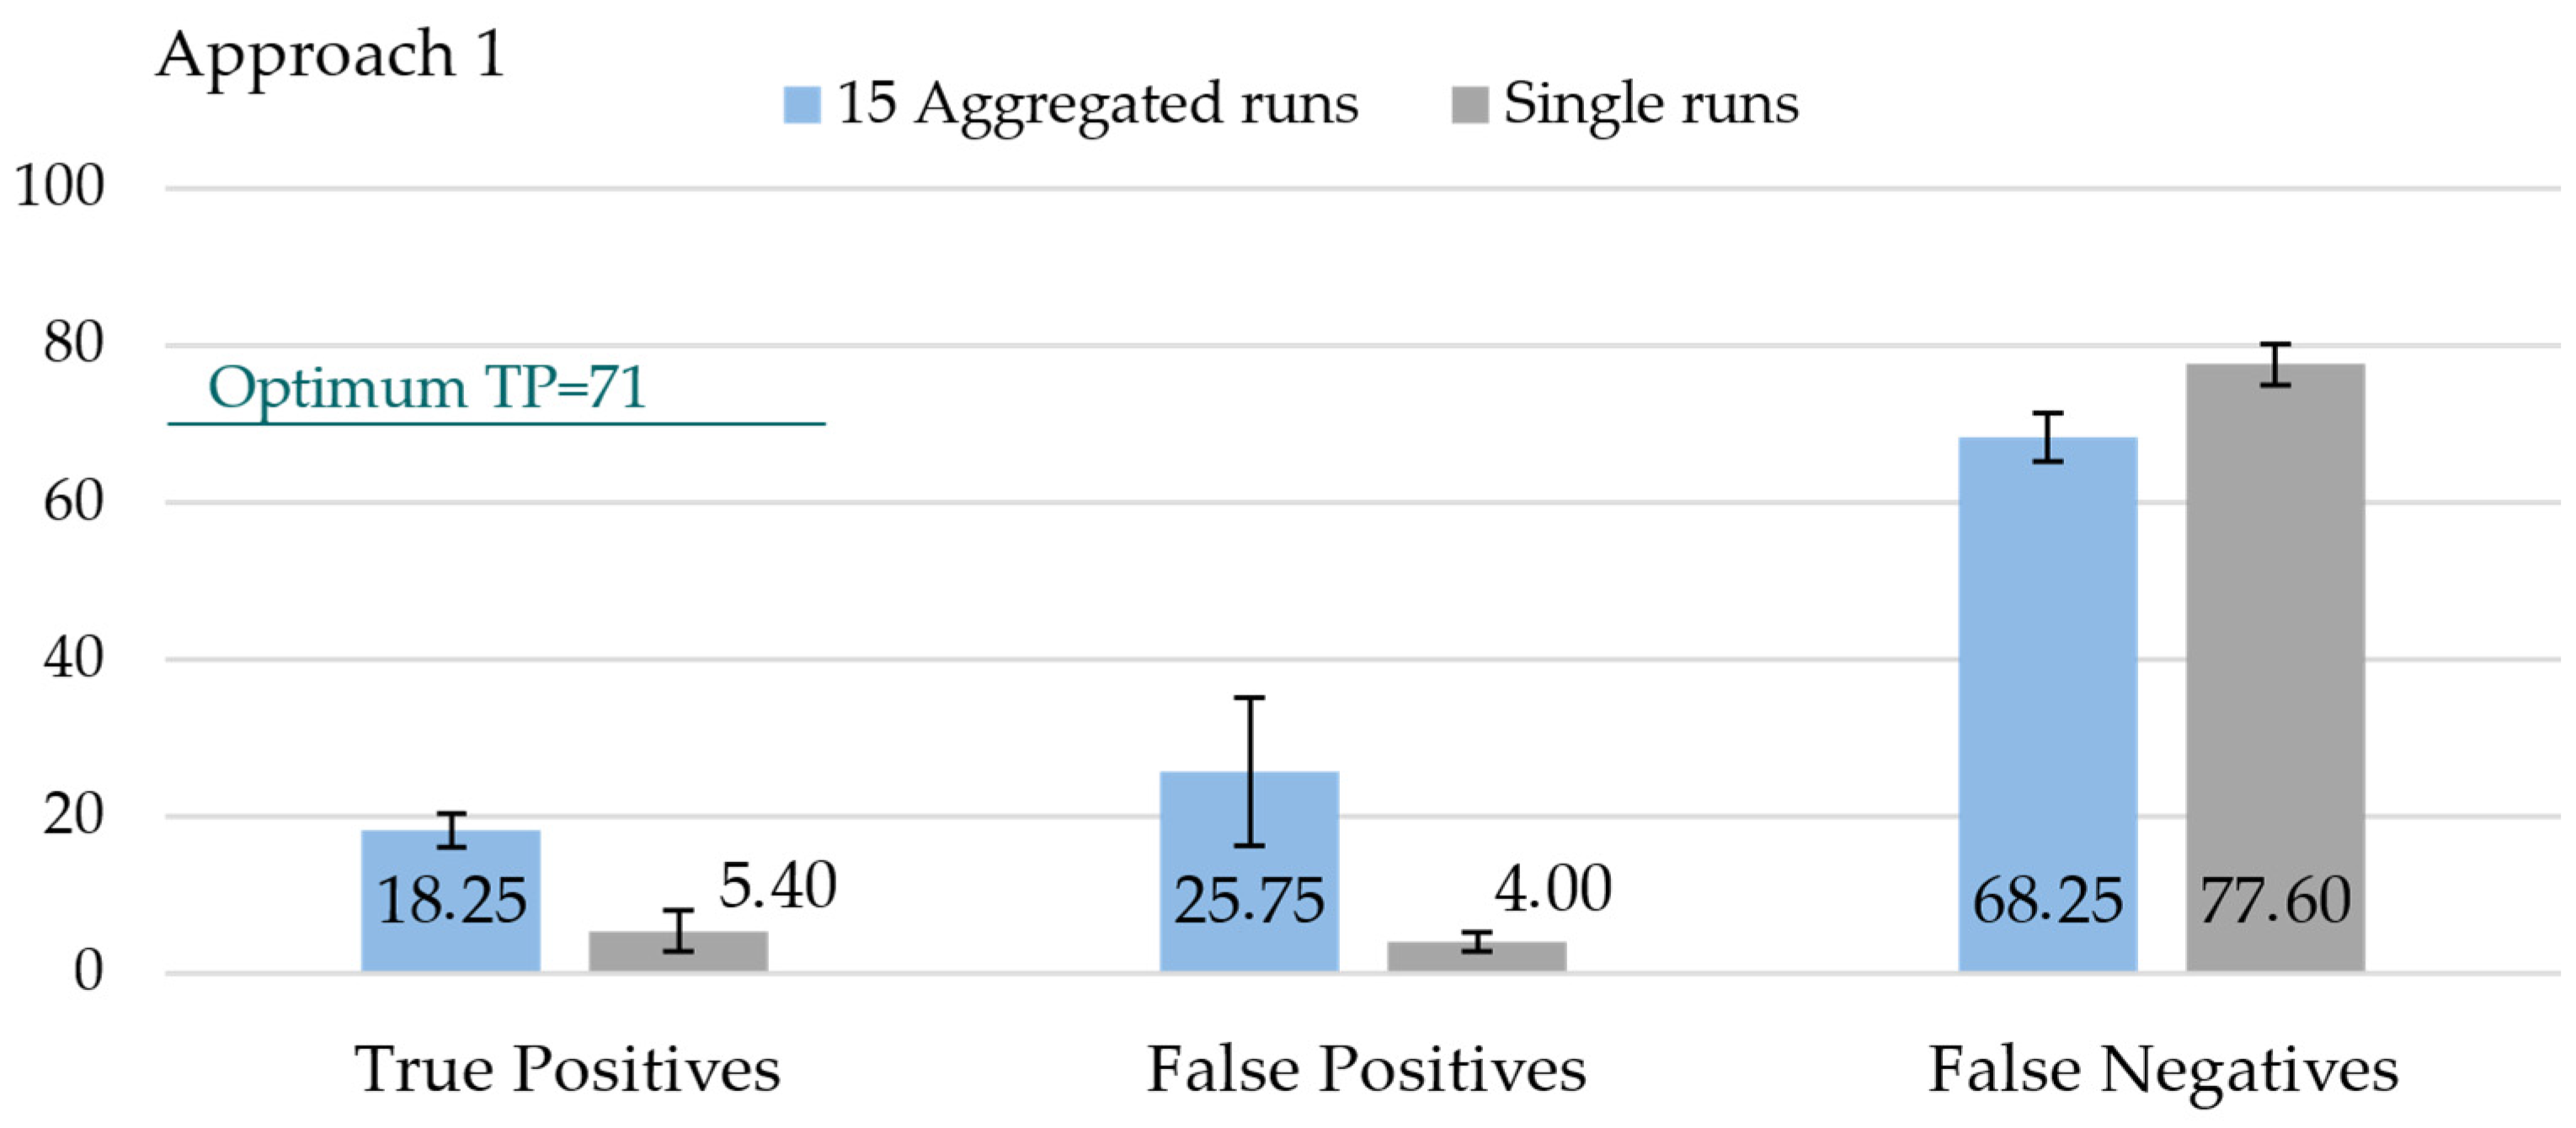
For Approach 1 evaluation (see
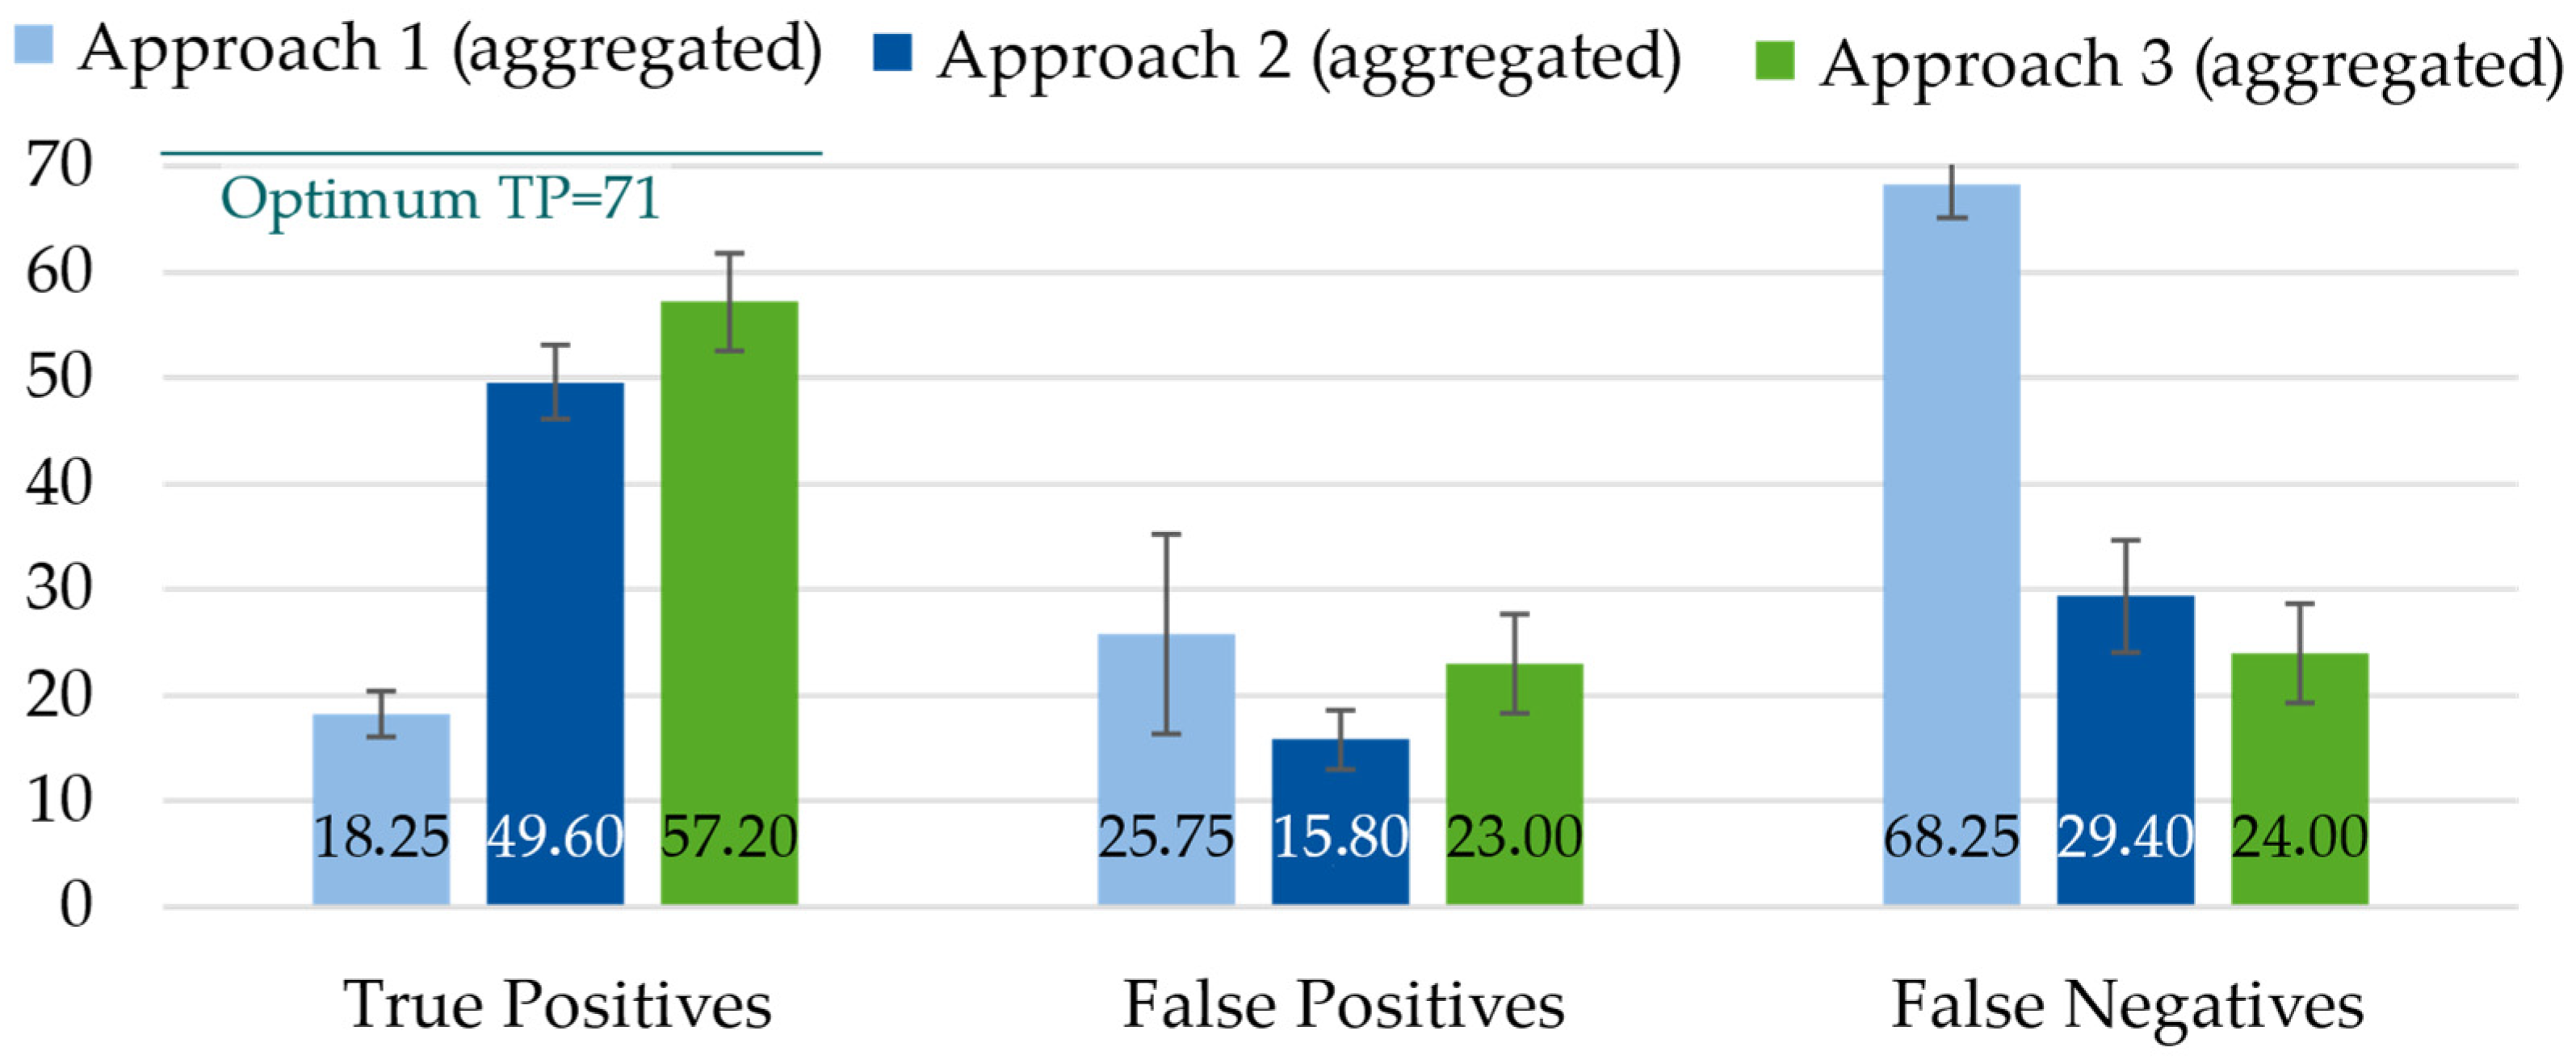
Figure 8), single runs are compared to an aggregated variant. With an optimum reference of 71 TPs, aggregation raises the mean TP rate from 5.4 (single runs, standard deviation SD = 2.61) to 18.25 (aggregated runs, SD = 2.22). This gain is offset by more FPs (mean 25.75, high variance, SD = 9.43). FNs decrease only slightly and remain high (68.25 on average, SD = 3.10). In short, aggregation improves coverage but not precision: the LLM finds more correct dependencies and, simultaneously, more incorrect ones. With a precision of 0.41 and a recall of only 0.21, Approach 1 reveals major limitations: without predefined relation types, the LLM largely relies on heuristic inference of what should be considered test-relevant boundary conditions for a given test target. These observations motivate the subsequent approaches.
4.3. Approach 2: Requirement Interdependency Taxonomy Provided to LLM
In this approach, the LLM receives an explicit taxonomy of test-relevant relationship types before any analysis is performed. The aim is to formalize how requirements interact from the testing perspective. The relation types were derived from the information that a complete, standardized test case must contain according to ISO 29119: boundary conditions such as (i) preconditions including configuration and environmental conditions and (ii) inputs such as stimuli, data, and actions to be executed, as well as test targets including (iii) expected behavior, and (iv) pass/fail criteria. Comparing these elements with the literature and mapping them to inter-requirement relations yields a compact set of types: Trigger, Environmental Condition, and Exclusion, Input and Assessment Criteria, as well as Goal Conflict (see
Table 4). The relation types are further intended to abstract common CPS interdependency patterns, such as mode switching, interface propagation, and cross-domain physical coupling. These patterns are captured through Trigger, Input, Environmental, and Exclusion relations, enabling broad applicability while preserving a compact, test-oriented taxonomy. For example, mode switching constraints can be represented via Trigger relationships, interface propagation constraints via Input relations, and cross-domain physical coupling via Environmental, Input, or Exclusion relationships.
The workflow extends Approach 1 by adding a second requirement analysis step before the final test-case requirement mapping (see
Figure 5 top). Before the requirements are mapped for their boundary condition and test target relationships, a deeper analysis of the requirement interdependence is performed.
Figure 9 illustrates Approach 2. In the first step (
Figure 9, number 1), the LLM (GPT-4o, temperature 0.1) is given the natural-language requirements and a set of Few-Shot examples—this time mapping the requirement analysis based on the given requirement interdependency taxonomy in
Table 4.
The prompt was defined as follows (abridged):
“[…] Compare all the following requirements with each other and create relationships between the requirements based on the relationship types given below. […] Possible relationship types are:
Trigger, formatted as A-Trigger->B, meaning that fulfillment of Requirement A triggers the execution of Requirement B.
Environmental, formatted as A-Environmental->B, meaning requirement A defines relevant environment information for the fulfillment of requirement B.
[…]
Return only relationships with a label ≠ "None".
Few-Shot examples of similar requirements are provided below to guide your decision-making.
{"id": "12", "text": "The valve shall prevent any leakage in the closed state.", "common": ["State", "Function"]},{"id": "67", "text": "During emergency shutdown, the valve closing time shall not exceed 2.5 s.", "common": ["State", "Phase"]},{ "id": "89", "text": "The valve actuator shall be electrically driven.", "common": ["Function"]} { "relationships": [ { "src": "48", "dst": "12", "relation": "Evaluation" },{ "src": "48", "dst": "67", "relation": "BoundaryCondition"}]}
[…]”
A structured output formatted as a JSON file was given (as well as an example for the structured output).
The second and third steps repeat the aggregation and consensus filtering used previously: multiple runs are merged in a Neo4j graph, a consensus confidence is computed for every proposed interdependency, and only relations above the threshold are retained to suppress volatile suggestions (
Figure 9, number 2 and number 3).
After step 3, the requirements are mapped based on the interdependency taxonomy in
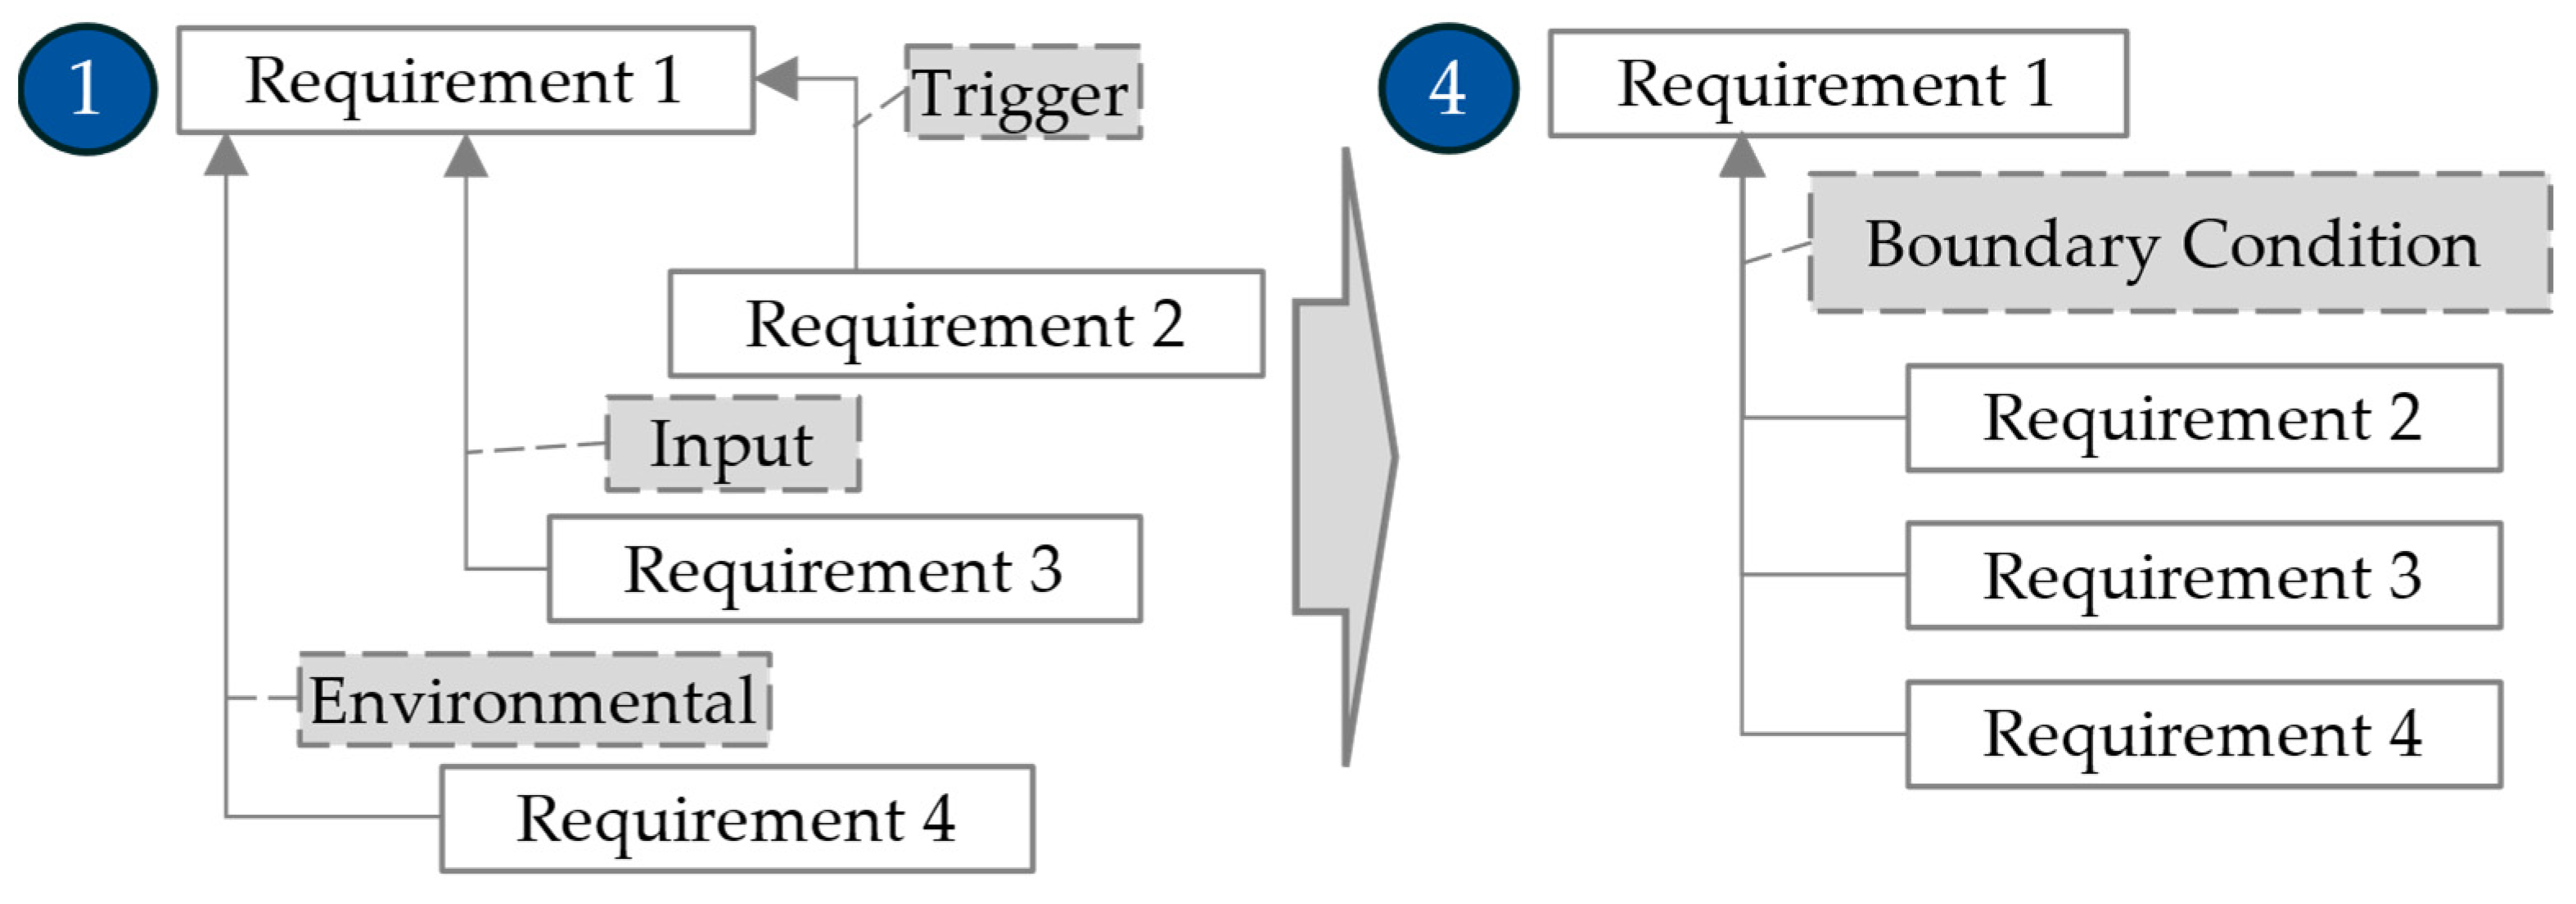
Table 4 and filtered based on the consensus. In the fourth step, the dependencies are translated from the interdependency taxonomy into the test-case requirement mapping structure of targets and boundary conditions (see
Figure 5 and
Figure 10 “Mapped requirements”). The translation rules are given in
Table 4 in the column “Representation in test case”.
4.4. Results After Approach 2 Evaluation: Preceding Taxonomy-Guided Requirement Analysis Improves Precision
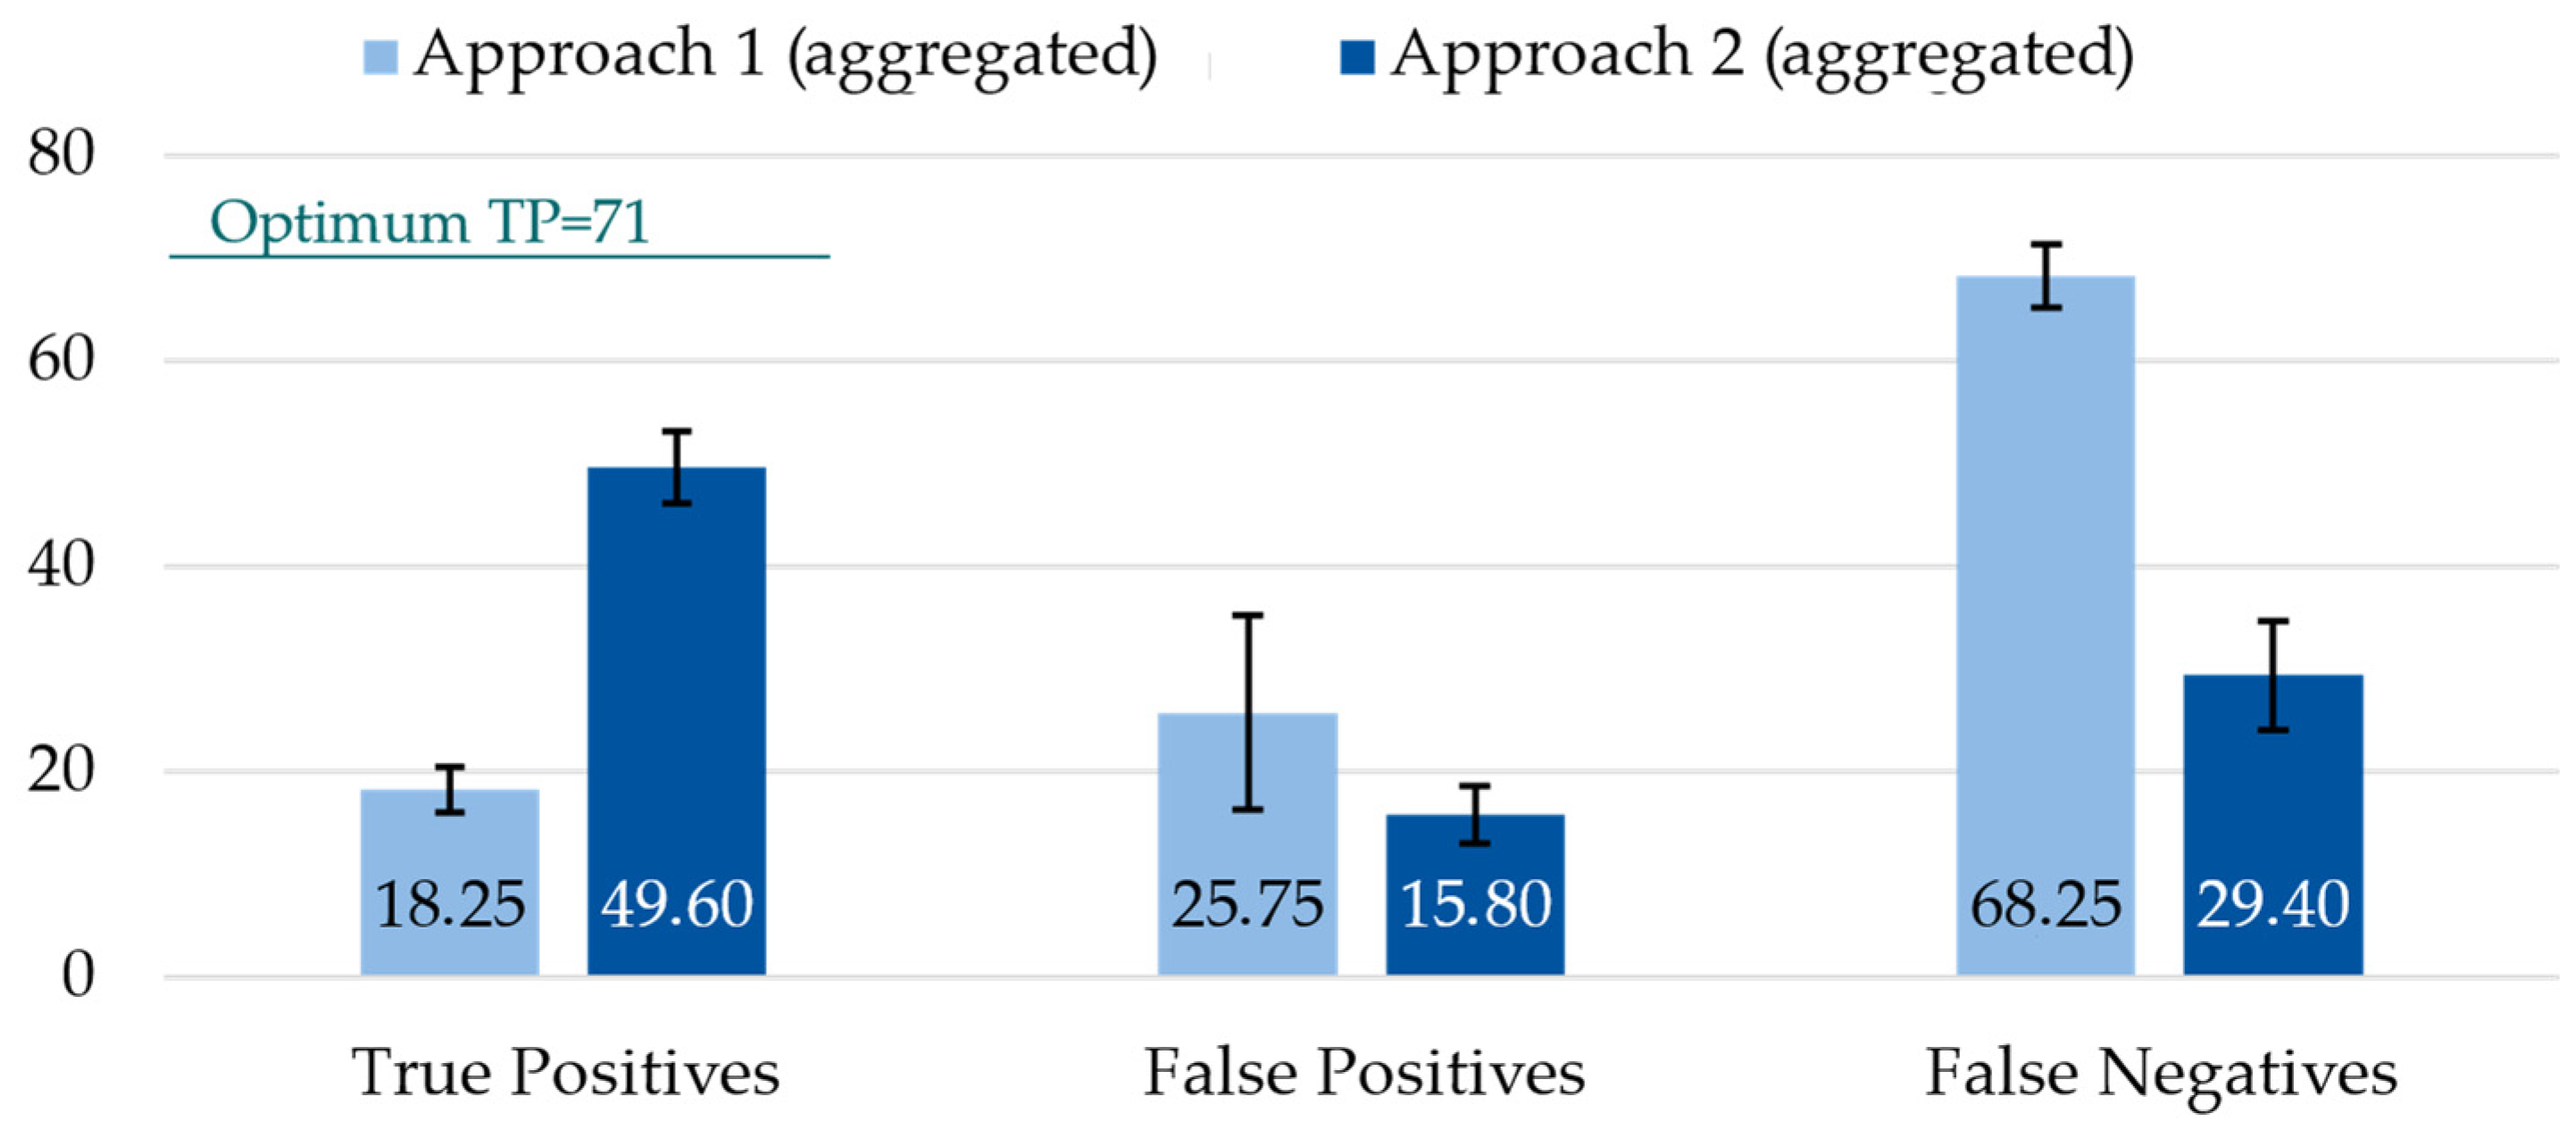
Evaluation of Approach 2 (see
Figure 11) shows that the taxonomy-guided analysis improves the results markedly relative to the aggregated direct baseline of Approach 1. TPs rise to 49.6 (SD = 3.51) on average (≈2.5× Approach 1, 70% of all possible TPs), FNs are almost halved to 29.4 (SD = 5.32), and FPs drop to 15.8 (SD = 2.77). The typed-relation step captures boundary conditions based on the requirements more systematically, yielding more complete and reliable test-case sets.
This process design integrating taxonomy-based requirement analysis offers a distinct advantage over free interdependency guessing. With the taxonomy, clearer rules for interdependency identification are given. The detailed taxonomy additionally leads to better generalization of the Few-Shot examples by the LLM. The association of Few-Shot examples with requirement interdependency types from the taxonomy leads to better learning and distinction in specific cases where an interdependency is to be identified. A general Few-Shot dataset like in approach 1 is ambiguous and leaves too much room for wrong interpretation and thus generalization of the Few-Shot examples. The number of Few-Shot examples in Approach 2 is not increased compared to Approach 1.
In sum, the results of Approach 2 (
Section 5, page 15) are drastically improved compared to Approach 1. Approach 2 provides a concise, test-oriented relation system that narrows and focuses the search space for the LLM while maintaining compatibility with established requirement analysis concepts, which results in more consistent and auditable test-case construction.
4.5. Approach 3: Requirement Interdependency Structure and System Model Context Provided to LLM
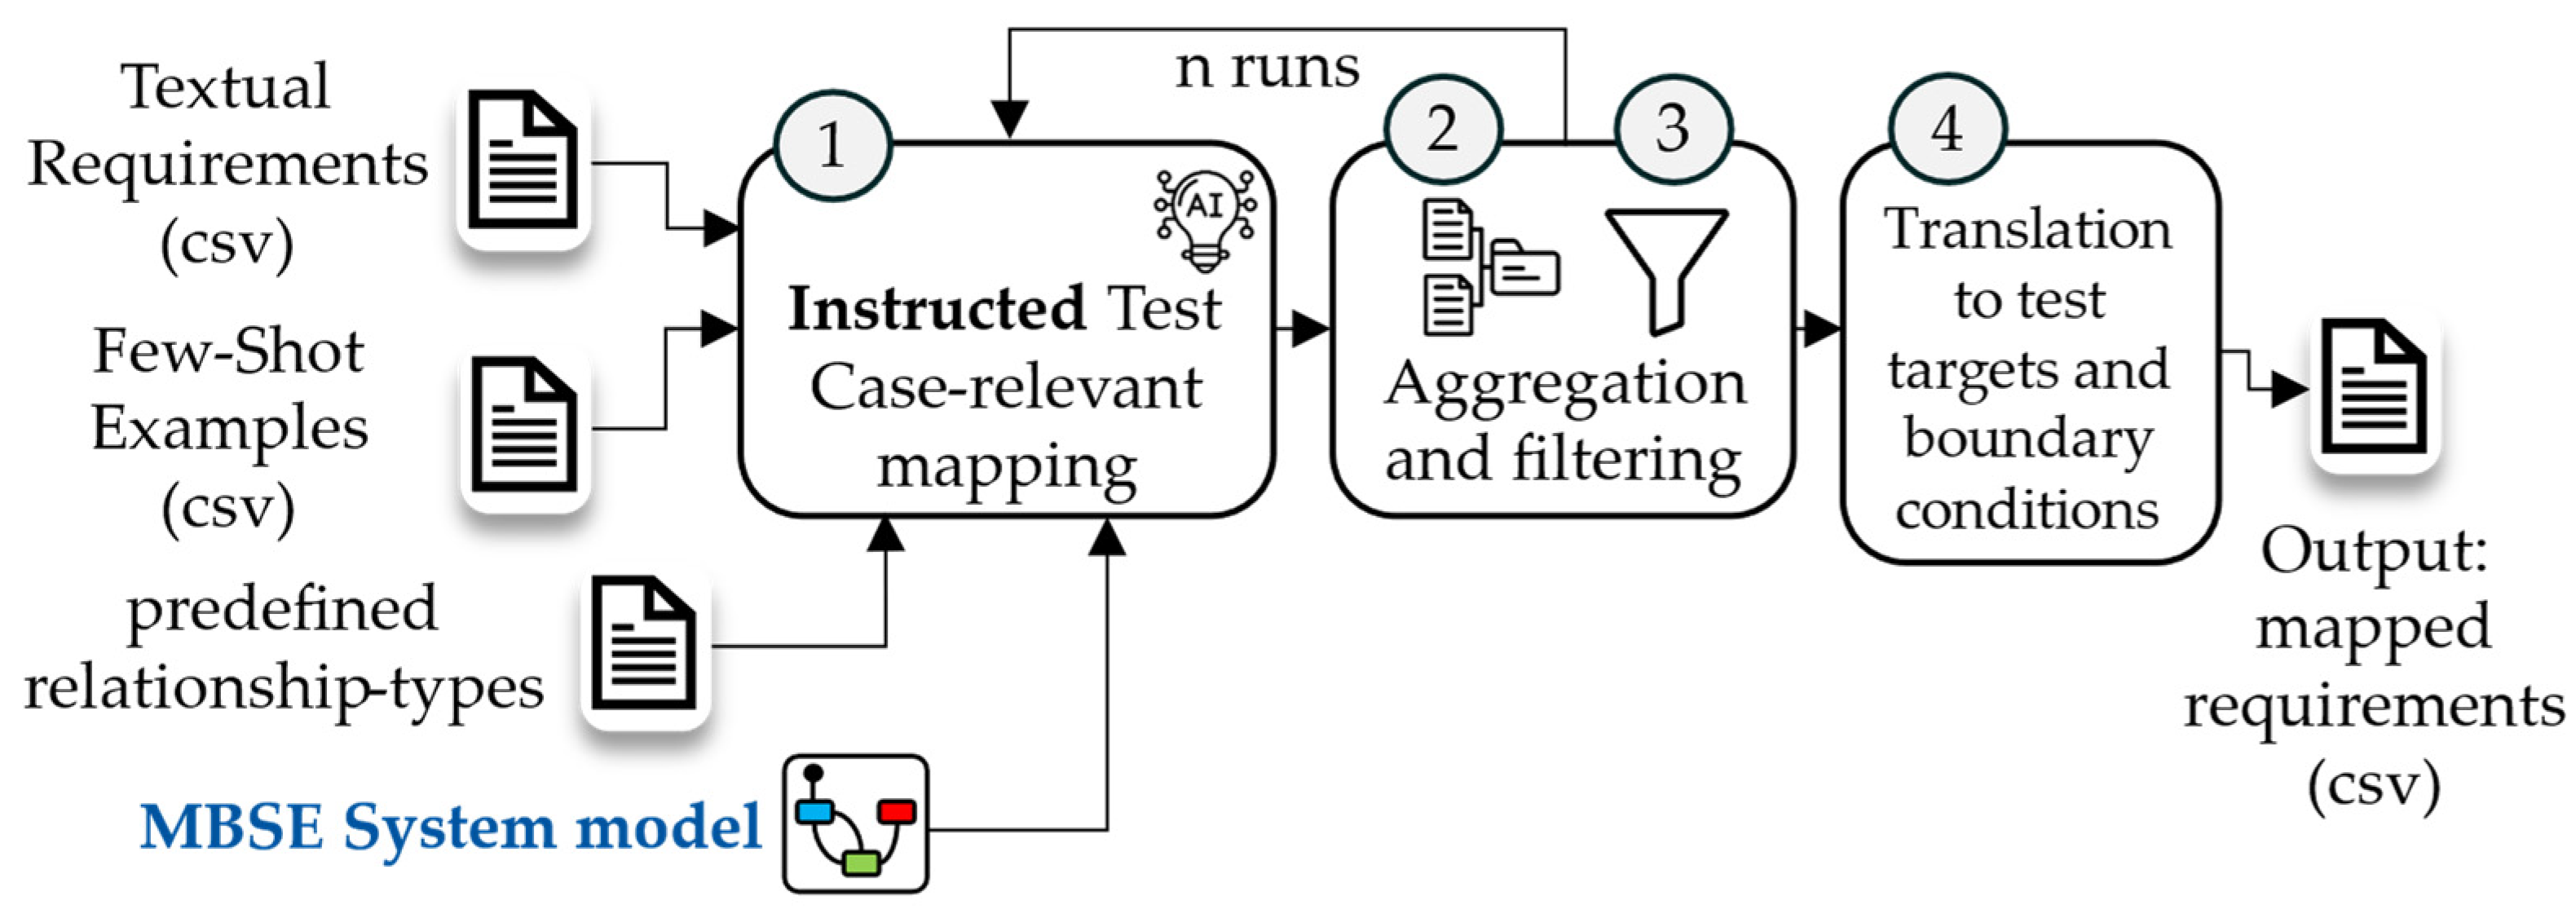
In this approach, Approach 2 is extended by the provision of system information from a MBSE system model. The LLM is given both the predefined taxonomy of requirement interdependency types and explicit MBSE system context prior to analysis as given in
Figure 12. A motego system model of the coolant pump—transferred to a Neo4j graph—is integrated via a Graph RAG procedure that retrieves a focused subgraph of system information. In the Graph RAG search only the information relevant to the specific analysis step is extracted, thus reducing the required tokens. With context in place, the interdependency identification step proceeds as in the previous approach, followed by the same aggregation and consensus filtering, and the rule-based translation into test-case structures (see
Figure 12, numbers 1–4).
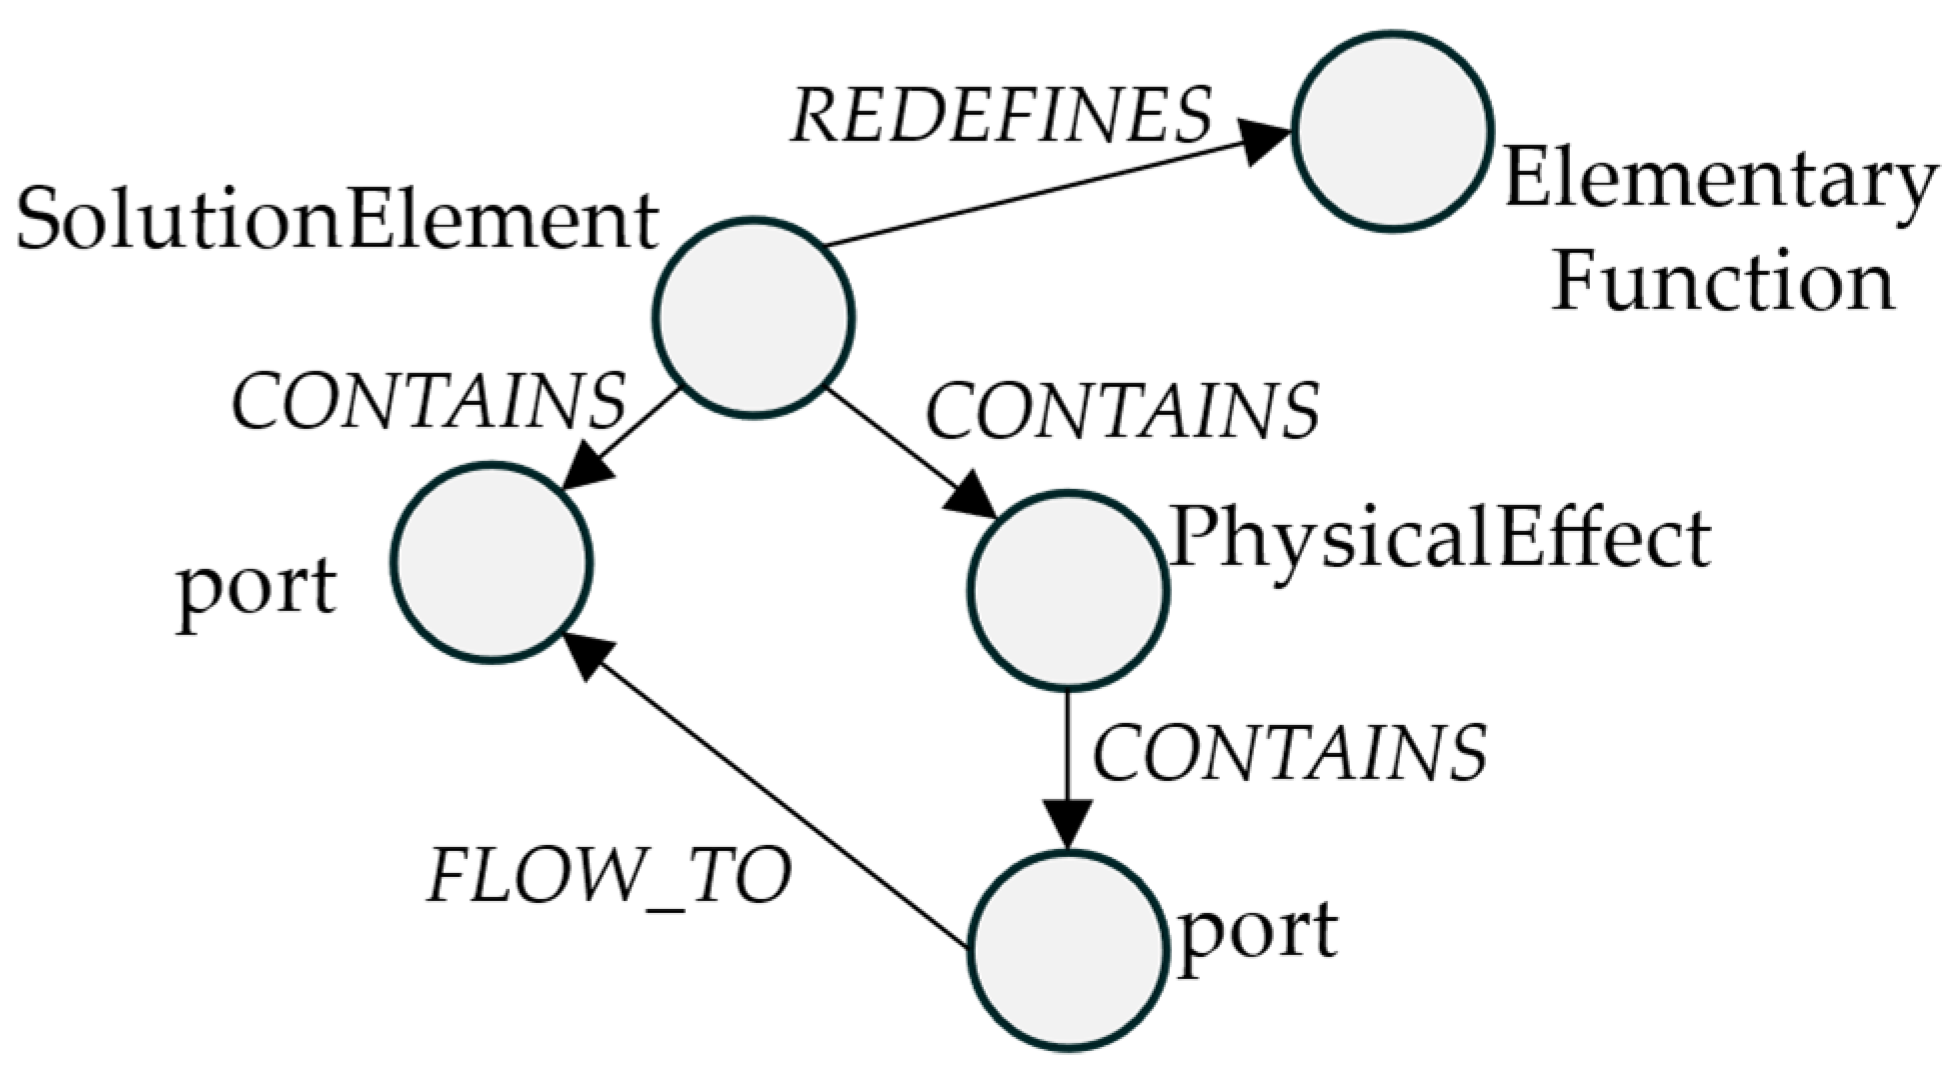
MBSE system models provide a rich knowledge source that contains all development information. The MBSE model is represented as a typed-property graph with a unified node schema (id, name, metadataTag, metaType). The graph elements are directly derived from the motego [
72] model structure of the system model as shown in
Figure 13. In the graph, model elements such as solution elements, ports and attributes are modeled as explicit nodes. Hierarchical connections are expressed using CONTAINS and REDEFINES relationships, including explicit base nodes for port redefinitions. Behavioral and structural relations are encoded as typed edges (e.g., FLOW_TO, BINDS, PERFORM, SUCCESSION). State machines are modeled explicitly with nodes for state machines, states, and actions, connected via containment and direct semantic links.
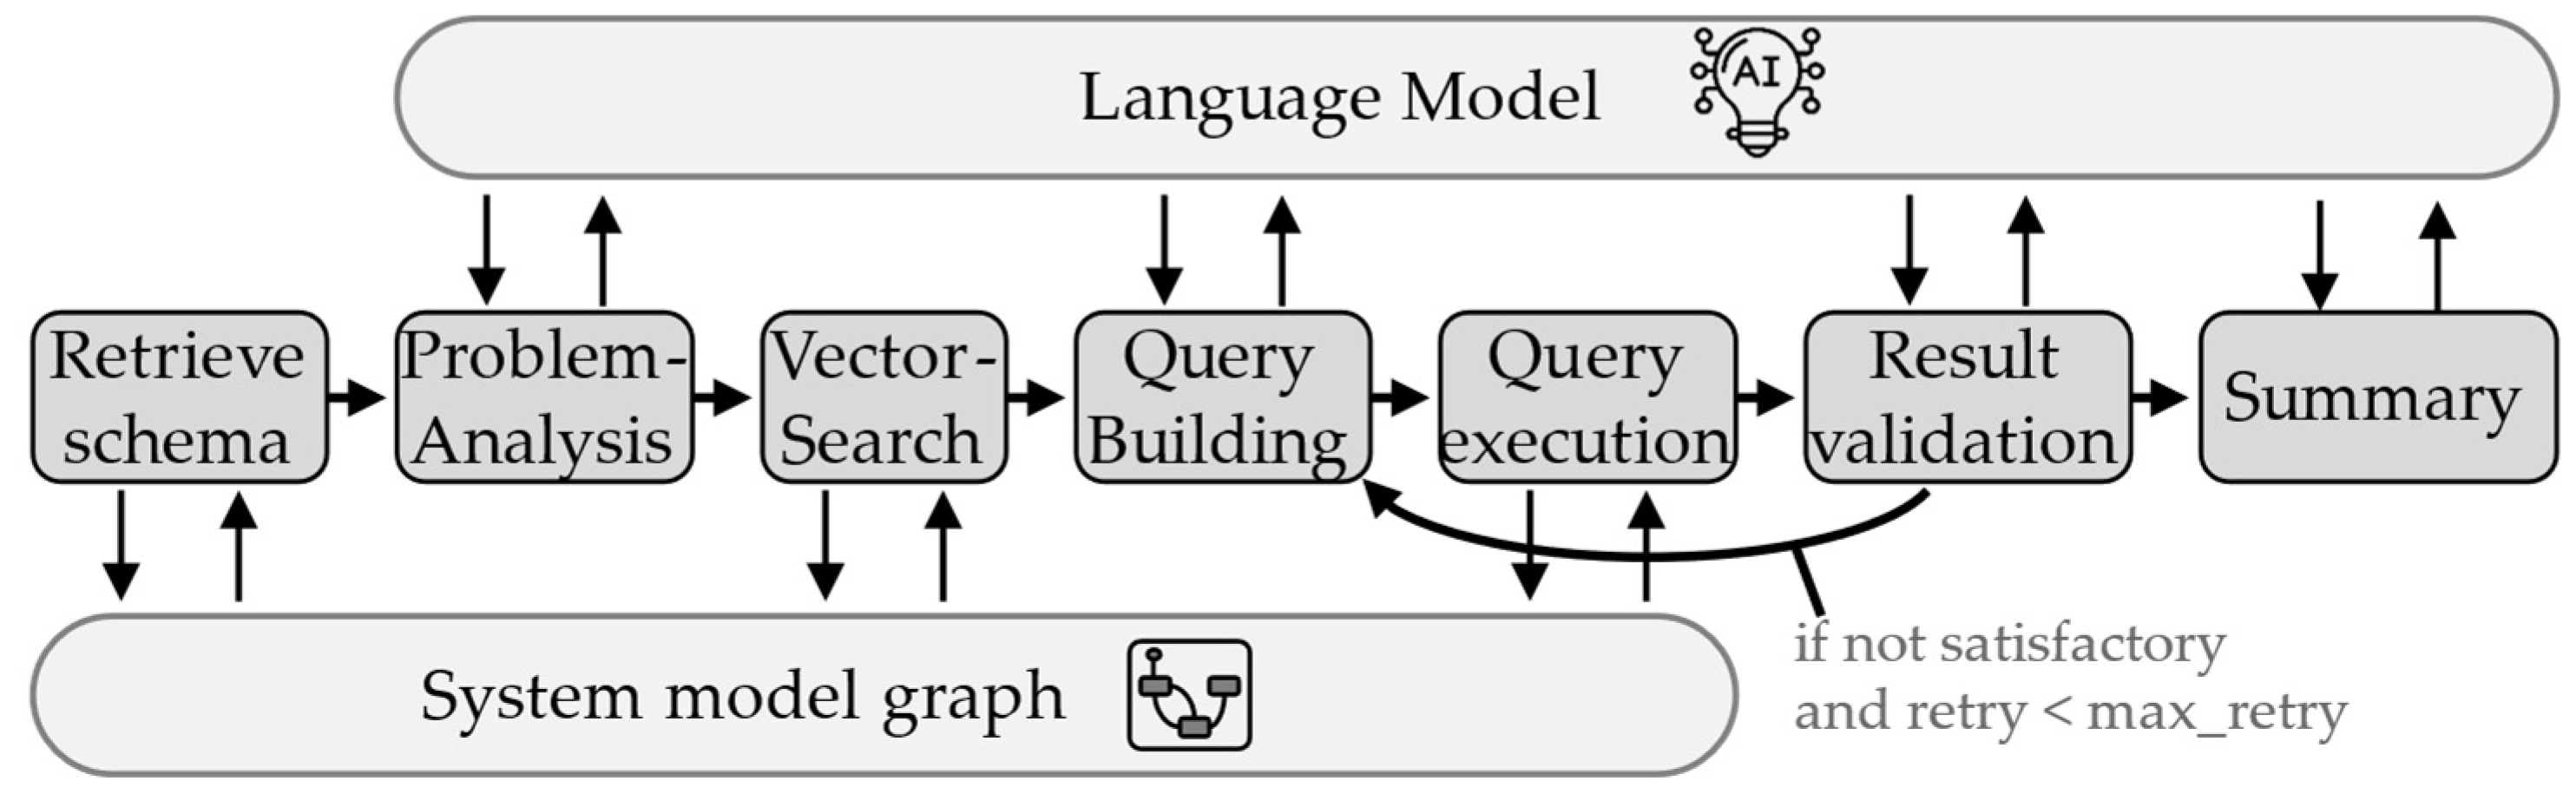
Adding the whole system model to the LLM input could exceed the token window of the LLM, depending on the size of the system model. On the other hand, for the analysis of a specific requirement, not all information from the system model is relevant. The comprehensive context injection process shown in
Figure 14 is required to identify the relevant information from the MBSE system model graph needed for the requirement analysis.
First the graph schema is queried so that the LLM is aware of the available node and edge types and their attributes. Based on the input requirement, the LLM then performs a brief problem analysis that extracts relevant technical keywords and search terms derived from the requirement text and its context. These keywords are then used in the vector search (semantic) in the graph to retrieve relevant model elements as entry points. Using these entry points and the previously extracted schema information, the LLM composes a graph query which is executed against the MBSE model to obtain a focused subgraph. This subgraph typically contains the identified elementary functions, their realization by solution elements and neighboring elements, and the relation types that describe their structural and behavioral context. The retrieved subgraph is then validated by the LLM against the information need defined by the problem analysis; if necessary, the query is iteratively refined. In a final step, the validated subgraph is transformed into a compact natural-language summary that lists the relevant functions, solution elements, and relationships. This textual summary is inserted as a dedicated context segment into the requirement interdependency mapping prompt and provides the domain- and product-specific knowledge required for more informed reasoning about possible dependencies.
The Graph RAG output is then inserted into the requirement analysis prompt:
“[…] Compare all the following requirements with each other and create relationships between the requirements based on the relationship types given below. […] Possible relationship types are:
The water pump (block Water Pump Assembly) is a central component of the vehicle’s cooling circuit. It is driven by a brushless DC motor (BLDC), which is controlled by the pump control unit (ECU_CoolantCtrl) via a PWM signal. The cooling circuit connects the water pump to the engine block, the heater core, and the radiator through coolant lines.
Relevant context was identified as energy sources of the water pump. In the SysML model, the water pump is connected via the following energy ports:
SignalPort → PWM control signal from ECU_CoolantCtrl
PowerPort → 12 V on-board power supply
[…]”
4.6. Overall Results After Approach 3 Evaluation: System Context Injection to the LLM Input Only Marginally Influences Results
Approach 3 (see
Figure 15) demonstrates that providing system context from a system model Graph RAG on top of the typed-relation analysis increases TPs further to 57.2 (SD = 4.66) (81% of all possible TPs) and reduces FNs to 24.0 (SD = 4.69). However, FPs rise from 15.8 (SD = 2.77) to 23.0 (SD = 4.74). Thus, system context increases recall but simultaneously reduces precision, resulting in no unambiguous improvement in overall performance compared to Approach 2 for the test example. The effect can therefore be interpreted as a trade-off between coverage and specificity rather than a clear performance gain. It can be assumed that the system context injection with MBSE system model information improves the LLM’s system understanding. Requirements are interpreted within the architecture and operating modes they affect.
The rise in false positives is likely due to an increased noise in the LLM input. The addition of the system information might overstimulate the LLM as it tries to integrate all system information provided to the requirement mapping. In the future, more work on the analysis of system models for test-case definition will be needed.
The results become even clearer when compared based on the evaluation metrics (see
Table 3). The predefined interdependency structure substantially improves both metrics (see
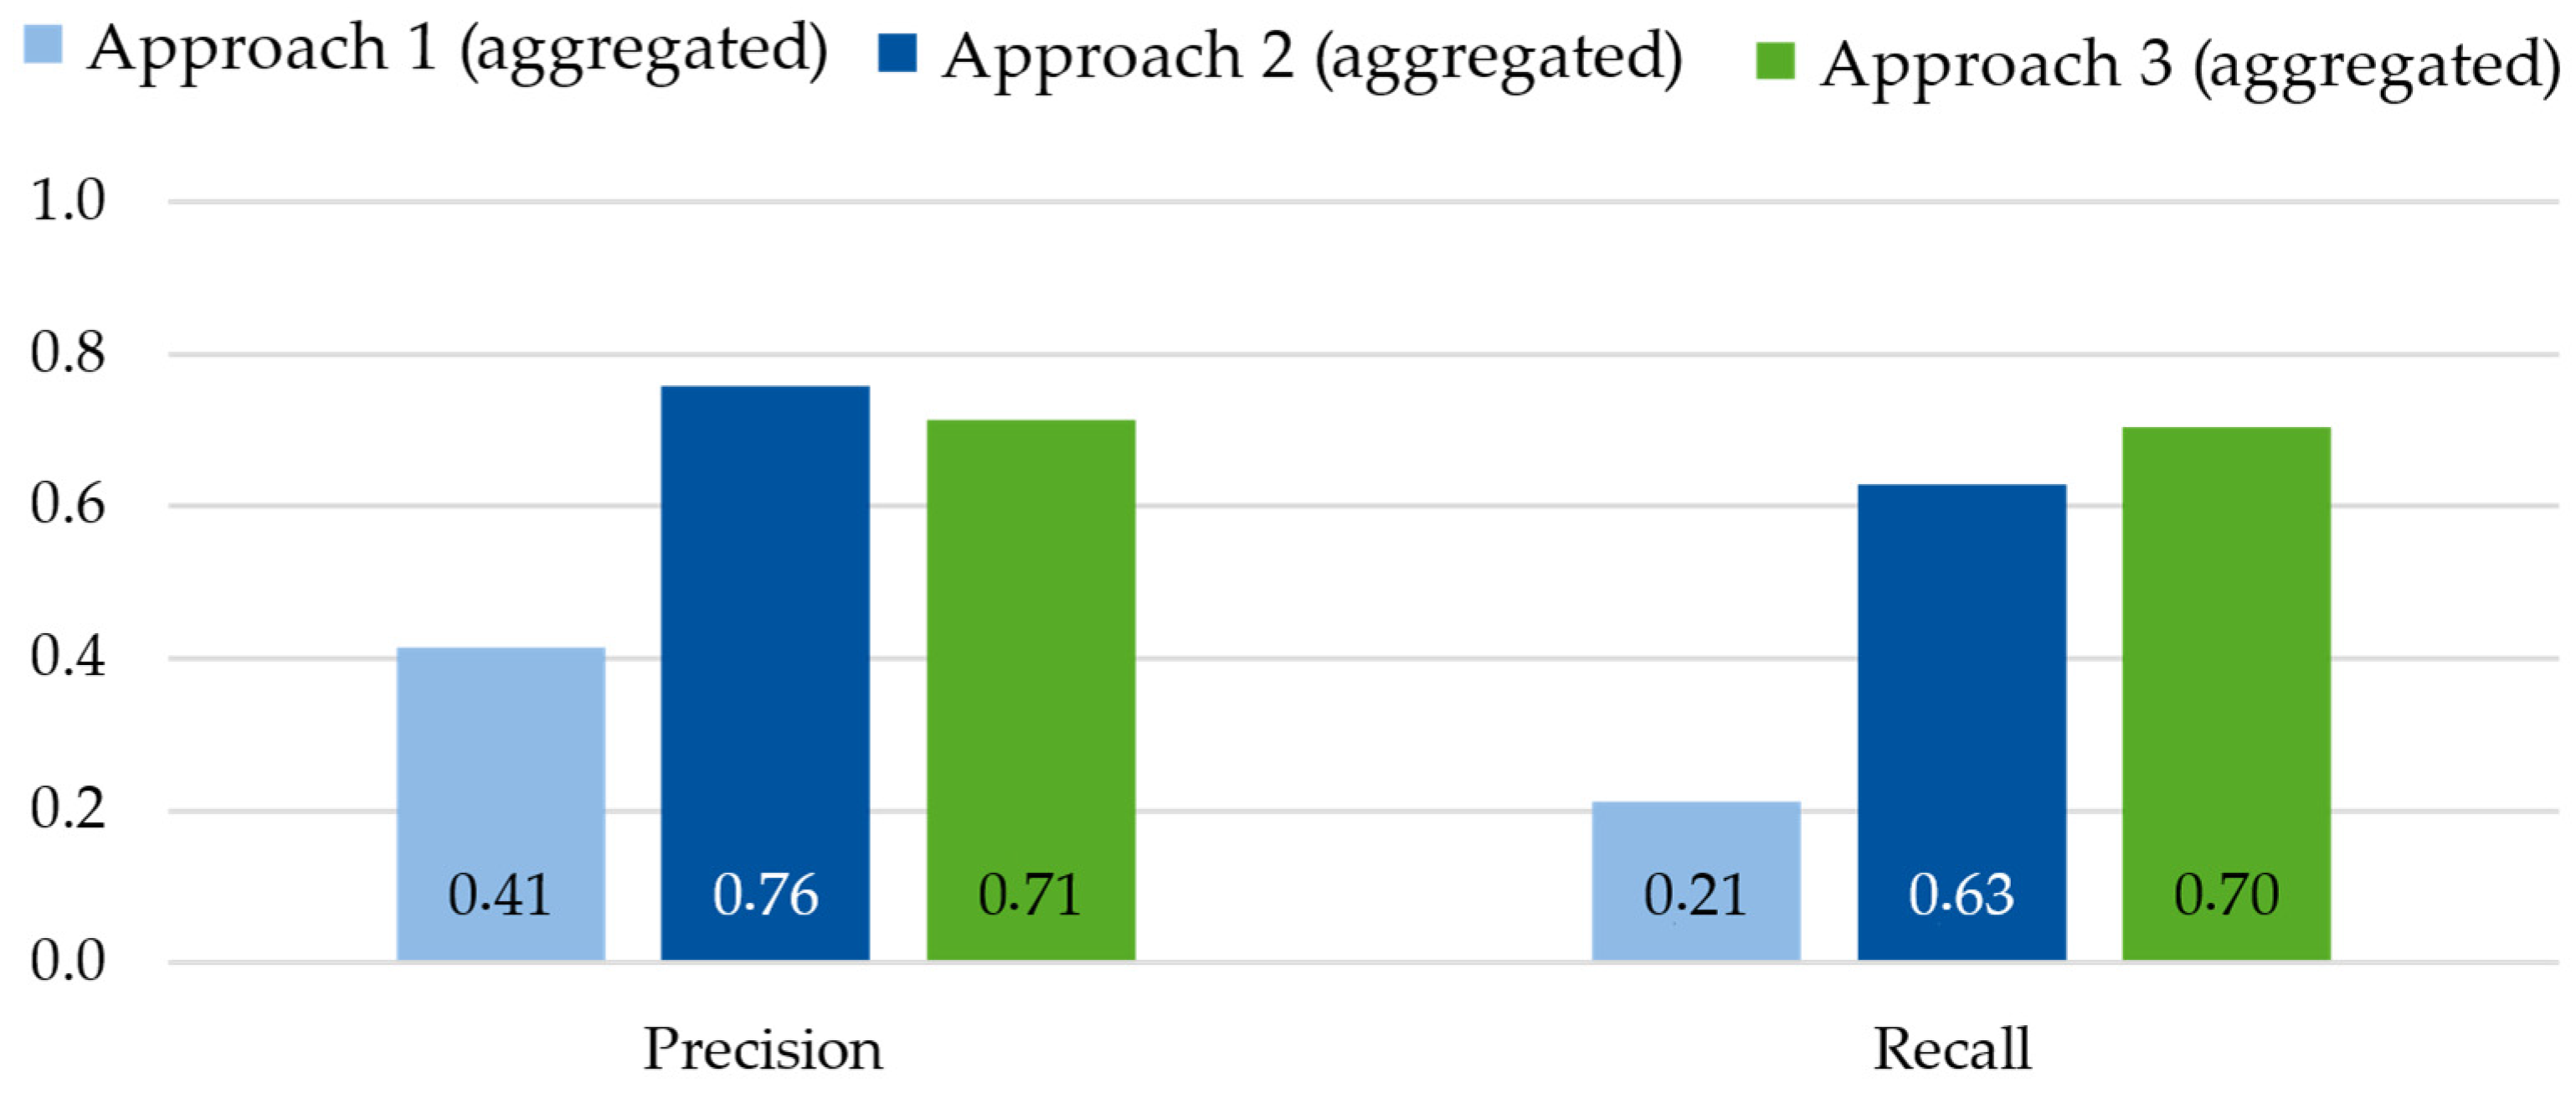
Figure 16) over the direct approach: precision climbs from 0.41 to 0.76 and recall from 0.21 to 0.63. Adding system context yields a small recall gain (0.70) but does not further increase precision (0.71).
Against the standardized ISO 9906 set, the taxonomy-based requirement analysis approach (Approach 2) aligns best: 73.9% overlap versus 0% (single) and 5.6% (aggregated) for the free approach. Adding system context achieves a similar score of 71.2%, i.e., no measurable improvement over Approach 2.
The modest impact of system context is plausibly due to the simplicity of the coolant pump example: the customer specification already encodes most functional and interface knowledge, leaving little for the MBSE model to add. For more complex, system-level scenarios, where architecture and cross-domain interactions dominate, the contextual grounding is expected to contribute more strongly. This case should be examined in the future.
5. Discussion
The evaluation results provide empirical support for the formulated research question (RQ, “How can LLMs be used to extract relevant information from natural-language requirements for test cases with boundary conditions that cover complex physical interdependencies of CPS?”) and are consistent with the stated hypotheses. Regarding hypothesis 1 (H1, “Aggregating multiple LLM outputs can compensate for the non-deterministic behavior of LLMs, improving the consistency.”), aggregation across multiple LLM runs demonstrably stabilizes the model’s non-deterministic behavior and increases the consistency of detected dependencies, though it alone is insufficient for accurate boundary condition extraction. RQ and hypothesis 2 (H2, “A provision of predefined relationship types describing the possible test-relevant influences between requirements enables the LLM to extract deeper boundary conditions in test-case generation.”) are addressed by introducing predefined relationship types, which significantly enhance the LLM’s ability to interpret complex dependencies between requirements and derive test-relevant boundary conditions from them. With this structured representation, the model identifies boundary conditions more reliably and forms test-relevant requirement groupings with higher precision and recall. Finally, in line with hypothesis 3 (H3, “Integrating MBSE system models as contextual information about system behavior can increase the reliability of the analysis.”), the integration of MBSE system model context through Graph RAG further strengthens the semantic understanding of system behavior, improving coverage of the derived test cases by providing additional architectural context, but does not consistently improve overall performance due to a simultaneous decrease in precision. A visible increase in true positives could be shown. Although the improvement is modest in the simple coolant pump example, the results suggest that contextual grounding increases the completeness in terms of recall, although this improvement is accompanied by additional false positives in the present case. Nevertheless, the addition of system information from the MBSE system model increased the false positives and therefore decreased the precision slightly. This can be explained by the expansion of the semantic input provided to the LLM. Architectural and behavioral information enriches the model’s understanding of the system and encourages the identification of a broader set of potential dependencies, some of which extend beyond the strictly test-relevant scope defined by the interdependency taxonomy. It therefore can lead to overstimulation and an increased amount of noise in the input, as all input to the LLM influences the next token-generation process. As a result, Graph RAG primarily enhances coverage and system-level awareness, while precise boundary-condition extraction remains sensitive to the relevance and abstraction level of the retrieved context. These findings underline that contextual grounding through MBSE system models must be carefully scoped to support disambiguation without introducing context-induced overgeneralization. While the Graph RAG system used in this paper already supports a detailed analysis of the relevant parts of the MBSE system model, future work is needed to validate the Graph RAG input in larger systems.
Overall, the results provide empirical support to confirm the main hypothesis and are consistent with the assumption that LLMs can identify complex boundary conditions by analyzing interdependencies between natural-language requirements. In the third approach, the model successfully detected 81% of the test-relevant dependencies, indicating the feasibility of semantic reasoning for test-case generation.
However, the approach alone is not yet sufficient for comprehensive coverage. In the current state, the approach can be used to support engineers in their work, not fully automate the task. The presented approach is furthermore applicable to scenarios in which requirements are primarily available in natural-language form, as is common in early development phases and cross-organizational engineering contexts. Structured or executable requirement representations (e.g., SysML models or parametric constraints) are considered complementary information sources and are not the primary focus of the present work. To achieve higher reliability, the approach in this paper should be combined with other approaches using structured input, focusing on deeper analysis of the system models. A deterministic approach deriving test cases directly from MBSE system models would possibly yield even more complex boundary conditions for CPS test cases. A combination of the flexible LLM-based approach proposed in this paper with a deterministic approach fully utilizing the system model information, would further advance the field of automated test-case generation.
Independent approaches such as classic NLP-based requirement analysis, rule-based RE tools, or deterministic MBSE-derived test generation address related problems but different problem settings, assumptions, and input representations, such as prior representation of requirements in formalized language. Accordingly, the present work does not aim to benchmark absolute competitiveness against deterministic approaches, but rather to evaluate the relative contribution of structured semantic guidance and contextual grounding within an LLM-based framework on the scope of CPS test-case generation. Depending on the available inputs, modeling maturity, and underlying assumptions, different approaches (classical NLP-based, rule-based or deterministic MBSE-derived) can coexist within an engineering toolchain.
6. Conclusions and Outlook
In mechanical and mechatronic system development, testing ensures that a system fulfills its required functional and physical behavior. Test cases form the basis of this process: they define the test objective and the boundary conditions under which verification must occur. Test cases must capture all functional goals and boundary conditions, yet manual definition of test cases remains time-consuming and costly, increasing with system complexity. A promising solution lies in automated requirement-based test-case definition (Requirement-to-Test), as requirements exist early in the development process and form the basis for verification.
The goal of this paper is to explore how modern large language models (LLMs) can extend Requirement-to-Test to derive more complex boundary conditions by semantically analyzing and structuring requirements. Three approaches were compared: (1) In a direct method, the LLM freely groups requirements into test-relevant sets. It is shown that aggregation of several outputs improves coverage but also produces more irrelevant dependencies. (2) An indirect method introduces a structured interdependency taxonomy, guiding the LLM to first identify and classify relationships between requirements based on this fixed taxonomy before translating them into test cases. This results in a more systematic and reliable outcome. (3) A final variant combines this taxonomy with system model context via Graph RAG, grounding the reasoning in MBSE knowledge of the system. This further improves coverage and interpretability but introduces slightly more false associations, as the expanded context increases complexity.
Overall, the results show that LLMs can identify complex boundary conditions for CPS test cases by analyzing interdependencies between natural-language requirements given the considered example system. In the third approach, the model successfully detected 81% of the test-relevant dependencies, indicating the feasibility of semantic reasoning for test-case generation. It is shown that structured, stepwise reasoning clearly outperforms direct interdependency identification. Providing explicit interdependency types enables more consistent and transparent mappings between requirements and test cases, while system model grounding adds contextual depth, although in the investigated case this did not result in a consistent overall performance improvement. Its benefit is expected to become more pronounced in systems with higher architectural complexity and stronger cross-domain interactions. Together, these elements form a practical framework for AI-supported, test-oriented requirement analysis. Its scalability to larger and more complex systems remains subject to future validation.
However, the approach alone is not yet sufficient for comprehensive coverage. With a precision of 0.71 the system can only support the engineers, not fully automate the task. The presented evaluation constitutes a controlled single-system case study and should be interpreted as proof-of-concept validation. Subsequent research should focus on deeper analysis of the system model, beyond the provision of context in the current process. Future work should investigate hybrid requirement settings in which natural-language requirements coexist with structured or executable system model constraints. Integrating structured requirements into system models, as well as tracing interdependencies in the system model deterministically, would add a parallel stream to the taxonomy-based approach in this paper. In such a hybrid scenario, LLM-based and deterministic approaches could potentially collaborate to flexibly combine each approach’s strengths and reduce ambiguity and misinterpretations in test-case derivation.
While the Graph RAG mechanism used in this work already enables a targeted extraction of relevant context from the MBSE system model, further investigation is required to validate the context selection in larger and more complex systems. In particular, future work should assess how the relevance, granularity, and abstraction level of retrieved system model information influence the balance between coverage and precision.
Statistical generalizability across CPS domains, system scales, and industrial contexts has not yet been established. Future research must therefore assess the robustness, scalability, and transferability of the proposed methodology in multiple and more heterogeneous CPS settings.
Further, evaluation of the methodology across different CPSs is important to advance robustness. Future work will therefore focus on collecting additional CPS examples and extending the empirical validation of the proposed approaches across a broader range of systems. This includes a more detailed and isolated analysis of the contribution of system-model-based context injection, in particular to better distinguish the effects of the taxonomy-guided approach and its extension with Graph RAG. Scalability and validation on more complex, system-level CPSs with stronger architectural and cross-domain interactions is recommended future work. Furthermore, an open-source CPS benchmark could be developed that provides requirements, models and reference test suites for different domains. Evaluation based on such a benchmark dataset would enable more systematic comparison of LLM-based approaches across studies and improve reproducibility.
With the proposed methodology, the LLM is easily interchangeable, allowing for different large language models to be integrated without modifying the underlying process. Although a systematic comparative analysis of various LLMs is not within the scope of this work, it represents an important direction for future research. Given that larger and more advanced LLMs generally demonstrate improved performance on complex reasoning tasks, this aspect becomes increasingly relevant in light of the rapid ongoing development of new models in the future.
Author Contributions
Conceptualization, M.M., S.D. and S.H.; methodology, M.M. and S.H.; software, M.M. and S.H.; validation, M.M.; formal analysis, M.M., G.J., S.D., G.H., T.Z., K.B. and S.H.; investigation, M.M., G.J., S.D., G.H., T.Z., K.B. and S.H.; resources, M.M., G.J., S.D., G.H., T.Z., K.B. and S.H.; data curation, M.M.; writing—original draft preparation, M.M. and S.D.; writing—review and editing, M.M., G.J., S.D., G.H., T.Z. and K.B.; visualization, M.M., S.D. and S.H.; supervision, G.J., G.H., T.Z. and K.B.; project administration, G.J., S.D. and G.H.; funding acquisition, S.D. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by Bundesministerium für Wirtschaft und Energie, Germany, in the grant KIMBA (grant number 19S24001I) for the program, “Neue Fahrzeug- und Systemtechnologien”. The APC was funded by the RWTH Open Access Publication Fund.
Data Availability Statement
The datasets presented in this article are not readily available.
Acknowledgments
The authors would like to thank the RWTH Open Access Publication Fund for funding the open access availability.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| CPS | Cyber-Physical Systems |
| LLM | Large Language Model |
| MBSE | Model-Based Systems Engineering |
| RAG | Retrieval-Augmented Generation |
| NLP | Natural-Language Processing |
| ISO | International Organization for Standardization |
| TP | True Positive |
| FP | False Positive |
| FN | False Negative |
| TN | True Negative |
| VDI | Verein Deutscher Ingenieure (Association of German Engineers) |
| GPT | Generative Pretrained Transformer |
| FEM | Finite Element Method |
| MBS | Multi-Body Simulation |
| SPOT | Single Point of Truth |
References
- ISO/IEC/IEEE 29119-2:2013; Software and Systems Engineering—Software Testing—Part 2: Test Processes. International Organization for Standardization: Geneva, Switzerland, 2013.
- IEEE 829-2008; IEEE Standard for Software and System Test Documentation: 829-2009. IEEE: New York, NY, USA, 2008.
- Wolfgang, R.; Katz, T.; Wheatcraft, L. Guide to Verification and Validation. INCOSE Technical Product INCOSE-TP-2021-004-01; INCOSE: San Diego, CA, USA, 2022.
- VDI/VDE 2206:2021; Entwicklung Mechatronischer und Cyber-Physischer Systeme. Beuth Verlag GmbH: Berlin, Germany, 2021.
- Zeller, A.; Weyrich, M.D.-I. Herausforderung Test verteilter Systeme—Wie Industrie 4.0 das Testen Verändert. 2015. Available online: https://www.ias.uni-stuttgart.de/dokumente/publikationen/2015_Herausforderung_Test_verteilter_Systeme.pdf (accessed on 10 October 2025).
- Facchi, C.; Heidepriem, S.; Jähnert, J.; Jung, T.; Köllner, C.; Kraas, A.; Krause, J.; Krüning, K.; Kugler, A.; Maschler, B.; et al. Testen vernetzter Systeme für Industrie 4.0: VDI-Statusreport. Düsseldorf, 2018. Available online: https://www.ias.uni-stuttgart.de/dokumente/publikationen/2018_Statusreport_Testen_vernetzter_Syteme_I4.0.pdf (accessed on 27 August 2025).
- Dowie, U. Testaufwandsschätzung in der Softwareentwicklung: Modell der Einflussfaktoren und Methode zur organisationsspezifischen Aufwandsschätzung. Ph.D. Thesis, Stuttgart University, Stuttgart, Germany, 2009. [Google Scholar]
- Yang, Z.; Huang, R.; Cui, C.; Niu, N.; Towey, D. Requirements-Based Test Generation: A Comprehensive Survey. J. ACM, 2018; accepted. [CrossRef] [Scilit]
- Almefelt, L.; Berglund, F.; Nilsson, P.; Malmqvist, J. Requirements management in practice: Findings from an empirical study in the automotive industry. Res. Eng. Design 2006, 17, 113–134. [Google Scholar] [CrossRef] [Scilit]
- Farooq, M.S.; Tahreem, T. Requirement-Based Automated Test Case Generation: Systematic Literature Review. VFAST Trans. Softw. Eng. 2022, 10, 133–142. [Google Scholar] [CrossRef] [Scilit]
- Akram, N.; Braun, T.; Reich, J. Software Testing: Using Large Language Models to Save Effort for Test Case Derivation from Safety Requirements. Available online: https://www.iese.fraunhofer.de/blog/software-testing-test-case-generation-using-ai-llm/ (accessed on 21 May 2025).
- Jastram, M. TdSE 2017: Menschen & Modellierung. Available online: https://www.se-trends.de/tdse-2017-menschen-modellierung/ (accessed on 27 August 2025).
- Escalona, M.-J.; Koch, N.; Garcia-Borgoñon, L. Lean requirements traceability automation enabled by model-driven engineering. PeerJ. Comput. Sci. 2022, 8, e817. [Google Scholar] [CrossRef] [Scilit]
- Grochtmann, M.; Betz, K.; Didrich, K.; Kiss, K.; Wagner, P. Kopplung von Anforderungen und Tests: Überblick und Erfahrungen. Köln. 2005. Available online: https://www.gm.th-koeln.de/~winter/tav/html/tav23/TAV23P4AKEmbeddedSystems.pdf (accessed on 29 March 2025).
- ISO 26262; Straßenfahrzeuge—Funktionale Sicherheit, 01.040.43; 43.040.10Kfz-Elektrik (IX30555409). International Organization for Standardization: Geneva, Switzerland, 2024.
- Brach, W.; Košťál, K.; Ries, M. The Effectiveness of Large Language Models in Transforming Unstructured Text to Standardized Formats. IEEE Access 2025, 13, 91808–91825. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.; Fu, Z.; Ding, M.; Ning, R.; Zhang, C.; Liu, X.; Zhang, Y. Logical Reasoning in Large Language Models: A Survey. arXiv 2025, arXiv:2502.09100. [Google Scholar] [CrossRef] [Scilit]
- Görz, G.; Schmid, U.; Braun, T. Handbuch der Künstlichen Intelligenz, 6th ed.; De Gruyter: Berlin, Germany, 2020; ISBN 3110659840. [Google Scholar]
- Mockenhaupt, A. Digitalisierung und Künstliche Intelligenz in der Produktion; Springer Fachmedien Wiesbaden: Wiesbaden, Germany, 2021; ISBN 978-3-658-32772-9. [Google Scholar]
- Korraprolu, B.R.; Pinninti, P.; Reddy, Y.R. Test Case Generation for Requirements in Natural Language—An LLM Comparison Study. In Proceedings of ISEC 2025: 18th Innovations in Software Engineering Conference, Kurukshetra, India, 20–22 February 2025; Chhabra, J., Kumar, L., Chimalakonda, S., Krishan, P., Godboley, S., Eds.; ACM: New York, NY, USA, 2025; pp. 1–5. ISBN 9798400714245. [Google Scholar]
- Lebioda, K.; Petrovic, N.; Pan, F.; Zolfaghari, V.; Schamschurko, A.; Knoll, A. Are requirements really all you need? A case study of LLM-driven configuration code generation for automotive simulations. arXiv 2025, arXiv:2505.13263. [Google Scholar] [CrossRef] [Scilit]
- Medeshetty, N.; Ghazi, A.N.; Alawadi, S.; Alkhabbas, F. From Requirements to Test Cases: An NLP-Based Approach for High-Performance ECU Test Case Automation. In Proceedings of the 2025 IEEE 5th International Conference on Human-Machine Systems (ICHMS), Abu Dhabi, United Arab Emirates, 26–28 May 2025. [Google Scholar]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, L.; Polosukhin, I. Attention Is All You Need. arXiv 2017, arXiv:1706.03762. [Google Scholar]
- OpenAI; Achiam, J.; Adler, S.; Agarwal, S.; Ahmad, L.; Akkaya, I.; Aleman, F.L.; Almeida, D.; Altenschmidt, J.; Altman, S.; et al. GPT-4 Technical Report. arXiv 2023, arXiv:2303.08774. [Google Scholar] [CrossRef] [Scilit]
- Bommasani, R.; Hudson, D.A.; Adeli, E.; Altman, R.; Arora, S.; von Arx, S.; Bernstein, M.S.; Bohg, J.; Bosselut, A.; Brunskill, E.; et al. On the Opportunities and Risks of Foundation Models. arXiv 2021, arXiv:2108.07258. [Google Scholar] [CrossRef] [Scilit]
- Brown, T.B.; Mann, B.; Ryder, N.; Subbiah, M.; Kaplan, J.; Dhariwal, P.; Neelakantan, A.; Shyam, P.; Sastry, G.; Askell, A.; et al. Language Models are Few-Shot Learners. In Proceedings of the 34th Conference on Neural Information Processing Systems (NeurIPS 2020), Online, 6–12 December 2020; pp. 1877–1901. [Google Scholar]
- Jurafsky, D.; Martin, J.H. Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition. 2014. Available online: https://web.stanford.edu/~jurafsky/slp3/ (accessed on 3 October 2025).
- Goodfellow, I.; Bengio, Y.; Courville, A. Deep Learning; The MIT Press: Cambridge, MA, USA, 2016; ISBN 9780262337373. [Google Scholar]
- Priyanshu, A.; Maurya, Y.; Hong, Z. AI Governance and Accountability: An Analysis of Anthropic’s Claude. arXiv 2024, arXiv:2407.01557. [Google Scholar]
- DeepSeek-AI; Liu, A.; Feng, B.; Xue, B.; Wang, B.; Wu, B.; Lu, C.; Zhao, C.; Deng, C.; Zhang, C.; et al. DeepSeek-V3 Technical Report. arXiv 2024, arXiv:2412.19437. [Google Scholar]
- Bahri, Y.; Dyer, E.; Kaplan, J.; Lee, J.; Sharma, U. Explaining neural scaling laws. Proc. Natl. Acad. Sci. USA 2024, 121, e2311878121. [Google Scholar] [CrossRef] [Scilit]
- Kaplan, J.; McCandlish, S.; Henighan, T.; Brown, T.B.; Chess, B.; Child, R.; Gray, S.; Radford, A.; Wu, J.; Amodei, D. Scaling Laws for Neural Language Models. arXiv 2020, arXiv:2001.08361. [Google Scholar] [CrossRef] [Scilit]
- Hoffmann, J.; Borgeaud, S.; Mensch, A.; Buchatskaya, E.; Cai, T.; Rutherford, E.; de Las Casas, D.; Hendricks, L.A.; Welbl, J.; Clark, A.; et al. Training Compute-Optimal Large Language Models. arXiv 2022, arXiv:2203.15556. Available online: http://arxiv.org/pdf/2203.15556v1 (accessed on 5 October 2025). [CrossRef] [Scilit]
- Highmore, C. In-Context Learning in Large Language Models: A Comprehensive Survey. Preprint 2024. [Google Scholar] [CrossRef] [Scilit]
- Vellum. What Is LLM Temperature? Available online: https://www.vellum.ai/llm-parameters/temperature (accessed on 30 November 2025).
- Izacard, G.; Grave, E. Leveraging Passage Retrieval with Generative Models for Open Domain Question Answering. In Proceedings of the 16th Conference of the European Chapter of the Association for Computational Linguistics: Main Volume; Association for Computational Linguistics: Stroudsburg, PA, USA, 2020; Available online: https://arxiv.org/pdf/2007.01282v2 (accessed on 3 October 2025).
- Hopsworks. Hopswork AI Dictionary: LLM Temperature. Available online: https://www.hopsworks.ai/dictionary/llm-temperature (accessed on 30 November 2025).
- Li, L.; Sleem, L.; Gentile, N.; Nichil, G.; State, R. Exploring the Impact of Temperature on Large Language Models:Hot or Cold? Procedia Comput. Sci. 2025, 264, 242–251. [Google Scholar] [CrossRef] [Scilit]
- Peeperkorn, M.; Kouwenhoven, T.; Brown, D.; Jordanous, A. Is Temperature the Creativity Parameter of Large Language Models? arXiv 2024, arXiv:2405.00492. [Google Scholar] [CrossRef] [Scilit]
- Mehta, S. The Need for Sampling Temperature and Differences Between Whisper, GPT-3, and Probabilistic Model’s Temperature. Available online: https://shivammehta25.github.io/posts/temperature-in-language-models-open-ai-whisper-probabilistic-machine-learning/ (accessed on 11 December 2025).
- Xu, F.; Hao, Q.; Shao, C.; Zong, Z.; Li, Y.; Wang, J.; Zhang, Y.; Wang, J.; Lan, X.; Gong, J.; et al. Toward large reasoning models: A survey of reinforced reasoning with large language models. Patterns 2025, 6, 101370. [Google Scholar] [CrossRef] [Scilit]
- Gao, Y.; Xiong, Y.; Gao, X.; Jia, K.; Pan, J.; Bi, Y.; Dai, Y.; Sun, J.; Wang, M.; Wang, H. Retrieval-Augmented Generation for Large Language Models: A Survey. arXiv 2023, arXiv:2312.10997. Available online: https://arxiv.org/pdf/2312.10997v5 (accessed on 3 October 2025).
- Lewis, P.; Perez, E.; Piktus, A.; Petroni, F.; Karpukhin, V.; Goyal, N.; Küttler, H.; Lewis, M.; Yih, W.; Rocktäschel, T.; et al. Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. arXiv 2020, arXiv:2005.11401. Available online: https://arxiv.org/pdf/2005.11401v4 (accessed on 7 October 2025).
- Provost, F.; Kohavi, R. Guest Editors’ Introduction: On Applied Research in Machine Learning. Mach. Learn. 1998, 30, 127–132. [Google Scholar] [CrossRef] [Scilit]
- Jurafsky, D.; Martin, J.H. Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition with Language Models, 3rd ed. draft; 2025; Available online: https://web.stanford.edu/~jurafsky/slp3/ (accessed on 1 October 2025).
- Wang, C.; Pastore, F.; Goknil, A.; Briand, L.C. Automatic Generation of Acceptance Test Cases from Use Case Specifications: An NLP-based Approach. IEEE Trans. Softw. Eng. 2020, 48, 585–616. [Google Scholar] [CrossRef] [Scilit]
- Schäfer, M.; Nadi, S.; Eghbali, A.; Tip, F. An Empirical Evaluation of Using Large Language Models for Automated Unit Test Generation. IEEE Trans. Softw. Eng. 2023, 50, 85–105. [Google Scholar] [CrossRef] [Scilit]
- Koziolek, H.; Ashiwal, V.; Bandyopadhyay, S.; Chandrika, K.R. Automated Control Logic Test Case Generation using Large Language Models. In Proceedings of the 2024 IEEE 29th International Conference on Emerging Technologies and Factory Automation (ETFA), Padova, Italy, 10–13 September 2024; IEEE: New York, NY, USA, 2024; pp. 1–8. ISBN 979-8-3503-6123-0. [Google Scholar]
- Zhang, H.; Li, J.; Zhu, L.; Jeffery, R.; Liu, Y.; Wang, Q.; Li, M. Investigating dependencies in software requirements for change propagation analysis. Inf. Softw. Technol. 2014, 56, 40–53. [Google Scholar] [CrossRef] [Scilit]
- Carlshamre, P.; Sandahl, K.; Lindvall, M.; Regnell, B.; Natt och Dag, J. An industrial survey of requirements interdependencies in software product release planning. In Proceedings of the Fifth IEEE International Symposium on Requirements Engineering, Toronto, ON, Canada, 27–31 August 2001; IEEE: New York, NY, USA, 2001; pp. 84–91. ISBN 0-7695-1125-2. [Google Scholar]
- Deshpande, G.; Arora, C.; Ruhe, G. Data-driven Elicitation and Optimization of Dependencies between Requirements. In Proceedings of the 2019 IEEE 27th International Requirements Engineering Conference, Jeju Island, Republic of Korea, 23–27 September 2019. [Google Scholar]
- Tabassum, M.R.; Siddik, M.S.; Shoyaib, M.; Khaled, S.M. Determining interdependency among non-functional requirements to reduce conflict. In Proceedings of the 2014 International Conference on Informatics, Electronics & Vision (ICIEV), Dhaka, Bangladesh, 23–24 May 2014; IEEE: New York, NY, USA, 2014; pp. 1–6. ISBN 978-1-4799-5180-2. [Google Scholar]
- Gärtner, A.E.; Göhlich, D. Automated requirement contradiction detection through formal logic and LLMs. Autom. Softw. Eng. 2024, 31, 49. [Google Scholar] [CrossRef] [Scilit]
- Rodriguez, A.D.; Dearstyne, K.R.; Cleland-Huang, J. Prompts Matter: Insights and Strategies for Prompt Engineering in Automated Software Traceability. In Proceedings of the 2023 IEEE 31st International Requirements Engineering Conference Workshops (REW), Hannover, Germany, 4–5 September 2023; IEEE: New York, NY, USA, 2023. [Google Scholar]
- Fazelnia, M.; Koscinski, V.; Herzog, S.; Mirakhorli, M. Lessons from the Use of Natural Language Inference (NLI) in Requirements Engineering Tasks. In Proceedings of the 2024 IEEE 32nd International Requirements Engineering Conference (RE), Reykjavik, Iceland, 24–28 June 2024; IEEE: New York, NY, USA, 2024. [Google Scholar]
- Lubos, S.; Felfernig, A.; Tran, T.N.T.; Garber, D.; Mansi, M.E.; Erdeniz, S.P.; Le, V.-M. Leveraging LLMs for the Quality Assurance of Software Requirements. arXiv 2024, arXiv:2408.10886. [Google Scholar] [CrossRef] [Scilit]
- Uygun, Y.; Momodu, V. Local large language models to simplify requirement engineering documents in the automotive industry. Prod. Manuf. Res. 2024, 12, 2375296. [Google Scholar] [CrossRef] [Scilit]
- Ferrari, A.; Abualhaija, S.; Arora, C. Model Generation with LLMs: From Requirements to UML Sequence Diagrams. In Proceedings of the 2024 IEEE 32nd International Requirements Engineering Conference (RE), Reykjavik, Iceland, 24–28 June 2024; IEEE: New York, NY, USA, 2024. [Google Scholar]
- Chen, S.; Chen, X.; Jin, Z. Building Device Models Using LLMs for Requirements Simulation in Smart Homes. In Proceedings of the 2024 IEEE 32nd International Requirements Engineering Conference Workshops (REW), Reykjavik, Iceland, 24–25 June 2024; IEEE: New York, NY, USA, 2024; pp. 176–183. ISBN 979-8-3503-9551-8. [Google Scholar]
- Bragilovski, M.; van Can, A.T.; Dalpiaz, F.; Sturm, A. Deriving Domain Models from User Stories: Human vs. Machines. In Proceedings of the 2024 IEEE 32nd International Requirements Engineering Conference (RE), Reykjavik, Iceland, 24–28 June 2024; IEEE: New York, NY, USA, 2024; pp. 31–42. ISBN 979-8-3503-9511-2. [Google Scholar]
- Abualhaija, S.; Ceci, M.; Sannier, N.; Bianculli, D.; Briand, L.C.; Zetzsche, D.; Bodellini, M. AI-Enabled Regulatory Change Analysis of Legal Requirements. In Proceedings of the 2024 IEEE 32nd International Requirements Engineering Conference (RE), Reykjavik, Iceland, 24–28 June 2024; IEEE: New York, NY, USA, 2024; pp. 5–17. ISBN 979-8-3503-9511-2. [Google Scholar]
- Hassani, S.; Sabetzadeh, M.; Amyot, D.; Liao, J. Rethinking Legal Compliance Automation: Opportunities with Large Language Models. In Proceedings of the 2024 IEEE 32nd International Requirements Engineering Conference (RE), Reykjavik, Iceland, 24–28 June 2024; IEEE: New York, NY, USA, 2024. [Google Scholar]
- Nouri, A.; Cabrero-Daniel, B.; Törner, F.; Sivencrona, H.; Berger, C. Engineering Safety Requirements for Autonomous Driving with Large Language Models. In Proceedings of the 2024 IEEE 32nd International Requirements Engineering Conference (RE), Reykjavik, Iceland, 24–28 June 2024; IEEE: New York, NY, USA, 2024. [Google Scholar]
- Campioli, S.; Luccisano, G.; Ferretto, D.; Stesina, F. Towards a Unified Modeling and Simulation Framework for Space Systems: Integrating Model-Based Systems Engineering with Open Source Multi-Domain Simulation Environments. Aerospace 2025, 12, 745. [Google Scholar] [CrossRef] [Scilit]
- Di Maio, M.; Weilkiens, T.; Hussein, O.; Aboushama, M.; Javid, I.; Beyerlein, S.; Grotsch, M. Evaluating MBSE Methodologies Using the FEMMP Framework. In 2021 IEEE International Symposium on Systems Engineering (ISSE); IEEE: Piscataway, NJ, USA, 2021; pp. 1–8. [Google Scholar]
- Vazquez-Santacruz, J.; Portillo-Velez, R.; Torres-Figueroa, J.; Marin-Urias, L.F.; Portilla-Flores, E. Towards an integrated design methodology for mechatronic systems. Res. Eng. Des. 2023, 34, 497–512. [Google Scholar] [CrossRef] [Scilit]
- Qamar, A.; Törngren, M.; Wikander, J.; During, C. Integrating multidomain models for the design and development of mechatronic systems. In Proceedings of the 7th European Systems Engineering Conference EuSEC, Stockholm, Sweden, 23–26 May 2010. [Google Scholar]
- Morkevicius, A.; Aleksandraviciene, A.; Mazeika, D.; Bisikirskiene, L.; Strolia, Z. MBSE Grid: A Simplified SysML-Based Approach for Modeling Complex Systems. In Proceedings of the 27th INCOSE International Symposium, Adelaide, SA, Australia, 15–20 July 2017. [Google Scholar]
- Estefan, J.A. Survey of Model-Based Systems Engineering (MBSE) Methodologies; California Institute of Technology: Pasadena, CA, USA, 2008. [Google Scholar]
- Delligati, L. SysML Distilled: A Brief Guide to the Systems Modeling Language; Addison-Wesley: Boston, MA, USA, 2013; ISBN 978-0-321-92786-6. [Google Scholar]
- Koller, R.; Katrup, N. Prinziplösungen zur Konstruktion Technischer Produkte; Springer: Berlin/Heidelberg, Germany, 1998. [Google Scholar]
- Spütz, K.; Jacobs, G.; Zerwas, T.; Konrad, C. Modeling language for the function-oriented development of mechatronic systems with motego. Forsch. Ingenieurwes. 2023, 87, 387–398. [Google Scholar] [CrossRef] [Scilit]
- Habermehl, C.; Höpfner, G.; Berroth, J.; Neumann, S.; Jacobs, G. Optimization Workflows for Linking Model-Based Systems Engineering (MBSE) and Multidisciplinary Analysis and Optimization (MDAO). Appl. Sci. 2022, 12, 5316. [Google Scholar] [CrossRef] [Scilit]
- Berges, J.M. Systemmodell zur virtuellen Auslegung und Optimierung von thermisch gefügten laserstrukturierten Kunststoff-Metall-Verbindungen. Ph.D. Thesis, RWTH Aachen University, Aachen, Germany, 2024. [Google Scholar]
- Spütz, K.; Jacobs, G.; Konrad, C.; Wyrwich, C. Integration of Production and Cost Models in Model-Based Product Development. Open J. Soc. Sci. 2021, 9, 53–64. [Google Scholar] [CrossRef]
- Zerwas, T.; Jacobs, G.; Kowalski, J.; Husung, S.; Gerhard, D.; Rumpe, B.; Zeman, K.; Vafaei, S.; König, F.; Höpfner, G. Model Signatures for the Integration of Simulation Models into System Models. Systems 2022, 10, 199. [Google Scholar] [CrossRef] [Scilit]
- Jacobs, G.; Konrad, C.; Berroth, J.; Zerwas, T.; Höpfner, G.; Spütz, K. Function-Oriented Model-Based Product Development. In Design Methodology for Future Products; Springer: Cham, Switzerland, 2022; pp. 243–263. [Google Scholar]
| Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |


 ,