Article

Comparative Evaluation of AI Programming Assistants: An Exploratory Longitudinal Case Study of GitHub Copilot, ChatGPT, and Cursor Configurations in Full-Stack Development


by
Goran Đambić
*,
Anton Maurovic
,
Ivana Ogrizek Biškupić
and
Aleksander Radovan
Software Engineering Department, Algebra Bernays University, Gradišćanska ulica 24, 10000 Zagreb, Croatia
*
Author to whom correspondence should be addressed.
Information 2026, 17(9), 918; https://doi.org/10.3390/info17090918 (registering DOI)
Submission received: 17 August 2026 / Revised: 16 September 2026 / Accepted: 17 September 2026 / Published: 19 September 2026

Abstract

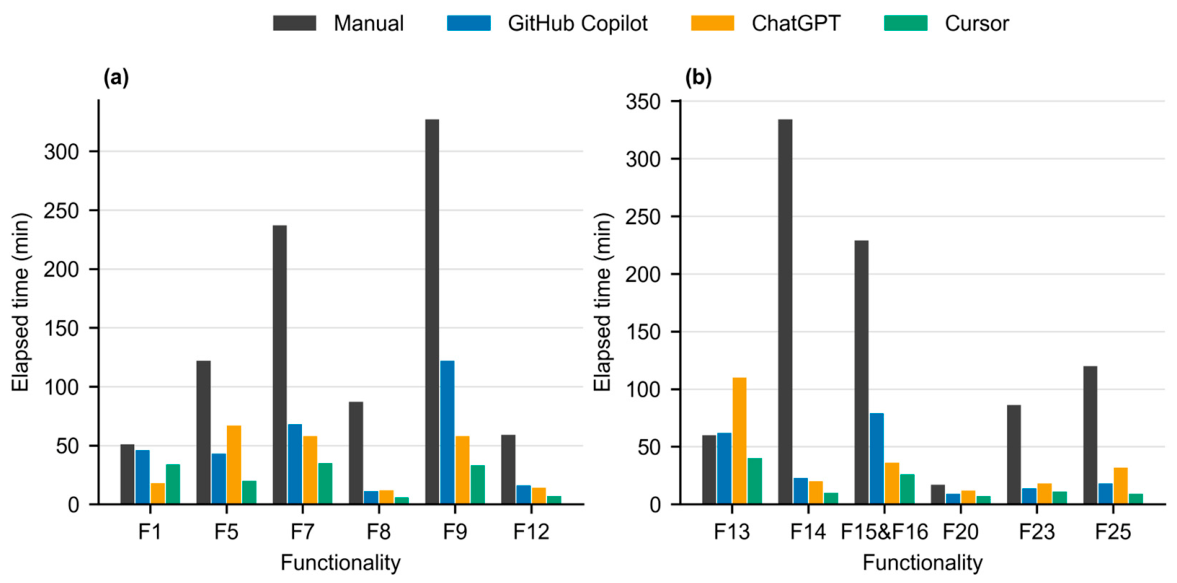
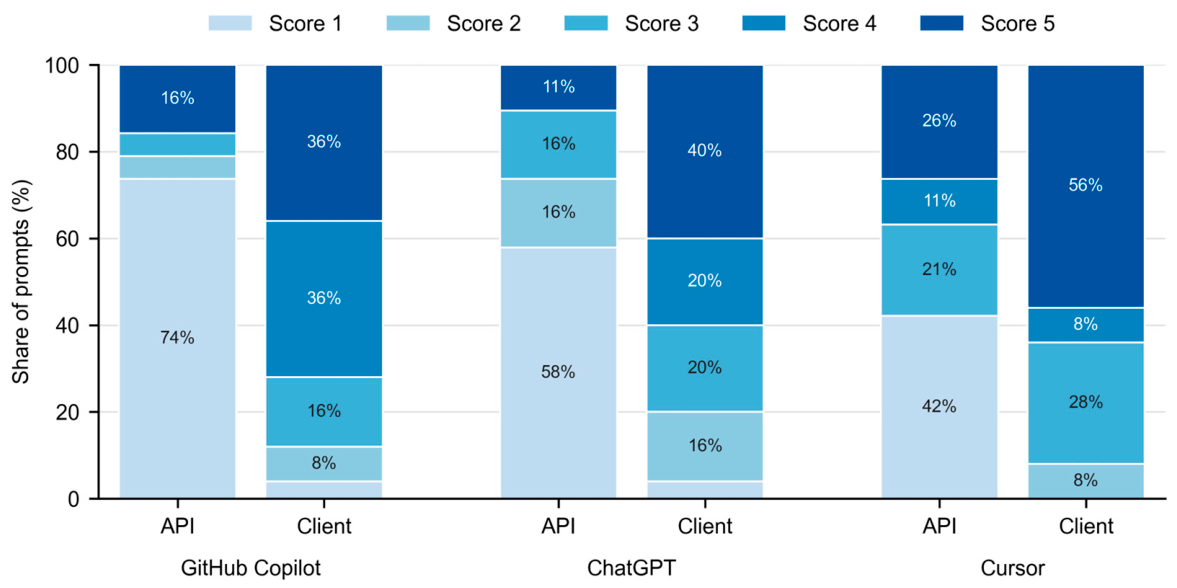
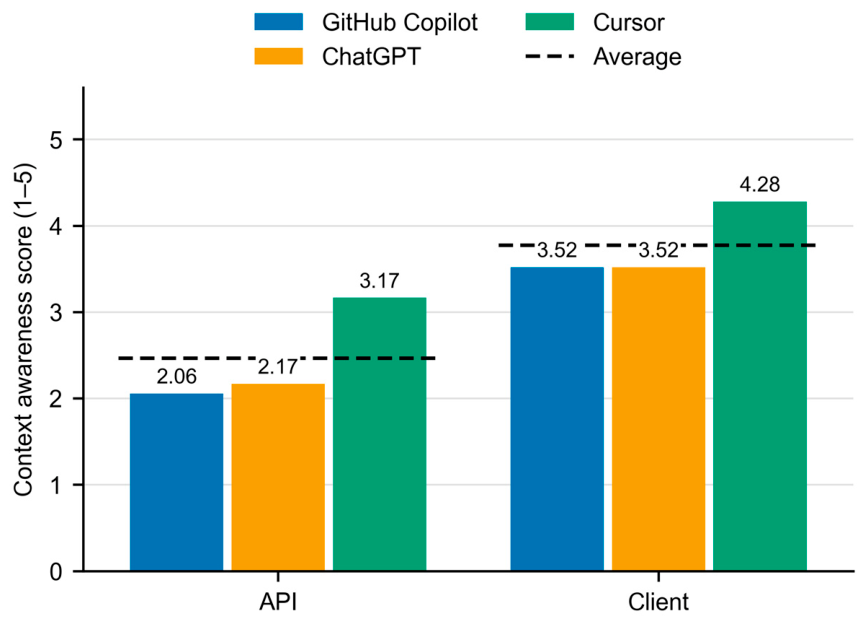
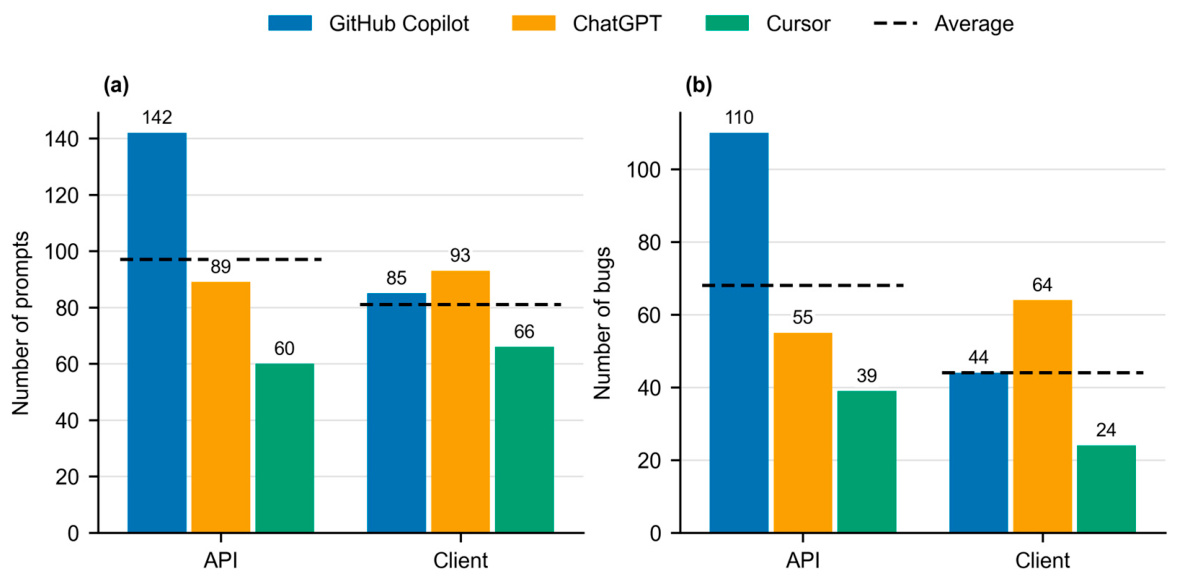
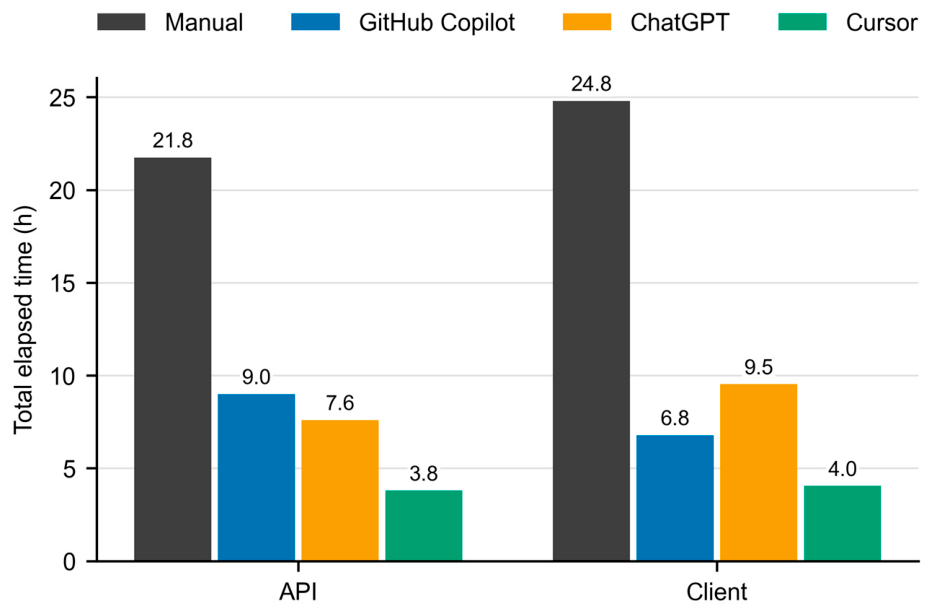
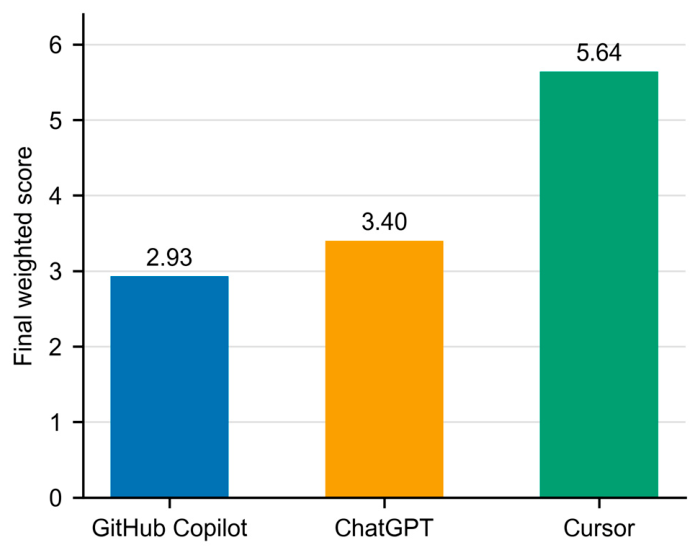
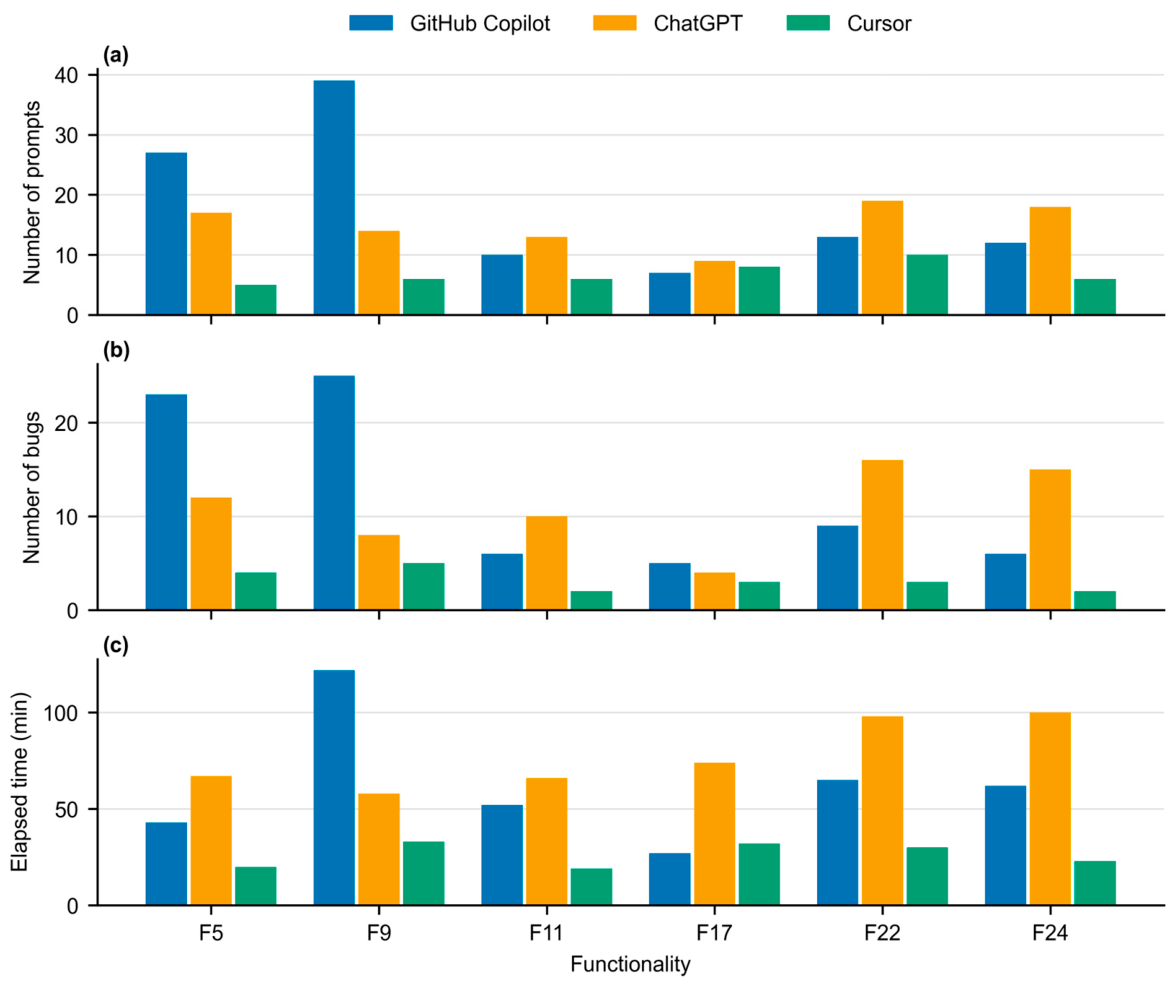
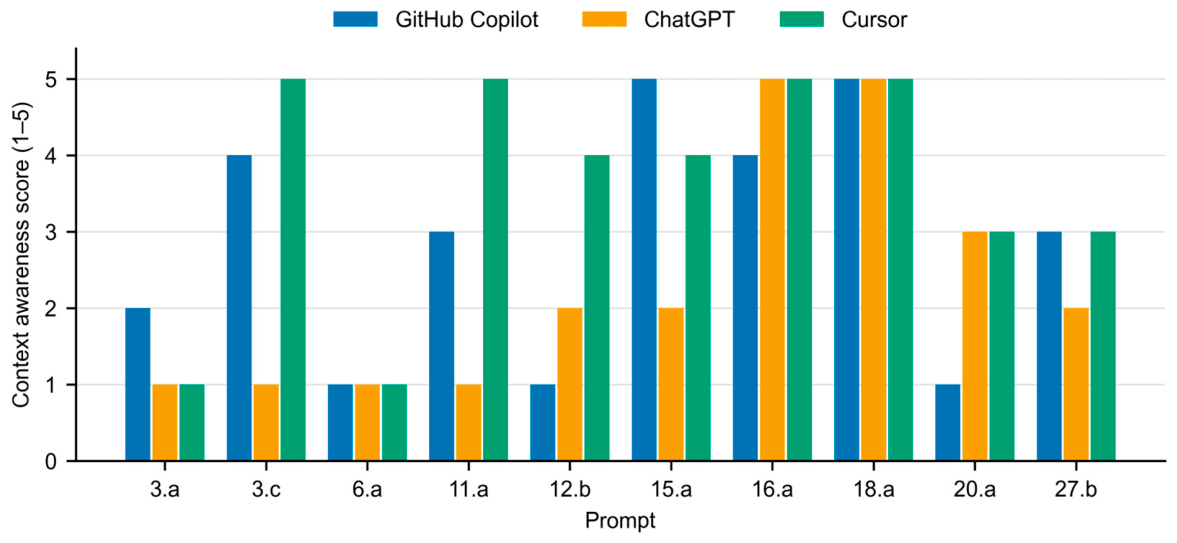
The rapid adoption of artificial intelligence (AI) programming assistants has raised questions about the actual benefits they provide in professional software development. This exploratory longitudinal case study compares configurations of three AI programming assistants (GitHub Copilot, ChatGPT, and Cursor)—specific combinations of tool, underlying model, interaction interface, and period of use—by reimplementing a full-stack thesis management application (a .NET Core 8.0 representational state transfer (REST) application programming interface (API) and a React.js client with 25 functionalities) that was first developed manually to establish a baseline. Each tool was evaluated using a seven-criteria framework covering code correctness, prompt complexity, context awareness, number of prompts, bug count, bug severity, and recorded implementation time. All three configurations significantly reduced the total recorded implementation time relative to manual implementation (by 66%, 63%, and 83% for Copilot, ChatGPT, and Cursor, respectively; p < 0.001). The Cursor configuration ranked best on four of the five evaluation criteria, with significantly higher context awareness and significantly fewer bugs than Copilot; because the tools were applied in a fixed order between January and November 2025, a period during which the underlying models were upgraded, and Cursor was both applied last and received the largest such upgrade, these results reflect tool–model–interface–time configurations rather than the tools in isolation. All tools performed significantly worse on the multi-layer API than on the client application. All 336 recorded bugs were organized into a fourteen-category taxonomy, in which hallucinated code elements and incomplete multi-file modifications were the most frequent failure modes, a pattern consistent with the tools’ limited ability to track context across files and architectural layers. The results indicate that AI programming assistants are most effective as pair programming tools whose output requires systematic human review before integration.
Keywords: AI programming assistant; GitHub Copilot; ChatGPT; Cursor; code generation; implementation time; empirical software engineering; large language models AI programming assistant; GitHub Copilot; ChatGPT; Cursor; code generation; implementation time; empirical software engineering; large language models