Article

Language Identification-Based Evaluation of Single Channel Speech Separation of Overlapped Speeches


College of Information Science and Engineering, Xinjiang University, Urumqi 830017, China
*
Author to whom correspondence should be addressed.
Information 2022, 13(10), 492; https://doi.org/10.3390/info13100492
Submission received: 29 July 2022 / Revised: 3 October 2022 / Accepted: 8 October 2022 / Published: 11 October 2022

Abstract

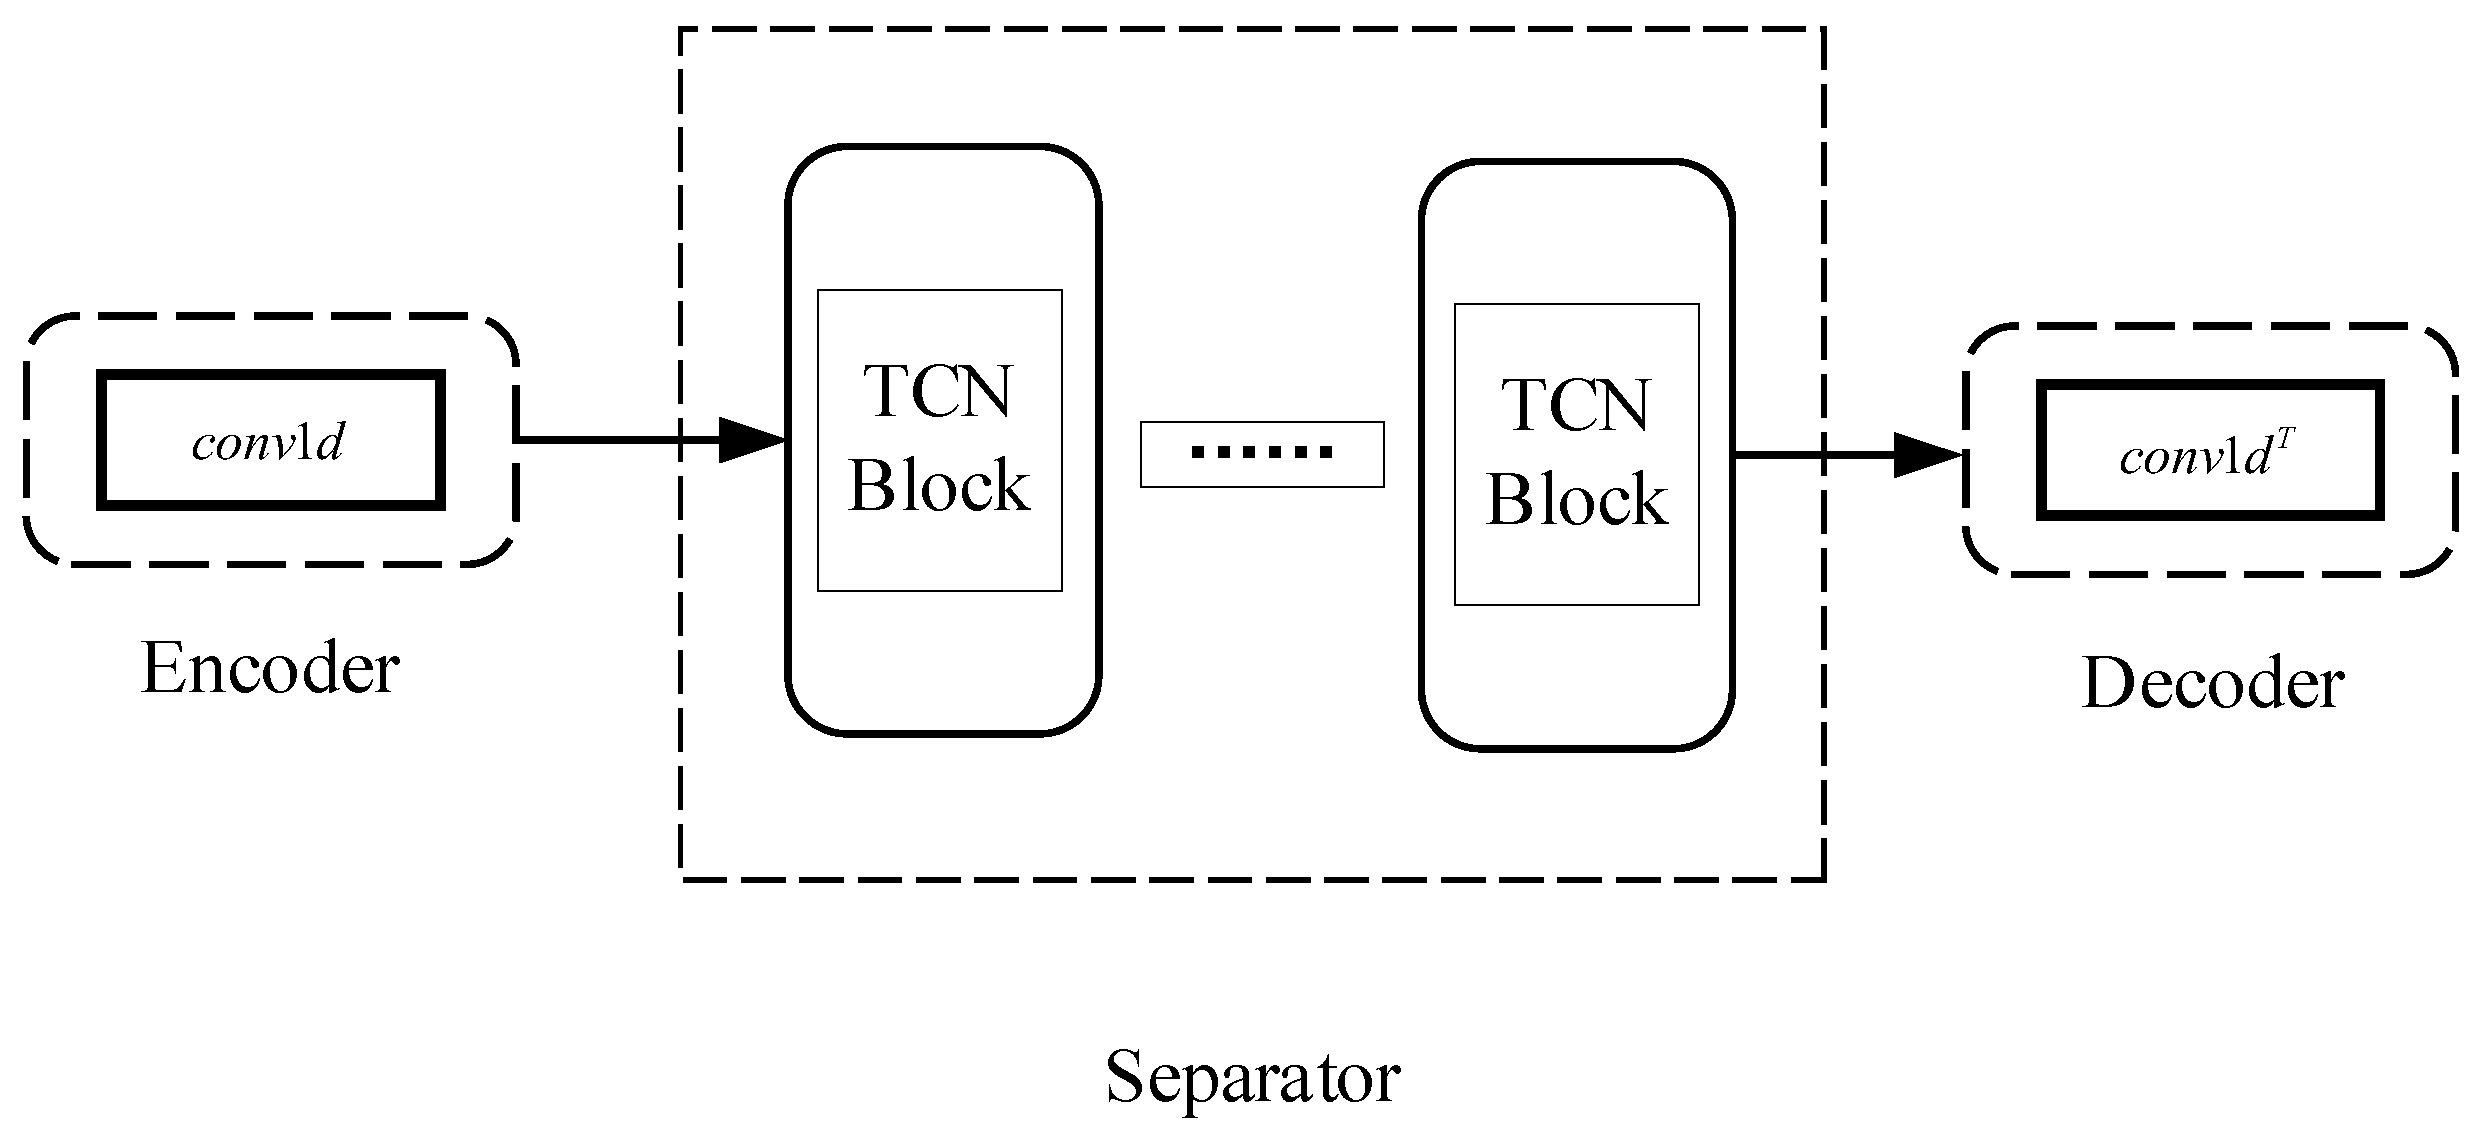
In multi-lingual, multi-speaker environments (e.g., international conference scenarios), speech, language, and background sounds can overlap. In real-world scenarios, source separation techniques are needed to separate target sounds. Downstream tasks, such as ASR, speaker recognition, speech recognition, VAD, etc., can be combined with speech separation tasks to gain a better understanding. Since most of the evaluation methods for monophonic separation are either single or subjective, this paper used the downstream recognition task as an overall evaluation criterion. Thus, the performance could be directly evaluated by the metrics of the downstream task. In this paper, we investigated a two-stage training scheme that combined speech separation and language identification tasks. To analyze and optimize the separation performance of single-channel overlapping speech, the separated speech was fed to a language identification engine to evaluate its accuracy. The speech separation model was a single-channel speech separation network trained with WSJ0-2mix. For the language identification system, we used an Oriental Language Dataset and a dataset synthesized by directly mixing different proportions of speech groups. The combined effect of these two models was evaluated for various overlapping speech scenarios. When the language identification network model was based on single-person single-speech frequency spectrum features, Chinese, Japanese, Korean, Indonesian, and Vietnamese had significantly improved recognition results over the mixed audio spectrum.
Keywords: speech separation; Conv-TasNet; language identification; overlap rate; spectrogram speech separation; Conv-TasNet; language identification; overlap rate; spectrogram