


Abstract
Maritime ship detection faces challenges due to complex object poses, variable target scales, and background interference. This paper introduces YOLO-PFA, a novel SAR ship detection model that integrates multi-scale feature fusion and dynamic alignment. By leveraging the Bidirectional Feature Pyramid Network (BiFPN), YOLO-PFA enhances cross-scale weighted feature fusion, improving detection of objects of varying sizes. The C2f-Partial Feature Aggregation (C2f-PFA) module aggregates raw and processed features, enhancing feature extraction efficiency. Furthermore, the Dynamic Alignment Detection Head (DADH) optimizes classification and regression feature interaction, enabling dynamic collaboration. Experimental results on the iVision-MRSSD dataset demonstrate YOLO-PFA’s superiority, achieving an mAP@0.5 of 95%, outperforming YOLOv11 by 1.2% and YOLOv12 by 2.8%. This paper contributes significantly to automated maritime target detection.
1. Introduction
Over the past decade, due to the swift advancement of the maritime economic sector, the dependence on ocean resources and maritime space has been steadily increasing. As critical carriers for ocean resource exploitation and economic activities, ships require accurate and efficient monitoring. Therefore, advancing research on automated maritime target detection holds great significance for strengthening maritime area management [1]. Due to the highly variable marine environment and the diverse appearances of vessels, ship detection must take into account a wide range of conditions and scenarios. Conventional approaches to ship detection chiefly hinge on image processing and manual feature extraction techniques such as edge detection, shape analysis, and threshold segmentation. These approaches depend on handcrafted features and fixed rules, which often fail to maintain accuracy in complex or dynamic maritime environments [2]. In addition, High-Frequency Surface Wave Radar (HFSWR), as a technology capable of over-the-horizon monitoring, is also an important means for maritime target detection and has long been a key research direction in the field of primary signal processing algorithms. For instance, Li et al. [3] proposed an automatic ship target detection algorithm for HFSWR based on wavelet transform. This algorithm adopts a peak signal-to-noise ratio (SNR)-based method to adaptively determine the wavelet transform scale, enhances high-frequency coefficients via a fuzzy set approach, and reconstructs these coefficients to suppress clutter and background noise. It is applied to the ship target detection scenario of HFSWR, aiming to improve the target detectability in clutter environments. Golubović et al. [4] proposed a dual-frequency HFSWR system architecture, a supporting signal model, and a high-resolution primary signal processing method based on the Multiple Signal Classification Algorithm. Through experimental verification, this scheme was shown to improve the detection performance and accuracy of both large and small maritime targets compared with the single-frequency mode. Zhang et al. [5] proposed an optimized Error Self-adjustment Extreme Learning Machine (OES-ELM) and applied it to high-frequency surface wave radar (HFSWR) target detection, aiming to further improve the model’s adaptability to complex marine interference and enhance detection performance.
Lately, breakthroughs in deep learning have propelled image understanding forward, anchored by influential Convolutional Neural Network (CNN) designs such as Faster R-CNN [6], Mask R-CNN [7], and successive YOLO iterations [8,9,10,11]. Deep learning-based object detection algorithms can be categorized into two main types: multi-stage and single-stage methods. Multi-stage approaches, such as the R-CNN series, first generate region proposals within the image, allowing for effective feature extraction and background noise suppression [12]. Single-stage methods, on the other hand, directly predict object locations and categories from the entire image, offering faster inference times [13]. Notable single-stage detectors include YOLO, Single Shot MultiBox Detector (SSD) [14], and CenterNet [15]. With the continuous evolution and widespread adoption of the YOLO series, many researchers have focused on enhancing ship detection using YOLO-based architectures. For instance, Cheng et al. [16] proposed YOLOv5-ODConvNeXt, a more accurate and faster model designed to detect ships from Unmanned Aerial Vehicle (UAV) imagery to improve maritime surveillance. However, their approach mainly targets large marine objects, neglecting performance on smaller targets. Chen [17] created a vessel identification model with YOLOv7, designed to tackle intricate environment complexities, using a multi-level strategy. This model integrates Atrous Spatial Pyramid Pooling (ASPP) and Shuffle Attention mechanisms to minimize the loss of critical features associated with vessels. Liu et al. [18] introduced the YOLO-SSP model, which is a variant of the YOLOv8m architecture. They have boosted the detection capabilities for objects in satellite imagery by swapping out the original downsampling layer for a nimbler SPD-Conv module. Additionally, they have incorporated the Pyramid Spatial Attention Mechanism (PYSAM) to refine the detection process. Luo et al. [19] further refined YOLOv8n by adding a Shuffle Attention module to both the backbone’s SPPF (Spatial Pyramid Pooling—Fast) block and the neck’s second upsampling layer, boosting ship target sensitivity. They also integrated a re-parameterized RepGhost bottleneck into the C2f module, reducing parameters and computational complexity. Zhou et al. [20] introduced DAP-Net, boosting Synthetic Aperture Radar (SAR) ship recognition via a dual-path extractor that leverages SENet to handle multi-polarization imagery, and an enhanced focal loss that mitigates dataset imbalance. Shen [21] introduced DS-YOLO, an SAR ship detector built upon YOLOv11 incorporating Space-to-Depth Convolution, Cross-Stage Partial Pyramid Attention, and the Adaptive Weighted Normalized Wasserstein Distance (AWNWD) loss function. While this approach improves detection accuracy across varying image qualities, its ability to distinguish densely packed small targets remains limited.
Overall, despite the continuous advancement of ship target detection technology driven by deep learning, several challenges remain unresolved. Firstly, ships in real SAR images exhibit remarkable diversity; owing to variations in their types and configurations, substantial discrepancies exist in their sizes and aspect ratios. Accurately detecting and accentuating the intrinsic features of ships thus remains a critical challenge. Secondly, SAR images inherently exhibit speckle noise, which is an unavoidable consequence of the SAR imaging process. In intricate settings, reduced visibility of tiny objects is frequently caused by sea clutter and speckle noise, impairing detection precision. Existing ship detection methods suffer from two key limitations: insufficient capability to detect multi-scale targets and vulnerability of target features to distortion during the image feature extraction process. To tackle these issues, this paper presents an enhanced YOLOv11-based ship detection method named YOLO-Partial Feature Aggregation (YOLO-PFA), specifically designed for SAR ship detection scenarios in complex marine environments. The main contributions of this study are outlined as follows:
- (1)
- To address the limitations of YOLOv11 in managing targets of varying scales—such as inefficient multi-scale feature fusion, inadequate adaptive balancing of cross-layer feature contributions, and suboptimal detection of small objects—this study incorporates the Bidirectional Feature Pyramid Network (BiFPN) [22]. BiFPN utilizes bidirectional connections to facilitate efficient information flow across multi-resolution feature maps, along with an adaptive weighting strategy that dynamically prioritizes salient features, thereby enhancing multi-scale fusion. These mechanisms significantly improve the capture of details for small objects, ultimately leading to enhanced detection accuracy and robustness for YOLOv11.
- (2)
- To resolve the issue in ship detection where misalignment between classification and localization tasks makes their joint optimization difficult, this study integrates Depthwise Separable Convolution with Group Normalization (DSConv_GN) into the Task-aligned Dynamic Detection Head (TADDH) [23], proposing an enhanced Dynamic Alignment Detection Head (DADH). This module dynamically selects discriminative features critical for both tasks in complex marine scenarios, thereby improving detection accuracy across ship types and scales. Additionally, DSConv_GN mitigates overfitting and reduces computational overhead.
- (3)
- To address low detection accuracy caused by large-scale variations and heavy background clutter in ship detection, the C2f-Partial Feature Aggregation (C2f-PFA) module is proposed. It extracts multi-scale features via varied convolutional kernels and fuses raw and processed multi-scale features to strengthen comprehensive ship feature expression. Integrating 1 × 1 convolution and residual connections further refines key features, reduces information loss, and alleviates gradient vanishing.
- (4)
- Experiments on the public iVision-MRSSD ship dataset evaluate the impact of the proposed modules. Results show the improved YOLO-PFA achieves a mAP@0.5 of 95%, outperforming YOLOv11 by 1.2% and YOLOv12 by 2.8%.
The structure of this paper is as follows. Section 1 is the Introduction, which elaborates on the research background and significance of ship detection, analyzes the limitations of traditional methods and the advantages of deep learning, reviews the status of relevant research, points out existing problems, and proposes the YOLO-PFA model and research contributions. Section 2 is the Related Works, which summarizes existing research and identifies problems to be solved from three aspects: the evolution of SAR ship detection technology, multi-scale feature fusion, and detection head structure innovation. Section 3 is the Methodology, which introduces the design of the three core optimization modules of the YOLO-PFA model. Section 4 is the Experiments and Results Analysis, which verifies the effectiveness of each module and the overall performance of the model through experiments. Section 5 is the Conclusions, which summarizes the research results, analyzes the advantages and limitations of the model, and looks forward to future directions.
2. Related Works
This chapter systematically organizes and reviews existing research from three core directions closely related to this study: First, it reviews the evolutionary process of Synthetic Aperture Radar (SAR) ship target detection technology from traditional machine learning to deep learning, and analyzes the advantages and limitations of different methods. Second, it focuses on multi-scale feature fusion, a key technology for improving target detection performance, and expounds on the development context and design ideas from early image pyramids to modern Feature Pyramid Networks (FPN) and their improved algorithms. Finally, regarding the target detection head—a core module that directly affects prediction results—it sorts out the structural innovations of detection heads represented by the YOLO series, especially the adaptability of anchor-free designs and decoupled head optimizations to ship detection tasks. By summarizing relevant work, this chapter clarifies the progress of current research and the problems to be solved, laying a theoretical foundation for the subsequent proposal of a more optimized SAR ship target detection scheme.
2.1. Ship Target Detection
As deep learning has emerged, the field of SAR vessel detection has effectively been divided into two key phases of advancement: classic machine learning methodologies and the cutting-edge approaches grounded in deep learning technology.
Traditional machine learning techniques include methods like regional delineation, fractal analysis, wavelet transformation, fuzzy logic detection, and feature matching techniques. However, these methods all have obvious shortcomings, such as being susceptible to interference from a single point, inaccurate detection in complex environments, and difficulty in designing appropriate feature functions [24]. One algorithm that is often studied and widely used is the Constant False Alarm Rate (CFAR) [25]. The approach aims to detect ships by constructing statistical models of ambient noise. However, accurately characterizing the distribution of background noise in complex environments is challenging, as selecting an appropriate probability density function proves to be difficult; moreover, due to the extensive computations required to solve distribution parameters, the processing speed of this algorithm fails to meet practical demands [26]. Furthermore, along with the ongoing development of deep learning approaches, a great number of Convolutional Neural Network (CNN)-based research studies have been presented for detecting ships in marine scenarios. For instance, Zhou et al. [27] introduced an enhanced pyramid network module designed for the adaptive fusion of features in SAR images, with the objective of selecting optimal features for multi-scale target detection tasks. Zhang [28] utilized YOLO’s concept to introduce an innovative rapid maritime detection technique for SAR imagery via a Grid Convolutional Neural Network. Zwemer et al. [29] trained a Single Shot MultiBox Detector (SSD) to detect targets by identifying ship features such as scale and aspect ratio.
2.2. Multi-Scale Feature Fusion
Multi-scale feature fusion entails the integration of features across various scales to achieve a more comprehensive and accurate representation. A prevalent method for multi-scale feature fusion is the pyramid structure, which has undergone several developmental stages. The earliest pyramid structures were based on image pyramids, where the input image is downsampled multiple times to generate images of varying scales, after which features are extracted and fused. With the advancement of deep learning, researcher Lin [30] proposed the Feature Pyramid Network (FPN) method in 2017, which achieves feature fusion by constructing a multi-scale feature pyramid within the network. FPN leverages the hierarchical structure of features obtained through downsampling and pooling, upsamples, concatenates, and weights features of different resolutions, ultimately generating high-resolution, high-semantic feature maps. Here “high-resolution” is a relative concept, consistent with the resolution of shallow network features. Specifically, FPN upsamples deep low-resolution features (rich in semantics) to match shallow feature resolution (good at capturing details), then fuses them to form the aforementioned high-resolution feature maps. Subsequently, this method was further improved and applied by more scholars. Liu [31] introduced Path Aggregation Network (PANet), which appends an upward-flowing path after FPN’s downward hierarchy to refine multiscale feature integration. Tan’s Bidirectional Feature Pyramid Network (BiFPN) represents a further refinement of PANet; it addresses the limitations of traditional FPN by introducing top-down and bottom-up information exchange paths, enabling more effective feature aggregation and context propagation. Some scholars have also incorporated feature pyramid structures into other network architectures. For example, DAMO-YOLO [32] refines YOLOv4 with a reparameterized generalized FPN that enriches feature fusion across the backbone and neck. Gold-YOLO [33] introduced an advanced Gather-and-Distribute mechanism, which abandons the recursive approach of traditional FPN structures. Instead, it collects and fuses information from all layers through a unified module before distributing it to different layers, mitigating the intrinsic data degradation in conventional FPN and boosting the regional information integration prowess of the neck.
2.3. Target Detection Head
The detection head of YOLO is a pivotal piece that drives predictions using the insights gathered from the core network. It receives feature maps, derived from every level of the feature pyramid, and then it gets to work by pinpointing object boundaries, estimating class likelihoods, and scoring objects [34]. YOLOv8 forgoes the customary anchor-based detection in YOLO iterations, opting for an anchorless detection head structure. It directly detects and locates targets on feature maps, achieving object detection by predicting the central coordinates, width, height, and class probabilities of targets. This anchorless architecture streamlines detection, minimizes anchor-dependent parameters, and enhances the model’s adaptability and speed. The optimized design of the decoupled head architecture is the core innovation of YOLOv11. The decoupled head segregates the combined detection of categories and locations into distinct pathways for handling. In YOLOv11’s decoupled head, the classification branch introduces Spatial Attention Mechanism and Channel Attention Mechanism to enhance the extraction of target location and class features, respectively. The localization branch incorporates Deformable Convolution v3 (DCNv3) to adaptively adjust the shape of the receptive field, matching irregular target boundaries. These improvements effectively enhance YOLOv11’s multi-scale target detection capability while improving computational efficiency.
3. Methodology
To tackle key challenges in Synthetic Aperture Radar (SAR) ship target detection, which mainly include complex environment, significant ship scale variations, and insufficient information interaction between detection tasks, this chapter proposes an improved model named YOLO-PFA based on the YOLOv11 framework. The optimization of YOLO-PFA focuses on three core modules of the original model. First, it replaces the neck network of YOLOv11 with a Bidirectional Feature Pyramid Network (BiFPN) to enhance the efficiency and comprehensiveness of multi-scale feature fusion. Second, it upgrades the detection head to a Dynamic Adaptive Decoupled Head (DADH) to bridge the information gap between the classification and localization branches. Third, it substitutes the original C3k2 module in the backbone with a C2f-PFA module to strengthen the extraction of discriminative features for ship targets. The following sections elaborate on the detailed design and operational mechanism of each optimized module.
3.1. YOLO-PFA Structure
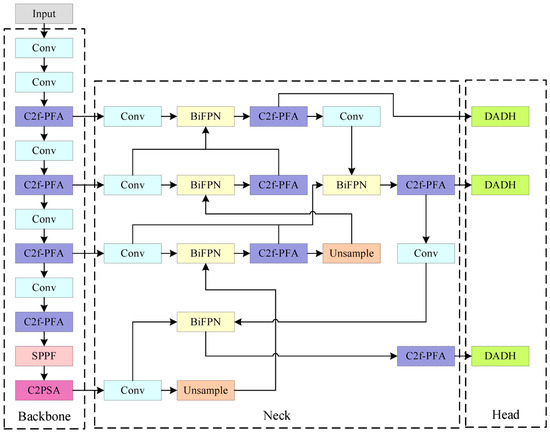
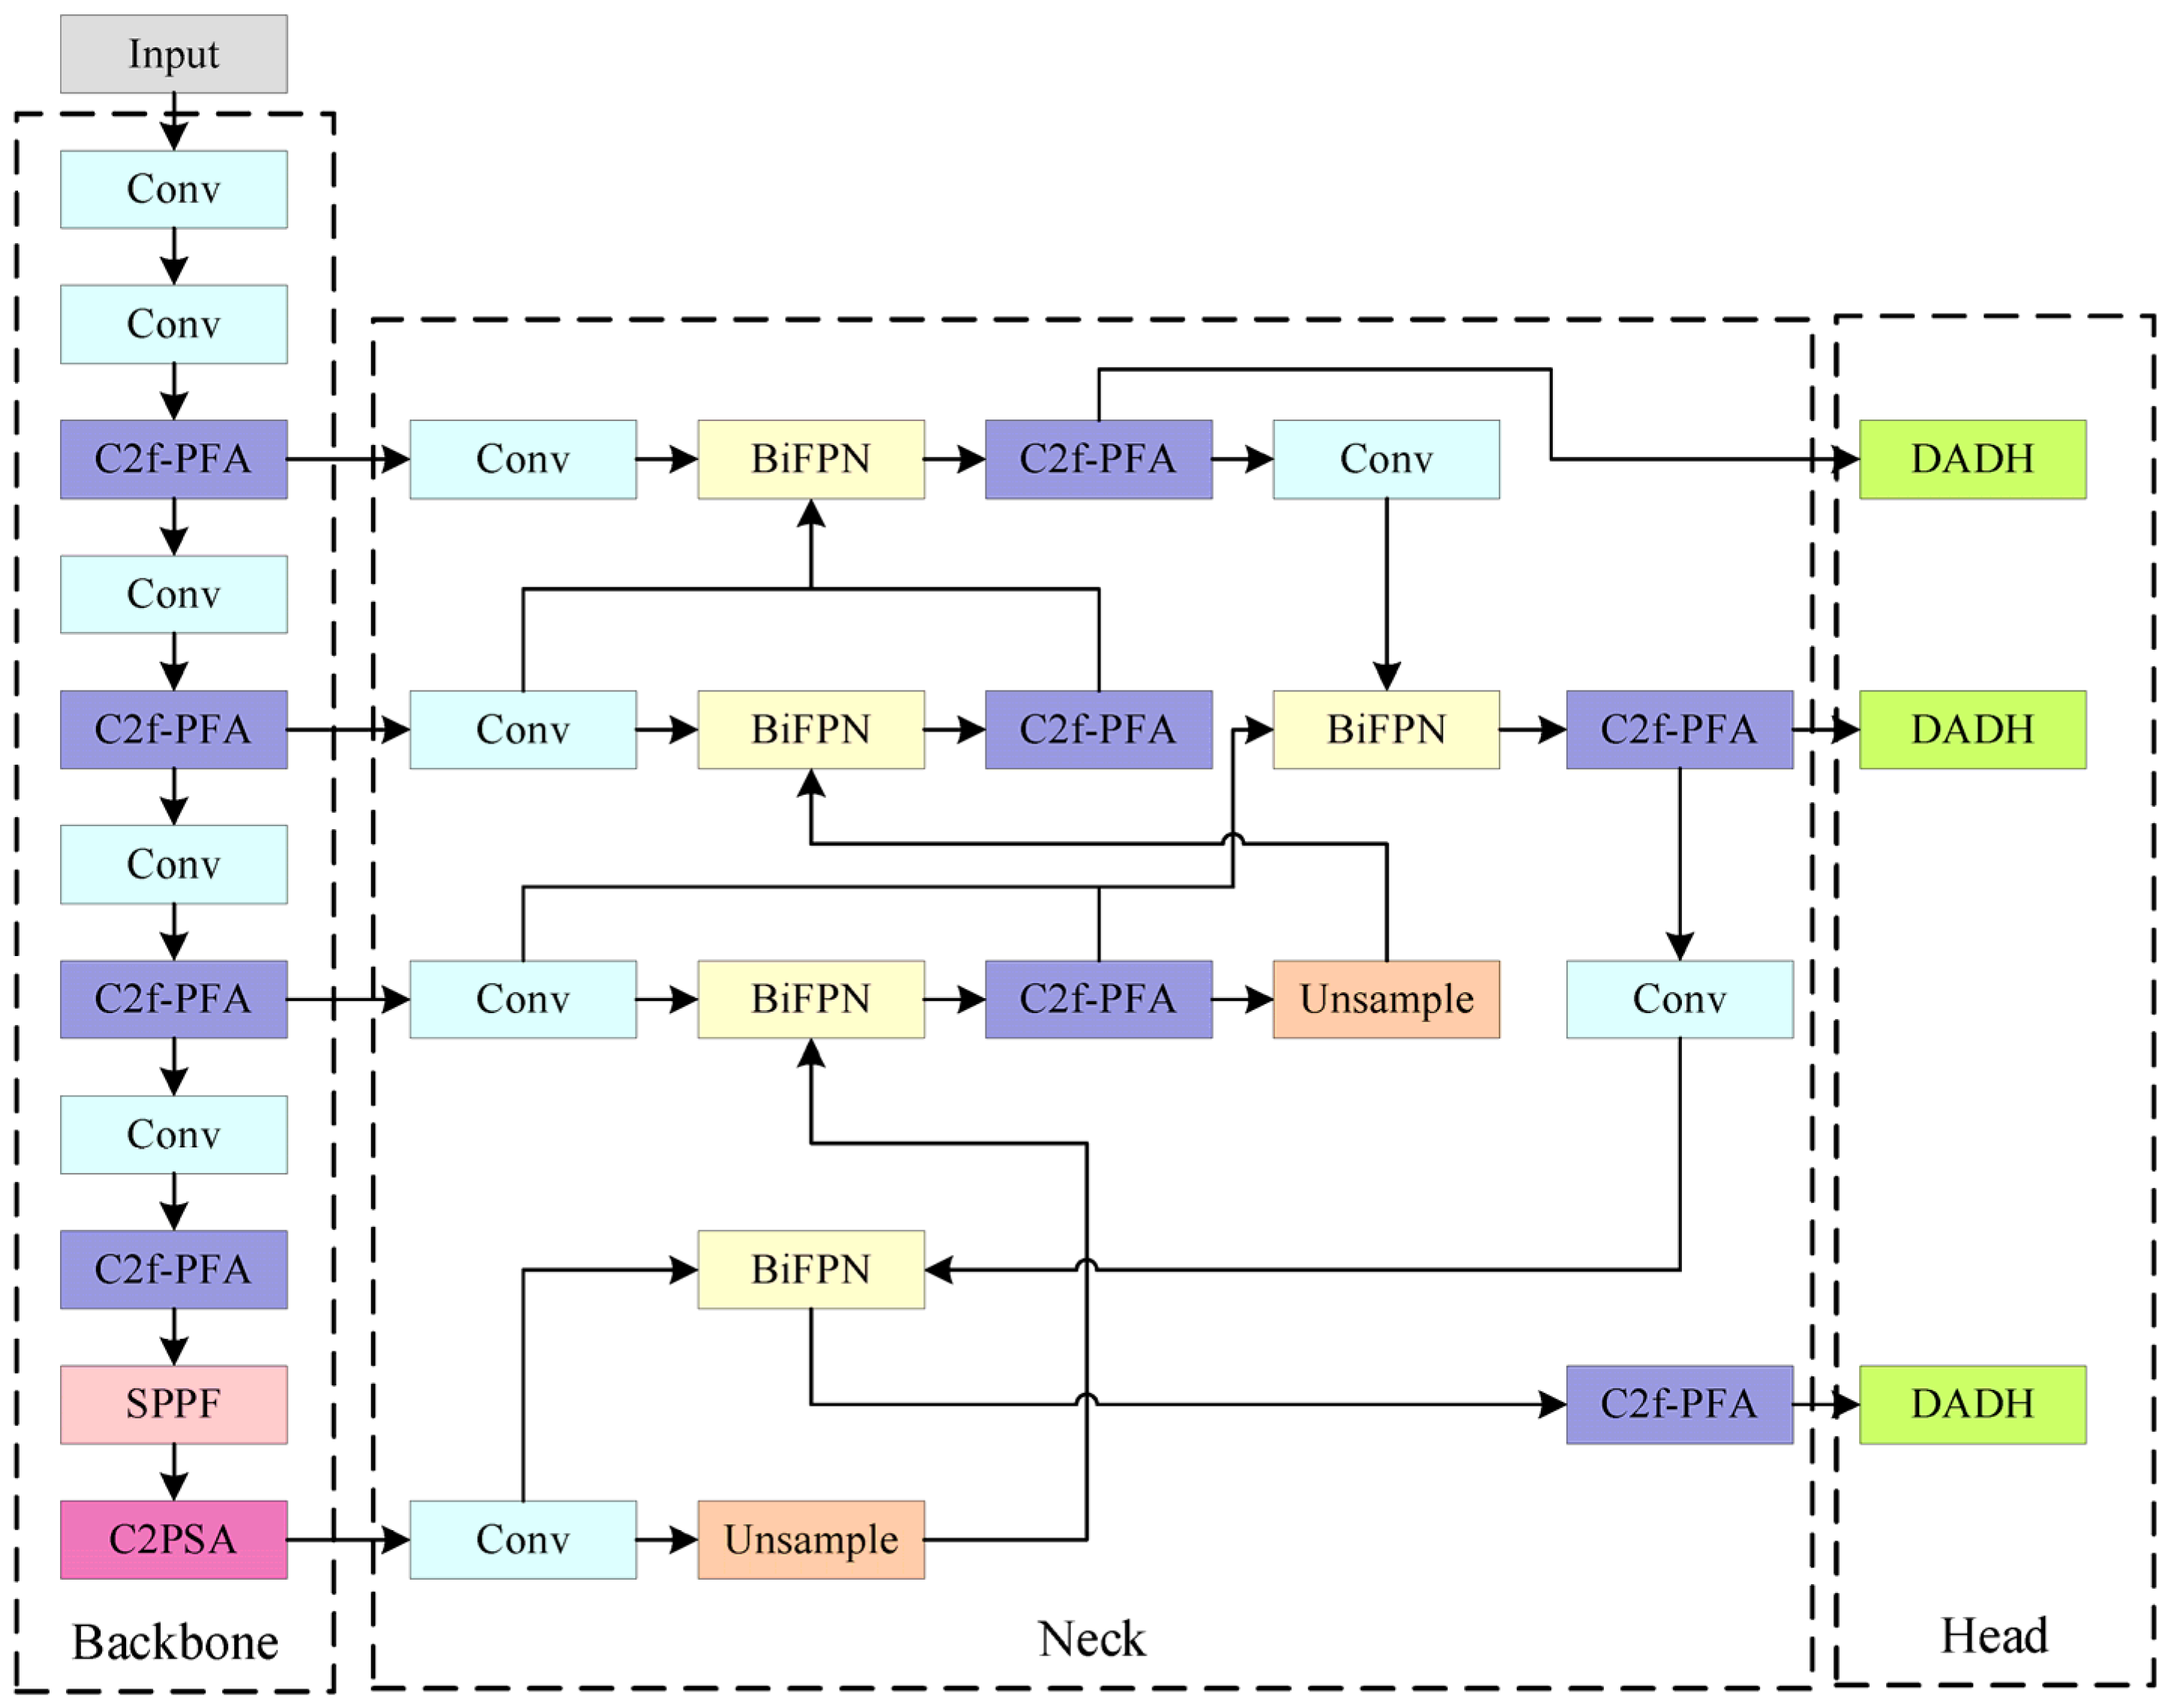
Based on the YOLOv11 model, we have improved a new model architecture, YOLO-Partial Feature Aggregation (YOLO-PFA), as shown in Figure 1. The specific implementation involves integrating BiFPN into YOLOv11: BiFPN, featuring top-down and bottom-up bidirectional pathways, enables more efficient fusion of multi-scale feature information. Equipped with optimized connection mechanisms and weight allocation strategies, this module facilitates more direct and comprehensive transmission of features across different layers. Additionally, we replace the original C3k2 module with the C2f-PFA module, which preserves a portion of the raw feature information and aggregates it with processed multi-level features, thereby effectively boosting the efficiency and stability of the model’s feature extraction. The DADH module revises the original detection head, realizing dynamic selection of interactive features through components such as task decomposition and deformable convolution networks. This addresses the discordance between categorization and pinpointing in single-stage object recognition systems, thus enhancing accuracy in identification.
Figure 1.
YOLO-PFA Structure.
3.2. Bidirectional Characteristic Pyramid Network
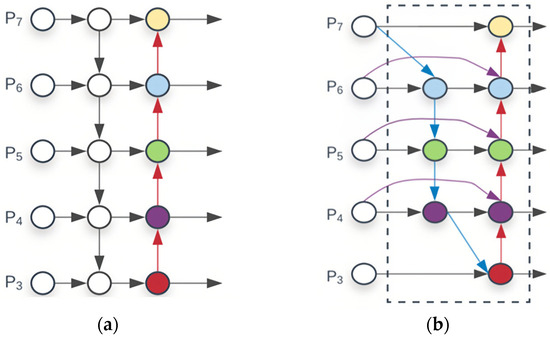
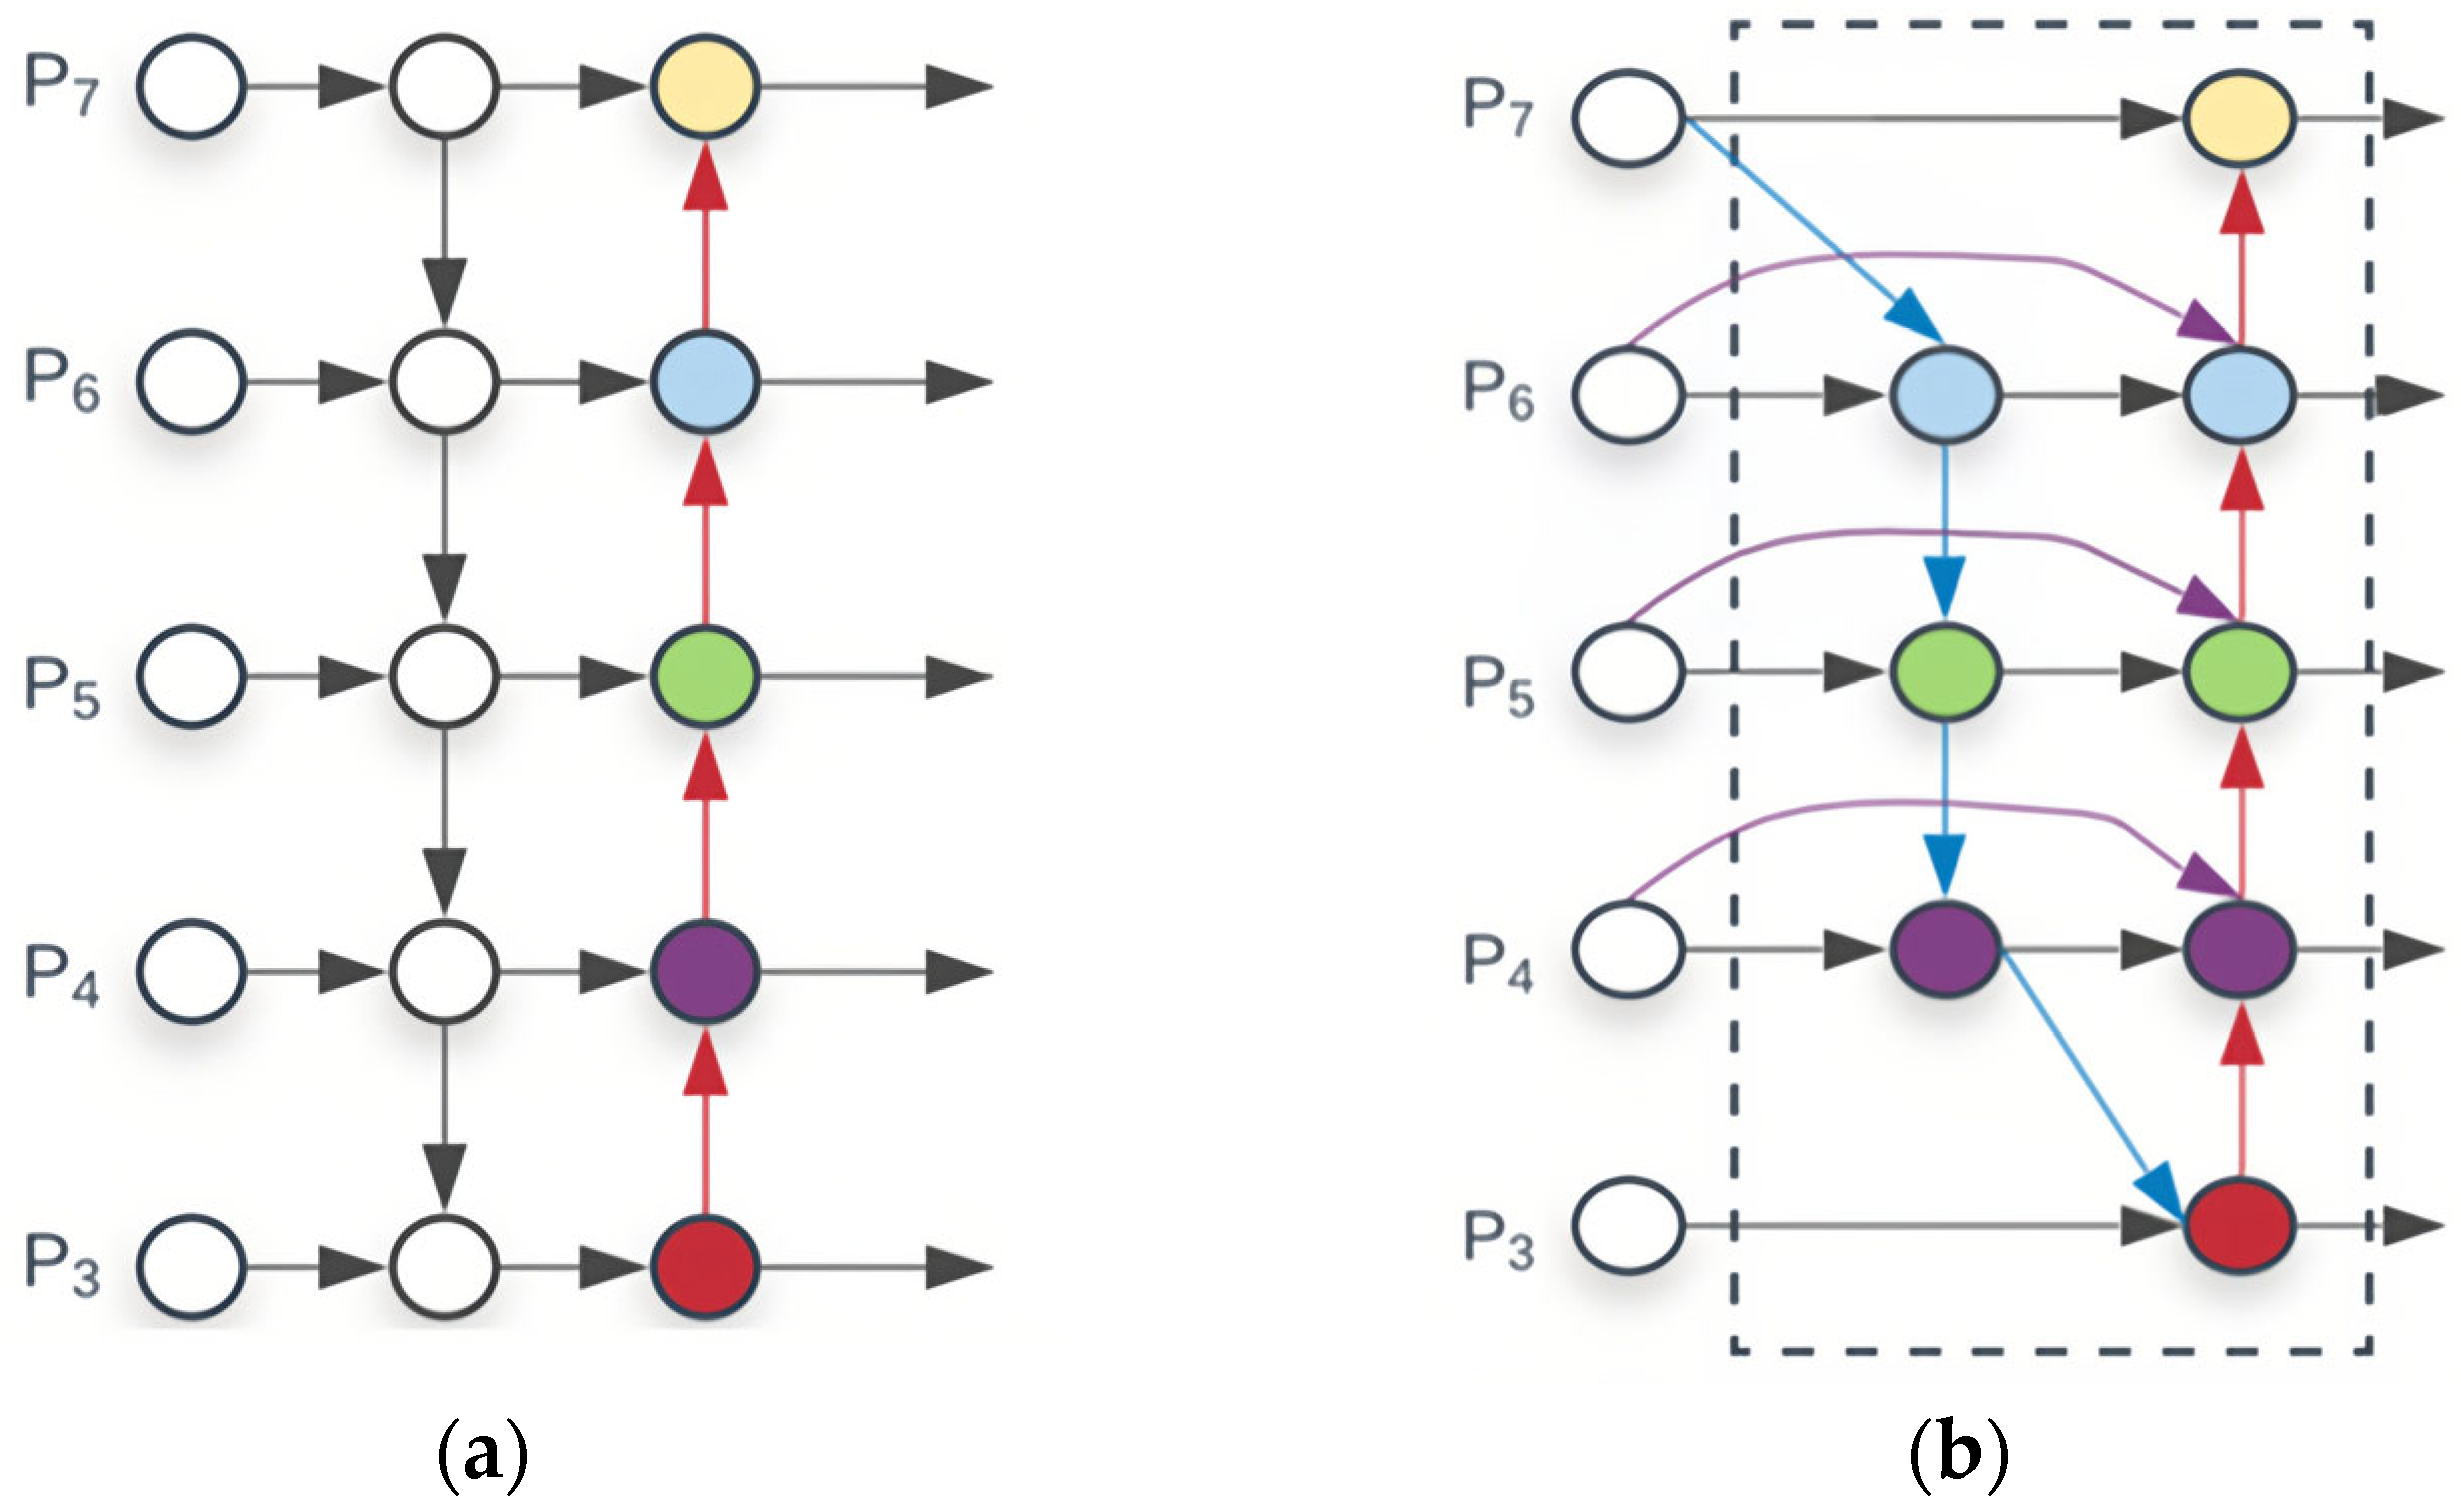
In YOLOv11, the neck region gets a major upgrade with a tweak of the PANet architecture for improved feature integration. The BiFPN takes this a step further by incorporating adaptive weights to gauge the importance of various input features. It cleverly combines a mix of top-down and bottom-up path aggregation, horizontal interconnections, and feature consolidation. Moreover, it leverages multi-scale fused features from both directions, repeatedly, to handle multi-scale info processing, thus enriching the semantic understanding. As shown in Figure 2, the network structures of PANet and BiFPN are compared. BiFPN’s operational framework enhances the network’s prowess in mastering diverse scales of feature representations, bolstering its adaptability in tackling targets with a wide range of complexities and dimensions. Considering the diverse types and varying postures of ship targets, YOLO-PFA modifies the neck network of YOLOv11 by replacing the improved PANet with BiFPN, thereby elevating feature fusion across the entire network.
Figure 2.
Comparison of PANet and BiFPN network structures: (a) PANet; (b) BiFPN.
3.3. DADH Detection Head Structure
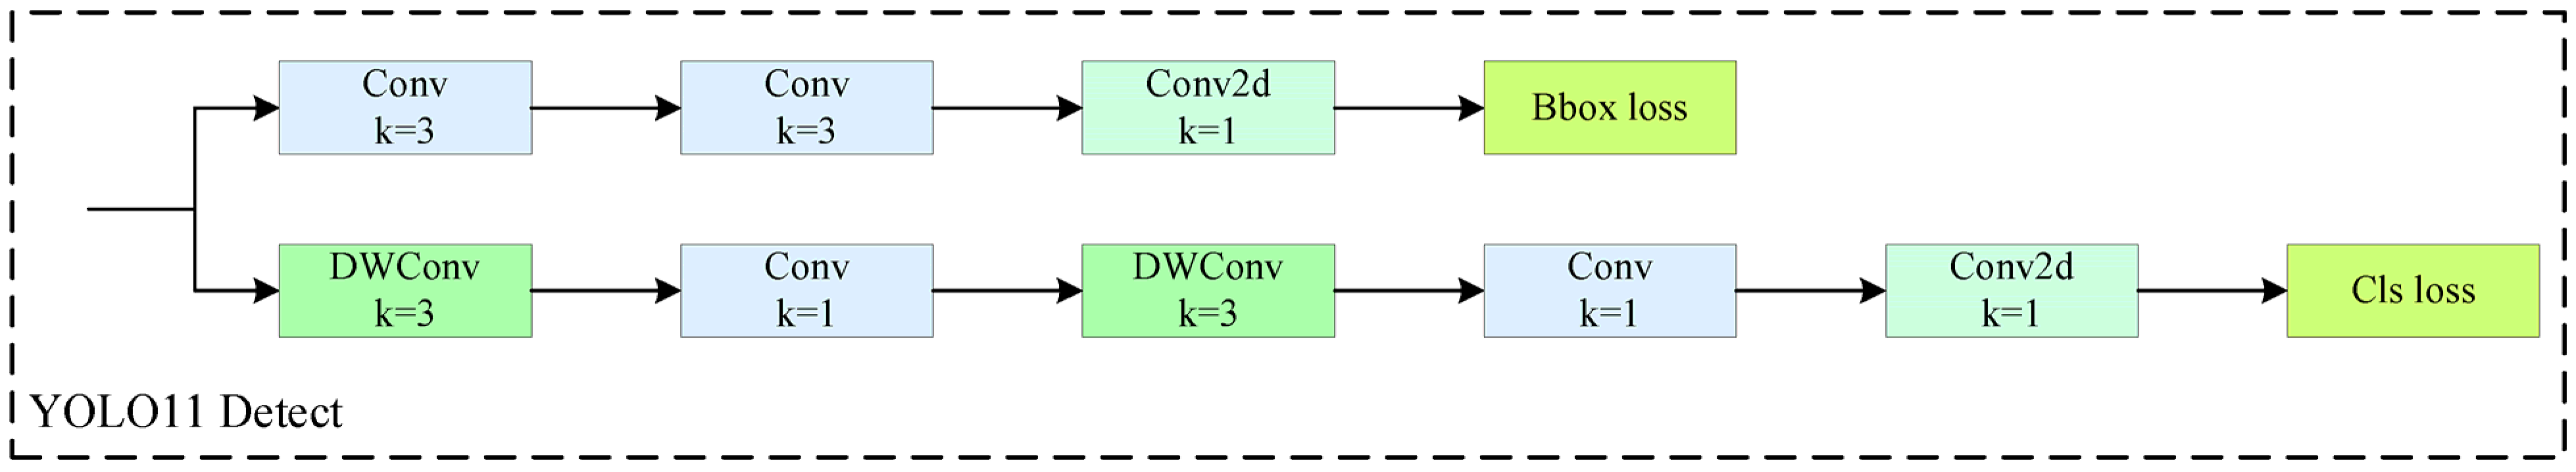
The decoupled head of YOLOv11 assigns classification and localization tasks to separate subnetworks, handling class prediction and bounding box regression independently. Each branch is equipped with its own dedicated multi-layer architecture. While this design enhances feature learning capability, it also leads to a substantial increase in the number of parameters within the detection module. Furthermore, the classification branch focuses on learning category-specific features (e.g., texture and color in images), whereas the regression branch specializes in localization features (e.g., boundaries and shapes). However, the independent optimization of these two branches, devoid of information interaction, constrains the model’s performance in handling complex and dynamically changing detection scenarios. The structure of YOLOv11’s detection head is illustrated in Figure 3.
Figure 3.
Structure of YOLOv11 detection head.
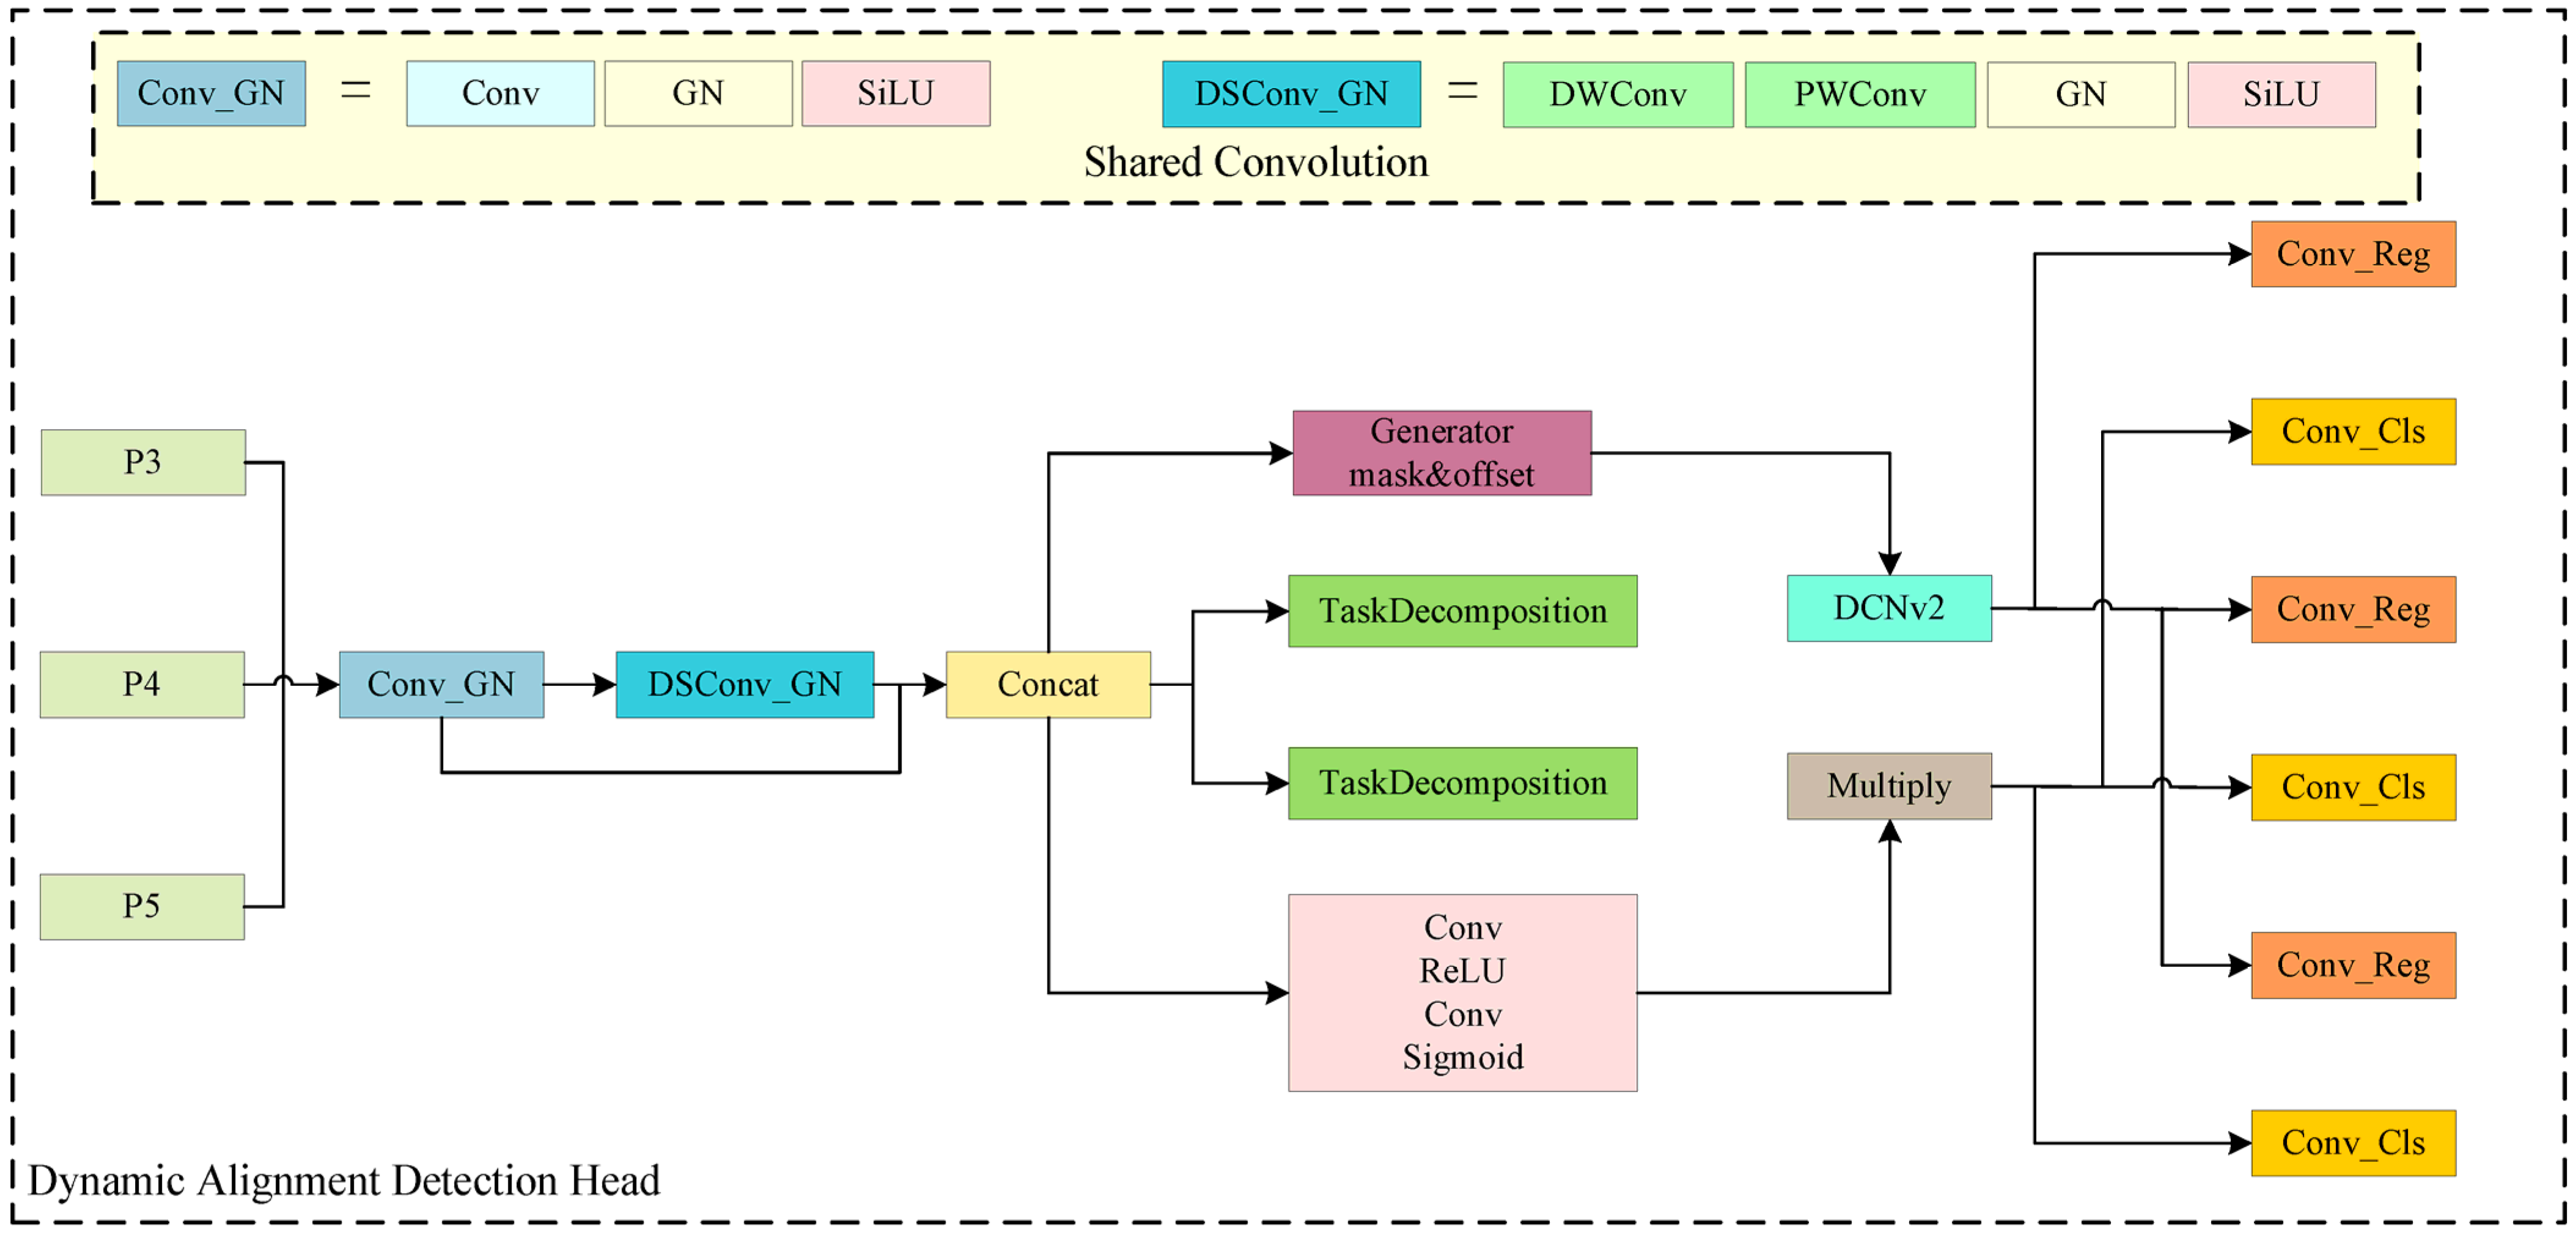
To tackle the info gap between the separate assignments, we have merged the TADDH detection module into the YOLOv11 framework and finessed it to introduce the DADH design. The key enhancement is swapping out the old Conv_GN component for the DSConv_GN, capitalizing on the benefits of depthwise separable convolution for sleeker builds and quicker feature sifting. The depthwise convolution (DWConv) works solo on each channel input, which lets it zero in on finer details and edge info in the images. Then, the pointwise convolution (PWConv) combines these channels from the DWConv output with ease, cutting down on the number of parameters while still allowing for a flexible tweak of feature sizes. The DSConv_GN module, working in conjunction with the Conv_GN module within the detection head network, achieves more efficient feature extraction and inter-task information interaction.
The DSConv_GN module in DADH combines depthwise separable convolution with group normalization (GN) and the SiLU activation function, with its mathematical expression as follows:
Given the input features , where Cin, H, and W represent the number of channels, height, and width of the input feature map, respectively, and R indicates that the input is a “3D tensor”. The forward propagation process of the DSConv_GN module can be decomposed as:
- (1)
- Depthwise convolution operation:
- (2)
- Pointwise convolution operation:
- (3)
- Group normalization operation:
- (4)
- Application of activation function:
Combining the above steps, the full expression of the DSConv_GN module is:
The overall network structure of DADH is illustrated in Figure 4. The shared convolution layer structure integrates convolution layers, group normalization layers, and activation functions, responsible for extracting initial features from input feature maps. It compresses the feature maps to half their channel count, delivering high-quality interactive features that empower subsequent task decomposition modules. DADH decomposes detection tasks via the TaskDecomposition module, where the category decomposition module extracts category features from shared features, and the regression decomposition module extracts regression features. To further enhance the alignment accuracy of regression features, DADH incorporates Deformable ConvNet V2 (DCNv2) [35] into the localization branch. This module uses convolution layers to generate offsets and masks from interactive features, dynamically adjusting the position and shape of convolution kernels to achieve precise feature alignment [36]; the classification branch utilizes interactive features for dynamic feature selection. Finally, the regression and category features are processed, with corresponding convolution layers generating bounding box regression values and category predictions, respectively. Through the collaborative design of multiple modules, DADH optimizes inter-task cooperation, effectively improving overall detection performance.
Figure 4.
DADH network structure.
3.4. C2F-PFA Module
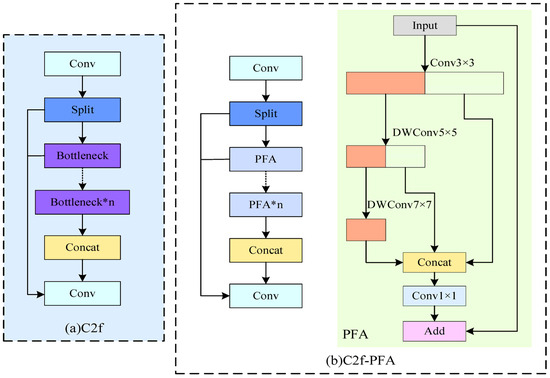
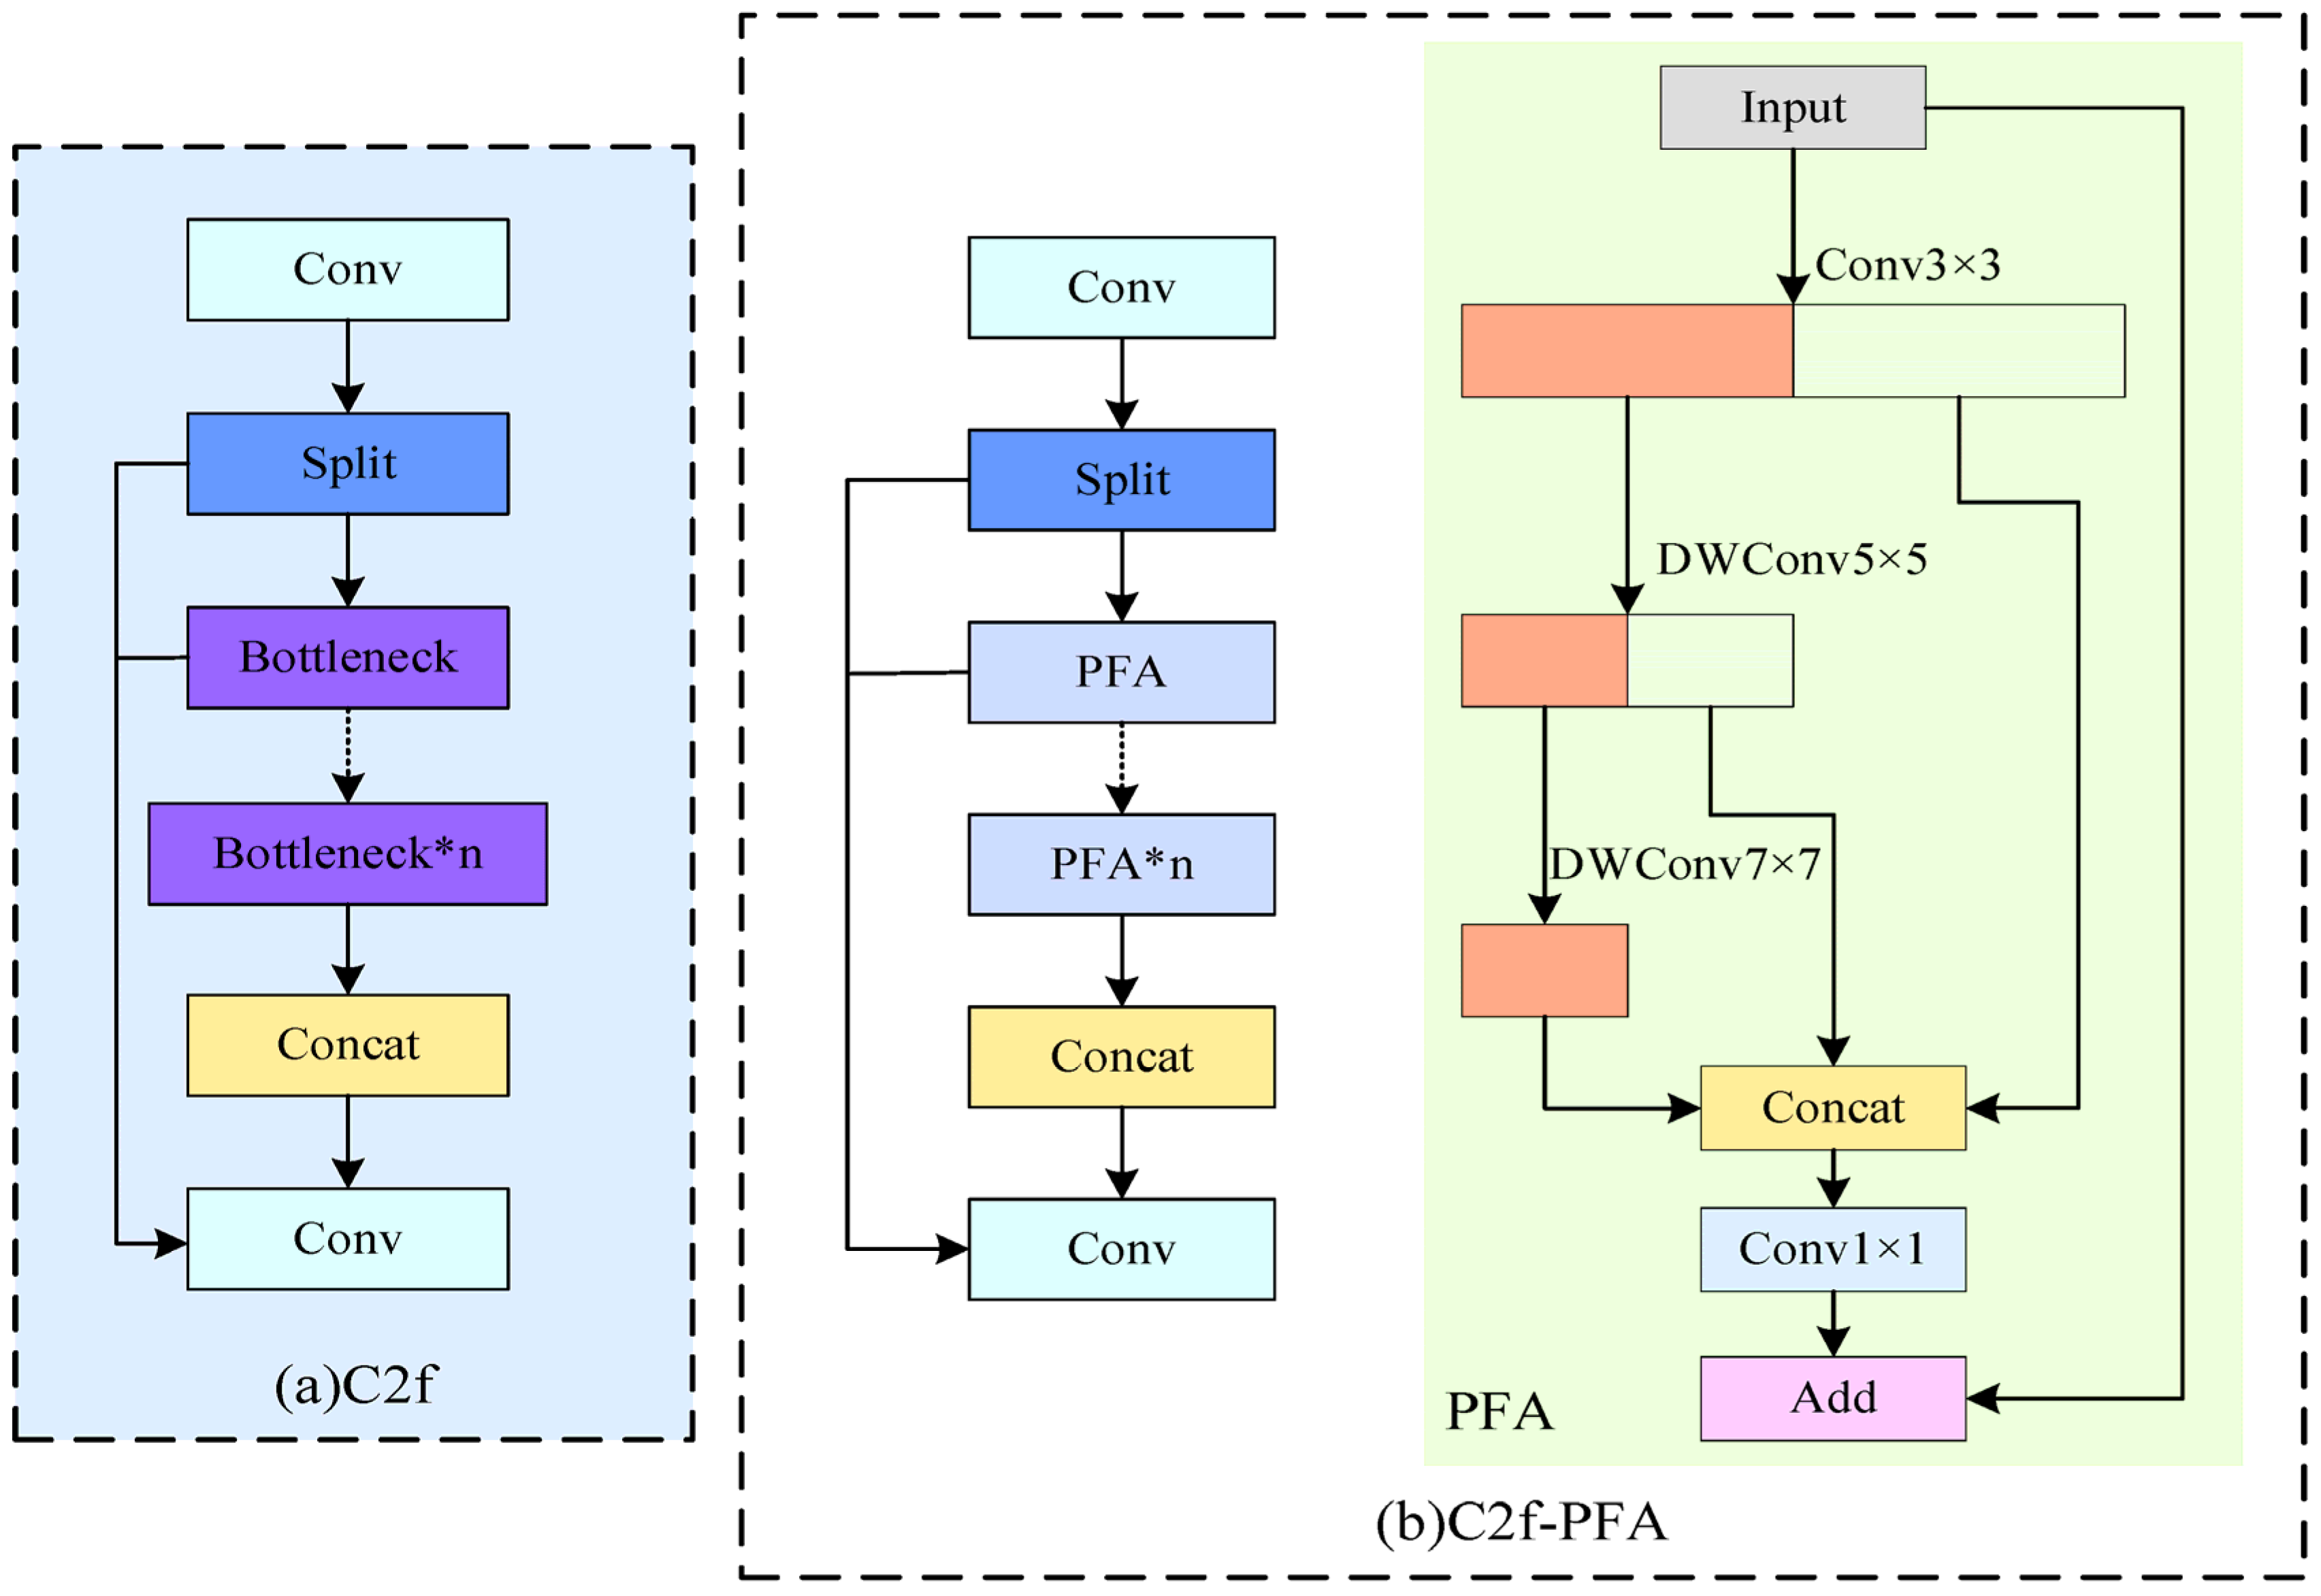
The C2f module excels at aggregating multi-scale information by concatenating outputs from different bottleneck modules with the original feature map. It demonstrates superior local feature extraction capabilities in complex scenarios involving occlusions and overlapping objects, making it highly suitable for low-light and high-contrast environments. Considering that ships at sea have diverse morphologies, are prone to occlusions, and are also susceptible to interference from special environmental conditions—specifically, in SAR imaging, sea surface reflections appear as strong scattering points, which are easily confused with the scattering features of small-scale ships; under low incident angles during dawn and dusk, ship shadows tend to stretch, obscuring the key structural information of the hull; meteorological conditions such as fog will increase the background clutter intensity in SAR images, causing ship targets to be “submerged” in the clutter. All these environmental factors significantly reduce the feature extraction accuracy and target recognition stability of conventional detection modules. Therefore, in consideration of the aforementioned scenario-specific characteristics and environmental challenges of ship detection, we introduce the C2f module into the YOLOv11 architecture, further optimize its feature fusion strategy, and propose the C2f-PFA module to enhance the model’s ability to capture features of ship targets and resist interference under complex sea conditions.
The structural comparison between C2f and C2f-PFA is shown in Figure 5. The PFA module achieves multi-scale feature representation through a multi-branch feature extraction and fusion mechanism, with the overall formula as follows:
where denotes the input feature map, C, H, and W represent the number of channels, height, and width of the input feature map, respectively. F(X) represents the feature transformation function, and the final addition operation signifies a residual connection. The feature transformation function F(X) comprises the following steps:
Figure 5.
Structural comparison between C2f and C2f-PFA.
- (1)
- Initial convolution processing:
- (2)
- Feature Splitting and First Branch:
- (3)
- Secondary Splitting and Second Branch:
- (4)
- Feature Fusion:
As illustrated in Figure 5, the PFA module employs convolutional kernels of varying scales for successive convolution operations. After the input feature information undergoes concatenation of multi-scale convolutional features, a 1 × 1 convolution is applied to adjust channels and enhance feature fusion. This is followed by a residual connection with the original input features. Such a fusion approach not only integrates features derived from multi-scale convolutions but also preserves the original input features, effectively strengthening the expressive power of ship target features. This enables the model to more accurately determine information such as ship positions and categories—particularly for ships with similar appearances or partial occlusions, which can be better distinguished and detected using the fused features.
4. Experimental and Results Analysis
This chapter first specifies the experimental environment, iVision-MRSSD dataset and evaluation indicators. The iVision-MRSSD dataset contains 11,590 Synthetic Aperture Radar (SAR) images, and the evaluation indicators include precision, recall and mAP@0.5. Then it conducts ablation experiments and comparative experiments: the former verifies the effect of each module, while the latter compares YOLO-PFA with mainstream models such as YOLOv8, YOLOv12, and RT-DETR. Results show YOLO-PFA outperforms other models, with mAP@0.5 reaching 95%.
4.1. Experimental Settings and Evaluation Indicators
4.1.1. Experimental Environment
Table 1 displays the experimental setups employed in the research.
Table 1.
Experimental platform.
4.1.2. Datasets
This paper employs the iVision-MRSSD dataset, initially proposed by Farhan et al. [37]. iVision-MRSSD is a robust, thoroughly annotated SAR ship detection dataset that boasts a collection of 11,590 images and their corresponding label files. These images have been meticulously gathered from six unique spaceborne sensors and cover a wide array of nearshore and offshore environments, all in different conditions. The dataset is divided into three parts: training, validation, and testing, with a distribution of 70% for training, 20% for validation, and 10% for testing.
4.1.3. Evaluation Indicators
To evaluate the effectiveness of YOLO-PFA, three key performance metrics are introduced: precision, recall, and mean average precision. These metrics are derived from four components: True Positives (TP), False Positives (FP), True Negatives (TN), and False Negatives (FN). TP refers to positive samples correctly predicted as ships, while FP denotes positive samples incorrectly predicted as ships. TN represents negative samples correctly predicted as background, and FN indicates negative samples incorrectly predicted as background. Precision, denoted as P, has the mathematical expression:
The recall is expressed as R, and the mathematical expression is:
Average Precision, referred to as AP, here involves the function P(R) representing the precision–recall curve, with its mathematical expression:
Mean Average Precision (mAP) is used to measure the detection performance of the model for all types of ships. This study utilizes mAP@0.5 as a comprehensive metric to evaluate the overall performance of the model, and its calculation formula is shown as follows. In addition, in this formula, Pi represents the detection precision of the i-th type of ship. However, the dataset used in the experiments only includes one category, namely “ship”. Therefore, Pi in this paper specifically refers to the detection precision of the “ship” category.
4.2. Experimental Results
4.2.1. Ablation Experimental Results and Analysis
The key parameter configurations utilized during the model training process are detailed in Table 2.
Table 2.
Parameter settings.
To gauge the effectiveness of each module in the proposed method, we gradually added these modules to the baseline network and implemented ablation experiments based on the iVision-MRSSD dataset. The baseline network employed herein is YOLOv11n. Table 3 exhibits the experimental outcomes, with “√” signifying the implementation of the respective improvement strategy. These ablation experiments were performed under identical configuration environments, and the results demonstrate that the application of these improvement strategies can effectively enhance detection capability and accuracy.
Table 3.
Results of ablation experiment.
As illustrated in Table 3, the ablation experiments elucidate the optimization mechanisms of the DADH, BiFPN, and C2f-PFA modules within the YOLOv11 model. The data indicates that when the DADH module is introduced independently, Recall increases by 2.3% compared to the baseline model, with mAP@0.5 rising by 0.7%. This module effectively maps features to distinct subspaces through Task Decomposition and dynamically adjusts the receptive field using DCNv2, significantly enhancing localization accuracy for small targets while reducing parameters to 2.17M. The implementation of BiFPN alone strengthens information fusion among multi-scale features; however, due to information overlap during feature fusion, redundant information is not adequately suppressed. Furthermore, the fixed weight mechanism may result in an imbalance in weight distribution between low-level localization features and high-level semantic features, leading to less precise detection outcomes. Consequently, this results in a slight decrease in mAP@0.5 as well as Precision and Recall metrics; nevertheless, it does yield an increase of 0.4% in mAP@0.5:0.95. The C2f-PFA module extracts hierarchical features via its PFA sub-module’s multi-scale convolution method and incorporates residual connections to enhance the backbone network’s multi-receptive field representation capability—boosting Recall by 0.7%. However, since the linear residual connection component does not fully activate non-linear mapping capabilities, there may be limitations on feature fusion efficiency across different scales, which restrict substantial improvements in mAP@0.5 performance levels. This observation further suggests that merely enhancing local expressive abilities within the backbone cannot sufficiently elevate overall model performance without synergistic collaboration with other modules.
When conducting ablation experiments on pairwise combinations of the above modules, the DADH-BiFPN ensemble achieves an 88.7% Recall, indicating that the DADH module enhances spatial sensitivity while BiFPN supplements cross-scale fusion capability. Despite a slight drop in Precision, the overall mAP@0.5 remains stable, demonstrating the complementarity of these two modules. The DADH-C2f-PFA combination exhibits excellent performance in boosting Precision and mAP@0.5. DADH provides stronger decoupled detection capability, and C2f-PFA enhances the information extraction ability of the backbone network; their integration effectively improves the detector’s target discrimination and boundary regression accuracy. The BiFPN-C2f-PFA combination also shows complementary effects: the hierarchical features from C2f-PFA supply higher-quality inputs to BiFPN, while BiFPN’s bidirectional connections compensate for C2f-PFA’s deficiencies in high-level semantic transmission, resulting in a 0.9% improvement in the mAP@0.5:0.95 metric.
The ablation experiments in this section demonstrate that the combined use of the DADH, BiFPN, and C2f-PFA modules maximizes their synergistic advantages, significantly boosting the overall performance of the YOLOv11 model in object detection tasks—most notably achieving an optimal balance between mAP and Recall. Their collaborative mechanisms are as follows: the DADH module provides accurate decoupled detection structure and dynamic receptive field; BiFPN realizes efficient and weighted information fusion between the features of each layer; and C2f-PFA enhances the multi-scale expressive capacity of the backbone network. Together, they optimize information flow at three critical stages—the detection head, feature fusion, and backbone network, forming an end-to-end feature enhancement loop, achieving the optimal overall performance while keeping the parameter count nearly flat.
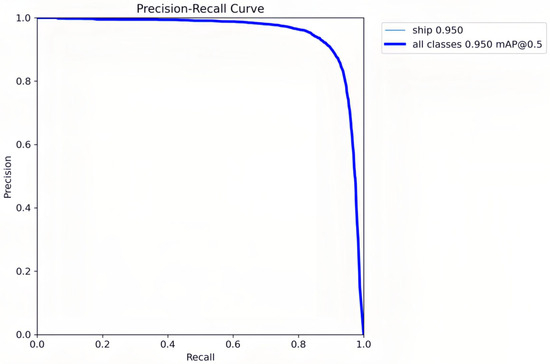
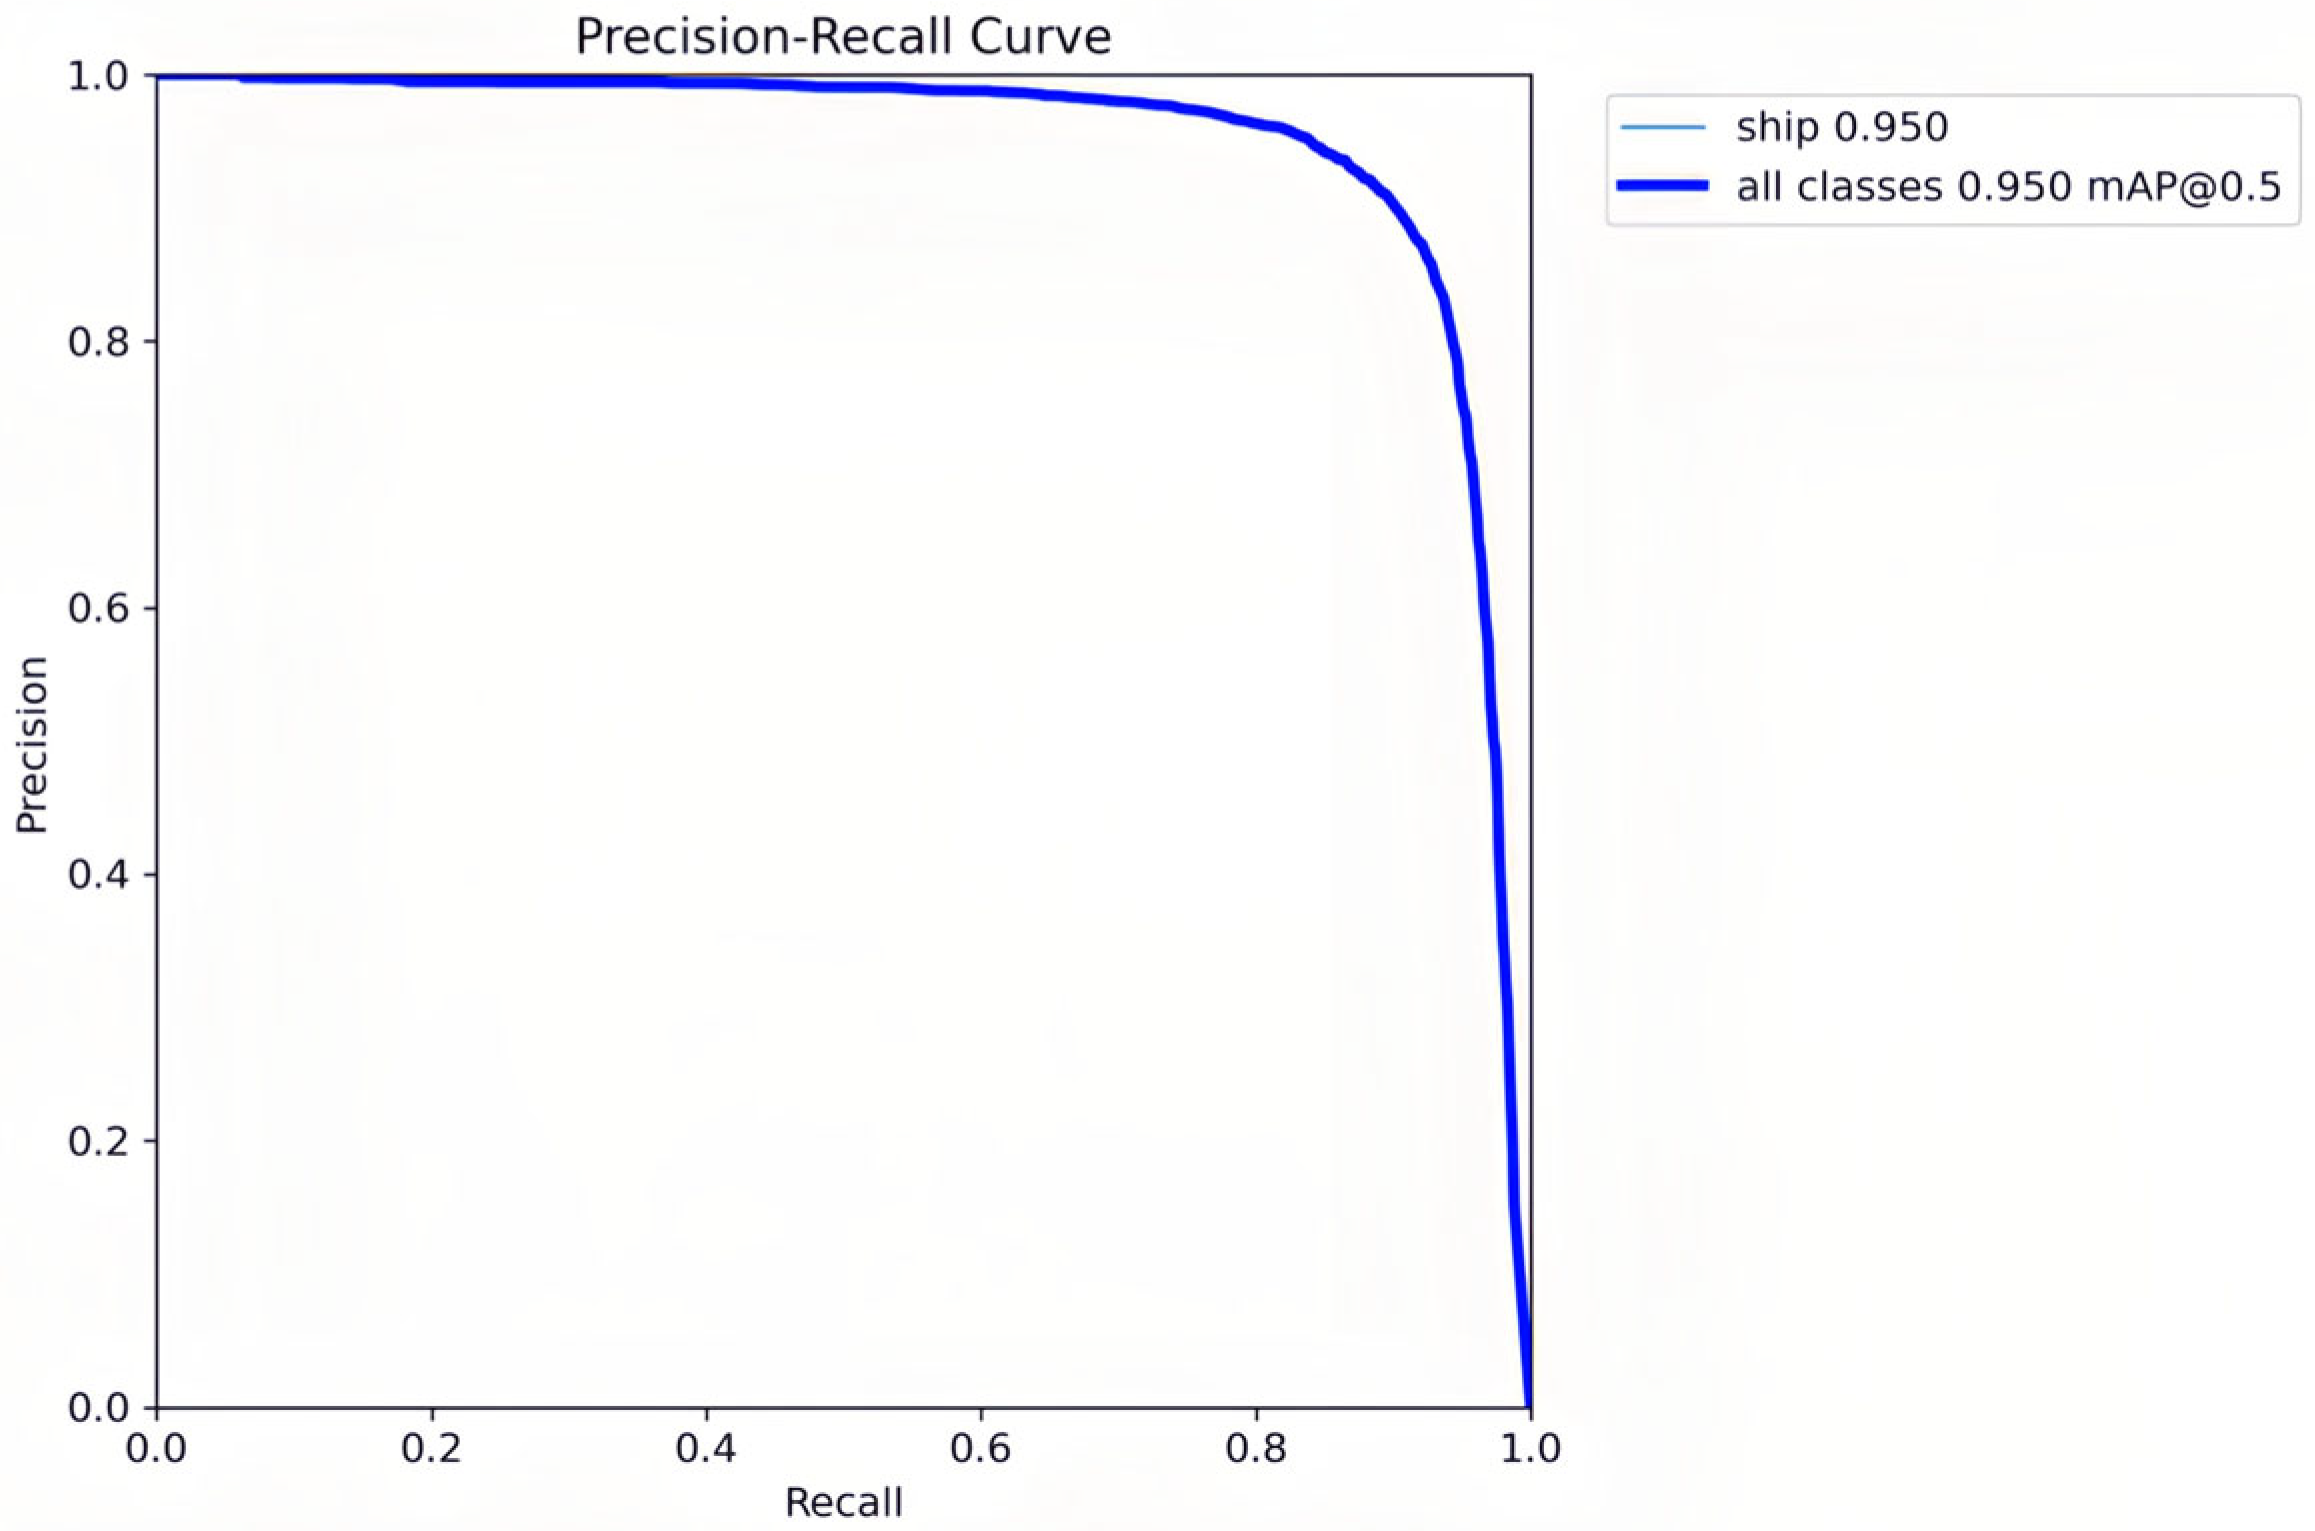
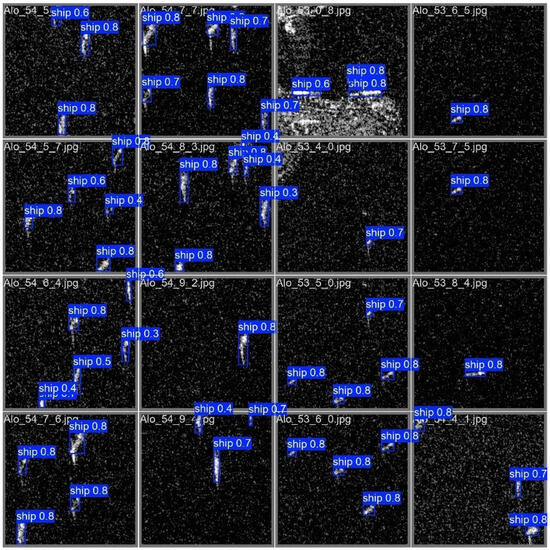
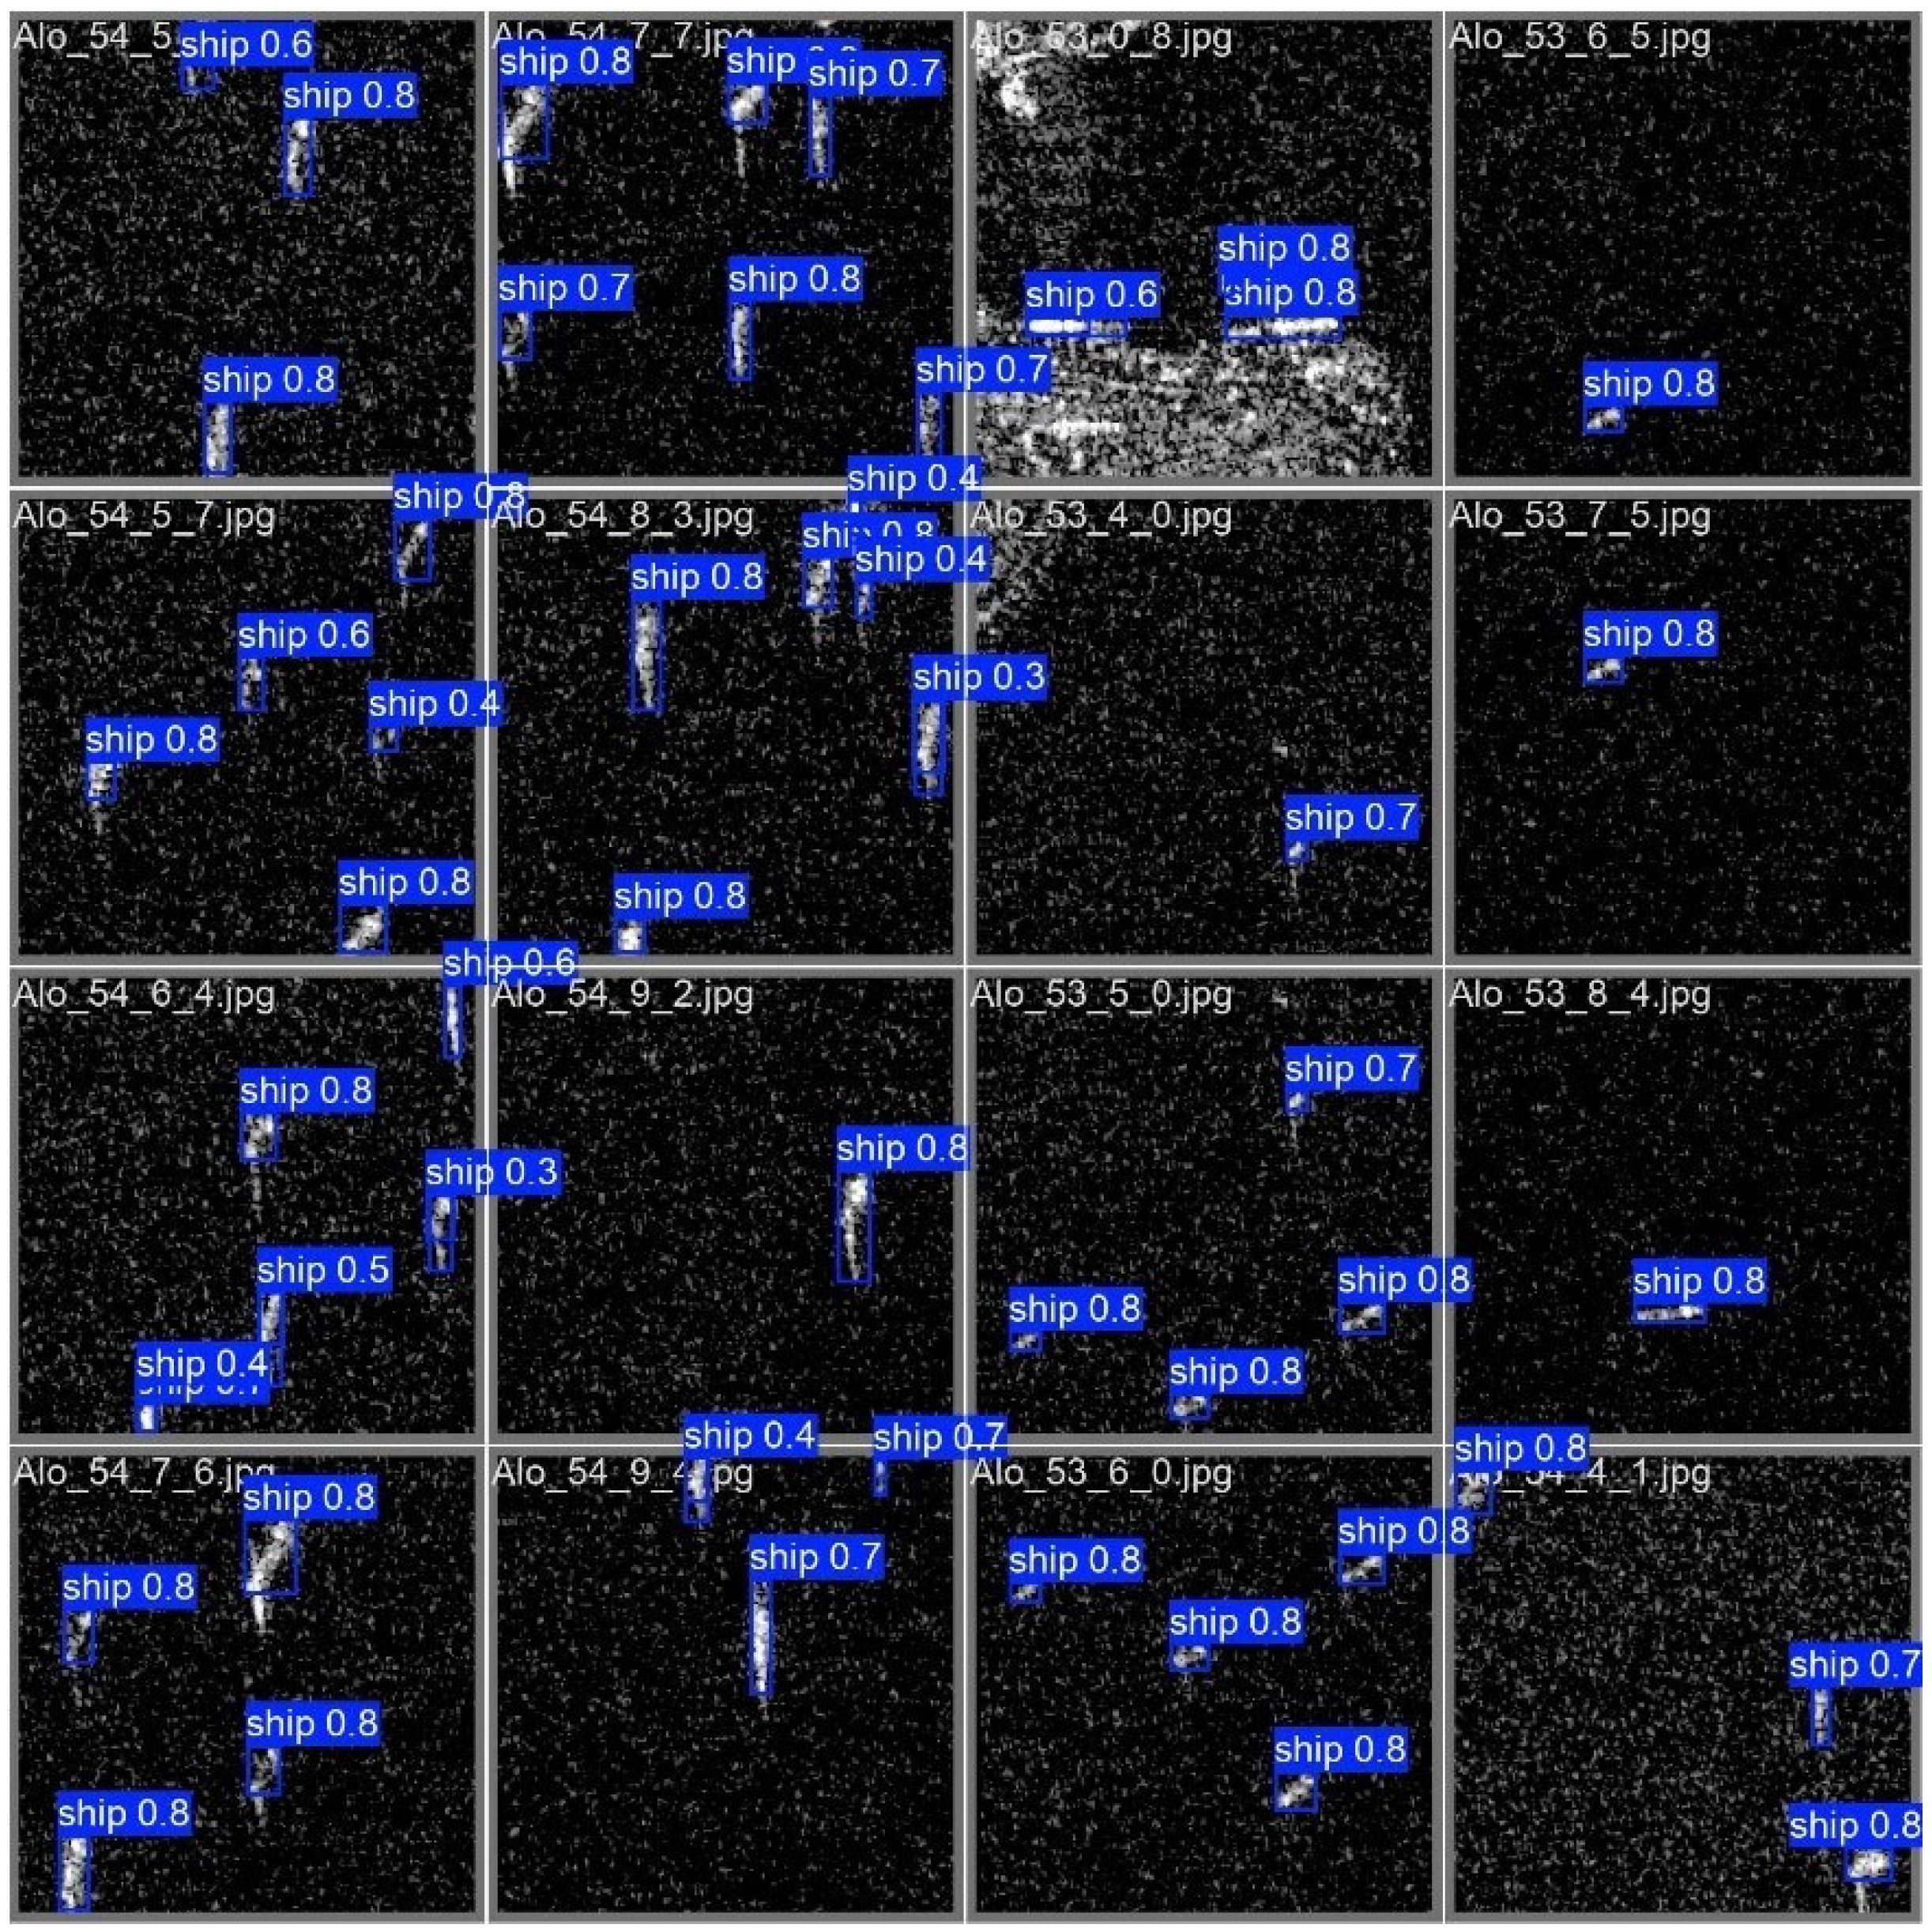
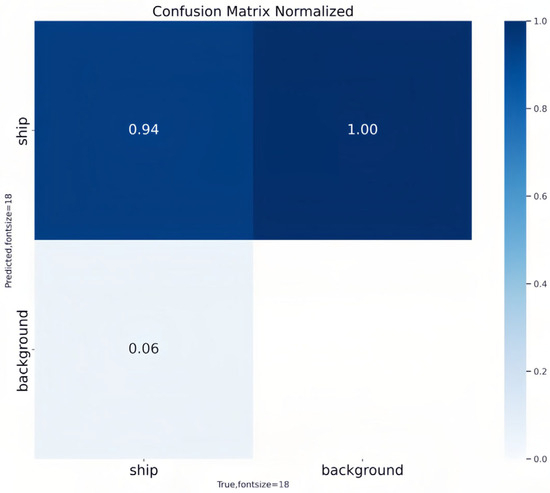
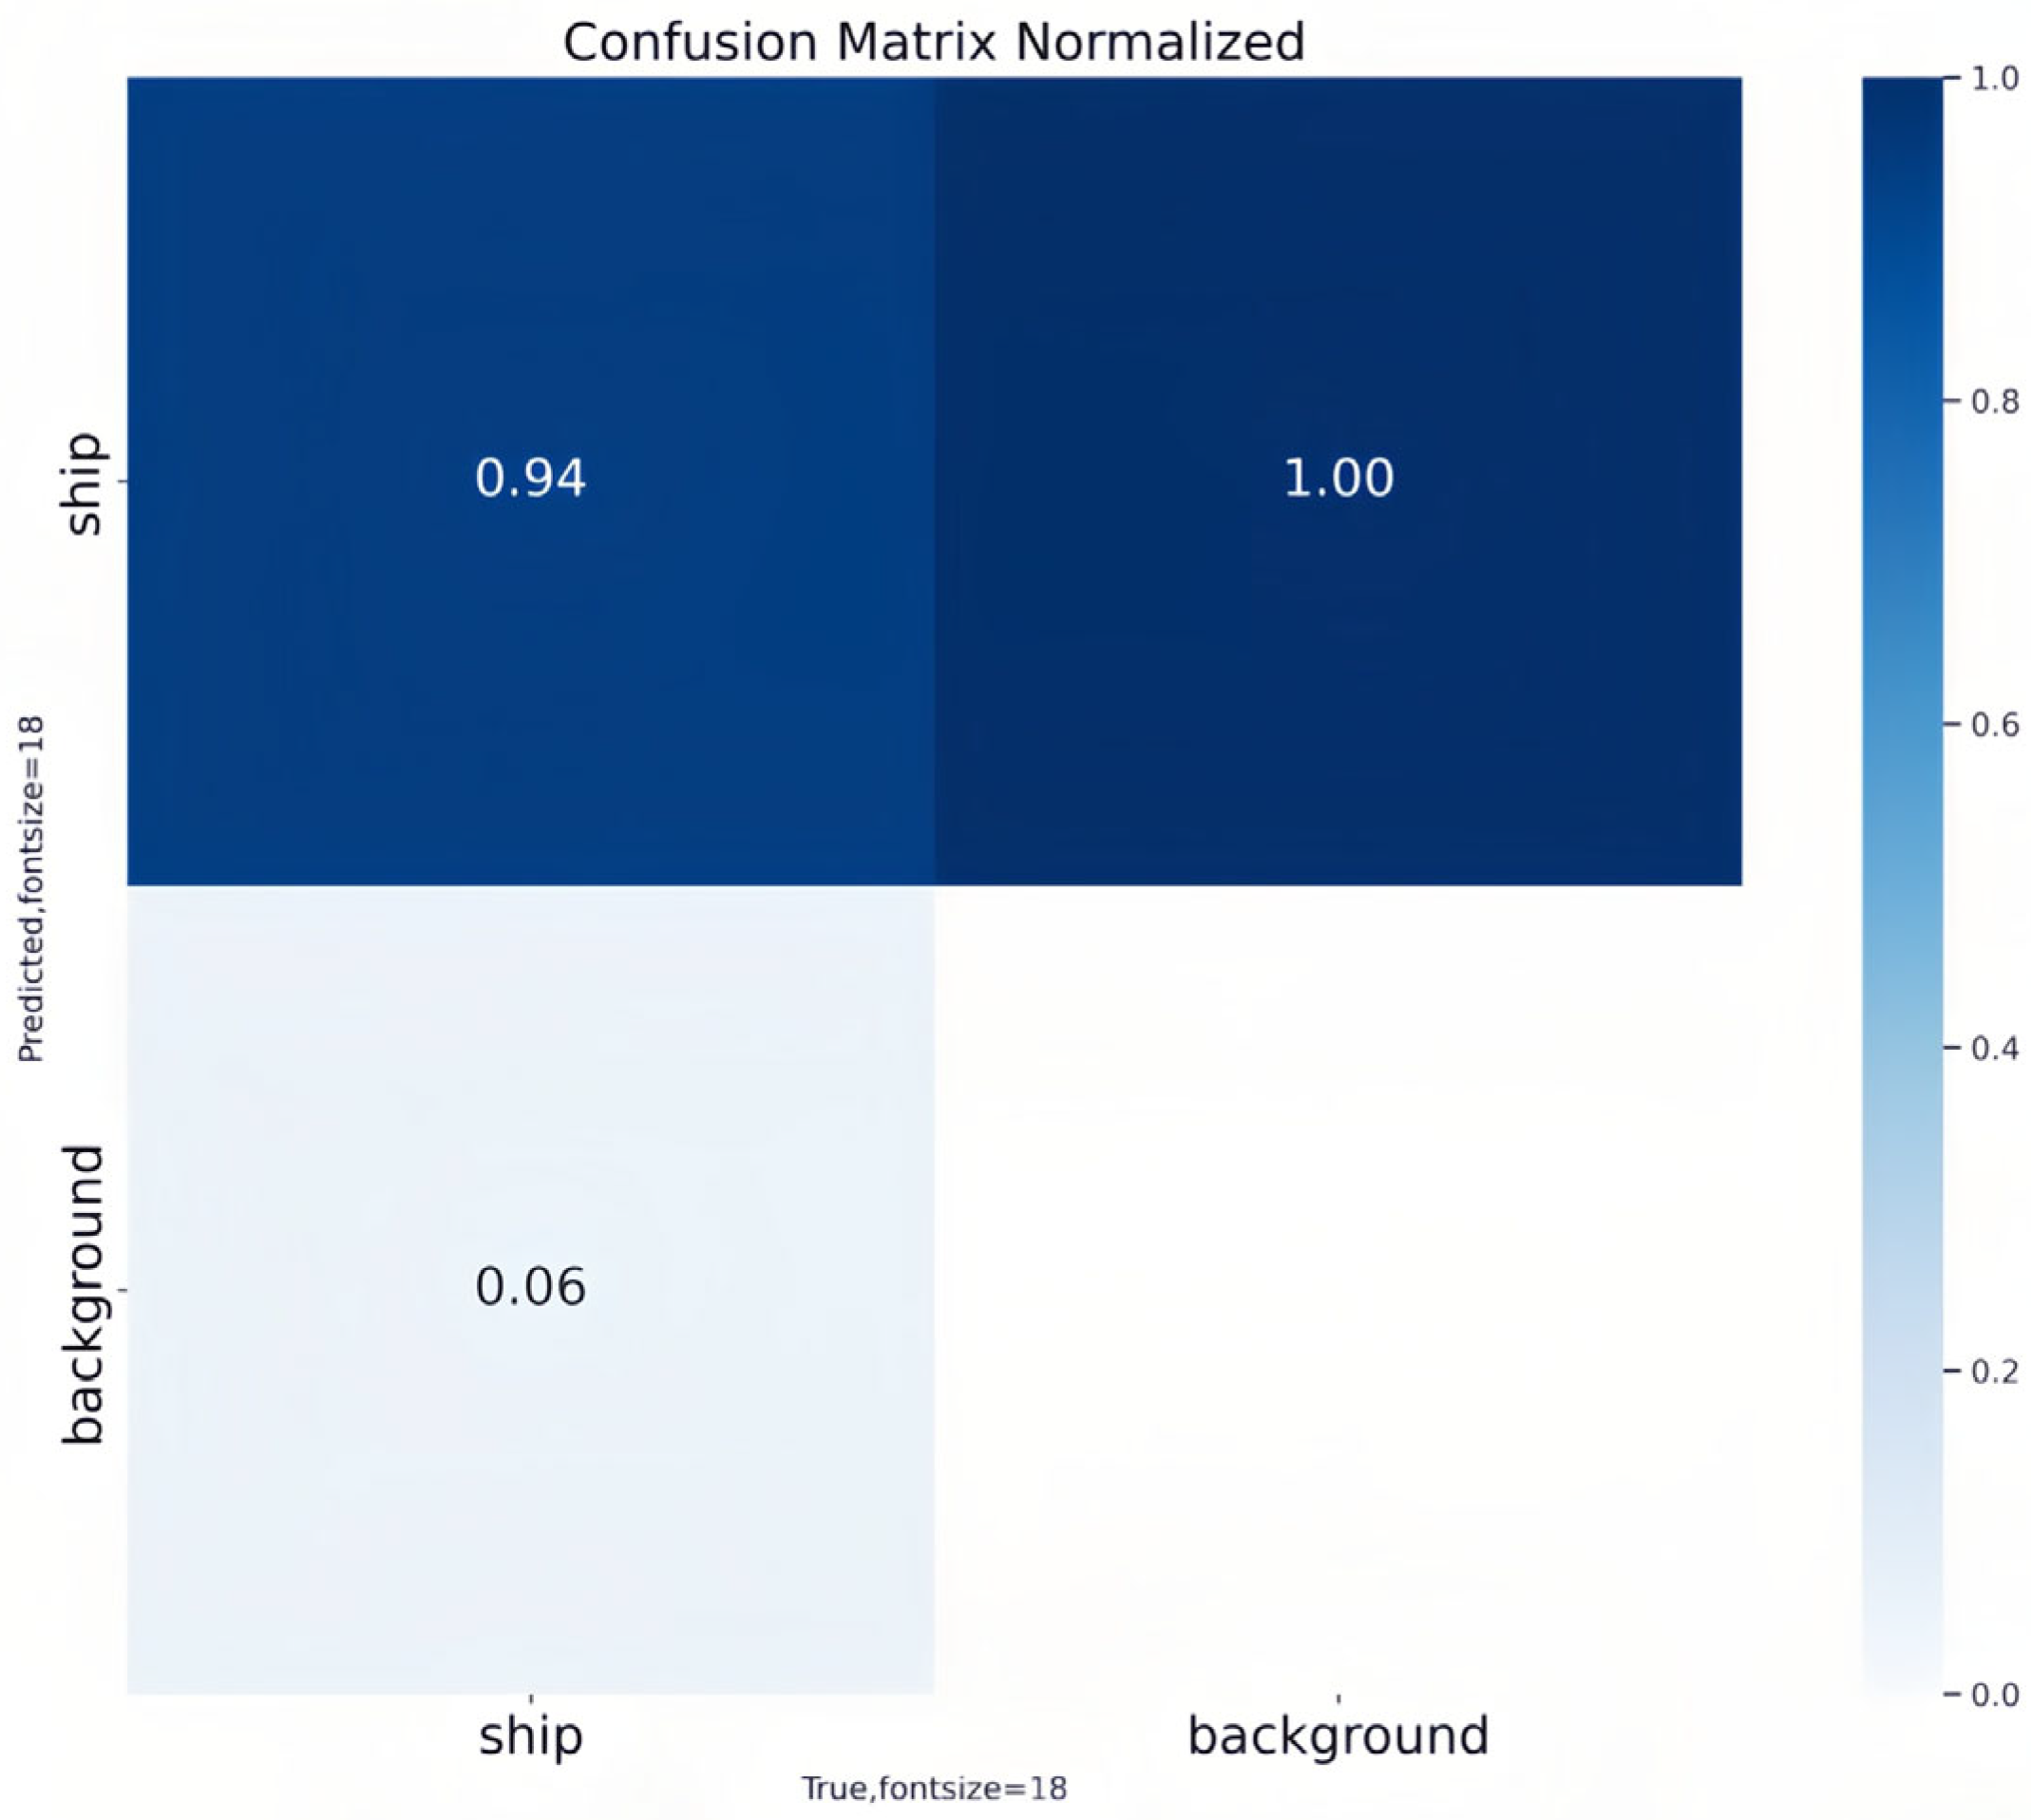
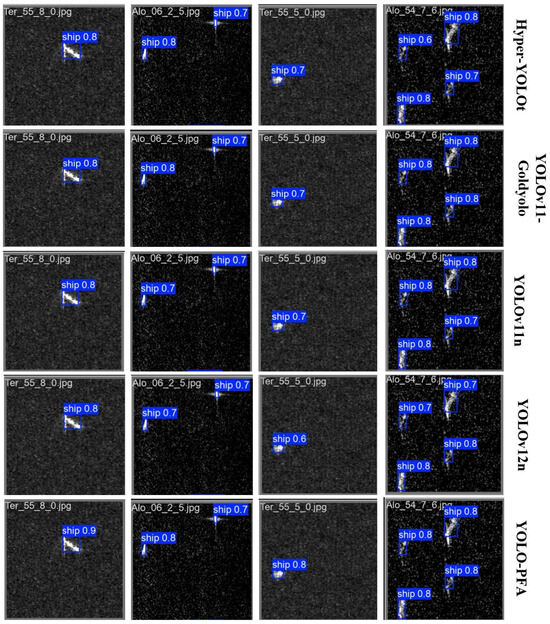
Figure 6 presents the precision–recall (PR) curve for the “ship” category in the iVision-MRSSD dataset, illustrating the magnitude of average precision. Figure 7 displays the visualization results of detections within the dataset, where blue bounding boxes and corresponding confidence scores (e.g., “ship 0.8”) represent the detected ships and their confidence levels, respectively. The results reveal that our model network exhibits excellent capability in capturing and detecting ships with small scales and complex postures. Figure 8 presents the normalized confusion matrix for YOLO-PFA, illustrating the model’s classification accuracy in ship detection tasks. As indicated in the figure, the model achieves favorable classification results for ships and backgrounds, with a 94% correct recognition rate for ships and 100% for backgrounds, featuring only a small number of cases where backgrounds are mistakenly classified as ships.
Figure 6.
The P-R curve.
Figure 7.
Visualization of detection results of YOLO-PFA on the iVision-MRSSD dataset.
Figure 8.
Confusion matrix for YOLO-PFA network model.
4.2.2. Comparative Experiments
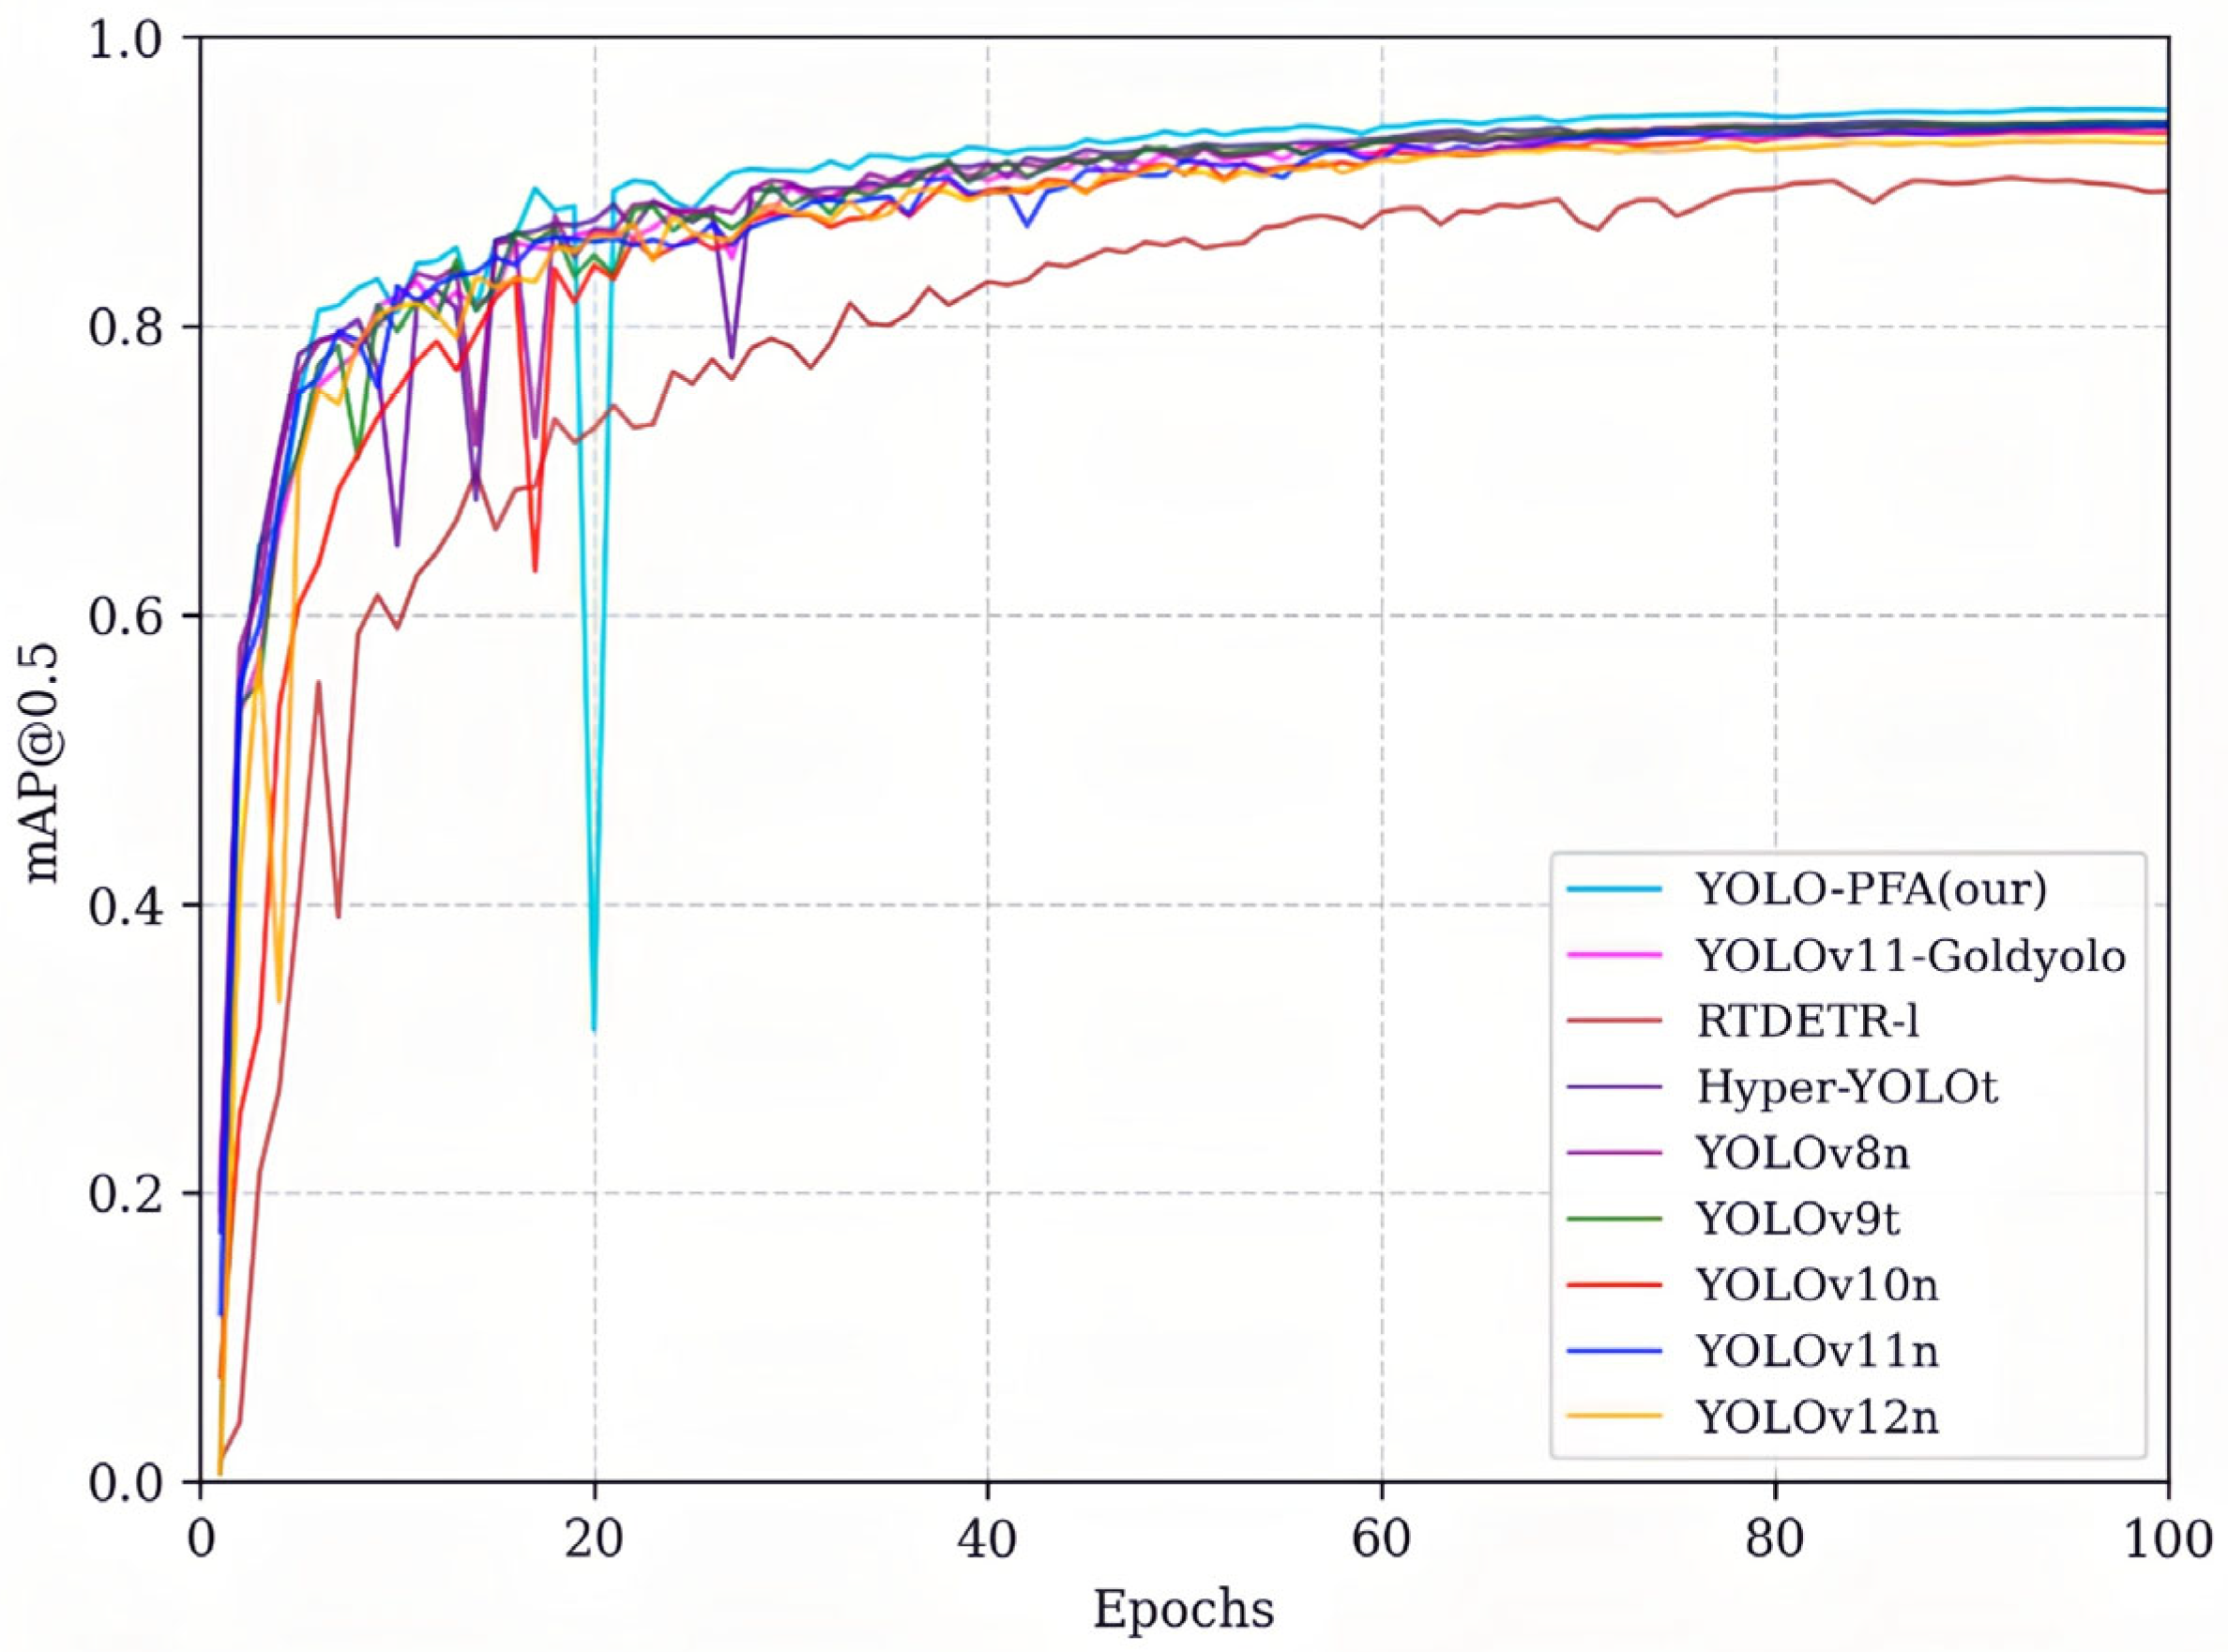
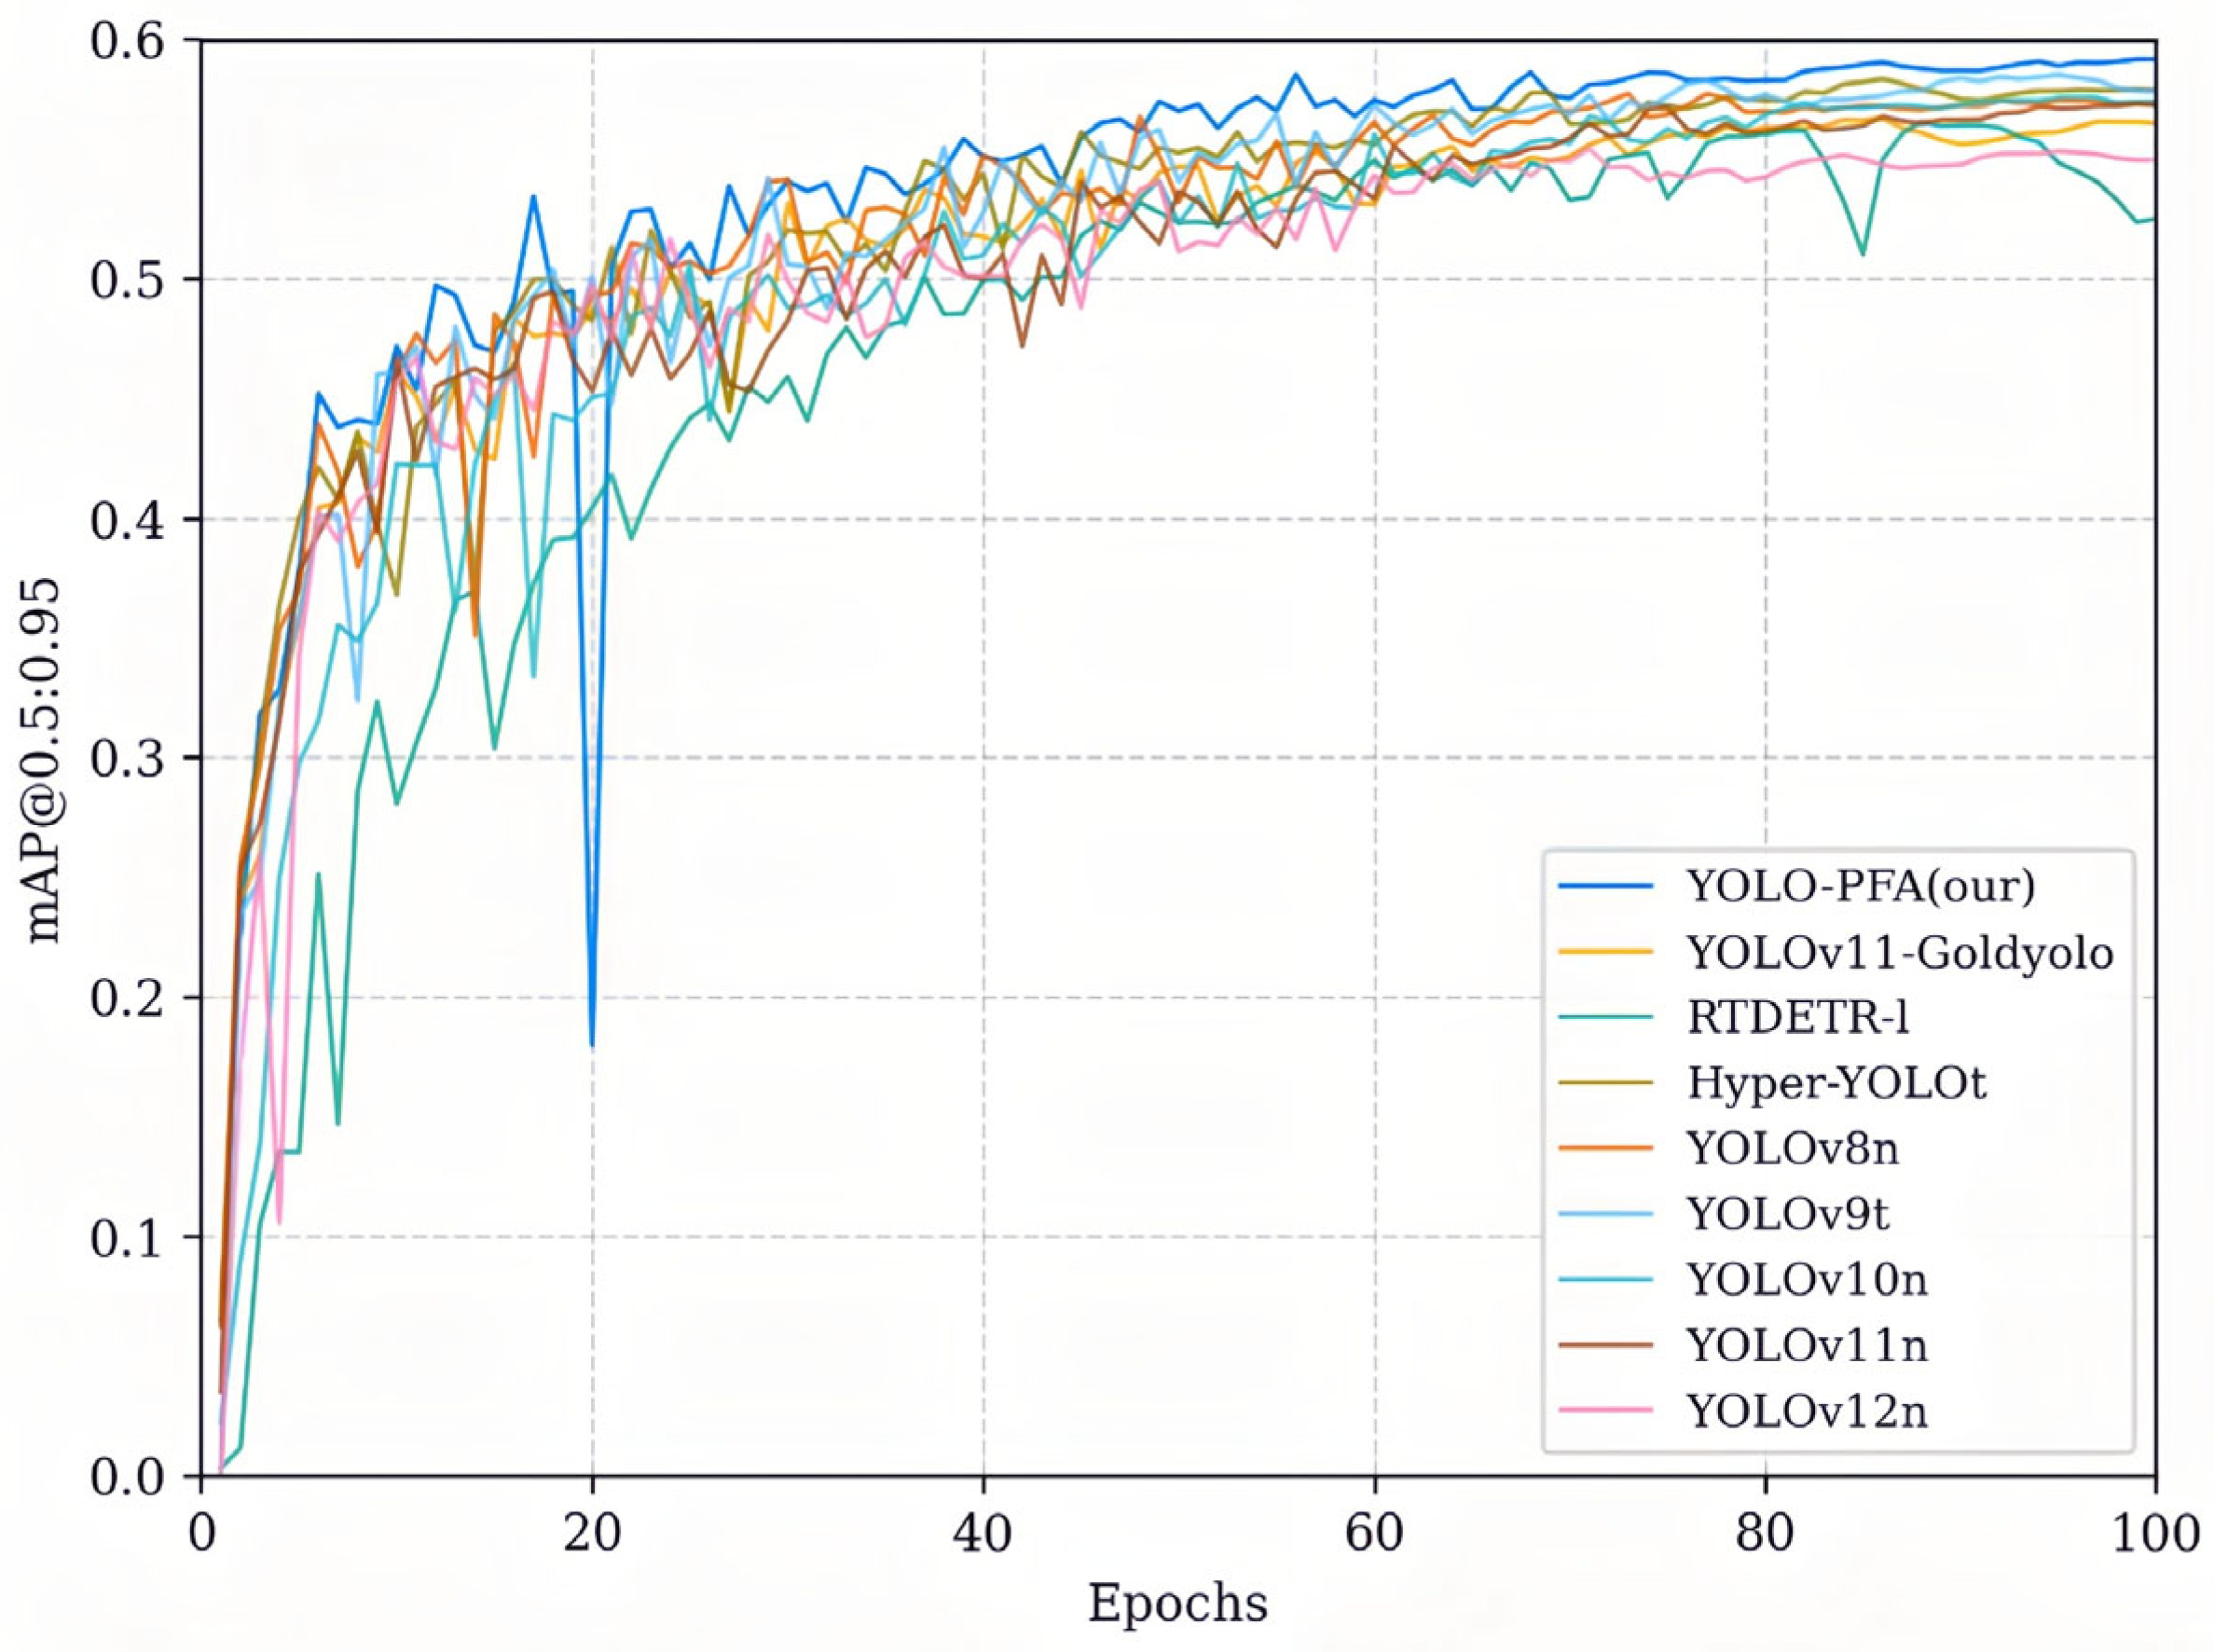
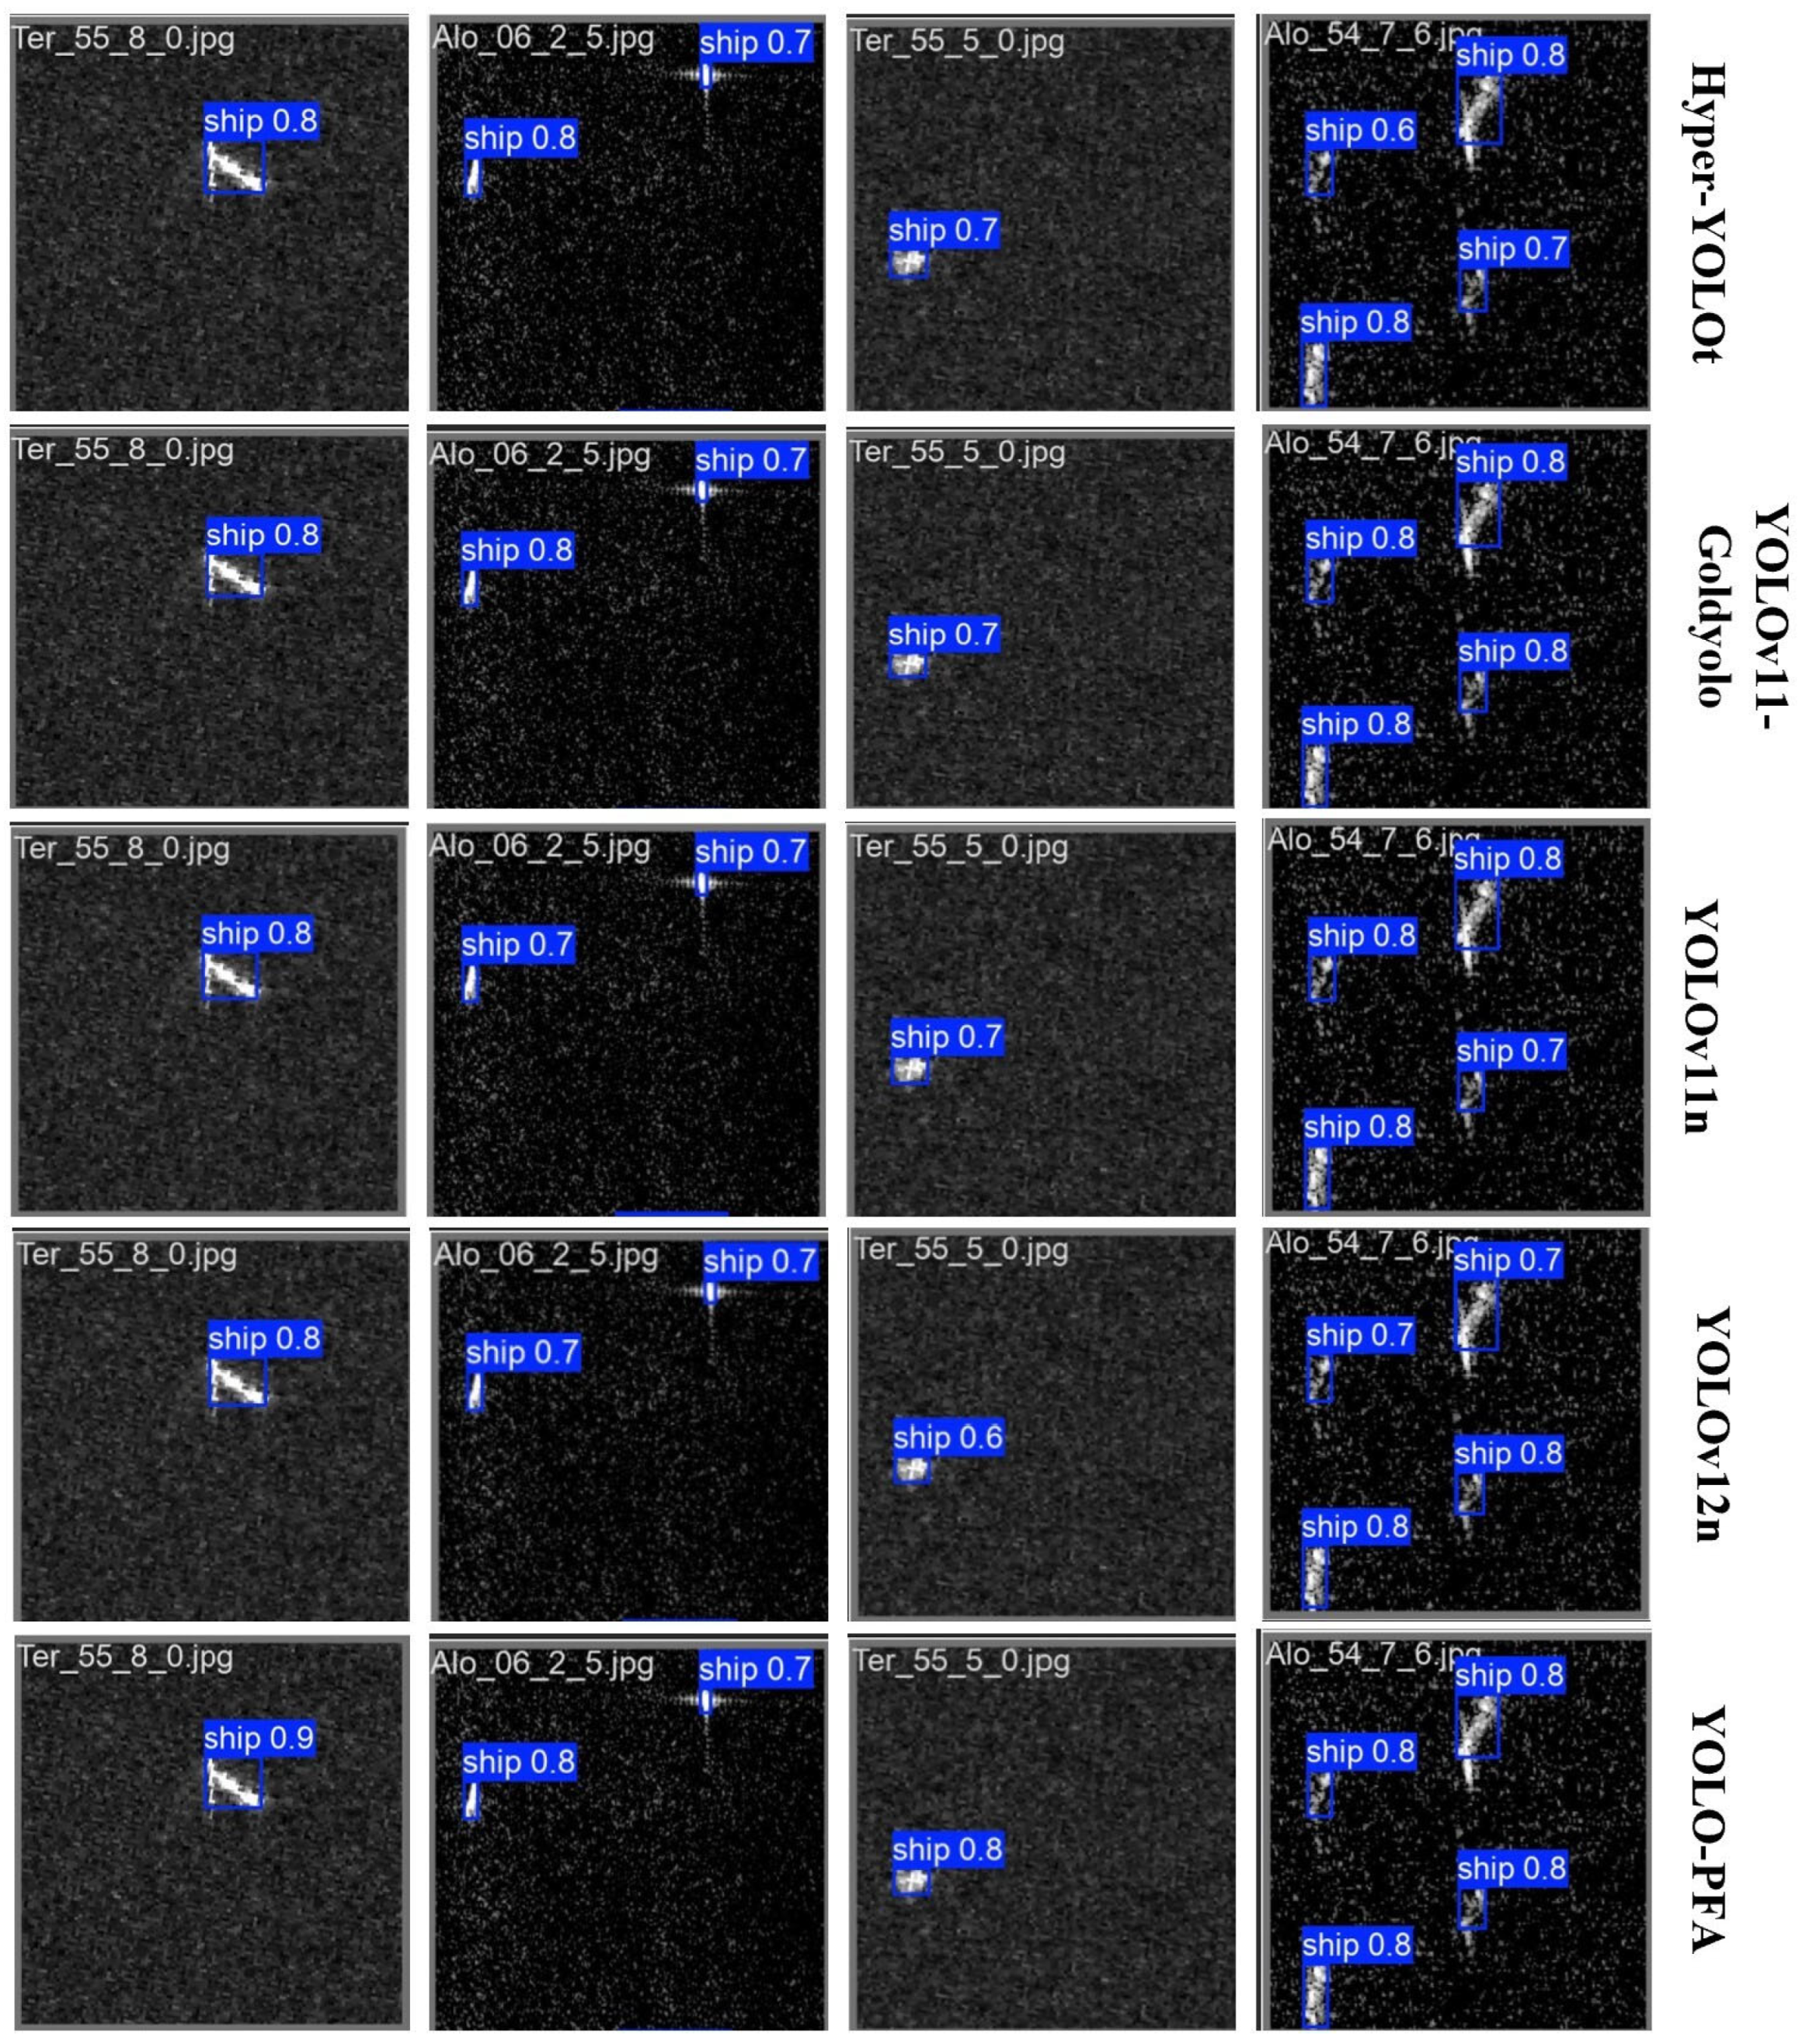
To validate the performance advantages of YOLO-PFA over other object detection models, we conducted comparative experiments against YOLOv8, YOLOv9, YOLOv10, YOLOv11-GoldYOLO, Hyper-YOLO, YOLOv11, YOLOv12, and RT-DETR networks, using the same dataset and evaluation metrics. The results, presented in Table 4, show that in terms of accuracy, YOLO-PFA achieves a 95% mAP@0.5, outperforming YOLOv10 [10] and YOLOv12 [11] by 1.6% and 2.8%, respectively. In the comparative tests, we integrated the Gold-YOLO algorithm [33] into YOLOv11, and the findings indicate that YOLOv11-GoldYOLO lags behind YOLO-PFA in both accuracy and parameter efficiency. Additionally, we compared YOLO-PFA with RT-DETR, an advanced model based on the DEtection TRansformer (DETR) architecture. The results indicate that RT-DETR has significantly more parameters and performs worse across all detection metrics. Furthermore, besides a 1.2% increase in mAP@0.5 compared to the baseline model, YOLO-PFA shows improvements in other metrics such as P, R, and mAP@0.5:0.95, and is significantly superior to other models. Figure 9 and Figure 10 illustrate the performance of each model in terms of mAP@0.5 and mAP@0.5:0.95, respectively. It is evident that YOLO-PFA outperforms the other models significantly, achieving the highest overall performance.
Table 4.
Results of comparison experiments.
Figure 9.
Comparison curve of mAP@0.5 among various models.
Figure 10.
Comparison curve of mAP@0.5:0.95 among various models.
As shown in Figure 11, the visualization results of YOLO-PFA and other detection algorithms for the same targets on the iVision-MRSSD dataset are presented. It can be observed that YOLO-PFA achieves better recognition performance for the same targets compared with other detection methods.
Figure 11.
Multiple object detection algorithms comparison results.
5. Conclusions
In this paper, we propose a novel network model, YOLO-PFA, designed for ship detection in complex marine environments. Specifically, we introduce the BiFPN architecture to facilitate cross-scale weighted feature fusion, enabling the network to adaptively adjust the contribution of features at various levels. This significantly enhances its capability to capture targets of differing sizes. In the detection head, we implement the Dynamic Alignment Detection Head (DADH), which constructs a feature interaction mechanism based on a multi-module collaborative design. This approach allows for dynamic alignment optimization of classification and regression features. Consequently, the model can dynamically select interactive features, thereby improving target recognition accuracy while simultaneously reducing parameters to some extent. The proposed C2f-PFA feature aggregation module overcomes the limitations associated with traditional feature processing methods that rely on “simple concatenation of original and deep features”. Instead, it aggregates original detailed features with those processed through multiple layers. This effectively addresses information loss during feature transmission and enhances both efficiency and stability in feature extraction. Experimental validation conducted on the SAR ship detection dataset iVision-MRSSD demonstrates that YOLO-PFA achieves an mAP@0.5 that is 1.2% higher than that of the YOLOv11. Additionally, Precision, Recall, and mAP@0.5:0.95 improve by 0.6%, 3.4%, and 1.7%, respectively. Furthermore, YOLO-PFA outperforms other comparative models by achieving optimal overall performance.
Although the network model we designed performs better in terms of accuracy metrics, it still has shortcomings in real-time performance and scenario adaptability. Therefore, future research can focus on two aspects. For enhancing the model’s lightweight nature, we can start with structured pruning, knowledge distillation, and low-bit quantization techniques to reduce the model size and computational cost while ensuring performance. For improving adaptability to different scenarios, we can strengthen the model’s robustness and generalization to scenarios such as complex weather and illumination through multi-environment data augmentation, domain adaptation algorithms, and dynamic modular design, where adversarial training can be used to implement domain adaptation algorithms.
Author Contributions
Methodology, P.L.; Validation, M.S.; Data curation, Z.W.; Writing—original draft, S.L.; Writing—review & editing, P.H. All authors have read and agreed to the published version of the manuscript.
Funding
This research was financially supported by Yantai City 2023 School-Land Integration Development Project Fund (No.2323013-2023XDRH001), the Science and Technology-based Small and Medium-sized Enterprise Innovation Capacity Enhancement Project of Yantai City (No. 2023TSGC112), Shandong Provincial Science and Technology-based Small and Medium-sized Enterprises Innovation Capability Enhancement Engineering Plan Project (2023TSGC0823), Qingdao West Coast Principal Fund (XZJJZY01,GXXZJJ202302), and Open Project of State Key Laboratory of Process Industry Integrated Automation, Northeastern University( SAPI-2024-KFKT08, SAPI-2024-KFKT-09).
Data Availability Statement
The authors declare that the data supporting the findings of this study are from publicly available datasets. Further inquiries can be directed to the corresponding author according to reasonable requirements.
Conflicts of Interest
All the authors declare they have no financial interests.
References
- Fu, H.; Song, G.; Wang, Y. Improved YOLOv4 Marine Target Detection Combined with CBAM. Symmetry 2021, 13, 623. [Google Scholar] [CrossRef] [Scilit]
- Yang, J.; Ran, L.; Dang, J.; Wang, Y.; Qu, Z. Deeper Multiscale Encoding–Decoding Feature Fusion Network for Change Detection of VHR Images. IEEE Geosci. Remote Sens. Lett. 2023, 20, 6012105. [Google Scholar] [CrossRef] [Scilit]
- Li, Q.; Zhang, W.; Li, M.; Niu, J.; Wu, Q.J. Automatic detection of ship targets based on wavelet transform for HF surface wavelet radar. IEEE Geosci. Remote Sens. Lett. 2017, 14, 714–718. [Google Scholar] [CrossRef] [Scilit]
- Golubović, D.; Erić, M.; Vukmirović, N.; Orlić, V. High-Resolution Sea Surface Target Detection Using Bi-Frequency High-Frequency Surface Wave Radar. Remote Sens. 2024, 16, 3476. [Google Scholar] [CrossRef] [Scilit]
- Zhang, W.; Li, Q.; Wu, Q.J.; Li, M. Sea surface target detection for RD images of HFSWR based on optimized error self-adjustment extreme learning machine. Acta Autom. Sin. 2019, 47, 108–120. [Google Scholar]
- Ren, S.; He, K.; Girshick, R.; Sun, J. Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks. IEEE Trans. Pattern Anal. Mach. Intell. 2016, 39, 1137–1149. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- He, K.; Gkioxari, G.; Dollár, P.; Ross, G. Mask r-cnn. In Proceedings of the IEEE International Conference on Computer Vision, Venice, Italy, 22–29 October 2017; pp. 2961–2969. [Google Scholar]
- Yang, G.; Feng, W.; Jin, J.; Lei, Q.; Li, X.; Gui, G.; Wang, W. Face mask recognition system with YOLOv5 based on image recognition. In Proceedings of the 2020 IEEE 6th International Conference on Computer and Communications (ICCC), Chengdu, China, 11–14 December 2020; pp. 1398–1404. [Google Scholar]
- Li, C.; Li, L.; Jiang, H.; Weng, K.; Geng, Y.; Li, L.; Ke, Z.; Li, Q.; Cheng, M.; Nie, W.; et al. YOLOv6: A single-stage object detection framework for industrial applications. arXiv 2022, arXiv:2209.02976. [Google Scholar] [CrossRef] [Scilit]
- Wang, A.; Chen, H.; Liu, L.; Chen, K.; Lin, Z.; Han, J. YOLOv10: Real-Time End-to-End Object Detection. Adv. Neural Inf. Process. Syst. 2024, 37, 107984–108011. [Google Scholar]
- Tian, Y.; Ye, Q.; Doermann, D. Yolov12: Attention-centric real-time object detectors. arXiv 2025, arXiv:2502.12524. [Google Scholar]
- Huang, Q.; Sun, H.; Wang, Y.; Yuan, Y.; Guo, X.; Gao, Q. Ship Detection Based on YOLO Algorithm for Visible Images. IET Image Process. 2024, 18, 481–492. [Google Scholar] [CrossRef] [Scilit]
- Zou, Z.; Chen, K.; Shi, Z.; Guo, Y.; Ye, J. Object Detection in 20 Years: A Survey. Proc. IEEE 2023, 111, 257–276. [Google Scholar] [CrossRef] [Scilit]
- Liu, W.; Anguelov, D.; Erhan, D.; Liu, W.; Anguelov, D.; Erhan, D.; Szegedy, C.; Reed, S.; Fu, C.Y.; Berg, A.C. Ssd: Single shot multibox detector. In Proceedings of the Computer Vision–ECCV 2016: 14th European Conference, Amsterdam, The Netherlands, 11–14 October 2016; Proceedings, Part I 14. Springer International Publishing: Cham, Switzerland, 2016; pp. 21–37. [Google Scholar]
- Duan, K.; Bai, S.; Xie, L.; Qi, H.; Huang, Q.; Tian, Q. Centernet: Keypoint triplets for object detection. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Seoul, Republic of Korea, 27 October–2 November 2019; pp. 6569–6578. [Google Scholar]
- Cheng, S.; Zhu, Y.; Wu, S. Deep Learning Based Efficient Ship Detection from Drone-Captured Images for Maritime Surveillance. Ocean Eng. 2023, 285, 115440–115446. [Google Scholar] [CrossRef] [Scilit]
- Chen, Z.; Liu, C.; Filaretov, V.F.; Yukhimets, D.A. Multi-Scale Ship Detection Algorithm Based on YOLOv7 for Complex Scene SAR Images. Remote Sens. 2023, 15, 2071. [Google Scholar] [CrossRef] [Scilit]
- Liu, Y.; Yang, D.; Song, T.; Ye, Y.; Zhang, X. YOLO-SSP: An Object Detection Model Based on Pyramid Spatial Attention and Improved Downsampling Strategy for Remote Sensing Images. Vis. Comput. 2025, 41, 1467–1484. [Google Scholar] [CrossRef] [Scilit]
- Luo, Y.; Li, M.; Wen, G.; Tan, Y.; Shi, C. SHIP-YOLO: A Lightweight Synthetic Aperture Radar Ship Detection Model Based on YOLOv8n Algorithm. IEEE Access 2024, 12, 37030–37041. [Google Scholar] [CrossRef] [Scilit]
- Zhou, F.; Yang, T.; Tan, L.; Xu, X.; Xing, M. DAP-Net: Enhancing SAR Target Recognition with Dual-Channel Attention and Polarimetric Features. Vis. Comput. 2025, 41, 7641–7656. [Google Scholar] [CrossRef] [Scilit]
- Shen, Y.; Gao, Q. DS-YOLO: A SAR Ship Detection Model for Dense Small Targets. Radioengineering 2025, 34, 407–421. [Google Scholar] [CrossRef] [Scilit]
- Tan, M.; Pang, R.; Le, Q.V. Efficientdet: Scalable and efficient object detection. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, Seattle, WA, USA, 13–19 June 2020; pp. 10781–10790. [Google Scholar]
- Gu, J.; Pan, Y.; Zhang, J. Deep Learning-Based Intelligent Detection Algorithm for Surface Disease in Concrete Buildings. Buildings 2024, 14, 3058. [Google Scholar] [CrossRef] [Scilit]
- Jiang, J.; Fu, X.; Qin, R.; Wang, X.; Ma, Z. High-Speed Lightweight Ship Detection Algorithm Based on YOLO-V4 for Three-Channel RGB SAR Image. Remote Sens. 2021, 13, 1909. [Google Scholar] [CrossRef] [Scilit]
- Leng, X.; Ji, K.; Yang, K.; Zou, H. A Bilateral CFAR Algorithm for Ship Detection in SAR Images. IEEE Geosci. Remote Sens. Lett. 2015, 12, 1536–1540. [Google Scholar] [CrossRef] [Scilit]
- Liao, M.; Wang, C.; Wang, Y.; Jiang, L. Using SAR Images to Detect Ships from Sea Clutter. IEEE Geosci. Remote Sens. Lett. 2008, 5, 194–198. [Google Scholar] [CrossRef] [Scilit]
- Zhou, K.; Zhang, M.; Wang, H.; Tan, J. Ship Detection in SAR Images Based on Multi-Scale Feature Extraction and Adaptive Feature Fusion. Remote Sens. 2022, 14, 755. [Google Scholar] [CrossRef] [Scilit]
- Zhang, T.; Zhang, X. High-Speed Ship Detection in SAR Images Based on a Grid Convolutional Neural Network. Remote Sens. 2019, 11, 1206. [Google Scholar] [CrossRef] [Scilit]
- Zwemer, M.H.; Wijnhoven, R.G.J.; de With Peter, H.N. Ship Detection in Harbour Surveillance based on Large-Scale Data and CNNs. In Proceedings of the VISIGRAPP (5: VISAPP), Funchal, Portugal, 27–29 January 2018; pp. 153–160. [Google Scholar]
- Lin, T.Y.; Dollár, P.; Girshick, R.; He, K.; Hariharan, B.; Belongie, S. Feature pyramid networks for object detection. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Honolulu, HI, USA, 21–26 July 2017; pp. 2117–2125. [Google Scholar]
- Liu, S.; Qi, L.; Qin, H.; Shi, J.; Jia, J. Path aggregation network for instance segmentation. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–23 June 2018; pp. 8759–8768. [Google Scholar]
- Xu, X.; Jiang, Y.; Chen, W.; Huang, Y.; Zhang, Y.; Sun, X. Damo-yolo: A report on real-time object detection design. arXiv 2022, arXiv:2211.15444. [Google Scholar]
- Wang, C.; He, W.; Nie, Y.; Guo, J.; Liu, C.; Wang, Y.; Han, K. Gold-YOLO: Efficient Object Detector via Gather-and-Distribute Mechanism. Adv. Neural Inf. Process. Syst. 2023, 36, 51094–51112. [Google Scholar]
- Wang, Y.; Jiang, Y.; Xu, H.; Xiao, C.; Zhao, K. Detection Method of Key Ship Parts Based on YOLOv11. Processes 2025, 13, 201. [Google Scholar] [CrossRef] [Scilit]
- Zhu, X.; Hu, H.; Lin, S.; Dai, J. Deformable convnets v2: More deformable, better results. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Long Beach, CA, USA, 15–20 June 2019; pp. 9308–9316. [Google Scholar]
- Dai, X.; Chen, Y.; Xiao, B.; Chen, D.; Liu, M.; Yuan, L.; Zhang, L. Dynamic head: Unifying object detection heads with attentions. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Nashville, TN, USA, 20–25 June 2021; pp. 7373–7382. [Google Scholar]
- Humayun, M.F.; Bhatti, F.A.; Khurshid, K. iVision MRSSD: A Comprehensive Multi-Resolution SAR Ship Detection Dataset for State of the Art Satellite Based Maritime Surveillance Applications. Data Brief 2023, 50, 109505–109508. [Google Scholar] [CrossRef] [Scilit] [PubMed]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).