


Abstract
Meteorological data from automatic weather stations (AWS) in tea plantations is critical for agricultural management, but is often compromised by sensor errors and physical implausibilities that traditional quality control (QC) methods fail to detect. This study proposes a novel, meteorologically informed QC framework that mines association rules from long-term ERA5 reanalysis data (2012–2023) using the Apriori algorithm to establish a knowledge base of normal multivariate atmospheric patterns. A comprehensive feature engineering process generated temporal, physical, and statistical features, which were discretized using meteorological thresholds. The mined rules were filtered, prioritized, and integrated with hard physical constraints. The system employs a fuzzy logic mechanism for violation assessment and a weighted anomaly scoring system for classification. When validated on a synthetic dataset with injected anomalies, the method significantly outperformed traditional QC techniques, achieving an F1-score of 0.878 and demonstrating a superior ability to identify complex physical inconsistencies. Application to an independent historical dataset from a Zhenjiang tea plantation (2008–2016) successfully identified 14.6% anomalous records, confirming the temporal transferability and robustness of the approach. This framework provides an accurate, interpretable, and scalable solution for enhancing the quality of meteorological data, with direct implications for improving the reliability of frost prediction and pest management in precision agriculture.
1. Introduction
Meteorological data is a critical asset in agricultural management, climate research, and environmental monitoring [1,2]. Accurate meteorological data is a prerequisite for reliable frost prediction models in tea plantations. This study focuses on ensuring the quality of this foundational data through a novel QC framework. The resulting high-quality dataset is positioned to enhance the reliability of subsequent frost risk assessments and other agricultural decision-support systems [3,4,5]. Automatic Weather Stations (AWS) deployed within agro-ecosystems provide this essential, high-resolution data. However, these stations are susceptible to sensor drift, calibration errors, and physical damage, often resulting in anomalous data that can severely undermine the reliability of downstream analyses and decisions [6,7]. Therefore, implementing robust and automated Quality Control (QC) procedures is paramount to ensuring the integrity of meteorological datasets.
Conventional QC methods for meteorological data predominantly rely on univariate checks, including physical range tests, internal consistency verification, and spatial comparisons with neighboring stations [8,9,10]. While effective at identifying gross errors (e.g., relative humidity exceeding 100%), these approaches are inherently limited in detecting subtle, physically coherent anomalies that involve complex, non-linear interactions among multiple variables. For instance, a combination of moderate temperature, high humidity, and clear skies might be physically inconsistent, yet each variable individually may fall within its plausible range. This limitation is particularly acute in regions with sparse station networks, where spatial redundancy is low. The emergence of high-quality reanalysis products, notably the ERA5 dataset from the European Centre for Medium-Range Weather Forecasts (ECMWF), offers a transformative opportunity by providing a spatially and temporally complete, physically consistent gridded climate record [11,12]. Studies show that ERA5-based estimates for key variables (e.g., air temperature, relative humidity, solar radiation) generally align well with ground observations, and can reliably support agrometeorological applications such as crop water requirement calculations [13,14,15,16,17,18]. The central challenge, however, evolves from simple data comparison to developing an intelligent, knowledge-driven QC system that can comprehend and validate the multivariate relationships inherent in meteorological systems.
The pursuit of multi-variable QC has led researchers to explore data mining techniques. Among these, Association Rule Mining (ARM) is a powerful paradigm for discovering frequent co-occurrence patterns—or “association rules”—within large datasets [19]. The Apriori algorithm, a cornerstone of ARM, is particularly adept at this task. While ARM has been successfully applied in diverse fields such as sports health monitoring, behavioral studies, and aviation safety analysis [20,21,22], its application in meteorology, particularly for QC, remains nascent. Most meteorological QC studies focus on single-element controls [23,24,25], with only a few pioneering works exploring ARM to capture inter-variable relationships for anomaly detection [26,27,28]. These mined associations effectively encode “climatological common sense,” allowing for the identification of observations that, despite passing univariate checks, violate expected multi-variable patterns, thus flagging potential anomalies.
However, the application of ARM to the QC of microclimatic data in specialized agricultural settings, such as tea plantations, is significantly underexplored. This niche demands sophisticated feature engineering to encapsulate temporal and physical contexts, alongside meteorologically informed discretization strategies to render continuous variables suitable for rule mining. This gap is of practical importance. In the Zhenjiang tea plantation region, a primary application of high-quality meteorological data is the accurate prediction of frost events, which can cause severe economic losses [29,30,31]. The effectiveness of such prediction models is fundamentally contingent on the quality of input data. Anomalies in temperature, humidity, or radiation can lead to missed forecasts or false alarms, directly impacting growers’ ability to implement protective measures.
To address this gap, we propose a novel, meteorologically informed QC framework that leverages the Apriori algorithm for association rule mining. Unlike prior studies that mine association rules directly from potentially noisy or sparse observational records, our framework derives rules from long-term, physically consistent ERA5 reanalysis data. This strategy treats ERA5 not as a reference for direct bias correction, but as a knowledge base encoding robust multivariate climatological relationships. These ERA5-derived rules thus represent transferable “physical consistency priors” that can be applied even to isolated stations lacking spatial neighbors or long clean histories. Focusing on a tea plantation located in Zhenjiang, China, our research is structured in three phases: first, we mine a set of robust association rules from over a decade of ERA5 reanalysis data, specifically tailored to the plantation’s location and the critical tea growing season (November to April). Second, we rigorously validate the efficacy of these rules by applying them to a synthetically generated ERA5 test dataset with injected anomalies. Finally, we deploy the validated rule set to perform quality control on real-world observational data collected from a tea plantation AWS.
The principal aims of this work are: (1) to develop a comprehensive feature engineering framework that transforms raw meteorological data into a discretized form conducive to mining meaningful association rules; (2) to implement the Apriori algorithm to extract and prioritize high-quality, physically interpretable rules from historical ERA5 data; (3) to design a fuzzy, weighted anomaly detection and scoring system based on rule violations; and (4) to comprehensively evaluate the method’s performance against traditional QC approaches, demonstrating its practical utility in enhancing the quality of real-world tea plantation meteorological data, thereby contributing to more reliable downstream applications like frost forecasting. Our results demonstrate that the proposed framework significantly outperforms conventional methods, particularly in detecting complex, multi-variable anomalies.
The remainder of this paper is organized as follows. Section 2 details the materials and methods, including data sources, feature engineering, the Apriori algorithm implementation, and the QC methodology. Section 3 presents the results of the association rule mining, validation with synthetic anomalies, and application to real-world data. Section 4 discusses the implications of our findings, the robustness of the method, and its potential for broader application. Finally, Section 5 concludes the paper.
2. Materials and Methods
2.1. Data Sources and Preparation
2.1.1. Study Area and Data Purpose
This study focuses on the Zhenjiang Maichun Tea Plantation (32.02 °N, 119.68 °E) in Jiangsu Province, China with an average elevation of 18.5 m—a major premium green tea production area located in the Yangtze River Delta. The plantation covers approximately 800 hectares within a landscape that is predominantly flat alluvial plain, interspersed with scattered low hills and gentle slopes (Figure 1). This rolling topography is typical of eastern China’s tea-growing regions and plays a critical role in modulating the local microclimate: variations in elevation and slope aspect influence cold-air drainage and accumulation, leading to fine-scale heterogeneity in frost risk. As a result, the site is frequently exposed to radiative frost events during autumn, winter, and spring.
Figure 1.
Geographical context and topography of the study area. (a) Location of Zhenjiang City within Jiangsu Province, China. (b) Detailed map of the Zhenjiang area showing topography (hillshade), the automatic weather station (AWS, red triangle), and the ERA5 grid cell (blue rectangle).
The critical growth period for high-quality spring tea spans from November to April, during which meteorological factors—particularly temperature, humidity, and solar radiation—directly impact yield and quality, and frost events pose a significant risk [32,33]. In Jiangsu Province alone, tea plantations covered approximately 34,000 hectares with an annual output value exceeding 33 billion CNY (2022 China Tea Production and Marketing Report). This economic vitality is persistently threatened by spring frosts. For instance, a late-spring cold event in March 2016 caused severe frost damage to tea plantations across eastern China, reducing spring tea yield in Jiangsu by an estimated 20–30% (China Tea Circulation Association). A contemporaneous study of the neighboring Zhejiang Province quantified the impact of the same event, reporting damage to over 100,000 hectares of tea plantations and economic losses of approximately 1.8 billion CNY [34]. These recurring disasters underscore the critical need for reliable meteorological data to support accurate frost forecasting and mitigation. Consequently, developing a robust quality control system for plantation weather data is an urgent priority to safeguard this economically significant industry.
To address this need, this study utilizes two primary data sources: in situ observations from a tea plantation automatic weather station (AWS) as the QC target, and the ERA5 reanalysis dataset for mining the association rules. The ERA5 period 2012–2023 was selected as it represents the most recent, high-quality decade, providing a robust sample of contemporary climatic variability while remaining computationally efficient for the Apriori algorithm. The target AWS dataset spans 2008–2016. This design intentionally creates a test scenario for temporal transferability: rules derived from a later period (2012–2023) are applied to quality-control data from an earlier, independent period (2008–2011).
Although the AWS station captures site-specific microclimatic conditions, the physical consistency constraints among meteorological variables (e.g., synoptic patterns, humidity) are governed by universal thermodynamic and radiative laws. For the study area, characterized by relatively gentle and homogeneous terrain, the large-scale atmospheric conditions captured by ERA5 are highly representative of the background state at the plantation scale. Although absolute values may differ from point observations, the multivariate co-variability patterns are robustly represented in the reanalysis at the regional scale. Therefore, association rules mined from ERA5 reflect physically plausible relationships that remain valid for quality-controlling local AWS measurements. The physical consistency relationships learned from this representative site are inherently based on fundamental atmospheric principles, suggesting strong potential for the method’s adaptation to other perennial crop systems in similar subtropical monsoon climates.
2.1.2. Automatic Meteorological Station Observation Data
Hourly in situ observations were collected from a plantation AWS from November 2008 to May 2016. The data includes air temperature (T), relative humidity (RH), wind speed (WS), and solar radiation (SR), with key sensor accuracies as follows: T (±0.2 °C), RH (±2% RH), and WS (±0.3 m/s). This dataset serves as the target for applying the quality control rules.
2.1.3. ERA5 Reanalysis Data for Rule Mining
The ERA5 reanalysis data was retrieved for the grid cell encompassing the tea plantation (see Figure 1) for the period November 2012 to April 2023, covering 12 complete tea growth seasons [35]. This long-term, physically consistent dataset provides a robust foundation for mining the fundamental multivariate relationships between meteorological variables. The core hourly variables extracted were: 2 m air temperature (t2m), 2 m dew point temperature (d2m), 10 m u- and v-wind components (u10, v10), surface solar radiation (ssr), and total precipitation (tp).
2.1.4. ERA5 Data Processing for Variable Alignment
To ensure consistency with the AWS observations, the ERA5 data underwent the following processing:
- Temperature unit conversion: t2m and d2m were converted from Kelvin to Celsius using the formula:
This ensures consistency with the observation data’s temperature unit (°C).
- 2.
- Relative humidity (RH) calculation: RH was derived from t2m (°C) and d2m (°C) using the Magnus–Tetens formula [36]:where is the vapor pressure at the dew point temperature, and is the saturation vapor pressure at air temperature , calculated as:
- 3.
- Wind speed: Wind speed (WS) was calculated from u10 (east–west component) and v10 (north–south component):These transformations convert vector wind components to scalar speed (m/s), consistent with the observation data’s wind metrics.
- 4.
- Radiation and precipitation unit adjustment: Surface net solar radiation (SSR) was converted from cumulative hourly energy (J/m2) to average flux (W/m2) by dividing by 3600 s (1 h), aligning with the observation data’s SR unit (W/m2). Total precipitation (TP) was converted from meters to millimeters through multiplying by 1000.
This processing yielded a final dataset of aligned variables (T, RH, WS, P, SR), structured for direct integration into the association rule mining workflow.
2.2. Feature Engineering Framework
The six raw meteorological variables provide a foundational dataset but are insufficient for detecting complex quality issues rooted in physical inconsistencies or temporal dynamics. To enable the discovery of meaningful association rules, we engineered a comprehensive set of features categorized into four groups: temporal context, physical relationships, time-series statistics, and meteorological anomalies. This enriched representation transforms each hourly observation into a multi-faceted description of the atmospheric state.
2.2.1. Temporal and Climatic Context Features
To embed each observation within its diurnal and annual cycle, we extracted fundamental temporal indicators: hour, month, and season. Furthermore, to benchmark against long-term climatic norms, we calculated the hourly climatological mean and standard deviation for core variables (t2m, rh, windspeed, ssr) from the 12-year ERA5 dataset, grouped by month and hour. These features, denoted as [var]_clim_mean and [var]_clim_std, provide a reference for identifying conditions that deviate from expected seasonal and diurnal patterns.
2.2.2. Physically Derived Relationship Features
We computed key agrometeorological variables to explicitly encode fundamental physical relationships:
- dew_point (Td): Calculated from t2m and rh using the Magnus formula, providing a direct measure of atmospheric moisture content for physical consistency checks.The dew point temperature is computed using the Magnus formula [37]:where a = 17.27, b = 237.7 °C.
- vapour_pressure_deficit (vpd): Derived from t2m and rh, a critical variable influencing plant transpiration and stress.
- apparent_temperature and wind_chill: Computed to integrate the combined effects of temperature, humidity, and wind on perceived temperature, relevant for assessing bioclimatic stress and frost risk.
2.2.3. Time-Series Statistical Features
To capture short-term dynamics and sensor failure modes (e.g., stuck values), we generated rolling statistics for key variables over 3, 6, and 24 h windows. These included the immediate change ([var]_change_[n]h), rolling standard deviation ([var]_std_[n]h), precipitation accumulation (tp_accumulate_[n]h), and smoothed solar radiation (ssr_mean_[n]h).
2.2.4. Derived Meteorological Anomaly and Context Features
To highlight statistically extreme events, we computed Z-score anomalies ([var]_anomaly_z) for each core variable against its respective climatological mean and standard deviation. The Z-score anomaly for each observation was then computed as:
Additionally, a simple weather_type classification (e.g., ‘clear’, ‘cloudy’, ‘rainy’) was implemented based on thresholds of tp, ssr, and rh to provide a high-level weather state context for rule mining.
The framework of the engineered features is summarized in Table 1, and the complete listing of all 63 features is provided in Appendix A (Table A1). All continuous features were subsequently discretized for association rule mining, as detailed in Section 2.3.
Table 1.
Summary of engineered feature categories.
2.3. Meteorologically Informed Discretization
2.3.1. Feature Selection for Rule Mining
The initial feature engineering produced 63 variables. To ensure computational tractability and the meteorological relevance of the mined rules, a rigorous feature selection was performed [38,39], guided entirely by domain knowledge and statistical redundancy analysis. This approach ensured that the features fed into the rule miner were both meteorologically meaningful and statistically non-redundant.
First, inherently redundant or uninformative features were removed, including temporal identifiers (time, hour, month) and high-frequency noise features (e.g., t2m_std_3h). Second, a domain-knowledge-guided review selected features that best capture sensor failure modes (e.g., rapid change features for rh and windspeed) and meaningful meteorological states (e.g., accumulation for tp, variability for ssr). Raw climatological benchmarks (*_clim_mean, *_clim_std) were also removed as their information is encapsulated in the Z-score anomalies. Finally, Spearman correlation analysis [40] (|ρ| ≥ 0.85) was used to eliminate one feature from any highly correlated pair, prioritizing the one with clearer physical interpretability (e.g., ssr_std_24h was retained over ssr_mean_24h). This process resulted in a curated set of 22 features for discretization.
2.3.2. Discretization Strategy and Thresholds
The selected continuous features were discretized into categorical bins using meteorologically and statistically defined thresholds. The discretization strategy was systematically tailored to each feature category, as defined in Table 2. The complete binning scheme with exact numerical thresholds for all features is available in Appendix A (Table A2).
Table 2.
Definition of discretization strategies by feature category.
2.3.3. Handling of Boundary Conditions and Special Cases
Key boundary conditions were addressed to ensure meteorological validity:
- Precipitation: A threshold of 0.01 mm/h distinguished ‘none’ from ‘trace’ precipitation, preventing instrument noise from being misclassified as rain.
- Nighttime: A threshold of 1 W/m2 defined the ‘night’ bin for solar radiation, accounting for measurement noise.
- Data Integrity: Records with missing values in core variables were excluded. Physical constraints (e.g., RH within 0–100%, near-zero SSR at night) were enforced as sanity checks prior to discretization.
2.3.4. Automatic Station Data Preprocessing
Before applying the quality control rules, the tea plantation AWS data underwent consistent preprocessing: missing values were filled via linear interpolation, the same discretization scheme detailed in Appendix A (Table A2) was applied to transform the data into the required categorical format.
2.4. Association Rules Mining Process
The curated, discretized meteorological dataset was processed using the Apriori algorithm to discover strong association rules that form the knowledge base for quality control. Although more computationally efficient algorithms (e.g., FP-Growth) exist, Apriori was selected for two practical reasons: (1) its transparent, stepwise candidate generation process facilitates interpretability—a critical requirement when rules must reflect physically meaningful meteorological relationships; (2) Apriori’s explicit control over minimum support, confidence and lift thresholds enables fine-grained tuning aligned with domain knowledge. The algorithm efficiently identifies frequent co-occurrence patterns (itemsets) by leveraging the anti-monotonicity property (all subsets of a frequent itemset must be frequent), then generates rules of the form X → Y from these itemsets [41,42].
2.4.1. Rule Quality Metrics and Thresholds
The quality of generated rules was assessed using three standard metrics [43]:
- Support: Support measures the frequency of a rule’s antecedent and consequent occurring together in the dataset. It reflects how common the rule is across all transactions, represented by:
- Confidence: Confidence measures the conditional probability of the consequent given the antecedent . It evaluates how reliable the rule is when the antecedent occurs.
- Lift: Lift measures the strength of the association between and , independent of their individual frequencies. It quantifies whether the co-occurrence of and is statistically significant or merely due to chance. A lift value of 1 indicates that and are independent—there is no association between them. If lift > 1, and are positively correlated, meaning the rule occurs more frequently than would be expected by chance, indicating a meaningful association.
To ensure the mined rules were both statistically significant and meteorologically robust, minimum thresholds were set based on preliminary experimentation and the following practical considerations. We tested a range of values (e.g., min_support: 0.005–0.05; min_confidence: 0.7–0.9; min_lift: 1.1–1.5). A min_support of 0.01 was chosen to capture a sufficiently broad and diverse—yet computationally manageable—set of multivariate meteorological patterns. A min_confidence of 0.8 was selected to guarantee that the mined rules represent strong, reliable implications, which is crucial for trustworthy quality control decisions. A min_lift of 1.2 ensures that the identified associations are statistically meaningful, representing co-occurrences significantly more frequent than expected by chance, thereby filtering out spurious correlations. This configuration serves as an initial, pragmatic threshold setting.
2.4.2. Rule Filtering and Prioritization
The initial rule mining often yields a substantial number of associations, many of which are redundant, meteorologically trivial, or physically implausible. To curate a high-quality rule set for practical quality control, a multi-stage filtering and prioritization pipeline was implemented.
First, rules failing to meet the above metric thresholds were discarded. Second, redundant rules (e.g., those subsumed by a more specific rule with similar confidence) were removed. Finally, a manual review was conducted to eliminate rules that, despite high metric scores, were meteorologically trivial or physically implausible (e.g., {is_daytime = 0} → {ssr_bin = night}), with approximately 1800 such rules removed. This manual curation inevitably entails some subjectivity.
To prioritize the most effective rules for the QC system, a composite score was calculated for each rule:
This scoring scheme emphasizes reliability (Confidence) and interestingness (Lift) over mere frequency (Support). The final rule set was sorted in descending order of this composite score, resulting in a prioritized knowledge base that enables both efficient computation and high-fidelity anomaly detection during the quality control process.
2.5. Meteorological Data Quality Control Framework
The curated association rules form a “soft” knowledge base for detecting deviations from normal meteorological patterns. To create a comprehensive QC system, these are integrated with a set of inviolable “hard” rules encoding fundamental physical principles and domain-specific constraints. The overall QC process for each data point is outlined in Figure 2 and detailed in the following subsections.
Figure 2.
Workflow of the integrated quality control system for tea plantation meteorological data.
2.5.1. Integrated Rule Execution with Fuzzy Handling
Data points are evaluated through a sequential, prioritized rule-checking pipeline:
- Hard Rule Check: Rules from Table 3 (e.g., physical impossibilities, logical conflicts) are checked first. Any violation immediately classifies the point as a High-Confidence Anomaly.Table 3. Representative hard constraint rules for meteorological quality control.
- Soft Rule Check (with Fuzzy Logic): If no hard rules are violated, the data point is checked against the prioritized list of association rules. To mitigate the rigidity of discrete bins, a fuzzy membership function is applied when assessing the consequent (Y). If a rule’s antecedent (X) is satisfied but the consequent is not, a Violation_Degree between 0 and 1 is calculated based on the continuous value’s distance from the target bin’s boundaries, using a tolerance δ derived from sensor uncertainty. The complete list of tolerance parameters for all variables is provided in Appendix A Table A3.
For a target bin with lower bound b and upper bound U’, we define a symmetric tolerance δ based on measurement uncertainty (e.g., ±1 °C for temperature, ±5% for relative humidity changes), thus creating a lower transition boundary L = b − δ and an upper transition boundary U = U’ + δ. The fuzzy membership of a value x in the target bin is then given by:
The corresponding violation degree is subsequently defined as:
2.5.2. Anomaly Scoring and Classification
For data points that only violate soft rules, a normalized anomaly score is computed by aggregating the contributions from all violated rules, weighted by their composite score:
This scoring mechanism ensures that a severe violation of a highly reliable and significant rule contributes the most to the total score.
Data points that trigger any hard constraint rule (Section 2.5.3) are immediately classified as anomalies. For all other points, the continuous Anomaly_Score is compared against a single, optimized decision threshold to generate the final binary quality flag (normal vs. anomalous). The optimal threshold was determined through a precision–recall (PR) analysis on the synthetic validation dataset (Section 2.6.1).
2.5.3. Hard Constraint Rule Base
Apriori-based soft rules can only mine frequent patterns in normal data and cannot cover anomalies such as physical boundary violations, meteorological logical conflicts, and tea garden-specific anomalies (e.g., tea bud frost damage risk). To address this gap, a hard rule base was constructed from first principles and domain knowledge. These rules are checked prior to any soft rule evaluation; any violation triggers an immediate High-Confidence Anomaly flag, ensuring operational safety.
Representative examples of these rules are provided in Table 3, while the complete, implementable rule set is available in Appendix A (Table A4).
The performance of this integrated QC framework, combining both hard constraints and soft association rules, is rigorously evaluated in the following section.
2.6. Evaluation Methodology
A comprehensive evaluation was designed to quantitatively assess the performance of the proposed QC system against a known ground truth, primarily using a synthetic dataset with injected anomalies. The system was also compared to traditional QC methods to benchmark its effectiveness.
2.6.1. Synthetic Anomaly Injection
To create a benchmark with perfect ground truth, five distinct types of anomalies were systematically injected into the pristine ERA5 2024 dataset (4360 hourly records), with each record modified at most once to avoid overlap. The anomaly types, designed to simulate common sensor failures [44,45,46] and data issues, were:
- Physical Boundary: Values outside plausible physical ranges (e.g., T < −10 °C, RH > 100%).
- Physical Consistency: Violations of fundamental physical relationships (e.g., high solar radiation under 100% cloud cover).
- Logical Consistency: Violations of empirical, region-specific logical relationships (e.g., heavy precipitation under clear skies).
- Temporal Consistency: Physically implausible short-term fluctuations (e.g., |ΔT| > 5 °C/hr without supporting changes).
- Pattern Anomalies: Violations of multi-variable meteorological patterns specific to the Zhenjiang tea plantation, derived from historical data.
The five categories of anomalies injected in this study were designed to systematically evaluate the QC system’s capability against both typical sensor failure modes and more complex, physically implausible scenarios. Physical boundary violations often stem from calibration drift; temporal inconsistencies typically mimic electronic spikes or data logging errors; and violations of physical or logical consistency frequently result from environmental interference such as dust accumulation on radiation sensors or blockage of rain gauges. While traditional fault categories (e.g., spikes, drift, stuck values) describe the origin of errors, our taxonomy focuses on their manifestation in the data stream, which is more relevant for detection. The detailed parameters and logic for each anomaly type are specified in Appendix A (Table A5).
2.6.2. Performance Metrics and Baseline Comparison
The effectiveness of the QC system was evaluated using standard binary classification metrics, treating the injected anomalies as the positive class. The following metrics were calculated based on the confusion matrix (True Positives, False Positives, True Negatives, False Negatives) [47,48]:
- Precision: Measures the reliability of the anomaly alarms. It is the fraction of flagged data points that are truly anomalous.
- 2.
- Recall (Sensitivity): Measures the ability of the system to detect all true anomalies. It is the fraction of all true anomalies that are successfully detected.
- 3.
- F1-Score: The harmonic mean of precision and recall. It provides a single metric that balances the trade-off between the two, especially useful when class distribution is imbalanced.
- 4.
- False Positive Rate (FPR): Measures the fraction of normal data points that are incorrectly flagged as anomalous.
To establish a performance benchmark, the proposed method was compared against three traditional QC approaches:
- Range Check (plausible value limits)
- Step Check (temporal change thresholds)
- Internal Consistency Check (simple physical relationships)
All methods were evaluated on the same synthetic dataset to ensure a fair comparison.
2.7. Application to Tea Plantation Observational Data
The fully developed and validated QC framework was applied directly to the independent observational data from the Zhenjiang tea plantation AWS for the 2008–2016 growing seasons. This step tested the operational utility and generalizability of the method on the real-world data it was designed to safeguard.
The raw AWS data underwent an identical preprocessing, feature engineering, and discretization pipeline as the ERA5 data (Section 2.2 and Section 2.3), ensuring feature consistency. Crucially, the same climatological benchmarks (e.g., *_clim_mean) derived from ERA5 were used to calculate Z-score anomalies, demonstrating the ability to apply a pre-defined knowledge base without retraining.
The curated association rules and hard constraints (Section 2.4 and Section 2.5) were then executed on this prepared dataset. The fuzzy logic and weighted anomaly scoring system were employed without any modification or threshold recalibration, generating a continuous Anomaly_Score for each observation.
The overall workflow of the proposed quality control system, from data ingestion to final classification, is summarized in Figure 2. This integrated process illustrates how the historical knowledge base, comprising both hard constraints and soft association rules, is applied to automatically assess the quality of incoming tea plantation observational data.
3. Results
3.1. Feature Selection and Correlation Analysis
The application of the three-stage feature selection methodology detailed in Section 2.3.1 resulted in a refined set of 22 salient features (Table 4), successfully reduced from the initial 63 variables.
Table 4.
Final set of 22 features selected for discretization and association rule mining.
The efficacy of this selection strategy is conclusively demonstrated by both the distribution of pairwise Spearman correlation coefficients (Figure 3) and the corresponding correlation matrix (Figure 4) among the final feature set. The distribution is strongly leptokurtic, with the vast majority of coefficients (over 85%) concentrated within the range of |ρ| < 0.3. This indicates that the selected features are predominantly weakly correlated or independent. The limited number of residual strong correlations (|ρ| > 0.7) correspond to feature pairs with well-established physical dependencies and distinct meteorological interpretations, such as the expected relationship between relative humidity (rh) and vapor pressure deficit (vpd). These were intentionally retained for their complementary diagnostic value. The effective elimination of spurious strong correlations confirms that redundant multicollinearity has been mitigated.
Figure 3.
Distribution of pairwise Spearman correlation coefficients for the final set of 22 selected features.
Figure 4.
Spearman correlation matrix of the final feature set.
This outcome validates the selection methodology: it successfully eliminated redundant feature pairs that would have generated semantically overlapping rules, while retaining a core set of meteorologically meaningful variables that provide diverse and complementary information for identifying data quality issues. The resulting feature set achieves an optimal balance between comprehensiveness and parsimony.
3.2. Characteristics and Meteorological Interpretation of Mined Association Rules
The Apriori algorithm, applied to the curated ERA5 dataset (Zhenjiang, 2012–2023), successfully encoded complex multivariate relationships into a high-fidelity knowledge base for quality control. From an initial pool of 247,593 frequent itemsets, a multi-stage filtering strategy—progressively tightening thresholds (e.g., confidence ≥ 0.95, lift ≥ 3.0) and removing meteorologically trivial patterns—yielded a final set of 11,005 robust rules. The top 500 rules, ranked by a composite score, were selected for the QC knowledge base. This number represents a practical compromise between capturing the most prevalent meteorological inconsistency patterns and maintaining a computationally tractable rule set. Preliminary evaluation indicated that these top rules account for the vast majority of rule-triggered flags in validation data, with diminishing returns from lower-ranked rules. Informal tests with nearby values (600 rules) yielded similar QC performance, suggesting the system is not highly sensitive to the exact cutoff.
The statistical profile of this final rule set underscores its exceptional quality and reliability (Table 5). The near-perfect average confidence (0.98) indicates that the consequents are almost certain given the antecedents. The remarkably high average lift (8.94) signifies that these relationships are far from random; they represent strong, inherent dependencies within the atmospheric system. The moderate average support (0.017) confirms that the rules capture meaningful patterns that are neither too rare to be useful nor too common to be obvious.
Table 5.
Statistical summary of the top 500 association rules.
To visualize the exceptional quality of the curated rule set, Figure 5 presents a scatter plot of confidence versus lift for the top 500 association rules that constitute the final quality control knowledge base. The density of points in the high-confidence, high-lift quadrant demonstrates the effectiveness of our multi-stage filtering and ranking process. These rules exhibit consistently high predictive reliability (confidence ≥ 0.95) and represent strong, non-random meteorological relationships (lift ≥ 3.0). The size and color of each point provide additional dimensions of information, representing rule support (prevalence) and composite score (overall quality), respectively. This concentrated distribution of high-quality rules forms a robust foundation for dependable automated quality control.
Figure 5.
Quality distribution (confidence vs. lift) of the top 500 association rules.
The mined rules were systematically categorized based on the meteorological variables present in their antecedents and consequents. Each rule was assigned to one or multiple predefined categories based on the physical nature of the variables involved: temperature-related (t2m, dew_point, apparent_temperature, wind_chill), humidity-related (rh, vpd), wind-related (windspeed), precipitation-related (tp), radiation-related (ssr), anomaly-related (anomaly_z), change-related (change_, std_), and time-related (hour, season, is_daytime). Analysis of the resulting rule categories (Figure 6) reveals that the knowledge base comprehensively encapsulates core physical processes. The most prevalent categories pertained to temperature-humidity relationships (e.g., rules involving t2m, apparent_temperature, dew_point, rh, vpd), followed by rules concerning precipitation events (tp) and time (e.g., is_daytime).
Figure 6.
Distribution of association rules by meteorological variable category.
To illustrate the nature and quality of the mined knowledge, two exemplary high-scoring rules are presented:
- Rule 1: {t2m_bin = hot ∧ dew_point_bin = dew_cool} → {rh_bin = dry ∧ wind_chill_bin = windchill_warm} (Confidence: 0.97, Lift: 20.0)
Interpretation: Encodes a key thermodynamic principle: high temperature with low absolute moisture (cool dew point) must result in low relative humidity. Violations indicate sensor inconsistencies.
- Rule 2: {t2m_anomaly_z_bin = t2m_cold_anomaly ∧ rh_bin = humid ∧ wind_chill_bin = windchill_cold} → {t2m_bin = very_cold} (Confidence: 0.97, Lift: 16.3)
Interpretation: Identifies coherent anomalous states. A statistically cold temperature anomaly is consistent with high humidity and a cold wind chill perception. Violations signal internal data inconsistency.
In summary, the rule mining process successfully translated multidimensional data into a concise, physically intelligible knowledge base, providing a robust foundation for identifying implausible meteorological states that traditional methods would overlook.
3.3. Validation of the Quality Control Methodology
3.3.1. Overview and Synthetic Anomaly Injection
To rigorously evaluate the proposed quality control (QC) method, we constructed a synthetic benchmark dataset by systematically injecting 480 anomalous data points into the pristine ERA5 reanalysis data. This corresponds to an anomaly prevalence of 11% within the 4360-record dataset, providing a substantial basis for performance assessment.
The injected anomalies encompass five distinct types, designed to simulate common meteorological data quality issues. As shown in Figure 7, the dataset composition is as follows: 90 Temporal Consistency anomalies, 120 Physical Boundary anomalies, 90 Pattern anomalies, 90 Logical Consistency anomalies, and 90 Physical Consistency anomalies. A detailed log of all injections was maintained to serve as the definitive ground truth for evaluation.
Figure 7.
Distribution of Injected Anomaly Types in the Synthetic Dataset.
3.3.2. Performance Comparison with Traditional QC Methods
The proposed rule-based method was rigorously benchmarked against three traditional QC approaches: Range Check, Step Check, and Internal Consistency Check. This choice aligns with our focus on interpretability and operational transparency: while modern black-box machine learning (ML) methods may achieve comparable detection accuracy, they prioritize statistical pattern recognition over physical consistency and often lack the traceability required for auditable meteorological quality control. Therefore, we benchmark against traditional rule-based baselines that share our emphasis on physically grounded, human-verifiable checks.
The performance metrics in Table 6 are reported as the mean ± standard deviation from 10 independent runs of the QC process, each with a different random seed for synthetic anomaly injection. This demonstrates the statistical stability of the results. As summarized in Table 6, the proposed method demonstrated superior overall performance, achieving the highest mean accuracy (0.975 ± 0.002) and a best-in-class mean F1-score (0.878 ± 0.009) by effectively balancing high precision (0.927 ± 0.012) and recall (0.832 ± 0.008). Crucially, it maintained a low mean false positive rate (FPR = 0.008 ± 0.001), substantially outperforming the Step Check (FPR = 0.091 ± 0.002) without succumbing to the severe under-detection that plagued the other methods.
Table 6.
Overall performance comparison of QC methods on the synthetic dataset.
The confusion matrices in Figure 8 provide further insight into the detection behavior of each method. Both the Range Check (Figure 8a) and Internal Consistency Check (Figure 8c) produced no false positives (FP = 0) but failed to detect a large number of true anomalies, with false negatives (FN) reaching 423 and 474, respectively. The Step Check (Figure 8b) reduced the number of false negatives to 211 but at the cost of introducing 353 false positives (FPR = 0.092). In contrast, the proposed rule-based method (Figure 8d) achieved a more balanced outcome, correctly identifying 444 true anomalies (TP) with only 65 false positives and 89 false negatives.
Figure 8.
Confusion matrices for the QC methods. (a) Range Check, (b) Step Check, (c) Internal Consistency Check, (d) Proposed Rule-based Method.
This superior discriminative power is further confirmed by the Receiver Operating Characteristic (ROC) [49] curves in Figure 9. The proposed rule-based method achieved the highest area under the curve (AUC = 0.911), significantly outperforming the Step Check (AUC = 0.825), Internal Consistency Check (AUC = 0.555), and Range Check (AUC = 0.512). Notably, the proposed method’s ROC curve rises steeply at low false positive rates (FPR < 0.2), achieving a true positive rate (TPR) exceeding 0.8. This indicates that the method can detect the majority of anomalies while maintaining a low rate of false alarms—a key advantage over the traditional methods, which either sacrifice recall or incur excessive false positives.
Figure 9.
ROC curves comparing the proposed method against traditional QC approaches.
3.3.3. Performance Across Different Anomaly Types
A fine-grained analysis reveals the consistent and exceptional performance of the proposed rule-based QC method across all categories of injected anomalies, as detailed in Figure 10.
Figure 10.
Precision and recall of the proposed rule-based QC method across different anomaly types.
The method demonstrated perfect precision (1.000) across all five anomaly types, indicating that every flagged data point was a true anomaly. Concurrently, it maintained consistently high recall, successfully detecting over 80% of anomalies in each category, with perfect recall (1.000) for Physical Boundary errors. This dual achievement of flawless precision and high recall across the board provides direct, quantitative validation of the core premise: the mined association rules effectively encode the fundamental physical limits and complex multivariate relationships that define normal meteorological states.
This stratified performance profile underscores a principal advantage of the proposed method. Unlike traditional approaches which excel only within their narrow domain (e.g., Range Check excels only at Physical Boundary errors), the association rule-based framework provides comprehensive, high-fidelity detection across the entire spectrum of anomaly types—from simple boundary violations to the most complex, physically based inconsistencies. Its ability to combine perfect precision with high recall makes it a uniquely reliable tool for automated meteorological data quality control.
3.3.4. Case Study: Detection of Complex Physical Consistency Anomalies
This case study demonstrates the method’s capability to identify subtle, physically implausible conditions that evade traditional QC checks. A sophisticated anomaly was injected into a 6 h nighttime period (00:00–05:00 on 11 March 2024), simulating a sensor fault that produced meteorologically impossible readings while maintaining stable values to avoid triggering standard temporal checks.
The injected anomaly created a “steady-state” physical inconsistency characterized by sustained high temperature (22 °C, t2m_bin = ‘hot’), very high relative humidity (rh_bin = ‘very_humid’), and zero solar radiation (ssr_bin = ‘night’) during a spring night. This combination represents a fundamental violation of energy balance principles, as a clear, humid night should experience strong radiative cooling leading to lower temperatures, not sustained warmth. Critically, this anomaly avoided triggering hard rules for temporal consistency by maintaining stable values throughout the injection period.
As shown in Figure 11, the proposed method successfully identified all six anomalous records, assigning each the maximum anomaly score of 1.0. The detection was triggered by the violation of a single but highly significant association rule:
{hour_bin = ‘night’, t2m_anomaly_z_bin = ‘t2m_warm_anomaly’, wind_chill_bin = ‘windchill_warm’} → {t2m_bin = ‘warm’}.
This rule encapsulates an established meteorological pattern: on a climatically warm night with light winds, the observed air temperature is typically ‘warm’. The injected data point, while satisfying all antecedent conditions, presented a t2m_bin value of ‘hot’—directly and completely violating the rule’s consequent. The maximum anomaly score of 1.0 reflects both the high confidence of the violated rule and the complete degree of the violation under the fuzzy matching scheme.
Figure 11.
A case study of complex anomaly detection. The top four panels show the time series of key meteorological variables (t2m, rh, ssr, tp). The bottom panel shows the corresponding anomaly score from the proposed method. The shaded area marks a 6 h window containing an injected physical consistency anomaly.
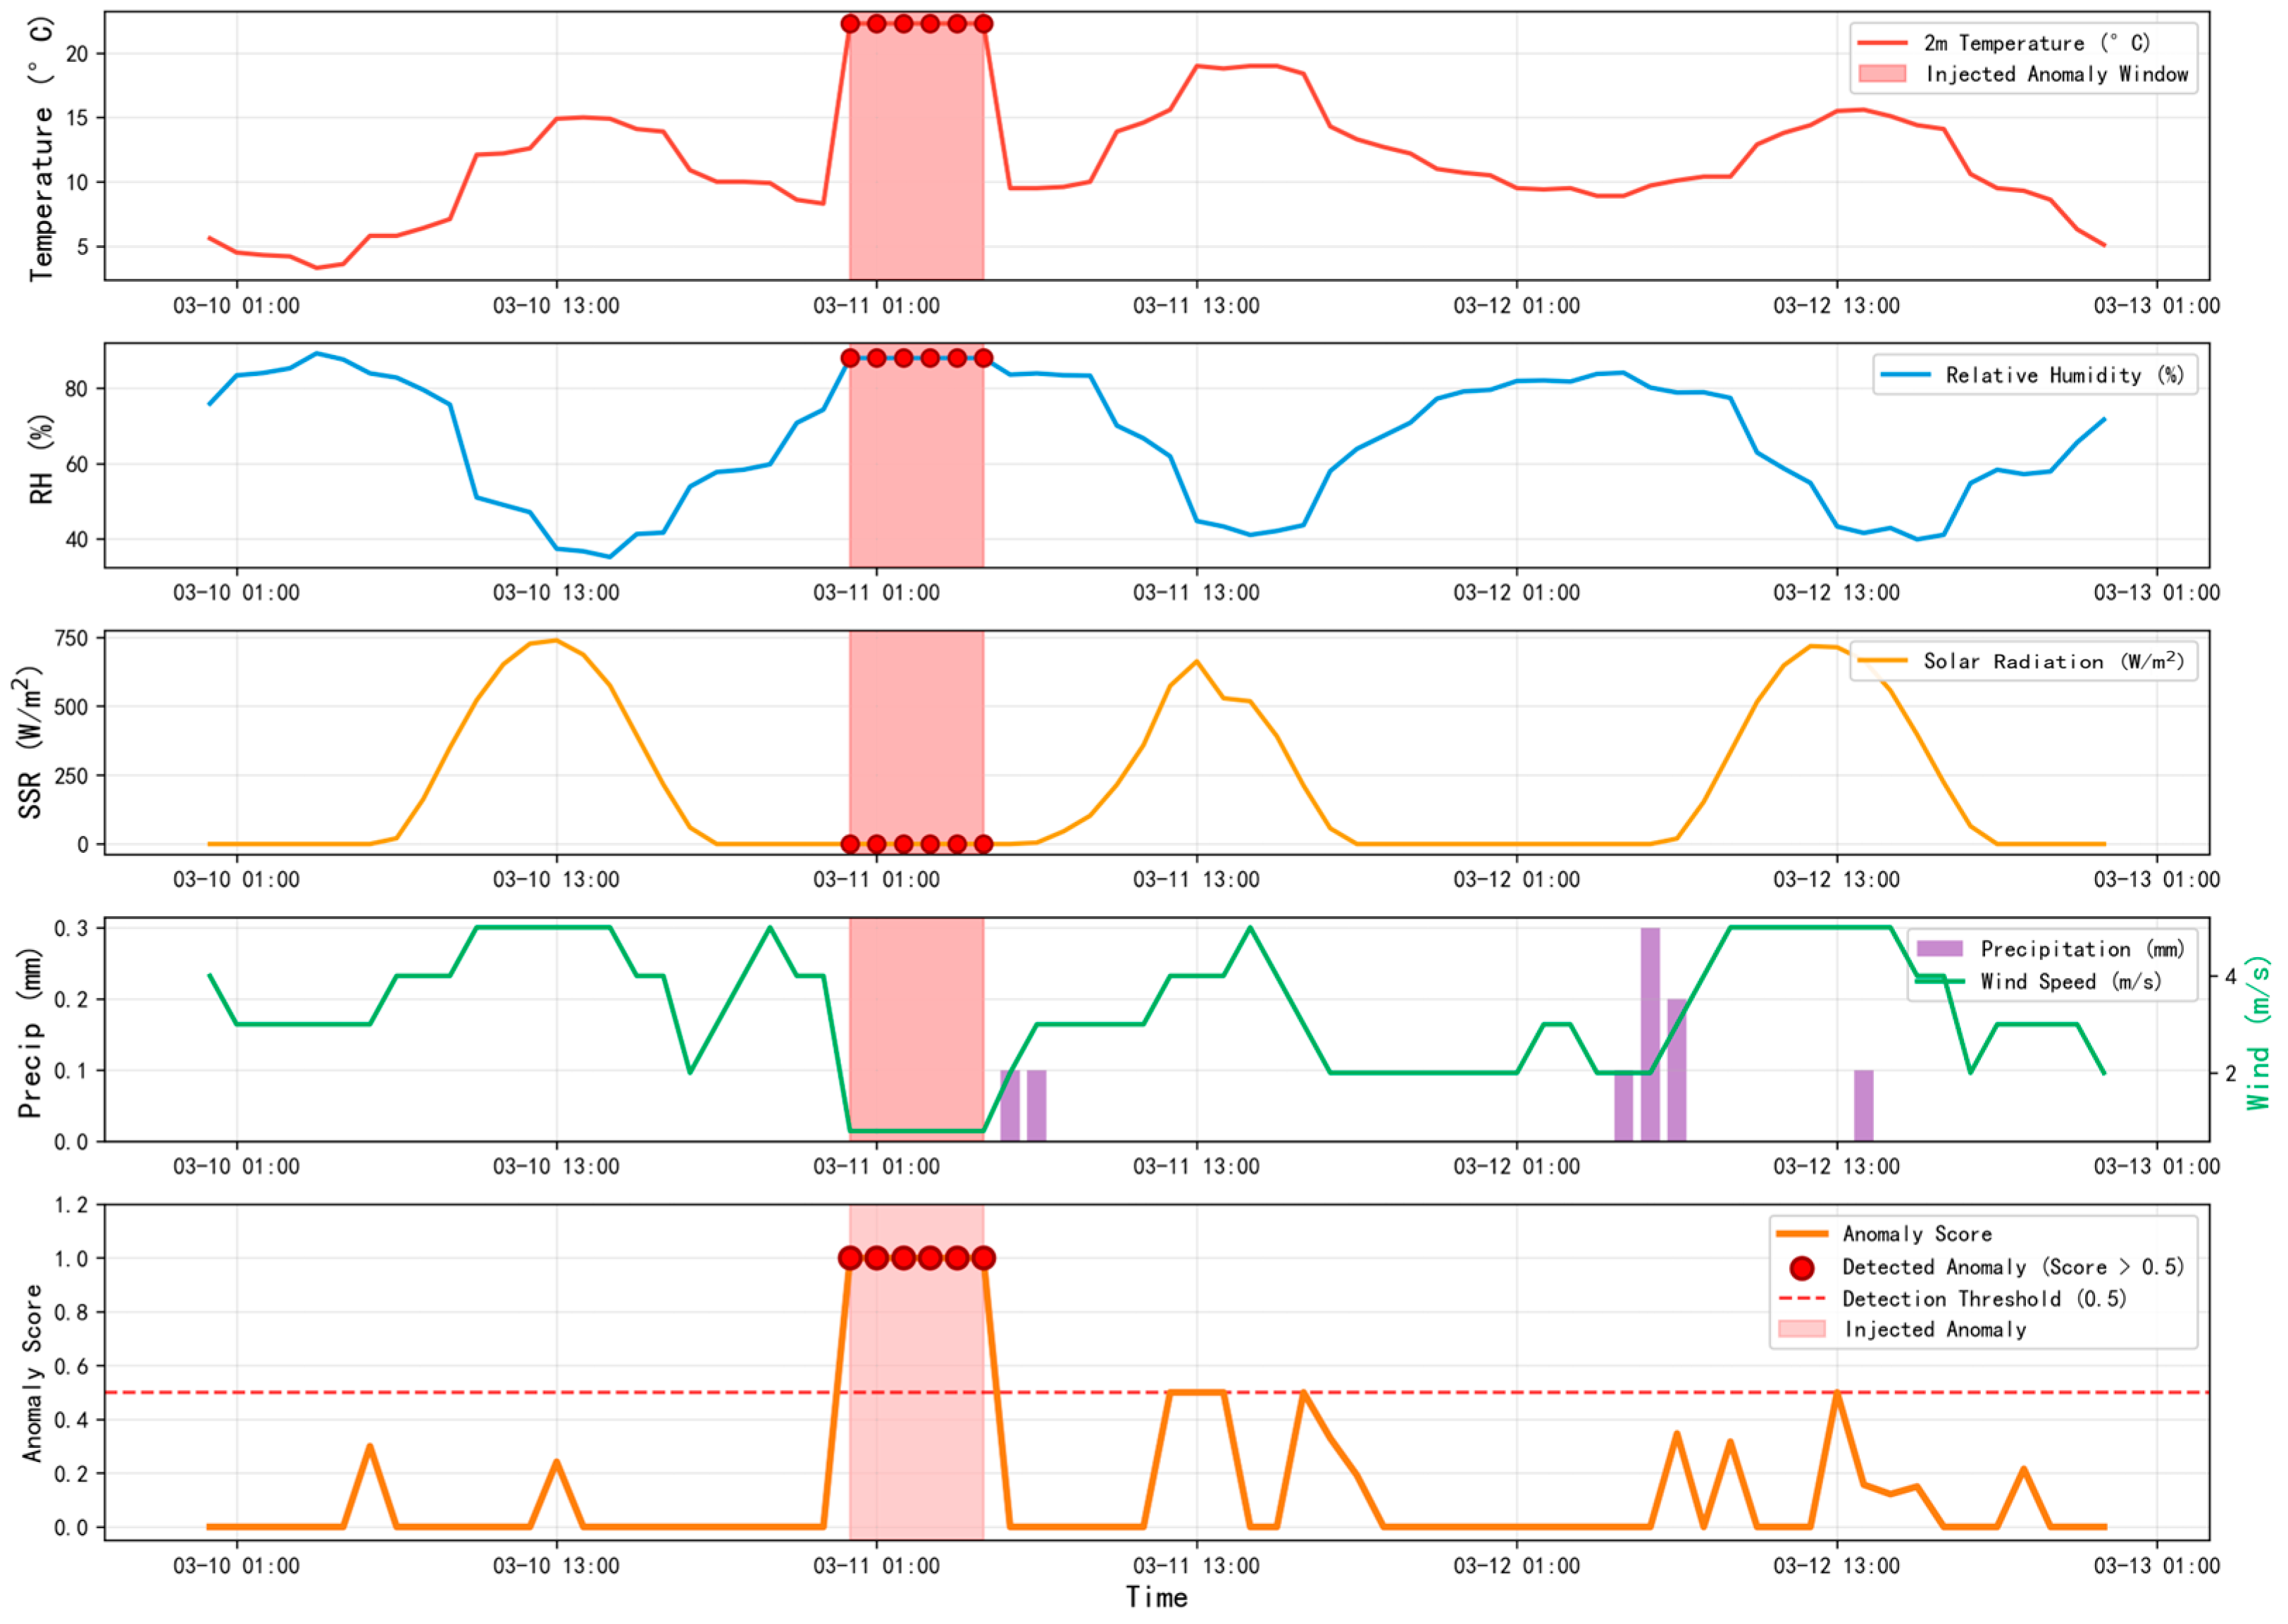
This case highlights three key advantages of the proposed approach:
- Superior Detection Capability: Traditional methods (Range, Step, Internal Consistency Checks) would fail to detect this anomaly, as all individual variables remained within plausible bounds and were temporally stable.
- Diagnostic Precision: The method flags the anomaly based on a specific, interpretable physical principle, providing diagnostic insight beyond a binary classification.
- Robust Signal Aggregation: The scoring mechanism effectively amplifies the signal from a single rule violation when it represents a fundamental physical inconsistency.
This successful detection underscores the method’s value as a guardian of physical plausibility in meteorological observations, capable of identifying sophisticated errors that evade traditional quality control approaches.
3.4. Robustness and Sensitivity Analysis
To ensure the practical reliability of the proposed quality control (QC) framework, we conducted a sensitivity analysis focusing on its core components: (1) the rule filtering criteria, and (2) the anomaly score threshold for final decision-making.
3.4.1. Sensitivity to Rule Filtering Criteria
A systematic analysis was conducted to determine the optimal thresholds for filtering the mined association rules. We evaluated five parameter combinations to identify the set that achieves the best balance between rule quality and QC performance, as measured by the F1-score on the synthetic test dataset. The performance of these parameter combinations on the synthetic test dataset is quantitatively compared in Table 7.
Table 7.
Performance comparison of different rule filtering parameter combinations.
The analysis revealed several key findings regarding parameter sensitivity:
- Confidence is Paramount: Higher confidence thresholds consistently improved both precision and recall. Increasing confidence from 0.92 to 0.94 (with fixed lift = 3.0, support = 0.03) boosted precision from 0.908 to 0.923 and recall from 0.809 to 0.821, resulting in a superior F1-score (0.869). This indicates that stricter confidence requirements filter out unreliable rules without sacrificing detection capability.
- Lift Controls a Trade-off: The lift parameter demonstrated a critical trade-off between precision and recall. Higher lift thresholds (3.0 vs. 2.5) significantly enhanced precision at the cost of moderate recall reduction. This is evident when comparing conf_0.92_lift_3.0_supp_0.03 (precision: 0.908, recall: 0.809) with conf_0.92_lift_2.5_supp_0.025 (precision: 0.794, recall: 0.920), where the higher lift threshold improved precision by 0.114 while reducing recall by 0.111. This suggests that lift thresholds control the balance between rule specificity and coverage.
- A Robust Optimal Region: The combinations conf_0.94_lift_3.0_supp_0.03 and conf_0.94_lift_2.5_supp_0.03 achieved identical top performance. This indicates a robust operational region where, once a high confidence threshold (≥0.94) is applied, the system’s performance becomes stable and less sensitive to variations in the lift threshold.
Based on these findings, the parameter set conf_0.94_lift_3.0_supp_0.03 was selected for the final QC system, providing the optimal compromise between detection accuracy and reliability.
3.4.2. Sensitivity to the Anomaly Score Threshold
The continuous anomaly score requires a definitive threshold for binary classification. We analyzed the Precision–Recall trade-off [50,51] to identify the optimal threshold for the final QC system, balancing detection sensitivity with false alarm rates.
The precision–recall curve (Figure 12a) exhibits a characteristic concave shape, indicating strong detection performance across the full range of thresholds. With an area under the curve (AUPRC) of 0.832, the model demonstrates robust ability to distinguish anomalies from normal data, even at varying confidence levels. The optimal operating point, marked by the red dot, corresponds to a threshold of 0.910, achieving a precision of 0.942 and recall of 0.813, with an F1-score of 0.873—highlighting a favorable balance between accuracy and completeness in anomaly detection.
Figure 12.
Sensitivity analysis of anomaly score threshold for quality control decision: (a) Complete precision–recall curve showing the trade-off between detection accuracy and coverage, with the optimal operating point marked; (b) Performance metrics evolution across different threshold values, illustrating the precision–recall trade-off and F1-score optimization.
The evolution of precision, recall, and F1-score with increasing anomaly score threshold (Figure 12b) reveals three distinct operational regimes:
- High-Sensitivity Regime (Threshold: 0.0–0.4): High recall (>0.85) ensures most true anomalies are detected, but at the cost of lower precision (~0.6–0.75) due to numerous false alarms.
- Balanced Trade-off Regime (Threshold: 0.4–0.6): Recall gradually declines while precision improves steadily, illustrating the core trade-off.
- Optimal Precision–Recall Balance (Threshold: 0.91): The F1-score peaks at 0.873, achieving an optimal equilibrium with a precision of 0.942 and a recall of 0.813. Further increases in threshold yield only marginal gains in precision and no significant improvement in F1-score.
Based on this analysis, the threshold of 0.91 was selected for operational deployment. This value ensures highly reliable anomaly flags (high precision) while maintaining substantial detection coverage (good recall), making it ideally suited for practical meteorological QC. Importantly, this threshold is not a universal constant but is data-driven and optimized for our specific evaluation scenario. In practice, users can readily adjust it based on their operational priorities—such as favoring higher recall for early warning or higher precision to reduce false alarms—using the full trade-off curve in Figure 12 as a decision guide.
Finally, regarding computational efficiency, the proposed framework is well-suited for real-time operational deployment in agricultural monitoring systems. The offline rule-mining process (including feature engineering) for 12 years of hourly ERA5 data requires approximately 3 min on a standard laptop (Intel i5-8250U, 16 GB RAM) using Python (v3.10), but this step is only needed periodically (e.g., monthly or annually). In contrast, the online quality control—applying the pre-mined rules to new observations—is extremely fast, requiring approximately 50 ms per record. This enables real-time, explainable anomaly detection for streaming data from agricultural IoT networks, making the system suitable for integration into live monitoring platforms.
3.5. Application to Tea Plantation Observation Data
To validate its practical utility and generalizability, the fully developed QC framework was applied to an independent, historical dataset from the Zhenjiang tea plantation AWS (2008–2016). The system identified 4821 anomalous records out of 32,916 total observations, corresponding to an anomaly rate of 14.6%. As shown in Figure 13, the rules identified anomalies not only in the overlapping period (2012–2016) but also consistently in the preceding non-overlapping years (2008–2011), indicating that the rules generalize well to earlier times. In operational practice, these flagged records are not automatically discarded but are instead prioritized for expert review, with the option to remove, correct, or retain them based on contextual evidence and error type.
Figure 13.
Distribution of Detected Anomalies in AWS Data (2008–2016).
A qualitative analysis of the flagged records revealed insightful patterns. The majority of anomalies fell into two categories: (1) Plausible Sensor Faults, characterized by sudden, unphysical spikes or sustained drifts in a single variable (e.g., a 5 °C temperature jump while other variables remained stable); and (2) Complex Physical Implausibilities, where multiple variables combined in a physically inconsistent manner (e.g., moderate rainfall co-occurring with high solar radiation under clear skies). This distinction is critical for operational maintenance, as the former suggests specific sensor calibration issues, while the latter may indicate complex data integration errors.
By systematically flagging and categorizing these errors, our method transforms the historical dataset. It enables researchers to make informed decisions—whether to exclude, correct, or investigate flagged points—thereby creating a more reliable foundation for downstream applications like frost risk assessment and pest modeling.
Most importantly, this successful application of our method to this independent historical period demonstrates its robustness and temporal generalizability. It confirms that the physical relationships captured in the association rules remain valid across different timeframes and operational conditions.
4. Discussion
4.1. Interpretation of Principal Findings and Mechanistic Insights
This study establishes that association rules mined from large-scale reanalysis data can form a robust, transferable knowledge base for quality controlling point-scale meteorological observations. The core achievement lies in the creation of a QC system that achieves superior performance (e.g., F1-score of 0.889) and demonstrates a fundamental capability to identify complex, multi-variable inconsistencies that violate physical principles, as evidenced by the case study (Section 3.3.4). The high temporal transferability of the rules—that is, successfully identifying 14.6% anomalies in an independent historical dataset (2008–2016) using rules mined from data from the period 2012–2023 without retraining—challenges the conventional paradigm that necessitates station-specific QC parameter tuning. This strongly suggests that the mined rules encode universal, scale-aware physical relationships (e.g., energy balance, thermodynamic constraints) that govern atmospheric behavior.
The discretization of continuous features into categorical bins is a fundamental step that influences the mined association rules. Two aspects warrant discussion: the choice of binning strategy and the sensitivity to specific thresholds. First, our approach employed a meteorologically informed strategy, where bin boundaries were defined by operational standards, biological thresholds, agronomic ranges, and statistical anomaly criteria. This knowledge-driven design was deliberately chosen over purely statistical methods (e.g., equal-frequency or equal-width binning) to ensure that each resulting category (e.g., “cold”, “humid”, “strong wind”) carries a direct and consistent physical meaning. While statistical binning might optimize data distribution, it risks splitting a coherent physical regime or merging distinct ones, potentially yielding rules that are statistically valid but meteorologically opaque, thereby limiting their interpretability and cross-context transferability. Second, regarding threshold sensitivity, while association rule mining can conceptually be sensitive to bin edges in principle, our use of semantically broad and physically anchored thresholds renders the resulting rules inherently tolerant to minor discretization variations. For instance, shifting the boundary between “hot” and “very_hot” by 1–2 °C is unlikely to invalidate a rule like “IF extreme_hot AND very_dry THEN high_vpd”, because the underlying thermodynamic relationship persists across this range. Furthermore, stringent post-mining filtering (e.g., by confidence and lift) preferentially retains strong, non-spurious associations. Consequently, while minor threshold adjustments might yield quantitatively different rule sets, the essential physical couplings captured—such as the consistency between temperature, humidity, and derived variables—are expected to be stable across reasonable discretization choices.
4.2. Comparison with Existing Methodologies and Advancement of the Field
Our findings position the proposed framework as a bridge between simplistic threshold-based checks and complex, opaque machine learning models. As quantitatively demonstrated in Section 3.3.2, traditional methods like Range and Step Checks, while computationally efficient, operate in a univariate vacuum and fail catastrophically when faced with physically plausible yet impossible multi-variable combinations. In contrast, modern machine learning-based anomaly detectors (e.g., autoencoders, isolation forests) can capture high-dimensional statistical patterns but typically function as black boxes, offering little insight into why a record was flagged. This lack of interpretability hinders their adoption in operational meteorology, where auditability and physical traceability are paramount. Our method advances the field by offering the “explainability” of a physical model with the pattern-discovery power of data mining. Crucially, the system’s decision is based on a single, optimized threshold (determined via PR curve analysis) and a set of violated rules, providing a clear, physics-based rationale for each flag, which is essential for building trust in operational settings.
4.3. Broader Implications and Practical Utility
The implications extend beyond technical methodology into practical agricultural management. For critical applications like frost prediction [52,53] and pest modeling [54], where model inputs are derived from AWS data, the consequences of undetected anomalies are direct and economic. By improving the quality and physical consistency of the underlying meteorological observations, our framework indirectly strengthens the reliability of these decision-support systems. Furthermore, by enabling the retrospective quality control of historical datasets from early-generation AWS, which revealed a 14.6% anomaly rate comprising both sensor faults and complex physical implausibilities, this work facilitates the creation of more homogeneous and reliable long-term climate records for agricultural regions. This is a vital contribution to climate change impact studies, ensuring that trend analyses are based on high-fidelity data.
4.4. Limitations and Future Research
We acknowledge two primary limitations. First, the efficacy of the method depends on ERA5 reasonably representing the large-scale physical relationships that also govern surface meteorological observations at the study site. The AWS is situated at a low elevation (18.5 m), typical of agricultural plains, where such large-scale relationships—such as those governed by energy balance and thermodynamic constraints—are generally well captured by ERA5’s ~25 km resolution. This favorable representativeness underpins the strong transferability of the association rules observed in our study. Nevertheless, performance may degrade in regions with complex terrain (e.g., steep mountains or deep valleys) or pronounced microclimatic effects (e.g., persistent temperature inversions, localized wind systems, or strong land-cover-induced thermal contrasts), where ERA5’s coarse spatial resolution can smooth out critical sub-grid variability. Second, and more intrinsically, the method may be less sensitive to anomalies arising from highly localized phenomena that fall below the resolution of the reanalysis grid. This limitation stems from the fact that the association rules are derived from meteorological patterns resolved at the ERA5 scale. However, it is crucial to emphasize that the primary design objective of this QC system is to detect sensor malfunctions and violations of fundamental physical consistency—precisely the types of errors that manifest as deviations from large-scale, physically coherent relationships.
Future work should therefore focus on: (1) Developing hybrid systems that integrate our reanalysis-derived rules with a small set of site-specific constraints. (2) Exploring incremental learning strategies to allow the rule base to adapt to a changing climate without full retraining. (3) Implementing operational deployment for real-time decision support. The most impactful prospect is integrating this QC framework into a live monitoring platform for tea plantations, providing instant, explainable validation for data feeding into frost warning or pest forecast models.
5. Conclusions
This study proposed and validated a novel, meteorologically informed quality control (QC) framework for tea plantation meteorological data, leveraging association rules mined from ERA5 reanalysis data. The principal conclusions are as follows:
- The association rules, derived from large-scale reanalysis data, formed a robust and temporally transferable QC knowledge base, successfully identifying 14.6% anomalous records in an independent historical dataset from a tea plantation automatic weather station.
- The proposed framework significantly outperformed traditional univariate QC methods, achieving a balanced F1-score of 0.878 on a synthetic testbed, with particular strength in detecting complex, multi-variable physical inconsistencies that evade conventional checks.
- The integration of hard constraint rules with a fuzzy-logic-based soft rule scoring system ensured both operational safety and nuanced anomaly detection.
This work provides agricultural meteorologists and precision farming practitioners with an accurate, explainable, and automated tool for enhancing the reliability of field-collected weather data. The framework’s success in a tea plantation context suggests its potential for adaptation to other perennial crop systems, contributing to more resilient data foundations for climate-smart agriculture.
Author Contributions
Conceptualization, Z.Z., P.L. and J.W.; methodology, Z.Z.; software, Z.Z.; validation, Z.Z.; formal analysis, Z.Z.; investigation, Z.Z. resources, Z.Z.; data curation, Z.Z.; writing—original draft preparation, Z.Z.; writing—review and editing, Z.Z., P.L. and J.W.; visualization, Z.Z.; supervision, P.L.; project administration, J.W. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Data Availability Statement
The data presented in this study are available on request from the corresponding author. The data are not publicly available due to the privacy policy of the authors’ institution.
Conflicts of Interest
The authors declare no conflicts of interest.
Appendix A
Table A1.
Comprehensive list of engineered features.
Table A2.
Meteorologically informed discretization scheme for selected features.
Table A3.
List of tolerance parameters for all variables.
Table A4.
Hard Rule Base for Meteorological Data of Zhenjiang Tea Gardens in Winter and Spring.
Table A5.
Synthetic Anomaly Injection Protocol.
References
- Faybishenko, B.; Versteeg, R.; Pastorello, G.; Dwivedi, D.; Varadharajan, C.; Agarwal, D. Challenging Problems of Quality Assurance and Quality Control (QA/QC) of Meteorological Time Series Data. Stoch. Environ. Res. Risk Assess. 2022, 36, 1049–1062. [Google Scholar] [CrossRef] [Scilit]
- Patro, B.S.; Bartakke, P.P. Quality Control (QC) and Quality Assurance (QA) Procedures for Meteorological Data from Automatic Weather Stations. In Proceedings of the 2025 4th International Conference on Range Technology (ICORT), Chandipur, Balasore, India, 6–8 March 2025; pp. 1–6. [Google Scholar]
- Yari, R.; Darzi-Naftchali, A.; Dehghanisanij, H.; Qi, Z. Effect of Meteorological Data Quality Control and Data Adjustment on the Reference Evapotranspiration: A Case Study in Jafariye, Iran. Theor. Appl. Climatol. 2020, 141, 331–342. [Google Scholar] [CrossRef] [Scilit]
- Li, S.; Wang, Z.; Huang, J. Evaluation of Tea Frost Risk in Zhejiang Province Based on GIS. In Proceedings of the 2018 7th International Conference on Agro-Geoinformatics (Agro-Geoinformatics), Hangzhou, China, 6–9 August 2018; pp. 1–4. [Google Scholar]
- Lou, W. Frost Risk Assessment Based on the Frost-Induced Injury Rate of Tea Buds: A Case Study of the Yuezhou Longjing Tea Production Area, China. Eur. J. Agron. 2023, 147, 126839. [Google Scholar] [CrossRef] [Scilit]
- Khatri, P.; Shakya, K.S.; Kumar, P. A Probabilistic Framework for Identifying Anomalies in Urban Air Quality Data. Environ. Sci. Pollut. Res. 2024, 31, 59534–59570. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Srinath, Y.; Vijayakumar, K.; Revathy, S.M.; Rangaraj, A.G.; Sheelarani, N.; Boopathi, K.; Balaraman, K. Automated Data Quality Mechanism and Analysis of Meteorological Data Obtained from Wind-Monitoring Stations of India. In Data Management, Analytics and Innovation; Sharma, N., Chakrabarti, A., Balas, V.E., Bruckstein, A.M., Eds.; Lecture Notes on Data Engineering and Communications Technologies; Springer: Singapore, 2022; Volume 71, pp. 237–262. ISBN 978-981-16-2936-5. [Google Scholar]
- Chi, W.; Zhang, Y.; Zhang, X.; Jing, J.; Yan, P. Analysis of Quality Control Effect of Reactive Gas Observation Data Based on Multiple Data Quality Control Methods. In Proceedings of the 2019 International Conference on Meteorology Observations (ICMO), Chengdu, China, 28–31 December 2019; pp. 1–4. [Google Scholar]
- Ouyang, H.; Qin, Z.; Xu, X.; Xu, Y.; Huangfu, J.; Li, X.; Hu, J.; Zhan, Z.; Yu, J. Autonomous Quality Control of High Spatiotemporal Resolution Automatic Weather Station Precipitation Data. Remote Sens. 2025, 17, 404. [Google Scholar] [CrossRef] [Scilit]
- Chen, Y.; Mao, J.; Li, T.; Zhang, X.; Wang, L. Comprehensive Quality Control Method and Effect Analysis of Brightness Temperature Data of Ground-Based Microwave Radiometer. In Proceedings of the 2019 International Conference on Meteorology Observations (ICMO), Chengdu, China, 28–31 December 2019; pp. 1–4. [Google Scholar]
- Hersbach, H.; Bell, B.; Berrisford, P.; Hirahara, S.; Horányi, A.; Muñoz-Sabater, J.; Nicolas, J.; Peubey, C.; Radu, R.; Schepers, D.; et al. The ERA5 Global Reanalysis. Q. J. R. Meteorol. Soc. 2020, 146, 1999–2049. [Google Scholar] [CrossRef] [Scilit]
- Muñoz-Sabater, J.; Dutra, E.; Agustí-Panareda, A.; Albergel, C.; Arduini, G.; Balsamo, G.; Boussetta, S.; Choulga, M.; Harrigan, S.; Hersbach, H.; et al. ERA5-Land: A State-of-the-Art Global Reanalysis Dataset for Land Applications. Earth Syst. Sci. Data 2021, 13, 4349–4383. [Google Scholar] [CrossRef] [Scilit]
- Jiao, D.; Xu, N.; Yang, F.; Xu, K. Evaluation of Spatial-Temporal Variation Performance of ERA5 Precipitation Data in China. Sci. Rep. 2021, 11, 17956. [Google Scholar] [CrossRef] [Scilit]
- Zou, J.; Lu, N.; Jiang, H.; Qin, J.; Yao, L.; Xin, Y.; Su, F. Performance of Air Temperature from ERA5-Land Reanalysis in Coastal Urban Agglomeration of Southeast China. Sci. Total Environ. 2022, 828, 154459. [Google Scholar] [CrossRef] [Scilit]
- Li, Q.; Jiang, Y.; Wei, L.; Liu, F.; Zhu, J. Comparison of ERA5-Land and CMPAS Reanalysis Data for the Regional Assessment of Precipitation in Chongqing, China. Meteorol. Atmos. Phys. 2025, 137, 16. [Google Scholar] [CrossRef] [Scilit]
- Fatolahzadeh Gheysari, A.; Maghoul, P.; Ojo, E.R.; Shalaby, A. Reliability of ERA5 and ERA5-Land Reanalysis Data in the Canadian Prairies. Theor. Appl. Climatol. 2024, 155, 3087–3098. [Google Scholar] [CrossRef] [Scilit]
- Oses, N.; Azpiroz, I.; Marchi, S.; Guidotti, D.; Quartulli, M.; Olaizola, I.G. Analysis of Copernicus’ ERA5 Climate Reanalysis Data as a Replacement for Weather Station Temperature Measurements in Machine Learning Models for Olive Phenology Phase Prediction. Sensors 2020, 20, 6381. [Google Scholar] [CrossRef] [Scilit]
- Jiang, Q.; Li, W.; Fan, Z.; He, X.; Sun, W.; Chen, S.; Wen, J.; Gao, J.; Wang, J. Evaluation of the ERA5 Reanalysis Precipitation Dataset over Chinese Mainland. J. Hydrol. 2021, 595, 125660. [Google Scholar] [CrossRef] [Scilit]
- He, P. Multi-Dimensional Information Multimedia Big Data Mining Analysis Relying on Association Rule Mapping Model. Arab. J. Sci. Eng. 2025, 50, 7361–7373. [Google Scholar] [CrossRef] [Scilit]
- Hao, Q.; Choi, W.J.; Meng, J. A Data Mining-Based Analysis of Cognitive Intervention for College Students’ Sports Health Using Apriori Algorithm. Soft Comput. 2023, 27, 16353–16371. [Google Scholar] [CrossRef] [Scilit]
- Chen, H.; Yang, M.; Tang, X. Association Rule Mining of Aircraft Event Causes Based on the Apriori Algorithm. Sci. Rep. 2024, 14, 13440. [Google Scholar] [CrossRef] [Scilit]
- Ding, H.; Sun, Q. Application of the Modified Apriori Algorithm in Addictive Behavior and Mental Health. In Frontier Computing on Industrial Applications Volume 1; Hung, J.C., Yen, N., Chang, J.-W., Eds.; Lecture Notes in Electrical Engineering; Springer Nature: Singapore, 2024; Volume 1131, pp. 429–435. ISBN 978-981-99-9298-0. [Google Scholar]
- Yan, Q.; Zhang, B.; Jiang, Y.; Liu, Y.; Yang, B.; Wang, H. Quality Control of Hourly Rain Gauge Data Based on Radar and Satellite Multi-Source Data. J. Hydroinform. 2024, 26, 1042–1058. [Google Scholar] [CrossRef] [Scilit]
- Xu, Y.; Shen, Y.; Jiang, X.; Tian, F.; Cao, L.; Wang, N. Quality Control Technique for Ground-Based Lightning Detection Data Based on Multi-Source Data over China. Remote Sens. 2025, 17, 1928. [Google Scholar] [CrossRef] [Scilit]
- Terán-Chaves, C.A.; Duarte-Carvajalino, J.M.; Polo-Murcia, S.M. Quality Control and Filling of Daily Temperature and Precipitation Time Series in Colombia. Meteorol. Z 2021, 30, 489–501. [Google Scholar] [CrossRef] [Scilit]
- Shan, W.; Zhang, H.; Luan, Y.; Li, H.; Zhu, J. Research on Meteorological Data Quality Control Based on Association Rule Algorithm. In Proceedings of the 2024 7th International Conference on Advanced Algorithms and Control Engineering (ICAACE), Shanghai, China, 1–3 March 2024; pp. 766–770. [Google Scholar]
- Li, T.; Lu, Z.; Zhao, R.; Ren, Y.; Yu, M.; Zhang, T. Meteorological Observation Equipment Consistency Testing Based on Association Rule Mining Algorithm. In Proceedings of the 2018 1st International Cognitive Cities Conference (IC3), Okinawa, Japan, 7–9 August 2018; pp. 75–80. [Google Scholar]
- Sarma, R.; Sarma, P.K.D. Discovery of Fuzzy and Composite Fuzzy Association Rules in Meteorological Data. J. Inf. Syst. Eng. Manag. 2025, 10, 1–21. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.-C.; Chen, C.-T.; Li, R.-Y.; Lu, Y.-H.; Chiang, L.-C. Climate Risk Analysis of Low-Altitude Tea Gardens in Central Taiwan Using a Bayesian Network. Environ. Monit. Assess. 2024, 196, 809. [Google Scholar] [CrossRef] [Scilit]
- Han, Y.; He, Y.; Liang, Z.; Shi, G.; Zhu, X.; Qiu, X. Risk Assessment and Application of Tea Frost Hazard in Hangzhou City Based on the Random Forest Algorithm. Agriculture 2023, 13, 327. [Google Scholar] [CrossRef] [Scilit]
- Pan, Q.; Lu, Y.; Hu, Y. Influences of Sprinkler Frost Protection on Air and Soil Temperature and Chlorophyll Fluorescence of Tea Plants in Tea Gardens. Agriculture 2024, 14, 2302. [Google Scholar] [CrossRef] [Scilit]
- De, D.; Sarkar, S.; Chhetri, H.; Chatterjee, J.; Sinha, N.; Das, S.; Sarkar, A.; Das, S.; Ray, S. Impact of Meteorological and Processing Factors on Metabolite Composition of Darjeeling Tea. J. Anal. Sci. Technol. 2024, 15, 54. [Google Scholar] [CrossRef] [Scilit]
- Song, H.; Hu, Y.; Lu, Y.; Wang, J.; Pan, Q.; Li, P. A Review of Methods and Techniques for Detecting Frost on Plant Surfaces. Agriculture 2021, 11, 1142. [Google Scholar] [CrossRef] [Scilit]
- Xu, J.; Guga, S.; Rong, G.; Riao, D.; Liu, X.; Li, K.; Zhang, J. Estimation of Frost Hazard for Tea Tree in Zhejiang Province Based on Machine Learning. Agriculture 2021, 11, 607. [Google Scholar] [CrossRef] [Scilit]
- ERA5 Hourly Data on Single Levels from 1940 to Present. Available online: https://cds.climate.copernicus.eu/datasets/reanalysis-era5-single-levels?tab=overview (accessed on 10 July 2025).
- Thrasher, B.; Khajehei, S.; Kim, J.B.; Brosnan, I. NASA Earth Exchange Downscaled Climate Projections 30 Arcseconds CMIP6. Sci. Data 2024, 11, 1346. [Google Scholar] [CrossRef] [Scilit]
- Hernandez-Torres, J.A.; Torreglosa, J.P.; Sanchez-Herrera, R.; Bischi, A.; Baccioli, A. Development of an Optimized Non-Linear Model for Precise Dew Point Estimation in Variable Environmental Conditions. Appl. Sci. 2024, 14, 10508. [Google Scholar] [CrossRef] [Scilit]
- Theng, D.; Bhoyar, K.K. Feature Selection Techniques for Machine Learning: A Survey of More than Two Decades of Research. Knowl. Inf. Syst. 2024, 66, 1575–1637. [Google Scholar] [CrossRef] [Scilit]
- Chandrashekar, G. A Survey on Feature Selection Methods. Comput. Electr. Eng. 2014, 40, 16–28. [Google Scholar] [CrossRef] [Scilit]
- Schober, P.; Boer, C.; Schwarte, L.A. Correlation Coefficients: Appropriate Use and Interpretation. Anesth. Analg. 2018, 126, 1763–1768. [Google Scholar] [CrossRef] [Scilit]
- Godhrawala, H.; Sridaran, R. Apriori Algorithm Based Approach for Improving QoS and SLA Guarantee in IaaS Clouds Using Pattern-Based Service-Oriented Architecture. SN Comput. Sci. 2023, 4, 700. [Google Scholar] [CrossRef] [Scilit]
- Zhuang, C.; Liu, Z.; Liu, J.; Ma, H.; Zhai, S.; Wu, Y. Digital Twin-Based Quality Management Method for the Assembly Process of Aerospace Products with the Grey-Markov Model and Apriori Algorithm. Chin. J. Mech. Eng. 2022, 35, 105. [Google Scholar] [CrossRef] [Scilit]
- Hassan, M.M.; Zaman, S.; Mollick, S.; Hassan, M.M.; Raihan, M.; Kaushal, C.; Bhardwaj, R. An Efficient Apriori Algorithm for Frequent Pattern in Human Intoxication Data. Innov. Syst. Softw. Eng. 2023, 19, 61–69. [Google Scholar] [CrossRef] [Scilit]
- Noshad, Z.; Javaid, N.; Saba, T.; Wadud, Z.; Saleem, M.Q.; Alzahrani, M.E.; Sheta, O.E. Fault Detection in Wireless Sensor Networks through the Random Forest Classifier. Sensors 2019, 19, 1568. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Park, M.-S.; Baek, K. Quality Management System for an IoT Meteorological Sensor Network—Application to Smart Seoul Data of Things (S-DoT). Sensors 2023, 23, 2384. [Google Scholar] [CrossRef] [Scilit]
- Teh, H.Y.; Kempa-Liehr, A.W.; Wang, K.I.-K. Sensor Data Quality: A Systematic Review. J. Big Data 2020, 7, 11. [Google Scholar] [CrossRef] [Scilit]
- Fang, Y.; Zhang, Z. Employee Turnover Prediction Model Based on Feature Selection and Imbalanced Data Handling. IEEE Access 2025, 13, 126736–126755. [Google Scholar] [CrossRef] [Scilit]
- Alarfaj, F.K.; Malik, I.; Khan, H.U.; Almusallam, N.; Ramzan, M.; Ahmed, M. Credit Card Fraud Detection Using State-of-the-Art Machine Learning and Deep Learning Algorithms. IEEE Access 2022, 10, 39700–39715. [Google Scholar] [CrossRef] [Scilit]
- Nahm, F.S. Receiver Operating Characteristic Curve: Overview and Practical Use for Clinicians. Korean J. Anesthesiol. 2022, 75, 25–36. [Google Scholar] [CrossRef] [Scilit]
- Keilwagen, J.; Grosse, I.; Grau, J. Area under Precision-Recall Curves for Weighted and Unweighted Data. PLoS ONE 2014, 9, e92209. [Google Scholar] [CrossRef] [Scilit]
- Williams, C.K.I. The Effect of Class Imbalance on Precision-Recall Curves. Neural Comput. 2021, 33, 853–857. [Google Scholar] [CrossRef] [Scilit]
- Rozante, J.R.; Ramirez, E.; Ramirez, D.; Rozante, G. Improved Frost Forecast Using Machine Learning Methods. Artif. Intell. Geosci. 2023, 4, 164–181. [Google Scholar] [CrossRef] [Scilit]
- Lira, H.; Martí, L.; Sanchez-Pi, N. A Graph Neural Network with Spatio-Temporal Attention for Multi-Sources Time Series Data: An Application to Frost Forecast. Sensors 2022, 22, 1486. [Google Scholar] [CrossRef] [Scilit]
- Donatelli, M.; Magarey, R.D.; Bregaglio, S.; Willocquet, L.; Whish, J.P.M.; Savary, S. Modelling the Impacts of Pests and Diseases on Agricultural Systems. Agric. Syst. 2017, 155, 213–224. [Google Scholar] [CrossRef] [Scilit]
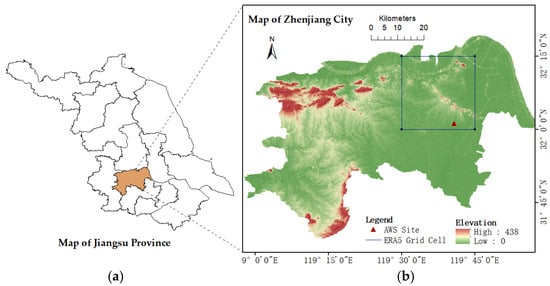
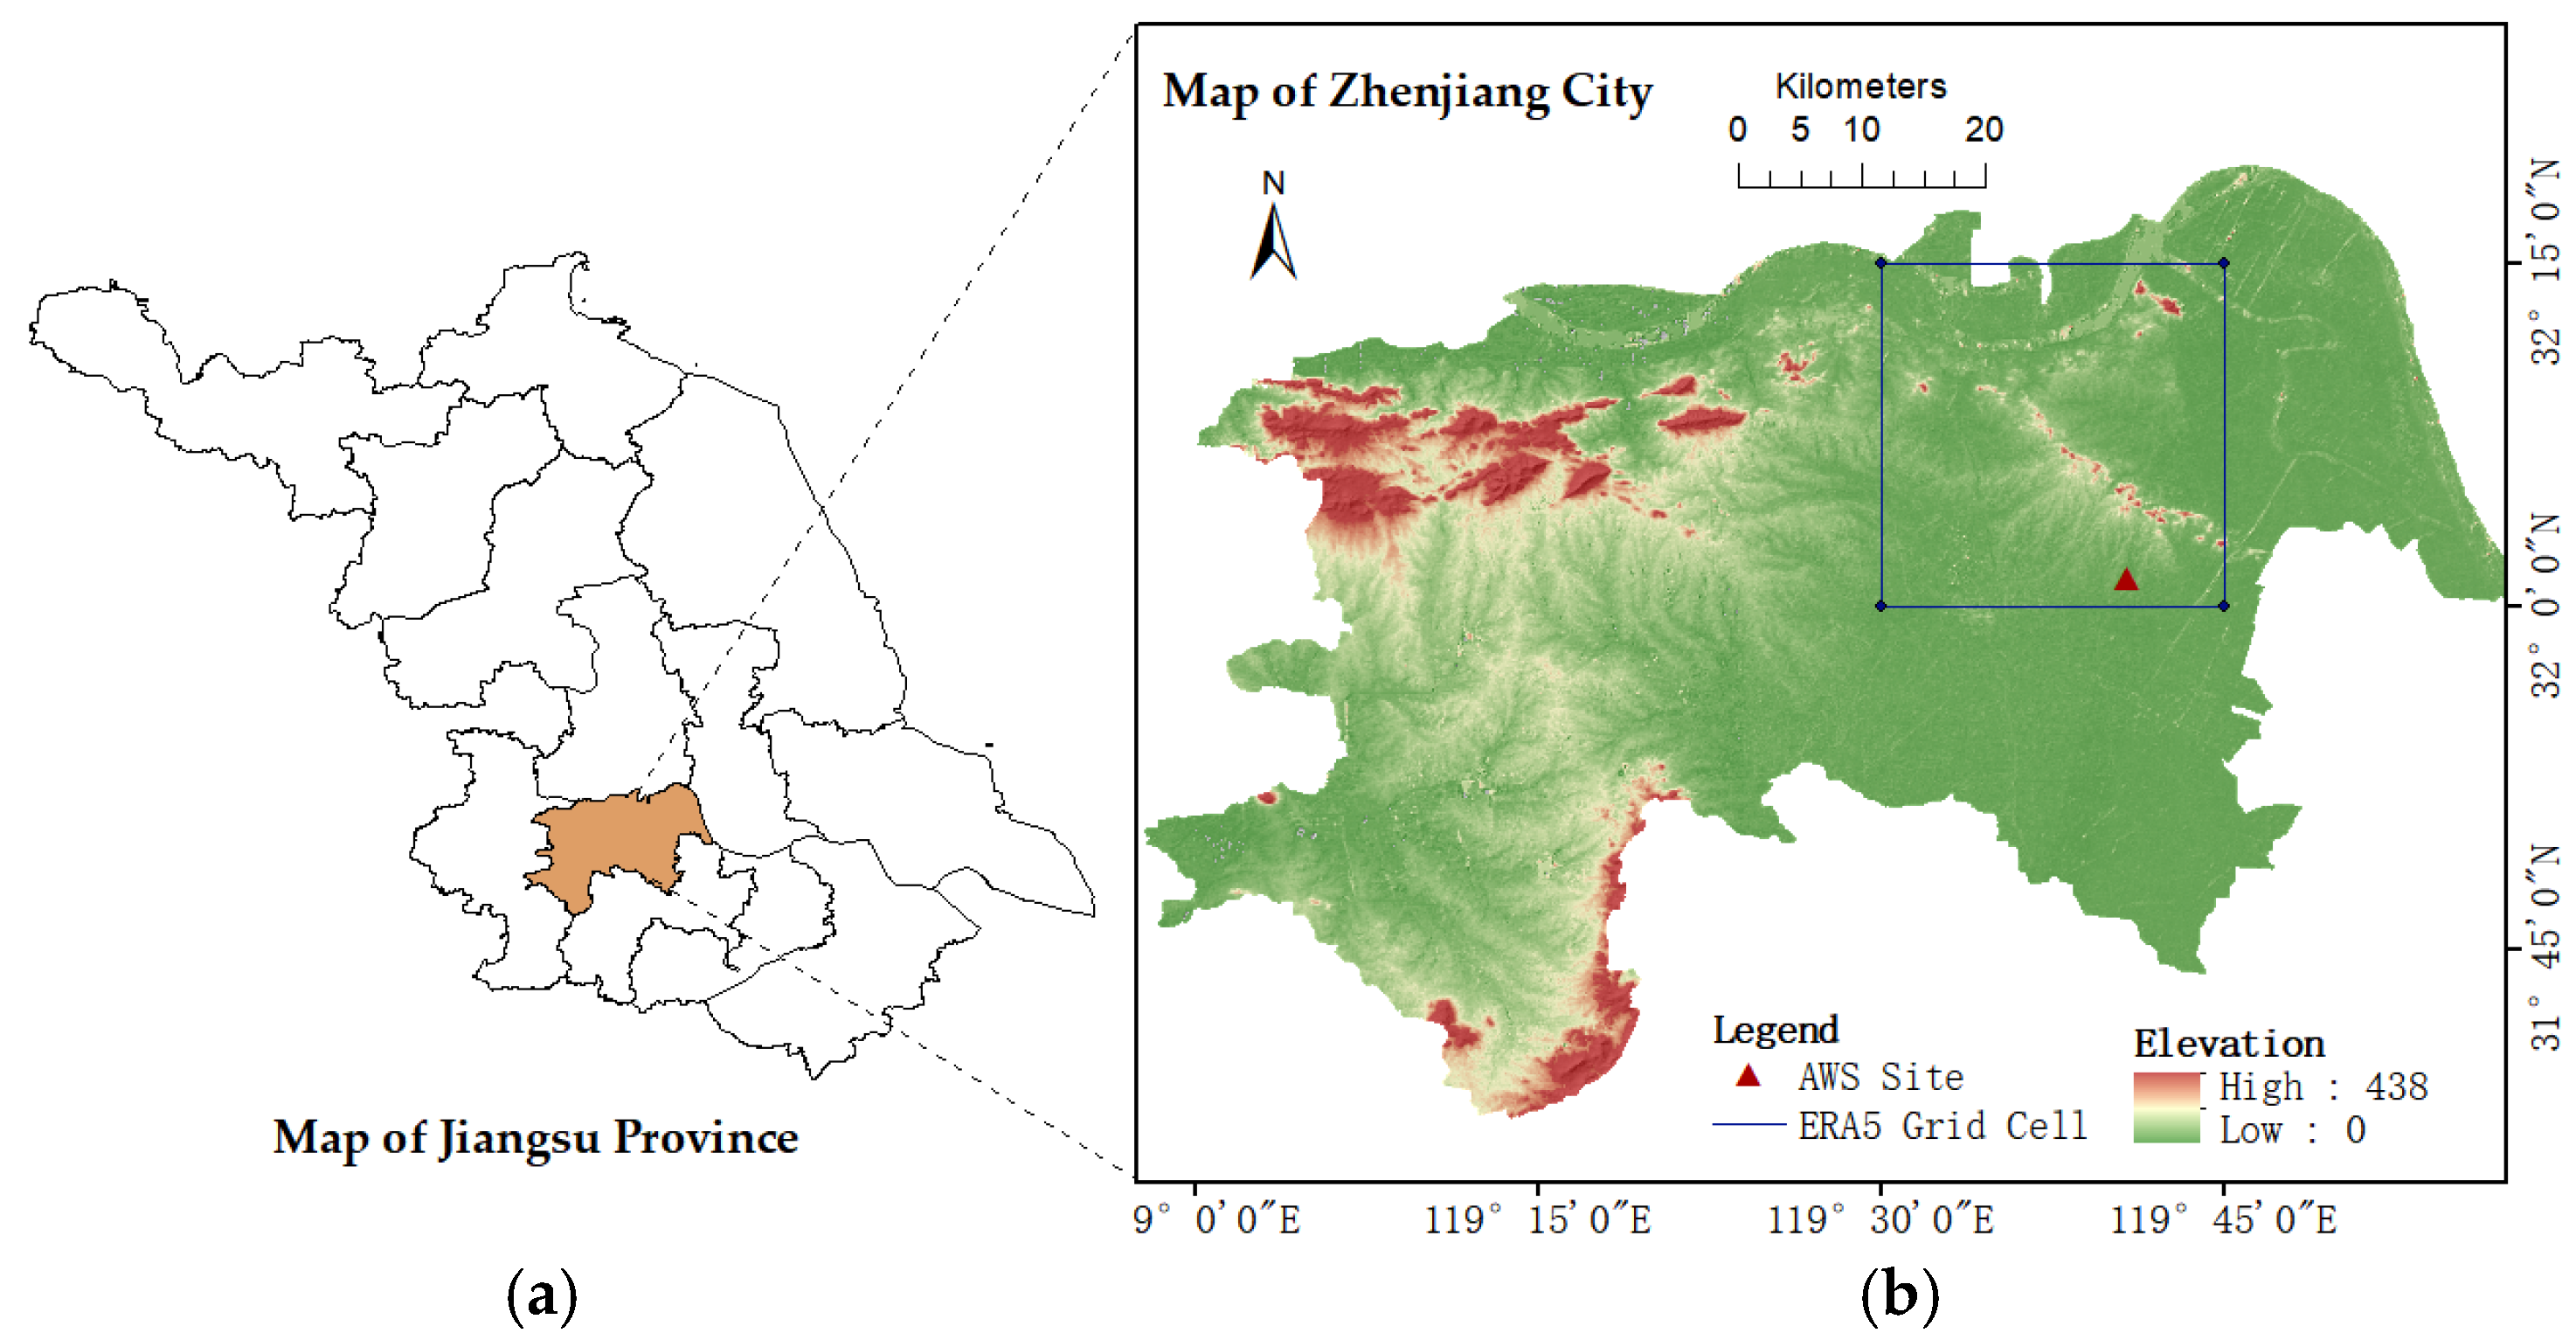
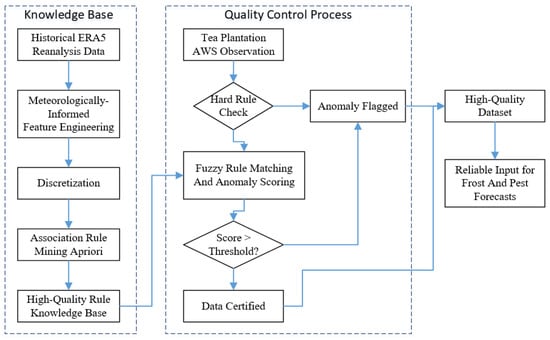
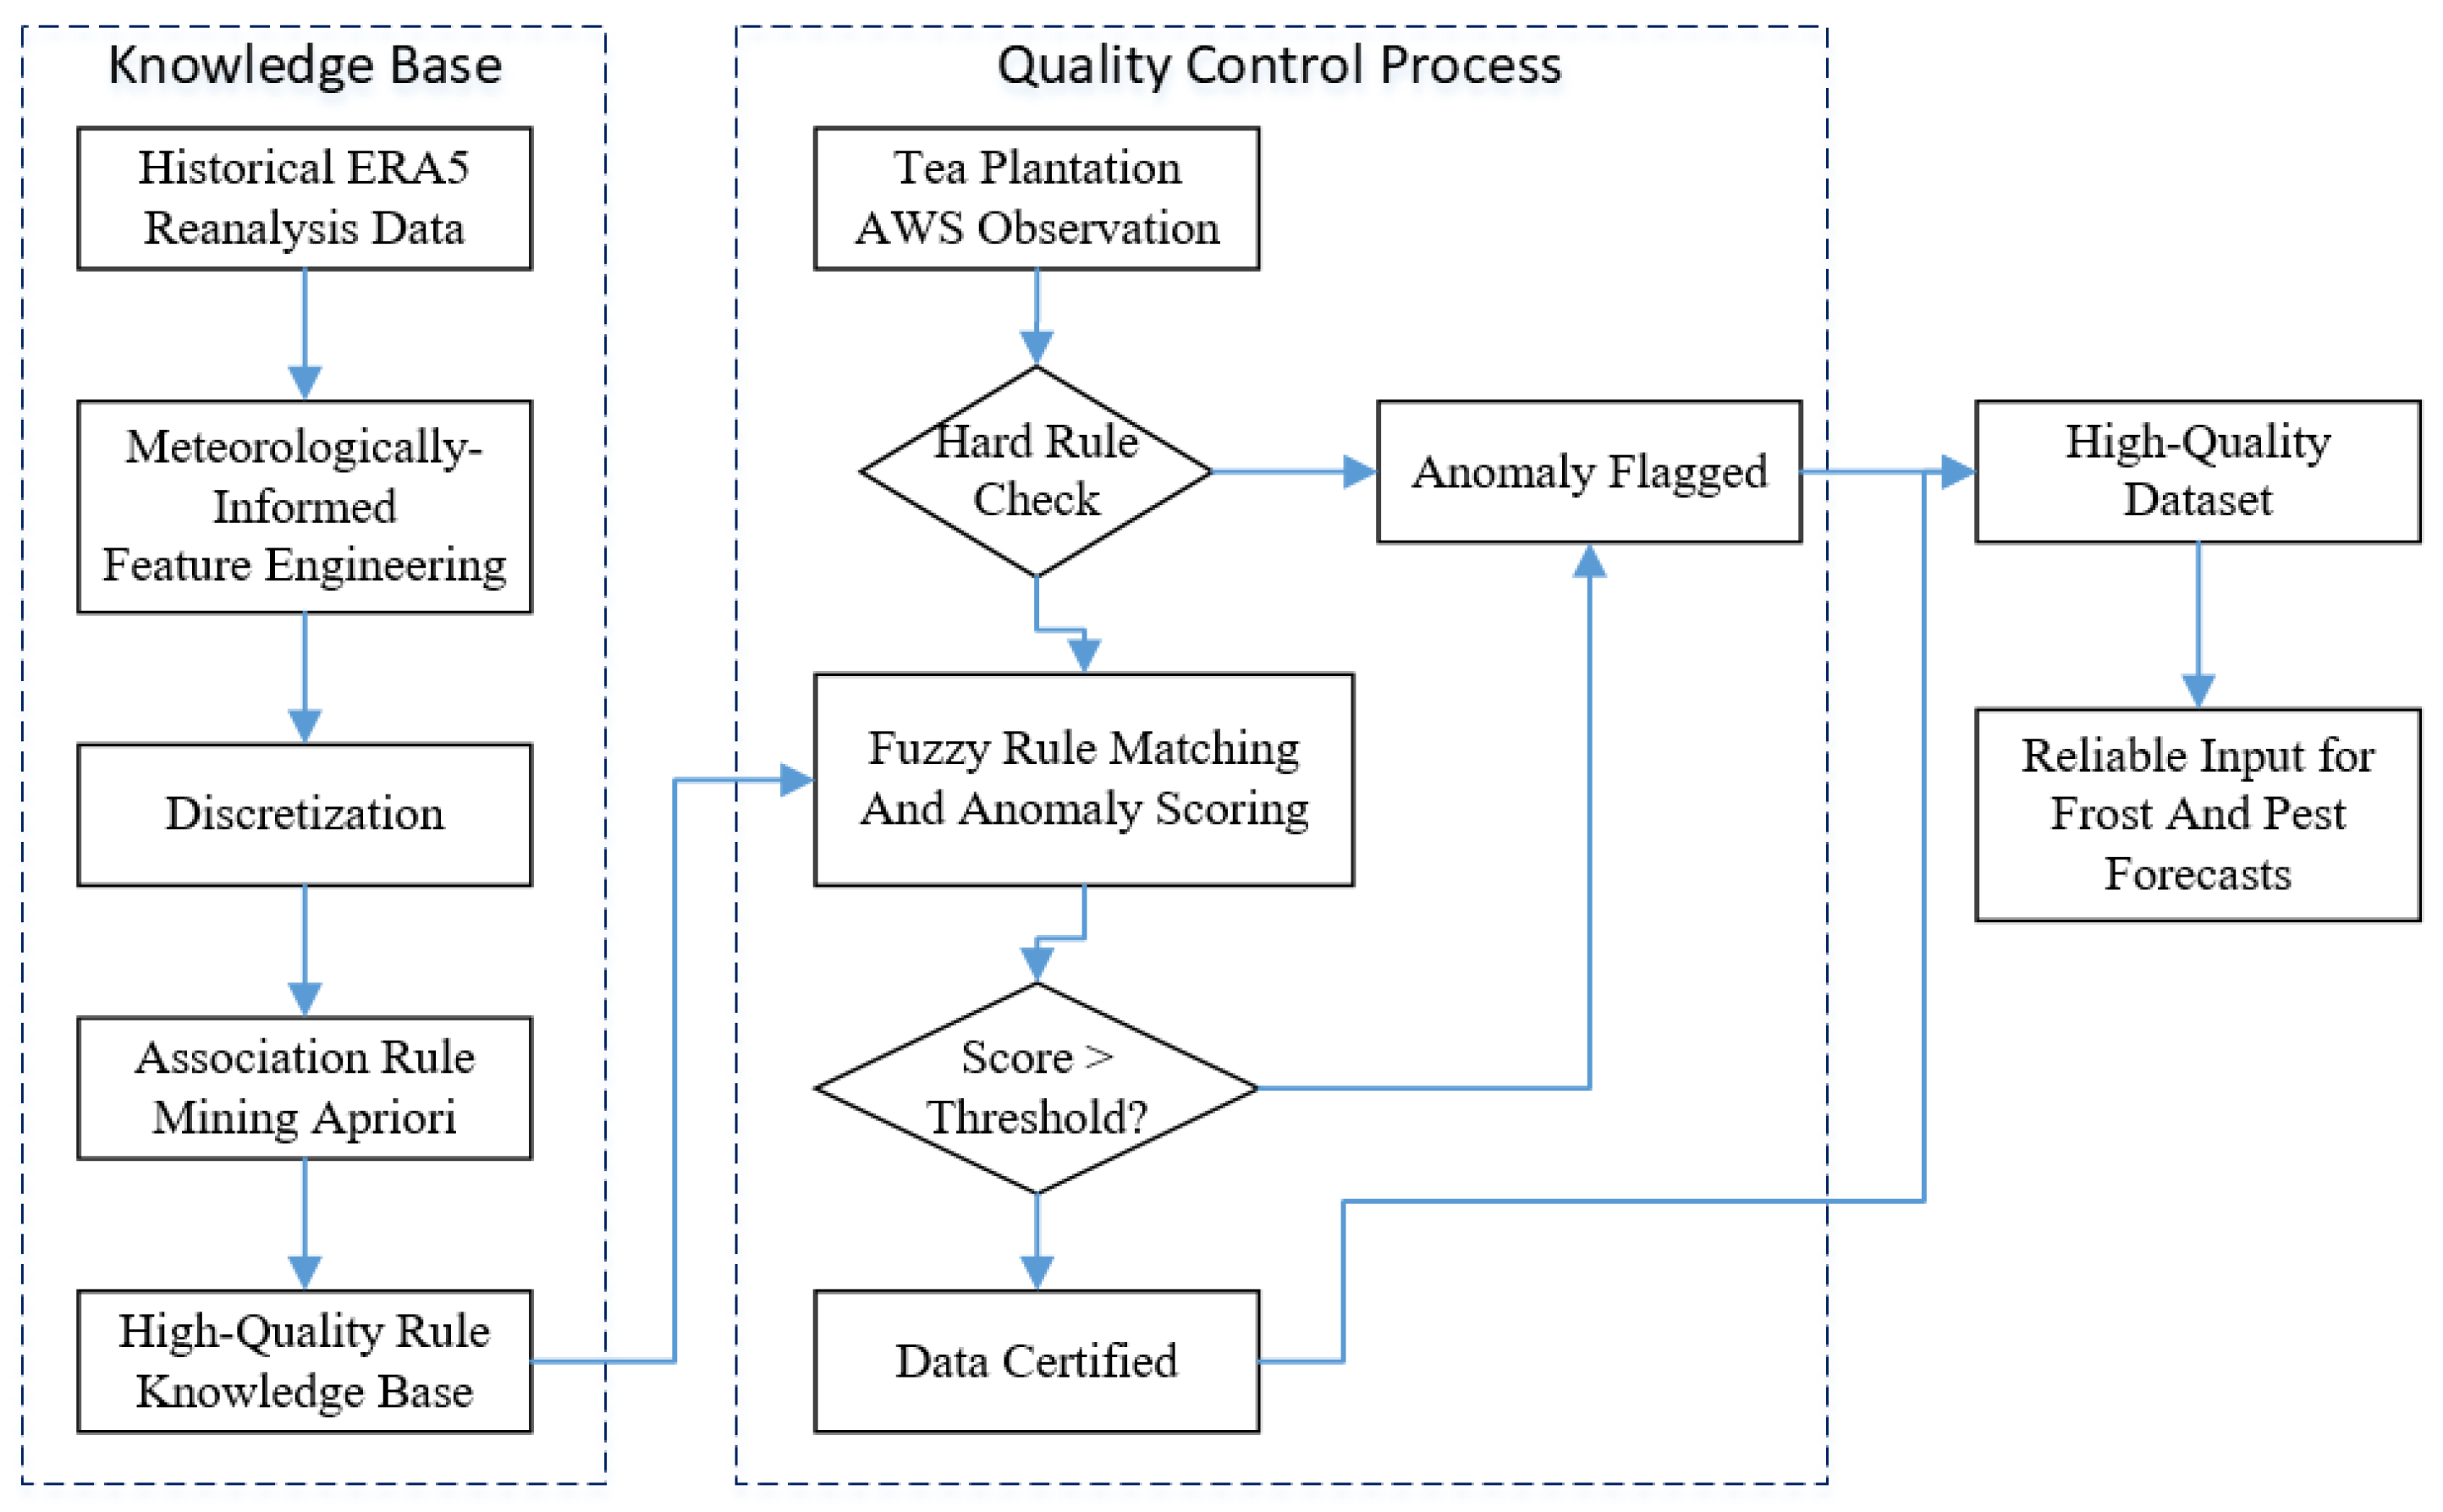
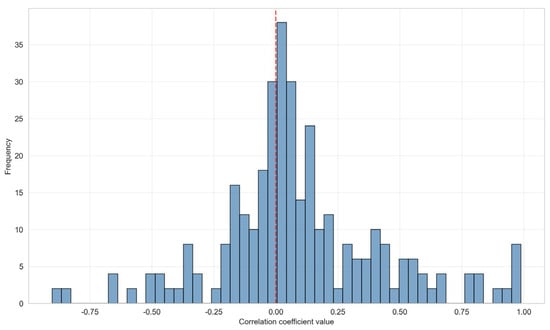
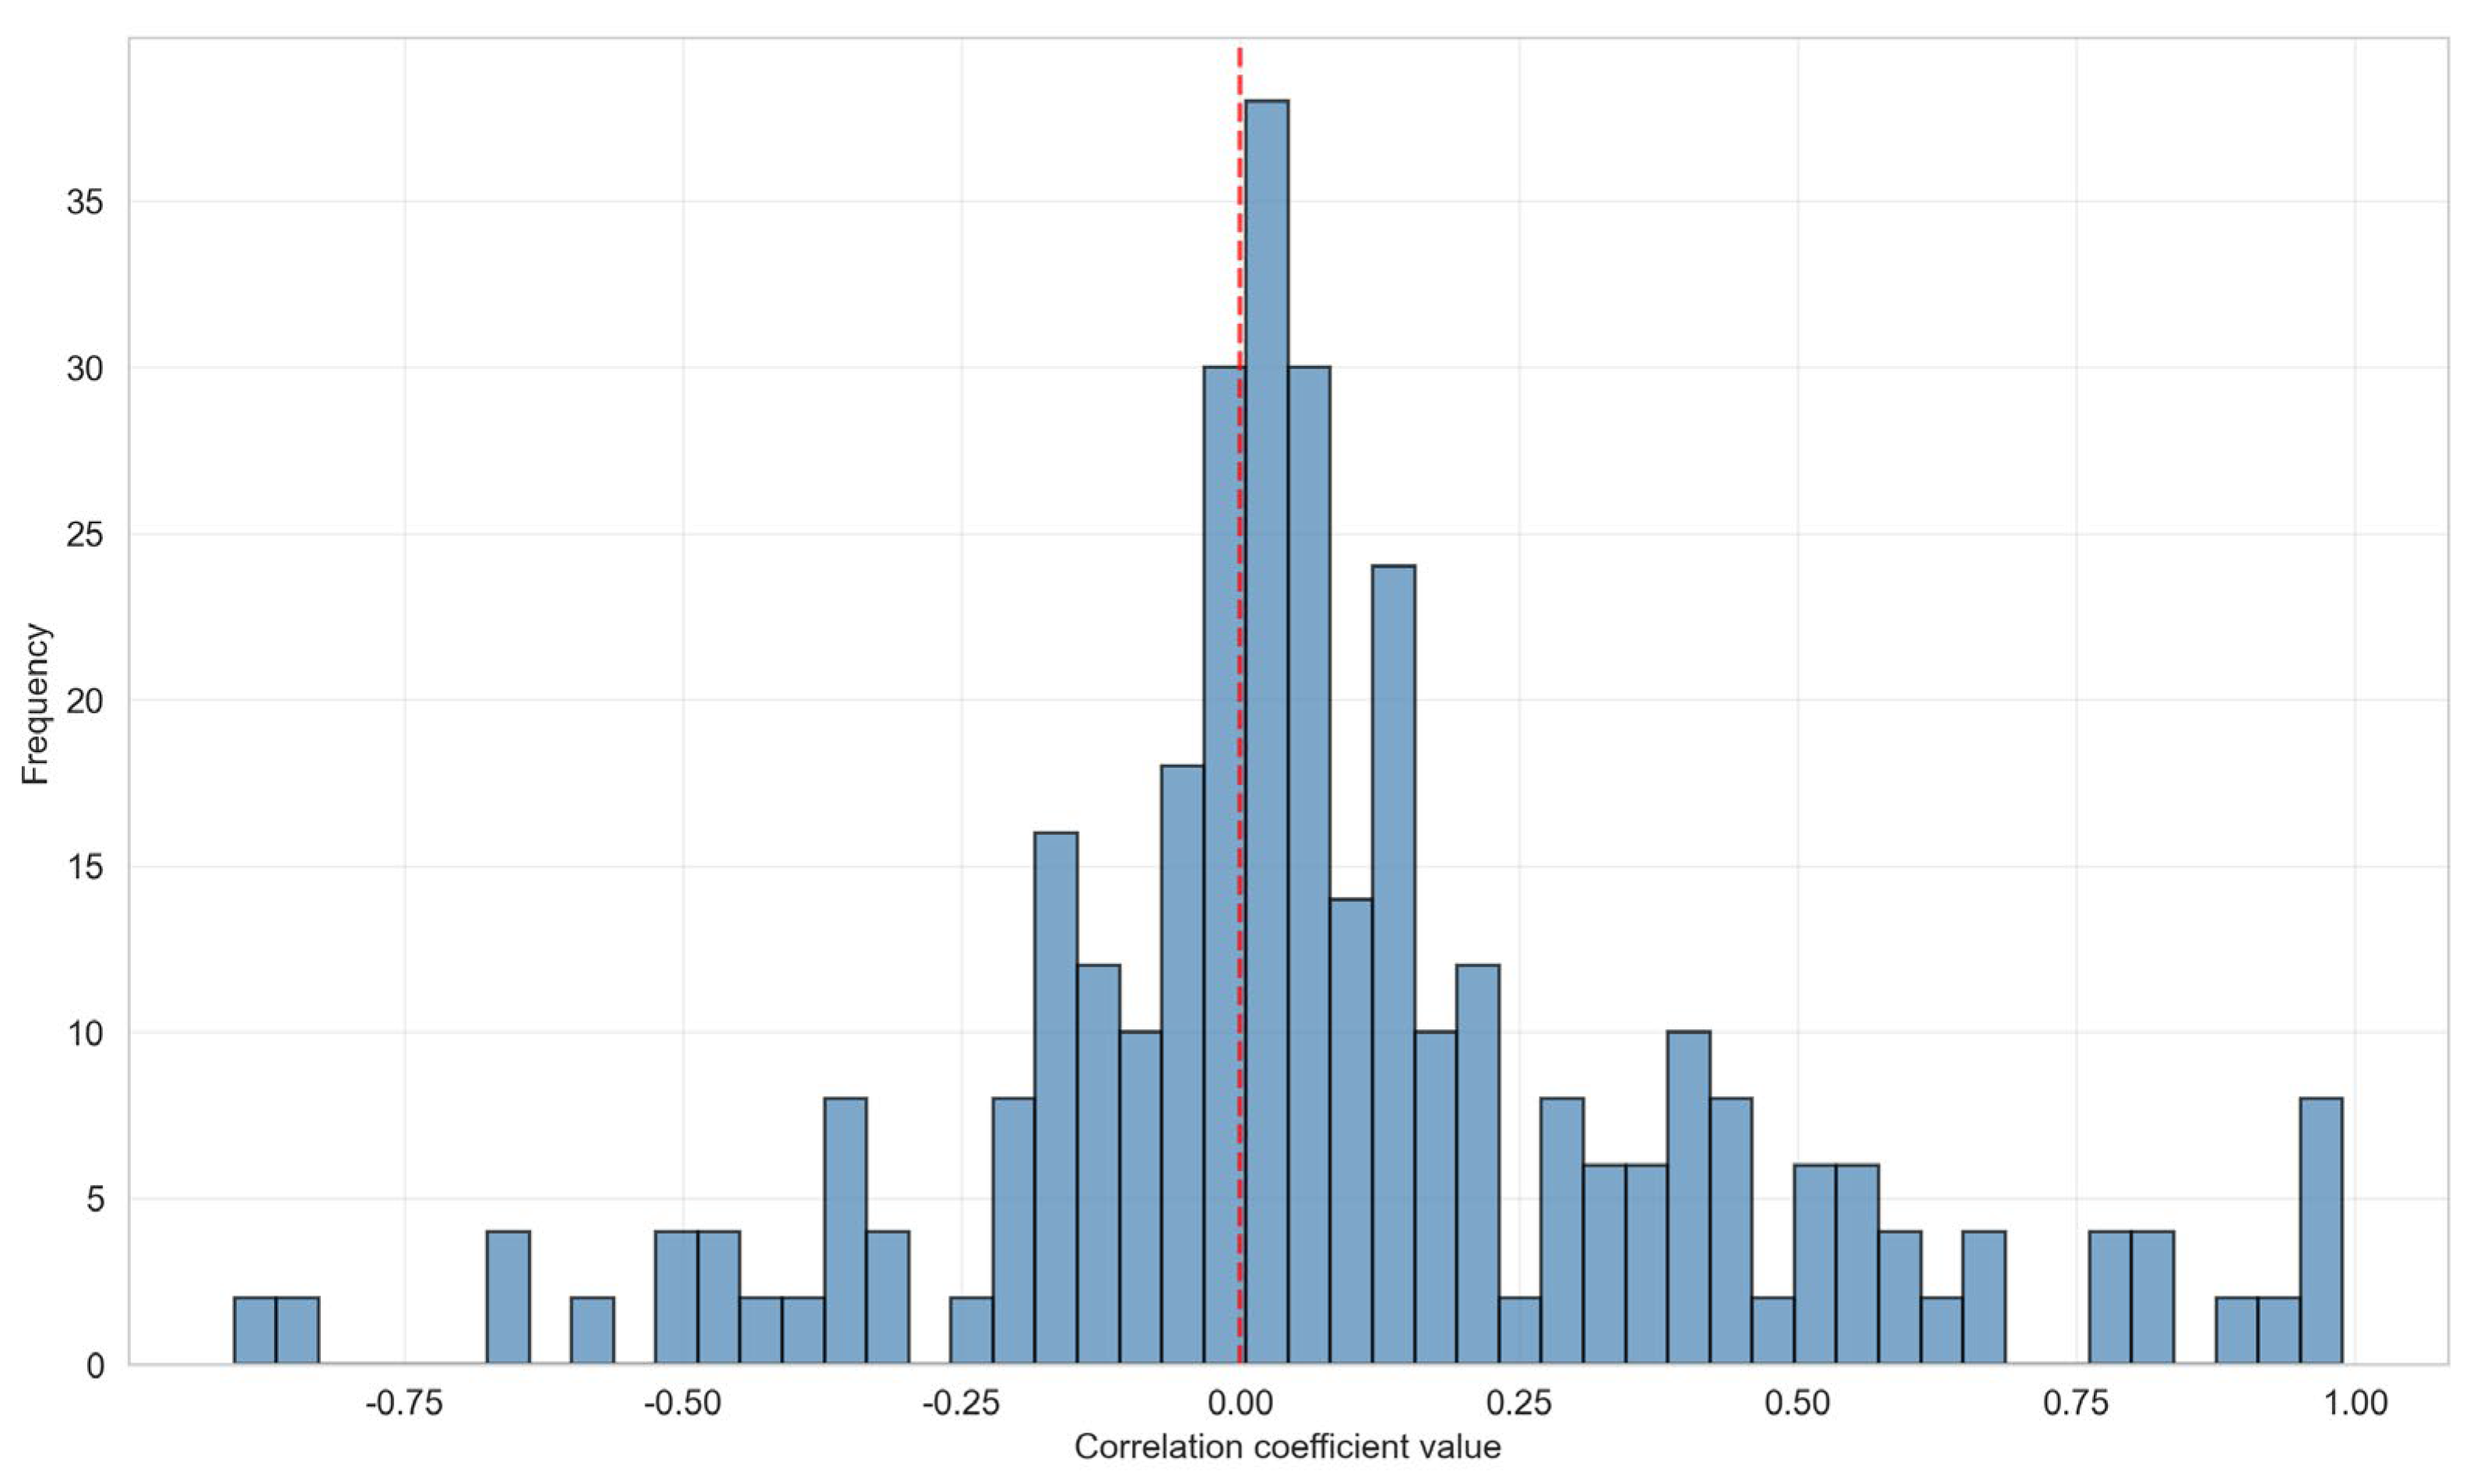
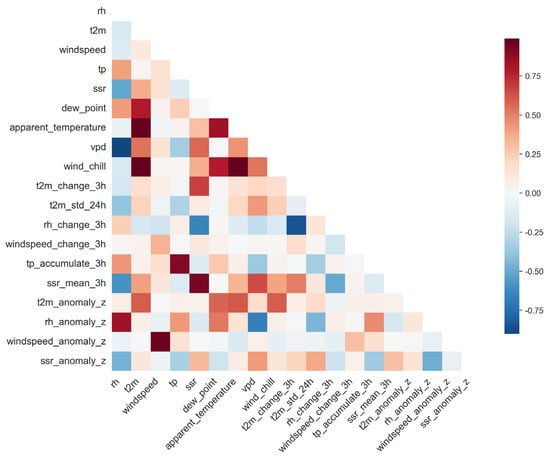
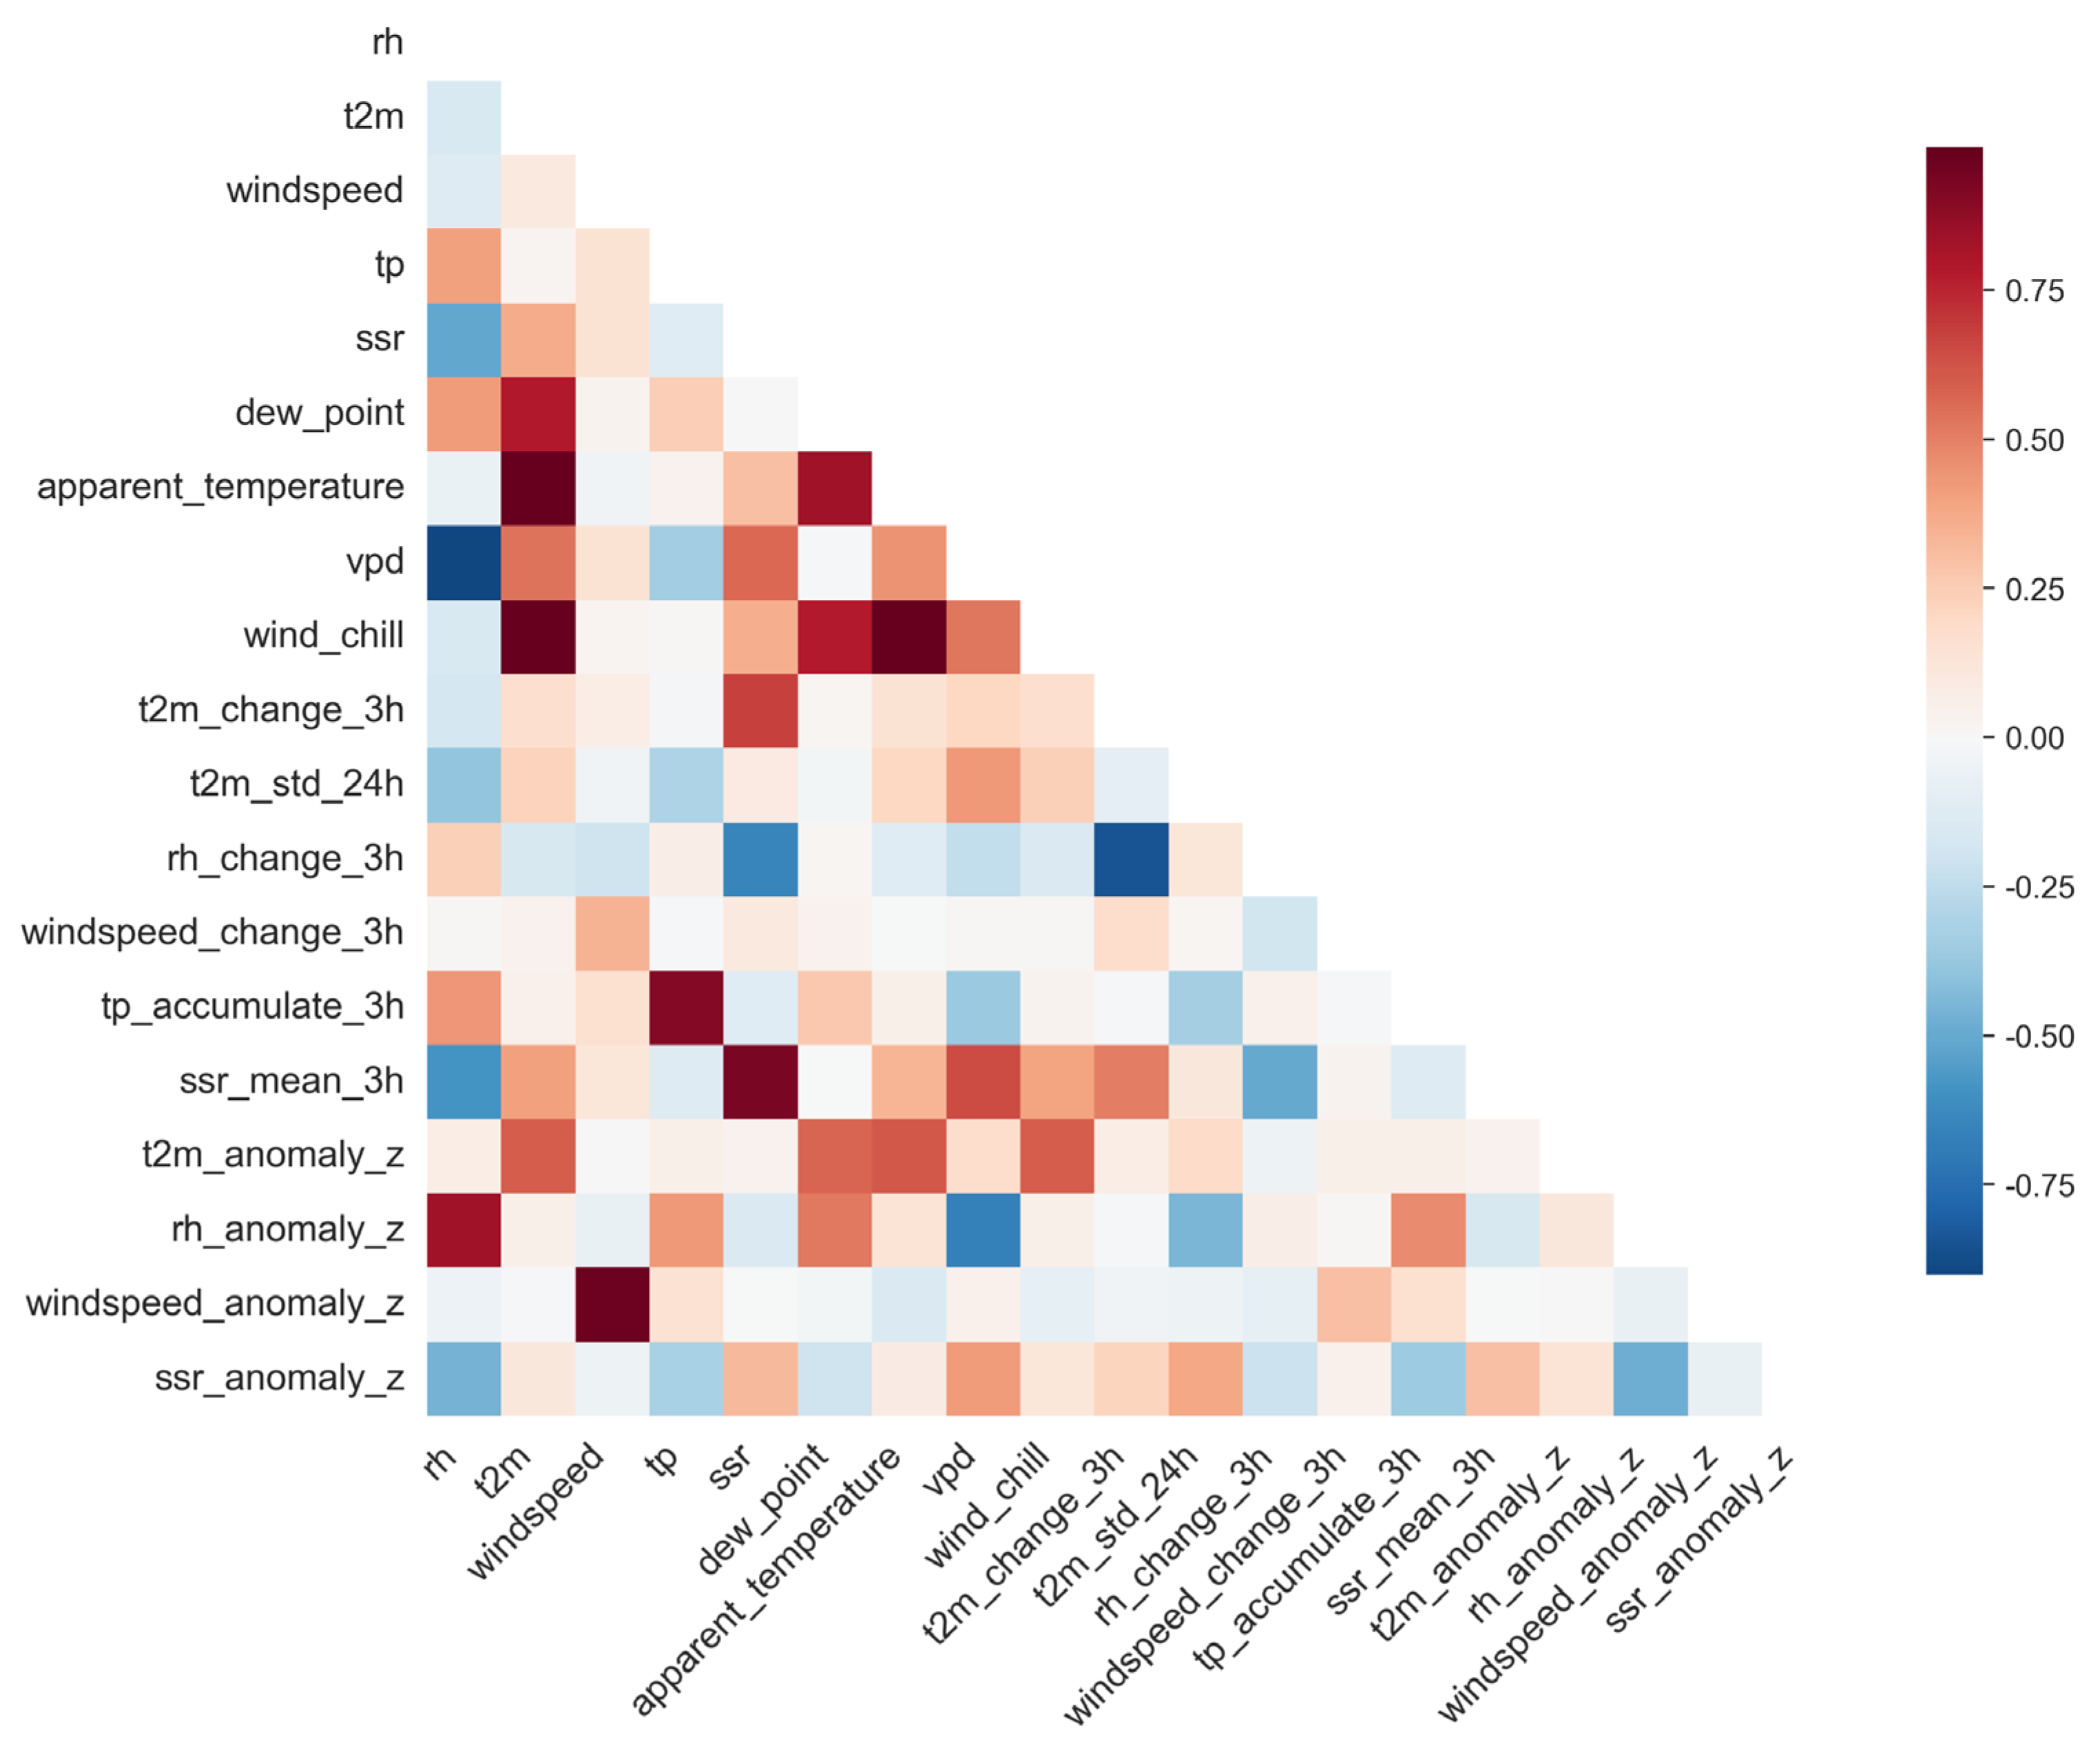
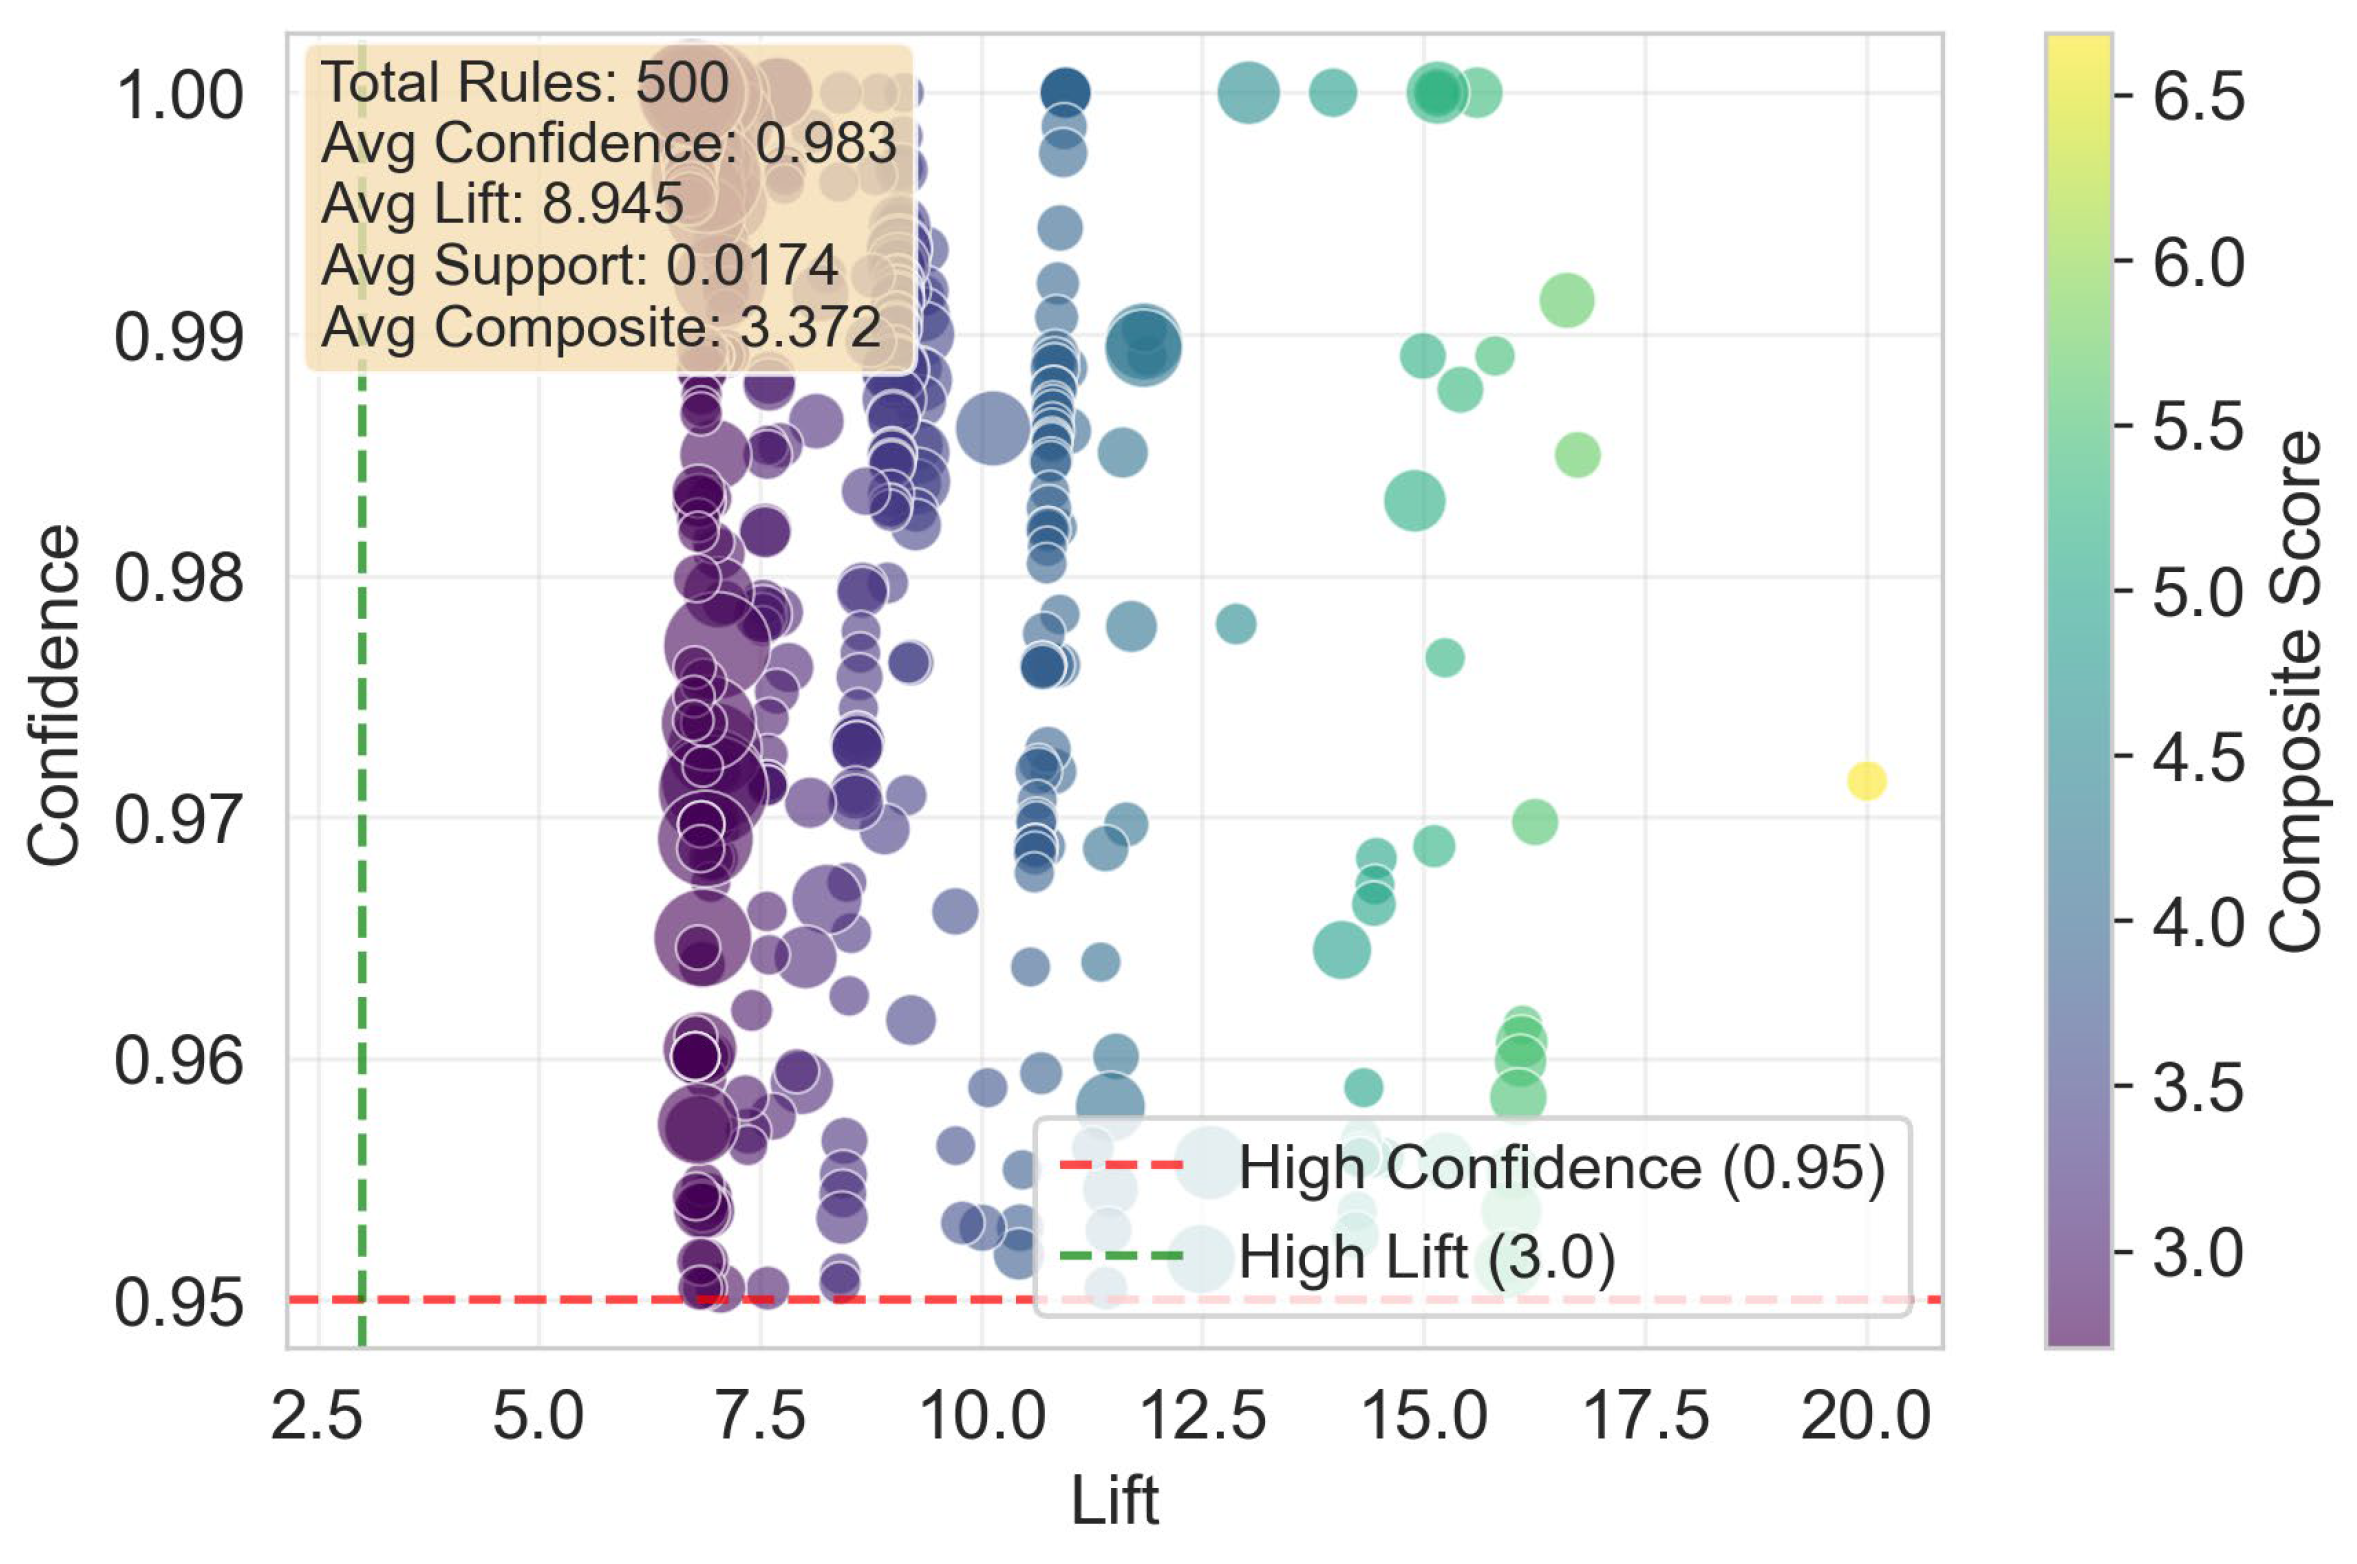
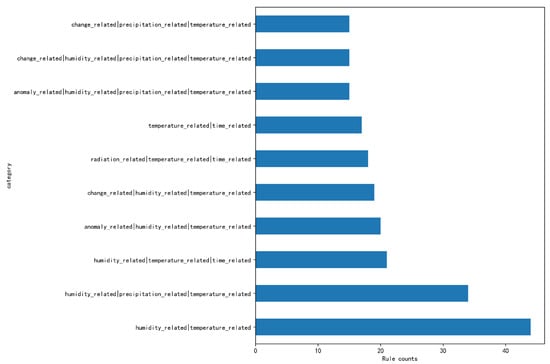
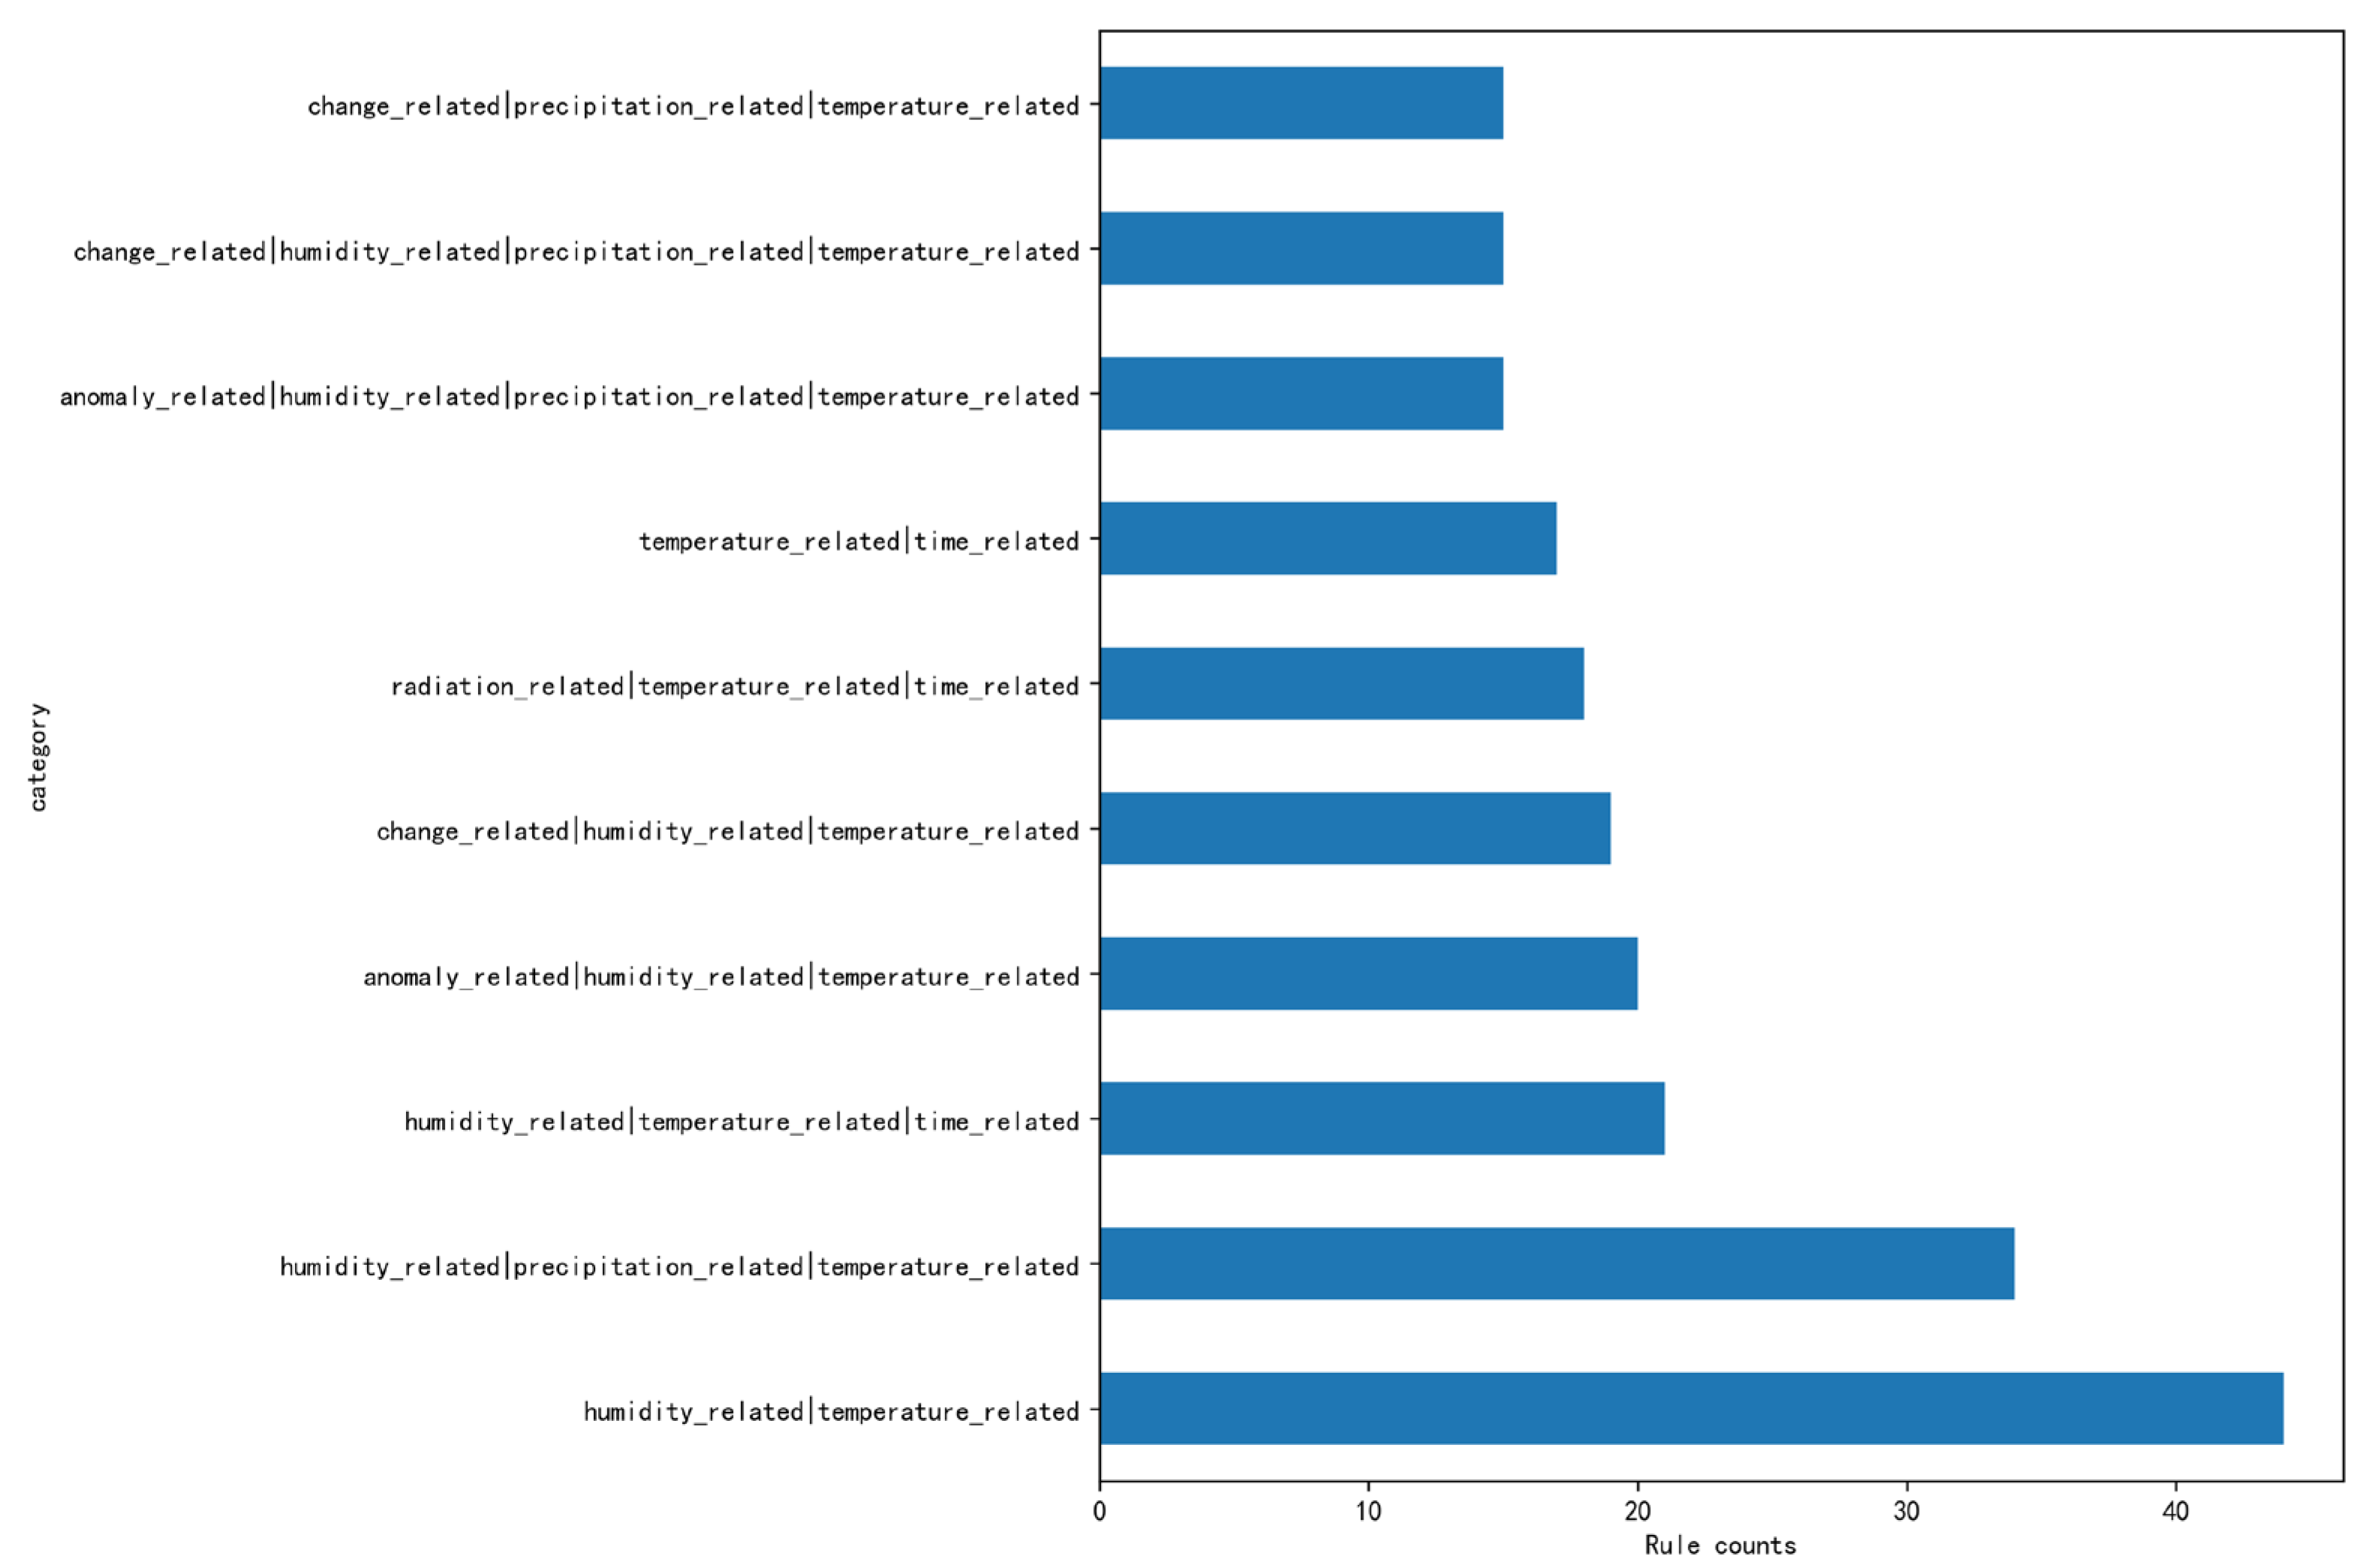
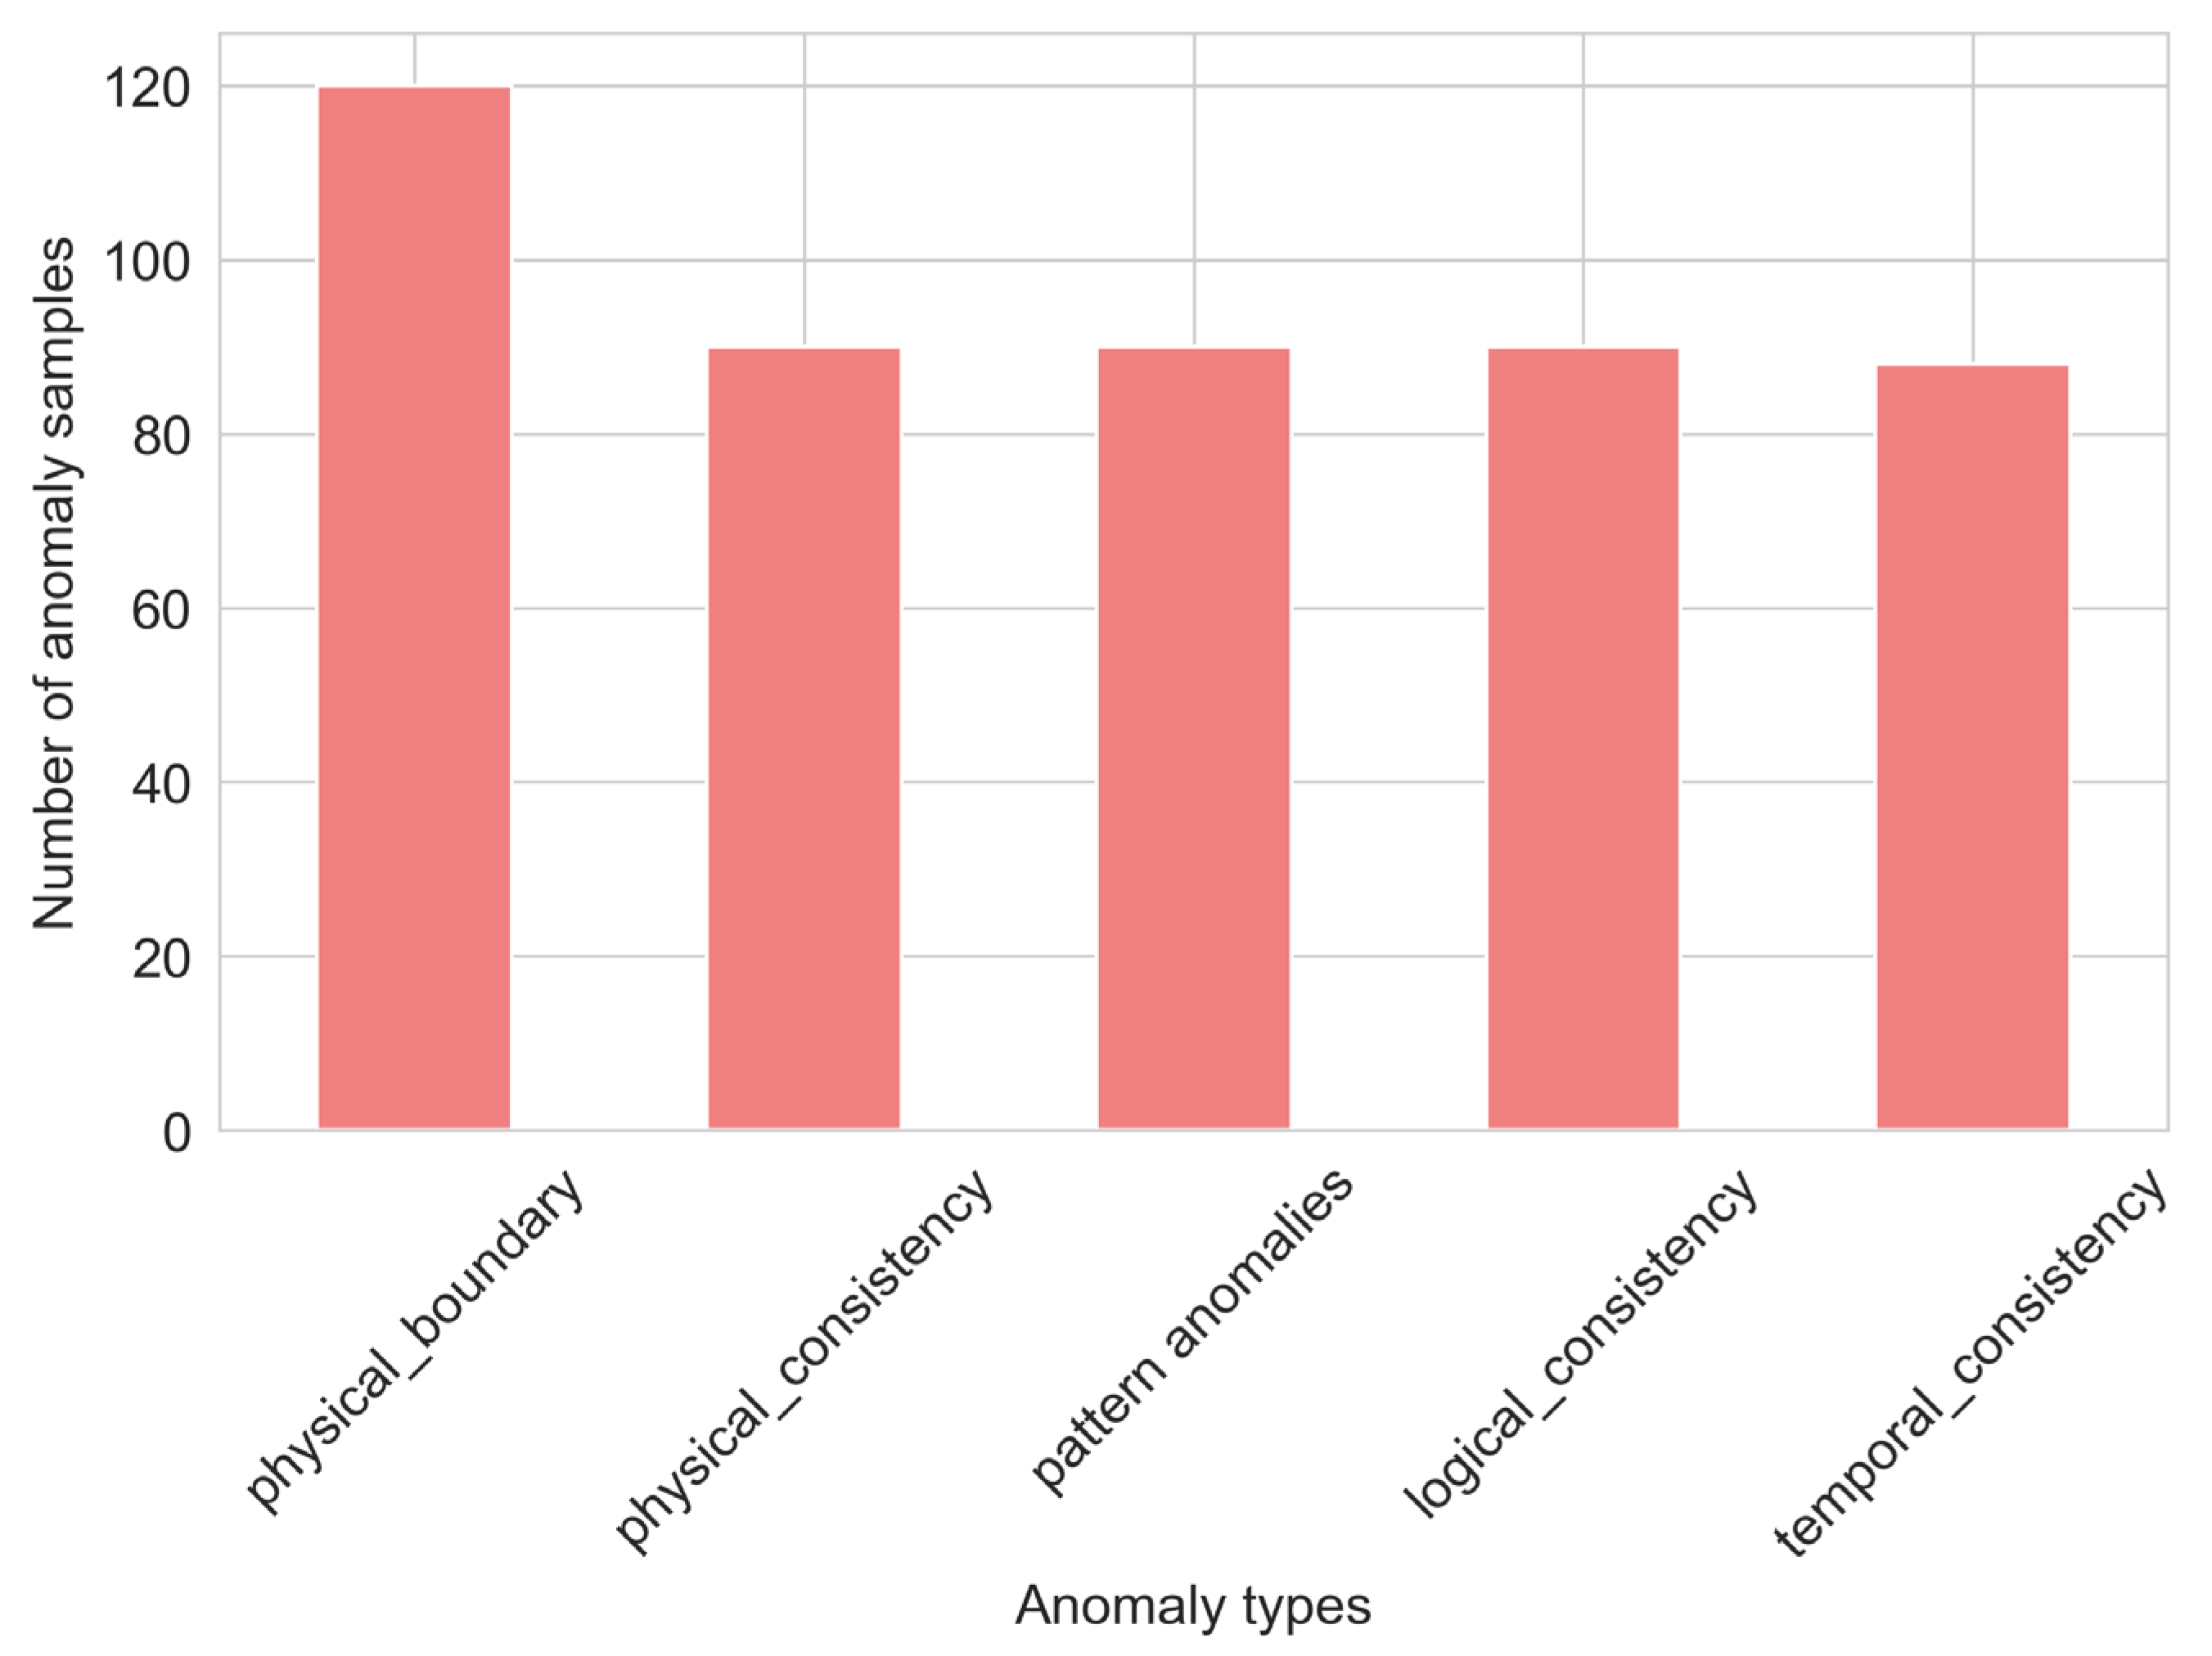
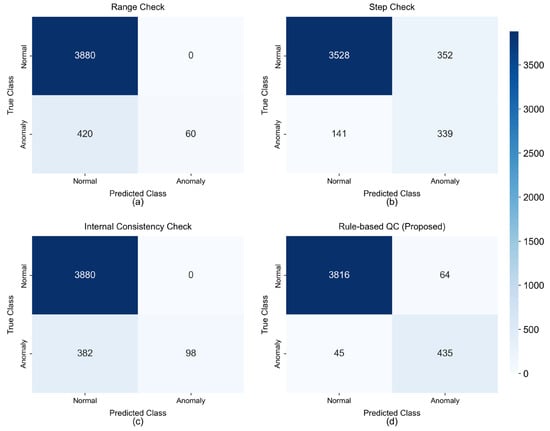
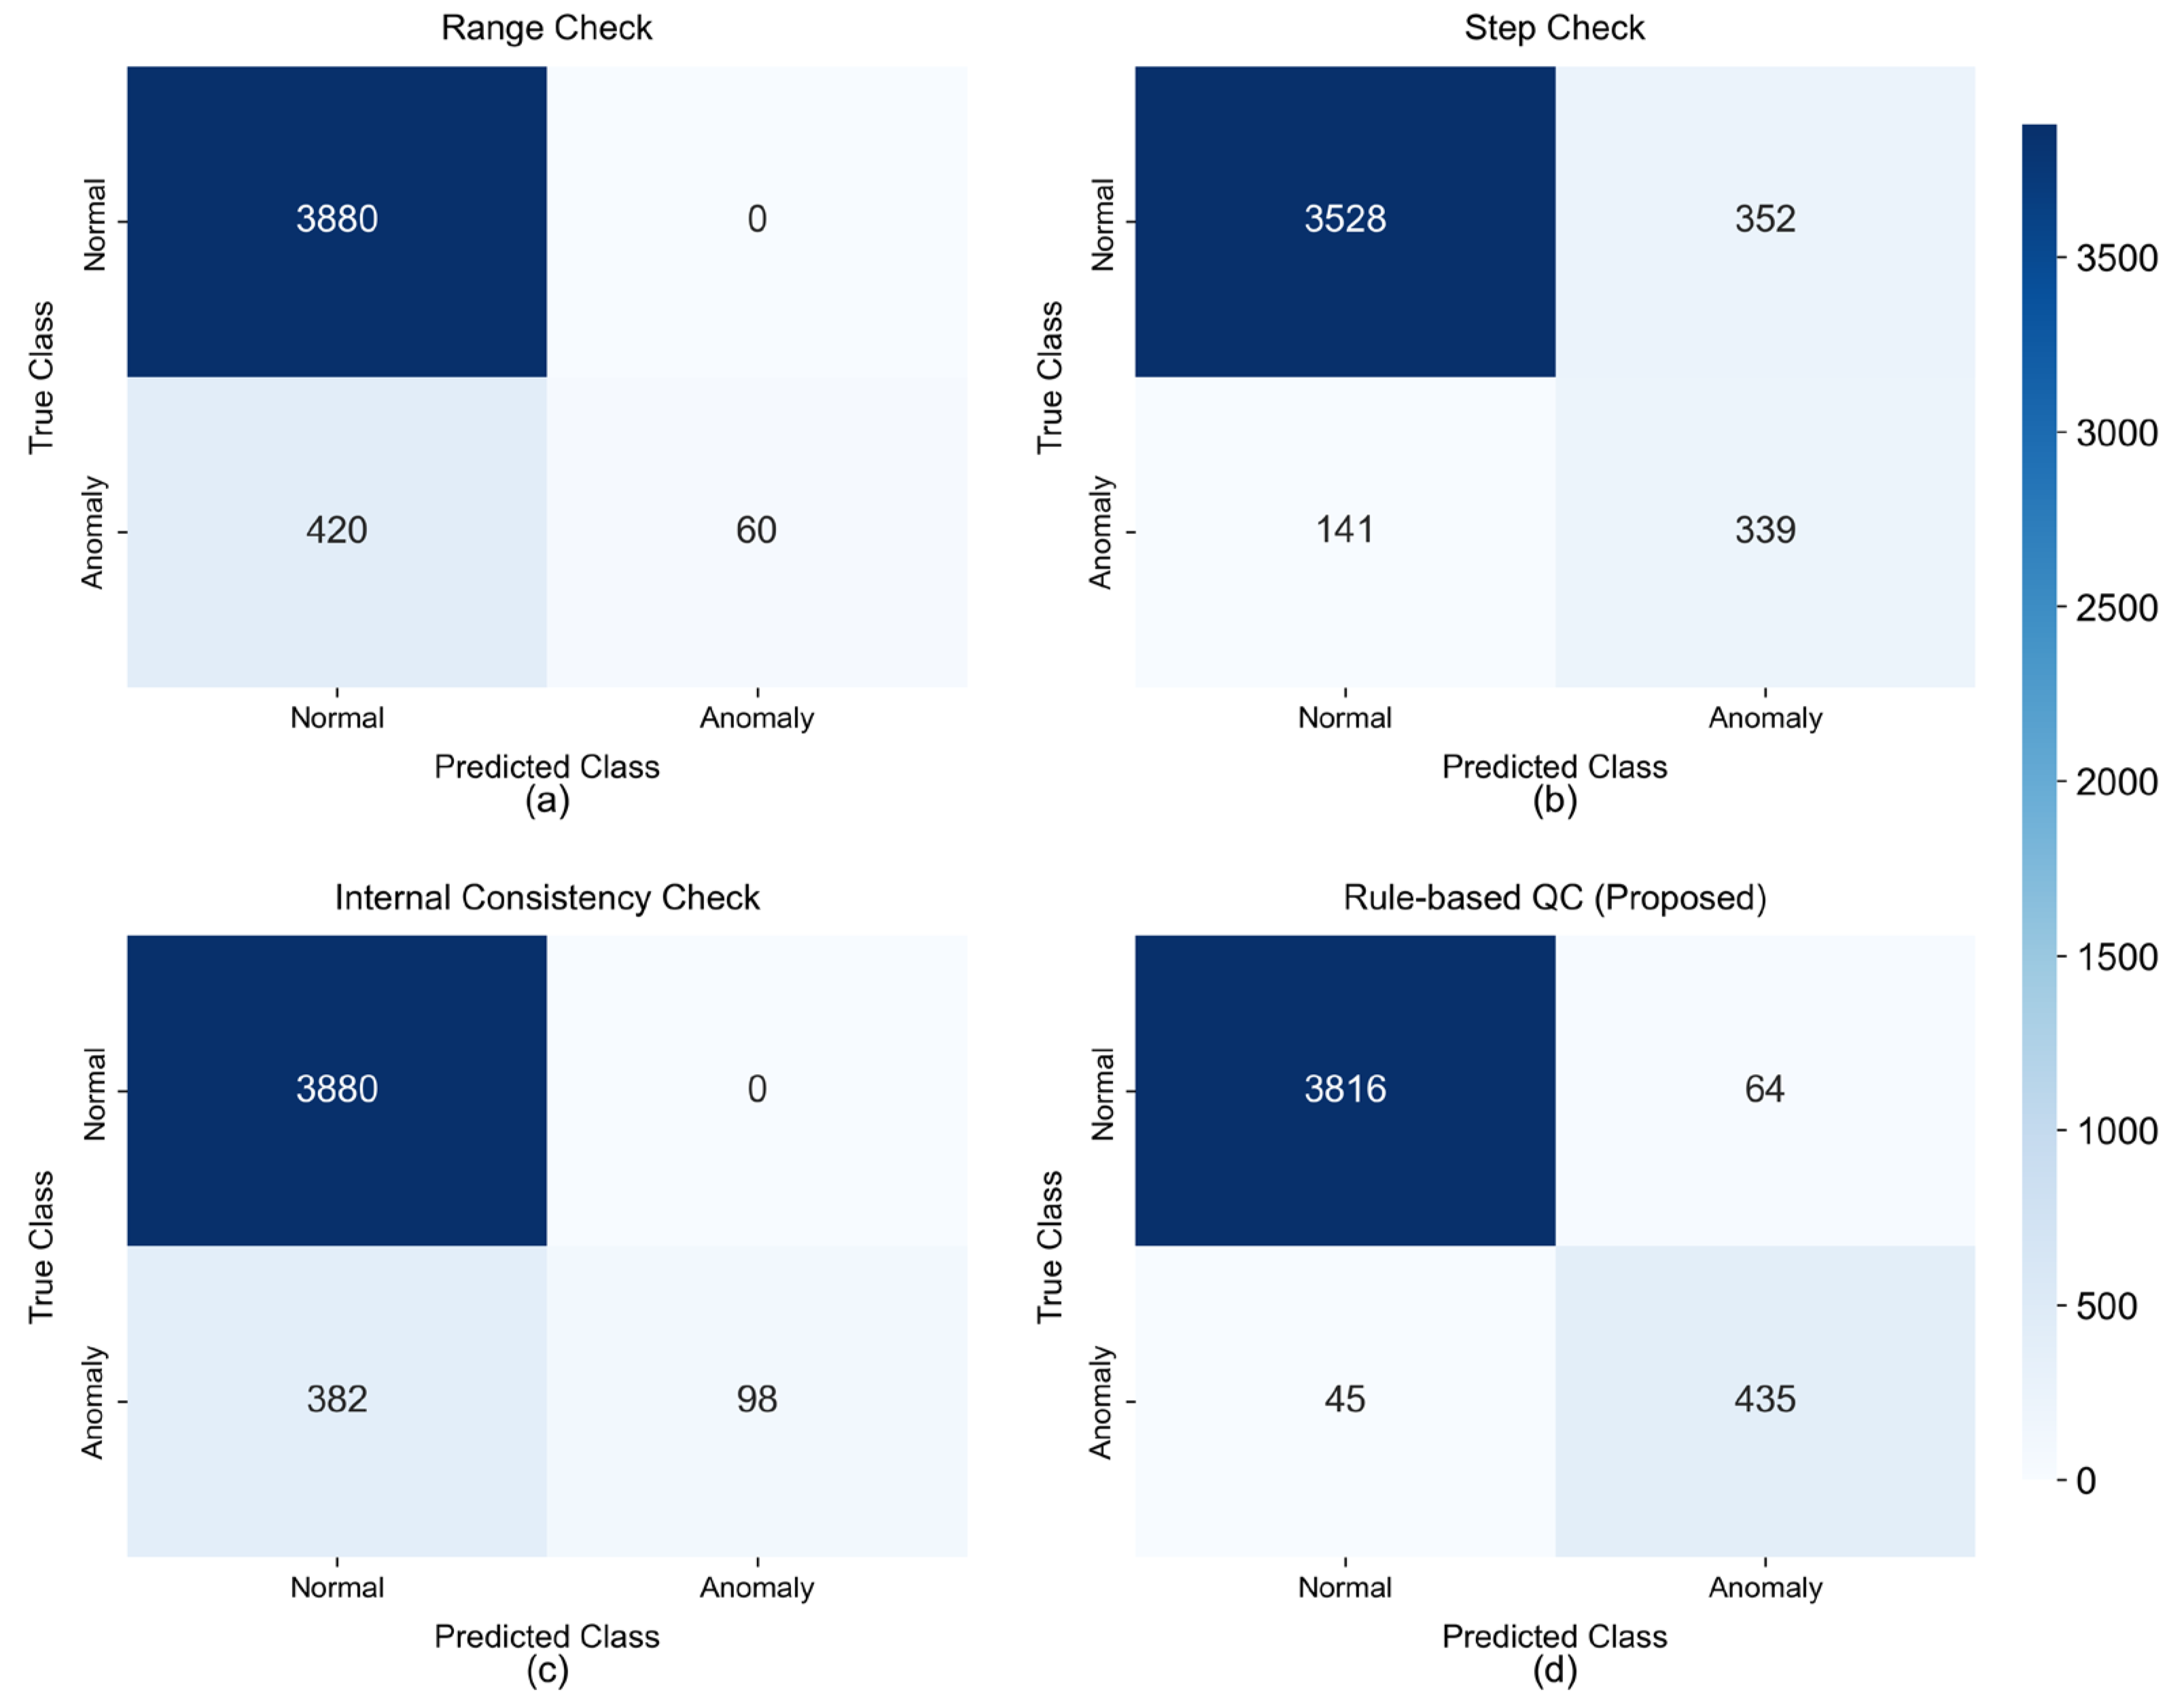
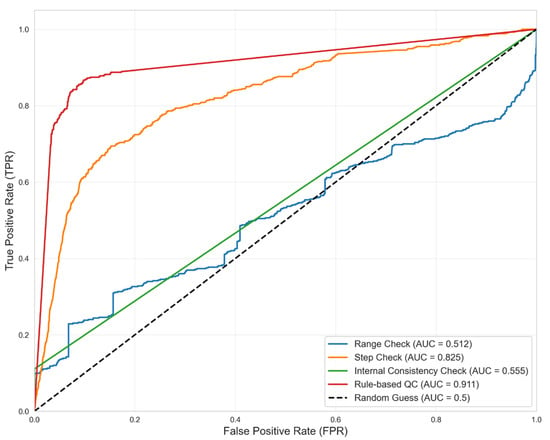
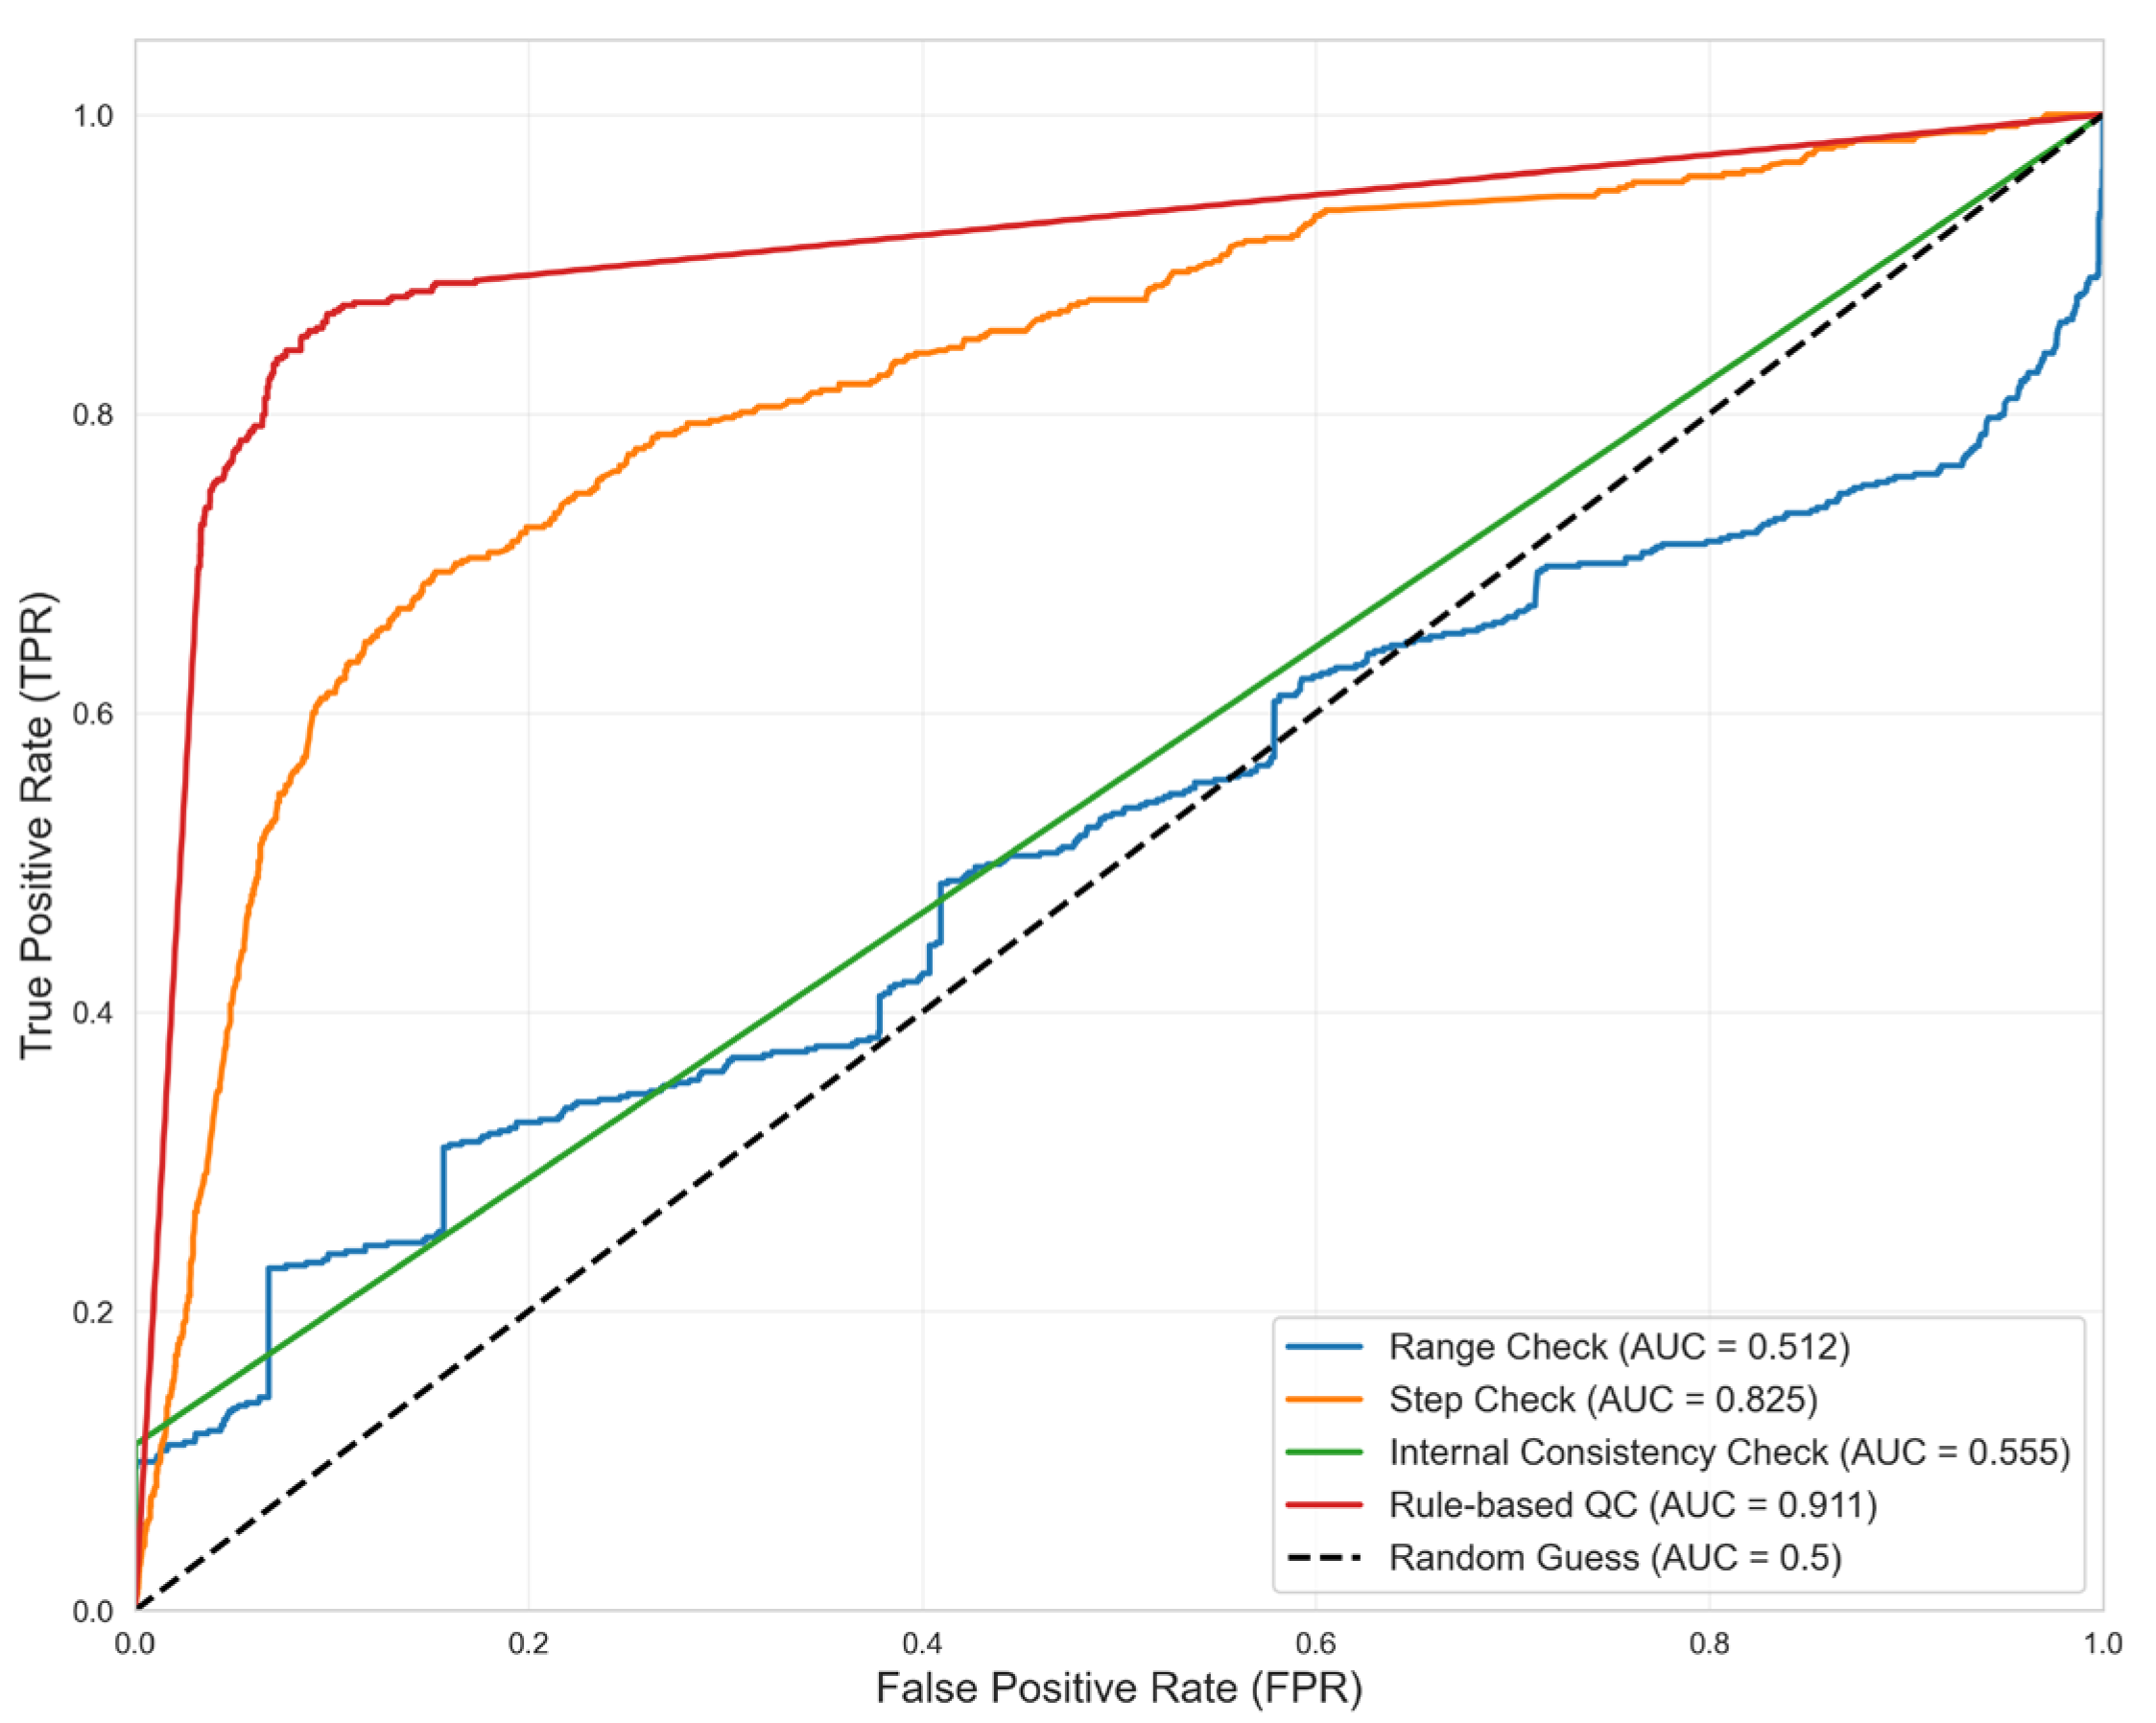
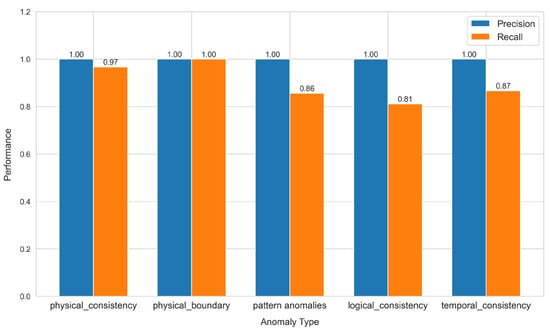
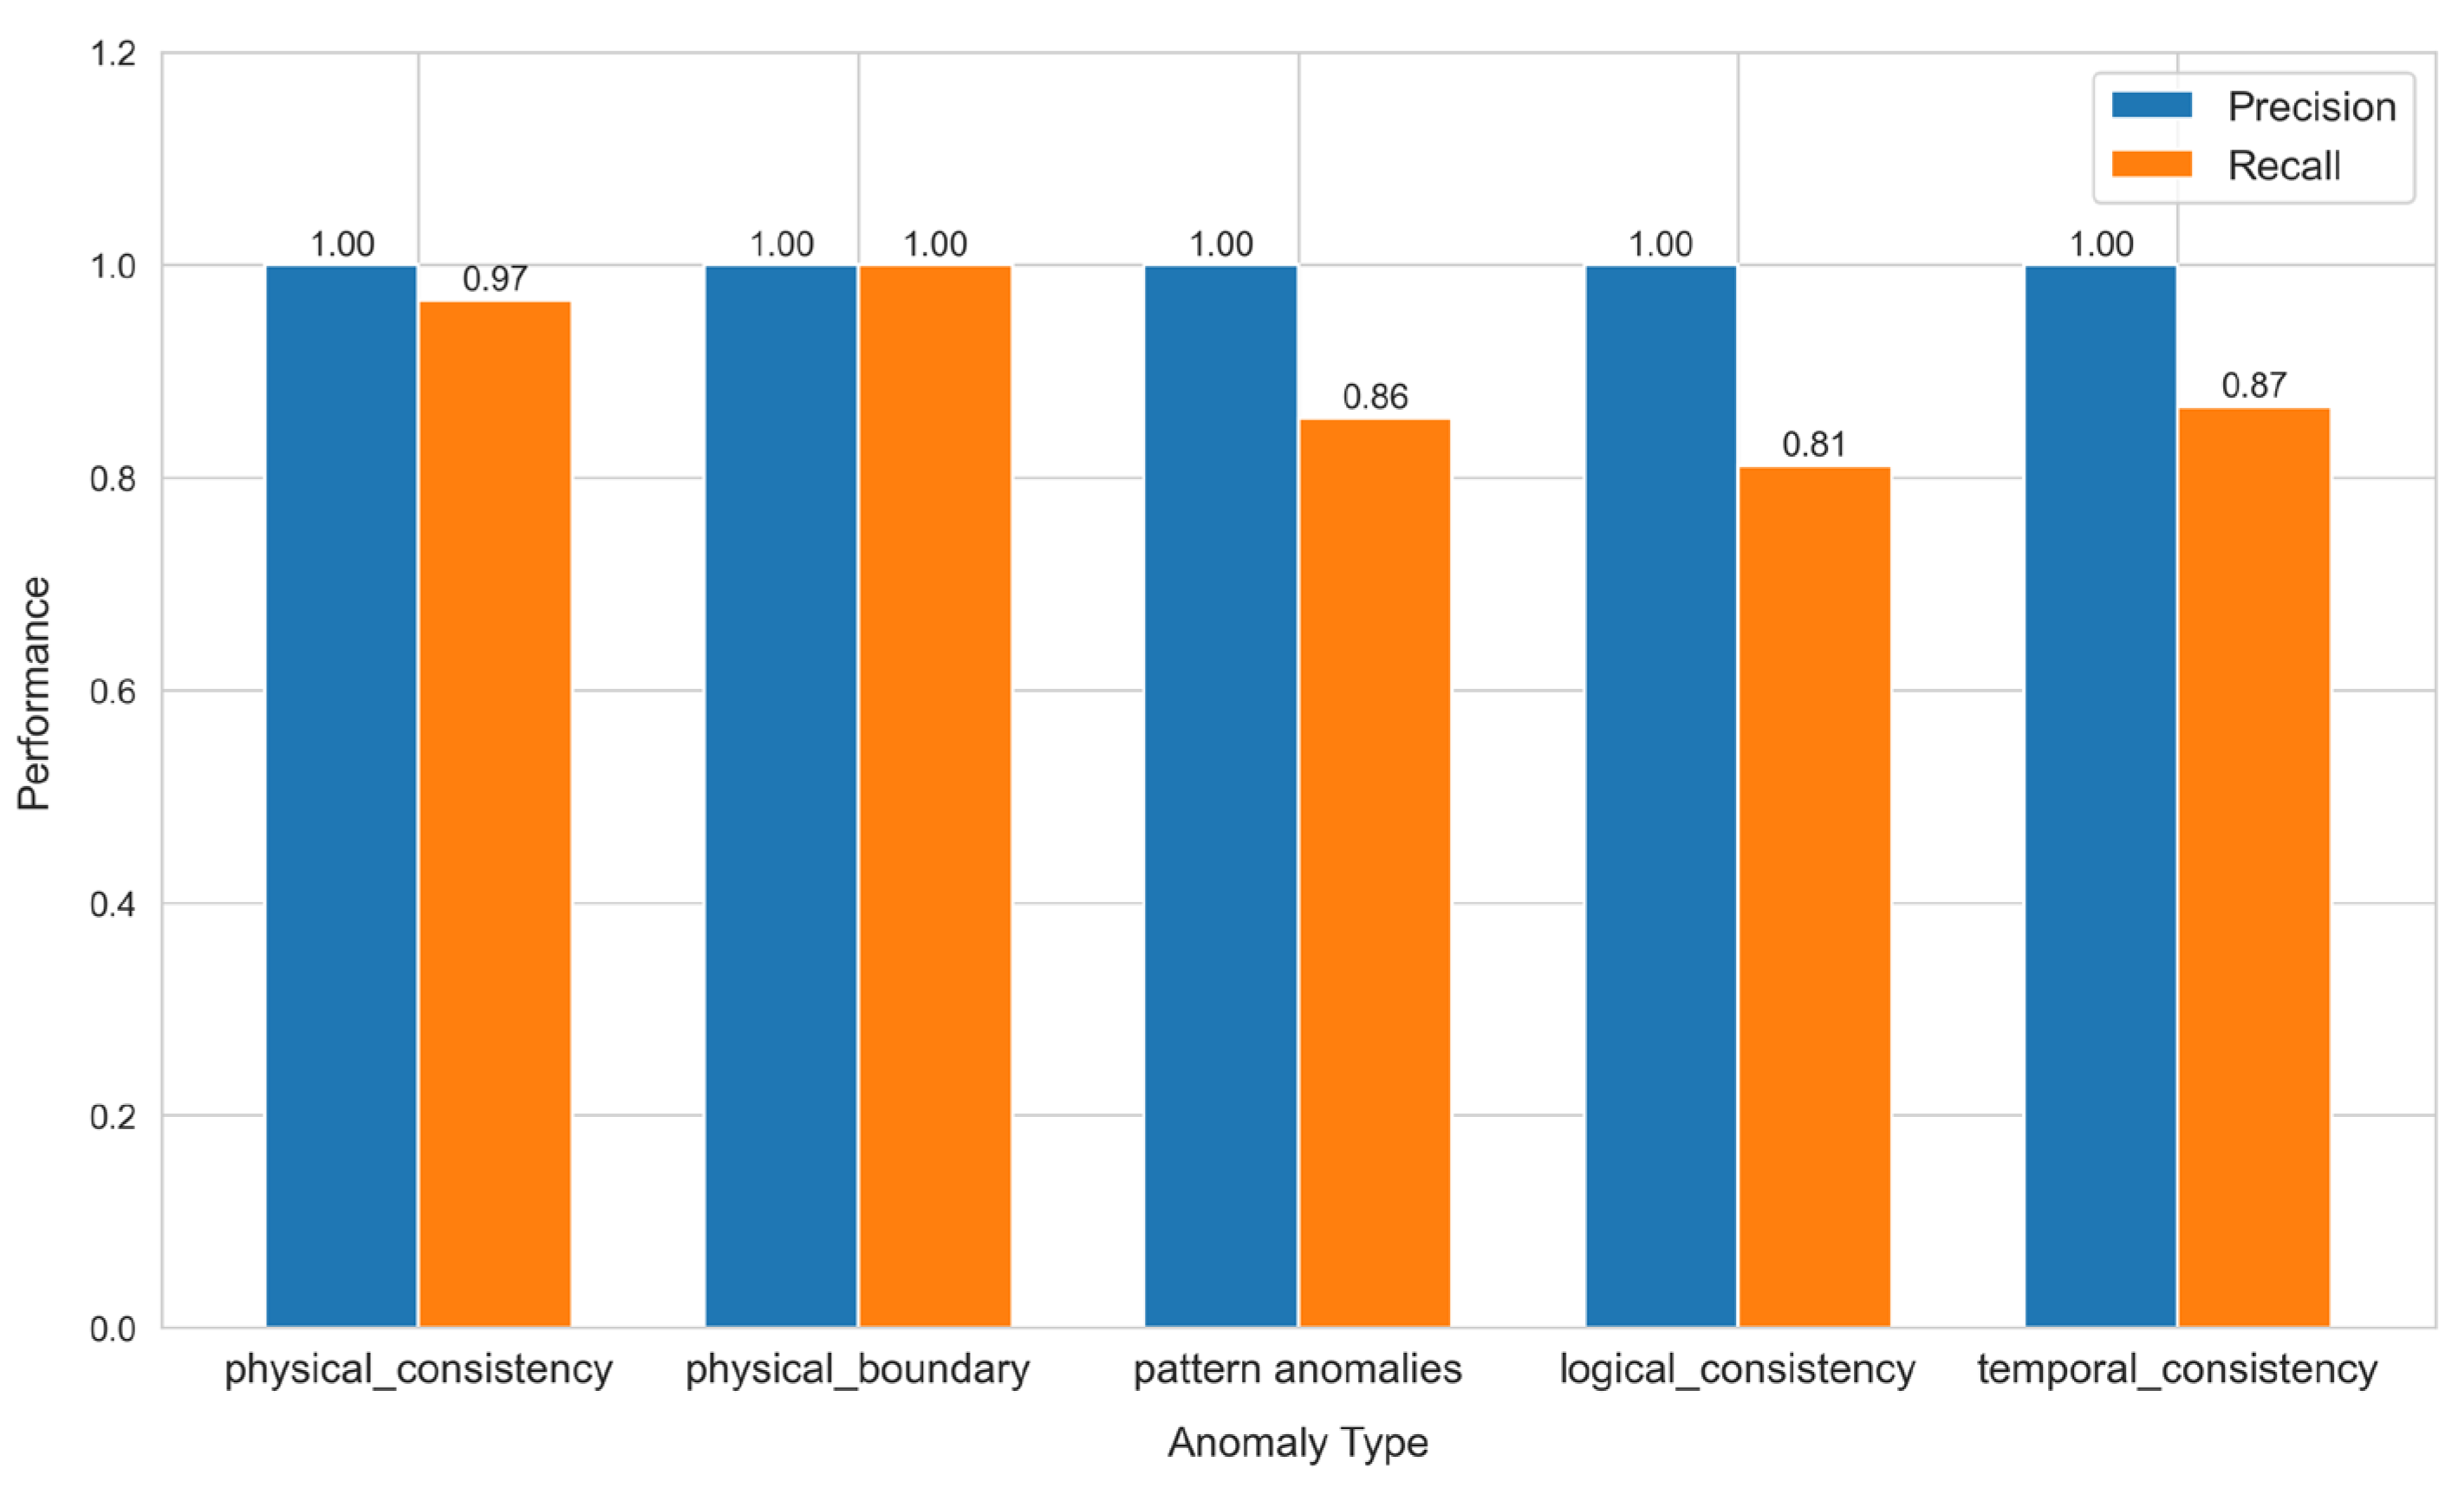
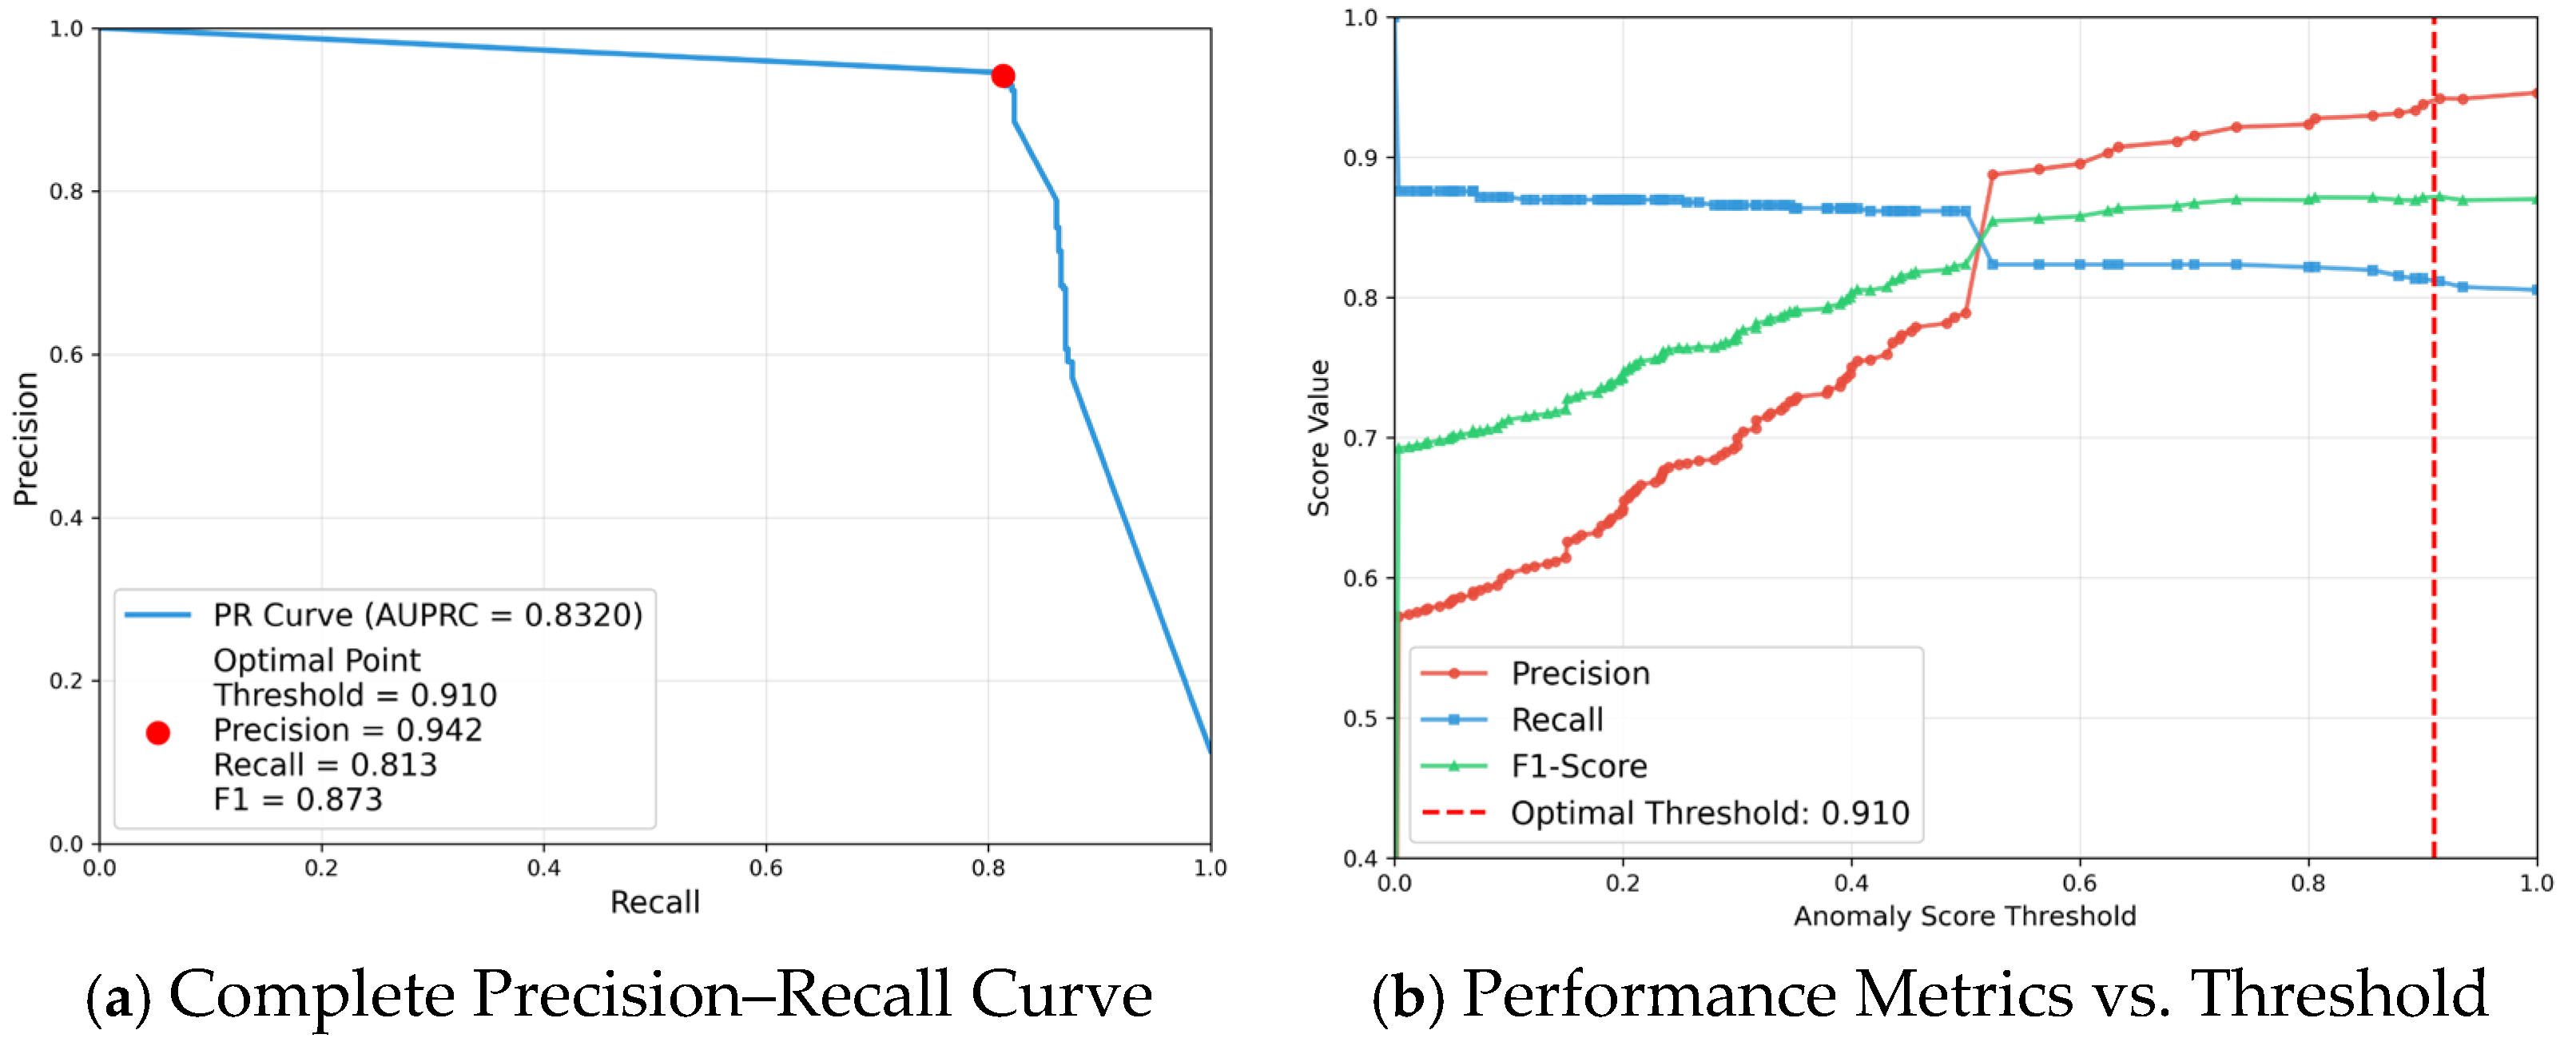
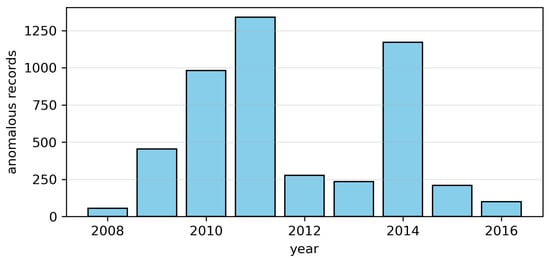
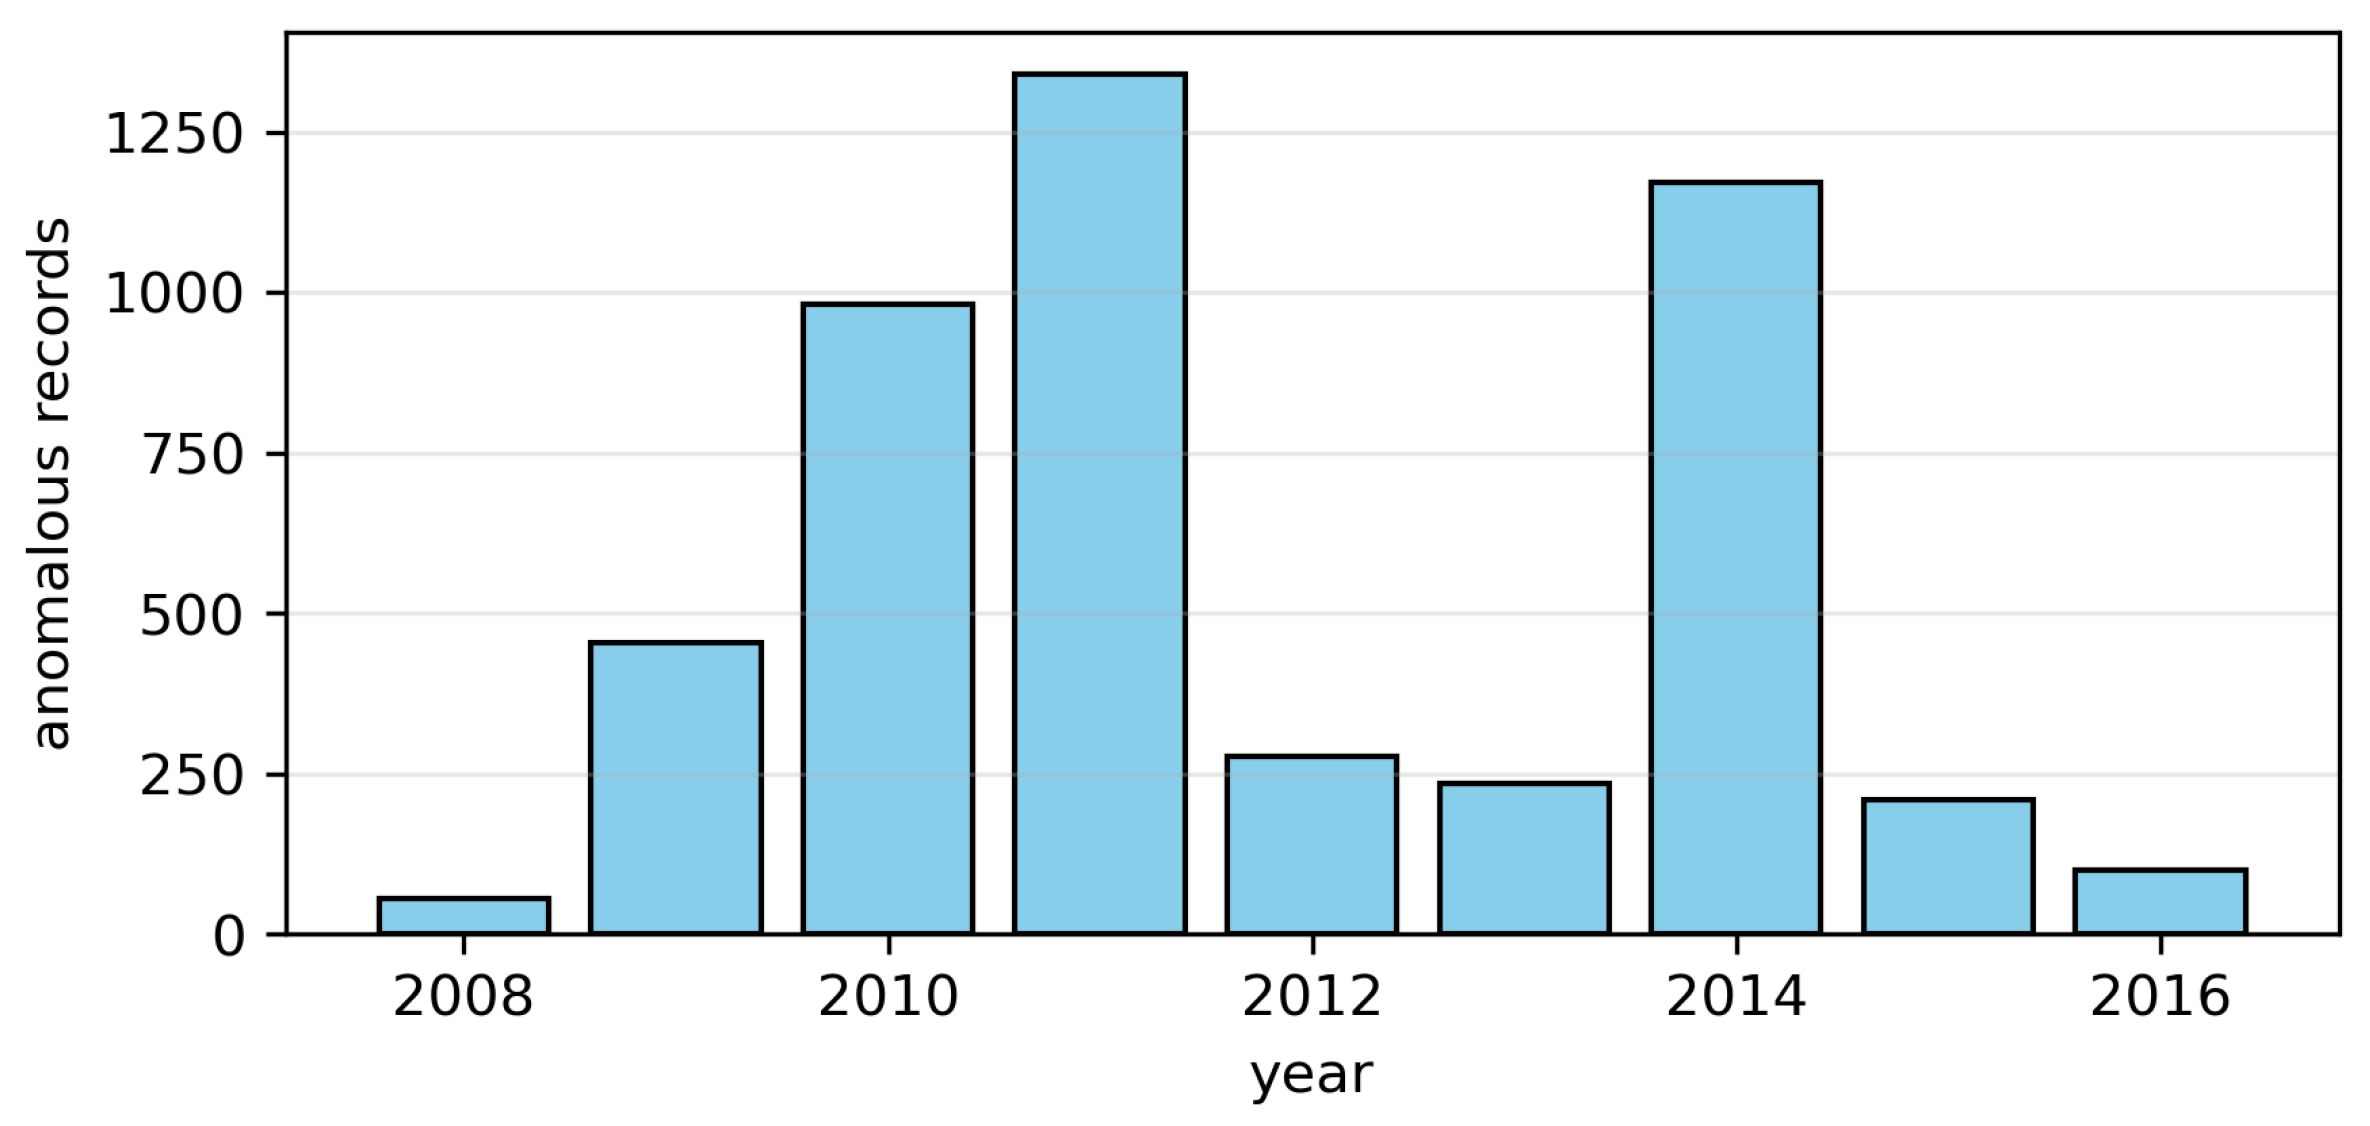

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.