


Abstract
Underwater images exhibit severe colour distortion, low contrast, and blurred details due to light absorption and scattering, which limits their practical use in marine applications. Existing methods face poor generalisation, high computational costs and weak integration of physical priors. To address these issues, this paper proposes TIDE-Net, a triple-branch illumination and detail enhancement network for underwater images. It decomposed inputs into illumination, reflectance intensity, and chromaticity branches for parallel optimisation, enabling decoupled handling of brightness, texture, and colour degradation. A piecewise colour correction module mitigated complex colour casts without introducing artefacts; a lightweight U-Net branch enhanced fine details while suppressing noise; and a local gain compensation module improved brightness uniformity and reduced halo effects. Experiments on four datasets showed that TIDE-Net outperforms some state-of-the-art methods, achieving a PSNR of 29.44 dB, an SSIM of 0.94, and competitive UIQM/UCIQE scores with only 7.74 M parameters. The results confirmed that the proposed triple-branch strategy effectively balances physical interpretability, restoration quality, and computational efficiency. In conclusion, TIDE-Net provides a robust and lightweight solution suitable for deployment on resource-limited underwater platforms, offering practical value for real-world underwater vision tasks.
1. Introduction
Underwater optical imaging is fundamentally constrained by the wavelength-dependent absorption and scattering of light in water, resulting in images that exhibit severe colour deviation, diminished contrast, and blurred structural details. The practical importance of clear underwater imagery, vital in marine ecological monitoring, autonomous underwater vehicle navigation, subsea infrastructure inspection, and archaeological surveying, has sustained decades of research aimed at reversing these degradations, yet robust and efficient enhancement across the diversity of real-world aquatic environments remains an unsettled challenge.
Early enhancement methodologies bifurcated into non-physical pixel-level manipulations and physics-based restoration grounded in the underwater image formation model. The former, including histogram equalisation, Retinex decompositions, and fusion-based blending, offered computational simplicity but lacked an understanding of the degradation mechanism, frequently amplifying noise or introducing unnatural colour shifts. The latter attempted to invert the image formation process by estimating the background light and medium transmission using hand-crafted priors such as the dark channel prior or its underwater variants. Although physically interpretable, these prior-driven frameworks are inherently fragile: their performance critically hinges on the validity of statistical assumptions that might break down in turbid, shallow, or artificially illuminated scenes, leading to unreliable parameter estimation and visually implausible artefacts. The subsequent adoption of deep convolutional neural networks marked a paradigm shift, enabling end-to-end learning of enhancement mappings from paired datasets. Generative adversarial networks and cycle-consistent domain translation further advanced perceptual realism, while vision Transformers introduced long-range dependency modelling to address spatially non-uniform attenuation. More recently, denoising diffusion models and state-space architectures such as Mamba have pushed generative fidelity and computational efficiency forward, yet several fundamental bottlenecks remain.
First, the generalisation capability of data-driven models is constrained by the limited scale, scene diversity, and water-type coverage of existing training benchmarks, whose reference images are typically generated through subjective expert selection rather than physical measurement, introducing label ambiguity. Second, the substantial computational requirements of diffusion-based and large Transformer architectures hinder deployment on resource-limited autonomous platforms. Third, plenty of recent research works integrate physical prior information including transmission estimation, background light assumptions, and colour constancy rules into deep learning models; yet few standardised frameworks can effectively coordinate learned features and optical physical constraints, thus producing inconsistent restoration results across different underwater scenarios. Fourth, while frequency-domain and multi-domain processing strategies have shown promise in decoupling degradation factors, their robustness under severe broadband attenuation remains under-explored.
A range of interconnected difficulties mark the current research boundaries of underwater image enhancement, namely weak cross-domain robustness, high computational consumption, poorly unified embedding schemes for physical priors, and inadequate utilisation of multi-source feature information. Within this context, this paper proposes a parallel triple-branch illumination and detail enhancement network (TIDE-Net) for underwater images. The contributions of this work are as follows:
- (1)
- A parallel triple-branch strategy is proposed to distinguish underwater image degradations on different sub-images. Different from the multi-stage strategy, by decomposing the underwater image into multiple branches to individually represent different degradations, side effects arising from their interaction are mitigated.
- (2)
- A lightweight U-Net is adopted and adapted via reduced channel dimensions, LeakyReLU activation and an adjusted loss function with a higher weight of SSIM loss. These adjustments suppress noise, preserve fine textures in turbid scenes, and improve low-light adaptability without altering the core encoder–decoder architecture.
- (3)
- Mature piecewise colour correction and local gain compensation strategies are introduced and organically integrated into the triple-branch framework to suppress blue–green colour casts and uneven illumination, achieving favourable enhancement performance without extra computational overhead.
The remainder of this paper is structured as follows. Section 2 reviews application requirements and recent developments in underwater image enhancement. Section 3 details the proposed methodology. The experimental setup is described in Section 4. Section 5 presents and discusses the results and comparisons. Finally, Section 6 concludes the study and suggests directions for future research.
2. Related Work
Underwater image enhancement (UIE) has been an enduring research focus owing to the complex optical degradation mechanisms inherent in aquatic environments. The absorption and scattering of light by water molecules and suspended particles introduce severe colour casts, reduced contrast, and blurred details, which collectively compromise the utility of captured imagery for scientific and engineering applications [1]. Over the past few decades, UIE methodologies have evolved through three distinguishable yet partially overlapping phases: from traditional prior-driven restoration and pixel-level manipulation, to purely data-driven deep learning, and most recently to hybrid paradigms that integrate physical knowledge with advanced neural architectures across multiple representational domains. This section surveys this developmental trajectory, highlighting the motivations, innovations, and limitations of each paradigm.
2.1. Traditional Enhancement and Physics-Based Restoration
Early UIE efforts concentrated on direct pixel-level adjustments or explicit inversion of the underwater image formation model. Non-physical enhancement techniques, such as histogram equalisation, contrast stretching, white-balance correction, and Retinex-based decomposition, improve visual appearance by redistributing intensity values or separating illumination from reflectance [2,3]. Fusion-based strategies further combine multiple derived inputs optimised for different attributes, such as colour balance and local contrast, using pyramidal blending to produce a visually coherent result [4]. Although computationally efficient and straightforward, these methods lack a physical understanding of the degradation process; they often amplify noise, introduce unnatural colour shifts, or over-enhance specific regions when confronted with spatially varying underwater conditions.
Physics-based restoration, in contrast, models the image formation process explicitly. The simplified Jaffe–McGlamery model describes the observed radiance as the superposition of a direct attenuated signal and a backscattered component, with the medium transmission map and background light serving as the key unknowns [5]. Numerous priors have been proposed to solve this ill-posed inverse problem. The dark channel prior (DCP) was adapted from atmospheric dehazing to underwater scenes, leading to variants such as the underwater dark channel prior (UDCP) that omit the strongly attenuated red channel from the dark pixel assumption [6]. Other priors exploit wavelength-dependent attenuation differences: the Maximum Intensity Prior uses the discrepancy between the red channel and the maxima of the green and blue channels to estimate depth [7]; the Red Channel Prior compensates for the rapid decay of red light [8]; and the Underwater Light Attenuation Prior posits a strong correlation between red-channel attenuation and scene depth [9]. More recently, the Zero-Point Symmetry Prior was introduced, which observes that the histograms of the a and b channels in the Lab colour space exhibit symmetry around zero for colour-balanced images, thereby enabling statistically grounded colour correction without explicit optical parameter tuning [10].
Each of the above five mainstream physical priors also presents distinct practical limitations. UDCP features low computational cost and works well for haze removal in clear shallow water, yet it struggles to eliminate inherent blue–green colour casts and performs poorly in turbid or artificially lit environments. The Maximum Intensity Prior delivers reliable background light estimation under uniform natural illumination but easily misjudges depth information under dim or artificial light, resulting in uneven brightness across restored images. The Red Channel Prior achieves targeted colour restoration by compensating for the rapidly attenuated red channel, while excessive compensation frequently causes noticeable red artefacts and weakens its adaptability to complex lighting. The Underwater Light Attenuation Prior suits most conventional shallow-water scenes, but it is sensitive to variations in water turbidity and tends to lose fine textures or generate false colours in highly turbid water. As a parameter-free colour correction method, the Zero-Point Symmetry Prior produces natural colour tones, but it only focuses on chromatic calibration and cannot effectively improve low-contrast or blurred details. Collectively, all these prior-driven approaches are restricted by fixed empirical and optical assumptions, and none can simultaneously address colour distortion, contrast degradation and detail blurring across diverse underwater scenarios.
Despite their physical interpretability, all prior-based methods share a fundamental fragility: their performance is contingent on the validity of the underlying assumptions in the specific imaging environment. In turbid, dynamically illuminated, or artificially lit settings, these assumptions sometimes fail, leading to inaccurate background light estimation, over- or under-corrected transmission maps, and visually implausible colour artefacts. The difficulty of simultaneously estimating multiple coupled parameters from a single degraded observation further limits their robustness and generalisability.
2.2. Deep Learning-Driven Methods
The limitations of hand-crafted priors motivated a decisive shift towards data-driven approaches that learn mappings directly from paired or unpaired training samples. Early convolutional neural networks (CNNs) for UIE, such as the underwater image enhancement convolutional neural network (UWCNN) and Water-Net, established encoder–decoder architectures that reconstruct clear images from degraded inputs by implicitly capturing multi-scale degradation patterns [11,12]. To improve perceptual realism, generative adversarial networks (GANs) were introduced: WaterGAN generated synthetic underwater image pairs via unsupervised domain translation [13], while fast underwater image enhancement generative adversarial networks (FUnIE-GANs) achieved real-time enhancement with a lightweight conditional GAN framework [14]. Subsequent GAN variants incorporated self-attention mechanisms and a frequency-domain discriminator, namely the adaptive underwater image enhancement based on generative adversarial networks (AUIE-GAN), to stabilise training and enhance texture fidelity [15], and some employed cycle-consistency losses, namely the implicit neural-guided cycle generative adversarial networks (INGC-GANs), to learn bidirectional mappings between degraded and clear domains without paired supervision, bridging the gap between metric-optimal and perceptually friendly results [16].
Despite the considerable success of CNNs and GANs, their reliance on local convolutions or limited receptive fields impedes the correction of global colour casts and spatially non-uniform attenuation—both hallmarks of underwater degradation. To tackle this issue, researchers adopted Transformer architectures for underwater image enhancement. The U-Shape Transformer introduced channel-wise multi-scale feature fusion and spatial-wise global feature modelling modules, enabling the network to attend more strongly to severely attenuated colour channels and regions [17]. Swin Transformer variants exploited shifted-window self-attention to balance computational efficiency with long-range dependency modelling [18], and dual-attention fusion designs adaptively combined non-local Transformer features with local convolutional features to improve both colour correction and detail reconstruction [19]. Nevertheless, the quadratic complexity of standard self-attention limits the scalability of Transformer-based models to high-resolution underwater imagery, stimulating interest in more computationally efficient alternatives.
Denoising diffusion probabilistic models (DDPMs) constitute a more recent generative paradigm that has been extended to UIE. Diffusion models learn to reverse a Markovian noising process, generating high-fidelity images by iteratively denoising a Gaussian sample. For underwater enhancement, the degraded image often serves as a conditioning input to guide the reverse diffusion trajectory [20]. Frequency-domain latent diffusion models, such as the frequency-domain-based latent diffusion model (FD-LDM), decompose images into high- and low-frequency components and process them in a compressed latent space, enabling targeted recovery of global colour and local texture [21]. The Fourier transform-guided dual-channel underwater image enhancement diffusion network (FDNet) further exploits Fourier amplitude–phase dual channels to improve brightness and edge sharpness before feeding the enhanced representation into a lightweight Transformer-based diffusion denoiser [22]. However, the iterative sampling procedure inherent to diffusion models incurs significant inference latency. To address this, the diffusion-empowered efficient restoration (DEER) model for underwater images proposed a “diffusion-empowered” paradigm in which the diffusion model provides gradient guidance during training only and is discarded at inference, enabling a lightweight restoration network to achieve real-time performance while retaining the generative prior [23].
Most recently, state-space models (SSMs), particularly the Mamba architecture, have emerged as an efficient alternative for capturing long-range dependencies with linear complexity. Mamba-based UIE networks, such as Hero-Mamba and WaterMamba, process spatial and spectral features in parallel branches and employ selective scan mechanisms to model pixel-channel dependencies across the entire image [24,25]. These models match or surpass the enhancement quality of Transformer-based approaches while requiring significantly fewer computational resources, making them better suited for deployment on resource-constrained underwater platforms.
Across all these deep learning paradigms, a synthetic comparison of their core characteristics and practical performance is conducted. Traditional CNN-based models such as Water-Net and UWCNN achieve stable local feature extraction and low inference latency, yet they are limited by small receptive fields and struggle to correct global colour casts and spatially uneven attenuation. GAN-based methods represented by FUnIE-GAN produce visually vivid enhancement results and maintain a lightweight structure, but they frequently suffer from unstable training and unexpected colour artefacts in complex turbid scenes. Transformer-based U-shape models excel at modelling long-range spatial dependencies and global degradation, but their high computational complexity restricts their application to high-resolution imagery and edge devices. Diffusion models including DM-Water and Diff-Water deliver outstanding restoration fidelity, while their iterative sampling process leads to considerable inference delay. As the latest efficient architecture, Mamba-based state-space models balance long-range feature modelling and computational efficiency, yet their performance still has room for improvement when handling extreme colour distortion.
2.3. Multi-Domain Fusion and Physically Guided Architectures
A growing recognition that purely data-driven strategies may overlook the physical mechanisms of underwater imaging has driven the development of hybrid architectures that embed domain knowledge and operate across multiple representational spaces. One prominent direction is frequency-aware processing, which exploits the fact that degradation factors manifest differently in the amplitude and phase spectra. Methods such as FD-LDM and FDNet explicitly decompose images into amplitude and phase components, correcting colour and brightness via the former while sharpening edges and suppressing noise via the latter [21,22]. Multi-scale Laplacian pyramid networks decompose images into band-pass components and apply adaptive frequency-domain enhancement via discrete cosine transforms and band-attention mechanisms, selectively amplifying the most scattering-prone frequency bands [26]. Wavelet-based frameworks similarly disentangle low- and high-frequency information, enabling simultaneous colour correction and detail restoration without excessive reliance on deep convolutional stacks [27].
Another significant research thrust involves the explicit integration of physical priors into deep architectures. Rather than treating physics-based restoration as a pre- or post-processing step, these methods embed model-informed modules within the learning pipeline. For instance, the Joint Prior Module in the multi-scale joint prior network (MJPNet) framework estimates a background light prior through object colour constancy and dynamically fuses it with learnable features within a multi-scale network, guiding the model to respect optical propagation laws and improve colour accuracy across diverse water bodies [28]. Transmission-guided attention mechanisms inject a physically estimated transmission map into the self-attention computation of a U-shaped Transformer, enabling the network to allocate representational capacity preferentially to severely attenuated regions [29]. Deep unfolding networks unroll iterative ADMM-based optimisation into a series of neural stages, solving a joint inverse problem that enforces photometric constraints and underwater-specific image priors through learned proximal operators [30].
Uncertainty modelling represents a complementary line of research. Since the “ground-truth” references in common UIE benchmarks are typically generated by subjective expert selection rather than physical measurement, there exists inherent ambiguity in the enhancement target. Probabilistic frameworks built upon conditional variational auto-encoders and adaptive instance normalisation such as the network based on multi-dimensional feature fusion and probabilistic adaptive uncertainty distribution (MFP-PAINet) learn a distribution over plausible enhanced outputs, explicitly encoding uncertainty in a latent space and selecting the most probable reconstruction [31]. Such approaches improve robustness to label noise and produce structurally consistent results even in highly ambiguous underwater scenes.
Collectively, these multi-domain and physically guided architectures represent a synthesis of the preceding paradigms: they retain the adaptability of deep learning while incorporating the inductive biases of physical optics and the representational efficiency of frequency-domain processing. This convergence promises not only improved perceptual quality but also enhanced generalisability to the diverse and unpredictable conditions encountered in real-world underwater operations.
3. Methodology
The classic Retinex theory posits that an image I can be decomposed, on a per-pixel, channel-wise basis, into the Hadamard product of an illumination component L and a reflectance component R [32]; this decomposition mechanism is adopted as the core theoretical basis for tackling multiple types of underwater image degradation:
where L denotes the scene’s illumination distribution, encompassing light source intensity, colour, shadows, and the superposition of scattered light, and is generally assumed to vary slowly across the spatial domain; R represents the intrinsic reflectance properties of object surfaces, which contain textural details (high-frequency components) and colour (surface albedo), and are independent of incident illumination [10].
I(x) = L(x)⊙R(x)
In underwater scenes, this formulation aligns directly with the Jaffe–McGlamery model [5]:
where J is the clear-scene radiance, t is the transmission map, and A denotes the background ambient light. These three physical components are the core parameters governing underwater image degradation and serve as the implicit optimisation objectives of our enhancement network.
I = J⋅t + A(1 − t)
If L is taken to approximately capture the smooth illumination and scattering contributions inherent in J⋅t + A(1 − t), then R = I/L approximates the scattering-free, clear-scene radiance J. This provides a rigorous theoretical foundation for the task of underwater image de-scattering. The background ambient light A and transmission map t from the Jaffe–McGlamery model are also fully considered in our branch design for colour correction and detail restoration.
Meanwhile, the reflectance R inherently encodes both textural intensity and colour chromaticity. The R branch then can be further decomposed into two distinct sub-branches to perform colour correction without amplifying high-frequency textural noise:
where L stands for the illumination field; r denotes the reflectance intensity; and c accounts for the reflectance chromaticity.
I(x) = L(x)⋅r(x)⋅c(x)
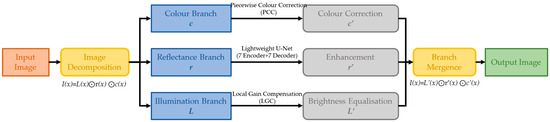
As such, the proposed method uses a triple-branch strategy (shown in Figure 1) which decomposes the input image into sub-images representing different degradations and then optimises them individually in parallel. Compared to the commonly used multi-stage strategy, the triple-branch strategy can effectively avoid mutual influence among degradations, thus maximising the optimisation of each degradation. In this paper, the proposed parallel triple-branch underwater image enhancement method is named as “Triple-branch Illumination and Detail Enhancement Network”, shortened to “TIDE-Net”.
Figure 1.
The complete architecture of the proposed TIDE-Net. The input underwater image is first decomposed into illumination, reflectance intensity and chromaticity components, which are processed in parallel by three dedicated branches. The outputs of the three branches are then fused via element-wise product to generate the final enhanced image.
3.1. Triple-Branch Decomposition
Assuming the illumination map L is spatially smooth, its estimation is conventionally realised by low-pass convolution:
L(x) ≈ I(x)⊛Gσ
The decomposition of a trichromatic reflectance image into a scalar intensity field and a chromaticity map is accomplished through a deterministic, parameter-free transformation rooted in the linearity of luminance perception [33,34,35]. Let denote the standard luminance operator, defined as a weighted sum of the colour channels in accordance with the ITU-R BT.601 [36] specification as is shown in Equation (5).
The intensity component is then obtained directly as , which collapses the three-dimensional colour signal onto a single channel that encodes the achromatic magnitude of reflectance—its lightness, texture, and spatial contrast—without any chromatic information.
The chromaticity layer is subsequently derived by element-wise division of the original reflectance by this intensity,
where is an infinitesimal positive constant introduced solely for numerical stability.
Because the luminance operator is linear, it follows that . Hence, by construction, the chromaticity map is everywhere normalised to unit luminance; every pixel of is a pure chromatic vector that carries the complete spectral signature of the surface material but is entirely devoid of intensity variation [37,38]. All shadows, shading, and textural modulations have been absorbed into the single-channel .
This separation is both exact and non-parametric: it requires no optimisation, no training data, and no prior assumptions about image statistics beyond the choice of the luminance weighting coefficients, which are themselves standardised physiological constants. The procedure functions as an analytical, invertible transform, with the original reflectance recovered exactly through the pointwise product . In the context of computational imaging and restoration pipelines, the decomposition may be instantiated as a stateless, differentiable layer, providing a theoretically clean decoupling of achromatic structure from chromatic content. Such a decoupling is foundational for tasks in which texture enhancement (e.g., sharpening or local contrast adjustment) and colour correction (e.g., white balancing or saturation compensation) must be performed independently without mutual interference, thereby preserving the fidelity of both luminance detail and hue.
3.2. Branch 1: Colour Correction
The colour correction branch consists of piecewise colour correction (PCC) [39].
Underwater imagery is inherently prone to a range of colour distortions, owing to the scarcity of ambient light and the intricacies of the submerged environment. To address the limitations of conventional linear colour correction approaches [40,41,42], notably their tendency to induce residual red tints and spatially localised artefacts, this branch utilises a piecewise linear transmission strategy for colour correction.
First, the mean grey-level intensity of each colour channel was computed, as defined by the following equation:
where H and W correspond, respectively, to the number of rows and columns in the input image, while c ∈ {r, g, b} indexes the red, green and blue colour channels.
Subsequently, the maximum grey-level mean across all colour channels is obtained via Equation (8):
where max(⋅) denotes the maximum operator, and represents this maximum reference mean value.
Using this reference value, a piecewise correction is then applied to each colour channel, as formalised in Equation (9):
where and denote the per-channel gain correction coefficients for the two segments of the piecewise mapping.
For pixels where < , the grey-level values of the respective colour channel are linearly stretched to the range (, 255]. Conversely, for ≥ , the values are mapped to the interval [0, ].
Combining these definitions, the full correction procedure can be consolidated into a single formulation, as given in Equation (10):
where indicates the colour-corrected result.
3.3. Branch 2: Enhancement and Denoising
The U-Net architecture [43] is fundamentally built upon an encoder–decoder framework [44] augmented with skip connections, which equips it with two pivotal capabilities well-suited to image enhancement and denoising tasks:
- Multi-scale receptive fields: The down-sampling encoder progressively extracts hierarchical features spanning from local edge textures to global illumination distributions, while the up-sampling decoder recovers spatial resolution to enable precise pixel-wise reconstruction of target intensity values [44,45].
- Feature preservation via skip connections: Skip pathways directly propagate high-resolution feature maps from corresponding encoder layers to the decoder, mitigating the loss of fine-grained textural information. This property is particularly critical for the sharpening and deblurring of the reflectance r branch in our framework.
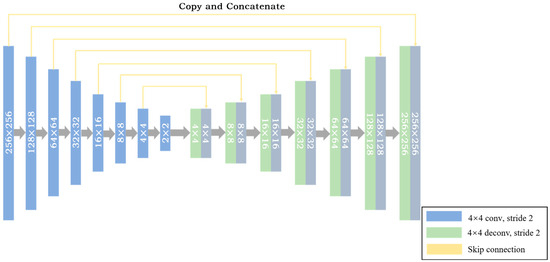
At its core, image enhancement and denoising constitute pixel-to-pixel mapping problems, where a degraded input image is transformed into its clear, enhanced counterpart. This paradigm aligns directly with the original design intent of the U-Net architecture (shown in Figure 2), making it an ideal choice for our underwater image restoration pipeline [46,47].
Figure 2.
Enhancement: U-Net architecture.
As a popular U-shaped architecture, UNet++ adopts nested skip connections and deep supervision to improve feature fusion, while it still lacks the ability to capture long-range spatial dependencies. Integrating a Transformer into UNet++ makes up for this defect, yet the hybrid structure inevitably increases model complexity. Our adapted U-Net is modified for lightweight deployment, delivering a favourable trade-off between restoration quality and resource consumption.
Adjustments to the standard U-Net in this branch were made as follows:
- The U-Net is configured with reduced channel dimensions tailored to underwater low-frequency characteristics, effectively suppressing noise and reducing parameter redundancy.
- LeakyReLU activation replaces standard ReLU to avoid dead neurons in dark underwater regions and improve low-light adaptability.
- The loss function balances L1 and SSIM with a higher SSIM weight to prioritise structural fidelity for blurry underwater textures [48].
In the U-Net adapted in this paper, all 7 encoder layers and 7 decoder layers adopt a unified configuration with a 4 × 4 kernel size, a stride of 2 and zero-padding set to 1, a standard setup widely deployed in the Pix2Pix-based U-Net architectures to halve or double feature-map dimensions consistently across down-sampling and up-sampling operations. Except for the final output layer, all convolutional blocks are followed consecutively by the LeakyReLU activation function and batch normalisation (BN).
The standard ReLU activation function will zero out negative feature values, which easily causes the dead neuron problem. For underwater images with extensive dark regions and low-intensity areas, dead neurons will lead to the loss of shadow details and fine textures [49]. To address this issue, we adopt LeakyReLU to replace ReLU in our lightweight U-Net. By reserving a small gradient for negative inputs, LeakyReLU ensures continuous gradient propagation during training, effectively avoiding dead neurons and enhancing the network’s adaptability to low-light underwater environments. It can fully retain subtle texture and colour information in dim areas without increasing additional computational overhead, which fits well with the lightweight positioning of the proposed network.
These lightweight, task-oriented adaptations improve detail recovery and noise robustness without altering the core encoder–decoder structure, ensuring stable performance while maintaining low computational overhead.
All the above structural and hyperparameter adjustments constitute the parametric enhancement strategies tailored for underwater image enhancement in our modified U-Net.
3.4. Branch 3: Brightness Improvement
Following the three-component decomposition described earlier, the illumination branch L(x) is obtained as a low-frequency map encoding the spatial scattering and illumination distributions inherent in the underwater scene. To achieve uniform brightness across L(x) while minimising parameter overhead, this work adopts a local gain compensation strategy.
Uneven illumination fundamentally arises from deviations in local brightness from the global mean. A smoothed “local reference brightness” is first derived, and a per-pixel gain is then applied to adjust each pixel’s brightness towards a predefined target value. The step-by-step implementation is detailed as in Algorithm 1:
| Algorithm 1: Local gain compensation for brightness improvement. |
| Input: Original illumination map ; image width , height ; a small constant to prevent division by zero; gain clipping range Output: Uniformised illumination map 1: Compute Gaussian blur kernel scale: 2: Apply large-scale Gaussian blur to with standard deviation to obtain a smooth reference brightness map : |
Conceptually straightforward and computationally efficient, the adapted illumination equalisation strategy relies solely on blurring operations and basic arithmetic (multiplication and division), delivering extremely fast processing. Critically, the large-scale blurring prevents illumination edge leakage, thereby mitigating halo artefacts, while the imposed gain range constraints safeguard both highlight and shadow details from over-amplification or attenuation.
4. Experiment Settings
4.1. Datasets
4.1.1. Training Datasets
The training of the proposed model was conducted on the Enhancing Underwater Visual Perception (EUVP) dataset [14], a large-scale collection specifically curated to facilitate supervised learning for underwater image enhancement.
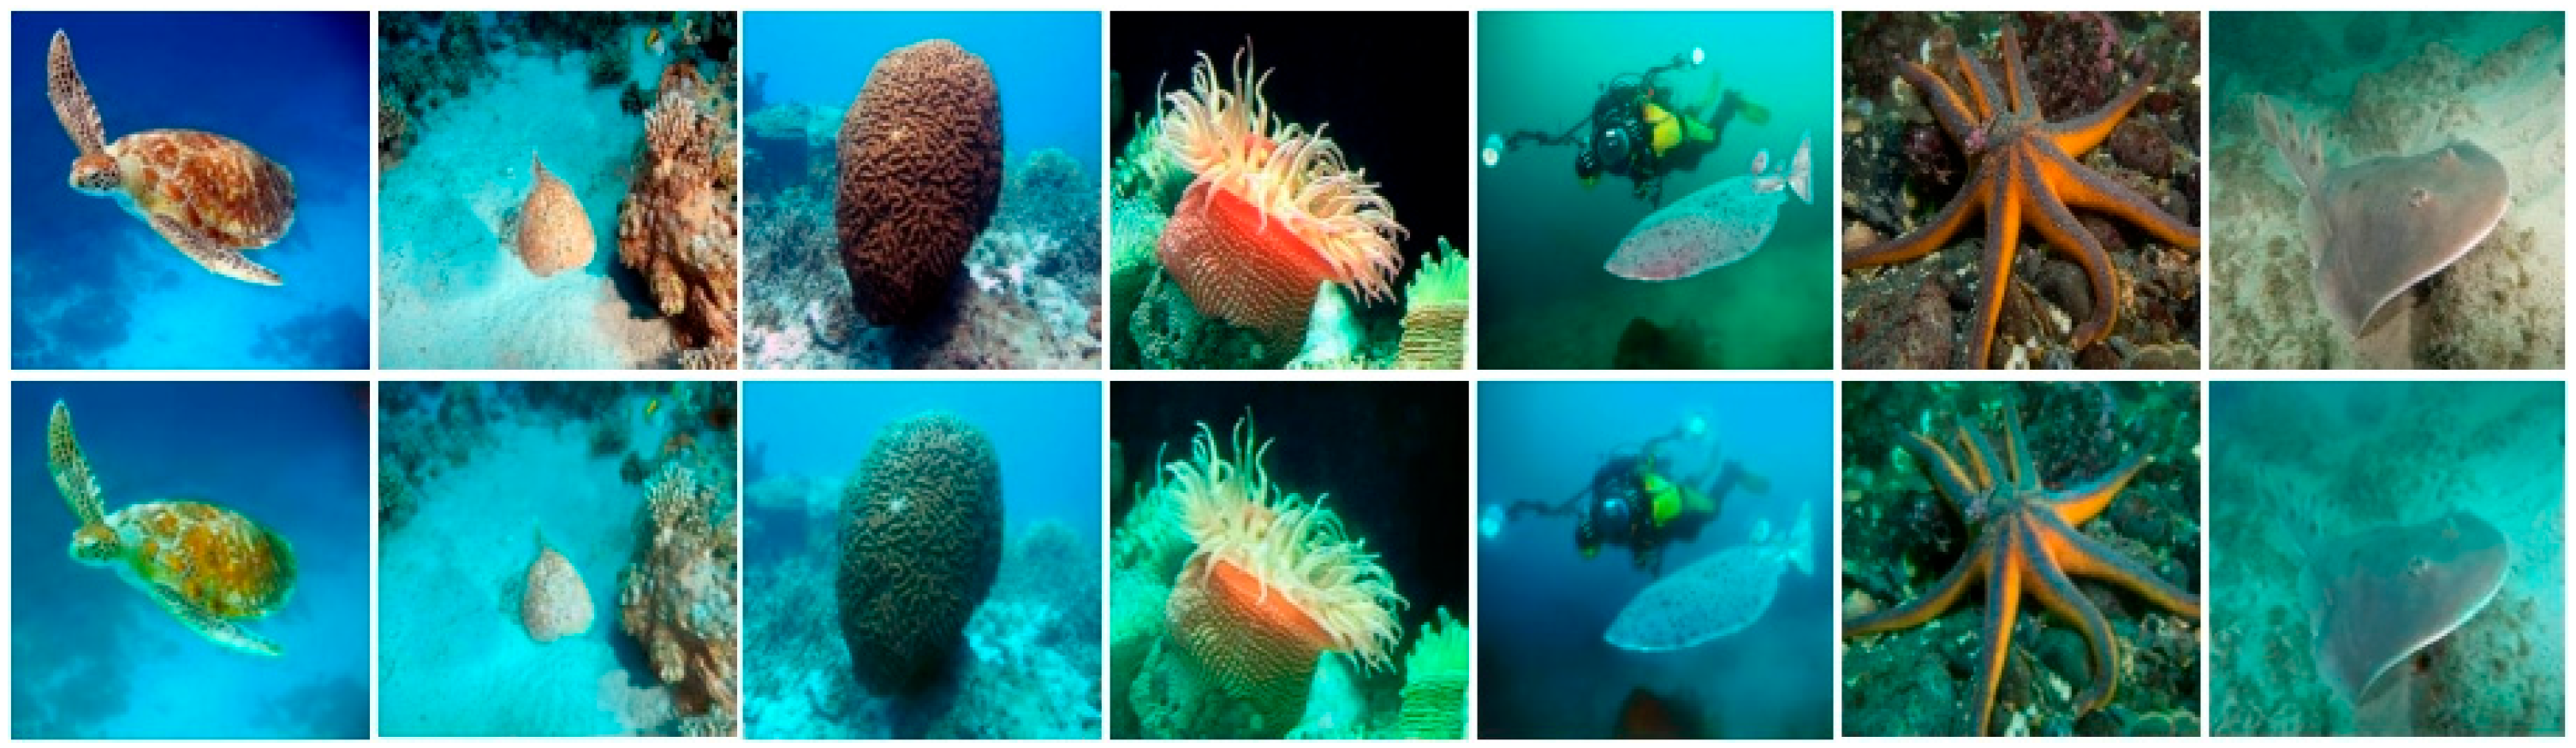
Established by Islam et al., EUVP encompasses a substantial corpus of paired and unpaired underwater images, captured across a broad spectrum of visibility conditions using seven distinct cameras during oceanic explorations and human–robot collaborative experiments. Within its paired subset (as shown in Figure 3 and Table 1), the dataset comprises over 11,000 training pairs distributed across three thematic categories: Underwater Dark, Underwater ImageNet, and underwater scenes, each containing corresponding poor- and good-quality image counterparts. This volume and diversity render EUVP particularly well-suited for training deep models, as it exposes the network to a wide variety of degradation patterns, scene geometries, and lighting conditions, thereby encouraging the learning of robust, generalisable enhancement priors.
Figure 3.
Paired instances of EUVP [14]: ground-truth images and their respective degraded images are shown in pairs on the top and bottom row, respectively.
Table 1.
Statistics of three paired datasets.
4.1.2. Test Datasets
To comprehensively evaluate the generalisation capacity and robustness of the proposed method, four distinct test datasets were adopted: UIEB, LSUI, U45, and C60. Each dataset was selected to probe a different dimension of underwater image degradation, ensuring that the evaluation transcends any single data distribution.
The Underwater Image Enhancement Benchmark (UIEB) [12], constructed by Li et al., is a widely recognised real-world benchmark comprising 950 underwater images, of which 890 are paired with human-validated reference images through a rigorous subjective selection protocol. UIEB spans diverse aquatic environments—from coral reefs and marine fauna to shipwrecks and man-made structures—and encompasses heterogeneous resolutions ranging from 300 × 200 to 8000 × 6000 pixels, with colour casts, scattering, and haze-like degradation comprehensively represented. As a de facto standard in the field, UIEB enables meaningful comparison with a broad body of prior work.
The LSUI dataset addresses the particularly challenging scenario of low-light underwater imaging in turbid, sediment-laden waters, where reduced contrast, detail loss, and colour distortion are prevalent [17]. LSUI is considerably larger in scale for testing purposes and complements than UIEB by concentrating on visibility degradation induced by particulate matter rather than purely chromatic aberration.
The U45 dataset [50], introduced by Li et al. as a public testbed, was explicitly assembled to embody three cardinal underwater degradation effects: colour casts, low contrast, and a haze-like appearance. Its categorisation according to these degradation types facilitates a structured diagnostic analysis of algorithmic performance.
Finally, the C60 dataset [12] consists of 60 underwater images, incorporating images that did not meet the reference image satisfaction criteria during the UIEB dataset creation.
Collectively, these four test sets cover the principal degradation axes encountered in underwater imaging—chromatic distortion, low contrast, turbidity-induced visibility loss, and spectral attenuation—and naturally correspond to real underwater scenes with different light attenuation coefficients and water turbidity qualities. They thus furnish a holistic and rigorous evaluation framework, where both qualitative and quantitative results can effectively reflect the performance of the proposed algorithm under varying light attenuation degrees.
4.2. Evaluation Criteria
To comprehensively assess the proposed algorithm for underwater image processing, both full-reference and no-reference metrics were employed across different evaluation scenarios. Collectively, these metrics provide a multifaceted quantitative evaluation of the algorithm from pixel fidelity, structural preservation, perceptual naturalness, and task-specific underwater image quality perspectives.
4.2.1. Full-Reference Metrics
In cases where ground-truth reference images were available, the peak signal-to-noise ratio (PSNR) [51] and the Structural Similarity Index Measure (SSIM) [52] were adopted. PSNR quantifies pixel-level reconstruction fidelity by computing the logarithm of the ratio between the maximum possible pixel intensity and the mean squared error, expressed in decibels, with higher values indicating lower distortion. SSIM moves beyond raw error by measuring the degradation of structural information through comparisons of luminance, contrast, and local spatial structure; these components are computed within sliding windows and averaged to yield a final index bounded between 0 and 1, where a value closer to 1 signifies greater perceptual similarity to the reference.
4.2.2. No-Reference Metrics
For experiments where reference images were unavailable, the no-reference metrics were utilised.
Natural Image Quality Evaluator (NIQE) [53] operates by extracting a set of quality-aware spatial features, specifically the local mean-subtracted contrast-normalised (MSCN) coefficients and their pairwise products, whose histograms are modelled by a generalised Gaussian distribution. The estimated shape and variance parameters are then fitted to a multivariate Gaussian model, and the NIQE score is computed as the Mahalanobis-like distance between this model and a reference model pre-learnt from a corpus of pristine natural photographs; a smaller distance corresponds to higher perceived naturalness.
Additionally, two underwater-specific evaluators, the Underwater Image Quality Measure (UIQM) [54] and the Underwater Colour Image Quality Evaluation (UCIQE) [55], were incorporated to capture domain-specific characteristics. UIQM is formulated as a linear combination of three complementary components: the Underwater Colourfulness Measure (UICM), which analyses colour distribution in an opponent colour space; the Underwater Sharpness Measure (UISM), derived from the Sobel edge response; and the Underwater Contrast Measure (UIConM), computed from the log-energy of intensity variation. The final score is given by UIQM = , with empirically determined coefficients , , and , where higher values denote superior colour richness, edge clarity, and overall contrast. UCIQE, in contrast, is defined as UCIQE = , where is the standard deviation of chroma, denotes the mean of saturation, and represents luminance contrast. The coefficients are typically set to , , and , reflecting the relative importance of colourfulness and contrast in human perception of underwater scenes, with a higher UCIQE value indicating a better balance of colour richness and sharpness.
4.3. Training Process
The experimental platform’s hardware environment consists of an Ultra 9 275HX CPU and an NVIDIA GeForce RTX 5080 Laptop GPU. The software environment includes CUDA13.0, Python 3.12, and the PyTorch 2.9.0 framework. All underwater images (degraded inputs and corresponding ground-truth (GT) references) were resized to a fixed spatial dimension of 256 × 256 pixels; data augmentation was applied to the training dataset to improve model generalisation, while the validation dataset used no augmentation. The full training dataset is split into training and validation subsets at a ratio of 5% for model validation. Data loading was implemented using PyTorch’s DataLoader with a batch size of 32, 8 worker threads, and pin memory enabled to optimise data throughput.
The TIDE-Net is optimised via the Adam optimiser with an initial learning rate of 1 × 10⁻⁴. A composite loss function was utilised, combining L1 loss with SSIM loss, and the corresponding mathematical expression is defined as
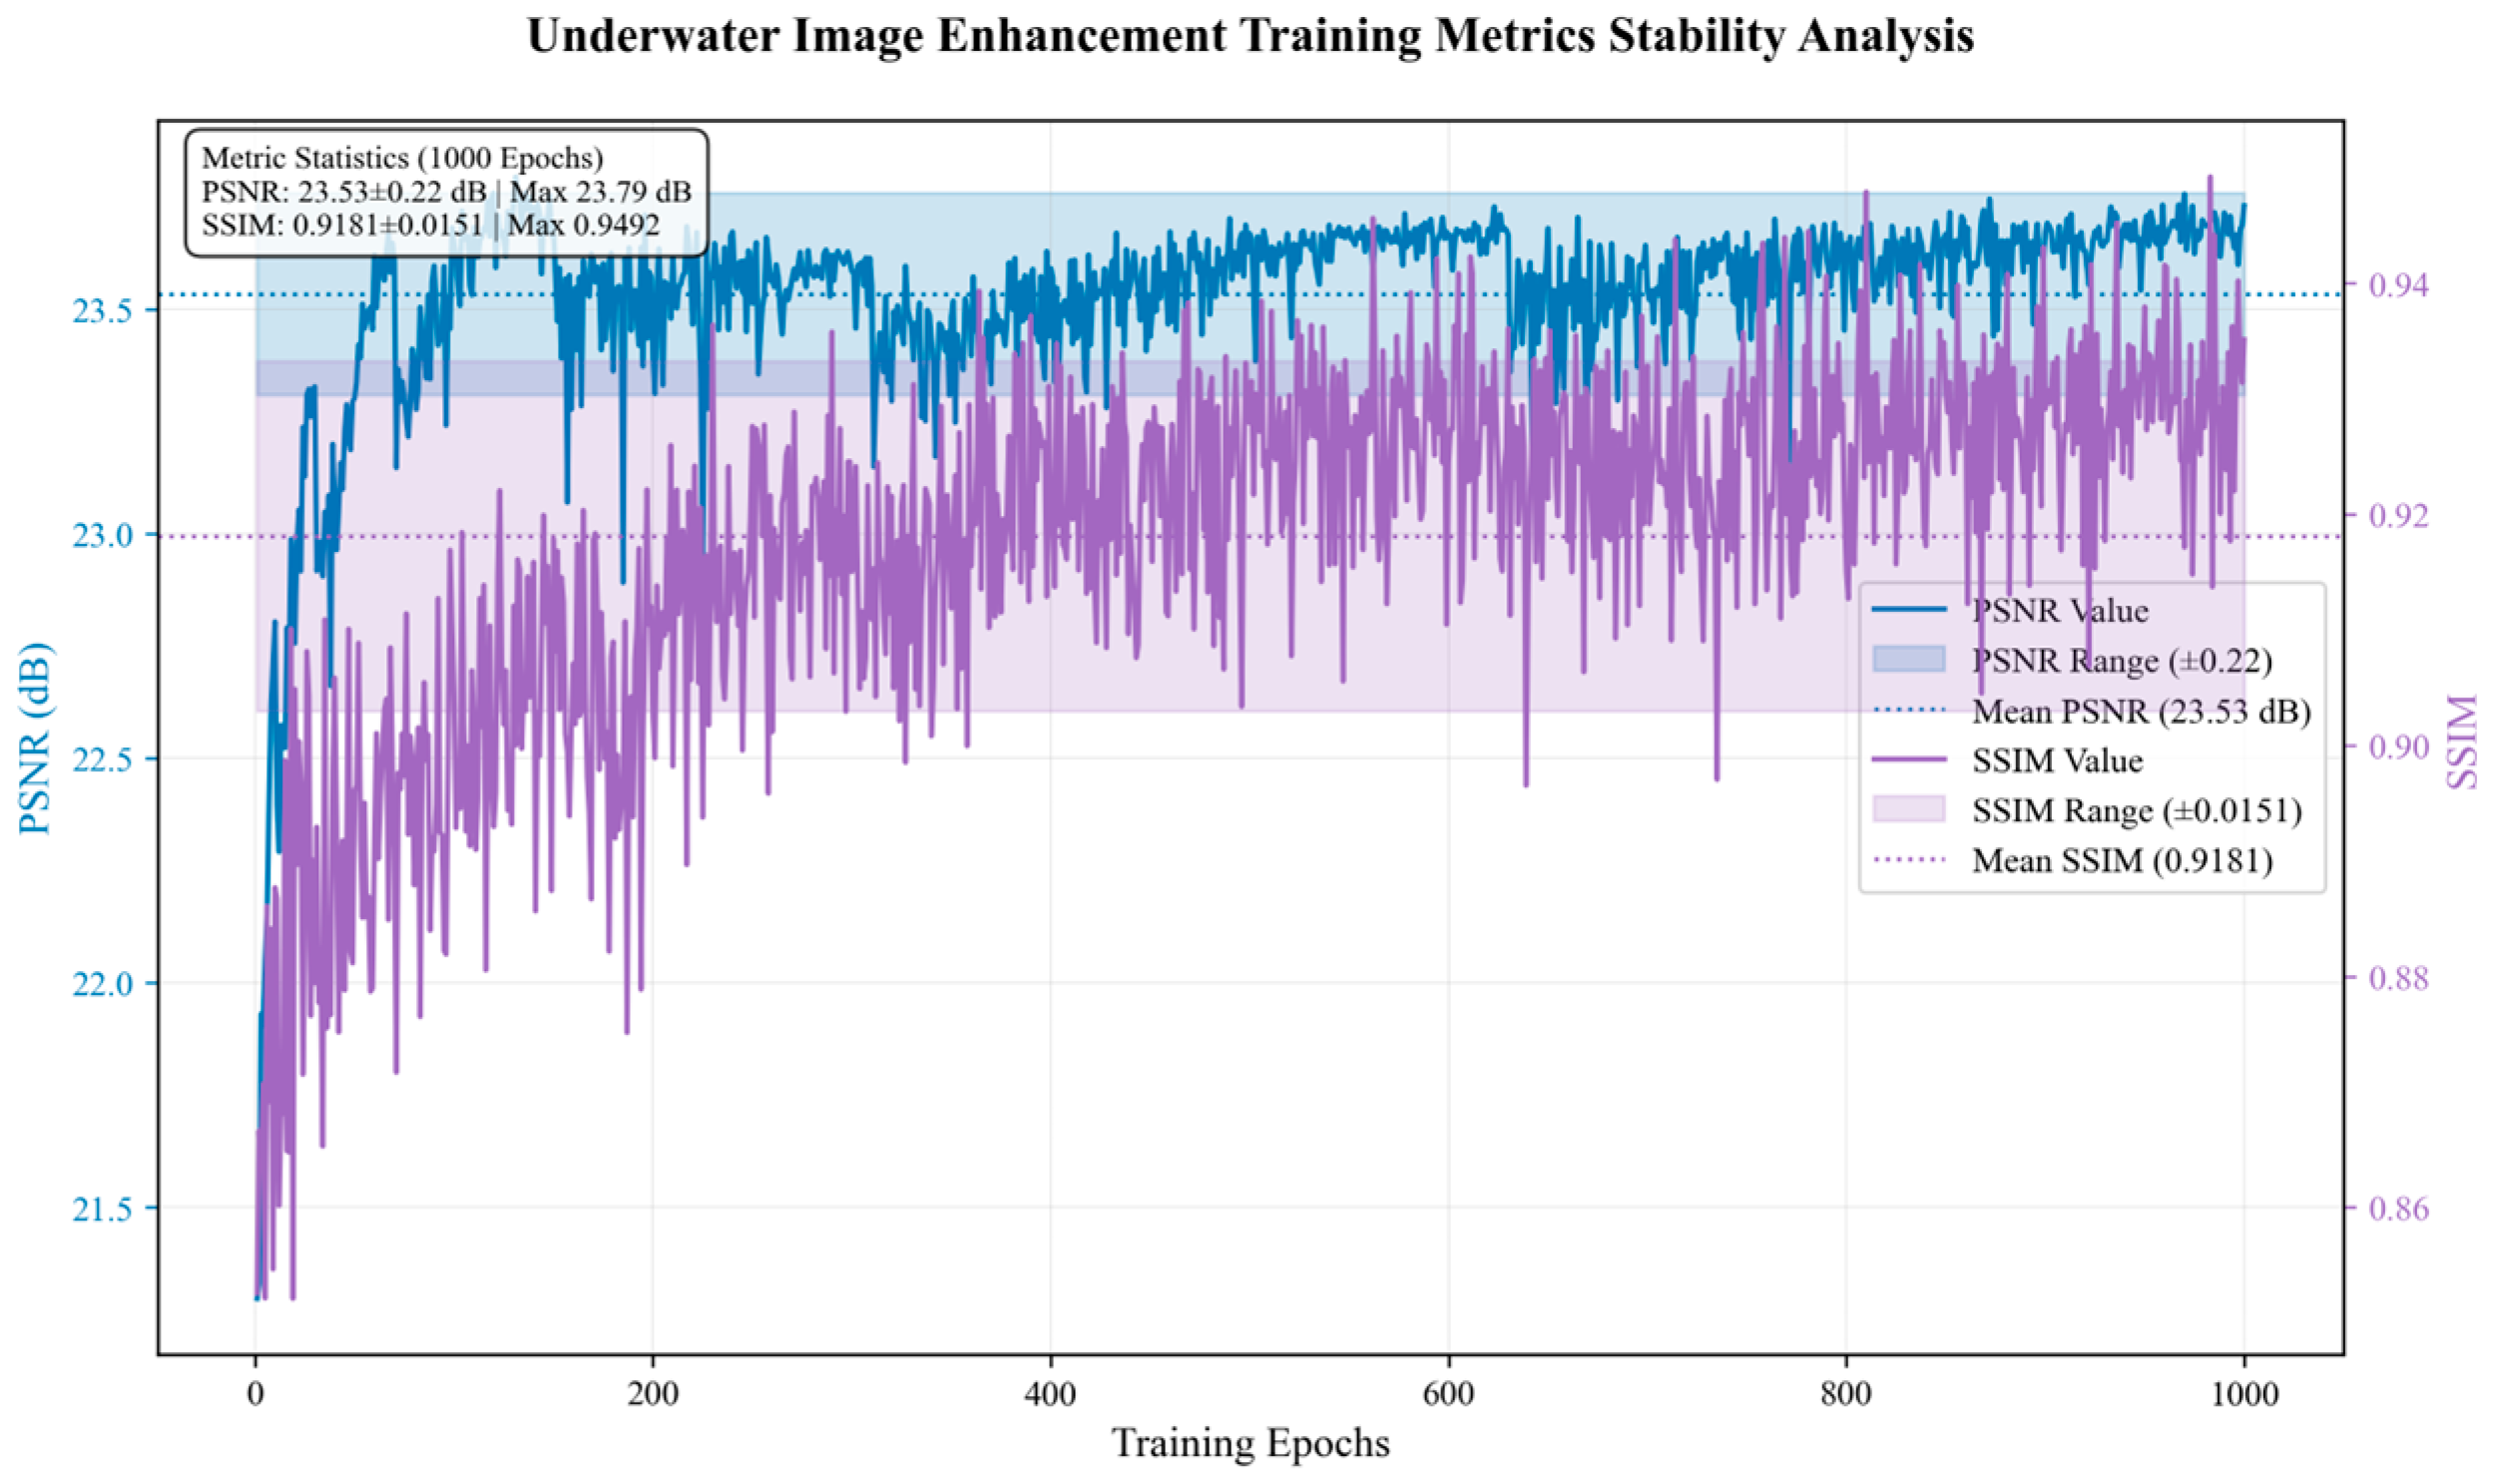
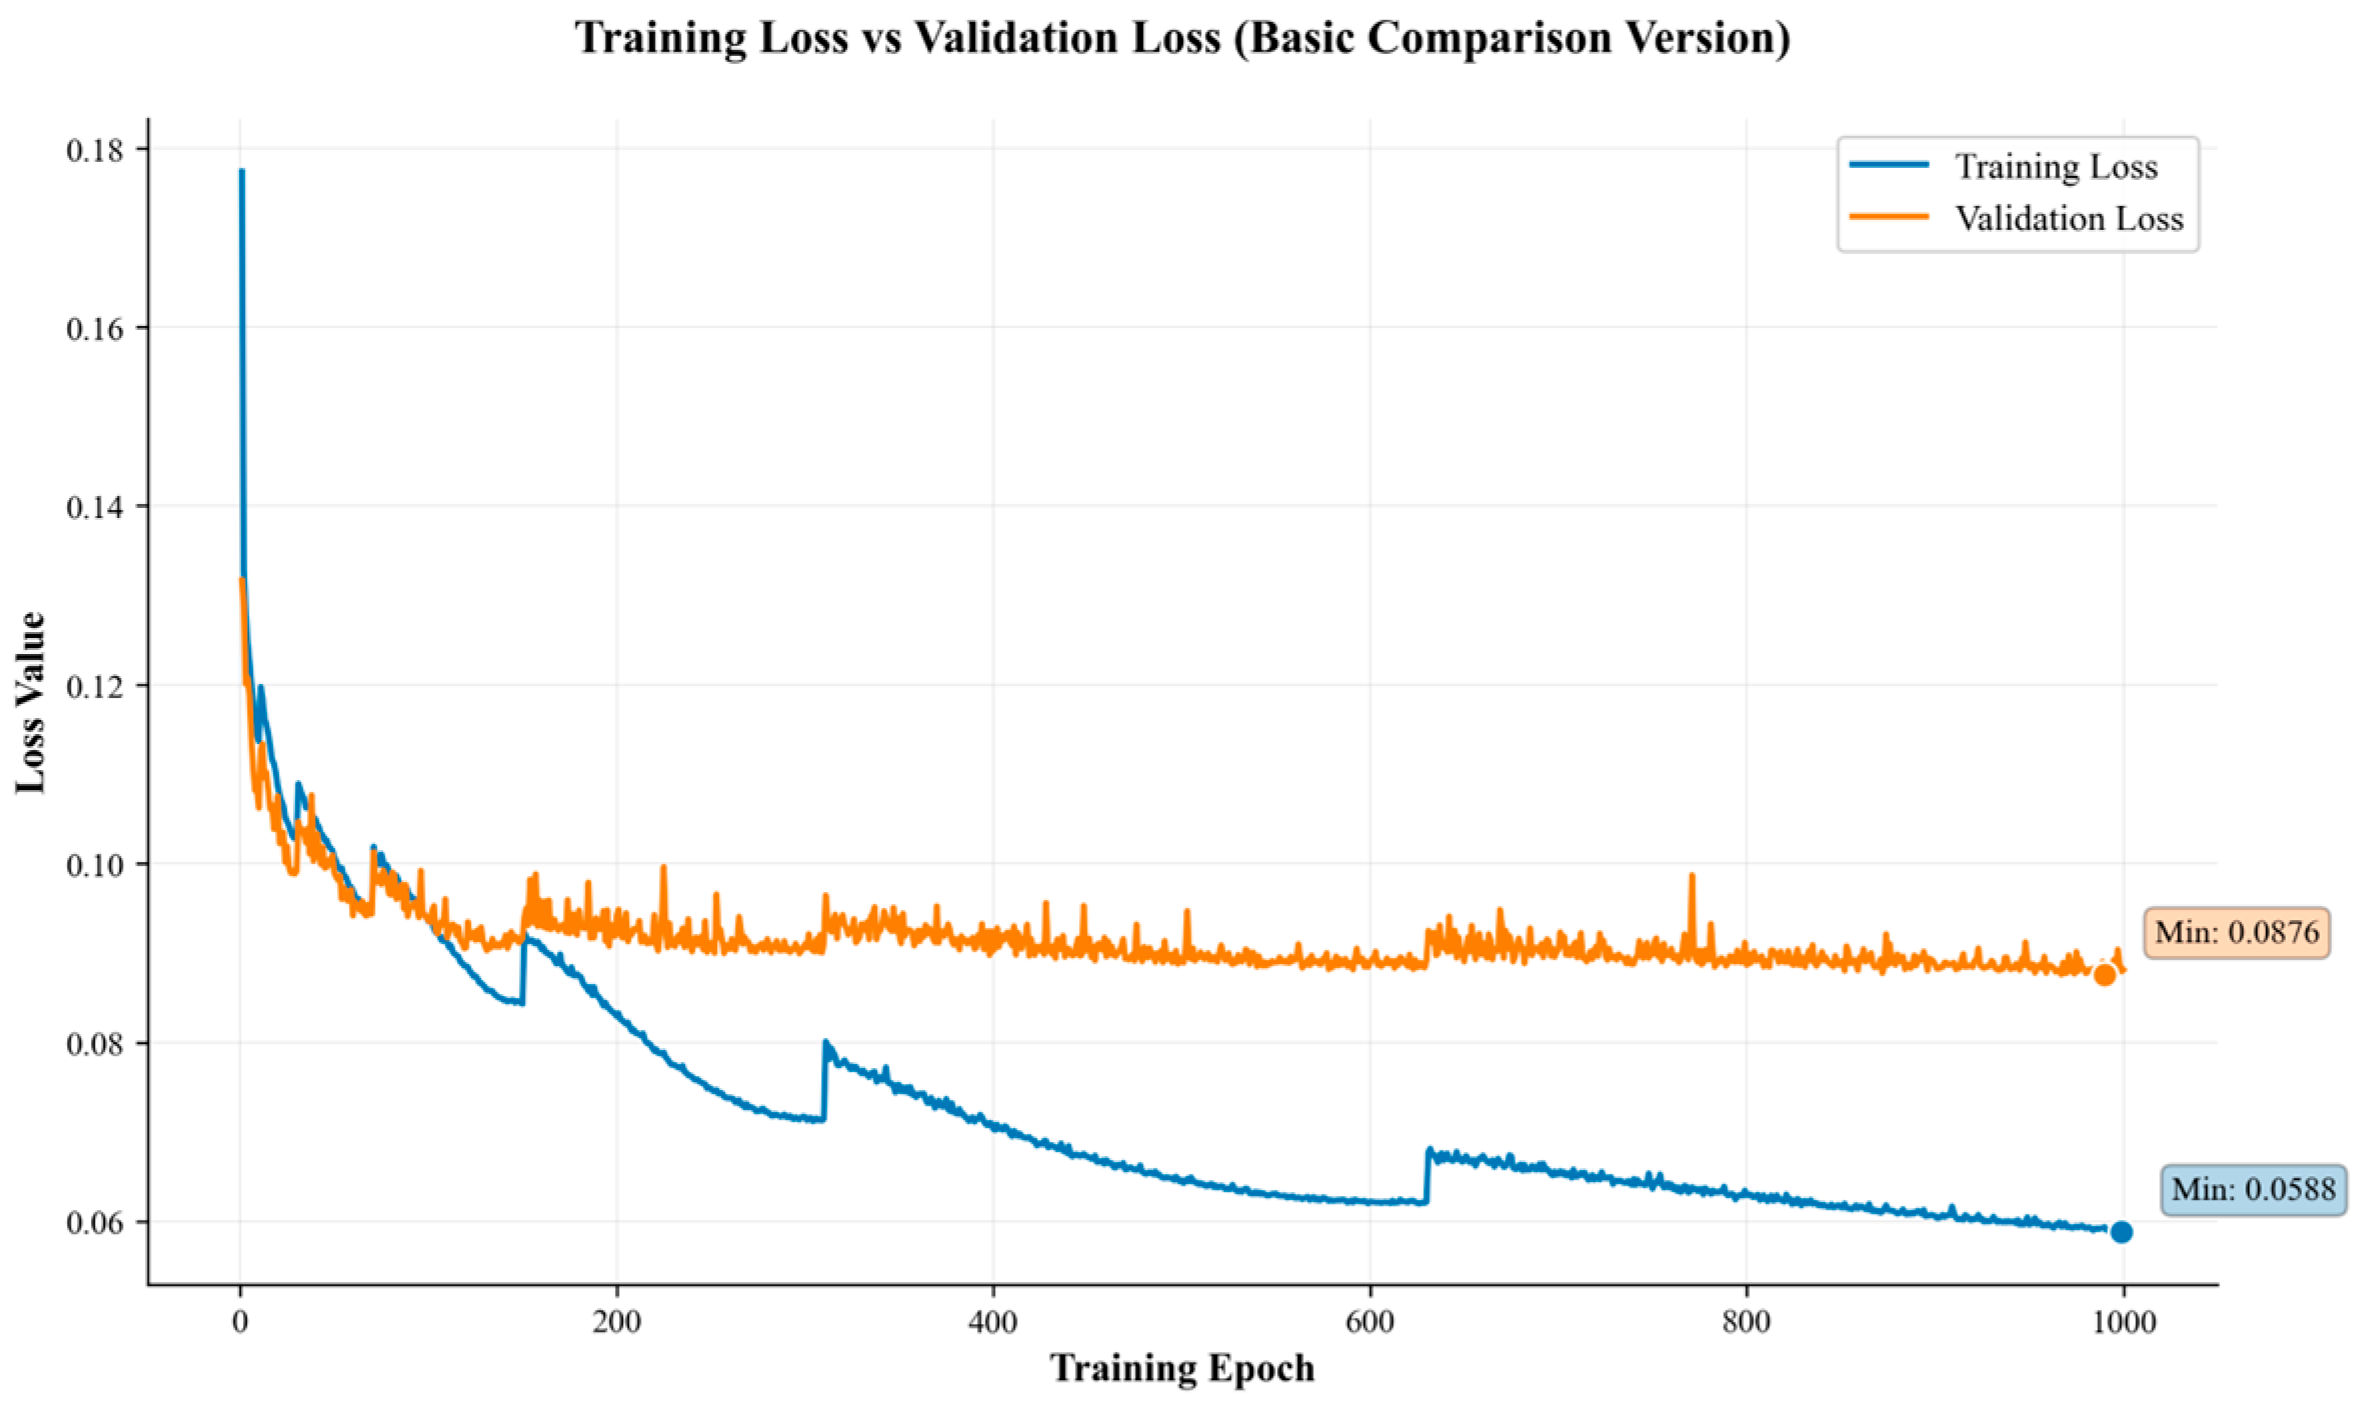
where denotes the total loss, represents the pixel-wise L1 loss, is the enhanced underwater image, refers to the ground-truth clear image, and the weighting coefficient is set to 0.5. The SSIM loss was calculated using a Gaussian kernel of size 11 and sigma value of 1.5. The learning rate was dynamically adjusted throughout training via a Cosine Annealing Warm Restarts scheduler, and the model was trained for a total of 1000 epochs. Periodic validation was performed to compute average validation loss (L1 + weighted SSIM loss) and peak signal-to-noise ratio (PSNR) as key evaluation metrics. The model weights were saved when the lowest validation loss was achieved, and TensorBoard was used to log training dynamics (including loss curves, PSNR values, learning rate variations, and visual comparisons of degraded, enhanced, and GT validation images).
Figure 4.
Variation in quantitative metrics (PSNR and SSIM) during the model training process.
Figure 5.
Trend of training and validation loss values throughout the training procedure.
5. Experiments and Discussion
The proposed underwater image enhancement method was evaluated and compared with eight state-of-the-art (SOTA) approaches: UCDP [6], WWPE [56], Water-Net [12], Ucolour [57], FUnIE GAN [14], Ushape [17], DM-Water [20], and Diff-Water [58]. Experiments were conducted on four publicly available underwater datasets: UIEB, LSUI, U45 and C60, which cover diverse underwater conditions including varying turbidity, colour casts and lighting scenarios.
5.1. Ablation Study
Ablation tests were implemented to validate the effectiveness of Gaussian Blur regularisation and varying SSIM loss weights (as presented in Table 2). The baseline without Gaussian Blur obtains decent UCIQE but inferior UIQM and NIQE due to over-sharpening bias. Raising SSIM loss weight from 0.3 to 0.7 significantly boosts PSNR, SSIM and UIQM at the cost of degraded colour and naturalness metrics. Our full model combining Gaussian Blur regularisation achieves well-balanced scores across all criteria, confirming that SSIM loss optimises structural retention while Gaussian Blur regularisation restrains unreasonable over-enhancement for comprehensive underwater image enhancement.
Table 2.
Results of ablation study.
We conducted repeated experiments with random seeds. The small standard deviations verify the stability of our ablation results. Configurations with different SSIM weights show distinguishable performance in terms of PSNR, UIQM and UCIQE.
5.2. Qualitative Comparisons
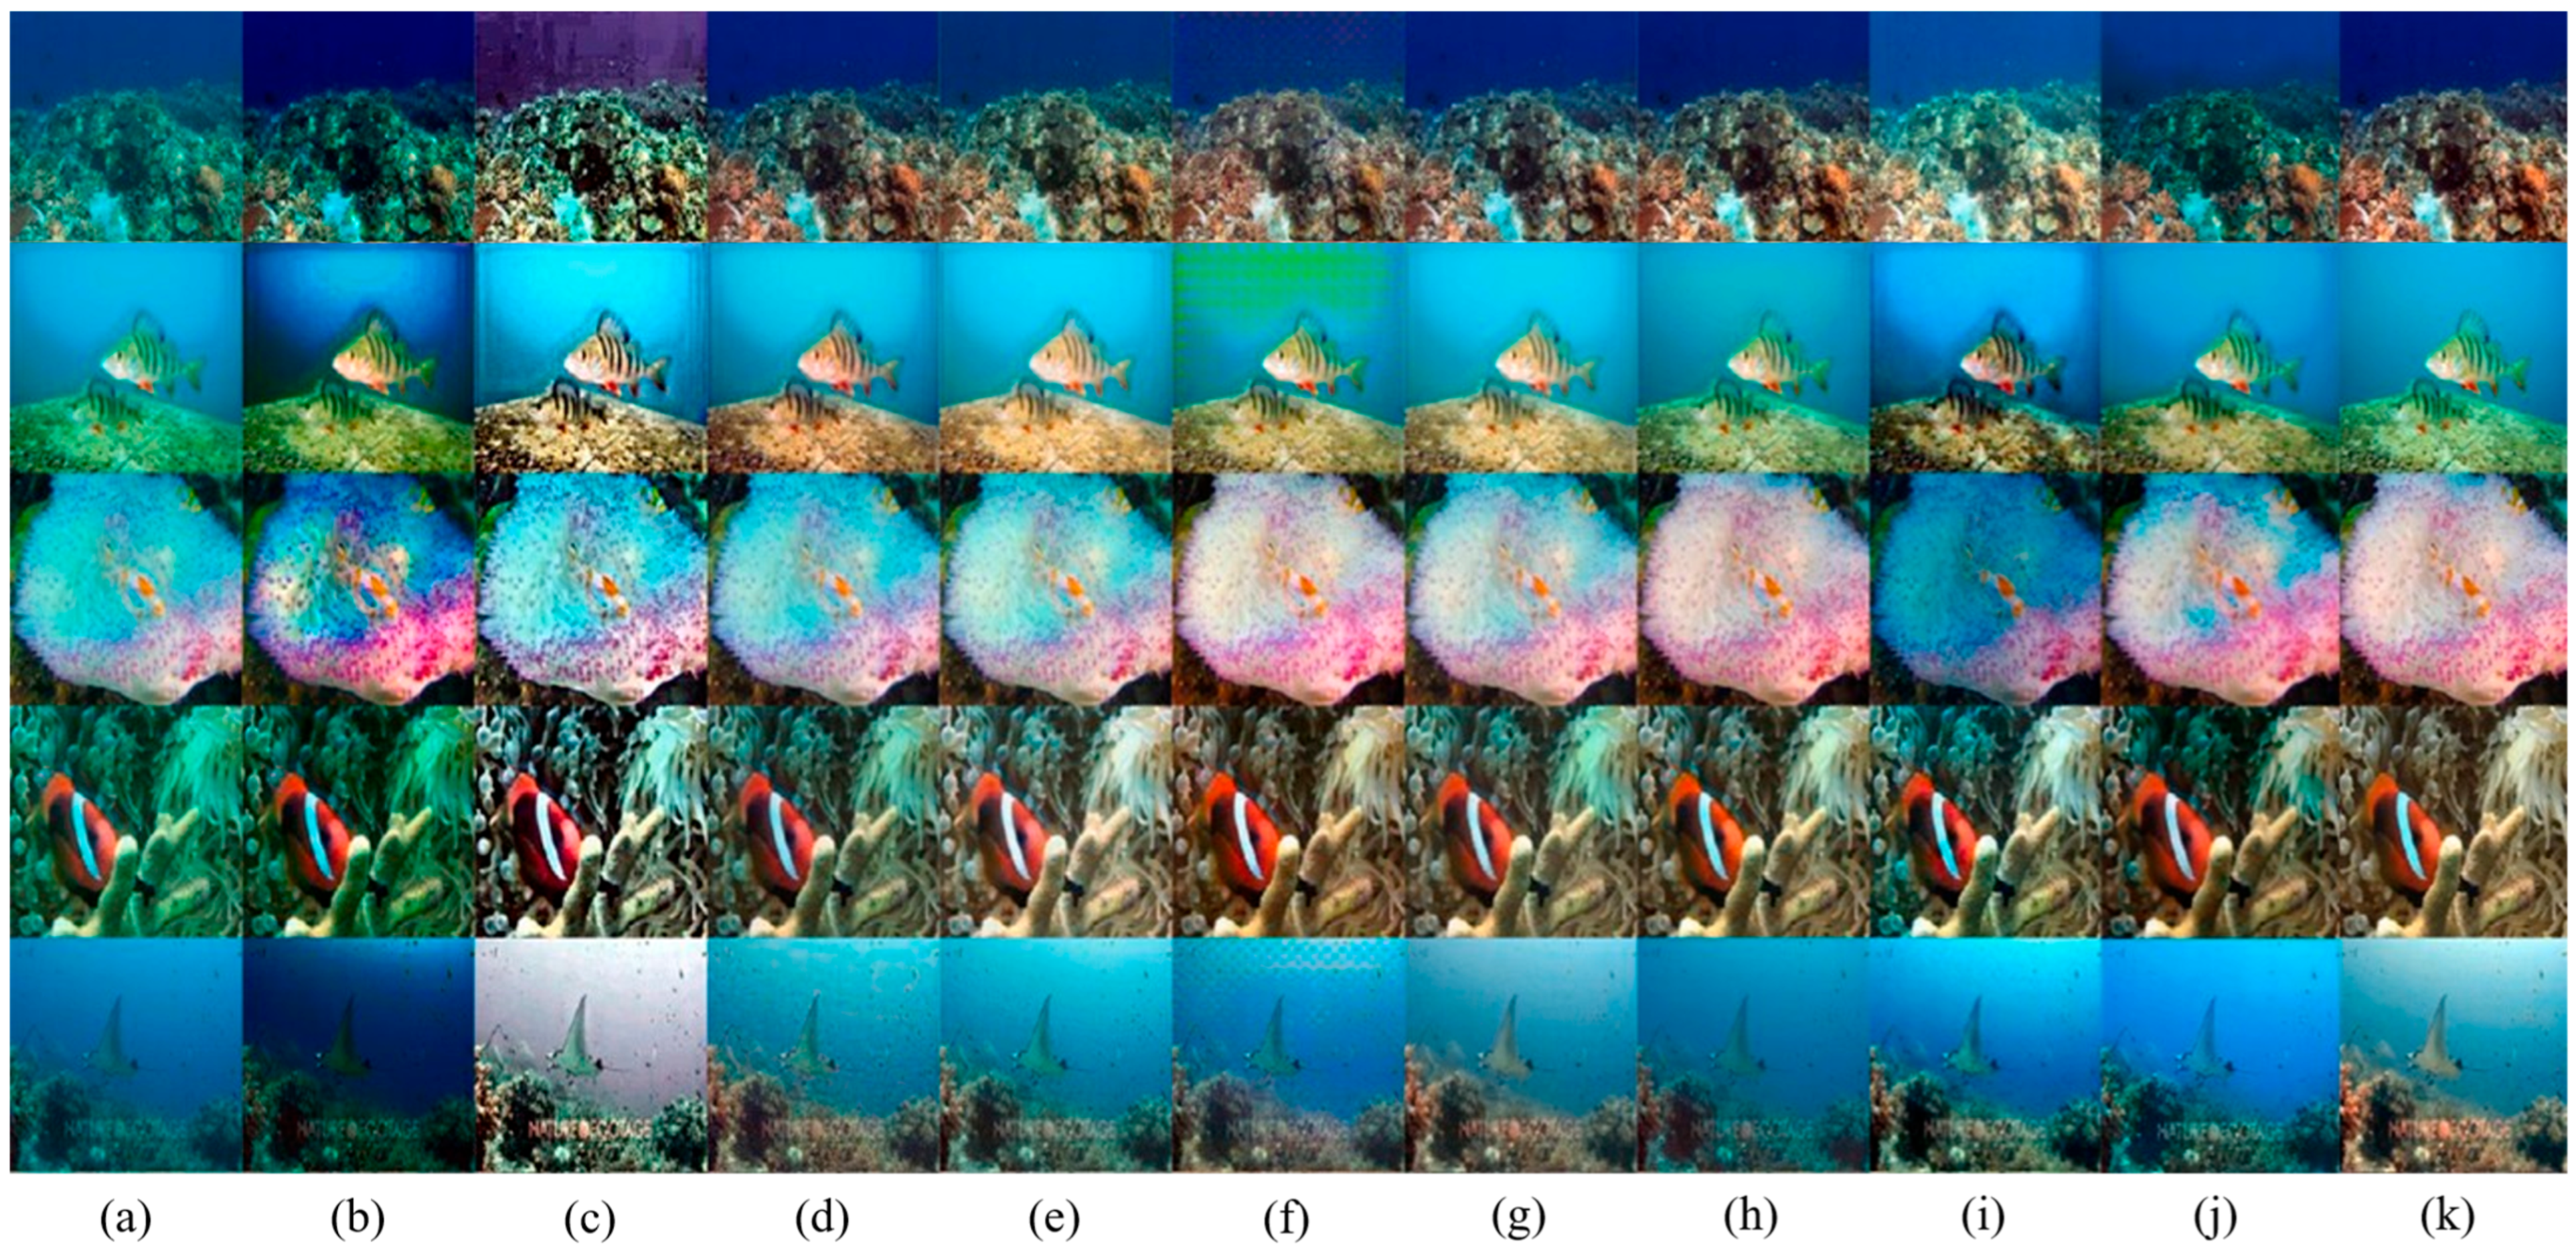
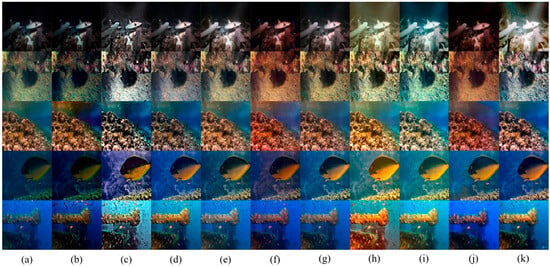
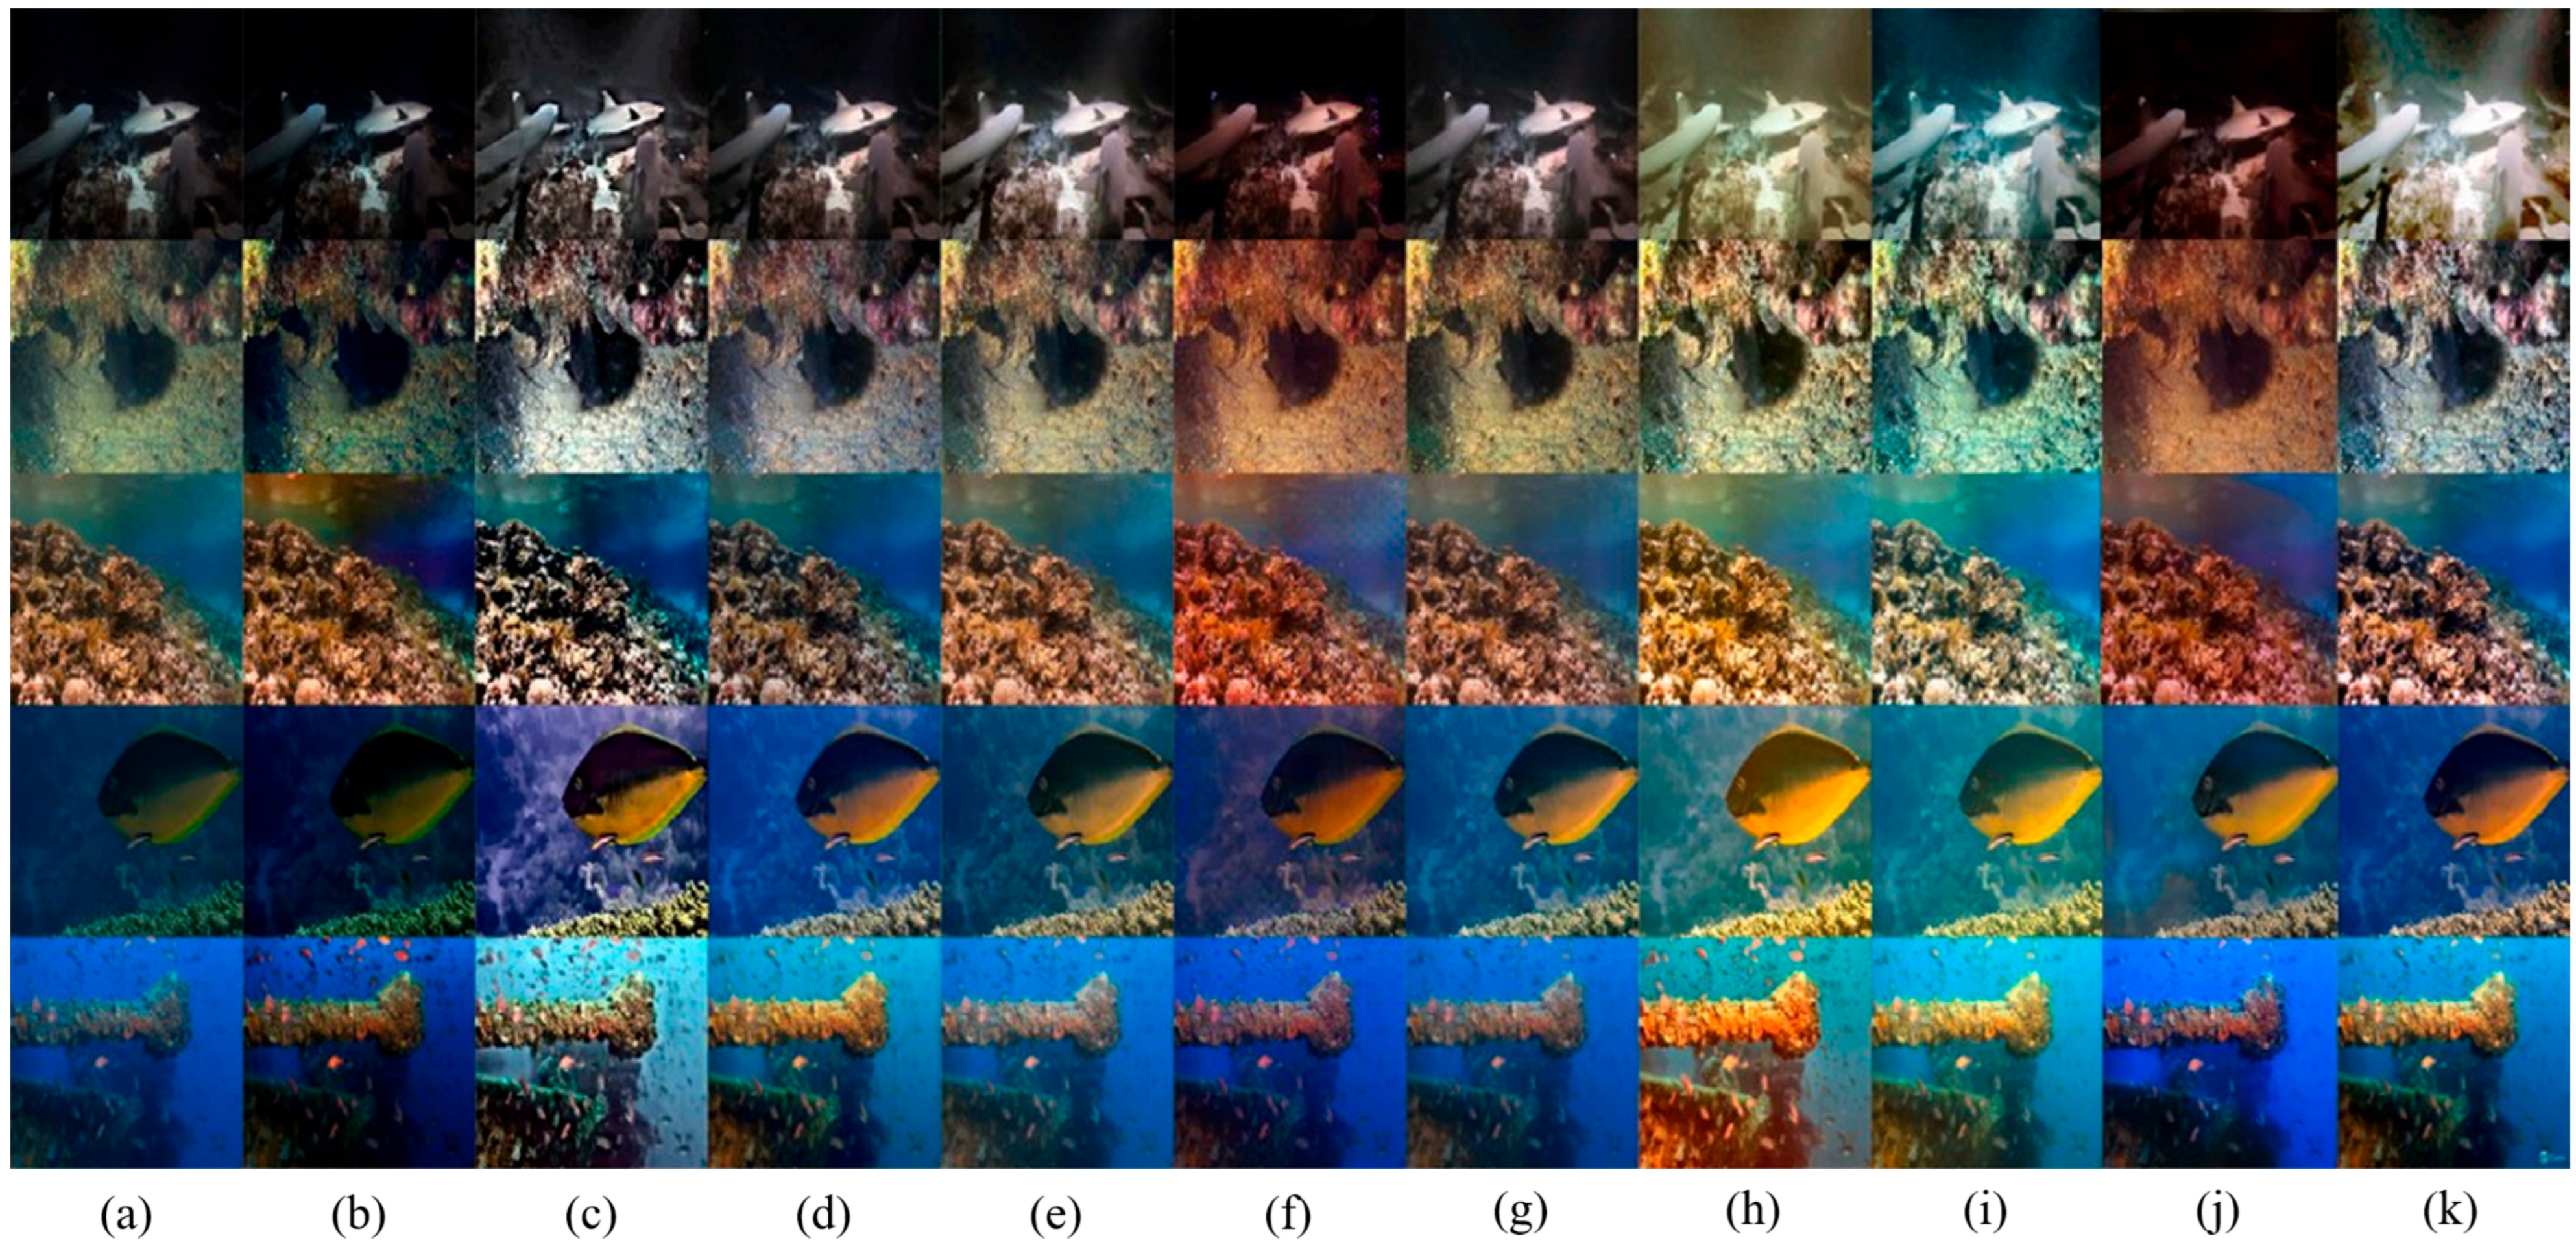
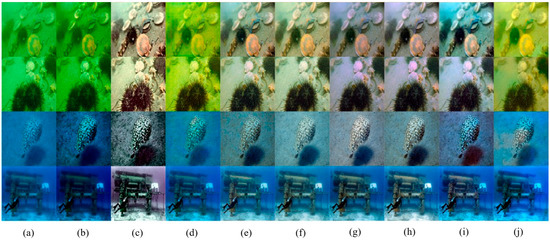
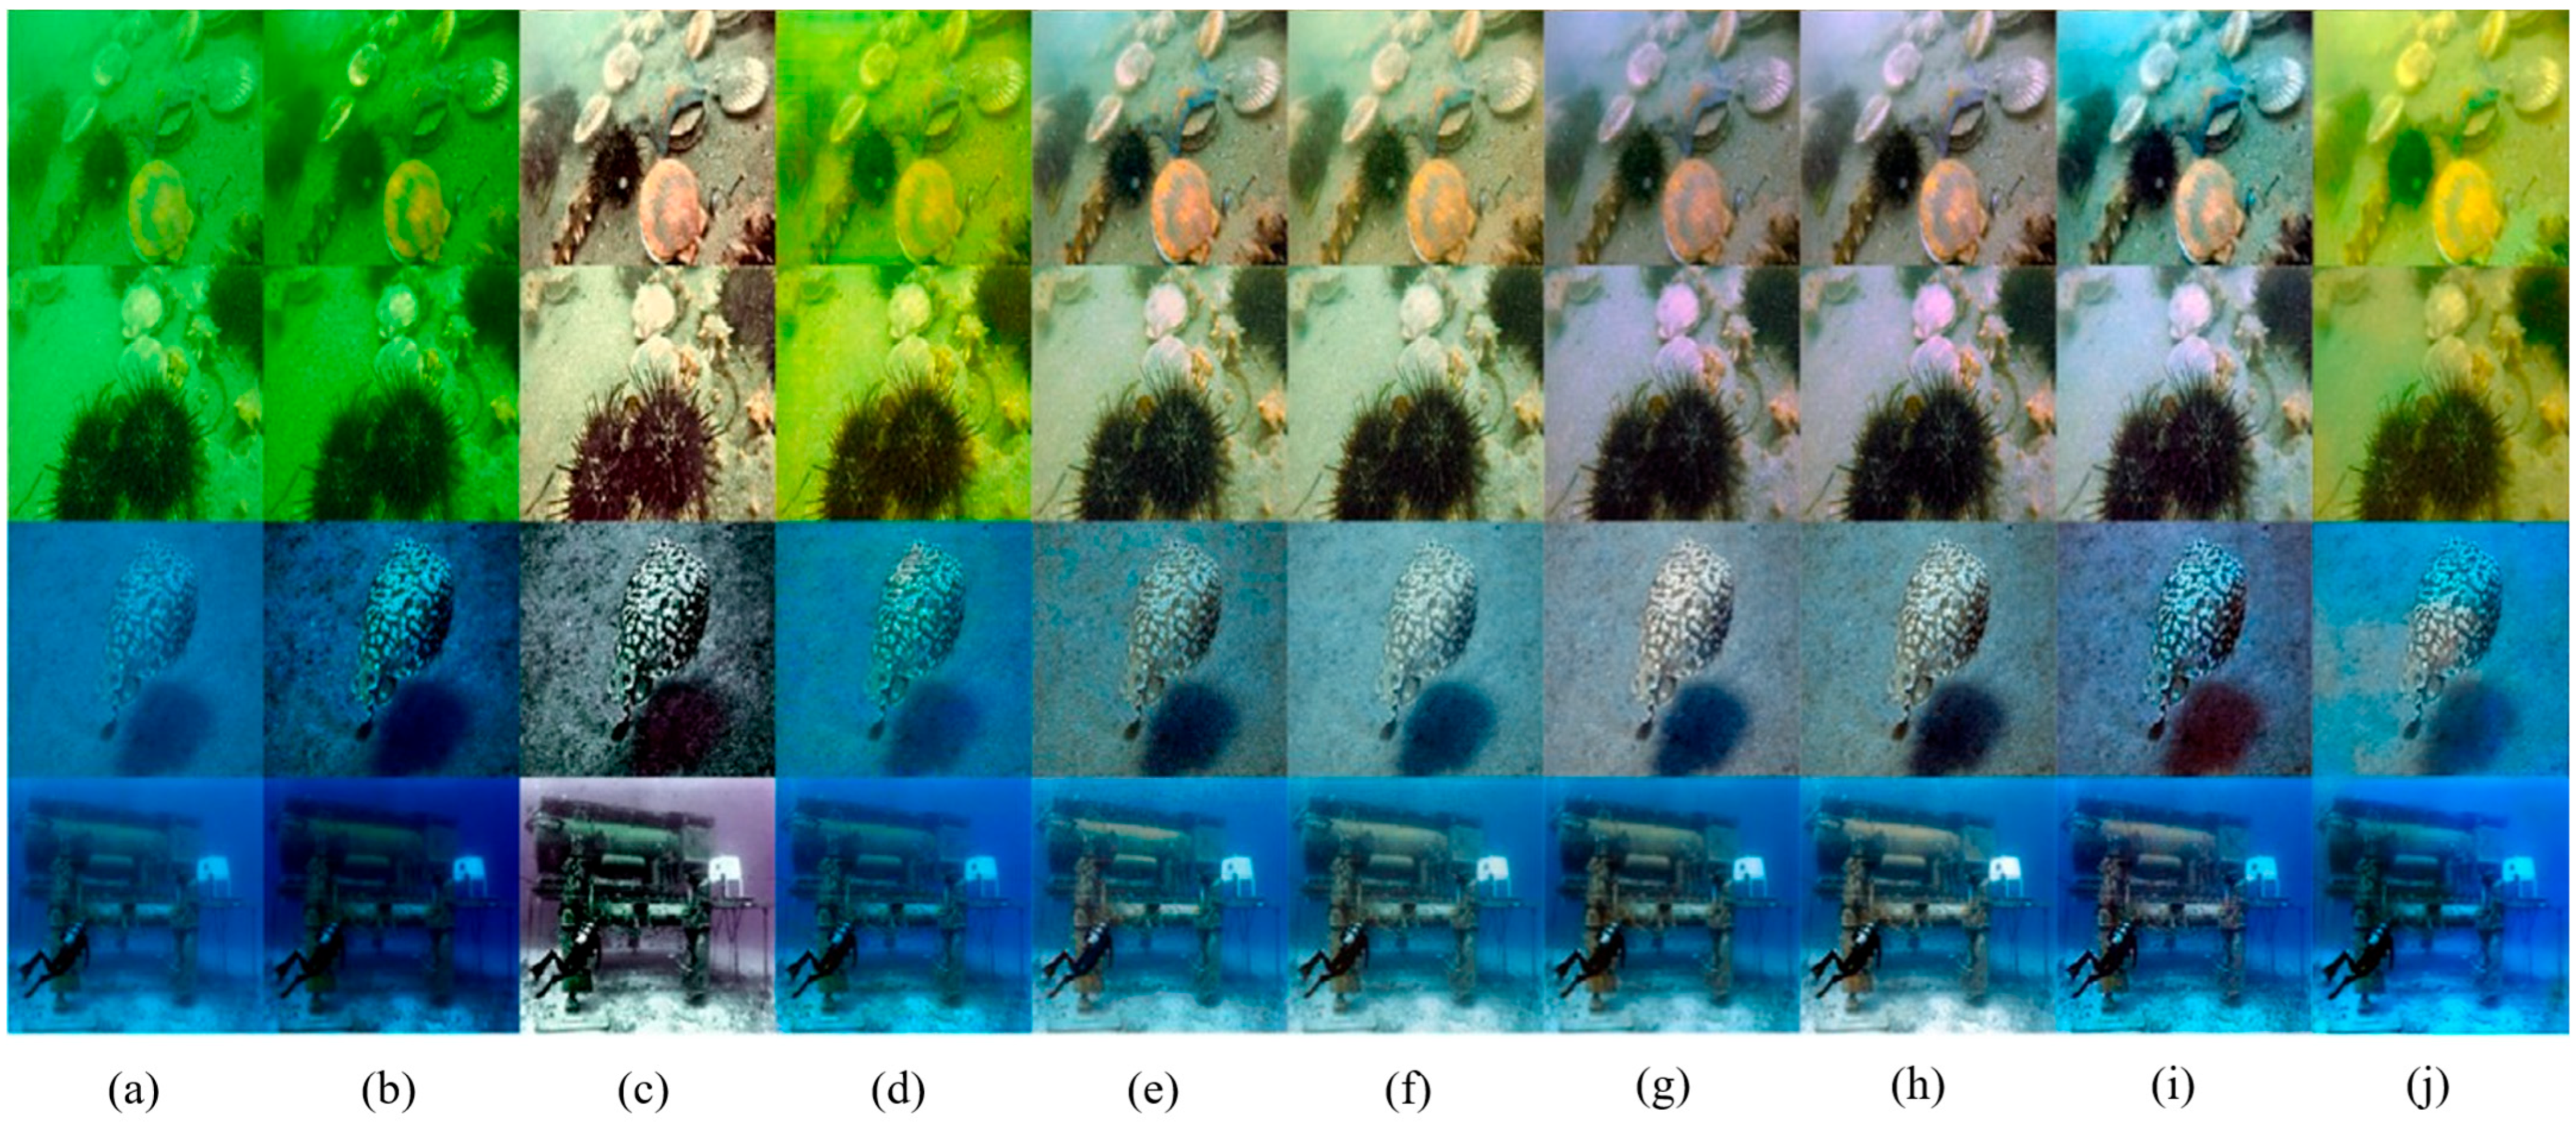
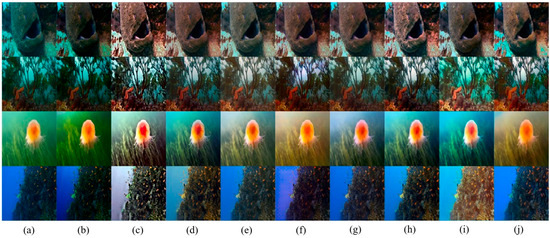
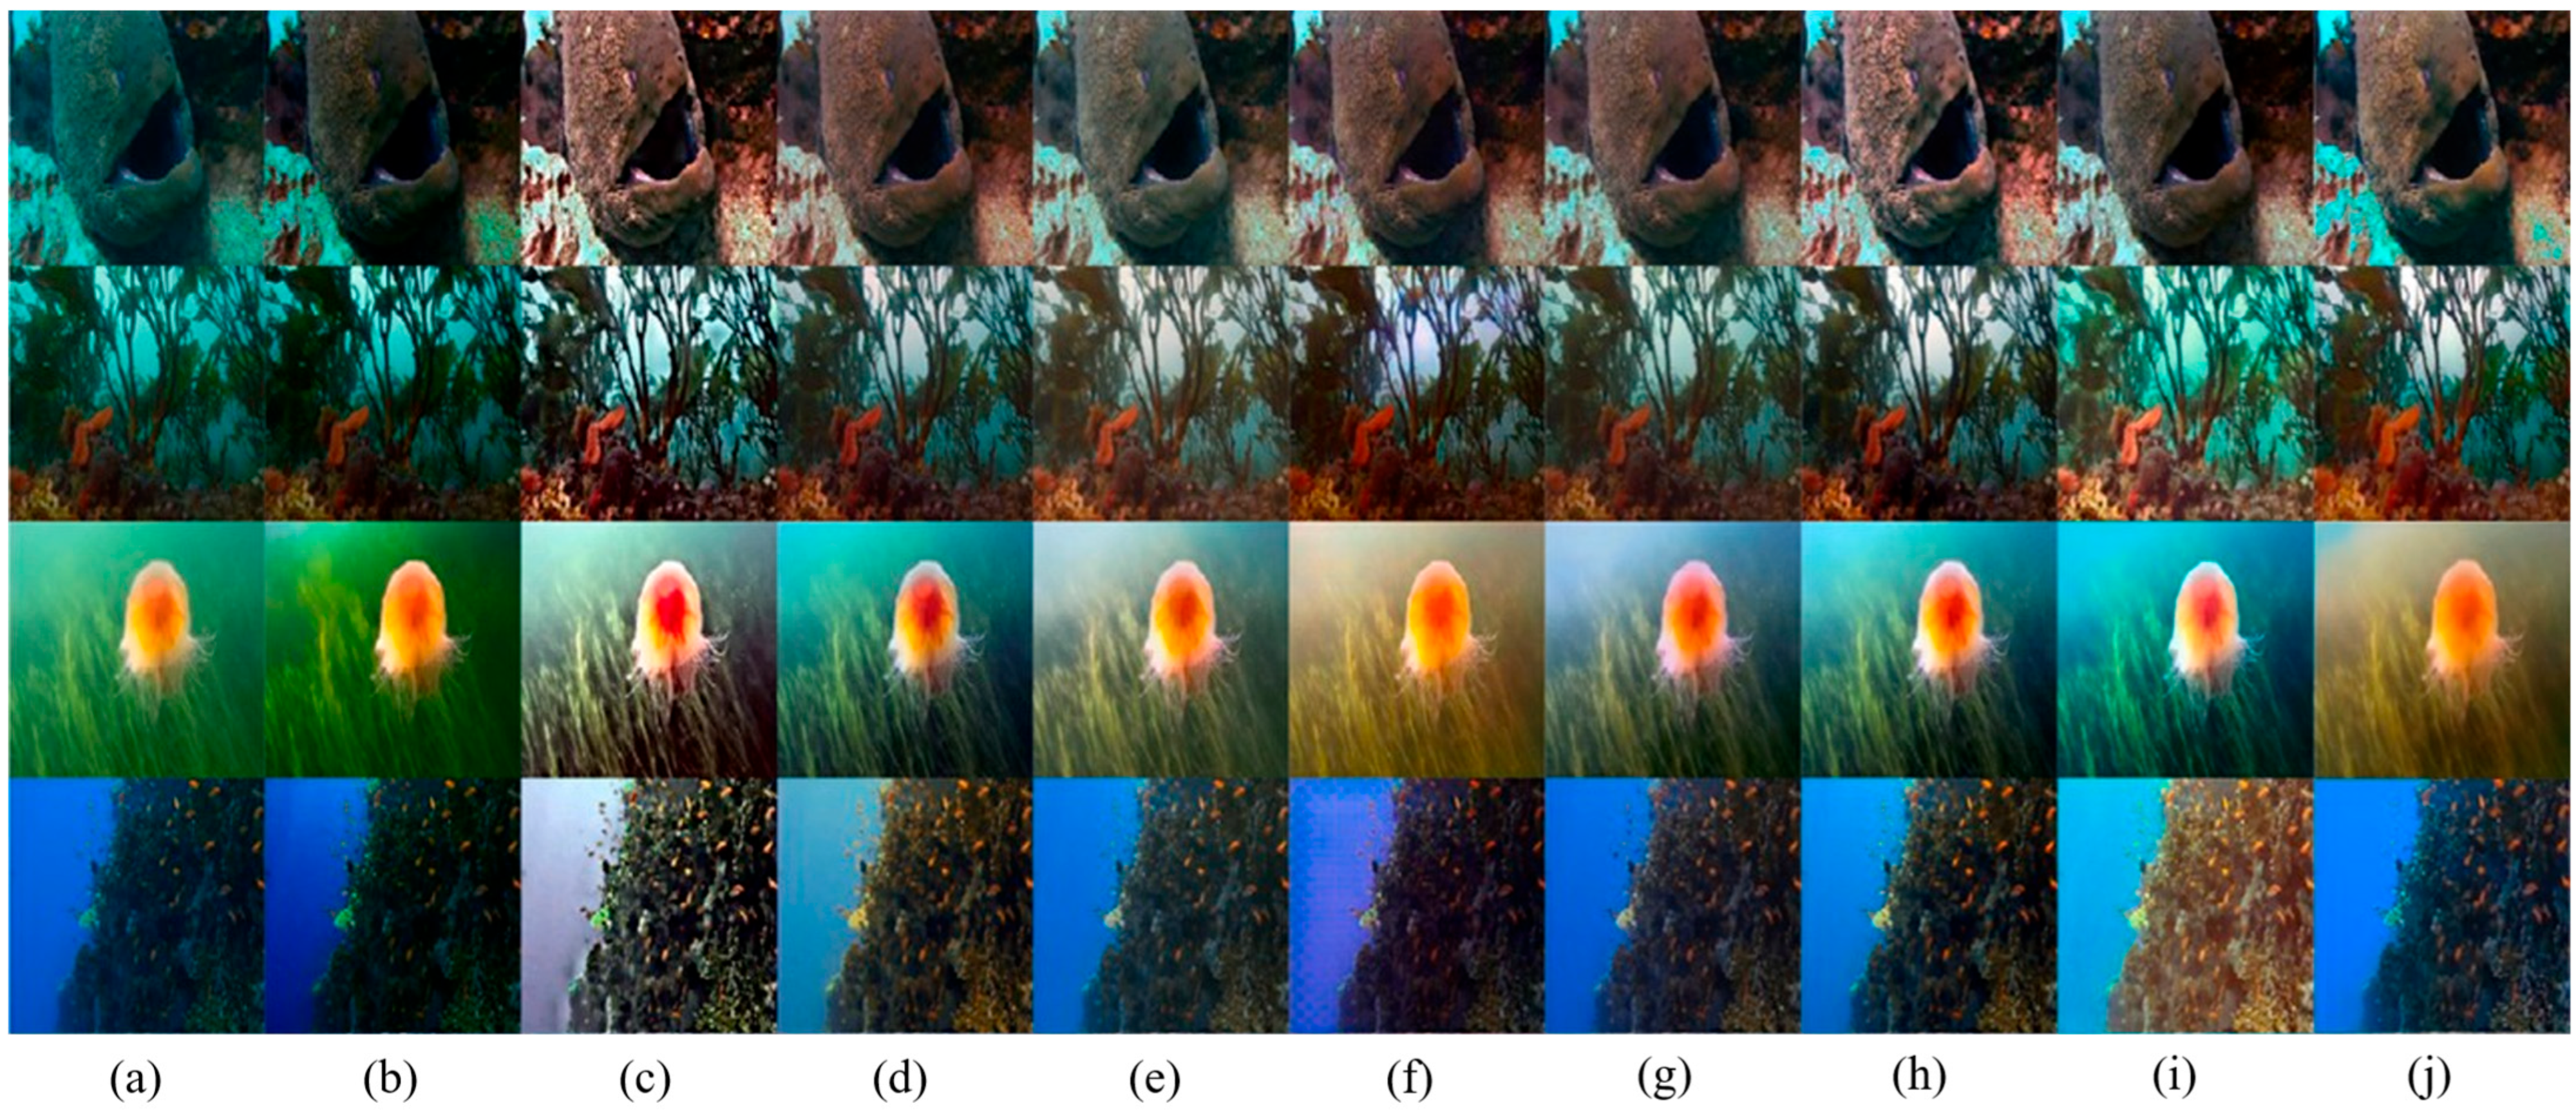
The enhancement outcomes of the various comparative methods are illustrated Figure 6, Figure 7, Figure 8 and Figure 9. A comprehensive analysis reveals that no single method achieves perfect performance across all scenarios, with each approach exhibiting distinct strengths and weaknesses.
Figure 6.
Visualisation of different enhancement methods on UIEB. From left to right, the images are (a) RAW, (b) UDCP, (c) WWPE, (d) Water-Net, (e) Ucolour, (f) FunIE, (g) Ushape, (h) DM-Water, (i) Diff-Water, (j) our method, and (k) the ground truth.
Figure 7.
Visualisation of different enhancement methods on LSUI. From left to right, the images are (a) RAW, (b) UDCP, (c) WWPE, (d) Water-Net, (e) Ucolour, (f) FunIE, (g) Ushape, (h) DM-Water, (i) Diff-Water, (j) our method, and (k) the ground truth.
Figure 8.
Visualisation of different enhancement methods on U45. From left to right, the images are (a) RAW, (b) UDCP, (c) WWPE, (d) Water-Net, (e) Ucolour, (f) FunIE, (g) Ushape, (h) DM-Water, (i) Diff-Water, and (j) our method.
Figure 9.
Visualisation of different enhancement methods on C60. From left to right, the images are (a) RAW, (b) UDCP, (c) WWPE, (d) Water-Net, (e) Ucolour, (f) FunIE, (g) Ushape, (h) DM-Water, (i) Diff-Water, and (j) our method.
The physical modelling-based UDCP (column b) effectively boosts image contrast but proves inadequate in mitigating severe blue–green colour casts, as evident in the coral reef scenes in Figure 6b and Figure 7b. WWPE (column c) focuses on high contrast enhancement and colour correction, yet it tends to overcorrect underwater backgrounds, resulting in unnatural reddish tints in Figure 9c.
CNN-based models such as Water-Net (column d) and Ucolour (column e) demonstrate reasonable generalisation across diverse underwater scenes. However, Water-Net frequently introduces blurring artefacts and loses fine textures, particularly visible in the fish scales in Figure 6d and the coral details in Figure 7d. Ucolour produces relatively natural colour tones but suffers from low contrast in turbid scenes, as shown in Figure 8e.
GAN-based FUnIE GAN (column f) achieves fast processing speed but often generates unrealistic colour artefacts, such as the green artefacts of Figure 6f and the purple hue in the background of Figure 9f. Transformer-based Ushape (column g) excels at global colour correction but struggles to recover fine local details, leading to over-smoothing in textured regions in Figure 6g.
Diffusion models including DM-Water (column h) and Diff-Water (column i) deliver high-fidelity restoration in many cases. DM-Water achieves excellent colour accuracy but occasionally produces over-saturated results, as seen in Figure 7h. Diff-Water effectively removes haze but tends to introduce noise in dark regions, visible in Figure 8i.
The proposed TIDE-Net (column j) consistently produces visually pleasing results that are closest to the ground truth (column k) across all datasets. It effectively eliminates blue–green colour casts without introducing artefacts, preserves fine textures such as fish scales and coral polyps, and maintains balanced brightness distribution. For example, in Figure 6j, TIDE-Net accurately recovers the natural colour of the coral reef while retaining sharp edge details, outperforming all other methods in both colour fidelity and texture preservation. In the low-light turbid scene of Figure 7j, our method successfully enhances visibility without amplifying noise, demonstrating superior robustness to challenging underwater conditions.
5.3. Quantitative Comparisons
The average quantitative experimental results demonstrated that the proposed method achieved outstanding performance in the full-reference evaluation indicators (as presented in Table 2), with an average PSNR value of 29.44 dB and an average SSIM value reaching 0.94, both of which surpass all involved comparison methods significantly. Such numerical advantages fully prove that the proposed strategy can effectively restore real scene information while completing image enhancement, maintain the complete edge textures and spatial structural features of the original underwater images, and effectively avoid common visual distortion and detail loss phenomena caused by excessive enhancement in many existing algorithms. In specific numerical comparison, the PSNR index of this method is 1.79 dB higher than that of the suboptimal DM-Water method, and there is an even more obvious performance gap when compared with traditional classic underwater enhancement models such as Water-Net.
When observing the experimental results on separate datasets, it can be clearly found that the proposed method maintains stable indicator outputs in test datasets, without obvious performance attenuation affected by changes in water environment, which reflects its generalisation ability in complex underwater scenes.
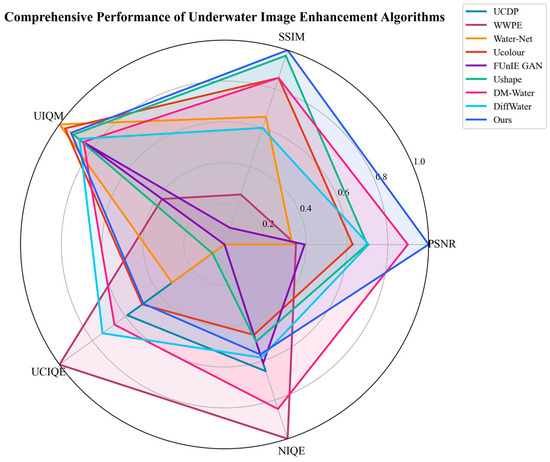
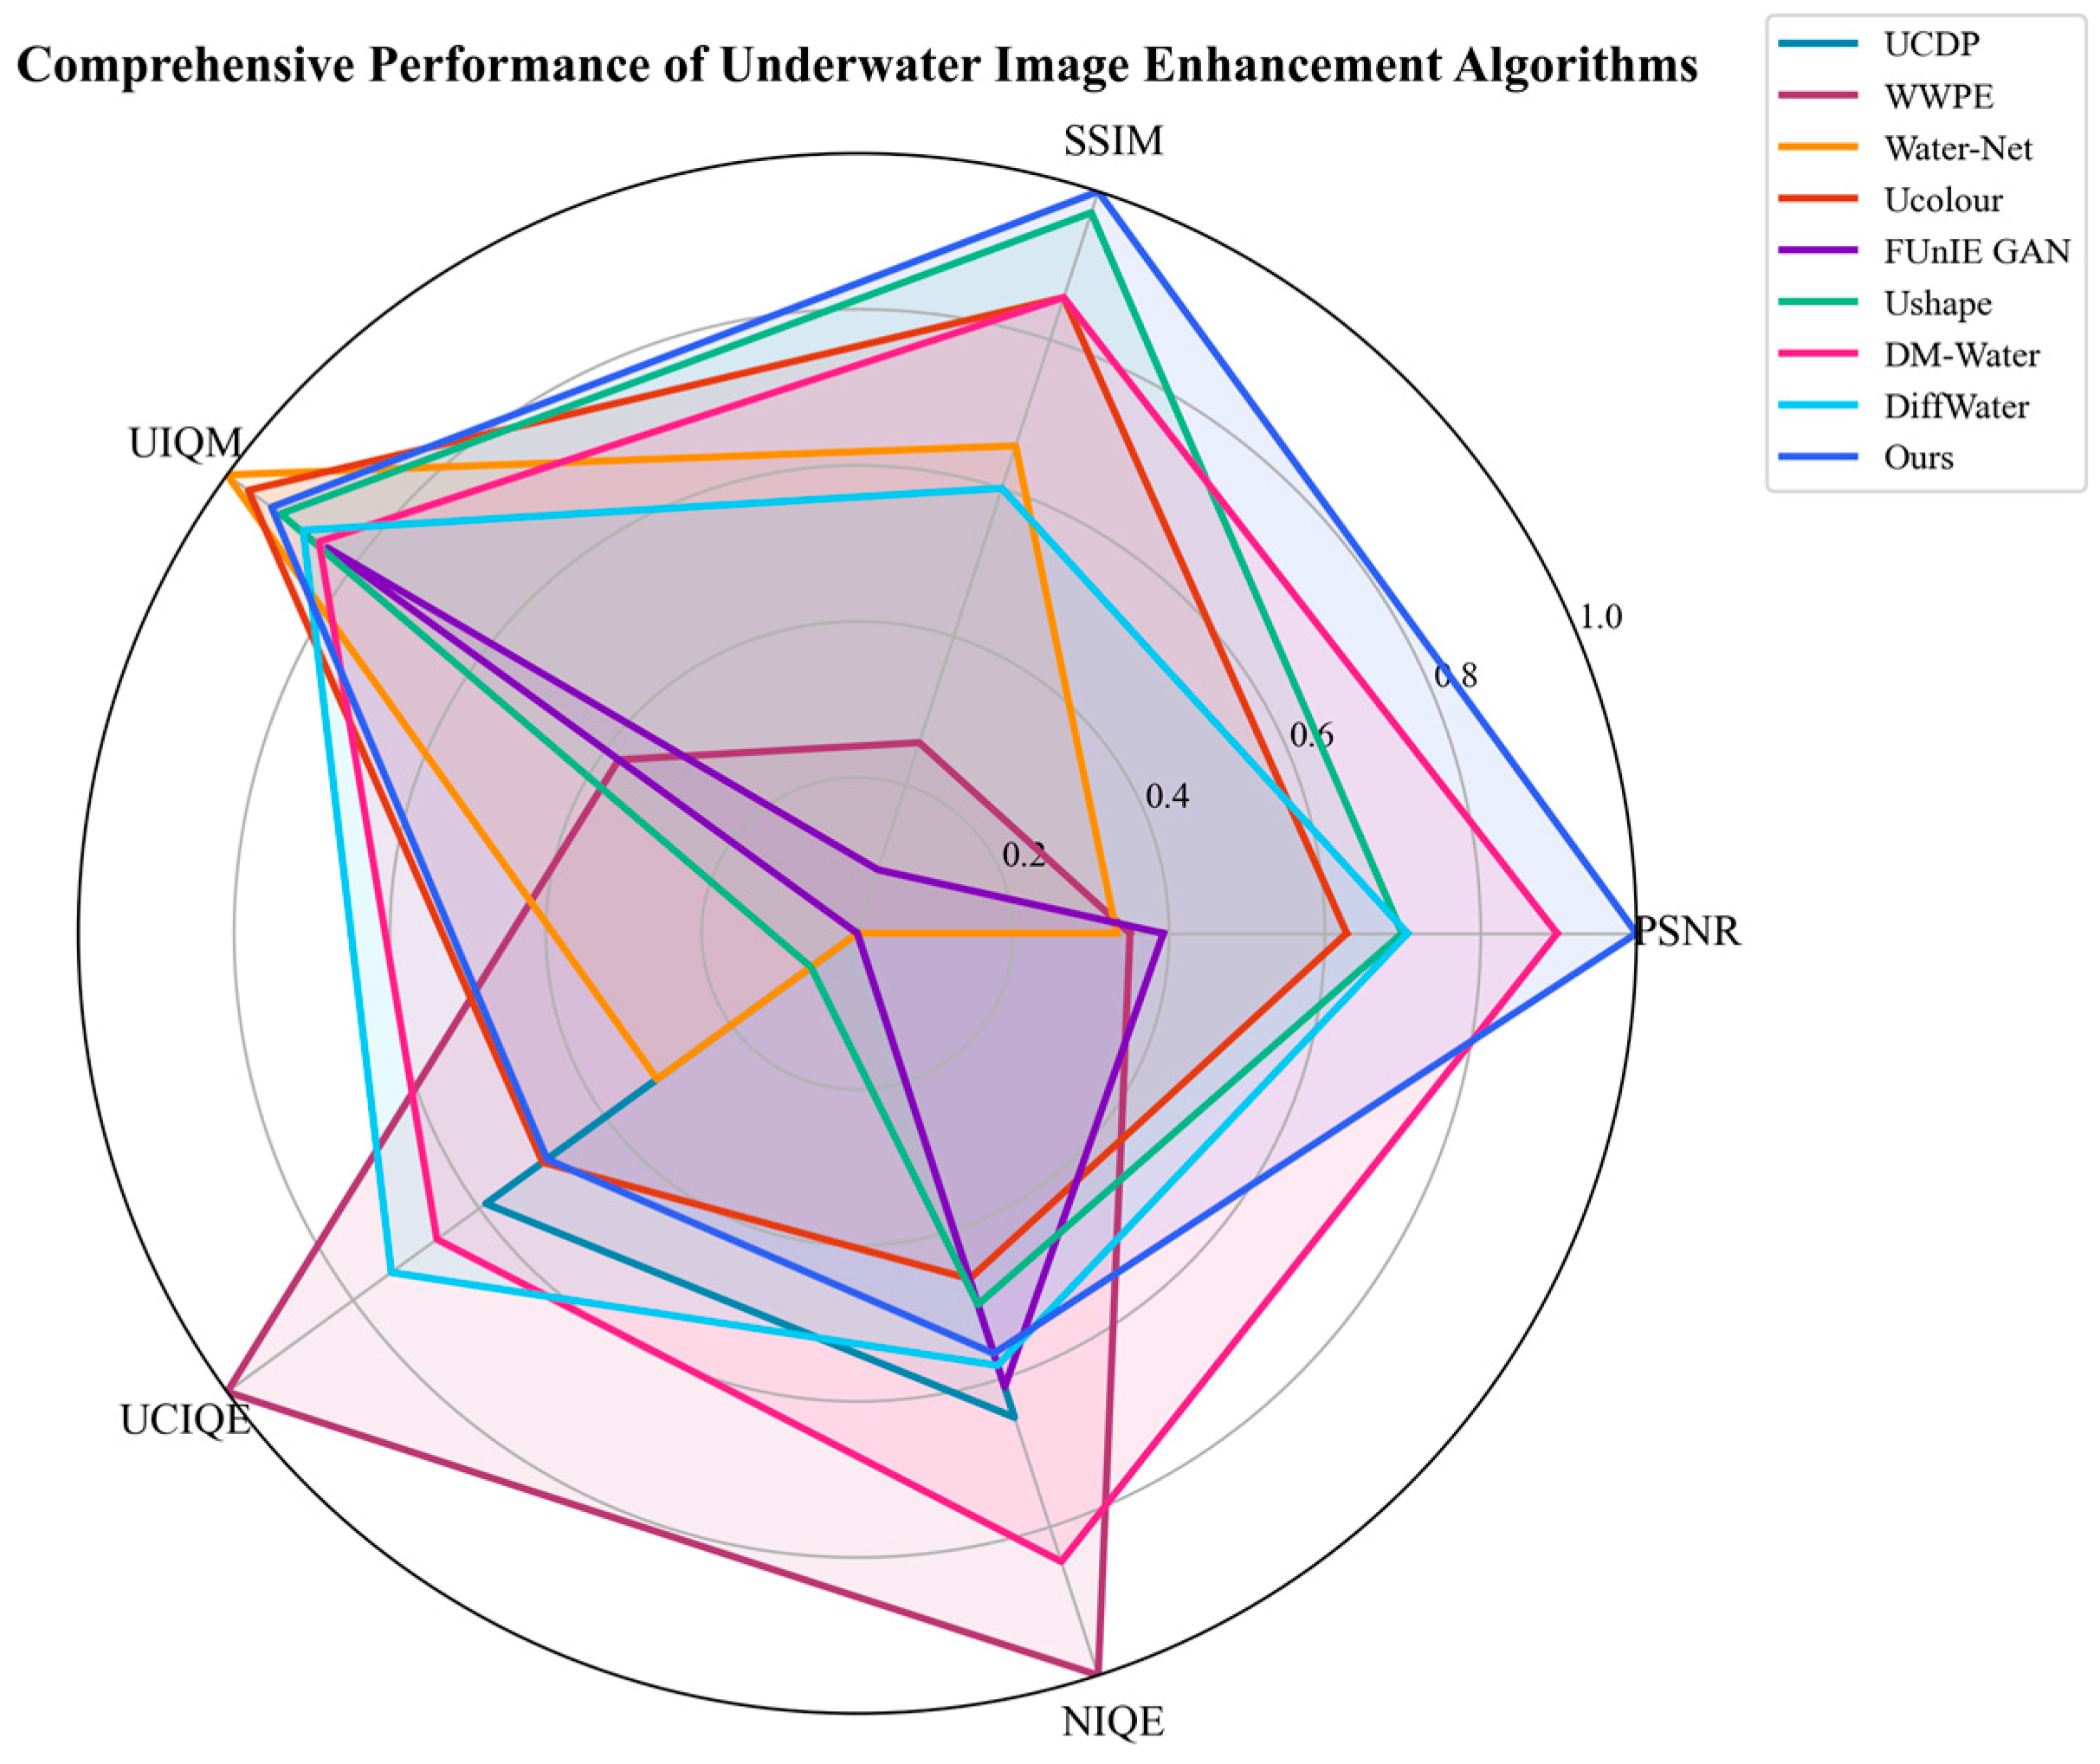
In terms of underwater-dedicated no-reference evaluation indicators (as presented in Table 3 and Table 4 and Figure 10), the proposed method also maintains excellent overall performance, with the average UIQM score of 3.058 and average UCIQE score of 0.5863 staying within the top tier among all comparison schemes. Although several existing methods obtain slightly higher scores on individual underwater visual quality indicators, such results are often obtained through forced saturation adjustment and excessive contrast stretching, which will damage the real consistency between enhanced images and actual underwater scenes to some extent, and their low scores on full-reference indicators also confirm the deviation of their enhancement effects.
Table 3.
Quantitative comparisons across different test datasets (mainly focused on underwater image metrics).
Table 4.
Average quantitative comparisons of different models.
Figure 10.
Performance comparisons of different enhancement methods.
In terms of naturalness evaluation reflected by the NIQE indicator, the numerical performance of the proposed method is not the optimal among all schemes, and this phenomenon has reasonable practical rationality. The evaluation tendency of the NIQE indicator itself is more inclined to low-contrast and low-saturation natural terrestrial images, while the core goal of underwater image enhancement is to weaken blue–green colour cast, improve blurred visual perception and highlight scene effective feature information. Appropriate promotion of image contrast and colour restoration degree will inevitably cause small fluctuations in NIQE values, and such reasonable performance trade-off is completely in line with the actual application demand of underwater vision tasks such as underwater target detection and scene recognition.
From the perspective of the overall performance of existing deep learning models, Transformer and diffusion-based methods obtain competitive full-reference metrics but are constrained by large parameter volumes and slow inference speed. Lightweight GAN and ordinary CNN models feature low computational cost, but their restoration quality and robustness in diverse underwater scenes are relatively weak. Our TIDE-Net outperforms most peer deep learning approaches on PSNR and SSIM and retains a compact parameter scale of only 7.74 M, which demonstrates its comprehensive superiority over existing mainstream deep learning underwater image enhancement models.
Evaluated on the NVIDIA GeForce RTX 5080 Laptop GPU with input resolution of 256 × 256, the proposed TIDE-Net achieves an average inference time of 8.2 ms per image. Such low latency confirms that our lightweight design is highly applicable to resource-constrained embedded and underwater vision platforms.
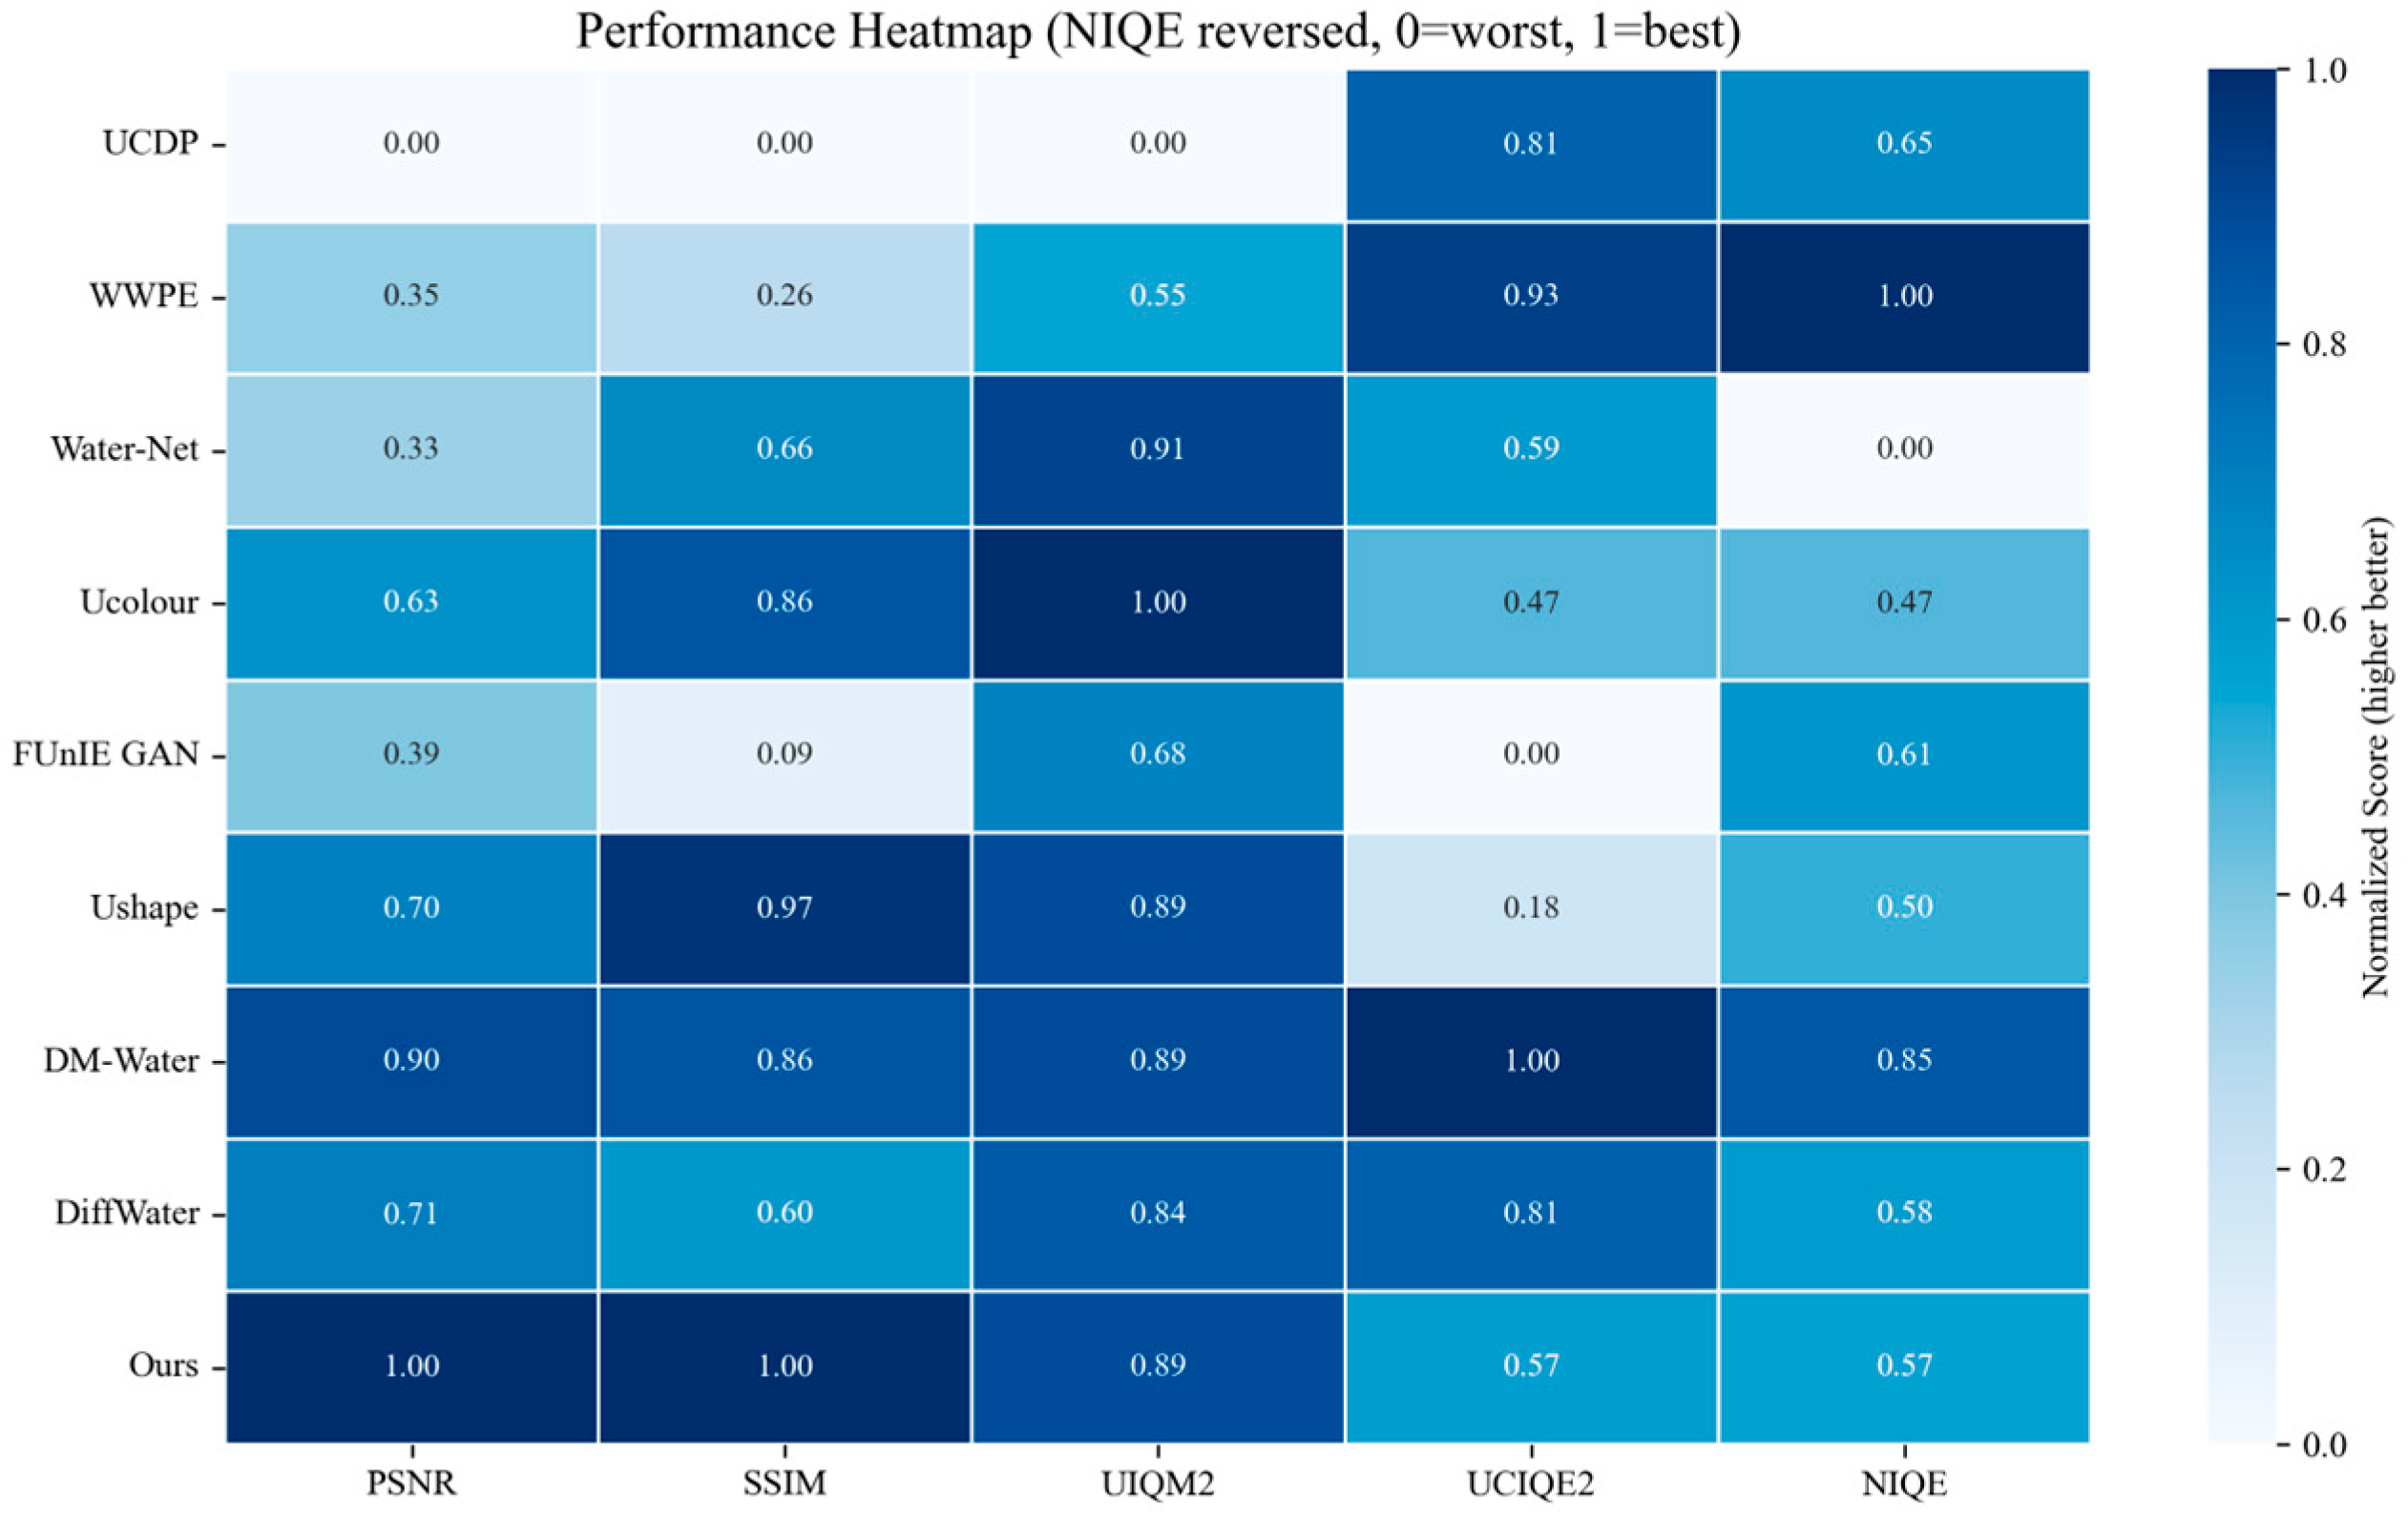
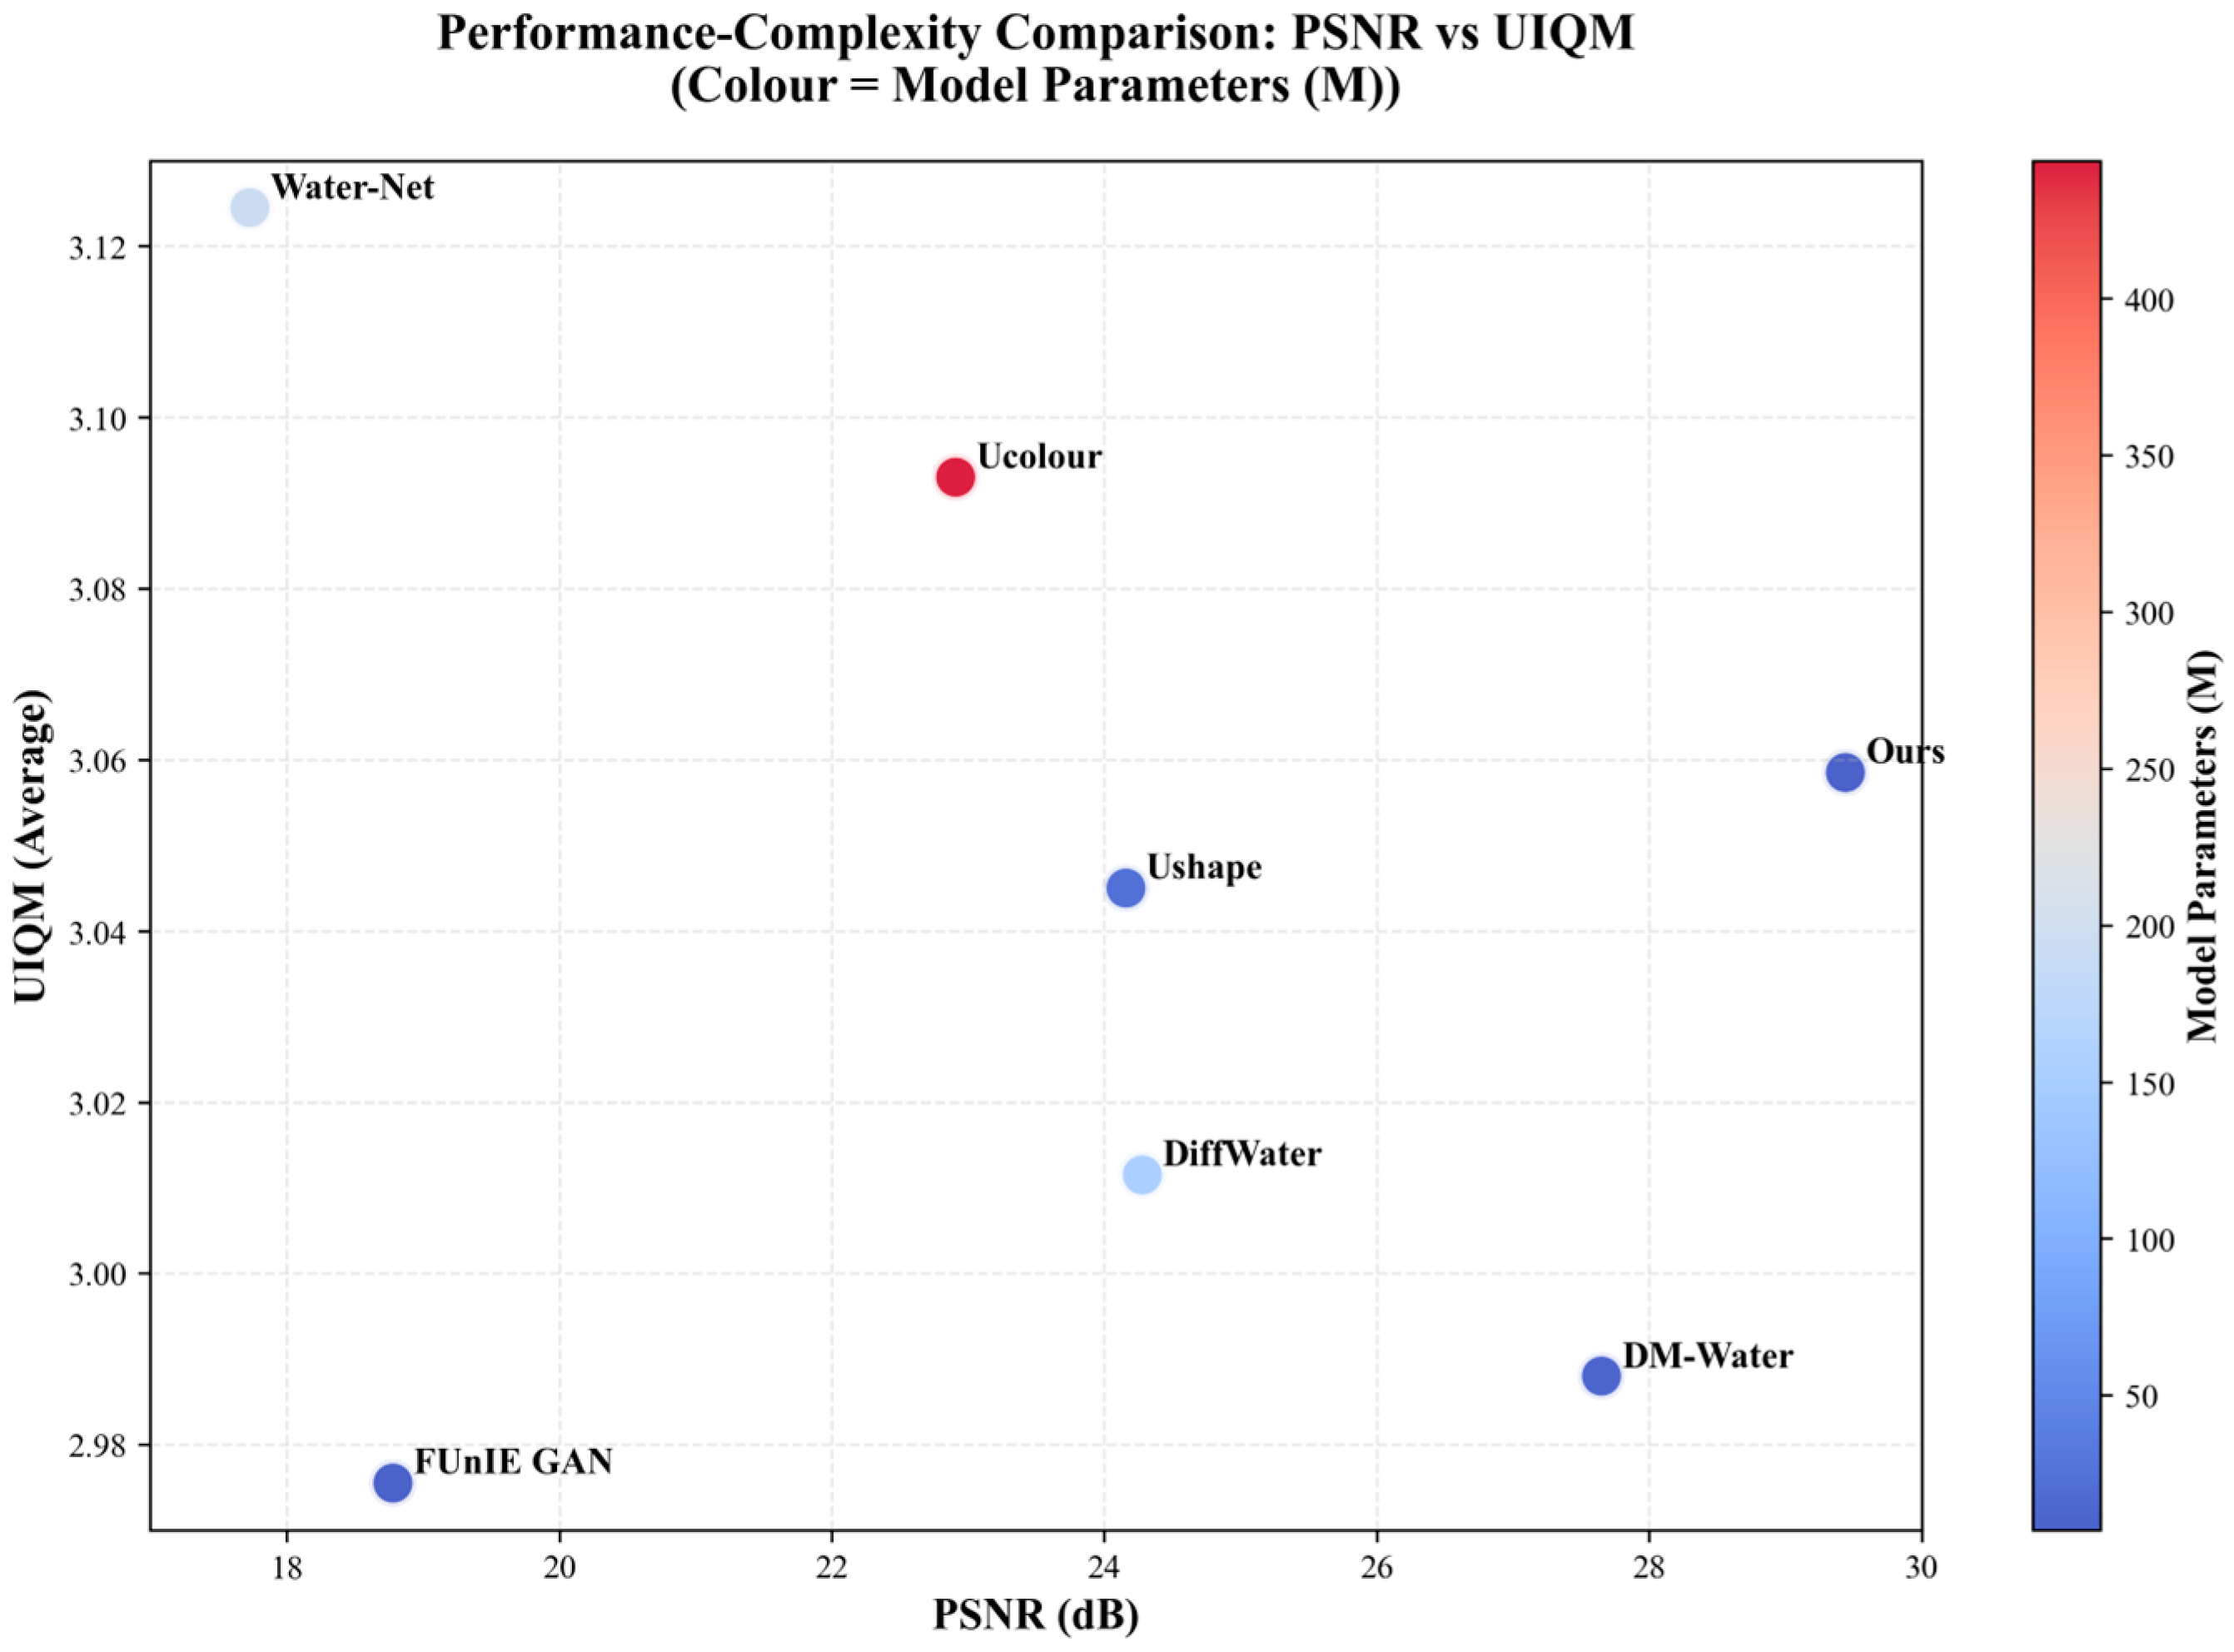
It can also be seen in Figure 11 and Figure 12 that in addition to excellent image enhancement quality the proposed method also possesses prominent advantages in lightweight model design. Our method demonstrates high efficiency, with only 7.74 million parameters, making it the second-lightest model among all compared approaches, only marginally heavier than FUnIE GAN (7 M). It is significantly lighter than other competing methods:
Figure 11.
Performance heatmap of different enhancement methods.
Figure 12.
Comparisons of performance–complexity trade-off of different enhancement methods.
- The model has 66% fewer parameters than Ushape (22.8 M);
- It has 28% fewer parameters than DM-Water (10.7 M);
- It has over 95% fewer parameters than Water-Net (193.7 M) and Ucolour (443.9 M).
The compact model structure greatly reduces the hardware computing resource demand in the actual application process, making this enhancement scheme highly applicable to resource-limited underwater mobile carriers and portable underwater imaging equipment, and laying a solid foundation for large-scale practical popularisation and on-site real-time processing work.
6. Conclusions and Future Work
This paper has presented TIDE-Net, a lightweight triple-branch illumination and detail enhancement network designed specifically for underwater imagery. The architecture builds upon a physically motivated decomposition strategy, separating the input into illumination, reflectance intensity and chromaticity branches for parallel optimisation. This decoupled formulation enables the network to address colour distortion, detail blurriness and uneven illumination independently, thereby mitigating the mutual interference common in multi-stage enhancement pipelines.
Within the proposed framework, mature and well-established enhancement strategies are systematically integrated and adapted to underwater characteristics. A piecewise colour correction module is employed to mitigate blue–green colour casts without introducing visible artefacts. Meanwhile, a lightweight U-Net is tailored for reflectance enhancement via reduced channel dimensions, LeakyReLU activation and a structurally weighted loss function. These adjustments improve noise robustness and low-light adaptability while preserving the core encoder–decoder structure. A local gain compensation branch further refines illumination uniformity, suppressing halo effects and ensuring balanced brightness distribution across the scene.
Extensive experiments conducted on four widely applied underwater datasets demonstrate that TIDE-Net achieves competitive performance against state-of-the-art methods. The proposed model attains a PSNR of 29.44 dB and an SSIM of 0.94, alongside favourable UIQM and UCIQE scores, while maintaining a compact parameter footprint of only 7.74 M. These results validate that such a design effectively balances restoration quality, physical interpretability and computational efficiency, making the method suitable for deployment on resource-limited underwater platforms.
Despite the promising performance, the proposed TIDE-Net still has several evident limitations under challenging underwater scenarios. First, the method struggles with images captured in extremely turbid water. Severe light absorption and scattering cause a massive loss of effective image information, making complete restoration difficult and resulting in suboptimal enhancement quality. Second, when processing images with strong artificial point light sources, abrupt local brightness changes will interfere with the brightness equalisation and colour correction modules, leading to unnatural visual effects. Third, all training images are uniformly resized to 256 × 256. When directly applied to ultra-high-resolution images far beyond this size, the model cannot fully retain fine textures and detailed features, restricting its application to high-definition underwater equipment.
Future work will focus on integrating more advanced physical priors, exploring frequency-domain feature interaction mechanisms, and developing adaptive module weighting strategies to enhance robustness across diverse underwater environments, especially for extremely turbid scenes and complex lighting conditions. To tackle the limitation of fixed-resolution training, we will adopt random cropping at different scales and multi-resolution data augmentation during training to improve the model’s generalisation across various image resolutions. We will also further optimise the network structure and explore patch-based inference schemes to fully adapt the model to ultra-high-resolution input images. Further research will also consider extending the framework to video enhancement tasks, supporting real-time processing for underwater robotic vision applications.
Author Contributions
Conceptualization, B.P.; methodology, B.P.; software, B.P.; validation, B.P.; formal analysis, B.P.; investigation, B.P.; resources, B.P.; data curation, B.P.; writing—original draft preparation, B.P.; writing—review and editing, C.J.; visualisation, B.P.; supervision, B.P.; project administration, Z.W.; funding acquisition, Z.W. All authors have read and agreed to the published version of the manuscript.
Funding
This research was funded by Shanghai City Research Foundation under Grant GO3230007.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
The data presented in this study are available on request from the corresponding author.
Acknowledgments
During the preparation of this manuscript, the authors used DeepseekV3 for the purposes of language polishing and grammar checking. The authors have reviewed and edited the output and take full responsibility for the content of this publication.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Schettini, R.; Corchs, S. Underwater image processing: State of the art of restoration and image enhancement methods. EURASIP J. Adv. Signal Process. 2010, 2010, 746052. [Google Scholar] [CrossRef] [Scilit]
- Hitam, M.S.; Yussof, W.N.J.H.W.; Awalludin, E.A.; Bachok, Z. Mixture contrast limited adaptive histogram equalization for underwater image enhancement. In 2013 International Conference on Computer Applications Technology (ICCAT); IEEE: Piscataway, NJ, USA, 2013. [Google Scholar]
- Fu, X.; Zhuang, P.; Huang, Y.; Liao, Y.; Zhang, X.-P.; Ding, X. A retinex-based enhancing approach for single underwater image. In 2014 IEEE International Conference on Image Processing (ICIP); IEEE: Piscataway, NJ, USA, 2014. [Google Scholar]
- Ancuti, C.; Haber, T.; Bekaert, P. Enhancing underwater images and videos by fusion. In 2012 IEEE Conference on Computer Vision and Pattern Recognition; IEEE: Piscataway, NJ, USA, 2012. [Google Scholar]
- Jaffe, J.S. Computer modeling and the design of optimal underwater imaging systems. IEEE J. Ocean. Eng. 2002, 15, 101–111. [Google Scholar] [CrossRef] [Scilit]
- Drews, P.; Nascimento, E.; Moraes, F.; Botelho, S.; Campos, M. Transmission estimation in underwater single images. In Proceedings of the IEEE International Conference on Computer Vision Workshops; IEEE: Piscataway, NJ, USA, 2013. [Google Scholar]
- Carlevaris-Bianco, N.; Mohan, A.; Eustice, R.M. Initial results in underwater single image dehazing. In Oceans 2010 Mts/IEEE Seattle; IEEE: Piscataway, NJ, USA, 2010. [Google Scholar]
- Galdran, A.; Pardo, D.; Picón, A.; Alvarez-Gila, A. Automatic red-channel underwater image restoration. J. Vis. Commun. Image Represent. 2015, 26, 132–145. [Google Scholar] [CrossRef] [Scilit]
- Song, W.; Wang, Y.; Huang, D.; Tjondronegoro, D. A rapid scene depth estimation model based on underwater light attenuation prior for underwater image restoration. In Pacific Rim Conference on Multimedia; Springer: Cham, Switzerland, 2018. [Google Scholar]
- Li, F.; Liu, C.; Li, X. Underwater image enhancement with zero-point symmetry prior and reciprocal mapping. Displays 2024, 85, 102845. [Google Scholar] [CrossRef] [Scilit]
- Li, C.; Anwar, S.; Porikli, F. Underwater scene prior inspired deep underwater image and video enhancement. Pattern Recognit. 2020, 98, 107038. [Google Scholar] [CrossRef] [Scilit]
- Li, C.; Guo, C.; Ren, W.; Cong, R.; Hou, J.; Kwong, S.; Tao, D. An underwater image enhancement benchmark dataset and beyond. IEEE Trans. Image Process. 2019, 29, 4376–4389. [Google Scholar] [CrossRef] [Scilit]
- Li, J.; Skinner, K.A.; Eustice, R.M.; Johnson-Roberson, M. WaterGAN: Unsupervised generative network to enable real-time color correction of monocular underwater images. IEEE Robot. Autom. Lett. 2017, 3, 387–394. [Google Scholar] [CrossRef] [Scilit]
- Islam, M.J.; Xia, Y.; Sattar, J. Fast underwater image enhancement for improved visual perception. IEEE Robot. Autom. Lett. 2020, 5, 3227–3234. [Google Scholar] [CrossRef] [Scilit]
- Guan, F.; Lu, S.; Lai, H.; Du, X. AUIE–GAN: Adaptive underwater image enhancement based on generative adversarial networks. J. Mar. Sci. Eng. 2023, 11, 1476. [Google Scholar] [CrossRef] [Scilit]
- Li, W.; Wu, X.; Fan, S.; Wei, S.; Gowing, G. Ingc-gan: An implicit neural-guided cycle generative approach for perceptual-friendly underwater image enhancement. IEEE Trans. Neural Netw. Learn. Syst. 2025, 36, 10084–10098. [Google Scholar] [CrossRef] [Scilit]
- Peng, L.; Zhu, C.; Bian, L. U-shape transformer for underwater image enhancement. IEEE Trans. Image Process. 2023, 32, 3066–3079. [Google Scholar] [CrossRef] [Scilit]
- Tian, S.; Sirikham, A.; Konpang, J.; Wang, C. A Deep Feature Fusion Underwater Image Enhancement Model Based on Perceptual Vision Swin Transformer. J. Imaging 2026, 12, 44. [Google Scholar] [CrossRef] [Scilit]
- Hu, X.; Liu, J.; Li, H.; Liu, H.; Xue, X. An effective transformer based on dual attention fusion for underwater image enhancement. PeerJ Comput. Sci. 2024, 10, e1783. [Google Scholar] [CrossRef] [Scilit]
- Tang, Y.; Kawasaki, H.; Iwaguchi, T. Underwater image enhancement by transformer-based diffusion model with non-uniform sampling for skip strategy. In Proceedings of the 31st ACM International Conference on Multimedia; ACM: New York, NY, USA, 2023. [Google Scholar]
- Song, J.; Xu, H.; Jiang, G.; Yu, M.; Chen, Y.; Luo, T.; Song, Y. Frequency domain-based latent diffusion model for underwater image enhancement. Pattern Recognit. 2025, 160, 111198. [Google Scholar] [CrossRef] [Scilit]
- Zhu, Z.; Li, X.; Ma, Q.; Zhai, J.; Hu, H. FDNet: Fourier transform guided dual-channel underwater image enhancement diffusion network. Sci. China Technol. Sci. 2025, 68, 1100403. [Google Scholar] [CrossRef] [Scilit]
- Wang, C.; Chen, J.; Zhao, W.; Gao, W.; Jiao, G. DEER: Diffusion-Empowered Efficient Restoration for Underwater Images. Pattern Recognit. 2026, 176, 113167. [Google Scholar] [CrossRef] [Scilit]
- Guan, M.; Xu, H.; Jiang, G.; Yu, M.; Chen, Y.; Luo, T.; Song, Y. WaterMamba: Visual state space model for underwater image enhancement. arXiv 2024, arXiv:2405.08419. [Google Scholar] [CrossRef] [Scilit]
- Pokuri, T.; Rai, S. Hero-Mamba: Mamba-based Dual Domain Learning for Underwater Image Enhancement. In AAAI-26 AI for Environmental Science Workshop; AAAI Press: Washington, DC, USA, 2026. [Google Scholar]
- Zhao, W.; Rong, S.; He, B. Multi-scale Laplacian pyramid network for frequency-aware underwater image enhancement. Opt. Laser Technol. 2025, 192, 113980. [Google Scholar] [CrossRef] [Scilit]
- Zhao, C.; Cai, W.; Dong, C.; Hu, C. Wavelet-based fourier information interaction with frequency diffusion adjustment for underwater image restoration. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition; IEEE: Piscataway, NJ, USA, 2024. [Google Scholar]
- Fan, J.; Xu, J.; Zhou, J.; Meng, D.; Lin, Y. See Through Water: Heuristic Modeling Toward Color Correction for Underwater Image Enhancement. IEEE Trans. Circuits Syst. Video Technol. 2024, 35, 4039–4054. [Google Scholar] [CrossRef] [Scilit]
- Hu, N.; Li, S.; Tan, J. Hybrid Underwater Image Enhancement via Dual Transmission Optimization and Transformer-Based Feature Fusion. Sensors 2026, 26, 627. [Google Scholar] [CrossRef] [Scilit]
- Pham, T.T.; Mai, T.T.N.; Lee, C. Deep unfolding network with physics-based priors for underwater image enhancement. In 2023 IEEE International Conference on Image Processing (ICIP); IEEE: Piscataway, NJ, USA, 2023. [Google Scholar]
- Wu, S.; Xu, H.; Zhou, X.; Wan, Z.; Zhai, Z.; Wu, X. MFP-PAINet: Enhancing Underwater Images Through Multi-Dimensional Feature Fusion and Probabilistic Uncertainty Modeling. J. Mar. Sci. Eng. 2025, 13, 2250. [Google Scholar] [CrossRef] [Scilit]
- Peng, Y.-T.; Cosman, P.C. Underwater image restoration based on image blurriness and light absorption. IEEE Trans. Image Process. 2017, 26, 1579–1594. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Jobson, D.J.; Rahman, Z.-u.; Woodell, G.A. Properties and performance of a center/surround retinex. IEEE Trans. Image Process. 1997, 6, 451–462. [Google Scholar] [CrossRef] [Scilit]
- Land, E.H.; McCann, J.J. Lightness and retinex theory. J. Opt. Soc. Am. 1971, 61, 1–11. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Grosse, R.; Johnson, M.K.; Adelson, E.H.; Freeman, W.T. Ground truth dataset and baseline evaluations for intrinsic image algorithms. In 2009 IEEE 12th International Conference on Computer Vision; IEEE: Piscataway, NJ, USA, 2009. [Google Scholar]
- BT.601; Studio Encoding Parameters of Digital Television for Standard 4:3 and Wide Screen 16:9 Aspect Ratios. International Telecommunication Union (ITU): Geneva, Switzerland, 2011.
- Drew, M.S.; Funt, B.V. Natural metamers. CVGIP Image Underst. 1992, 56, 139–151. [Google Scholar] [CrossRef] [Scilit]
- Buchsbaum, G. A spatial processor model for object colour perception. J. Frankl. Inst. 1980, 310, 1–26. [Google Scholar] [CrossRef] [Scilit]
- Zhang, W.; Jin, S.; Zhuang, P.; Liang, Z.; Li, C. Underwater image enhancement via piecewise color correction and dual prior optimized contrast enhancement. IEEE Signal Process. Lett. 2023, 30, 229–233. [Google Scholar] [CrossRef] [Scilit]
- Zhuang, P.; Li, C.; Wu, J. Bayesian retinex underwater image enhancement. Eng. Appl. Artif. Intell. 2021, 101, 104171. [Google Scholar] [CrossRef] [Scilit]
- Li, C.; Guo, J.; Guo, C.; Cong, R.; Gong, J. A hybrid method for underwater image correction. Pattern Recognit. Lett. 2017, 94, 62–67. [Google Scholar] [CrossRef] [Scilit]
- Liu, J.; Zhang, X. Parameter-adaptive compensation (PAC) for processing underwater selective absorption. IEEE Signal Process. Lett. 2020, 27, 2178–2182. [Google Scholar] [CrossRef] [Scilit]
- Huang, H.; Lin, L.; Tong, R.; Hu, H.; Zhang, Q.; Iwamoto, Y.; Han, X.; Chen, Y.-W.; Wu, J. Unet 3+: A full-scale connected unet for medical image segmentation. In ICASSP 2020-2020 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP); IEEE: Piscataway, NJ, USA, 2020. [Google Scholar]
- Ibtehaz, N.; Kihara, D. Acc-unet: A completely convolutional unet model for the 2020s. In International Conference on Medical Image Computing and Computer-Assisted Intervention; Springer: Cham, Switzerland, 2023. [Google Scholar]
- Liu, F.; Hua, Z.; Li, J.; Fan, L. Dual UNet low-light image enhancement network based on attention mechanism. Multimed. Tools Appl. 2023, 82, 24707–24742. [Google Scholar] [CrossRef] [Scilit]
- Ghosh, T. Separated Attention: An Improved Cycle GAN Based Under Water Image Enhancement Method. arXiv 2024, arXiv:2404.07649. [Google Scholar] [CrossRef] [Scilit]
- Nezla, N.; Haridas, T.M.; Supriya, M. Semantic segmentation of underwater images using unet architecture based deep convolutional encoder decoder model. In 2021 7th International Conference on Advanced Computing and Communication Systems (ICACCS); IEEE: Piscataway, NJ, USA, 2021. [Google Scholar]
- Wang, X.; Luo, Z.; Huang, W.; Zhang, Y.; Hu, R. Optimized UNet framework with a joint loss function for underwater image enhancement. Sci. Rep. 2025, 15, 7327. [Google Scholar] [CrossRef] [Scilit]
- Xu, B.; Wang, N.; Chen, T.; Li, M. Empirical evaluation of rectified activations in convolutional network. arXiv 2015, arXiv:1505.00853. [Google Scholar] [CrossRef] [Scilit]
- Li, H.; Li, J.; Wang, W. A fusion adversarial underwater image enhancement network with a public test dataset. arXiv 2019, arXiv:1906.06819. [Google Scholar] [CrossRef] [Scilit]
- Korhonen, J.; You, J. Peak signal-to-noise ratio revisited: Is simple beautiful? In 2012 Fourth International Workshop on Quality of Multimedia Experience; IEEE: Piscataway, NJ, USA, 2012. [Google Scholar]
- Wang, Z.; Bovik, A.C.; Sheikh, H.R.; Simoncelli, E.P. Image quality assessment: From error visibility to structural similarity. IEEE Trans. Image Process. 2004, 13, 600–612. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Mittal, A.; Soundararajan, R.; Bovik, A.C. Making a “completely blind” image quality analyzer. IEEE Signal Process. Lett. 2012, 20, 209–212. [Google Scholar] [CrossRef] [Scilit]
- Panetta, K.; Gao, C.; Agaian, S. Human-visual-system-inspired underwater image quality measures. IEEE J. Ocean. Eng. 2015, 41, 541–551. [Google Scholar] [CrossRef] [Scilit]
- Yang, M.; Sowmya, A. An underwater color image quality evaluation metric. IEEE Trans. Image Process. 2015, 24, 6062–6071. [Google Scholar] [CrossRef] [Scilit]
- Zhang, W.; Zhou, L.; Zhuang, P.; Li, G.; Pan, X.; Zhao, W.; Li, C. Underwater image enhancement via weighted wavelet visual perception fusion. IEEE Trans. Circuits Syst. Video Technol. 2023, 34, 2469–2483. [Google Scholar] [CrossRef] [Scilit]
- Li, C.; Anwar, S.; Hou, J.; Cong, R.; Guo, C.; Ren, W. Underwater image enhancement via medium transmission-guided multi-color space embedding. IEEE Trans. Image Process. 2021, 30, 4985–5000. [Google Scholar] [CrossRef] [Scilit]
- Guan, M.; Xu, H.; Jiang, G.; Yu, M.; Chen, Y.; Luo, T.; Zhang, X. DiffWater: Underwater image enhancement based on conditional denoising diffusion probabilistic model. IEEE J. Sel. Top. Appl. Earth Obs. Remote Sens. 2023, 17, 2319–2335. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.