


Abstract
This paper presents a distributed smoothing neurodynamic approach for solving the - minimization problem, with application to robust and collaborative multi-view three-dimensional (3D) space localization. To handle the non-Lipschitz continuity gradients, a smooth approximation technique is introduced, yielding a distributed neurodynamic model that integrates classical smoothing neural networks with multi-agents consensus theory. Theoretical analysis guarantees the global convergence of each agent’s state to the optimal solution. The stability and convergence of the proposed approaches are rigorously proved using Lyapunov theory. Numerical experiments on multi-view 3D space localization in the presence of measurement noise demonstrate the method’s effectiveness and practical value for distributed visual computing.
1. Introduction
The rapid advancement of robotic navigation and autonomous driving has created a pressing demand for accurate environmental perception and modeling. On these intelligent platforms, vision systems based on video and image data have garnered significant academic attention as core perception modules, exemplified by applications such as visual odometry [1], the vision language model [2], and generalized visual localization [3]. The construction of semantic maps [4,5], which integrate geometric and semantic information, represents a significant research direction by facilitating a fundamental transition in environmental perception from a purely geometric to a cognitive level. This process often relies on the accurate estimation of 3D positions from two-dimensional observations [6], and even one-dimensional distances [7], which is 3D space localization, which often relies on triangulation measurements. Modern computer vision techniques can reliably detect objects and extract their corresponding 2D pixel coordinates from video and image data, such as convolutional neural network [8,9,10], YOLO [11,12], and Transformer Networks [13]. Therefore, triangulation emerges as a fundamental technique for solving systems of overdetermined equations derived from multi-view geometric constraints [14], used to reconstruct precise 3D coordinates of objects from their 2D coordinates. Consequently, significant research efforts have been dedicated to enhancing its robustness and accuracy. Reference [15] offers a robust optimization solution to the triangulation problem for uncertain data. Reference [16] proposes an approach based on convex relaxations for certifiably optimal robust multi-view triangulation that is capable of achieving provably optimal reconstructions in the presence of substantial noise and a high proportion of outliers. The applicability of robust triangulation extends to diverse domains. For instance, it has been utilized to reconstruct accurate height profiles of steep terrain [17]. In the context of mobile robots in Reference [18], monocular odometry systems benefit from constraints imposed on feature matching by semantic information and on triangulation by depth, thereby enhancing localization accuracy. Furthermore, triangulation serves as the foundational mechanism for depth estimation in Simultaneous Localization and Mapping (SLAM) [19] and constitutes the core of traditional Structure from Motion (SfM) [20]. In these systems, the 3D space localization of the detection target is well completed based on visual image data and triangulation methods.
Computationally, triangulation can be formulated as an optimization problem, aiming to find the optimal 3D coordinates that best explain the multi-view observations. This paradigm of "recovering original data from observed data" shares a profound mathematical similarity with the framework of Compressed Sensing (CS), which seeks to reconstruct a sparse signal from under-sampled linear measurements. According to CS theory, a sparse signal can be exactly recovered from its underdetermined linear measurements , where is the sensing matrix. Within the vast majority of pragmatic implementations, the measurements are inescapably adulterated by certain noise perturbations. Under such circumstances, the compressed measurements can be typically formulated as
where denotes measurement noise.
An orthodox tactic to retrieve the sparse vector is converted to the ensuing -minimization problem [21]:
where signifies -norm, to wit the quantity of non-vanishing entries within vector . constrains the residual error of -norm and is pre-determined by the noise level. However, addressing Problem (2) is NP-hard [22]. Thus, to address this problem, it is replaced by the succeeding model, i.e., BP denoising (BPDN) [23]:
where , namely -norm. Later, Wen et al. focused on the optimization problem to realize the robust sparse recovery under impulsive measurement perturbations [24]:
where . When , the optimization problem (4) constitutes a particular instance of (3).
In particular, sparse signal reconstruction with a neurodynamic approach has attracted a large number of scholars [25,26,27,28,29,30,31,32,33,34,35,36]. The minimization problem can be addressed by a neurodynamic approach based on a recurrent neural network (RNN) model, which is capable of attaining the global optimum and has been applied to sparse signal recovery [25]. Two neurodynamic stratagems via -minimization were proposed for sparse signal restitution through the integration of augmented Lagrangian multipliers and differential feedback [28]. Using scaled gradient projection, a neural network was presented for minimization by Liu et al., and the stability was proved by constructing a Lyapunov function [29]. Wang et al. developed a sparse recovery minimization model and proposed a gradient projection smoothing neural network, which applied to the compressed sensing problem [31]. To address the minimization, a smoothing neural network (SNN) was developed by dint of a smoothing approximate artifice for sparse signal restitution with measurement perturbations [32].
Distributed neurodynamic approaches have gained popularity due to their high reliability, scalability, and privacy protection. In multi-agent systems, while data transmission heavily relies on channel resources and efficient transmission methods have been widely studied [37,38], a distributed strategy keeps observation data localized. This not only reduces communication overhead but also enhances the privacy of each agent. Consequently, numerous distributed neurodynamic methods have been developed for solving distributed optimization problems [39,40,41,42,43,44,45,46,47]. To address the distributed optimization problem featuring globally coupled constraints, Li et al. propounded a distributed neurodynamic stratagem using recurrent neural networks (RNNs) [42]. By Che and Wang, a collaborative neurodynamic stratagem was propounded with an augmented Lagrangian function for the resolution of a global and combinatorial optimization problem [43]. Concerned with constrained global optimization problems, Yan et al. proposed the distributed neuraldynamic approach, which utilized multiple RNNs to ascertain the global optimal solution collectively [44]. In the context of multiple-objective distributed optimization, a collaborative neurodynamic stratagem with objective weighting and decision space decomposition was developed, which focuses on Pareto optimal solutions [45]. Zhao et.al presented a decentralized smoothing projection neurodynamic stratagem with an expedient convergence rate in addressing constrained nonsmooth generalized convex optimization problems. Meanwhile, by dint of the continuous variant of Polyak’s heavy ball methodology, a distributed smoothing projection neurodynamic stratagem also was proposed for a constrained nonsmooth strongly convex optimal problem [46]. Later, by virtue of a projection operator, two decentralized continuous-time and discrete-time neurodynamic stratagems were developed via minimization to sparse recovery [47]. Recently, to address the -minimization problem, Zhao et al. tries to propose a distributed neurodynamic approach by smooth approximation and projection operator. Considering that the distributed - minimization problem uses the distributed smooth neurodynamic approach, further in-depth research and discussion is necessary for sparse recovery. Furthermore, measurement noise is customarily factored in within most practical applications. In compressed sensing (CS), the --minimization is designed with robust sparse signal recovery with measurement noise, which brings both practical and academic value to our research.
Inspired by preliminary work, such as the distributed neurodynamic approach for -minimization via smooth approximation [46], we identify a compelling opportunity to extend this paradigm. Therefore, this paper aims to develop a novel distributed neurodynamic algorithm that leverages the - minimization framework from compressed sensing to achieve accurate 3D localization from multi-view, noisy observations. It avoids raw data centralization, exchanges only state estimates with neighboring nodes, and keeps sensitive observations local. These features make the approach particularly suitable for scalable multi-agent systems under bandwidth constraints. The main contributions of this article are highlighted as below:
- We propose a robust, distributed computing framework for multi-view 3D localization by innovatively formulating it as a compressed sensing problem. This design inherently leverages the anti-noise ability of sparse recovery theory. Compared to other triangulation-based solutions, this is a distributed approach that can be deployed on multi-agent systems without having to worry about computing power limitations.
- We develop a novel distributed smoothing neurodynamic approach (Equation (14)), featuring a derivative feedback item. A key feature of which is its effective handling of the non-Lipschitz continuity issue through smooth approximation. The stability and convergence of this algorithm are theoretically guaranteed by a constructed Lyapunov function.
An outline of the remainder of this paper is as follows. Section 2 mainly introduces smoothing approximation, the nonnegative quadrant, and other introductory knowledge. In Section 3, a distributed - optimization problem is proposed, and the proposal of a distributed smoothing neurodynamic approach is accompanied by formal proofs establishing its global convergence and stability. In Section 4, the multi-view 3D localization problem is formulated as a compressed sensing task and addressed with the proposed distributed smoothing neurodynamic approach for - minimization, thereby achieving robust and collaborative recovery of 3D coordinates under measurement noise.
2. Preliminary Knowledge
This section expounds on the smoothing approximation and nonnegative quadrant which can be used in the later parts.
- A.
- Smoothing approximation [48]:
Definition 1.
Function is locally Lipschitz, and is a smoothing function corresponding to , provided that satisfies the ensuing stipulations:
- 1.
- For any fixed and any fixed , the function is continuously differentiable on , and is differentiable on , respectively.
- 2.
- For any prescribed .
- 3.
- There is a positive constant such that
- 4.
From (2) and (3) of Definition 1, the following properties are deduced:
There are two propositions concerning the compositions of smoothing functions introduced in [33]:
Lemma 1.
- 1.
- Suppose that are smoothing functions of , then is a smoothing function of with under the conditions that and is regular for each .
- 2.
- For a regular function and a continuously differentiable with smoothing function , it follows that smooths the composition and satisfies .
The following smooth approximation function is frequently performed, which will also be used in this paper.
For any , the function is convex. Additionally, for any , the function is continuous and nondecreasing.
Assumption 1.
In , both and functions are convex.
Assumption 2
(Slater Condition). There exists , such that .
- B.
- Nonnegative Quadrant [49]:
The positive projection of a is denoted as , namely . Enumerated below are two properties:
3. The Distributed Smoothing Approximation for Problem
In this part, the smoothing approximation for the distributed optimization problem with local prior information of the blocked observation matrix (i.e., for any , the evaluation of the noise level is known) is described in detail.
where , , Laplacian matrix of G (an undirected weighted connected graph). , and represents the set of ), , . We reformulate the original equality as the inequality in distributed multi-linear-equation solving primarily to handle varying sensor observation errors. Using equality constraints or least squares forces equal influence from each sensor, allowing high-error sensors to negatively affect others. Instead, inequality constraints define norm balls for each sensor; the radii of norm balls are . The consensus constraint then seeks a common point within the intersection of these balls.
Obviously, is a convex, nonsmooth function, so is a convex, nonsmooth function. When , the gradient of is not Lipschitz continuous (not bounded). When , and is also a convex, nonsmooth function. However, the traditional proximal gradient methods are no longer appropriate. In order to solve Problem (6) by the neuraldynamic approach, we perform a smooth approximation.
Remark 1.
Note the local prior information of the blocked observation matrix (i.e., for any , the evaluation of the noise level is known); thus, one has with when , and the distributed - minimization problem (6) is equivalent to the optimization problem (7) in [32].
where . Namely, the optimal solution of the distributed - optimization problem (6) is the optimal solution of (7).
Assumption 3.
In this paper, are considered.
Since , can be approximated by
can be approximated by
Therefore, the optimization problem (6) is converted to the following problem:
4. Distributed Smoothing Neurodynamic Approach
In this section, a distributed smoothing neurodynamic approach is proposed for solving Problem (11), which is based on the multi-agent consensus condition and derivative feedback.
For any agent ,
and its vector form can be written as
where is a penalty parameter, , , . .
is a gradient of the smoothing function in terms of
is a gradient of the smoothing function with respect to
Lemma 2.
The proposed distributed smooth neurodynamic approach (13) is tantamount to the ensuing distributed dynamic system:
Obviously, the distributed smooth neurodynamic approach (14) can be directly deduced from (13). Thus, if is the equilibrium point of (13), then is also the equilibrium point (14), vice versa.
Proof.
Theorem 1.
Proof.
In accordance with the Karush–Kuhn–Tucker (KKT) conditions
where are Lagrange multipliers, and denotes an optimal solution to the optimization problem (11). According to (4) in Definition 1, , if and . We have
In conclusion, all the ensuing equations hold true.
Therefore, if is the option solution of Problem (6), Approach (14) converges to point . Conversely, if is an equilibrium point of (14), it must acquit the following:
Further, by (16a) and (16c), it may be deduced that . Define an augment Lagrangian function ; one has for any . Due to (16b), , we can get , and it can definitely get , when . Thus, this equation likewise holds. When , this equation fails to hold. Consequently, one can deduce that is held; . In light of the variational analysis theory, the equilibrium point is a saddle point of the convex function , and moreover, the equilibrium point of (14) constitutes the optimal solution to Problem (11). Therefore, the proof of Theorem 1 is brought to a conclusion. □
Theorem 2.
Proof.
Considering the following Lyapunov function:
where . Since convexity of and combines and , we can get .
For the convenience of subsequent proofs, we decompose into four parts, each of which can be more easily shown to be negative definite.
And we have
For , since it is the negative square of a 2-norm, we have .
For , exploiting the convexity of about and , we have
Taking the upper and lower bounds from this inequality and rearranging them to the same side and multiplying by 2 as a whole, we yield . Since , we have
Thus, we can easily derive that .
For , we can use logical manipulations of the type exemplified by . Following this logic, we can decompose some of the terms to construct certain ones. Equation is transformed into
According to the convexity of of and , we have
Based on , we have
It should be noted that due to the convexity of of , is a vector with all negative elements. Due to (21)
This process essentially further decomposes into several smaller terms, and the negative definiteness of each is individually demonstrated. Thus
For ,
Thus
5. Multi-View 3D Localization Using the Distributed Smoothing Neurodynamic Approach via - Minimization
We apply the proposed algorithm to a multi-view 3D localization problem. While triangulation in multi-view 3D localization and distributed compressed sensing are not conventionally directly related, our recent research focuses on constructing semantic maps from images captured by multiple cameras viewing the same environment from different perspectives. With mature solutions like YOLO available for object recognition and matching, we focus on the subsequent problem: given the projection matrix for each camera and the matching relationships of objects across multiple views, we aim to reconstruct 3D object coordinates using a distributed computing approach based on multi-view pixel coordinates.
5.1. Formulating Multi-View 3D Localization as a - Minimization Problem
Consider a multi-agent system comprising n cameras indexed by . Each camera i has a known projection matrix . The camera network collectively observes m objects, where denotes the observation of object i (with ) by camera j. Let represent the true homogeneous 3D coordinate of object i. Based on camera geometry principles, we establish the fundamental relationship:
To formulate this comprehensively, let represent the collective observation homogeneous coordinates from camera j, and denote the complete set of original 3D homogeneous coordinates (homogeneous coordinates use dimensions to represent N dimensional coordinates, and usually, the extra bit is the constant 1). The observation matrix for camera j is constructed as a block diagonal matrix , where each diagonal block contains the projection matrix . Notably, this observation process inherently constitutes a compressed measurement since it projects 3D homogeneous coordinates onto 2D image planes. Thus, we obtain:
If there exists an appropriate invertible linear transformation that converts to such that becomes sparse, we can reconstruct it using compressed sensing principles. For instance, in intelligent connected vehicle systems where cameras monitor vehicle positions and all vehicles remain on the road surface, we can employ a coordinate transformation to align the road plane with in the coordinate system. Here the linear transformations are priori knowledge.
Additionally, considering that the fourth component of homogeneous coordinates is always 1, we address a more generalized problem by defining , where is a column vector of all ones. This yields:
In this formulation, contains at least m zero elements. Since all cameras observe the same scene, we require for consistency, enforced through the constraint or , where L represents the graph Laplacian matrix.
Thus, the multi-view 3D localization problem is transformed into a - minimization problem. We formulate this as the following distributed - minimization problem:
This formulation follows the robust sparse recovery framework, where the norm promotes sparsity in the reconstructed 3D coordinates, while the constraint handles measurement noise and outliers. In special cases, it can help restore coordinates on a certain plane or line. The consensus constraint ensures that all cameras collaboratively recover a consistent 3D representation of the scene.
5.2. Numerical Experiments
Based on the content presented earlier, we have established that the multi-view 3D localization problem can be solved via - minimization, and the algorithm along with its principles has been detailed in Section 3 and Section 4. Therefore, this subsection will demonstrate the effectiveness of the algorithm through numerical experiments.
5.2.1. Simulation Experiment Design
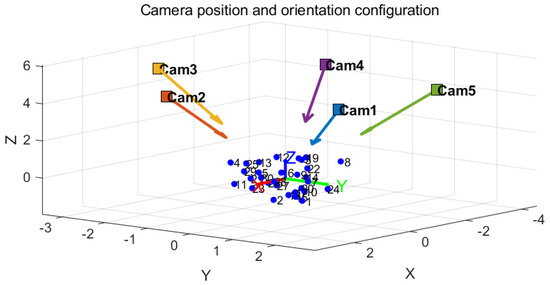
We consider a scenario where five cameras capture the same scene from different viewpoints, as illustrated in Figure 1.
Figure 1.
Camera configuration: five cameras capturing the same scene from different viewpoints.
The cameras communicate in a pairwise ring topology, as follows: .
We model each camera as an ideal camera with unit focal length, where conventional cameras can be equivalently represented through appropriate linear transformations. Therefore, the intrinsic matrix of the camera is:
Let the position of each camera be denoted by , with its optical axis pointing toward the origin, so that the rotation matrix describing its orientation can be derived from . Subsequently, the projection matrix for each camera is computed based on . Subsequently, we randomly generate a point cloud consisting of 30 points and convert them into homogeneous coordinates . The observed coordinates for each camera are then obtained via the camera projection matrices based on Formula (27). Additionally, Gaussian observation noise with amplitude is added to the generated coordinates to simulate the noisy recognition results from the cameras j. The actual input for the algorithm is then produced based on the formulation of Equation (29).
In short, the experiment is designed as follows: a set of coordinates is randomly generated and observed by a group of ideal cameras, yielding precise 2D observation coordinates for each camera. Noise is then added to these precise observations to simulate real noisy measurements. Our algorithm is subsequently applied to recover the 3D coordinates of each camera’s local value from the noisy observations. The effectiveness of the algorithm is validated by comparing the reconstructed coordinates or average reconstructed coordinates under noise with the original coordinates .
Regarding the parameter settings in the algorithm: the parameter p determines the shape of the norm ball corresponding to the observation equation . Apart from the requirement that , there is no strict constraint on its value. In the experiment, we set . The parameter represents the radius of the norm ball, which is linked to the noise amplitude as . The smoothing parameter is set to . As a continuous-time algorithm, the solving process employs Euler discretization, which is equivalent to using a fixed, sufficiently small step size. The discrete step size is chosen as 0.0001
5.2.2. Simulation Performance
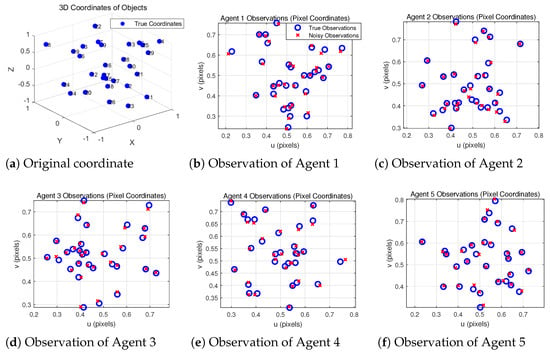
The projection relationships from 3D coordinates to 2D pixel coordinates under this camera model are illustrated in Figure 2. Noise amplitude .
Figure 2.
Projection patterns: example images captured by the five cameras.
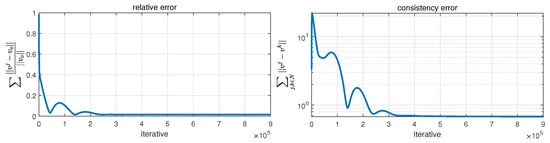
The Figure 3 illustrate the convergence behavior of the proposed algorithm during the iterative optimization process. Specifically, we present the evolution of two key performance metrics: the relative error and the consensus error among agents. The relative reconstruction error, defined as , quantifies the accuracy of the recovered 3D coordinates, while the consensus error, expressed as , measures the agreement between neighboring agents in the distributed network.
Figure 3.
Convergence behavior of relative multi-view 3D localization error and consensus error during iterative optimization.
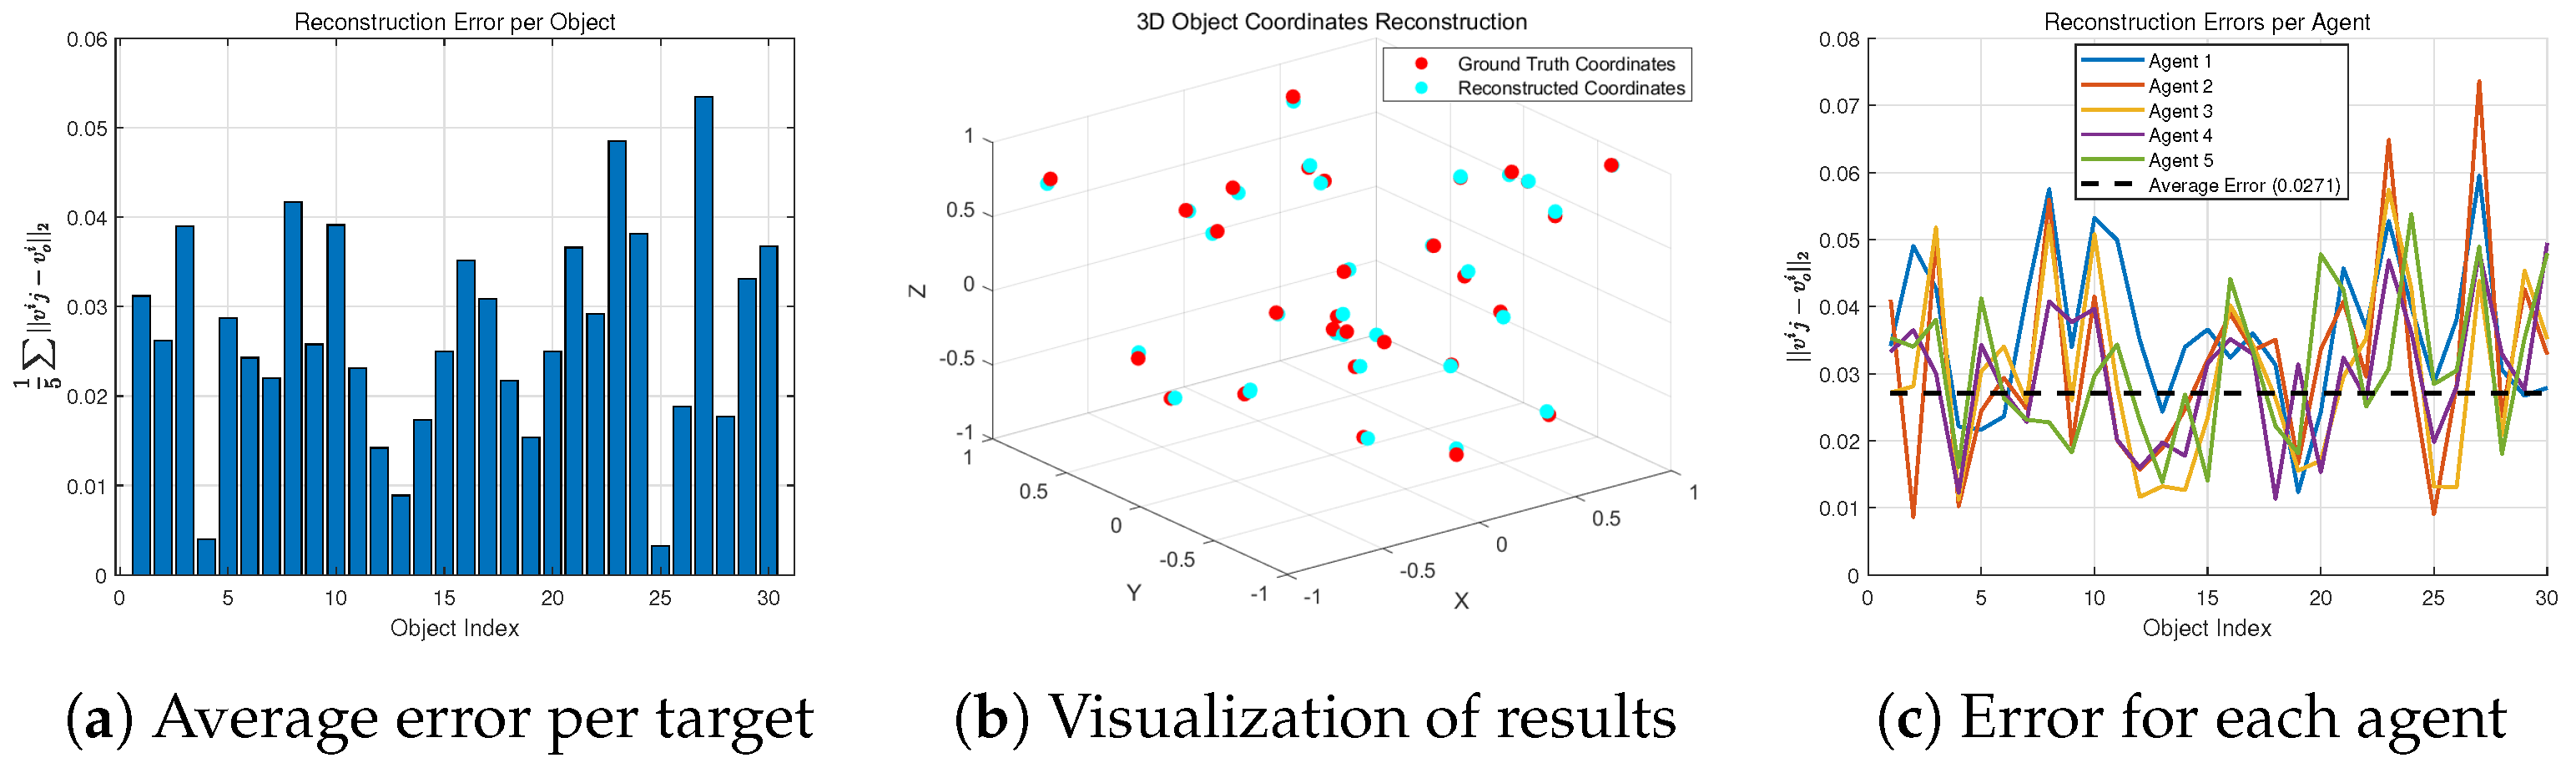
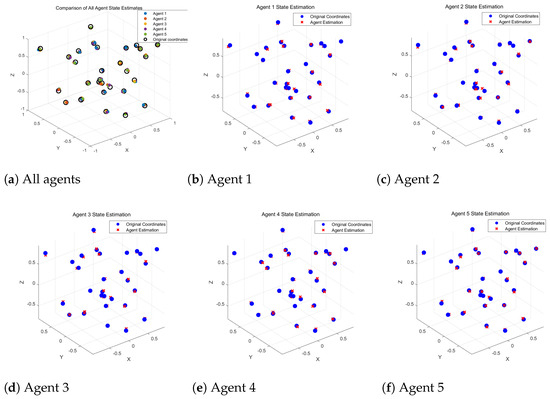
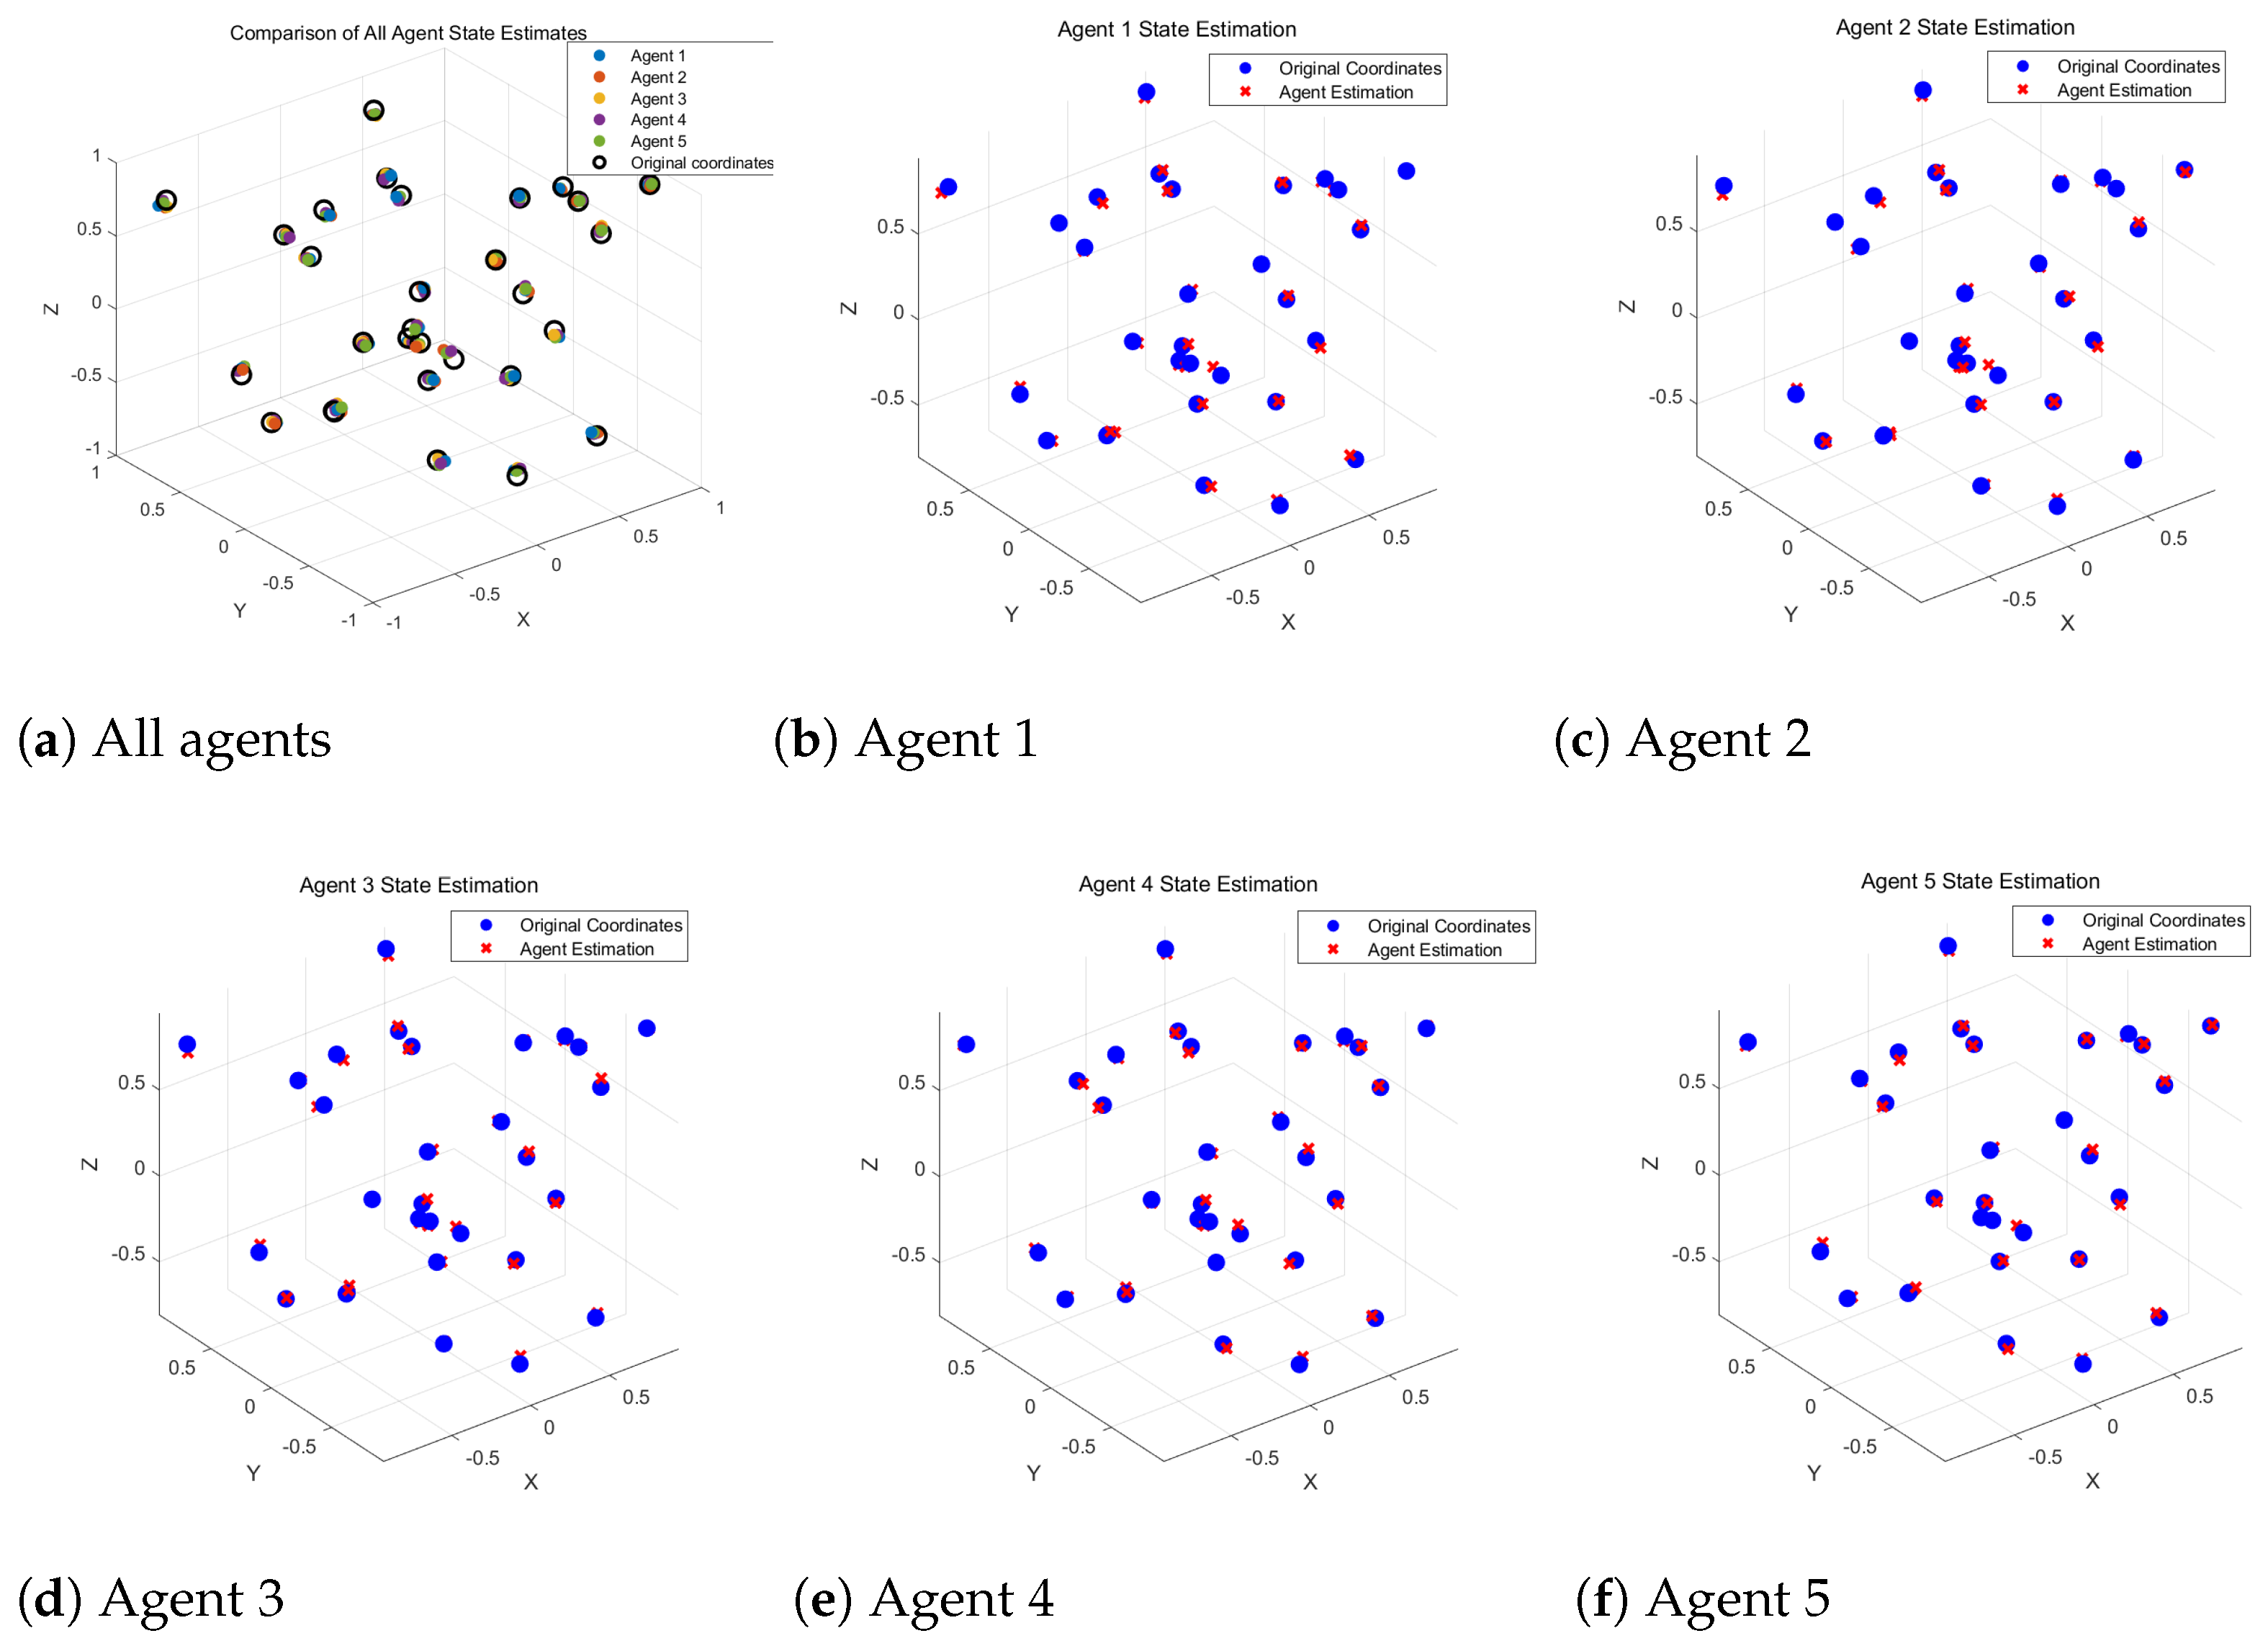
Based on the simulation setup described above, the proposed algorithm successfully recovers the object’s 3D coordinates from the multi-view observations. The results demonstrate the effectiveness of our approach, as shown in Figure 4 and Figure 5.
Figure 4.
Overall multi-view 3D localization results.
Figure 5.
Distributed reconstruction: 3D coordinates recovered locally by each agent.
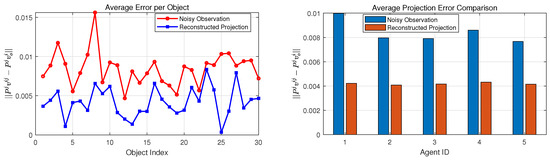
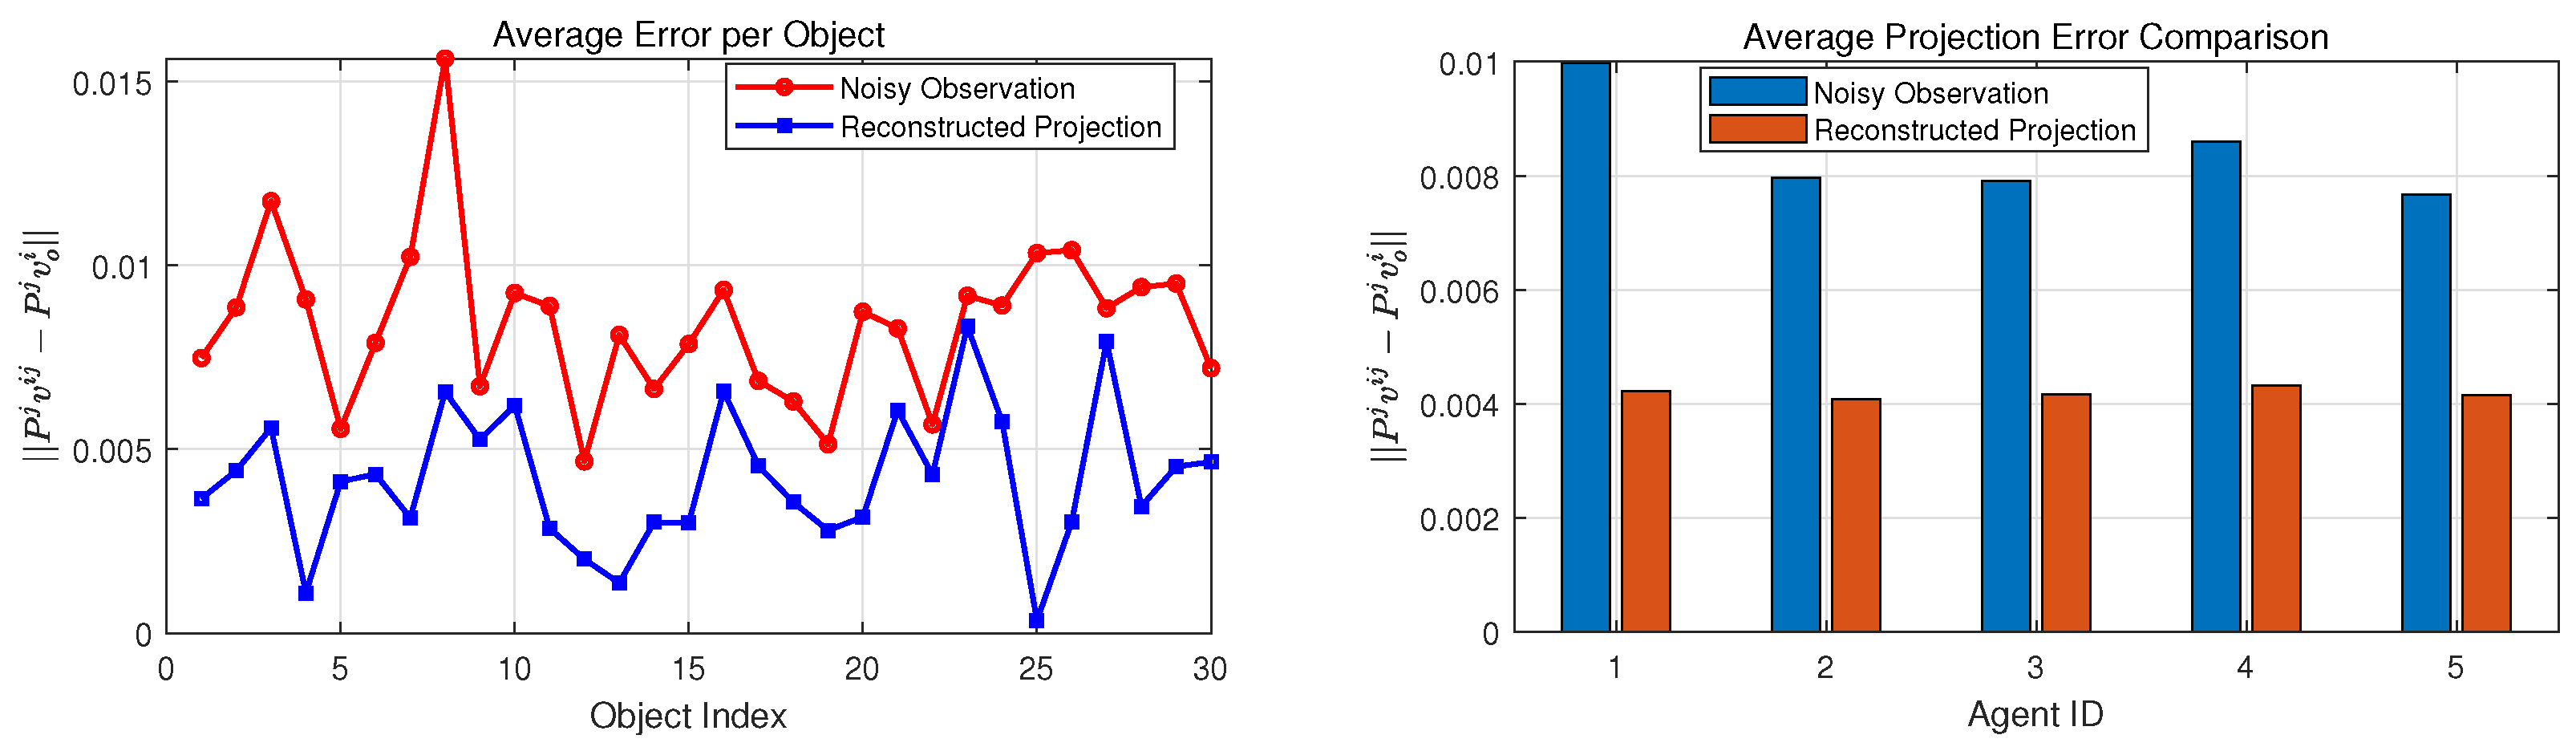
The reprojected 2D coordinates from reconstructed 3D coordinates are compared with the original projections and noisy observations in the Figure 6.
Figure 6.
Reprojection error.
Both from the comparison of average observation errors per agent for individual objects and the comparison of observation errors versus reprojection errors per object under specific agents, it is evident that the reprojection errors of reconstructed coordinates are significantly reduced compared to noisy observations. This demonstrates the strong robustness of the proposed method, establishing it as an effective distributed approach for 3D space localization by triangulation with fusing multi-view data and without global data.
5.2.3. Algorithm Comparison and Analysis
Based on the validated effectiveness of the proposed algorithm in the previous section, this section provides a deeper analysis through comparative experiments with a series of least-squares (LS)-based methods.
Typically, triangulation is formulated as solving an overdetermined system, often approached via the centralized least-squares problem . In a distributed setting, this is decomposed into local subproblems coordinated by consensus constraints:
Standard distributed solvers for this formulation include Distributed Gradient Descent (DGD), Distributed Alternating Direction Method of Multipliers (D-ADMM), and Distributed Levenberg–Marquardt (D-LM). In the following, we compare our proposed algorithm against these distributed algorithm.
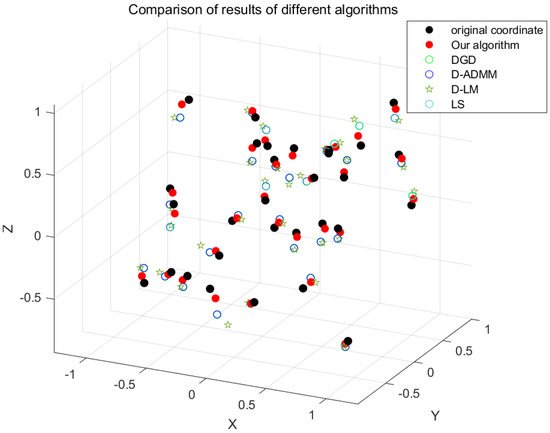
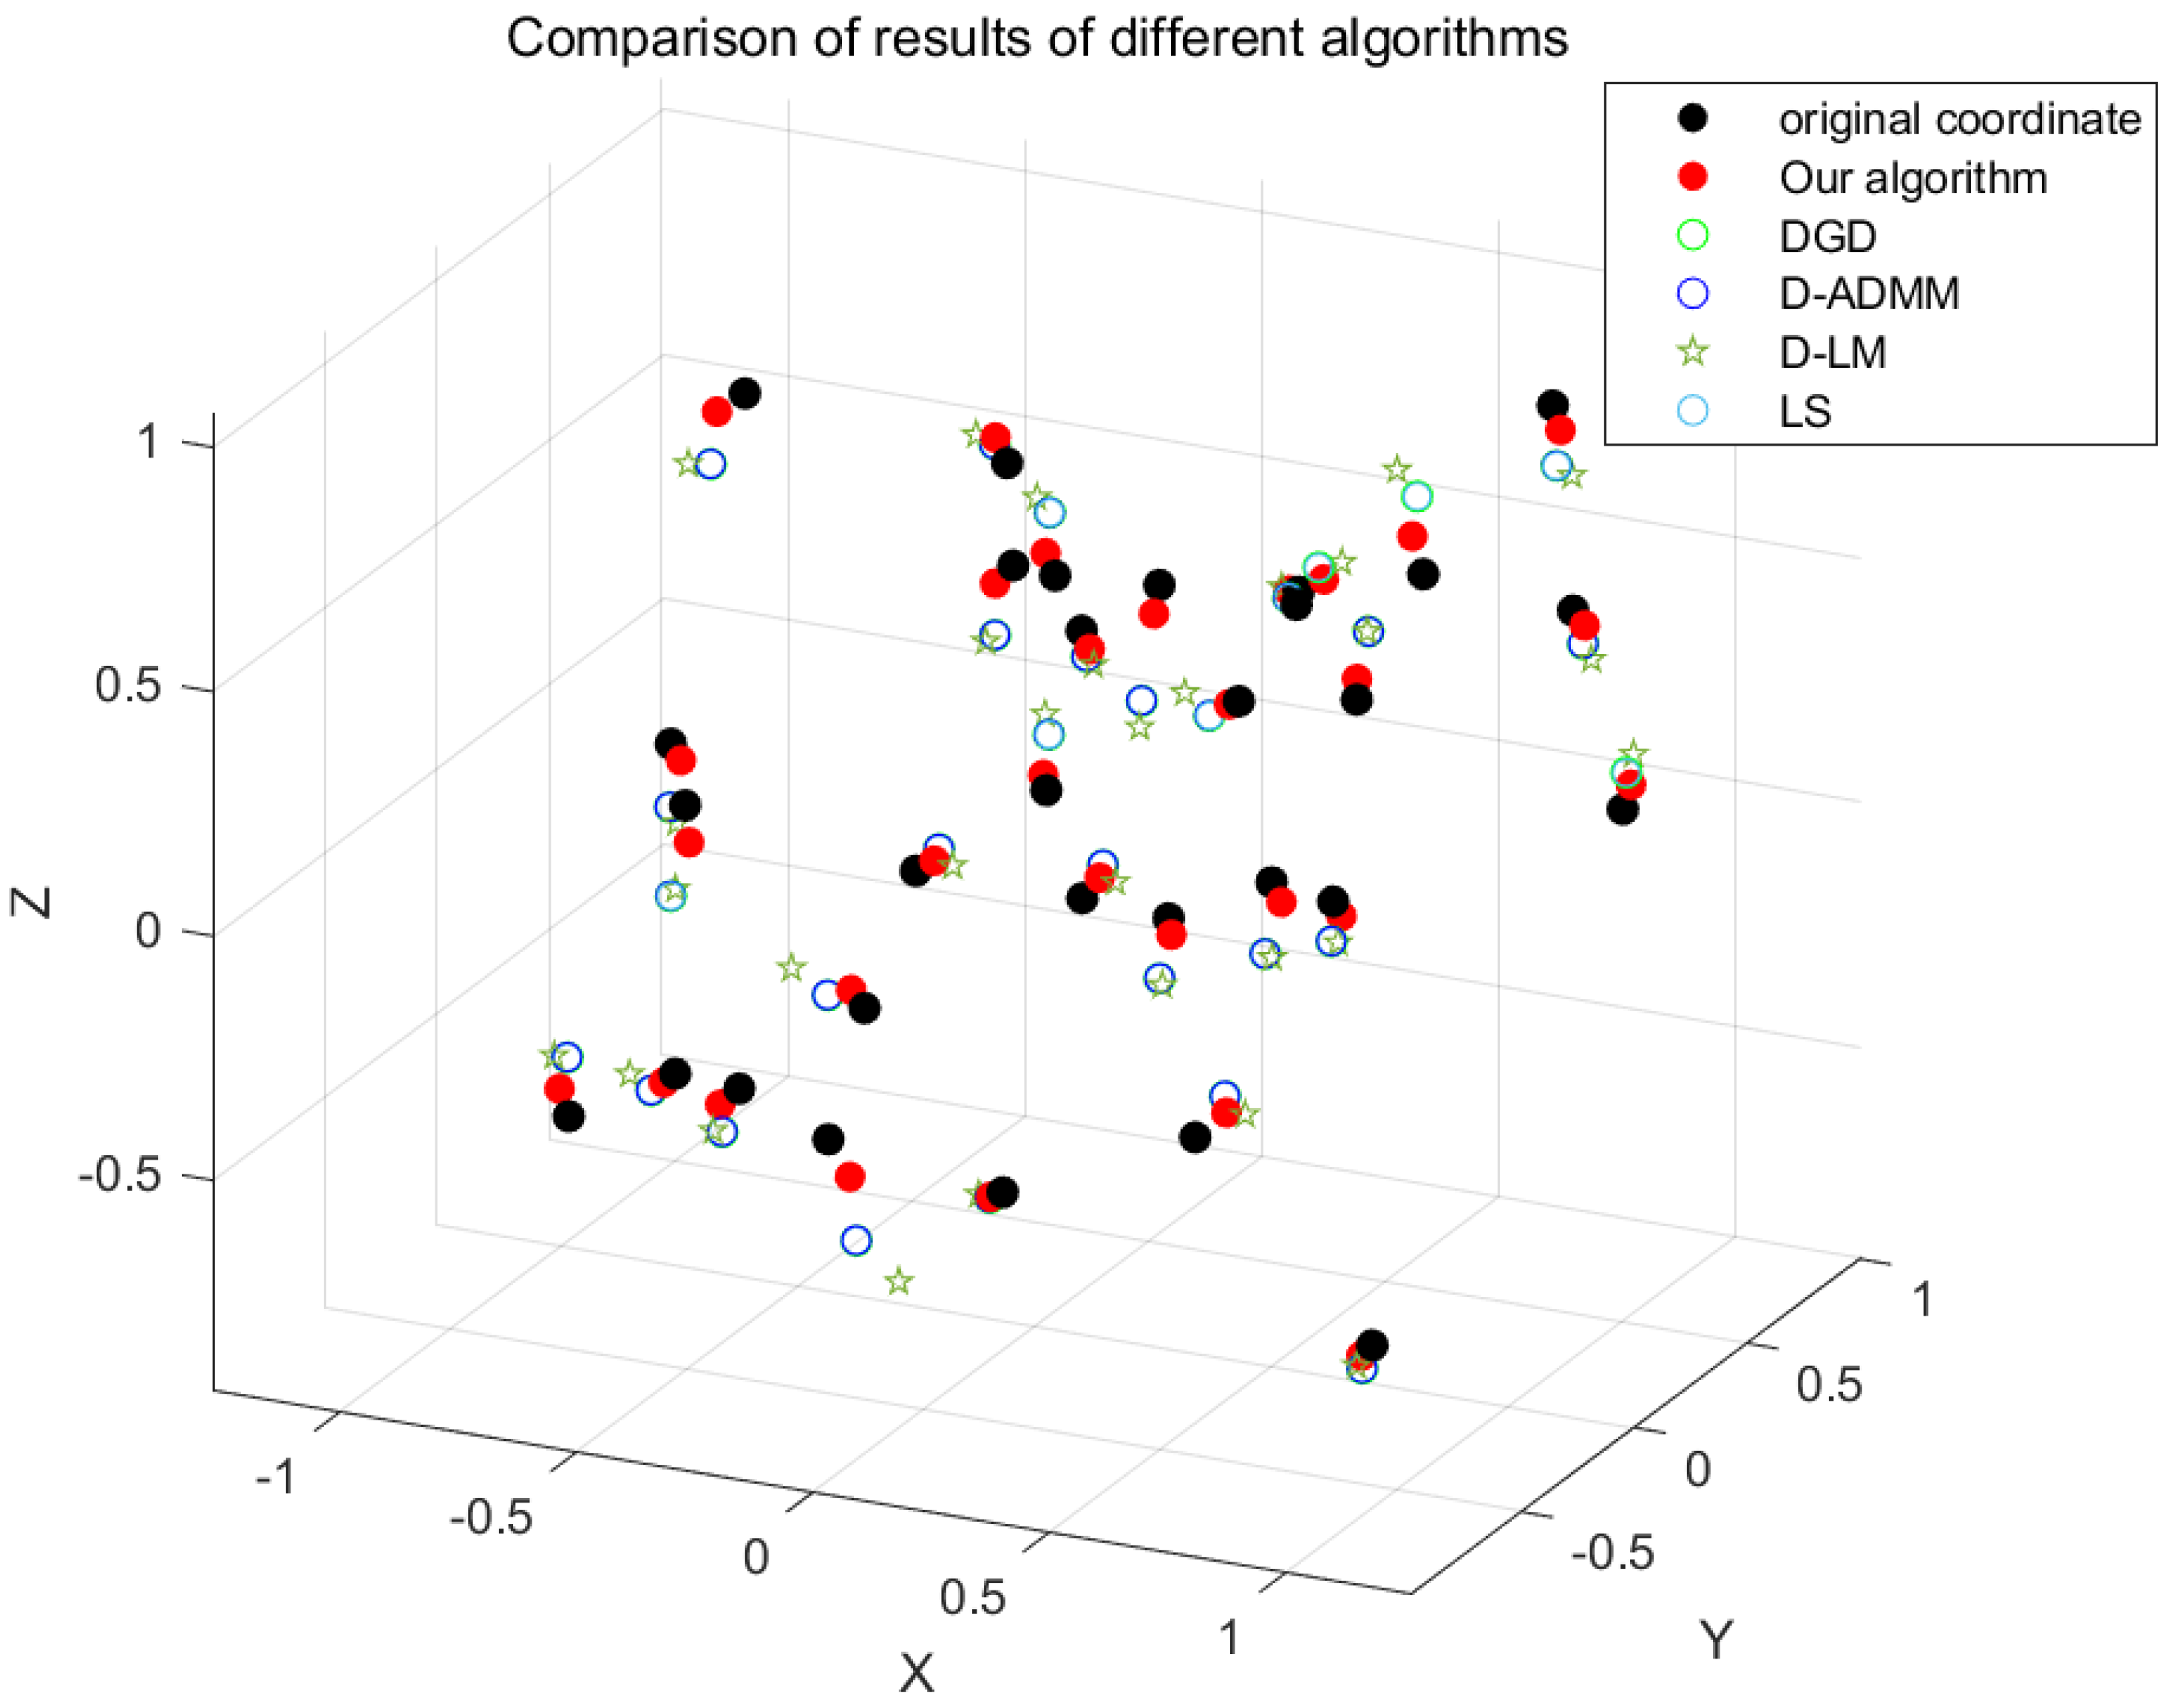
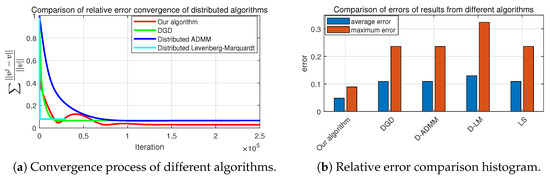
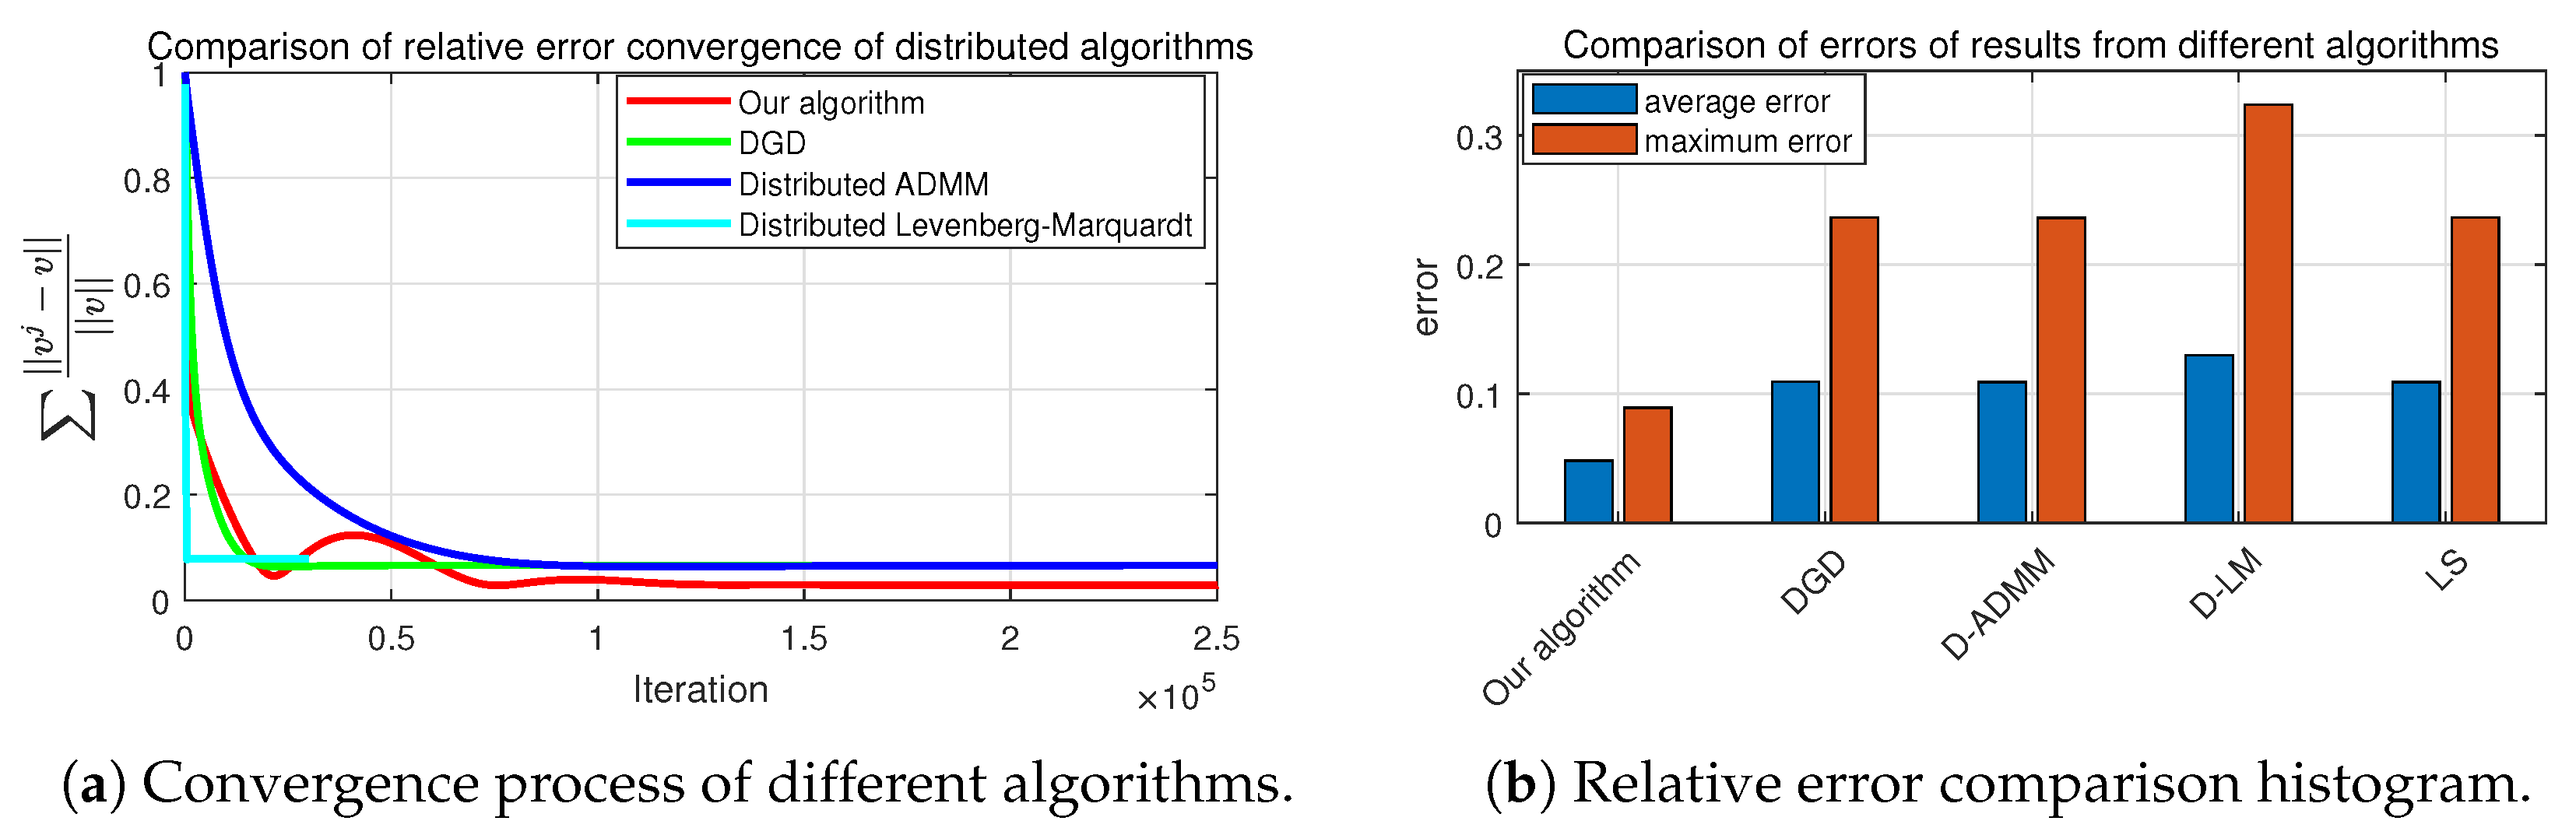
We design the following experiment: different levels of Gaussian noise are added to the observed coordinates of the five cameras. Specifically, agent 3 is assigned the highest noise amplitude , while the remaining agents receive much lower noise with . The corresponding tolerance parameter for each agent is set as . Results are as follow:
As demonstrated by the results in Figure 7 and Figure 8, when the problem is framed from a least-squares perspective, any algorithm will ultimately converge to the least-squares solution (LS). However, since each agent in such a method strongly adheres to its own observations, the collective solution can be disproportionately biased by the agent with the largest error, leading to significant final localization inaccuracy. In contrast, our proposed method incorporates prior knowledge by assigning a permissible tolerance range to each observation. This design allows agents with large observation error to adapt more actively to others, thereby demonstrating superior robustness.
Figure 7.
Visual display of calculation results of different algorithms.
Figure 8.
Algorithm comparison.
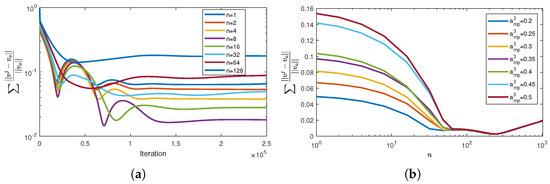
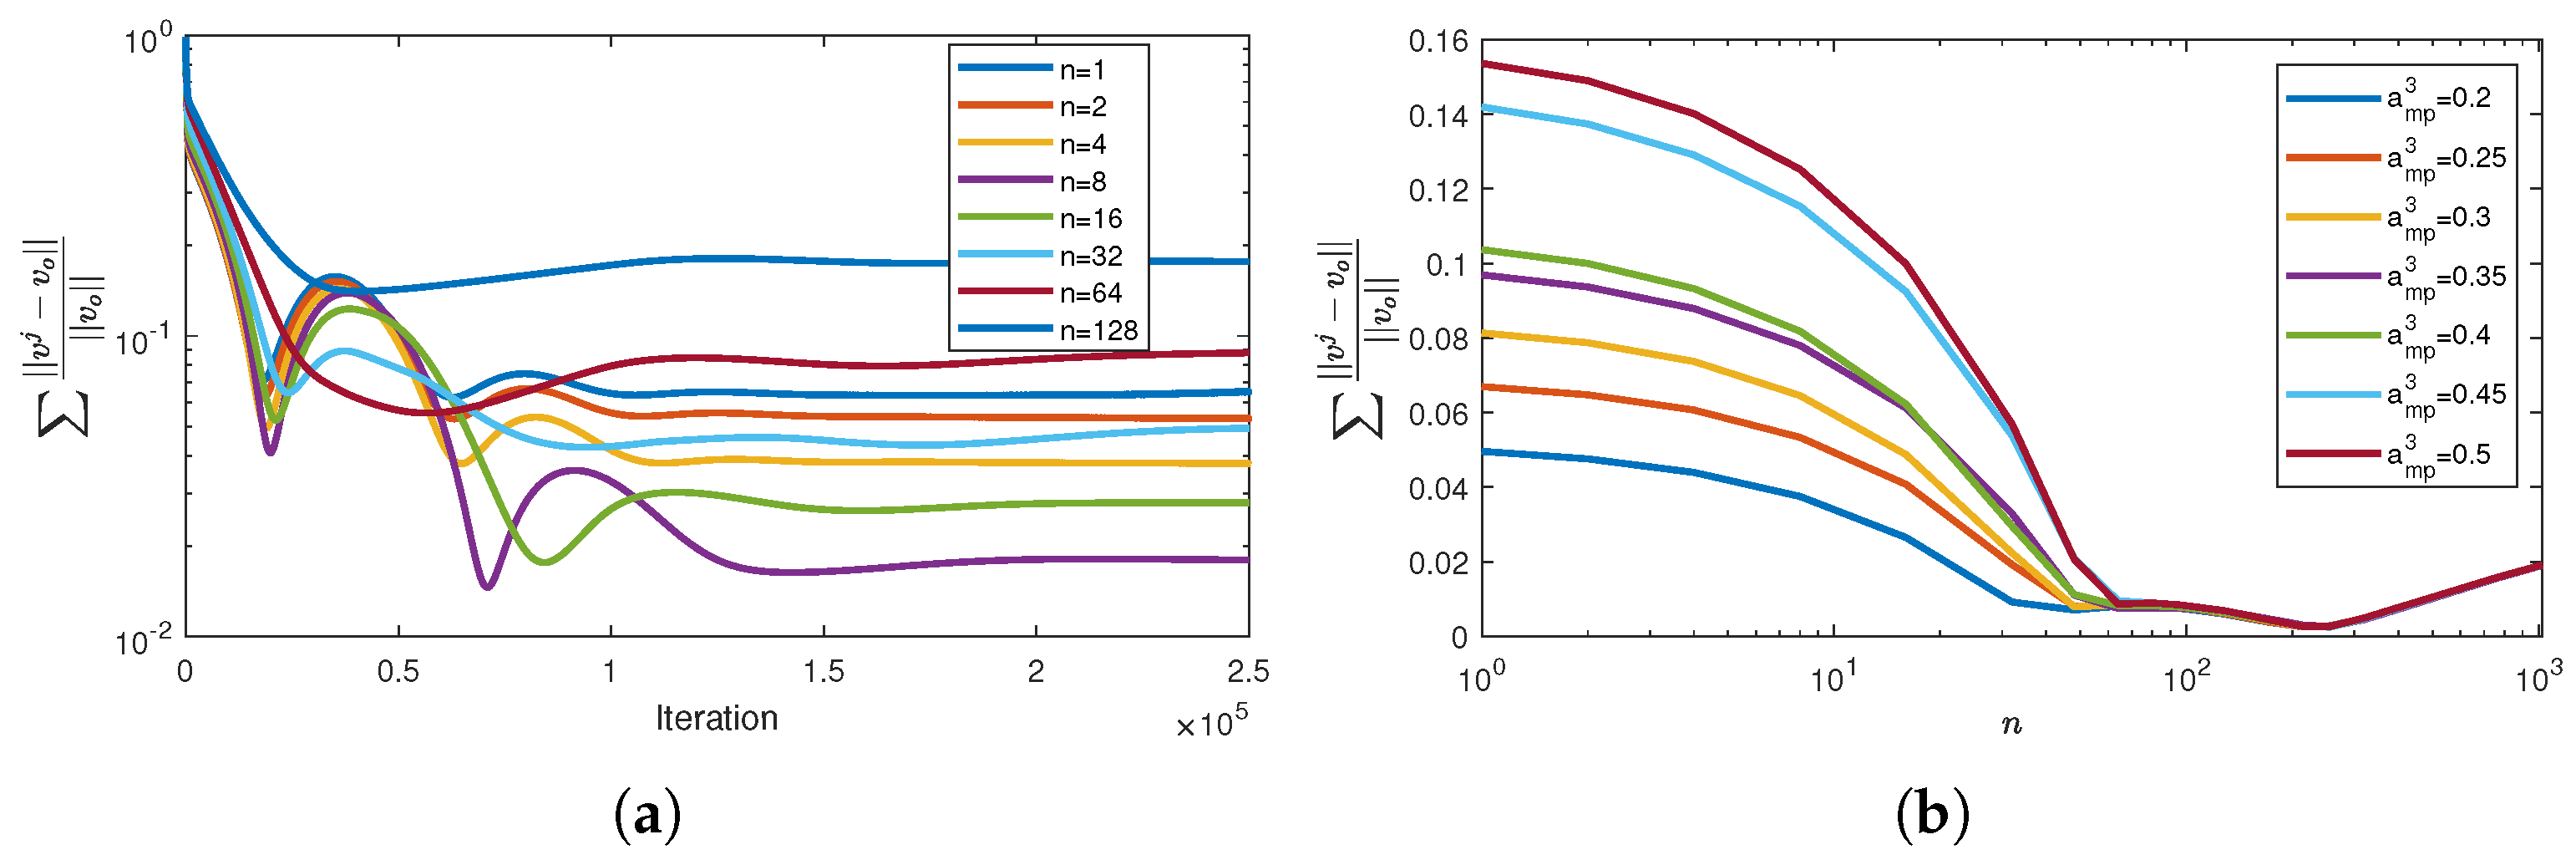
The proposed algorithm’s robustness stems from a key design parameter: the local error tolerance . To validate the aforementioned robustness mechanism, we design the following experiment: We continue to maintain the aforementioned agent noise amplitude settings and record the iterative behavior of the relative error under different values of n as defined by . Additionally, we adjust the noise amplitude of agent 3, record the final relative error for different n, and present the results as follows:
As shown in Figure 9, when one agent is subject to significant noise, the final relative error first decreases and then increases as the parameter n grows. This behavior occurs because defines the error tolerance of the observation constraints, modeled as a norm ball . The value of is designed based on prior estimates of sensor error. Each agent estimates the target coordinates by combining its own observations with estimates from neighboring nodes. An agent with a small strongly enforces agreement with its own observations, whereas an agent with a large imposes a looser constraint. When all values are small, each agent trusts its own observations highly; the corresponding norm balls do not intersect, and reaching consensus among agents becomes equivalent to solving a least-squares problem—a process that is often difficult. If the agent with larger error is assigned a larger and agents with smaller errors are assigned smaller , the high-error observation defines a larger norm ball, which can accommodate the more accurate observations without unduly distorting the overall estimate. In this regime, the objective function also acts as a regularizer. Conversely, if all values are very large, the intersection of the norm balls becomes too extensive, and the solution tends to collapse toward the origin under the influence of the objective function.
Figure 9.
Effect of parameter on robustness. (a) When the , the convergence process under different . (b) Under different noise amplitudes, the change in relative error as parameter increases.
6. Discussion
This paper presents a distributed smoothing neurodynamic approach for solving the – minimization problem, with application to multi-view 3D localization. By formulating localization as a distributed compressed sensing task, the method inherently enhances robustness against measurement noise. Theoretical analysis confirms the global convergence and stability of the model under smooth approximation. Numerical experiments demonstrate that the approach accurately and collaboratively recovers 3D coordinates from noisy multi-view observations. Its distributed nature offers practical deployment advantages in multi-agent systems with limited computational resources, and its robustness is further validated through parameter analysis. Future work will explore applications in more complex scenarios, such as calibration with unknown camera parameters, operation in dynamic environments, and the fusion of heterogeneous sensor data.
Furthermore, the current experiments in this study are based on simulated data considering noisy environments, which is sufficient to validate the algorithm’s fundamental principles and convergence. Future work will include validation on practically collected multi-view sequences. In the comparative analysis, our method is primarily compared with distributed optimization approaches based on the classic and mainstream least-squares model, clearly demonstrating the robustness improvements of our proposed method. The distributed neurodynamic model presented in this paper is a continuous-time system. For practical implementation on digital platforms, discretization (such as the Euler method) is required for simulation. This fixed-step scheme does not involve complex logic during iteration, making it well-suited for execution on GPUs. However, further exploration is needed to design adaptive step-size strategies or more efficient discretization schemes for engineering deployment.
Author Contributions
Conceptualization, J.Y.; methodology, Y.Q.; software, Y.Q.; validation, Y.Q.; formal analysis, J.Y.; investigation, Y.Q. and J.Y.; writing—original draft preparation, Y.Q. and H.L.; visualization, Y.Q. and H.L.; writing—review and editing, Y.Z. and X.W.; supervision, Y.Z. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported by the Natural Science Foundation of China (Grant nos. 62406261, 62576293).
Institutional Review Board Statement
Not applicable. This study does not involve humans or animals.
Informed Consent Statement
Not applicable. This study involves theoretical algorithm development and mathematical proofs without any human participation or clinical data.
Data Availability Statement
The scripts used in the numerical experiments in this paper are uploaded to Github, accessed on 25 December 2025 (https://github.com/quyouran/Neurodynamic-Approach-for-Multi-View-Three-dimensional-Space-Localization).
Acknowledgments
The authors would like to acknowledge all colleagues and reviewers who have provided support and valuable suggestions for this work.
Conflicts of Interest
The authors declare no conflicts of interest.
Abbreviations
The following abbreviations are used in this manuscript:
| 3D | Three-dimensional |
| 2D | Two-dimensional |
| SfM | Structure from Motion |
| SLAM | Simultaneous Localization and Mapping |
| CS | Compressed Sensing |
| BPDN | Basis Pursuit De-Noising |
Variables
The list of the variables and parameters presented in the mathematical formulas of this manuscript:
| m | Scalar | Observation dimension |
| n | Scalar | Signal dimension |
| w | Scalar | Number of agents (e.g., cameras) |
| Vector | Local state estimate of the j-th agent | |
| Matrix | Local observation matrix of the j-th agent | |
| Vector | Observation vector of the j-th agent | |
| Scalar | Noise tolerance of the j-th agent | |
| L | Matrix | Graph Laplacian matrix, used for consensus constraint |
| Set | Set of neighbors of agent j | |
| Scalar | Smoothing parameter, typically set as | |
| Row vector | Smoothing parameter, every element in the vector is | |
| Function | Smooth approximation function for | |
| Function | Smooth approximation of | |
| Function | Smooth approximation of | |
| Vector | Gradient of with respect to | |
| Vector | Gradient of with respect to | |
| Vector | Lagrange multiplier or penalty variable | |
| Vector | Auxiliary state variable for consensus constraint | |
| Vector | Lagrange multiplier for consensus constraint | |
| Operation | Positive projection operation: | |
| Function | Sign function | |
| Derivative | Time derivative of the state variable | |
| Matrix | Camera projection matrix (intrinsic and extrinsic parameters) | |
| K | Matrix | Camera intrinsic matrix |
| Matrix | Rotation matrix of the j-th camera | |
| Vector | Translation vector of the j-th camera | |
| Vector | Homogeneous 3D coordinates of the object | |
| Vector | All-ones vector, used for coordinate translation | |
| Vector | ||
| Scalar | Observation noise amplitude of the j-th agent |
References
- Simsek, E.; Ozyer, B. DeepDCT-VO: 3D directional coordinate transformation for low-complexity monocular visual odometry using deep learning. Image Vis. Comput. 2025, 163, 105742. [Google Scholar] [CrossRef] [Scilit]
- Fu, Y.; Jain, A.; Chen, X.; Mo, Z.; Di, X. Drivegenvlm: Real-world video generation for vision language model based autonomous driving. In Proceedings of the 2024 IEEE International Automated Vehicle Validation Conference (IAVVC), Pittsburgh, PA, USA, 21–23 October 2024; pp. 1–6. [Google Scholar]
- Dai, M.; Cheng, W.; Liu, J.J.; Yang, L.; Feng, Z.; Yang, W.; Wang, J. Improving generalized visual grounding with instance-aware joint learning. IEEE Trans. Pattern Anal. Mach. Intell. 2025, 48, 448–465. [Google Scholar] [CrossRef] [Scilit]
- Berrio, J.S.; Shan, M.; Worrall, S.; Nebot, E. Camera-LIDAR integration: Probabilistic sensor fusion for semantic mapping. IEEE Trans. Intell. Transp. Syst. 2022, 23, 7637–7652. [Google Scholar] [CrossRef] [Scilit]
- Jiao, J.; Geng, R.; Li, Y.; Xin, R.; Yang, B.; Wu, J.; Wang, L.; Liu, M.; Fan, R.; Kanoulas, D. Real-time metric-semantic mapping for autonomous navigation in outdoor environments. IEEE Trans. Autom. Sci. Eng. 2025, 22, 5729–5740. [Google Scholar] [CrossRef] [Scilit]
- Xu, Y.; Dai, Q.; Gu, H.; Lu, G.; Gu, J.; Hua, L. Semantic map construction based on monocular vision. In Proceedings of the 2019 11th International Conference on Intelligent Human-Machine Systems and Cybernetics (IHMSC), Hangzhou, China, 24–25 August 2019; Volume 2, pp. 126–129. [Google Scholar]
- Lorenc, A.; Szarata, J.; Czuba, M. Real-Time Location System (RTLS) Based on the Bluetooth Technology for Internal Logistics. Sustainability 2023, 15, 4976. [Google Scholar] [CrossRef] [Scilit]
- Yan, J.; Zhang, B.; Zhou, M.; Campbell-Valois, F.X.; Siu, S.W. A deep learning method for predicting the minimum inhibitory concentration of antimicrobial peptides against Escherichia coli using Multi-Branch-CNN and Attention. mSystems 2023, 8, e00345-23. [Google Scholar] [CrossRef] [Scilit]
- Yan, J.; Zhang, B.; Zhou, M.; Kwok, H.F.; Siu, S.W. Multi-Branch-CNN: Classification of ion channel interacting peptides using multi-branch convolutional neural network. Comput. Biol. Med. 2022, 147, 105717. [Google Scholar] [CrossRef] [Scilit]
- Gao, T.; Sheng, W.; Zhou, M.; Fang, B.; Luo, F.; Li, J. Method for fault diagnosis of temperature-related mems inertial sensors by combining Hilbert–Huang transform and deep learning. Sensors 2020, 20, 5633. [Google Scholar] [CrossRef] [Scilit]
- He, X.; Zhang, Y.; Zhan, Q. AIN-YOLO: A lightweight YOLO network with attention-based InceptionNext and knowledge distillation for underwater object detection. Adv. Eng. Inform. 2025, 66, 103504. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Feng, Y.; Zhou, M.; Xiong, X.; Wang, Y.; Qiang, B. DMA-YOLO: Multi-scale object detection method with attention mechanism for aerial images. Vis. Comput. 2024, 40, 4505–4518. [Google Scholar] [CrossRef] [Scilit]
- Yuan, S.; Qin, H.; Yan, X.; Akhtar, N.; Mian, A. SCTransNet: Spatial-channel cross transformer network for infrared small target detection. IEEE Trans. Geosci. Remote Sens. 2024, 62, 5002615. [Google Scholar]
- Hartley, R.; Kahl, F. Optimal algorithms in multiview geometry. In Proceedings of the Asian Conference on Computer Vision, Tokyo, Japan, 18–22 November 2007; pp. 13–34. [Google Scholar]
- Zhang, L.; Zhang, J.; Chen, B.; Lu, Z.; Hu, Y.; Zhang, J. Multiview triangulation with uncertain data. In Proceedings of the 2013 IEEE International Conference on Robotics and Biomimetics (ROBIO), Shenzhen, China, 12–14 December 2013; pp. 1414–1419. [Google Scholar]
- Härenstam-Nielsen, L.; Zeller, N.; Cremers, D. Semidefinite relaxations for robust multiview triangulation. In Proceedings of the 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Vancouver, BC, Canada, 17–24 June 2023; pp. 749–757. [Google Scholar]
- Li, H.; Deng, Y.; Wang, J.; Zhao, F.; Wu, Y.; Zheng, M. Refined two-stage programming approach to multibaseline phase unwrapping via gradient regularization and quality-guided triangulation. IEEE Geosci. Remote Sens. Lett. 2024, 21, 1–5. [Google Scholar] [CrossRef] [Scilit]
- Kim, J.S.; Kim, C.H.; Shin, Y.M.; Cho, I.S.; Cho, D.I.D. Outdoor monocular visual odometry enhancement using depth map and semantic segmentation. In Proceedings of the 2020 20th International Conference on Control, Automation and Systems (ICCAS), Busan, Republic of Korea, 13–16 October 2020; pp. 1040–1045. [Google Scholar]
- Yuan, J.; Zhu, S.; Tang, K.; Sun, Q. ORB-TEDM: An RGB-D SLAM approach fusing ORB triangulation estimates and depth measurements. IEEE Trans. Instrum. Meas. 2022, 71, 5006315. [Google Scholar] [CrossRef] [Scilit]
- Takao, S.; Kita, T.; Hirabayashi, T. Towards reconstruction of 3D geometry of underwater rubble mounds via structure from motion. In Proceedings of the 2023 IEEE Underwater Technology (UT), Tokyo, Japan, 6–9 March 2023; pp. 1–6. [Google Scholar]
- Thomas, B.; Mike E., D. Iterative hard thresholding for compressed sensing. Appl. Comput. Harmon. Anal. 2008, 27, 265–274. [Google Scholar]
- Kausik, B.N. Sparse aApproximate solutions to linear systems. Siam J. Comput. 1995, 24, 227–234. [Google Scholar]
- Scott, S.; David, L.; Michael, A. Atomic decomposition by basis pursuit. Siam Rev. 2001, 43, 129–159. [Google Scholar]
- Wen, F.; Liu, P.; Liu, Y.; Qiu, R.C.; Yu, W. Robust sparse recovery in impulsive noise via ℓp -ℓ1 optimization. IEEE Trans. Signal Process. 2017, 65, 105–118. [Google Scholar]
- Guo, C.; Yang, Q. A neurodynamic optimization method for recovery of compressive sensed signals with globally converged solution approximating to l0 minimization. IEEE Trans. Neural Netw. Learn. Syst. 2015, 26, 1363–1374. [Google Scholar] [PubMed]
- Wang, Y.; Li, X.; Wang, J. A neurodynamic approach to L0-constrained optimization. In Proceedings of the 2020 12th International Conference on Advanced Computational Intelligence (ICACI), Dali, China, 14–16 March 2020; pp. 44–50. [Google Scholar]
- Liu, Q.; Wang, J. L1-minimization algorithms for sparse signal reconstruction based on a projection neural network. IEEE Trans. Neural Netw. Learn. Syst. 2016, 27, 698–707. [Google Scholar]
- Zhao, Y.; Liao, X.; He, X.; Tang, R. Centralized and collective neurodynamic optimization approaches for sparse signal reconstruction via L1-minimization. IEEE Trans. Neural Netw. Learn. Syst. 2022, 33, 7488–7501. [Google Scholar]
- Liu, Y.; Hu, J. A neural network for ℓ1 -ℓ2 minimization based on scaled gradient projection: Application to compressed sensing. Neurocomputing 2016, 173, 988–993. [Google Scholar] [CrossRef] [Scilit]
- Zhu, L.; Wang, J.; He, X.; Zhao, Y. An inertial projection neural network for sparse signal reconstruction via l1–2 minimization. Neurocomputing 2018, 315, 89–95. [Google Scholar] [CrossRef] [Scilit]
- Wang, D.; Zhang, Z. Generalized sparse recovery model and its neural dynamical optimization method for compressed sensing. Circuits, Syst. Signal Process. 2017, 36, 4326–4353. [Google Scholar] [CrossRef] [Scilit]
- Zhao, Y.; He, X.; Huang, T.; Huang, J.; Huang, P. A smoothing neural network for minimization l1-lp in sparse signal reconstruction with measurement noises. Neural Netw. 2020, 122, 40–53. [Google Scholar]
- Bian, W.; Chen, X. Smoothing neural network for constrained non-lipschitz optimization with applications. IEEE Trans. Neural Netw. Learn. Syst. 2012, 23, 399–411. [Google Scholar]
- Li, W.; Bian, W.; Xue, X. Projected neural network for a class of non-lipschitz optimization problems with linear constraints. IEEE Trans. Neural Netw. Learn. Syst. 2020, 31, 3361–3373. [Google Scholar]
- Liu, Y.; Li, Q.; Zhu, L. Smoothing neural network for constrained convex optimization with global attractivity. In Proceedings of the 2014 International Conference on Mechatronics and Control (ICMC), Shenyang, China, 29–31 August 2014; pp. 924–929. [Google Scholar]
- Bian, W.; Chen, X. Neural network for nonsmooth, nonconvex constrained minimization via smooth approximation. IEEE Trans. Neural Netw. Learn. Syst. 2014, 25, 545–556. [Google Scholar] [CrossRef] [Scilit]
- Zhou, M.; Zhang, Y.; Li, B.; Lin, X. Complexity Correlation-Based CTU-Level Rate Control with Direction Selection for HEVC. ACM Trans. Multimed. Comput. Commun. Appl. 2017, 13, 1551–6857. [Google Scholar]
- Wei, X.; Zhou, M.; Wang, H.; Yang, H.; Chen, L.; Kwong, S. Recent Advances in Rate Control: From Optimization to Implementation and Beyond. IEEE Trans. Circuits Syst. Video Technol. 2024, 34, 17–33. [Google Scholar] [CrossRef] [Scilit]
- Yan, Z.; Wang, J.; Li, G. A collective neurodynamic optimization approach to bound-constrained nonconvex optimization. Neural Netw. 2014, 55, 20–29. [Google Scholar] [CrossRef] [Scilit]
- Gharesifard, B.; Cortes, J. Distributed continuous-time convex optimization on weight-balanced digraphs. IEEE Trans. Autom. Control 2014, 59, 781–786. [Google Scholar]
- Liu, Q.; Yang, S.; Wang, J. A collective neurodynamic approach to distributed constrained optimization. IEEE Trans. Neural Netw. Learn. Syst. 2017, 28, 1747–1758. [Google Scholar]
- Le, X.; Chen, S.; Yan, Z.; Xi, J. A neurodynamic approach to distributed optimization with globally coupled constraints. IEEE Trans. Cybern. 2018, 48, 3149–3158. [Google Scholar]
- Che, H.; Wang, J. A collaborative neurodynamic approach to global and combinatorial optimization. Neural Netw. 2019, 114, 15–27. [Google Scholar] [PubMed]
- Yan, Z.; Fan, J.; Wang, J. A collective neurodynamic approach to constrained global optimization. IEEE Trans. Neural Netw. Learn. Syst. 2017, 28, 1206–1215. [Google Scholar] [CrossRef] [Scilit]
- Yang, S.; Liu, Q.; Wang, J. A collaborative neurodynamic approach to multiple-objective distributed optimization. IEEE Trans. Neural Netw. Learn. Syst. 2018, 29, 981–992. [Google Scholar] [CrossRef] [Scilit]
- Zhao, Y.; Liao, X.; He, X. Distributed smoothing projection neurodynamic approaches for constrained nonsmooth optimization. IEEE Trans. Syst. Man, Cybern. Syst. 2023, 53, 675–688. [Google Scholar]
- Zhao, Y.; Liao, X. Distributed continuous and discrete time projection neurodynamic approaches for sparse recovery. IEEE Trans. Emerg. Top. Comput. Intell. 2022, 6, 1411–1426. [Google Scholar] [CrossRef] [Scilit]
- Chen, X. Smoothing methods for nonsmooth, nonconvex minimization. Math. Program. 2012, 134, 71–99. [Google Scholar] [CrossRef] [Scilit]
- Liu, Q.; Yang, S.; Hong, Y. Constrained consensus algorithms with fixed step size for distributed convex optimization over multiagent networks. IEEE Trans. Autom. Control 2017, 62, 4259–4265. [Google Scholar]
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.