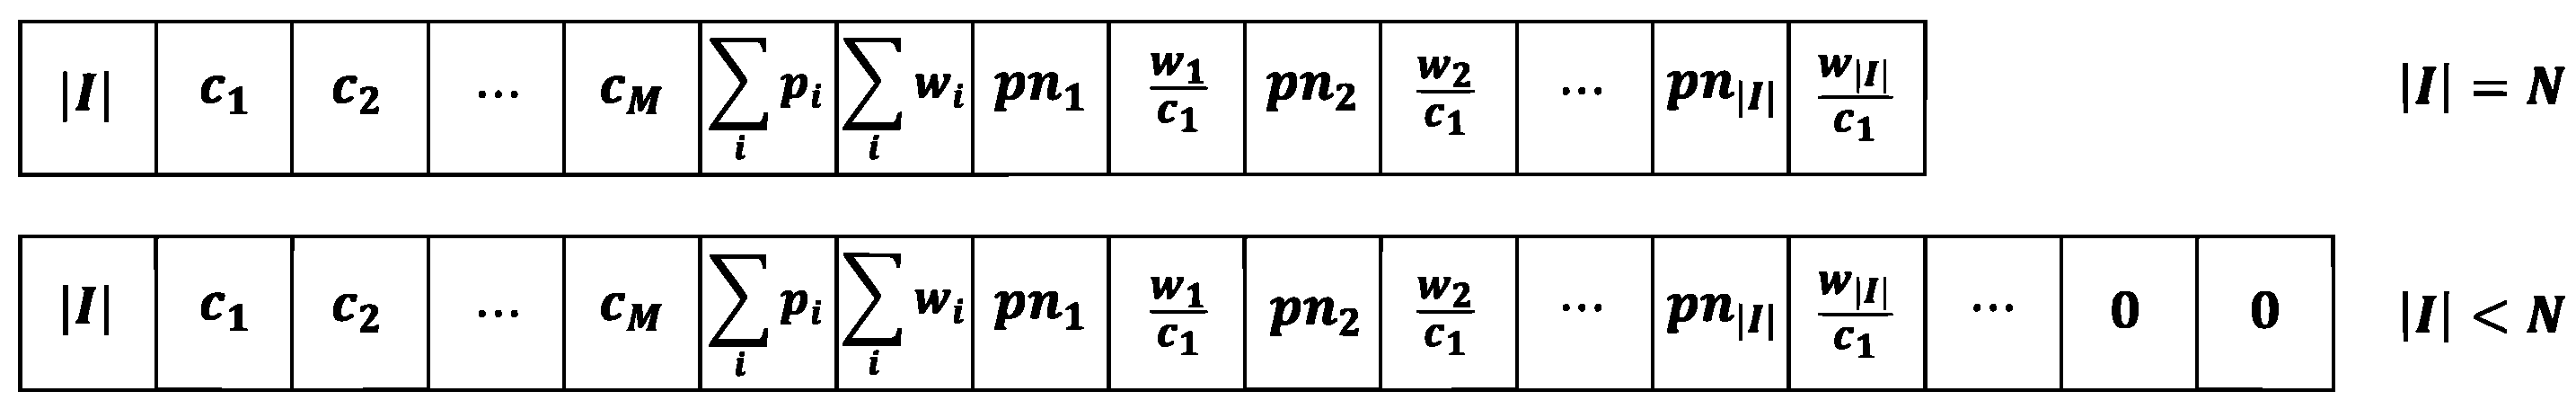Article

A Deep Reinforcement Learning-Based Scheme for Solving Multiple Knapsack Problems
1
Korea Institute of Energy Technology (KENTECH), Naju-si 58217, Korea
2
Defense AI Technology Center, Agency for Defense Development (ADD), Daejeon 34186, Korea
3
AI Graduate School, Gwangju Institute of Science and Technology (GIST), Gwangju 61005, Korea
*
Author to whom correspondence should be addressed.
Appl. Sci. 2022, 12(6), 3068; https://doi.org/10.3390/app12063068
Submission received: 15 February 2022 / Revised: 13 March 2022 / Accepted: 14 March 2022 / Published: 17 March 2022
(This article belongs to the Topic Complex Systems and Artificial Intelligence)

Abstract

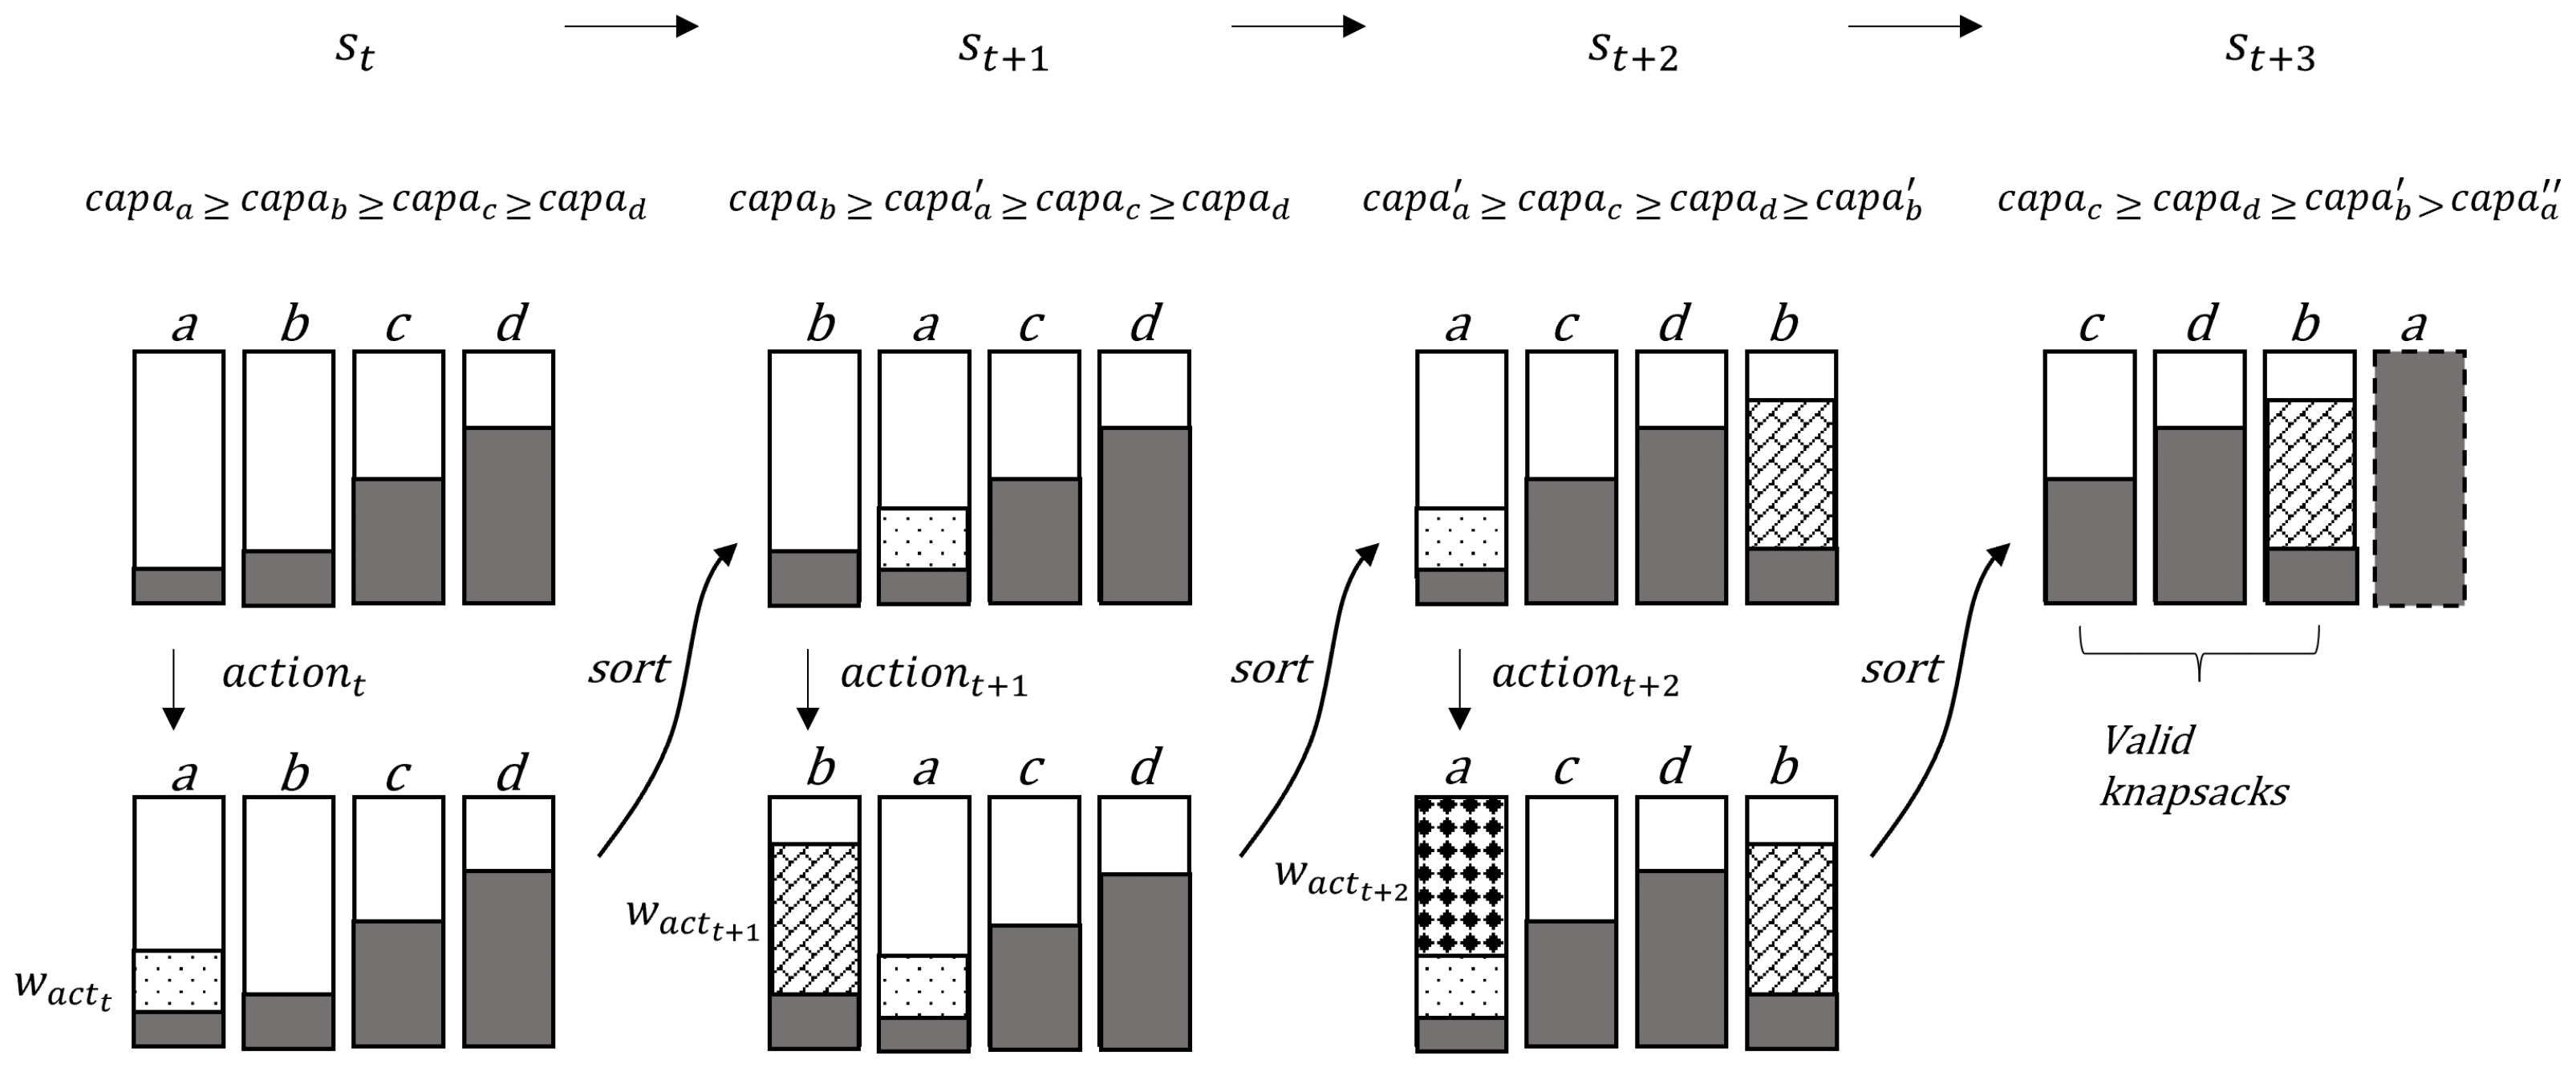
A knapsack problem is to select a set of items that maximizes the total profit of selected items while keeping the total weight of the selected items no less than the capacity of the knapsack. As a generalized form with multiple knapsacks, the multi-knapsack problem (MKP) is to select a disjointed set of items for each knapsack. To solve MKP, we propose a deep reinforcement learning (DRL) based approach, which takes as input the available capacities of knapsacks, total profits and weights of selected items, and normalized profits and weights of unselected items and determines the next item to be mapped to the knapsack with the largest available capacity. To expedite the learning process, we adopt the Asynchronous Advantage Actor-Critic (A3C) for the policy model. The experimental results indicate that the proposed method outperforms the random and greedy methods and achieves comparable performance to an optimal policy in terms of the profit ratio of the selected items to the total profit sum, particularly when the profits and weights of items have a non-linear relationship such as quadratic forms.
Keywords: knapsack problem; deep reinforcement learning; profit maximization knapsack problem; deep reinforcement learning; profit maximization