


Abstract
Information in multiple views is typically symmetrical and distinctive. Multi-view clustering generally attempts to address two key issues: (1) how to mine/leverage additional useful information between different views for current view clustering, and (2) how to combine multiple clustering results from multiple views by using compatible and complementary information hidden in multiple views. In order to achieve this, we propose a multi-view clustering method, namely the multi-view utility-based clustering method (MUC), from the novel perspective of utility-based mutual supervision between different views. The proposed method, MUC, has notable merits: (1) It moves multi-view clustering from the level of feature and/or sample side to partition side information. That is, in order to handle the first issue, MUC considers how to use utility-based partition-level side information from all the other views for current view clustering. Such partition-level side information is consistent with human thinking; it is high-caliber and instructional for clustering. (2) The utility-based partition-level side information provided by other views complements current view information in a mutually supervised way. Then, we conduct multi-view clustering via a mutual supervision mode to circumvent the second issue. As a result, using an alternating optimization strategy, the objective function of MUC can be solved in a K-means-like way. Moreover, we leverage multi-view weight learning based on maximum entropy to integrate multi-view clustering results and further improve performance. The extensive experimental results on various multi-view datasets indicate that the proposed method is better than—or at least comparable to—the existing commonly used single- and multi-view clustering methods, in terms of both clustering performance and running speed.
1. Introduction
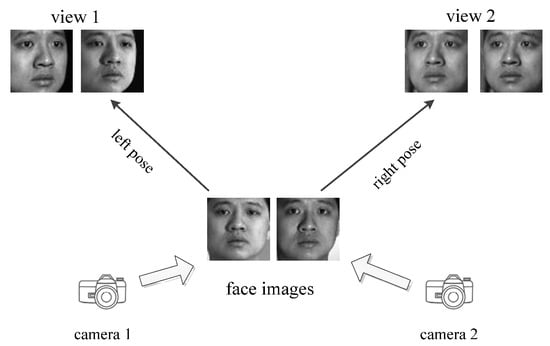
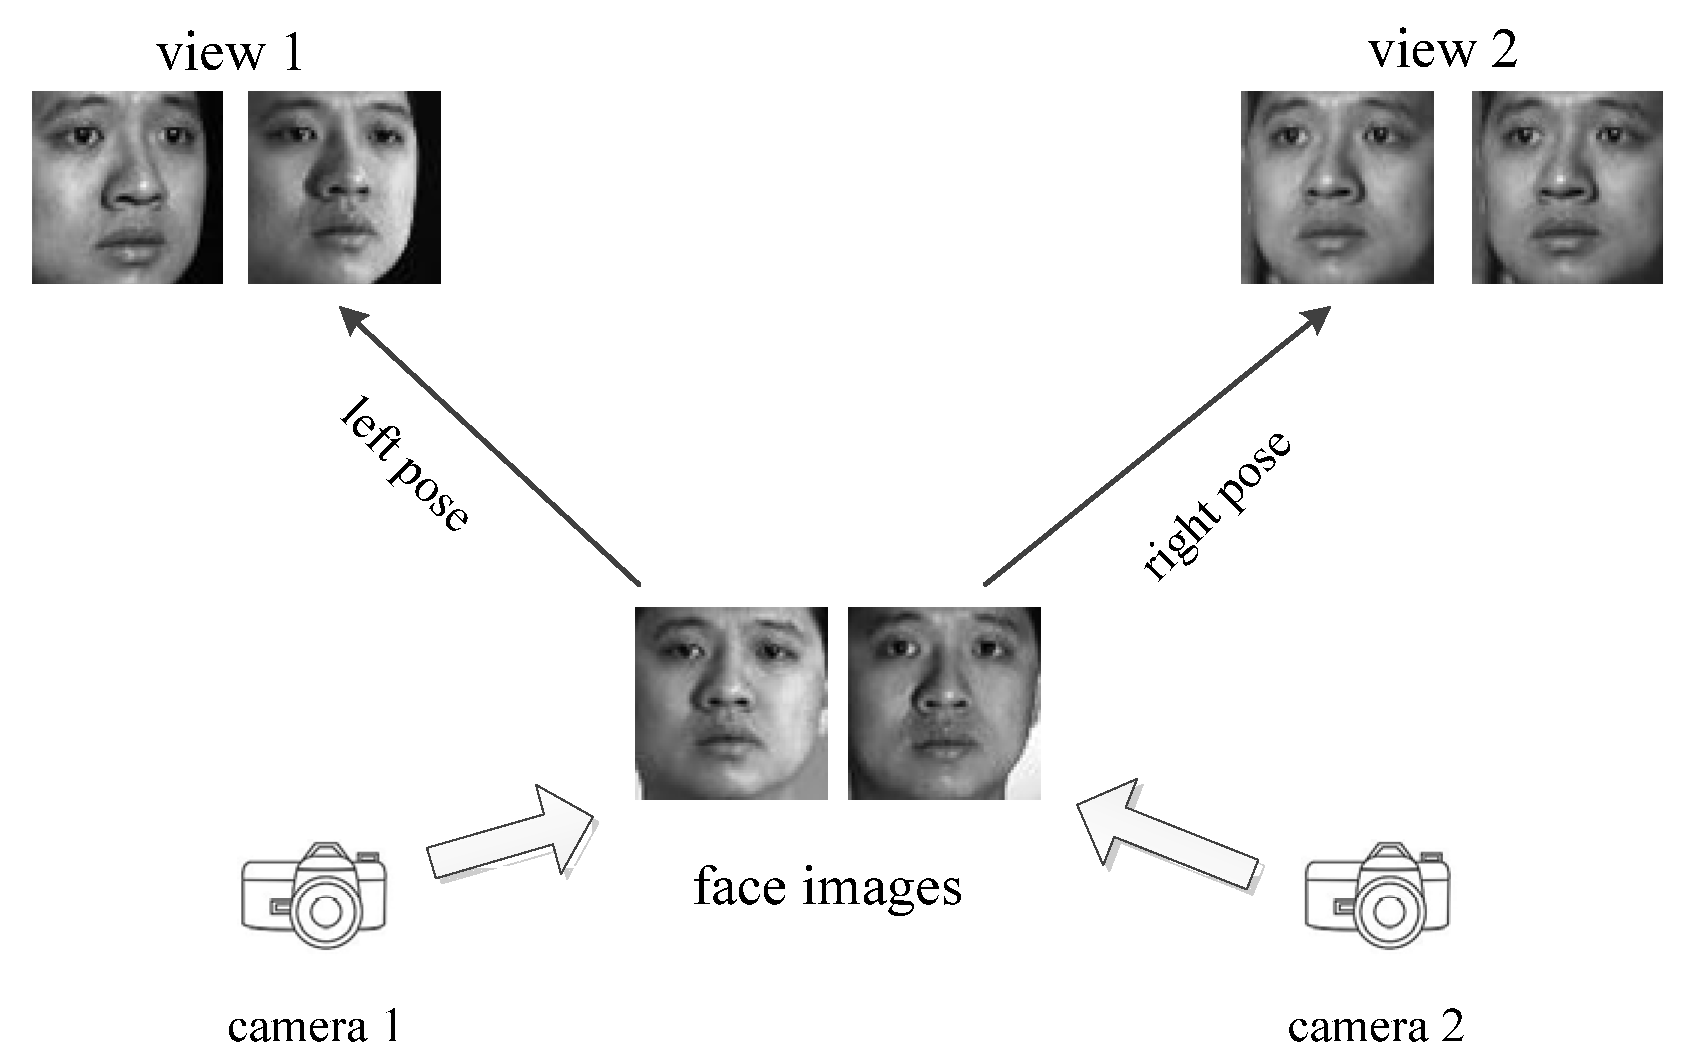
With fast advances in multimedia, a tremendous amount of unlabeled data with multiple attribute sets emerge on the Internet every day [1,2]. Today, in most scientific data analytics, in video surveillance, social computing and environmental sciences, after data available from diverse domains are preprocessed by means of various feature extractors, they often exhibit heterogeneous properties, because their features can be naturally partitioned into groups. They are called multi-view or multi-modal datasets [3]. For multi-view data, different views are different representations of the same set of objects, describing the same subject. Figure 1 gives an illustrative example of multi-view data on the same subject. It is therefore naturally desirable that we combine multiple views properly, so as to explore more useful information for improving learning performance. This leads to the emergence of the challenging machine learning problem of multi-view learning [4]. Recently, multi-view learning has attracted widespread attention, and various multi-view learning methods, such as regression [5], classification [6], and clustering [7,8,9,10,11,12,13], have emerged.
Figure 1.
Multi-view data of face images.
Among the existing multi-view learning research, multi-view clustering plays an important role. Thus far, various multi-view clustering methods have been designed for multi-view data, such as Co-FKM [11], MVKKM [12], and MV-Co-FCM [13]. Unlike traditional equivalents, multi-view clustering methods improve clustering performance by leveraging the connections between different views. There are two key issues in multi-view clustering: (1) how to mine useful additional information between different views for learning, and (2) how to combine multiple clustering results from multiple views by using the hidden, compatible, and complementary information.
For the first of these issues, since clustering is not ordered, the most instructional additional information, like the labels in supervised learning, cannot be used directly to guarantee which cluster belongs to a particular class. In response to this, and inspired by [14], we tend to utilize utility-based partition-level side information to circumvent these limitations of mining additional feature and/or sample-level side information in multi-view clustering. By utility-based partition-level side information, we mean that current view data are associated with an auxiliary partition. For two-view data, this comes from the whole data partition generated by some clustering method for the other view; for multi-view data, it comes from the averaging of or majority-voting on the whole data partitions generated by some clustering methods for all the other views. Utility-based partition-level side information is also consistent with human thinking. It is high-caliber and instructional for clustering, just as humans also tend to like to divide samples directly instead of first determining the cluster centers of the samples and then using them for division.
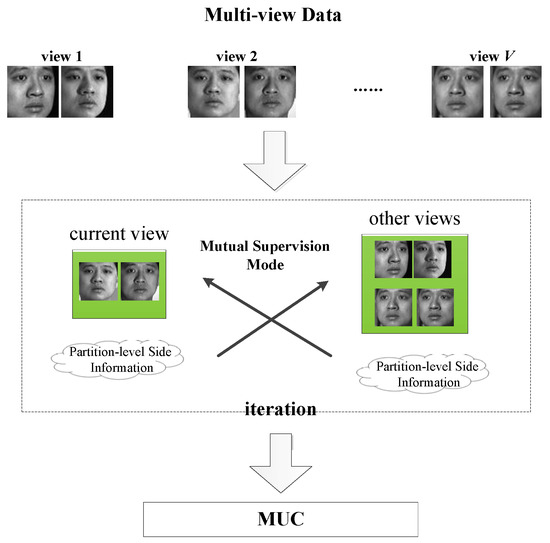
In relation to the second key issue, there are three types of view combination methods: concatenation, distributed and centralized. Unlike these above strategies, to address this, we propose a novel, mutual, supervised learning mechanism. In fact, since multi-view data describe the same objects from different views, naturally there is complementary partition information between multiple views. Therefore, it is reasonable for us to use the utility-based partition-level side information to learn multiple views in a mutual supervision mode. More concretely, taking two-view clustering as an example, the utility-based partition-level side information from the other view is used as the auxiliary supervised information to guide current view clustering; then, the resultant clustering results will be taken as the auxiliary partition-level information for clustering the other view. This mutual supervision procedure will be carried out alternately until certain termination criteria are met.
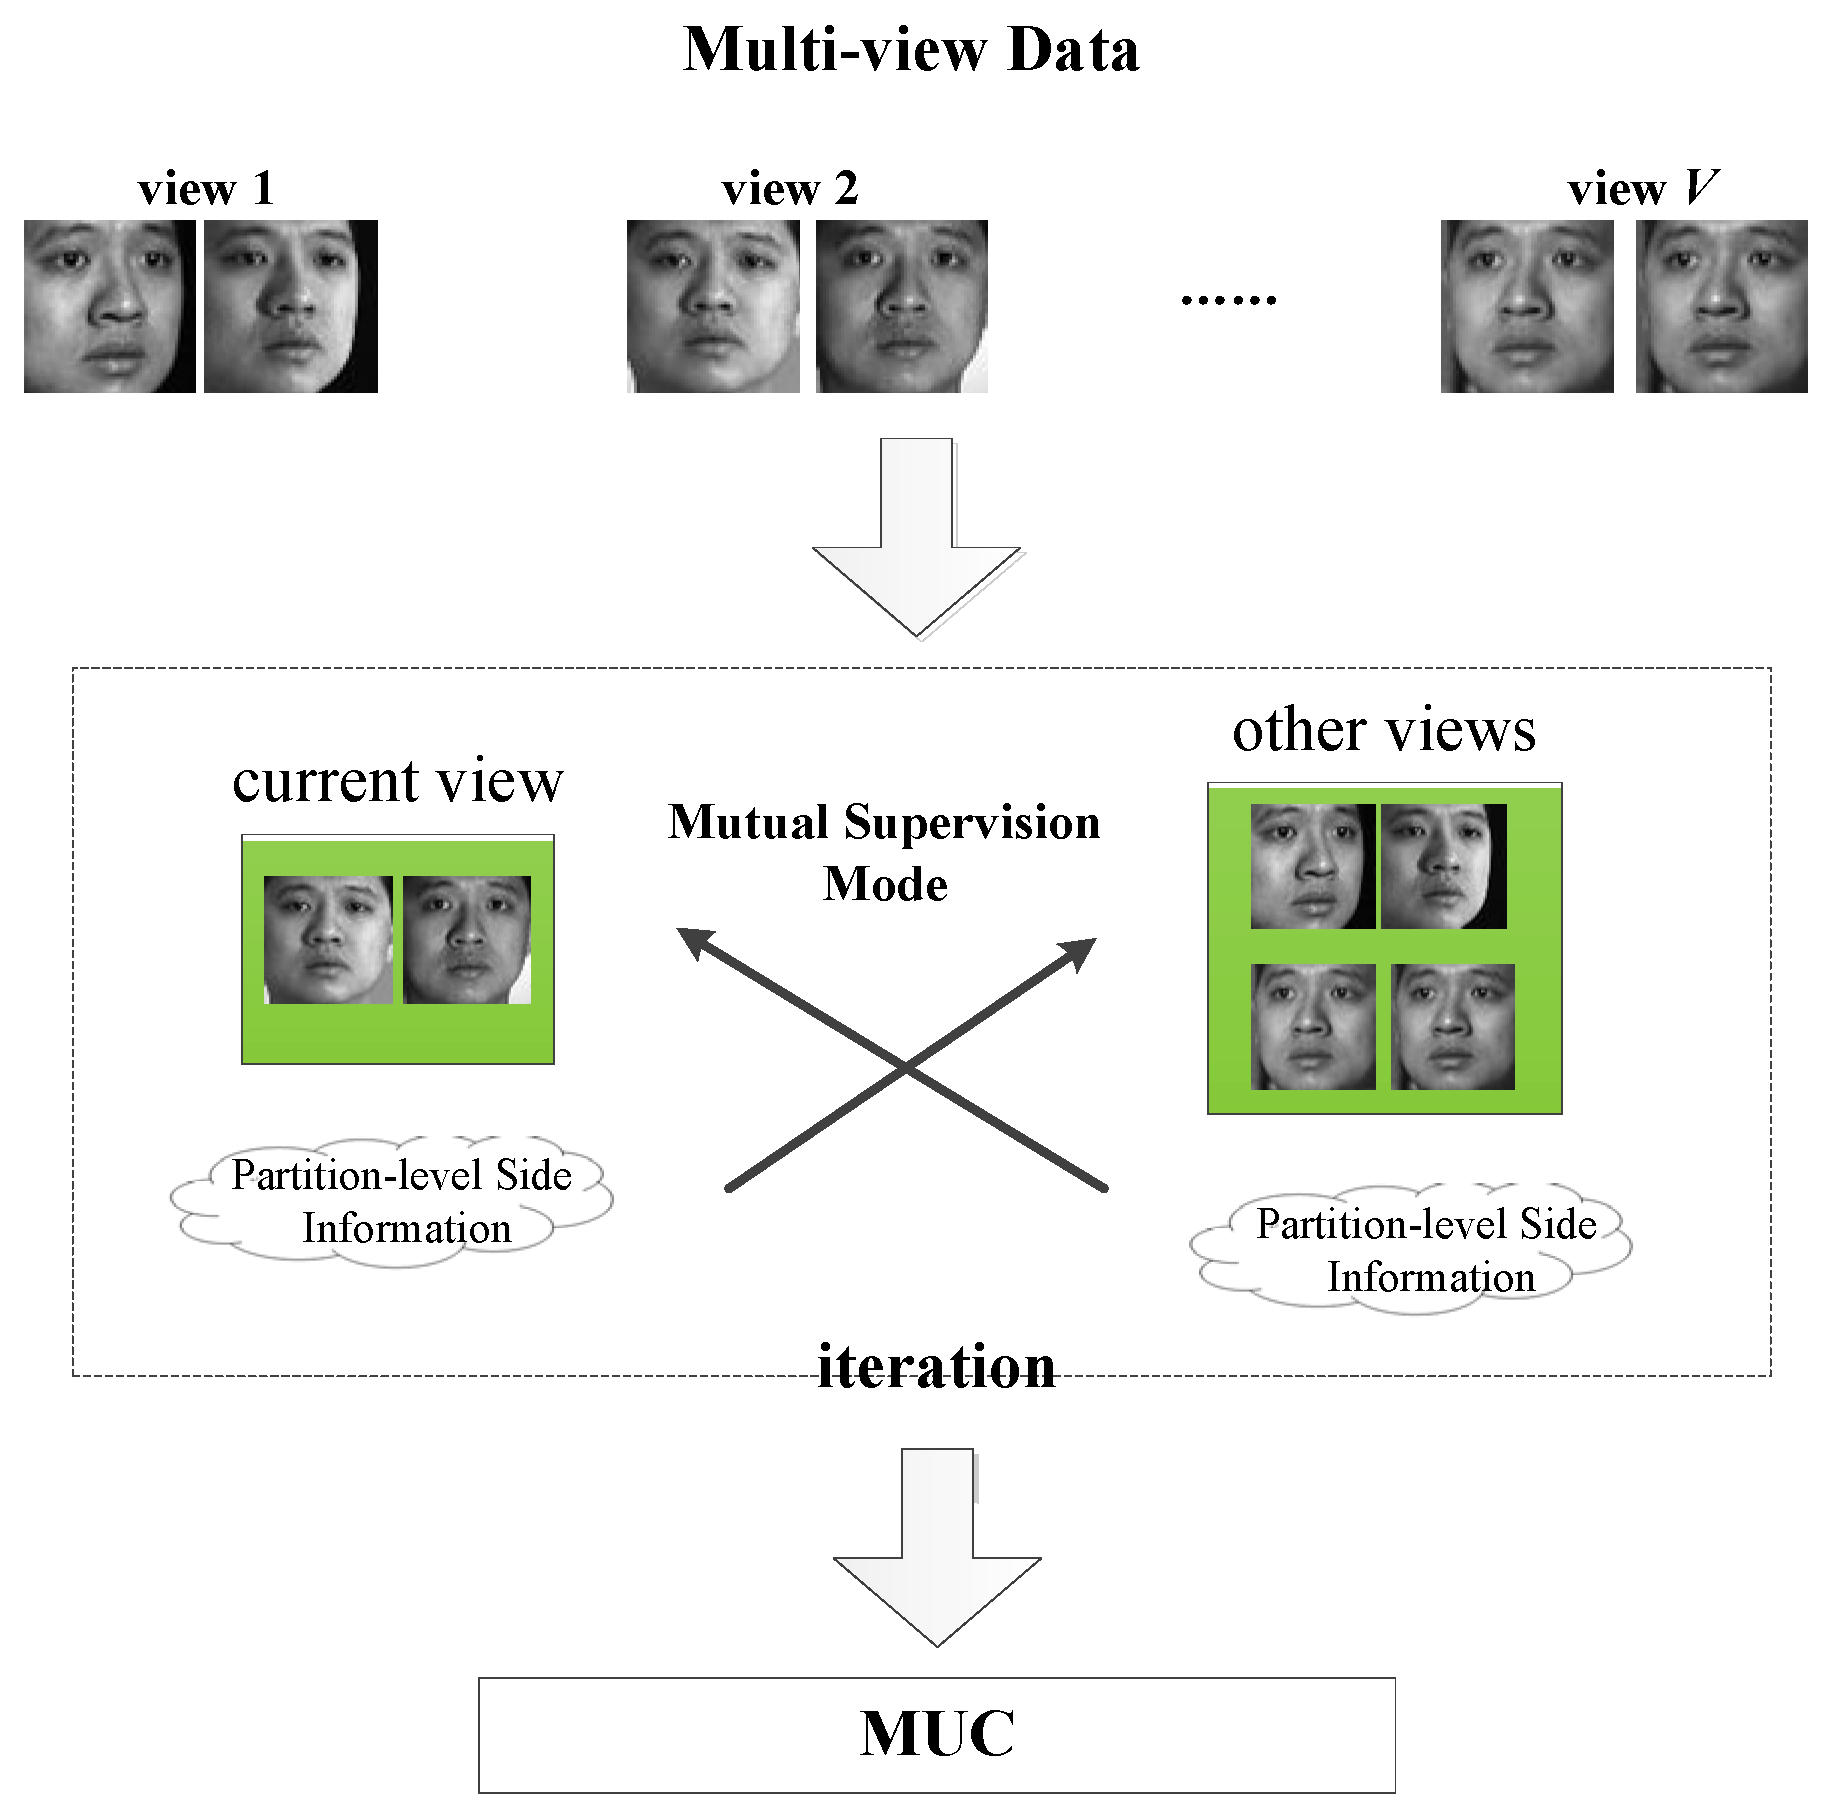
Furthermore, as is well known, different views have different forms of expression and provide different information, so they may have differing impacts on the final clustering. Therefore, in addition to the proposed novel use of multi-view utility-based partition-level side information, we also anticipate important evaluations of each view. Inspired by the weighted clustering algorithms presented in [15], we leverage multi-view weight learning based on maximum entropy to integrate multiple results and further improve clustering performance. In this study, considering the above two multi-view clustering issues, we propose a multi-view clustering method, namely the multi-view utility-based clustering method (MUC), presented from the novel perspective of mutual supervision between different views. The extensive experimental results on various multi-view datasets indicate that the proposed MUC is better than—or at least comparable to—the existing commonly used single view and multi-view clustering methods, in both performance and running speed. Figure 2 illustrates the framework of the proposed MUC method.
Figure 2.
The framework of the proposed MUC method.
The main contributions of this study are as follows:
- (1)
- The proposed MUC method moves multi-view clustering from the level of feature and/or sample side information to that of the partition. By leveraging the proposed utility-based partition-level side information, the clustering process of MUC is more consistent with human thinking; it is higher-caliber and more instructional than that of sample or feature-level side information-based multi-view clustering.
- (2)
- While existing multi-view clustering methods share the benefits of mutual supervision learning in a co-trained and/or -regularized way, the proposed MUC method achieves a novel mutual supervision mode for first guiding the clustering of each view, in the sense of utility-based partition-level side information, for combining multi-view results. The distinctive merit of such a mutual supervision mode is that, using an alternating optimization strategy, the objective function of MUC can be solved in a K-means-like way. Our theoretical analysis indicates that MUC can guarantee an enhanced multi-view clustering performance.
- (3)
- In addition, based on the maximum entropy, the proposed MUC method considers the weight learning of each view, so as to further improve multi-view clustering performance.
- (4)
- Extensive experimental studies on various multi-view datasets justify the effectiveness of the proposed MUC method, in contrast to the existing commonly used single-and multi-view clustering methods.
2. Related Works
In clustering research, efforts have been focused on multi-view clustering in order to generate better results. In what follows, we will briefly introduce related multi-view clustering methods from the perspective of the three granulation levels of the side information used for multi-view clustering [16,17], i.e., feature-, sample- and partition-level side information. The related studies are summarized in Table 1.
Table 1.
Related studies of three levels of side information.
Feature-level side information-based methods usually mine this information from multiple views, obtaining the resultant multi-view clustering results according to a specific combination strategy. Typical methods concatenate multiple views into one, either by directly juxtaposing the feature sets or indirectly combining the proximity matrices obtained from different views. For example, Bickel and Scheffer [7] first extended the co-EM algorithm to the general multi-view EM algorithm, before developing a variety of two-view EM and spherical K-means algorithms. Kailing et al. [18] extended DBSCAN as a multi-view version. The authors of [19] proposed two-view spectral clustering, assuming that each view is independent. Zhou and Burges [20] integrated the general single-view normalized cut of multiple views and proposed a multi-view spectral clustering algorithm. In addition, some hidden feature space-based multi-view clustering methods [21,22,23,24] also belong to this class. These methods use several feature transformation techniques [21,22,23,24] to search for the hidden feature space for multiple views; this includes canonical correlation analysis (CCA), sparse subspace clustering and non-negative matrix factorization (NMF). Then, these methods mine the additional information from the original or hidden feature for multi-view clustering.
Sample-level side information-based methods usually mine this information by, for example, restricting the consistency of cluster centers. Among these methods, some methods first cluster the samples from individual views separately, before finding a solution to express a consensus among the clustering sets. For example, with the help of a distributed framework, Long et al. [25] proposed a general model for multi-view clustering. Greene and Cunningham [26] used a late integration strategy to derive their multi-view clustering algorithm for multi-view data. Other methods utilize multiple views simultaneously and in a collaborative way, in order to ascertain multi-view dataset clusters. For example, Pedrycz [27] proposed the collaborative clustering method, CoFC, based on FCM for multi-view data, introducing a family of collaborative fuzzy matrices whose elements describe the intensity of interactions between views. Cleuziou et al. [11] developed the multi-view collaborative fuzzy clustering algorithm, CoFKM. Jiang et al. [13] introduced view weights into Co-FCM, deriving the multiple weighted view Co-FCM algorithm, WV-Co-FCM. These methods utilize the consistency of multi-view clustering centers to mine more sample-level information.
When we move from sample- or feature-level side information to a higher granulation level, partition-level side information-based methods should attempt to mine additional information directly from the whole partitions—which are generated individually in each other view—to guide current view clustering. In this regard, Han et al. [28] achieved current view clustering in a self-supervised way by identifying nearby samples in the other view as positive samples; in this way, they avoided positive samples of the same class being treated as false negative current view samples, or vice versa. Kang et al. [29] proposed a unified multi-view subspace clustering model, incorporating graph learning from each view, basic partition generation, and consensus partition fusion. Wang et al. [30] proposed a novel multi-scale deep multi-view subspace clustering (MDMVSC) method, which unifies the multi-scale learning module, self-weighting fusion module and structure preserving constraint. Lan et al. [31] proposed a novel MVSC via low-rank symmetric affinity graph to mine the consistent information and angular information of different views.
Unlike the above methods, this study attempts to first take utility-based partition-level other view side information as the auxiliary supervised information in a mutually supervised way to guide current view clustering.
3. Multi-View Utility-Based Clustering: A Mutually Supervised Perspective
In this section, we first introduce the concept of utility-based partition-level side information from other views. Then, we propose the multi-view clustering MUC method, leveraging the utility-based partition-level side information in mutual supervision mode. The corresponding solution is also derived. Theoretical discussions and details regarding computational complexity are also contained in this section.
3.1. Utility-Based Partition-Level Side Information from Other Views
According to the concept of partition-level side information outlined in Section 1, the entirety of this information generated from other views can be naturally taken as supervised information and used to guide current view clustering. In contrast to the classical feature- and/or sample-level side information, partition-level side information is more consistent with human thinking, in that it is higher-caliber and more intuitive and instructional for clustering. In order to leverage the partition-level side information from other views to help current view clustering in a mutually supervised way, we define utility-based partition-level side information from other views, based on the concept of categorical utility function [32,33], as follows.
Definition 1.
Given the total number K of clusters, the partition of current view v denoted by the corresponding indicator matrix , for current view dataset containing n objects, we can take the partition on all the other views as the partition-level side information for current view . Note that is generated by averaging or majority-voting on the whole data partitions from all the other views. Then we term the categorical utility functions as the utility-based partition-level side information for current view .
To clearly understand , we introduce the contingency matrix in Table 2 in which K clusters, denoted as and (j = 1, 2, ⋯⋯, K) are assumed in and , respectively. Let denoted the number of objects belonging to both the cluster centroids matrix in and the cluster centroids matrix in , and , . Let , and , we have a normalized contingency matrix and accordingly can define a variety of utility functions. In this study, we prefer to adopt the following widely used category utility function:
Table 2.
Contingency matrix.
Note that the last term in Equation (1) is a constant when the partition-level side information is given. Since the same objects are always described by multi-view datasets, we should make the two partitions and as same as possible, which actually means that we should manage to maximize the utility-based partition-level side information . In order to conveniently utilize the for multi-view clustering, we prove the following theorem.
Theorem 1.
Given the utility-based partition-level side information , we have
where , is the kth row of .
Proof.
According to the Lemma 1 in [33], is the K cluster centers of the binary partition , where is the kth row of . Obviously, the right-hand-side of Equation (2) is the standard K-means on the binary partition . The generalized form can be expressed as:
where is ith row of the binary partition , is the kth center, denotes some distance function from a data point to a center. Here we take as the Bregman divergence [34] which is a family of distance measures fitting the classic K-means. That is, can be defined as:
where is a differentiable strictly-convex function.
Substituting Equation (4) into Equation (3), we have
Since both and n are constants for the binary partition , we have
According to the definition of in Equation (1), we can readily express it as
which means
By Equation (6) and Equation (8), we have
Therefore, Theorem 1 holds true. □
According to Theorem 1, given , the equivalent relationship between and holds on for the vth view, since . In other words, one extra variable is introduced to capture the mapping relationship from to .
3.2. MUC
3.2.1. Objective Function of MUC
Based on the above discussion about utility-based partition-level side information, we designed the following objective function for the proposed MUC method:
where the value of denotes whether the ith sample belongs to the kth cluster or not; is the weight of the vth view; and are two trade-off parameters; and V is the number of views.
The above objective function in Equation (10) consists of three terms. The first corresponds to the objective function of the standard K-means [35] with squared Euclidean distance for each weighted view. The second reflects mutual supervision by maximizing the utility-based partition-level side information . The third considers the well-known Shannon entropy-based weighting scheme to weigh each view. We attempt to search for a solution, , which not only captures the intrinsic structural information from the original objects, but also agrees as much as possible with the partition-level side information, .
Remark 1.
The trade-off parameter is used to control the influence of the Shannon entropy about the weight of each view. In general, we may set it to follow [13]. The trade-off parameter as the utility-based information regulation coefficient is used to control the utility-based effect of other views on current view. The bigger its value is, the more effect of the utility-based information from other views.
According to Theorem 1, we can leverage the utility-based partition-level side information in an efficient manner. This means that we can revisit the objective function in Equation (10) from the following new insight:
In order to further justify the above objective function of MUC, we have the following analyses and explanations.
Remark 2.
MUC leverages the additional utility-based partition-level side information in a mutually supervised way. Such a leverage can be conveniently and directly realized in Equation (11) for multi-view clustering. Please note, when handling multi-view (more than two views) datasets,
in Equation (11) can be obtained by averaging or majority-voting on the data partitions generated by some clustering methods for all the other views.
Besides, the following Theorem 2 will reveal that MUC has a theoretical guarantee of enhanced multi-view clustering.
Theorem 2.
The leverage of utility-based partition-level side information in the mutual supervised way in Equation (11) can guarantee enhanced multi-view clustering performance.
Proof.
By following Theorem 1, we can get:
For the multi-view data , the above transformations are equivalent to expanding the corresponding dimensions, that is, corresponds the data of the vth view. Please note, and are actually the partitions of the multi-view datasets which describe the same objects.
After the above transformation, according to Equation (11), in the same cluster, any two samples and have the same expansion component after expanding the dimensions, so (the distance of the two samples and ) will not change after expanding the dimension; while in different clusters, any two samples and have different expansion components, so increases after expanding the dimensions. Therefore, the margins of samples in different clusters will be larger while those of samples in same clusters keeps unchangeable. Therefore, in such a way, the performance of multi-view clustering will be improved. In other words, Theorem 2 holds. □
3.2.2. Solution of MUC
In this subsection, we attempt to optimize the objective function of MUC. The proposed objective function in Equation (11) can clearly be transformed into two subproblems: multiple clustering and weight learning; these can be solved in alternative ways. That is to say, we update one by keeping the other fixed, repeating this process until convergence is achieved. The optimization process can be more concretely summarized as follows.
(1) Update with , , and fixed. Equation (11) can be expressed as follows:
where
In order to make Equation (13) unconstrained, we express its Lagrange function as follows:
where is the Lagrange multiplier. By setting the derivative of L w.r.t to zero for each view, we obtain
In order for the KKT condition to be met [36], we substitute Equation (15) into the constraint , finally obtaining the following optimal weight for each view:
(2) Update , and with fixed . Equation (11) can equally be converted as follows:
It is obviously not possible to update all variables directly to solve this subproblem. We can generally adopt an alternative optimization technique [37] with a closed solution in each iteration. Although such a solution can be adopted for simplicity, it becomes inefficient due to matrix multiplication and inversion. Furthermore, because MUC is designed for multiple views, the data are divided into too many fractured pieces; in practice, this makes operation difficult. In order to confirm the above novel mutual supervised learning mechanism, the subproblem of the current vth view in Equation (18) should be converted as follows:
Then, the subproblems in Equation (19) are alternately solved on multiple views until the objective function value in Equation (18) remains unchanged.
According to [15], the above subproblem in Equation (19) can be solved very efficiently in a mathematical way. Below the above subproblem can be equivalently transformed into a K-means-like optimization problem by concatenating the utility-based partition-level side information with the original objects, which actually implies that Equation (19) has the distinctive merit in the sense that it can be solved in K-means-like way.
We introduce the auxiliary matrices of the vth view, respectively, as follows
Because the partition-level side information is utilized to guide clustering in utility-based way, the centroids of K-means clustering becomes no longer the mean of the samples belonging to a certain cluster. Let be the kth expanded centroid of the vth view:
Let us recall that in the standard K-means clustering, the centroids are calculated by arithmetic means, and its denominator denotes the number of objects in its corresponding cluster. Based on the above mathematical transformation, we finally transform Equation (19) as a K-means-like problem in Equation (22),
which can be handy solved by the existing standard K-means solver.
So far, we alternately update , , and by optimizing the corresponding subproblems until Equation (4) becomes converged. Note that the proposed MUC utilizes the utility-based partition-level side information in a mutual supervision mode. After obtained from other views by a classical K-means algorithm, the utility-based partition-level side information is used as the auxiliary supervised information to guide clustering of current view, and then the resultant clustering results of current view will be taken as the auxiliary partition-level information for clustering of the other view. Such a mutual supervision procedure will be carried out alternately until certain termination criterion are met.
Based on the above-mentioned descriptions and analysis, the implementation of MUC is summarized in Algorithm 1.
| Algorithm 1: MUC |
| Input: The multi-view dataset , where . The random initialization of partition . The total number K of clusters. The convergence threshold . The parameters and . |
| Output: Final partition matrix H. |
| Procedure: |
| 1: Generate the auxiliary matrices of each view according to Equation (22), where the partition-level side information is generated by averaging or majority-voting on the whole data partitions from all other views |
| 2: while not converge do |
| 3: Randomly select K expanded centroids of each view ; |
| 4: Compute the distance matrices of each view by Equation (14) |
| 5: Update for each view by Equation (17) |
| 6: repeat |
| 7: Update the partition of the vth view by Equation (23) |
| 8: Update the centroids of the vth view by Equation (24) |
| 9: Carry out step 7~step 8 alternately on each view. |
| 10: until the change value of the objective function in Equation (22) between two iterations is smaller than |
| 11: end while |
| 12: Output the final partition matrix H obtained by averaging or majority-voting on the partitions of all views. |
3.3. On Computational Complexity
In this subsection, we discuss the computational complexity of Algorithm 1.
According to the above optimization process, the whole computational complexity of Algorithm 1 can be divided into two parts to discuss. The first part deals with step 4~step 5, computational complexity of computing is about . Thus, the total computational complexity for this part is about , where K is the total number of clusters, n and are the total numbers of instances and features in , respectively. The second part deals with step 6~step 10, which can be readily solved by a K-means-like optimization. Hence, the second part shares almost the same computational complexity with standard K-means, i.e., , where is the total number of inner loops. Let be the total number of the outer loops in the algorithm; we immediately derive that its whole computational complexity becomes times the sum of the first and second parts, i.e., .
4. Experimental Studies
In this section, we present our extensive experimental results on various multi-view datasets, i.e., one synthetic, seven multi-view UCI and two real-life image datasets, to verify the performance of the proposed MUC method. We likewise present a comparative study with two commonly used single-view clustering methods, i.e., K-means [35] and ComBKM [38], and six state-of-the-art multi-view clustering methods, i.e., Co-FKM [11], MVKKM [12], MVSpec [12], WV-Co-FCM [13], TW-K-means [9], and MVASM [10]. These were assessed according to the two clustering performance indices, NMI and RI, for ten runs. The experiments were conducted using MATLAB R2016a on a computer with Intel Core i5-3317 1.70 GHz CPU and 16 GB RAM.
4.1. Datasets
4.1.1. Synthetic Dataset
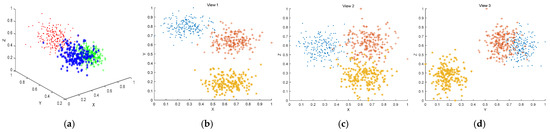
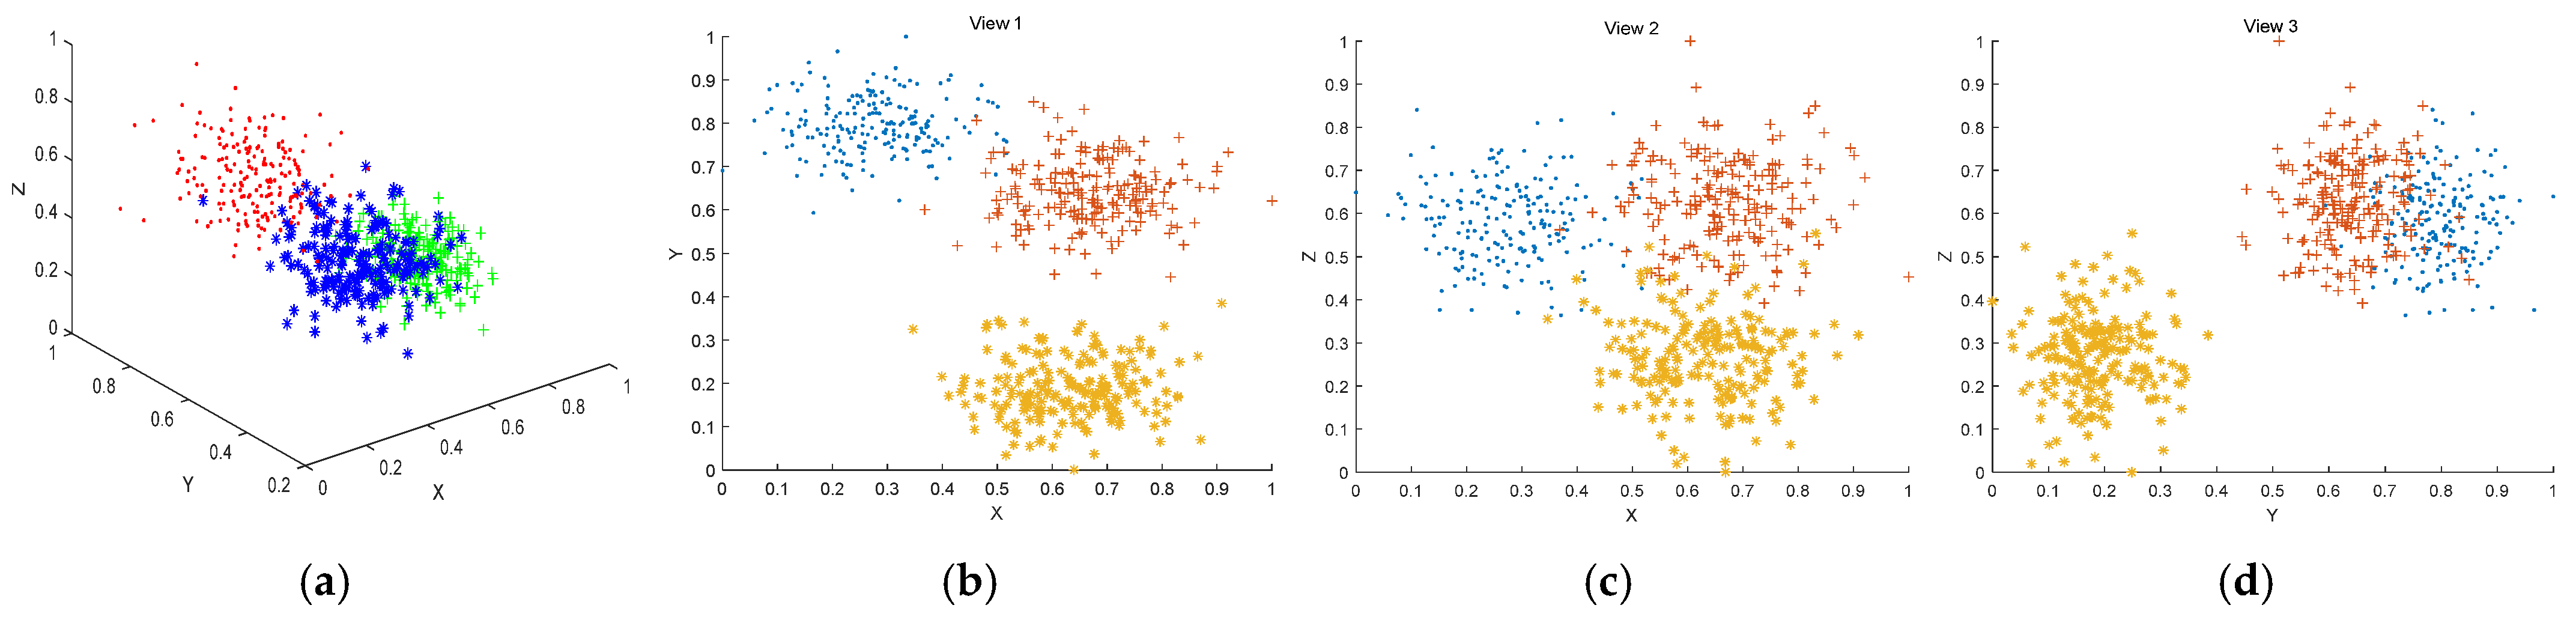
In this study, we construct a three-dimensional synthetic dataset that contains three clusters with a total of 600 samples (200 samples per cluster). In order to generate different multi-view datasets, we map the synthetic one into 2D subspaces. The 3D original synthetic dataset, and its corresponding 2D equivalents, are shown in Figure 3.
Figure 3.
Synthetic dataset (three different colored dots represent three clusters in each sub-figure). (a) Original 3-D dataset and (b) view 1 (X, Y), (c) view 2 (X, Z), and (d) view 3 (Y, Z) datasets.
4.1.2. UCI Datasets
Seven multi-view datasets from the frequently used UCI [39] data repositories, of which details are listed in Table 3, were adopted in the experiments.
Table 3.
Multi-view datasets from UCI used in the experiments.
4.1.3. Real-Life Image Datasets
- (1)
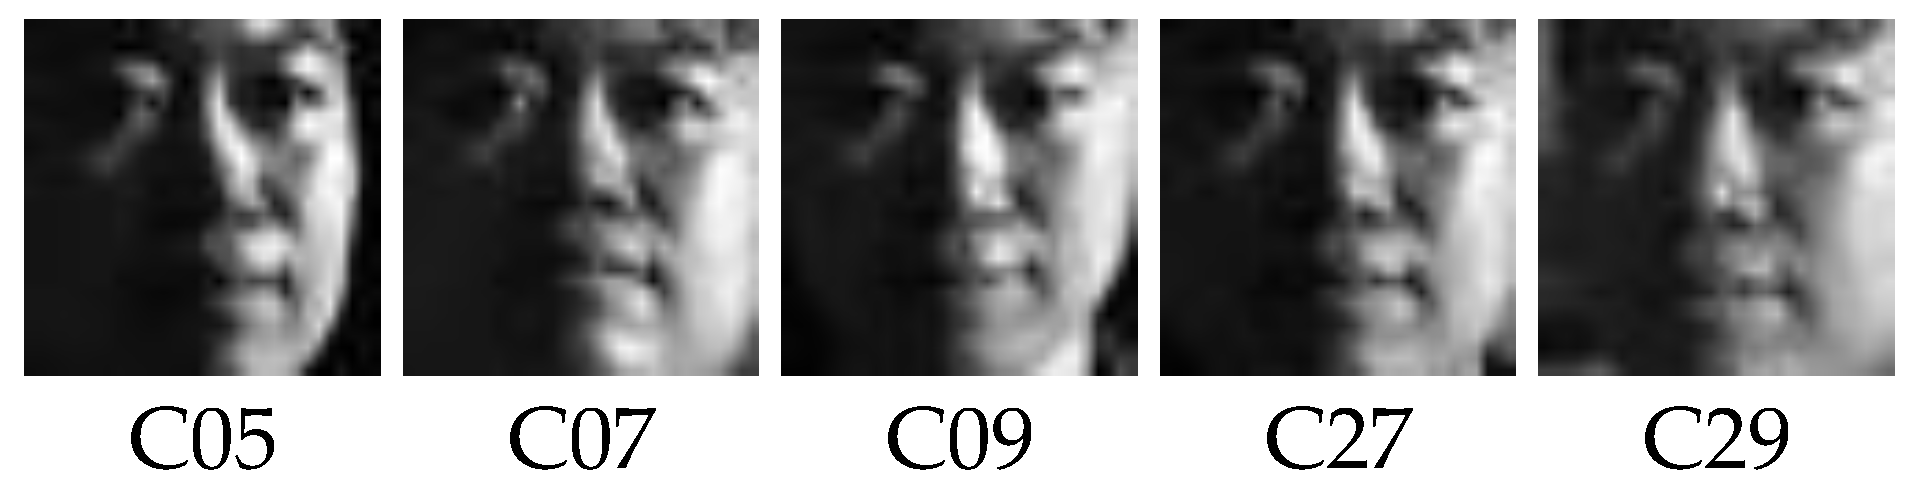
- The CMU PIE image dataset [40] consists of a total of 41,368 facial images (64 × 64 in pixels) from 68 persons. The common versions of CMU PIE consist of five poses (views), i.e., C05 (left), C07 (upward), C09 (downward), C27 (frontal), and C29 (right), as organized by Deng Cai. In each view, 120 images of five different persons are randomly selected. Figure 4 illustrates images of one person from these five views. In order to make full use of the CMU PIE image dataset, we generate five combinational multi-view datasets (i.e., D1, D2, D3, D4 and D5) of the above five views, the details of which are listed in Table 4.Figure 4. Facial images of one person from five views.Table 4. Multi-view datasets from CMU PIE image dataset used in the experiments.
- (2)
- The AwA image dataset [41] consists of 30,475 images of 50 animals with six pre-extracted feature representations (views) each. In this study, we randomly select eight classes (5133 images) for experiments.
4.2. Evaluation Criteria
In this study, we take the following two commonly used evaluation criteria, i.e., the Normalized mutual information (NMI) [13] and Rand index (RI) [9], to evaluate the clustering results. These are defined as follows:
Normalized mutual information (NMI)
Rand index (RI)
where
For a dataset with N objects, Nij denotes the number of common objects between cluster i generated by an approach and the jth ground-truth category. Ni and Nj denote the numbers of objects in cluster i and cluster j, respectively. Note that the values of NMI and RI are from [0, 1] and , respectively. The higher their values, the better the performance of the corresponding clustering method.
4.3. Adopted Methods and Parameters Settings
We experimentally compared MUC with two commonly used single-view clustering methods, i.e., K-means [35] and ComBKM [38], and six state-of-the-art multi-view clustering methods, i.e., Co-FKM [11], MVKKM [12], MVSpec [12], WV-Co-FCM [13], TW-K-means [9], and MVASM [10]. For K-means and ComBKM, single-view datasets were directly generated by combining features from all views. Following the guidelines presented in [9,11], and [13], and according to our extensive experiments, we used the grid search strategy to determine the appropriate parameters involved in all the adopted methods. The parameter settings for all these clustering methods are given in Table 5.
Table 5.
Parameter settings of all the adopted methods.
4.4. Experimental Results
4.4.1. Synthetic Dataset
We used the proposed MUC and seven other methods on the synthetic dataset to examine effectiveness in improving multi-view clustering performance, utilizing utility-based partition-level side information in a mutually supervised manner. The clustering results are shown in Table 6 and Table 7, where the best results are highlighted in bold. Please note that the last two rows these tables list the overall average NMI (or RI) and Std. of each adopted method across all views.
Table 6.
NMI of all the adopted methods on the synthetic dataset.
Table 7.
RI of all the adopted methods on the synthetic dataset.
From these two tables, we can see that the performances of multi-view clustering methods, i.e., Co-FKM, MVKKM, MVSpec, WV-Co-FCM TW-K-means, MVASM and MUC, are obviously superior to those of single-view equivalents, i.e., K-means and ComBKM, in terms of both NMI and RI. The reason for this is that, although single-view clustering methods are capable of clustering multi-view data using all the available features, they are not specifically designed to effectively cluster several subsets of the available features.
Another observation is that the proposed MUC method performs best among all the adopted methods in terms of overall average performance. This means that mutual supervision based on utility-based partition-level side information can effectively guide clustering for each view and improve the final multi-view clustering performance.
4.4.2. UCI Datasets
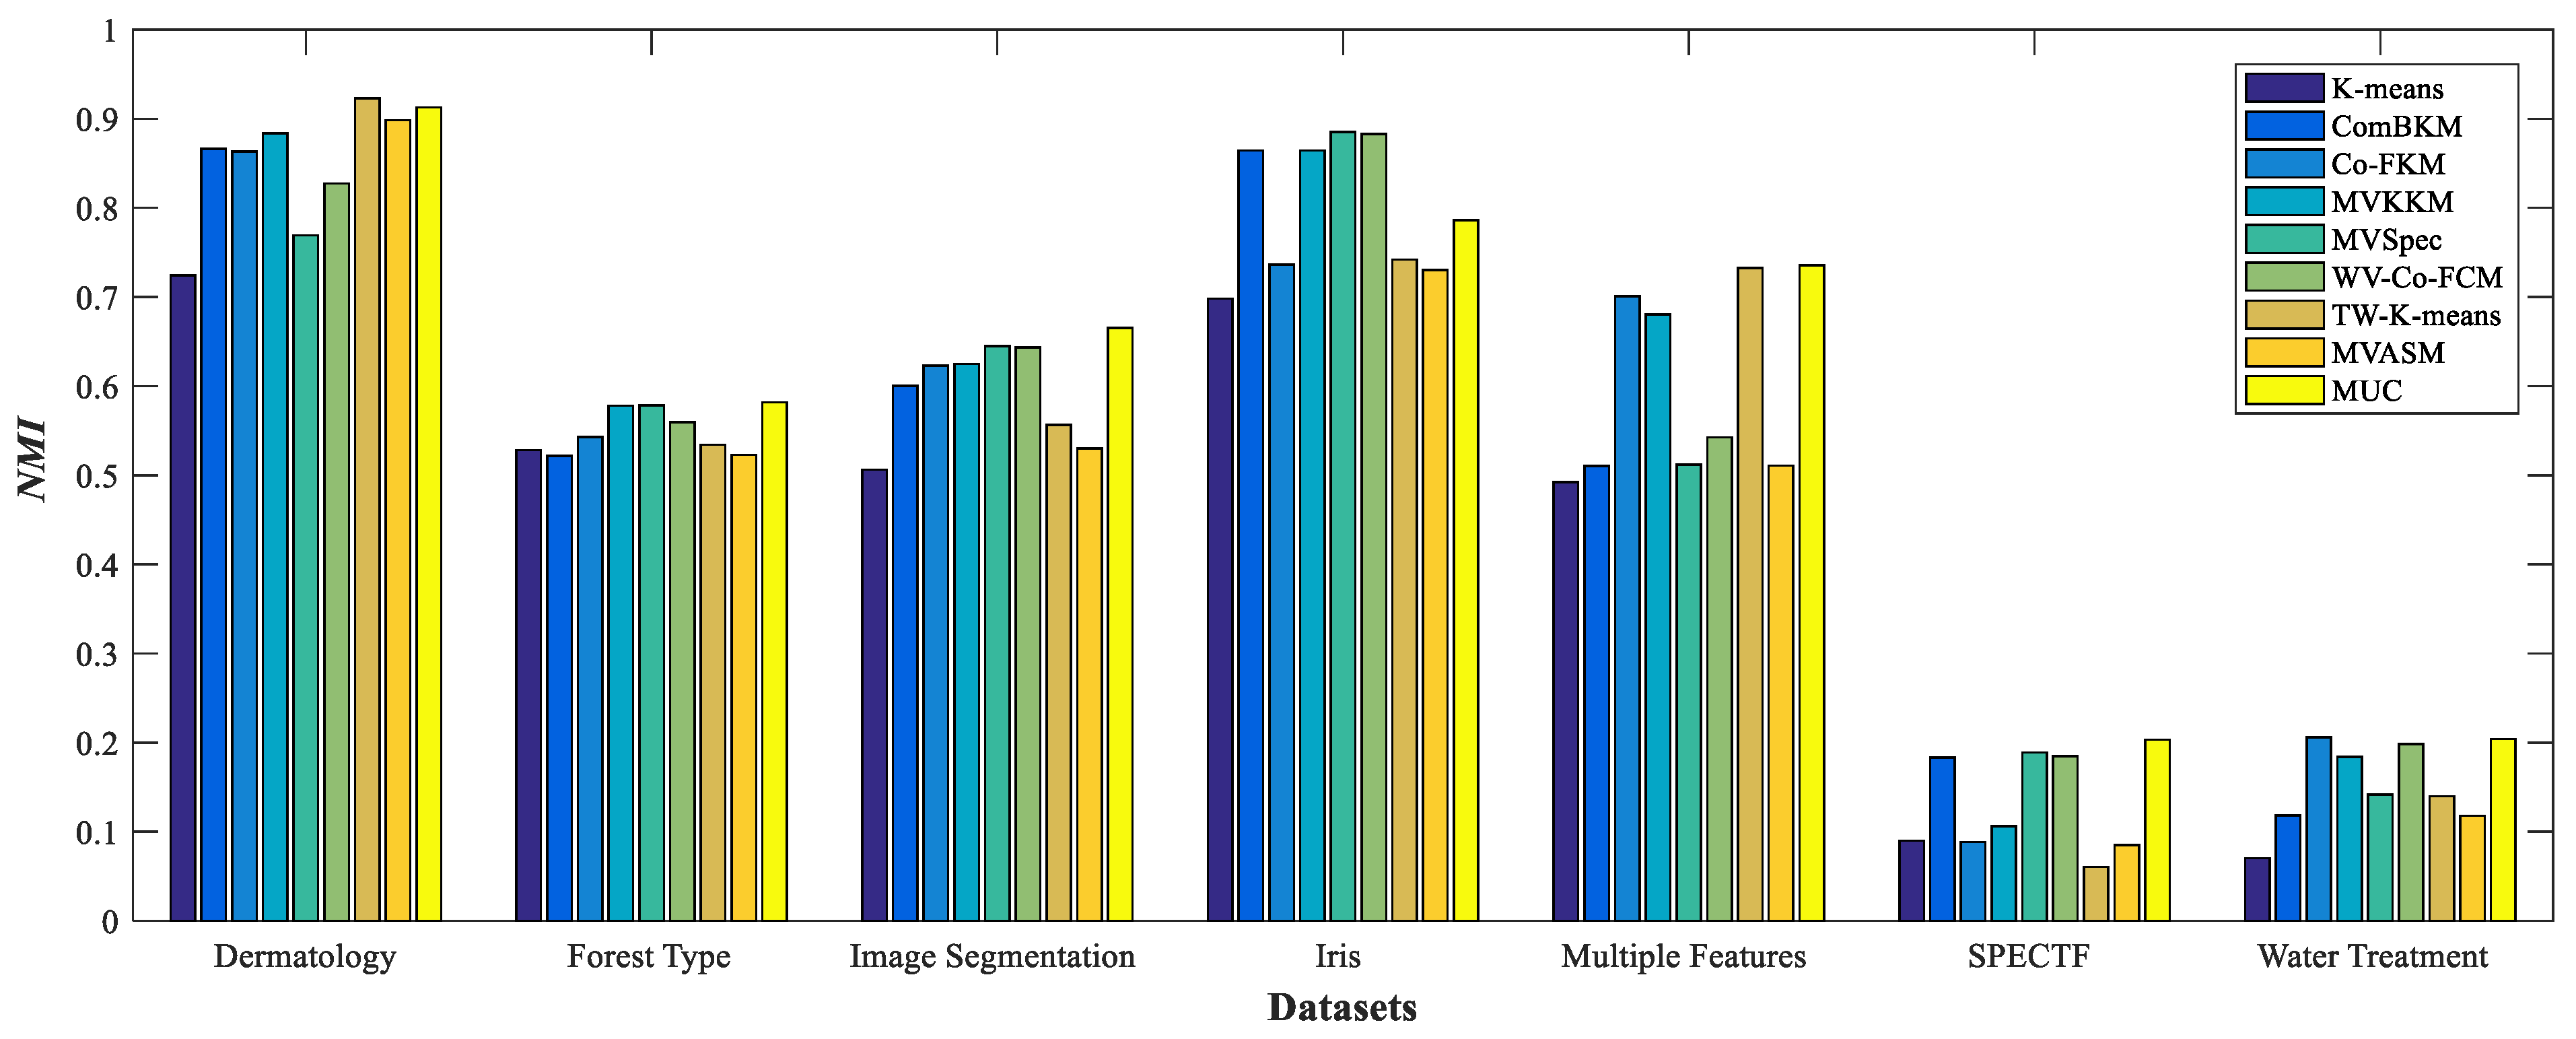
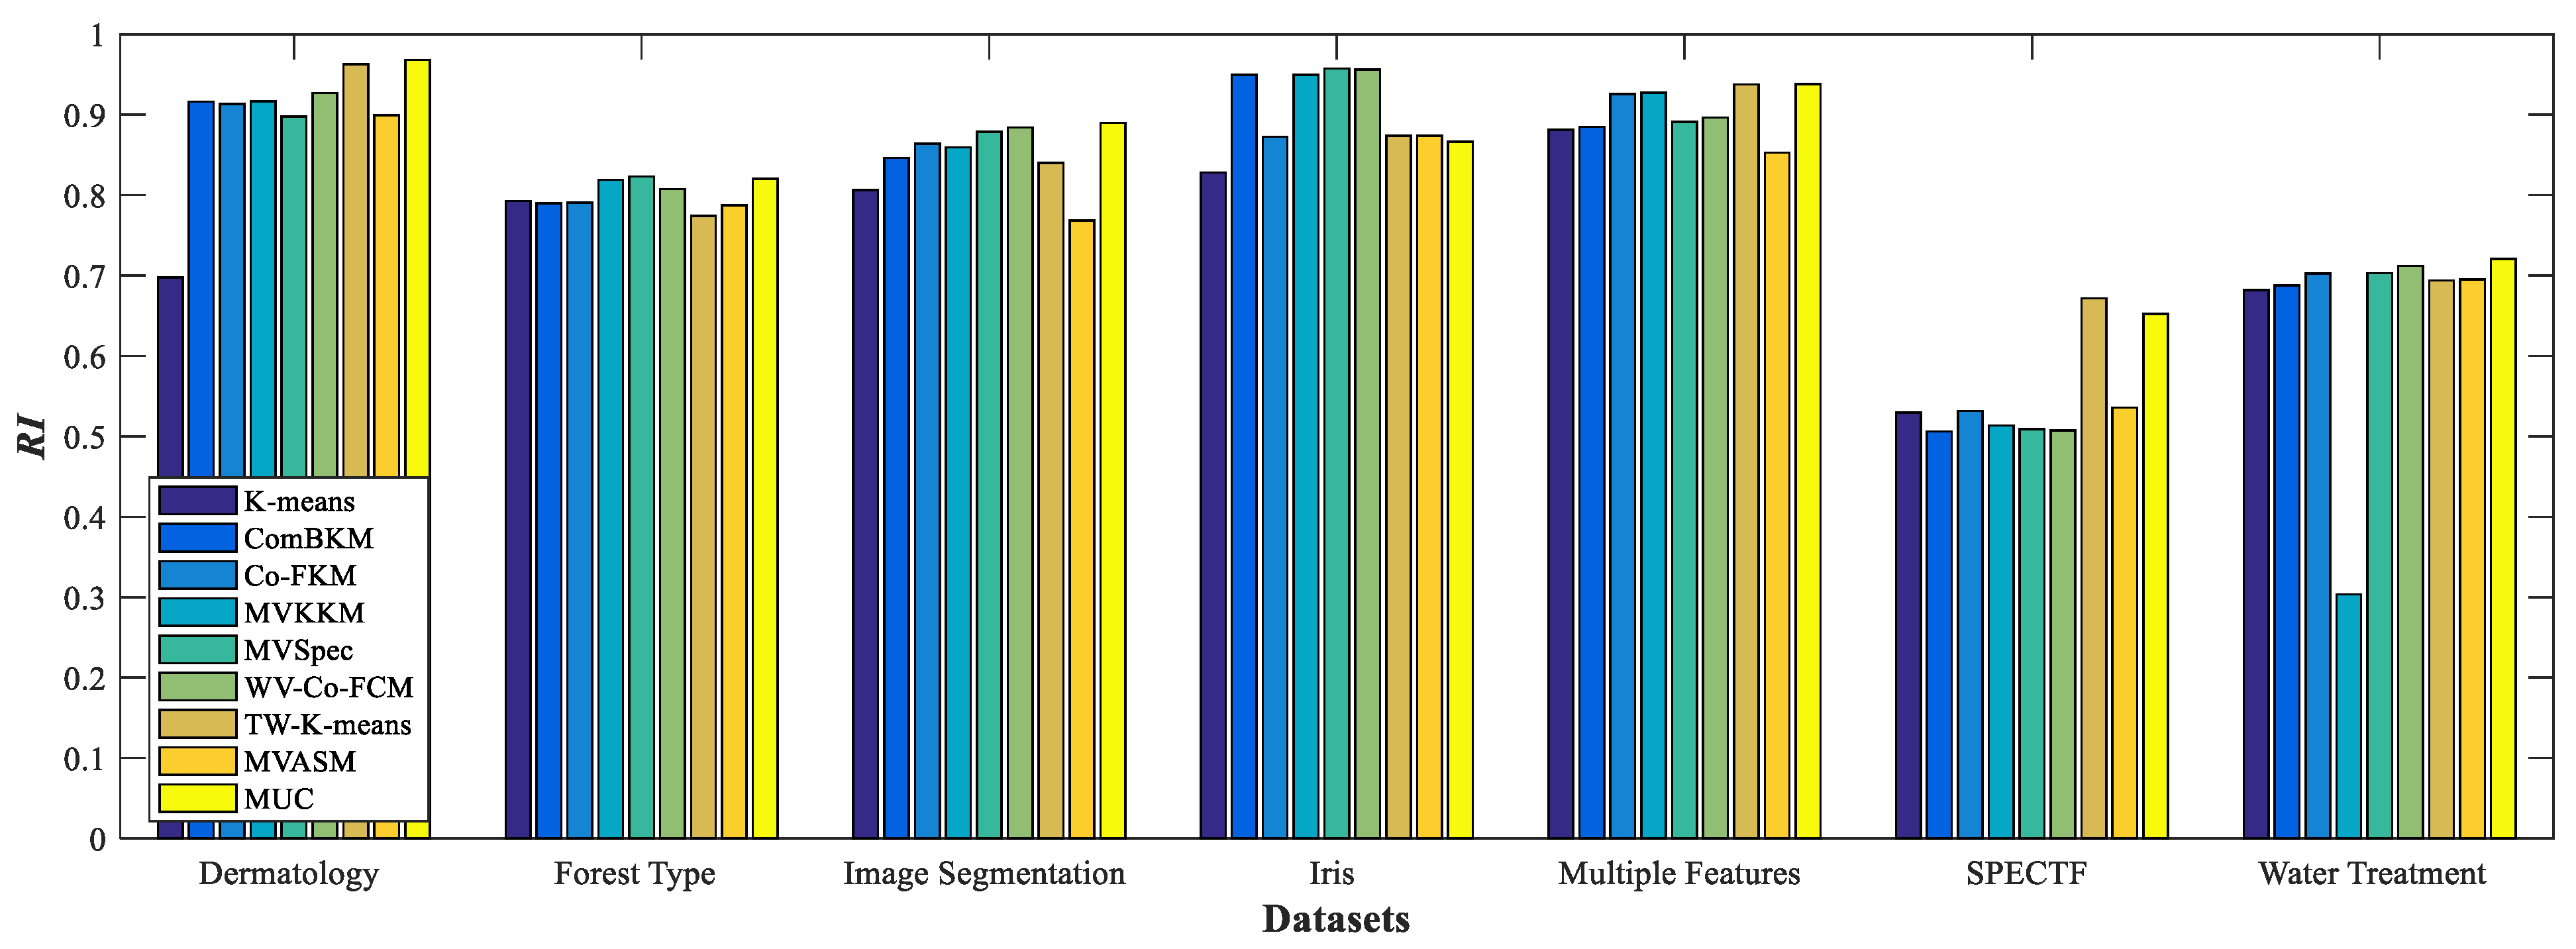
The clustering performance of the proposed method was experimentally evaluated on the seven multi-view datasets from the UCI repository. The corresponding clustering results, in terms of the mean and standard deviation of NMI and RI, are shown in Figure 5 and Figure 6. We can draw the following conclusions.
Figure 5.
NMI of all the adopted methods on the seven UCI datasets.
Figure 6.
RI of all the adopted methods on the seven UCI datasets.
- (1)
- In general, the performances of the seven multi-view methods, i.e., Co-FKM, MVKKM, MVSpec, WV-Co-FCM, TW-K-means, MVASM and MUC, are superior to those of the two single-view clustering methods, K-means and ComBKM.
- (2)
- The proposed method, MUC, clearly performs best on all the seven multi-view datasets in terms of overall average NMI and RI, demonstrating the benefit of multi-view clustering from mutual supervision based on utility-based partition-level side information. In terms of NMI and RI, the proposed MUC method is not always significantly superior to WV-Co-FCM or TW-K-means on every dataset (see, for example, Dermatology); however, it remains a very close second. The possible reason for this is that this dataset is so easy to cluster; as such, additional utility-based partition-level side information does not play a crucial role in enhancing the corresponding multi-view clustering performance.
- (3)
- An additional meaningful observation is that the weights of two views vary considerably on some datasets, such as SPECTF. This is possibly because view features are very different. That is, the amount of effective feature information provided by two views is different. Moreover, the degree of separability of the data from different views is different.
4.4.3. Real-Life Image Datasets
In this subsection, the proposed MUC is experimentally compared against other methods on the two real-life image datasets. The results for these multi-view image datasets are reported in Table 8, Table 9 and Table 10. Please note that, as with the five-view dataset, CMU PIE, we adopted an averaging strategy across whole data partitions from all the other views.
Table 8.
NMI of all the adopted methods on the CMU PIE dataset.
Table 9.
RI of all the adopted methods on the CMU PIE dataset.
Table 10.
NMI and RI of all the adopted methods on the AWA dataset.
According to Table 8, Table 9 and Table 10, all the multi-view clustering methods outperform the single-view equivalents, K-means and ComBKM, on two real-life image datasets. Furthermore, MUC maintains the best results in terms of the overall average NMI and RI values, owing to the use of both utility-based partition-level side information and the multi-view mutual supervision mode. Although the proposed MUC method performs slightly unsatisfactorily, and even worse in terms of RI, its clustering performance remains comparable to those of multi-view methods.
4.4.4. Statistical Analysis Results
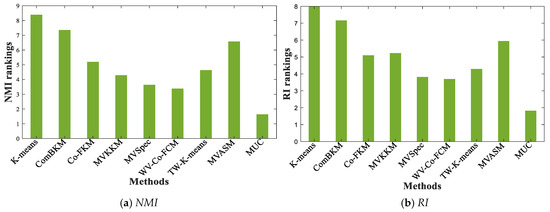
In addition, we conducted the Friedman test [42] for statistical analysis, observing significant performance differences between the proposed MUC and other adopted methods. First, as shown in Figure 7, we calculated the average performance rankings of all the adopted methods on all datasets in terms of NMI and RI. The proposed method, MUC, clearly ranks the highest, which means that it performs best.
Figure 7.
Rankings of all methods (Friedman test): (a) NMI; (b) RI.
Then, we conducted a post hoc hypothesis test to assess performance differences between MUC and other adopted methods. The obtained post hoc comparison results () are presented in Table 11 and Table 12, respectively, in terms of NMI and RI. Please note that we have ordered all the adopted methods (except the proposed MUC) according to the z-value obtained from the post hoc hypothesis test. The null hypothesis is clearly rejected when (or ) because . It can be seen from Table 11 and Table 12 that there are significant performance differences between MUC and other adopted methods in terms of NMI or RI, which indicates that our proposed method is very effective in multi-view clustering.
Table 11.
Post hoc comparison of NMI for .
Table 12.
Post hoc comparison of RI for .
4.4.5. Sensitivity Analysis
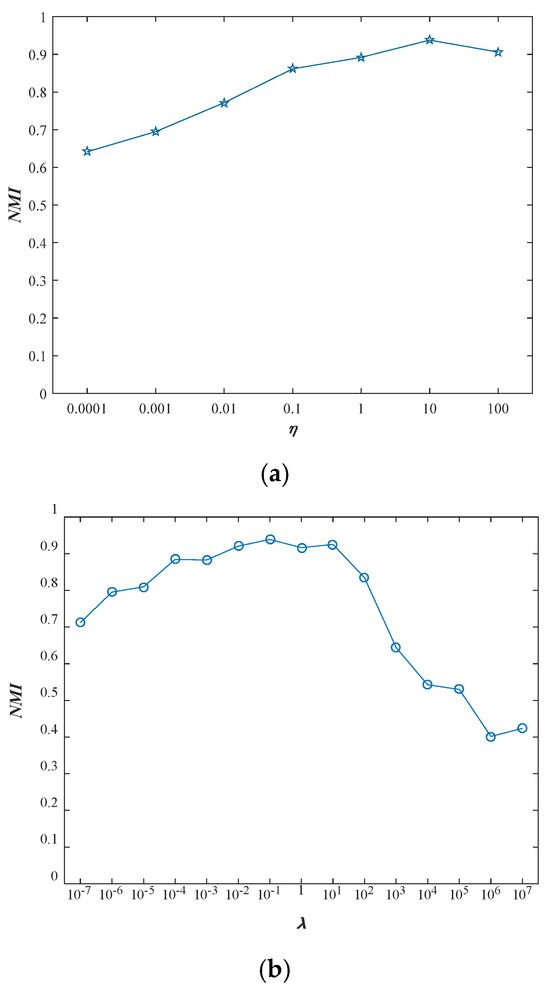
We conducted experiments to study the sensitivity of MUC with respect to both the parameters and . Below we take the Multiple Features dataset as an example to carry out the sensitivity analysis. Figure 8a,b illustrate the NMI and RI changes with the increasing values of and , respectively. According to Table 3, the parameter is determined in , and the parameter is determined in . Obviously, these two parameters have considerable influence on performance of MUC. In particular, should keep a comparatively big value, and an appropriate value of will be helpful in enhancing the performance of MUC.
Figure 8.
NMI changes of MUC with different values of parameter and on Multiple Features dataset. (a) (b) .
5. Conclusions
In this study, we propose a novel multi-view clustering method, MUC. We first designed a utility-based function to provide the proposed utility-based partition-level side information for multi-view clustering. Such information is consistent with human thinking, in that it is high-caliber and instructional for clustering. We used utility-based partition-level side information from all the other views for current view clustering. In addition, information provided by multiple other views complimented that of the current view. Then, we conducted multi-view clustering in utility-based mutual supervision mode in a K-means-like way. Moreover, we leveraged multi-view weight learning based on maximum entropy to identify the role of each view, in order to further improve multi-view clustering performance. The experimental results from various multi-view datasets indicate that the proposed MUC is comparable to—or even better than—the existing single view and multi-view clustering methods in terms of NMI and RI.
There is still a room for further study, such as the extension of both utility-based partition-level side information and the mutual supervision mode to other classical clustering methods, such as FCM. Moreover, although the regularization parameters can be determined by grid search and/or cross-validation, the corresponding procedure is still computationally expensive and even prohibitive for large scale datasets. Appropriate ways to speed up such a procedure are important and deserve in depth studies.
Author Contributions
Conceptualization, Z.J. and S.W.; Methodology, J.Z. and S.W.; Formal analysis, J.Z.; Data curation, Z.J. and J.Z.; Writing—original draft, Z.J.; Writing—review & editing, S.W. All authors have read and agreed to the published version of the manuscript.
Funding
This work was supported in part by the National Natural Science Foundation of China, under grants 62206177, 62106145, 61772198, 6197071117, and U20A20228; by the Natural Science Foundation of Jiangsu Province under grant BK20191331; by the Natural Science Foundation of Zhejiang Province under grants LY23F020007 and LQ22F020024; and by the National First-class Discipline Program of Light Industry and Engineering (LITE2018).
Data Availability Statement
The original contributions presented in this study are included in the article. Further inquiries can be directed to the corresponding author.
Conflicts of Interest
The authors declare no conflict of interest.
References
- Zhang, P.; Wang, D.; Yu, Z.; Zhang, Y.; Jiang, T.; Li, T. A multi-scale information fusion-based multiple correlations for unsupervised attribute selection. Inf. Fusion 2024, 106, 102276. [Google Scholar] [CrossRef] [Scilit]
- Liu, Z.; Zhang, X.; Jiang, B. Active learning with fairness-aware clustering for fair classification considering multiple sensitive attributes. Inf. Sci. 2023, 647, 119521. [Google Scholar] [CrossRef] [Scilit]
- Hu, Z.; Cai, S.-M.; Wang, J.; Zhou, T. Collaborative recommendation model based on multi-modal multi-view attention network: Movie and literature cases. Appl. Soft Comput. 2023, 144, 110518. [Google Scholar] [CrossRef] [Scilit]
- Zhao, J.; Xie, X.; Xu, X.; Sun, S. Multi-view learning overview: Recent progress and new challenges. Inf. Fusion 2017, 38, 43–54. [Google Scholar] [CrossRef] [Scilit]
- Lai, Z.; Chen, F.; Wen, J. Multi-view robust regression for feature extraction. Pattern Recognit. 2024, 149, 110219. [Google Scholar] [CrossRef] [Scilit]
- Jiang, Y.; Deng, Z.; Chung, F.; Wang, S. Realizing Two-View TSK Fuzzy Classification System by Using Collaborative Learning. IEEE Trans. Syst. Man Cybern. Syst. 2017, 47, 145–160. [Google Scholar] [CrossRef] [Scilit]
- Bickel, S.; Scheffer, T. Multi-view clustering. In Proceedings of the IEEE International Conference on Data Mining, Brighton, UK, 1–4 November 2004; pp. 19–26. [Google Scholar]
- Chen, X.; Xu, X.; Huang, J.; Ye, Y. TW-k-means: Automated two-level variable weighting clustering algorithm for multi-view data. IEEE Trans. Knowl. Data Eng. 2013, 25, 932–944. [Google Scholar] [CrossRef] [Scilit]
- Deng, Z.; Liu, R.; Xu, P.; Choi, K.-S.; Zhang, W.; Tian, X.; Zhang, T.; Liang, L.; Qin, B.; Wang, S. Multi-View Clustering with the Cooperation of Visible and Hidden Views. IEEE Trans. Knowl. Data Eng. 2022, 34, 803–815. [Google Scholar] [CrossRef] [Scilit]
- Han, J.; Xu, J.; Nie, F.; Li, X. Multi-view K-Means Clustering with Adaptive Sparse Memberships and Weight Allocation. IEEE Trans. Knowl. Data Eng. 2020, 34, 803–815. [Google Scholar] [CrossRef] [Scilit]
- Cleuziou, G.; Exbrayat, M.; Martin, L.; Sublemontier, J.-H. CoFKM: A centralized method for multiple-view clustering. In Proceedings of the 9th IEEE International Conference Data Mining (ICDM), Miami Beach, FL, USA, 6–9 December 2009; pp. 752–757. [Google Scholar]
- Tzortzis, G.F.; Likas, A.C. Kernel-based weighted multi-view clustering. In Proceedings of the IEEE 12th International Conference on Data Mining, Brussels, Belgium, 10–13 December 2012; pp. 675–684. [Google Scholar]
- Jiang, Y.; Chung, F.-L.; Wang, S.; Deng, Z.; Wang, J.; Qian, P. Collaborative fuzzy clustering from multiple weighted views. IEEE Trans. Cybern. 2015, 45, 688–701. [Google Scholar] [CrossRef] [Scilit]
- Liu, H.; Fu, Y. Clustering with Partition Level Side Information. In Proceedings of the 2015 IEEE International Conference on Data Mining, Atlantic City, NJ, USA, 14–17 November 2015; pp. 877–882. [Google Scholar]
- Deng, Z.; Choi, K.S.; Chung, F.L.; Wang, S. EEW-SC: Enhanced entropy-weighting subspace clustering for high dimensional gene expression data clustering analysis. Appl. Soft Comput. 2011, 11, 4798–4806. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Chung, F.-L.; Wang, S. A Multiview and Multiexemplar Fuzzy Clustering Approach: Theoretical Analysis and Experimental Studies. IEEE Trans. Fuzzy Sys. 2019, 27, 1543–1557. [Google Scholar] [CrossRef] [Scilit]
- Yang, Y.; Wang, H. Multi-view clustering: A survey. Big Data Min. Anal. 2018, 1, 83–107. [Google Scholar] [CrossRef] [Scilit]
- Kailing, K.; Kriegel, H.; Pryakhin, A.; Schubert, M. Clustering Multi-Represented Objects with Noise. In Advances in Knowledge Discovery and Data Mining, Proceedings of the 8th Pacific-Asia Conference, PAKDD 2004, Sydney, Australia, 26–28 May 2004; Springer: Berlin/Heidelberg, Germany, 2004; pp. 394–403. [Google Scholar]
- de Sa, V.R. Clustering with Two Views. In Proceedings of the International Conference on Machine Learning, Bonn, Germany, 7–11 August 2005; pp. 20–27. [Google Scholar]
- Zhou, D.; Burges, C. Spectral Clustering and Transductive Learning with Multiple Views. In Proceedings of the 24th International Conference on Machine Learning, Corvalis, OR, USA, 20–24 June 2007; pp. 1159–1166. [Google Scholar]
- Blaschko, M.B.; Lampert, C.H. Correlational Spectral Clustering. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, Anchorage, AK, USA, 23–28 June 2008; pp. 1–8. [Google Scholar]
- Chaudhuri, K.; Kakade, S.; Livescu, K.; Sridharan, K. Multiview Clustering via Canonical Correlation Analysis. In Proceedings of the 26th Annual International Conference on Machine Learning, Montreal, QC, Canada, 14–18 June 2009; pp. 129–136. [Google Scholar]
- Liu, J.; Wang, C.; Gao, J.; Han, J. Multi-view clustering via joint nonnegative matrix factorization. In Proceedings of the 2013 SIAM International Conference on Data Mining, Austin, TX, USA, 2–4 May 2013; pp. 252–260. [Google Scholar]
- Gupta, A.; Das, S. Transfer Clustering Using a Multiple Kernel Metric Learned Under Multi-Instance Weak Supervision. IEEE Trans. Emerg. Top. Comput. Intell. 2022, 6, 828–838. [Google Scholar] [CrossRef] [Scilit]
- Greene, D.; Cunningham, P. A Matrix Factorization Approach for Integrating Multiple Data Views. In Machine Learning and Knowledge Discovery in Databases, Proceedings of the European Conference, ECML PKDD 2009, Bled, Slovenia, 7–11 September 2009; Springer: Berlin/Heidelberg, Germany, 2009; pp. 423–438. [Google Scholar]
- Ye, J. A netting method for clustering-simplified neutrosophic information. Soft Comput. 2017, 21, 7571–7577. [Google Scholar] [CrossRef] [Scilit]
- Pedrycz, W. Collaborative fuzzy clustering. Pattern Recognit. Lett. 2002, 23, 1675–1686. [Google Scholar] [CrossRef] [Scilit]
- Han, T.; Xie, W.; Zisserman, A. Self-supervised Co-training for Video Representation Learning. In Proceedings of the Advances in Neural Information Processing Systems 33 (NeurIPS 2020), Virtual, 6–12 December 2020. [Google Scholar]
- Kang, Z.; Zhao, X.; Peng, C.; Zhu, H.; Zhou, J.T.; Peng, X.; Chen, W.; Xu, Z. Partition level multiview subspace clustering. Neural Netw. 2020, 122, 279–288. [Google Scholar] [CrossRef] [Scilit]
- Wang, J.; Wu, B.; Ren, Z.; Zhang, H.; Zhou, Y. Multi-scale deep multi-view subspace clustering with self-weighting fusion and structure preserving. Expert Syst. Appl. 2023, 213, 119031. [Google Scholar] [CrossRef] [Scilit]
- Lan, W.; Yang, T.; Chen, Q.; Zhang, S.; Dong, Y.; Zhou, H.; Pan, Y. Multiview subspace clustering via low-rank symmetric affinity graph. IEEE Trans. Neural Netw. Learn. Syst. 2024, 35, 11382–11395. [Google Scholar] [CrossRef] [Scilit]
- Mirkin, B. Reinterpreting the category utility function. Mach. Learn. 2001, 45, 219–228. [Google Scholar] [CrossRef] [Scilit]
- Wu, J.; Liu, H.; Xiong, H.; Cao, J.; Chen, J. K-means-based consensus clustering: A unified view. IEEE Trans. Knowl. Data Eng. 2015, 27, 155–169. [Google Scholar] [CrossRef] [Scilit]
- Hayashi, M. Bregman divergence based em algorithm and its application to classical and quantum rate distortion theory. IEEE Trans. Inf. Theory 2023, 69, 3460–3492. [Google Scholar] [CrossRef] [Scilit]
- Ahmed, M.; Seraj, R.; Islam, S.M.S. The k-means algorithm: A comprehensive survey and performance evaluation. Electronics 2020, 9, 1295. [Google Scholar] [CrossRef] [Scilit]
- Andreani, R.; Schuverdt, M.L.; Secchin, L.D. On enhanced KKT optimality conditions for smooth nonlinear optimization. SIAM J. Optim. 2024, 34, 1515–1539. [Google Scholar] [CrossRef] [Scilit]
- Zhou, J.; Zhang, X.; Jiang, Z. Recognition of Imbalanced Epileptic EEG Signals by a Graph-Based Extreme Learning Machine. Wirel. Commun. Mob. Comput. 2021, 2021, 5871684. [Google Scholar] [CrossRef] [Scilit]
- Gu, Q.; Zhou, J. Learning the shared subspace for multi-task clustering and transductive transfer classification. In Proceedings of the 2009 Ninth IEEE International Conference on Data Mining, Miami Beach, FL, USA, 6–9 December 2009; pp. 159–168. [Google Scholar]
- Bache, K.; Lichman, M. UCI Machine Learning Repository; University California, School of Information and Computer Science: Irvine, CA, USA, 2013; Available online: http://archive.ics.uci.edu/ml (accessed on 28 January 2024).
- Cai, D.; He, X.; Han, J. Spectral Regression for Efficient Regularized Subspace Learning. In Proceedings of the 2007 IEEE 11th International Conference on Computer Vision, Rio de Janeiro, Brazil, 14–21 October 2007; pp. 1–8. [Google Scholar]
- Motiian, S.; Piccirilli, M.; Adjeroh, D.A.; Doretto, G. Information bottleneck learning using privileged information for visual recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Las Vegas, NV, USA, 27–30 June 2016; pp. 1496–1505. [Google Scholar]
- Friedman, J.H. On bias, variance, 0/1—Loss, and the curse-of-dimensionality. Data Min. Knowl. Discov. 1997, 1, 55–77. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).