


Abstract
This paper concerns several important topics of the Symmetry journal, namely, pattern recognition, computer-aided design, diversity and similarity. We also take advantage of the symmetric and asymmetric structure of a transfer function, which is responsible to map a continuous search space to a binary search space. A new method for design of a fuzzy-rule-based classifier using metaheuristics called Gravitational Search Algorithm (GSA) is discussed. The paper identifies three basic stages of the classifier construction: feature selection, creating of a fuzzy rule base and optimization of the antecedent parameters of rules. At the first stage, several feature subsets are obtained by using the wrapper scheme on the basis of the binary GSA. Creating fuzzy rules is a serious challenge in designing the fuzzy-rule-based classifier in the presence of high-dimensional data. The classifier structure is formed by the rule base generation algorithm by using minimum and maximum feature values. The optimal fuzzy-rule-based parameters are extracted from the training data using the continuous GSA. The classifier performance is tested on real-world KEEL (Knowledge Extraction based on Evolutionary Learning) datasets. The results demonstrate that highly accurate classifiers could be constructed with relatively few fuzzy rules and features.
1. Introduction
Data classification is one of the most productive fields of study within the scope of data mining and machine learning. Classification can be applied to scientific and industrial data, handwritten text and multimedia content, biomedical data and social network data. Such a broad scope is due to the fact that the aim of classification is to identify the interrelation among the set of pre-defined input variables (features) and the desired output variable (class label). Some of the most common data classification methods are decision trees, rule-based methods, probabilistic methods, support vector machines and neural networks [1].
Fuzzy classifiers, which are rule-based classifiers, offer a significant advantage both in terms of their functionality and in terms of subsequent analysis and design. A unique advantage of fuzzy classifiers is associated with the interpretability of classification rules. The key measure of efficiency is classification accuracy that is frequently used in comparative analysis of fuzzy classifiers versus classifiers based on other principles [2,3].
Design of any classifier is based on the assumption that the class labels for each instance in the training dataset are known. Class labels in a test dataset are predicted using a classifier designed with a training set. The relation of accurately classified instances to the overall test data is indicative of classification accuracy. However, the large number of features found in datasets results in an increased calculation time and decreased accuracy of prediction. Selection of features makes it possible to reduce the dimensions of the feature input space by identifying and eliminating noise and irrelevant features [4].
The process of fuzzy classifier design includes the following principal stages: feature selection, structure formation (rule base), optimization of fuzzy rule parameters. Feature selection methods are conventionally grouped into two categories: filters and wrappers [5], the difference between the two being whether or not a classifier is designed during feature selection. The structure of the classifier is most often formed with the use of clustering methods designed to identify the data structure and build information granules that may be related to linguistic terms [2]. Parameters of fuzzy rules can be optimized using conventional approaches based on calculation of derivatives or with the help of metaheuristics methods [6].
No Free Lunch Theorem [7,8] tells us that there are no context- or problem-independent reasons to favour one learning or classification method over another. The performance of all the metaheuristics is by and large problem-dependent. The superiority of a classification method depends on dataset properties. If a classifier generalizes better to a certain data set, then it is a result of its better match for a specific problem rather than its supremacy over other classifiers [9].
A swarm optimization algorithm from the physical field was introduced in [10]. An algorithm was called Gravitational Search Algorithm (GSA). Its agents represent particles that have masses with different sizes that follow the Newtonian gravity law. GSA was compared with some known metaheuristic search methods.
To solve different kinds of optimization problems, modified versions of GSA have been introduced, including continuous, binary-valued, discrete, multimodal and multi-objective versions of GSA. The efficiency of GSA has been improved using enhanced operators, hybridization of GSA with other metaheuristic algorithms, designing the adaptive algorithms and intelligent techniques [11]. An adaptive GSA that switches between synchronous and asynchronous update is presented in Reference [12]. The proposed algorithm combines both synchronous and asynchronous updates. The integration of these iterative strategies changes the behaviour of the particles. In Reference [13] the authors propose a fuzzy gravitational search algorithm for the design of optimal 8th order IIR filters. The proposed algorithm is a combination between fuzzy techniques and gravitational search. Two Mamdani inference systems tune parameters of GSA, finding a good trade-off between exploration and exploitation of the search process. In Reference [14], to find trade-off between exploration and exploitation, it was proposed to use an approach, which combines neural network and fuzzy system for the tuning of GSA parameters. In Reference [15] the authors propose to tune a suitable parameter of GSA through a fuzzy controller whose membership functions are optimized by Genetic Algorithms, Particle Swarm Optimization and Differential Evolution.
The results which were obtained confirmed the high performance of the proposed method in solving various nonlinear functions. It has been demonstrated that the Gravitational Search Algorithm has the ability to find the optimum solution for many benchmarks [10,12,16,17,18,19]. For this reason, this algorithm was chosen to solve the problem of designing a fuzzy-rule-based classifier.
This paper aims at developing the fuzzy-rule-based classifier using Gravitational Search Algorithm.
The main contributions of this work are the following:
- A new technique for generating a fuzzy-rule-based classifier.
- A method that selects a compact and efficient subset of features.
- A new method of tuning fuzzy-rule-based classifier parameters.
- A statistical comparison among the results achieved by the fuzzy-rule-based classifiers generated by our technique and by two state-of-the-art learning algorithms.
2. Related Work
This section gives a brief overview of work in two related research fields, namely fuzzy classifier design using metaheuristics and approaches to feature selection for classification.
2.1. Fuzzy Classifier Design Using Metaheuristics
Several approaches using metaheuristics related to fuzzy classifier design can be found in the literature. Kumar and Devaraj [20] propose a modified genetic algorithm approach to obtain the optimal set of rules and a membership function for a fuzzy classifier. A modified form of representation is used to encode the rule base and membership functions. In the proposed approach, genetic operators were also modified to improve convergence and solution quality.
Chang and Lilly [21] propose to construct a fuzzy classifier directly from the data, without using a priori knowledge or assumptions about the distribution of data. Membership functions and fuzzy rules are created automatically and optimized during execution.
Olivas et al. [22] propose to design fuzzy classifiers using methods such as simple particle swarm optimization and methods with dynamically adapted parameters. Dynamical adjustment of the optimization method parameters can improve the quality of results and increase the diversity of solutions to a problem. Chen et al. [23] proposes an alternative approach using Particle Swarm Optimisation (PSO) in the search of a set of optimal rule weights, entailing high classification accuracy. This approach works for situations where an initial fuzzy rule-base has been built with predefined fuzzy sets, which must be maintained for the purpose of consistent interpretability, both in the learned models and in the inference results using such models. In Reference [24], the application of chaotic particle swarm optimization to fuzzy system parameter estimation is presented. Unlike traditional PSO, chaotic PSO uses chaotic coordinate transformations to improve the search capabilities of particles. Various mapping functions have been investigated to generate sequences of chaotic transformations.
Pulkkinen and Koivisto [25] use hybridization methods to find a compromise between accuracy and interpretability in the construction of fuzzy classifiers.
In order to solve the problem of high dimensional classification in linguistic fuzzy-rule-based classification systems Aydogan et al. [26] propose a hybrid heuristic approach based on a genetic algorithm and integer-programming formulation. In this algorithm, each chromosome represents a rule for the specified class, whereupon a genetic algorithm is used for producing several rules for each class, whilst an integer-programming formulation is utilized for selecting the rules from within a pool of rules obtained via the genetic algorithm.
In Reference [27], the construction of fuzzy classifiers using the algorithm of the classifier structure generation and 14 differential evolution algorithms are presented. The algorithm of structure generation is aimed at obtaining a compact classifier (the compactness depends on the number of rules). The differential evolution algorithms optimize the parameters to obtain an accurate classifier.
Alcala-Fdez et al. [28] propose a fuzzy association rule-based classification method for high-dimensional problems (FARC-HD). The method is based upon three stages in order to obtain an accurate and compact fuzzy-rule-based classifier whilst keeping computational costs low. This method is based on an improved weighted relative accuracy measure, which preselects the most interesting rules prior to a genetic post processing procedure for rule selection and parameter tuning.
In Reference [29], the authors present a multi-objective evolutionary method, which performs two processes in concurrence: a process of tuning as well as a rule-selection process performed upon an initial knowledge base of fuzzy-rule-based classifiers. A fuzzy discretization algorithm was designed in order to extract suitable granularities from data and also to generate fuzzy partitions that constitute the initial database. To generate an associative knowledge base, the FARC-HD methods described in Reference [28] were used.
2.2. Feature Selection
Feature selection is a procedure where such a subset of features is isolated from the initial set that entirely satisfies the current task or the training objective. The goals of feature selection are to: (1) avoid overtraining, (2) reduce the volume of data for analysis, (3) enhance classification efficiency, (4) eliminate irrelevant and noise features, (5) improve interpretability of the result [30].
Feature selection methods can be grouped into two categories: filter and wrapper [5,31,32]. Filter methods are based on certain metrics, such as entropy, probability distribution, or mutual information [33] and do not use a classifying algorithm during the process. Wrapper methods use the classifier to evaluate the feature subset and the classifier itself is “wrapped” in the feature selection cycle. Both filter and wrapper methods have their strengths and weaknesses. The advantage of the filter-based methods lies in their higher scalability and speed of execution. Its general disadvantage is that the lack of interaction with the classifier and disregard of the relationship between features result in a lower classification accuracy that varies for different classifiers. The advantage of the wrapper methods is that they work together with the specific classification algorithm and account for the synergy of the joint usage of selected features. The disadvantages of the wrapper methods are the higher risk of overtraining and long time required to calculate classification accuracy [34].
Let us consider the use of metaheuristics for the problem of feature selection. Yusta [35] considers three metaheuristic strategies to address the problem of feature selection—GRASP, Tabu Search and Memetic Algorithm. These three strategies are compared to a genetic algorithm, which is a metaheuristic strategy that is most often used to address this problem [36] and to other typical feature selection methods examples of which include Sequential Forward Floating Selection and Sequential Backward Floating Selection. The results demonstrate that in general GRASP and Tabu Search attain markedly better results than the other methods.
Aladeemy et al. [37] propose a variation of the cohort intelligence algorithm for feature selection. The efficiency of the proposed algorithm was compared to the well-known metaheuristics: Genetic Algorithm, Particle Swarm Optimization, Differential Evolution and Artificial Bee Colony. A comparative analysis shows that the proposed algorithm offers classification accuracy and a number of features selected that are comparable to the results obtained by the above algorithms.
Hodashinsky and Mekh [38] propose feature selection based on harmony search. Several feature subsets on the basis of discrete harmonic search are generated by using the wrapper scheme. The Akaike information criterion is deployed to identify the best performing classifiers. Experimental results show efficiency of the proposed approach and demonstrate that highly accurate classifiers can be constructed by using relatively few features.
Vieira et al. [39] propose an ant colony optimization algorithm for the feature selection problem and compare it with tree search methods for feature selection. To construct a fuzzy classifier of the Takagi–Sugeno type, all the above algorithms were used.
Gurav et al. [40] propose a hybrid filter-wrapper algorithm, named GSO-Infogain, for simultaneous feature selection, which improves the accuracy of classification. GSO-Infogain employs the Glowworm-Swarm Optimization (GSO) algorithm with the Support Vector Machine as its internal learning algorithm and utilizes feature ranking based on information gain as a heuristic. GSO-Infogain also performs well in this experiment. It gives similar prediction accuracies on the training and test datasets. This is a good indicator of its robustness.
Marinaki et al. [41] propose using the Honey Bees Mating Optimization algorithm for at the feature selection stage and the Nearest Neighbour based classifiers at the classification stage. The proposed method is tested in a financial classification task.
3. Materials and Methods
A fuzzy classifier is designed in three stages: feature selection, generation of a fuzzy-rule base and optimization of the antecedent parameters of rules. Features are selected with the Binary Gravitational Search Algorithm. The classifier structure is formed by the rule base generation algorithm, using extreme feature values. In the proposed learning method, the related parameters of the proposed classifier are tuned by using the continuous GSA. The performance of the classifier is tested on real-world KEEL datasets. At the final stage, classifiers designed with the proposed method are compared to similar classifiers using the Mann-Whitney-Wilcoxon test as the criterion.
3.1. Fuzzy Classifier
Classification consists in finding such a class label in a set of class labels that would correspond to the vector of the object’s feature values [38]. In universe U = (A, C), where A = {,, …, } is a set of input features, C = {, , …, } is a set of class labels, the object is characterized by its vector of feature values. Let x = × × … × ∈ ℜn be an n-dimensional feature space.
A fuzzy classifier can be represented as a function that assigns a class label to a point x in the input feature space with a calculable degree of confidence:
The fuzzy classifier is based on a production rule base that appears as follows:
where j is the rule index; R is the number of rules; Akj is a fuzzy term that characterizes the k-th feature in the j-th rule (k = 1, …, n); is the consequent class; S = (, , …, ) is the binary vector of features: line indicates presence ( = 1) or absence ( = 0) of a feature in the classifier.
The class label is defined in the observation table {(; ), } as follows:
where is the membership function value of fuzzy term Ajk at point .
3.2. Performance Measures
The classification accuracy measure is defined as a ratio between accurately determined class labels and the number of objects:
where f(; θ, S) is the fuzzy classifier output with parameters of fuzzy terms θ and features S at point .
The problem of fuzzy classifier design is confined to finding the maximum of the function in space S and θ = (θ1, θ2, …, θD):
where θimin, θimax are the upper and lower boundaries of the domain of each parameter, correspondingly. This problem is NP-hard; in this paper, we propose to solve it by splitting it into two tasks: feature selection and tuning fuzzy term parameters.
3.3. Binary Gravitational Search Algorithm
The feature selection problem consists in searching for such a subset of the predetermined set of features x that would not cause a decrease in classification accuracy as the number of features is reduced; the solution is represented as a binary vector S = (, , …, )T, where = 0 means that the i-th feature does not participate in classification, = 1 means that the i-th feature is used by the classifier. This problem can be solved with the Binary Gravitational Search Algorithm.
The idea of gravitational search is that the input vector population is presented as a system of elementary particles with gravity forces acting between them [10]. The higher the accuracy of a vector-based classifier, the higher the mass of a particle corresponding to that vector and the stronger it attracts other particles. But since the particle is affected by gravity forces as well, it will be moving while searching in its local domain.
The binary version of the algorithm is used to find the binary vector of features Sbest that makes it possible to achieve the highest level of classification accuracy.
The input data for gravitational search is the following: vectors of system parameters θ, number of vectors P, maximum number of iterations T, initial value of gravitational constant G0, coefficients α and small constant ε. The initial population S = {S1, S2, …, SP} is randomly generated. Before the start, a classifier is built based on each vector and fitness function is evaluated:
The mass, acceleration, velocity and movement of particles are measured at each iteration of the algorithm. The mass of the i-th particle is calculated with due regard to classification accuracy:
where m is the mass of the particle, t is the iteration number, best(t) and worst(t) are the values of fitness function of the least and the most accurate vectors at the current iteration, correspondingly.
According to Newton’s second law, the total force acting on a particle imparts acceleration to it:
where is the ordinal number of the vector element; rand(0; 1) is a random number within the interval [0; 1];
is the normalized mass value of the j-th particle; ;
is the value of the gravitational constant. The denominator uses the distance and not the distance squared, which, as the authors of the algorithm [10] believe, makes it possible to achieve better results.
The particle velocity is determined as follows:
Then each particle is updated with the help of the transfer function; a detailed description of the functions is given in Section 3.4 of this paper. An iteration of the algorithm is deemed to have ended after the vectors are updated and the value of the population classification accuracy is calculated. When the population counter reaches value T, the algorithm stops and feeds the vector with the highest accuracy value Sbest to the output.
3.4. The Transfer Functions
In the Binary Gravitational Search Algorithm, the velocity gained by the vector element shows how much the element needs to change to reach the best solution available in the population. If the velocity is high, it can be assumed that the element is far removed from the best solution element and the mass of the particle is rather low. Therefore, the element must be replaced with an inverse element or excluded from the vector by assigning a zero to it. Thus, the vector is updated with a certain probability that is calculated based on velocity [42] with the help of the transfer function, which is responsible to map a continuous search space to a discrete search space [43]. The study used four such functions.
The first function S1 belongs to the class of S-shaped asymmetric functions and represents the probability of 0:
The second function S2 makes use of an additional coefficient:
where
The third function V1 belongs to the class of V-shaped symmetric functions:
The last function used, V2, is also a V-shaped function that represents the probability that the vector element value will change to the opposite:
where ⨁ means the logical OR operator.
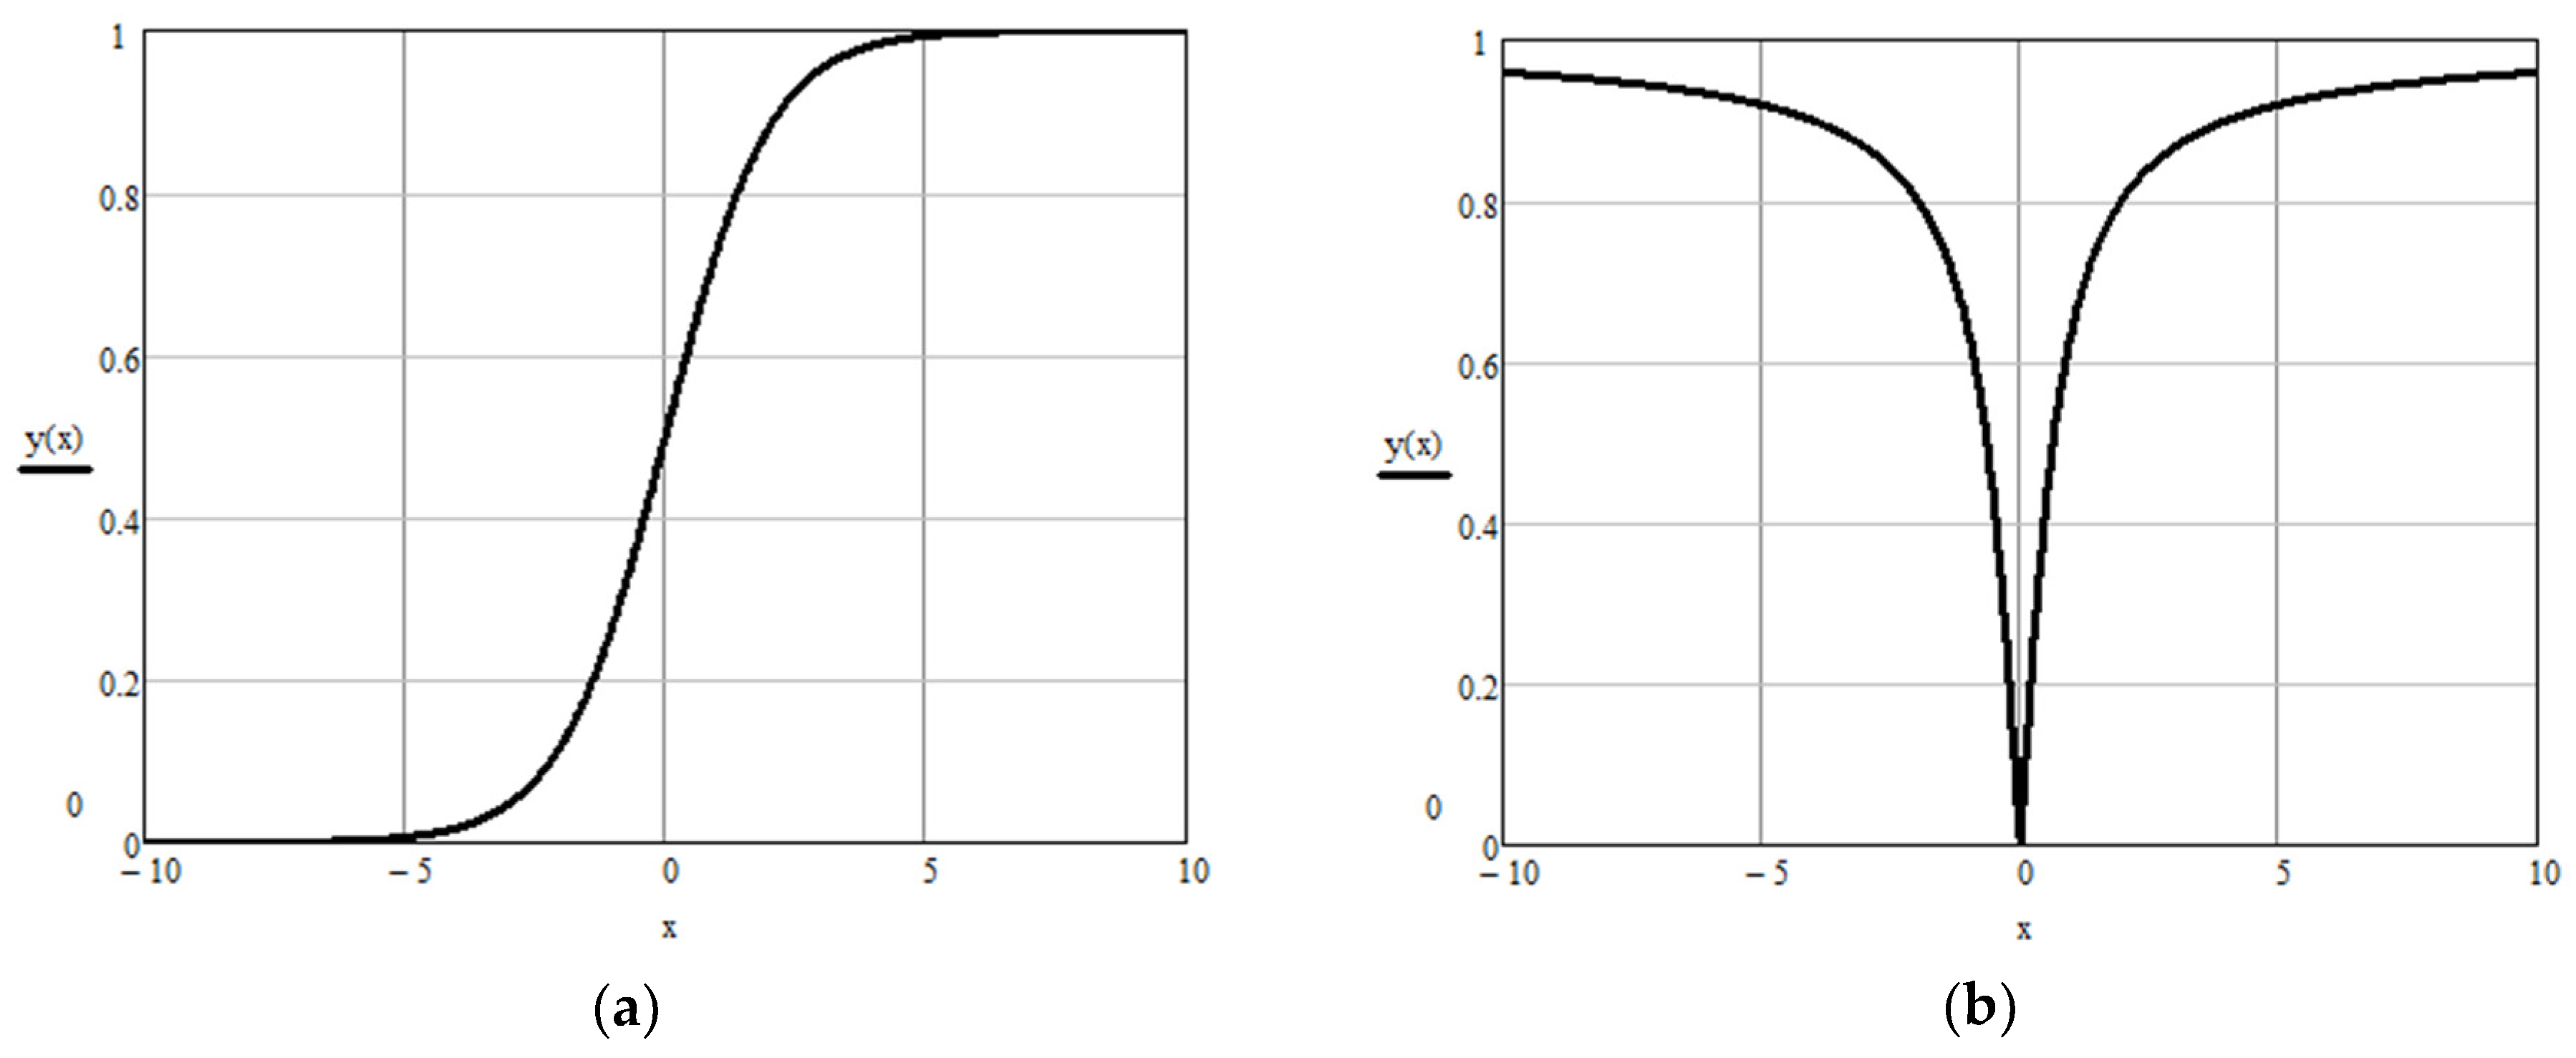
Figure 1 shows typical graphs produced by the functions used, where the S-shaped function is defined as follows:
V-shaped function:
Figure 1.
Transfer functions: (a) Example of an S-shaped asymmetric transfer function (b) Example of a V-shaped symmetric transfer function.
Velocity that is used to calculate the value of the transfer function is a numerical value. One disadvantage of S-shaped transfer functions for the Binary Gravitational Algorithm is that the particle elements that have gained a high negative velocity will with a high probability remain in the vector. V-shaped functions are symmetrical with respect to the axis of ordinates and therefore are free of that disadvantage.
A pseudo code of the Binary Gravitational Search Algorithm is shown in Algorithm 1.
| Algorithm 1. Binary Gravitational Search Algorithm. |
| Input: θ, P, T, G0, α, ε. |
| Output: Sbest. |
| begin |
| Initialize the population S = {S1, S2, …, SP}; |
| while (t < T) |
| by Equation (5) for i = 1, 2, ..., P; |
| find best(t) and worst(t); |
| update G(t) by Equation (9); |
| (t) by Equation (10) for i = 1, 2, ..., P; |
| update the position of particles with one of the Equations (11)–(14); |
| end while |
| output the particle with the best fitness value Sbest; |
| end |
3.5. Algorithm for Generating Rule Base by Extreme Feature Values
The algorithm is designed to form an initial base of rules of a fuzzy classifier containing one rule for each class. The rules are formed based on extreme values of the training sample Tr = {(xp; ), p = 1 ,..., |Tr|}. Let us introduce the following notation: m is the number of classes, n is the number of features, Ω* is the classifier rule base. A pseudo code of the generating algorithm is demonstrated in Algorithm 2.
| Algorithm 2. Algorithm for generating rule base by extreme feature values. |
| Input: m, n, Tr. |
| Output: classifier rule base Ω*. |
| begin |
| Ω:= ∅; |
| do loop j from 1 till m |
| do loop k from 1 till n |
| ; |
| ; |
| ]; |
| end of loop |
| creation of rule R1j on the basis of terms Ajk that refers observation to the class |
| ; |
| Ω*:= Ω ∪ {R1j} |
| end of loop |
| output Ω*. |
| end |
3.6. Continuous Gravitational Search Algorithm
Fuzzy term parameters obtained during the classifier structure generation will not always ensure that the classification is efficient. In order to improve its accuracy, the parameters must be adjusted. This can be achieved by optimizing the vector of fuzzy terms parameters θ using continuous gravitational search.
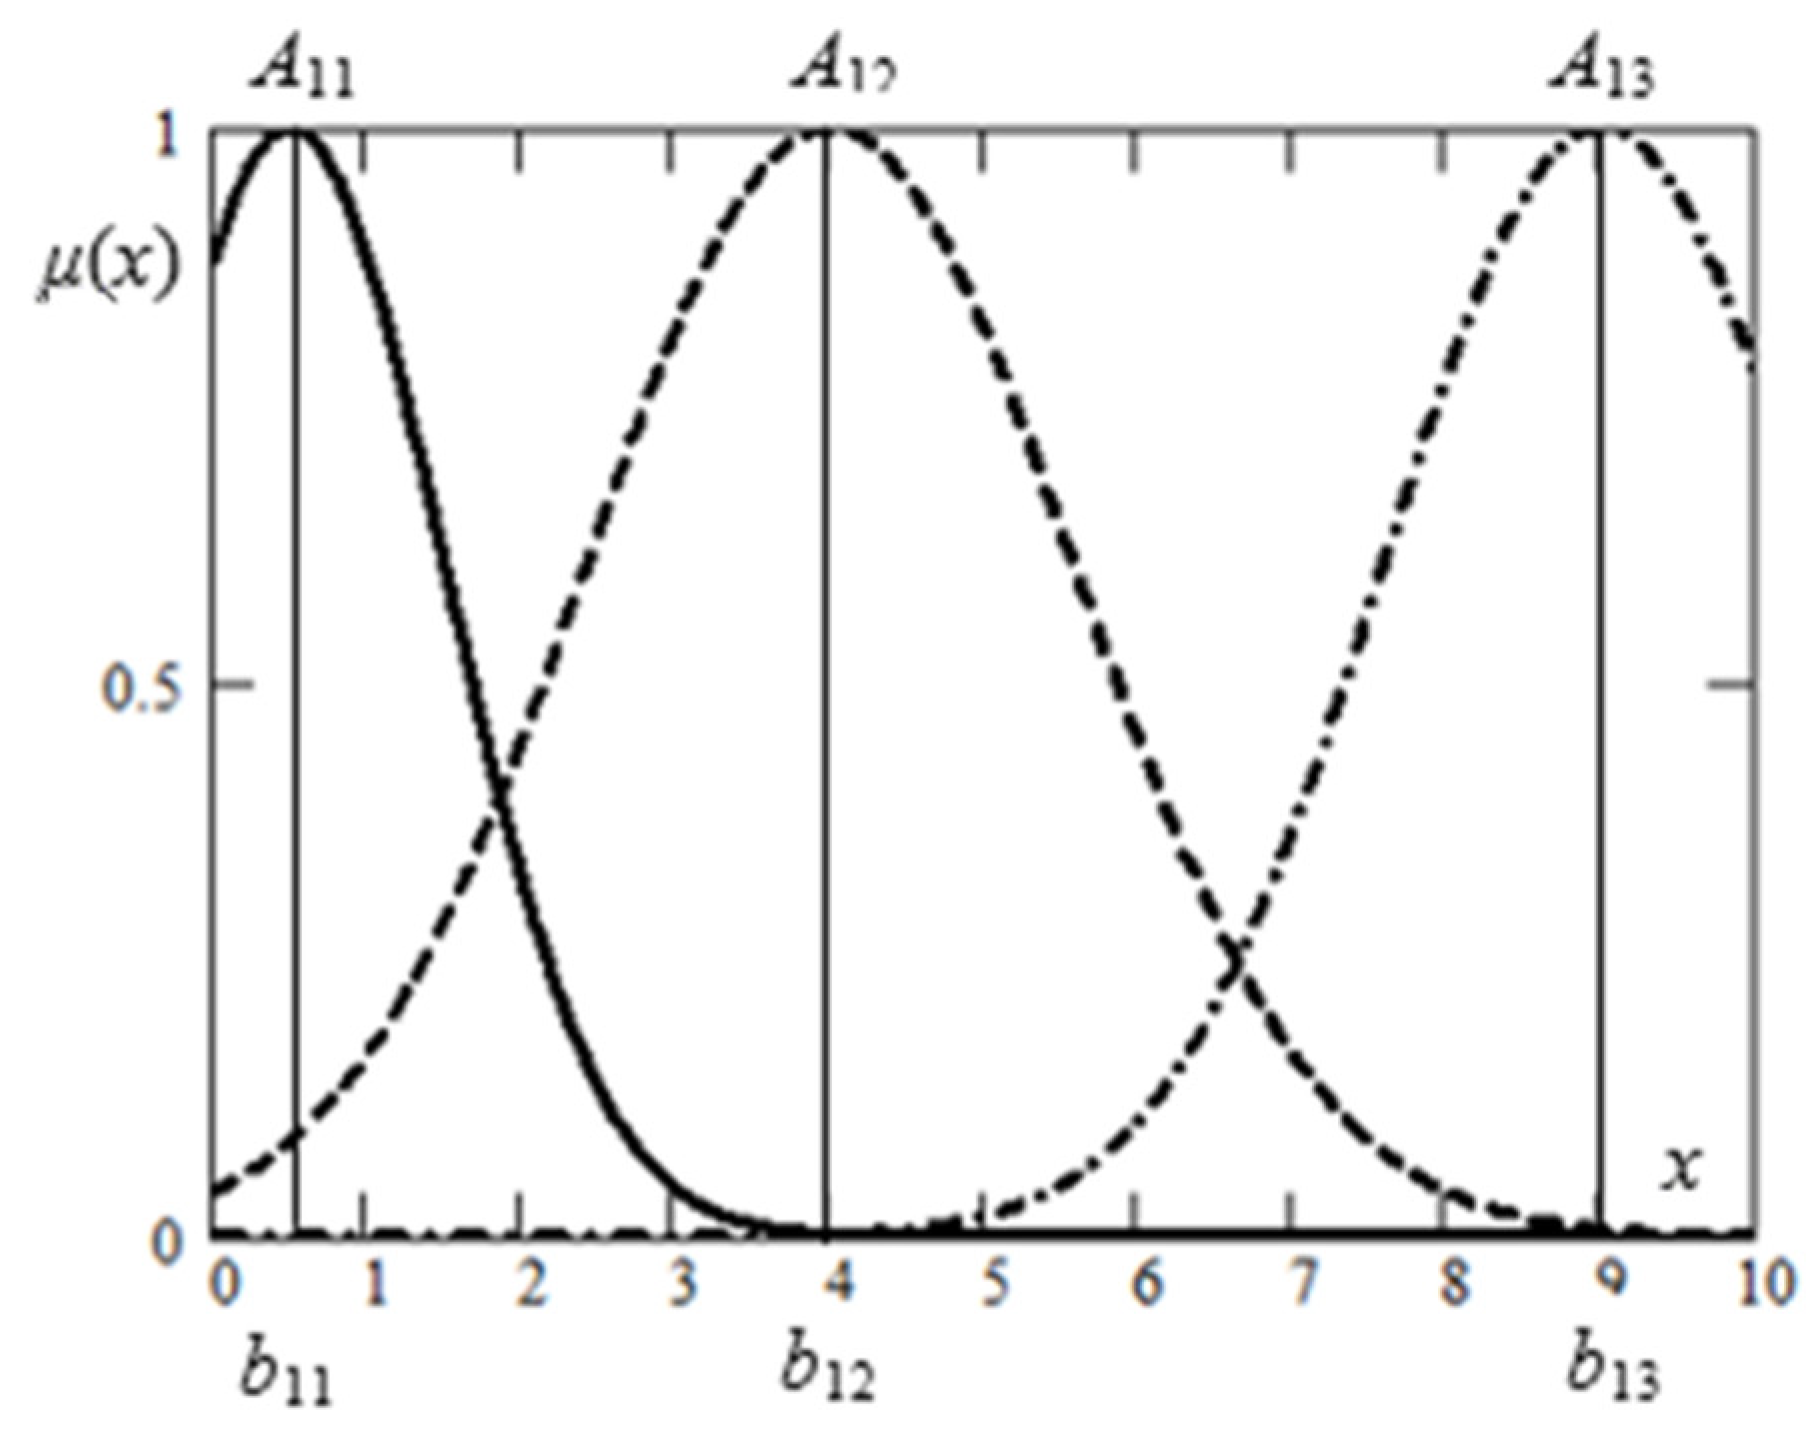
Figure 2 shows an example demonstrating the formation of vector θ. Feature a here is represented by three symmetric Gaussian terms, each of them determined by two parameters (b—the coordinate of the peak on the abscissa, c—scatter) included in vector θ = (, , , , , , , , …). The use of symmetric membership functions is preferable because of their better interpretability.
Figure 2.
Example of fuzzy partition of feature x by three symmetric Gaussian terms.
Dimensions of the vector θ are determined by the number of input features used in classification and by the number and type of terms describing each feature. For some datasets, asymmetrical types of terms, such as triangular membership functions, can be a better choice.
Population Θ = {θ1, θ2, …, θP} for the Continuous Gravitational Search Algorithm is created by copying the input vector θ1, generated by the classifier structure generation algorithm, with normal deviation. The input data for the algorithm is: vector of features S, number of term parameter vectors P, maximum number of iterations T, initial value of gravitational constant G0, coefficients α and small constant ε. Before the start, a classifier is built based on each vector and classification accuracy is evaluated:
The mass, acceleration, velocity and movement of particles are measured in each iteration as well as in the binary algorithm. According to Newton’s second law, the total force acting on a particle imparts acceleration to it:
where is the ordinal number of the vector element; rand(0; 1) is a random number within the interval [0; 1]; is the normalized value of the mass of the j-th particle; ; is the value of the gravitational constant.
Vector elements are updated as follows:
where . After the entire population is updated, classification accuracy is recalculated and the iteration ends.
The algorithm ends when the number of iterations (t = T) is exhausted, or if all vectors are equal. The output data produced by the algorithm is the vector of system parameters θbest that possess the highest level of classification accuracy.
A pseudo code of the Binary Gravitational Search Algorithm is shown in Algorithm 3.
| Algorithm 3. Continuous Gravitational Search Algorithm. |
| Input: S, P, T, G0, α, ε. |
| Output: θbest. |
| begin |
| Initialize the population Θ = {θ1, θ2, …, θP}; |
| while (t < T) |
| by Equation (17) for i = 1, 2, ..., P; |
| find best(t) and worst(t); |
| update G(t) by Equation (9); |
| (t) by Equation (10) for i = 1, 2, ..., P; |
| update the position of particles with the Equation (19); |
| end while |
| output the particle with the best fitness value θbest; |
| end |
3.7. Datasets
The algorithms described above have been validated using real-world datasets from the dataset repository KEEL (http://keel.es). Table 1 shows a description of the datasets used.
Table 1.
Dataset characteristics.
3.8. Test Phase
Two experiments have been conducted within the framework of the study. The first experiment focused on validation of the Binary Gravitational Search Algorithm in the wrapper mode for a fuzzy classifier while using various transfer functions. The feature selection experiment was designed as follows. Datasets with the number of features exceeding four were grouped into ten training and test sets in accordance with the cross-validation scheme. For each sample, the Binary Gravitational Search Algorithm was started with each of the four transfer functions, one at a time. Then, the resulting feature sets were used to design a fuzzy classifier with the help of a class extremum-based algorithm for all ten samples. The experiment has produced averages of classification accuracy and of the number of features for each transfer function.
The second experiment focused on designing fuzzy classifiers using the Binary and Continuous Gravitational Search Algorithms. Out of the feature set found in the first experiment, the best set in terms of its training accuracy was selected. The selected feature set was used to design a classifier with the help of a class extremum-based algorithm. Then the Continuous Gravitational Search Algorithm was used to optimize parameters of membership functions for the resultant classifier. The results were averaged over five independent runs of the Continuous Gravitational Search Algorithm.
The number of particles in gravitational search populations P is ten, the initial value of the gravitational constant is G0 = 10, coefficient α = 10, small constant ε = 0.01. The maximum number of iterations for the Continuous Binary Search Algorithm is T = 1000. The number of iterations for the Binary Algorithm varied depending on the number of features in the dataset (100 to 1000 iterations). The value of the parameters is determined empirically.
4. Experimental Results
The present study aims to identify different classifiers, which would encounter the performance for the data that was selected.
4.1. Comparison of Feature Selection Results Using the Binary Gravitational Algorithm with Various Transfer Functions
The first experiment focused on validation of the Binary Gravitational Algorithm in the wrapper mode for a fuzzy classifier.
The test accuracy obtained while designing a fuzzy system based on a full set of features (without feature selection) is compared to the test accuracy obtained after selecting features by the Binary Gravitational Search Algorithm for each of the transfer functions described in Section 3.3. Table 2 shows the results of the experiment for datasets with the number of features exceeding four. Here, #F is the number of features, #T is the classification accuracy percentage for the test data. The best results are in bold.
Table 2.
Results of feature selection using the Binary Gravitational Algorithm.
In all of the datasets used, at least one transfer function makes it possible to achieve an accuracy equal or superior to the classification accuracy obtained on the full dataset. The Wilcoxon signed rank test was used to evaluate the statistical significance of the difference between the resulting accuracy values. Table 3 shows the values calculated based on pairwise algorithm comparison.
Table 3.
Wilcoxon test for comparison of prediction accuracy.
The resulting values of the Wilcoxon test exceed the significance level of 0.05; therefore, there is no statistically significant difference between the test accuracy obtained with full dataset-based fuzzy classifiers and the accuracy values obtained after feature selection using the Binary Gravitational Algorithm. A conclusion can be made that there is no statistically significant difference between the accuracy values obtained on different transfer functions.
Table 4 shows the calculated values of the Wilcoxon test for evaluation of the statistical significance of difference in the number of features in the resulting classifiers.
Table 4.
Wilcoxon test for comparison of the numbers of features.
The above test values show that there is a statistically significant difference between the initial number of features and the number of features selected by any of the transfer functions. There is no statistically significant difference between the number of features selected with the help of different transfer functions.
GSA has the same computational complexity O(nd), where n is the number of agents and d is the search space dimension [14]. GSA in our work has not been modified, so it has complexity O(Pd), where P is the number of particles and d is the size of the dataset.
4.2. Comparison to Similar Solutions
Table 5 shows the experiment results. Here, #R is the number of rules, #F is the number of features when using selection, #L is the classification accuracy percentage on training data, #T is the classification accuracy percentage on test data. As a comparison, Table 5 also shows the results for the D-MOFARC and FARC-HD algorithms [28,29]. The best results are in bold.
Table 5.
Results of fuzzy classifier design.
The Wilcoxon signed-rank test was used to assess the statistical significance of differences in the accuracy of fuzzy classifiers formed using the Gravitational Algorithm and using D-MOFARC and FARC-HD. Table 6 shows the values calculated based on pairwise algorithm comparison.
Table 6.
Wilcoxon test for comparison of prediction accuracy.
The resulting values of the Wilcoxon test exceed the significance level of 0.05; therefore, there is no statistically significant difference between the test accuracy obtained with fuzzy classifiers using Gravitational Search Algorithms and accuracy values obtained using D-MOFARC and FARC-HD.
Pairwise comparison of the rule numbers shows that there exists a statistically significant difference between the number of rules in the resulting classifiers and the D-MOFARC algorithm (the test value is 2.47 × 10⁻⁹) and the number of rules in the resulting classifiers and the FARC-HD algorithm (the test value is 2.48 × 10⁻⁸).
Since the algorithms D-MOFARC and FARC-HD are based on full datasets, it is necessary to compare the number of features in full datasets and the number of features selected by the Binary Gravitational Algorithm. A check with the Wilcoxon signed-rank test produces the value of 1.13 × 10⁻⁴, making it possible to conclude that the Binary Gravitational Algorithm demonstrates a high level of performance.
To compare the proposed method with other non-fuzzy classifiers, basic methods and ensemble methods were selected. Basic methods are a logistic regression method (LR), Gaussian Naive Bayes, a k-nearest-neighbour method (kNN), a Support Vector Machine (SVC), a Multi-Layer Perceptron (MLP), a WiSARD Classifier (WNN). Ensemble methods are a Random Forest (RF), Adaboost (AB), a Gradient Tree Boosting (GTB) [44]. Table 7 lists the benchmarking methods we have compared to fuzzy classifier using GSA.
Table 7.
Average accuracy of methods.
Classification accuracies compared by means of a statistical analysis based on Wilcoxon test with a significance level of 0.05 to prove how the fuzzy classifiers using Gravitational Search Algorithms is very close in performance to the best methods of machine learning. The null hypothesis is the following:
H0:
The distribution of classification accuracy for the GSA and another method is the same over N datasets; where N = 23.
Pairwise comparisons of methods conducted in the statistical analysis proved that fuzzy classifiers using Gravitational Search Algorithms is very close to Support Vector Machines, while it outperforms Gaussian Naive Bayes (Table 8).
Table 8.
p-Values of Wilcoxon test for comparison of 9 algorithms.
The numerical experimentations were performed on a personal computer equipped with a 2.40 GHz Intel(R) Core™ i5-2430M with NVIDEA GeForce GT 520MX Graphics processor and 4 GB of RAM. The described method was implemented using C# programming language under Microsoft Windows operating system environment.
5. Conclusions
This paper discusses methods for fuzzy classifier design with feature selection. Features were selected using the Binary Gravitational Algorithm. The classifier structure was formed by the rule base generation algorithm by using extreme feature values. Parameter classifier optimization was achieved by using the Continuous Gravitational Algorithm.
The performance of the fuzzy classifiers adjusted by the algorithms described above is tested on 26 real-world KEEL datasets. The resulting classifiers possess good trainability, which is confirmed by the high percentage of accurate classification on training samples and equally good predictive capability, which is supported by the high percentage of accurate classification on test samples.
The number of features used by the classifiers designed with the help of the algorithms is significantly smaller than the total number of features in datasets.
As can be seen from the above, the classifier design algorithms based on combinations of the algorithms proposed in this paper make it possible to design fuzzy classifiers that use a smaller number of features while offering an accuracy on the reduced number of features that is statistically equivalent to the accuracy of classifiers designed based on a full set of features.
In the future, the authors expect to study other ways to binarize the Gravitational Search Algorithm and increase the number of test datasets. Based on [45], in our future research a strict computational complexity analysis of GSAB + GSAC will be carried out.
Author Contributions
Conceptualization, A.S.; data curation, M.B. and A.K.; funding acquisition, A.S.; investigation, M.B. and I.H.; methodology, I.H. and A.S.; project administration, A.K.; software, M.B.; supervision, A.S., validation, I.H.; writing—original draft preparation, M.B. and I.H., writing—review & editing, A.K., I.H. and A.S.
Funding
This research was funded by the Ministry of Education and Science of Russia, Government Order no. 2.8172.2017/8.9 (TUSUR).
Conflicts of Interest
The authors declare no conflict of interest. The sponsors had no role in the design, execution, interpretation, or writing of the study.
References
- Aggarwal, C.C. An Introduction to data classification. In Data Classification: Algorithms and Applications; Aggarwal, C.C., Ed.; CRC Press: New York, NY, USA, 2015; pp. 2–36. [Google Scholar]
- Hu, X.; Pedrycz, W.; Wang, X. Fuzzy classifiers with information granules in feature space and logic-based computing. Pattern Recognit. 2018, 80, 156–167. [Google Scholar] [CrossRef] [Scilit]
- Evsutin, O.; Shelupanov, A.; Meshcheryakov, R.; Bondarenko, D.; Rashchupkina, A. The algorithm of continuous optimization based on the modified cellular automaton. Symmetry 2016, 8, 84. [Google Scholar] [CrossRef] [Scilit]
- Das, A.K.; Goswami, S.; Chakrabarti, A.; Chakraborty, B. A new hybrid feature selection approach using feature association map for supervised and unsupervised classification. Expert Syst. Appl. 2017, 88, 81–94. [Google Scholar] [CrossRef] [Scilit]
- Bolon-Canedo, V.; Sanchez-Marono, N.; Alonso-Betanzos, A. Feature Selection for High-Dimensional Data; Springer: Heidelberg, Germany, 2015; ISBN 978-3-319-21857-1. [Google Scholar]
- Lavygina, A.; Hodashinsky, I. Hybrid algorithm for fuzzy model parameter estimation based on genetic algorithm and derivative based methods. In Proceedings of the International Conference on Evolutionary Computation Theory and Applications (FCTA-2011), Paris, France, 24–26 October 2011; pp. 513–515. [Google Scholar] [CrossRef] [Scilit]
- Wolpert, D.H. The existence of a priori distinctions between learning algorithms. Neural Comput. 1996, 8, 1341–1390. [Google Scholar] [CrossRef] [Scilit]
- Wolpert, D.H. The lack of a priori distinctions between learning algorithms. Neural Comput. 1996, 8, 1391–1420. [Google Scholar] [CrossRef] [Scilit]
- Duda, R.O.; Hart, P.E.; Stork, D.G. Pattern Classification; John Wiley & Sons: New York, NY, USA, 2001; ISBN 0-476-05669-3. [Google Scholar]
- Rashedi, E.; Nezamabadi-pour, H.; Saryazdi, S. GSA: A Gravitational Search Algorithm. Inf. Sci. 2009, 179, 2232–2248. [Google Scholar] [CrossRef] [Scilit]
- Rashedi, E.; Rashedi, E.; Nezamabadi-pour, H. A comprehensive survey on gravitational search algorithm. Swarm Evolut. Comput. 2018, 41, 141–158. [Google Scholar] [CrossRef] [Scilit]
- Aziz, N.A.A.; Ibrahim, Z.; Mubin, M.; Sudin, S. Adaptive switching gravitational search algorithm: An attempt to improve diversity of gravitational search algorithm through its iteration strategy. Sādhanā 2017, 42, 1103–1121. [Google Scholar] [CrossRef] [Scilit]
- Pelusi, D.; Mascella, R.; Tallini, L. A fuzzy Gravitational Search Algorithm to Design Optimal IIR Filters. Energies 2018, 11, 736. [Google Scholar] [CrossRef] [Scilit]
- Pelusi, D.; Mascella, R.; Tallini, L.; Nayak, J.; Naik, B.; Abraham, A. Neural network and fuzzy system for the tuning of Gravitational Search Algorithm parameters. Expert Syst. Appl. 2018, 102, 234–244. [Google Scholar] [CrossRef] [Scilit]
- Pelusi, D.; Mascella, R.; Tallini, L. Revised gravitational search algorithms based on evolutionary-fuzzy systems. Algorithms 2017, 10, 44. [Google Scholar] [CrossRef] [Scilit]
- Tsai, H.-C.; Tyan, Y.-Y.; Wu, Y.-W.; Lin, Y.-H. Gravitational particle swarm. Appl. Math. Comput. 2013, 219, 9106–9117. [Google Scholar] [CrossRef] [Scilit]
- Yin, B.; Guo, Z.; Liang, Z.; Yue, X. Improved gravitational search algorithm with crossover. Comput. Electr. Eng. 2018, 66, 505–516. [Google Scholar] [CrossRef] [Scilit]
- Bahrololoum, A.; Nezamabadi-pour, H.; Bahrololoum, H.; Saeed, M. A prototype classifier based on gravitational search algorithm. Appl. Soft Comput. 2012, 12, 819–825. [Google Scholar] [CrossRef] [Scilit]
- Zhao, F.; Xue, F.; Zhang, Y.; Ma, W.; Zhang, C.; Song, H. A hybrid algorithm based on self-adaptive gravitational search algorithm and differential evolution. Expert Syst. Appl. 2018, 113, 515–530. [Google Scholar] [CrossRef] [Scilit]
- Kumar, P.G.; Devaraj, D. Fuzzy Classifier Design using Modified Genetic Algorithm. Int. J. Comput. Intell. Syst. 2010, 3, 334–342. [Google Scholar] [CrossRef] [Scilit]
- Chang, X.; Lilly, J.H. Evolutionary design of a fuzzy classifier from data. IEEE Trans. Syst. Man. Cybern. B Cybern. 2004, 34, 1894–1906. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Olivas, F.; Valdez, F.; Castillo, O. Fuzzy classification system design using PSO with dynamic parameter adaptation through fuzzy logic. Stud. Comput. Intell. 2015, 574, 29–47. [Google Scholar] [CrossRef] [Scilit]
- Chen, T.; Shen, Q.; Su, P.; Shang, C. Fuzzy rule weight modification with particle swarm optimization. Soft Comput. 2016, 20, 2923–2937. [Google Scholar] [CrossRef] [Scilit]
- Hodashinsky, I.A.; Bardamova, M.B. Tuning fuzzy systems parameters with chaotic particle swarm optimization. J. Phys. Conf. Ser. 2017, 803, 012053. [Google Scholar] [CrossRef] [Scilit]
- Pulkkinen, P.; Koivisto, H. Identification of interpretable and accurate fuzzy classifiers and function estimators with hybrid methods. Appl. Soft Comput. 2007, 7, 520–533. [Google Scholar] [CrossRef] [Scilit]
- Aydogan, E.K.; Karaoglan, I.; Pardalos, P.M. hGA: Hybrid genetic algorithm in fuzzy rule-based classification systems for high-dimensional problems. Appl. Soft Comput. 2012, 12, 800–806. [Google Scholar] [CrossRef] [Scilit]
- Mekh, M.A.; Hodashinsky, I.A. Comparative analysis of differential evolution methods to optimize parameters of fuzzy classifiers. J. Comput. Syst. Sci. Int. 2017, 56, 616–626. [Google Scholar] [CrossRef] [Scilit]
- Alcala-Fdez, J.; Alcala, R.; Herrera, F. A fuzzy association rule-based classification model for high-dimensional problems with genetic rule selection and lateral tuning. IEEE Trans. Fuzzy Syst. 2011, 19, 857–872. [Google Scholar] [CrossRef] [Scilit]
- Fazzolari, M.; Alcala, R.; Herrera, F. A multi-objective evolutionary method for learning granularities based on fuzzy discretization to improve the accuracy-complexity trade-off of fuzzy rule-based classification systems: D-MOFARC algorithm. Appl. Soft Comput. 2014, 24, 470–481. [Google Scholar] [CrossRef] [Scilit]
- Alkuhlani, A.; Nassef, M.; Farag, I. Multistage feature selection approach for high-dimensional cancer data. Soft Comput. 2017, 21, 6895–6906. [Google Scholar] [CrossRef] [Scilit]
- Kohavi, R.; John, G.H. Wrappers for feature subset selection. Artif. Intell. 1997, 97, 273–324. [Google Scholar] [CrossRef] [Scilit]
- Dash, M.; Liu, H. Feature selection for classification. Intell. Data Anal. 1997, 1, 131–156. [Google Scholar] [CrossRef] [Scilit]
- Torkkola, K. Information-theoretic methods. Stud. Fuzz. Soft Comput. 2006, 207, 167–185. [Google Scholar] [CrossRef] [Scilit]
- Veerabhadrappa; Rangarajan, L. Multi-level dimensionality reduction methods using feature selection and feature extraction. Int. J. Artif. Intell. Appl. 2010, 1, 54–68. [Google Scholar] [CrossRef] [Scilit]
- Yusta, S.C. Different Metaheuristic Strategies to Solve The Feature Selection Problem. Pattern Recognit. Lett. 2009, 30, 525–534. [Google Scholar] [CrossRef] [Scilit]
- Pedergnana, M.; Marpu, P.R.; Dalla Mura, M.; Benediktsson, J.A.; Bruzzone, L. A novel technique for optimal feature selection in attribute profiles based on genetic algorithms. IEEE Trans. Geosci. Remote Sens. 2013, 51, 3514–3528. [Google Scholar] [CrossRef]
- Aladeemy, M.; Tutun, S.; Khasawneh, M.T. A New Hybrid Approach for Feature Selection and Support Vector Machine Model Selection Based on Self-Adaptive Cohort Intelligence. Expert Syst. Appl. 2017, 88, 118–131. [Google Scholar] [CrossRef] [Scilit]
- Hodashinsky, I.A.; Mekh, M.A. Fuzzy Classifier Design Using Harmonic Search Methods. Programm. Comput. Soft. 2017, 43, 37–46. [Google Scholar] [CrossRef] [Scilit]
- Vieira, S.M.; Sousa, J.M.C.; Runkler, T.A. Ant colony optimization applied to feature selection in fuzzy classifiers. Lect. Notes Comput. Sci. 2007, 4529, 778–788. [Google Scholar] [CrossRef] [Scilit]
- Gurav, A.; Nair, V.; Gupta, U.; Valadi, J. Glowworm Swarm Based Informative Attribute Selection Using Support Vector Machines for Simultaneous Feature Selection and Classification. Lect. Notes Comput. Sci. 2015, 8947, 27–37. [Google Scholar] [CrossRef] [Scilit]
- Marinaki, M.; Marinakis, Y.; Zopounidis, C. Honey Bees Mating Optimization algorithm for financial classification problems. Appl. Soft Comput. 2010, 10, 806–812. [Google Scholar] [CrossRef] [Scilit]
- Rashedi, E.; Nezamabadi-pour, H. Feature subset selection using improved binary gravitational search algorithm. J. Intell. Fuzzy Syst. 2014, 26, 1211–1221. [Google Scholar] [CrossRef] [Scilit]
- Mirjalili, S.; Lewis, A. S-shaped versus V-shaped transfer functions for binary Particle Swarm Optimization. Swarm Evolut. Comput. 2013, 9, 1–14. [Google Scholar] [CrossRef] [Scilit]
- De Gregorio, M.; Giordano, M. An experimental evaluation of weightless neural networks for multi-class classification. Appl. Soft Comput. 2018, 72, 338–354. [Google Scholar] [CrossRef] [Scilit]
- Pelusi, D.; Elmougy, S.; Tallini, L.; Bose, B. m-ary Balanced Codes with Parallel Decoding. IEEE Trans. Inf. Theory 2015, 61, 3251–3264. [Google Scholar] [CrossRef] [Scilit]

© 2018 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (http://creativecommons.org/licenses/by/4.0/).