Article

SESQ: Spatially Aware Encoding and Semantically Guided Querying for 3D Grounding

1
School of Computer Engineering, Jimei University, Xiamen 361000, China
2
Xiamen Taqu Information Technology Co., Ltd., Xiamen 361000, China
*
Authors to whom correspondence should be addressed.
Computers 2026, 15(3), 145; https://doi.org/10.3390/computers15030145

Submission received: 25 January 2026 / Revised: 13 February 2026 / Accepted: 14 February 2026 / Published: 1 March 2026
(This article belongs to the Special Issue Advanced Image Processing and Computer Vision (2nd Edition))

Abstract

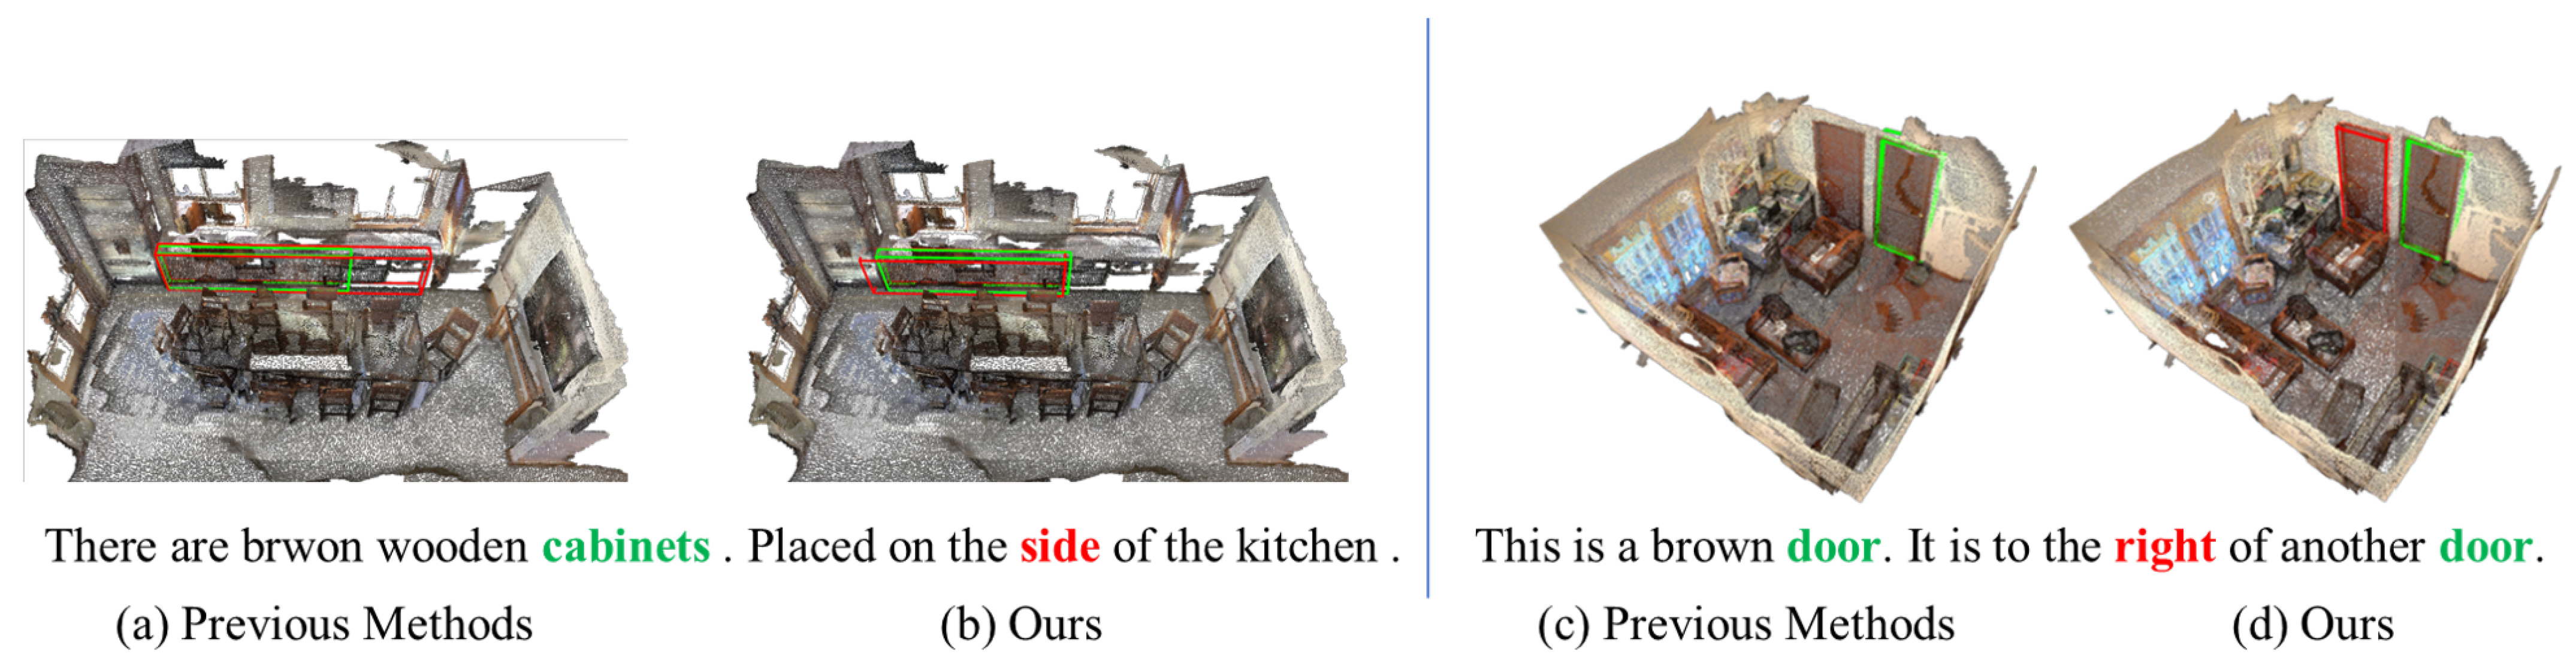
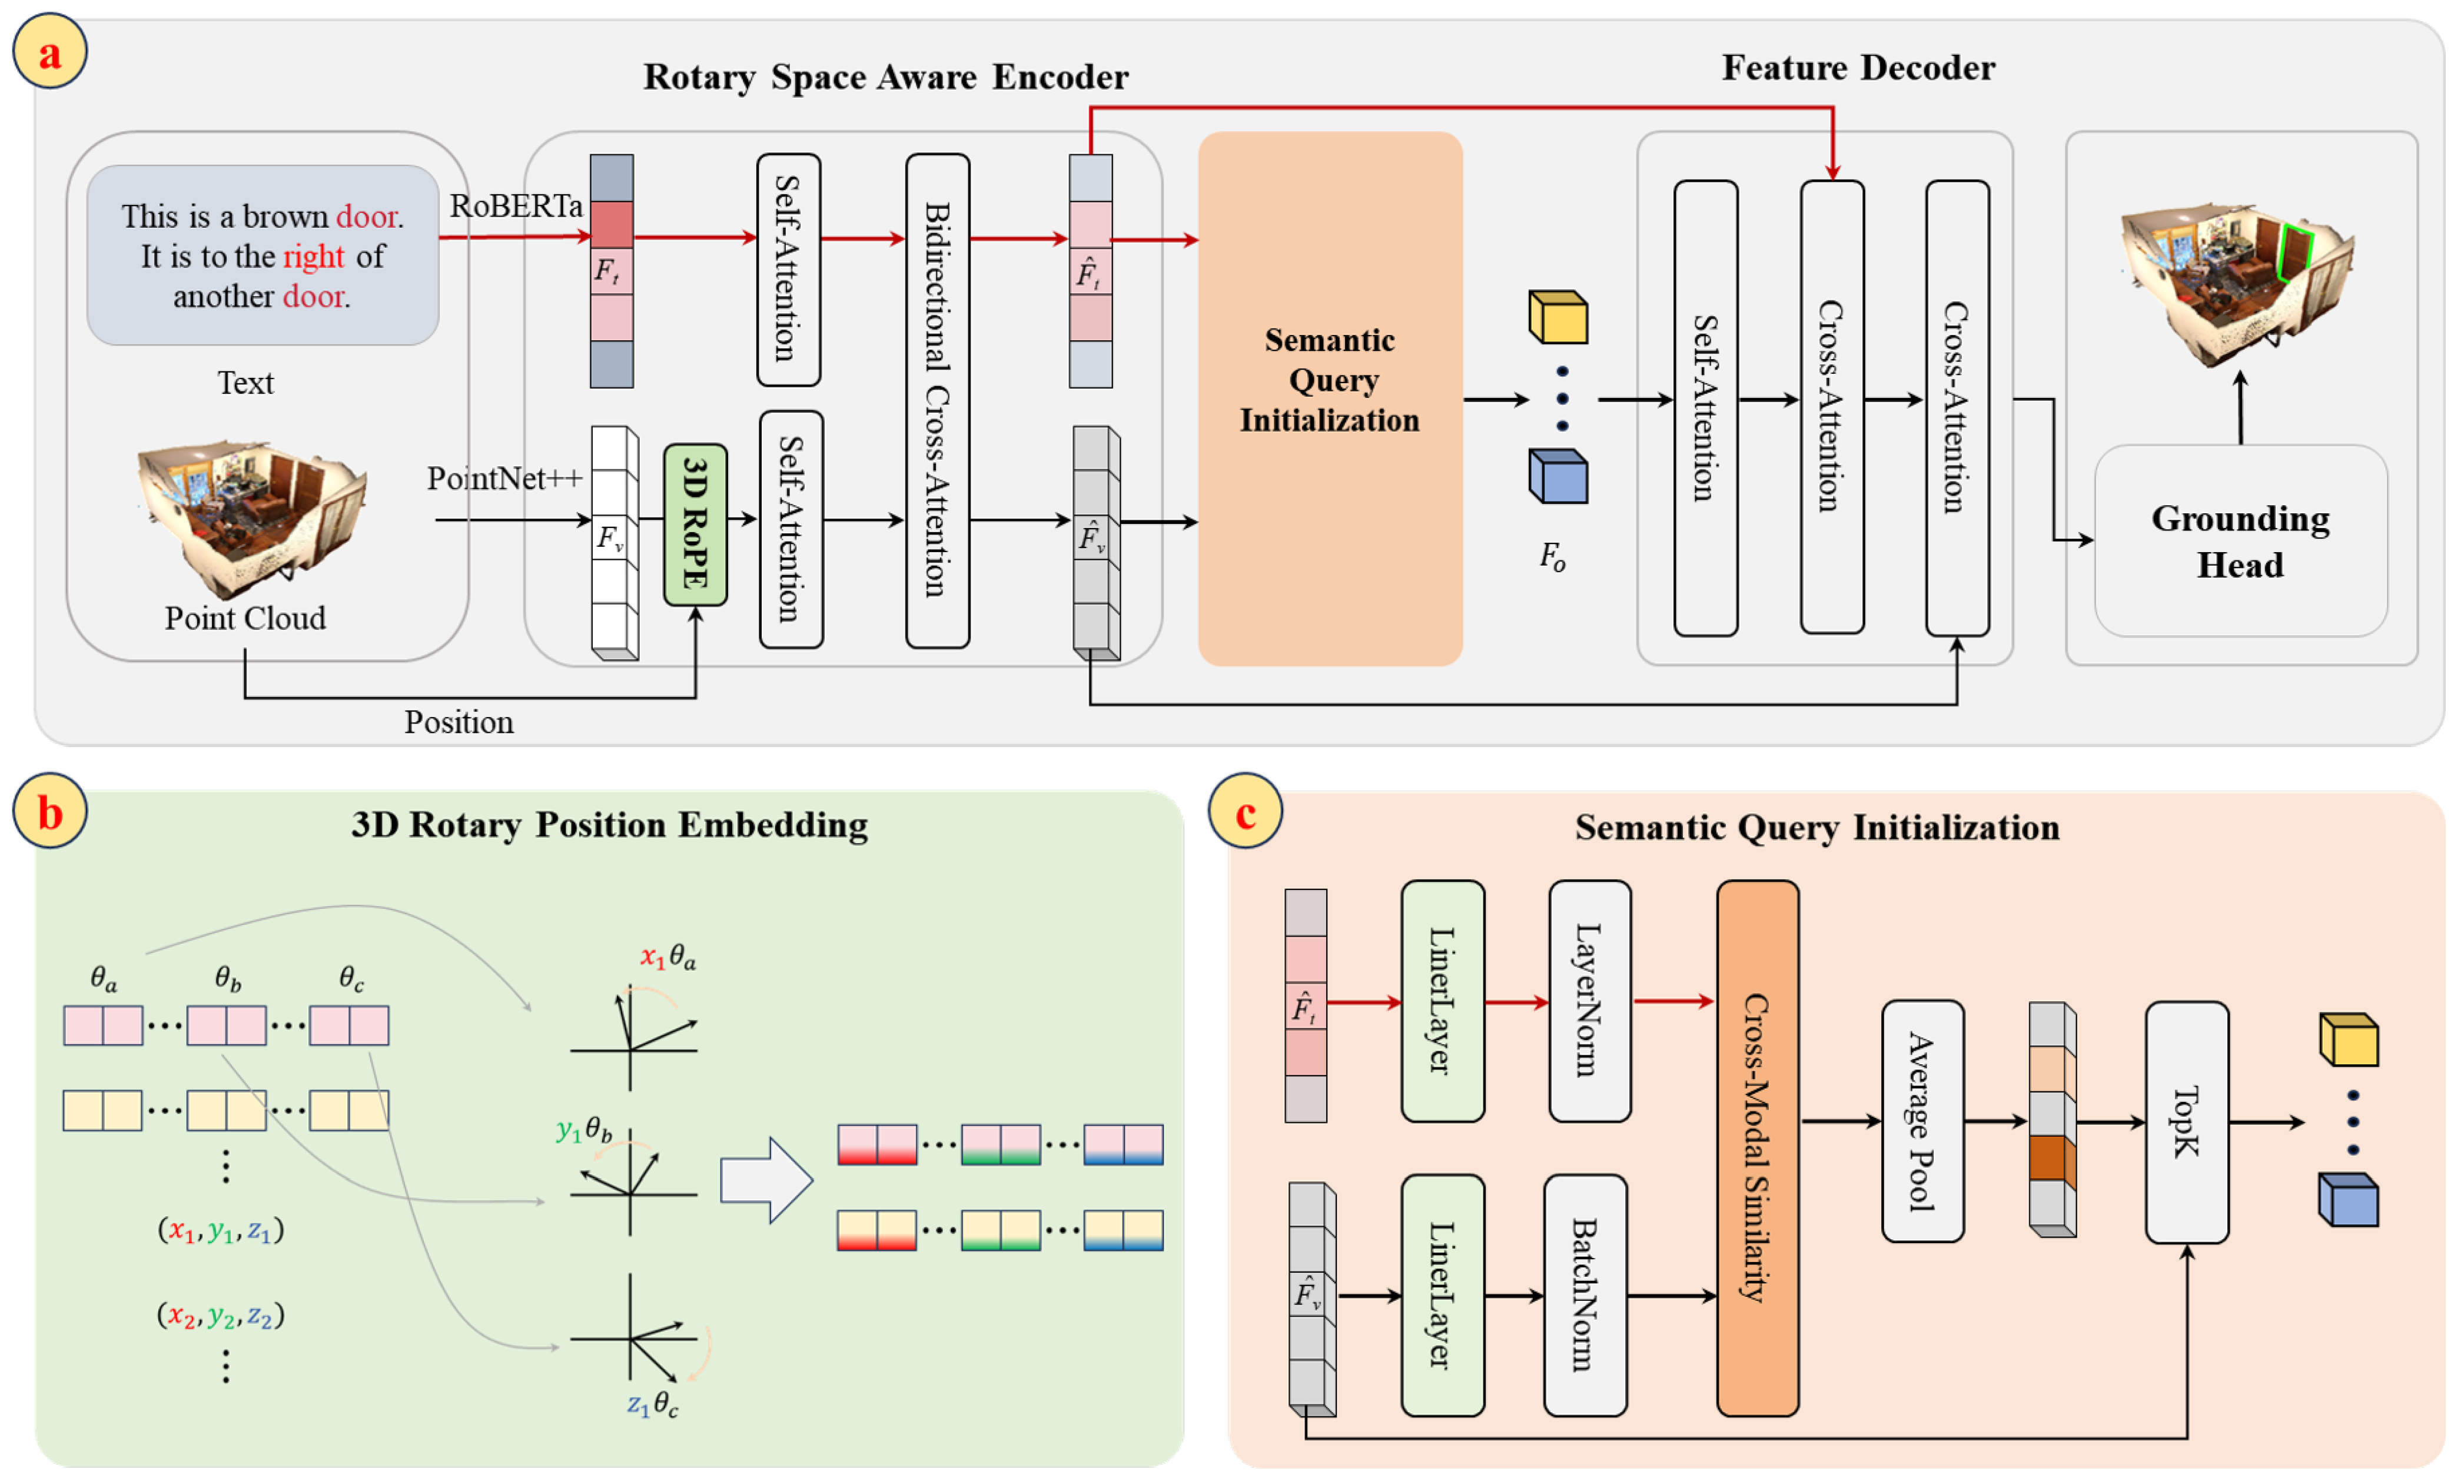
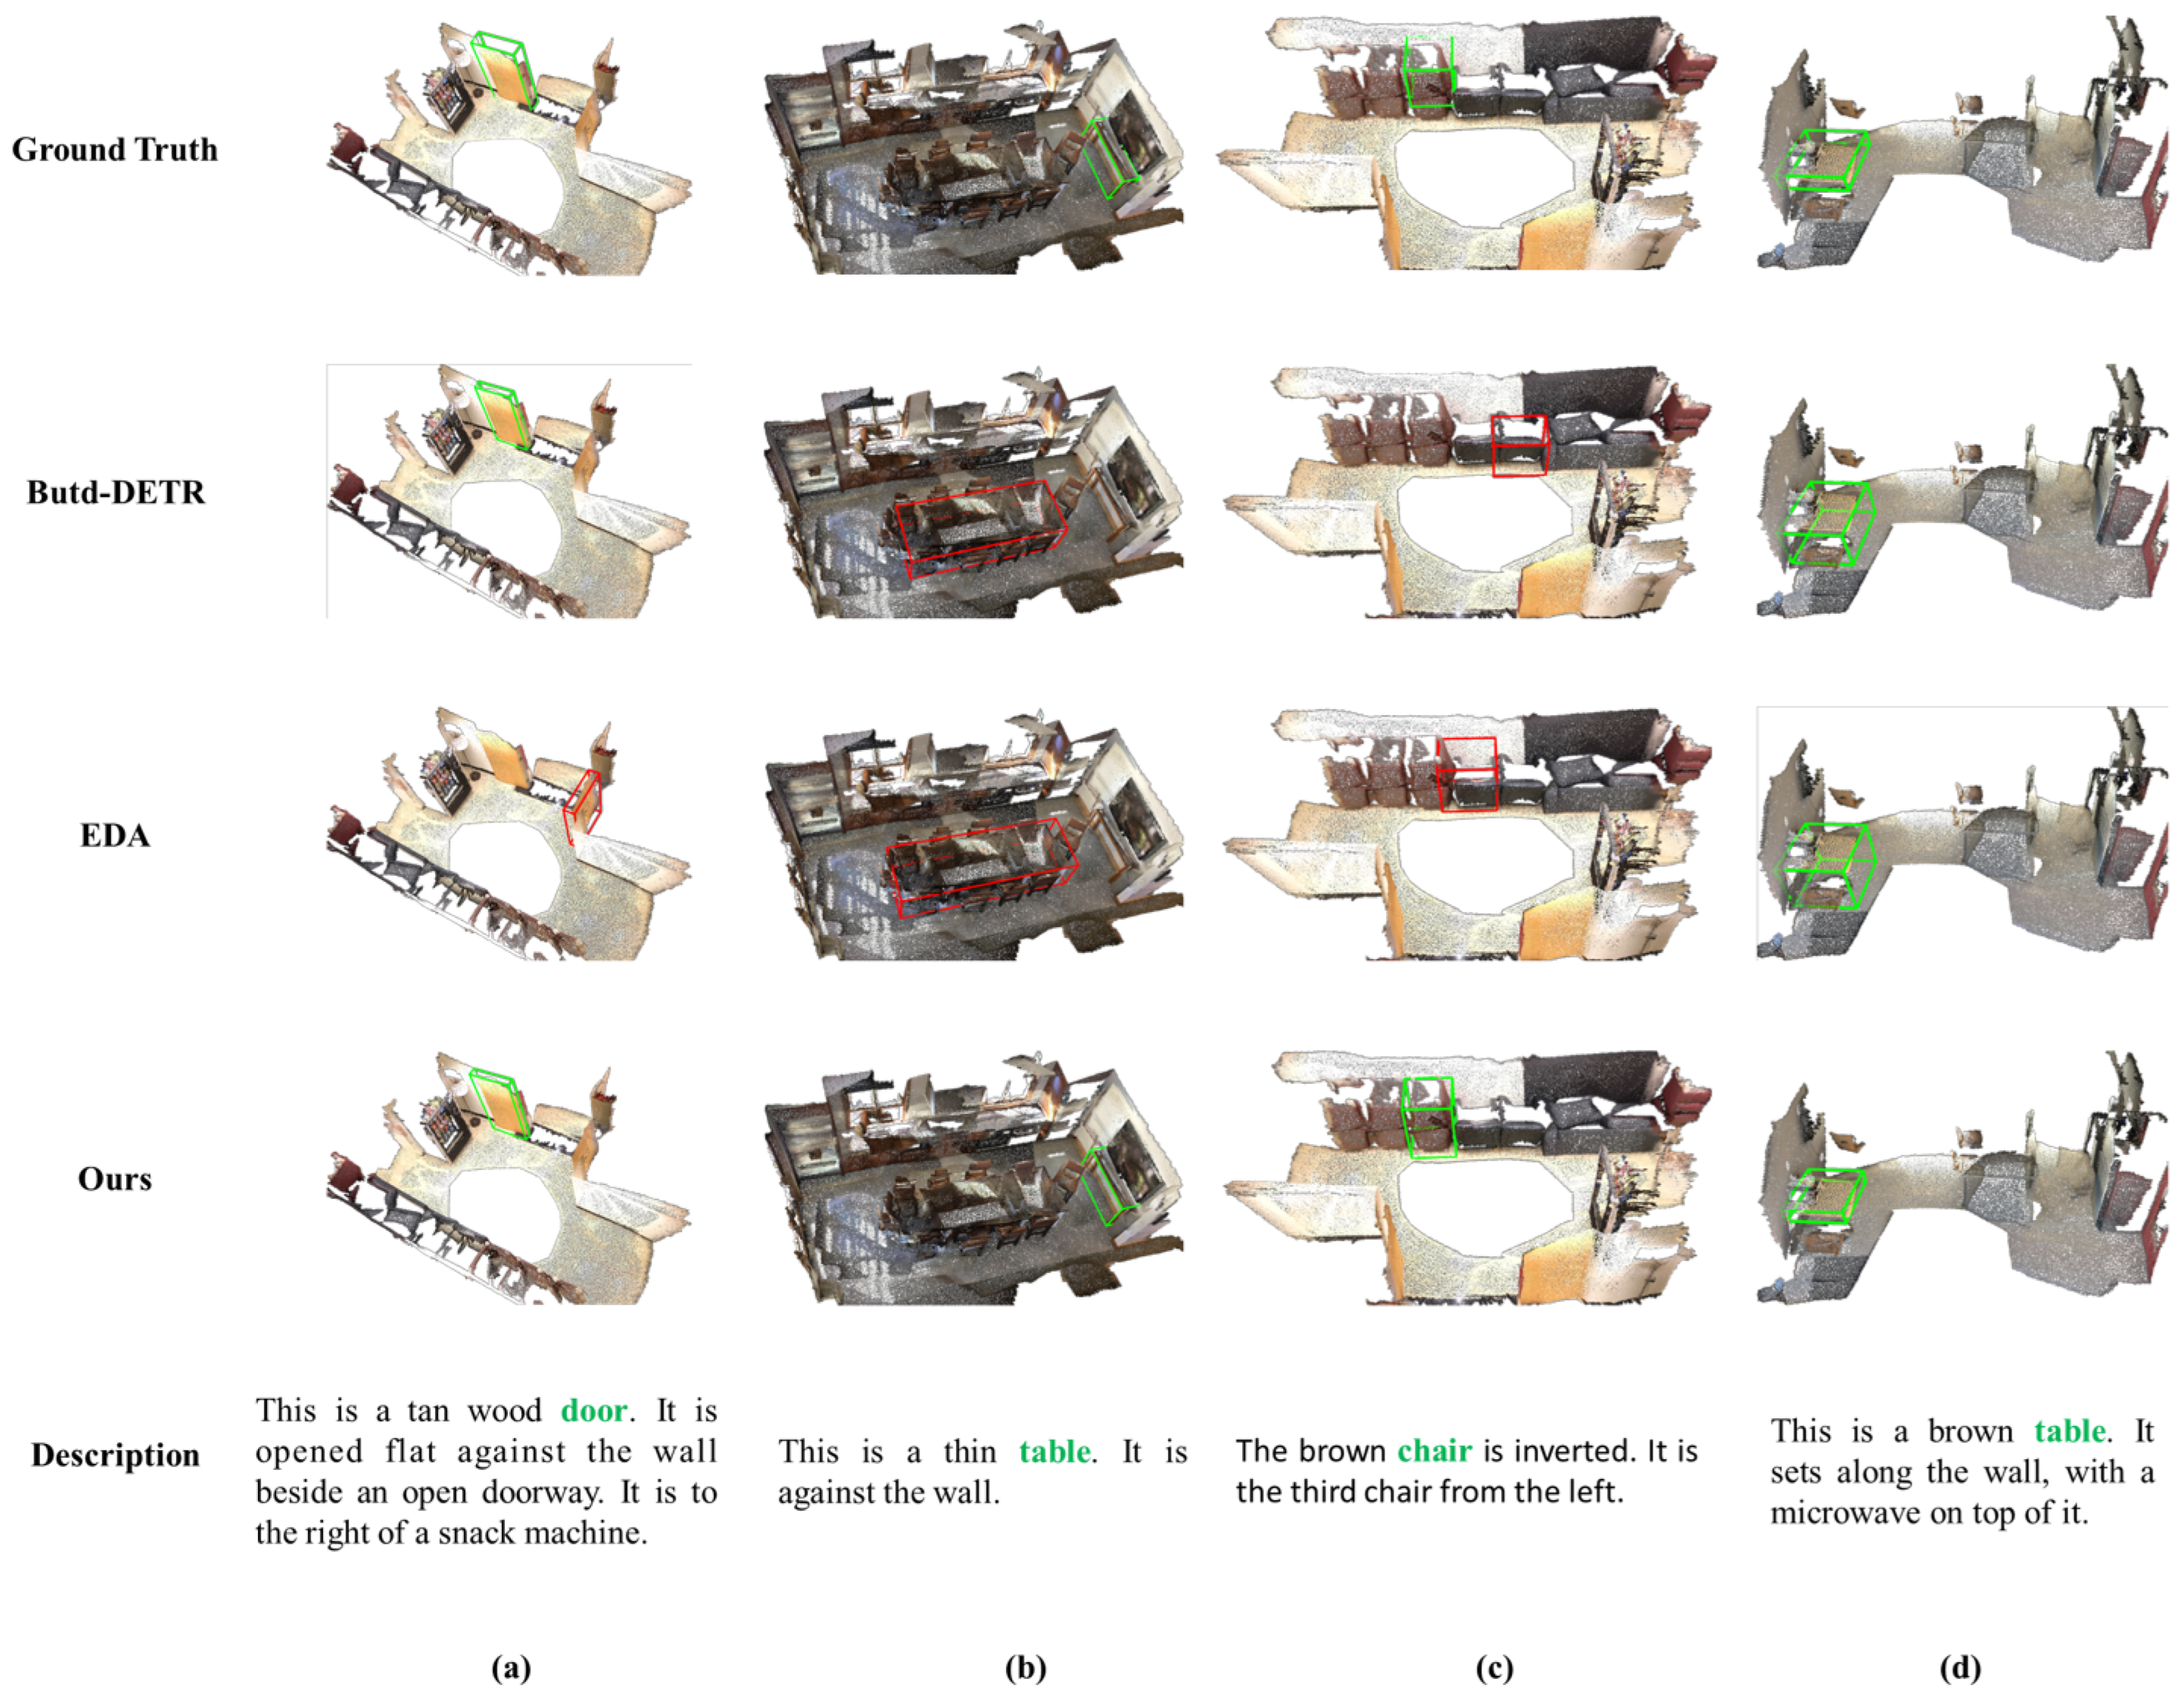
3D visual grounding is a fundamental task for human–machine interaction, aiming to localize specific objects in complex 3D point clouds based on natural language descriptions. Despite recent advancements, existing Transformer-based architectures often rely on absolute position embeddings and heuristic query initialization, which lack the capacity to capture fine-grained relative spatial dependencies and fail to effectively filter out scene clutter. In this paper, we propose SESQ, a novel framework that synergizes Spatially Aware Encoding and Semantically Guided Querying for 3D grounding. Our approach introduces two key innovations. First, we propose the Rotary Spatially Aware Encoder (RSAE), which incorporates Rotary Position Embeddings (RoPE) into the self-attention layers. By transforming 3D coordinates into a rotary representation, RSAE enables the model to inherently capture relative spatial distances and maintains geometric consistency throughout the encoding stage. Second, a Semantic Query Initialization (SQI) module is designed to initialize object queries by explicitly computing the cross-modal similarity between textual embeddings and visual point cloud features. By replacing traditional heuristic-based selection with semantic-aware alignment, SQI ensures that the decoding process originates from contextually relevant object candidates, significantly reducing the impact of task-irrelevant distractors. Extensive experiments on ScanRefer and ReferIt3D (Nr3D/Sr3D) benchmarks demonstrate the effectiveness of our framework. Compared to the baseline EDA, our method achieves a significant performance gain of 2.68% in overall Acc@0.5 on ScanRefer, a 4.9% improvement on the challenging Nr3D “Hard” subset, and a 1.1% increase in overall Acc@0.25 on Sr3D.
Keywords: 3D visual grounding; point cloud; semantic understanding; spatial reasoning 3D visual grounding; point cloud; semantic understanding; spatial reasoning