ChangePixel: Pixel-Level Evidence-Grounded Disaster Change Narration via Single-Backbone Transfer


Highlights
- ChangePixel upgrades remote sensing change captioning into pixel-level disaster change narration using a single grounding backbone.
- BCTA, CRGP, and WAB produce mask–phrase evidence while preserving competitive caption quality without manual grounding labels.
- Disaster change captions become more traceable by linking generated descriptions to explicit changed-region evidence.
- Dedicated phrase-to-region benchmarks are needed to evaluate grounded remote sensing change narration.
Abstract
1. Introduction
- 1.
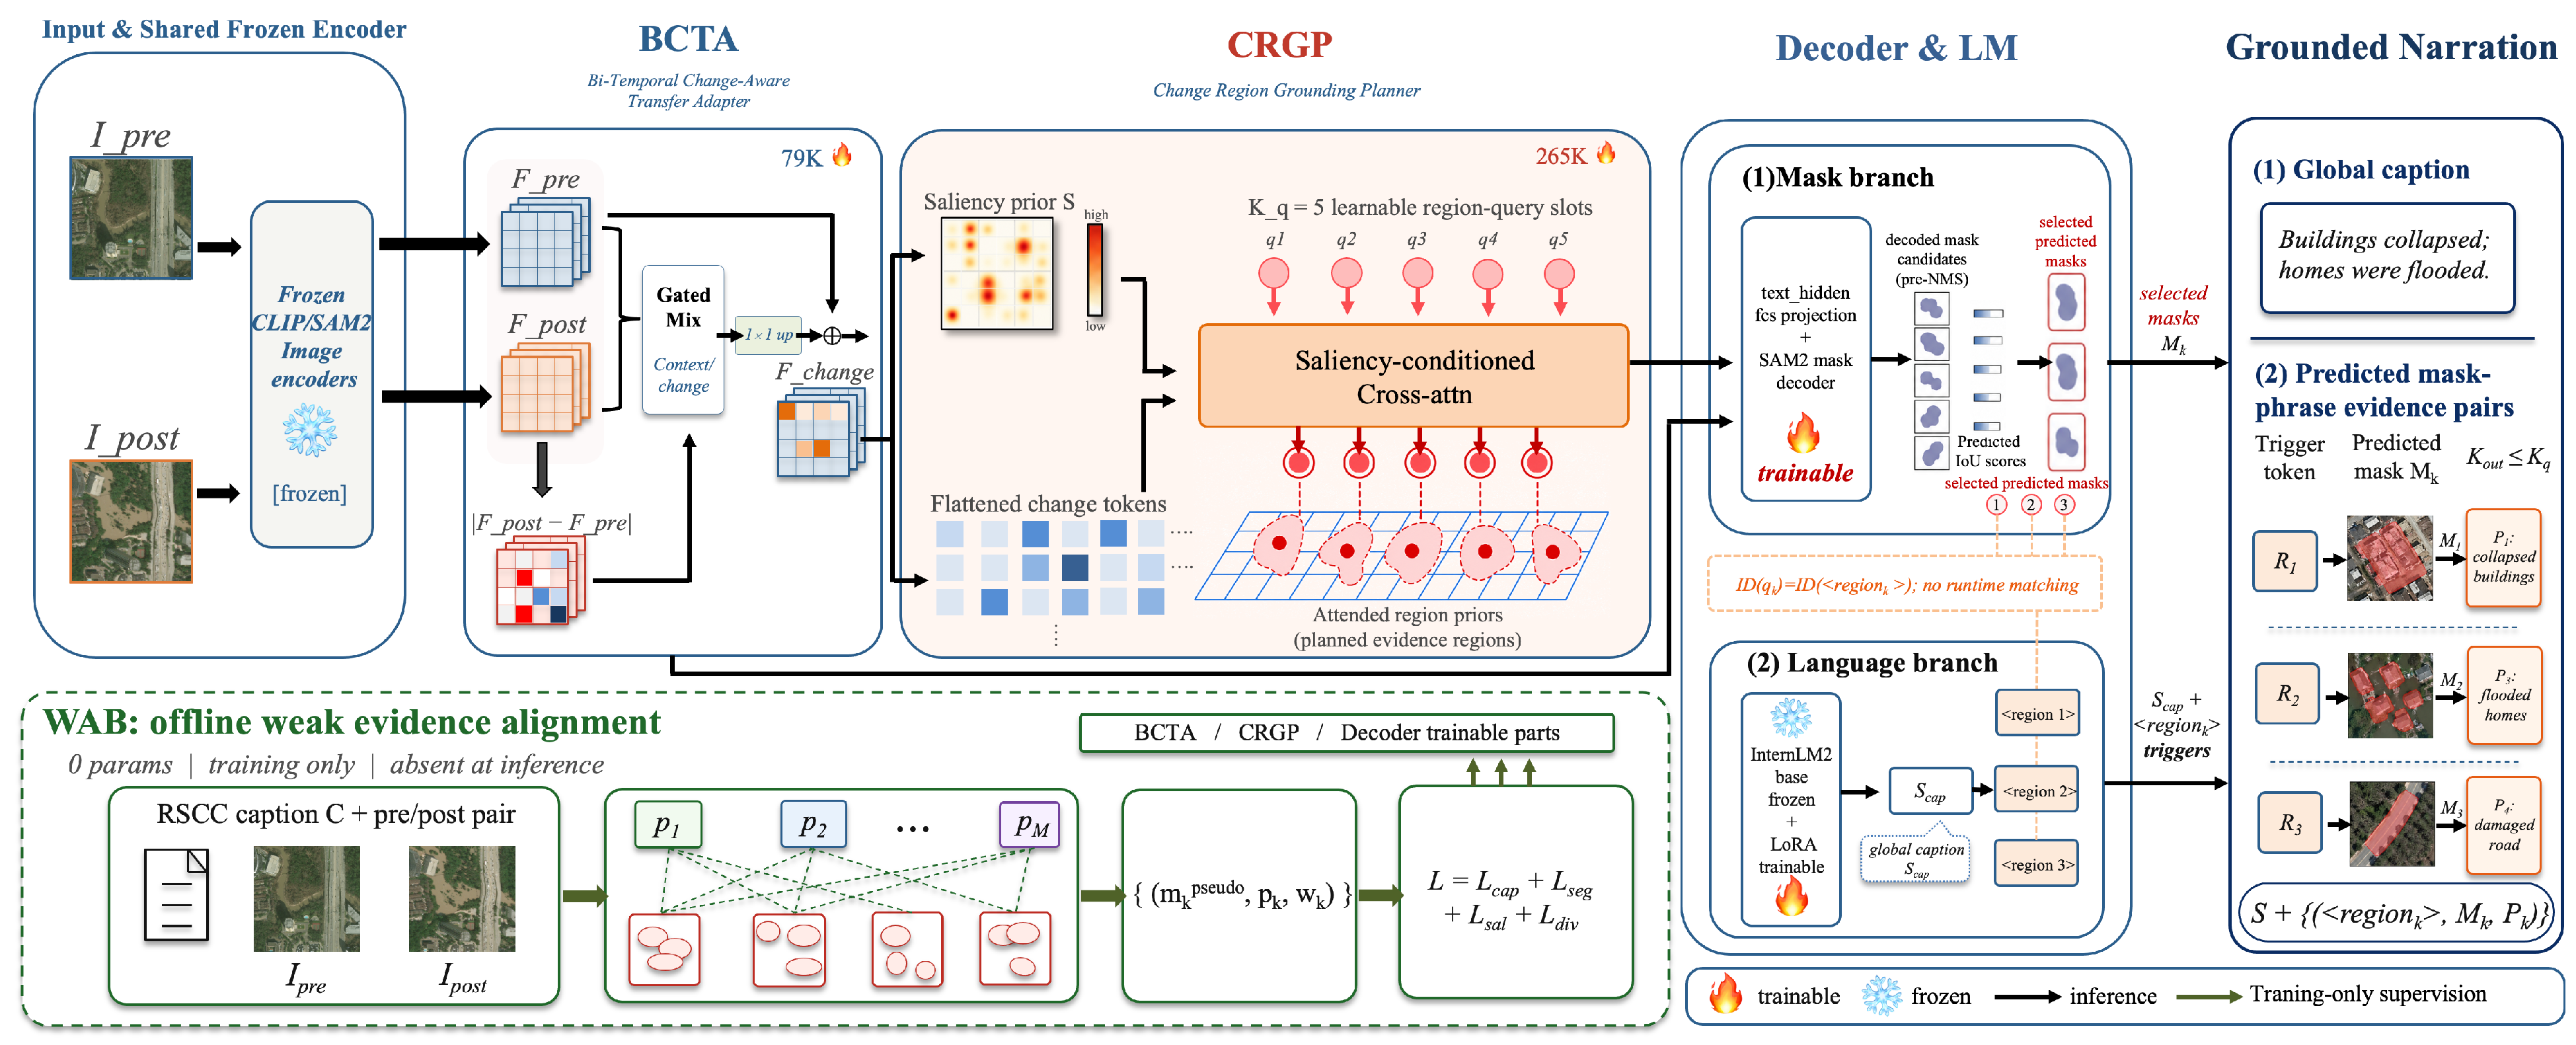
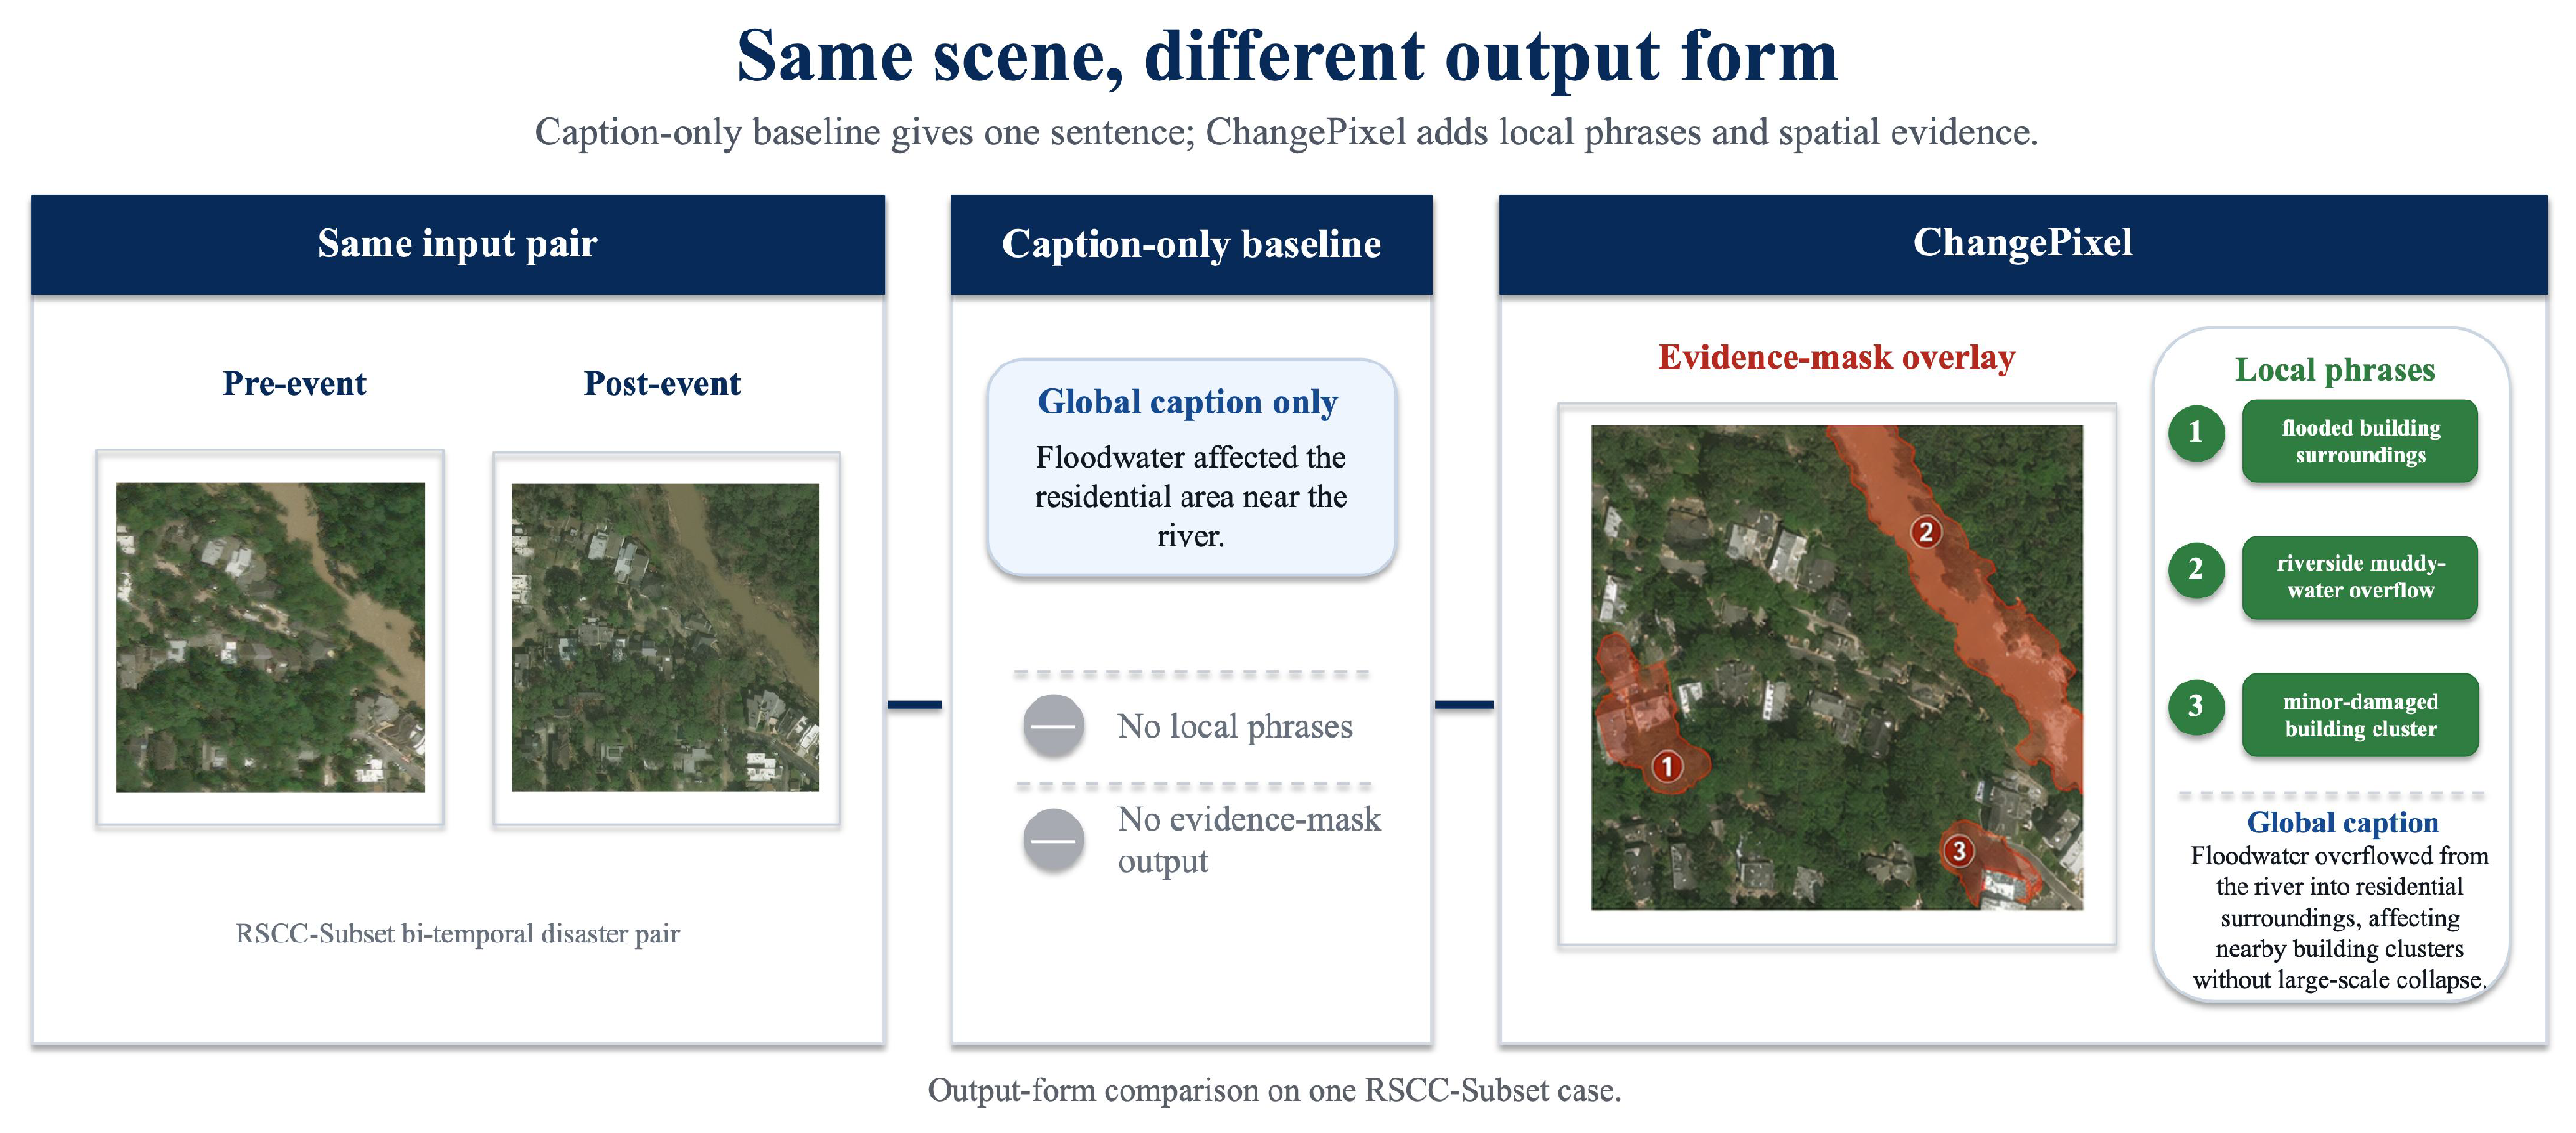
- We present ChangePixel, a single-backbone framework that upgrades remote sensing change captioning into pixel-level, evidence-grounded change narration and jointly produces a global change description together with region masks and corresponding local phrases without introducing new manual grounding labels.
- 2.
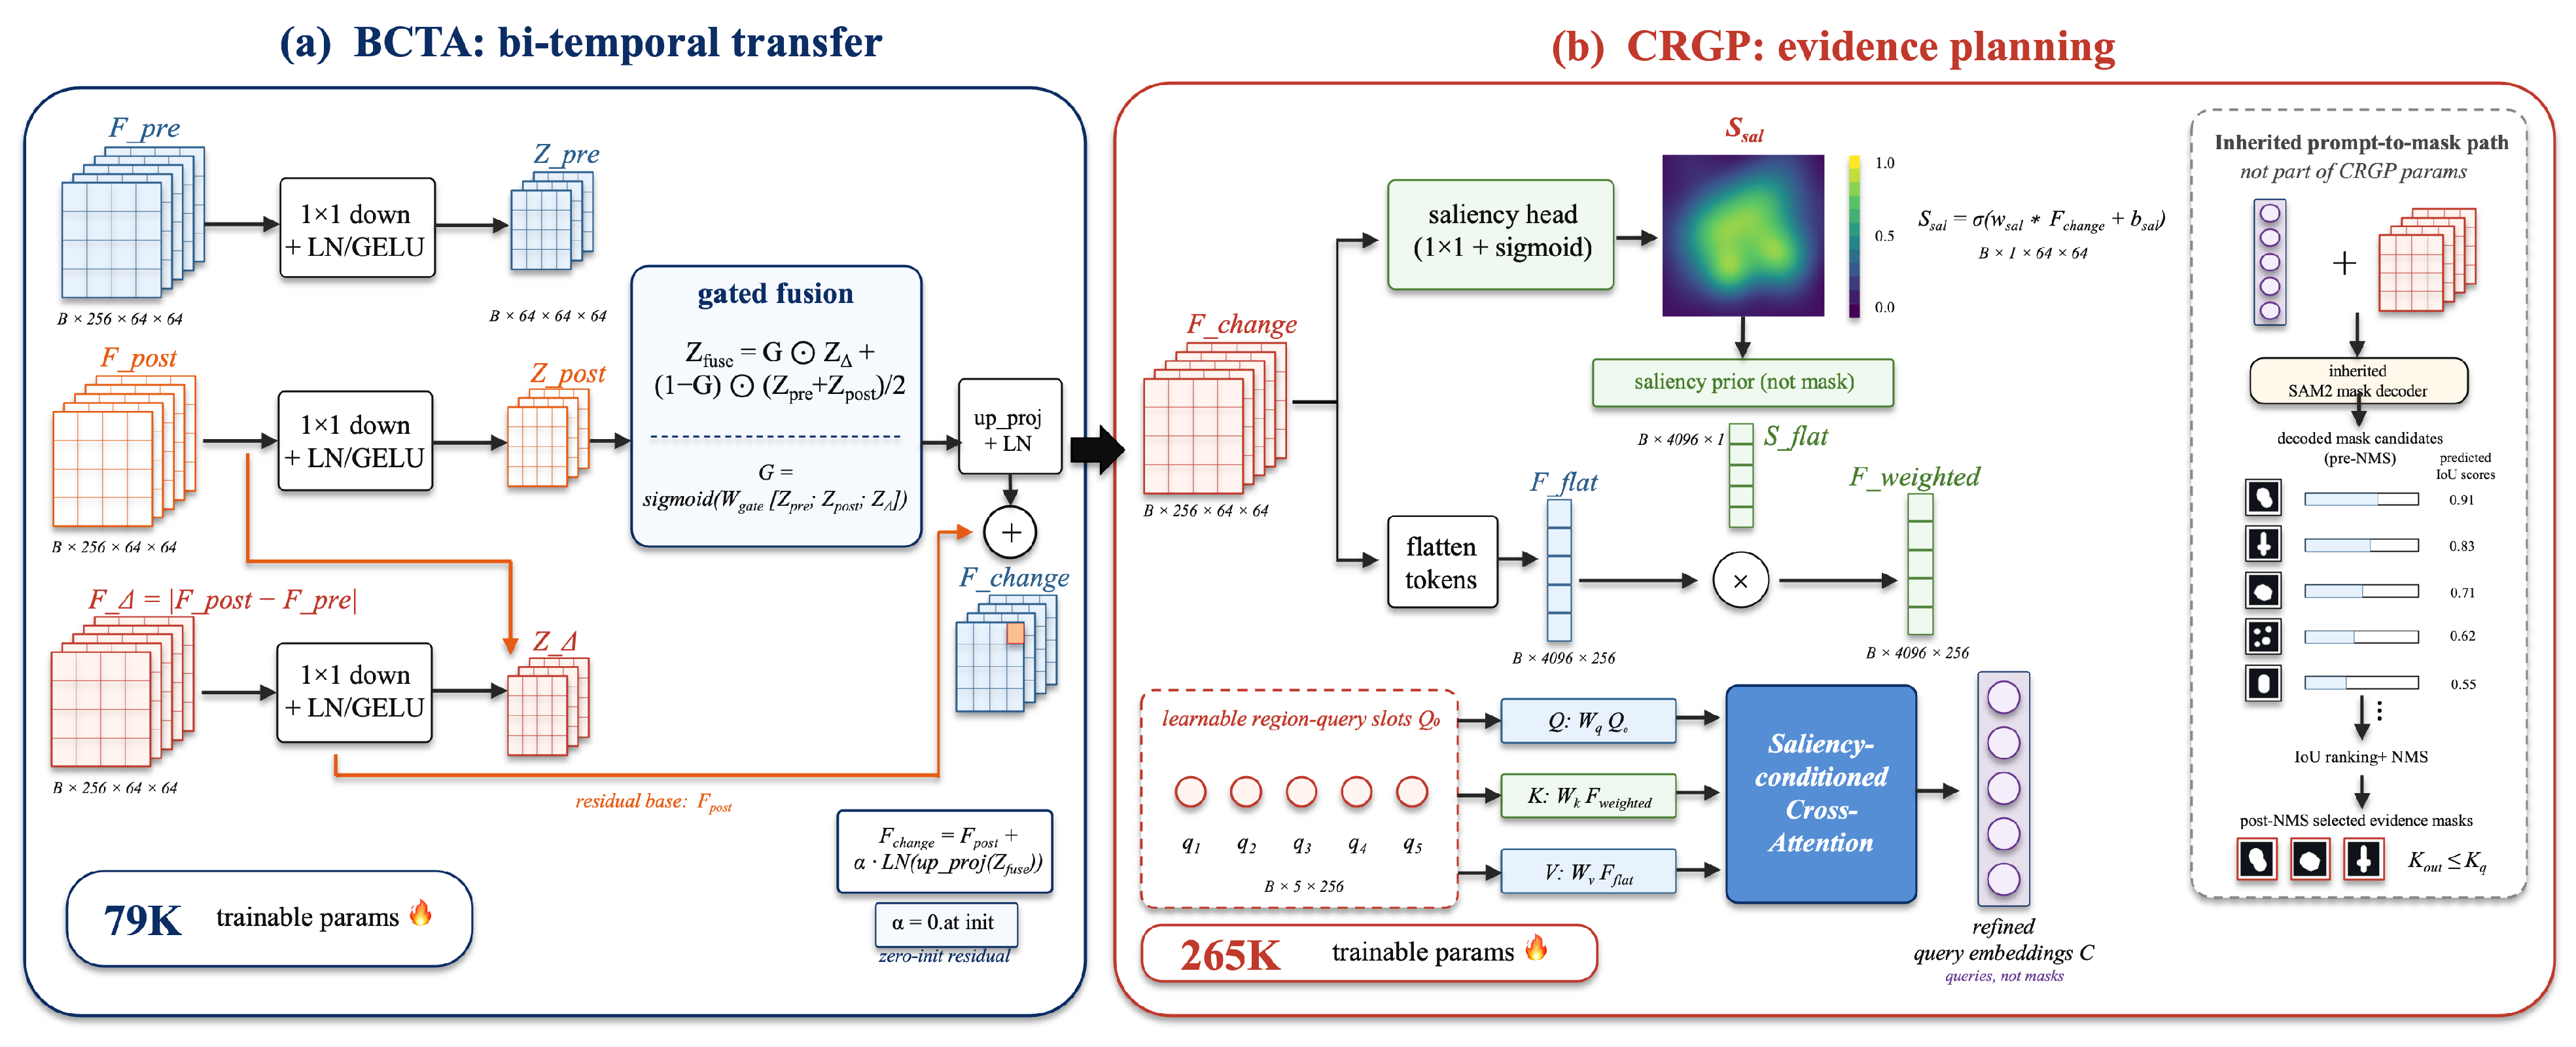
- We introduce two lightweight mechanisms, BCTA and CRGP, which extend single-image grounding to bi-temporal change-aware grounding through bottleneck-gated temporal fusion and saliency-conditioned region planning, adding only a small number of new trainable parameters without requiring a second backbone.
- 3.
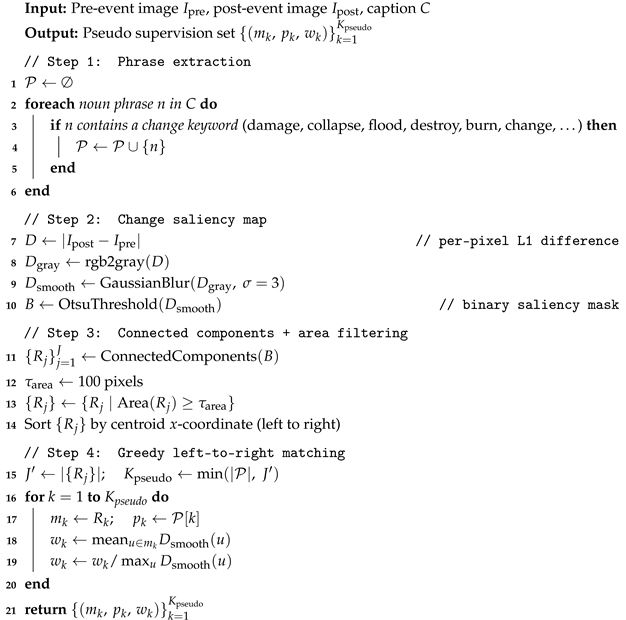
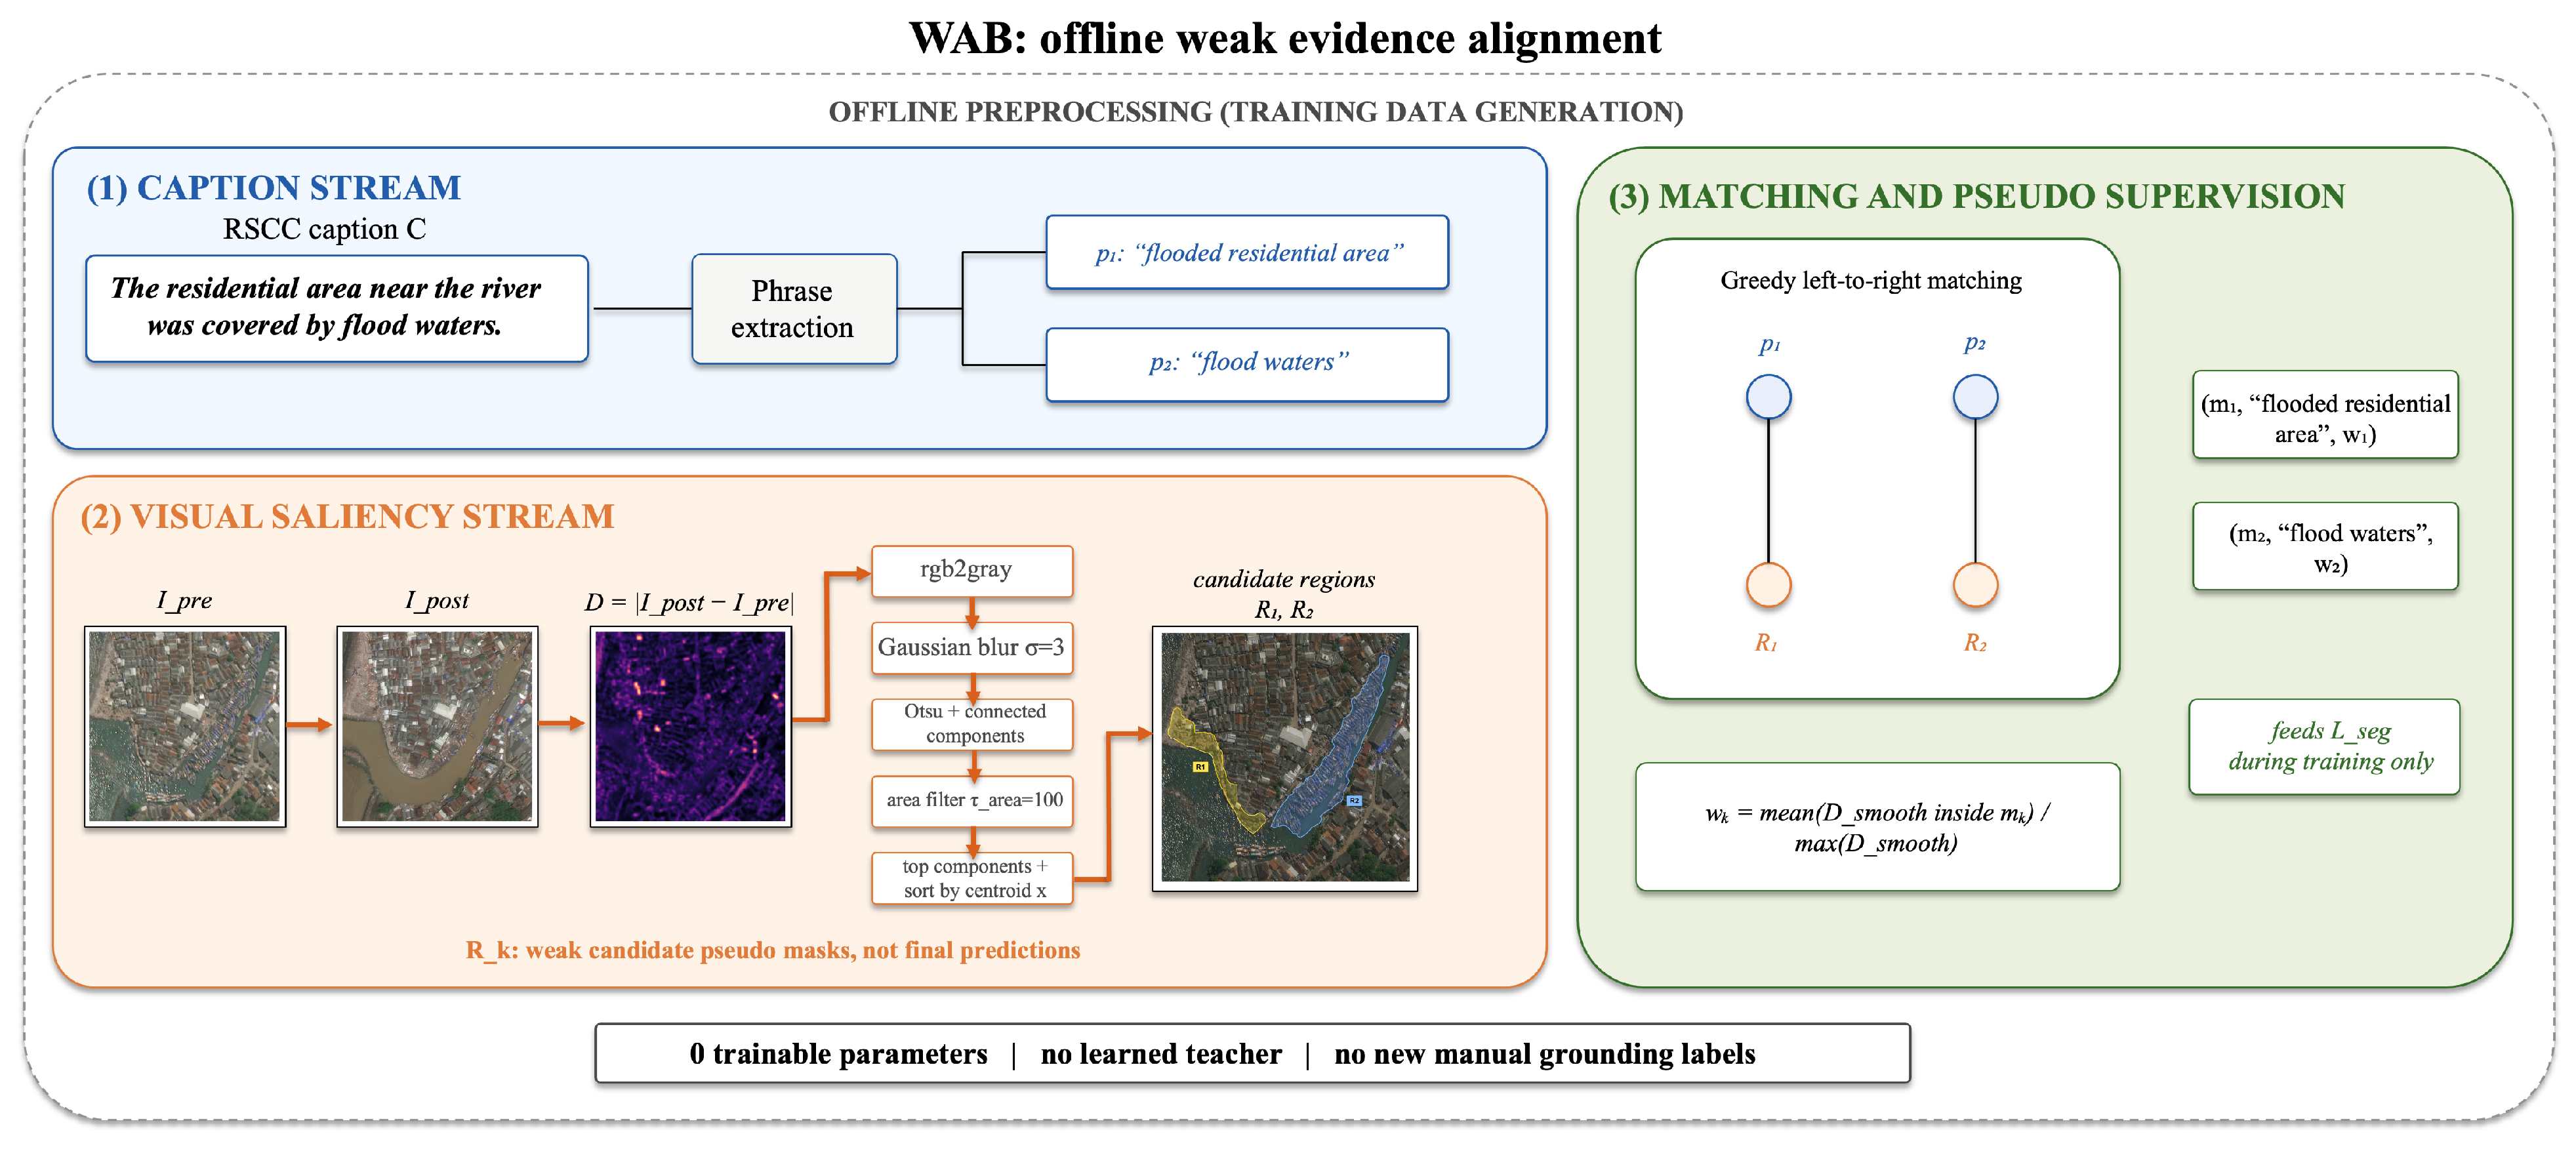
- We design a weak evidence alignment scheme (WAB) that exploits two RSCC-specific properties—semantically rich localized captions and high-contrast disaster imagery—to construct phrase-to-region supervision without external learned models or manual annotation.
2. Related Work
2.1. Remote Sensing Change Captioning
2.2. Region-Aware Change Captioning
2.3. Remote Sensing Grounded Vision–Language Models
2.4. Natural Image Grounded Narration
3. Method
3.1. Problem Formulation
3.2. GeoPixel Backbone
3.3. Bi-Temporal Change-Aware Transfer Adapter (BCTA)
3.4. Change Region Grounding Planner (CRGP)
3.5. Weak Evidence Alignment Bridge (WAB)
| Algorithm 1: WAB: Weak Evidence Alignment Bridge |
 |
3.6. Training Objectives
3.7. Implementation Summary
4. Experiments
4.1. Datasets
4.2. Implementation Details
4.3. Evaluation Metrics
4.4. Baselines
- (1)
- (2)
- Group A’ (specialized change captioning) covers CCExpert-7B [4] and TEOChat-7B [5], both trained on domain-specific change captioning datasets. While these models report strong caption quality within their training domains, they may exhibit substantial degradation when transferred to RSCC’s disaster imagery.
- (3)
- Group B (learned RSCC baseline) consists of RSCCM [1], a Qwen2.5-VL-7B model fine-tuned directly on RSCC. This model serves as a strong caption-only reference on the RSCC benchmark and appears only in the RSCC table; it produces no evidence output.
- (4)
- Group C/C’ groups direct competitors and classic methods. ChangeChat [8] is evaluated on RSCC under zero-shot transfer and on LEVIR-CC with its native training domain. RSICCformer [2], Chg2Cap [3], and Change-Agent [22] serve as established LEVIR-CC baselines. SAGE-CC [9] and BTCChat [10] are discussed qualitatively in the competitor comparison (Section 4.5.2) rather than included in the main tables because, as of our experiments, public code was unavailable for consistent reproduction.
- (5)
- Group D (structural ablation) comprises four variants: GeoPixel naive (LoRA-tuned backbone without BCTA, CRGP, or WAB), +BCTA, +BCTA+CRGP, and ChangePixel full. These variants isolate each module’s contribution. We additionally include a non-learned Pixel-Diff baseline (pixel-difference map → Otsu thresholding → connected-component analysis) as an evidence quality floor, providing a lower-bound reference for the evidence metrics.
- (6)
- Group E (supervised change detection references) covers FC-Siam-Diff [32] and BIT [33], both trained on LEVIR-CD with full pixel-level supervision. These domain-specific binary change detection methods provide supervised reference points: they produce accurate change masks but no captions, and their scores contextualize the evidence output of ChangePixel—a captioning system whose evidence maps are trained under weak supervision rather than full pixel-level labels. LEVIR-MCI evidence metrics apply only to methods that actually produce pixel-level masks; in the current design, this layer analyzes the Group D variants alongside Group E reference methods rather than every caption baseline. Caption tables carry explicit source tags (reported or ours); the ablation table specifies provenance in its caption. We do not compute direct score differences across different source types.
4.5. Results
4.5.1. Main Results on RSCC and LEVIR-CC
4.5.2. Comparison with Direct Competitors
4.5.3. Qualitative Analysis
- (1)
- Quality of WAB pseudo supervision.
- (2)
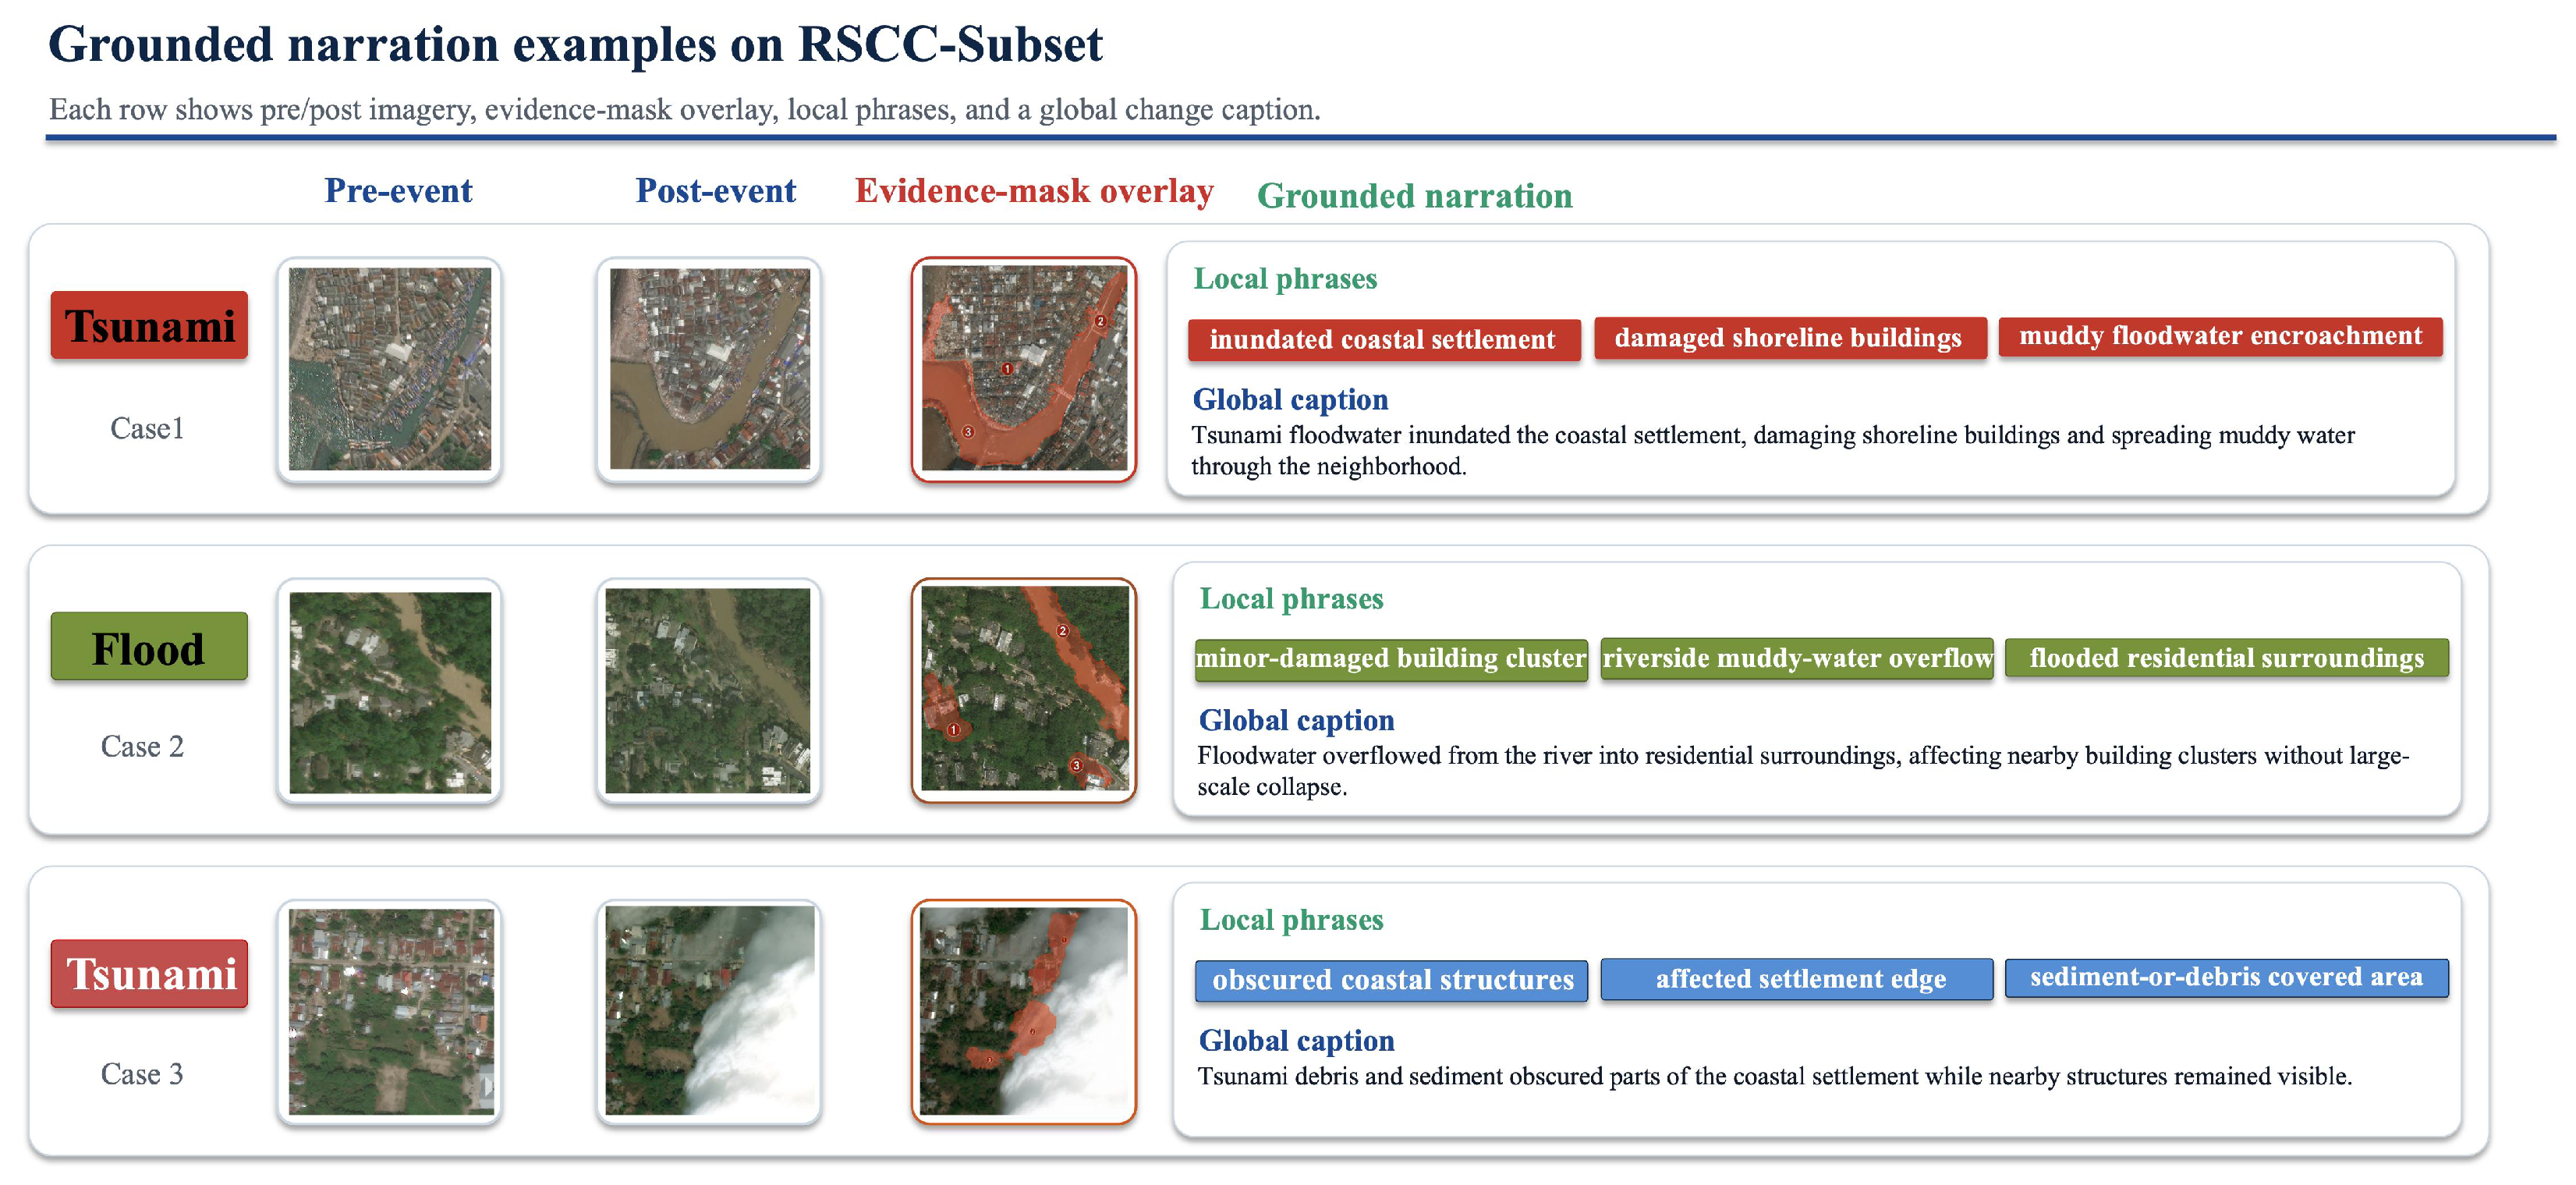
- Grounded narration examples.
4.6. Sensitivity Analysis
4.6.1. Sensitivity to the Number of Region Queries K
4.6.2. Sensitivity to Loss Weights
4.6.3. Additional Sensitivity Analyses
4.7. Ablation Study
5. Discussion
5.1. Why ChangePixel Works
5.2. Evidence as Output, Not Benchmark Claim
5.3. Weak-Supervision Sufficiency
5.4. RSCC Reference Quality
5.5. Limitations
6. Conclusions
Author Contributions
Funding
Data Availability Statement
Conflicts of Interest
Abbreviations
| BCTA | Bi-Temporal Change-Aware Transfer Adapter |
| CRGP | Change Region Grounding Planner |
| WAB | Weak Evidence Alignment Bridge |
| RS | Remote Sensing |
| VLM | Vision–Language Model |
References
- Chen, Z.; Wang, C.; Zhang, N.; Zhang, F. RSCC: A Large-Scale Remote Sensing Change Caption Dataset for Disaster Events. In Proceedings of the Advances in Neural Information Processing Systems (NeurIPS), Datasets and Benchmarks Track, San Diego, CA, USA, 2–7 December 2025. [Google Scholar]
- Liu, C.; Zhao, R.; Chen, H.; Zou, Z.; Shi, Z. Remote Sensing Image Change Captioning with Dual-Branch Transformers: A New Method and a Large-Scale Dataset. IEEE Trans. Geosci. Remote Sens. 2022, 60, 5633520. [Google Scholar] [CrossRef] [Scilit]
- Chang, S.; Ghamisi, P. Changes to Captions: An Attentive Network for Remote Sensing Change Captioning. IEEE Trans. Image Process. 2023, 32, 6047–6060. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, Z.; Wang, M.; Xu, S.; Li, Y.; Zhang, B. CCExpert: Advancing MLLM Capability in Remote Sensing Change Captioning with Difference-Aware Integration and a Foundational Dataset. arXiv 2024, arXiv:2411.11360. [Google Scholar]
- Irvin, J.A.; Liu, E.R.; Chen, J.C.; Dormoy, I.; Kim, J.; Khanna, S.; Zheng, Z.; Ermon, S. TEOChat: A Large Vision-Language Assistant for Temporal Earth Observation Data. arXiv 2024, arXiv:2410.06234. [Google Scholar]
- Shabbir, A.; Zumri, M.; Bennamoun, M.; Khan, F.S.; Khan, S. GeoPixel: Pixel Grounding Large Multimodal Model in Remote Sensing. In Proceedings of the 42nd International Conference on Machine Learning, PMLR, Proceedings of Machine Learning Research, Vancouver, BC, Canada, 13–19 July 2025; Volume 267, pp. 54095–54111. [Google Scholar]
- Hoxha, G.; Chouaf, S.; Melgani, F.; Smara, Y. Change Captioning: A New Paradigm for Multitemporal Remote Sensing Image Analysis. IEEE Trans. Geosci. Remote Sens. 2022, 60, 5627414. [Google Scholar] [CrossRef] [Scilit]
- Deng, P.; Zhou, W.; Wu, H. ChangeChat: An Interactive Model for Remote Sensing Change Analysis via Multimodal Instruction Tuning. arXiv 2024, arXiv:2409.08582. [Google Scholar]
- Wang, F.; Wang, M.; Wang, X.; Wang, H.; Tang, J. SAM Guided Semantic and Motion Changed Region Mining for Remote Sensing Change Captioning. arXiv 2025, arXiv:2511.21420. [Google Scholar]
- Li, Y.; Xu, W.; Zhang, Y.; Wei, Z.; Peng, M. BTCChat: Advancing Remote Sensing Bi-temporal Change Captioning with Multimodal Large Language Model. In Proceedings of the IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), Barcelona, Spain, 4–8 May 2026. [Google Scholar]
- Guo, X.; Lao, J.; Dang, B.; Zhang, Y.; Yu, L.; Ru, L.; Zhong, L.; Huang, Z.; Wu, K.; Hu, D.; et al. SkySense: A Multi-Modal Remote Sensing Foundation Model Towards Universal Interpretation for Earth Observation Imagery. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, WA, USA, 17–21 June 2024. [Google Scholar]
- Soni, S.; Dudhane, A.; Debary, H.; Fiaz, M.; Munir, M.A.; Danish, M.S.; Fraccaro, P.; Watson, C.D.; Klein, L.J.; Khan, F.S.; et al. EarthDial: Turning Multi-sensory Earth Observations to Interactive Dialogues. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Nashville, TN, USA, 11–15 June 2025; pp. 14303–14313. [Google Scholar]
- Ravi, N.; Gabeur, V.; Hu, Y.T.; Hu, R.; Ryali, C.; Ma, T.; Khedr, H.; Rädle, R.; Rolland, C.; Gustafson, L.; et al. SAM 2: Segment Anything in Images and Videos. In Proceedings of the International Conference on Learning Representations, Singapore, 24–28 April 2025. [Google Scholar]
- Huang, X.; Wang, J.; Tang, Y.; Zhang, Z.; Hu, H.; Lu, J.; Wang, L.; Liu, Z. Segment and Caption Anything. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, WA, USA, 17–21 June 2024. [Google Scholar]
- Kirillov, A.; Mintun, E.; Ravi, N.; Mao, H.; Rolland, C.; Gustafson, L.; Xiao, T.; Whitehead, S.; Berg, A.C.; Lo, W.Y.; et al. Segment Anything. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Paris, France, 2–6 October 2023; pp. 4015–4026. [Google Scholar]
- Rasheed, H.; Maaz, M.; Mullappilly, S.S.; Shaker, A.; Khan, S.; Cholakkal, H.; Anwer, R.M.; Xing, E.; Yang, M.H.; Khan, F.S. GLaMM: Pixel Grounding Large Multimodal Model. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, WA, USA, 17–21 June 2024. [Google Scholar]
- Hu, R.; Zhu, L.; Zhang, Y.; Cheng, T.; Liu, L.; Liu, H.; Ran, L.; Chen, X.; Liu, W.; Wang, X. GroundingSuite: Measuring Complex Multi-Granular Pixel Grounding. In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Honolulu, HI, USA, 19–23 October 2025; pp. 23105–23114. [Google Scholar]
- Hu, E.J.; Shen, Y.; Wallis, P.; Allen-Zhu, Z.; Li, Y.; Wang, S.; Wang, L.; Chen, W. LoRA: Low-Rank Adaptation of Large Language Models. In Proceedings of the ICLR, Virtual Event, 25–29 April 2022. [Google Scholar]
- Carion, N.; Massa, F.; Synnaeve, G.; Usunier, N.; Kirillov, A.; Zagoruyko, S. End-to-End Object Detection with Transformers. In Proceedings of the European Conference on Computer Vision, Glasgow, UK, 23–28 August 2020; pp. 213–229. [Google Scholar]
- Bodla, N.; Singh, B.; Chellappa, R.; Davis, L.S. Soft-NMS–Improving Object Detection with One Line of Code. In Proceedings of the IEEE International Conference on Computer Vision (ICCV), Venice, Italy, 22–29 October 2017; pp. 5562–5570. [Google Scholar]
- Otsu, N. A Threshold Selection Method from Gray-Level Histograms. IEEE Trans. Syst. Man. Cybern. 1979, 9, 62–66. [Google Scholar] [CrossRef] [Scilit]
- Liu, C.; Chen, K.; Zhang, H.; Qi, Z.; Zou, Z.; Shi, Z. Change-Agent: Toward Interactive Comprehensive Remote Sensing Change Interpretation and Analysis. IEEE Trans. Geosci. Remote Sens. 2024, 62, 5635616. [Google Scholar] [CrossRef] [Scilit]
- Lin, C.Y. ROUGE: A Package for Automatic Evaluation of Summaries. In Proceedings of the Text Summarization Branches Out: Proceedings of the ACL-04 Workshop, Barcelona, Spain, 25–26 July 2004; pp. 74–81. [Google Scholar]
- Banerjee, S.; Lavie, A. METEOR: An Automatic Metric for MT Evaluation with Improved Correlation with Human Judgments. In Proceedings of the ACL Workshop on Intrinsic and Extrinsic Evaluation Measures for MT And/or Summarization, Ann Arbor, MI, USA, 29 June 2005; pp. 65–72. [Google Scholar]
- Zhang, T.; Kishore, V.; Wu, F.; Weinberger, K.Q.; Artzi, Y. BERTScore: Evaluating Text Generation with BERT. In Proceedings of the International Conference on Learning Representations (ICLR), Addis Ababa, Ethiopia, 26–30 April 2020. [Google Scholar]
- Ni, J.; Ábrego, G.H.; Constant, N.; Ma, J.; Hall, K.B.; Cer, D.; Yang, Y. Sentence-T5: Scalable Sentence Encoders from Pre-trained Text-to-Text Models. In Proceedings of the Findings of the Association for Computational Linguistics (ACL Findings), Dublin, Ireland, 22–27 May 2022; pp. 1864–1874. [Google Scholar]
- Papineni, K.; Roukos, S.; Ward, T.; Zhu, W.J. BLEU: A Method for Automatic Evaluation of Machine Translation. In Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics (ACL), Philadelphia, PA, USA, 7–12 July 2002; pp. 311–318. [Google Scholar]
- Vedantam, R.; Lawrence Zitnick, C.; Parikh, D. CIDEr: Consensus-based Image Description Evaluation. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Boston, MA, USA, 7–12 June 2015; pp. 4566–4575. [Google Scholar]
- Wang, P.; Bai, S.; Tan, S.; Wang, S.; Fan, Z.; Bai, J.; Chen, K.; Liu, X.; Wang, J.; Ge, W.; et al. Qwen2-VL: Enhancing Vision-Language Model’s Perception of the World at Any Resolution. arXiv 2024, arXiv:2409.12191. [Google Scholar]
- Zhu, J.; Chen, W.; Wang, Z.; Liu, S.; Ye, X.; Gu, L.; Duan, H.; Tian, H.; Su, W.; Shao, J.; et al. InternVL3: Exploring Advanced Training and Test-Time Recipes for Open-Source Multimodal Models. arXiv 2025, arXiv:2504.10479. [Google Scholar]
- Agrawal, P.; Antoniak, S.; Hanna, E.B.; Bout, B.; Chaplot, D.; Chudnovsky, J.; Costa, D.; Monicault, B.D.; Garg, S.; Gervet, T.; et al. Pixtral 12B. arXiv 2024, arXiv:2410.07073. [Google Scholar]
- Daudt, R.C.; Le Saux, B.; Boulch, A. Fully Convolutional Siamese Networks for Change Detection. In Proceedings of the 25th IEEE International Conference on Image Processing (ICIP), Athens, Greece, 7–10 October 2018; pp. 4063–4067. [Google Scholar]
- Chen, H.; Qi, Z.; Shi, Z. Remote Sensing Image Change Detection with Transformers. IEEE Trans. Geosci. Remote Sens. 2022, 60, 5607514. [Google Scholar] [CrossRef] [Scilit]
- Lin, J.; Yin, H.; Ping, W.; Molchanov, P.; Shoeybi, M.; Han, S. VILA: On Pre-training for Visual Language Models. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, WA, USA, 17–21 June 2024; pp. 26689–26699. [Google Scholar]





| Component | Params | Status |
|---|---|---|
| CLIP ViT encoder | 304 M | Frozen |
| Vision projector | 34 M | Frozen in our setting |
| InternLM2-7B | 7.0 B | LoRA () |
| SAM2 Hiera-L encoder | 214 M | Frozen |
| text_hidden_fcs projection | 17.8 M | Trainable |
| SAM2 mask decoder | 4.1 M | Trainable |
| BCTA (new) | 79 K | Trainable |
| CRGP (new) | 265 K | Trainable |
| Dataset | Domain | Pairs | Caption Source | Mask Labels | Evaluation Role |
|---|---|---|---|---|---|
| RSCC [1] | Disaster | 62,351 | Model-gen. | None | train source; eval: 988 subset |
| LEVIR-CC [2] | Urban | 10,077 | Human ×5 | None | Zero-shot caption transfer |
| LEVIR-MCI [22] | Urban | 10,077 | — | 3-class | Zero-shot evidence evaluation |
| Component | Params | Trainable | New |
|---|---|---|---|
| InternLM2-7B LoRA () | 4.2 M | ✓ | — |
| text_hidden_fcs projection | 17.8 M | ✓ | — |
| SAM2 mask decoder | 4.1 M | ✓ | — |
| BCTA | 79 K | ✓ | ✓ |
| CRGP | 265 K | ✓ | ✓ |
| WAB (offline) | 0 | — | ✓ |
| Total trainable | 26.4 M | ✓ | ✓ |
| of which new | 344 K | ✓ | ✓ |
| % of full model (∼7.6B) | new: 0.0045%; trainable: 0.34% | ||
| Group | Category | Models | Source | Evidence | Appears in |
|---|---|---|---|---|---|
| A | General VLMs | Qwen2-VL, InternVL3, Pixtral | rep./ours | — | RSCC and LEVIR-CC |
| A’ | Specialized change captioning | CCExpert, TEOChat | rep. | — | RSCC and LEVIR-CC |
| B | Learned RSCC baseline | RSCCM | rep. | — | RSCC |
| C | Direct competitor (zero-shot on RSCC) | ChangeChat | rep. | internal | LEVIR-CC and structural comparison |
| C’ | In-domain LEVIR-CC references | RSICCformer, Chg2Cap, Change-Agent | rep. | — | LEVIR-CC |
| D | Structural ablation (ours) | GeoPixel naive, +BCTA, +BCTA+CRGP, ChangePixel | ours | ✓ (CRGP) | RSCC, LEVIR-CC, and ablation |
| E | Supervised CD references | FC-Siam-Diff, BIT | rep. | mask-only | Ablation |
| Model | Group | Source | ROUGE ↑ | METEOR ↑ | BERTScore | ST5-SCS ↑ |
|---|---|---|---|---|---|---|
| Qwen2-VL-7B (TP) | A | reported | 19.04 | 25.20 | 99.01 | 72.65 |
| InternVL3-8B (TP) | A | reported | 19.81 | 28.51 | 99.55 | 78.57 |
| Pixtral-12B (TP) | A | reported | 19.87 | 29.01 | 99.51 | 79.07 |
| CCExpert-7B (VP) | A’ | reported | 8.84 | 5.41 | 99.23 | 46.58 |
| TEOChat-7B (TP) | A’ | reported | 11.81 | 10.24 | 99.12 | 61.73 |
| RSCCM (VP) | B | reported | 22.37 | 33.81 | —† | 78.87 |
| GeoPixel naive | D | ours | 17.23 ± 0.31 | 23.85 ± 0.42 | 99.14 ± 0.05 | 70.42 ± 0.61 |
| +BCTA | D | ours | 18.41 ± 0.27 | 26.17 ± 0.35 | 99.28 ± 0.03 | 73.56 ± 0.54 |
| +BCTA+CRGP | D | ours | 18.53 ± 0.29 | 26.89 ± 0.41 | 99.24 ± 0.04 | 74.83 ± 0.46 |
| ChangePixel full | D | ours | 19.52 ± 0.19 | 28.34 ± 0.26 | 99.42 ± 0.02 | 76.91 ± 0.38 |
| Model | Group | Source | BLEU-4 ↑ | METEOR ↑ | ROUGE_L ↑ | CIDEr-D ↑ |
|---|---|---|---|---|---|---|
| CCExpert-7B | A’ | reported | 65.49 | 41.82 | 76.55 | 143.32 |
| RSICCformer | C’ | reported | 62.77 | 39.61 | 74.12 | 134.12 |
| Chg2Cap | C’ | reported | 64.39 | 40.03 | 75.12 | 136.61 |
| ChangeChat | C | reported | — | 38.73 | 74.01 | 136.56 |
| Qwen2-VL-7B (TP) | A | ours | 25.14 | 22.87 | 46.31 | 40.53 |
| InternVL3-8B (TP) | A | ours | 28.37 | 24.63 | 49.85 | 46.18 |
| Pixtral-12B (TP) | A | ours | 30.62 | 25.15 | 51.42 | 51.74 |
| GeoPixel naive | D | ours | 28.73 ± 0.52 | 21.46 ± 0.39 | 48.52 ± 0.68 | 42.18 ± 1.14 |
| +BCTA | D | ours | 31.25 ± 0.46 | 23.18 ± 0.30 | 51.37 ± 0.61 | 48.65 ± 0.89 |
| +BCTA+CRGP | D | ours | 30.87 ± 0.51 | 23.87 ± 0.42 | 51.92 ± 0.55 | 51.23 ± 0.96 |
| ChangePixel full | D | ours | 34.56 ± 0.33 | 25.41 ± 0.28 | 54.78 ± 0.42 | 56.82 ± 0.74 |
| Method | Region Output | Per-Region Phrases | Single Backbone | Loc. Superv. | Training Domain |
|---|---|---|---|---|---|
| ChangeChat [8] | loc. response | — | — | ✓ | LEVIR-CC |
| SAGE-CC [9] | internal | — | — | — | LEVIR-CC |
| BTCChat [10] | — | — | — | — | LEVIR-CC |
| CCExpert † [4] | — | — | ✓ | — | LEVIR-CC |
| RSCCM † [1] | — | — | ✓ | — | RSCC |
| ChangePixel (ours) | pixel mask | ✓ | ✓ | — | RSCC |
| Dataset | Pairs | Triples | Triples/img | Correct | Partial | Wrong | Usable | |
|---|---|---|---|---|---|---|---|---|
| RSCC | 150 | 370 | 2.47 | 0.71 | 79% | 12% | 9% | 91% |
| LEVIR-CC | 150 | 270 | 1.80 | 0.65 | 68% | 20% | 12% | 88% |
| Failure Mode | Frequency (95% CI) | Oracle mIoU | Implication |
|---|---|---|---|
| Missed small regions | 56/200 (28%, [22–35%]) | +2.8 | largest recoverable loss |
| Over-segmentation | 36/200 (18%, [13–24%]) | +0.9 | limited union effect |
| Phrase drift | 24/200 (12%, [8–17%]) | ≈0 | invisible to mIoU |
| Any mode (non-additive) | 88/200 (44%, [37–51%]) | +3.4 | small vs. paradigm gap |
| Caption Quality | Evidence Quality | |||
|---|---|---|---|---|
| ROUGE | CIDEr-D | PGT-IoU | Ch.mIoU | |
| 3 | 19.71 | 57.41 | 0.462 | 30.2 |
| 5 | 19.52 | 56.82 | 0.518 | 33.8 |
| 8 | 19.18 | 55.37 | 0.536 | 34.5 |
| ROUGE | PGT-IoU | Ch.mIoU | |||||
|---|---|---|---|---|---|---|---|
| Caption-heavy | 2.0 | 0.5 | 0.25 | 0.05 | 19.73 | 0.448 | 29.6 |
| Evidence-heavy | 0.5 | 2.0 | 1.0 | 0.2 | 18.91 | 0.547 | 34.7 |
| Equal | 1.0 | 1.0 | 1.0 | 1.0 | 19.14 | 0.503 | 32.1 |
| Default | 1.0 | 1.0 | 0.5 | 0.1 | 19.52 | 0.518 | 33.8 |
| RSCC-Subset | RSCC Evidence | LEVIR-CC | LEVIR-MCI Evidence | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Variant | BCTA | CRGP | WAB | ROUGE | METEOR | BERTSc. | ST5-SCS | PGT-IoU | PD-Ov. | CIDEr-D | Ch.mIoU | Bin.F1 |
| GeoPixel naive | 17.23 ± 0.31 | 23.85 ± 0.42 | 99.14 ± 0.05 | 70.42 ± 0.61 | — | — | 42.18 ± 1.14 | — | — | |||
| +BCTA | ✓ | 18.41 ± 0.27 | 26.17 ± 0.35 | 99.28 ± 0.03 | 73.56 ± 0.54 | — | — | 48.65 ± 0.89 | — | — | ||
| +BCTA+CRGP | ✓ | ✓ | 18.53 ± 0.29 | 26.89 ± 0.41 | 99.24 ± 0.04 | 74.83 ± 0.46 | 0.337 ± .014 | 0.412 ± .018 | 51.23 ± 0.96 | 27.4 ± 0.7 | 0.398 ± .013 | |
| ChangePixel full | ✓ | ✓ | ✓ | 19.52 ± 0.19 | 28.34 ± 0.26 | 99.42 ± 0.02 | 76.91 ± 0.38 | 0.518 ± .017 | 0.573 ± .016 | 56.82 ± 0.74 | 33.8 ± 0.5 | 0.487 ± .011 |
| Pixel-Diff | — | — | — | — | 0.253 | 0.681 | — | 18.5 | 0.350 | |||
| FC-Siam-Diff † | — | — | — | — | — | — | — | 54.6 | 0.812 | |||
| BIT † | — | — | — | — | — | — | — | 61.3 | 0.878 | |||
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Zhou, Q.; Yang, B.; Wei, X.; Qin, D.; Leng, T.; Liu, X. ChangePixel: Pixel-Level Evidence-Grounded Disaster Change Narration via Single-Backbone Transfer. Remote Sens. 2026, 18, 2480. https://doi.org/10.3390/rs18152480
Zhou Q, Yang B, Wei X, Qin D, Leng T, Liu X. ChangePixel: Pixel-Level Evidence-Grounded Disaster Change Narration via Single-Backbone Transfer. Remote Sensing. 2026; 18(15):2480. https://doi.org/10.3390/rs18152480
Chicago/Turabian StyleZhou, Qinyu, Ben Yang, Xinyan Wei, Ding Qin, Tingting Leng, and Xiaojing Liu. 2026. "ChangePixel: Pixel-Level Evidence-Grounded Disaster Change Narration via Single-Backbone Transfer" Remote Sensing 18, no. 15: 2480. https://doi.org/10.3390/rs18152480
APA StyleZhou, Q., Yang, B., Wei, X., Qin, D., Leng, T., & Liu, X. (2026). ChangePixel: Pixel-Level Evidence-Grounded Disaster Change Narration via Single-Backbone Transfer. Remote Sensing, 18(15), 2480. https://doi.org/10.3390/rs18152480