1. Introduction
In the field of remote sensing, numerous studies have shown that hyperspectral imagery [
1] plays a crucial role in multiple domains, such as agriculture and geological exploration [
2,
3]. However, due to the limitations of hyperspectral imaging technology [
4], hyperspectral images have relatively low spatial resolution. In contrast, multispectral images (MSI) usually possess higher spatial resolution but contain fewer spectral channels (e.g., RGB). Therefore, many studies have employed various technical approaches to fuse these two modalities, aiming to exploit their complementary advantages.
Modern hyperspectral satellites, such as PRISMA and HYPERION [
1], have relatively low spatial resolution. Thus, directly applying their data to fields such as geological exploration [
3], biomass inversion [
2,
5], and agricultural monitoring [
6] often results in reduced or insignificant performance. In forest resource surveys and ecological monitoring, the accuracy of existing tree species distribution maps remains limited, and a single remote sensing data source is often insufficient to fully characterize the differences among forest types. Since large-scale field surveys are costly and slow to update, multi-source remote sensing data fusion and machine learning methods have been used to improve tree species identification and distribution mapping capabilities [
7]. This limitation is particularly critical in mainstream tasks, such as object detection [
8], change detection [
9,
10], and land-cover classification [
11,
12,
13], where the rich spectral information in HSI is indispensable. Current research trends have shifted from purely improving imaging hardware toward deep learning–based fusion methods [
10,
14]. These methods integrate LR-HSI with HR-MSI to obtain high-resolution HR-HSI with both high spectral and spatial fidelity.
In traditional methods, multi-resolution analysis (MRA) techniques, such as the Laplacian pyramid [
15], extract high-frequency spatial details from MSI and inject them into upsampled HSI to enhance spatial resolution. However, such high-frequency injection is typically based on simple addition or ratio transfer, which lacks spectral consistency and leads to spectral distortion. Statistical and matrix-based methods, such as principal component analysis [
16], tensor decomposition [
17,
18], and nonnegative matrix factorization (NMF) [
19,
20], utilize the low-rank property of HSI to project MSI’s spatial information into the spectral domain for representation, reconstructing spectra via low-rank coefficients [
21,
22]. These linear mathematical models, however, struggle to establish complex nonlinear spectral relationships, require high computational costs, and depend heavily on training data. Wavelet transform–based methods [
23,
24,
25] perform multi-scale analysis by replacing low-frequency and high-frequency components and conducting fusion in the frequency domain via inverse transformation. However, their performance depends heavily on the choice of wavelet basis [
26], limiting their generalizability. Prior-knowledge-based fusion [
27] maintains spectral or spatial consistency through constraints, offering good interpretability and overall performance but relying on idealized assumptions and manual parameter tuning. These iterative algorithms have high computational costs, weak generalization, and the risk of local minima.
Pan-sharpening-based methods [
28,
29,
30] usually enhance spatial details by fusing panchromatic images with multispectral data, offering the advantages of simple implementation and effective spatial sharpening. However, these methods are prone to spectral distortion, physical inconsistency, and noise sensitivity, which limit their application in hyperspectral image fusion and further promote the development of deep learning-based fusion methods [
31]. Meanwhile, in hyperspectral full-band sharpening tasks, maintaining consistent spectral quality across different bands remains an important challenge. Recent research [
32] has improved spatial sharpening quality and spectral fidelity without relying on external training data by introducing zero-shot unsupervised training, a band-adaptive lightweight network, and a hysteresis-based loss tuning strategy, providing new insights for hyperspectral image fusion research.
In recent years, the rapid rise of convolutional neural networks (CNNs) [
14] has made deep learning a key technology across various fields. CNNs [
33] extract features such as textures and edges through local convolution kernels and multi-level architectures [
34], effectively capturing spatial detail. Modern deep fusion networks [
35] employ activation functions and multi-layer structures to learn complex nonlinear mappings between spectral and spatial domains. However, CNNs have difficulty effectively utilizing spatial positional information and modeling long-range dependencies, leading to a loss of global contextual information. On this basis, the Transformer [
36] has emerged with its unique self-attention mechanism, which models associations between features at any position. It is particularly suitable for capturing long-range dependencies across spatial and spectral dimensions, thereby solving the spectral inconsistency and global structure misalignment caused by the limited receptive fields of CNNs [
37]. However, Transformers still suffer from high computational complexity and dependence on large-scale training data.
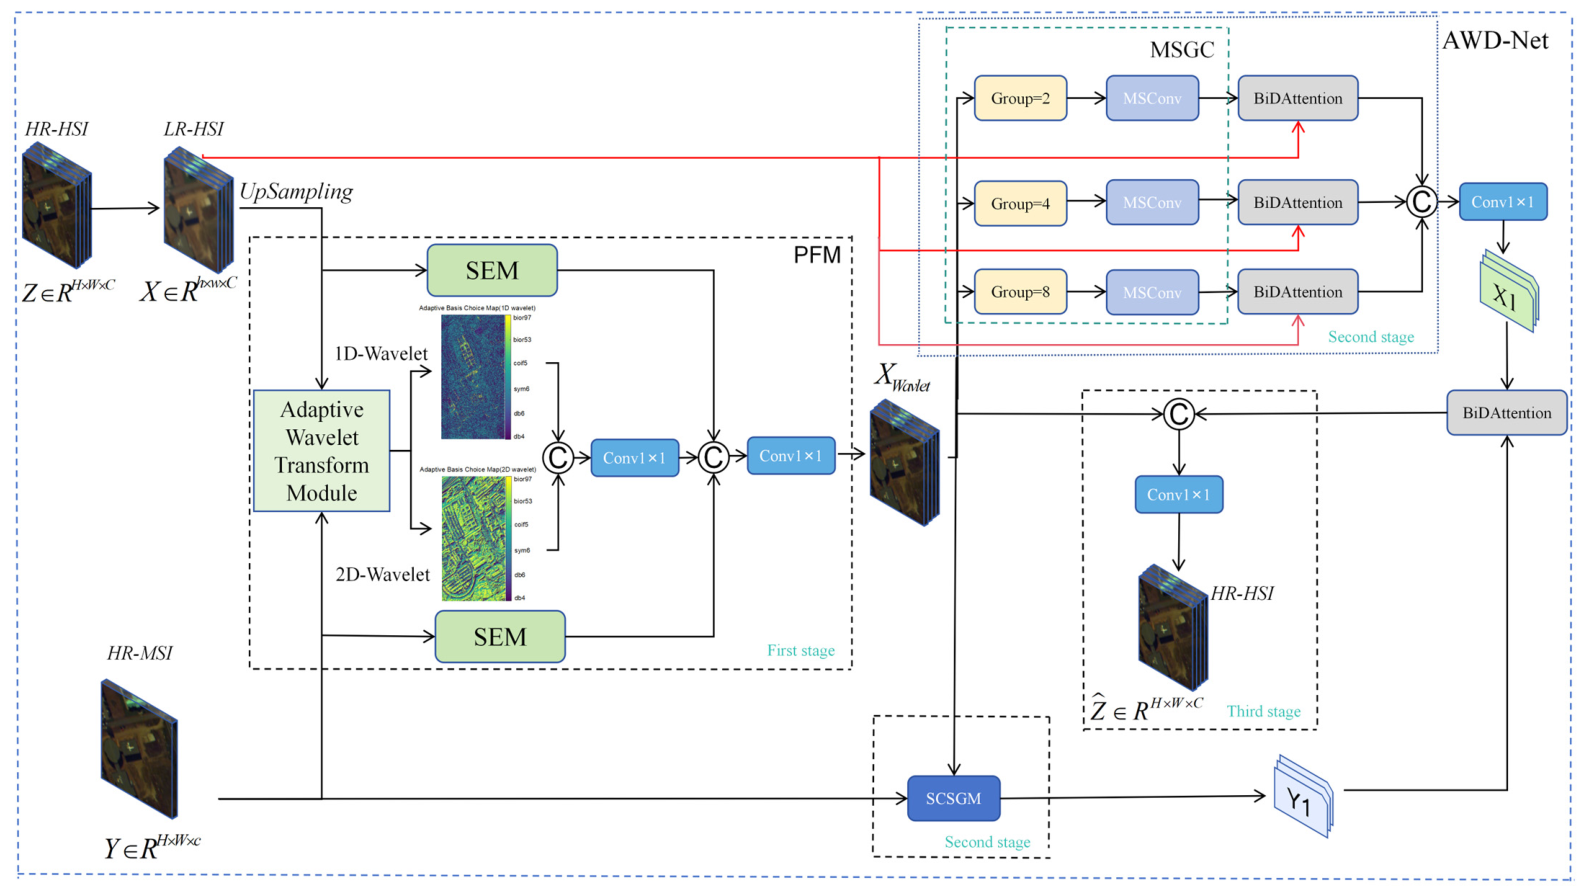
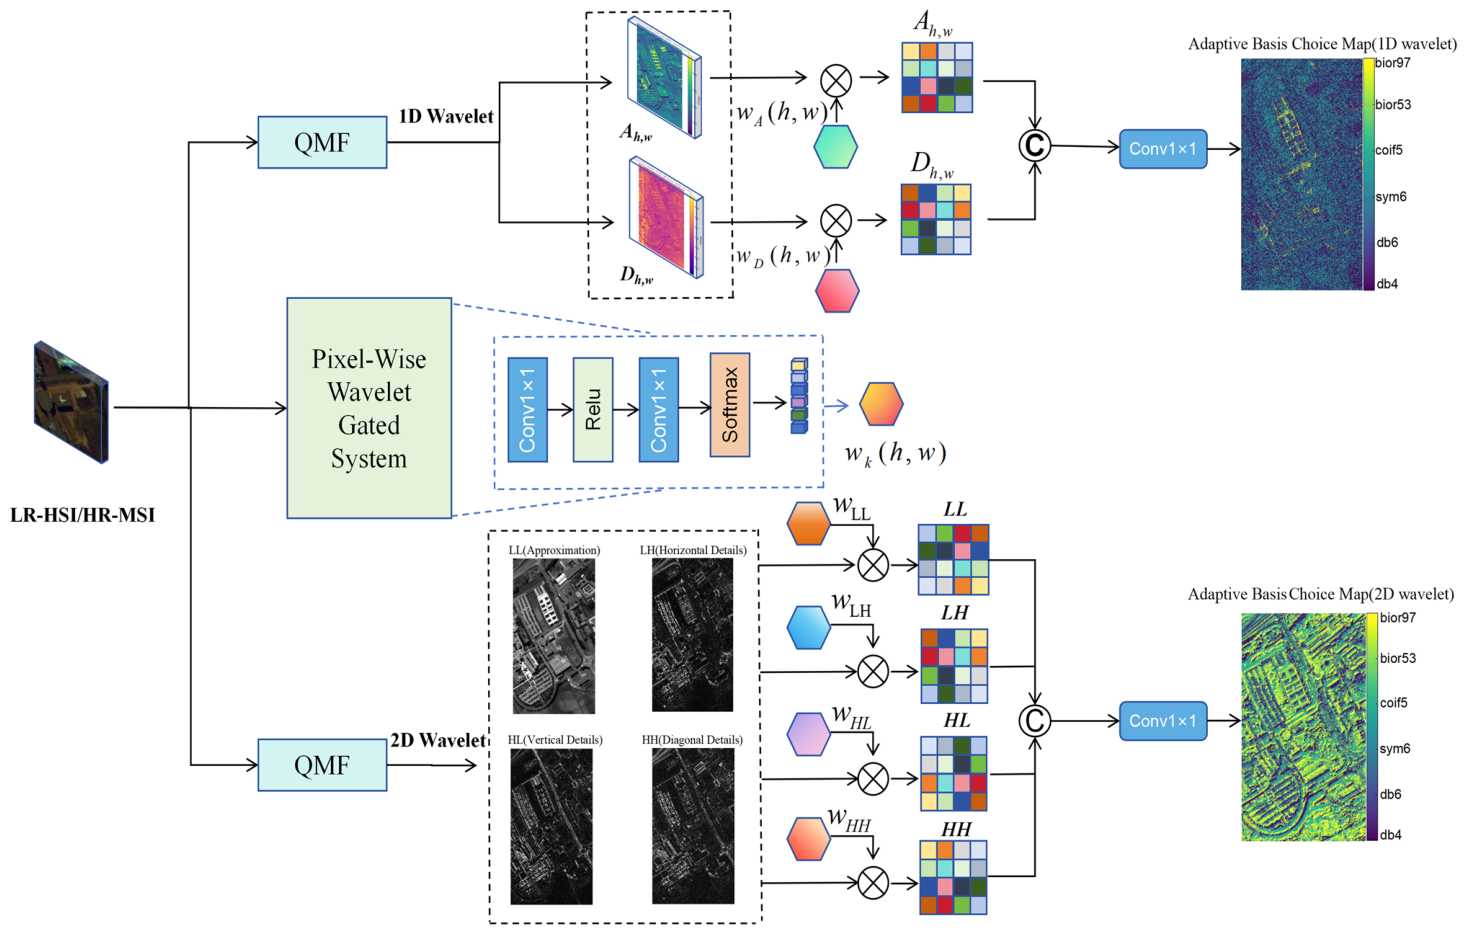
This paper proposes a hybrid framework that integrates traditional methods with deep learning for hyperspectral and multispectral image fusion, aiming to efficiently model the nonlinear correspondence between spectral and spatial information and significantly improve reconstruction accuracy. Traditional wavelet-based methods typically use fixed basis functions and decomposition levels, making them inadequate for complex scenarios. To address this limitation, this study introduces an adaptive spectral decomposition approach based on learnable wavelet bases. Specifically, 1D wavelet transforms are utilized to extract spectral features, while 2D wavelet transforms capture spatial features. By reconstructing candidate wavelet bases and applying a Softmax-based gating mechanism, the model performs pixel-wise adaptive weighting, enabling each pixel to select the optimal wavelet basis automatically. A learnable “soft selection combine lightweight scaling” strategy is further employed to enhance flexibility in spectral decomposition while maintaining interpretability and stability. End-to-end optimization jointly trains wavelet selection and the fusion objective, yielding task-specific optimal solutions.
In the downstream fusion stage, a multi-scale grouped convolution module (MSGC) is introduced to overcome the limited receptive field of single convolutions. This module employs parallel grouped convolutions at different scales to capture multi-granular texture information under spatial constraints, achieving both detail enhancement and spectral fidelity. Grouped spectral modeling strengthens texture discrimination, reduces channel redundancy, and improves network trainability and generalization.
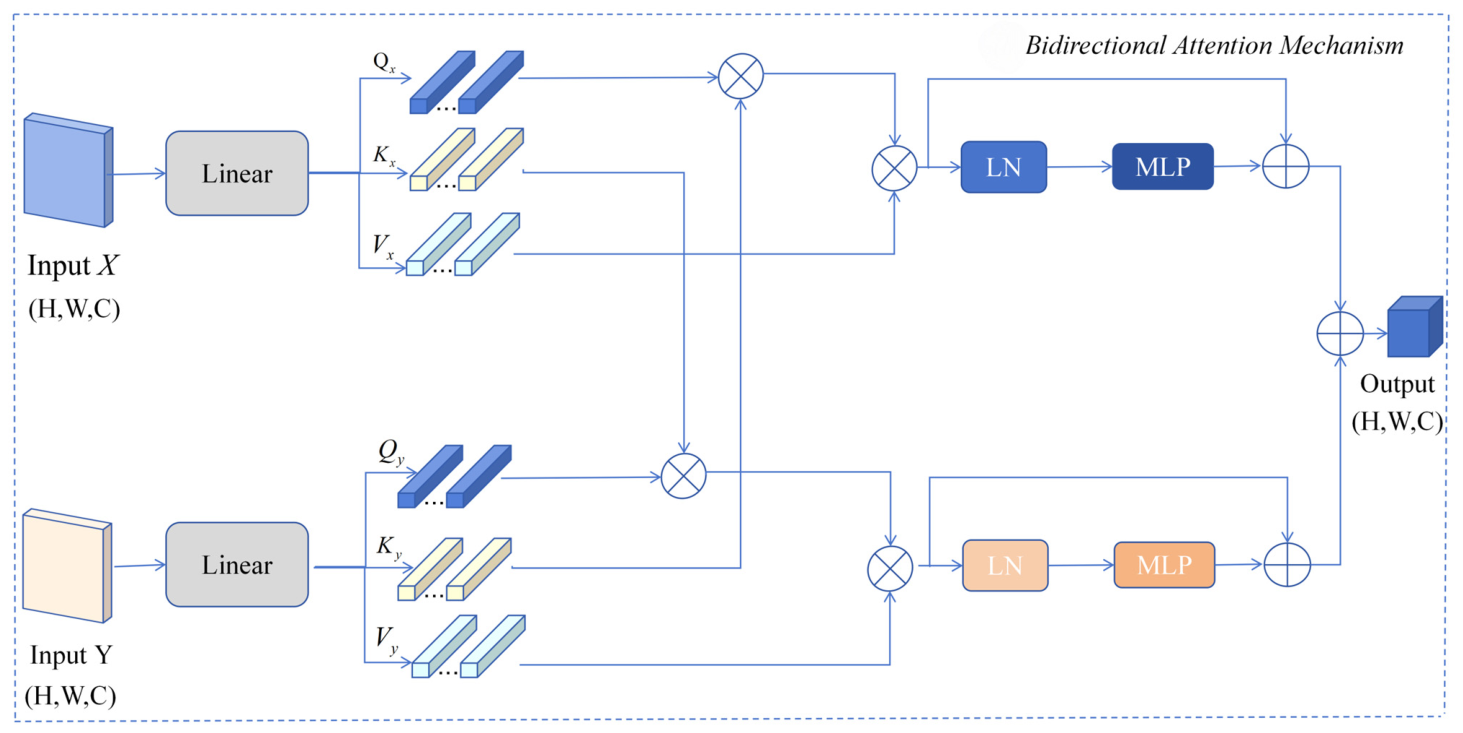
Moreover, the Transformer’s self-attention mechanism struggles to learn cross-modal relationships. To address this, a cross-attention mechanism is incorporated into the spatial and spectral branches to achieve complementary alignment between MSI and HSI. The bidirectional attention effectively eases gradient propagation and reduces feature redundancy, which are issues found in conventional residual structures. The framework strikes a balance between computational efficiency, interpretability, robustness, and high performance.
The main contributions of this paper are summarized as follows:
We propose a parallel architecture that leverages a 1D wavelet transform for spectral dimension extraction and a 2D wavelet transform for spatial dimension extraction, respectively. A Softmax gating mechanism is designed to adaptively select wavelet basis functions for each pixel based on varying weight distributions, which enhances the frequency-domain modeling capability. This framework fully preserves the spectral and spatial information across different bands, leading to a significant improvement in both image quality and fusion accuracy.
A multi-scale grouped convolution module (MSGC) is designed for spectral feature extraction. It expands the receptive field and strengthens inter-group interaction while reducing computational cost and parameter redundancy.
A Bidirectional attention mechanism (BiDAttention) is introduced to enable long-range interaction with the original information. By integrating local and global features, it enhances fusion quality while maintaining image completeness and fidelity.
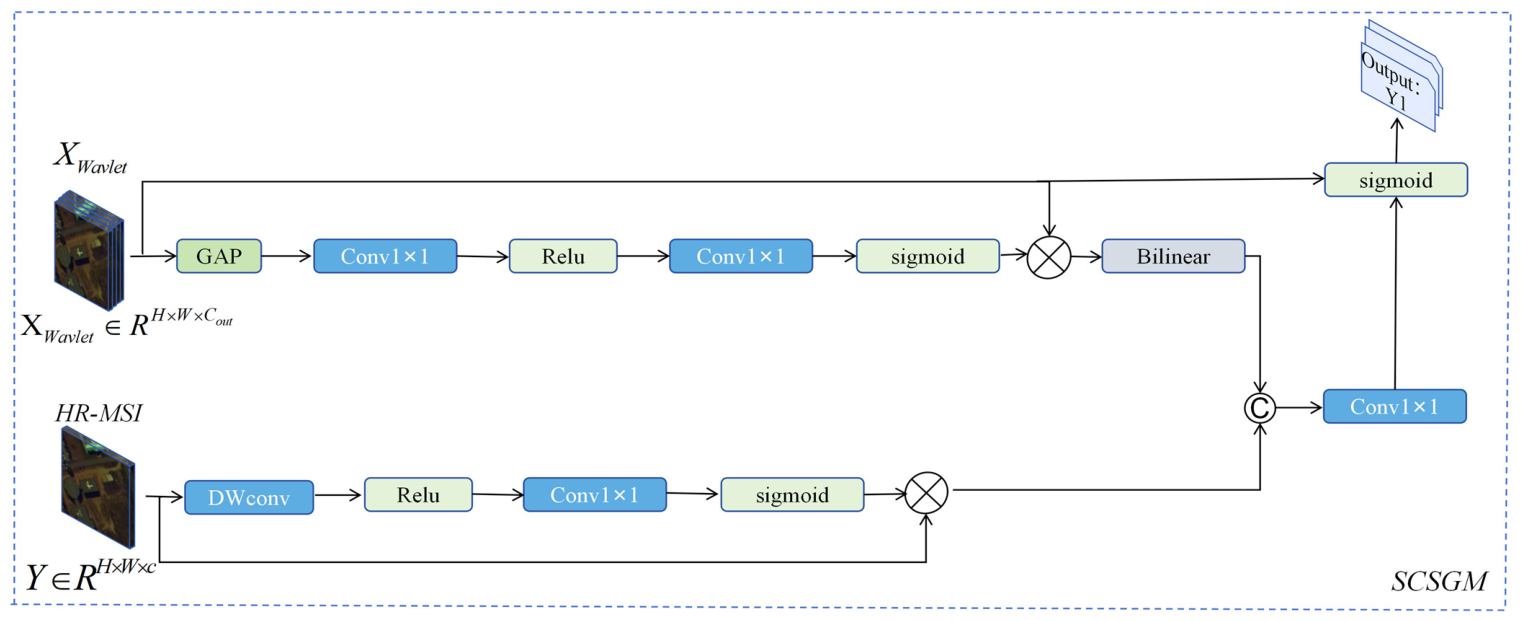
A spatial feature extraction module (SCSGM) is developed, employing multiple gating systems to dynamically and adaptively select features during computation. This design strengthens spatial texture representation and highlights edge and structural information.
The remainder of this paper is organized as follows:
Section 2 reviews related work on traditional and deep learning–based methods.
Section 3 provides a detailed description of the proposed model, clarifying the theoretical basis and implementation steps of model construction.
Section 4 presents the experimental results on four benchmark datasets, along with discussions and an ablation study analysis of each module. Finally,
Section 5 concludes the paper.
4. Experiments
To comprehensively evaluate the proposed framework, we conduct comparisons with twelve representative state-of-the-art fusion methods, including CNMF [
5], CSU [
13], SSE [
20], MSDCNN [
34], TFNet [
35], ResTFNet [
35], SFFCNN [
14], RSST [
56], SSR-NET [
49], UMSFT [
52], UPFW [
50], and MCT-Net [
55].
All experimental parameters are configured according to the original authors’ code or the recommendations provided in their papers. The traditional methods are tested using MATLAB R2014a on a system equipped with an Intel Core i9 processor and 32 GB RAM running Windows 11. The deep learning methods are implemented in Python 3.8 using PyTorch 1.8 and accelerated with an NVIDIA RTX 4060 Ti GPU. Data preprocessing and analysis are conducted using MATLAB R2014a, along with NumPy and Pandas libraries in Python.
The proposed network is implemented based on the PyTorch 2.8.0 framework and trained using the Adam optimizer with a learning rate of 1 × 10⁻⁴. During training, the mean squared error (MSE) loss is adopted to constrain the pixel-level differences between the reconstructed HSI and the reference HSI. Meanwhile, 128 × 128 spatial patches are randomly cropped from the training region as network inputs, with the batch size set to 4. The model is trained for 1000 epochs, and the checkpoint with the best validation PSNR is saved for final testing. To ensure the fairness and reliability of the evaluation, a central region with the same spatial size is selected as the test area and masked during training to avoid information leakage between the training and test samples.
4.1. Dataset Description
To verify the superiority of the proposed method, experiments were conducted on four publicly available datasets: Pavia University, Pavia Centre, Urban, and Washington DC Mall.
- (1)
Pavia University:
The Pavia University dataset was also collected by the ROSIS sensor in 2003, with a spatial resolution of 1.3 m and an image size of 610 × 340 pixels. It initially contains 115 spectral bands; after discarding 12 noisy bands, 103 effective bands are used for further analysis.
- (2)
Pavia Centre:
The Pavia Centre dataset was acquired in 2003 by the ROSIS sensor, covering the spectral range of 430–860 nm with a spatial resolution of 1096 × 715 pixels. The original data contain 115 spectral bands, of which 102 bands are retained after removing noisy and water absorption bands for subsequent processing.
- (3)
Urban:
The Urban dataset was captured in 1995 by the HYDICE sensor over Copperas Cove, TX, USA. The dataset has a spatial size of 307 × 307 pixels and originally contains 210 spectral bands. After removing noisy and water absorption bands, 162 bands are retained for analysis.
- (4)
Washington DC Mall (WDCM):
The WDCM dataset was collected in 1995 by the HYDICE sensor over the Washington DC Mall. It covers a wavelength range of 200–2400 nm and originally contains 210 spectral bands; after eliminating water vapor absorption bands, 191 bands are preserved. The spatial size of the image is 1280 × 307 pixels, with a spatial resolution of 2.5 m.
These datasets collectively cover diverse landscapes, including urban areas, vegetation, and natural ecosystems, providing a comprehensive evaluation of the proposed fusion framework’s robustness and adaptability.
4.2. Evaluation Metrics
To comprehensively evaluate the performance of the image fusion algorithm, multiple quantitative metrics are commonly used for comparison, including RMSE, PSNR, SAM, and ERGAS. These metrics are applied to verify the effectiveness of the proposed framework in the fusion task between LR-HSI and HR-MSI. The four metrics are described as follows:
- (1)
Root Mean Squared Error (RMSE):
RMSE measures the error energy between the fused result and the ground truth (the square root of the mean squared error), directly reflecting the pixel-level intensity deviation.
Here, H, W, and C represent the height, width, and number of spectral bands of the image, respectively. A smaller value indicates better reconstruction quality.
- (2)
Peak Signal-to-Noise Ratio (PSNR):
PSNR is one of the most widely used and objective image quality evaluation metrics. Essentially, it represents the capability of error suppression in terms of the signal-to-noise ratio.
Here, H and W denote the height and width of the image. A higher PSNR value indicates higher signal quality and better detail recovery.
- (3)
Spectral Angle Mapper (SAM):
SAM measures the spectral angle between two spectral vectors, quantifying the similarity between spectral curves. It effectively evaluates spectral differences between remote sensing images.
- (4)
Error Relative Global Dimensionless Synthesis (ERGAS):
ERGAS essentially represents the normalized root mean square spectral error, which is used to quantify the relative variation of spectral errors across different bands and serves as a commonly used metric in multi-modal image fusion.
A lower
ERGAS value indicates better fusion performance. Conversely, higher values mean poorer quality.
Here, h represents the resolution of HR-MSI, l denotes the resolution of LR-HSI, C is the number of spectral bands, is the radiance of HR-MSI, and is the mean radiance of HR-MSI.
4.3. Experimental Implementation Details
In the spatial degradation process, a spatial degradation observation model combining Gaussian blurring and spatial downsampling is adopted to generate the LR-HSI. Specifically, the Gaussian filter is used to approximate the optical blurring effect caused by the sensor point spread function (PSF), while spatial downsampling is employed to simulate the spatial resolution loss resulting from the limited sampling capability of the sensor. This “blurring–downsampling” degradation model explicitly characterizes the optical blur and sampling degradation processes in practical imaging systems and has been widely used in hyperspectral–multispectral image fusion studies [
68,
69]. Following the experimental setting of Wei et al. [
68], each spectral band of the reference HR-HSI is first convolved with a Gaussian low-pass filter with a kernel size of 5 and a standard deviation of
, and is then downsampled in both the horizontal and vertical directions with a scale factor of s = 4 to obtain the corresponding LR-HSI.
For spectral degradation, we adopt the official spectral response function (SRF) of the Sentinel-2 multispectral instrument (MSI) released by the European Space Agency (ESA) to perform spectral weighted integration on the reference high-resolution hyperspectral image (HR-HSI), thereby generating the high-resolution multispectral image (HR-MSI). This strategy introduces the band response characteristics of a real multispectral sensor, making the simulated spectral degradation process consistent with the physical imaging mechanism of the MSI sensor [
69,
70]. Specifically, the official Sentinel-2 SRF [
71] document provides spectral response curves for 13 MSI bands. For each MSI band, its SRF is first resampled to the central wavelength positions of the hyperspectral bands. Then, the hyperspectral bands overlapping with the response range of the corresponding MSI band are weighted and integrated, and the response weights are normalized so that their sum equals 1. In this way, the spectral sensitivity characteristics of each MSI band can be preserved. As shown in
Table 2, since different hyperspectral datasets have different valid wavelength ranges, only the Sentinel-2 bands overlapping with the wavelength range of each dataset are selected for simulation. Specifically, the Pavia and PaviaU datasets use B1–B8, resulting in eight simulated multispectral bands, while the Urban and Washington datasets use B1–B8, B8a, B11, and B12, resulting in twelve simulated multispectral bands.
The spectral degradation process can be formulated as:
where
denotes the simulated value of the b-th MSI band at spatial position (x, y),
denotes the HR-HSI value at wavelength
,
represents the spectral response value of the b-th Sentinel-2 MSI band at
, and
denotes the set of hyperspectral bands overlapping with the response range of the b-th MSI band.
In
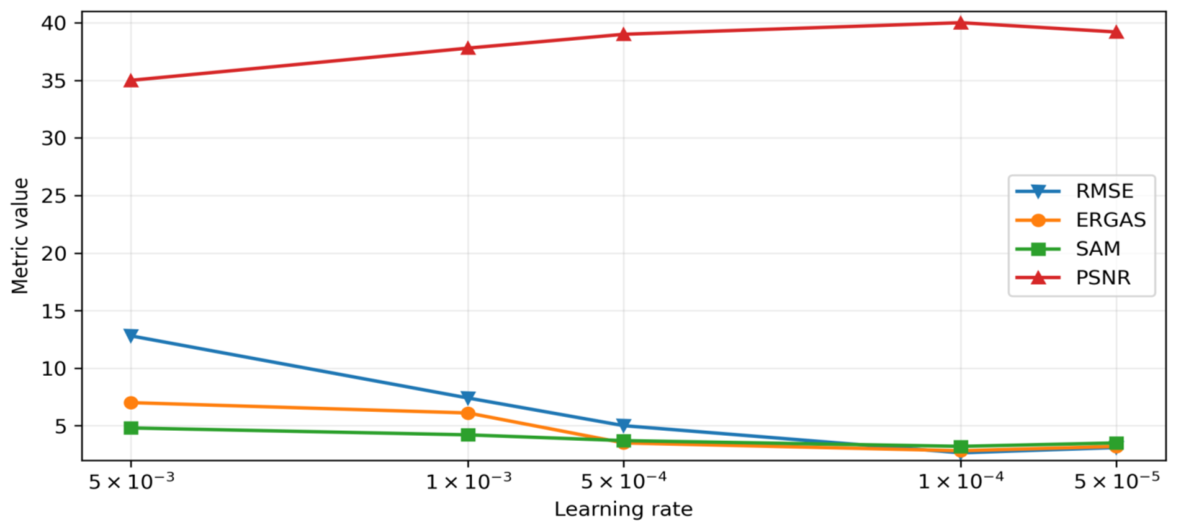
Figure 6, we evaluated the fusion performance under different learning rates on the Pavia Center dataset and ultimately determined to adopt a learning rate of 0.0001 based on the experimental data.
4.4. Comparison with Existing Popular Methods
We compare our proposed method with twelve mainstream hyperspectral image fusion algorithms across multiple datasets.
These methods include CNMF [
5], CSU [
13], SSE [
20], MSDCNN [
34], TFNet [
35], ResTFNet [
35], SFFCNN [
14], RSST [
56], SSR-NET [
49], UMSFT [
52], UPFW [
50], and MCT-Net [
55].
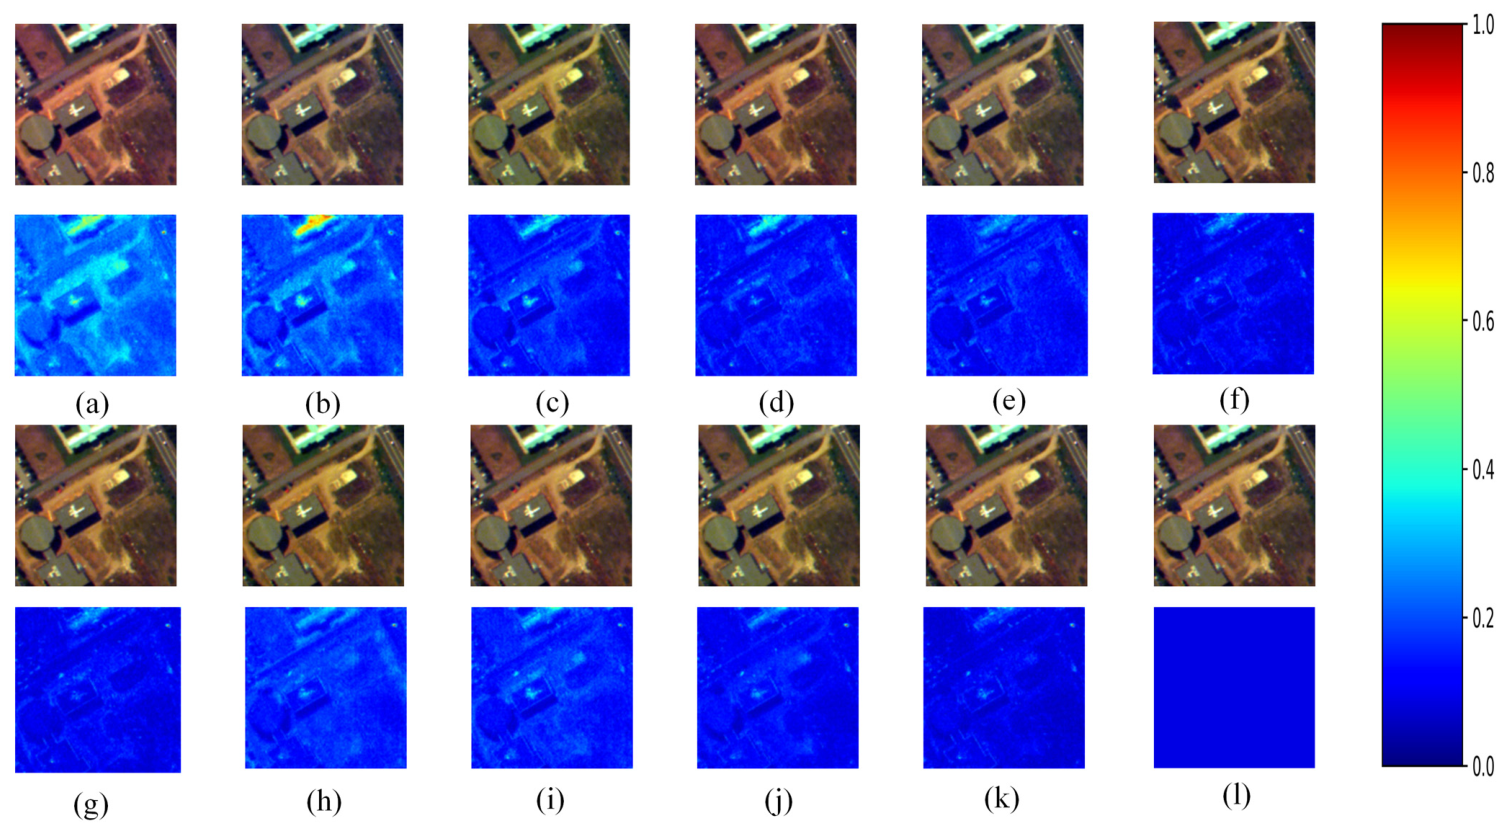
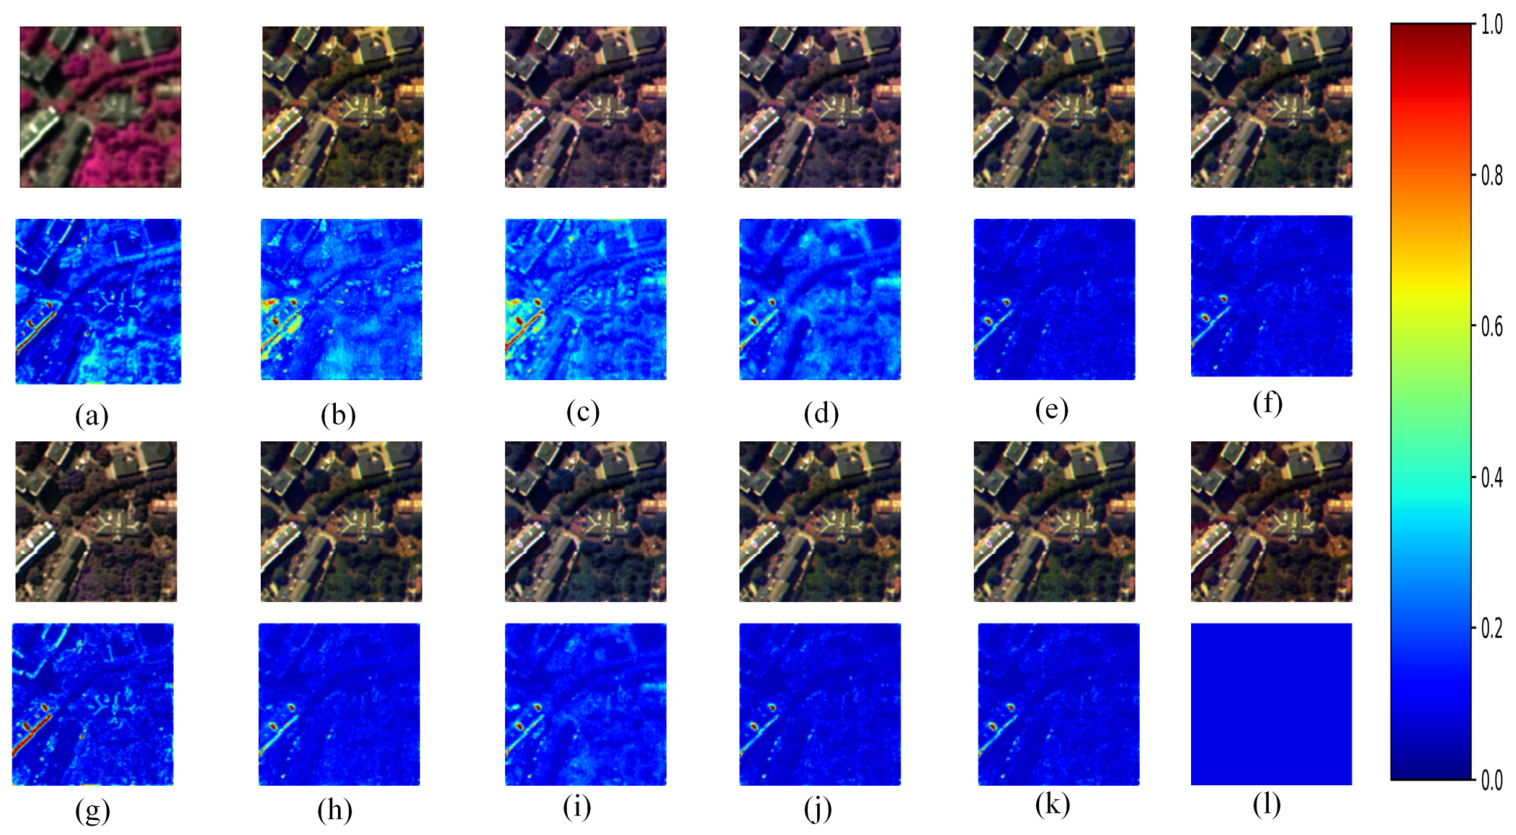
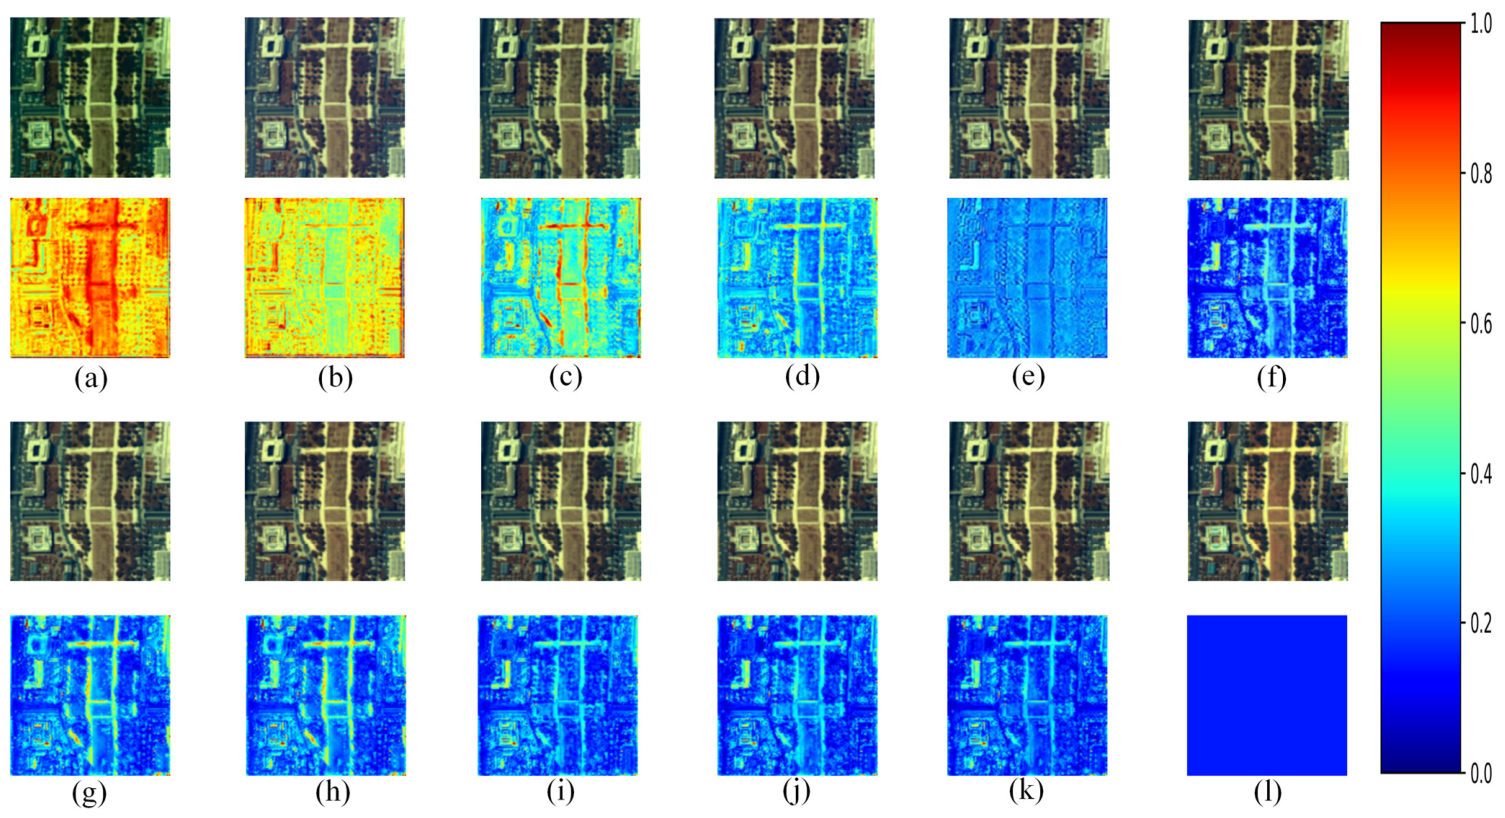
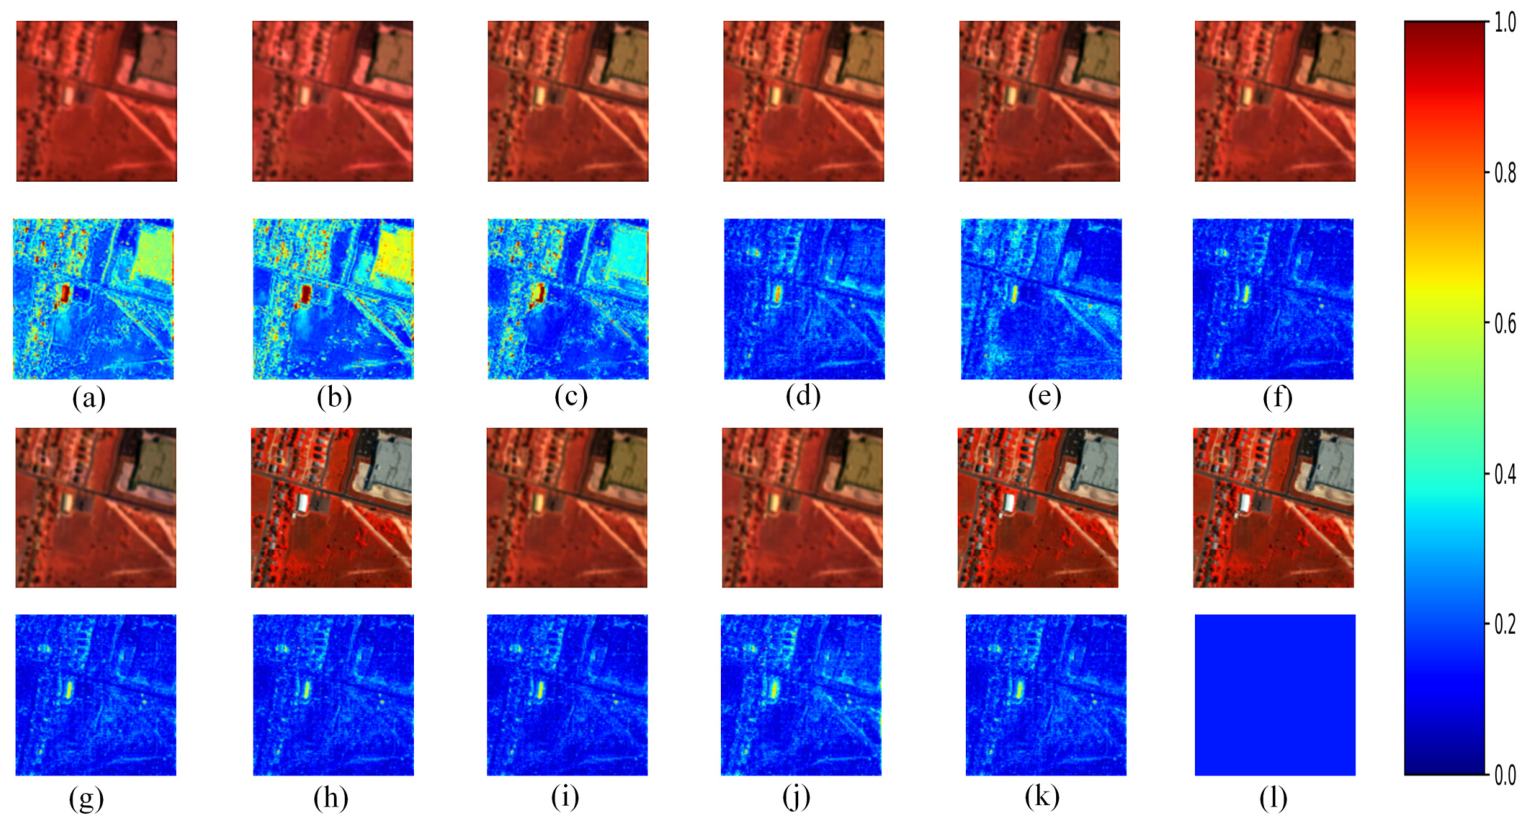
For visualization, pseudo-RGB images are generated by selecting three representative spectral bands. To ensure fair comparison, a shared linear stretching strategy is adopted within each dataset, where the stretching parameters are computed from the ground truth (GT) using percentile normalization and consistently applied to all methods. Considering that different datasets exhibit distinct dynamic ranges, the color scales are independently normalized per dataset rather than using a global scale. For residual visualization, the mean absolute error across spectral bands is normalized into [0, 1] using a hybrid scheme that combines percentile clipping and GT-based scaling, resulting in relatively scaled and visually stable error maps.
To comprehensively evaluate the robustness of the proposed method, all methods are compared under two spatial downsampling scales (4× and 8×). The quantitative results are reported under both degradation scales, while the visual results are presented under the 4× downsampling setting.
- (1)
Results on the Pavia University Dataset
As shown in
Table 3, which presents the evaluation metrics for the Pavia University dataset, it is evident that our fusion method achieves significant improvements compared to both the traditional CNMF method and the deep learning-based RSST method.
Figure 7 presents the pseudo-color processed difference images of various methods, and it can be clearly observed that darker blue shades indicate better fusion performance. Our method adopts a synchronous bidirectional coupling update of cross-modal features. Compared with MCT-NET, which relies on traditional unidirectional and cascaded information transmission, it achieves simultaneous updates. A visual inspection clearly demonstrates that our network framework achieves optimal fusion results.
Since the PaviaU dataset contains a wide variety of urban land-cover types, the spectral responses among different classes vary significantly, and complex mixed pixels exist in local regions. RSST shows strong residual responses when recovering transition areas between roads and buildings, while the proposed method better preserves fine-grained details along boundaries such as rooftops and road edges.
It can be observed that RSST exhibits strong robustness under a higher degradation scale and still maintains competitive fusion performance under the 8× downsampling setting. In comparison, our proposed method shows a slight performance decrease under 8× downsampling compared with the 4× setting, but it still achieves the better results on the main evaluation metrics. This indicates that the proposed framework maintains good stability and adaptability even under more severe spatial degradation conditions.
- (2)
Results on the Pavia Centre Dataset
Visual comparison clearly demonstrates that our fusion framework achieves superior performance. As shown by the quantitative metrics in
Table 4, our method consistently outperforms all competing approaches across all four evaluation indicators. Specifically, compared to the second-best method MCT-NET, it achieves a 10.06% reduction in the SAM metric. These results fully validate that the pixel-wise adaptive wavelet extraction architecture, when combined with subsequent deep feature extraction modules, effectively establishes long-range information dependencies while preserving excellent spectral fidelity and spatial resolution.
As shown in the visualization results of
Figure 8, the reconstruction errors of different methods are mainly concentrated in transition regions, such as building boundaries and road intersections. The traditional CNMF method struggles to accurately recover boundary details and tends to produce blurring and spectral distortion around edge regions. In contrast, deep learning-based methods, such as MCT-Net and the proposed method, exhibit lower errors around building contours and road edges, indicating that they can achieve a better balance between spatial detail preservation and spectral consistency.
- (3)
Results on the Urban Dataset
The experimental results on the Urban dataset are presented in
Table 5 and
Figure 9. Through comparative analysis, it is evident that our fusion strategy achieves a significant 3.73% improvement in PSNR and a 14.74% reduction in the SAM metric compared to the suboptimal fusion approach. In contrast to SSR-NET, which adopts spatial–spectral concatenated recovery combined with edge loss constraints and thus has limited representation capability, the proposed method employs a deep cross-interaction dynamic information flow that enables bidirectional synchronous coupling.
The Urban dataset contains more complex urban spatial structures, where SSR-Net shows relatively clear advantages. This is mainly because its spatial–spectral residual network explicitly constrains the image fusion process by jointly using spatial edge loss and spectral edge loss, thereby enhancing local structural representation while preserving the overall spectral trend. In addition, the bidirectional attention mechanism and grouped convolution adopted in the proposed method can capture fine-grained band differences at different spectral scales, enabling it to achieve superior performance in such complex urban scenes.
- (4)
Results on the Washington DC Mall Dataset
The Washington DC Mall dataset contains a large number of spectral bands and has high spatial resolution. However, our method still achieves significant improvements in both the spectral and spatial dimensions. The effect is clearly visible in
Figure 10.
As shown in
Table 6, compared with the advanced MCT-Net model, our method achieves a 1.83% improvement in PSNR and reduces RMSE by approximately 20.57%. These results indicate that AWD-Net is particularly effective in modeling high-dimensional spectral correlations while preserving fine-grained spatial details. This can be attributed to its unified cross-modal interaction design, which facilitates efficient information exchange and joint optimization across spatial and spectral domains, even under complex data distributions.
The proposed method maintains a low overall error in large homogeneous regions, while also showing good structural preservation in areas where fusion errors tend to concentrate, such as water boundaries and transition regions between vegetation and artificial objects. Compared with other methods, our proposed method exhibits a smoother error distribution in complex boundary regions. This indicates that it can not only recover the global spectral trend but also effectively constrain local spatial details, thereby achieving more stable fusion performance in large-scale complex scenes.
4.5. Ablation Study
To evaluate the impact of each module in the AWD-Net framework on the fusion performance, we conducted ablation experiments on the individual components of AWD-Net.
4.5.1. Ablation on the Adaptive Wavelet Transform
This module dynamically selects the most appropriate subband responses in the wavelet domain, enabling adaptive feature extraction for various regions, including textures, edges, and smooth areas. Within the overall framework, this module is embedded before the spatial–spectral dual-branch structure, allowing the input low-resolution hyperspectral (LR-HSI) and high-resolution multispectral (HR-MSI) data to obtain frequency-domain enhanced features at the early fusion stage.
To verify the effectiveness of this module, we conducted a systematic ablation study: keeping all other parts of the network identical, we compared different training strategies for the adaptive wavelet transform module. Specifically, the input LR-MSI has a size of 128 × 128, and the LR-HSI has a size of 32 × 32. We compared one-iteration and three-iteration training strategies and analyzed how weight sharing between iterative blocks affects performance.
When weights are shared across iterations, the model has fewer parameters and is computationally more efficient. When weights are not shared, each iteration can learn independent feature representations, thereby enhancing the model’s multi-stage fitting capability.
To assess these training strategies, experiments were conducted on the Pavia University dataset, recording four evaluation metrics (RMSE, PSNR, ERGAS, and SAM).
As shown in
Table 7, the proposed pixel-wise adaptive wavelet transform model (AWTM) achieves excellent performance across all four evaluation metrics. In the iterative architecture, the SR-HSI obtained from the first round of adaptive wavelet reconstruction is regarded as the updated hyperspectral prior. After re-encoding through shallow convolution, it serves as the input for the next iteration, undergoing adaptive wavelet decomposition and gated fusion again with the same MSI image. This enables the model to reselect optimal wavelet bases based on the current error distribution. Residual information is generated through inverse transformation, thereby progressively correcting spectral distortion and complementing spatial details. This cyclic process of “previous output → adaptive wavelet decomposition → weighted reconstruction → residual update” endows the model with capabilities analogous to iterative optimization.
The comparison results between weight sharing and non-sharing indicate that assigning independent parameters to each iteration can significantly enhance the model’s stage-wise representation capacity, allowing different iterations to focus on repairing features at varying scales. This approach ultimately improves the Peak Signal-to-Noise Ratio (PSNR) by approximately 0.131 dB, while also achieving significant reductions in both Root Mean Square Error (RMSE) and Relative Global Error in Synthesis (ERGAS). Conversely, increasing the number of iterations in the weight-sharing configuration did not yield performance gains, indicating that repeated application of the same operator leads to representational redundancy and gradient coupling, thereby hindering the model’s ability to learn new details.
Considering both performance and model complexity, we ultimately adopted the single-iteration, non-shared weight wavelet transform module as the standard configuration, achieving strong generalization capability while maintaining a low parameter count.
To further verify the necessity of the adaptive wavelet selection mechanism, we conducted an additional comparison between six fixed wavelet bases and the proposed adaptive wavelet transform module. In this experiment, the subsequent spatial–spectral dual-branch structure was removed, so that the analysis focuses only on the contribution of the adaptive wavelet transform module, while the remaining network structure and training settings were kept consistent. As shown in
Table 8, changing only the wavelet basis leads to noticeable performance variations. Among the fixed wavelet bases, db4 achieves the best performance. In contrast, the RMSE values of coif5 and bior53 increase to 3.5438 and 3.5493, respectively, while their PSNR values decrease to 37.1413 and 37.1277. These results indicate that the choice of wavelet basis directly affects the model’s ability to recover spatial details and preserve spectral information, and that a single fixed wavelet basis is easily limited by its inherent decomposition characteristics. Compared with db4, our AWTM achieves the best performance among the fixed wavelet bases, and our method outperforms it on all four evaluation metrics. Specifically, RMSE is reduced by approximately 12.26%, and ERGAS is reduced by approximately 10.18%. This demonstrates that the advantage of the proposed method does not simply come from relying on a specific wavelet basis, but from dynamically adjusting the contributions of different wavelet bases through the gating mechanism. In this way, the model can better exploit the complementary representation abilities of multiple wavelet bases for edge details, texture structures, and smooth regions, confirming the necessity of the adaptive wavelet selection mechanism.
To further analyze the spatial–spectral representation differences among different wavelet bases, it can be observed that db4 and db6, although both belonging to the Daubechies wavelet family, show clear performance differences. db4 achieves the best performance among the fixed wavelet bases, whereas db6 increases the RMSE to 3.5056 and decreases the PSNR to 37.2353. This result suggests that, for the Pavia Centre dataset, increasing the wavelet order does not necessarily lead to better fusion performance. The Pavia dataset contains complex land-cover regions, requiring both the recovery of high-frequency spatial details and the preservation of spectral continuity in smooth regions. Compared with db6, db4 has a relatively shorter support range and is more sensitive to local discontinuities and fine structural variations, making it more suitable for preserving edge contours and local textures in urban scenes. In contrast, although the wider support range of db6 may be beneficial for smooth representation, it may reduce sensitivity to fine edges and local textures. Similarly, the different results of sym6, coif5, and the bior wavelets indicate that different wavelet bases have different adaptability to various land-cover regions in the Pavia Centre dataset. Therefore, relying on a single fixed wavelet basis makes it difficult to simultaneously preserve structural details and spectral consistency in complex urban hyperspectral images.
4.5.2. Ablation on the MSGC
To validate the effectiveness of multi-scale grouped convolution and the bidirectional attention mechanism, in the experiments, we used the upsampled LR-HSI and the original MSI as input branches, retaining one round of non-shared adaptive wavelet modules and spatial extraction modules. Under the same training conditions, the impact of different grouping and scale configurations on the experimental results was compared.
As shown in
Table 9, in the grouping experiments, the configurations were set as three groups: 1, 3, 9; 2, 4, 8; two groups: 4, 8; and one group: 2. The scale configurations were maintained as 3 × 3, 5 × 5, and 7 × 7, as in the paper. This experiment aimed to verify whether different grouping strategies would affect the experimental results.
Based on the above data, it can be observed that the grouping strategy of 2, 4, and 8 adopted in this study achieves better accuracy. Hyperspectral images exhibit strong local continuity along the spectral dimension, where adjacent bands are highly correlated, while the degree of information redundancy and spectral variation differs across different band ranges. Therefore, a single grouping scale is insufficient to simultaneously capture the global spectral trend and local spectral differences. According to the experimental results, single-group or few-group settings show relatively limited performance, whereas group = 4 and group = 8 outperform group = 2, indicating that medium- and fine-grained grouping strategies are more effective in enhancing local spectral feature representation. Furthermore, the combination of group = 2, 4, and 8 achieves the best performance, suggesting that coarse-, medium-, and fine-grained spectral partitioning are complementary. Specifically, coarse-grained grouping helps preserve the overall spectral structure, medium-grained grouping captures spectral variations within a moderate range, and fine-grained grouping is more suitable for modeling local band differences. By combining these three grouping scales, the model can obtain both global spectral context and local spectral details, thereby improving fusion performance. In contrast, the performance of group = 1, 3, and 9 is inferior to that of group = 2, 4, and 8, indicating that the grouping strategy is not effective when arbitrarily selected. The grouping scales of 2, 4, and 8 follow a binary hierarchical partitioning manner, forming a stable coarse-to-fine spectral modeling process. In comparison, irregular group settings, such as 1, 3, and 9, may lead to imbalanced band numbers and weakened spectral correlations within each subgroup, thereby reducing the ability to preserve the continuity of adjacent spectral bands.
4.5.3. Ablation on the Bidirectional Cross-Attention
Therefore, while keeping the grouping unchanged, we aim to verify whether the bidirectional attention mechanism truly achieves cross-scale attention correlation. In the ablation experiment, all bidirectional attention modules are replaced with the self-attention mechanism from Transformer. Additionally, with the self-attention mechanism adopted, bidirectional attention interaction between
and
is not performed at the final stage; instead, they are concatenated along the channel dimension and then convolved back to the original dimensions. The final experimental results are shown in
Table 10.
It can be observed that after switching to the self-attention mechanism, all evaluation metrics underperform compared to the bidirectional attention. The PSNR metric decreased by 2.24%, while the SAM metric surged by 13.63%. This indicates that the bidirectional cross-scale attention mechanism can effectively capture the spatial and spectral relationships between the original hyperspectral data and the fused data. To a large extent, it compensates for the detail loss and other feature deficiencies caused by convolution, thereby achieving efficient performance.
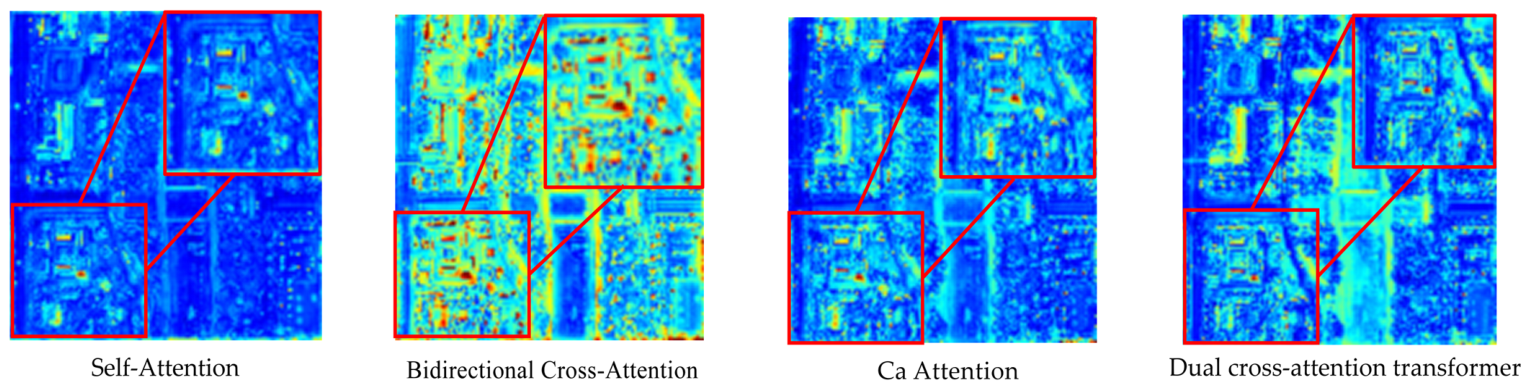
In addition, this study compares the proposed method with the state-of-the-art Dual Cross-Attention Transformer [
58] and Ca Attention [
57]. To ensure a fair comparison, the analysis focuses primarily on differences at the attention-mechanism level rather than on overall network architecture design. Specifically, under the same backbone structure, only the attention modules are replaced, enabling a more direct evaluation of the modeling capabilities of different cross-modal interaction strategies.
As shown in
Figure 11, this paper visualizes the attention mechanism on the highly challenging Washington DC Mall dataset. In the attention heatmap, warmer colors indicate stronger responses of the attention mechanism. It is worth noting that although a similar color scheme is used as in the fused pseudo-color visualization results mentioned above, their physical meanings are exactly opposite.
The experimental results demonstrate that the proposed bidirectional attention mechanism achieves clear performance advantages. One reason is that the Dual Cross-Attention Transformer can essentially be regarded as a combination of two unidirectional cross-attention modules, where each direction is modeled separately. Although this design enables bidirectional information flow, the interaction process remains relatively decoupled. Ca Attention, in contrast, mainly enhances single-feature representations through intra-domain recalibration in the spatial and spectral domains. It emphasizes internal dependency modeling but does not explicitly construct cross-modal correspondences between hyperspectral and multispectral data.
However, the key to hyperspectral–multispectral fusion lies in cross-modal joint modeling and complementary information alignment, rather than merely intra-domain feature enhancement. In comparison, the proposed method performs bidirectional cross-attention within the same layer, enabling synchronous updating and coupled interaction between the two modalities. This design strengthens symmetric constraints and complementary modeling capability, making it more suitable for fusion tasks involving strong complementarity between hyperspectral and multispectral images.
4.5.4. Ablation on the SCSGM
Finally, to further validate the impact of deep learning modules in the network on fusion performance, we extracted and independently tested the model with only the Spectral Compression and Spatial Guidance Module. This module uses depthwise separable convolutions and a feature attention mechanism. It precisely captures the interactive relationships between spatial textures and spectral information.
As shown in
Table 11, the SCSGM effectively learns spectral feature differences between spatial regions and achieves strong guidance among spatial features. The PSNR increased by 1.1120 dB, and the SAM decreased by 0.2598 dB. These results confirm that this module makes a significant contribution to noise suppression and spectral consistency.
In summary, the multi-level ablation studies clearly demonstrate the role and necessity of each sub-module in the overall architecture. Specifically, the pixel-level adaptive wavelet selection module is responsible for frequency domain enhancement and noise suppression, the multi-scale grouped convolution module enables fine-grained spectral feature extraction, and the spatial–spectral guidance module provides structural constraints and cross-dimensional feature reconstruction. The organic integration of these three components significantly enhances the comprehensive performance of hyperspectral and multispectral image fusion, providing a robust technical foundation for high-fidelity reconstruction of complex remote sensing imagery.
4.5.5. Time Efficiency Analysis of the Model
As shown in
Table 12, AWD-Net contains only 1.82 M parameters, which is significantly lower than MCT-Net with 11.23 M parameters, and also lower than MSDCNN, TFNet, ResTFNet, and RSST. This indicates that the proposed model maintains a relatively compact parameter scale. In terms of computational complexity, AWD-Net requires 32.01 G FLOPs, which is lower than MSDCNN, SSR-Net, RSST, and MCT-Net, but higher than SSFCNN, TFNet, and ResTFNet. This is mainly because AWD-Net introduces the adaptive wavelet transform, grouped multi-scale convolution, and spatial–spectral feature interaction modules, which bring additional computational cost. Although AWD-Net does not achieve the lowest FLOPs, it obtains the highest PSNR and the lowest SAM, demonstrating that it can effectively improve spatial detail recovery and spectral consistency preservation with a relatively small number of parameters, achieving a favorable balance between model complexity and fusion performance.
5. Conclusions
This paper proposes AWD-Net, a fusion framework for integrating LR-HSI and HR-MSI. In the adaptive wavelet transform module, shallow feature extraction is first performed to capture target textures and structural details, followed by a gating mechanism for adaptive wavelet selection. In addition, parallel one-dimensional wavelet transform and two-dimensional wavelet transform are adopted for preliminary fusion, where the former is used to extract spectral-dimensional information and the latter is used to capture spatial-dimensional features. In the subsequent fusion stage, a cross-scale cross-attention strategy and a spectral compression with spatial gated guidance module are introduced to enable cross-modal information interaction between high-resolution and multi-resolution images. This study aims to exploit the complementary advantages of traditional fusion techniques and deep learning, thereby developing a more effective fusion strategy.
Although the proposed method achieves favorable fusion performance on the experimental datasets, there remains room for further improvement. First, the current framework contains multiple feature extraction and cross-modal interaction modules. Although these modules jointly improve the reconstruction capability of hyperspectral images, they also introduce a certain computational cost. Specifically, for the adaptive wavelet transform module, future work may explore reducing the number of candidate wavelet bases or introducing a sparse gating strategy, so that the network assigns higher weights only to important wavelet branches, thereby reducing the computational cost caused by redundant frequency-domain decomposition. For the spectral grouping module, a dynamic grouping mechanism can be further investigated, in which the grouping scale is adaptively selected according to the spectral correlation of the input features, rather than using multiple fixed grouping branches, so as to reduce unnecessary convolution operations. For the attention module, window-based sparse attention, low-rank attention can be incorporated to reduce the computational cost of bidirectional cross-modal interaction.
The experiments in this paper are mainly conducted on simulated datasets, where LR-HSI is generated using a predefined spatial degradation model. Although this setting is a commonly used quantitative evaluation protocol in hyperspectral–multispectral image fusion tasks, it still cannot fully reflect the complex degradation factors in real imaging systems, such as sensor noise, atmospheric disturbance, and registration errors between HSI and MSI. Therefore, future work will further validate the proposed model on real HSI-MSI data pairs and explore self-supervised or unsupervised learning strategies to reduce the dependence on ideal reference images. In addition, domain adaptation methods will be considered to improve the generalization ability of the model under real degradation conditions, thereby promoting the deployment of the proposed framework in practical remote sensing applications.