


Abstract
Efficient and realistic large-scale scene modeling is an important application of low-altitude remote sensing. Although the emerging 3DGS technology offers a simple process and realistic results, its high computational resource demands hinder direct application in large-scale 3D scene reconstruction. To address this, this paper proposes a novel grid-based scene-segmentation technique for the process of reconstruction. Sparse point clouds, acting as an indirect input for 3DGS, are first processed by Z-Score and a percentile-based filter to prepare the pure scene for segmentation. Then, through grid creation, grid partitioning, and grid merging, rational and widely applicable sub-grids and sub-scenes are formed for training. This is followed by integrating Hierarchy-GS’s LOD strategy. This method achieves better large-scale reconstruction effects within limited computational resources. Experiments on multiple datasets show that this method matches others in single-block reconstruction and excels in complete scene reconstruction, achieving superior results in PSNR, LPIPS, SSIM, and visualization quality.
1. Introduction
Low-altitude remote sensing images are highly flexible, spatially resolved, and offer strong timeliness. Thus, they are crucial in virtual geographic environments across fields [1]. Before the popularity of artificial intelligence, the most common 3D reconstruction methods included artificial construction, oblique photogrammetry, laser scanning [2], and multi-view stereo matching [3,4], representing objects using explicit geometric models, such as meshes [5], point clouds [6], voxels [7], and depth [8]. Despite the extensive application of these established methods in the industry, they still exhibit certain limitations [9,10,11]. Recently, numerous neural implicit representation methods have emerged with the deep integration of neural networks and rendering [12,13,14,15]. Neural Radiance Fields (NeRF) [16], a leading technique, uses neural networks to compute spatial sampling points’ color and density. These are integrated along viewing rays to generate view pixel colors, achieving impressive photo-realistic view synthesis. However, NeRF has slow training and inference speed and is mostly limited to small-scale scenes. Moreover, its 3D modeling quality still has room for improvement.
Introduced as an advancement on NeRF, 3D Gaussian Splatting (3DGS) [17] starts with Structure from Motion (SFM) to calculate the input image’s camera pose, forming a sparse point cloud. This cloud initializes a 3D Gaussian cloud, which is projected onto the image plane via EWA and then rasterized with alpha-blending. The result is a point-cloud file containing all rendering information, representing the reconstructed scene. Notably, 3DGS outperforms NeRF in rendering speed and quality, and its storage format allows easy integration with existing explicit models like meshes and point clouds [17,18]. But, it is a memory-intensive 3D modeling method. For large-scale 3D scene reconstruction, conventional GPUs fall short in computational resources, failing to complete the task.
To achieve the research objective of efficiently reconstructing large-scale photorealistic geographic scenes, this study comprehensively analyzes the 3D scene modeling effects of NeRF and 3DGS. To mitigate the high memory demands of large-scene 3D reconstruction on GPU and enhance the visualization quality, this method introduces two innovations. Firstly, based on the distribution of the input sparse point cloud, Z-score and a percentile-based filter are employed to cleanse the point cloud, thereby eliminating isolated points and minimizing artifacts. Secondly, considering the 3D spatial distribution characteristic of the point cloud, the entire scene is segmented into uniform grids to mitigate the occurrence of excessively small or large segments, ensuring smooth large-scale reconstruction on normal GPUs.
2. Related Work
2.1. Three-Dimensional Modeling Using NeRF
Neural Radiance Fields (NeRF) was first introduced in 2020 [16]. This technique enables the photo-realistic visualization of 3D scenes through neural implicit stereo representation, significantly surpassing traditional methods in terms of fidelity and detail. Consequently, it has garnered extensive attention and experienced rapid development [19,20,21,22,23,24,25,26,27,28,29]. Current research hotspots can be categorized into four main areas [30]: enhancing the robustness of source data, enabling dynamic controllable scenes, improving rendering efficiency, and optimizing visual effects.
To boost source data robustness using NeRF, Ref. [31] enhances image pose accuracy via camera parameter optimization. Deblur-NeRF [32] uses denoising for high-quality view synthesis from poor images. Mirror-NeRF [33] uses a standardized multi-view system to improve source data quality. In dynamic scenes, D-NeRF and H-NeRF [34,35] enable scene editing via parameterizing the NeRF scene. Clip-NeRF [36] integrates generative models for autonomous scene generation. To render efficiency improvement, three main strategies are employed: incorporating explicit model data to enhance prior knowledge, such as Point-NeRF and E-NeRF [28,37]; optimizing sampling methods to cut down invalid sampling calculations, such as DONERF [38]; and decomposing scenes to improve parallel computing rates, such as KiloNeRF [39]. Among these, Instant-NGP [40] achieves the best results. In effect optimization, geometric reasoning with MVS improves accuracy. MVSNeRF [41] simulates some physical processes, like refraction, transmission, and reflection, while NeRFReN and Ref-NeRF [42,43] enhance the regularization terms to fully optimize reconstructed optical properties.
2.2. Three-Dimensional Modeling Using 3DGS
Three-dimensional Gaussian Splatting (3DGS), introduced in 2023 as an extension of NeRF [17], utilizes an explicit representation and a highly parallelized workflow. It projects millions of 3D Gaussians into the imaging space for alpha-blending to achieve scene representation.
Compared to NeRF, 3DGS significantly enhances computational and rendering efficiency while preserving the realism of the rendering effect. Research focused on 3DGS can be categorized into three primary areas [18,44]: enhancing detail rendering, extending dynamic scene modeling, and compressing Gaussian storage.
To enhance detail rendering, methods such as Multi-Scale 3DGS [45], Deblur-GS [46], and Mip-Splatting [47] tackle issues like low-resolution aliasing, high-frequency artifacts, blurring in training images, and color inaccuracies of 3D objects. For dynamic scene modeling, Gaussian-Flow [48] captures and reproduces temporal changes in a scene’s 3D structure and appearance. GaussianEditor and Gaussian Grouping [49,50,51] integrate semantic segmentation to segment the complete scene and then edit it based on objects’ attributes, such as geometry and surface. Animatable Gaussians [52] use explicit face models to better simulate complex facial expressions and details. To compress Gaussian storage, LightGaussian [53] and HiFi4G [54] focus on optimizing memory utilization during both the training and model storage phases. They have achieved significant compression rates while largely preserving visual quality.
2.3. Large-Scale 3D Scene Reconstruction
To support geographical applications, comprehensive scene reconstruction must be conducted over large areas with high efficiency. To date, there has been some progress in utilizing NeRF and 3DGS for the 3D modeling of geographical scenes.
On the NeRF side, several approaches have been proposed. S-NeRF [55], Sat-NeRF [27], and GC-NeRF [56] leverage multi-view high-resolution satellite images with known poses to achieve view synthesis, thereby obtaining more accurate digital surface models (DSMs). However, these methods still exhibit significant limitations in model generalization and handling illumination effects. Mega-NeRF [57] and Block-NeRF [58] divide scenes into multiple sub-blocks for parallel training, fusing information from adjacent blocks to mitigate boundary effects and ensure continuity across the entire large-scale scene.
Several 3D Gaussian Splatting (3DGS) methodologies, including VastGaussian [59], Octree-GS [60], DoGaussian [61], and Hierarchy-GS [62], have been developed. Due to the significant memory resources required for 3DGS training, large-scale scene modeling often needs extensive computational resources, incurring high costs. To tackle this, VastGaussian, DoGaussian, and Hierarchy-GS put forward their own scene-segmentation strategies to enable large-scene reconstruction using normal-level GPUs. However, these methods mainly focus on the XY-plane, overlooking the Z-axis distribution and causing uneven segmentation. To boost rendering speed and ease rendering pressure, Octree-GS and Hierarchy-GS adopt the Level of Detail (LOD) concept as another basic strategy. But Octree-GS’s transitions between different scene levels are less smooth than Hierarchy-GS due to its limited number of levels.
After analyzing these methods, this paper proposes a grid-based strategy based on point-cloud 3D distribution for more reasonable, universal, and uniform scene segmentation. It also integrates Hierarchy-GS’s LOD hierarchical rendering strategy to ensure a more complete 3D scene representation.
3. Preliminary
3.1. Three-Dimensional Gaussian Splatting
Three-dimensional Gaussian Splatting starts with a set of Sfm points and initializes the point cloud into several 3D Gaussians. Its mathematical representation is as follows:
where is an arbitrary position in the 3D space, is the center (average) position of the Gaussian, and represents the covariance matrix of the Gaussian. is the product of the rotation matrix and the scale matrix .
After initialization and training, millions of Gaussians are distributed in the 3D space. These Gaussians are projected onto a 2D image plane for rendering by splatting, as follows:
where J and W represent the first-order affine approximation of perspective projection transformation and the viewing angle transformation matrix, respectively.
Each Gaussian has properties such as position, opacity, rotation, scale, and spherical harmonic coefficients (color). When rendering, for each pixel on the imaging plane, its color is accumulated from several ellipses projected above it, and the rendering formula is as follows:
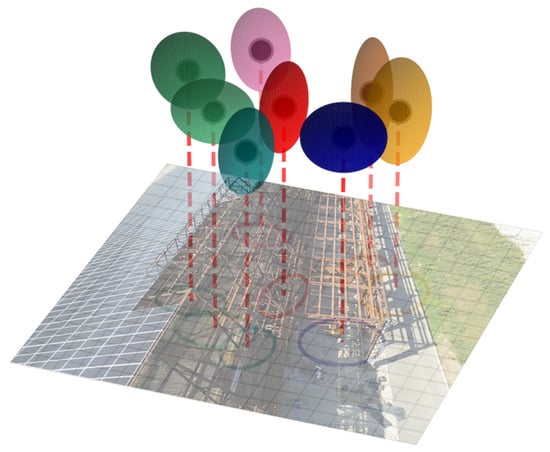
where is the Gaussians’ opacity and is the color. The expression of the scene is shown in Figure 1.
Figure 1.
Schematic of 3DGS’s scene expression.
3.2. Hierarchy-GS
During the 3DGS training process, tens of thousands to millions of Gaussians are generated, and most of these dozens of attributes are fed into the GPU for computation, thereby causing a heavy computational load. Hierarchy-GS introduces a skybox pre-trained with SfM points during training, which turns the unbounded scene into a bounded one and reduces the number of Gaussians generated during training. It also modifies the densification strategy of 3DGS, replacing the average with the maximum of the observed screen-space gradients for densification, thereby better controlling Gaussian growth. In addition, it adopts a scene-segmentation strategy, generating the Gaussians of the entire scene in separate time intervals to reduce their peak memory usage. These work together to achieve computational resource reduction.
Additionally, it proposes an LOD strategy based on the trained Gaussian set. Firstly, an AABB (Axis-Aligned Bounding Box) is created for the Gaussian set. Then, based on the binary median segmentation method, the Gaussian set in the bounding box is recursively split into each leaf node, and each leaf node is guaranteed to contain only one Gaussian. A Gaussian hierarchical tree with a binary tree structure is constructed, but only the leaf nodes have Gaussians. Finally, bottom–up Gaussian merging is performed, starting from the leaf node and merging upwards according to the weight of the node to form a new Gaussian as the internal node. The formula is as follows:
When consolidating the structure hierarchy trees of each sub-scene, almost repeated Gaussians and some Gaussians that are out of range will be deleted. When rendering, calculate the size of the AABB and the long side of the node Gaussian projected onto the imaging screen as the hierarchical granularity . If the of node is smaller than the given granularity , but its parent node does not meet the requirement, it will be used as the Gaussian participating in the rendering process.
4. Methodology
4.1. Architecture Overview
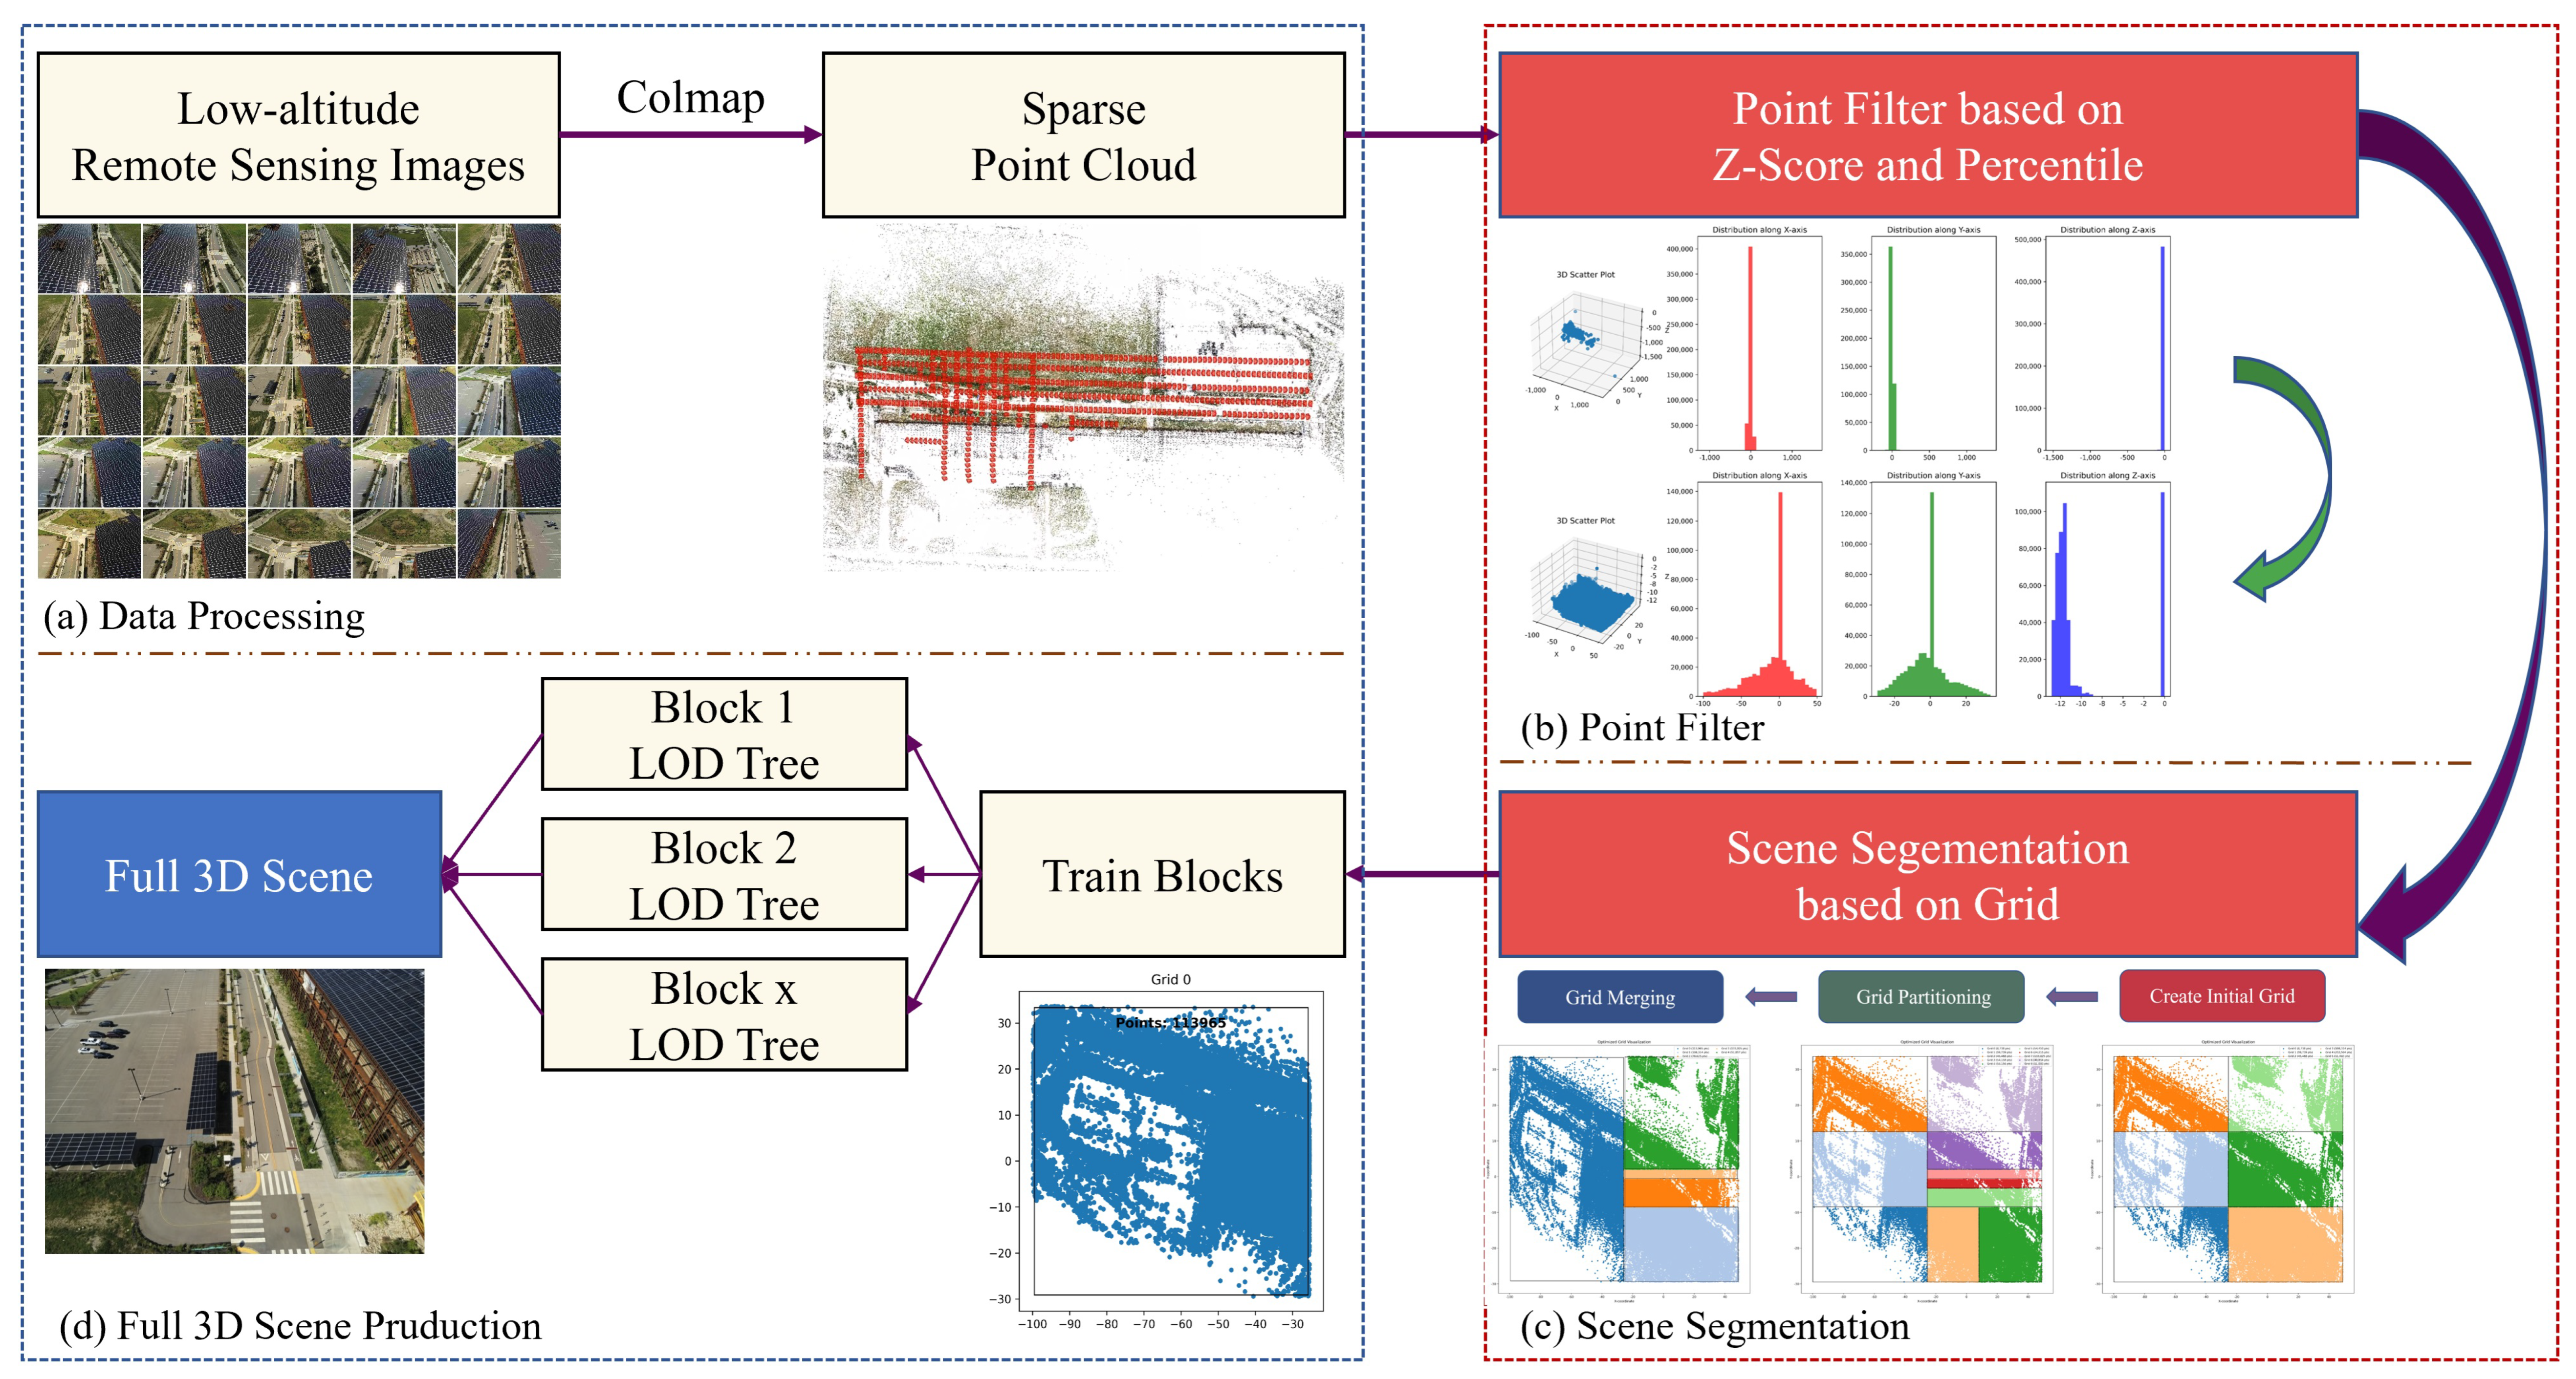
The general architecture proposed in this article, illustrated in the accompanying Figure 2, integrates advancements in the original 3DGS approach and the LOD strategy from Hierarchy-GS with our own segmentation strategy.
Figure 2.
General architecture and example effect based on Building data.
To acquire low-altitude remote sensing images via UAVs, this method uses Colmap for sparse reconstruction to obtain camera poses and sparse point clouds in the scene. It filters the point clouds with Z-Score and percentile-based approaches to remove redundant and stray points, yielding a cleaner point cloud. Then, the point cloud is mapped to the XY-plane for grid initialization. The scene is segmented into preset grid numbers and undergoes iterative grid partitioning and adjacent grid merging to obtain final scene blocks. Based on Hierarchy-GS’s training and LOD strategy, each block is trained with low computing resources and its hierarchical structure tree is built to obtain the complete scene rendering result.
4.2. Point Cloud Filtering
Three-dimensional Gaussian Splatting (3DGS) and its derivative methods heavily rely on the distribution of sparse point clouds obtained through SfM during the progress of Gaussian cloud initialization. Each point location generates a randomly initialized Gaussian. However, SfM-generated point clouds inevitably contain outlier points that deviate from the main structure, which consequently leads to redundant Gaussians. These will negatively impact optimization efficiency and rendering quality during subsequent training. To address this issue, this paper proposes a straightforward filtering approach for effective point selection and elimination.
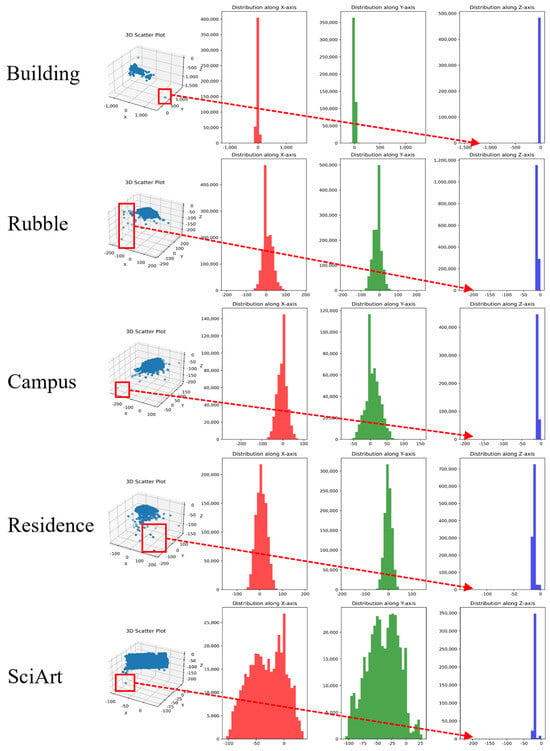
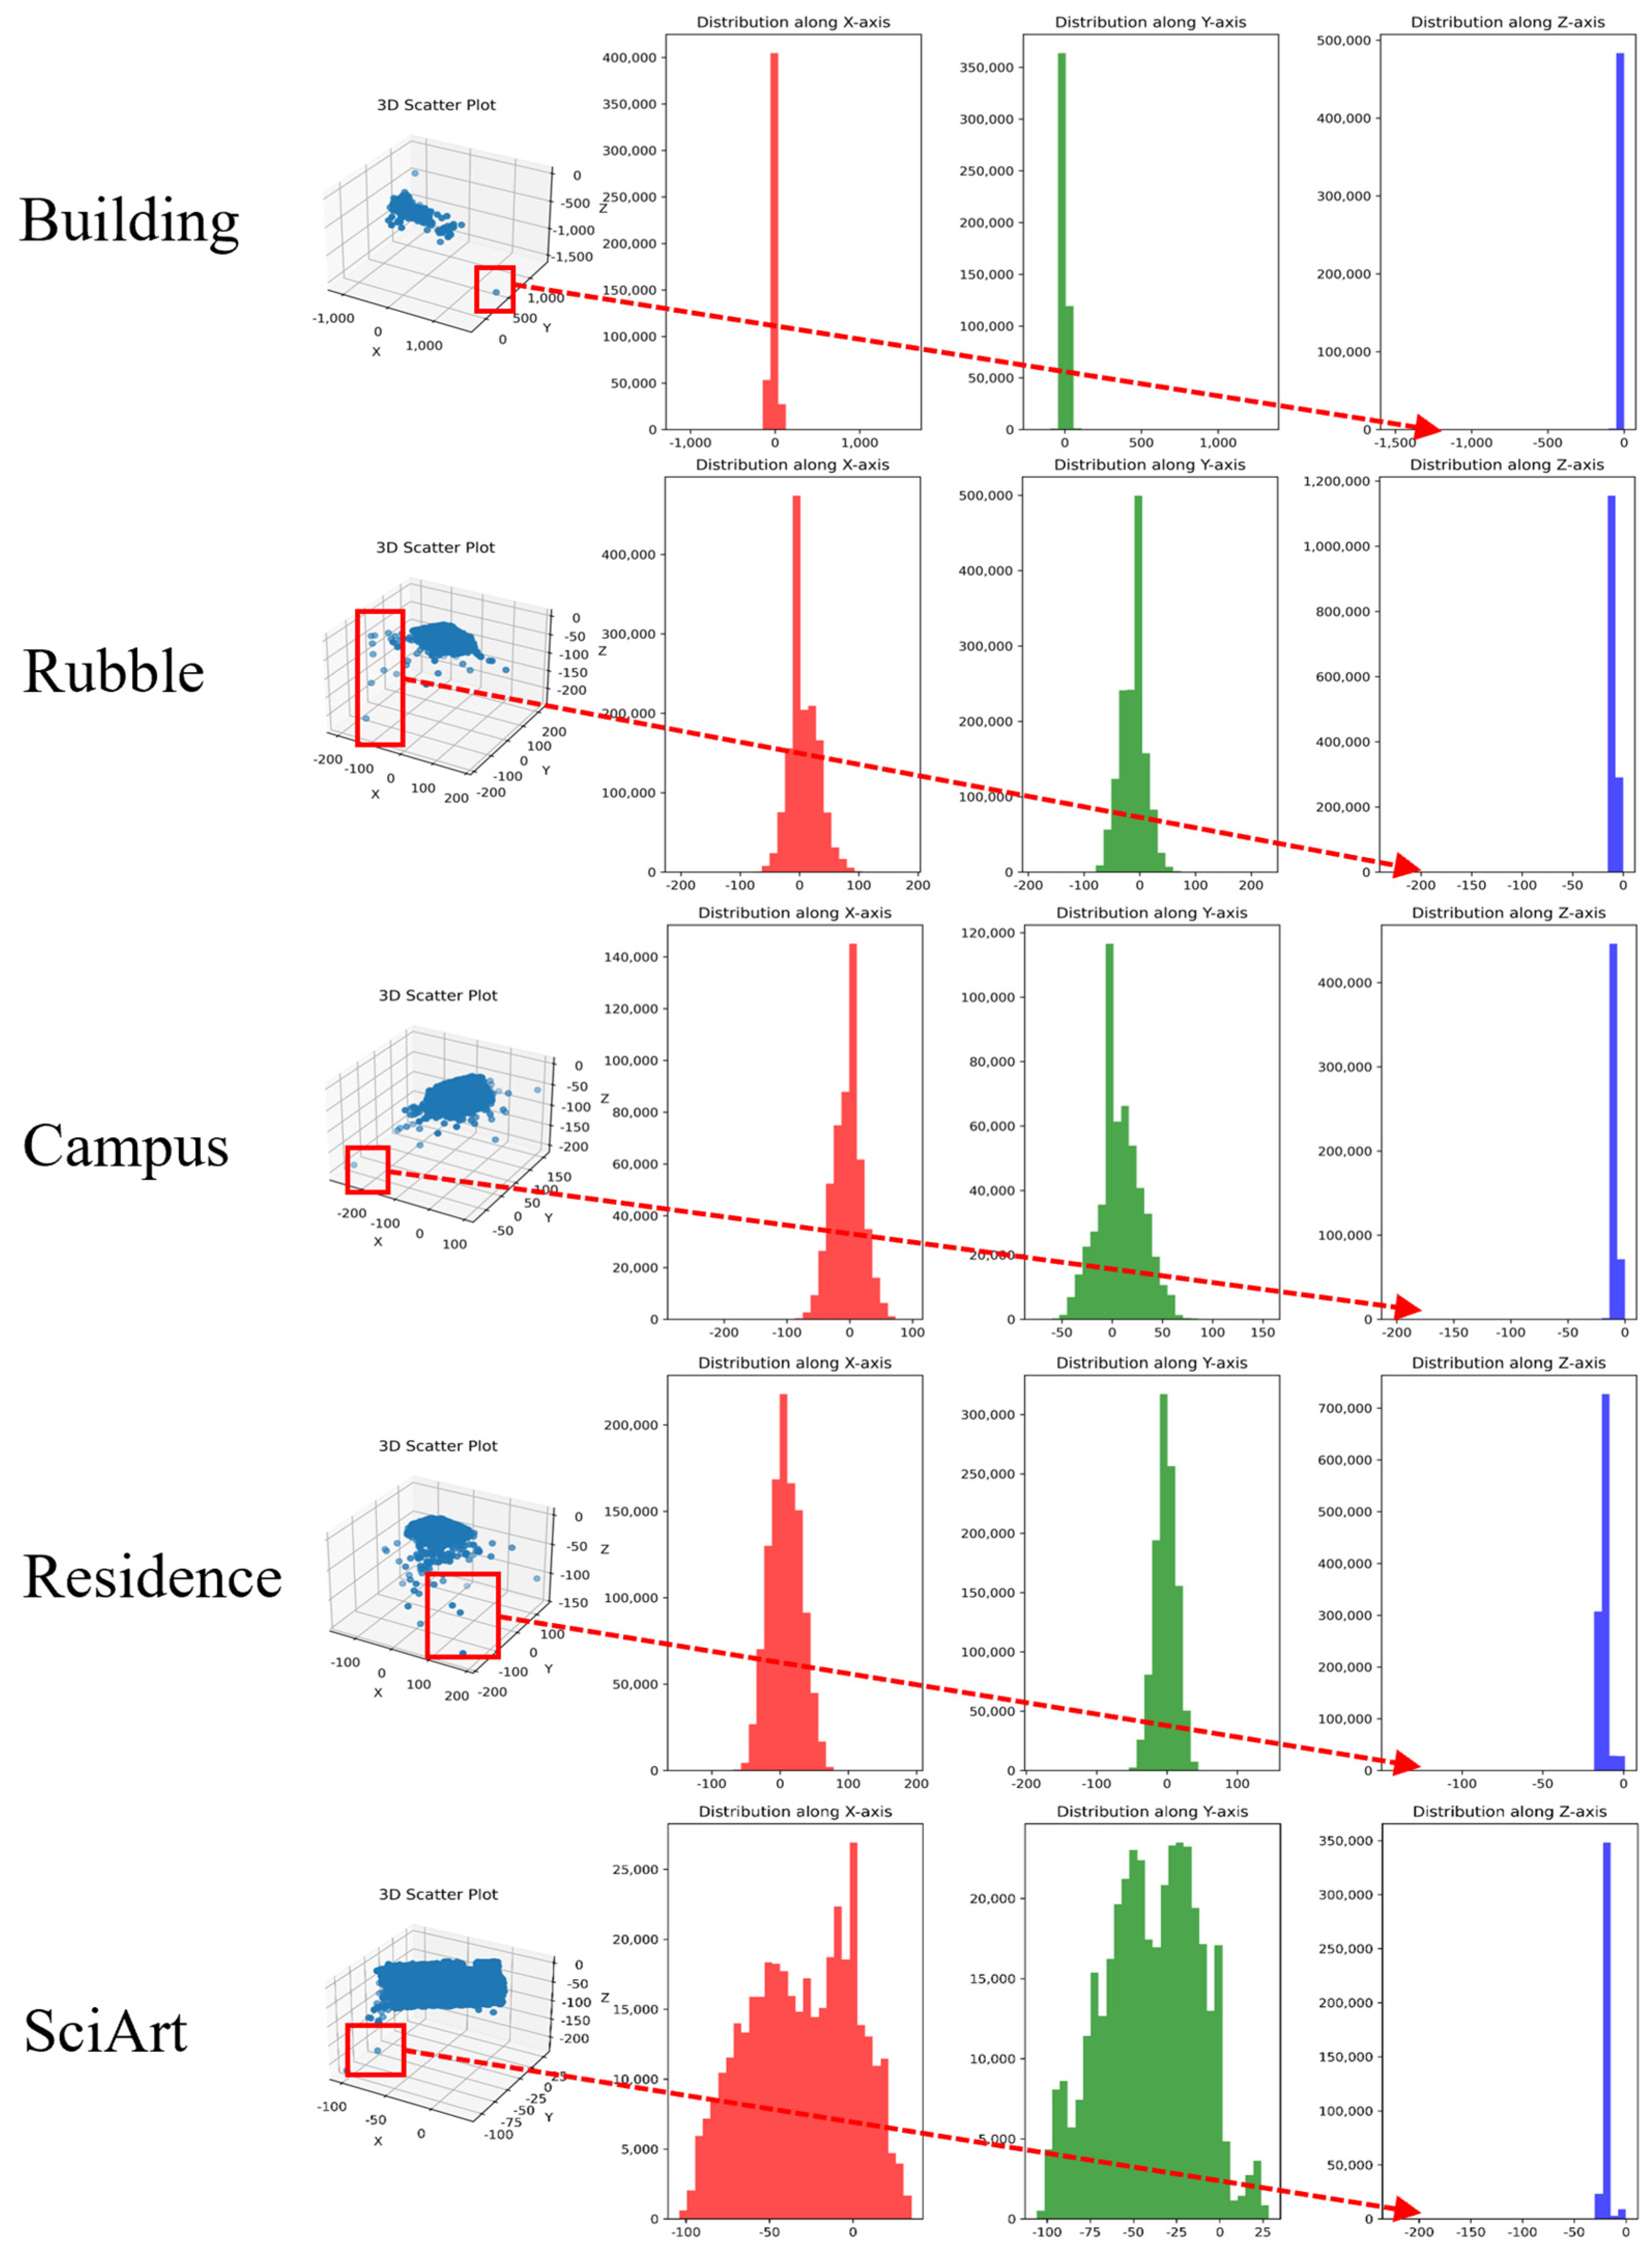
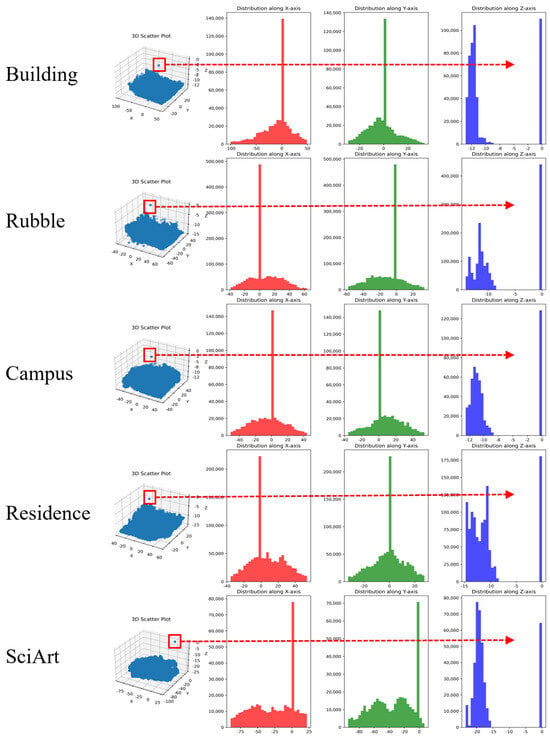
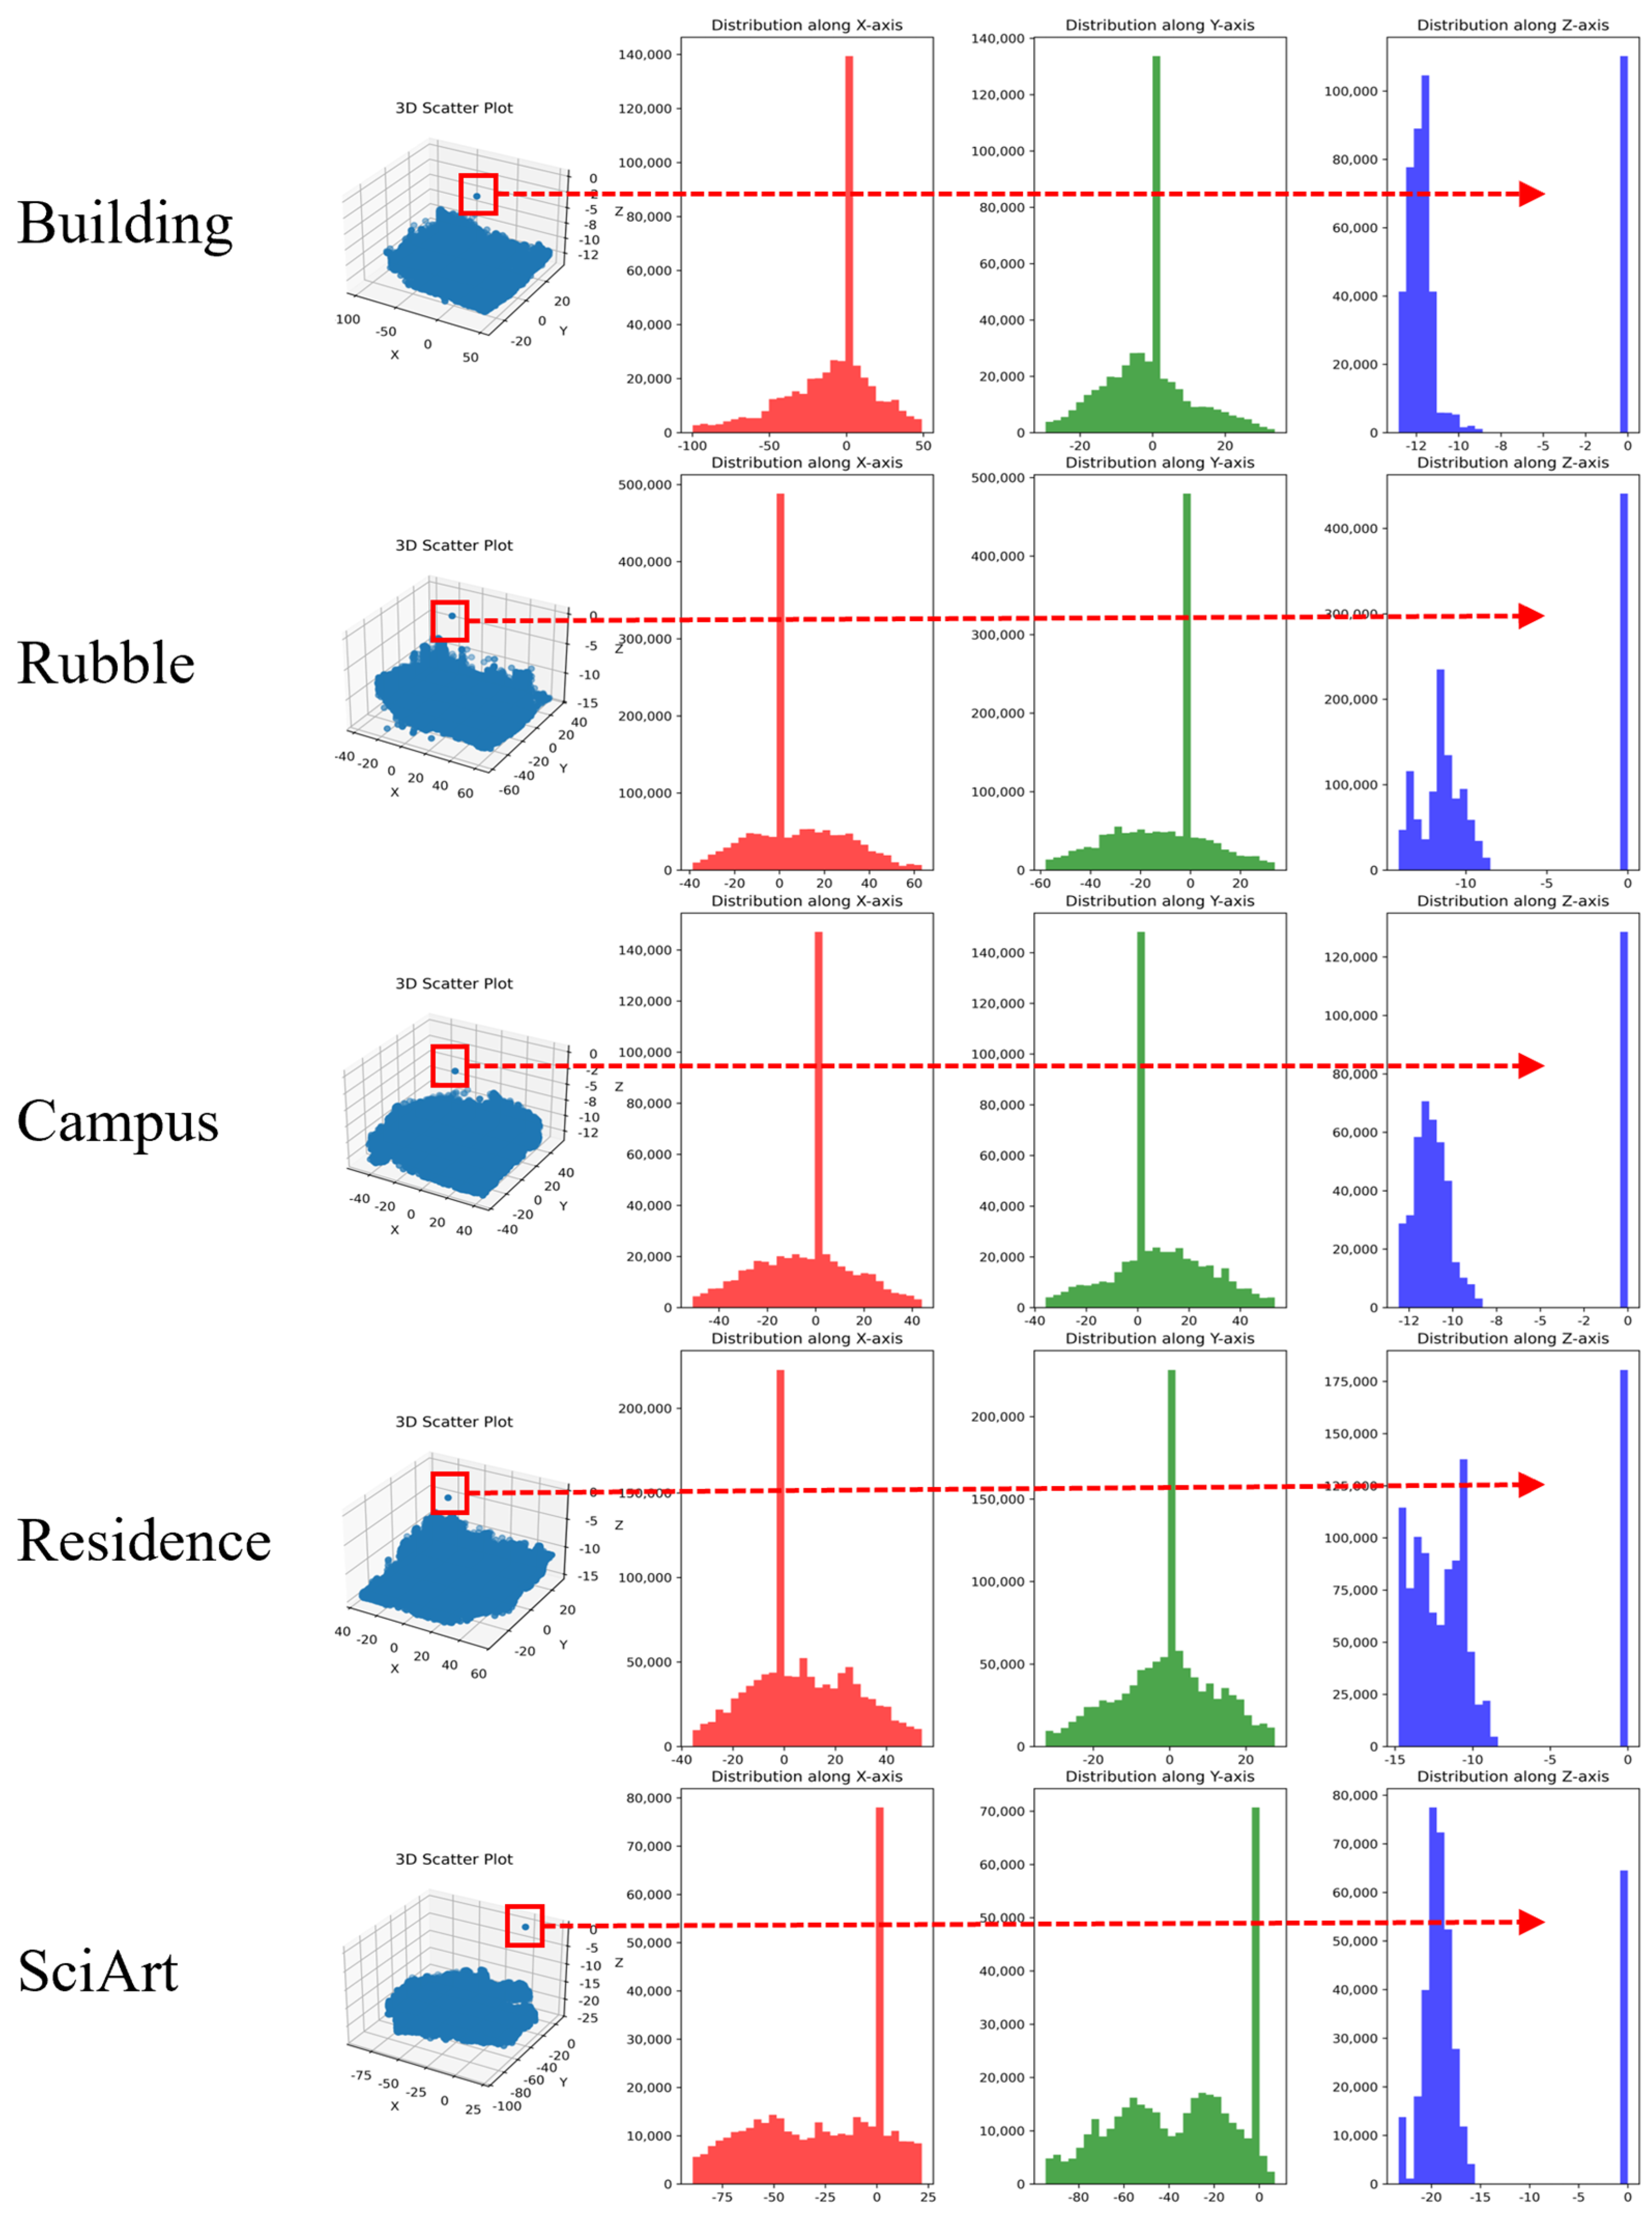
From Figure 3, several characteristics of the sparse point cloud reconstructed by SfM can be analyzed: ① The overall distribution is generally uniform, concentrated within a specific space, but there are still some stray points far from the main subject. ② The histogram distribution along the X-axis and Y-axis (red and green histograms) shows a class of normal distribution centered at the origin, gradually decreasing towards both sides, with a few stray points at the extreme edges. ③ From the Z-axis perspective, in addition to those concentrated near the origin, there are also a few stray points far from the main subject, often concentrated in the negative region.
Figure 3.
Histogram of original sparse point cloud.
Therefore, this method employs two filtering approaches for the -axis, -axis, and Z-axis directions. The point-cloud data exhibit characteristics of a normal distribution along the X- and Y-axis; hence, the Z-Score method is used for filtering, following the steps shown in Formula (8). The point-cloud data are mapped separately onto the X-axis and Y-axis and filtered directionally. For each data point in the point cloud, calculate the difference between it and the mean value of the dataset, then divide this difference by the standard deviation of the dataset. This yields the Z-score , representing the position of the data point relative to the center of the data distribution. Z-scores with absolute values exceeding 2 are considered outliers, as they deviate from the mean by more than 2 standard deviations. According to the normal distribution, this approach retains 95.45% of the data points.
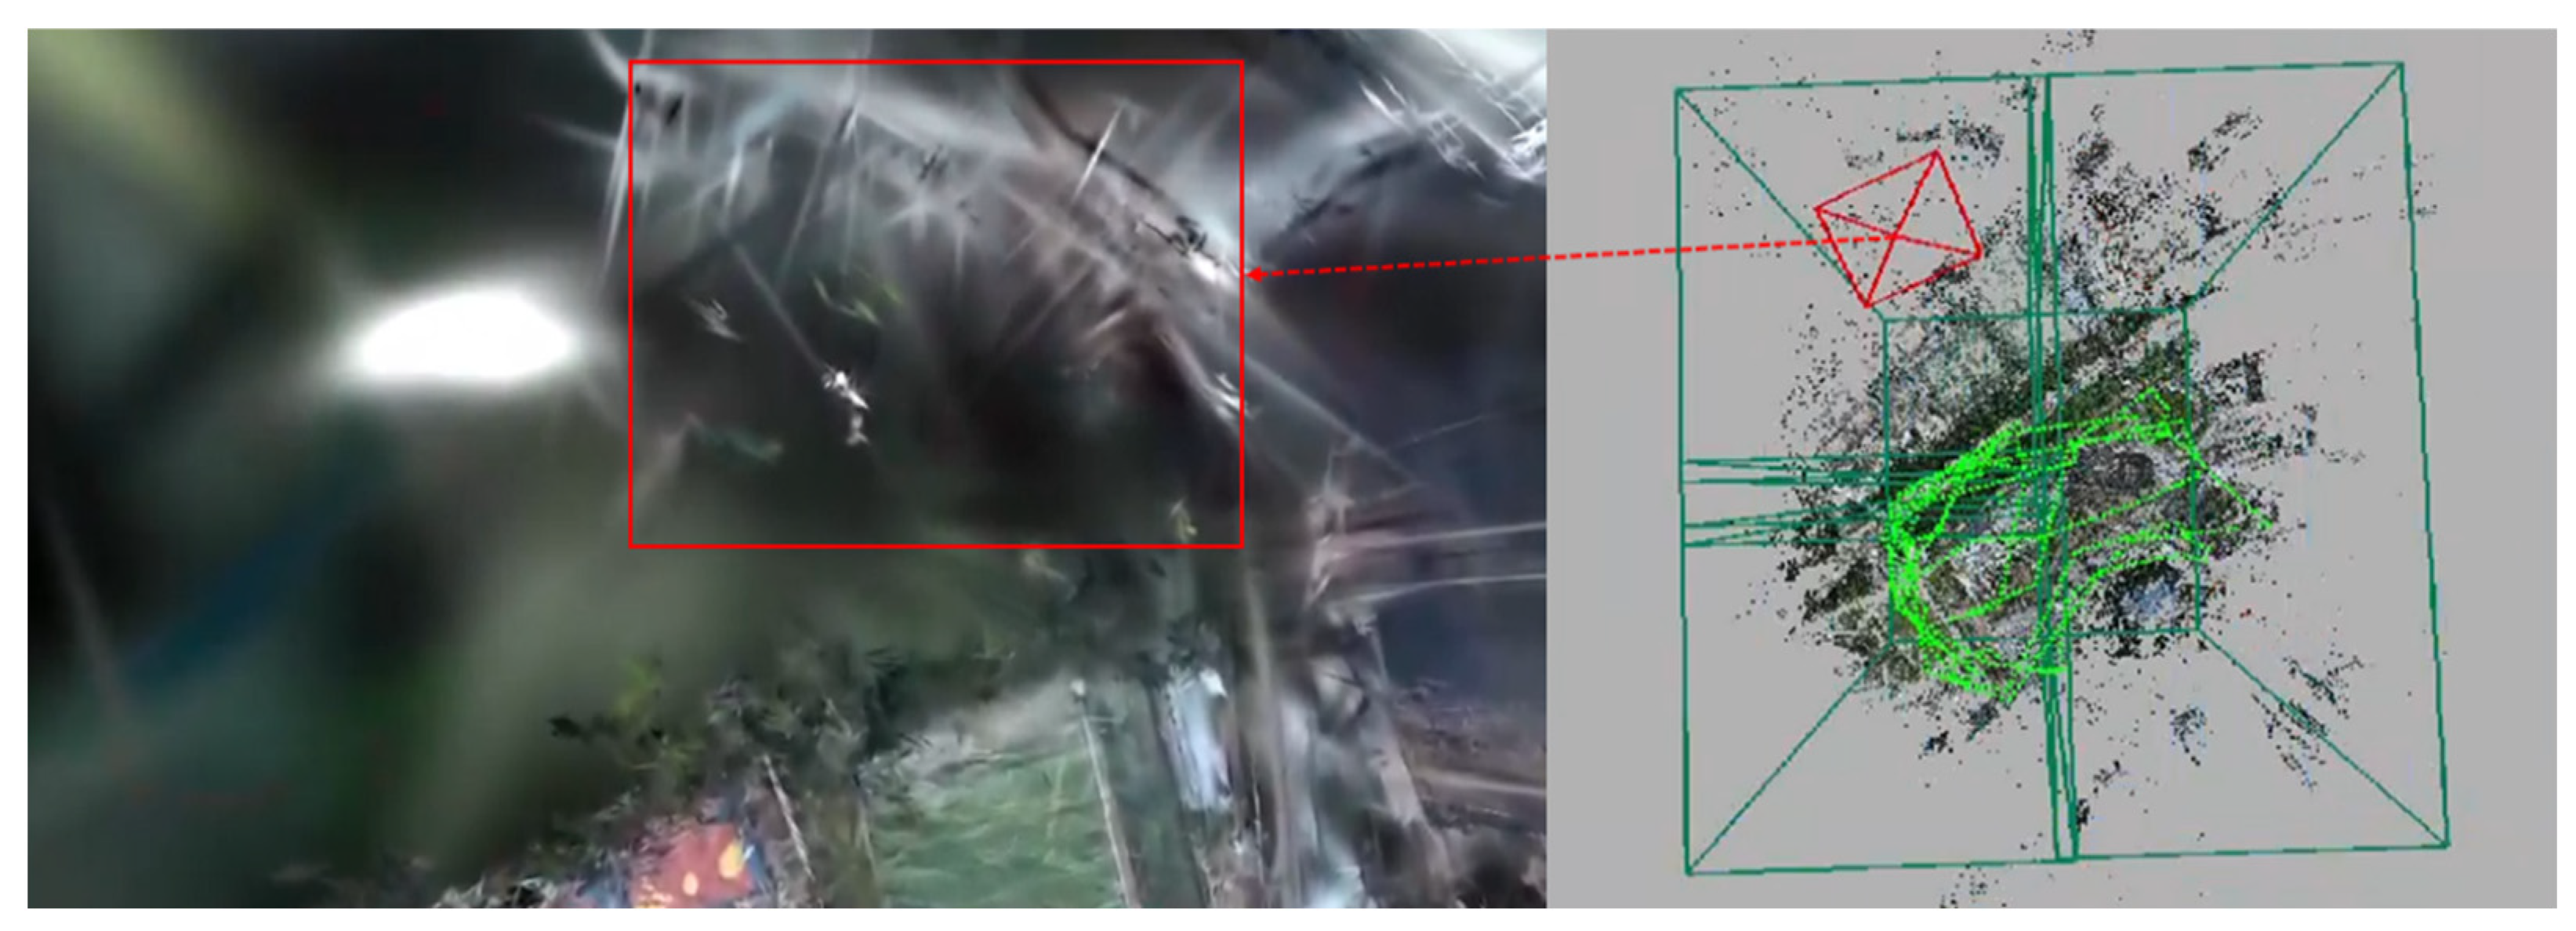
The threshold value is set to 2 instead of 3 due to the characteristics of the 3DGS class method in reconstructing scene edges. Points at the scene edges play a relatively minor role during training, and the reconstructed edge areas lack ground truth for comparison, resulting in poorer performance in these regions, as shown in Figure 4 with the Polytech edge reconstruction. Therefore, for the -plane, the range can be appropriately reduced to concentrate the data more effectively and eliminate stray points more thoroughly.
Figure 4.
Polytech edge reconstruction effect.
Regarding the Z-axis, there is no need for extensive consideration. It can be observed that the majority of points in the point cloud are concentrated near the origin, with only a very small number of points being extremely distant from the center of aggregation. Therefore, a simpler percentile filtering method can be employed to remove these outlier points, as shown in Equation (9).
After mapping all point-cloud data to the z-axis, sort them by size, and then select points between the 2.5th percentile and the 99th percentile. The final filtering result is shown in Figure 5.
Figure 5.
Histogram of filtered sparse point cloud.
4.3. Grid-Based Scene Segmentation
4.3.1. Create Initial Grid
The first step is to establish the initial grid by constructing a regular grid area according to the pre-specified number of blocks ( and , which are set at 2 and 3 by default) using the entire spatial range of the point set, with an optional overlap ratio. The method begins by projecting the 3D point cloud onto the -plane to form a 2D point set . The maximum and minimum values of the point set in the and directions are determined to define the extent of the grid. Based on the preset number of blocks and the overall range, this method then determines the width and height of each subgrid. Given the overlap ratio (here set to 5%) between blocks, the horizontal and vertical overlap distances and are computed. Following this, the lower-left corner coordinates () and upper-right corner coordinates () of each sub-grid are calculated to define the grid boundaries. Finally, the number of 3D points within each block is counted based on the block’s boundaries. Through projection, the point set not only accurately reflects the distribution on the -plane, but also considers the distribution characteristics along the -axis, thereby completing the initialization of the point cloud grid.
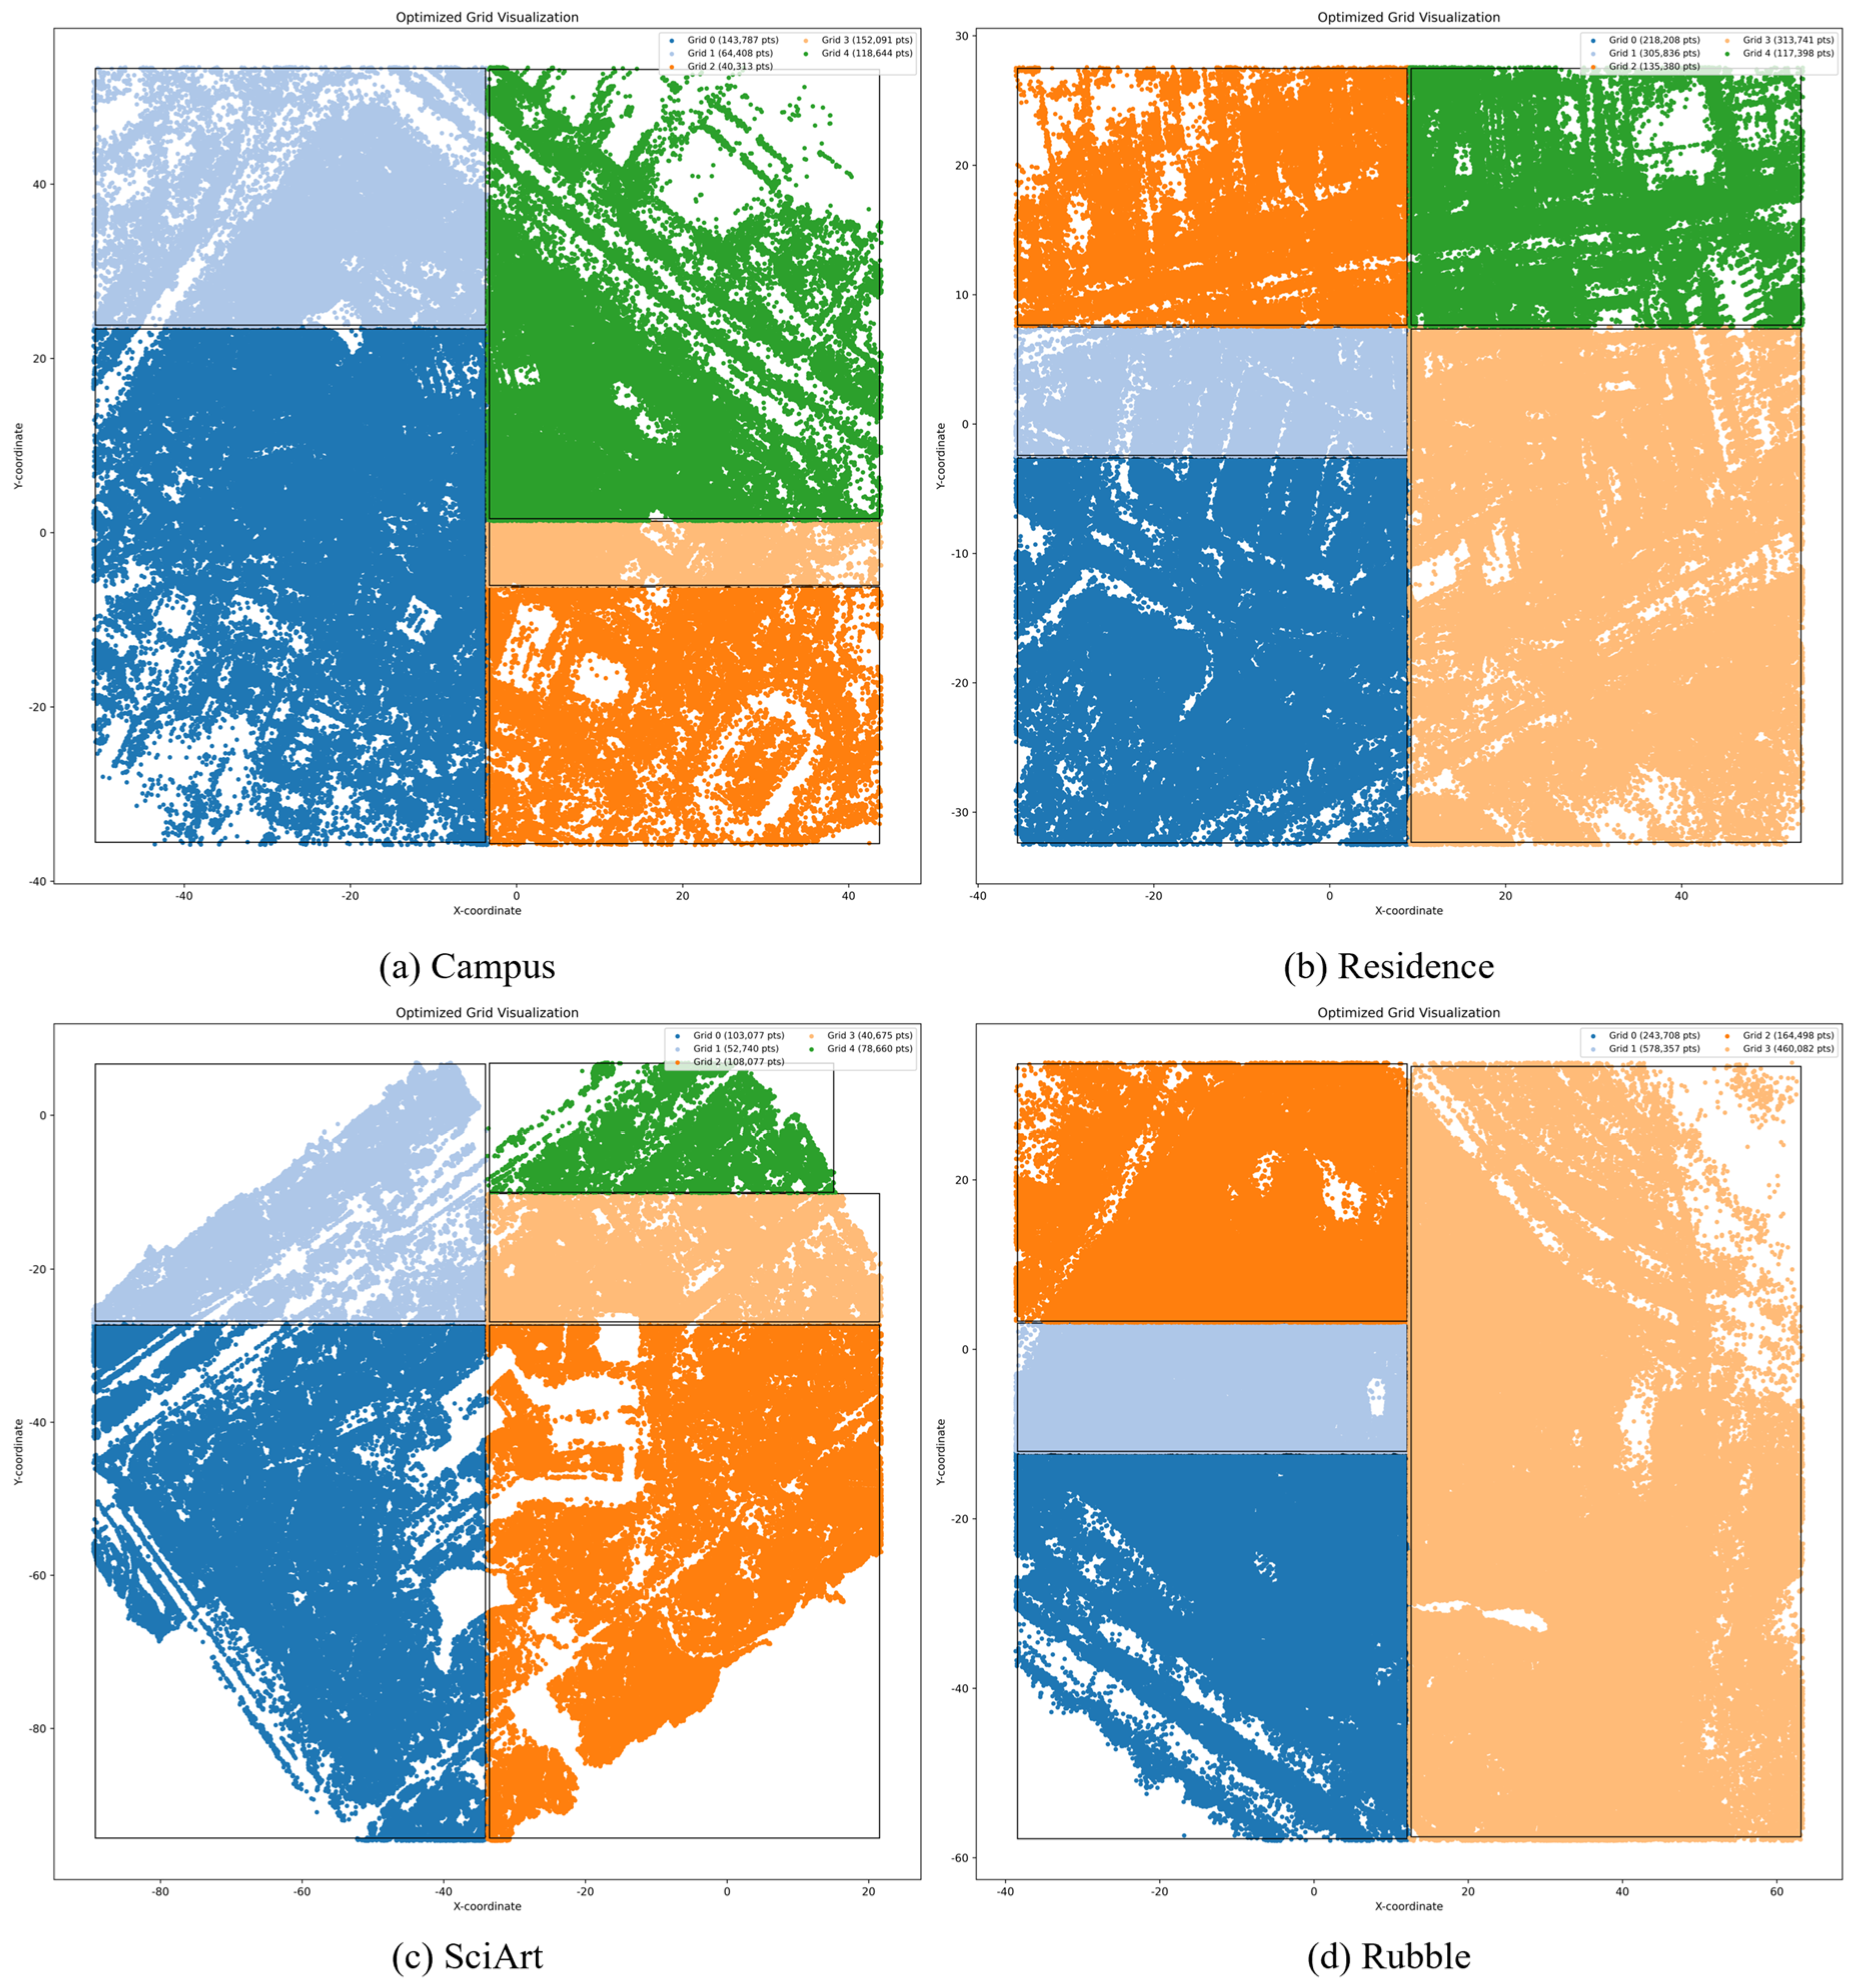
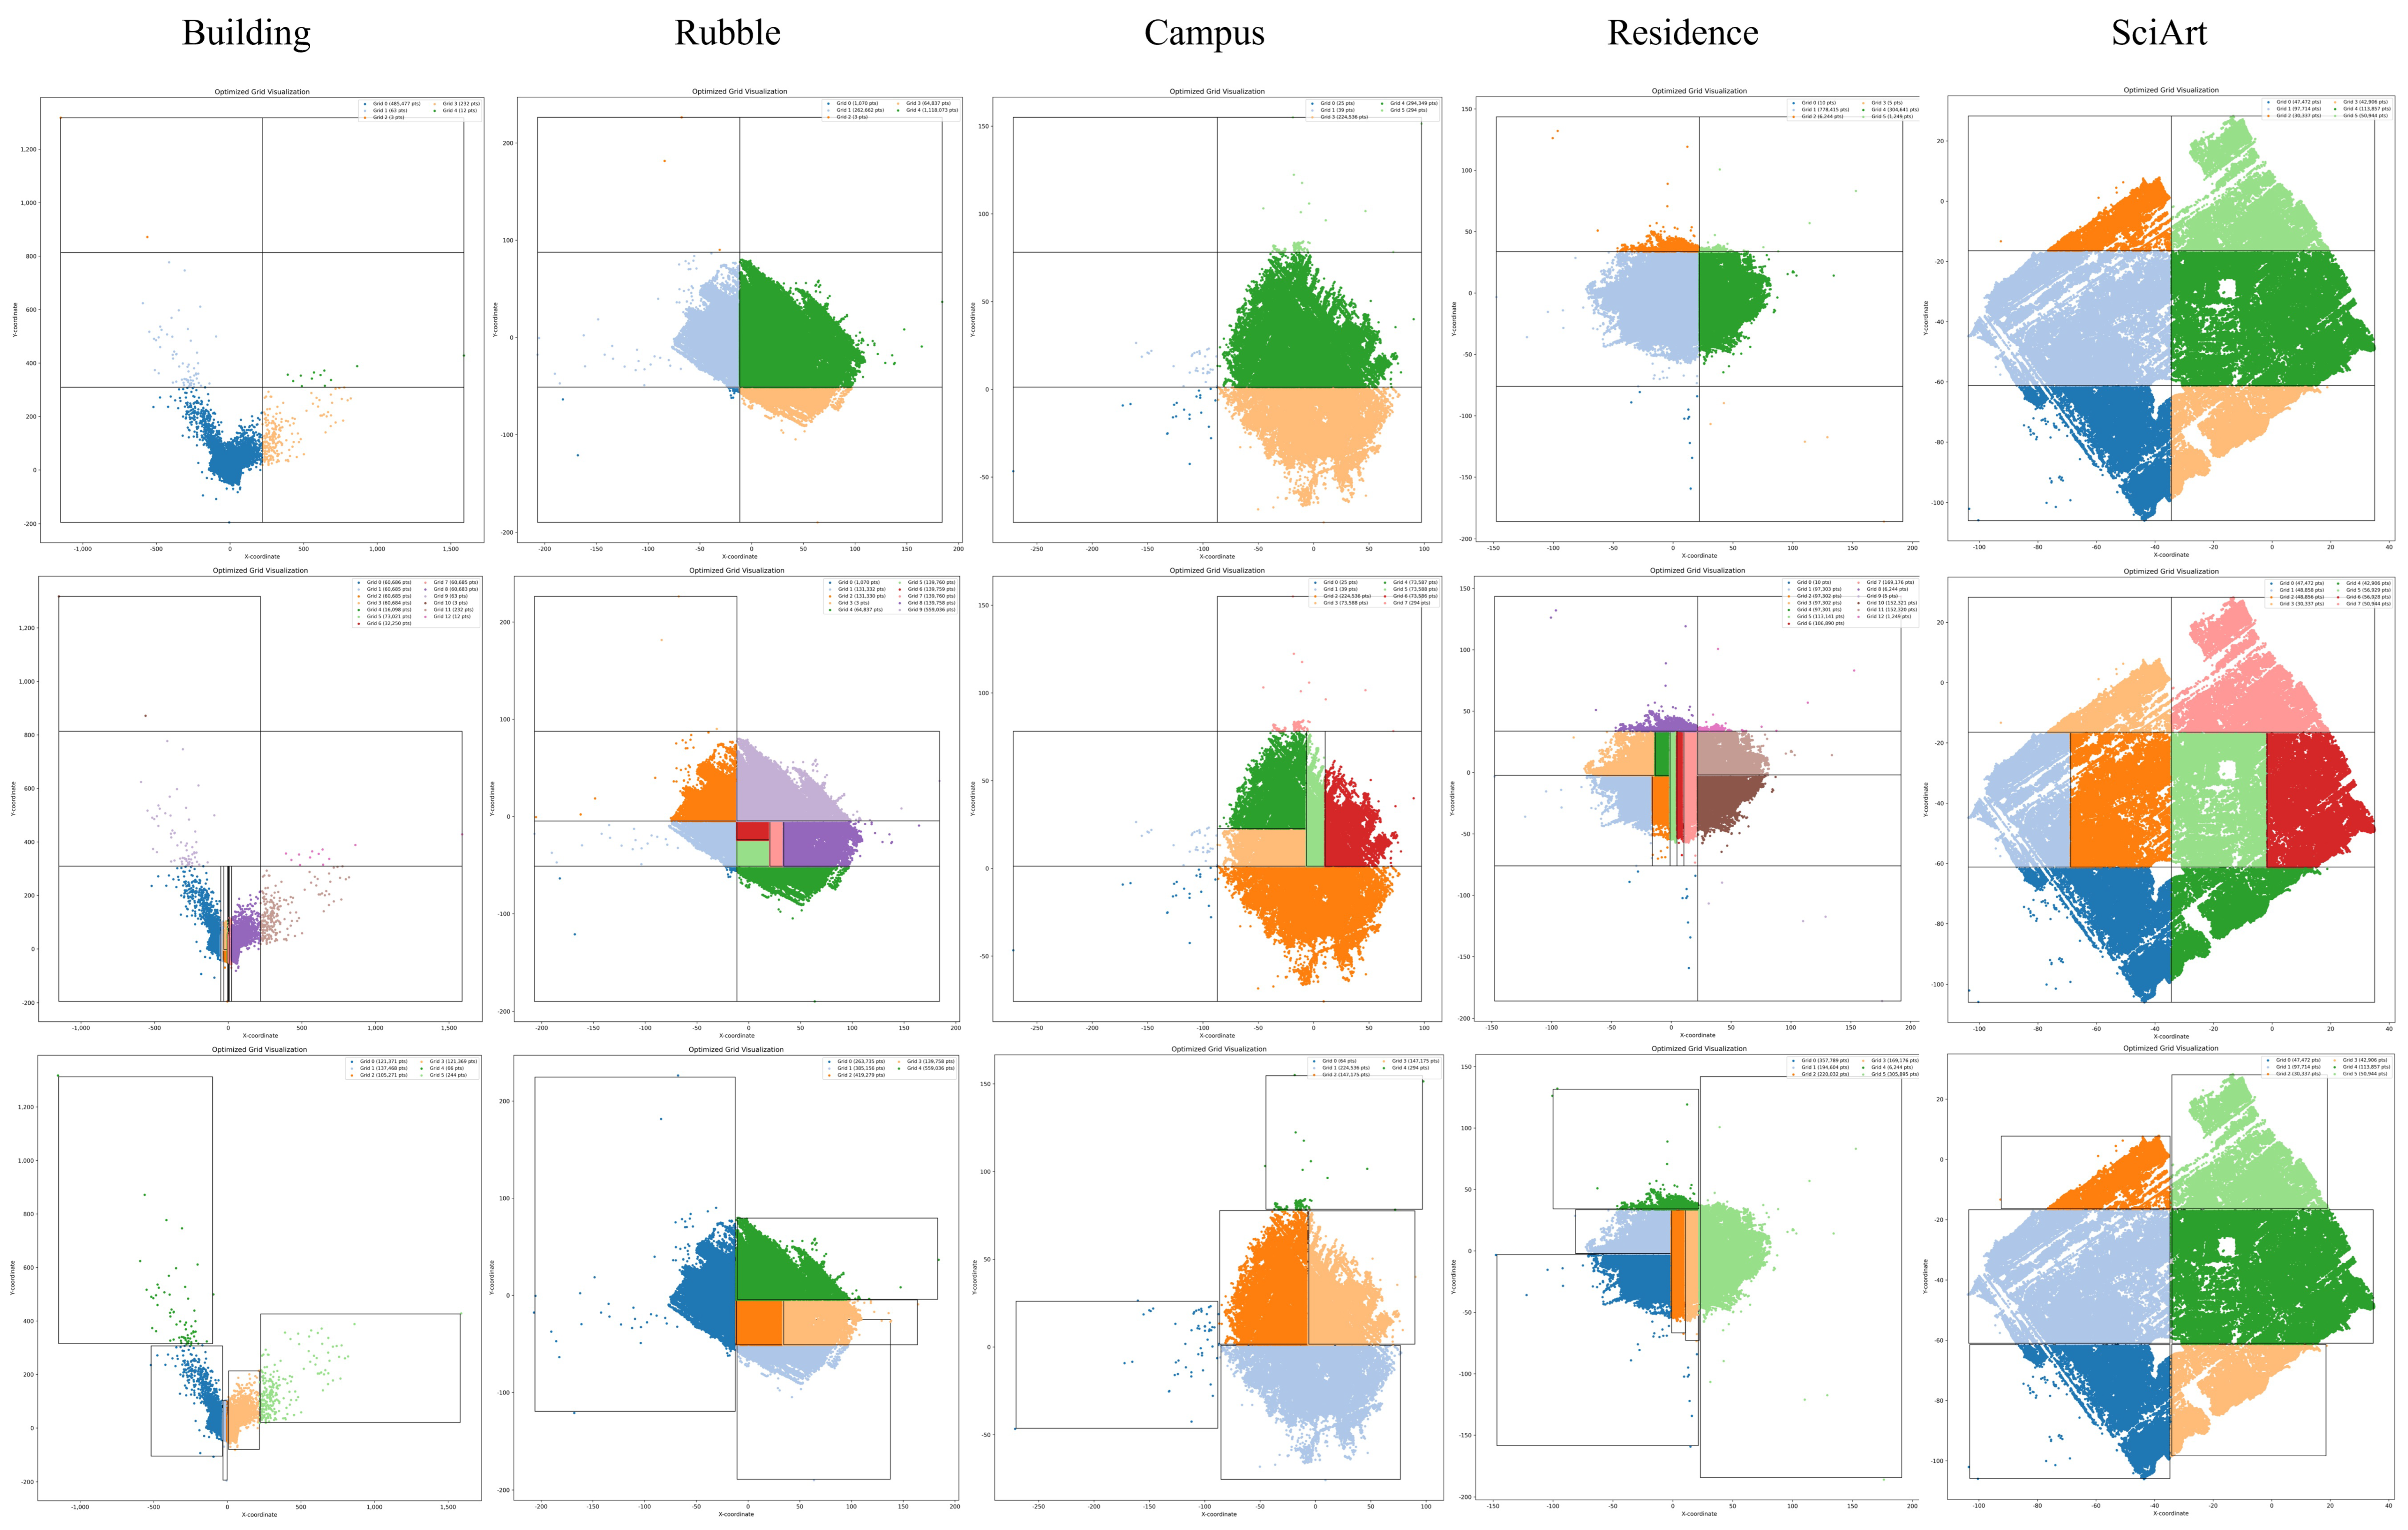
Table 1 and Figure 6 present the grid initialization results for five datasets, revealing significant uneven distributions. On SciArt, the point count difference is 3.08 times; on Building, it is 28.9 times; on Campus, 6.88 times; on Residence, 5.17 times; and on Rubble, 9.78 times. These large disparities lead to the poor performance of 3DGS-class methods in sparse areas. To address the distribution differences and fully utilize all valid data, iterative partitioning and block merging were performed on the grid, resulting in more uniform scene point-cloud segmentation.
Table 1.
Points in different original sub-grids.
Figure 6.
Point distribution of original grids.
4.3.2. Grid Partitioning
The aforementioned process generated several sub-grids of equal size; however, due to the highly uneven distribution of point clouds, the number of points contained in each sub-grid varies significantly. If the point cloud distribution were uniform, the ideal scenario would be that the number of points in each sub-grid would differ only slightly. Given a total of points and sub-grid blocks, each grid should contain approximately points. This segmentation method is proposed based on this concept, with specific implementation details as follows:
If the number of points in the current grid exceeds the specified threshold , the approach in this paper will partition the grid into two sub-grids, ensuring that the resulting sub-grids remain rectangular and have approximately equal numbers of points. It is known that a rectangle can be divided into two rectangles along the X-axis (major axis) or along the Y-axis (minor axis). Therefore, the first step is to choose the division direction and then choose the division position. Orthographically project the points in the grid onto the X-axis and Y-axis, and then calculate the variance of the points along the and directions. Select the direction with the larger variance for the division. If the X-axis is chosen as the division direction, the division position () should be the median value of the point projected onto the y-axis. Based on the division direction and position, divide the grid into a bottom sub-grid () and a top sub-grid (). Iteratively repeat this process for each grid and its sub-grids until the number of points in each grid meets the requirement or the maximum iteration is reached. Here, M is set to 10, which means each sub-grid will be split at most ten times.
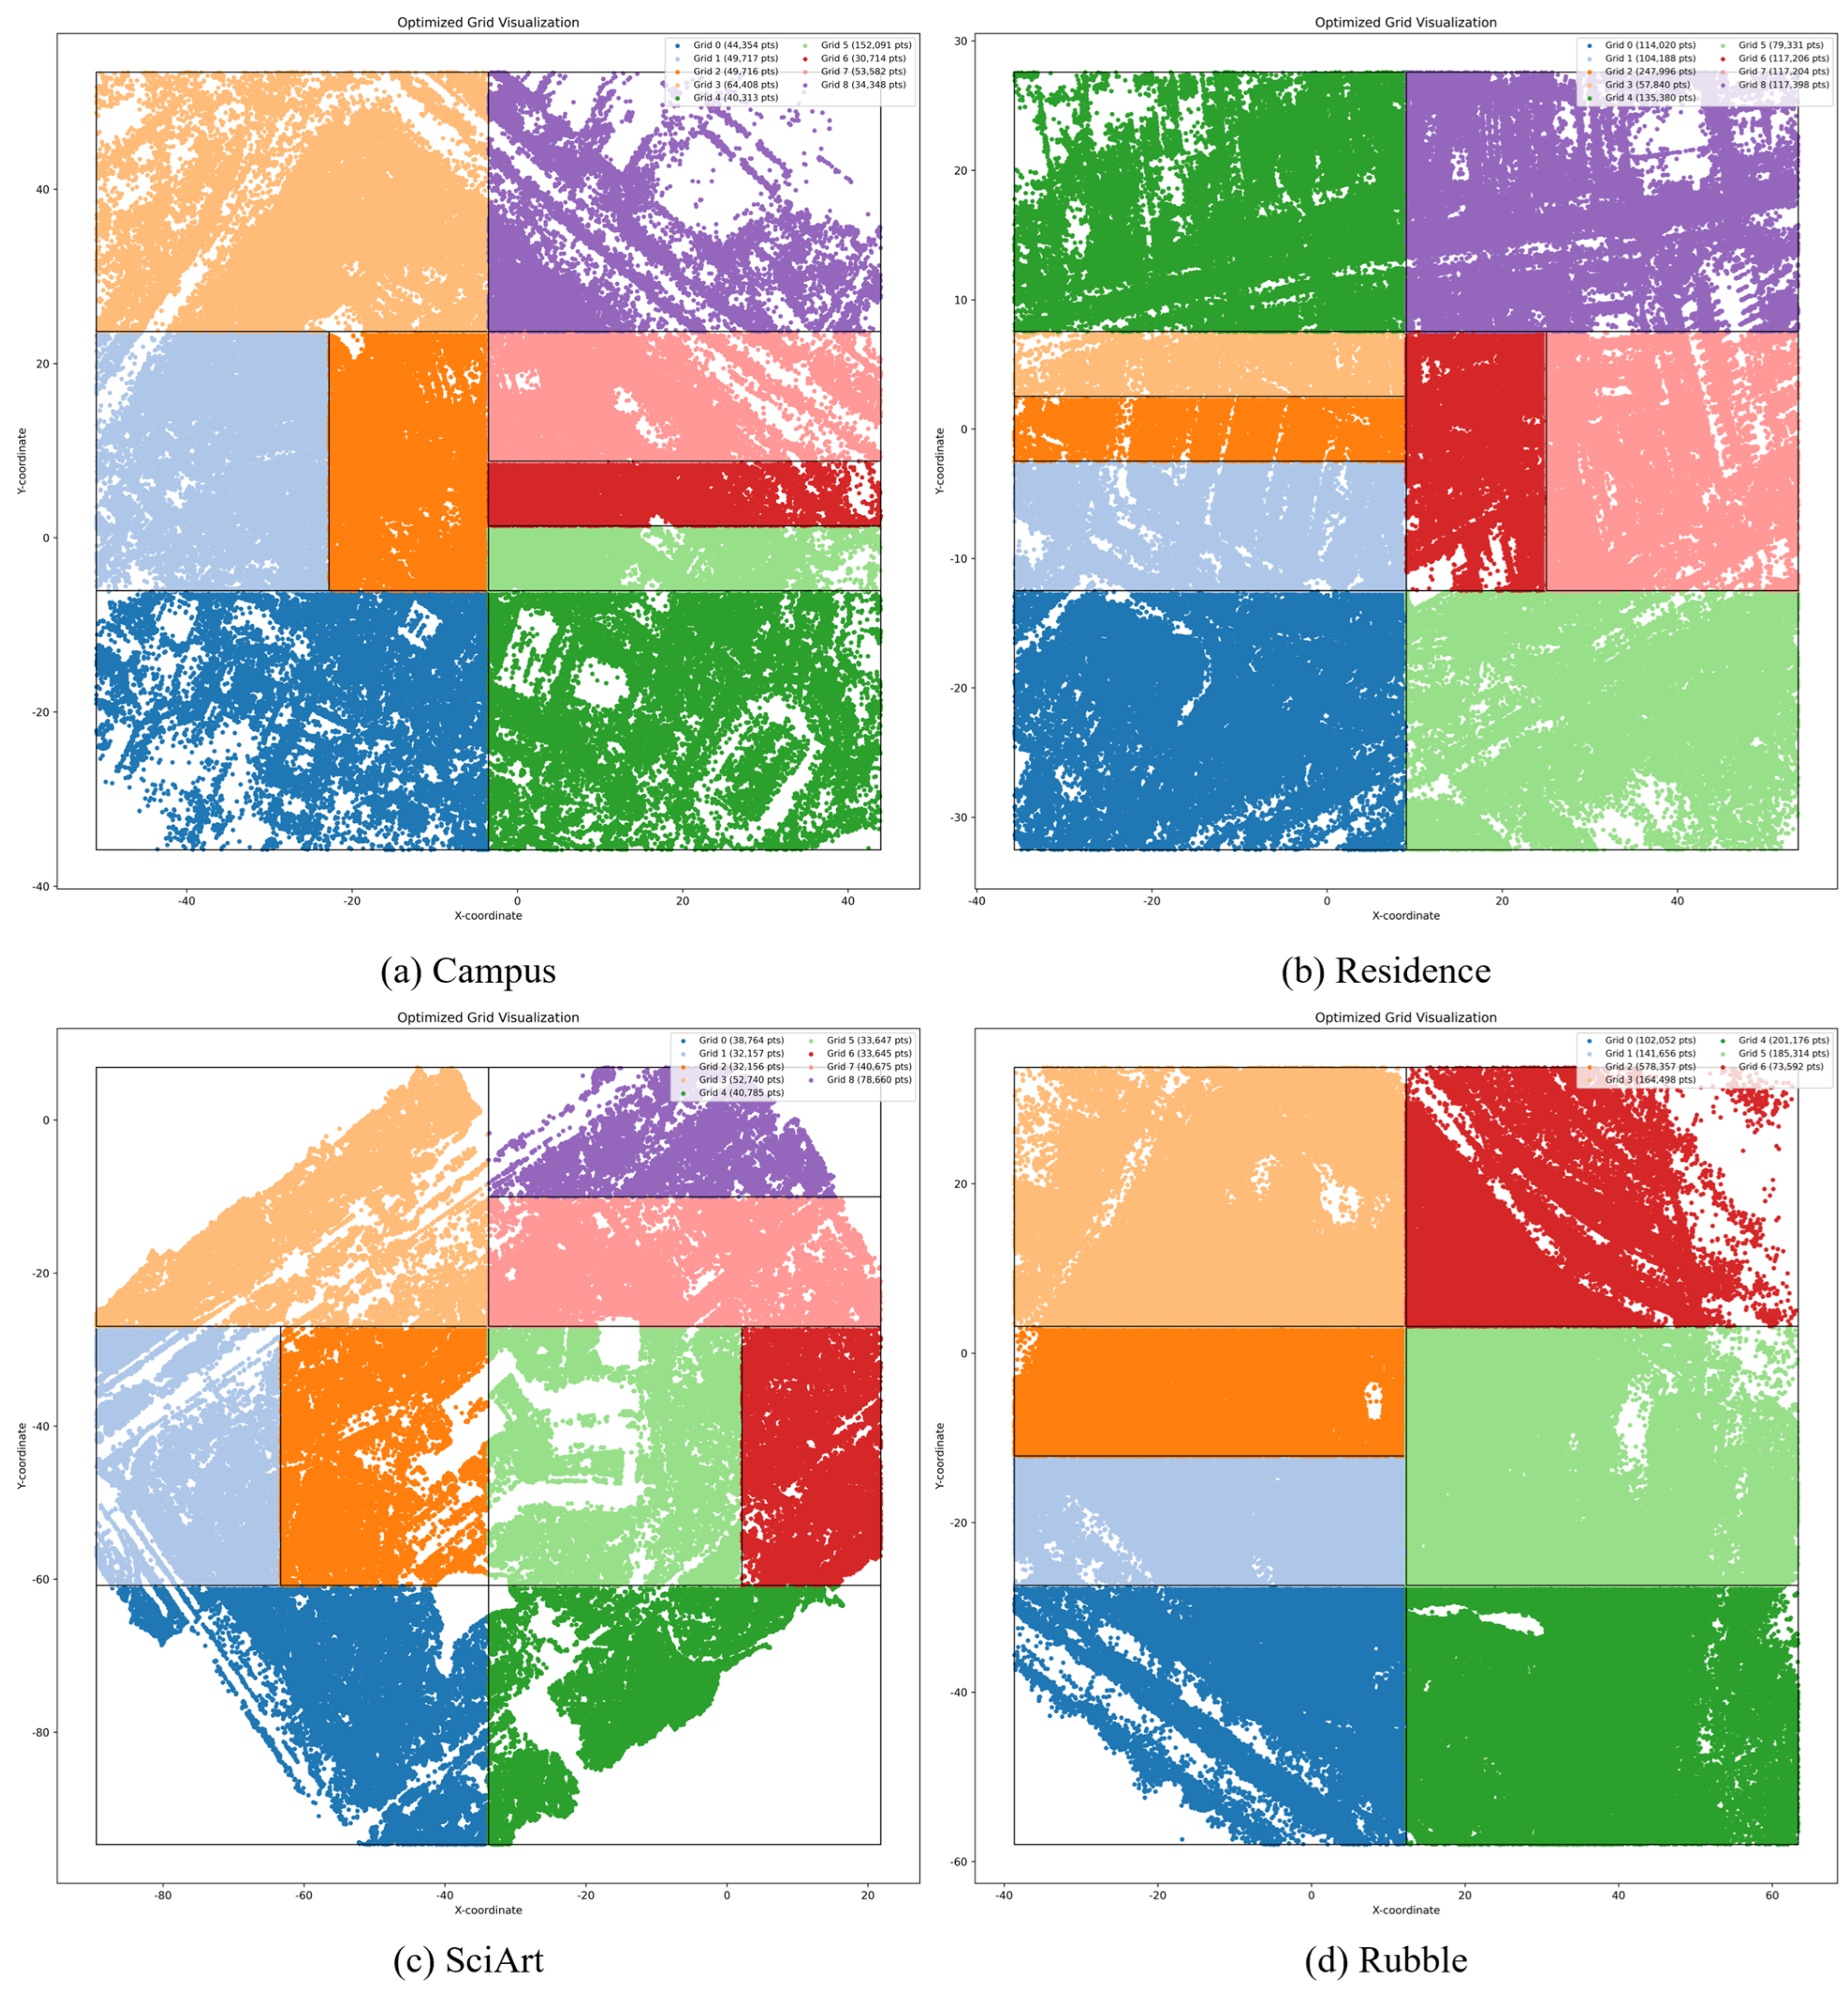
It is noteworthy that grid partitioning aims to alleviate the computational resource requirements for subsequent training processes while ensuring the final fused scene effect. To avoid point cloud distribution being too dense in certain areas, which may lead to significant differences in the area of two sub-grids, or even the occurrence of extremely small sub-grids, it is necessary to make judgments during the partitioning process to avoid such issues. This method determines that if the difference in the number of points included in the two sub-grids exceeds , the partitioning process will be halted, and the original grid will remain unchanged (where is set to 0.7). The results after partitioning are shown in Figure 7, and the number of points within each sub-block is relatively uniform, as shown in Table 2.
Figure 7.
Point distribution of the partitioned grids.
Table 2.
Points in different partitioned sub-grids.
4.3.3. Grid Merging
Although uniform point distribution grids were obtained through grid partitioning, each grid contains fewer points and has a smaller area, resulting in the selection of only a limited number of cameras in subsequent processes. This leads to an insufficient acquisition of camera-pose data, which significantly affects the modeling performance of 3DGS methods. Additionally, excessive partitioning increases training time substantially, indirectly raising the cost of scene modeling. Therefore, this method incorporates an additional grid merging module to consolidate overly fragmented partition grids, ultimately yielding uniformly distributed sub-grids with an appropriate number of segments.
If the number of points in a grid is less than , attempt to merge it with adjacent grids. Let the two grids to be merged be and , and the merged grid be , with the merged point set being . If , then perform the merge operation; otherwise, keep the original grid unchanged. Here, . After merging, each grid undergoes a certain degree of contraction to more tightly enclose its internal points, with a contraction rate of 99%, resulting in the final merged outcome as shown in Table 3.
Table 3.
Points in different merged sub-grids.
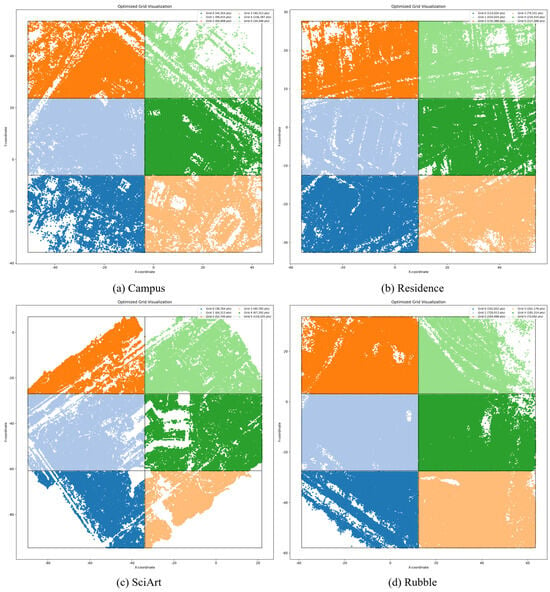
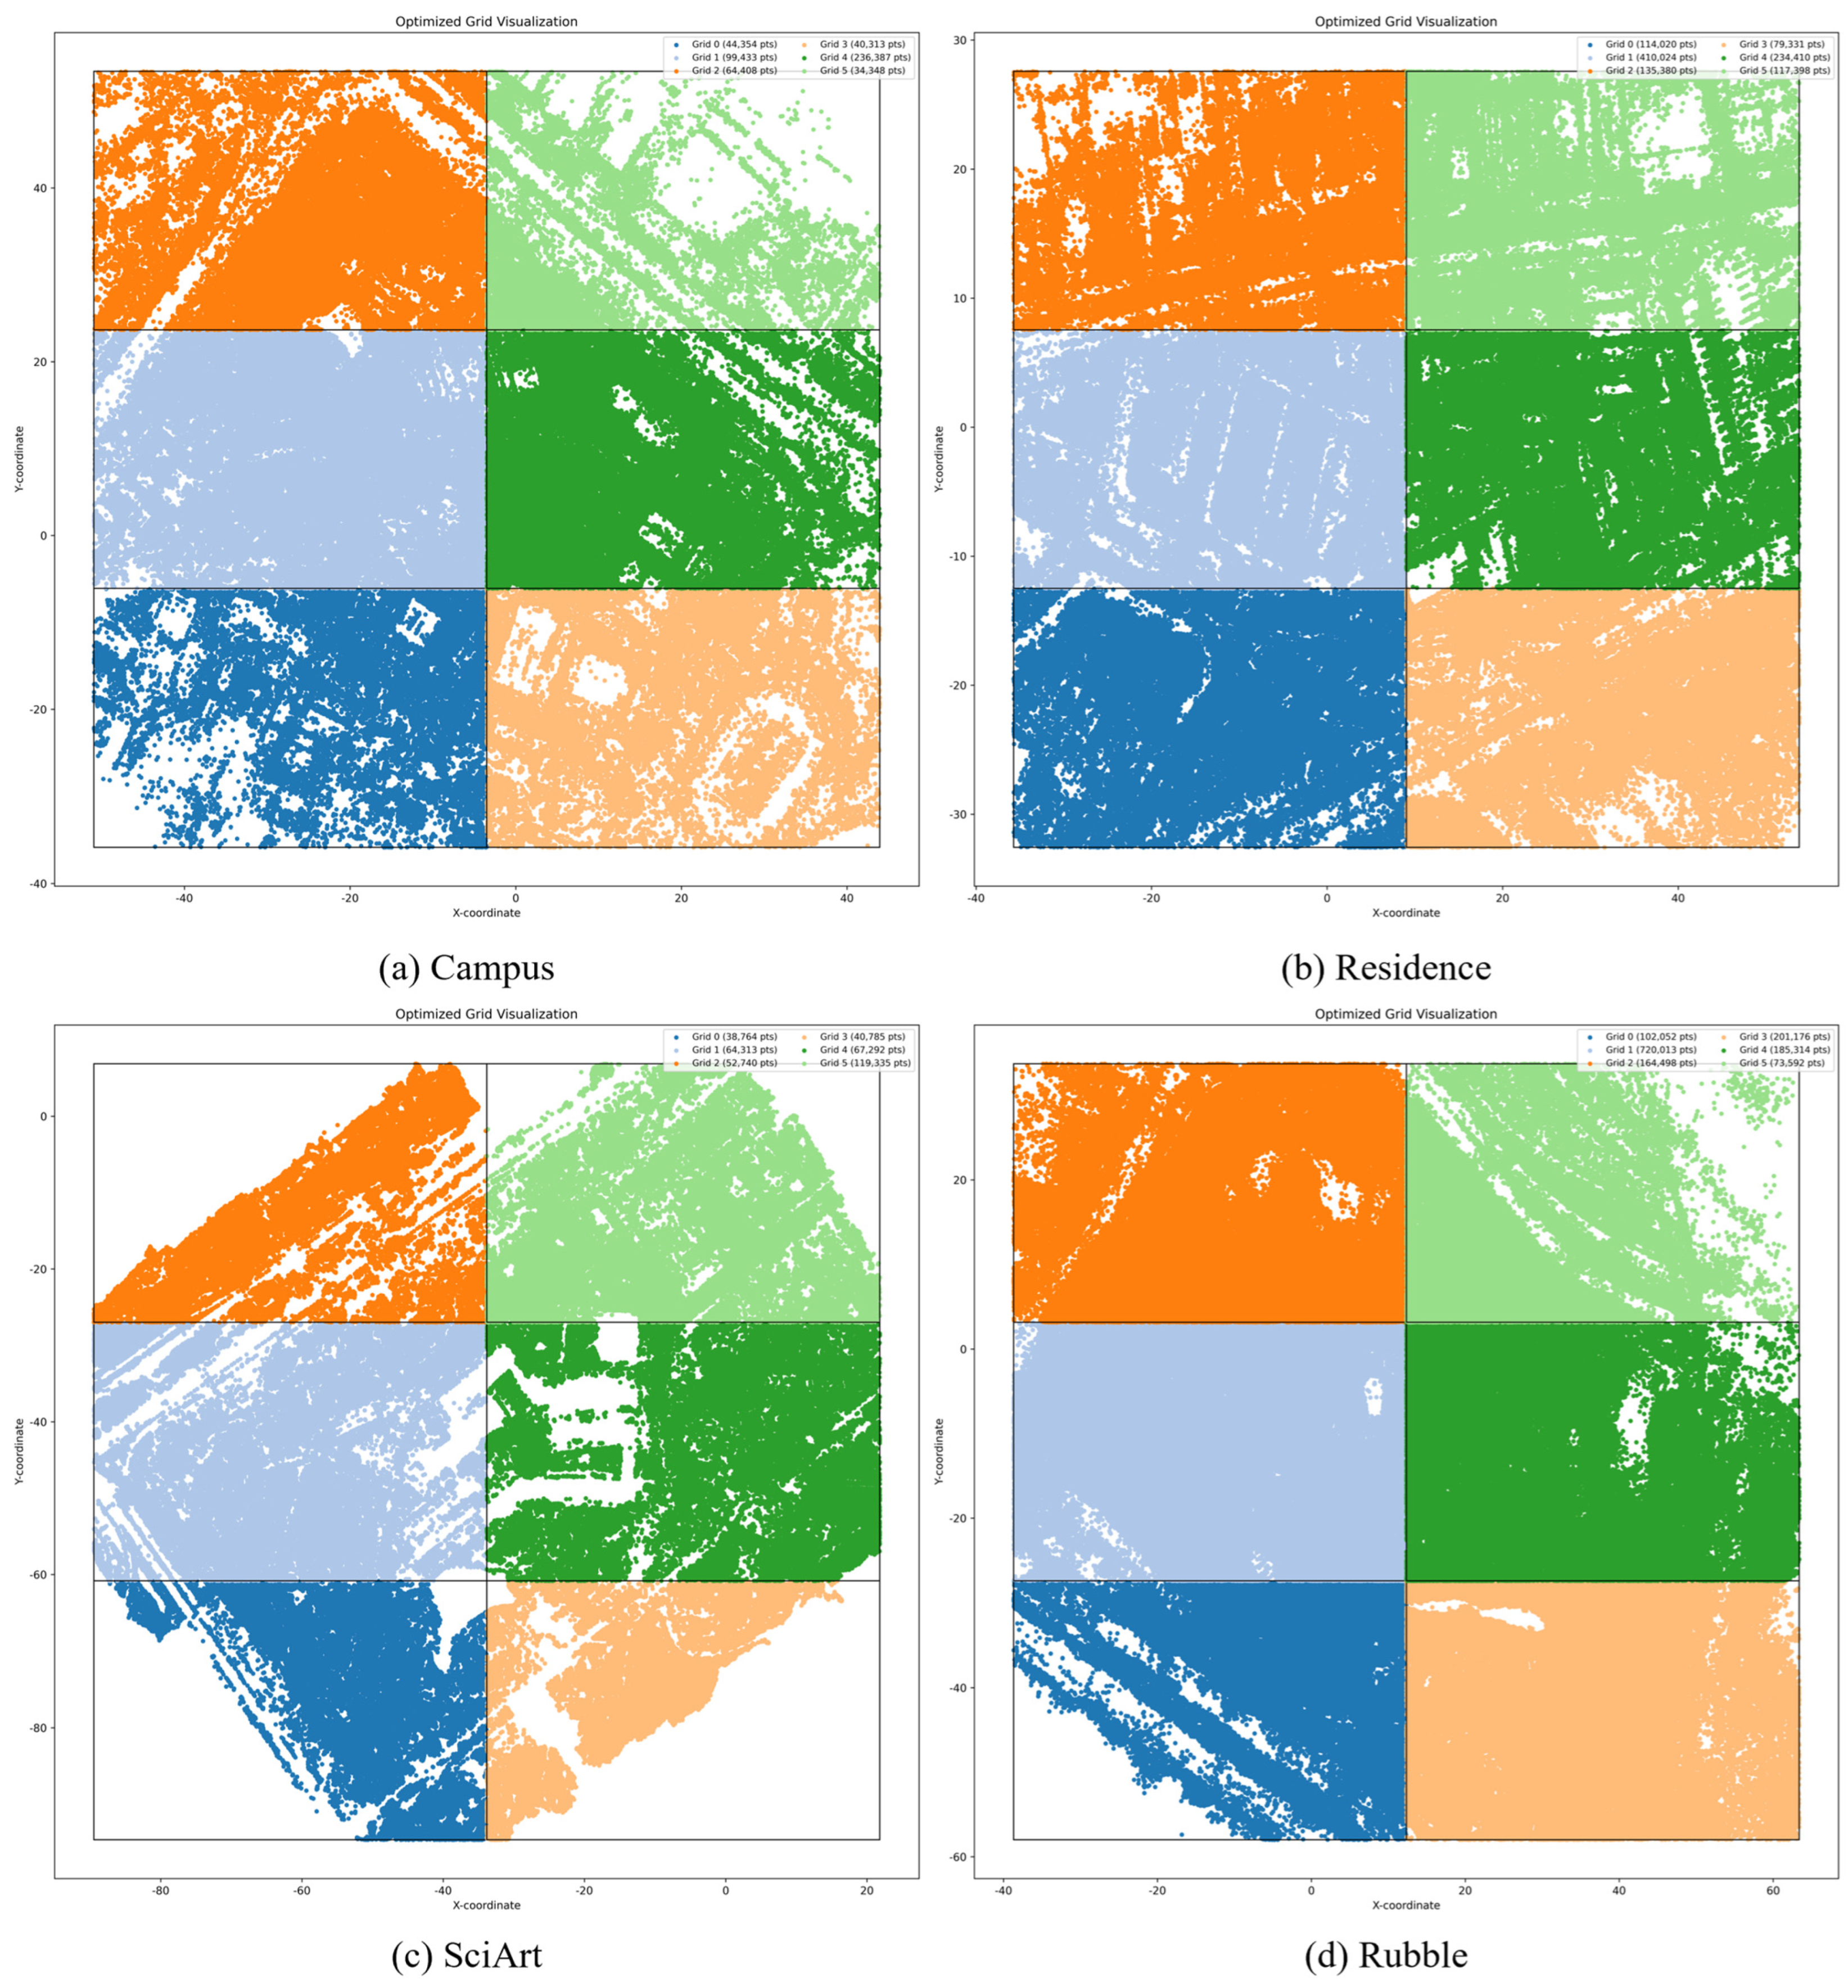
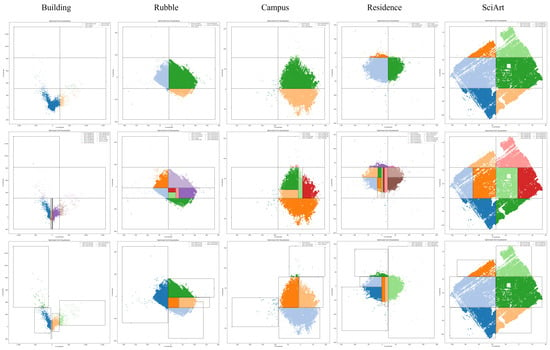
After undergoing the partitioning and merging steps, the distribution of sub-grid points for the five scenarios significantly improved. Even for the scenario with the largest difference, Campus, the ratio between the maximum and minimum values is only 3.77 times, and the standard deviation is within a reasonable range relative to the mean. The final result is shown in Figure 8.
Figure 8.
Point distribution of the merged grids.
4.3.4. Choose the Camera
After obtaining each segmented sub-grid and the number of points it contains, it is also necessary to match the corresponding camera pose for each sub-grid. The camera pose and 3D points already obtained a complete matching relationship in the previous Colmap process, so here we only need to divide them accordingly.
Traverse all cameras, filter out valid cameras based on the position of the 3D point and the position of the camera center, and then make a judgment. If the camera is within the double range of the sub-grid and has a matching relationship with the points in the grid, then the camera is chosen. Combined with the overlap ratio , the wider range of camera selection here can ensure that there is certain coverage between the sub-scene modeling to avoid a sense of separation between adjacent sub-scenes.
4.4. Evaluation Metrics
This paper uses PSNR (peak signal-to-noise ratio), LPIPS, (Learned Perceptual Image Patch Similarity) and SSIM (structural similarity index) to evaluate the reconstruction results and compare methods. PSNR is a measure of image generation quality. A higher PSNR value means the generated image is closer to the reference image. SSIM assesses the similarity between two images by comparing brightness, contrast, and structural information. A higher SSIM value indicates greater structural similarity. LPIPS is a deep learning-based method. It uses pre-trained deep neural networks to extract high-level features from images and evaluates similarity by comparing these features. A larger LPIPS value means greater perceptual differences between images, which implies poorer quality of the generated image. The calculation of PSNR, SSIM, and LPIPS indicators is as follows:
where is the mean square error and is the maximum possible pixel value of the image. is the mean value of the image; is the covariance of the image; and and C2 are constants to avoid calculation errors caused by division by zero.
5. Experiments and Results
5.1. Data
5.1.1. Mill19
The Mill 19 dataset, created by Carnegie Mellon University, is a large-scale scene dataset designed to boost NeRF and 3DGS development in computer vision. The Rubble and Building data from this dataset are chosen for the experiments. The Building scene consists of 1920 images, and the Rubble scene has 1657 images, both with a resolution of 4608 × 3456.
5.1.2. Urban Scene 3D
The UrbanScene3D dataset, developed by Shenzhen University’s Visual Computing Research Centre, promotes urban-scene awareness and reconstruction research. It contains over 128,000 images with a resolution of 5472 × 3648, covering 16 scenes, including real urban areas and 136 km2 of synthetic urban zones. The Campus (2129 images), Residence (2582 images), and SciArt (3620 images) scenes are used in the experiments.
5.1.3. Self-Collected
The NJU and CMCC-NanjingIDC datasets are acquired via DJI Mavic 2 Pro with a resolution of 5280 × 3956. The NJU dataset contains images of Nanjing University’s Xianlin Campus, and the CMCC-NanjingIDC dataset includes images of China Mobile Yangtze River Delta (Nanjing) data center. In this experiment, 304 and 2520 images are used for the scene reconstruction of these two datasets, respectively, to conduct ablation studies. The comparison between the datasets can be seen in Table 4. Original Images represents the original number of images, and Colmap Images represents the number of images actually involved in the acquisition of sparse point clouds by Colmap.
Table 4.
Basic attributes of datasets.
5.2. Preprocessing
To make fair comparisons between the methods, data are preprocessed in the same way in this paper. The images are downsampled to a quarter of their original resolution. During resampling, this paper uses a DOG method with a 3 × 3 convolution kernel and Lanczos interpolation to preserve image details.
5.3. Training Details
To demonstrate the effectiveness of the proposed method, comparative experiments are conducted against NeRF-like and 3DGS-like approaches. For NeRF-like methods, Nerfacto-big and Instant-NGP are reproduced using nerfstudio, which is an open-source modular NeRF development framework. The two models maintain their original model parameters and the training iterations are each set to 100,000. For 3DGS-like methods, the original 3DGS, Octree-GS, and Hierarchy-GS datasets are implemented based on their official open code. The training iterations of 3DGS and Hierarchy-GS are set to 30,000 and Octree-GS to 40,000. The more training iterations, the better the effect of the final result in theory. Additionally, Hierarchy-GS uses a fixed chunk size to segment the full scene into fixed-size sub-scenes. In this paper, it is uniformly set to 50.
For dataset preparation, training and test sets are selected by sampling one out of every ten images from those used in Colmap. Specifically, 90% of the images are used for training, and 10% are reserved for testing. All models are trained on the same dataset processed by Colmap to ensure a fair comparison.
The computational setup consists of a single standard 4090 GPU with 2G memory.
5.4. Comparison with SOTA Implicit Methods
To demonstrate the method’s feasibility, two types of comparisons are made. One compares the reconstruction of individual blocks with 3DGS, Octree-GS, and Hierarchy-GS, demonstrating the method’s competitiveness in individual block reconstruction. The other compares the modeling of complete scenes with Nerfacto-big, Instant-NGP, and Hierarchy-GS, highlighting the advantage of better visualization in full-scene reconstruction. Note that VastGaussian and DoGaussian are not compared due to the lack of official code, and Mega-NeRF is excluded for its excessive camera-pose requirements.
5.4.1. Single Block
Table 5 presents the single-block results on the Mill 19 and Urban Scene datasets. Notably, 3DGS and Octree-GS use blocks from this paper’s partitioning method, whereas Hierarchy-GS uses its own, with the most similar selected for comparison. Our method performs well across all five datasets. It achieves the best PSNR, LPIPS, and SSIM results on Building and SciArt, with minimal gaps in some cases. On Rubble, Campus, and Residence, though slightly underperforming compared to the original 3DGS method, it surpasses other large-scene modeling methods. Due to VRAM overflow, 3DGS reconstruction of the SciArt block scene stops at 8900 iterations, so the table shows results at 7000 iterations.
Table 5.
Metric results of single block.
As shown in Table 6, this method achieves good single-block modeling and requires less in terms of machine performance. Moreover, 3DGS and Octree-GS can consume up to nearly 24 GB of VRAM for individual scenes, the limit for a standard 4090 GPU. In contrast, both Hierarchy-GS and our method significantly reduce VRAM usage, with ours being slightly lower than Hierarchy-GS.
Table 6.
Max memory usage of single block.
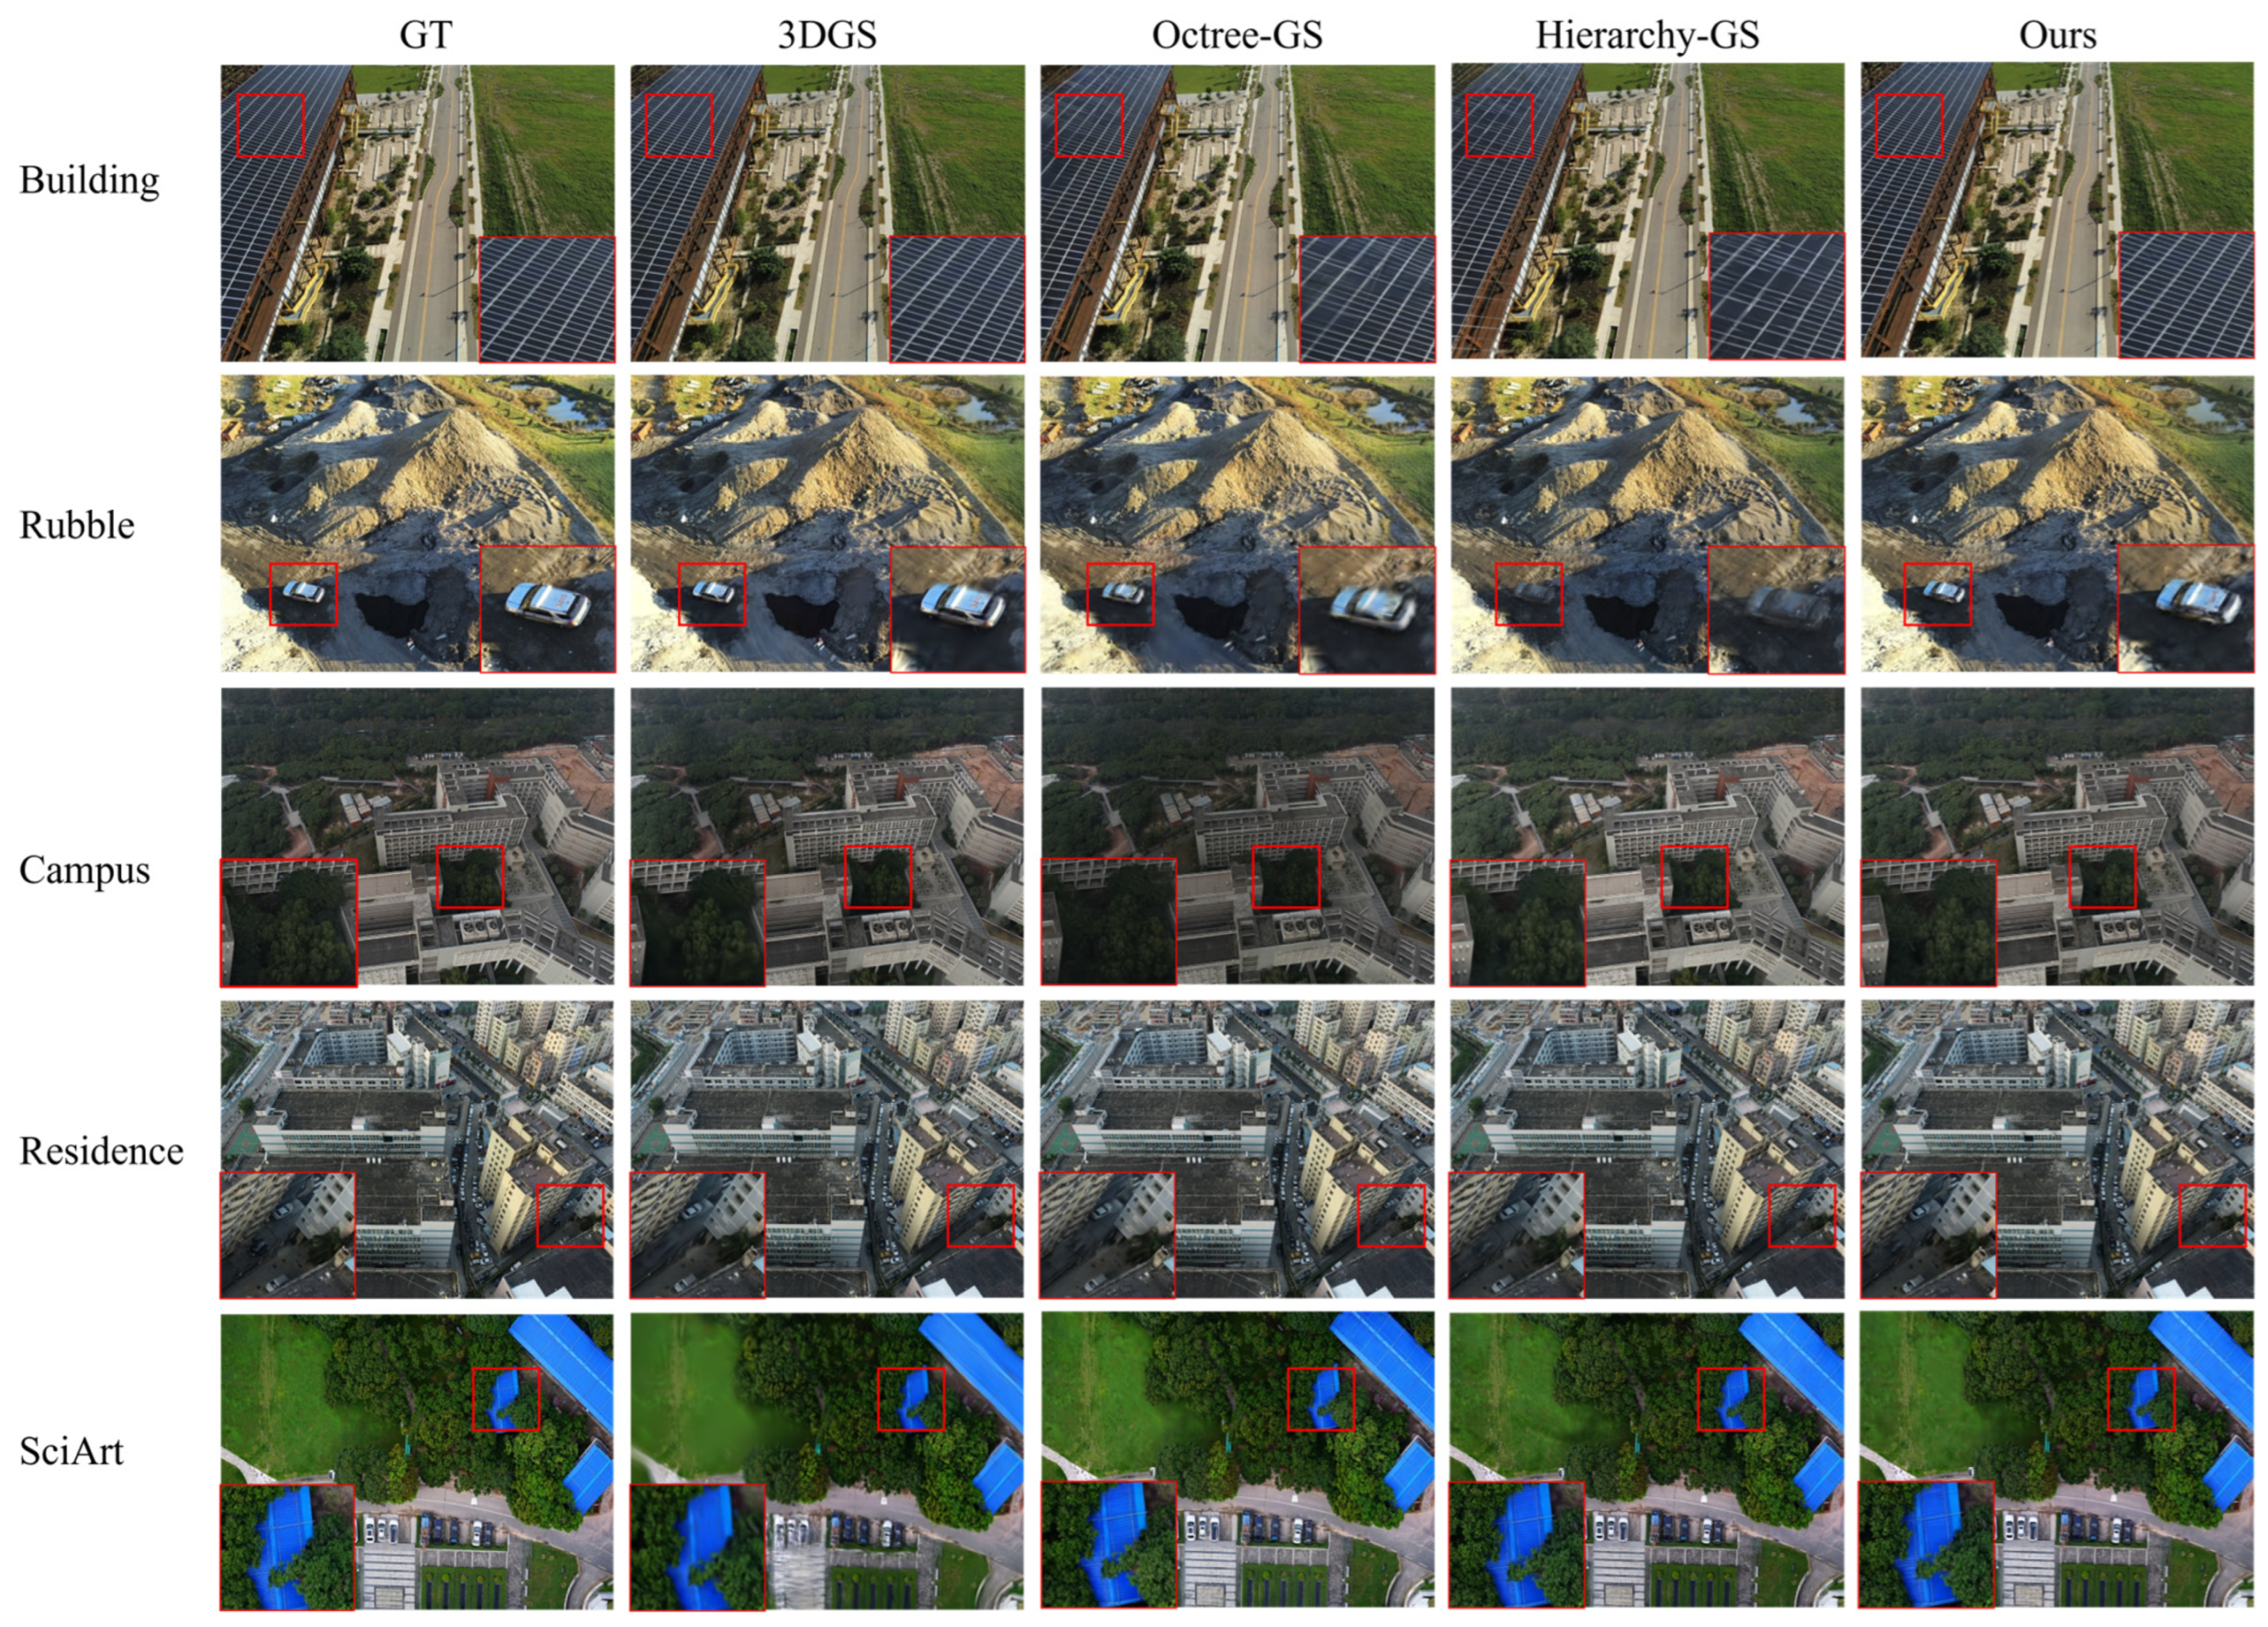
Figure 9 visually compares the results. In Building, 3DGS and our method better restore texture details. In Rubble, Hierarchy-GS fails to model shaded vehicles. In Campus, Octree-GS darkens shaded trees and loses details. In Residence, the results are mostly consistent, with minor differences on the road. In SciArt, Hierarchy-GS produces a more refined result.
Figure 9.
Results comparison of single block.
5.4.2. Full Scene
Table 7 compares the full-scene performance of our method, Nerfacto-big, Instant-NGP, and Hierarchy-GS. Our method generally achieves higher PSNR and SSIM scores and lower LPIPS scores, except possibly in the SciArt scene. The method achieves an average 2.45%, 6.41%, and 3.77% improvement in PSNR, SSIM, and LPIPS. During the experiments, Nerfacto-big uses 15–23 GB of VRAM, Instant-NGP uses 14–18 GB, and both Hierarchy-GS and our method use 10–14 GB.
Table 7.
Metric results of full scene.
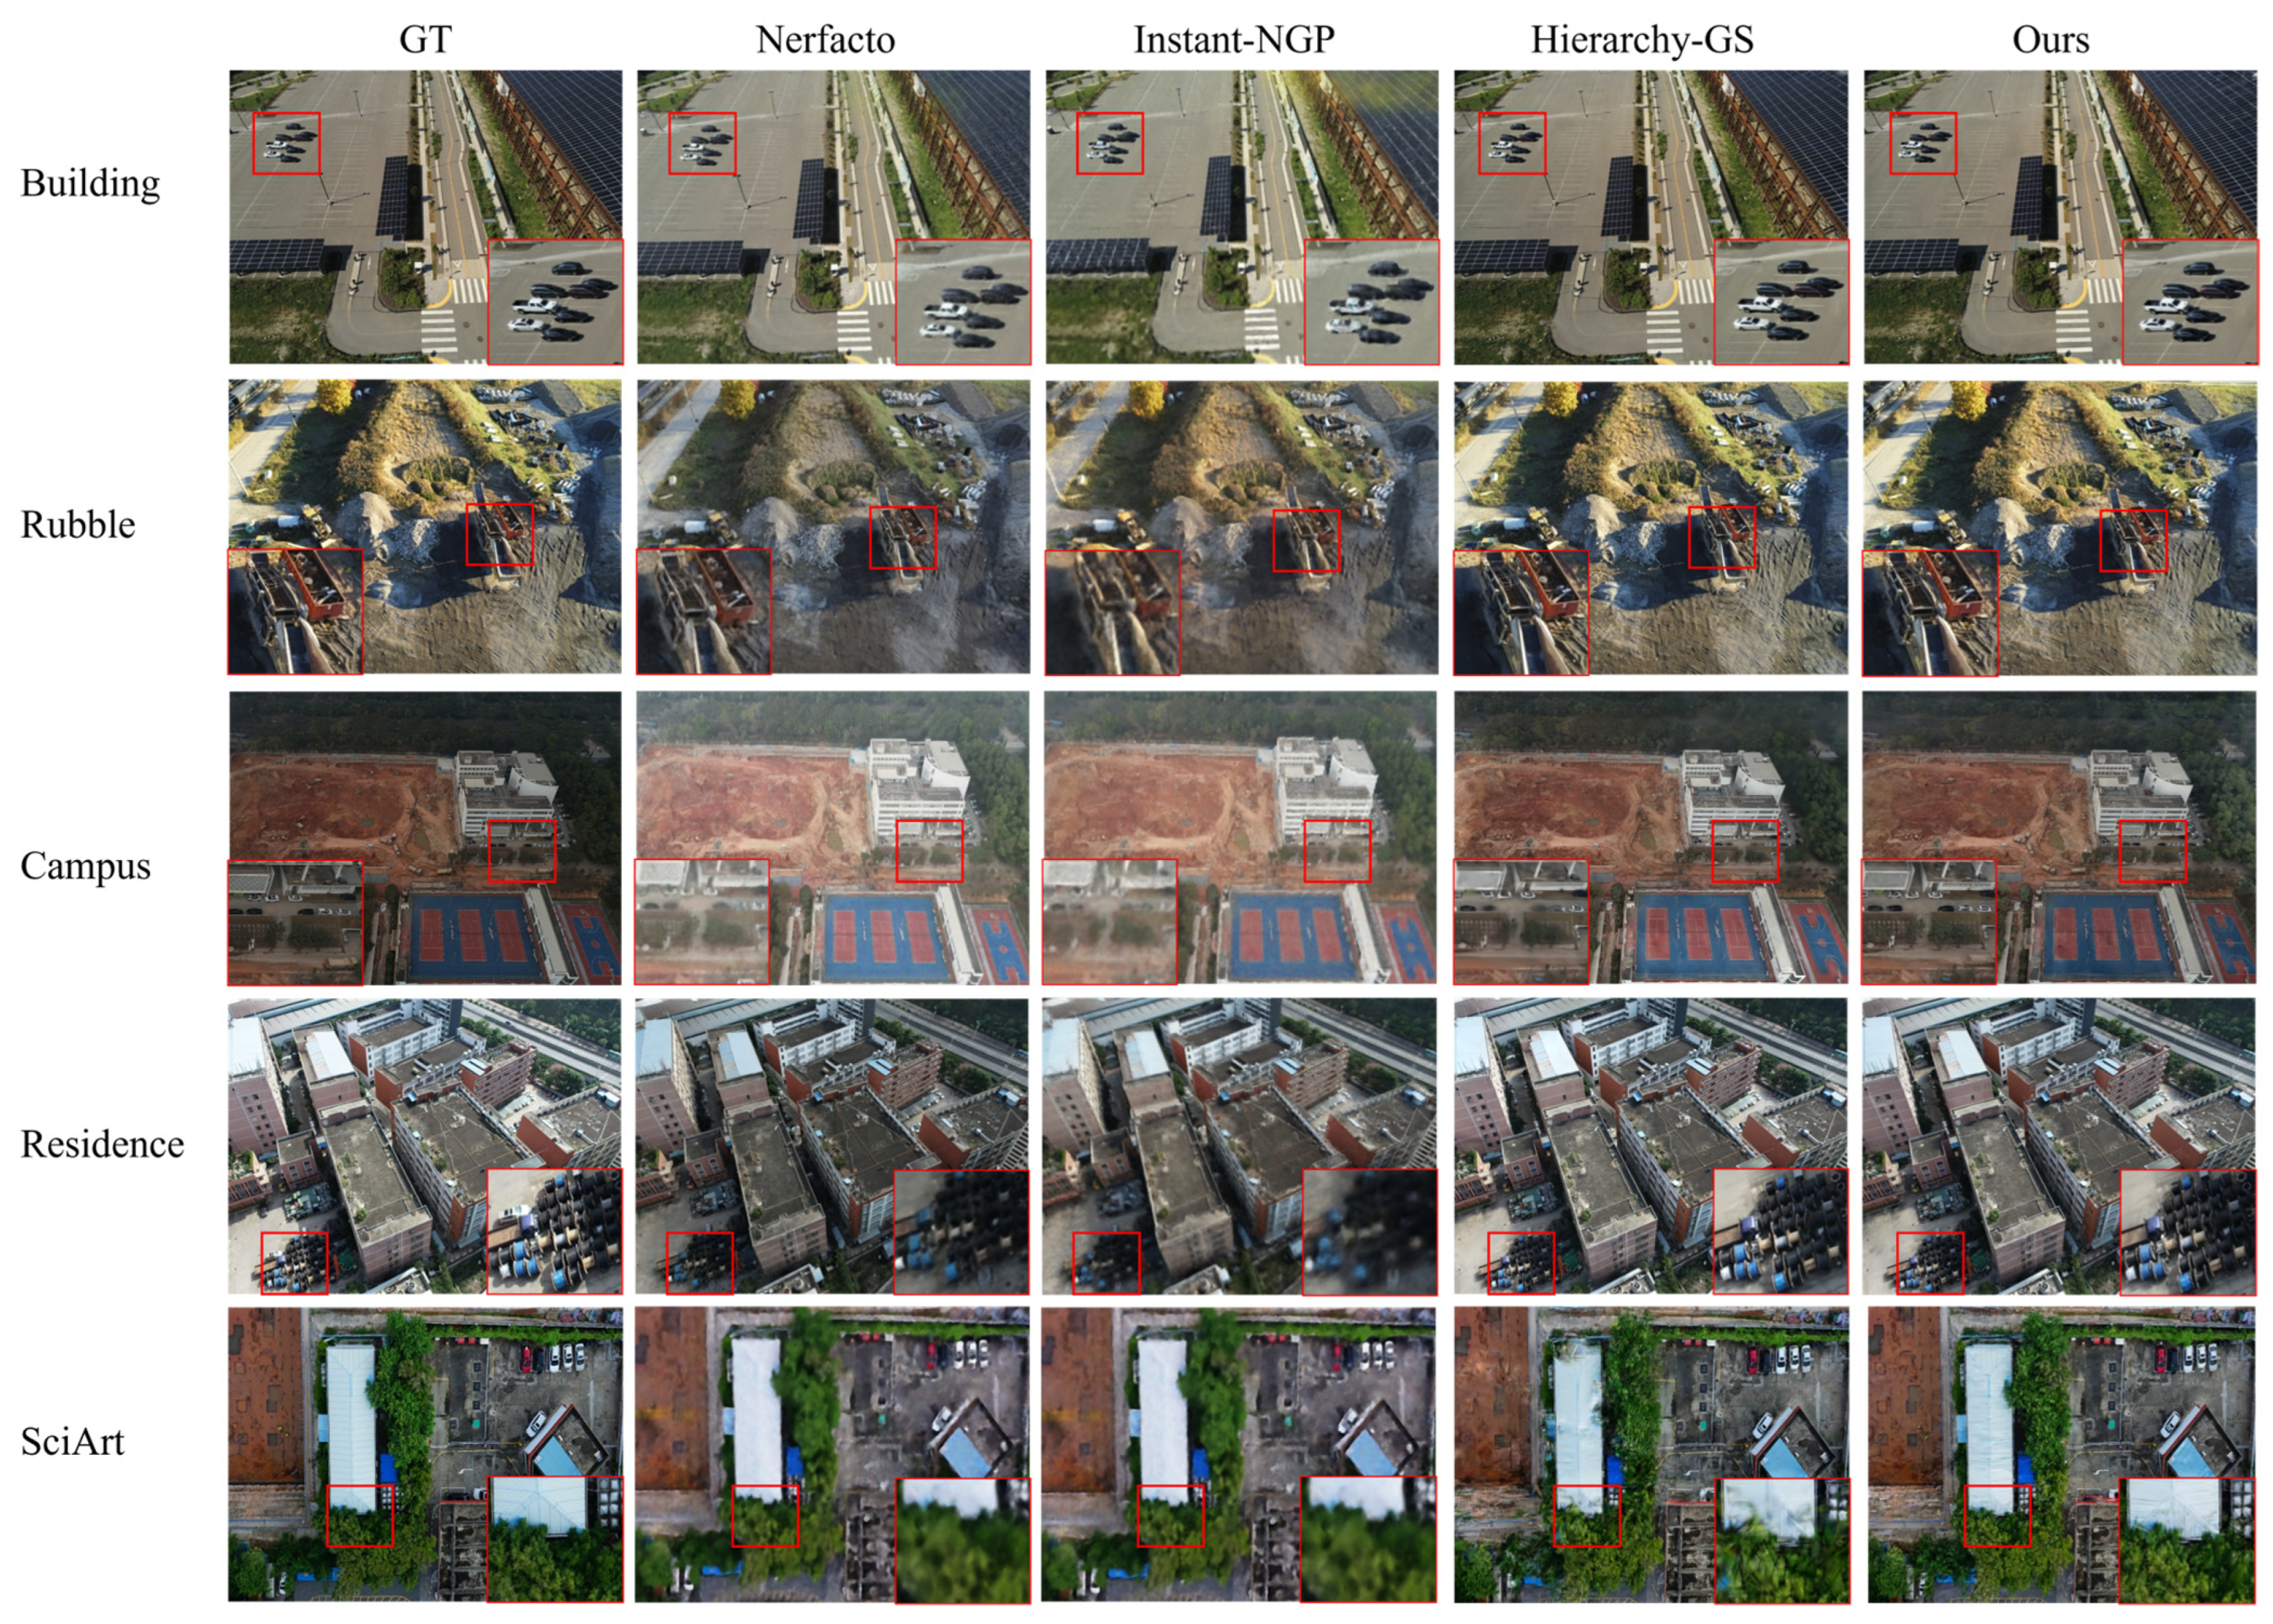
As shown in Figure 10, Nerfacto and Instant-NGP have less ideal reconstruction effects. Hierarchy-GS also underperforms in some details. In the Campus scene, it produces artifacts in the vehicles and trees marked by the red box. In the Residence scene, it lacks details in the roller. In the SciArt scene, it loses the stripes on the blue roof and the surrounding green vegetation.
Figure 10.
Results comparison of full scene.
6. Discussion
6.1. Importance of Filtering
The initial distribution of the input point cloud impacts the modeling results and our proposed region-segmentation method. As our approach is point-distribution-based, noise points can greatly affect the segmentation. Figure 11 shows the segmentation results without filtering. Stray points cause grid-range misjudgment in grid initialization, leading to extremely uneven segmentation. This affects the iterative partitioning and final grid merging, easily creating large-area blocks with few points and small-area blocks with many points. Such unreasonable partitioning is detrimental to subsequent scene modeling. The impact on Building, Rubble, Campus, and Residence is significant, while SciArt is less affected. This is because SciArt has fewer stray points, which are also close to the main body.
Figure 11.
Point distribution of grids without filter.
6.2. Ablation Analysis
To demonstrate the effectiveness of the proposed point cloud filter and scene segmentation, ablation experiments were conducted on the self-collected NJU and CMCC-NanjingIDC datasets, as well as the public Rubble dataset. As shown in Table 8, on the NJU dataset, the complete scene achieves slightly higher PSNR and SSIM values than removing only the segmentation or filtering module, with a similar LPIPS. On the CMCC-NanjingIDC and Rubble datasets, all three indicators show more significant improvements, especially on the Rubble dataset. Here, PSNR increases by 0.55 (2.05%) and 1.04 (3.95%) compared to removing partitioning or filtering; LPIPS decreases by 0.026 (10.5%) and 0.033 (12.9%); and SSIM rises by 0.015 (1.81%) and 0.021 (2.55%). Notably, removing only the filtering module generally has a larger impact across all datasets. Without filtering, redundant points affect both scene reconstruction and segmentation, causing double the negative effects on the final results.
Table 8.
Ablation analysis results.
6.3. Shortcomings
Although this method has realized large-scale scene reconstruction and has certain advantages over other methods in both individual blocks and complete scenes, it still has its own drawbacks. Both Instant-NGP and Nerfacto take about 40 min to complete full-scene training; 3DGS and Octree-GS take about half an hour to complete single-scene training. To cut down GPU usage, this method trades time for space. Each scene block takes nearly an hour to train, which is the same as Hierarchy-GS. Thus, the reconstruction time for a complete scene is directly proportional to the number of blocks, negatively affecting overall efficiency.
7. Conclusions
Low-altitude remote sensing images are one crucial data source for large-scale urban 3D reconstruction. This study introduces a novel approach to large-scale 3D scene reconstruction leveraging 3DGS. Initially, the sparse point cloud derived from indirect input data undergoes filtering to enhance data robustness, thereby improving the final reconstruction quality. The filtered point cloud also provides a more reliable foundation for scene segmentation, minimizing erroneous segmentations. During scene segmentation, the 3D distribution characteristics of the point cloud are fully exploited to develop a grid-based three-step strategy, ensuring high generalizability and rationality. To validate the effectiveness of the proposed method, experiments are conducted on five public datasets and two self-collected datasets. The results demonstrate that the method yields satisfactory outcomes. This method successfully achieves large-scale scene reconstruction with good visualization effects on low computing resources. However, due to the creation of the hierarchical tree, many intermediate node Gaussians are formed, resulting in the final result occupying about 1.5–1.8 times the disk space of the original 3DGS approach. In addition, the training time for each sub-scene is also relatively long—about 1 h—while the original 3DGS approach only takes half an hour. Improving these features could be undertaken in future works.
Author Contributions
Conceptualization, Y.G.; methodology, Y.G.; software, Y.G.; validation, Y.G., and Z.W.; formal analysis, Y.G.; investigation, Z.W.; resources, Y.G.; data curation, S.W.; writing—original draft preparation, Y.G.; writing—review and editing, Y.G., S.Z., J.H. and W.W.; visualization, Y.G.; supervision, Y.G., W.Z., S.W., Y.L. and Y.Z.; project administration, J.S. and Z.W.; funding acquisition, J.S. and Z.W. All authors have read and agreed to the published version of the manuscript.
Funding
This work was funded by the National Natural Science Foundation of China under Grant number 42471458, and also by Nanjing University-China Mobile Communications Group Co., Ltd. Joint Institute.
Data Availability Statement
The data used to support the results of this study are available from the respective authors upon request.
Acknowledgments
The authors acknowledge the GraphDeco-INRIA team for their inspiring work, which provided a valuable foundation for our research.
Conflicts of Interest
Authors Yan lv and Wei Zhou ere employed by the company Industrial Internet R&D Department at China Mobile Zijin (Jiangsu) Innovation Research Institute Co., Ltd. The remaining authors declare that the research was conducted in the absence of any commercial or financial relationships that could be construed as a potential conflict of interest.
References
- Zhu, H.; Zhang, Z.; Zhao, J.; Duan, H.; Ding, Y.; Xiao, X.; Yuan, J. Scene Reconstruction Techniques for Autonomous Driving: A Review of 3D Gaussian Splatting. Artif. Intell. Rev. 2024, 58, 30. [Google Scholar] [CrossRef] [Scilit]
- Cui, B.; Tao, W.; Zhao, H. High-Precision 3D Reconstruction for Small-to-Medium-Sized Objects Utilizing Line-Structured Light Scanning: A Review. Remote Sens. 2021, 13, 4457. [Google Scholar] [CrossRef] [Scilit]
- Chen, W.; Xu, H.; Zhou, Z.; Liu, Y.; Sun, B.; Kang, W.; Xie, X. CostFormer: Cost Transformer for Cost Aggregation in Multi-View Stereo. arXiv 2023, arXiv:2305.10320. [Google Scholar]
- Ding, Y.; Yuan, W.; Zhu, Q.; Zhang, H.; Liu, X.; Wang, Y.; Liu, X. TransMVSNet: Global Context-Aware Multi-View Stereo Network with Transformers. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 8575–8584. [Google Scholar]
- Kato, H.; Ushiku, Y.; Harada, T. Neural 3D Mesh Renderer. In Proceedings of the 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–23 June 2018; pp. 3907–3916. [Google Scholar]
- Berger, M.; Tagliasacchi, A.; Seversky, L.M.; Alliez, P.; Guennebaud, G.; Levine, J.A.; Sharf, A.; Silva, C.T. A Survey of Surface Reconstruction from Point Clouds. Comput. Graph. Forum 2017, 36, 301–329. [Google Scholar] [CrossRef] [Scilit]
- Häne, C.; Tulsiani, S.; Malik, J. Hierarchical Surface Prediction for 3D Object Reconstruction. In Proceedings of the 2017 International Conference on 3D Vision (3DV), Qingdao, China, 10–12 October 2017; pp. 412–420. [Google Scholar]
- Izadi, S.; Kim, D.; Hilliges, O.; Molyneaux, D.; Newcombe, R.; Kohli, P.; Shotton, J.; Hodges, S.; Freeman, D.; Davison, A.; et al. KinectFusion: Real-Time 3D Reconstruction and Interaction Using a Moving Depth Camera. In Proceedings of the 24th Annual ACM Symposium on User Interface Software and Technology, Santa Barbara, CA, USA, 16 October 2011; pp. 559–568. [Google Scholar]
- Fuentes Reyes, M.; d’Angelo, P.; Fraundorfer, F. Comparative Analysis of Deep Learning-Based Stereo Matching and Multi-View Stereo for Urban DSM Generation. Remote Sens. 2024, 17, 1. [Google Scholar] [CrossRef] [Scilit]
- Wang, T.; Gan, V.J.L. Enhancing 3D Reconstruction of Textureless Indoor Scenes with IndoReal Multi-View Stereo (MVS). Autom. Constr. 2024, 166, 105600. [Google Scholar] [CrossRef] [Scilit]
- Huang, H.; Yan, X.; Zheng, Y.; He, J.; Xu, L.; Qin, D. Multi-View Stereo Algorithms Based on Deep Learning: A Survey. Multimed. Tools Appl. 2024, 84, 2877–2908. [Google Scholar] [CrossRef] [Scilit]
- Park, J.J.; Florence, P.; Straub, J.; Newcombe, R.; Lovegrove, S. DeepSDF: Learning Continuous Signed Distance Functions for Shape Representation. In Proceedings of the 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, CA, USA, 15–20 June 2019; pp. 165–174. [Google Scholar]
- Mescheder, L.; Oechsle, M.; Niemeyer, M.; Nowozin, S.; Geiger, A. Occupancy Networks: Learning 3D Reconstruction in Function Space. In Proceedings of the 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, CA, USA, 15–20 June 2019; pp. 4455–4465. [Google Scholar]
- Chen, Z.; Zhang, H. Learning Implicit Fields for Generative Shape Modeling. In Proceedings of the 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Long Beach, CA, USA, 15–20 June 2019; pp. 5932–5941. [Google Scholar]
- Michalkiewicz, M.; Pontes, J.K.; Jack, D.; Baktashmotlagh, M.; Eriksson, A. Deep Level Sets: Implicit Surface Representations for 3D Shape Inference. arXiv 2019, arXiv:1901.06802. [Google Scholar]
- Mildenhall, B.; Srinivasan, P.P.; Tancik, M.; Barron, J.T.; Ramamoorthi, R.; Ng, R. NeRF: Representing Scenes as Neural Radiance Fields for View Synthesis. Commun. ACM 2022, 65, 99–106. [Google Scholar] [CrossRef] [Scilit]
- Kerbl, B.; Kopanas, G.; Leimkuehler, T.; Drettakis, G. 3D Gaussian Splatting for Real-Time Radiance Field Rendering. ACM Trans. Graph. 2023, 42, 139. [Google Scholar] [CrossRef] [Scilit]
- Chen, G.; Wang, W. A Survey on 3D Gaussian Splatting. arXiv 2024, arXiv:2401.03890. [Google Scholar]
- Barron, J.T.; Mildenhall, B.; Tancik, M.; Hedman, P.; Martin-Brualla, R.; Srinivasan, P.P. Mip-NeRF: A Multiscale Representation for Anti-Aliasing Neural Radiance Fields. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV), Montreal, QC, Canada, 10–17 October 2021; pp. 5835–5844. [Google Scholar]
- Cen, J.; Zhou, Z.; Fang, J.; Yang, C.; Shen, W.; Xie, L.; Jiang, D.; Zhang, X.; Tian, Q. Segment Anything in 3D with NeRFs. Adv. Neural Inf. Process. Syst. 2023, 36, 25971–25990. [Google Scholar]
- Chen, Z.; Funkhouser, T.; Hedman, P.; Tagliasacchi, A. MobileNeRF: Exploiting the Polygon Rasterization Pipeline for Efficient Neural Field Rendering on Mobile Architectures. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Nashville, TN, USA, 11–15 June 2023; pp. 16569–16578. [Google Scholar]
- Deng, C. NeRDi: Single-View NeRF Synthesis with Language-Guided Diffusion as General Image Priors. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, BC, Canada, 17–24 June 2023. [Google Scholar]
- Garbin, S.J.; Kowalski, M.; Johnson, M.; Shotton, J.; Valentin, J. FastNeRF: High-Fidelity Neural Rendering at 200FPS. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV), Montreal, QC, Canada, 10–17 October 2021; pp. 14326–14335. [Google Scholar]
- Hu, T.; Liu, S.; Chen, Y.; Shen, T.; Jia, J. EfficientNeRF Efficient Neural Radiance Fields. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Nashville, TN, USA, 11–15 June 2022; pp. 12902–12911. [Google Scholar]
- Jia, Z.; Wang, B.; Chen, C. Drone-NeRF: Efficient NeRF Based 3D Scene Reconstruction for Large-Scale Drone Survey. Image Vision. Comput. 2024, 143, 104920. [Google Scholar] [CrossRef] [Scilit]
- Johari, M.M.; Lepoittevin, Y.; Fleuret, F. GeoNeRF: Generalizing NeRF with Geometry Priors. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 21–24 June 2022; pp. 18344–18347. [Google Scholar]
- Mari, R.; Facciolo, G.; Ehret, T. Sat-NeRF: Learning Multi-View Satellite Photogrammetry with Transient Objects and Shadow Modeling Using RPC Cameras. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW), New Orleans, LA, USA, 19–20 June 2022; pp. 1310–1320. [Google Scholar]
- Xu, Q.; Xu, Z.; Philip, J.; Bi, S.; Shu, Z.; Sunkavalli, K.; Neumann, U. Point-NeRF: Point-Based Neural Radiance Fields. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 18–24 June 2022; pp. 5438–5448. [Google Scholar]
- Zhang, G.; Xue, C.; Zhang, R. SuperNeRF: High-Precision 3-D Reconstruction for Large-Scale Scenes. IEEE Trans. Geosci. Remote 2024, 62, 5635313. [Google Scholar] [CrossRef] [Scilit]
- Zhao, Q.; She, J.; Wan, Q. Progress in neural radiance field and its application in large-scale real-scene 3D visualization. Natl. Remote Bull. 2023, 28, 1242–1261. [Google Scholar] [CrossRef] [Scilit]
- Wang, Z.; Wu, S.; Xie, W.; Chen, M.; Prisacariu, V.A. NeRF--: Neural Radiance Fields Without Known Camera Parameters. arXiv 2021, arXiv:2102.07064. [Google Scholar]
- Ma, L.; Li, X.; Liao, J.; Zhang, Q.; Wang, X.; Wang, J.; Sander, P.V. Deblur-NeRF: Neural Radiance Fields from Blurry Images. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, LA, USA, 18–24 June 2022; pp. 12861–12870. [Google Scholar]
- Zeng, J.; Bao, C.; Chen, R.; Dong, Z.; Zhang, G.; Bao, H.; Cui, Z. Mirror-NeRF: Learning Neural Radiance Fields for Mirrors with Whitted-Style Ray Tracing. In Proceedings of the 31st ACM International Conference on Multimedia, Ottawa, ON, Canada, 26 October 2023; pp. 4606–4615. [Google Scholar]
- Pumarola, A.; Corona, E.; Pons-Moll, G.; Moreno-Noguer, F. D-NeRF: Neural Radiance Fields for Dynamic Scenes. In Proceedings of the 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Nashville, TN, USA, 20–25 June 2021; pp. 10313–10322. [Google Scholar]
- Xu, H.; Alldieck, T.; Sminchisescu, C. H-NeRF: Neural Radiance Fields for Rendering and Temporal Reconstruction of Humans in Motion. Adv. Neural Inf. Process. Syst. 2021, 34, 14955–14966. [Google Scholar]
- Wang, C.; Chai, M.; He, M.; Chen, D.; Liao, J. CLIP-NeRF: Text-and-Image Driven Manipulation of Neural Radiance Fields. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 3825–3834. [Google Scholar]
- Low, W.F.; Lee, G.H. Robust E-NeRF: NeRF from Sparse & Noisy Events under Non-Uniform Motion. In Proceedings of the 2023 IEEE/CVF International Conference on Computer Vision (ICCV), Paris, France, 1 October 2023; pp. 18289–18300. [Google Scholar]
- Neff, T.; Stadlbauer, P.; Parger, M.; Kurz, A.; Mueller, J.H.; Chaitanya, C.R.A.; Kaplanyan, A.; Steinberger, M. DONeRF: Towards Real-Time Rendering of Compact Neural Radiance Fields Using Depth Oracle Networks. Comput. Graph. Forum 2021, 40, 45–59. [Google Scholar] [CrossRef] [Scilit]
- Reiser, C.; Peng, S.; Liao, Y.; Geiger, A. KiloNeRF: Speeding up Neural Radiance Fields with Thousands of Tiny MLPs. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV), Montreal, QC, Canada, 10–17 October 2021; pp. 14315–14325. [Google Scholar]
- Müller, T.; Evans, A.; Schied, C.; Keller, A. Instant Neural Graphics Primitives with a Multiresolution Hash Encoding. ACM Trans. Graph. (TOG) 2022, 41, 102. [Google Scholar] [CrossRef] [Scilit]
- Chen, A.; Xu, Z.; Zhao, F.; Zhang, X.; Xiang, F.; Yu, J.; Su, H. MVSNeRF: Fast Generalizable Radiance Field Reconstruction from Multi-View Stereo. In Proceedings of the 2021 IEEE/CVF International Conference on Computer Vision (ICCV), Montreal, QC, Canada, 10–17 October 2021; pp. 14104–14113. [Google Scholar]
- Verbin, D.; Hedman, P.; Mildenhall, B.; Zickler, T.; Barron, J.T.; Srinivasan, P.P. Ref-NeRF: Structured View-Dependent Appearance for Neural Radiance Fields. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 18–24 June 2022; pp. 5481–5490. [Google Scholar]
- Guo, Y.-C.; Kang, D.; Bao, L.; He, Y.; Zhang, S.-H. NeRFReN: Neural Radiance Fields with Reflections. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 18–24 June 2022; pp. 18388–18397. [Google Scholar]
- Bao, Y.; Ding, T.; Huo, J.; Liu, Y.; Li, Y.; Li, W.; Gao, Y.; Luo, J. 3D Gaussian Splatting: Survey, Technologies, Challenges, and Opportunities. In IEEE Transactions on Circuits and Systems for Video Technology; IEEE: Piscataway, NJ, USA, 2024. [Google Scholar]
- Yan, Z.; Low, W.F.; Chen, Y.; Lee, G.H. Multi-Scale 3D Gaussian Splatting for Anti-Aliased Rendering. In Proceedings of the 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16 June 2024; pp. 20923–20931. [Google Scholar]
- Lee, B.; Lee, H.; Sun, X.; Ali, U.; Park, E. Deblurring 3D Gaussian Splatting. In European Conference on Computer Vision; Springer Nature Switzerland: Cham, Switzerland, 2024; pp. 127–143. [Google Scholar]
- Yu, Z.; Chen, A.; Huang, B.; Sattler, T.; Geiger, A. Mip-Splatting: Alias-Free 3D Gaussian Splatting. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, WA, USA, 17–21 June 2024. [Google Scholar]
- Lin, Y.; Dai, Z.; Zhu, S.; Yao, Y. Gaussian-Flow: 4D Reconstruction with Dynamic 3D Gaussian Particle. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, BC, Canada, 17–24 June 2023. [Google Scholar]
- Chen, Y.; Chen, Z.; Zhang, C.; Wang, F.; Yang, X.; Wang, Y.; Cai, Z.; Yang, L.; Liu, H.; Lin, G. GaussianEditor: Swift and Controllable 3D Editing with Gaussian Splatting. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, BC, Canada, 17–24 June 2023. [Google Scholar]
- Fang, J.; Wang, J.; Zhang, X.; Xie, L.; Tian, Q. GaussianEditor: Editing 3D Gaussians Delicately with Text Instructions. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, BC, Canada, 17–24 June 2023. [Google Scholar]
- Ye, M.; Danelljan, M.; Yu, F.; Ke, L. Gaussian Grouping: Segment and Edit Anything in 3D Scenes. In European Conference on Computer Vision; Springer Nature Switzerland: Cham, Switzerland, 2023; pp. 162–179. [Google Scholar]
- Li, Z.; Zheng, Z.; Wang, L.; Liu, Y. Animatable Gaussians: Learning Pose-Dependent Gaussian Maps for High-Fidelity Human Avatar Modeling. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, BC, Canada, 17–24 June 2023. [Google Scholar]
- Fan, Z.; Wang, K.; Wen, K.; Zhu, Z.; Xu, D.; Wang, Z. LightGaussian: Unbounded 3D Gaussian Compression with 15x Reduction and 200+ FPS. Adv. Neural Inf. Process. Syst. 2023, 37, 140138–140158. [Google Scholar]
- Jiang, Y.; Shen, Z.; Wang, P.; Su, Z.; Hong, Y.; Zhang, Y.; Yu, J.; Xu, L. HiFi4G: High-Fidelity Human Performance Rendering via Compact Gaussian Splatting. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, BC, Canada, 17–24 June 2023. [Google Scholar]
- Xie, Z.; Zhang, J.; Li, W.; Zhang, F.; Zhang, L. S-NeRF: Neural Radiance Fields for Street Views. arXiv 2023, arXiv:2303.00749. [Google Scholar]
- Wan, Q.; Guan, Y.; Zhao, Q.; Wen, X.; She, J. Constraining the Geometry of NeRFs for Accurate DSM Generation from Multi-View Satellite Images. ISPRS Int. J. Geo-Inf. 2024, 13, 243. [Google Scholar] [CrossRef] [Scilit]
- Turki, H.; Ramanan, D.; Satyanarayanan, M. Mega-NeRF: Scalable Construction of Large-Scale NeRFs for Virtual Fly- Throughs. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 21–24 June 2022; pp. 12912–12921. [Google Scholar]
- Tancik, M.; Casser, V.; Yan, X.; Pradhan, S.; Mildenhall, B.P.; Srinivasan, P.; Barron, J.T.; Kretzschmar, H. Block-NeRF: Scalable Large Scene Neural View Synthesis. In Proceedings of the 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), New Orleans, LA, USA, 21–24 June 2022; pp. 8238–8248. [Google Scholar]
- Lin, J.; Li, Z.; Tang, X.; Liu, J.; Liu, S.; Liu, J.; Lu, Y.; Wu, X.; Xu, S.; Yan, Y.; et al. VastGaussian: Vast 3D Gaussians for Large Scene Reconstruction. In Proceedings of the 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), Seattle, WA, USA, 16 June 2024; pp. 5166–5175. [Google Scholar]
- Ren, K.; Jiang, L.; Lu, T.; Yu, M.; Xu, L.; Ni, Z.; Dai, B. Octree-GS: Towards Consistent Real-Time Rendering with LOD-Structured 3D Gaussians. arXiv 2024, arXiv:2403.17898. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Chen, Y.; Lee, G.H. DoGaussian: Distributed-Oriented Gaussian Splatting for Large-Scale 3D Reconstruction Via Gaussian Consensus. Adv. Neural Inf. Process. Syst. 2024, 37, 34487–34512. [Google Scholar]
- Kerbl, B.; Meuleman, A.; Kopanas, G.; Wimmer, M.; Lanvin, A.; Drettakis, G. A Hierarchical 3D Gaussian Representation for Real-Time Rendering of Very Large Datasets. ACM Trans. Graph. 2024, 43, 62. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).