


Abstract
This paper evaluates neural-network approaches for lithium-ion battery state-of-charge (SoC) estimation under a unified pipeline, fixed data partitions, and identical preprocessing. We study FNNs trained with Levenberg–Marquardt (LM), Bayesian Regularization (BR), and Scaled Conjugate Gradient (SCG) across three hidden sizes (10, 20, 30) and three topologies: Fitting, Nonlinear Input–Output (Nonlinear I/O), and time-series NAR/NARX. Models are assessed using test MSE and RMSE, correlation (R), generalization gap, convergence indicators (final gradient, damping factor), wall time per epoch, and a relative compute-cost index. On the Fitting task, BR-Fitting-FNN with 20 neurons provides the best accuracy-efficiency balance, while LM-Fitting-FNN with 30 neurons reaches slightly lower error at a higher cost. For Nonlinear I/O, BR-Nonlinear I/O-FNN with 30 neurons achieves the lowest test MSE with clear evidence of effective weight shrinkage; LM-Nonlinear I/O-FNN with 20 neurons is a close alternative. In time-series settings, LM-NAR-FNN with 10 neurons attains the lowest test error and fastest epochs but shows a very negative gap that suggests test-split favorability; BR-NAR-FNN with 30 neurons is more costly yet consistently strong. For NARX, LM-NARX-FNN with 20 neurons yields the best test accuracy and robust convergence. Overall, BR delivers the most reliable accuracy–robustness trade-off as networks widen, LM often achieves the best raw accuracy with careful split validation, and SCG offers the lowest training cost when resources are limited. These results provide practical guidance for selecting SoC estimators to match accuracy targets, computing budgets, and deployment constraints in battery management systems.
1. Introduction
Lithium-ion batteries are widely used in devices ranging from smartphones to electric vehicles, making real-time state-of-charge (SoC) monitoring essential for safety, longer battery life, and efficient energy usage [1]. Traditional SoC estimation methods, such as open-circuit voltage look-up tables, equivalent circuit models with Kalman filtering, and full electrochemical observers, offer valuable physical insights. However, they often require extensive parameter tuning and tend to lose accuracy over time as the battery ages or operates under changing temperatures [2]. With the availability of large-scale cycling datasets and affordable computing power, data-driven methods have gained attention. ANNs are capable of directly learning the relationship between current, voltage, and temperature signals and SoC, without the need for explicit battery modeling [3]. Early approaches used FNNs trained with algorithms like Levenberg–Marquardt or Bayesian regularization. These models can handle nonlinear relationships but rely on sliding-window inputs to capture time-related behaviors [4]. Recurrent neural networks have been introduced to solve this limitation. LSTM networks can retain information over long sequences, while GRUs achieve similar performance with fewer parameters and faster training [5]. More recently, TCNs have replaced recurrence with one-dimensional dilated causal convolutions and residual blocks, ensuring that predictions at time step t depend only on inputs from time t and earlier [6]. Hybrid models that combine TCN and LSTM have shown further improvements by combining convolutional feature extraction with recurrent memory, leading to lower RMSE values [7].
1.1. Feedforward Neural Networks (FNNs)
Multilayer FNNs consist of an input layer, one or more hidden layers, and an output layer, where data flows strictly in a forward direction. Thanks to their universal approximation property, FNNs can model any Borel-measurable function on a compact domain in ℝⁿ, provided that enough hidden units and appropriate nonlinear activations are used [8]. Training typically relies on backpropagation with gradient-based optimization. For regression problems, squared-error loss and its gradient are computed efficiently using the chain rule [9]. In SoC estimation, shallow FNNs can capture nonlinear static relationships between voltage, current, and temperature. Still, they require manual time-windowing to handle temporal patterns and often struggle with long-term dependencies [5,7,10].
1.2. Training Algorithms for FNNs
The Levenberg–Marquardt (LM) algorithm is a damped least-squares method that interpolates between Gauss–Newton and gradient descent. It is well-suited for medium-sized networks and typically converges quickly when the Hessian is well behaved [9,11,12]. Bayesian Regularization (BR) introduces weight decay into a probabilistic framework, allowing the network to balance accuracy and complexity through data-driven hyperparameter adjustment automatically. This tends to improve generalization, especially in noisy battery datasets [5,13,14]. The Scaled Conjugate Gradient (SCG) algorithm avoids explicit line searches by using second-order information to scale conjugate gradient directions. It is more memory-efficient than LM and converges faster than standard gradient descent [15].
1.3. Neural-Network Time-Series Families (Shallow/Dynamic Nets)
NARX (Nonlinear Autoregressive with Exogenous Inputs) models use delayed inputs and past outputs to feed a static FNN. In contrast, NAR networks use only past outputs, and nonlinear input–output (NIO) networks process only current inputs without feedback [16,17,18]. NARX architectures are particularly effective for nonlinear dynamics and systems with memory [19]. In SoC estimation, where the battery evolves slowly over time, these architectures can outperform plain FNNs by embedding useful temporal information directly into the network structure [5,7].
1.4. Long Short-Term Memory (LSTM) Networks
LSTMs enhance standard recurrent neural networks with gated memory cells that control input, output, and forget mechanisms. These gates help retain long-term information and prevent vanishing gradient issues using a structure known as the constant error carousel [20]. LSTMs are widely used in SoC estimation because they can learn temporal dependencies in voltage, current, and temperature without the need to manually select time lags [7,21]. However, they typically require more training time and parameters compared to GRUs or convolutional models [6,20].
1.5. Gated Recurrent Units (GRUs)
GRUs simplify LSTM architecture by merging the input and forget gates into a single update gate, and using a reset gate to manage memory updates. This reduces the number of trainable parameters while retaining strong performance on sequential tasks [22]. For SoC estimation, GRUs often match LSTM accuracy on moderate-length sequences and benefit from faster convergence and reduced data requirements, making them suitable for real-time applications in battery management systems (BMS) [6].
1.6. Temporal Convolutional Networks (TCNs)
TCNs replace recurrence with one-dimensional dilated causal convolutions, ensuring that predictions at time t depend only on past inputs. Dilation enables the network to capture long-range dependencies with fewer layers, and residual connections with dropout improve training stability [4,23]. TCNs have shown strong performance on sequence modeling tasks and allow full parallelization during training [23]. In SoC applications, both TCNs and hybrid TCN–LSTM models have reported lower RMSE by combining convolutional feature extraction with recurrent memory mechanisms [7].
1.7. Comparative Analysis for SoC Estimation
A standard SoC estimation pipeline includes preprocessing (e.g., normalization, windowing), training with cross-validation, and evaluation using metrics such as RMSE, MAE, or MAPE [5,7]. FNNs trained with LM, BR, or SCG remain competitive for static mappings but rely on manual windowing to capture temporal trends [5,9,12,14,15]. NARX, NAR, and NIO networks explicitly embed time delays, which is useful when domain knowledge identifies key lags [5,16,17,18,19]. LSTMs are preferable when long-term temporal behavior is complex or unknown, though they may overfit smaller datasets without proper regularization [7,20,21]. GRUs offer a balance between performance and efficiency, often matching LSTM accuracy with fewer resources [6,22]. TCNs provide high accuracy with fast, parallel training but require careful design of receptive fields to handle both fast transient and long-term dependencies [7,23]. Hybrid models such as TCN–LSTM increasingly represent the best compromise between accuracy and robustness [7]. Final model selection should account for sequence length, sampling rate, computational cost, and deployment constraints within the target BMS platform [5,6,7,21].
Direct comparisons between FNN, LSTM, GRU, and TCN architectures are still limited. Many existing studies use different preprocessing methods or hyperparameter settings, which makes it difficult to judge which model performs best under the same conditions [24,25]. These variations create inconsistencies that complicate accurate cross-study benchmarking and obscure the evaluation of relative model effectiveness. Furthermore, the implementation of complex composite algorithms, utilizing serial or parallel architectures, substantially increases model complexity [26]. As the number of integrated modules expands, the overall controllability of the system decreases. This reduction in control increases sensitivity to disturbances, raising critical concerns regarding the model’s robustness in practical applications [27]. This study aims to address the gap by training all four architectures on the same dataset using identical preprocessing and a unified hyperparameter search. Their performance is then compared based on accuracy, computational cost, and generalization ability. This work has conducted a systematic and fair comparison of four neural network architectures, FNN, LSTM, GRU, and TCN, for estimating the SoC in lithium-ion batteries. In summary, the following task has been performed.
- It has evaluated and compared the predictive accuracy, generalization capability, and computational efficiency of FNN, LSTM, GRU, and TCN models using the same dataset and unified preprocessing methods.
- It has also investigated the impact of different network configurations and hyperparameters on model performance under varied test conditions, including multiple temperatures and dynamic drive cycles.
- It identified the optimal model architecture for SoC estimation based on test MSE, RMSE, convergence quality, runtime efficiency, and generalization gap.
The remainder of this work is organized as follows: Section 2 describes the data source, model architecture, and training configuration used for a comprehensive comparison of several neural network models (FNN, LSTM, GRU, and TCN) for SoC estimation. Section 3 presents detailed simulations, discussions, and the formulated findings summarized in tables. Finally, Section 4 concludes the paper and provides recommendations.
2. Methodology
This study compares the effectiveness of several neural network models: FNN, LSTM, GRU, and TCN, for estimating the SoC in lithium-ion batteries. All models were trained and evaluated using the same real-world dataset to ensure a fair and consistent comparison. The analysis is based exclusively on the McMaster University LG HG2 dataset, which contains high-resolution time-series data recorded under controlled thermal chamber conditions across a range of temperatures and operational modes.
2.1. Data Source and Preparation
The dataset was collected at McMaster University using a brand new 3Ah LG HG2 cell tested within an eight cubic feet. The thermal chamber is monitored using a Digatron Universal Battery Tester (Digatron Power Electronics, Aachen, Germany). Measurements were performed at six ambient temperatures: 40 °C, 25 °C, 10 °C, 0 °C, −10 °C, and −20 °C. Each test included multiple drive cycles (UDDS, HWFET, LA92, US06), hybrid pulse power characterizations (HPPC), and constant current discharges at various C-rates [28]. The dataset was provided in .mat format and directly imported into MATLAB (v2021s) without further cleaning or normalization, as the original research team had already preprocessed the data. For input features, combinations of voltage, current, power, amp-hours (Ah), watt-hours (Wh), and battery temperature were used.
2.2. Data Splitting Strategy
To evaluate generalization, the dataset was divided into training, validation, and testing sets. For models trained with LM and SCG, a 70/15/15 split was used. For BR, which does not require a validation set, an 85/0/15 split was applied. These splits were kept consistent across all architecture and neuron configurations after running multiple tests, and this setup provided the best overall model performance.
2.3. Model Architectures
Three model families were implemented: FNN, LSTM/GRU, and TCN. FNN models included Fitting, NAR, and NARX structures, each trained with LM, BR, and SCG algorithms using 10, 20, or 30 hidden neurons. All FNNs had a single tansig hidden layer and linear output. LSTM and GRU models used two stacked recurrent layers followed by a fully connected output, with windowed inputs (e.g., length 80, stride 20). They were trained using the Adam optimizer with tuned hyperparameters. The number of hidden units was aligned with the 20-neuron FNN for fairness. TCN replaced recurrence with 1D dilated causal convolutions using dilation rates from 1 to 16, residual blocks, ReLU activations, dropout, and causal padding. Input formatting for TCN matched that of LSTM and GRU.
2.4. Training Configuration
Each model was trained using one of three optimization algorithms, and the training was conducted in MATLAB. FNN models were developed using built-in functions such as fitnet, narnet, and narxnet. They were typically trained for up to 1000 epochs, with early stopping triggered by validation checks when applicable. BR-based FNNs trained to full completion without validation monitoring. In contrast, LSTM, GRU, and TCN models were implemented using custom code via the Deep Learning Toolbox and trained with manually selected epoch limits (e.g., 80 epochs), optimized for convergence and runtime. Learning rate, batch size, and other training parameters were tuned individually for each model family to achieve a balance between accuracy, stability, and efficiency.
2.5. Evaluation Metrics
Model performance was evaluated using several key metrics: MSE and RMSE were used to measure overall prediction accuracy. At the same time, the regression coefficient (R) assessed the correlation between predicted and actual SoC. The generalization gap, defined as the relative difference between test and training MSE, provided insight into overfitting or underfitting behavior. For FNN models, convergence quality was examined using the final gradient and damping factor (μ). Training time and compute cost were also recorded, normalized relative to the fastest configuration in each group. These metrics offered a comprehensive view of each model’s accuracy, efficiency, and generalization ability. All models were trained using identical input features, consistent preprocessing, and fixed data splits to ensure fair and unbiased comparisons.
3. Results and Discussion
3.1. FNN-Fitting
3.1.1. LM-Fitting-FNN
The 30-neuron LM-Fitting-FNN is the preferred model, as it delivers the lowest test error MSE of 3.6279 × 10⁻⁴ and the strongest generalization of −4.71%, despite requiring nearly three times the computational effort compared to the 10-neuron baseline. When computational resources are more constrained, the 20-neuron network offers a balanced alternative, achieving a 15.5% accuracy improvement over the 10-neuron model with only a moderate increase to 1.9× in runtime and resource usage. The 10-neuron configuration remains a practical choice when fast training and low computational cost are prioritized, exceeding the absolute minimum error as shown in Table 1 and Table 2.
Table 1.
Performance metrics for the LM-Fitting-FNN.
Table 2.
Derived indicators for the LM-Fitting-FNN.
3.1.2. BR-Fitting-FNN
The 30-neuron BR-Fitting-FNN model achieved the lowest MSE test error of 3.6074 × 10⁻⁴, among the three configurations, its improvement over the 20-neuron version is minimal at only +0.09%. It slightly outperforms by eliminating the positive generalization gap, but this comes at a computational cost that is 1.8 times higher. Therefore, the 20-neuron BR Fitting FNN offers the best balance between accuracy and efficiency. The 10-neuron model remains a practical choice for resource-constrained situations where a modest increase in error is acceptable in exchange for faster training and reduced computational requirements as shown in Table 3 and Table 4.
Table 3.
Performance metrics for the BR-Fitting-FNN.
Table 4.
Derived indicators for the BR-Fitting-FNN.
3.1.3. SCG-Fitting-FNN
The 30 neuron SCG Fitting FNN delivers the best accuracy of 5.363 × 10⁻⁴ and acceptable generalization gap of −2.4%, but it also requires the most time and resources reported in Table 5 and Table 6. The 20 neuron model is a practical compromise, offering most of the accuracy gains of the 30 neuron network while keeping computational demands modest. The 10 neuron configuration remains suitable for quick training and minimal cost when a slightly higher error can be tolerated.
Table 5.
Performance metrics for the SCG-Fitting-FNN.
Table 6.
Derived indicators for the SCG-Fitting-FNN.
3.1.4. Optimal Fitting-FNN Model
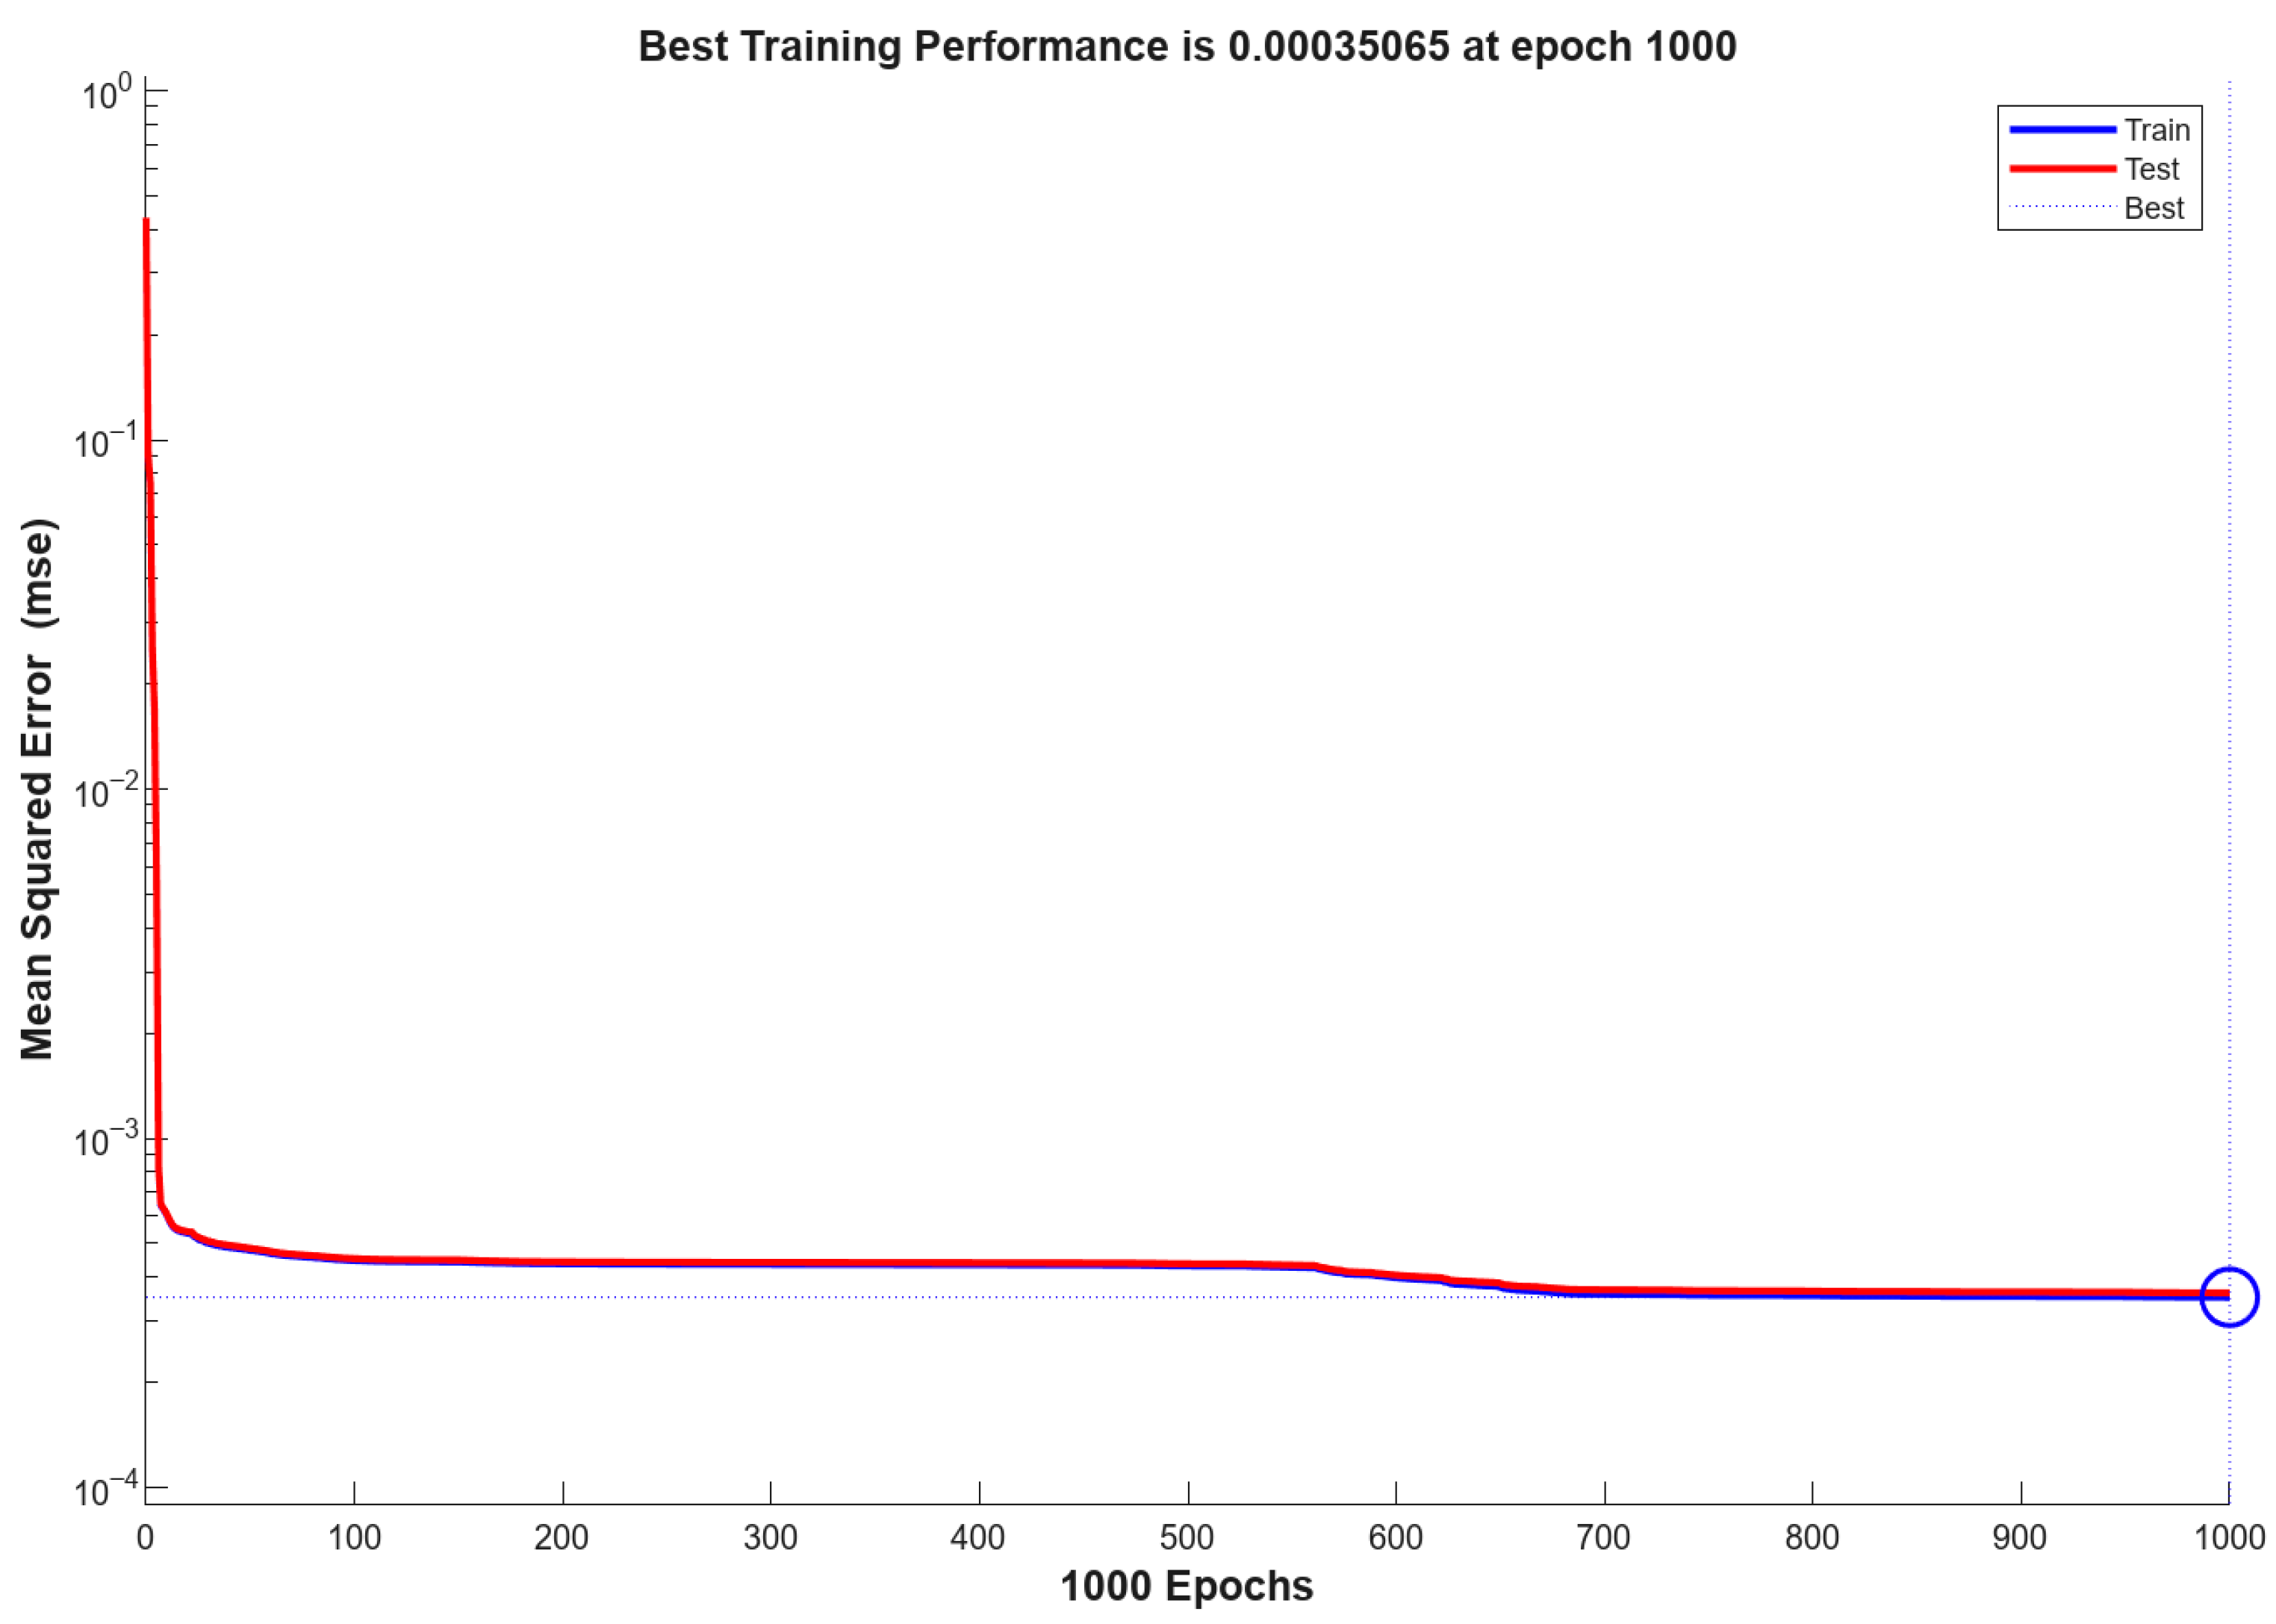
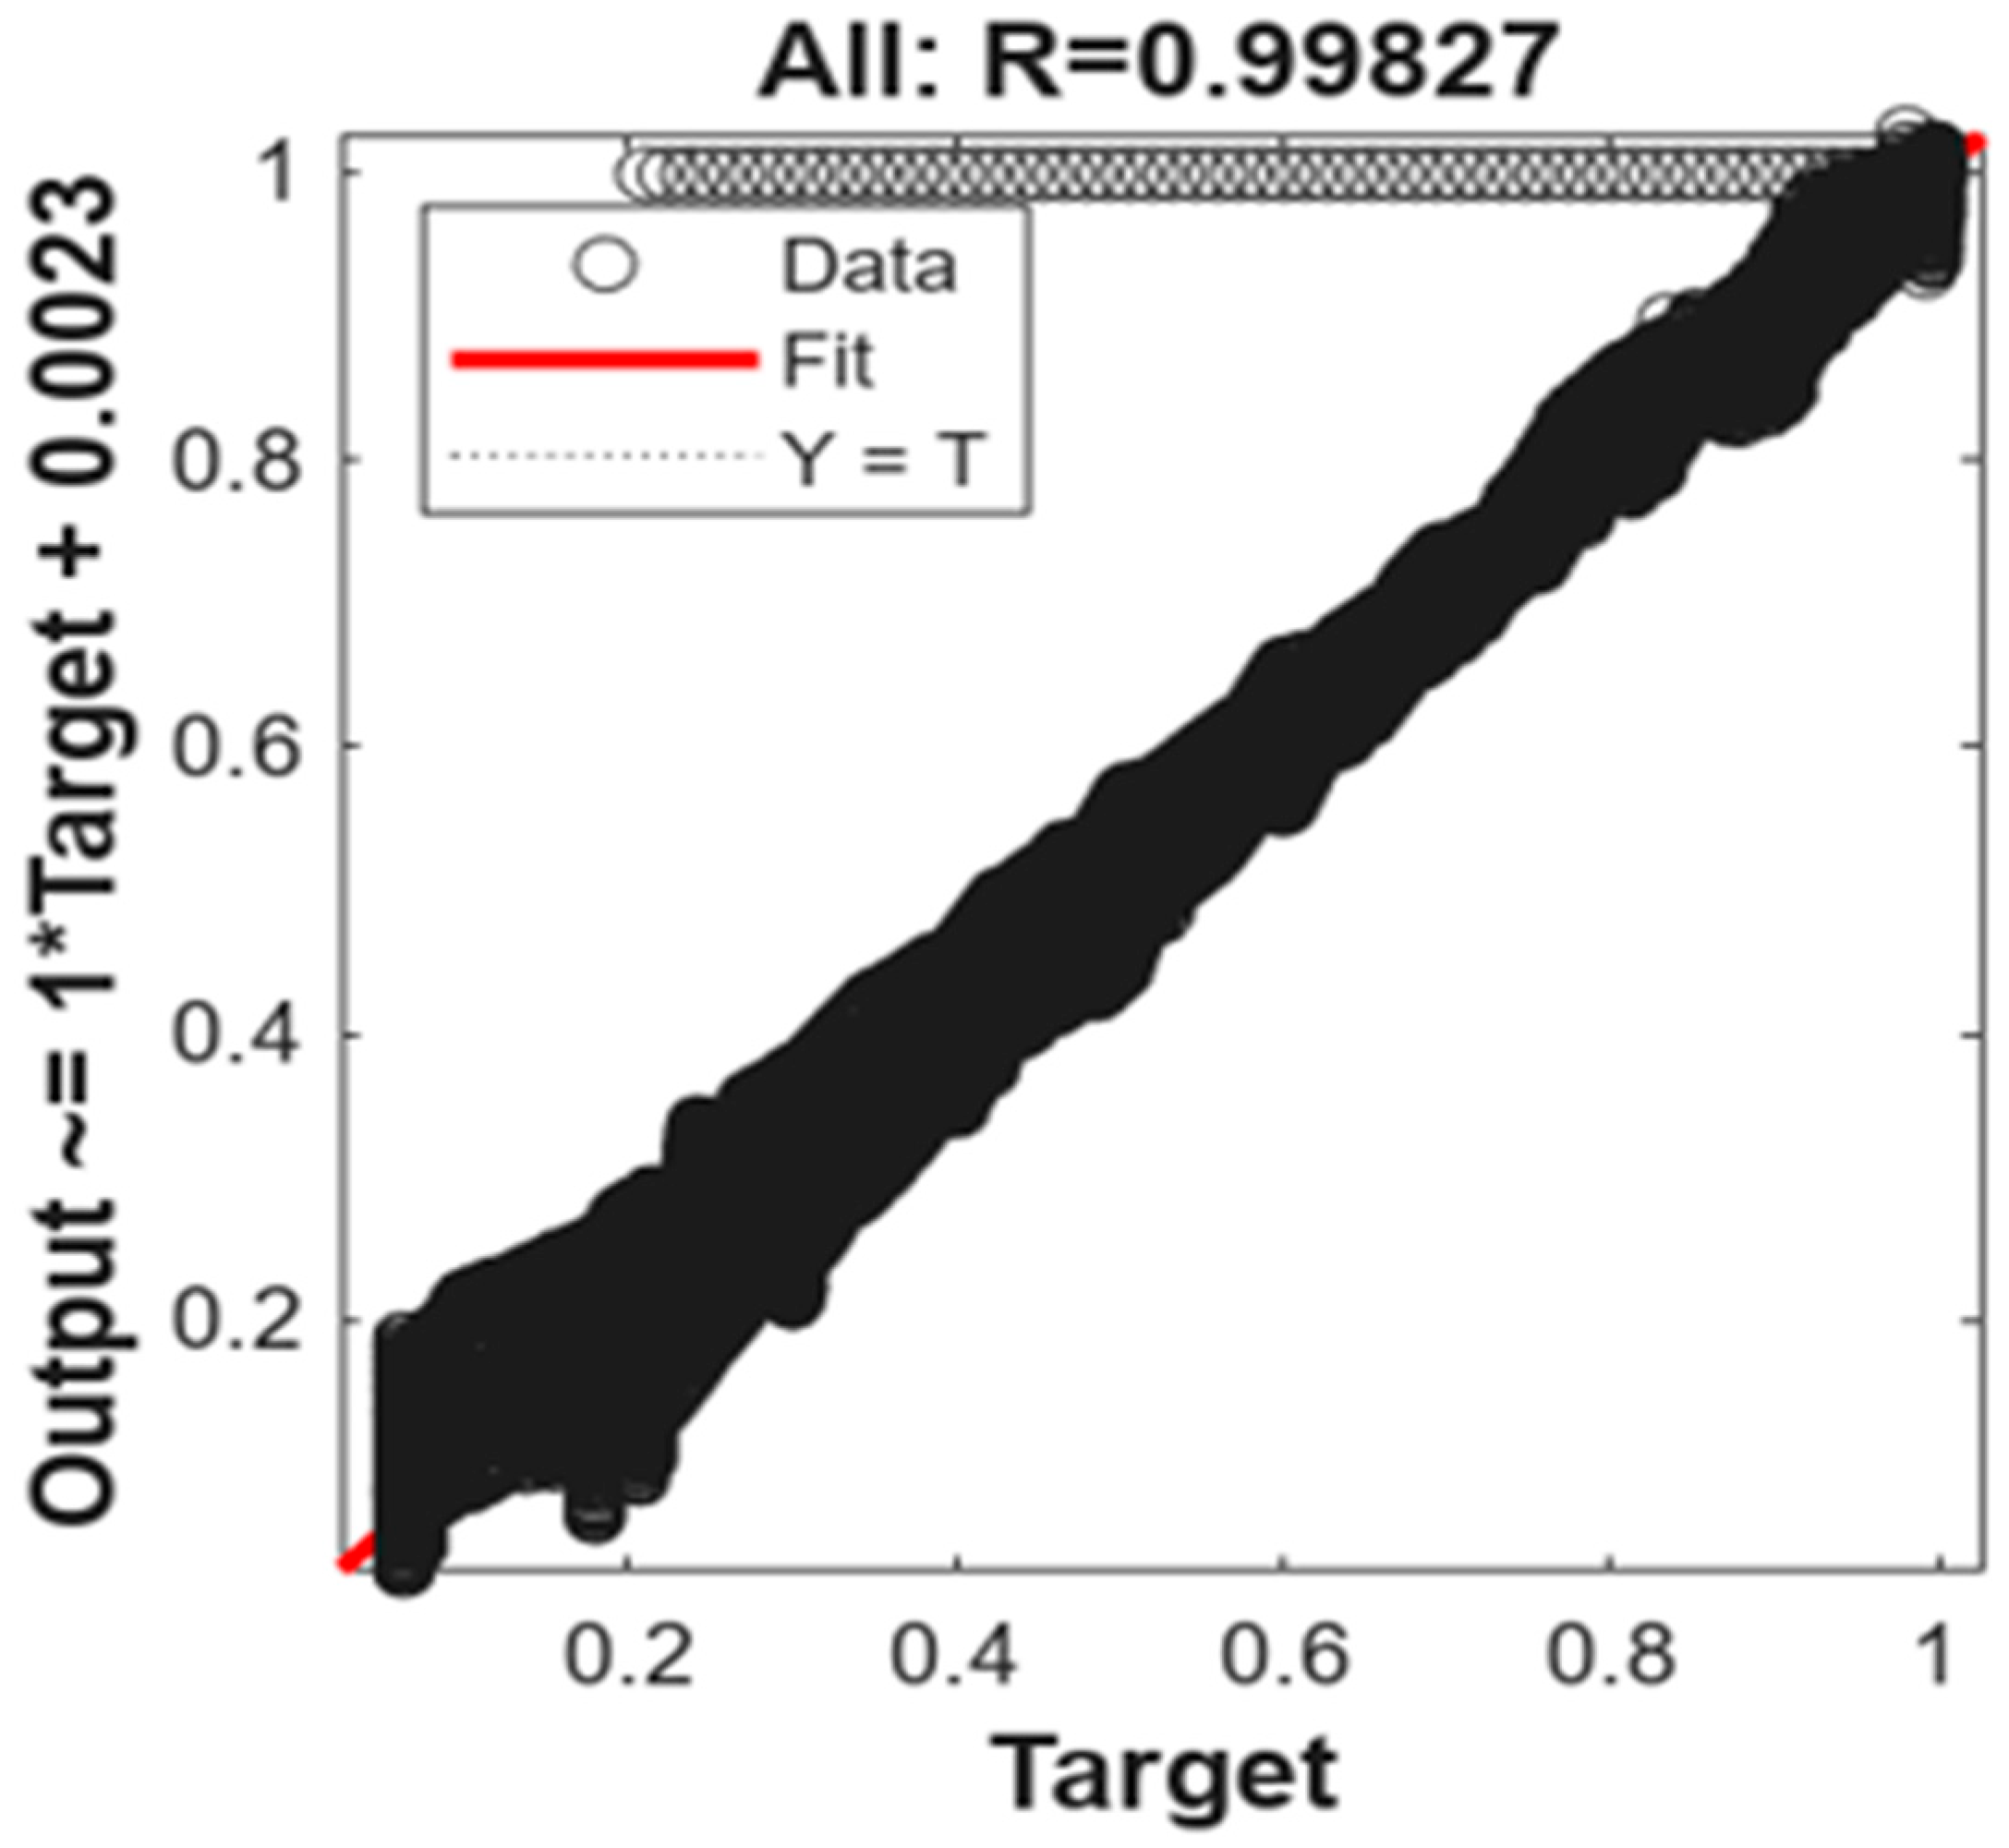
The 20-neuron BR-Fitting-FNN is the best overall performer, achieving the lowest test MSE of 3.6105 × 10⁻⁴ and a top R value of 0.9984, with a small +3.0% generalization gap and moderate computational cost. In addition, The MSE curves of the training and test drop rapidly within the first 50 epochs, decreasing by more than three orders of magnitude as shown in Figure 1. After around epoch 200, the curves start to flatten, indicating that further training leads to only minor improvements. By epoch 700, the training MSE reaches its minimum value of 3.5065 × 10⁻⁴ and stays stable through to epoch 1000. The test MSE shows a similar trend, and the “Best” marker appears at the point where both curves align. Since the gap between training and test errors remains small and does not increase, there is no indication of overfitting. Each subplot in Figure 2 shows how well the predictions match the actual values. The blue points closely follow the red 1:1 reference line. For both the training and test data, the correlation is R = 0.9983. The combined plot also shows a slope near one and an intercept around +2 × 10⁻³, which means there is almost no systematic bias across the full SoC range. The tight clustering of points around the line suggests that the remaining variation is likely due to noise in the data rather than model error.
Figure 1.
Performance curve for the 20-neuron BR-Fitting-FNN.
Figure 2.
Regression plots for the 20-neuron BR-Fitting-FNN.
3.2. FNN-Time Series
All runs use the NAR topology (only past y(t)), time delay = 2. Three algorithms were tested: LM, BR, and SCG with 10, 20, and 30 hidden neurons each. The goal is to select the optimal neuron size within each optimizer and then determine the best optimizer overall.
3.2.1. LM NAR-FNN
The 10-neuron LM-NAR-FNN is the most effective configuration based on test MSE, convergence behavior, and computational efficiency. It achieved the lowest test error of 7.9666 × 10⁻⁹ by a large margin, demonstrated clean convergence, and required the least training time per epoch. Although the strongly negative generalization gap of −99.7%, suggests the test fold may be easier than the training data, the results clearly favor this configuration under current partitions. The 30-neuron model offers reliable validation accuracy and moderate generalization at a higher computational cost. In contrast, the 20-neuron network shows signs of overfitting and is not recommended for deployment without further refinement as shown in Table 7 and Table 8.
Table 7.
Performance metrics for the LM-NAR-FNN.
Table 8.
Derived indicators for the LM-NAR-FNN.
3.2.2. BR NAR-FNN
The 30-neuron BR-NAR-FNN is the best-performing configuration when predictive accuracy is prioritized, considering test set accuracy, generalization behavior. It consistently achieves the lowest MSE error metrics of 1.3550 × 10⁻⁷ and demonstrates strong convergence of −94.4%, although this comes with the highest training time and a 4.8× compute cost relative to the baseline as presented in Table 9 and Table 10. The 10-neuron model provides a compelling alternative for scenarios where efficiency is critical, offering competitive accuracy at the lowest computational expense. In contrast, the 20-neuron configuration exhibits substantial overfitting and poor generalization to unseen data, making it unsuitable.
Table 9.
Performance metrics for the BR-NAR-FNN.
Table 10.
Derived indicators for the SCG-Fitting-FNN.
3.2.3. SCG NAR-FNN
The 10-neuron SCG-NAR-FNN is the best-performing configuration, considering test MSE as the primary accuracy metric. It achieved the lowest test MSE of 6.4303 × 10⁻⁷ with the smallest compute cost and stable convergence. Although the strongly negative generalization gap of −82.9% suggests the test fold may be easier than the training set. The 30-neuron model is a reasonable alternative, yielding a test MSE of 9.4941 × 10⁻⁷, which is better than the 20-neuron model by 19.4% but still falling short of the 10-neuron result and requiring substantially more computation. The 20-neuron model shows the worst test MSE, indicating the weakest generalization and making it unsuitable without improved regularization or adjusted data splits.
3.2.4. Optimal NAR-FNN Model
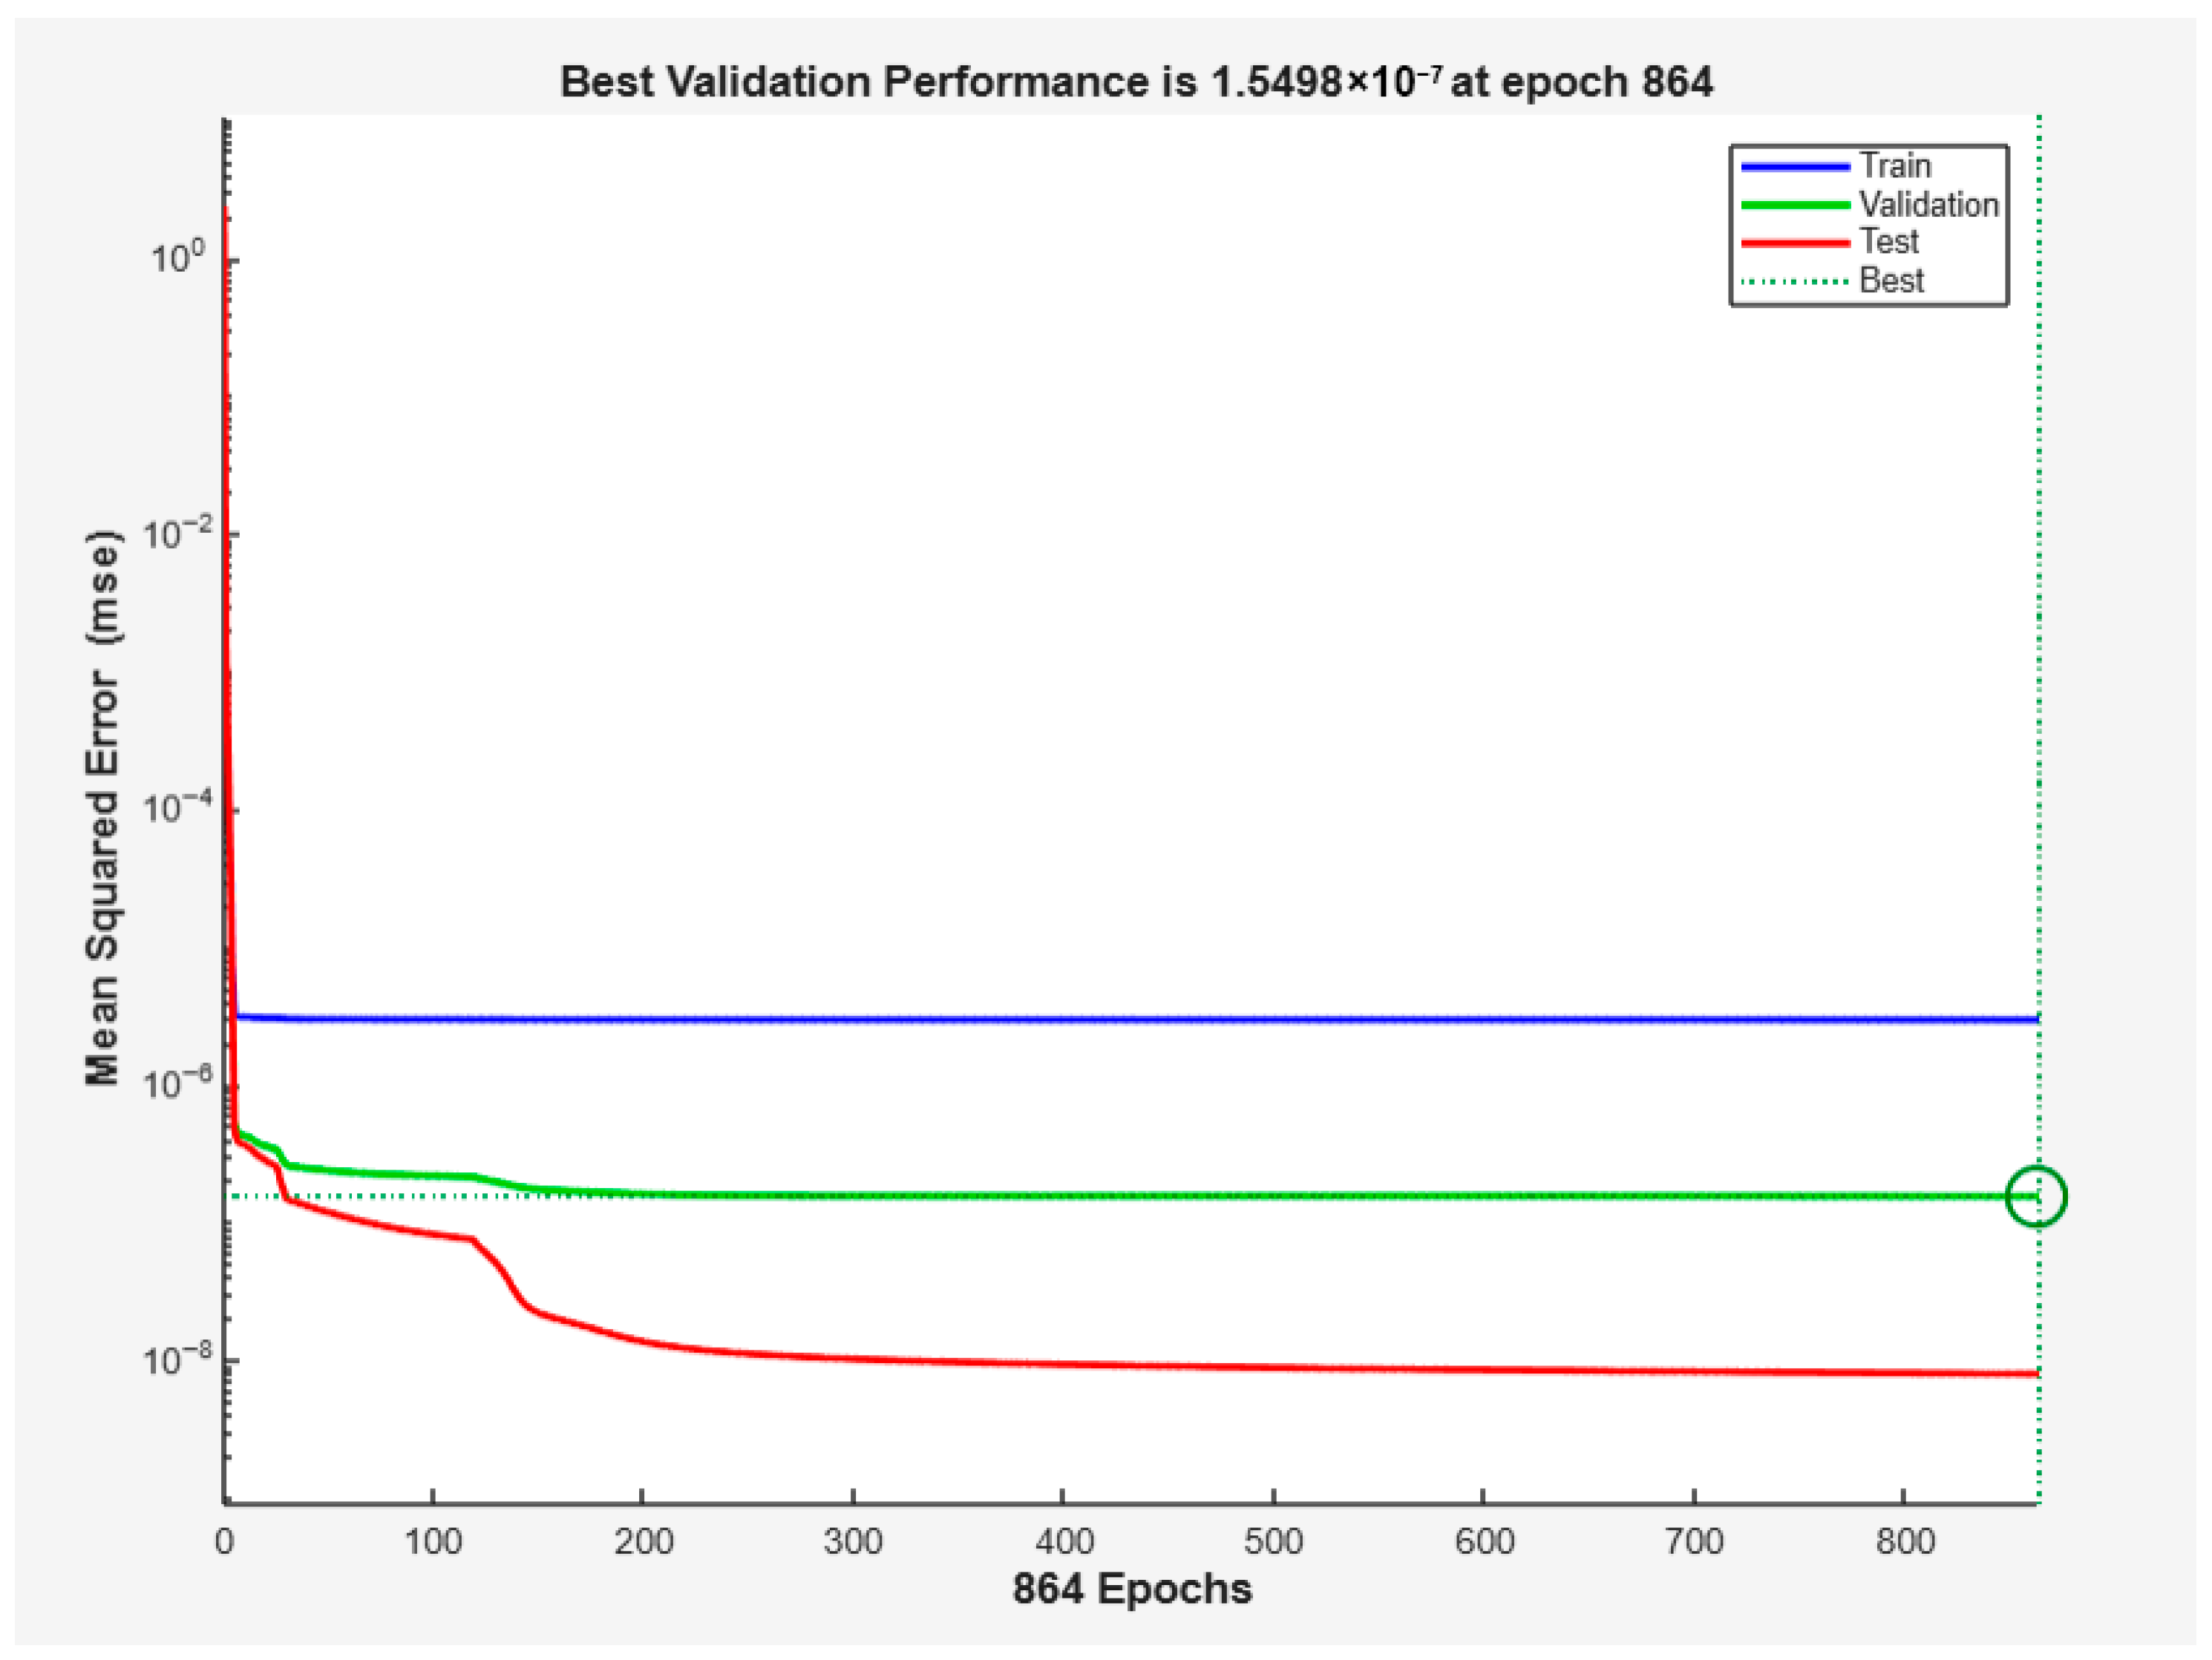
Across all NAR-FNN configurations and optimizers summarized in Table 7, Table 8, Table 9, Table 10, Table 11 and Table 12, the 10-neuron LM-NAR-FNN stands out as the best-performing model. It achieved the lowest test MSE of 7.9666 × 10⁻⁹, outperforming all BR and SCG variants by at least an order of magnitude. Convergence was stable, with a final gradient of 9.97 × 10⁻⁸ and a fixed damping factor μ = 1 × 10⁻⁸. In terms of efficiency, this model also recorded the fastest training time per epoch at 0.37 s and the lowest compute cost at 1× relative to the baseline. While the generalization gap was strongly negative at 99.7%, suggesting the test fold was much easier than the training set, this pattern was observed in other high-performing models as well. In addition, the MSE curves for the training, validation, and test sets drop rapidly during the first 100 epochs, reducing the error by more than three orders of magnitude before flattening with only minor changes as shown in Figure 3. The best validation performance occurs at epoch 864 with MSE = 1.5498 × 10⁻⁷. The generalization gap, calculated as (Test − Train)/Train, is −72.6%, indicating the test error is lower than the training error.
Table 11.
Performance metrics for the SCG-NAR-FNN.
Table 12.
Derived indicators for the SCG-NAR-FNN.
Figure 3.
Performance curve for the 10-neuron LM-NAR-FNN.
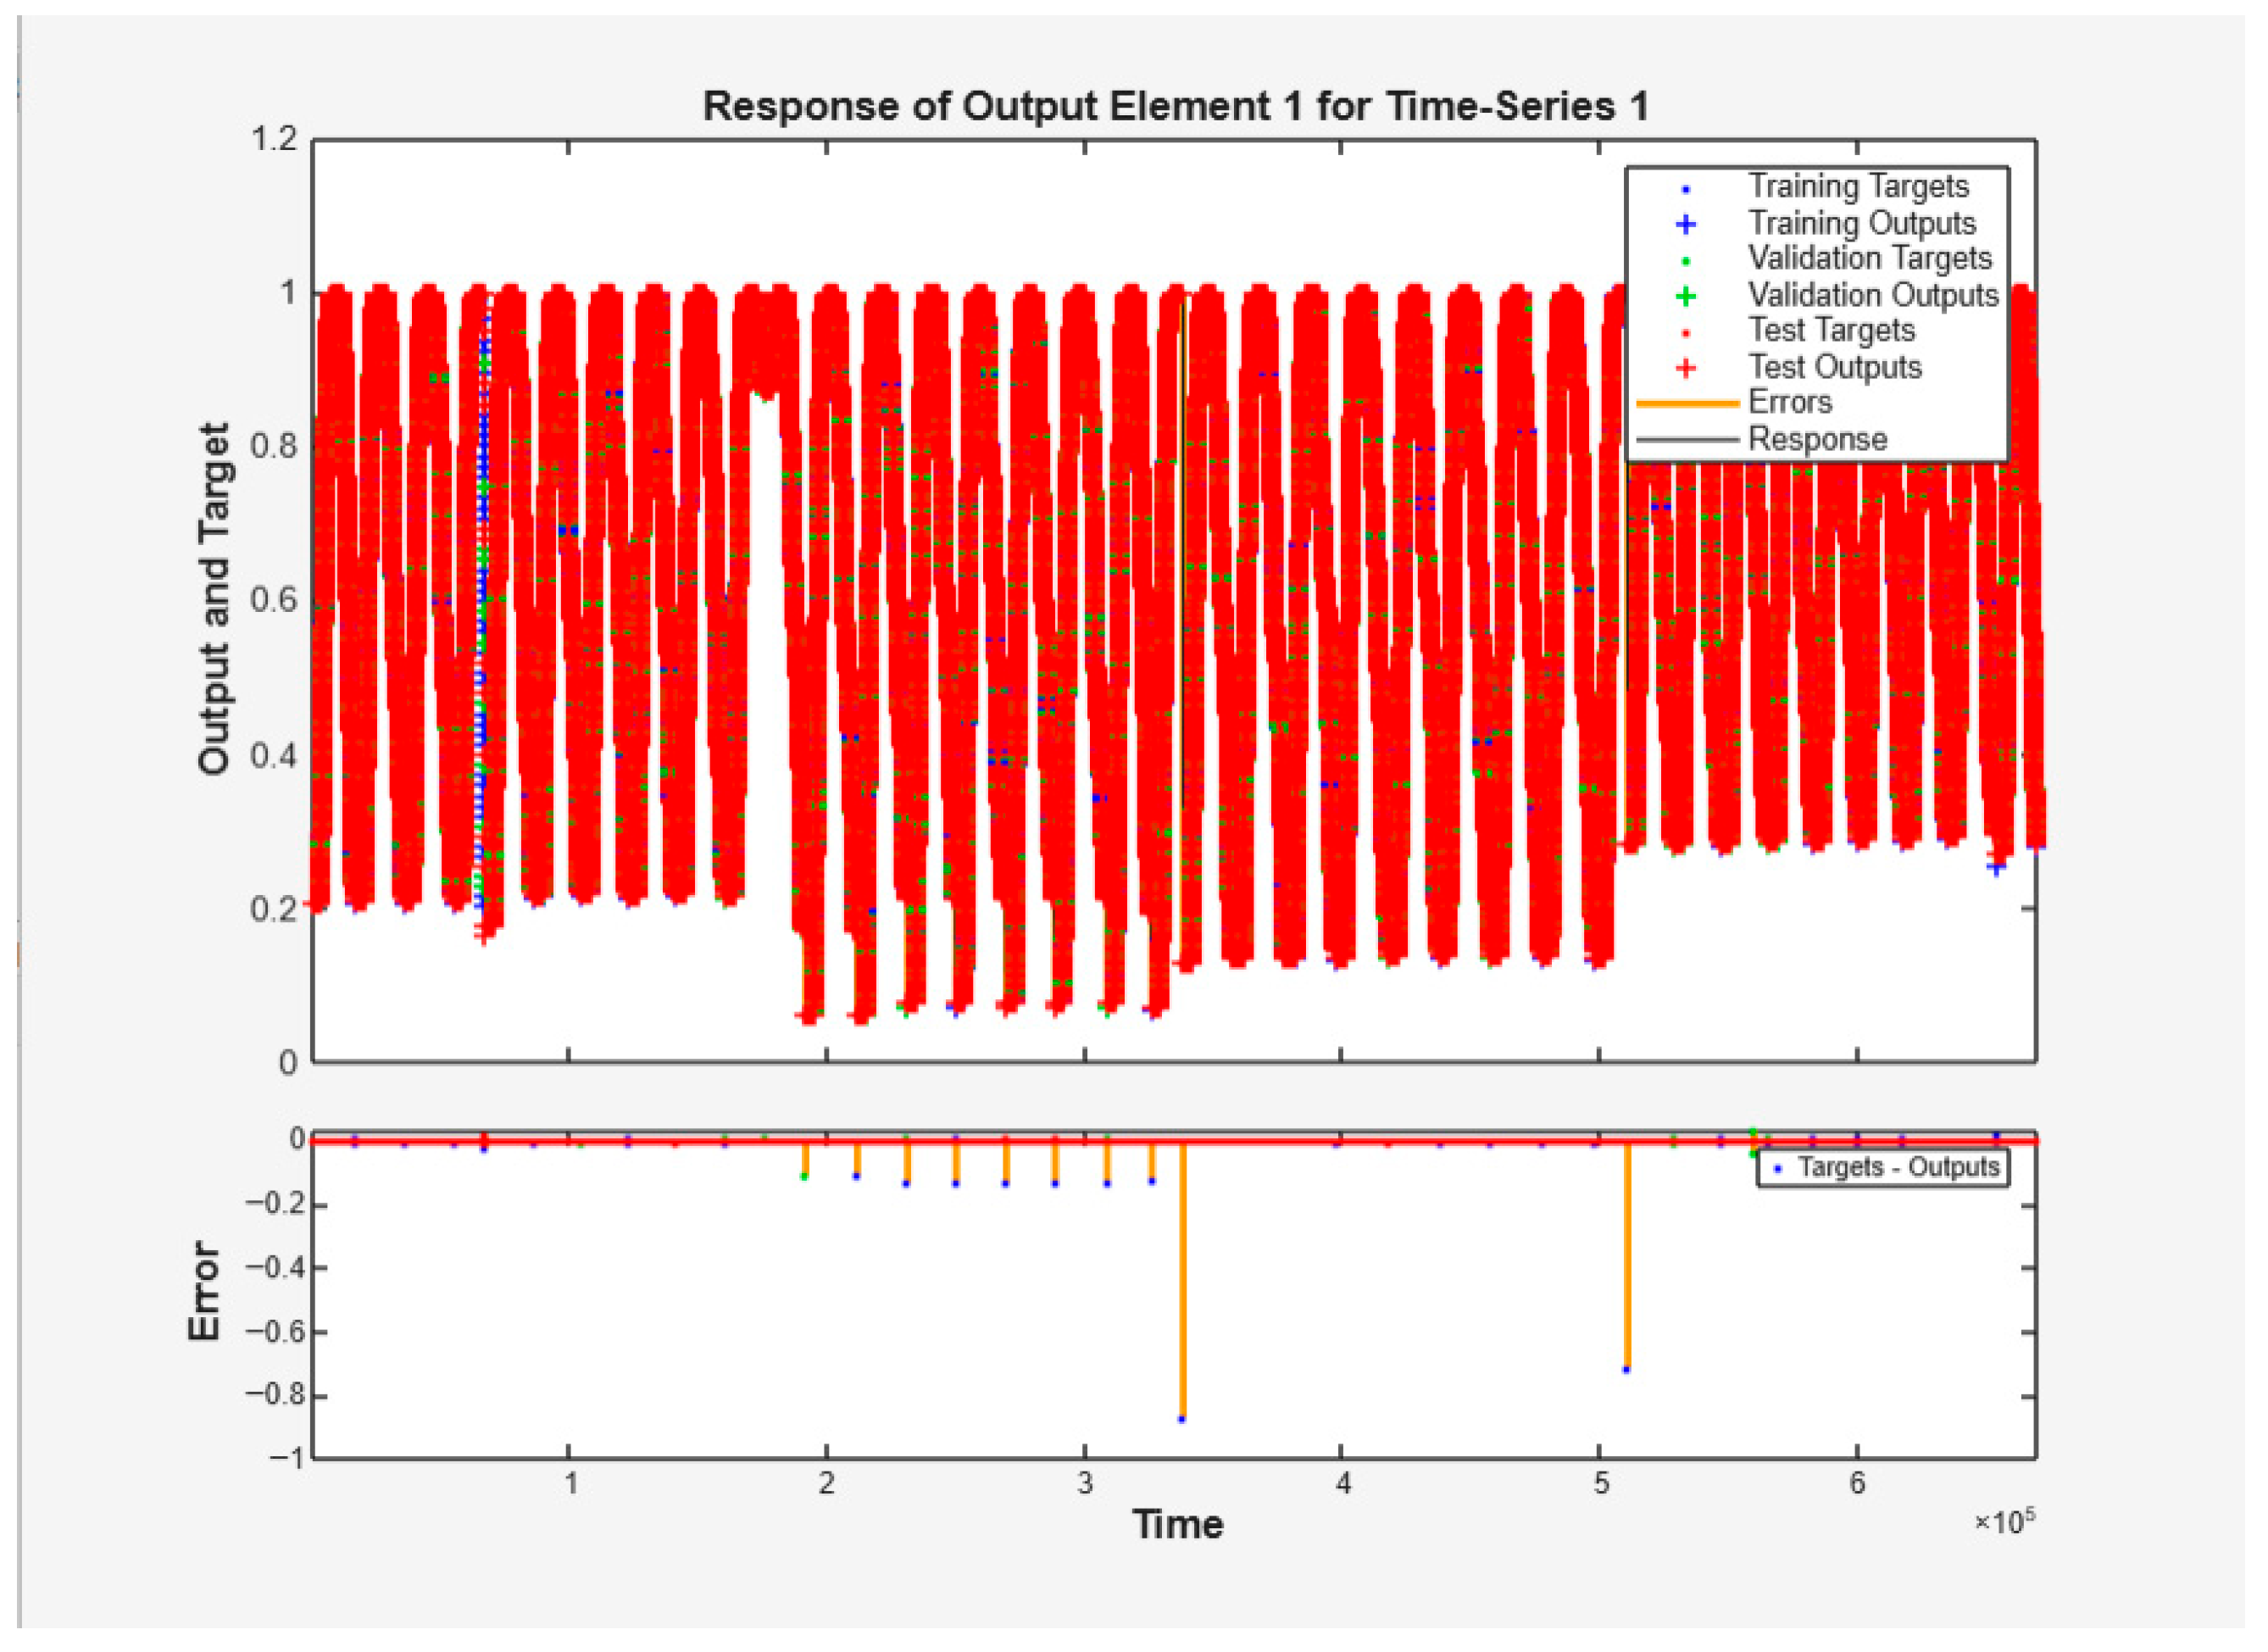
The time-series response plot in Figure 4 shows the network outputs closely following the targets over the whole horizon, with minor, bounded deviations. The error trace remains tight around zero with occasional brief spikes. This behavior indicates sound amplitude and phase tracking with limited drift or accumulation of error, in line with the overall accuracy and convergence characteristics.
Figure 4.
Time-series response and errors for the 10-neuron LM-NAR-FNN.
3.3. Nonlinear I/O FNN
All runs use the Nonlinear I/O topology. Three algorithms were tested: LM, BR, and SCG, with 10, 20, and 30 hidden neurons, respectively. The goal is to select the optimal neuron size within each optimizer and then determine the best optimizer overall.
3.3.1. LM Nonlinear I/O FNN
The 20-neuron LM-Nonlinear I/O-FNN is the best-performing configuration as per summarized results reported in Table 13 and Table 14. It delivers the lowest test MSE of 3.8568 × 10⁻⁴, the strongest convergence with the smallest final gradient, and maintains balanced behavior across training and validation sets. Although the generalization gap is slightly positive at 6.10%, it remains within acceptable bounds. The 10-neuron model offers the most computationally efficient option, completing training quickly with minimal compute cost and showing a near-zero generalization gap. Still, it falls short in predictive accuracy by 26.9% compared to the 20-neuron result. The 30-neuron model exhibits significant overfitting, with a large generalization gap of 73.7% and the worst test MSE, despite achieving the lowest training and validation errors. For this dataset and partition, the 20-neuron configuration offers the best balance of accuracy and convergence stability. The 10-neuron model is suitable when efficiency is the priority, while the 30-neuron variant should be avoided unless stronger regularization or revised data splits are applied.
Table 13.
Performance metrics for the LM-Nonlinear I/O-FNN.
Table 14.
Derived indicators for the LM-Nonlinear I/O-FNN.
3.3.2. BR Nonlinear I/O FNN
The 30-neuron BR-Nonlinear I/O-FNN is the best-performing model, offering the lowest MSE test error 3.7017 × 10⁻⁴, a 19.9% improvement over 10 neurons and 0.6% over the 20-neuron setup, robust convergence, and effective regularization as detailed in Table 15 and Table 16. The 20-neuron model is a close second, providing nearly equal accuracy at lower cost, making it an appealing compromise when efficiency matters. The 10-neuron model remains the most economical and converges cleanly but shows higher test error, making it suitable only for scenarios where speed and low computational load are prioritized over accuracy.
Table 15.
Performance metrics for the BR-Nonlinear I/O-FNN.
Table 16.
Derived indicators for the BR-Nonlinear I/O-FNN.
3.3.3. SCG Nonlinear I/O FNN
The 30-neuron SCG Nonlinear I/O FNN is the best-performing configuration, achieving the lowest test MSE of 5.3874 × 10⁻⁴, with stable convergence and reliable generalization of +0.57% as seen in Table 17 and Table 18. The 20-neuron model offers no meaningful improvement over the 10-neuron variant while requiring over three times the compute, making it inefficient. The 10-neuron model remains attractive when low compute and fast training are the priority, but it trails the 30-neuron accuracy by a small yet consistent margin. Therefore, select 30 neurons for best accuracy in the SCG Nonlinear I/O FNN group, use 10 neurons when efficiency matters most, and avoid 20 neurons unless architecture constraints demand it.
Table 17.
Performance metrics for the SCG-Nonlinear I/O-FNN.
Table 18.
Derived indicators for the SCG-Nonlinear I/O-FNN.
3.3.4. Optimal Nonlinear I/O FNN Model
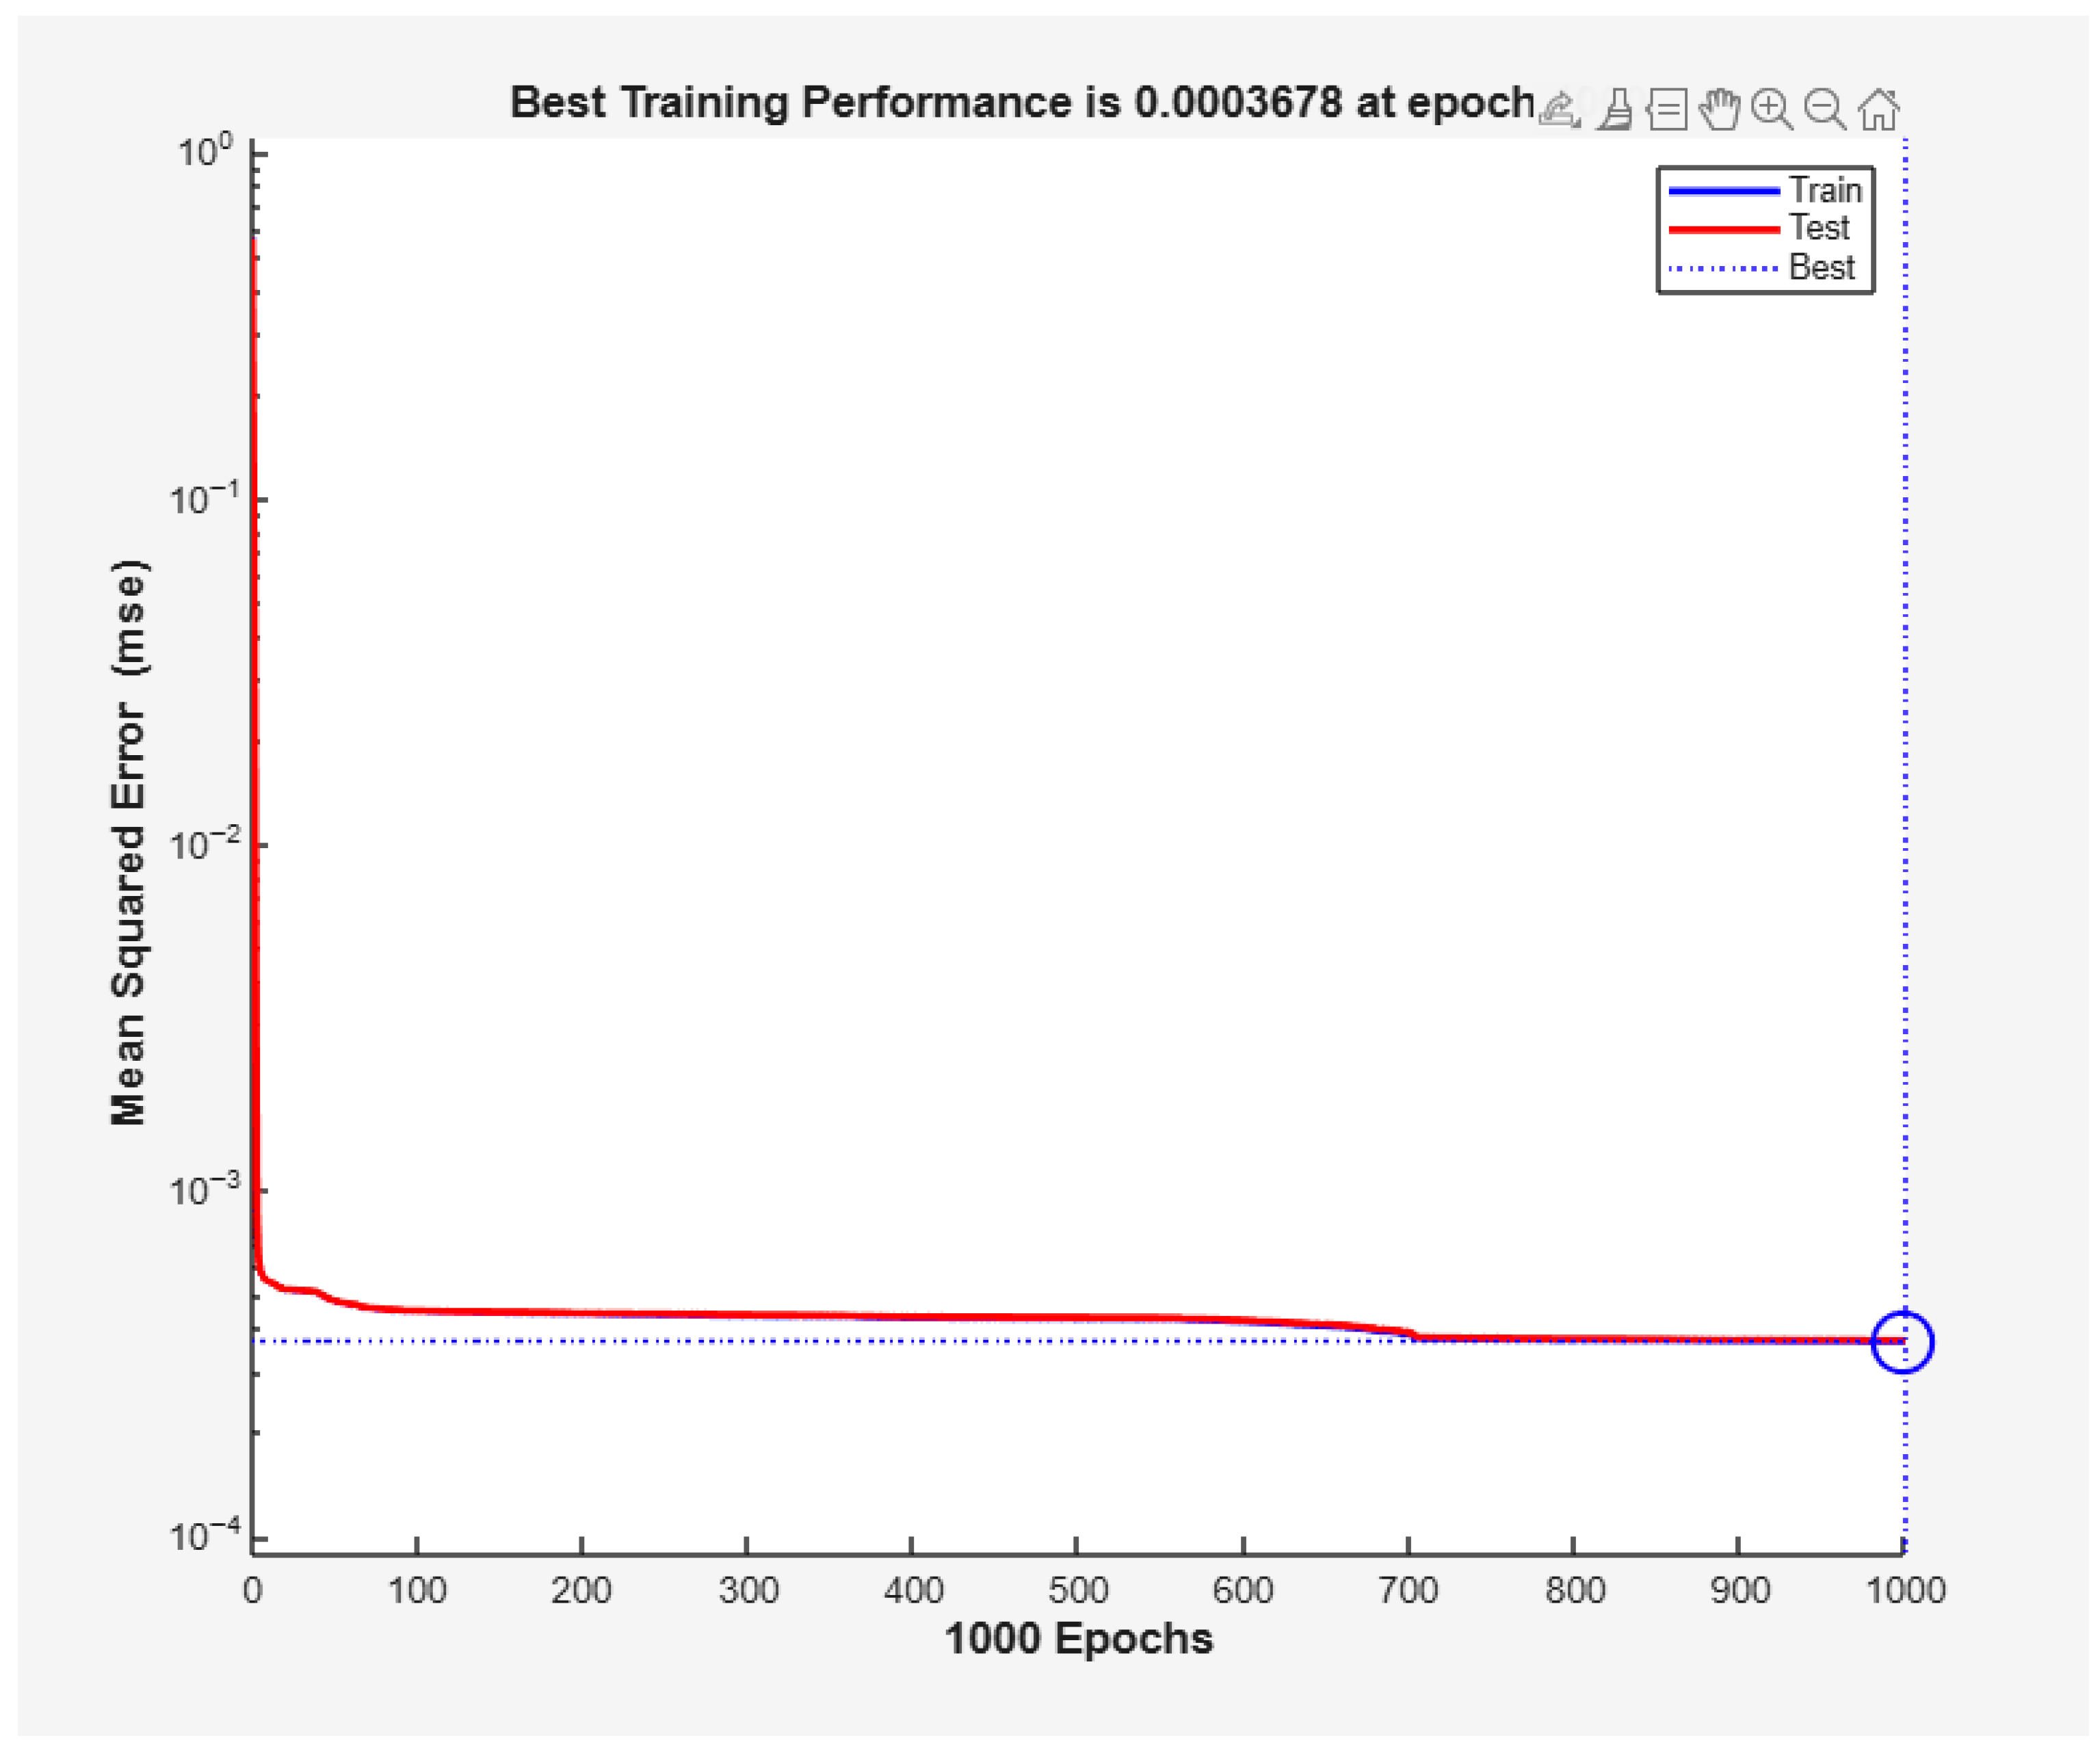
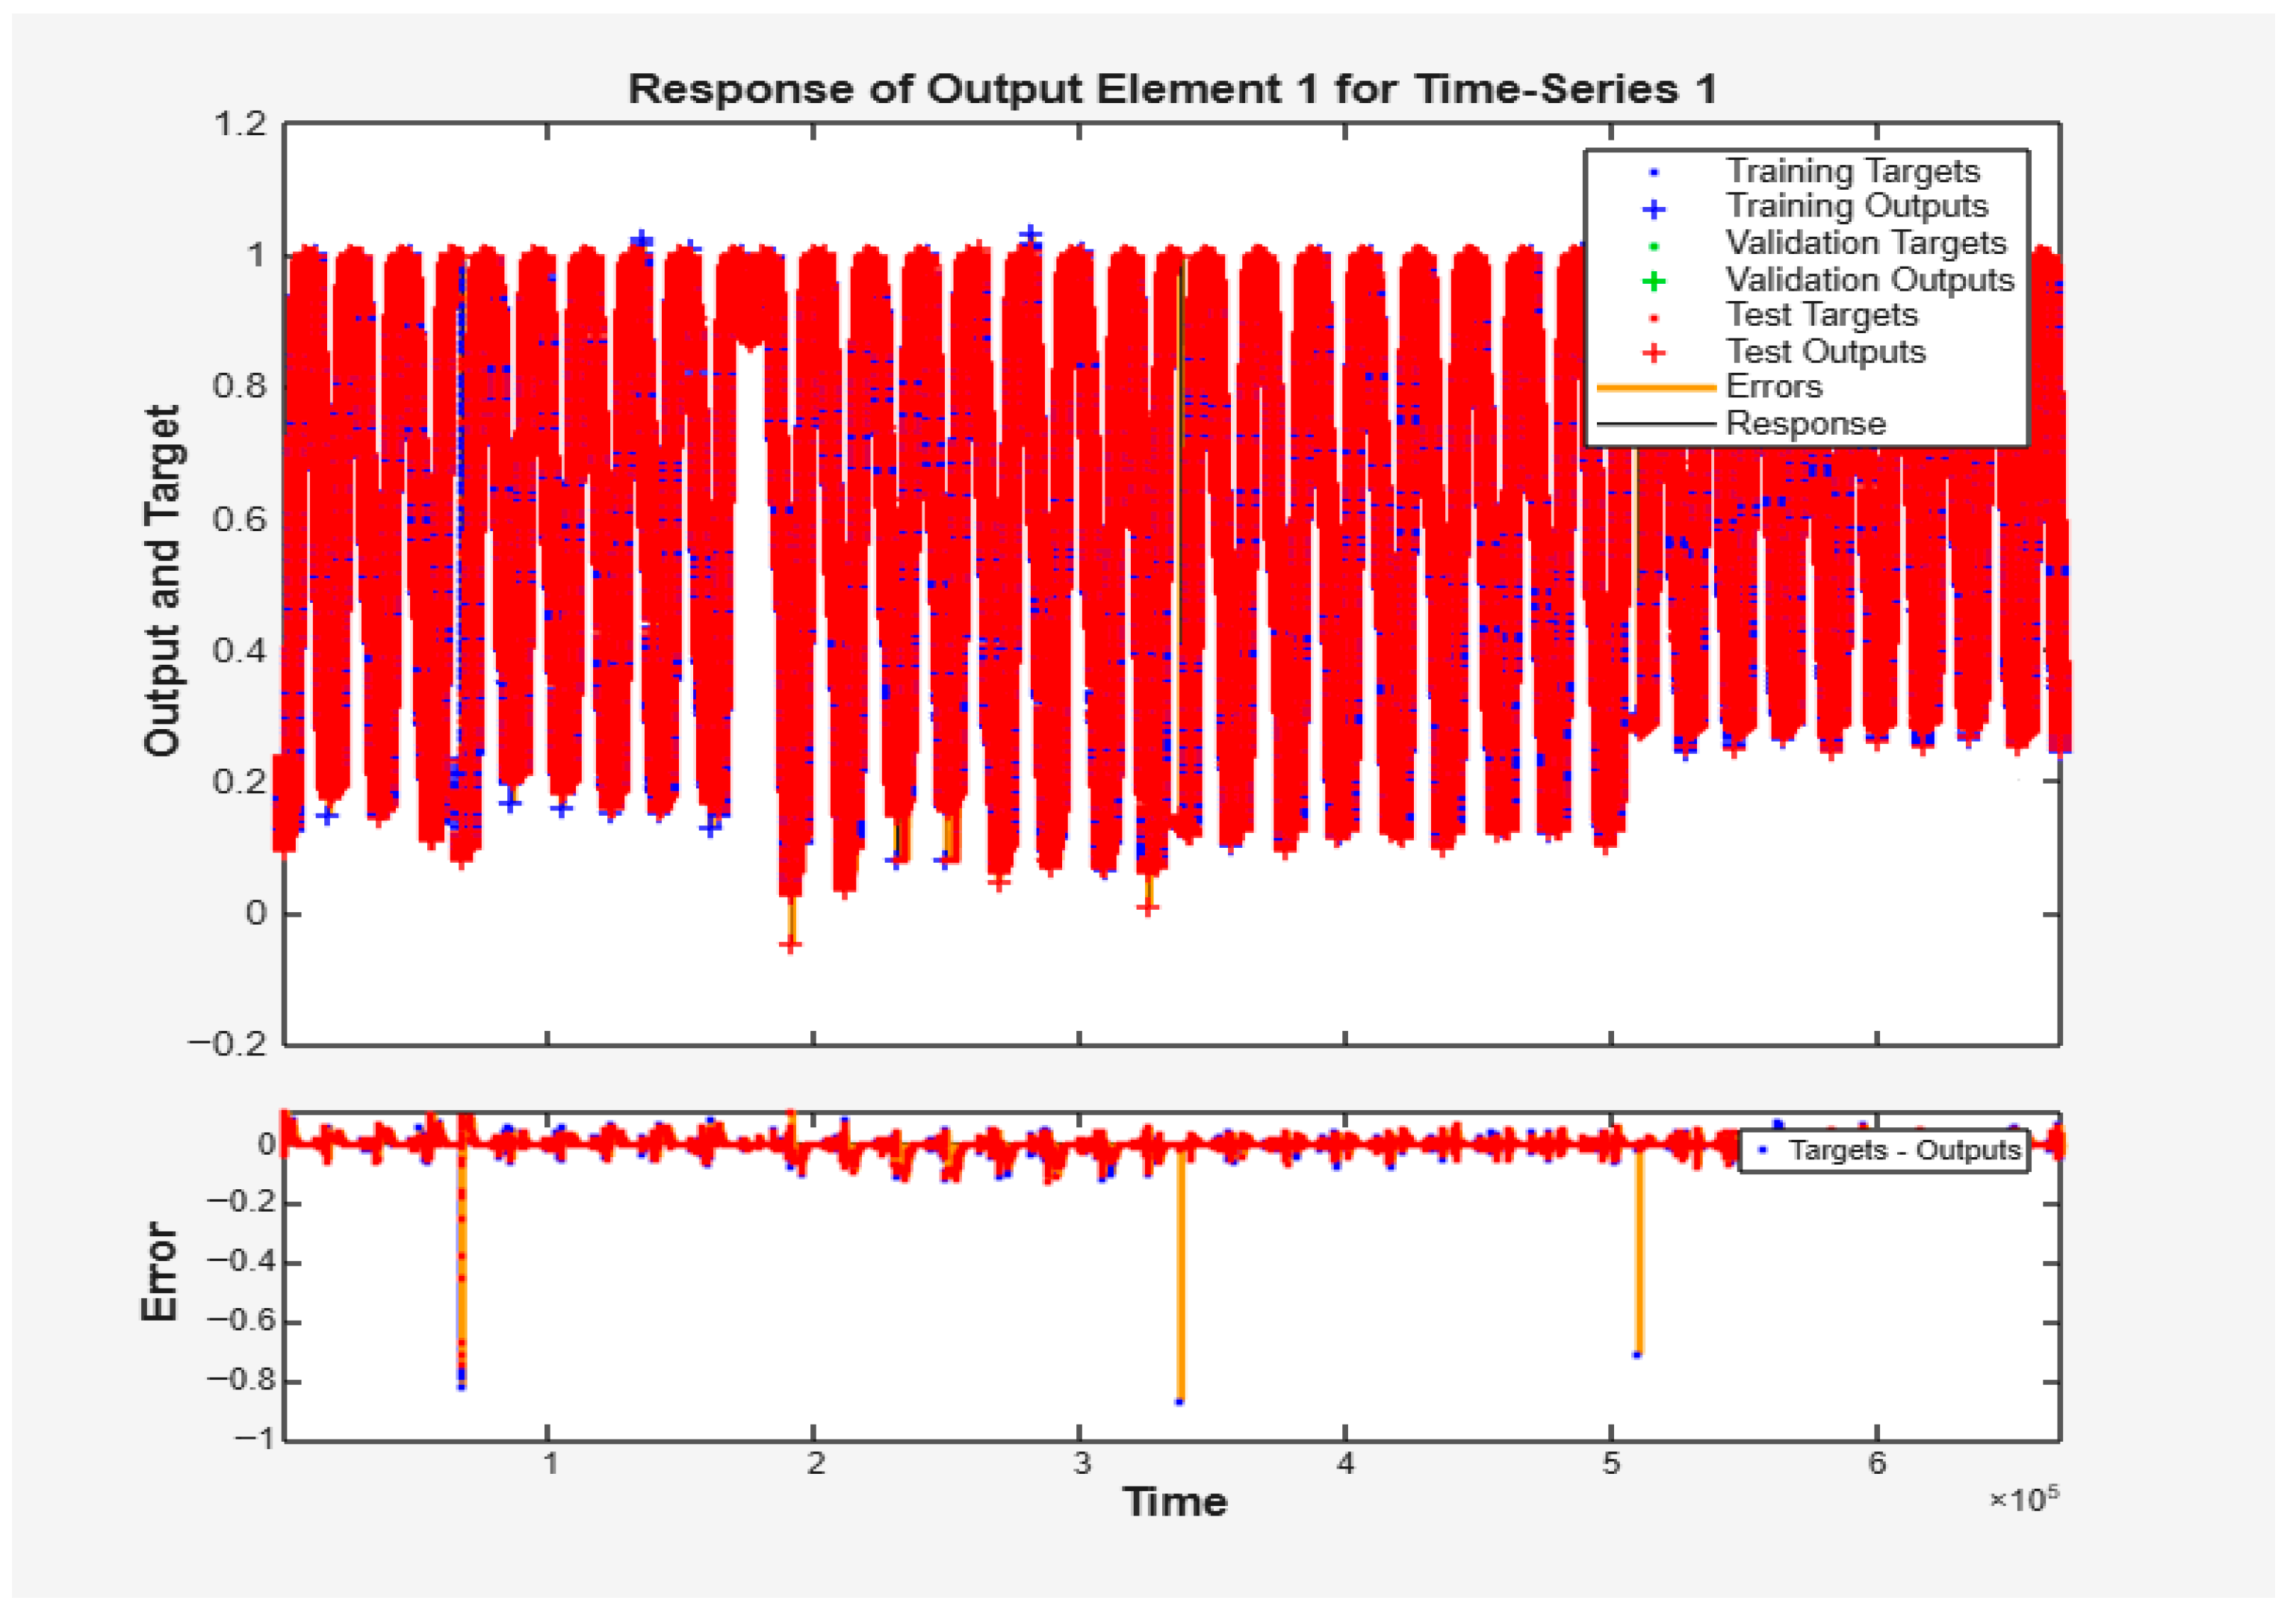
Across all tested configurations and training algorithms, the 30-neuron BR–Nonlinear I/O FNN stands out as the optimal model. It achieves the lowest test MSE at 3.7017 × 10⁻⁴, demonstrates the highest regularization efficiency with a sum of squared parameters equal to 8.22 × 10³, and maintains high predictive consistency with a test R value of 0.9983 and a generalization gap of +0.6%. Convergence is strong, and although its compute cost is the highest at 3.27 times the baseline. The performance curve in Figure 5, which plots MSE against epochs, shows a sharp drop in error during the initial training phase, followed by a prolonged plateau where both training and test losses settle in the mid-10−4 range. The best training performance marker at 3.66 × 10⁻⁴ aligns with the final training MSE as shown in Table 15, and the close alignment of the test curve reflects the small generalization gap of +0.6% as shown in Table 16. The absence of a validation curve is expected for Bayesian Regularization. The continued overlap between the training and test lines, along with the flattening trend in later epochs, suggests that overfitting does not occur and that further training yields only minor improvements. The time-series response plot in Figure 6 shows that the predicted outputs closely follow the target values across the whole-time horizon, with only minor and bounded deviations. In the lower panel, the error stays tightly clustered around zero, with occasional short spikes that do not accumulate over time. This pattern aligns with the low test MSE of 3.7017 × 10⁻⁴ reported in Table 15, the small positive generalization gap of +0.6% shown in Table 16, and the consistently high R = 0.9983 values across all data splits in Table 15. Overall, the model effectively captures the main system dynamics with accurate amplitude and phase tracking. The remaining differences are more likely due to measurement noise or rare outliers rather than consistent model error.
Figure 5.
Performance curve for the 30-neuron BR-Nonlinear I/O-FNN.
Figure 6.
Time-series response and errors for the 30-neuron BR-Nonlinear I/O-FNN.
3.4. NARX FNN
All runs use the NARX topology. Three algorithms were tested: LM, BR, and SCG, with 10, 20, and 30 hidden neurons each. The goal is to select the optimal neuron size within each optimizer and then determine the best optimizer overall.
3.4.1. LM NARX FNN
The 20-neuron LM-NARX FNN is the optimal configuration, offering the lowest test MSE of 1.6210 × 10⁻⁷, minimal of just 0.6× relative to the baseline, and the shortest training time, as seen in Table 19 and Table 20. The 10-neuron model ranks second, providing good accuracy at baseline cost and solid convergence. The 30-neuron model, while showing excellent internal optimization, fails to generalize effectively and incurs the highest computational load.
Table 19.
Performance metrics for the LM-NARX-FNN.
Table 20.
Derived indicators for the LM-NARX-FNN.
3.4.2. BR NARX FNN
The 10-neuron BR-NARX-FNN is the top performer in terms of test MSE, as shown in Table 21 and Table 22. It achieves the best accuracy of 1.3028 × 10⁻⁷, clean convergence by a final gradient of 9.67 × 10⁻⁸, and effective shrinkage at the lowest computational cost. The 20-neuron variant is more expensive and performs worse, whereas the 30-neuron setting overfits drastically and is not viable for generalization. For current data splits, 10 neurons are preferred.
Table 21.
Performance metrics for the BR-NARX-FNN.
Table 22.
Derived indicators for the BR-NARX-FNN.
3.4.3. SCG-NARX-FNN
The 10-neuron SCG-NARX-FNN remains the best configuration as per summarized results reported in Table 23 and Table 24, and considering test MSE as the primary performance metric. It delivers the lowest test error of 7.4190 × 10⁻⁷, fastest training time of 311 s, and lowest computing cost of 1.00× relative to baseline, while maintaining strong convergence with final gradient of 1.13 × 10⁻⁵. By contrast, both the 20- and 30-neuron models show inferior test accuracy and substantially higher computational demands. Under the current partition, the 10-neuron model is clearly optimal, balancing accuracy, efficiency, and convergence most effectively.
Table 23.
Performance metrics for the SCG-NARX-FNN.
Table 24.
Derived indicators for the SCG-NARX-FNN.
3.4.4. Optimal NARX FNN Model
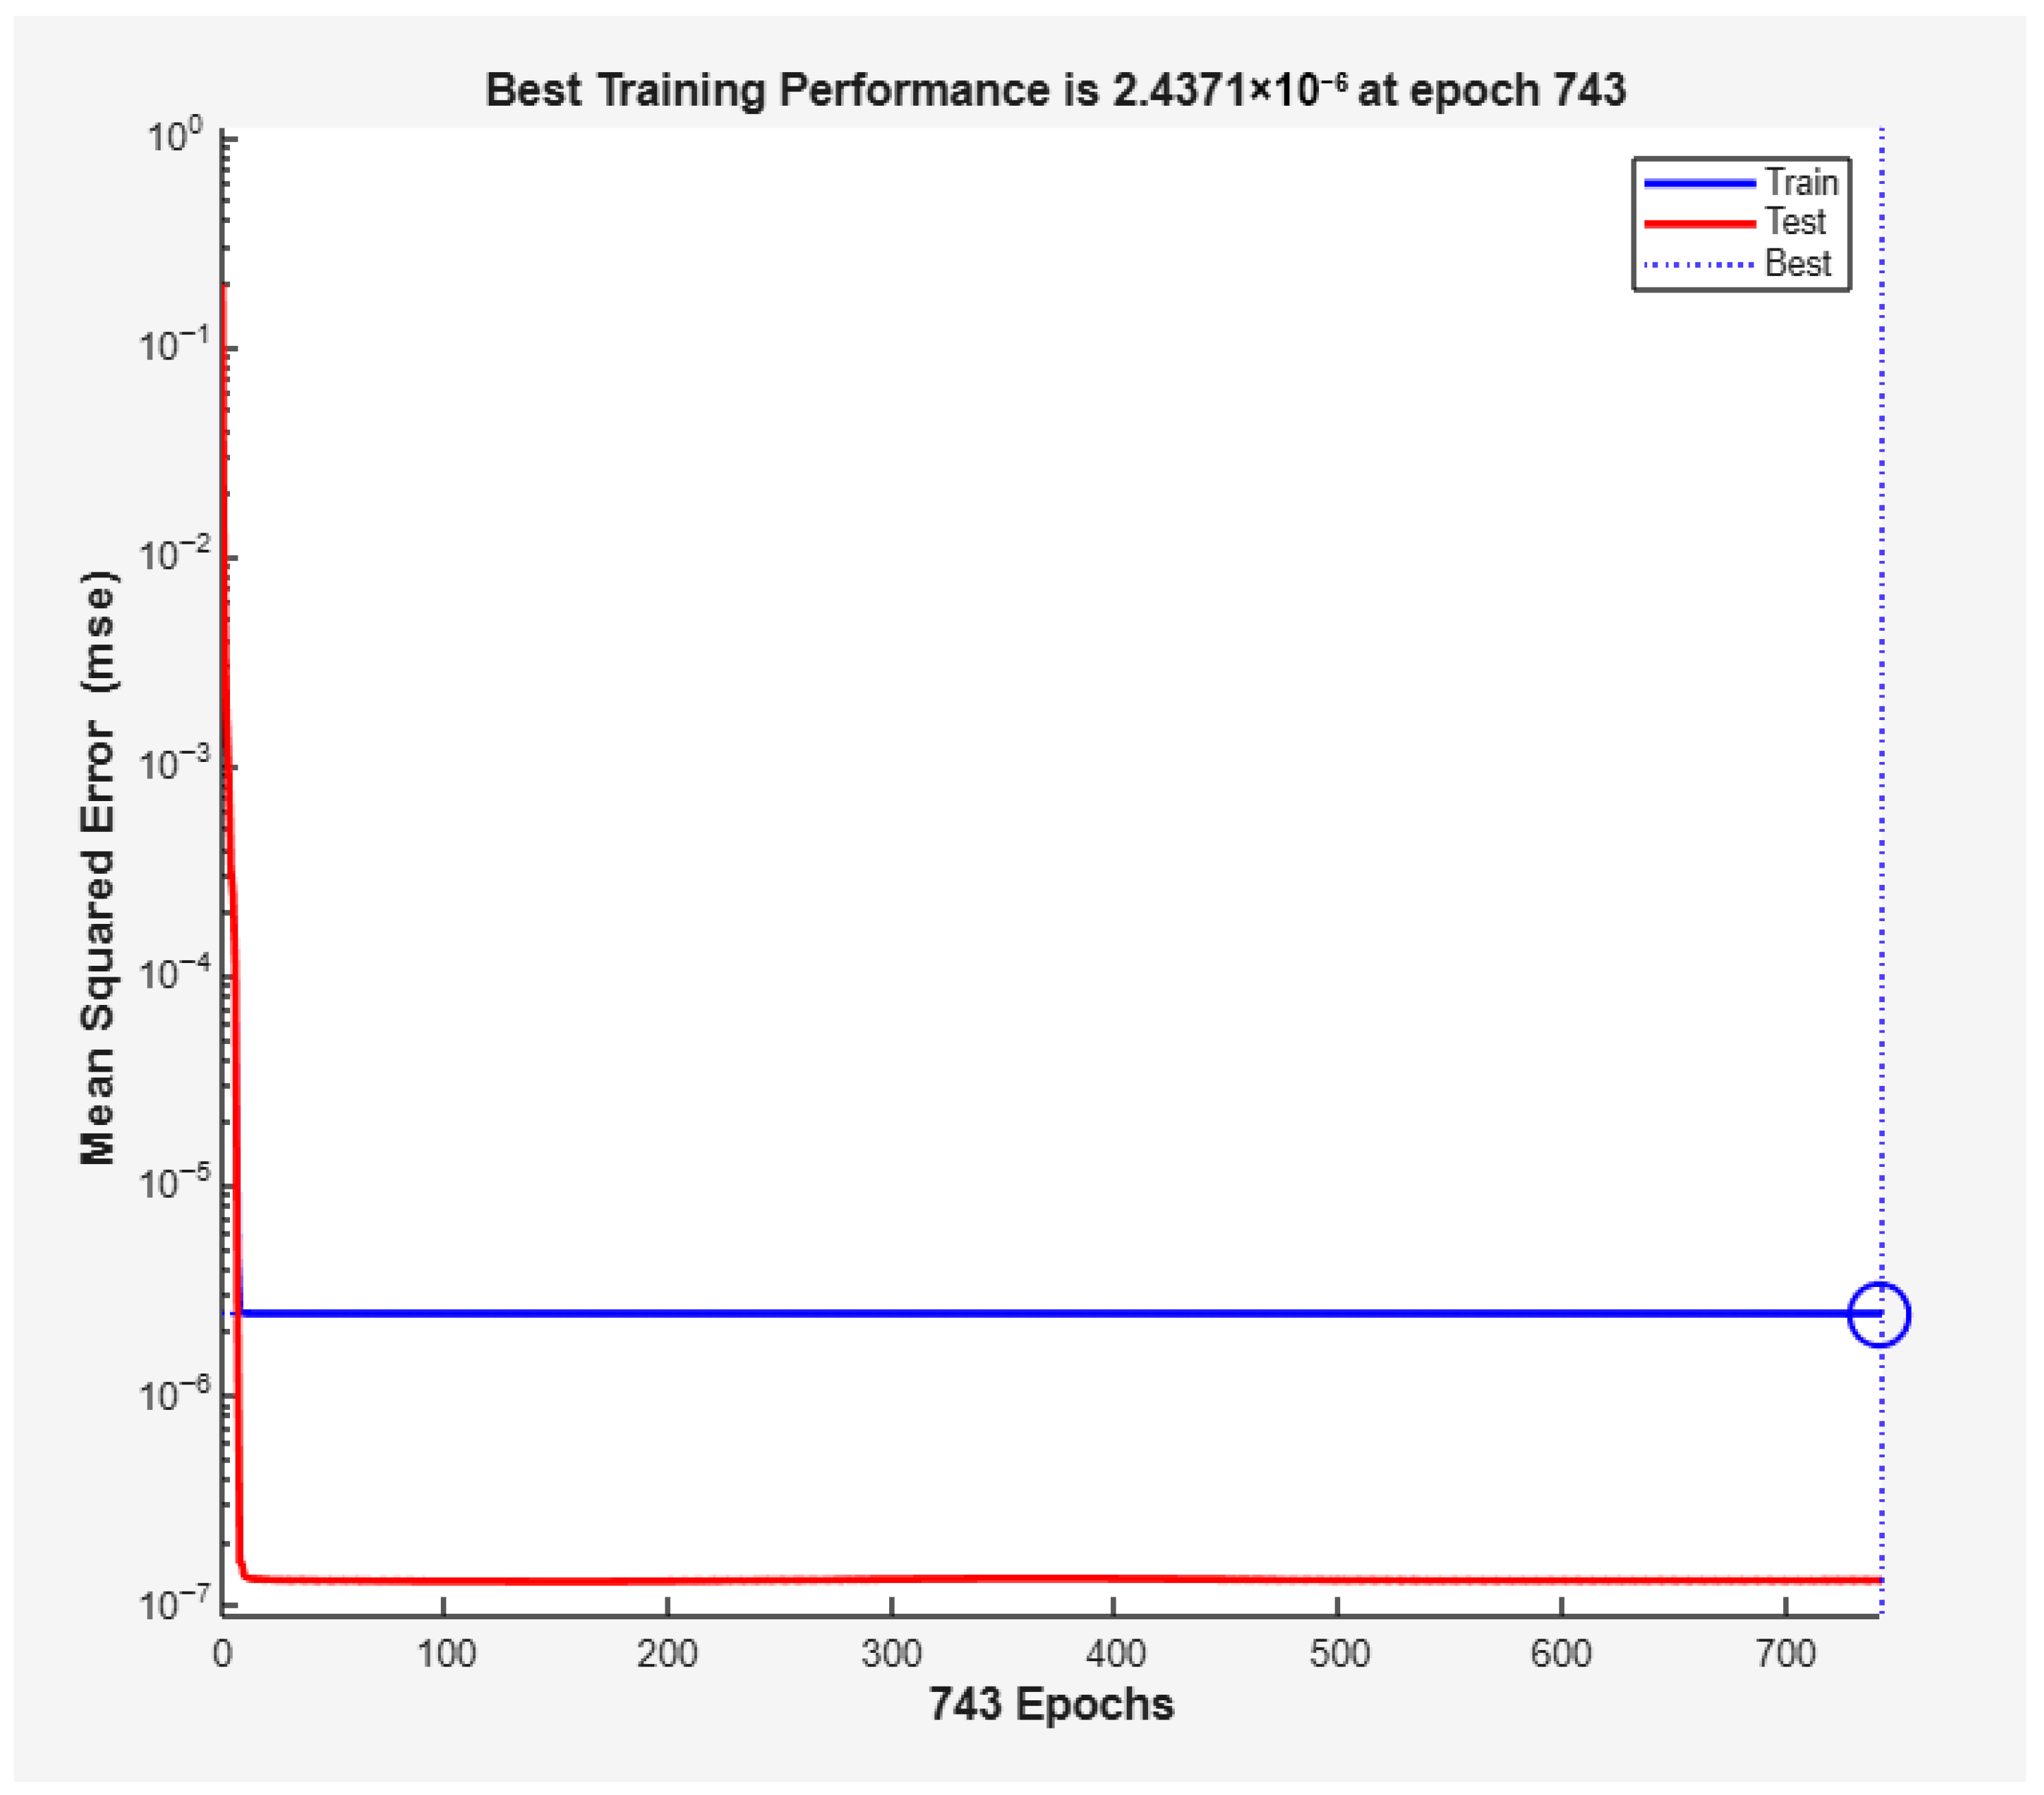
Across all NARX-FNN configurations tested, the 10-neuron BR-NARX-FNN emerges as the optimal model, achieving the lowest test MSE of 1.3028 × 10⁻⁷ and a perfect test R of 1.0000, as shown in Table 21 and Table 22. It also delivers robust convergence, with a final gradient of 9.67 × 10⁻⁸ and μ value of 500, a strong weight shrinkage signal with sum squared parameters of 9.95, and the lowest compute cost of 1.0× relative to baseline, completing training in under 10 min. The performance plot in Figure 7 shows a sharp drop in error during the early phase of training, followed by a long stretch where the error remains nearly flat. The best training performance is reached at epoch 743 with an MSE of 2.4371 × 10⁻⁶, which matches the value reported in Table 21. The test curve stays consistently below the training curve. It remains steady throughout, which corresponds to the very low test MSE of 1.3028 × 10⁻⁷ and the intensely negative generalization gap of −94.7% shown in Table 22. This behavior typically suggests that the test set is either easier or contains less noise, rather than the model genuinely outperforming its training. The flattening of both curves in the later stages indicates that further training brings slight improvement, which is in line with the strong convergence behavior reported.
Figure 7.
Performance curve for the 10-neuron BR-NARX-FNN.
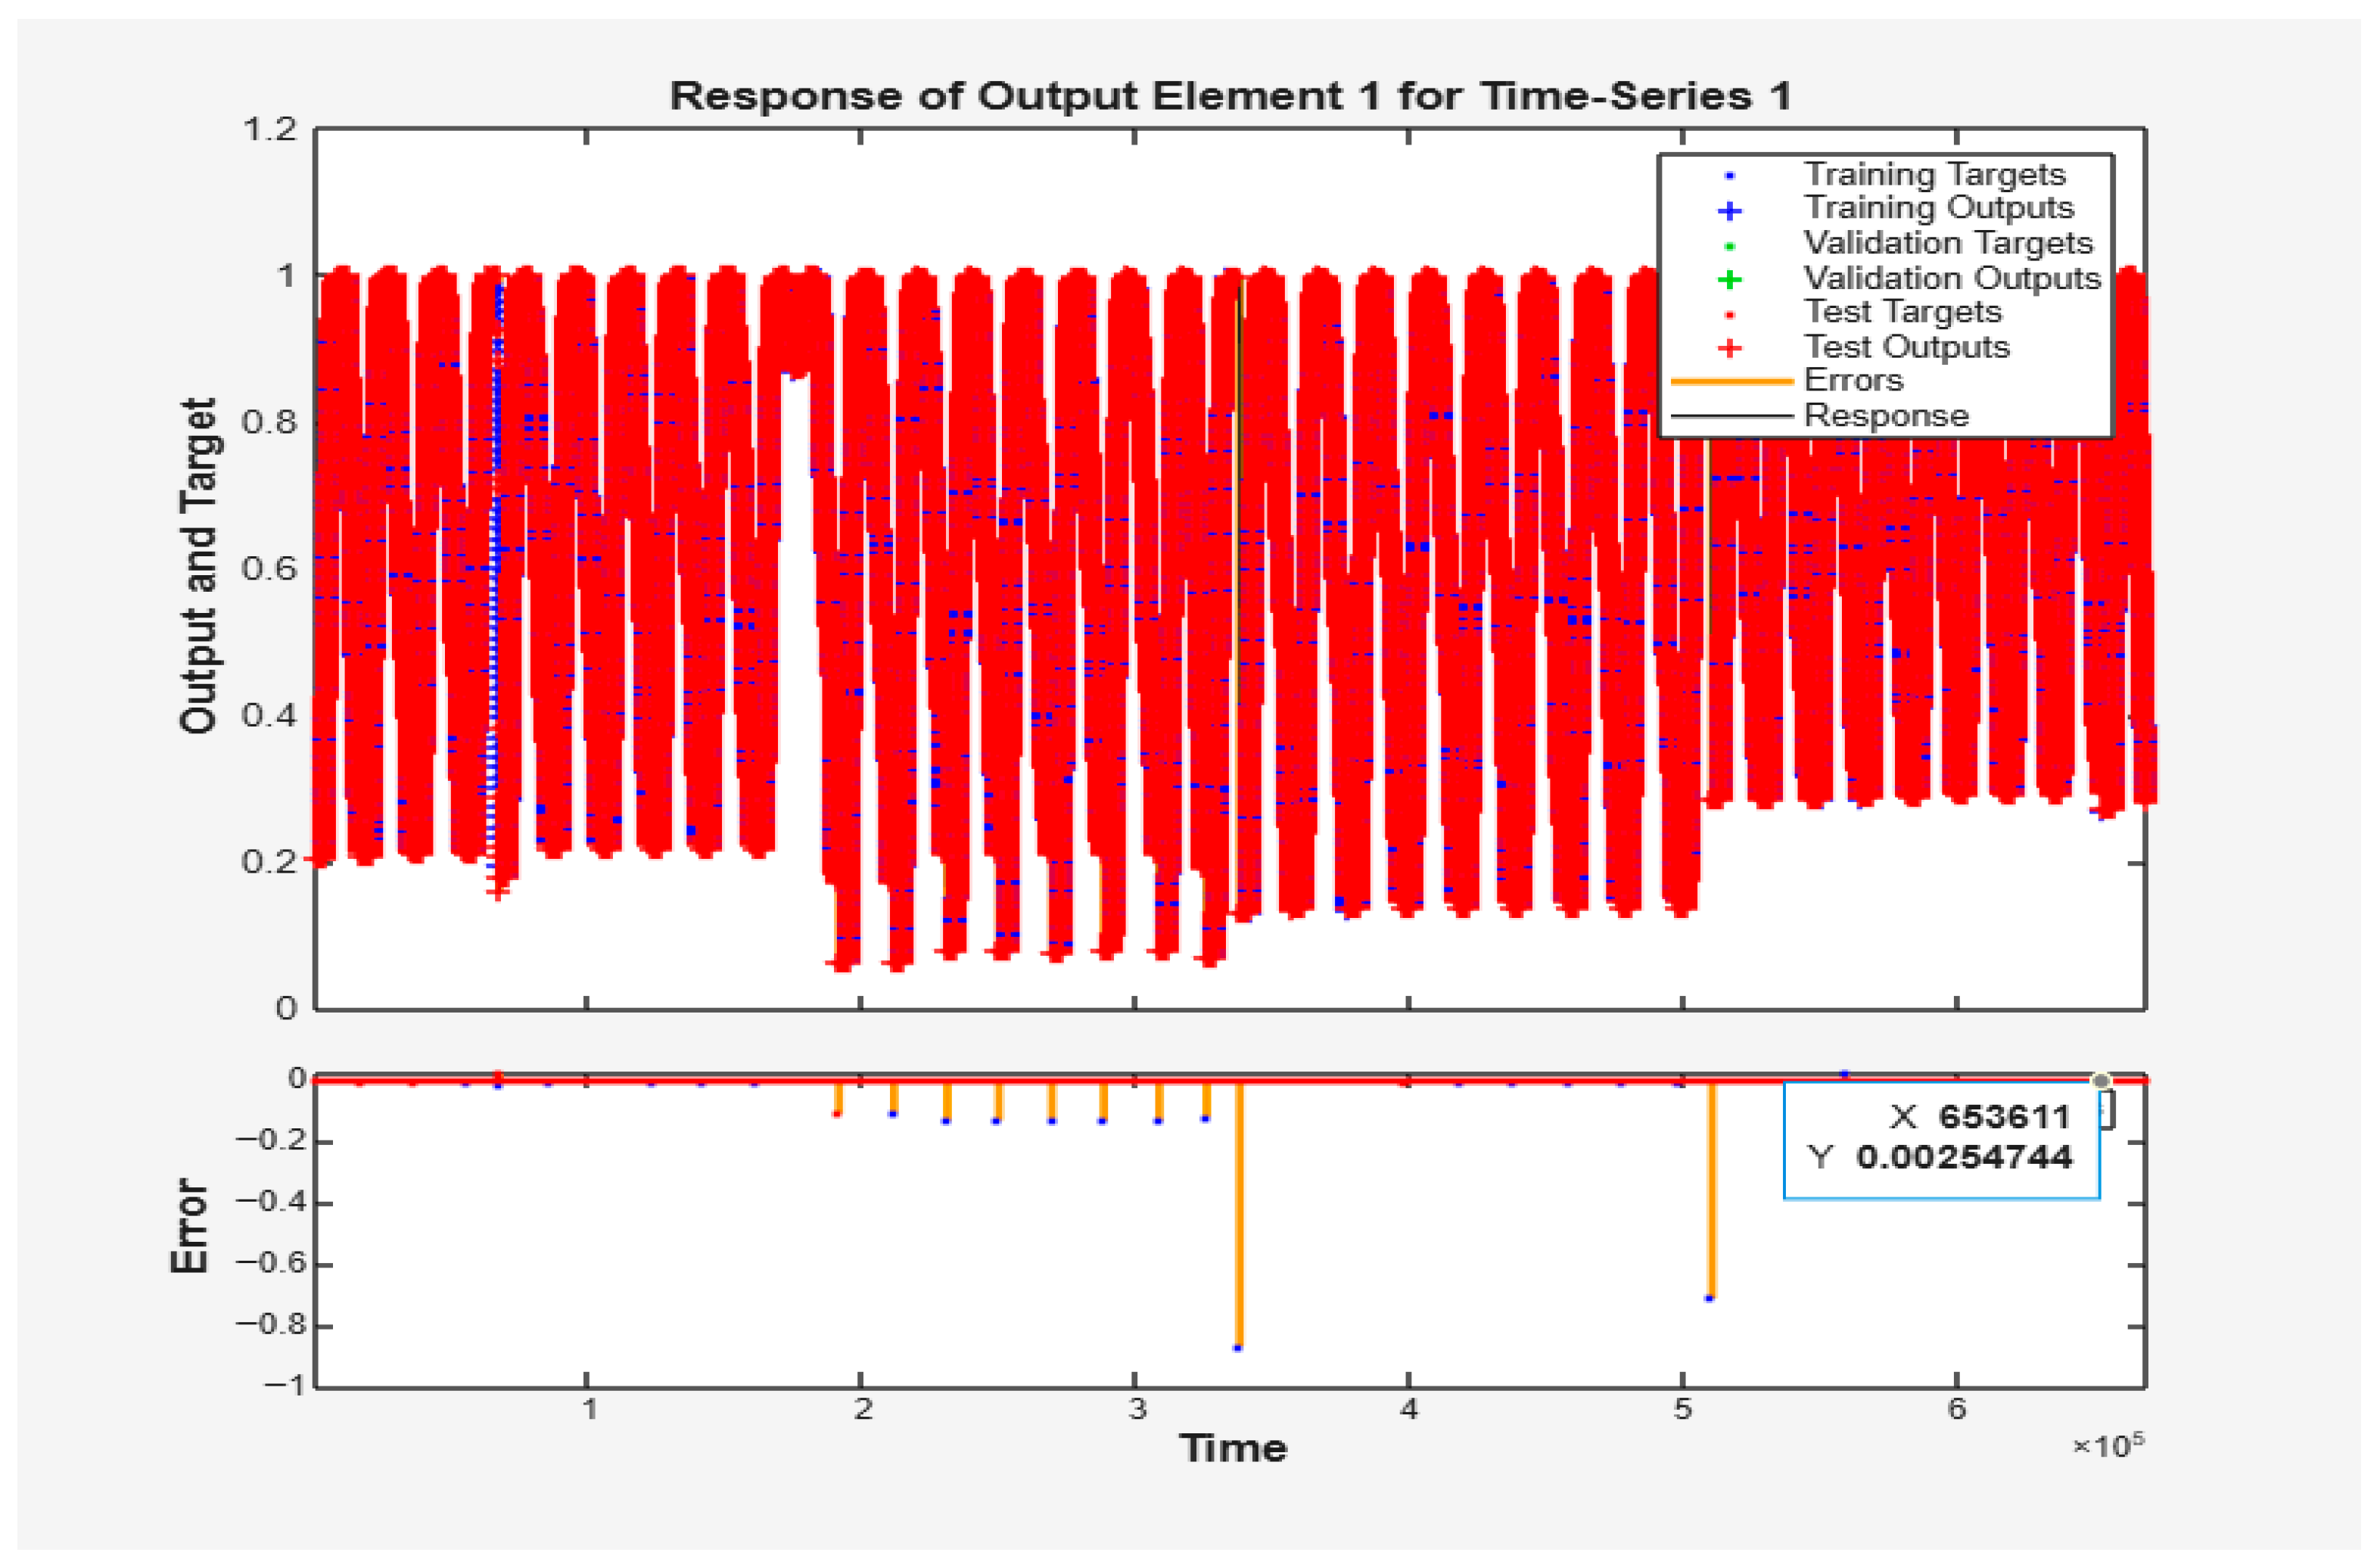
The time-series response in Figure 8 shows that the model’s output follows the target values closely across the entire time range, with only minor and controlled deviations. In the lower panel, the residuals stay centered around zero and show just a few brief spikes, without any signs of drift or buildup over time. This matches the low test MSE of 1.3028 × 10⁻⁷ and the strongly negative generalization gap of −94.7%, as shown in Table 21 and Table 22. The model tracks both the size and timing of the target signal well. The small differences are likely due to measurement noise or occasional outliers, rather than any consistent model error.
Figure 8.
Time-series response and errors for the 10-neuron BR-NARX-FNN.
3.5. GRU Model
As shown in Table 25, the dataset was split into three parts: training with about 1.88 million samples, validation with around 0.40 million, and test with approximately 0.40 million. The error metrics are very similar across all splits, with MSE values around 2.3 to 2.4 × 10⁻³ and RMSE close to 4.8 × 10⁻². The correlation values are also consistent, with R near 0.998 and R2 around 0.995. This strong agreement across splits suggests that the GRU model generalizes well and does not overfit, maintaining reliable performance on unseen data.
Table 25.
Data split and basic performance statistics for the GRU model.
Table 26 presents the architectural and training settings used for the GRU model. The network includes two GRU layers with 256 and 128 units, followed by a fully connected layer. This setup allows the model to capture temporal patterns over a window of 80 samples, with a stride of 20, resulting in 75% overlap. Training uses the Adam optimizer, starting with a learning rate of 0.002, which is reduced by a factor of 0.2 after epoch 40. A global gradient clipping threshold of 5 is applied to improve training stability, and dropout at 10% helps prevent overfitting. Input features are standardized using Z-score normalization, while the targets are scaled to the range from −1 to 1. Early stopping with a patience of 10 epochs selected the final model at epoch 17, keeping the total training time around 59 min.
Table 26.
Hyperparameters and training settings for the GRU model.
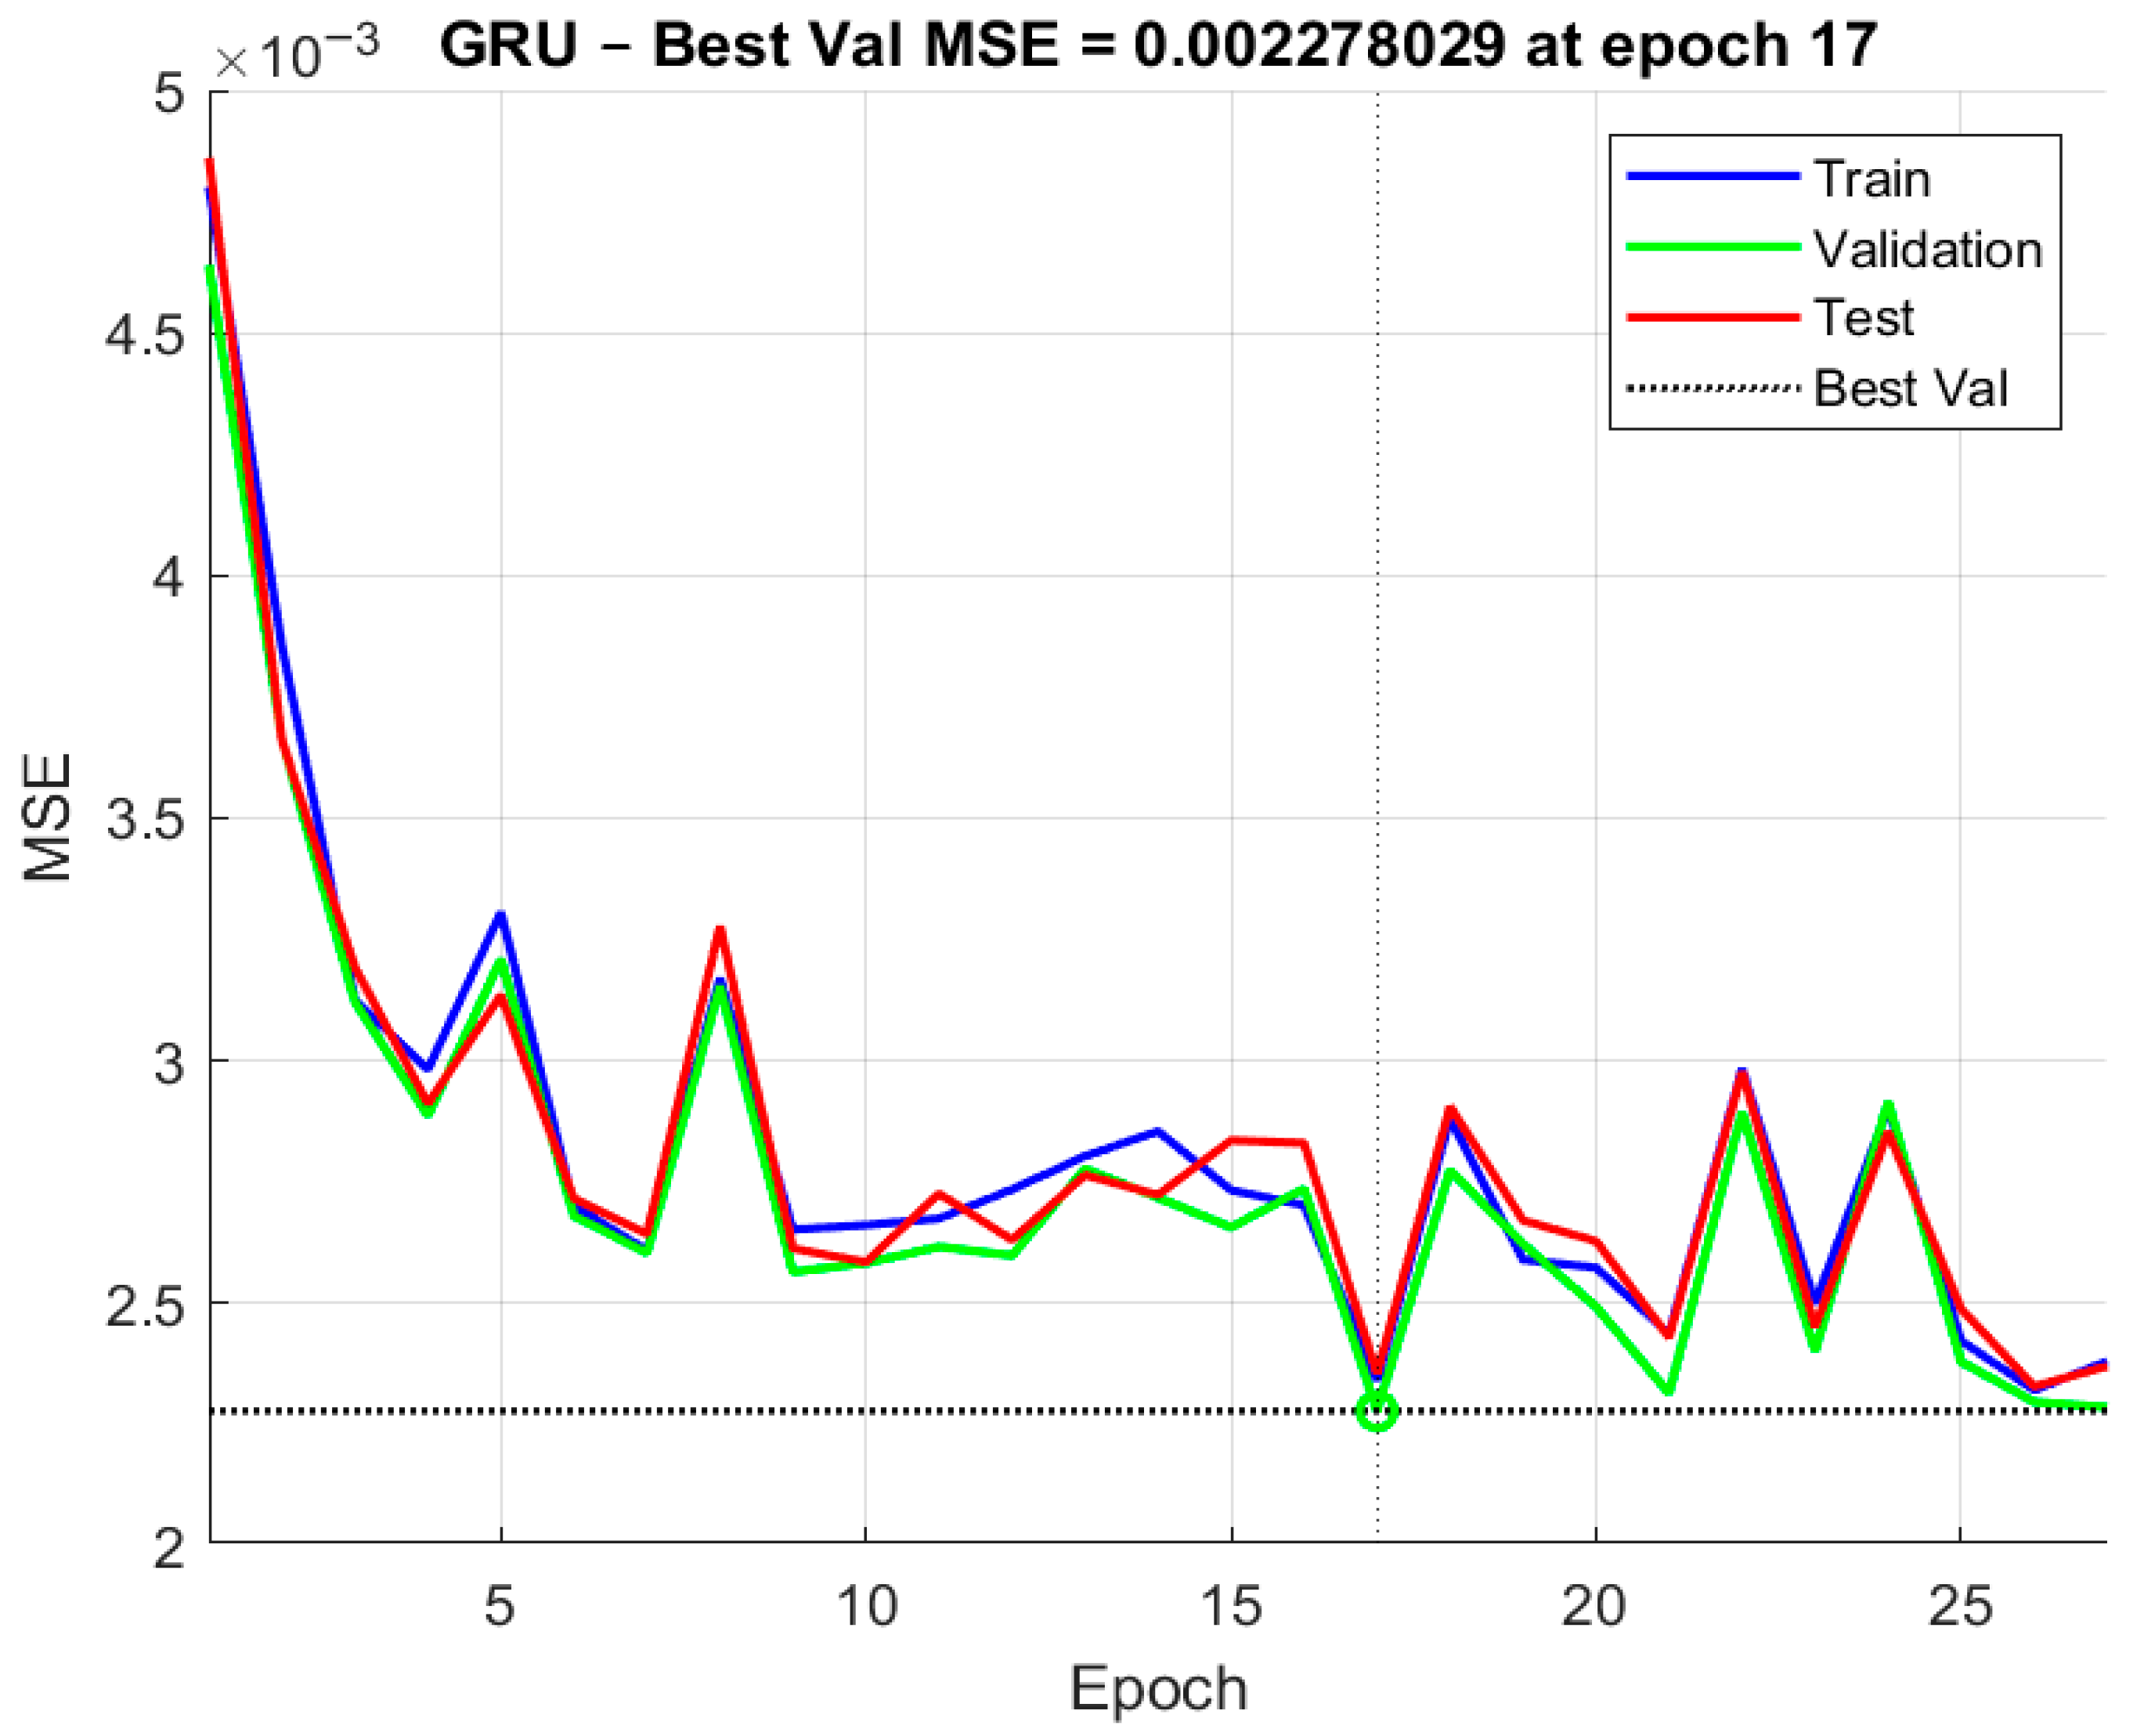
Figure 9 shows the MSE plotted against epochs. The error drops sharply during the first few epochs and then stabilizes, fluctuating within a narrow range of about 2.3 to 3.2 × 10⁻³. The lowest validation MSE is reached at epoch 17, which matches the point chosen by early stopping. The training, validation, and test curves remain very close to each other, indicating a minimal generalization gap and consistent performance across all data splits.
Figure 9.
Performance curve for the GRU model.
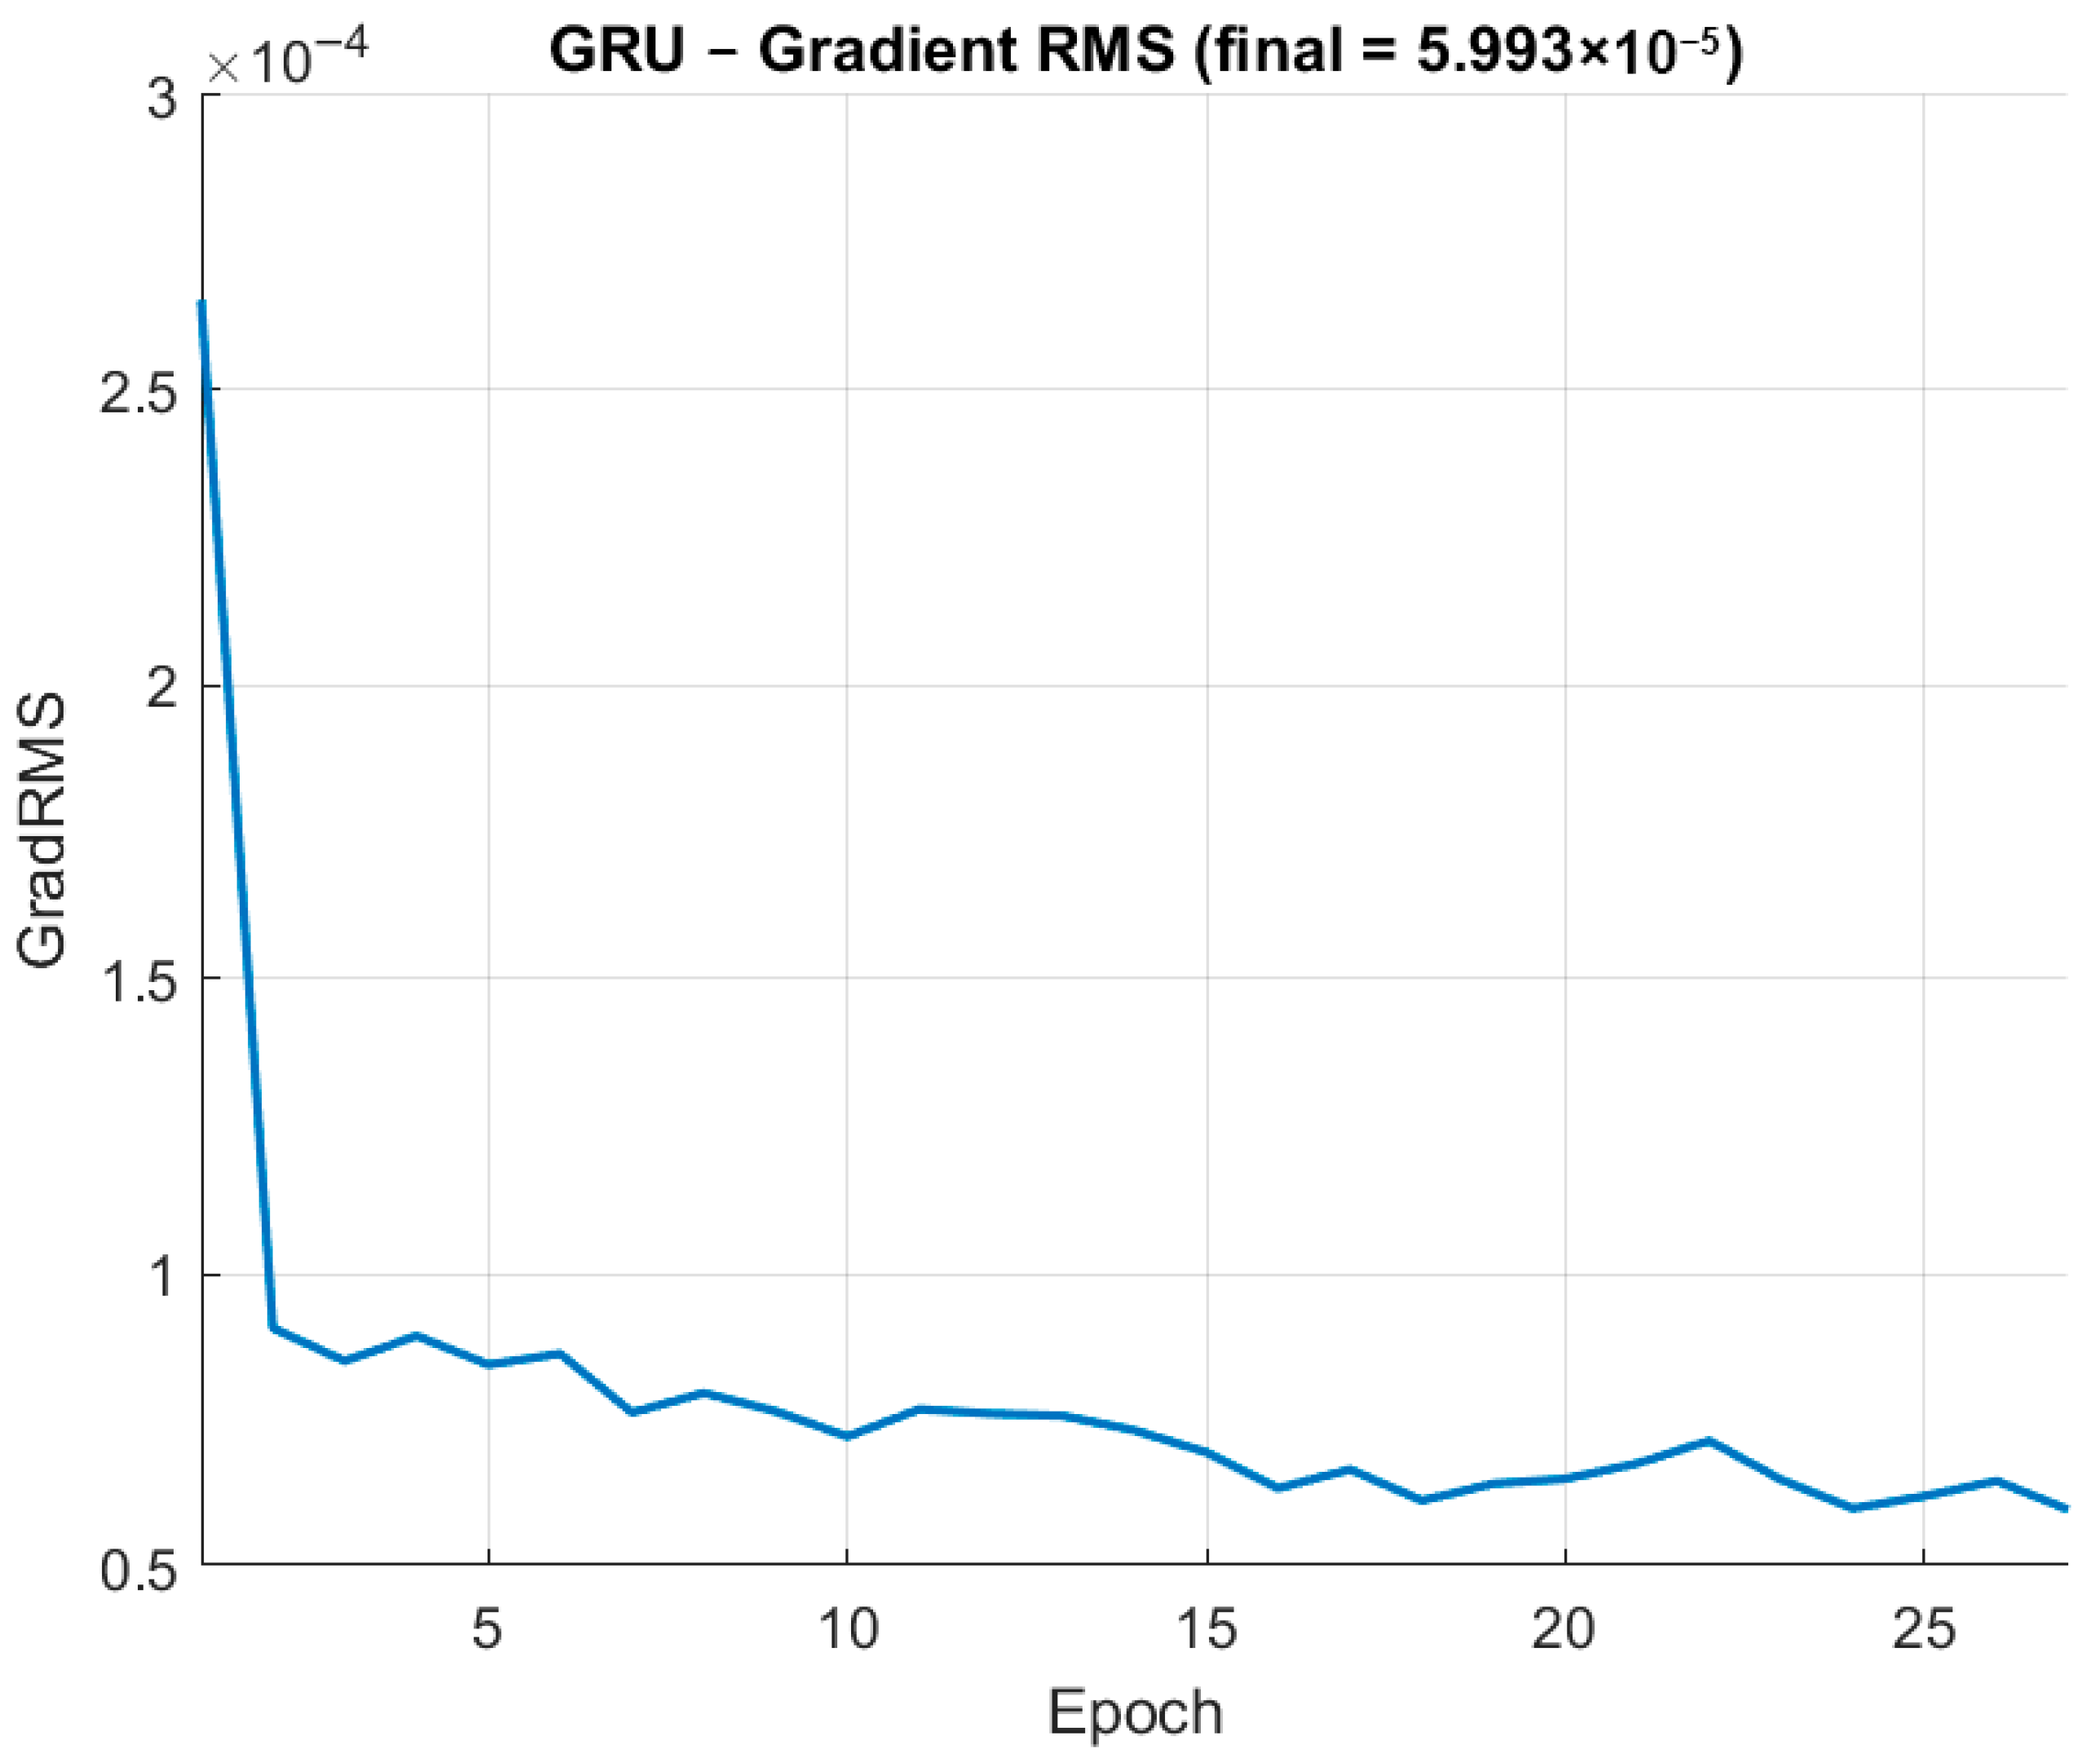
Figure 10 shows that the gradient magnitudes decrease from 2.7 × 10⁻⁴ to 0.5 × 10⁻⁴ and then stabilize. This pattern confirms smooth convergence, as the updates become smaller over time without any late spikes. The steady decline suggests that the learning rate schedule and gradient clipping are working effectively to maintain stable and efficient training.
Figure 10.
Gradient curve for GRU model.
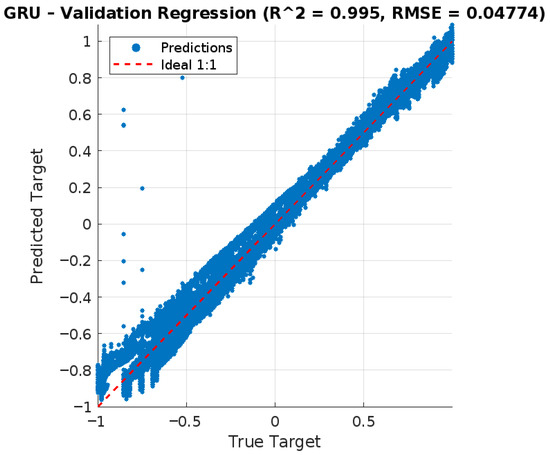
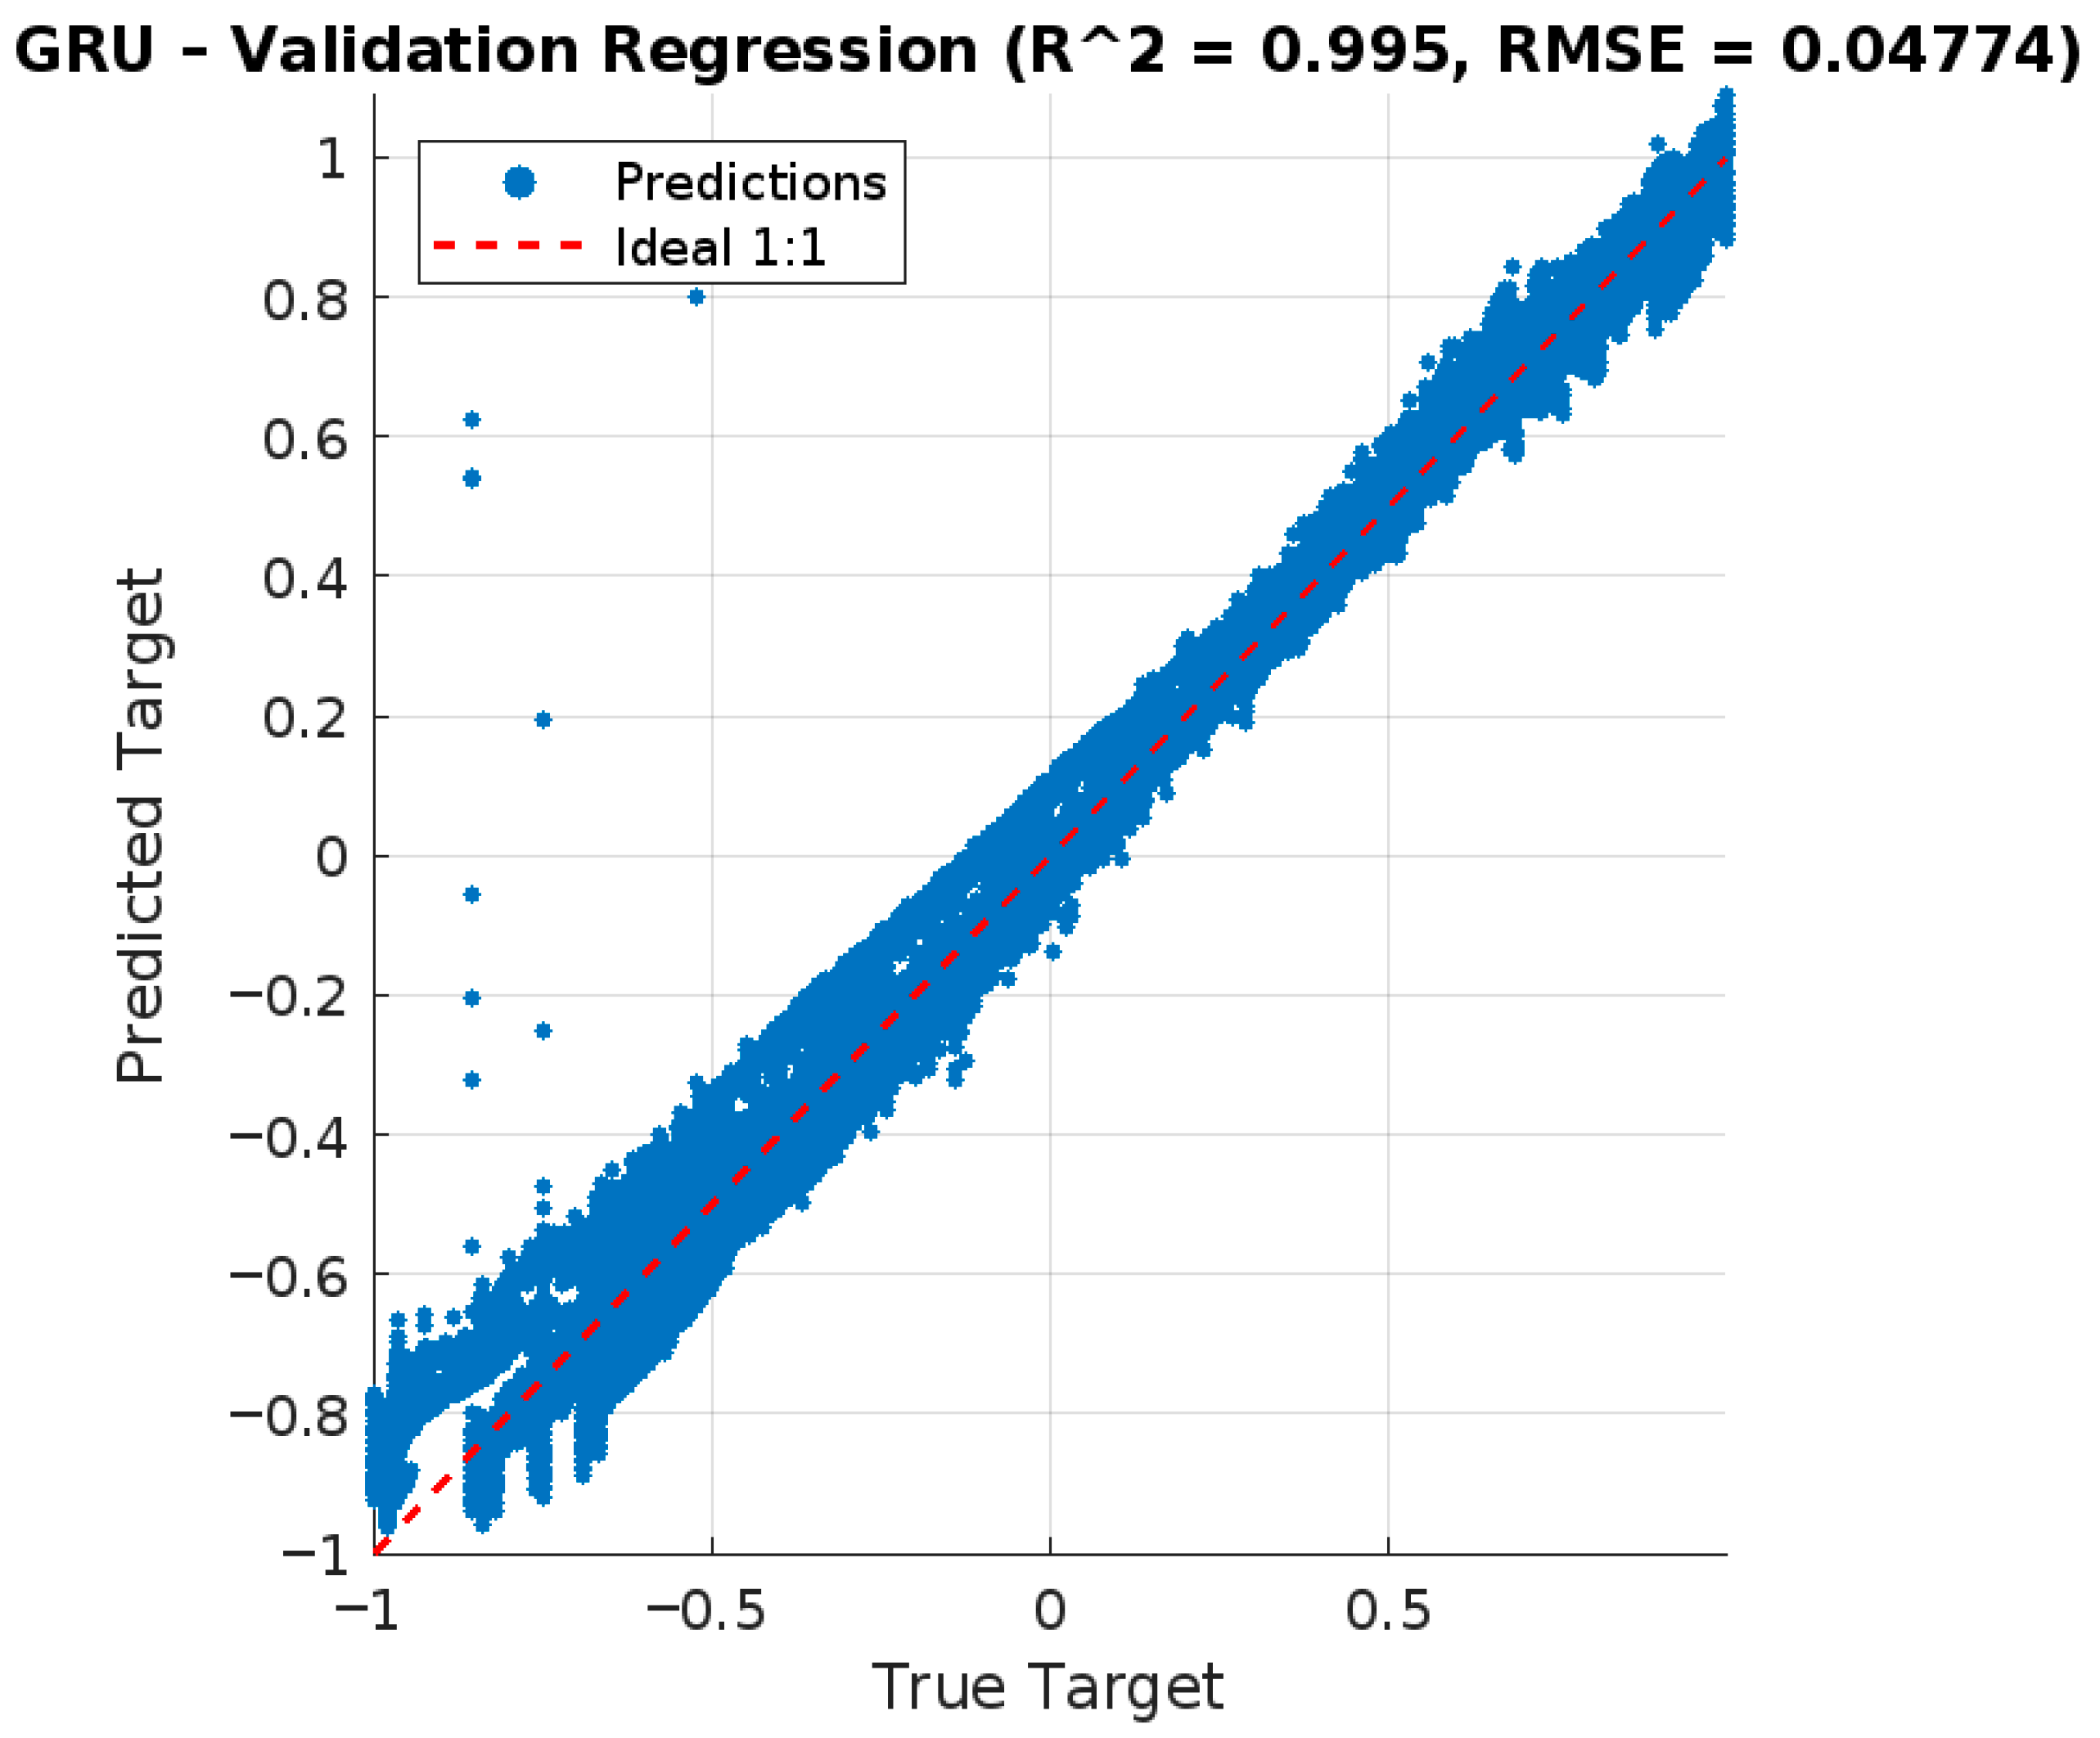
In Figure 11, the predicted SoC values align closely with the actual values along the 1:1 reference line, showing strong agreement between the model outputs and targets. The high R2 value of approximately 0.995 and low RMSE of around 0.0477 confirm that the predictions are accurate and largely unbiased. The few outliers that appear match the edge cases previously seen in the error histogram, further supporting the model’s consistent performance across most of the data.
Figure 11.
Regression plot for the GRU model.
3.6. LSTM Model
Table 27 shows the number of samples in each subset, with about 1.88 million for training and around 0.40 million each for validation and test. The error values across the three splits are very close, with MSE ranging from approximately 2.44 to 2.56 × 10⁻³ and RMSE between 4.94 and 5.06 × 10⁻². Correlation values are also high and consistent, with R around 0.9975 and R2 near 0.995. This close agreement shows that the LSTM model performs similarly on both seen and unseen data, indicating strong generalization and little to no overfitting.
Table 27.
Data split and basic performance statistics for the LSTM model.
Table 28 outlines the full training setup. The network architecture includes two LSTM layers with 256 and 128 hidden units, using “OutputMode = sequence”, followed by a fully connected layer. A window length of 80 and a stride of 20 (75% overlap) increases the temporal context and expands the number of training windows. The model is trained using the AdamW optimizer, which combines Adam with decoupled L2 weight decay set to 1.0 × 10⁻³. The learning rate starts at 0.002 and decreases using cosine decay to a minimum factor of 0.005. Gradient clipping with a global norm of 5 helps prevent exploding gradients, while a dropout rate of 10% reduces the risk of overfitting. Inputs are normalized using Z scores, and targets are scaled linearly to the range from −1 to 1. Early stopping with a patience of 10 epochs selected the best model at epoch 60, where the validation MSE reached approximately 2.4 × 10⁻⁴. Total training time was about 2.3 h. These settings together help ensure stable training and reproducibility.
Table 28.
Hyperparameters and training settings for the LSTM model.
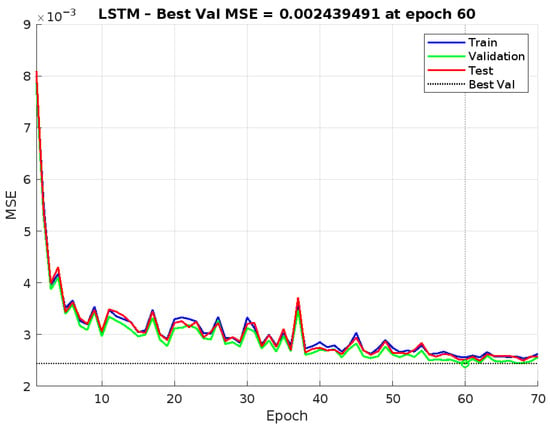
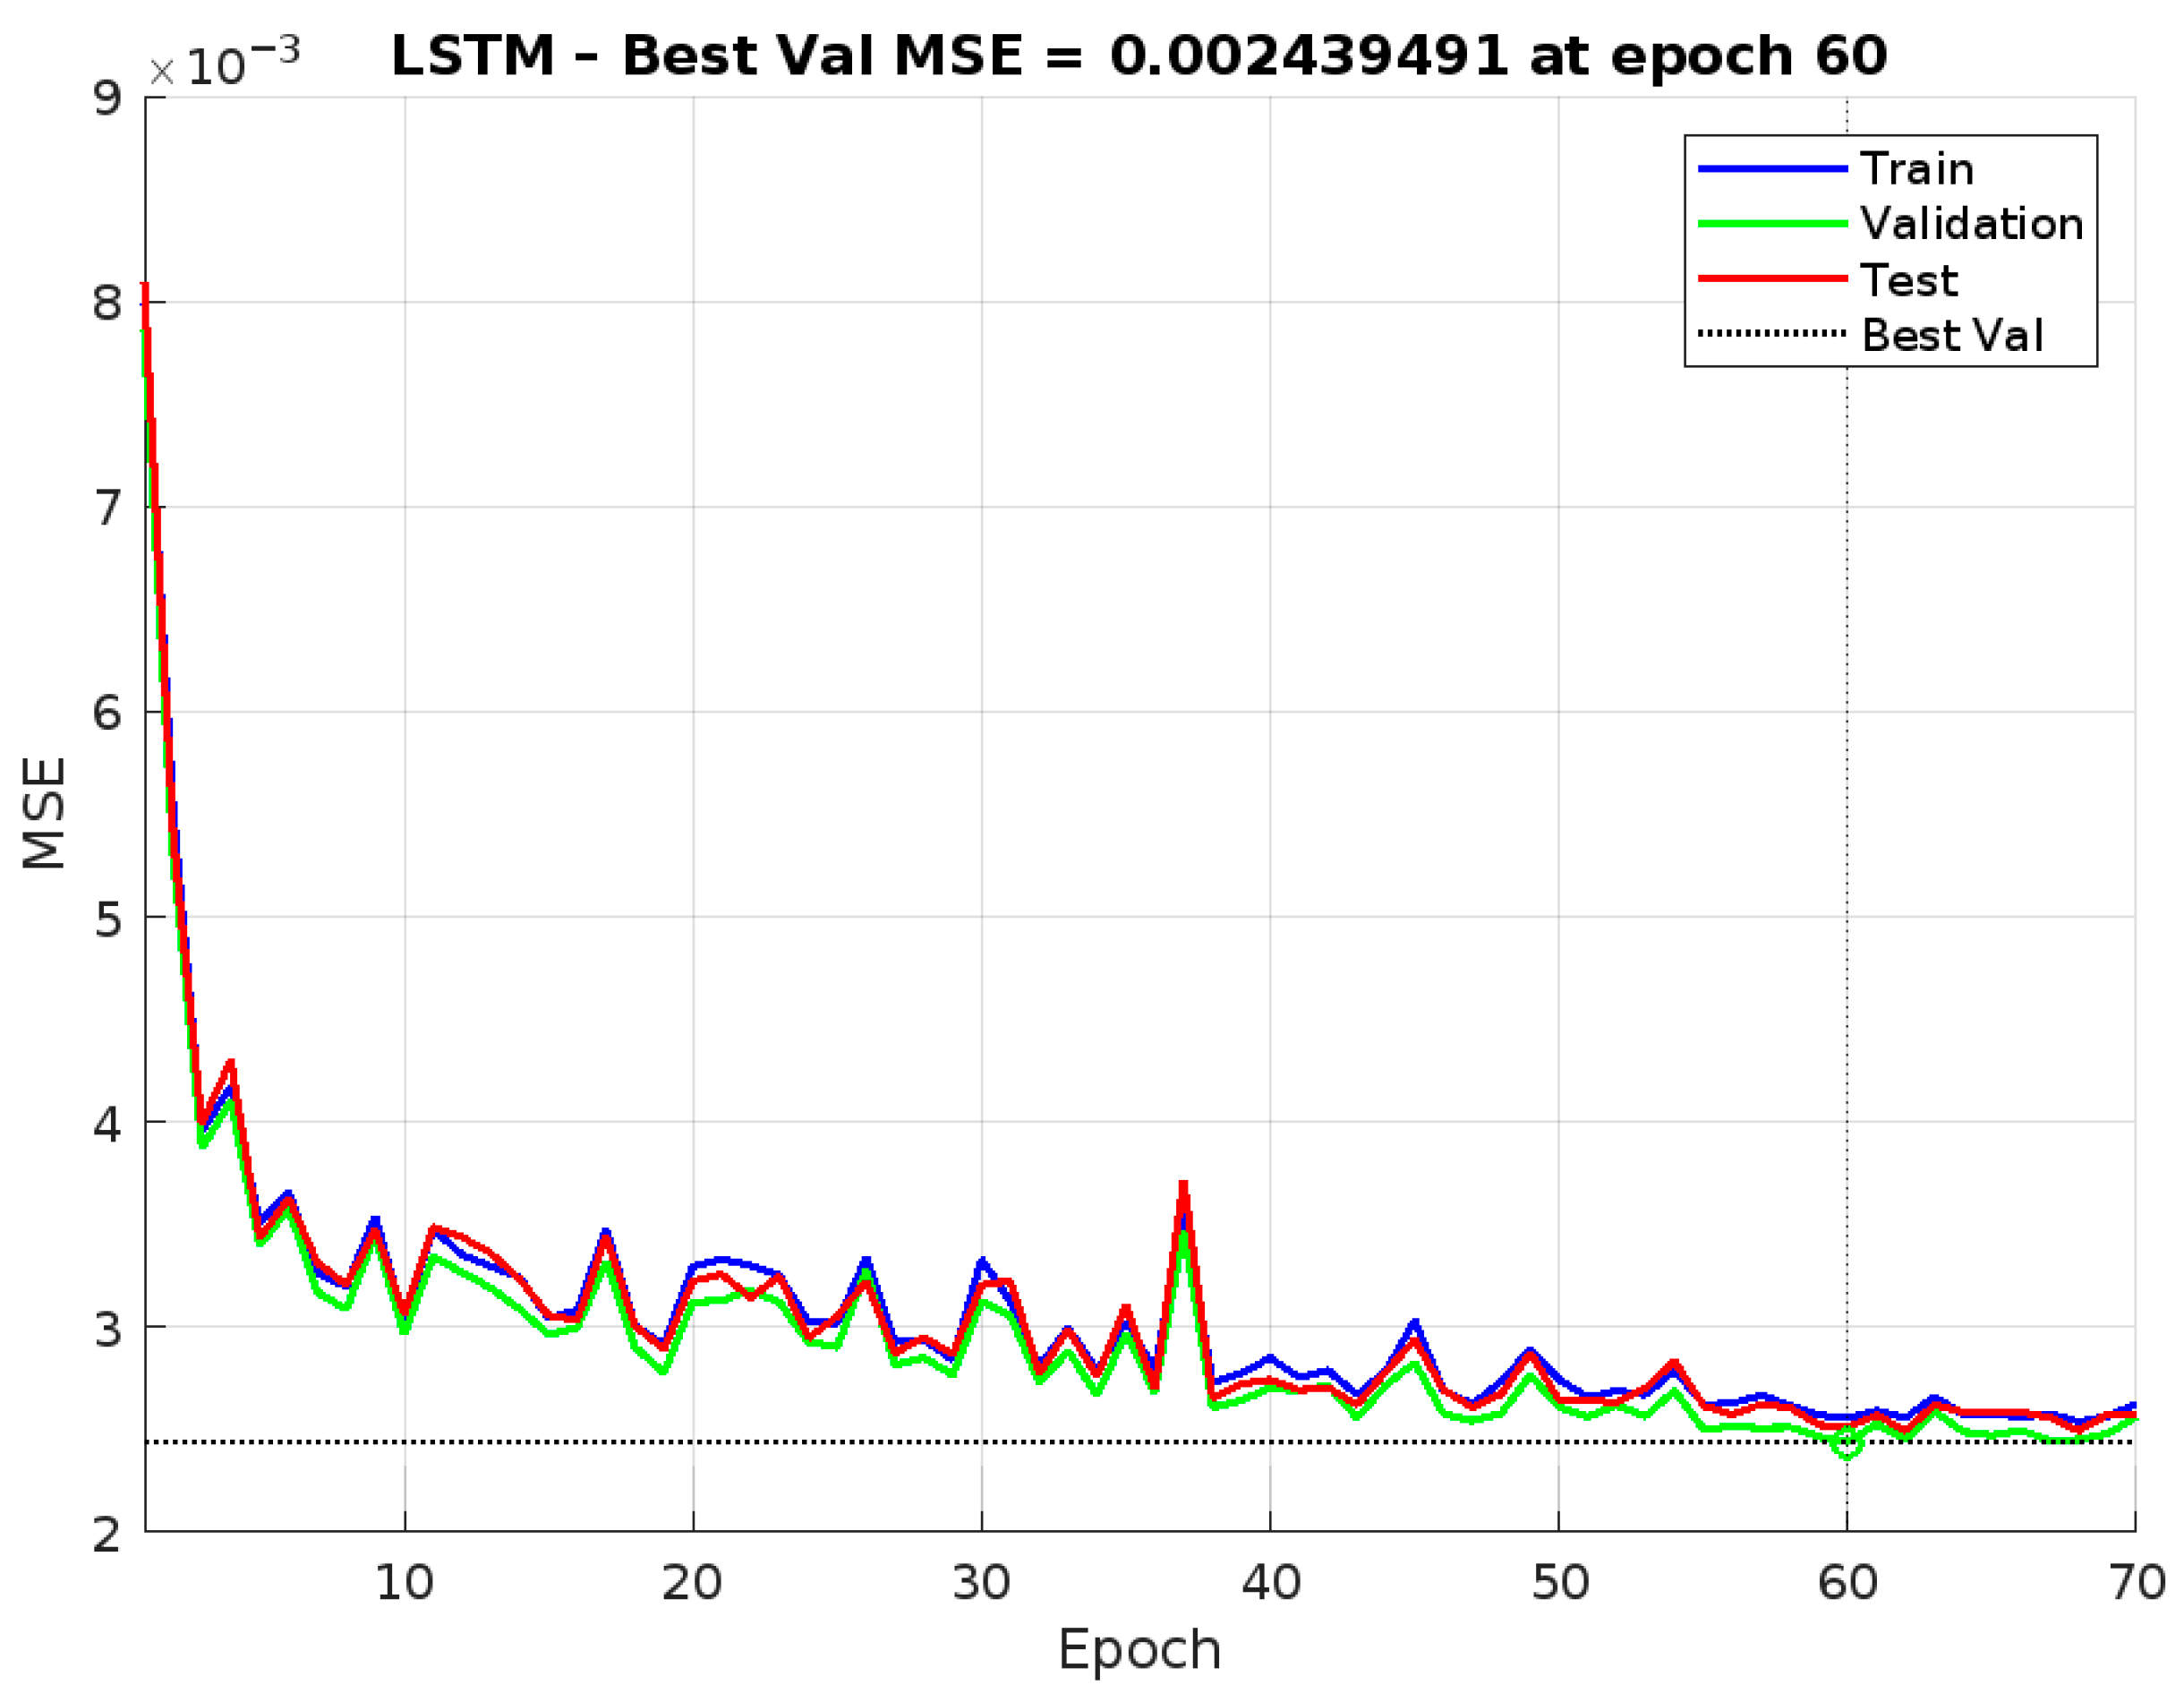
In Figure 12, the error drops steeply during the first 10 epochs, then fluctuates within a narrow range between approximately 2.4 and 3.5 × 10⁻³. A small spike around epoch 37 reflects temporary mini-batch variability rather than a structural problem. The lowest validation MSE appears at epoch 60, which matches the point selected by early stopping. The training, validation, and test curves stay closely grouped throughout, indicating a minimal generalization gap and confirming that the model has learned temporal features consistently across all data splits.
Figure 12.
Performance curve for the LSTM model.
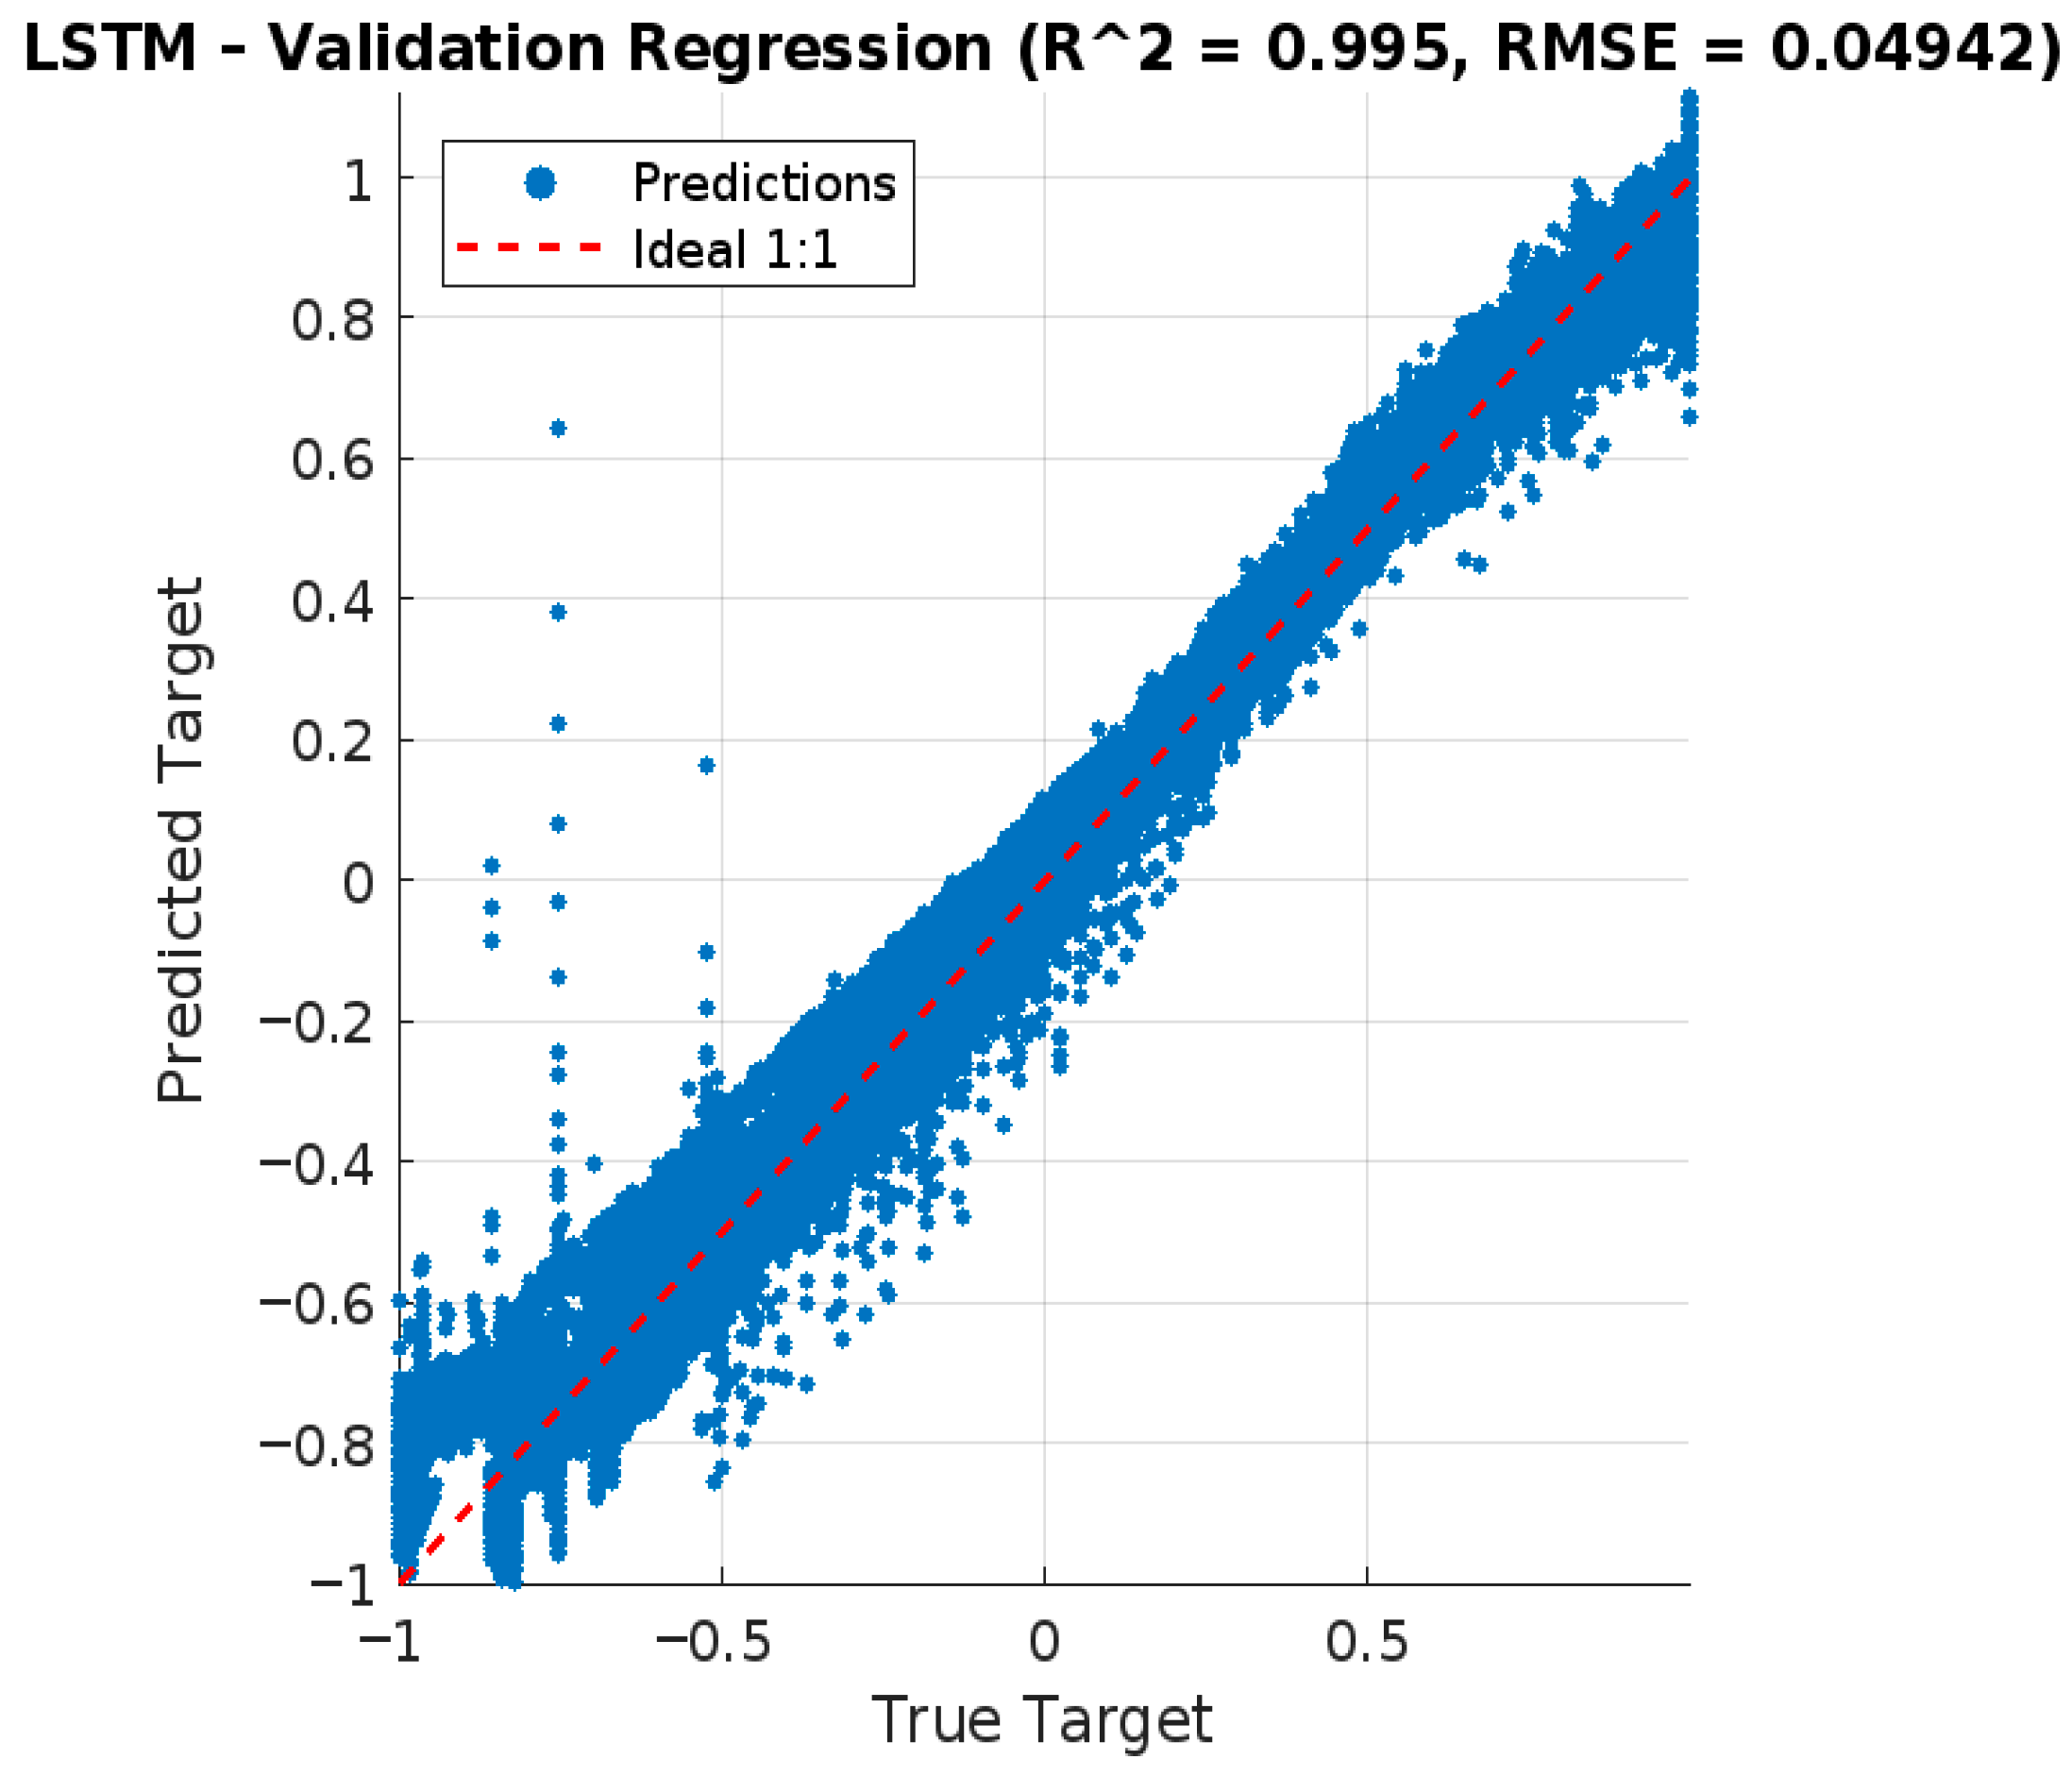
Figure 13 presents the LSTM validation regression, where predicted SoC values are plotted against the actual SoC values. The points cluster closely around the 1:1 reference line, with an R2 of 0.995 and an RMSE of 0.0494. There is a slight increase in spread near the boundaries of the range, which is common when those regions have fewer training samples or stronger nonlinear behavior. The fitted trend has a slope close to one and an intercept near zero, indicating minimal systematic bias. Overall, the residuals appear predominantly random rather than patterned, suggesting that the model is well calibrated and performs reliably across the validation set.
Figure 13.
Regression plot for the LSTM model.
3.7. TCN Model
As shown in Table 29, the training set includes 1,875,700 samples, while the validation and test sets each contain 401,920 samples. The MSE ranges from 3.02 × 10⁻³ to 3.12 × 10⁻³, and the RMSE falls between approximately 5.50 and 5.58 × 10⁻². Correlation values remain high, with R around 0.997 and R2 close to 0.994. The similarity of these values across all splits suggests that the TCN model performs consistently on both seen and unseen data, indicating strong generalization and minimal overfitting.
Table 29.
Data split and basic performance statistics for the TCN model.
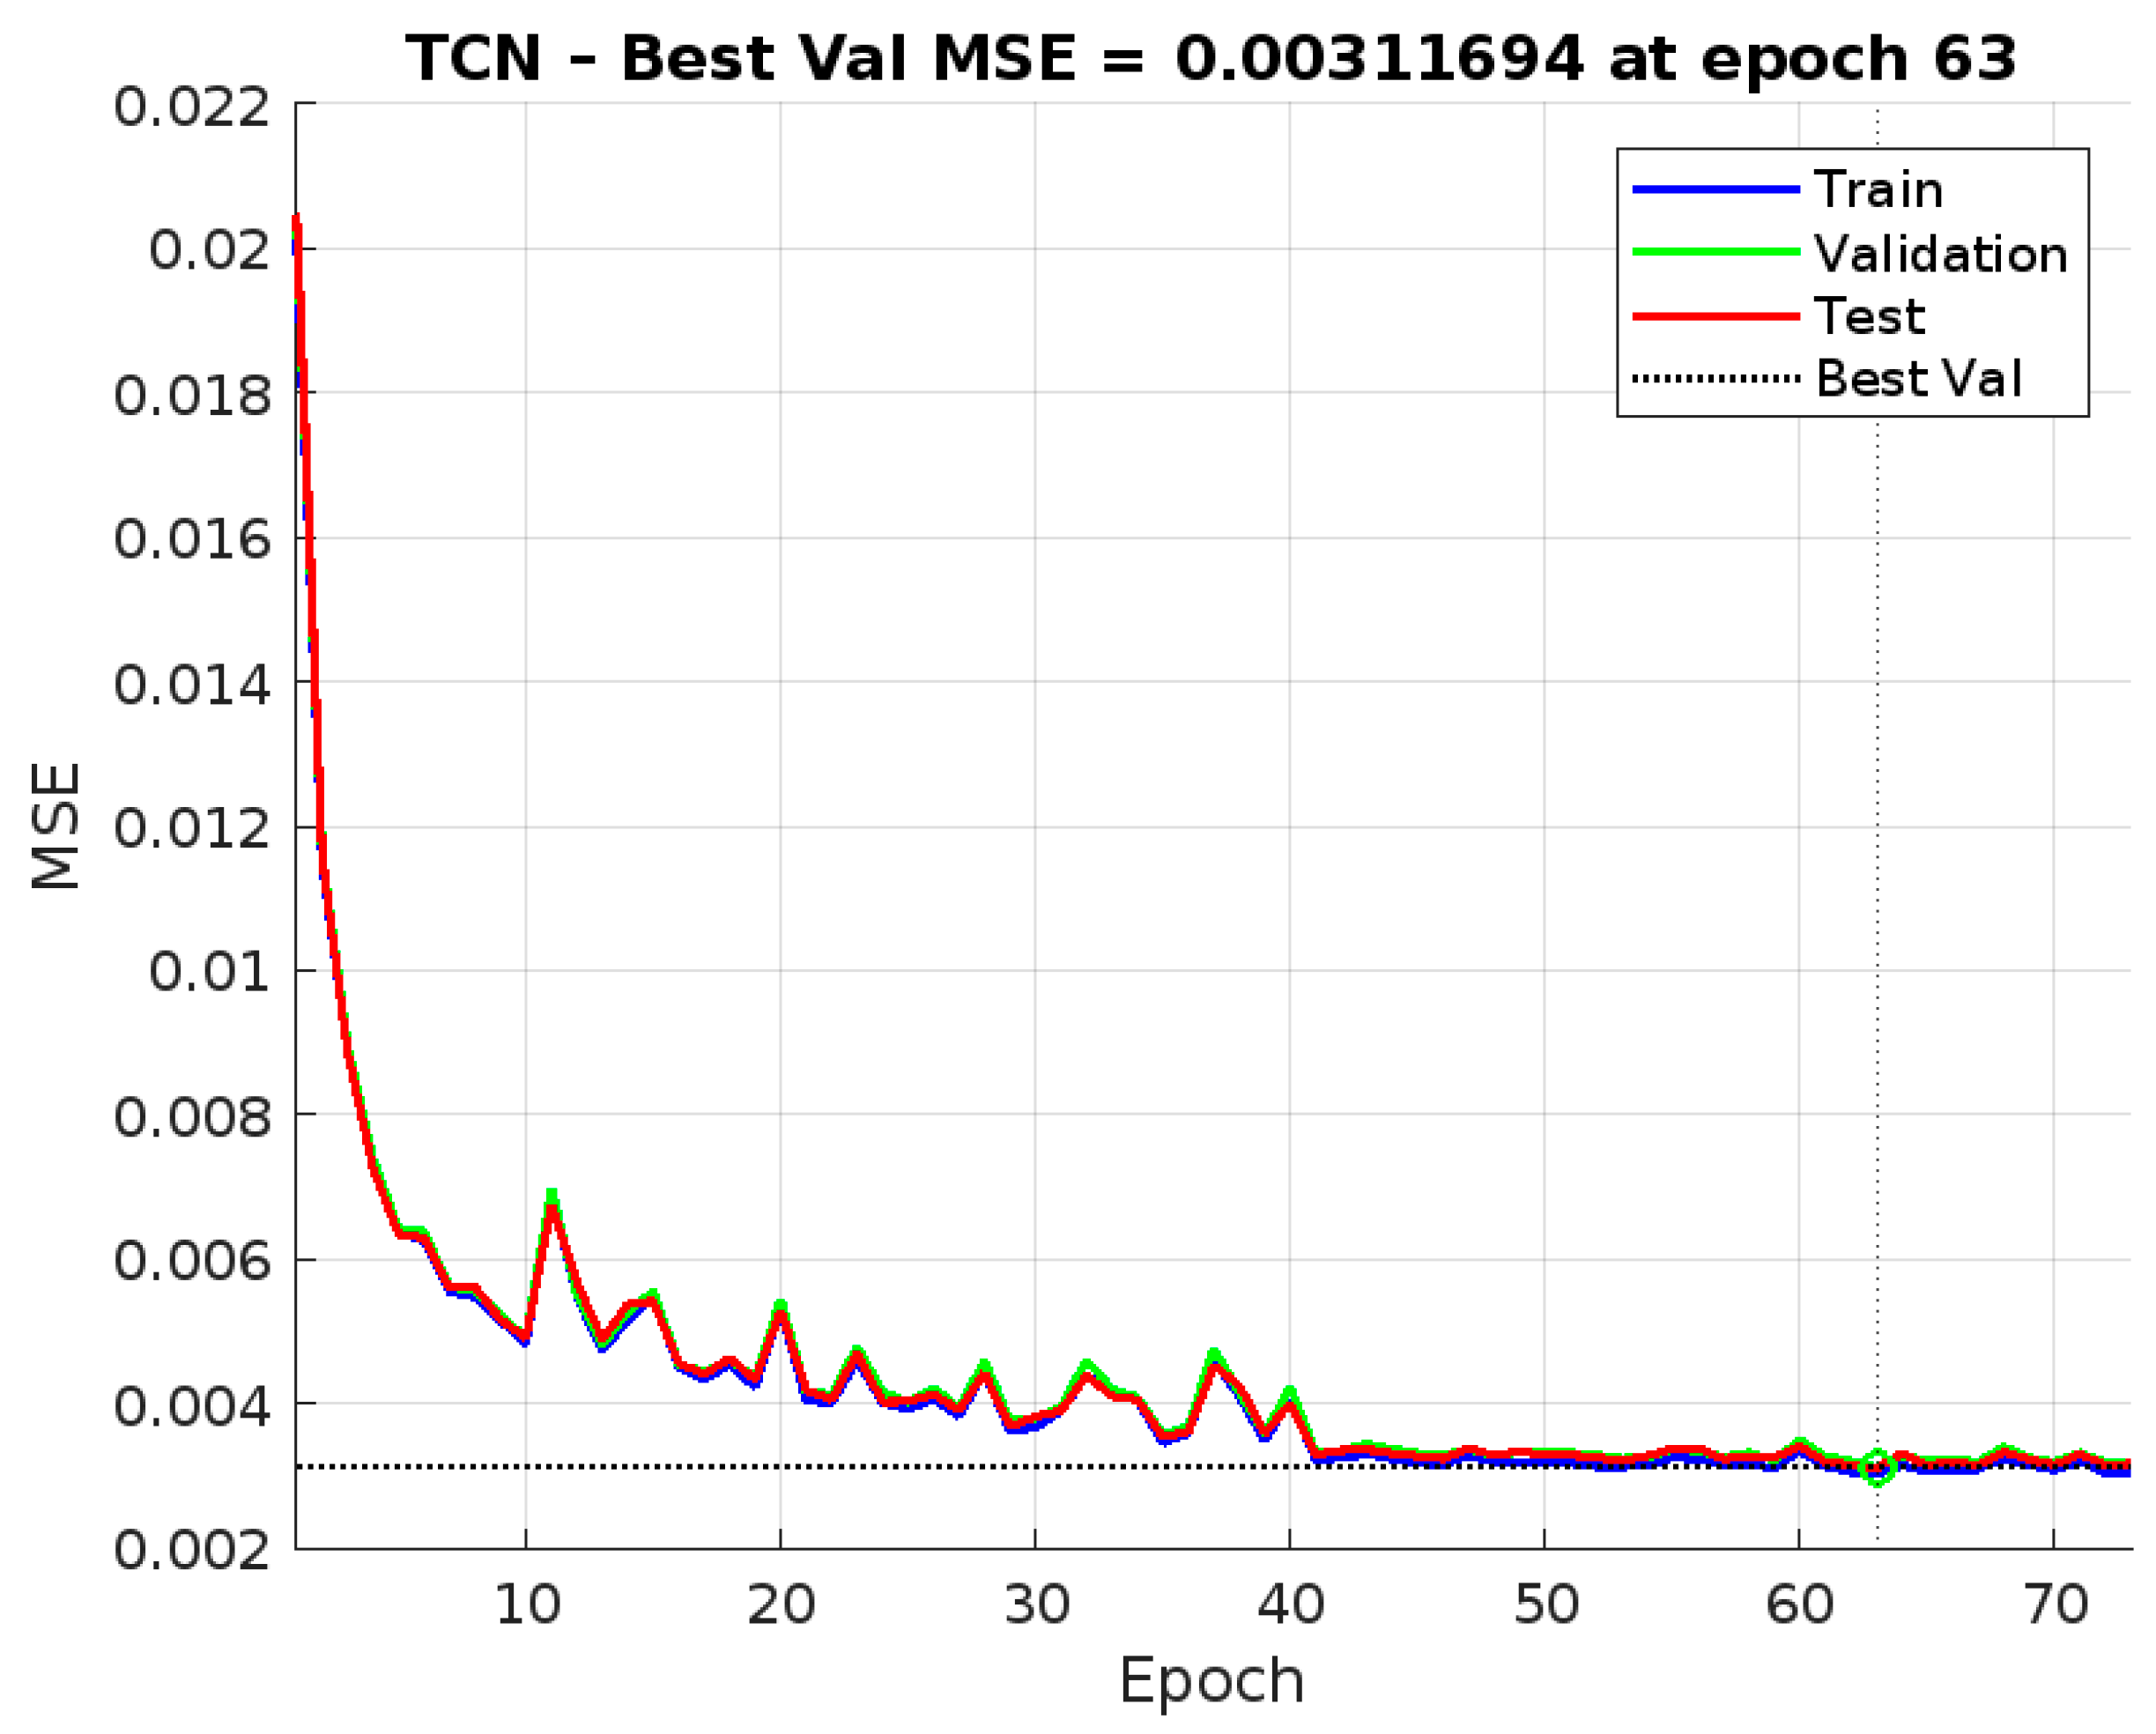
As summarized in Table 30, the network consists of five one-dimensional convolutional blocks with a kernel size of 3 and dilation rates of [1, 2, 4, 8, 16], followed by a fully connected layer. A window length of 80 and a stride of 20 (75% overlap) help capture longer temporal patterns and increase the number of training windows. The model is trained using the Adam optimizer with an initial learning rate of 0.002, which drops by a factor of 0.2 at epoch 40. Gradient clipping with a norm of 5 and dropout at 10% are applied to ensure stability and reduce overfitting. Inputs are standardized using Z-score normalization, and targets are scaled to the range from −1 to 1. Early stopping with a patience of 10 epochs selects the model at epoch 63, where the best validation MSE reaches approximately 3.1 × 10⁻³. The total training time is about 1.17 h.
Table 30.
Hyperparameters and training settings for the TCN model.
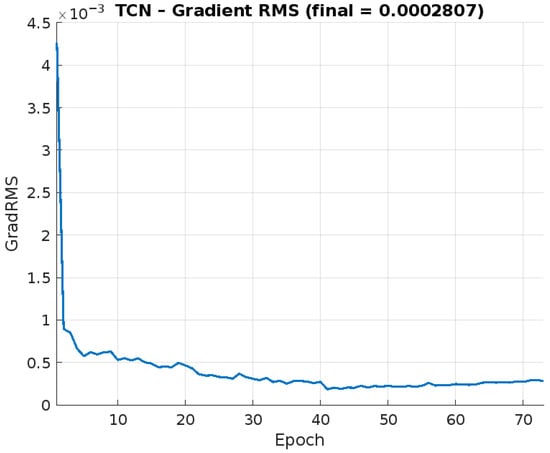
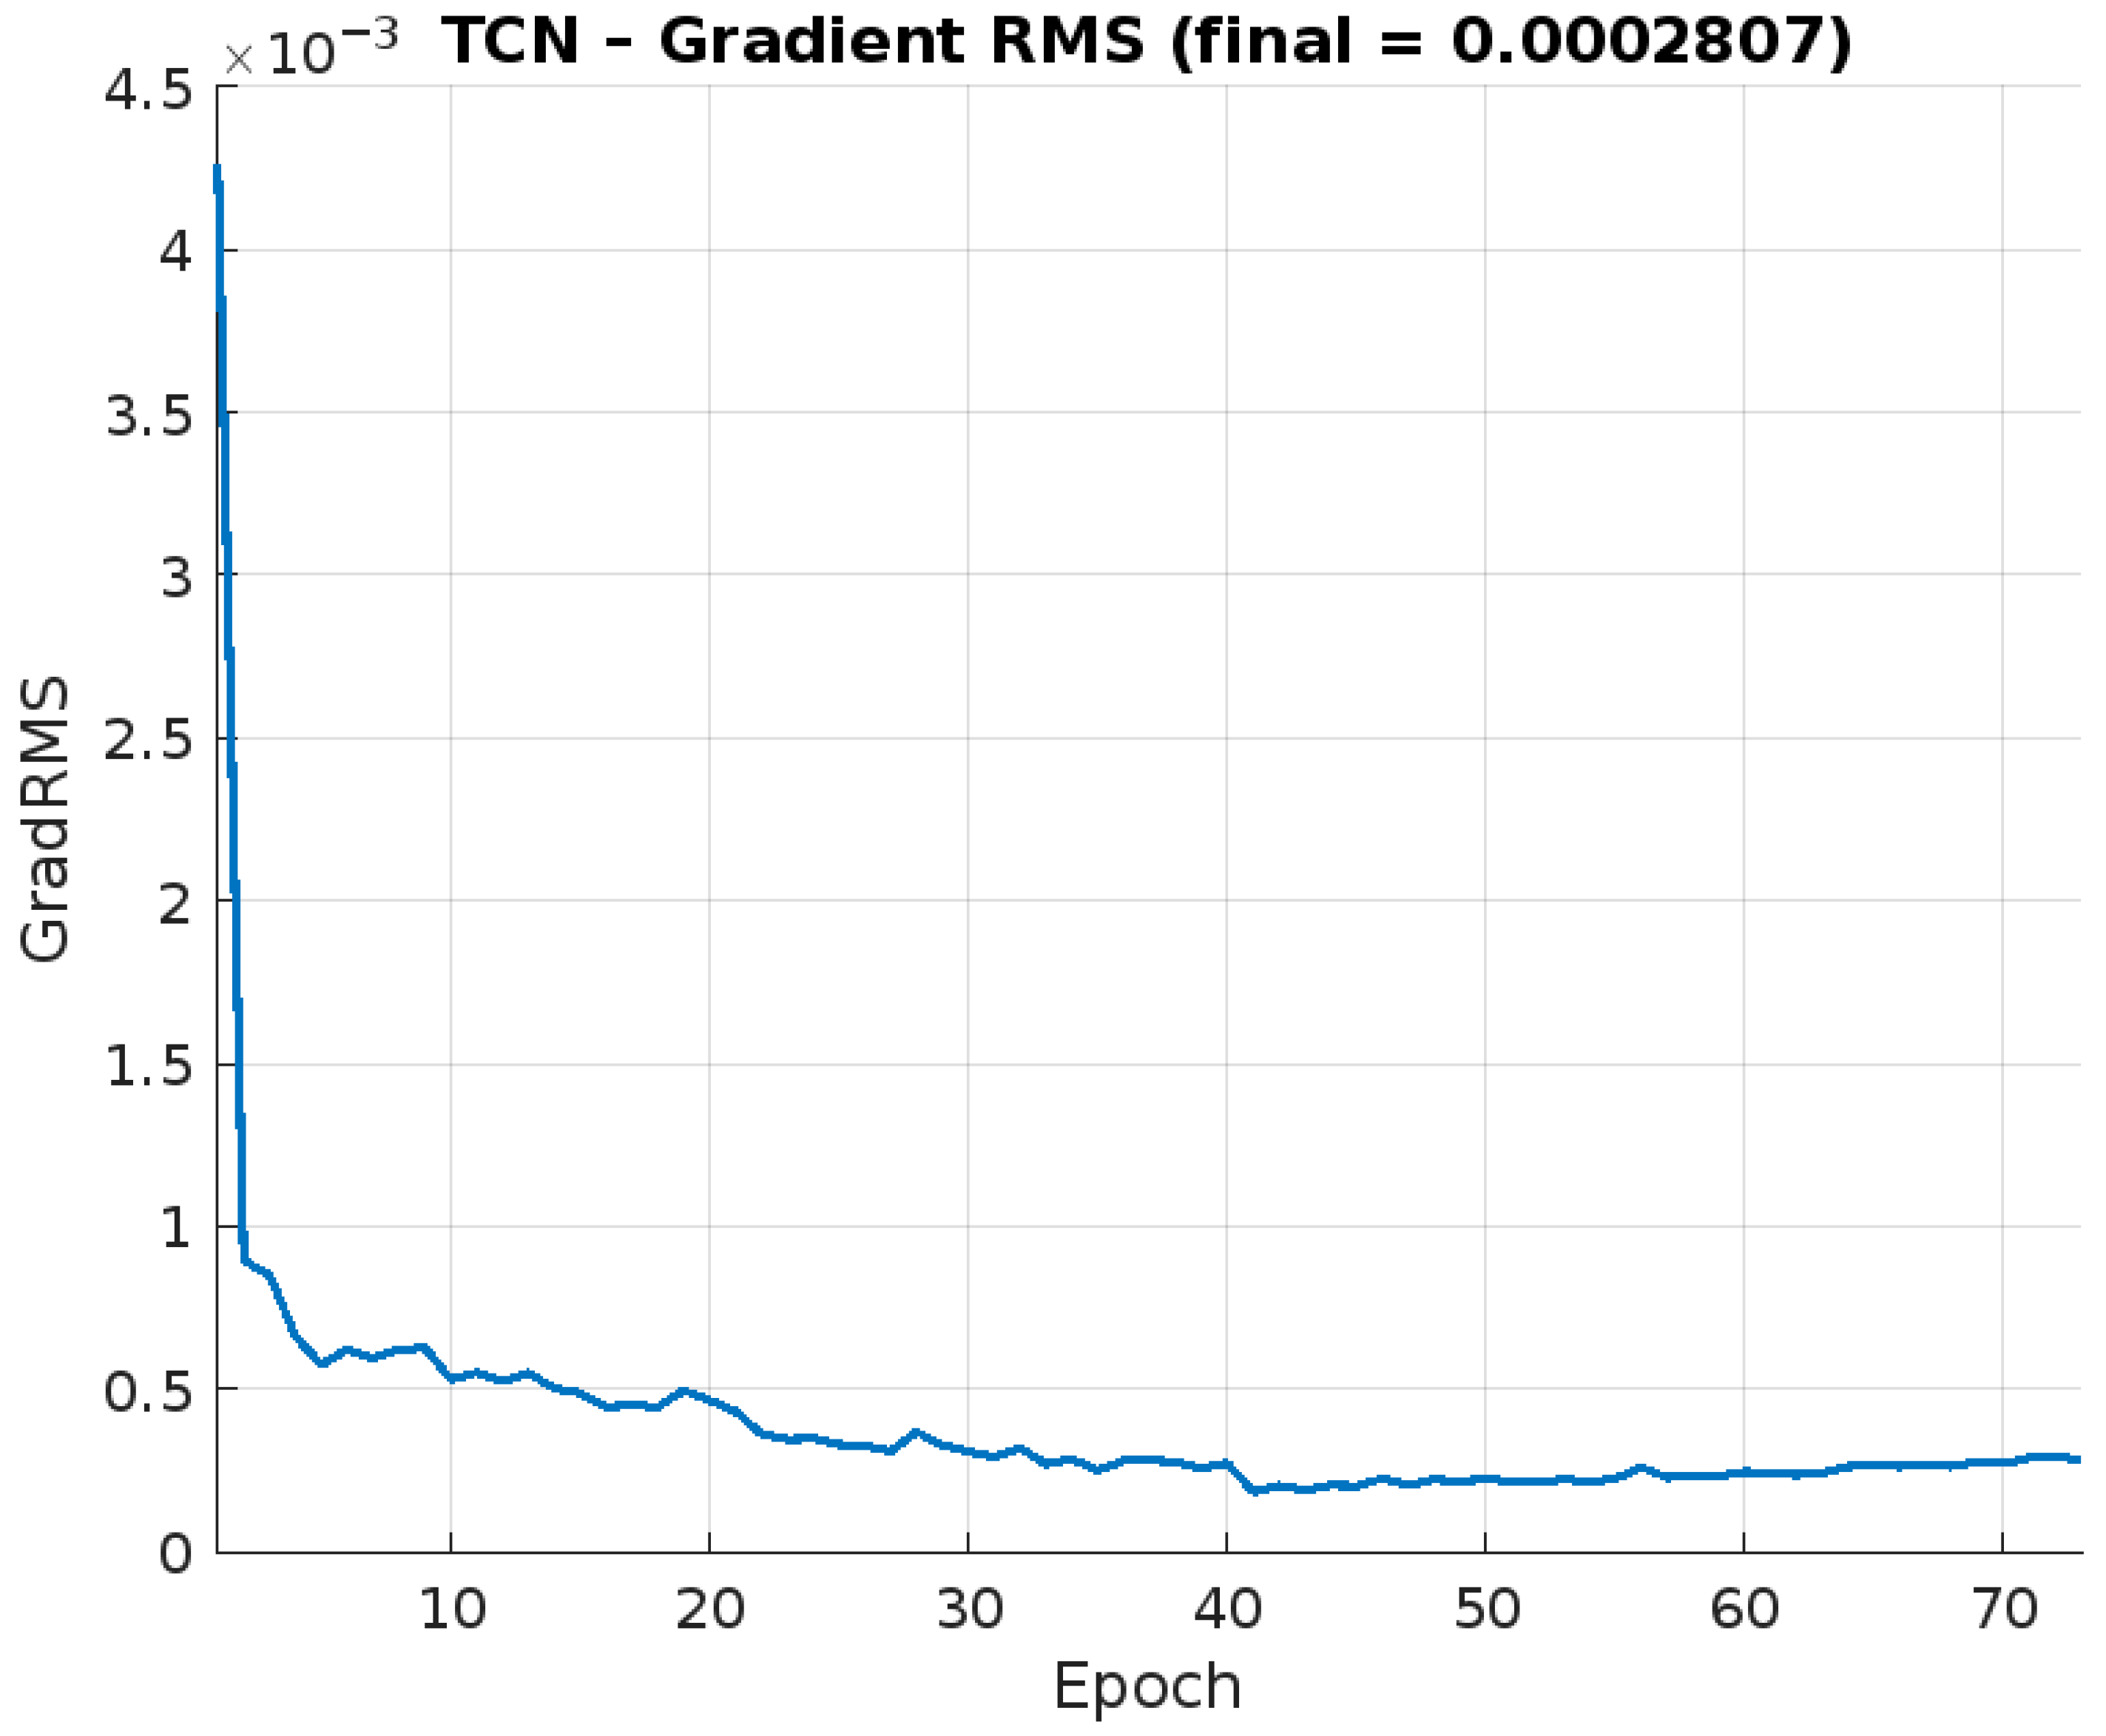
As shown in Figure 14, MSE decreases steeply in the first 10 epochs and then oscillates narrowly around 0.003–0.005. The minimum validation MSE occurs at epoch 63. The train, validation, and test curves almost overlap, indicating a negligible generalization gap. As reported in Figure 15, GradRMS falls from 4.5 × 10⁻³ to 2.8 × 10⁻⁴ and then shows small oscillations. This indicates progressively smaller parameter updates and well-controlled gradients after the initial phase.
Figure 14.
Performance curve for the TCN model.
Figure 15.
Gradient curve for the TCN model.
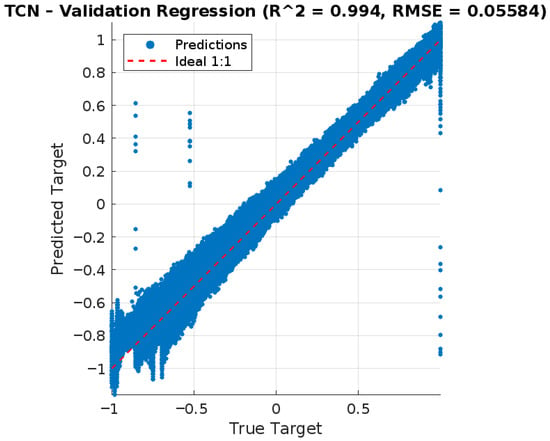
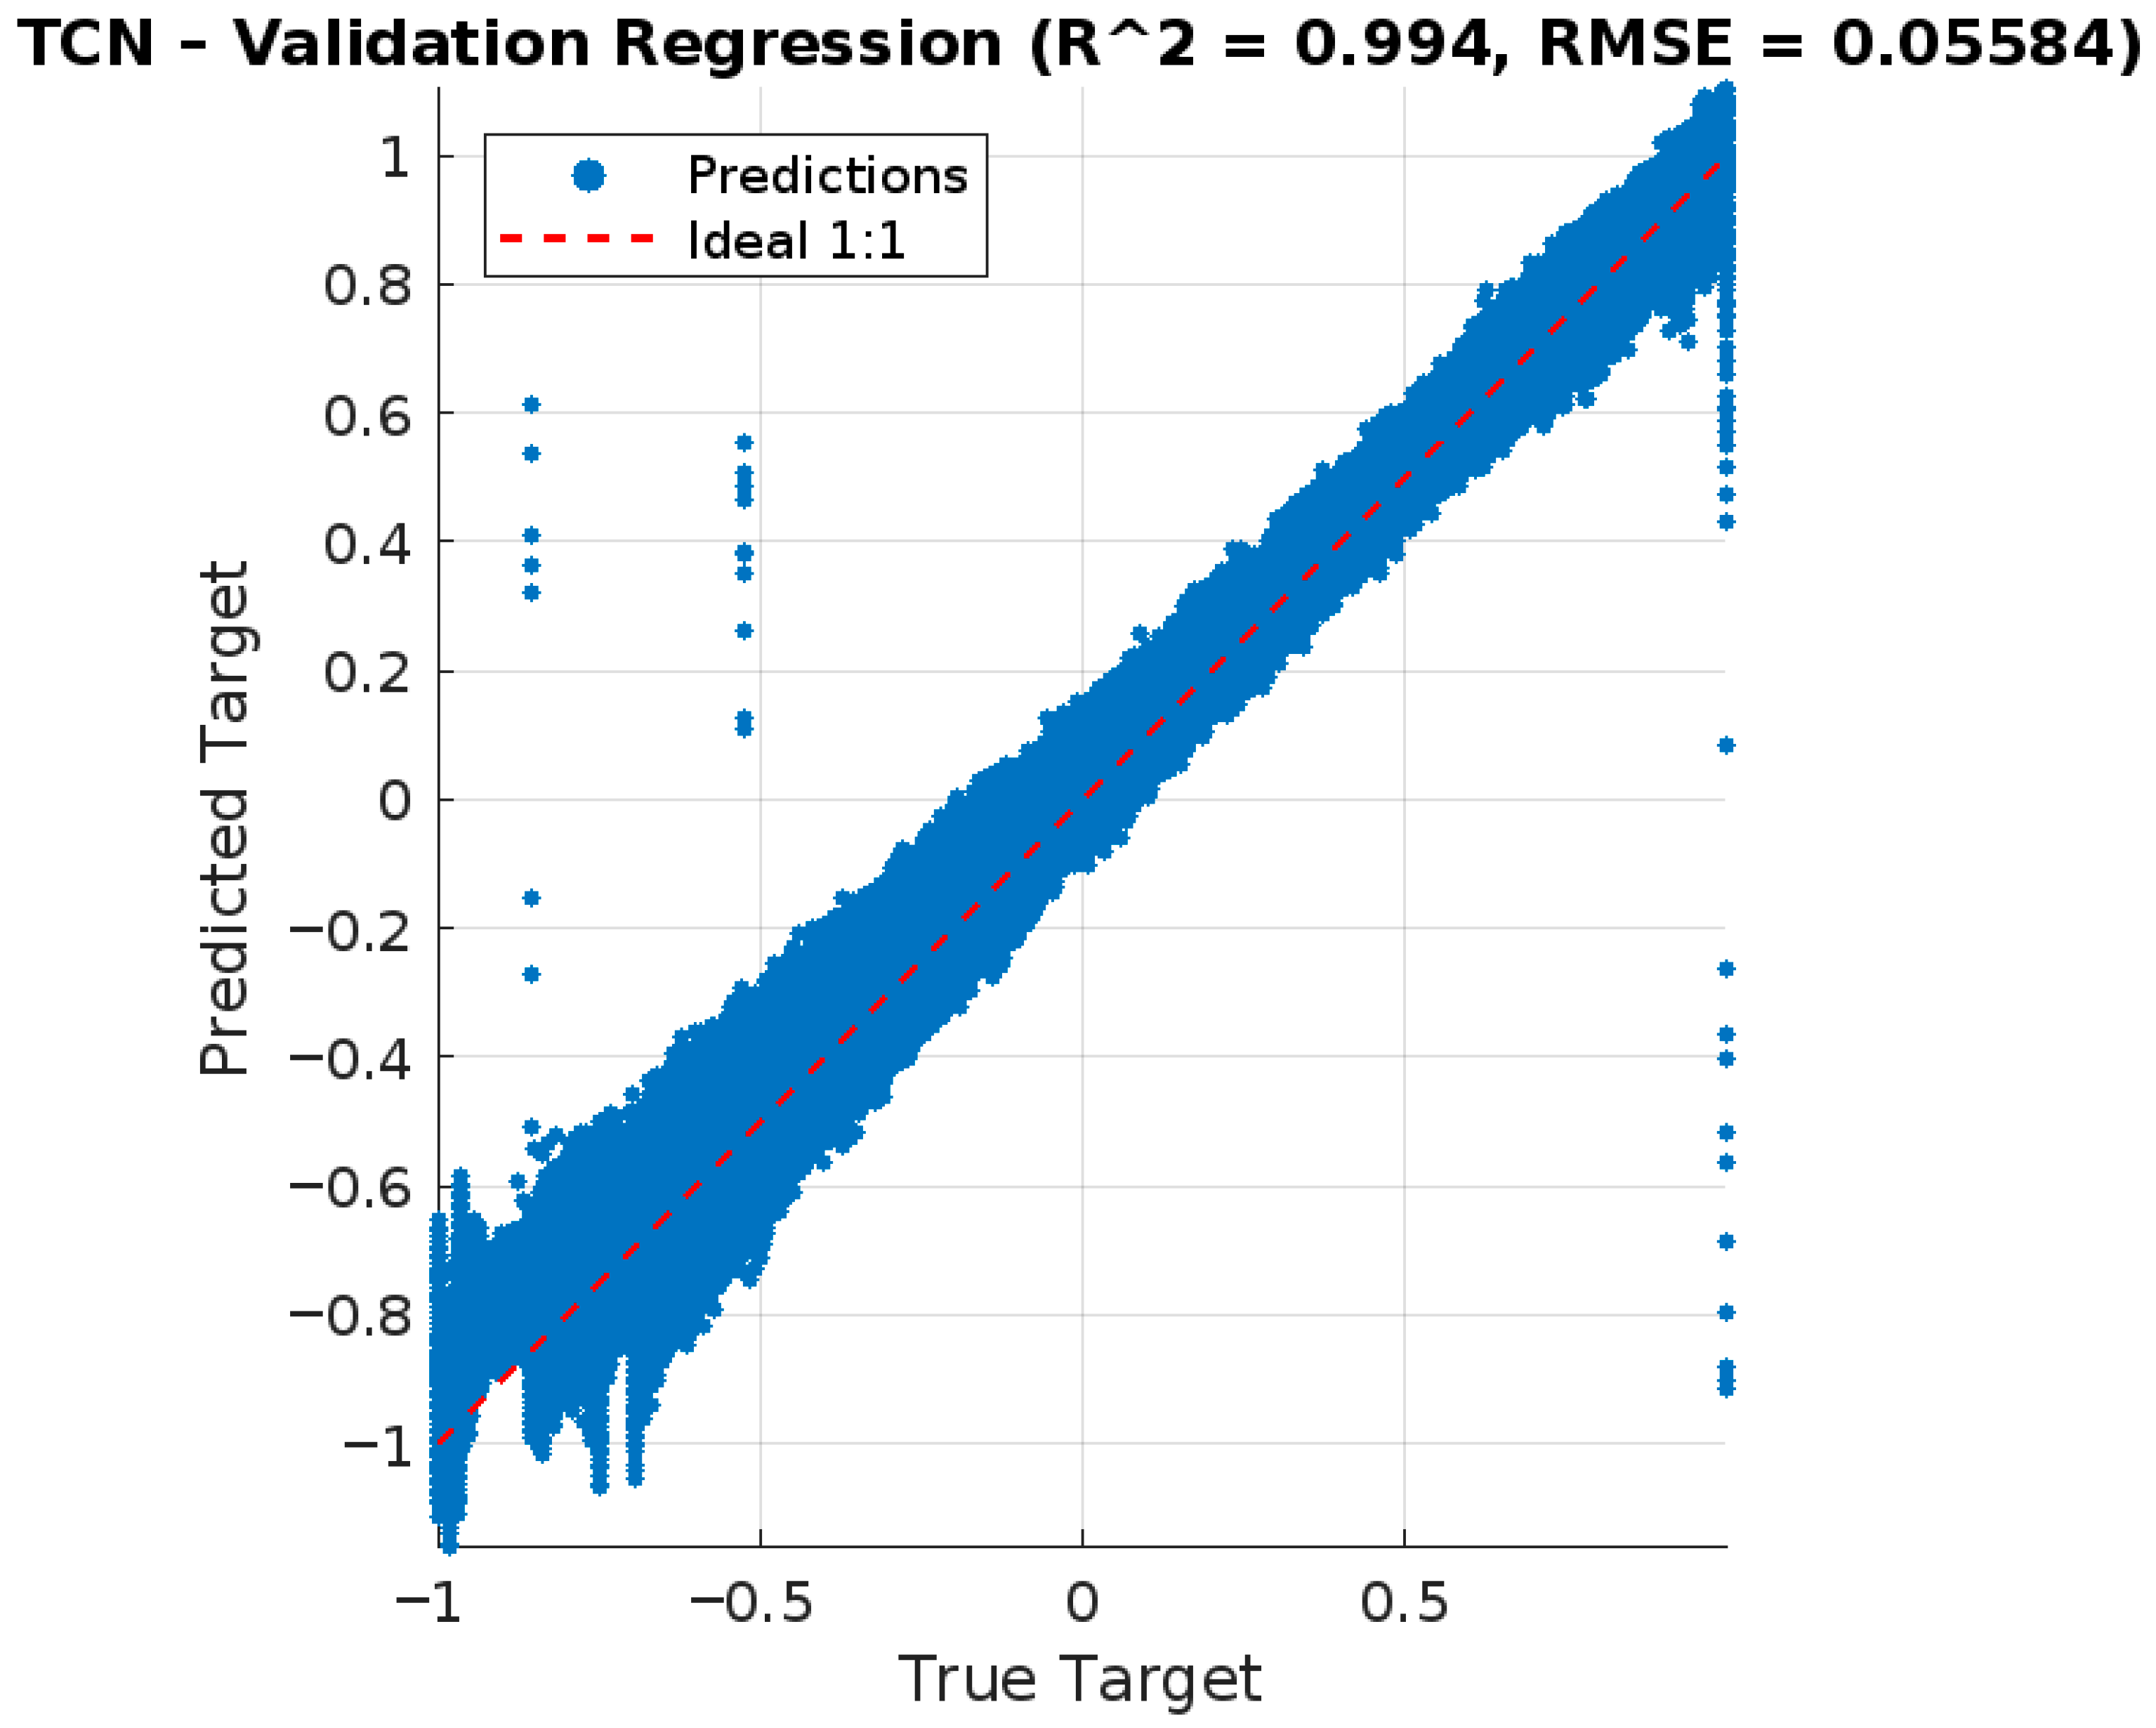
As illustrated in Figure 16, the predicted values align closely with the 1:1 reference line, resulting in an R2 of 0.994 and an RMSE of 0.0559. The scatter becomes slightly wider at the extreme SoC values, which is expected in regions with fewer data points or more complex nonlinear behavior. The slope remains close to one, indicating minimal systematic bias in the model’s predictions.
Figure 16.
Regression plot for the TCN model.
3.8. Test Results
All tests were conducted under ambient temperature, both charging and discharging conditions. Specifically, Test 1 was performed at −10 °C, Test 2 at 0 °C, Test 3 at 10 °C, and Test 4 at 25 °C.
3.8.1. Test 20-Neuron BR Fitting FNN
Table 31 presents the performance of the model across four distinct test sets. All four tests show very high linear correlation (R ≥ 0.9977) and low error values, confirming that the network generalizes well across different conditions. Test 4, conducted at 25 °C, clearly performs the best. It achieves the lowest MSE of 1.5883 × 10⁻⁴ while maintaining near-perfect correlation. Conversely, Test 3 recorded the worst metrics, with an MSE of 3.4559 × 10⁻⁴. Throughout all tests, the intercept values β0 remained near zero, ranging from +0.0028 to +0.020, confirming that the model maintains minimal systematic bias.
Table 31.
Test results for the 20-neuron BR-Fitting-FNN.
3.8.2. 10-Neurons LM NAR-FNN
Table 32 details the model demonstrated exceptional precision, achieving its best performance in Test 4 with the lowest MSE of 1.0750 × 10⁻⁸. Test 3 recorded the marginally highest error with an MSE of 1.3398 × 10⁻⁸, indicating very consistent behavior across different data splits. Notably, the correlation coefficient (R) remained at a perfect 1.0000 for all tests, confirming the model’s superior predictive capability and stability in capturing the underlying non-linear patterns.
Table 32.
Test results for the 10-neuron LM-NAR-FNN.
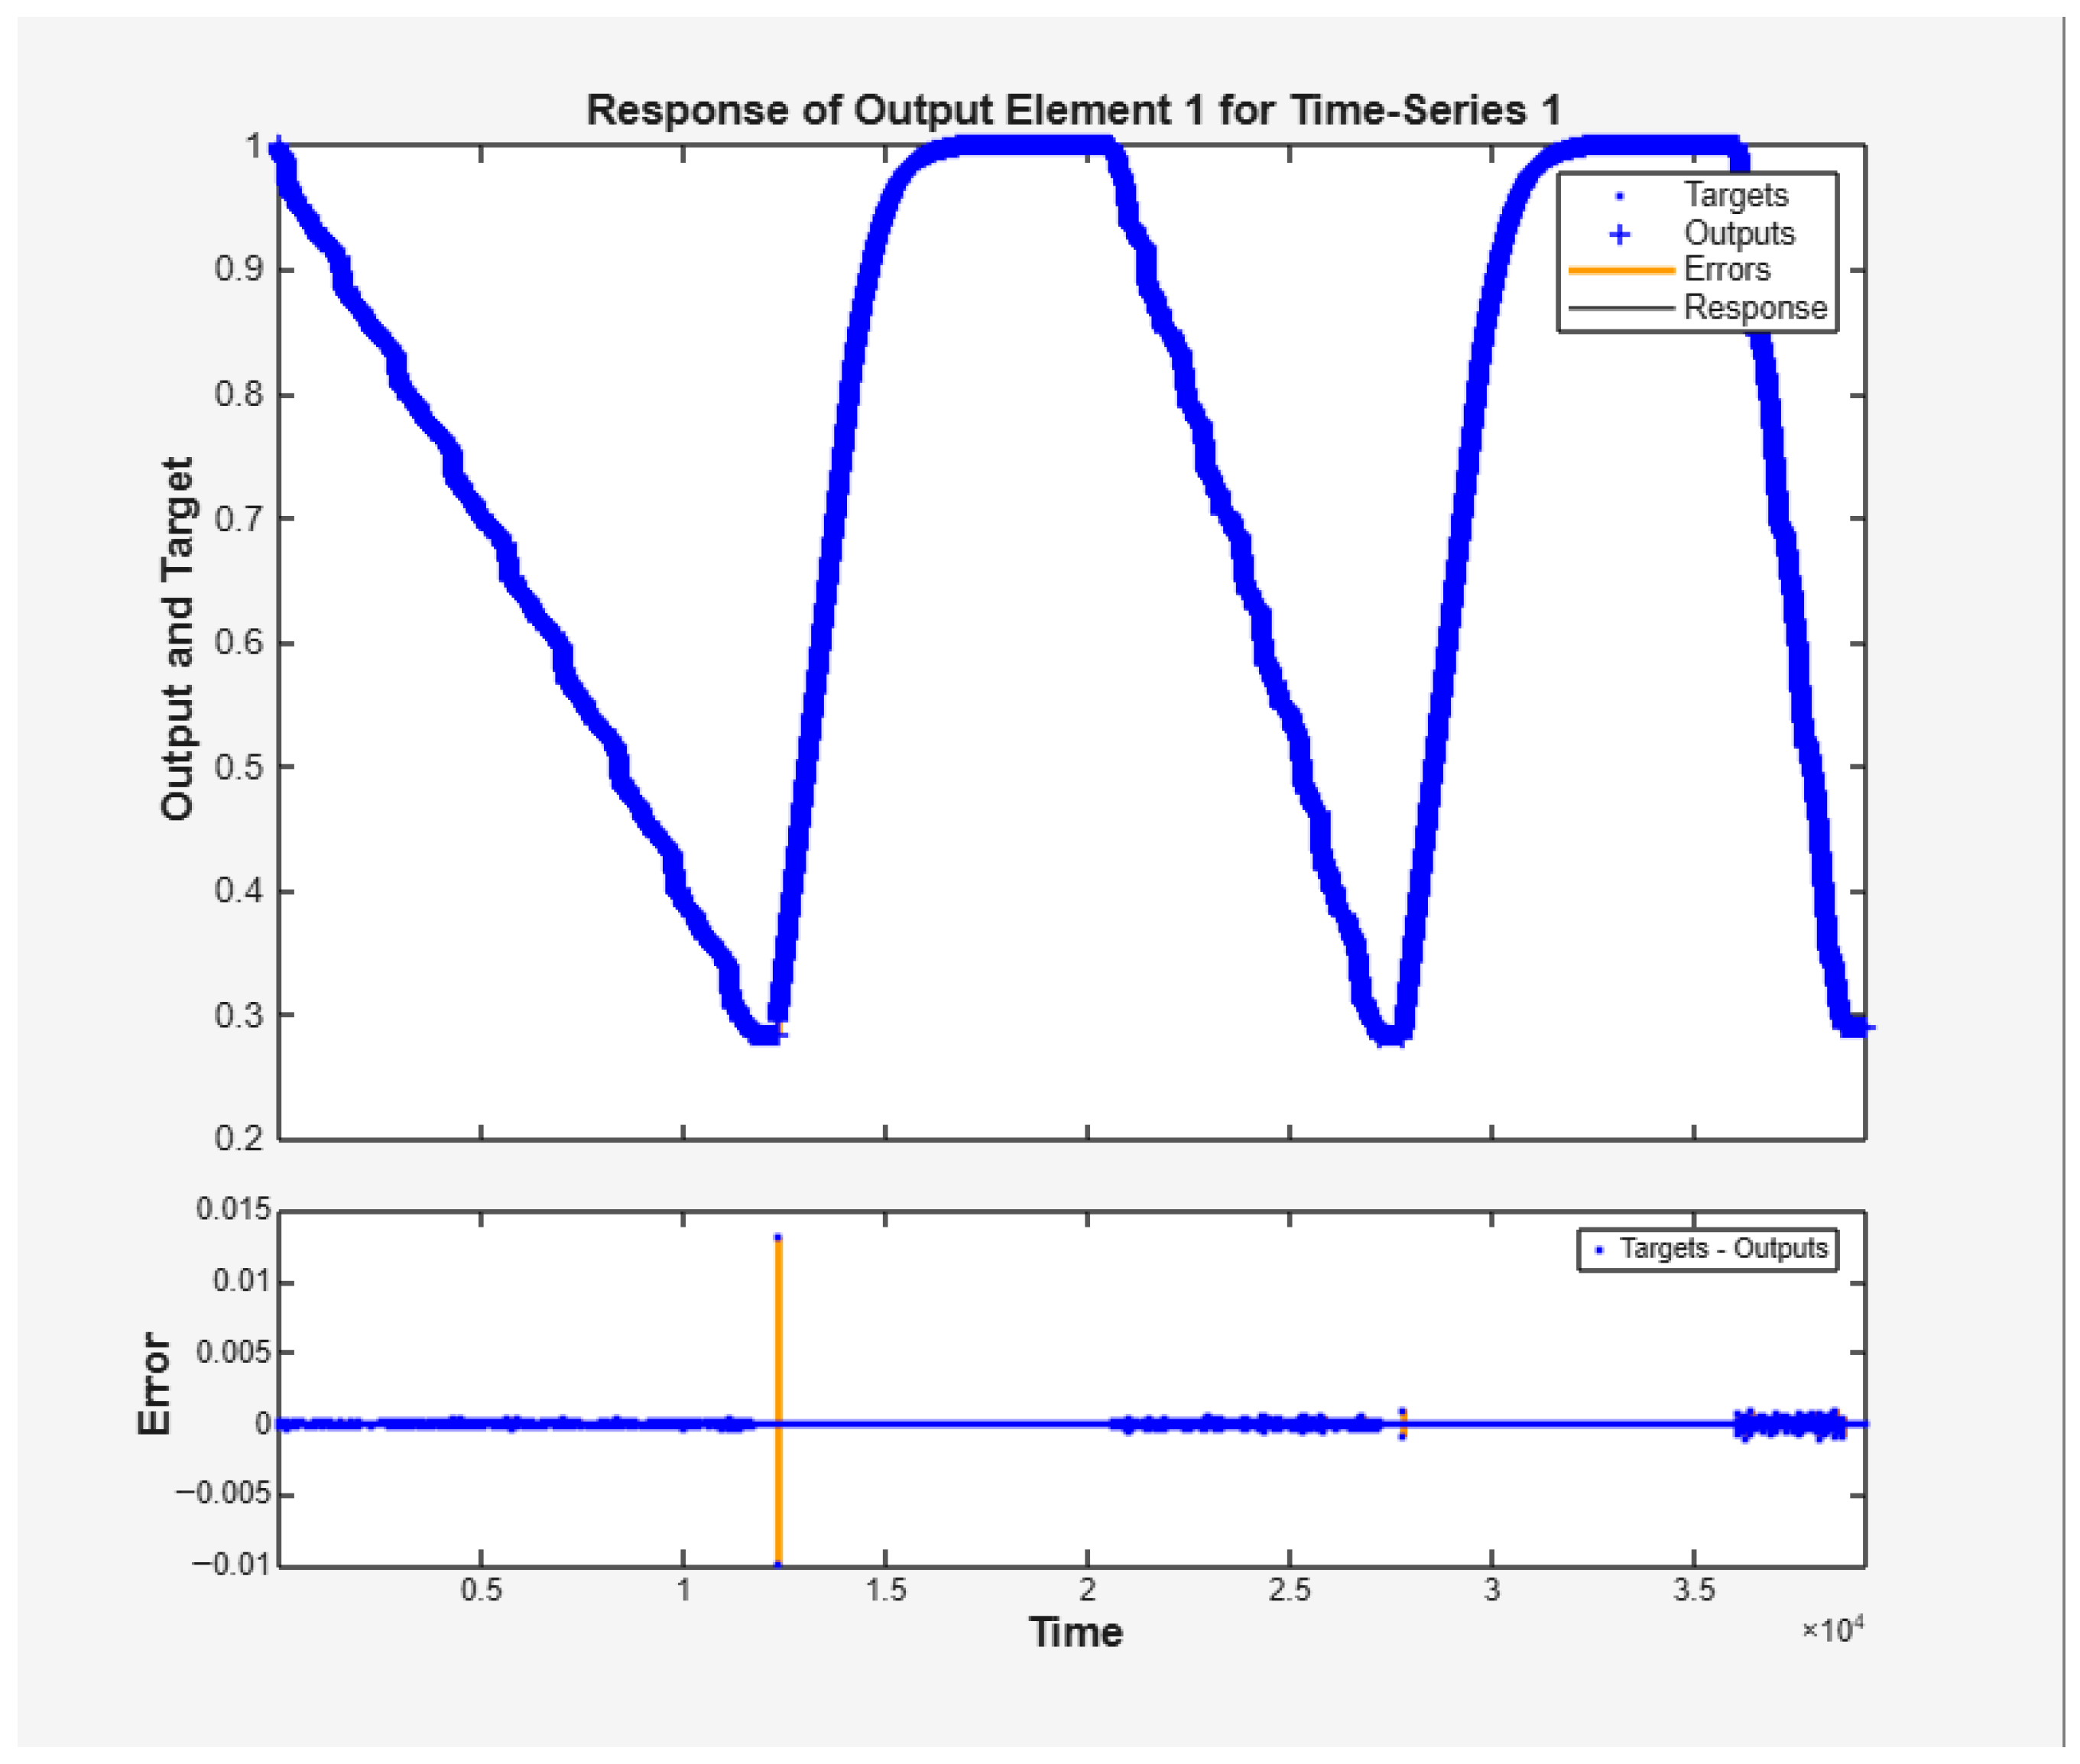
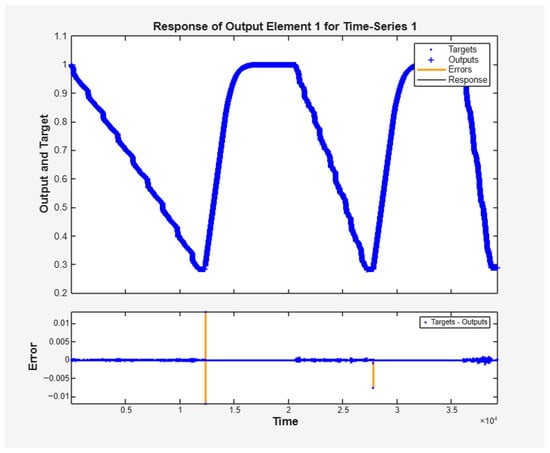
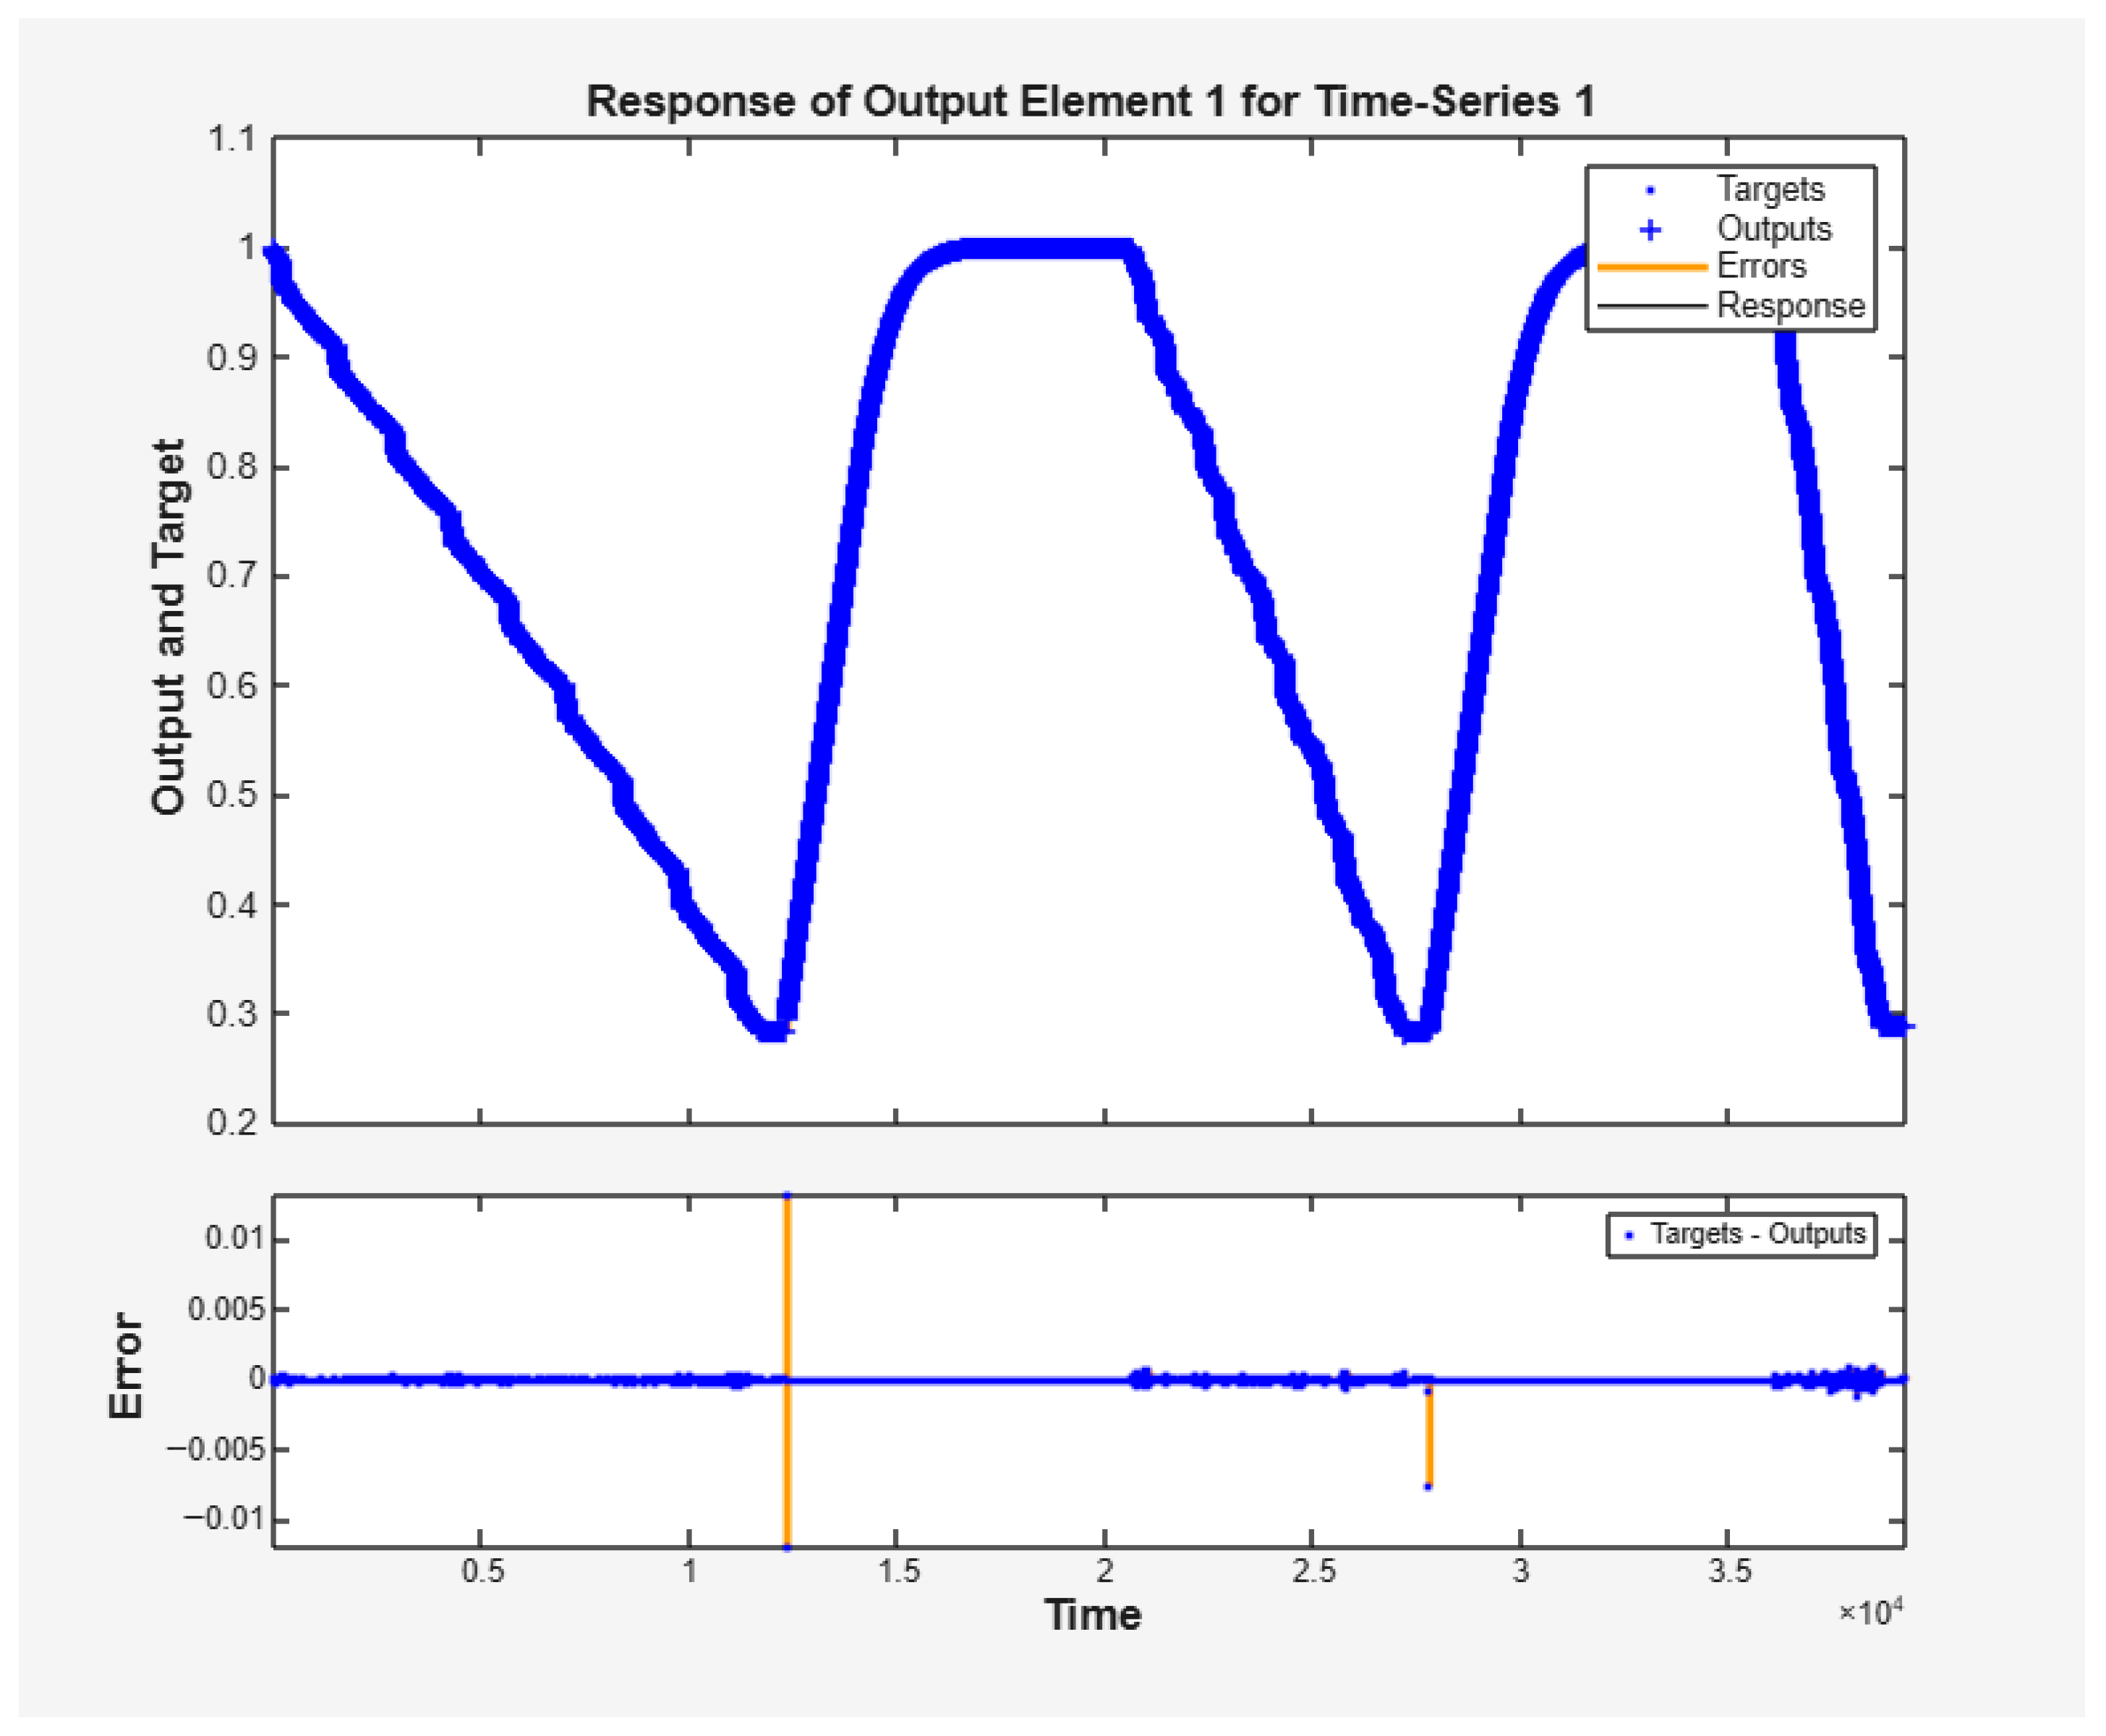
For 10-neurons LM NAR-FNN, the time-series plot as shown in Figure 17, demonstrates perfect alignment between the predicted and actual SoC curves across two full charge–discharge cycles, with no visible lag or offset. The output curve lies directly on top of the target, except for one brief spike near 1.25 × 10⁴ s, where the error reaches approximately ±1.4 × 10⁻².
Figure 17.
Time-series response and errors for Test 1 using the 10-neurons LM-NAR-FNN.
3.8.3. 30-Neuron BR-Nonlinear I/O-FNN
The model’s error continues to decrease, and the correlation improves as the temperature rises. At the lowest temperature (−10 °C), the test performs worse than the other tests. As per Table 33, test 4 is the most accurate and dependable for estimating the SoC, with its best performance observed, as the model achieved a MSE of 3.81 × 10⁻⁴ and R of 0.9978, indicating high prediction accuracy and strong agreement between the estimated and actual values.
Table 33.
Test results for the 30-neuron BR-Nonlinear I/O-FNN.
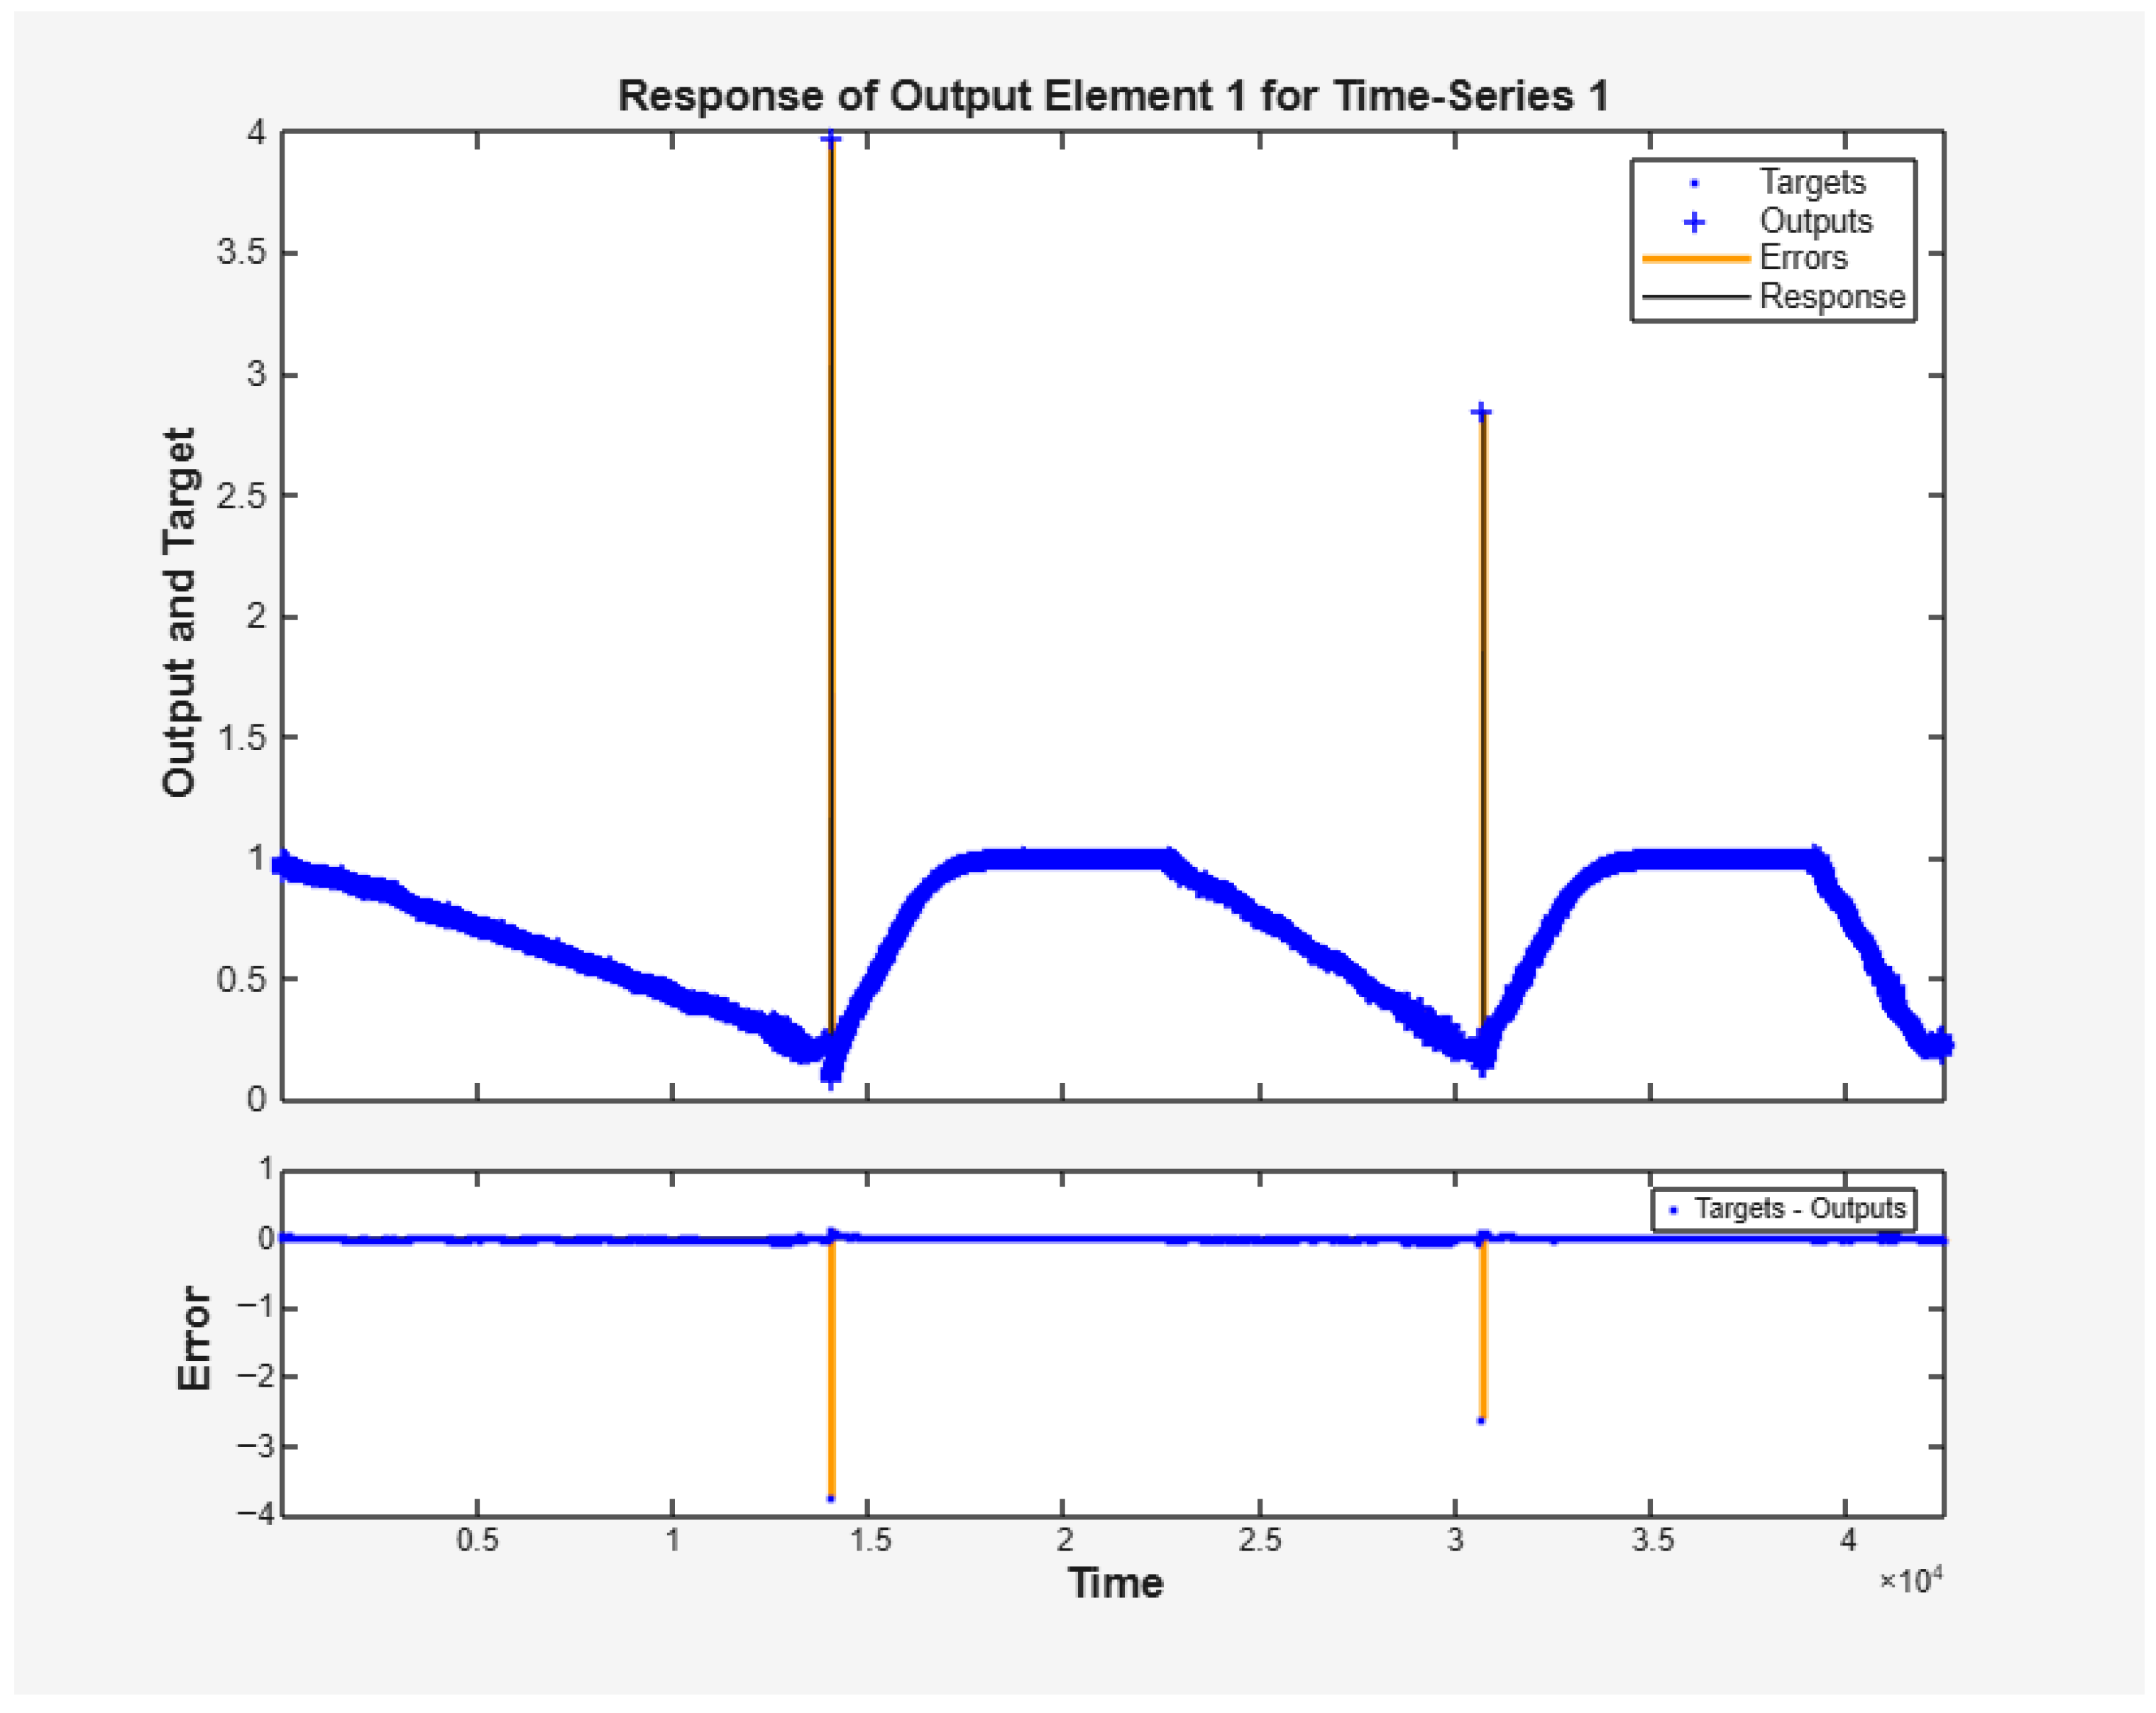
Similarly, the time series plot as illustrated in Figure 18 for 30-neuron BR-Nonlinear I/O-FNN, the most noticeable error spikes appear at around 1.4 × 10⁴ s and 3.1 × 10⁴ s, with corresponding errors of approximately −3.9 and −2.5 units, respectively.
Figure 18.
Time-series response and errors for Test 2 using the 30-neuron BR-Nonlinear I/O-FNN.
3.8.4. 10-Neuron BR-NARX-FNN
The 10-neuron BR-NARX-FNN achieves exceptionally high predictive accuracy across all four test sets as shown in Table 34. The model consistently produces extremely low MSE values, ranging from 1.3178 × 10⁻⁸ to as low as 6.5646 × 10⁻⁹, indicating near-perfect error minimization. The model maintains perfect correlation (R = 1.0000) in every test, reflecting flawless alignment between predicted and true outputs. These results confirm the model’s outstanding stability, precision, and generalization capability, making it highly reliable prediction. In Figure 19, the model output overlaps the target curve almost perfectly, with only two brief excursions approximately at 1.25 × 10⁴ s and 2.75 × 10⁴ s, pushing the error up to ±2 × 10⁻² and −0.5 × 10⁻², respectively.
Table 34.
Test results for the 10-neuron BR-NARX-FNN.
Figure 19.
Time-series response and errors for Test 1 using the 10-neuron BR-NARX-FNN.
3.8.5. Test Results for GRU Model
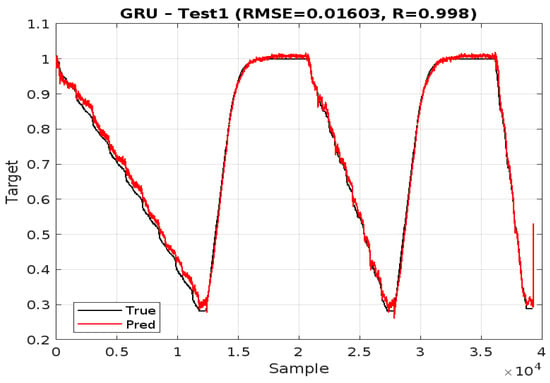
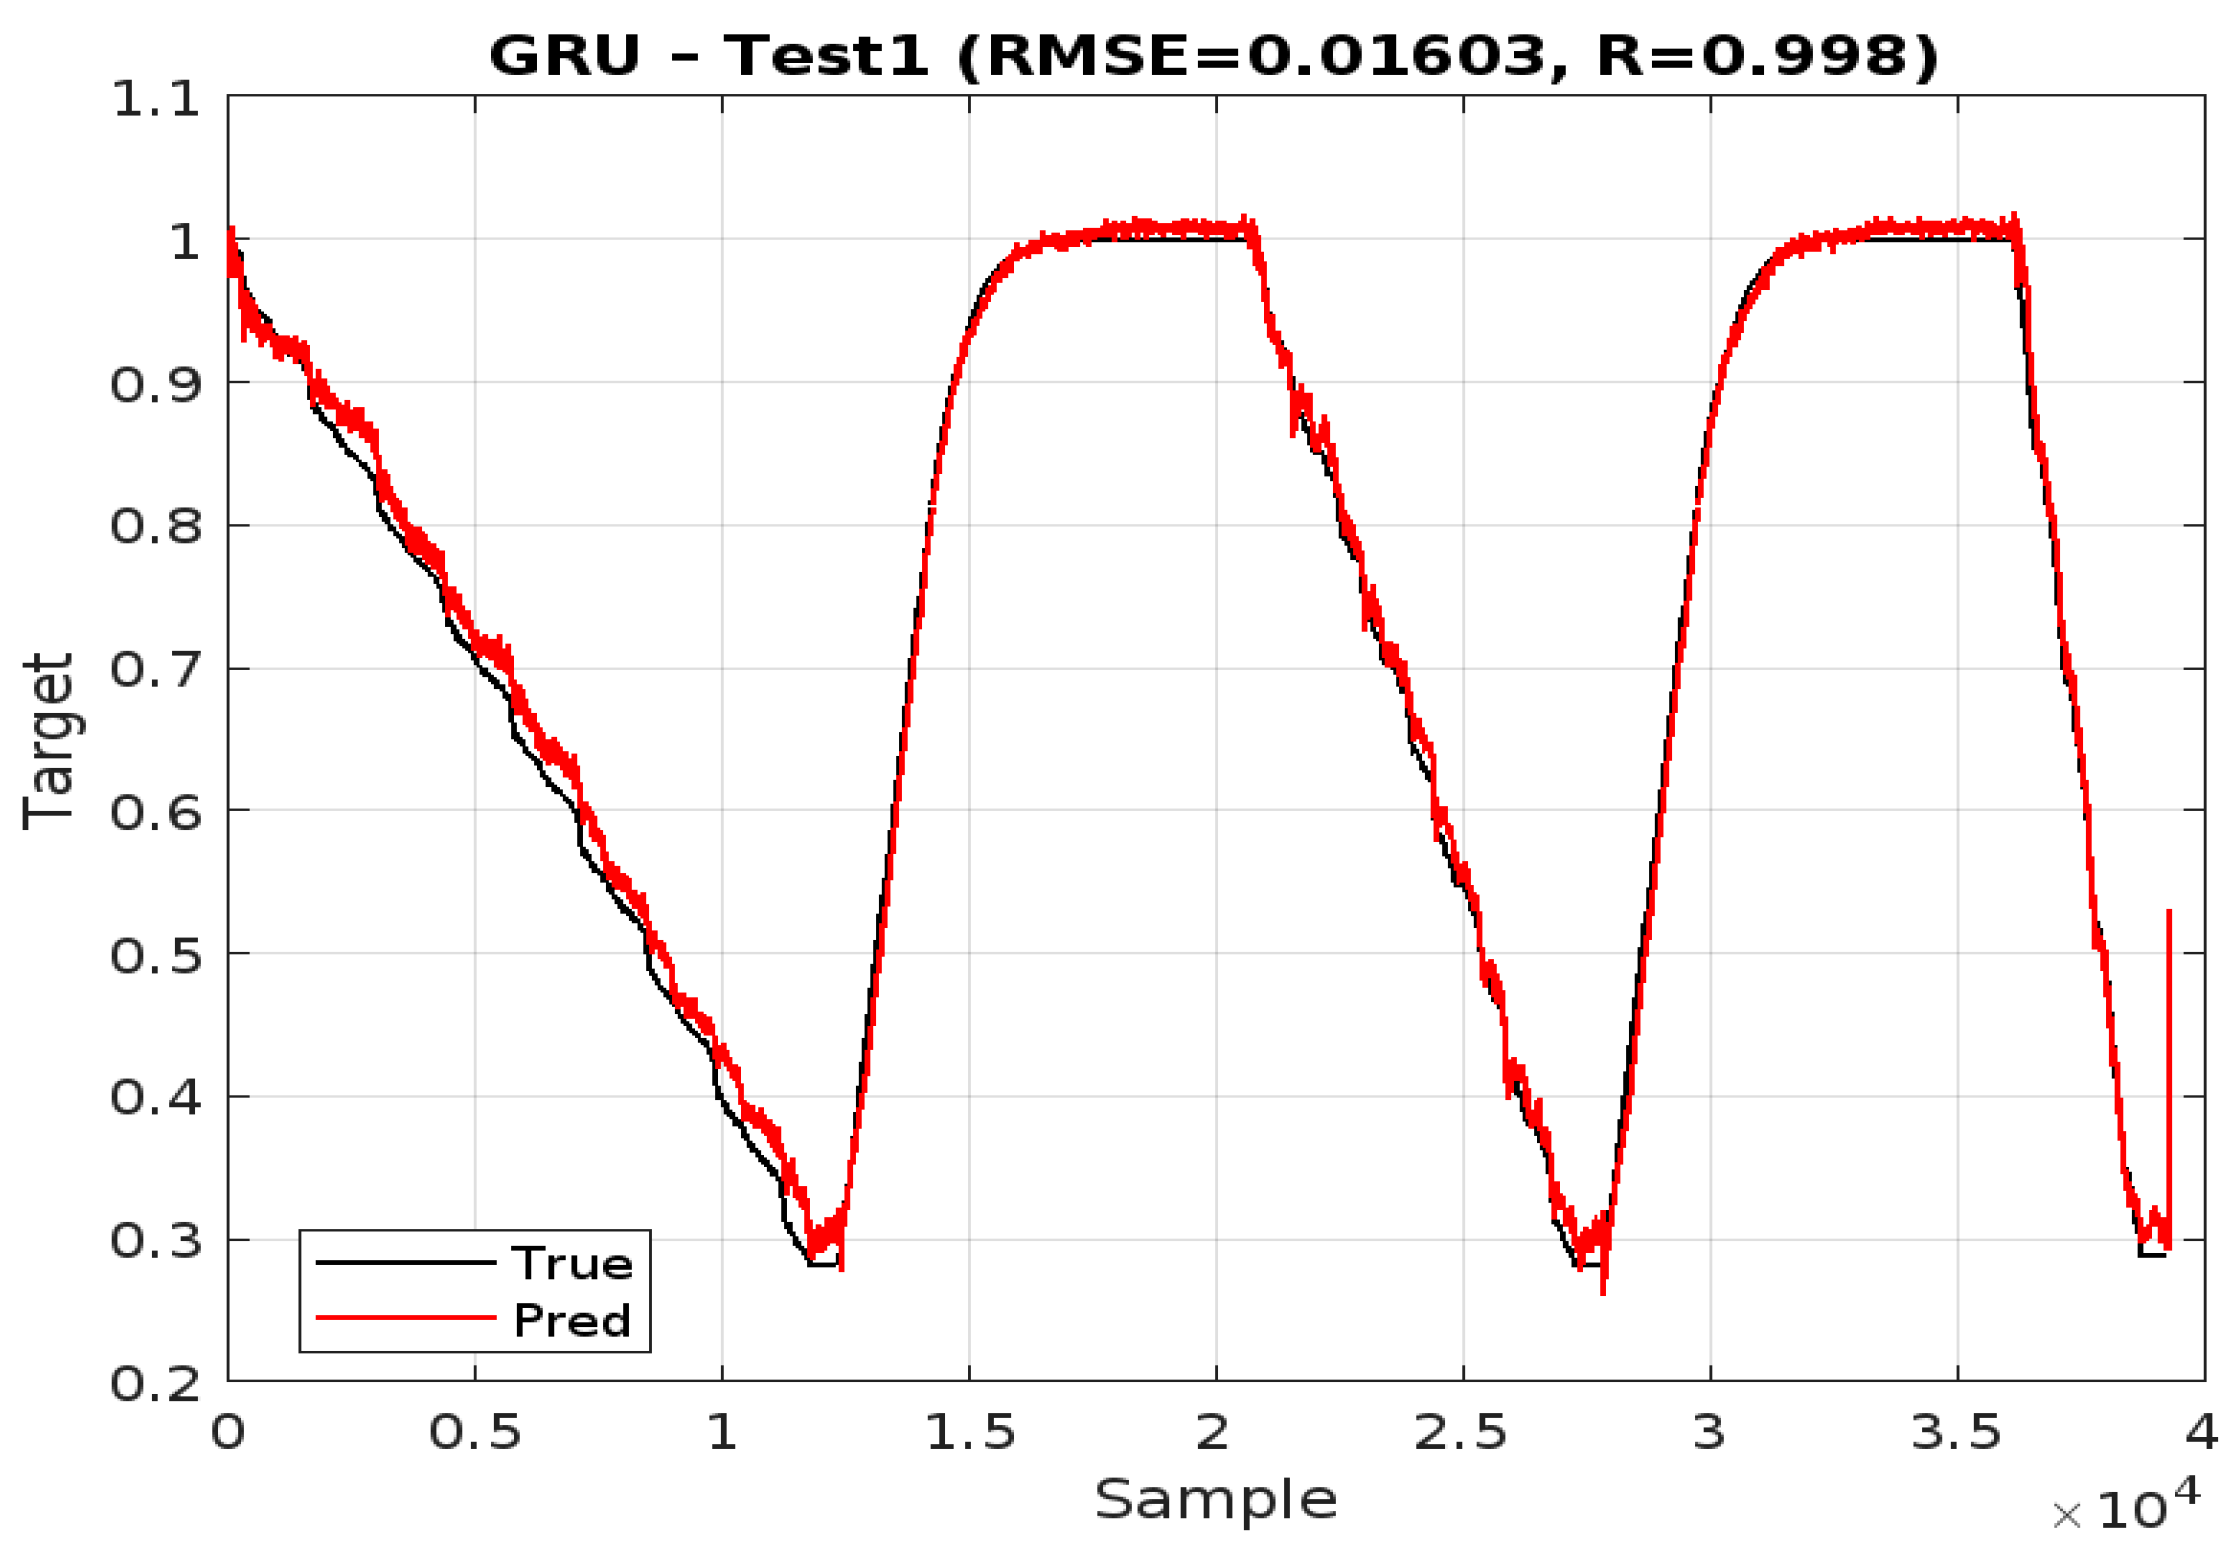
The performance of the GRU model across four distinct test sets with increasing sample sizes is shown in Table 35. The model exhibits a clear trend of improved accuracy as the sample size increases, with Test 4 achieving the optimal result and the lowest MSE of 1.7793 × 10⁻⁴. Conversely, Test 1 recorded the highest error, with an MSE of 2.5687 × 10⁻⁴. Across all partitions, the model maintained exceptional predictive strength, with Correlation (R) values consistently exceeding 0.998 and a stable Mean Overlap Count averaging approximately 3.99. In the time-series plot, as shown in Figure 20, the predicted SoC closely follows the true curve, although minor delays are observed during rapid SoC increases.
Table 35.
Test results for the GRU model.
Figure 20.
SoC prediction versus true curve for Test 1 using the GRU model.
3.8.6. LSTM Test Results
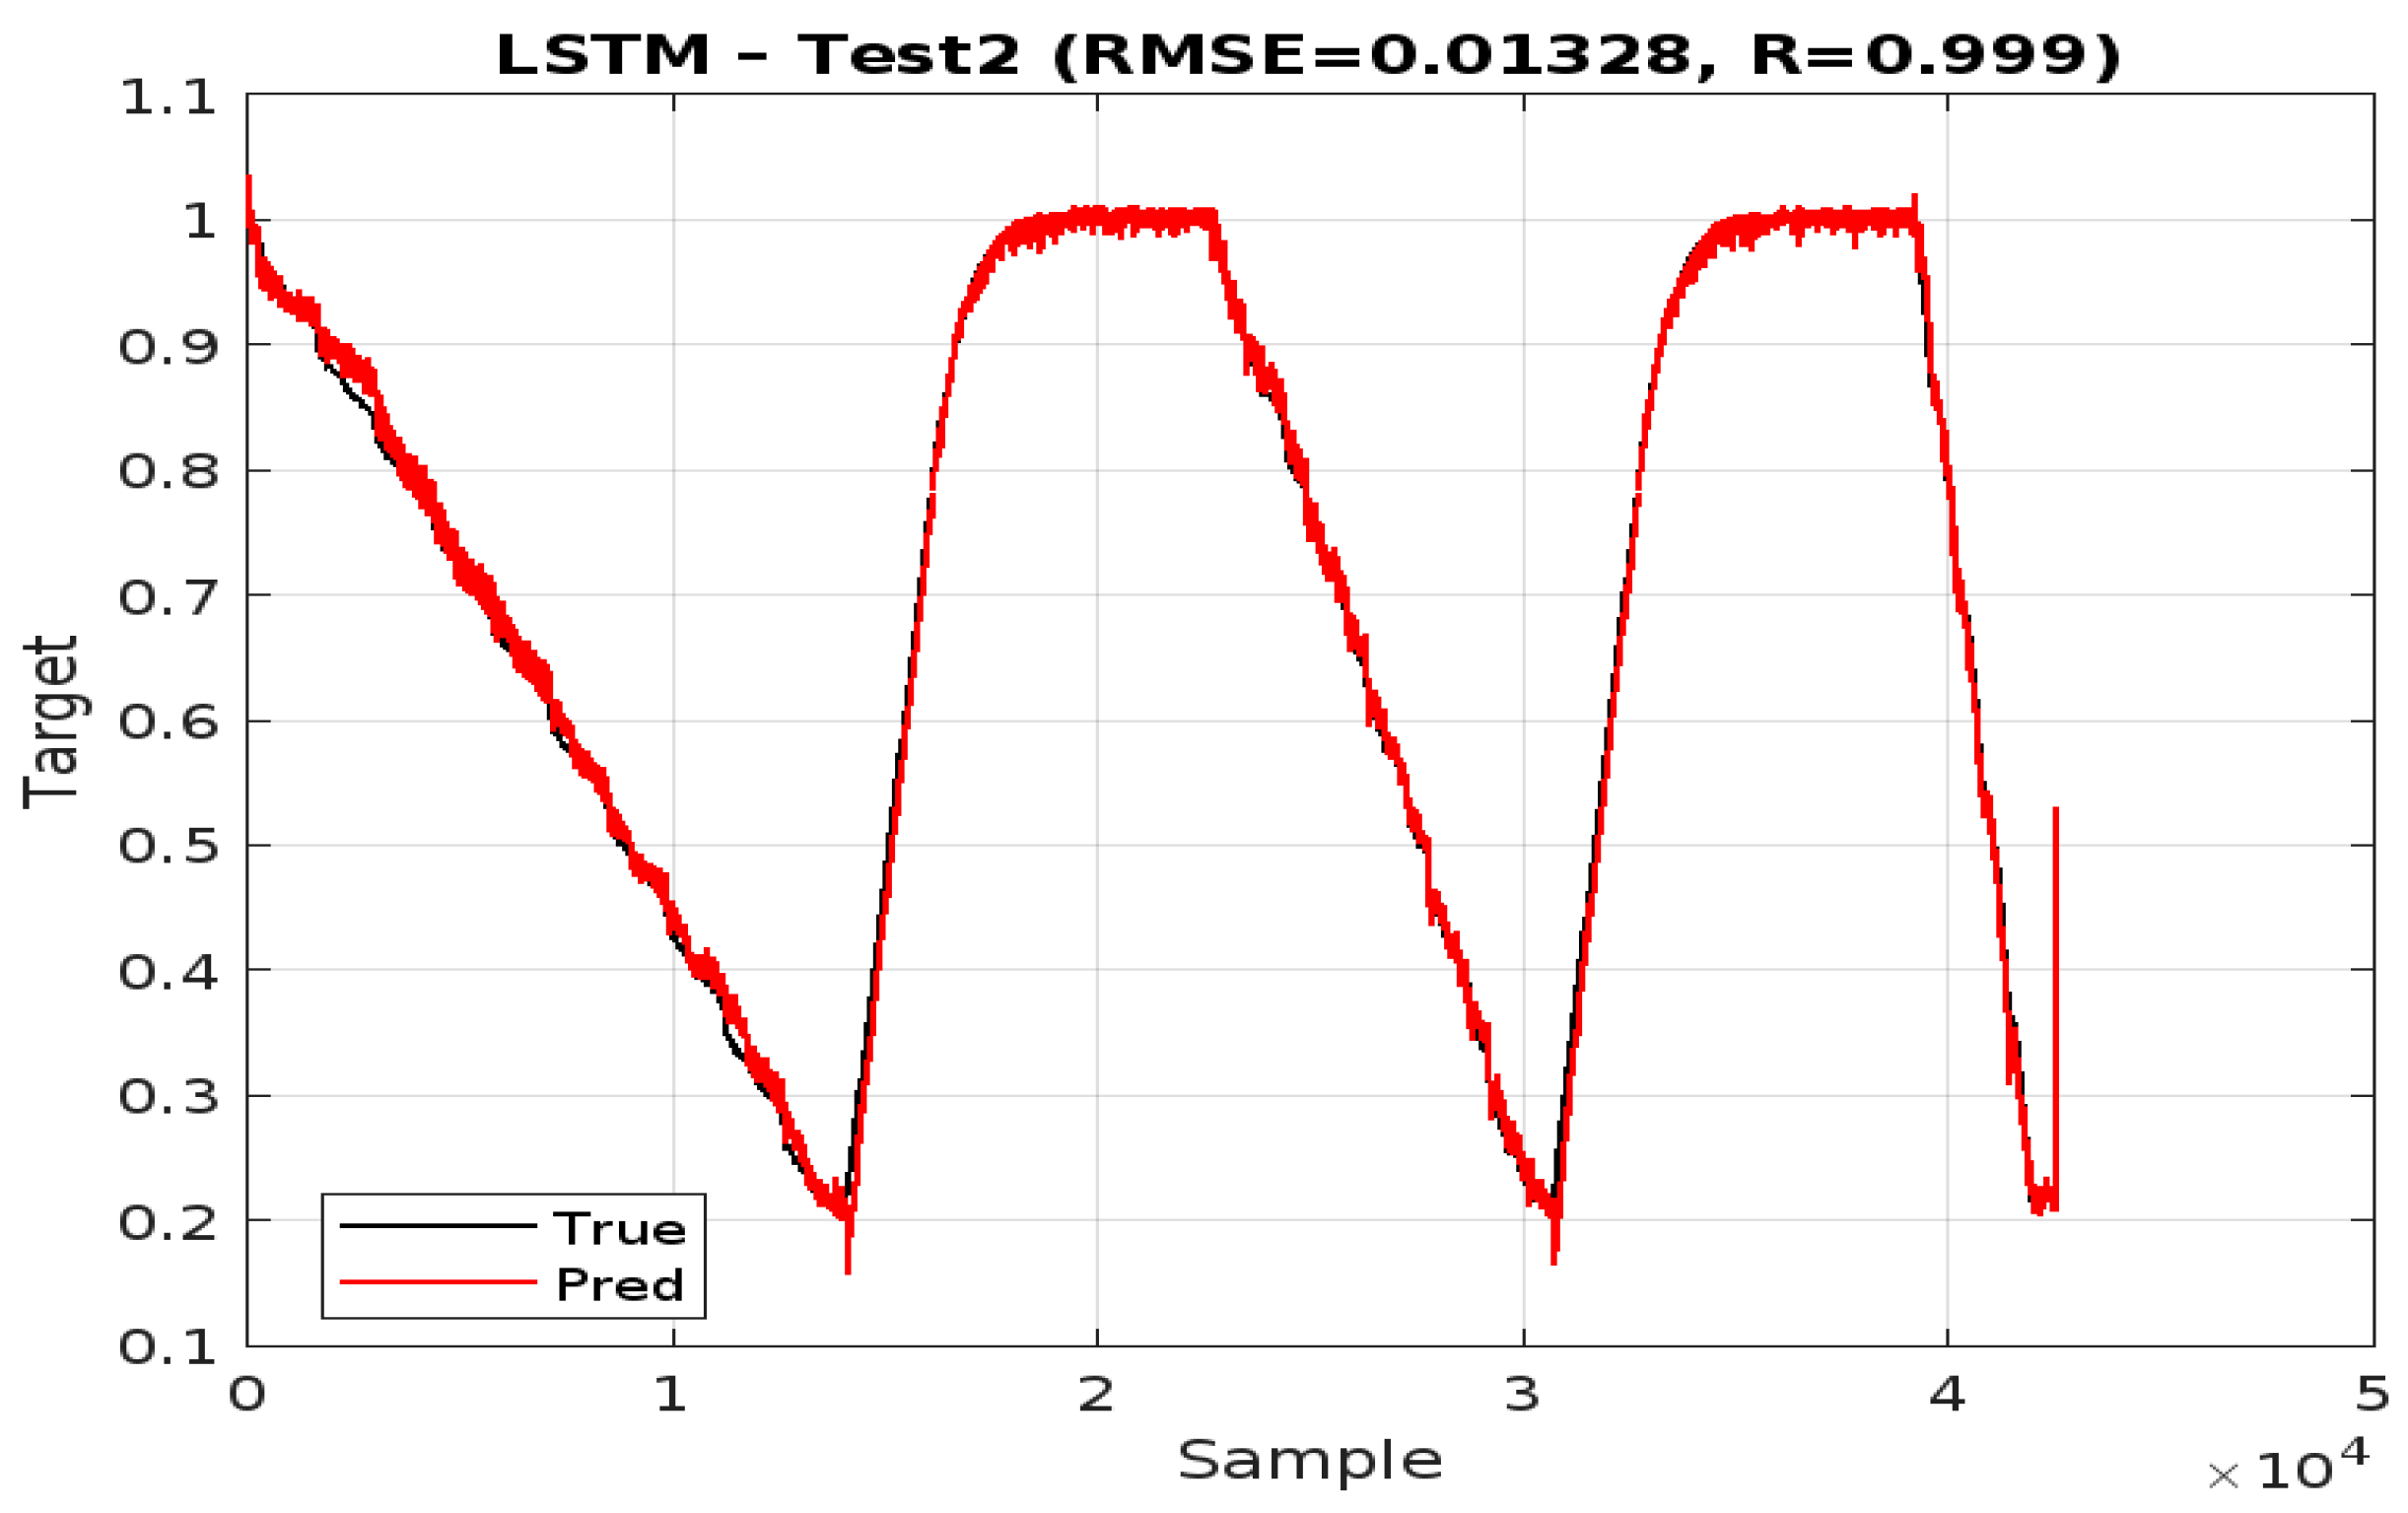
The performance results of the LSTM model show a clear temperature-dependent trend. Model accuracy steadily improves with temperature demonstrating consistently strong predictive accuracy, with MSE values ranging from 1.7065 × 10⁻⁴ to 2.9246 × 10⁻⁴, indicating low prediction error. The correlation coefficient R is extremely high, approximately 0.99 for all tests. Similarly, the R2 values ranging from 0.99612 to 0.99797 show that the model explains nearly all variance in the target output. As shown in Figure 21, performance improves and becomes more compact and symmetric, corresponding to a lower RMSE of 1.3277 × 10⁻² across 42,530 samples. The predicted SoC curve matches the true SoC almost exactly across all charging and discharging segments, with no visible phase lag.
Figure 21.
SoC prediction versus true curve for Test 2 using the LSTM model.
3.8.7. TCN Test Results
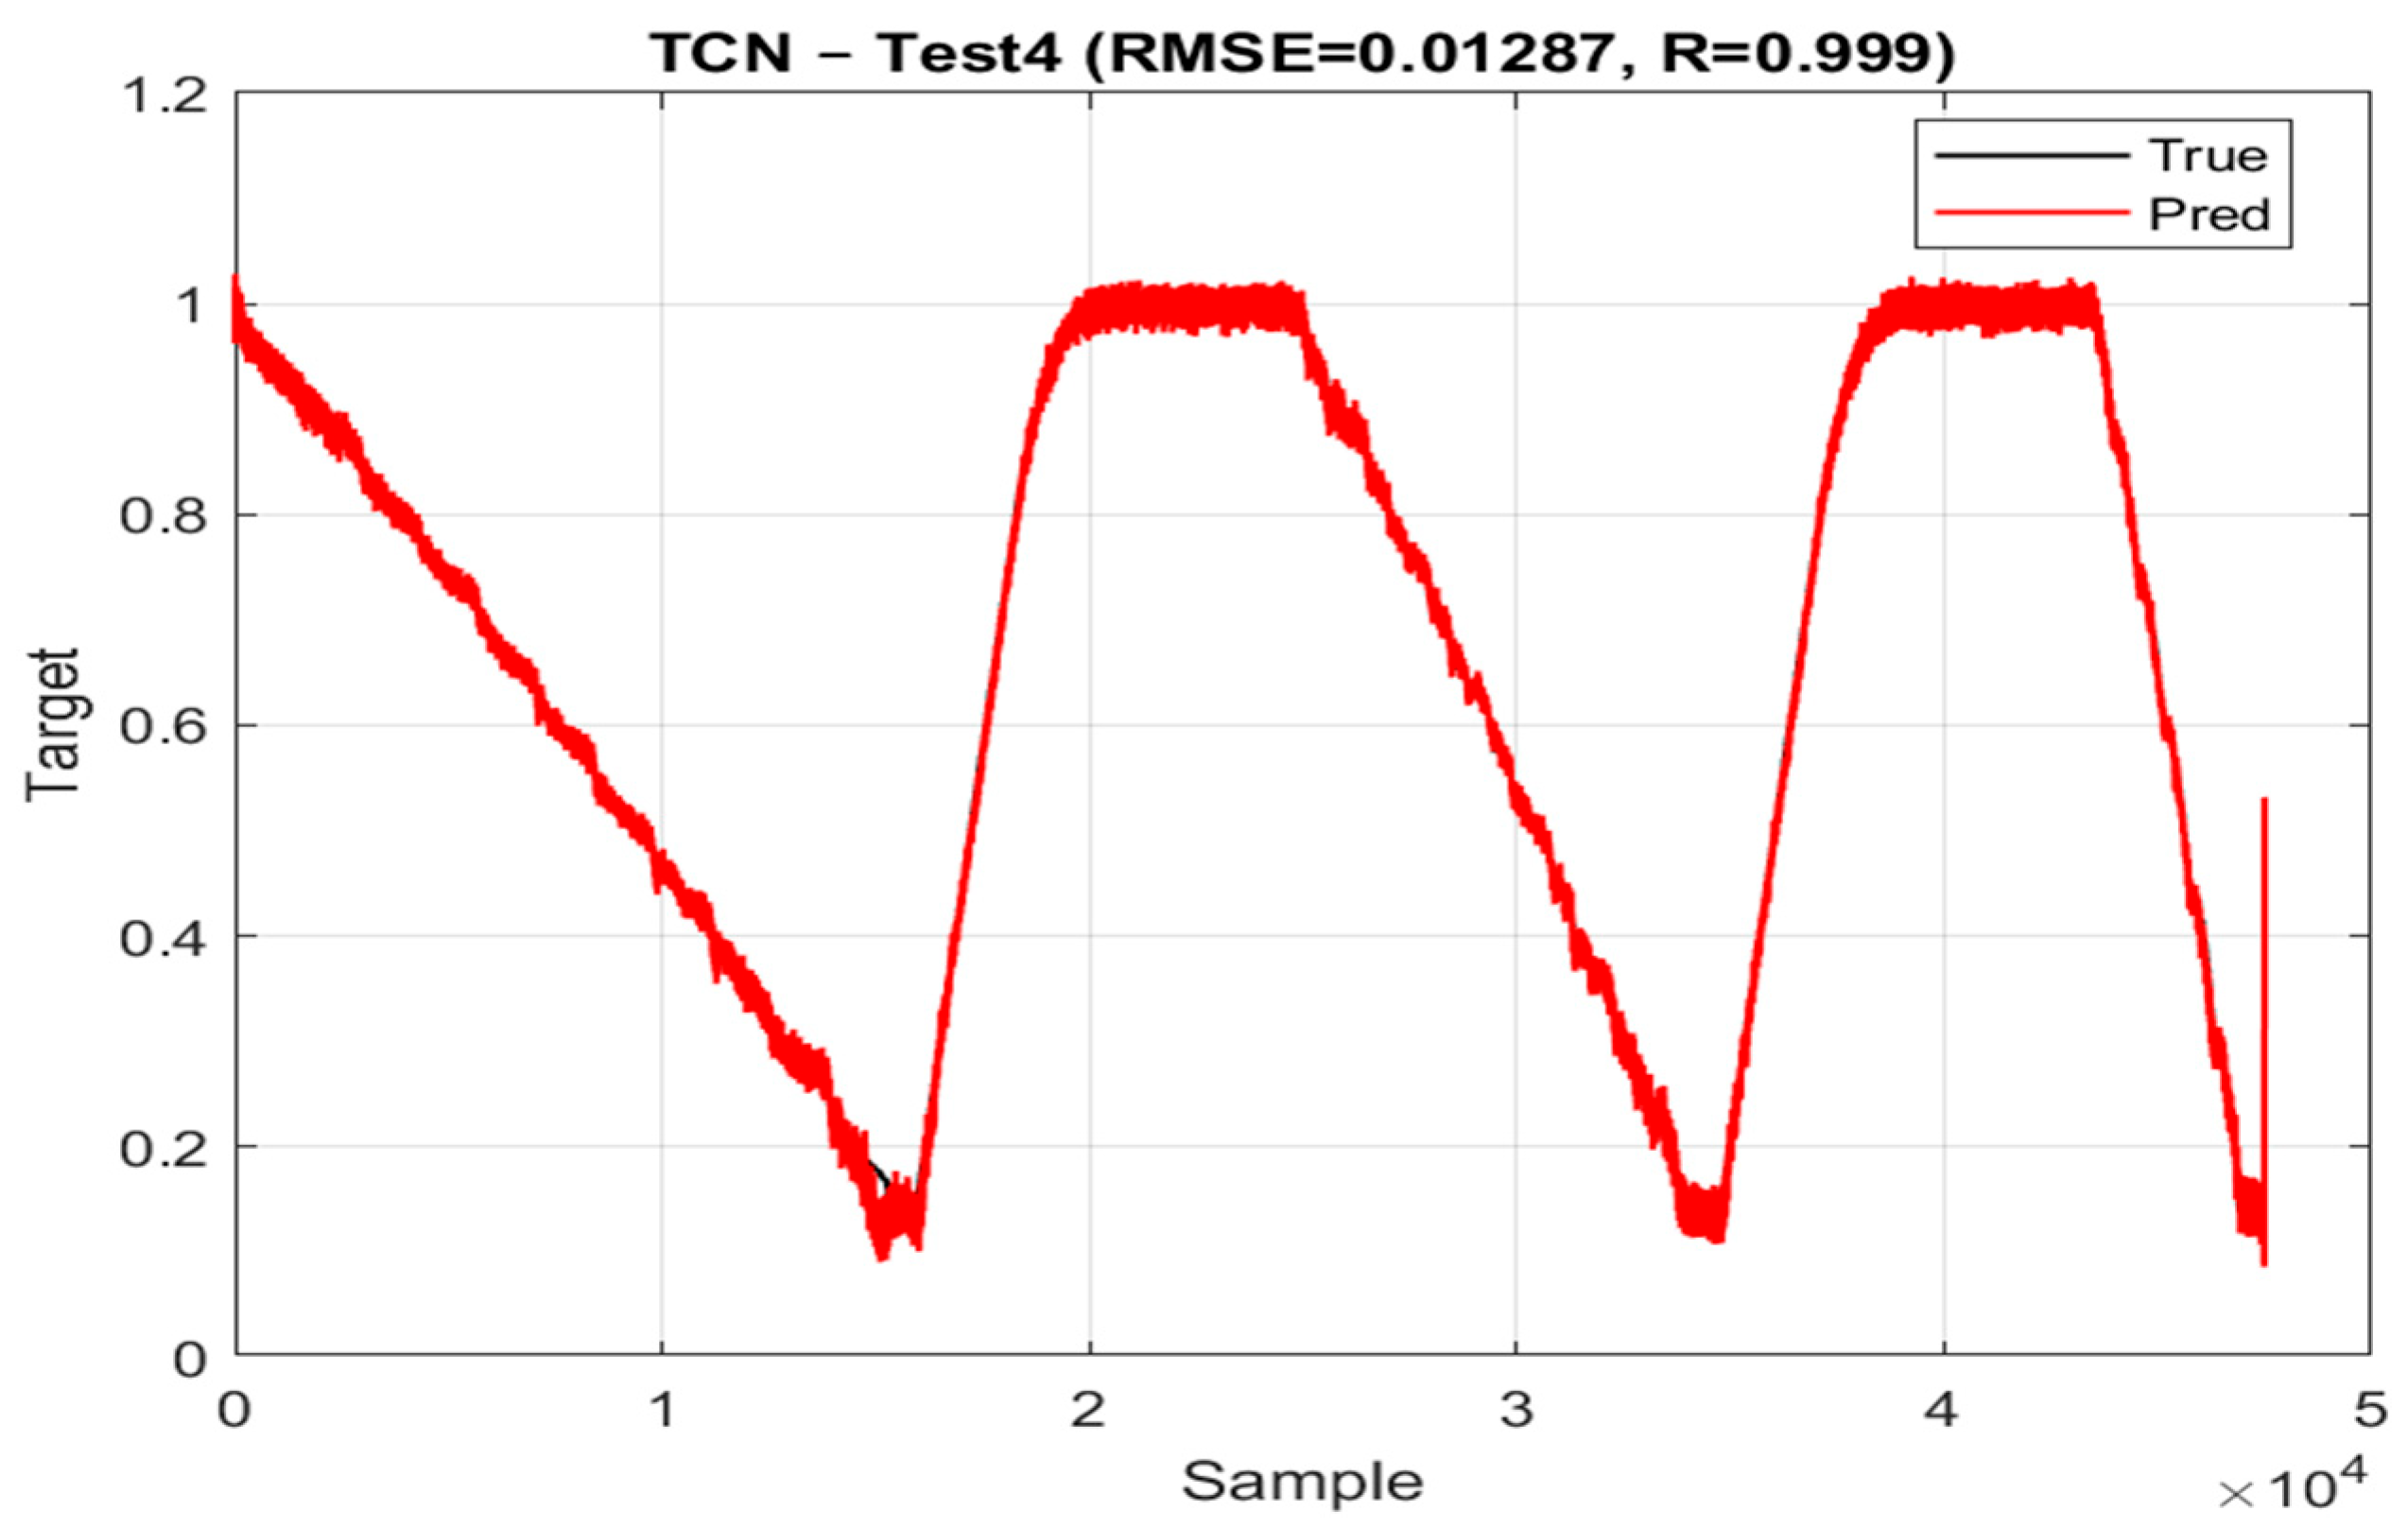
Across all four temperature conditions, the TCN model shows a clear trend. It performs best at the temperature extremes (−10 °C and 25 °C), while error increases slightly at 0 °C and peaks at 10 °C. All MSE values remain high, and R values are consistently above 0.998, showing that the model is highly reliable across a wide range of conditions. Compared with the GRU and LSTM models analyzed earlier, the TCN displays slightly better MSE than the LSTM at 25 °C. Overall, the TCN provides the most balanced performance, combining low random error with stable behavior across all SoC levels. Its best results occur at 25 °C, making that the model’s ideal operating point under the tested settings. In Figure 22, the predicted SoC closely follows the true curve during both charging and discharging, with no visible lag or deviation, which confirms that both random and systematic errors are at their lowest under these conditions.
Figure 22.
SoC prediction versus true curve for Test 4 using the TCN model.
3.9. Performance Comparison of All Models for SoC Estimation
Across the seven test tables (Table 31, Table 32, Table 33, Table 34, Table 35, Table 36 and Table 37), the effects of ambient temperature and network architecture on State of Charge (SoC) estimation can be evaluated in a structured way. In the feedforward group, the 20-neuron BR-Fitting-FNN in Table 1 shows apparent sensitivity to temperature. Its error values are highest at 10 °C and lowest at 25 °C. The positive intercept β0 also decreases as temperature increases, indicating that the model’s tendency to underpredict in cold conditions becomes less severe at warmer temperatures. In contrast, the two autoregressive feedforward models, the 10-neuron LM-NAR-FNN in Table 2 and the 10-neuron BR-NARX-FNN in Table 4, perform consistently across all temperature levels. Both maintain RMSE values around 3 × 10⁻⁵ and achieve perfect correlation with R equal to 1.0000 in every test. This high level of accuracy is achieved by relying on recent ground truth values, which limits their use in fully predictive onboard systems where past targets are unavailable. The 30-neuron BR-Nonlinear-IO-FNN in Table 3 shows both the most significant overall error and the most substantial dependence on temperature, highlighting the limitations of static input-output mappings when modeling dynamic battery behavior. Among the sequence learning models, the GRU in Table 5 and the LSTM in Table 6 show nearly identical behavior. In both cases, RMSE improves from about 1.6 × 10⁻² at −10 °C to just above 1.3 × 10⁻² at 25 °C, while correlation remains consistently high with R greater than 0.998. Both models show a slight positive bias at the lowest temperature, likely caused by increased impedance and voltage drop, but this bias disappears at warmer conditions. The TCN in Table 7 follows a similar trend but performs slightly better than the recurrent models in every test. At low temperature, its RMSE is slightly lower than that of the GRU, and at 25 °C, it achieves the best result among all sequence-based models, with an RMSE of 1.287 × 10⁻². It also produces the most symmetric residual distribution. Overall, the results suggest a clear performance ranking. If the use of past target values is acceptable, the BR-NARX-FNN delivers the highest accuracy across all temperatures. However, in fully predictive applications, the TCN offers the best combination of low random error, minimal bias, and stable performance across the whole temperature range from −10 °C to 25 °C. It consistently outperforms both GRU and LSTM models in terms of absolute accuracy and consistency, making it the most reliable sequence learning option under the tested conditions.
Table 36.
Test results for the LSTM model.
Table 37.
Test results for the TCN model.
4. Conclusions and Recommendations
This study compared four types of neural networks (FNN, LSTM, GRU, and TCN) for estimating the state of charge (SoC) in lithium-ion batteries using a unified process and fixed data splits. For the FNN models, three training algorithms were tested: Levenberg–Marquardt (LM), Bayesian Regularization (BR), and Scaled Conjugate Gradient (SCG). Each was evaluated with three hidden-layer sizes (10, 20, and 30 neurons) and across different model types: Fitting, Nonlinear Input-Output (I/O), and time-series-based NAR and NARX. All models were trained with the same preprocessing steps and input features. Their performance was assessed using metrics such as test MSE and RMSE, generalization gap, training convergence, average training time per epoch, and compute cost.
Among the Fitting-FNN models, the 20-neuron BR version showed the best balance between accuracy and training cost. The 30-neuron LM version performed slightly better in terms of accuracy but required more training time. The SCG-Fitting-FNN was faster but less accurate. For the Nonlinear I/O topology, the 30-neuron BR model gave the best results with strong regularization effects, while the 20-neuron LM model also performed well but took longer to converge. In the NAR models, the 10-neuron LM version achieved the lowest test error and stable convergence, although it is very negative generalization gap may mean the test data was easier than expected. The 30-neuron BR-NAR model was also reliable, though more computationally expensive. In the NARX models, the 20-neuron LM version achieved the highest accuracy. The 10-neuron BR version showed clean convergence and low compute cost, while the SCG version trained quickly but did not match LM’s accuracy.
In practical terms, the BR-Nonlinear I/O-FNN with 30 neurons and the LM-NARX-FNN with 20 neurons are the top choices when accuracy is the primary goal. The LM-NAR-FNN with 10 neurons can also be considered, but only after confirming its reliability on different data splits. For a balanced option between accuracy and computation time, the BR-Fitting-FNN with 20 neurons or the BR-Nonlinear I/O-FNN with 20 neurons is recommended. When fast training and low resource use are required, SCG-based models with 10 or 20 neurons are suitable.
The trained machine learning models in this study can be readily deployed in a Battery Management System (BMS) for real-time state-of-charge (SoC) estimation. In practice, the model would receive measured inputs such as voltage, current, and temperature from embedded sensors within the battery pack. These inputs are preprocessed—using normalization and windowing consistent with the training phase—and fed into the trained neural network to predict SoC instantaneously. The model can operate on embedded platforms such as microcontrollers, digital signal processors (DSPs), or edge computing units, depending on the computational complexity of the selected architecture (e.g., FNN, LSTM, GRU, or TCN).
However, these findings come with some limitations. The results are based on a single-cell dataset and a fixed data split. Very negative generalization gaps in some runs may indicate that the test split was easier, so more testing is needed. Battery aging, variation between cells, and pack-level behavior were not included. Uncertainty estimation was not performed, except for the effect of BR’s regularization. Also, real-time hardware limitations were not considered during training or model selection.
Future studies should include better validation methods like k-fold and temperature-based splits. More focus should be placed on adapting models to different temperatures and battery aging. Combining neural networks with physical models or Kalman filters could also improve accuracy and interpretability. Adding uncertainty estimation methods like dropout or ensemble learning, and testing deployment with pruning and quantization on real embedded systems, will help make the models more practical. Applying the same evaluation process to LSTM, GRU, and TCN models will provide a complete picture of the accuracy and efficiency trade-offs for real-time SoC estimation. In addition, a detailed analysis of hardware-specific parameter counts, and real-time inference performance can be explored to further validate the machine learning models.
Author Contributions
Conceptualization, M.A.; methodology, M.A. and M.I.H.; software, M.A.; validation, M.A., M.I.H. and M.S.; formal analysis, M.A., M.I.H. and M.S.; investigation, M.A.; resources, M.I.H.; data curation, M.A.; writing—original draft preparation, M.A.; writing—review and editing, M.I.H. and M.S., visualization, M.A. and M.I.H.; supervision, M.I.H.; project administration, M.I.H.; funding acquisition, M.I.H. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
We used data from reference [28] for training, testing, and validating the machine learning models.
Acknowledgments
The authors would like to acknowledge the support provided by the Deanship of Research at King Fahd University of Petroleum & Minerals. Dr. Md Ismail Hossain also acknowledges the resources and facilities provided by the Interdisciplinary Research Center for Aviation & Space Exploration (IRC-ASE), King Fahd University of Petroleum & Minerals, through the funded research project # INAE2501.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Alkouli, M.; Hossain, M.I.; Abido, M.A. Artificial Intelligence Approach to State of Charge Estimation for Smart Battery Management Systems. In Proceedings of the 2024 IEEE 8th Forum on Research and Technologies for Society and Industry Innovation (RTSI), Milano, Italy, 18–20 September 2024; pp. 154–159. [Google Scholar]
- Charkhgard, M.; Farrokhi, M. State-of-charge estimation for lithium-ion batteries using neural networks and extended Kalman filter. IEEE Trans. Ind. Electron. 2010, 57, 4178–4187. [Google Scholar] [CrossRef] [Scilit]
- Chang, C.; Bian, C.; He, H.; Li, J.; Li, S. State-of-charge estimation of Li-ion batteries using deep neural networks: A machine-learning approach. J. Power Sources 2018, 400, 242–255. [Google Scholar]
- Lea, C.; Flynn, M.D.; Vidal, R.; Reiter, A.; Hager, G.D. Temporal convolutional networks for action segmentation and detection. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Honolulu, HI, USA, 21–26 July 2017; pp. 1003–1012. [Google Scholar]
- Mohanty, N.; Goyal, N.K.; Naikan, V.A. Effect of training algorithms in accurate state-of-charge estimation of lithium-ion batteries using NARX model. Int. J. Heavy Veh. Syst. 2023, 30, 232–254. [Google Scholar] [CrossRef] [Scilit]
- Cao, X.; Li, Y.; Zhang, L.; Liu, J.; Wang, C. State of charge estimation for lithium-ion batteries using gated recurrent unit and adaptive Kalman filter. J. Energy Storage 2022, 55, 105396. [Google Scholar]
- Hu, C.; Cheng, F.; Ma, L.; Li, B. State-of-charge estimation for lithium-ion batteries based on TCN-LSTM neural networks. J. Electrochem. Soc. 2022, 169, 030544. [Google Scholar] [CrossRef] [Scilit]
- Hornik, K.; Stinchcombe, M.; White, H. Multilayer feedforward networks are universal approximators. Neural Netw. 1989, 2, 359–366. [Google Scholar] [CrossRef] [Scilit]
- Wilamowski, W.J.; Yu, H. Levenberg–Marquardt Training. In Industrial Electronics Handbook, 2nd ed.; CRC Press: Boca Raton, FL, USA, 2011; Chapter 12. [Google Scholar]
- Xiong, R.; Zhang, Y.; He, H.; Sun, F. A data-driven multi-scale extended Kalman filtering approach for lithium-ion battery state of charge estimation. Appl. Energy 2014, 113, 463–476. [Google Scholar] [CrossRef] [Scilit]
- Levenberg, K. A method for the solution of certain non-linear problems in least squares. Q. Appl. Math. 1944, 2, 164–168. [Google Scholar] [CrossRef] [Scilit]
- Marquardt, D.W. An algorithm for least-squares estimation of nonlinear parameters. J. Soc. Ind. Appl. Math. 1963, 11, 431–441. [Google Scholar] [CrossRef] [Scilit]
- MacKay, D.J.C. Bayesian interpolation. Neural Comput. 1992, 4, 415–447. [Google Scholar] [CrossRef] [Scilit]
- Foresee, F.D.; Hagan, M.T. Gauss–Newton approximation to Bayesian regularization. In Proceedings of the IEEE International Conference on Neural Networks, Houston, TX, USA, 9–12 June 1997; pp. 1930–1935. [Google Scholar]
- Møller, M.F. A scaled conjugate gradient algorithm for fast supervised learning. Neural Netw. 1993, 6, 525–533. [Google Scholar] [CrossRef] [Scilit]
- MathWorks. Neural Network Time Series app: Design Time-Series Networks; Documentation; MathWorks: Natick, MA, USA, 2021. [Google Scholar]
- MathWorks. narnet—Nonlinear Autoregressive Neural Network; Documentation; MathWorks: Natick, MA, USA, 2021. [Google Scholar]
- MathWorks. Design Time Series NARX Feedback Neural Networks; Documentation; MathWorks: Natick, MA, USA, 2021. [Google Scholar]
- Lin, T.; Horne, B.G.; Tino, P.; Giles, C.L. Learning long-term dependencies in NARX recurrent neural networks. IEEE Trans. Neural Netw. 1996, 7, 1329–1338. [Google Scholar] [PubMed]
- Hochreiter, S.; Schmidhuber, J. Long short-term memory. Neural Comput. 1997, 9, 1735–1780. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Chemali, E.; Kollmeyer, P.J.; Preindl, M.; Ahmed, R.; Emadi, A.; Kollmeyer, P. Long short-term memory networks for accurate state-of-charge estimation of Li-ion batteries. IEEE Trans. Ind. Electron. 2018, 65, 6730–6739. [Google Scholar] [CrossRef] [Scilit]
- Cho, K.; van Merriënboer, B.; Gulcehre, C.; Bahdanau, D.; Bougares, F.; Schwenk, H.; Bengio, Y. Learning phrase representations using RNN encoder–decoder for statistical machine translation. arXiv 2014, arXiv:1406.1078. [Google Scholar]
- Bai, S.; Kolter, J.Z.; Koltun, V. An empirical evaluation of generic convolutional and recurrent networks for sequence modeling. arXiv 2018, arXiv:1803.01271. [Google Scholar] [CrossRef] [Scilit]
- Kang, Y.; Zhao, Y.; Wu, Q. Deep learning approach toward accurate state of charge estimation of lithium-ion batteries. Sci. Rep. 2021, 11, 98915. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Liao, L.; Li, H.; Shang, W.; Ma, L. An empirical study of the impact of hyperparameter tuning and model optimization on the performance properties of deep neural networks. ACM Trans. Softw. Eng. Methodol. 2022, 31, 1–40. [Google Scholar] [CrossRef] [Scilit]
- Zhan, Z.-H.; Shi, L.; Tan, K.C.; Zhang, J. A survey on evolutionary computation for complex continuous optimization. Artif. Intell. Rev. 2022, 55, 59–110. [Google Scholar] [CrossRef] [Scilit]
- Raiaan, M.A.K.; Mukta, S.H.; Fatema, K.; Fahad, N.M.; Sakib, S.; Mim, M.M.J.; Ahmad, J.; Ali, M.E.; Azam, S. A review on large language models: Architectures, applications, taxonomies, open issues and challenges. IEEE Access 2024, 12, 26839–26874. [Google Scholar] [CrossRef] [Scilit]
- Kollmeyer, P.; Vidal, C.; Naguib, M.; Skells, M. LG 18650HG2 Li-ion Battery Data and Example Deep Neural Network xEV SOC Estimator Script. Mendeley Data, V3. Available online: https://data.mendeley.com/datasets/cp3473x7xv/3 (accessed on 21 December 2025).

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.