RSMamDet: Efficient UAV Remote Sensing Vehicle Detection via Linear State Space Models and Adaptive Multi-Level Feature Fusion

Highlights
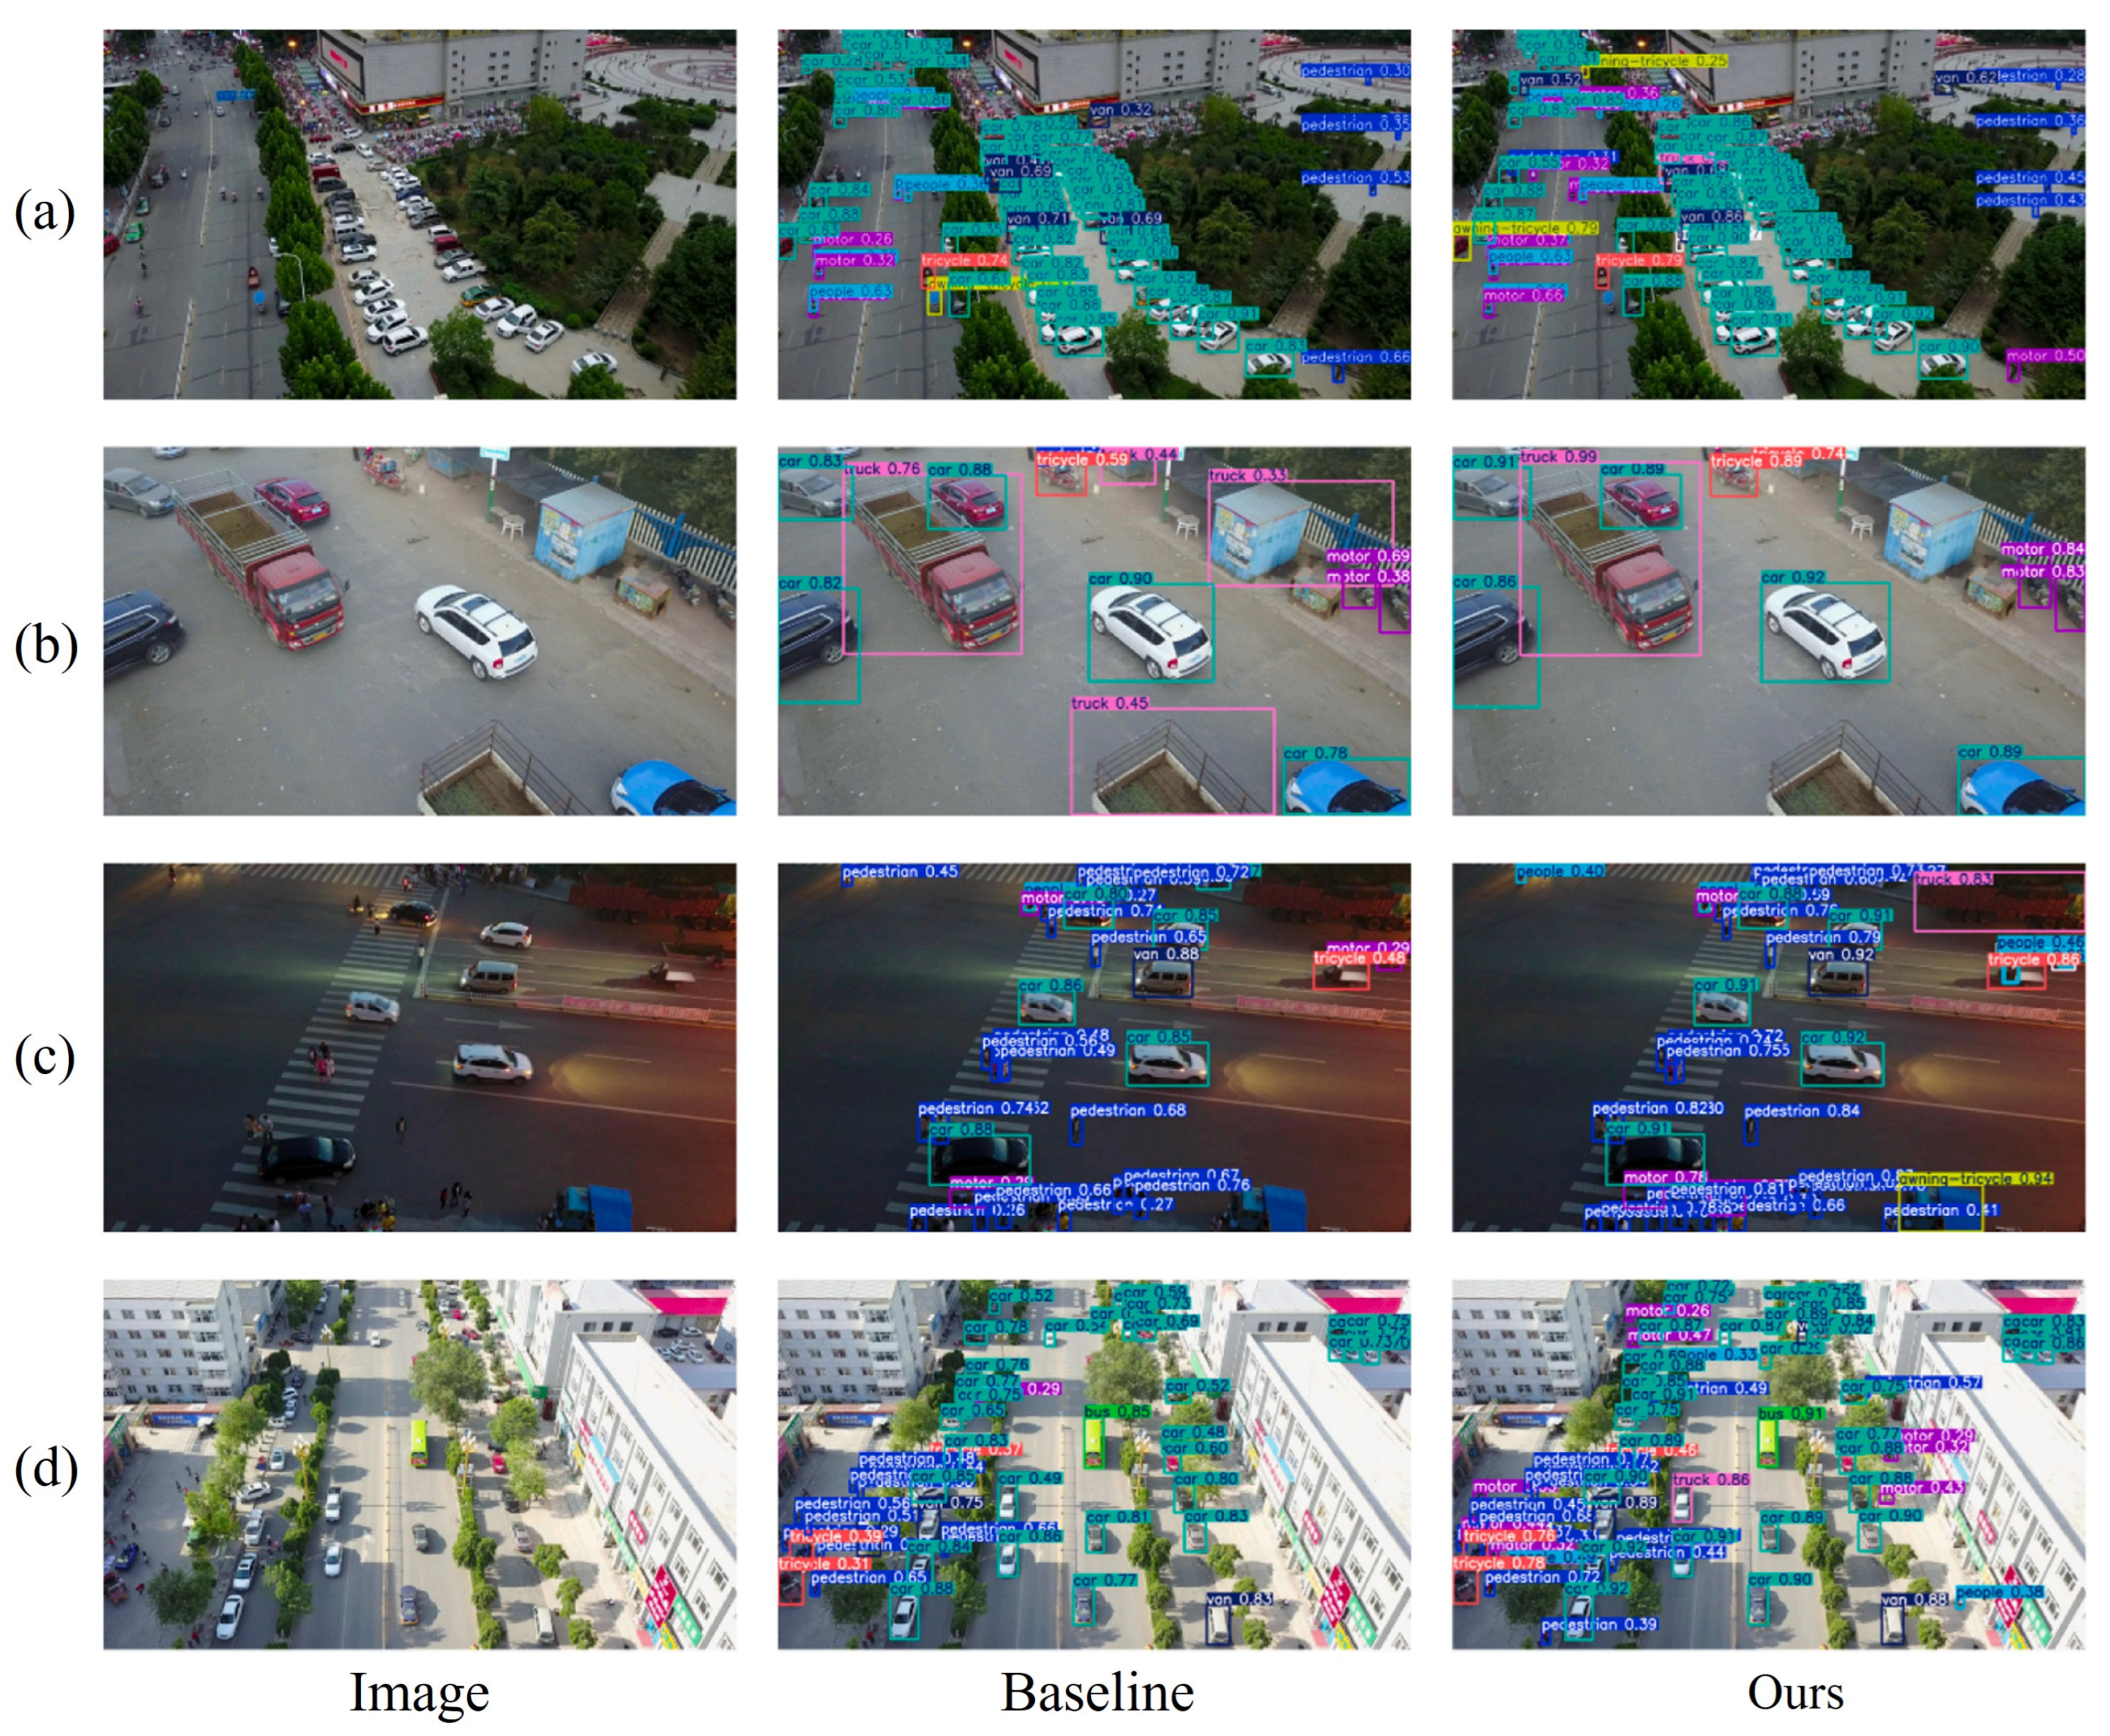
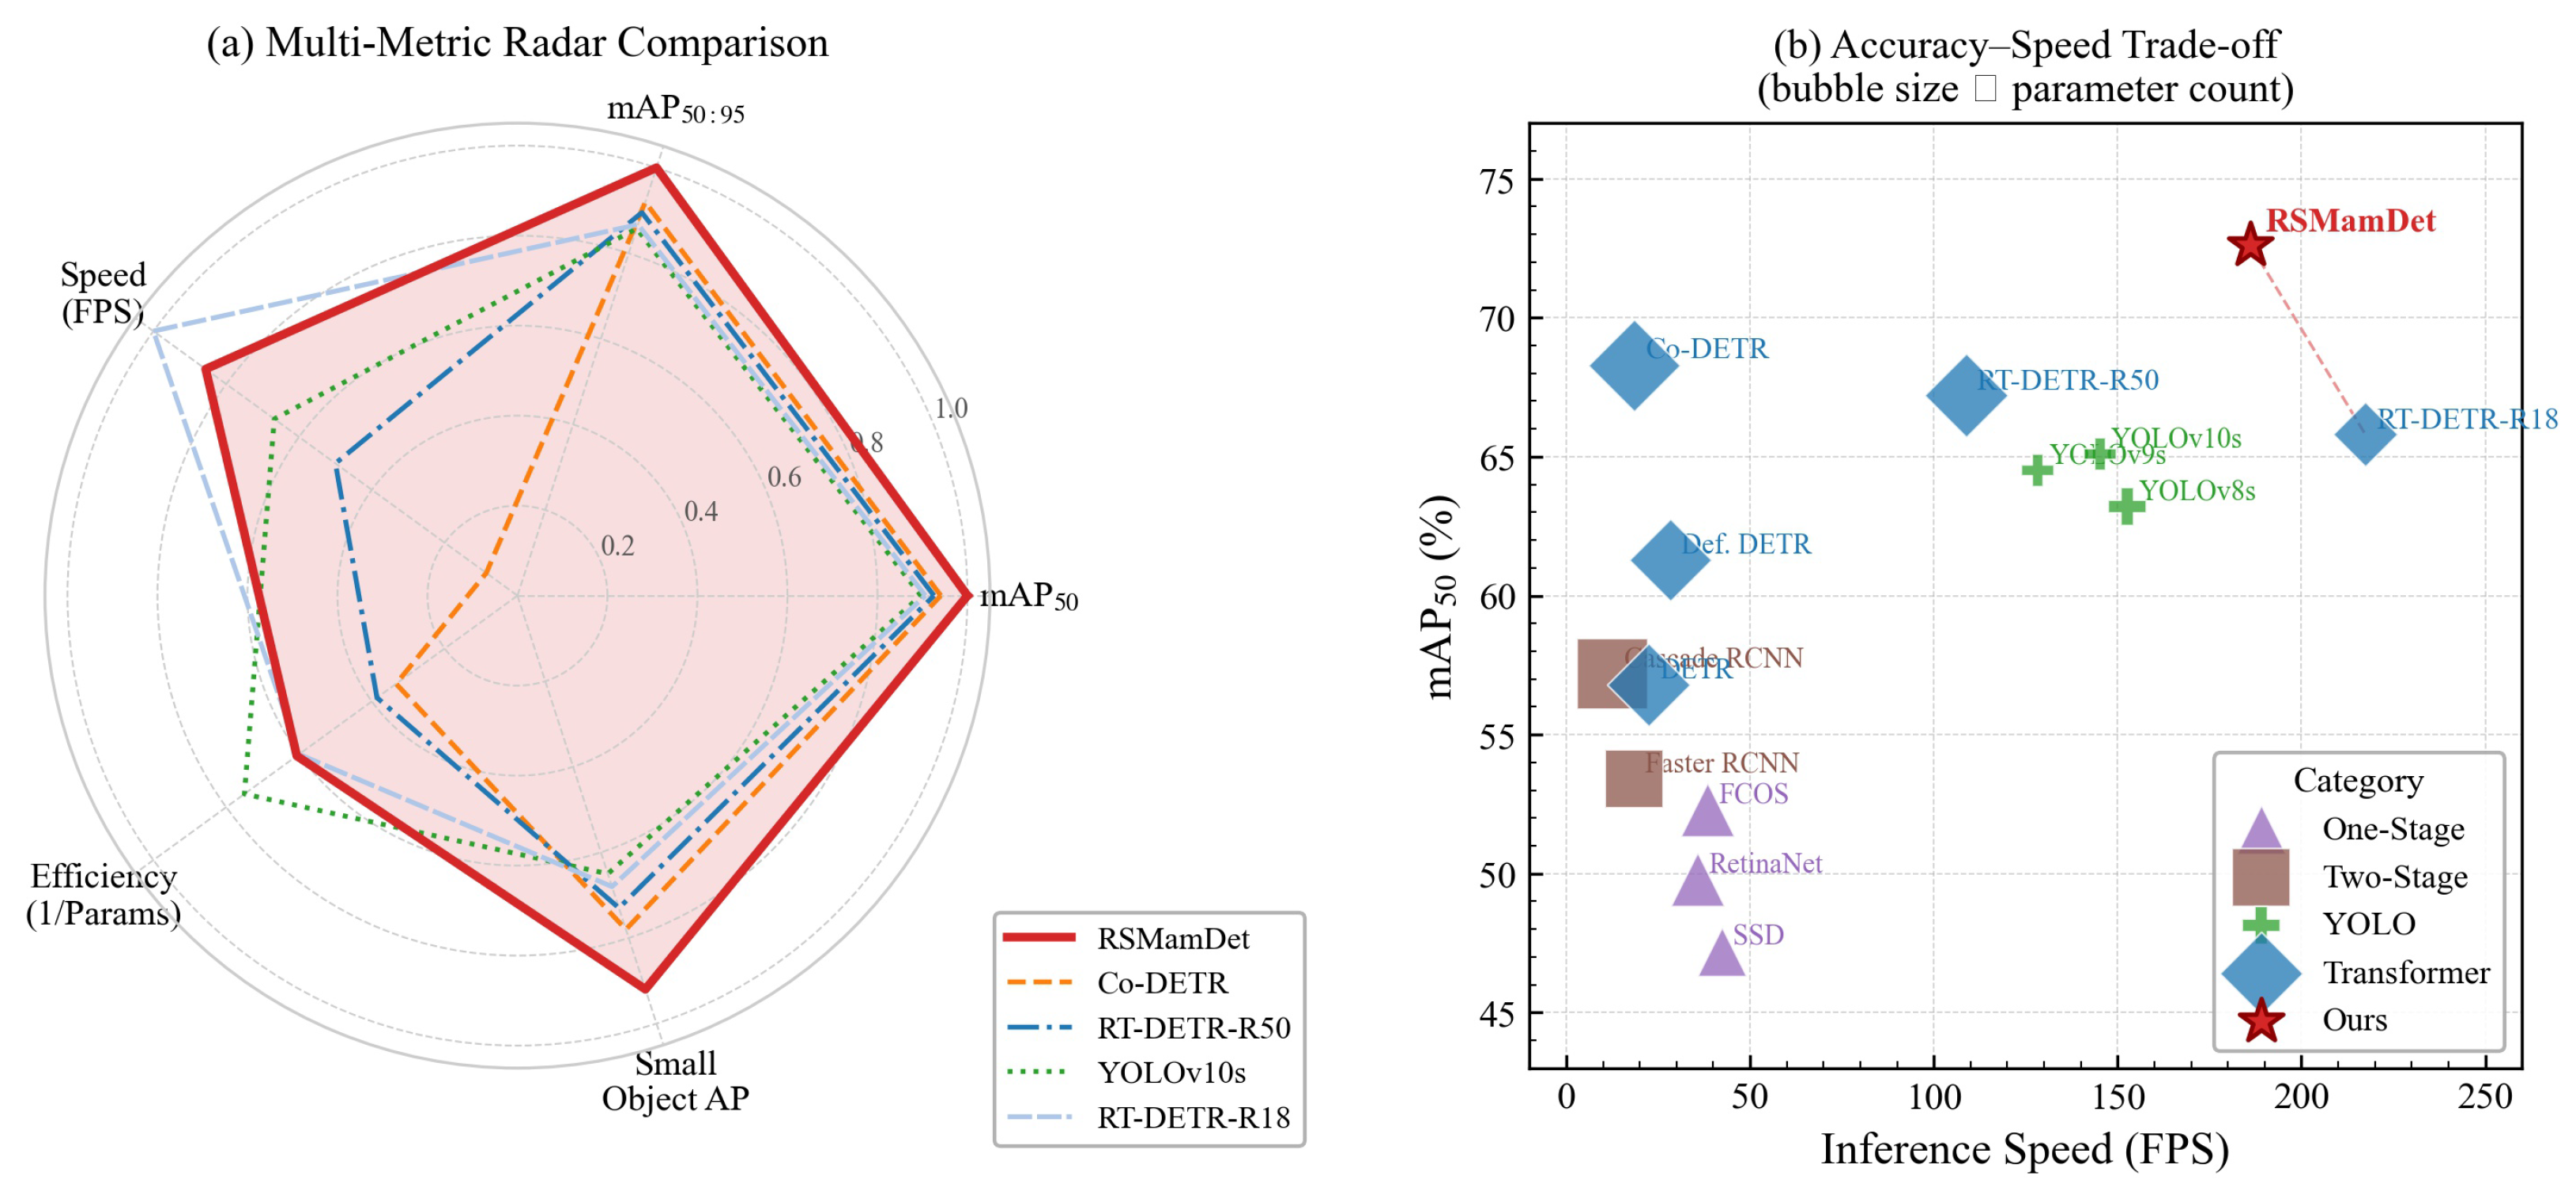
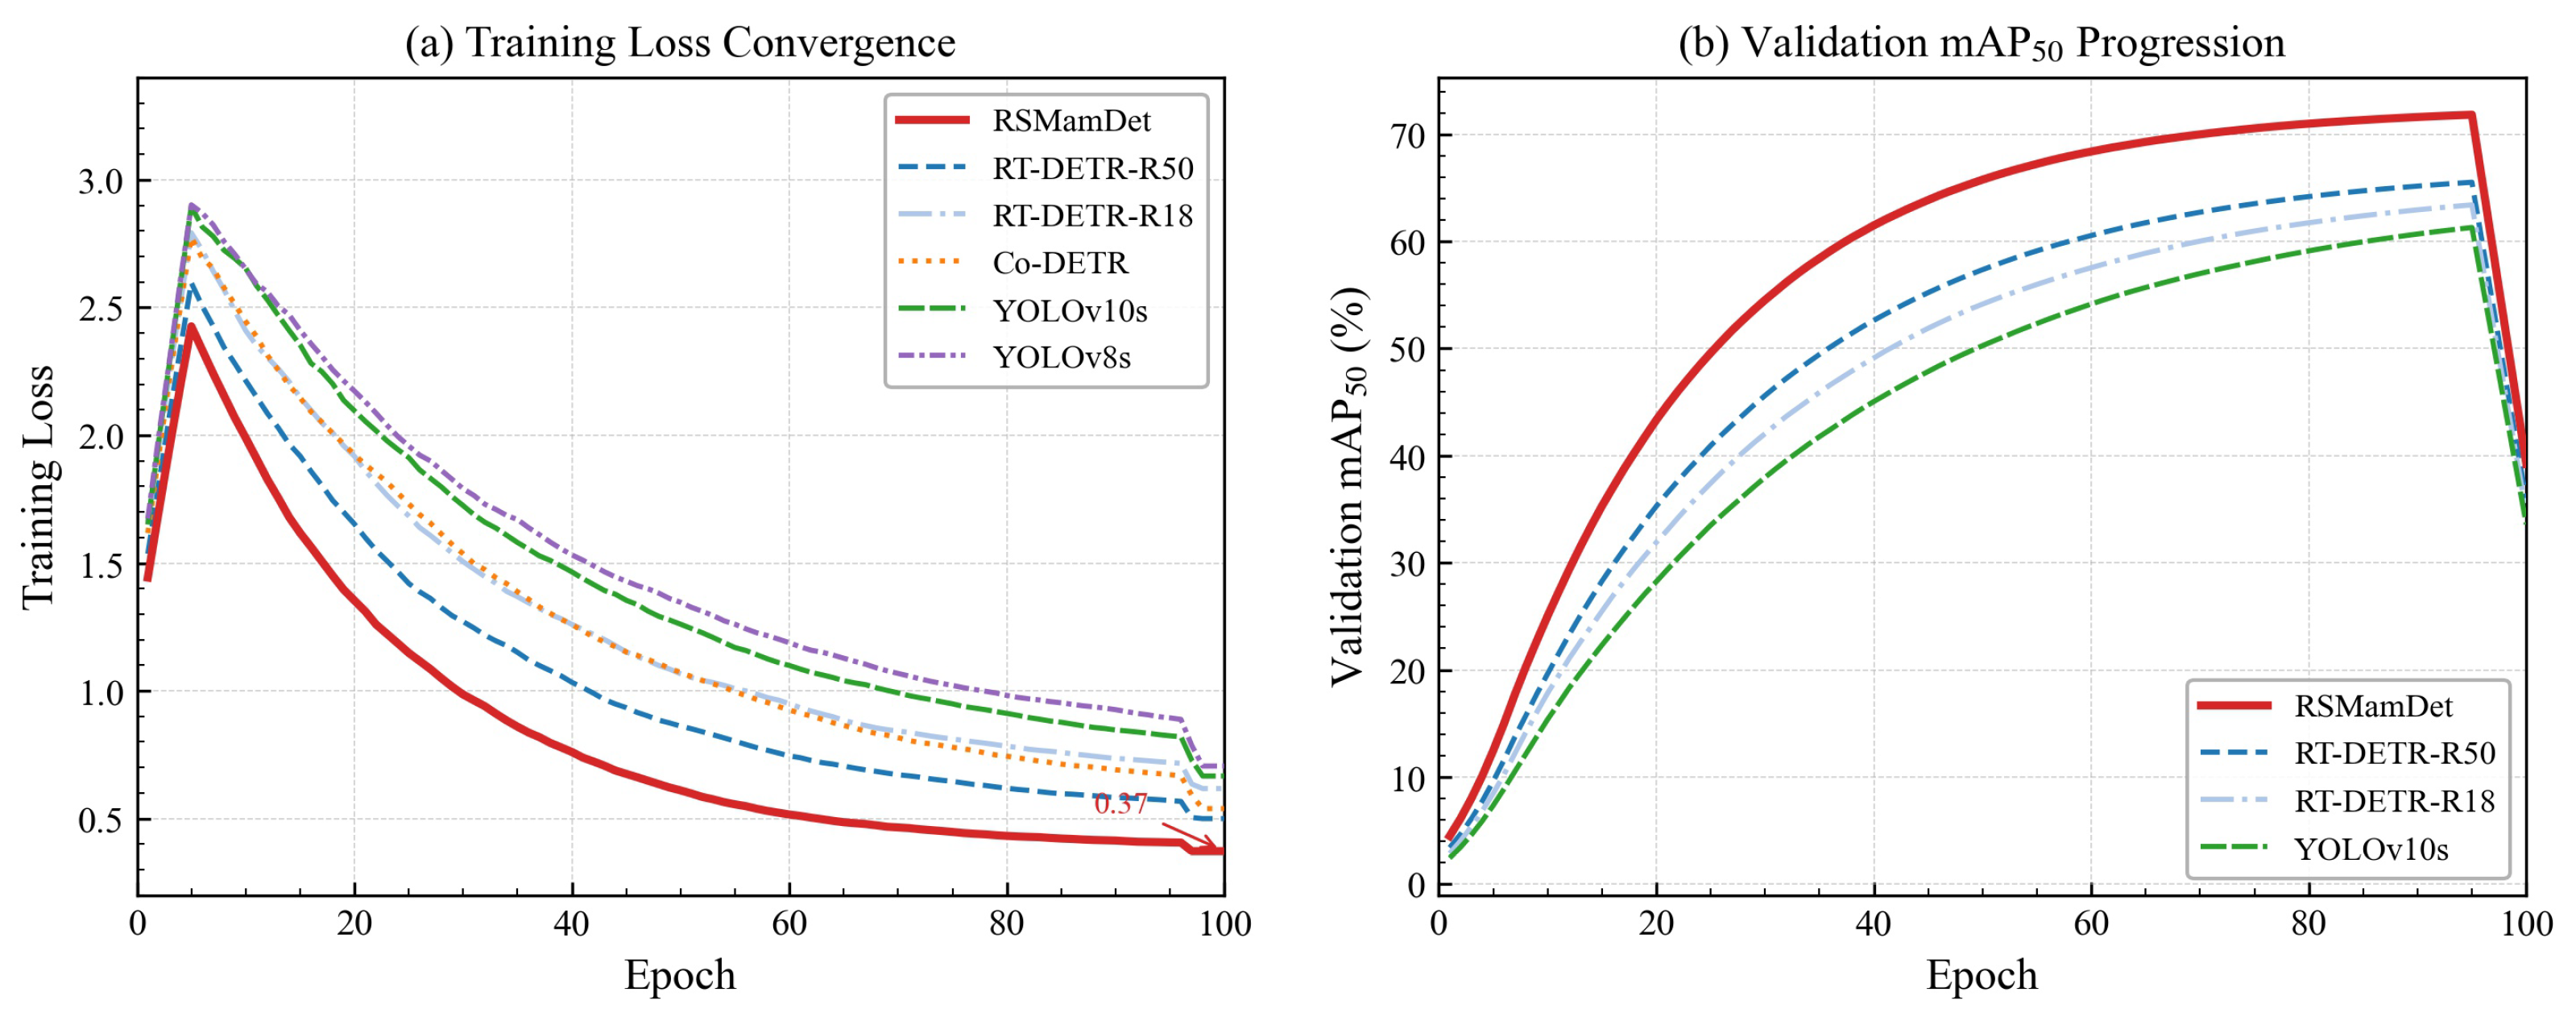
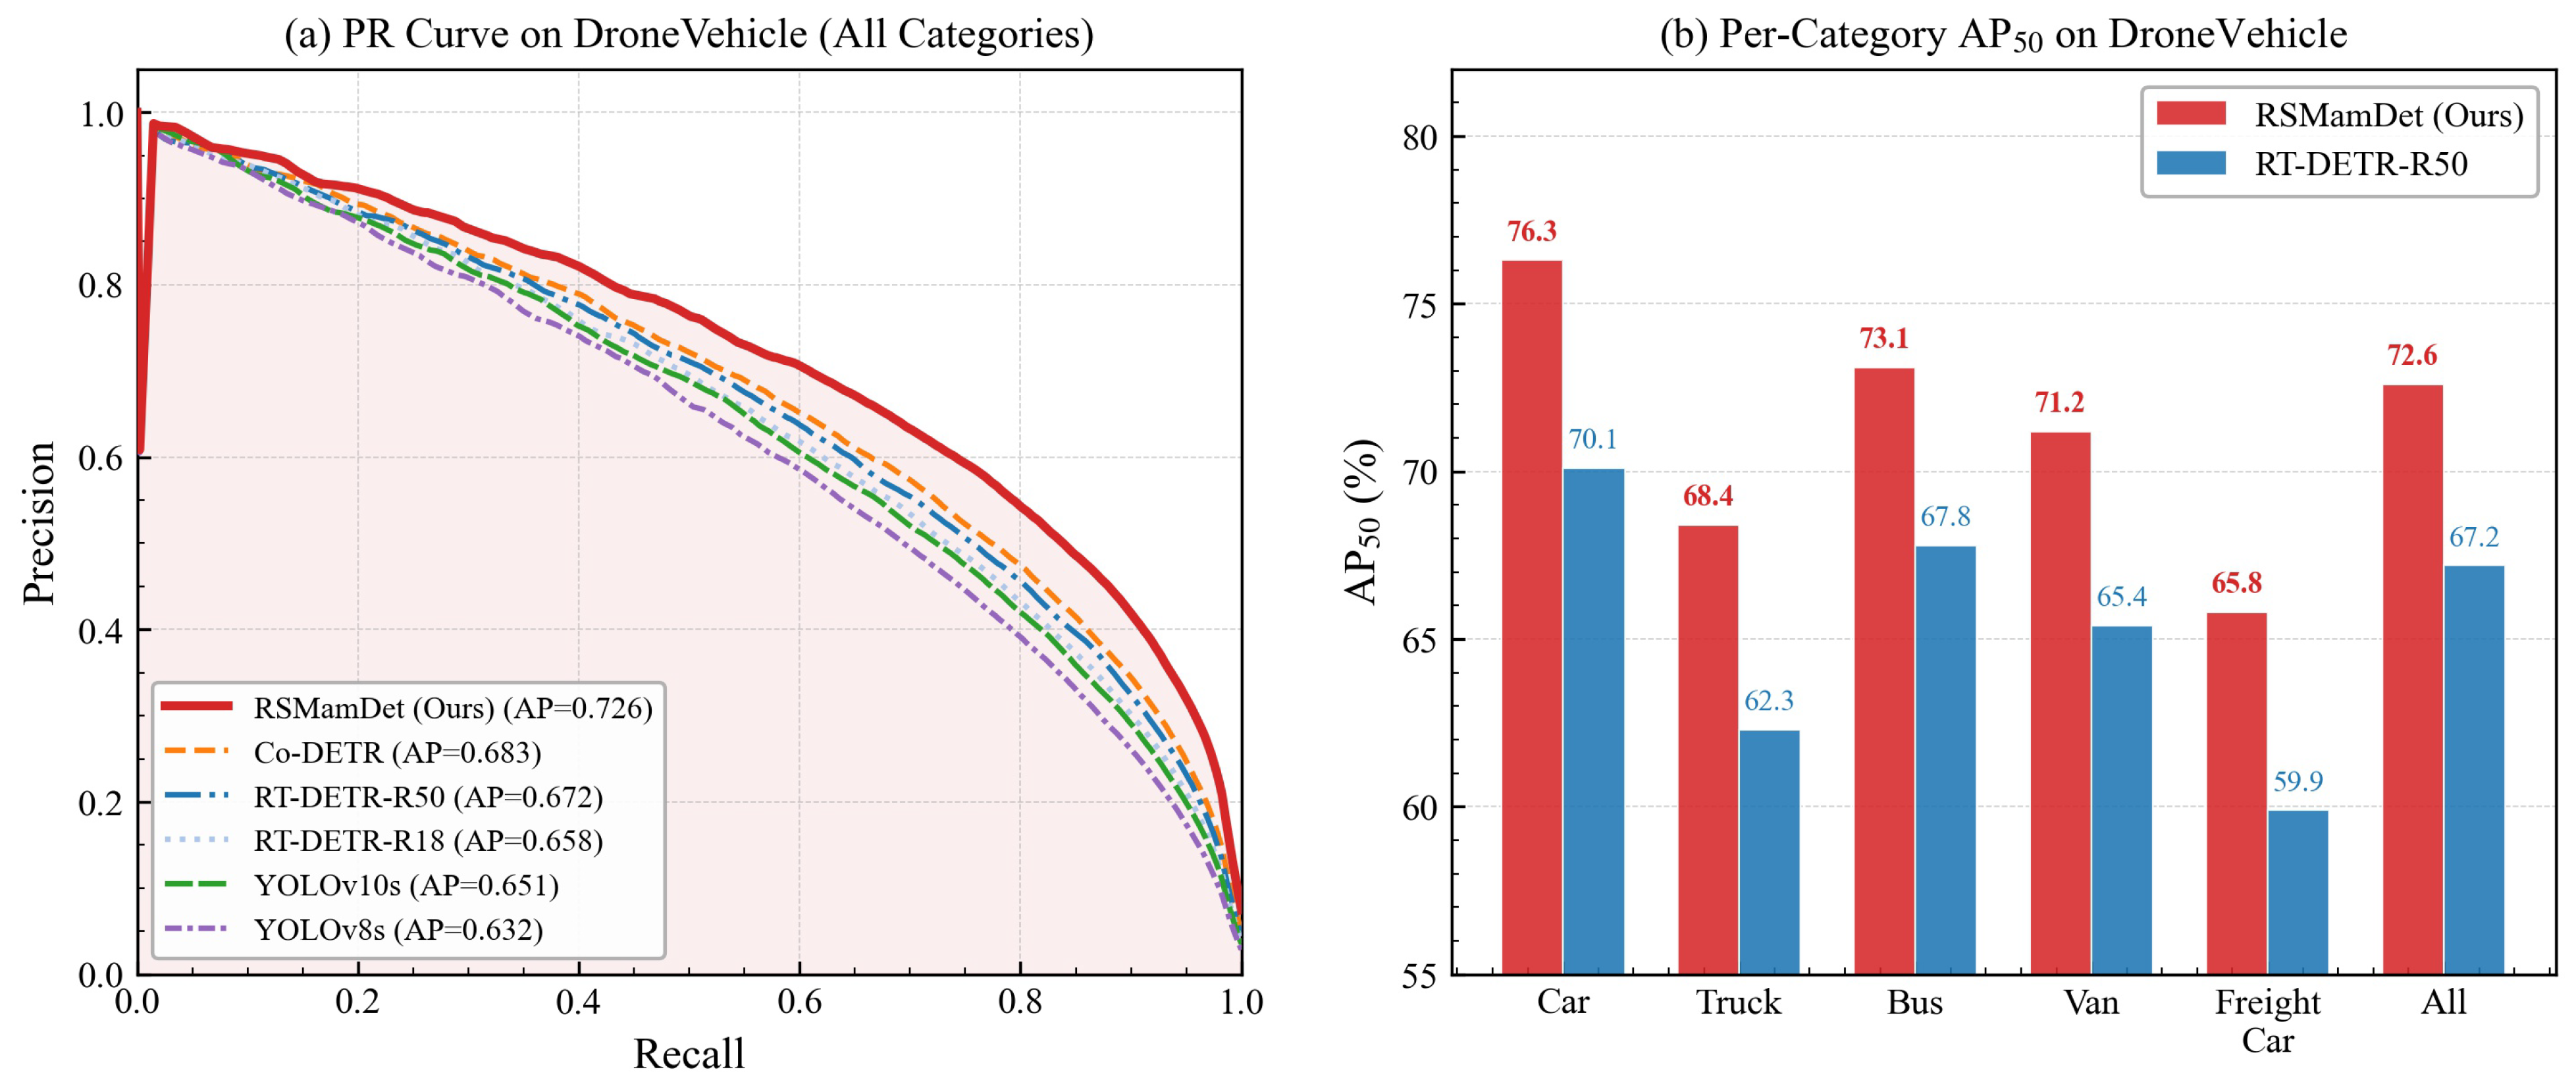
- RSMamDet achieves state-of-the-art mAP50 of 72.6% on DroneVehicle and 40.2% on VisDrone2019, surpassing prior best methods by 4.1% and 2.2%, respectively, while maintaining real-time inference at 186.2 FPS with only 19.8M parameters.
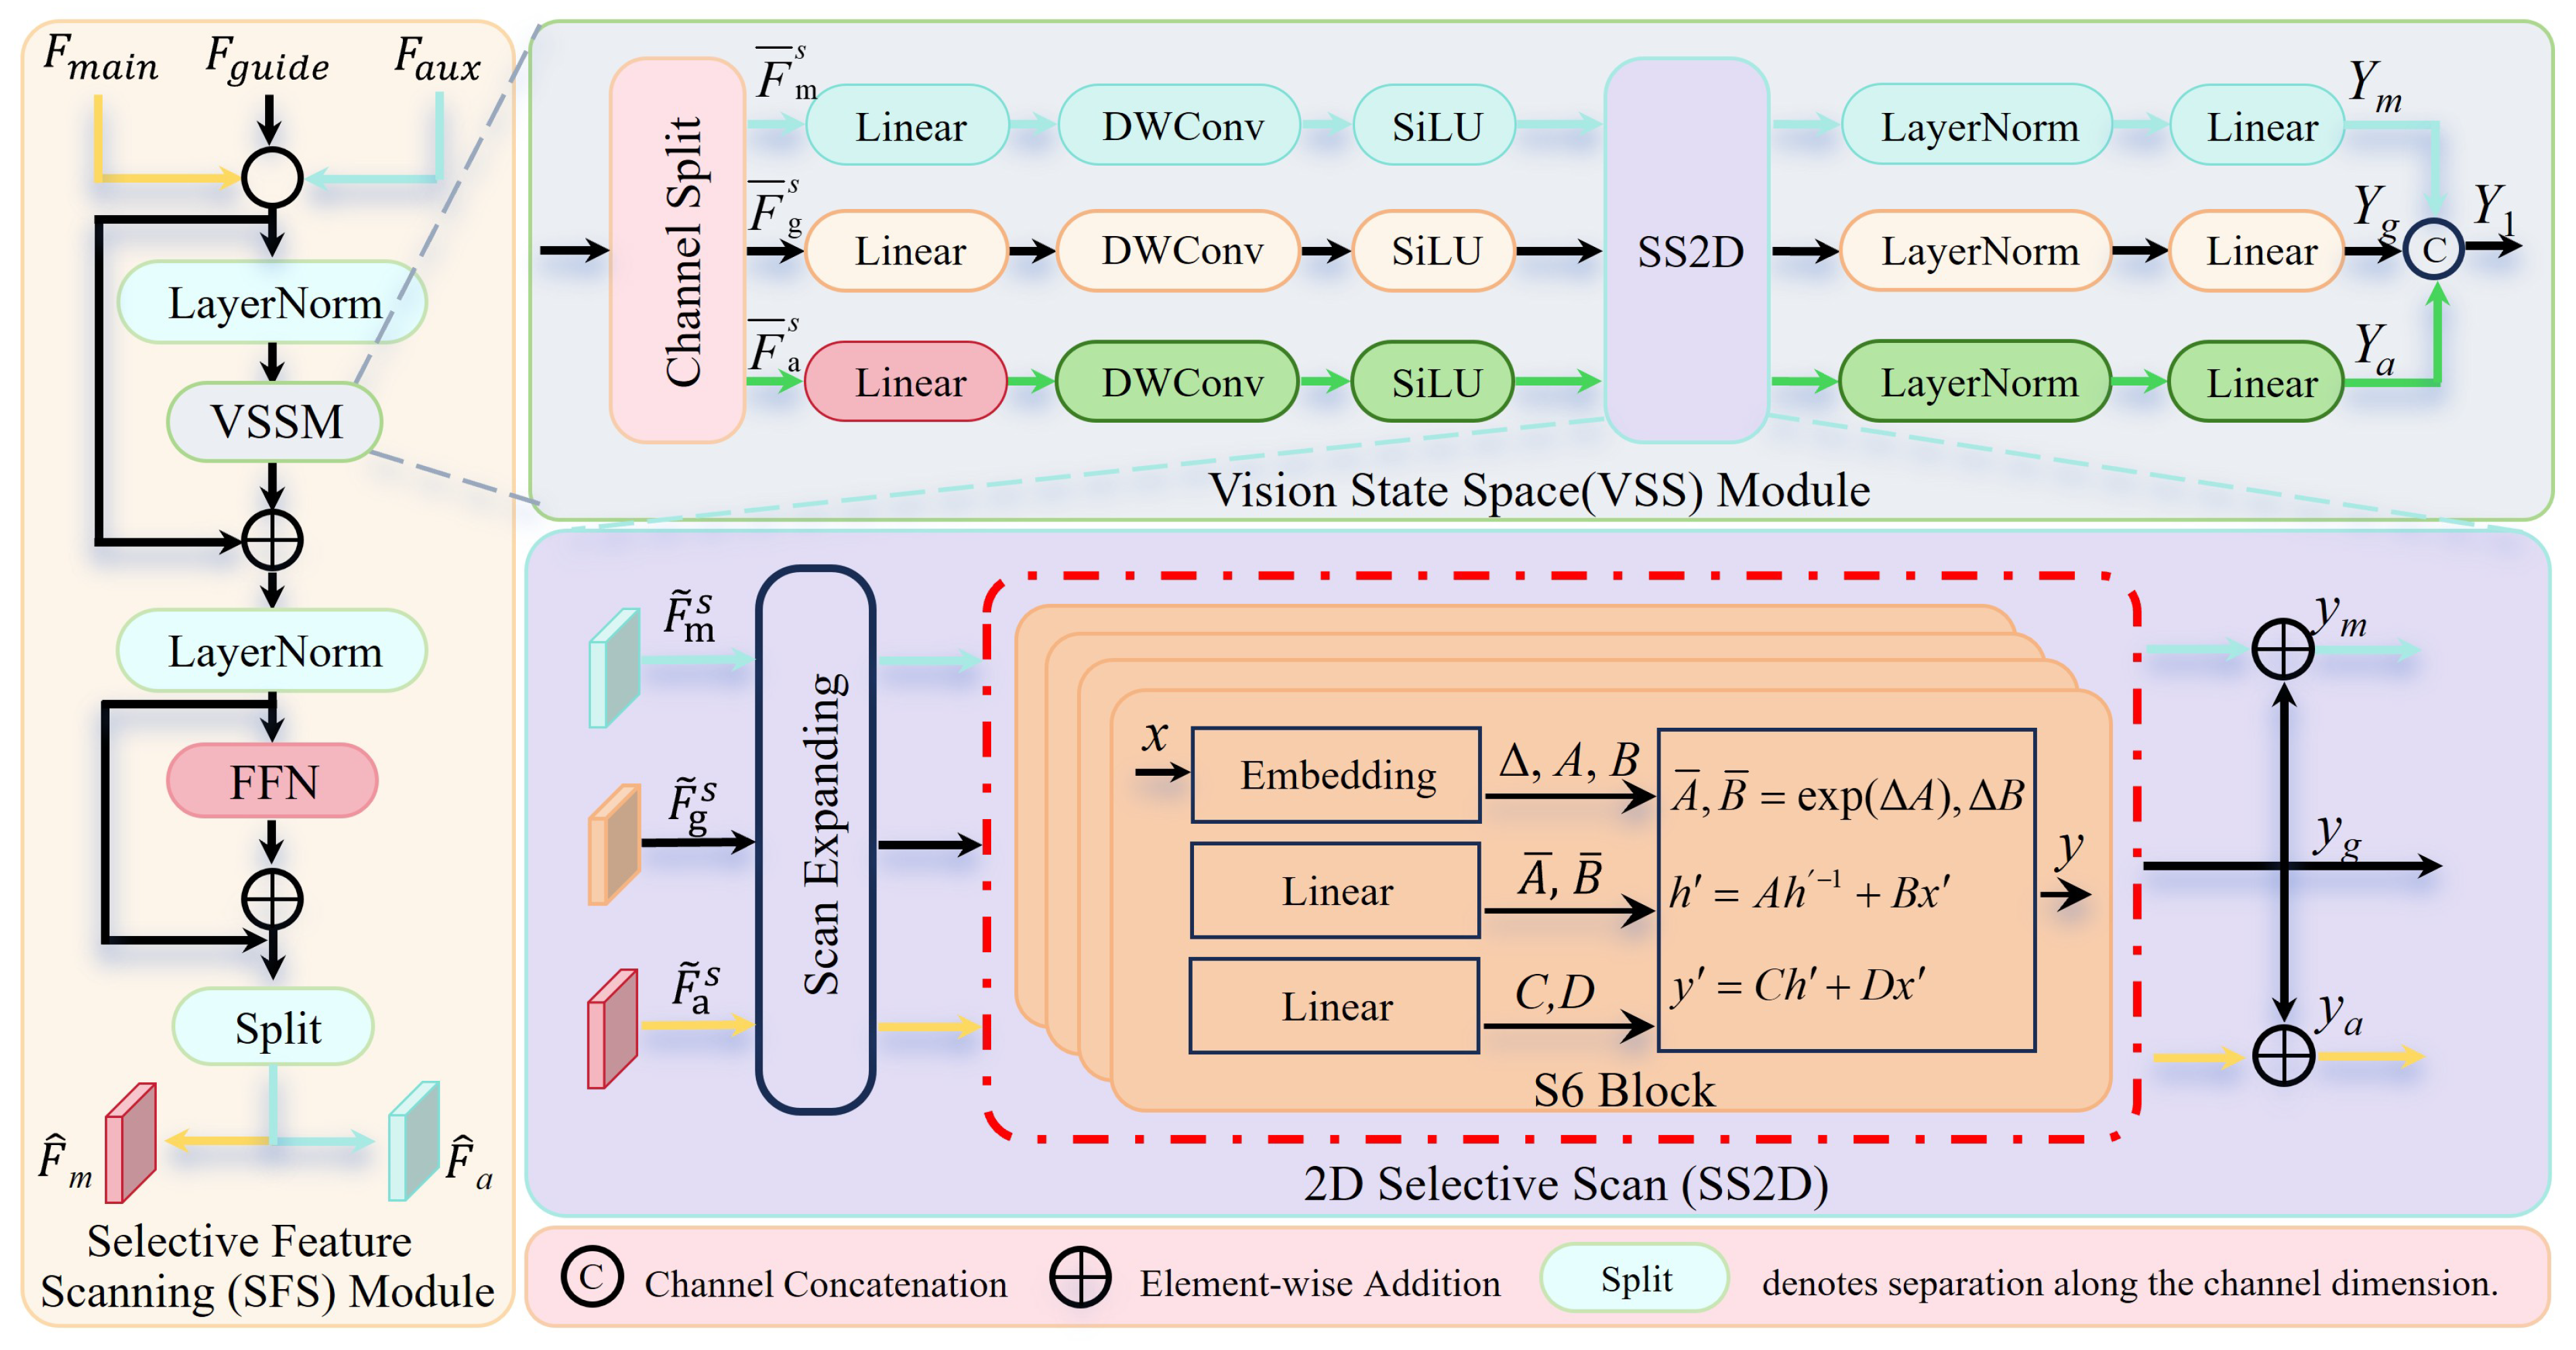
- Replacing quadratic self-attention with linear State Space Model scanning via the Selective Feature Scanning (SFS) module enables efficient global context modeling for high-resolution UAV imagery, reducing encoder FLOPs by approximately 38%.
- The proposed framework demonstrates that linear-complexity global context modeling can simultaneously satisfy both accuracy and real-time requirements for UAV-based vehicle detection, enabling practical deployment on resource-constrained aerial platforms.
- The modular design principles—adaptive cross-scale fusion (DASI), content-aware upsampling (AMFF), and uncertainty-aware training (UMC loss)—can generalize beyond vehicle detection to broader aerial remote sensing tasks such as crowd counting, infrastructure inspection, and disaster damage assessment.
Abstract
1. Introduction
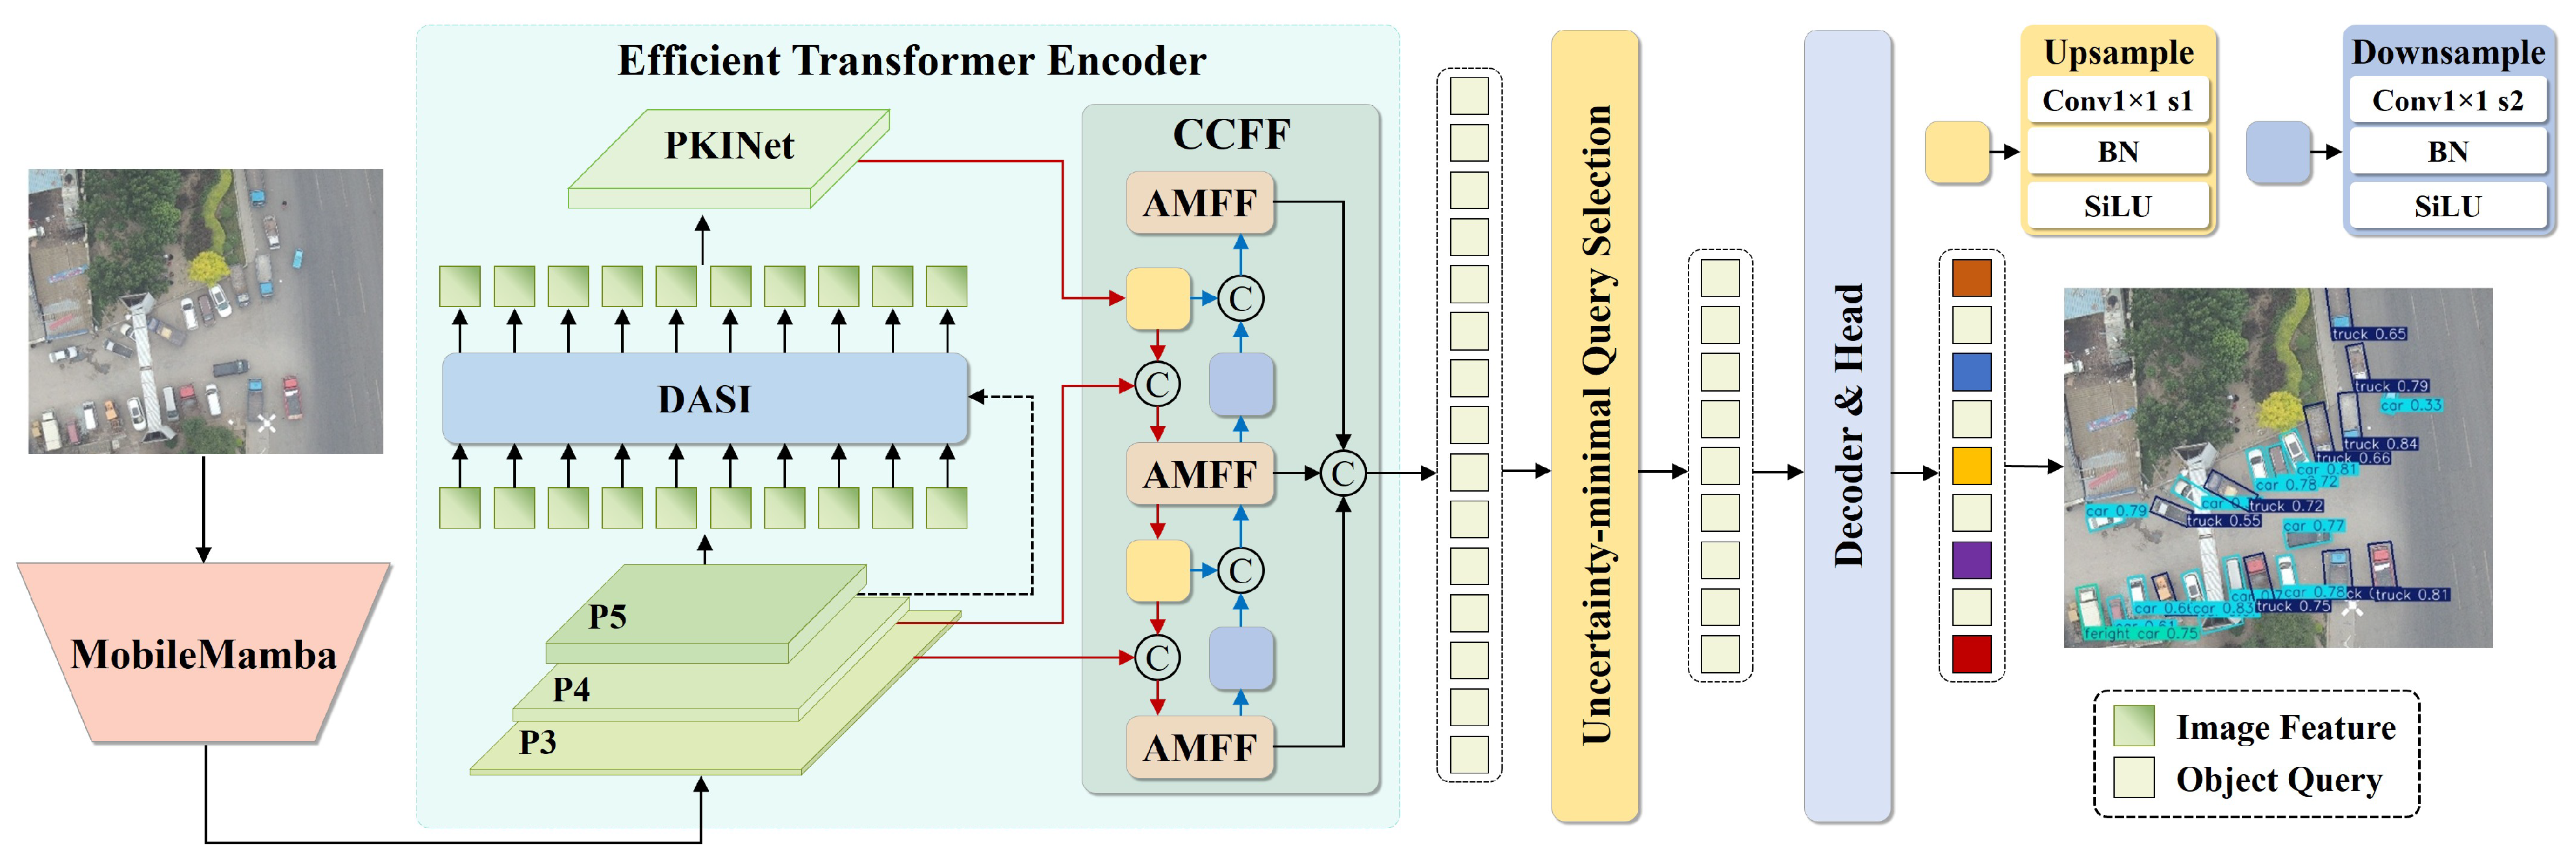
- A Selective Feature Scanning (SFS) module within MobileMamba that processes multi-stream features through 2D Selective Scan (SS2D), achieving global context modeling at complexity and replacing quadratic self-attention.
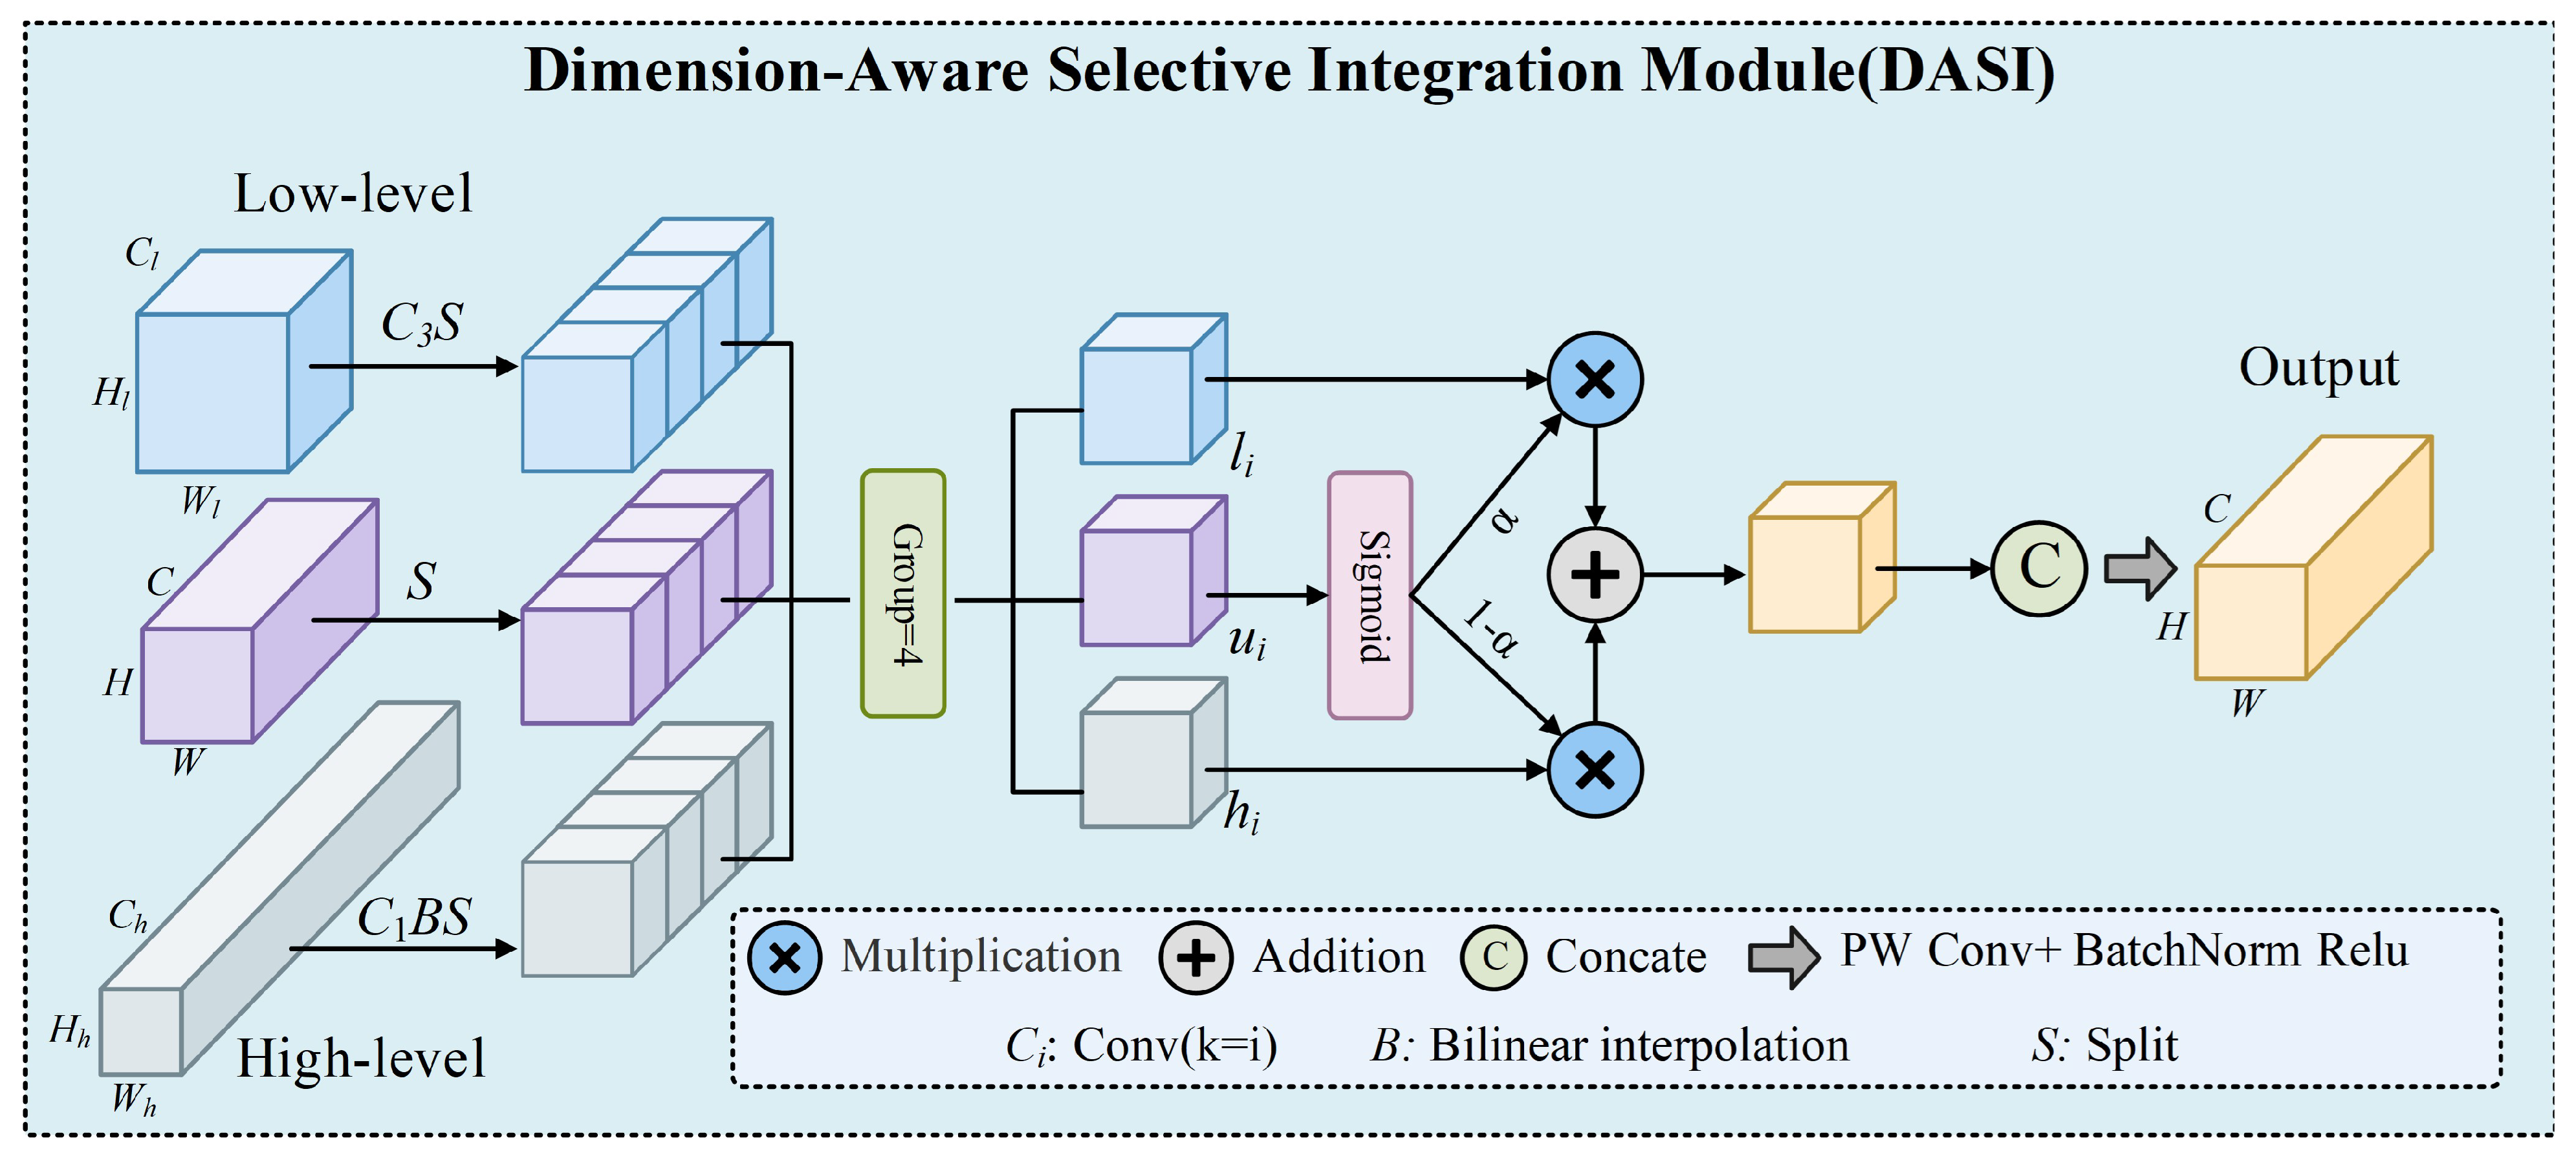
- A Dimension-Aware Selective Integration (DASI) module that adaptively fuses low-level and high-level features through sigmoid-gated cross-dimensional selection, bridging the semantic gap across feature pyramid levels.
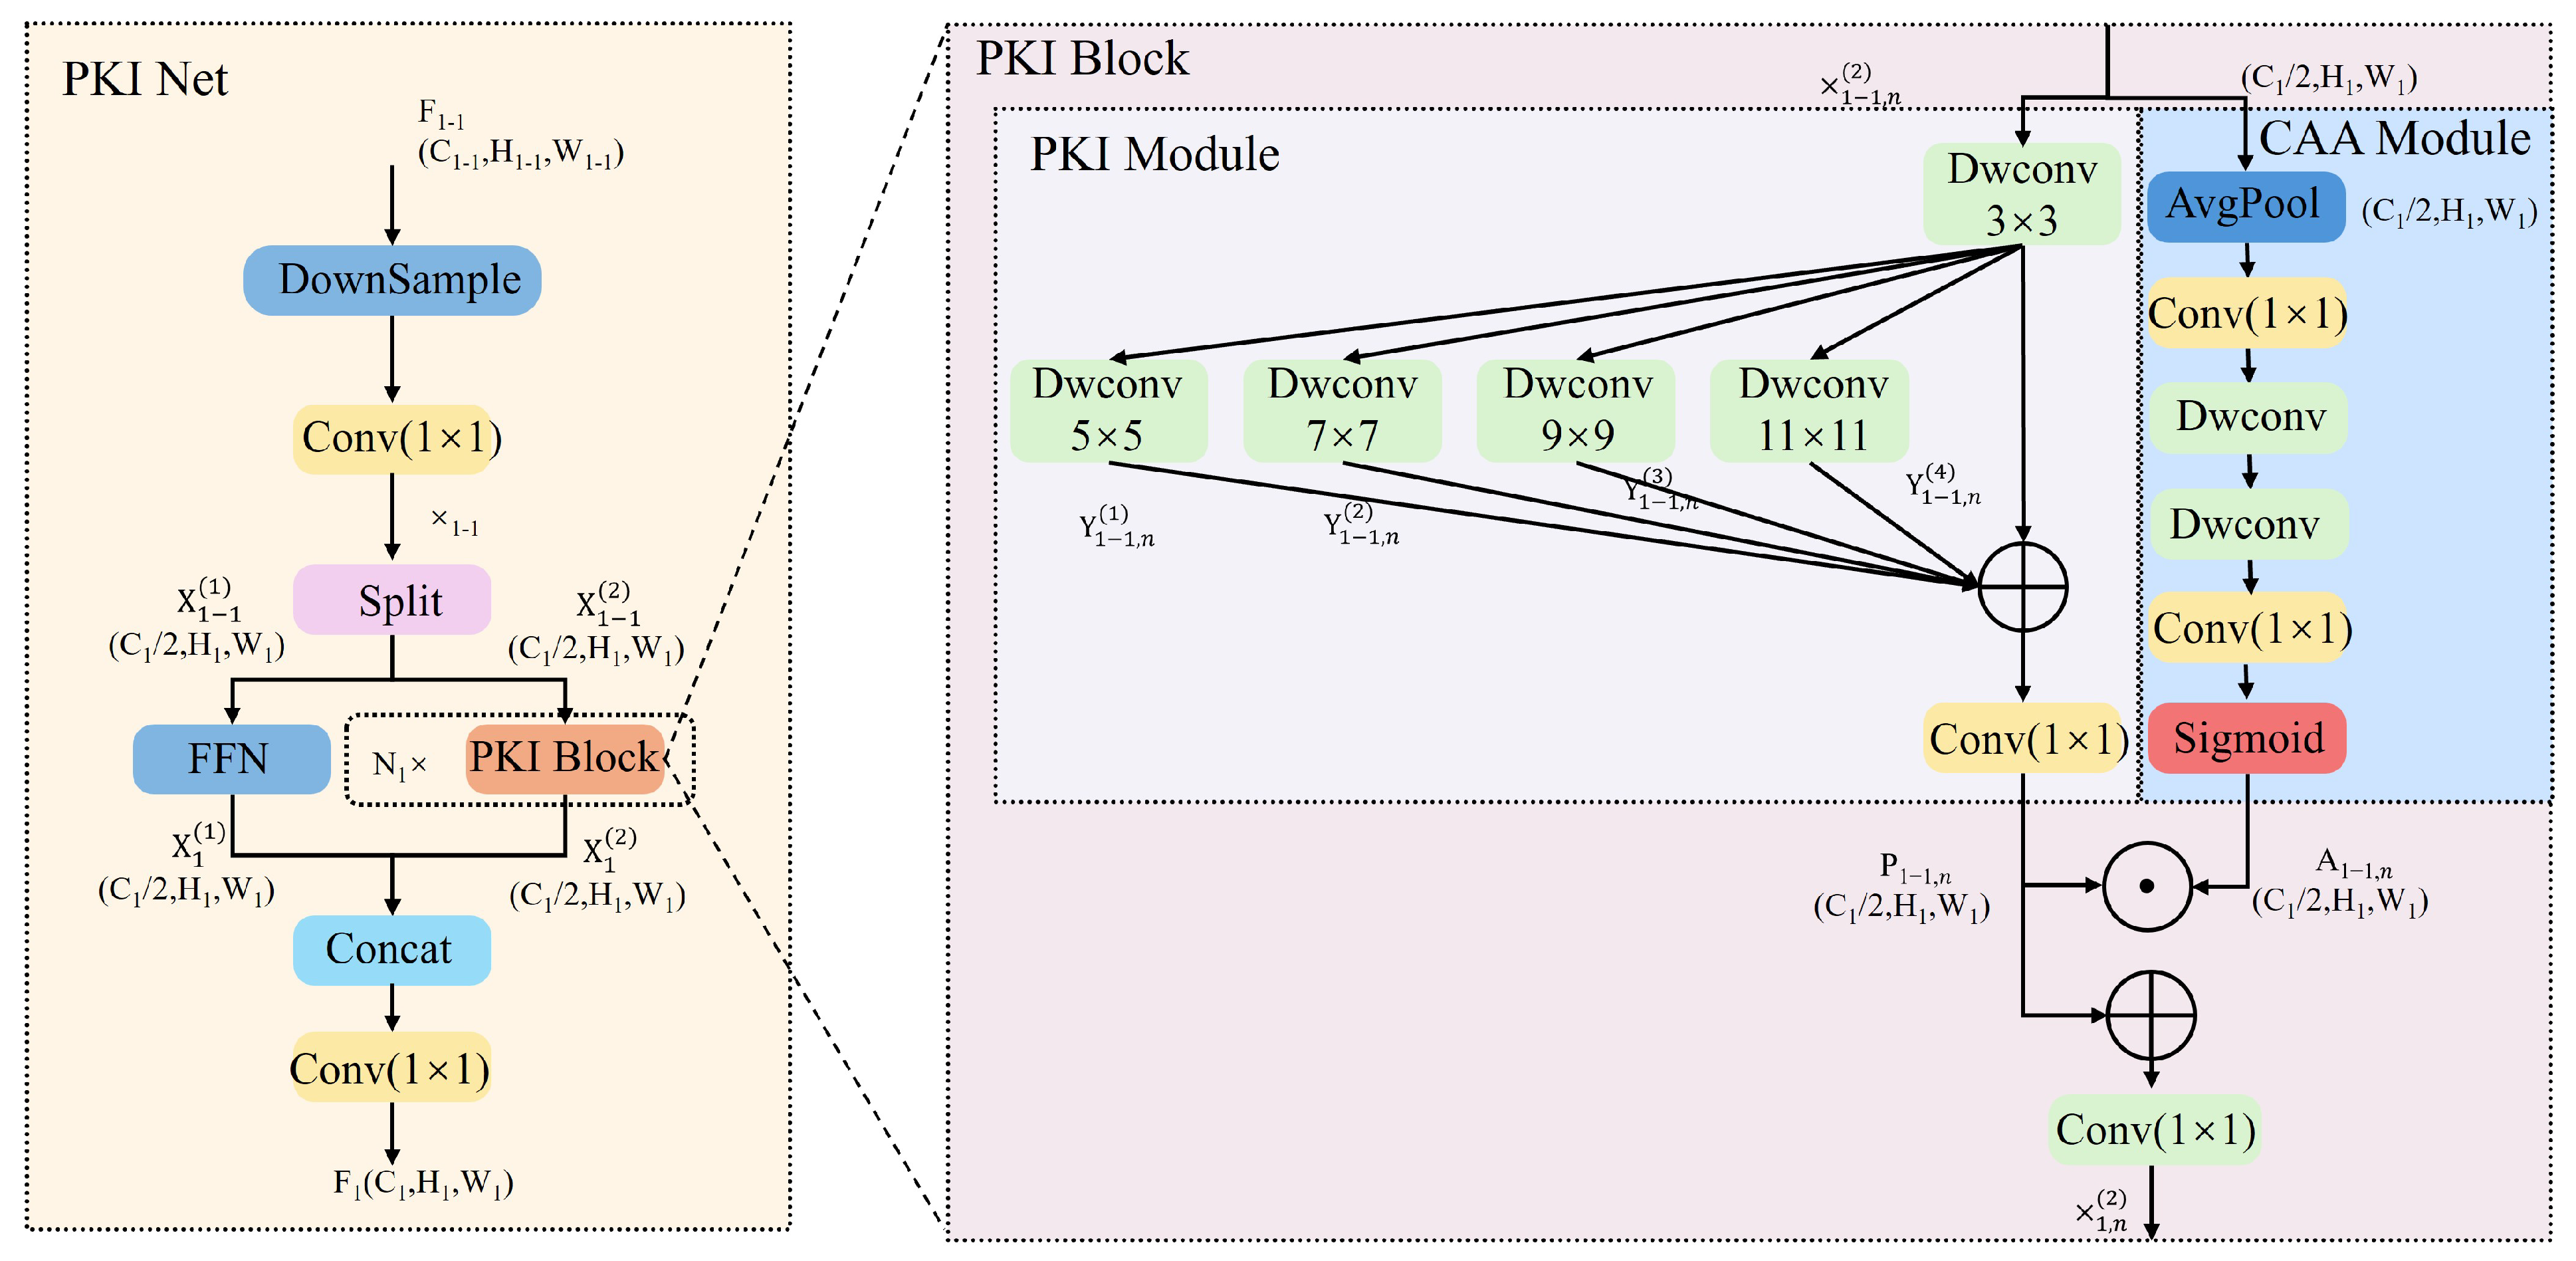
- A Poly Kernel Inception Network (PKINet) encoder that captures multi-scale spatial patterns via parallel depthwise convolutions ( to ) and Context Anchor Attention (CAA).
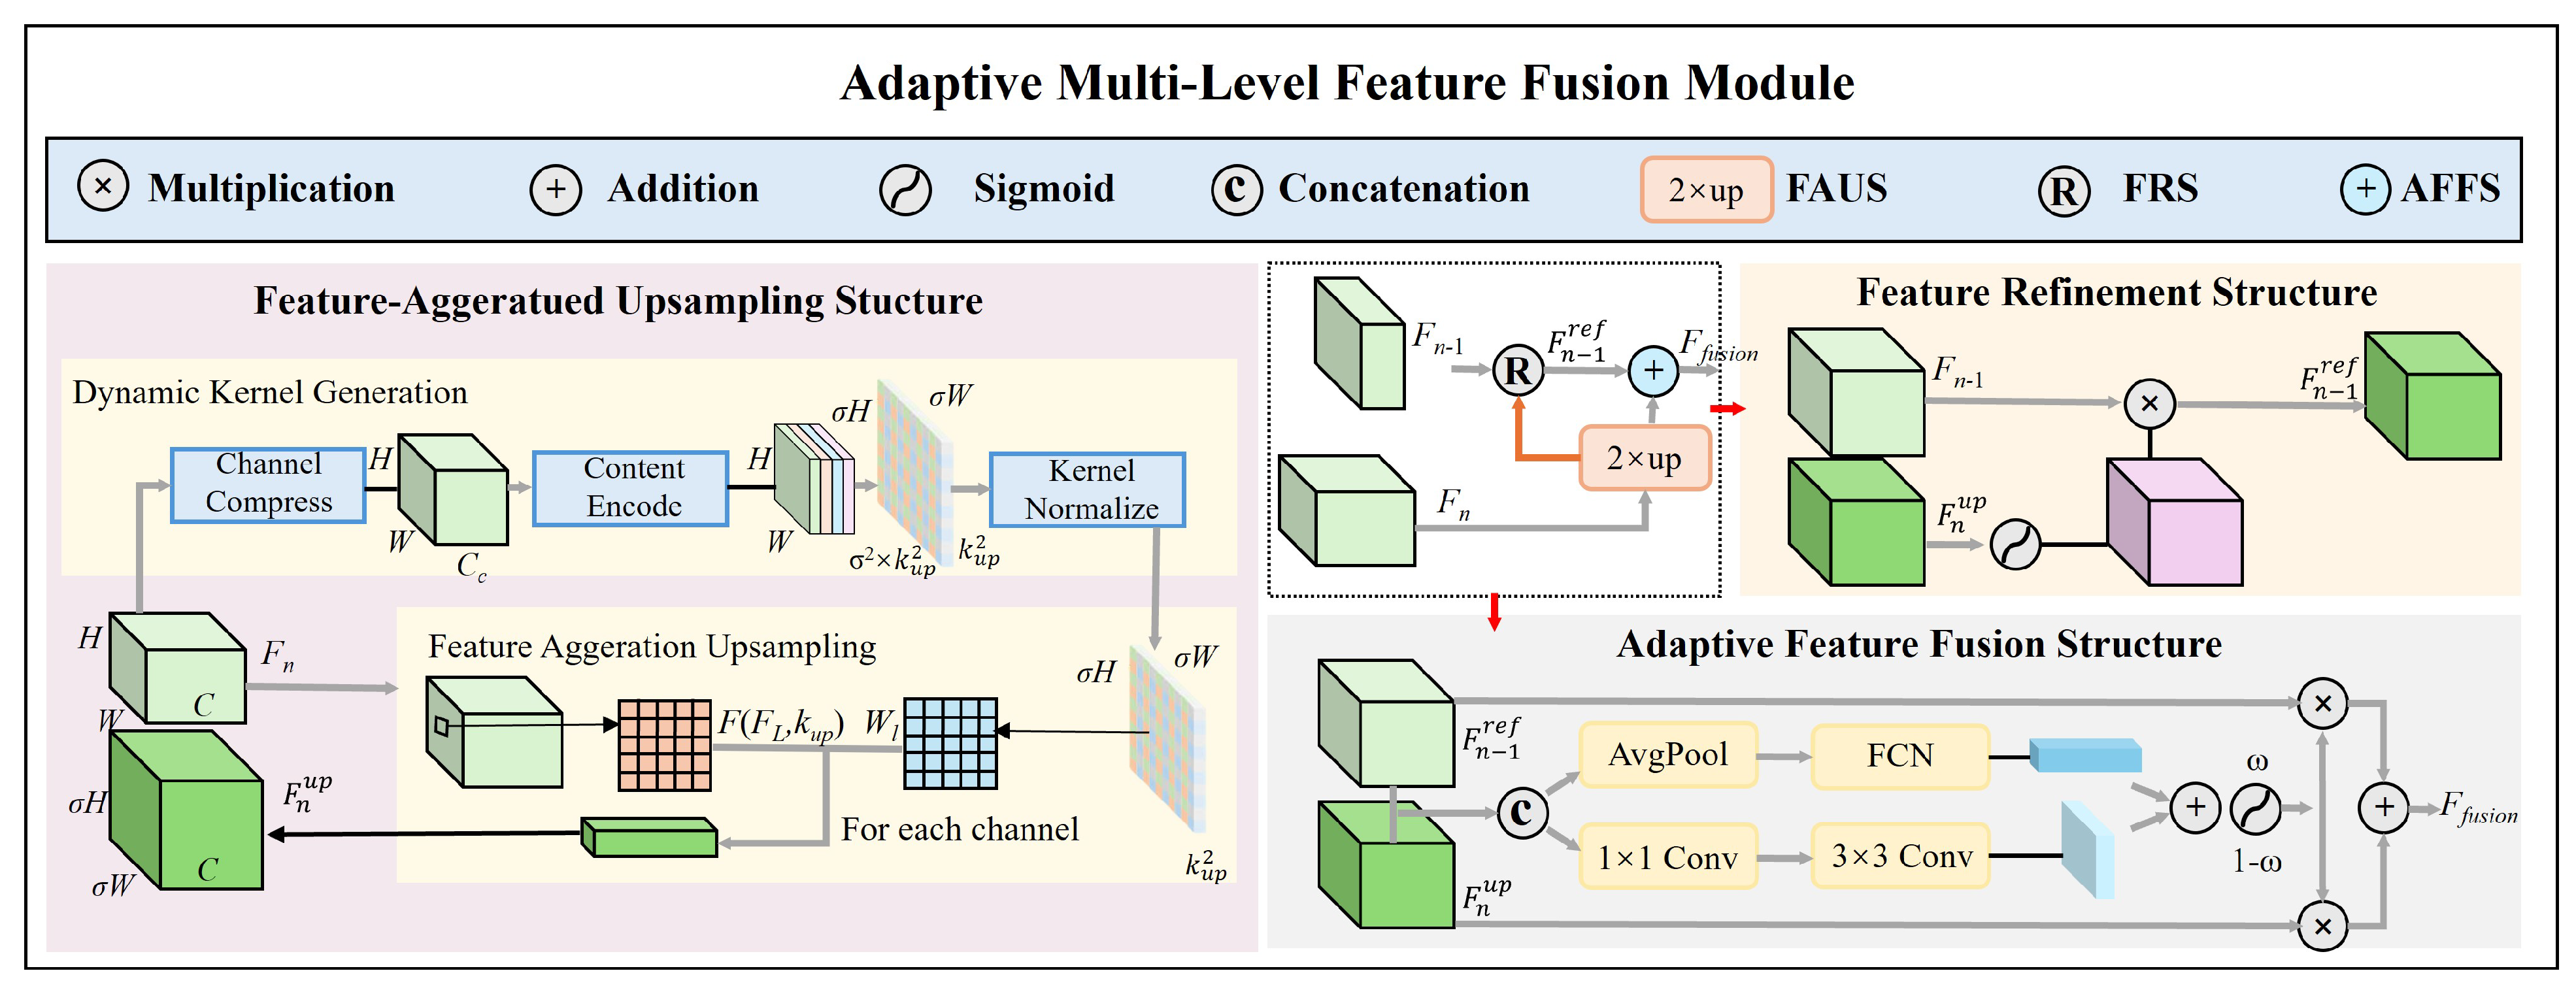
- An Adaptive Multi-Level Feature Fusion (AMFF) module combining content-aware dynamic upsampling with adaptive channel weighting for improved small-object feature representation.
- An Uncertainty-Minimal Composite (UMC) loss that incorporates uncertainty-aware query selection regularization to improve training stability in cluttered aerial scenes.
2. Related Work
2.1. DETR-Based Object Detection
2.2. State Space Models for Vision
2.3. UAV Vehicle Detection
2.4. Feature Pyramid and Fusion
3. Proposed Method
3.1. Overall Architecture
3.2. MobileMamba Backbone and Selective Feature Scanning (SFS) Module
3.2.1. State Space Model Foundations
3.2.2. 2D Selective Scan and SFS Design
3.3. Dimension-Aware Selective Integration (DASI) Module
3.4. Poly Kernel Inception Network (PKINet)
3.5. Adaptive Multi-Level Feature Fusion (AMFF) Module
3.5.1. Feature-Aggregated Upsampling Structure (FAUS)
3.5.2. Feature Refinement Structure (FRS)
3.5.3. Adaptive Feature Fusion Structure (AFFS)
3.6. Uncertainty-Minimal Composite (UMC) Loss
| Algorithm 1: Training Procedure of RSMamDet with UMC Loss |
|
4. Experiments
4.1. Datasets
4.2. Implementation Details
4.3. Comparison with State-of-the-Art Methods on DroneVehicle
4.4. Computational Efficiency and Model Complexity Analysis
4.5. Comparison with State-of-the-Art Methods on VisDrone2019
4.6. Ablation Study
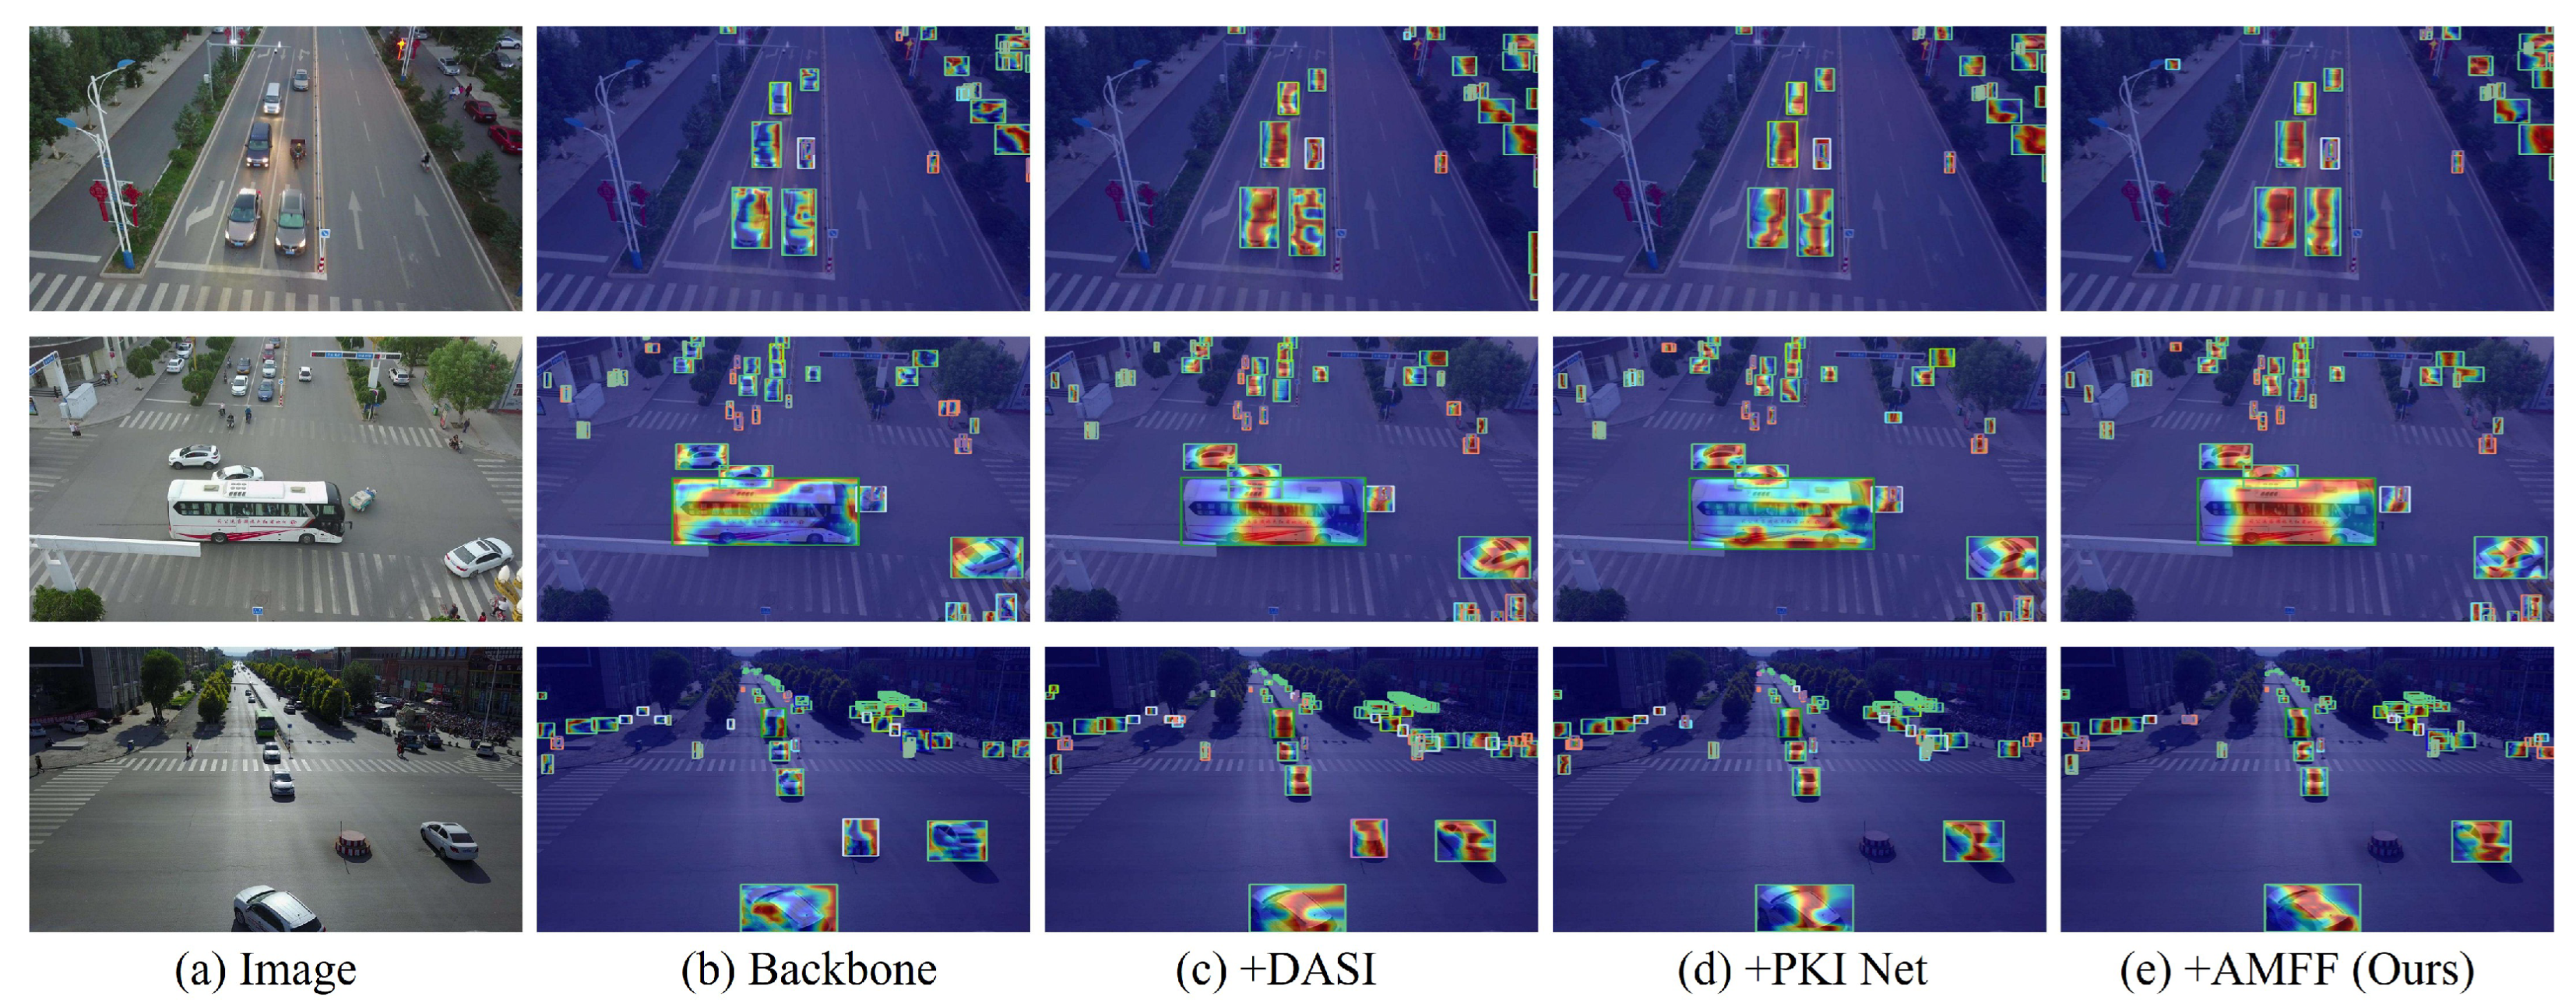
4.6.1. Component Ablation
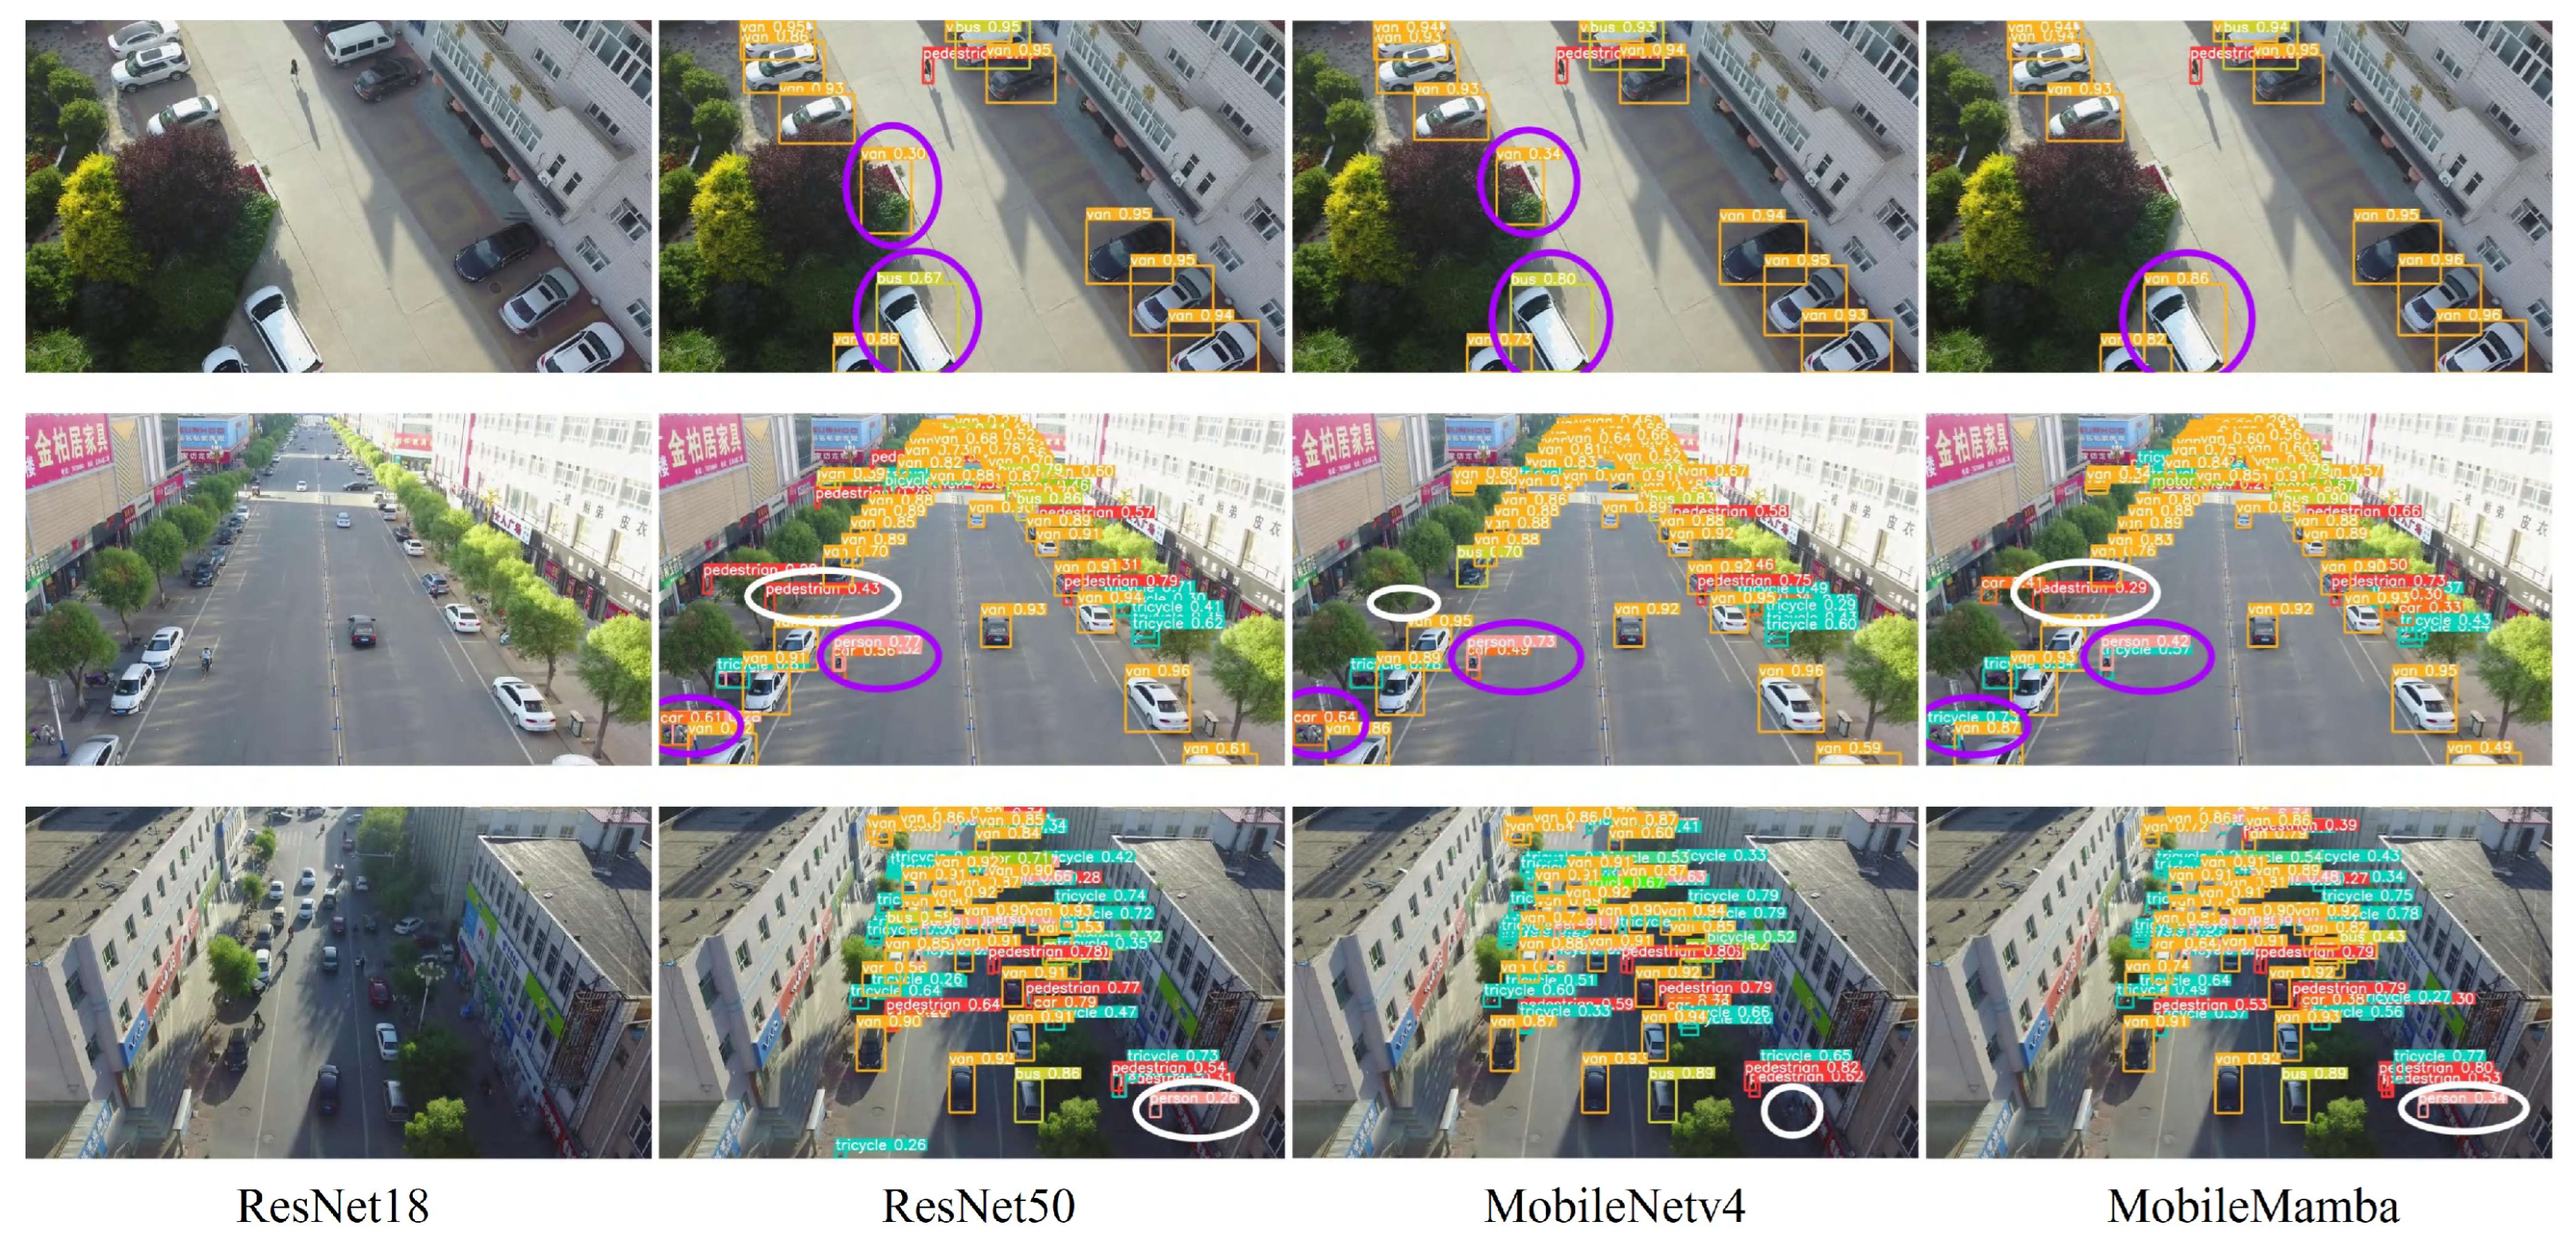
4.6.2. Backbone Comparison
4.6.3. Heatmap Visualization
5. Discussion
6. Conclusions
Author Contributions
Funding
Institutional Review Board Statement
Informed Consent Statement
Data Availability Statement
Conflicts of Interest
Abbreviations
| UAV | Unmanned Aerial Vehicle |
| SSM | State Space Model |
| SFS | Selective Feature Scanning |
| DASI | Dimension-Aware Selective Integration |
| PKINet | Poly Kernel Inception Network |
| AMFF | Adaptive Multi-Level Feature Fusion |
| UMC | Uncertainty-Minimal Composite |
| DETR | Detection Transformer |
| SS2D | 2D Selective Scan |
| VSSM | Visual State Space Module |
| FPN | Feature Pyramid Network |
| CAA | Context Anchor Attention |
| CCFF | Cross-scale Channel Feature Fusion |
| FAUS | Feature-Aggregated Upsampling Structure |
| FRS | Feature Refinement Structure |
| AFFS | Adaptive Feature Fusion Structure |
| mAP | mean Average Precision |
| FPS | Frames Per Second |
| ZOH | Zero-Order Hold |
| DWConv | Depthwise Convolution |
| BN | Batch Normalization |
References
- Zhu, P.; Wen, L.; Du, D.; Bian, X.; Fan, H.; Hu, Q.; Ling, H. Detection and Tracking Meet Drones Challenge. IEEE Trans. Pattern Anal. Mach. Intell. 2021, 44, 7380–7399. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Liu, W.; Li, Y.; Zhang, S.; Mao, R. Towards Smart City Supervision: A Detection Pipeline for Illegal Buildings. Eng. Appl. Artif. Intell. 2026, 163, 113052. [Google Scholar] [CrossRef] [Scilit]
- Yan, Z.; Li, Y. AMSRDet: An Adaptive Multi-Scale UAV Infrared-Visible Remote Sensing Vehicle Detection Network. Sensors 2026, 26, 817. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Liu, W.; Anguelov, D.; Erhan, D.; Szegedy, C.; Reed, S.; Fu, C.Y.; Berg, A.C. SSD: Single Shot MultiBox Detector. In Proceedings of the European Conference on Computer Vision; Springer: Berlin/Heidelberg, Germany, 2016; pp. 21–37. [Google Scholar]
- Lin, T.Y.; Goyal, P.; Girshick, R.; He, K.; Dollár, P. Focal Loss for Dense Object Detection. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Venice, Italy, 22–29 October 2017; pp. 2980–2988. [Google Scholar]
- Tian, Z.; Shen, C.; Chen, H.; He, T. FCOS: Fully Convolutional One-Stage Object Detection. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Seoul, Republic of Korea, 27 October–2 November 2019; pp. 9627–9636. [Google Scholar]
- Zhang, S.; Chi, C.; Yao, Y.; Lei, Z.; Li, S.Z. Bridging the Gap Between Anchor-based and Anchor-free Detection via Adaptive Training Sample Selection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, WA, USA, 13–19 June 2020; pp. 9759–9768. [Google Scholar]
- Li, X.; Wang, W.; Wu, L.; Chen, S.; Hu, X.; Li, J.; Tang, J.; Yang, J. Generalized Focal Loss: Learning Qualified and Distributed Bounding Boxes for Dense Object Detection. In Proceedings of the Advances in Neural Information Processing Systems, Virtual Event, 6–12 December 2020; Volume 33, pp. 21002–21012. [Google Scholar]
- Jocher, G. YOLOv5 by Ultralytics. 2020. Available online: https://github.com/ultralytics/yolov5 (accessed on 14 May 2026).
- Wang, C.Y.; Bochkovskiy, A.; Liao, H.Y.M. YOLOv7: Trainable Bag-of-Freebies Sets New State-of-the-Art for Real-Time Object Detectors. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, BC, Canada, 18–22 June 2023; pp. 7464–7475. [Google Scholar]
- Jocher, G.; Chaurasia, A.; Qiu, J. Ultralytics YOLOv8. 2023. Available online: https://github.com/ultralytics/ultralytics (accessed on 14 May 2026).
- Wang, C.Y.; Yeh, I.H.; Liao, H.Y.M. YOLOv9: Learning What You Want to Learn Using Programmable Gradient Information. In Proceedings of the European Conference on Computer Vision; Springer: Berlin/Heidelberg, Germany, 2024; pp. 1–21. [Google Scholar]
- Wang, A.; Chen, H.; Liu, L.; Chen, K.; Lin, Z.; Han, J.; Ding, G. YOLOv10: Real-Time End-to-End Object Detection. In Proceedings of the Advances in Neural Information Processing Systems, Vancouver, BC, Canada, 10–15 December 2024; Volume 37. [Google Scholar]
- Ren, S.; He, K.; Girshick, R.; Sun, J. Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks. In Proceedings of the Advances in Neural Information Processing Systems, Montreal, QC, Canada, 7–12 December 2015; Volume 28. [Google Scholar]
- Cai, Z.; Vasconcelos, N. Cascade R-CNN: Delving into High Quality Object Detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–22 June 2018; pp. 6154–6162. [Google Scholar]
- Carion, N.; Massa, F.; Synnaeve, G.; Usunier, N.; Kirillov, A.; Zagoruyko, S. End-to-End Object Detection with Transformers. In Proceedings of the European Conference on Computer Vision; Springer: Berlin/Heidelberg, Germany, 2020; pp. 213–229. [Google Scholar]
- Zhu, X.; Su, W.; Lu, L.; Li, B.; Wang, X.; Dai, J. Deformable DETR: Deformable Transformers for End-to-End Object Detection. In Proceedings of the International Conference on Learning Representations, Virtual Event, 3–7 May 2021. [Google Scholar]
- Li, F.; Zhang, H.; Liu, S.; Guo, J.; Ni, L.M.; Zhang, L. DN-DETR: Accelerate DETR Training by Introducing Query DeNoising. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, LA, USA, 19–24 June 2022; pp. 13619–13627. [Google Scholar]
- Zhang, H.; Li, F.; Liu, S.; Zhang, L.; Su, H.; Zhu, J.; Ni, L.M.; Shum, H.Y. DINO: DETR with Improved DeNoising Anchor Boxes for End-to-End Object Detection. In Proceedings of the International Conference on Learning Representations, Kigali, Rwanda, 1–5 May 2023. [Google Scholar]
- Zhao, Y.; Lv, W.; Xu, S.; Wei, J.; Wang, G.; Dang, Q.; Liu, Y.; Chen, J. DETRs Beat YOLOs on Real-time Object Detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, WA, USA, 17–21 June 2024; pp. 16965–16974. [Google Scholar]
- Qin, Z.; Li, Y. DCAM-DETR: Dual Cross-Attention Mamba Detection Transformer for RGB–Infrared Anti-UAV Detection. Information 2026, 17, 103. [Google Scholar] [CrossRef] [Scilit]
- Gu, A.; Dao, T. Mamba: Linear-time sequence modeling with selective state spaces. arXiv 2023, arXiv:2312.00752. [Google Scholar]
- Liu, Y.; Tian, Y.; Zhao, Y.; Yu, H.; Xie, L.; Wang, Y.; Ye, Q.; Liu, Y. VMamba: Visual State Space Model. In Proceedings of the Advances in Neural Information Processing Systems, Vancouver, BC, Canada, 10–15 December 2024; Volume 37. [Google Scholar]
- Zhu, L.; Liao, B.; Zhang, Q.; Wang, X.; Liu, W.; Wang, X. Vision Mamba: Efficient Visual Representation Learning with Bidirectional State Space Model. In Proceedings of the International Conference on Machine Learning, Vienna, Austria, 21–27 July 2024. [Google Scholar]
- He, H.; Zheng, J.; Xie, Y.; Huang, Q.; Dong, Y.; Tao, R.; Liu, Y.; Wang, C.; Chen, F.; Shen, Z. MobileMamba: Lightweight Multi-Receptive Visual Mamba Network. arXiv 2024, arXiv:2411.15941. [Google Scholar]
- Sun, Y.; Cao, B.; Zhu, P.; Hu, Q. DroneVehicle: Drone-based RGB-Infrared Vehicle Detection Benchmark and Baseline. IEEE Trans. Circuits Syst. Video Technol. 2022, 33, 3734–3746. [Google Scholar]
- Liu, S.; Li, F.; Zhang, H.; Yang, X.; Qi, X.; Su, H.; Zhu, J.; Zhang, L. DAB-DETR: Dynamic Anchor Boxes are Better Queries for DETR. In Proceedings of the International Conference on Learning Representations, Virtual Event, 25–29 April 2022. [Google Scholar]
- Zong, Z.; Song, G.; Liu, Y. DeTRs with Collaborative Hybrid Assignments Training. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Paris, France, 2–6 October 2023; pp. 6748–6758. [Google Scholar]
- Lv, W.; Zhao, Y.; Chang, Q.; Huang, K.; Wang, G.; Liu, Y. RT-DETRv2: Improved Baseline with Bag-of-Freebies for Real-Time Detection Transformer. arXiv 2024, arXiv:2407.17140. [Google Scholar]
- Sidi, L.; Zhensong, L.; Xiaotan, W.; Wang, Y.; Zhu, S. DPF-DETR: Enhancing Drone Image Detection with Density Perception and Multi-Scale Feature Fusion. Remote Sens. 2026, 18, 1221. [Google Scholar]
- Gu, A.; Goel, K.; Ré, C. Efficiently Modeling Long Sequences with Structured State Spaces. In Proceedings of the International Conference on Learning Representations, Virtual Event, 25–29 April 2022. [Google Scholar]
- Yang, C.; Chen, Z.; Espinosa, M.; Ericsson, L.; Wang, Z.; Liu, J.; Crowley, E.J. PlainMamba: Improving Non-Hierarchical Mamba in Visual Recognition. arXiv 2024, arXiv:2403.17695. [Google Scholar]
- Zhou, D.; Li, Y. SoccerDETR: Real-Time Soccer Object Detection via Visual State Space Models with Semantic-Aware Feature Fusion. Technologies 2026, 14, 142. [Google Scholar] [CrossRef] [Scilit]
- Li, Y.; Wang, T.; Luo, N.; Zhou, L.; Chen, Q. CGMamba: Intelligent Identification of Counterfeit Goods Based on State Space Models. Int. J. Intell. Syst. 2025, 2025, 9939880. [Google Scholar] [CrossRef] [Scilit]
- Yang, Z.; Li, Y.; Shao, J.; Li, W.; Luo, N. Lightweight Hybrid Attention for Channel, Spatial, and Token-level Enhancement. In Proceedings of the 2025 8th International Conference on Computer Information Science and Artificial Intelligence, Wuhan, China, 12–14 September 2025; pp. 212–217. [Google Scholar]
- Yang, F.; Fan, H.; Chu, P.; Blasch, E.; Ling, H. Clustered Object Detection in Aerial Images. In Proceedings of the IEEE/CVF International Conference on Computer Vision, Seoul, Republic of Korea, 27 October–2 November 2019; pp. 8311–8320. [Google Scholar]
- Huang, Y.; Chen, J.; Huang, D. UFPMP-Det: Toward Accurate and Efficient Object Detection on Drone Imagery. In Proceedings of the AAAI Conference on Artificial Intelligence, Virtual Event, 22 February–1 March 2022; Volume 36, pp. 1026–1033. [Google Scholar]
- Yang, C.; Huang, Z.; Wang, N. QueryDet: Cascaded Sparse Query for Accelerating High-Resolution Small Object Detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, New Orleans, LA, USA, 19–24 June 2022; pp. 13668–13677. [Google Scholar]
- Yuan, H.; Li, Y. CSFADet: Dual-Modal Anti-UAV Detection via Cross-Spectral Feature Alignment and Adaptive Multi-Scale Refinement. Algorithms 2026, 19, 254. [Google Scholar] [CrossRef] [Scilit]
- Zhu, S.; Luo, B.; Liu, J.; Li, Z. BSOEDet: Background Suppression and Object Enhancement Detector for UAV Aerial Imagery. IEEE Trans. Intell. Transp. Syst. 2026. [Google Scholar]
- Li, Y.; Chen, Q.; Zhu, J.; Li, Z.; Wang, M.; Zhang, Y. PM-YOLO: A powdery mildew automatic grading detection model for rubber tree. Insects 2024, 15, 937. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Zhang, Y.; Yuan, X.; Li, W.; Chen, S. Unmanned aerial vehicles for power line inspection: A cooperative way in platforms and communications. J. Commun. 2023, 14, 833–840. [Google Scholar]
- Lin, T.Y.; Dollár, P.; Girshick, R.; He, K.; Hariharan, B.; Belongie, S. Feature Pyramid Networks for Object Detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Honolulu, HI, USA, 21–26 July 2017; pp. 2117–2125. [Google Scholar]
- Liu, S.; Qi, L.; Qin, H.; Shi, J.; Jia, J. Path Aggregation Network for Instance Segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Salt Lake City, UT, USA, 18–22 June 2018; pp. 8759–8768. [Google Scholar]
- Tan, M.; Pang, R.; Le, Q.V. EfficientDet: Scalable and Efficient Object Detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Seattle, WA, USA, 13–19 June 2020; pp. 10781–10790. [Google Scholar]
- Chen, X.; Zhang, H.; Tan, Z.; Zhao, W.; Luo, B. PKINet: Poly Kernel Inception Network for Remote Sensing Object Detection. arXiv 2023, arXiv:2303.00988. [Google Scholar]
- Zhu, X.; Wang, Y.; Li, K.; Yang, L.; Gao, Y. Adaptive Feature Aggregation for Multi-Scale Object Detection in Remote Sensing Images. Remote Sens. 2023, 15, 3195. [Google Scholar]
- Rezatofighi, H.; Tsoi, N.; Gwak, J.; Sadeghian, A.; Reid, I.; Savarese, S. Generalized Intersection over Union: A Metric and a Loss for Bounding Box Regression. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Long Beach, CA, USA, 16–20 June 2019; pp. 658–666. [Google Scholar]
- Sun, P.; Zhang, R.; Jiang, Y.; Kong, T.; Xu, C.; Zhan, W.; Tomizuka, M.; Li, L.; Yuan, Z.; Wang, C.; et al. Sparse R-CNN: End in End Object Detection with Learnable Proposals. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Virtual Event, 19–25 June 2021; pp. 14454–14463. [Google Scholar]
- Wang, M.; Wang, Y.; Liu, D.; Zheng, Y.; Tang, M. YOLOv13: Real-Time Object Detection with Hyper-Graph-Enhanced Adaptive Aggregation Networks. arXiv 2025, arXiv:2503.01960. [Google Scholar]
- Wang, C.; He, W.; Nie, Y.; Guo, J.; Liu, C.; Han, K.; Wang, Y. Gold-YOLO: Efficient Object Detector via Gather-and-Distribute Mechanism. In Proceedings of the Advances in Neural Information Processing Systems, Vancouver, BC, Canada, 10–15 December 2024; Volume 36. [Google Scholar]





| Paradigm | Global Context | Complexity | Multi-Scale Fusion | UAV-Specific |
|---|---|---|---|---|
| CNN-based (YOLO, FCOS) | Limited | FPN / PANet | No | |
| Two-Stage (Faster/Cascade R-CNN) | Limited | FPN + RPN | No | |
| DETR-based (DETR, DINO) | Full | Deformable Attn. | No | |
| RT-DETR | Full | Hybrid Encoder | No | |
| SSM-based (VMamba) | Full | None | No | |
| RSMamDet (Ours) | Full | DASI + AMFF | Yes |
| Configuration | mAP50 (%) | Params (M) | FPS |
|---|---|---|---|
| Single-stream ( only) | 69.4 | 18.2 | 198.5 |
| Two-stream ( + ) | 71.2 | 19.0 | 192.3 |
| Three-stream (Full SFS) | 72.6 | 19.8 | 186.2 |
| Category | Method | Backbone | mAP50 (%) | mAP50:95 (%) | FPS |
|---|---|---|---|---|---|
| One-Stage | SSD [4] | VGG-16 | 47.2 | 28.6 | 42.3 |
| RetinaNet [5] | ResNet-50 | 49.8 | 31.3 | 35.7 | |
| FCOS [6] | ResNet-50 | 52.3 | 33.7 | 38.4 | |
| ATSS [7] | ResNet-50 | 54.6 | 35.9 | 36.2 | |
| GFL [8] | ResNet-50 | 56.1 | 37.4 | 33.8 | |
| Two-Stage | Faster R-CNN [14] | ResNet-50 | 53.4 | 34.8 | 18.5 |
| Cascade R-CNN [15] | ResNet-50 | 57.2 | 39.3 | 12.7 | |
| Sparse R-CNN [49] | ResNet-50 | 58.6 | 40.1 | 22.4 | |
| Grid R-CNN | ResNet-50 | 55.8 | 38.1 | 16.3 | |
| YOLO-Based | YOLOv5s [9] | CSPDarkNet | 59.3 | 38.7 | 163.5 |
| YOLOv7 [10] | E-ELAN | 61.7 | 41.2 | 113.2 | |
| YOLOv8s [11] | CSPDarkNet | 63.2 | 43.8 | 152.7 | |
| YOLOv8-L [11] | CSPDarkNet | 65.4 | 46.2 | 84.3 | |
| YOLOv9s [12] | Gelan | 64.5 | 45.1 | 128.3 | |
| YOLOv10s [13] | CSP | 65.1 | 45.8 | 145.2 | |
| YOLOv13 [50] | HyperGraph | 66.4 | 47.1 | 118.4 | |
| Gold-YOLO-S [51] | Gold | 64.8 | 45.3 | 142.7 | |
| Transformer-Based | DETR [16] | ResNet-50 | 56.8 | 37.2 | 22.5 |
| Deformable DETR [17] | ResNet-50 | 61.3 | 42.7 | 28.4 | |
| DAB-DETR [27] | ResNet-50 | 62.8 | 43.9 | 25.7 | |
| DN-DETR [18] | ResNet-50 | 63.5 | 44.6 | 23.8 | |
| RT-DETR-R18 [20] | ResNet-18 | 65.8 | 46.3 | 217.4 | |
| RT-DETR-R50 [20] | ResNet-50 | 67.2 | 47.8 | 108.7 | |
| Co-DETR [28] | ResNet-50 | 68.3 | 49.1 | 18.6 | |
| RT-DETR-L [20] | ResNet-101 | 68.5 | 49.4 | 74.2 | |
| Ours | RSMamDet | MobileMamba | 72.6 | 53.4 | 186.2 |
| Method | Params (M) | GFLOPs | Mem. (MB) | FPS | mAP50 (%) |
|---|---|---|---|---|---|
| SSD [4] | 26.3 | 35.2 | 312 | 42.3 | 47.2 |
| Faster R-CNN [14] | 41.5 | 180.7 | 1243 | 18.5 | 53.4 |
| YOLOv8s [11] | 11.2 | 28.6 | 284 | 152.7 | 63.2 |
| YOLOv8-L [11] | 43.7 | 165.2 | 1125 | 84.3 | 65.4 |
| YOLOv13 [50] | 36.8 | 127.5 | 876 | 118.4 | 66.4 |
| RT-DETR-R18 [20] | 20.0 | 60.4 | 487 | 217.4 | 65.8 |
| RT-DETR-R50 [20] | 42.0 | 136.5 | 892 | 108.7 | 67.2 |
| Co-DETR [28] | 64.2 | 234.5 | 1687 | 18.6 | 68.3 |
| RT-DETR-L [20] | 76.3 | 259.7 | 1842 | 74.2 | 68.5 |
| RSMamDet (Ours) | 19.8 | 42.3 | 276 | 186.2 | 72.6 |
| Category | Method | Backbone | mAP50 (%) | mAP50:95 (%) | FPS |
|---|---|---|---|---|---|
| One-Stage | SSD [4] | VGG-16 | 18.3 | 10.2 | 42.3 |
| RetinaNet [5] | ResNet-50 | 20.1 | 11.8 | 35.7 | |
| FCOS [6] | ResNet-50 | 22.8 | 13.4 | 38.4 | |
| ATSS [7] | ResNet-50 | 24.3 | 14.9 | 36.2 | |
| GFL [8] | ResNet-50 | 25.7 | 15.8 | 33.8 | |
| Two-Stage | Faster R-CNN [14] | ResNet-50 | 22.6 | 13.1 | 18.5 |
| Cascade R-CNN [15] | ResNet-50 | 26.1 | 16.4 | 12.7 | |
| Sparse R-CNN [49] | ResNet-50 | 27.3 | 17.2 | 22.4 | |
| ClusDet [36] | ResNet-50 | 26.7 | 15.9 | 8.6 | |
| YOLO-Based | YOLOv5s [9] | CSPDarkNet | 24.3 | 13.8 | 163.5 |
| YOLOv7 [10] | E-ELAN | 27.5 | 16.3 | 113.2 | |
| YOLOv8s [11] | CSPDarkNet | 29.1 | 18.2 | 152.7 | |
| YOLOv8-L [11] | CSPDarkNet | 31.4 | 20.1 | 84.3 | |
| YOLOv9s [12] | Gelan | 30.4 | 19.1 | 128.3 | |
| YOLOv10s [13] | CSP | 31.2 | 19.8 | 145.2 | |
| YOLOv13 [50] | HyperGraph | 32.1 | 20.6 | 118.4 | |
| Gold-YOLO-S [51] | Gold | 30.8 | 19.4 | 142.7 | |
| Transformer-Based | DETR [16] | ResNet-50 | 26.4 | 15.7 | 22.5 |
| Deformable DETR [17] | ResNet-50 | 31.7 | 20.4 | 28.4 | |
| DAB-DETR [27] | ResNet-50 | 32.4 | 21.1 | 25.7 | |
| DN-DETR [18] | ResNet-50 | 33.1 | 21.8 | 23.8 | |
| RT-DETR-R18 [20] | ResNet-18 | 34.2 | 22.6 | 217.4 | |
| RT-DETR-R50 [20] | ResNet-50 | 36.5 | 24.3 | 108.7 | |
| Co-DETR [28] | ResNet-50 | 37.8 | 25.4 | 18.6 | |
| RT-DETR-L [20] | ResNet-101 | 38.0 | 25.6 | 74.2 | |
| Ours | RSMamDet | MobileMamba | 40.2 | 27.6 | 186.2 |
| MobileMamba | SFS | DASI | PKINet | AMFF | UMC | mAP50(%) | GFLOPs | FPS |
|---|---|---|---|---|---|---|---|---|
| 65.8 | 60.4 | 217.4 | ||||||
| √ | 67.2 | 53.7 | 205.8 | |||||
| √ | √ | 68.5 | 49.2 | 196.3 | ||||
| √ | √ | √ | 69.8 | 46.8 | 194.5 | |||
| √ | √ | √ | √ | 71.1 | 44.1 | 190.7 | ||
| √ | √ | √ | √ | √ | 72.1 | 42.3 | 187.3 | |
| √ | √ | √ | √ | √ | √ | 72.6 | 42.3 | 186.2 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Wu, M.; Liu, X.; Li, X.; Gan, W. RSMamDet: Efficient UAV Remote Sensing Vehicle Detection via Linear State Space Models and Adaptive Multi-Level Feature Fusion. Drones 2026, 10, 396. https://doi.org/10.3390/drones10050396
Wu M, Liu X, Li X, Gan W. RSMamDet: Efficient UAV Remote Sensing Vehicle Detection via Linear State Space Models and Adaptive Multi-Level Feature Fusion. Drones. 2026; 10(5):396. https://doi.org/10.3390/drones10050396
Chicago/Turabian StyleWu, Man, Xiaozhang Liu, Xiulai Li, and Wenbiao Gan. 2026. "RSMamDet: Efficient UAV Remote Sensing Vehicle Detection via Linear State Space Models and Adaptive Multi-Level Feature Fusion" Drones 10, no. 5: 396. https://doi.org/10.3390/drones10050396
APA StyleWu, M., Liu, X., Li, X., & Gan, W. (2026). RSMamDet: Efficient UAV Remote Sensing Vehicle Detection via Linear State Space Models and Adaptive Multi-Level Feature Fusion. Drones, 10(5), 396. https://doi.org/10.3390/drones10050396