

Fast Adaptive Approximate Nearest Neighbor Search with Cluster-Shaped Indices

 , , ,
 , ,
Abstract
1. Introduction
2. Approximate Nearest Neighbors Search Methods
2.1. Graph-Based Search
2.2. Parallel Graph Systems
2.3. Parallel and General Search Techniques
2.4. Vector Quantization and Compression Algorithms
2.5. Scalar Quantization
2.6. Product Quantization
2.7. Approximate Search with the Use of the Inverted File Based on Standard Quantization
2.8. Selecting a Search Algorithm Under Established Requirements
3. IVF-Based Adaptive Search with Query Complexity Classification
3.1. Data Processing Query Complexity Analysis
3.2. Approximation of Cluster Number to Be Processed (nprobe) as a Function of Number of Effective Clusters (nres)
- If nres ≤ 19, then q is simple;
- If nres ≤ 21 and σ(l2) ≥ 4980.56, then q is simple;
- If nres ≤ 28 and σ(lc) ≥ 9593.3, then q is simple;
- If nres ≤ 33 and <l2> ≤ 48,853.7 and max(lc) ≥ 77,234.4, then q is simple;
- If nres ≤ 34 and <l2> ≤ 37,432.2 and <lc> ≤ 36,761.1, then q is simple;
- Otherwise, q is complex.
- If nres ≤ 21, then q is simple;
- If nres ≤ 30 and the number of vectors processed ≥ 31,676, then q is simple;
- Otherwise, q is complex.
- If nres ≤ 28 then q is simple.
| Algorithm 1. Simplified adaptive approximate nearest neighbors search. |
| Required: Built IVF index, query vector q, ratio of clusters for preliminary search n1, ratio of clusters for additional search n2, and maximal number of effective clusters for a query to be considered simple M. |
|
3.3. Query Complexity Classifier Based on the Number of Effective Clusters
| Algorithm 2. Classifier training algorithm (determining query complexity classes and selecting the presumably sufficient nprobe value for each class) |
| Required: Training set of queries Q as a random sample of data vectors, expected Recall@K value, number of nearest neighbors K, minimum number of clusters to be scanned nminchecked. |
|
| Algorithm 3. The process of requesting a vector and determining the nearest neighbors based on specific parameters. |
| Required: query vector q, number of desired nearest neighbors K, nminchecked, complexity classes borders M1, M2, M3, nprobes values for each complexity class S1, S2, S3, S4, trained classifier for K, nminchecked and expected Recall@K (see Algorithm 2). |
|
4. Computational Experiments
5. Conclusions
Author Contributions
Funding
Data Availability Statement
Conflicts of Interest
References
- Abbasifard, M.R.; Ghahremani, B.; Naderi, H. A Survey on Nearest Neighbor Search Methods. Int. J. Comput. Appl. 2014, 95, 39–52. [Google Scholar] [CrossRef] [Scilit]
- McLachlan, G.J. Mahalanobis Distance. Resonance 1999, 4, 20–26. [Google Scholar] [CrossRef] [Scilit]
- Ponomarenko, A.; Malkov, Y.; Logvinov, A.; Krylov, V. Approximate Nearest Neighbor Search Small World Approach. In Proceedings of the International Conference on Information and Communication Technologies and Applications, Orlando, FL, USA, 29 November–2 December 2011. [Google Scholar] [CrossRef] [Scilit]
- Peng, Y.; Choi, B.; Chan, T.N.; Yang, J.; Xu, J. Efficient approximate nearest neighbor search in multi-dimensional databases. Proc. ACM Manag. Data 2023, 1, 1–27. [Google Scholar] [CrossRef] [Scilit]
- Bhatia, N.; Ashev, V. Survey of Nearest Neighbor Techniques. arXiv 2010, arXiv:1007.0085. [Google Scholar] [CrossRef] [Scilit]
- Cunningham, P.; Delany, S.J. K-nearest neighbour classifiers-a tutorial. ACM Comput. Surv. 2021, 54, 1–25. [Google Scholar] [CrossRef] [Scilit]
- Hwang, Y.; Han, B.; Ahn, H.-K. A Fast Nearest Neighbor Search Algorithm by Nonlinear Embedding. In Proceedings of the 2012 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Providence, RI, USA, 16–21 June 2012; pp. 3053–3060. [Google Scholar] [CrossRef] [Scilit]
- Kaminska, O.; Cornelis, C.; Hoste, V. Fuzzy rough nearest neighbour methods for aspect-based sentiment analysis. Electronics 2023, 12, 1088. [Google Scholar] [CrossRef] [Scilit]
- Weber, R.; Schek, H.-J.; Blott, S. A Quantitative Analysis and Performance Study for Similarity-Search Methods in High-Dimensional Spaces. In Proceedings of the 24th International Conference on Very Large Data Bases (VLDB), New York, NY, USA, 24–27 August 1998; pp. 194–205. [Google Scholar]
- Heneghan, C. A Method for Initialising the K-means Clustering Algorithm Using kd-trees. Pattern Recognit. Lett. 2007, 28, 965–973. [Google Scholar] [CrossRef] [Scilit]
- Kraus, P.; Dzwinel, W. Nearest Neighbor Search by Using Partial KD-tree Method. Theor. Appl. Genet. 2008, 20, 149–165. [Google Scholar]
- Narasimhulu, Y.; Suthar, A.; Pasunuri, R.; Vadlamudi, C.V. CKD-Tree: An Improved KD-Tree Construction Algorithm. In Proceedings of the International Semantic Intelligence Conference 2021 (ISIC 2021), New Delhi, India, 25–27 February 2021; pp. 211–218. [Google Scholar]
- Yen, S.-H.; Shih, C.-Y.; Chang, H.-W.; Li, T.-K. Nearest Neighbor Searching in High Dimensions Using Multiple KD-trees. In Proceedings of the 10th WSEAS International Conference on Signal Processing, Computational Geometry and Artificial Vision, Taipei, Taiwan, 20–22 August 2010. [Google Scholar]
- Sun, Y.; Zhao, T.; Yoon, S.; Lee, Y. A Hybrid Approach Combining R*-Tree and k-d Trees to Improve Linked Open Data Query Performance. Appl. Sci. 2021, 11, 2405. [Google Scholar] [CrossRef] [Scilit]
- Guttman, A. R-Trees: A Dynamic Index Structure for Spatial Searching. In Proceedings of the 1984 ACM SIGMOD International Conference on Management of Data, Boston, MA, USA, 18–21 June 1984; pp. 47–57. [Google Scholar]
- Papadopoulos, A.; Manolopoulos, Y. Performance of Nearest Neighbor Queries in R-Trees. In Proceedings of the 6th International Conference on Database Theory (ICDT’97), Delphi, Greece, 8–10 January 1997; pp. 394–408. [Google Scholar] [CrossRef] [Scilit]
- Gu, T.; Feng, K.; Cong, G.; Long, C.; Wang, Z.; Wang, S. The rlr-tree: A reinforcement learning based r-tree for spatial data. Proc. ACM Manag. Data 2023, 1, 1–26. [Google Scholar] [CrossRef] [Scilit]
- Cheung, K.L.; Fu, A.W.-C. Enhanced Nearest Neighbour Search on the R-tree. ACM SIGMOD Rec. 1998, 27, 16–21. [Google Scholar] [CrossRef] [Scilit]
- Jagadish, H.V.; Ooi, B.C.; Tan, K.-L.; Yu, C.; Zhang, R. iDistance: An Adaptive B+-tree Based Indexing Method for Nearest Neighbor Search. ACM Trans. Database Syst. 2005, 30, 364–397. [Google Scholar] [CrossRef] [Scilit]
- Song, Z.; Qin, Z.; Deng, W.; Zhao, Y. The B+-tree-based Method for Nearest Neighbor Queries in Traffic Simulation Systems. TELKOMNIKA Indones. J. Electr. Eng. 2014, 12, 8175–8192. [Google Scholar] [CrossRef] [Scilit]
- Jafari, O.; Maurya, P.; Islam, K.M.; Nagarkar, P. Optimizing Fair Approximate Nearest Neighbor Searches Using Threaded b+−Trees. In International Conference on Similarity Search and Applications; Springer International Publishing: Cham, Switzerland, 2021; pp. 133–147. [Google Scholar]
- Beygelzimer, A.; Kakade, S.; Langford, J. Cover Trees for Nearest Neighbor. In Proceedings of the 23rd International Conference on Machine Learning (ICML 2006), Pittsburgh, PA, USA, 25–29 June 2006; pp. 97–104. [Google Scholar] [CrossRef] [Scilit]
- Elkin, Y. A new compressed cover tree for k-nearest neighbour search and the stable-under-noise mergegram of a point cloud. arXiv 2022, arXiv:2205.10194. [Google Scholar] [CrossRef] [Scilit]
- Beyer, K.; Goldstein, J.; Ramakrishnan, R.; Shaft, U. When Is “Nearest Neighbor” Meaningful? In Database Theory—ICDT’99, Proceedings of the 7th International Conference, Jerusalem, Israel, 10–12 January 1999; Beeri, C., Buneman, P., Eds.; Lecture Notes in Computer Science, 1540; Springer: Berlin/Heidelberg, Germany, 1999; pp. 217–235. [Google Scholar] [CrossRef] [Scilit]
- Malkov, Y.; Ponomarenko, A.; Logvinov, A.; Krylov, V. Scalable Distributed Algorithm for Approximate Nearest Neighbor Search Problem in High Dimensional General Metric Spaces. In Similarity Search and Applications, Proceedings of the 5th International Conference on Similarity Search and Applications (SISAP 2012), Toronto, ON, Canada, 9–10 August 2012; Navarro, G., Pestov, V., Eds.; Lecture Notes in Computer Science; Springer: Berlin/Heidelberg, Germany, 2012; pp. 132–147. [Google Scholar] [CrossRef] [Scilit]
- Malkov, Y.; Ponomarenko, A.; Logvinov, A.; Krylov, V. Approximate nearest neighbor algorithm based on navigable small world graphs. Inf. Syst. 2014, 45, 61–68. [Google Scholar] [CrossRef] [Scilit]
- Zhao, K.; Lu, H.; Mei, J. Locality Preserving Hashing. Proc. AAAI Conf. Artif. Intell. 2014, 28, 2874–2880. [Google Scholar] [CrossRef] [Scilit]
- Song, S.; Liu, L.; Chen, R.; Peng, W.; Wang, Y. Secure Approximate Nearest Neighbor Search with Locality-Sensitive Hashing. In European Symposium on Research in Computer Security; Springer Nature: Cham, Switzerland, 2023; pp. 411–430. [Google Scholar]
- Cover, T.; Hart, P. Nearest neighbor pattern classification. IEEE Trans. Inf. Theory 1967, 13, 21–27. [Google Scholar] [CrossRef] [Scilit]
- Slaney, M.; Casey, M. Locality-Sensitive Hashing for Finding Nearest Neighbors [Lecture Notes]. IEEE Signal Process. Mag. 2008, 25, 128–131. [Google Scholar] [CrossRef] [Scilit]
- Wei, C.; Li, C.; Liu, Y.; Chen, S.; Zuo, Z.; Wang, P.; Ye, Z. Causal Discovery and Reasoning for Continuous Variables with an Improved Bayesian Network Constructed by Locality Sensitive Hashing and Kernel Density Estimation. Entropy 2025, 27, 123. [Google Scholar] [CrossRef] [Scilit]
- Blott, S.; Weber, R. A Simple Vector-Approximation File for Similarity Search in High-Dimensional Vector Spaces; Esprit: Penrith, UK, 1998. [Google Scholar]
- Yerpude, P. Vector Approximation File: Cluster Bounding in High-Dimension Data Set. Int. J. Eng. Adv. Technol. 2011, 1, 126–130. [Google Scholar]
- Kröger, P.; Schubert, M.; Zhu, Z. Efficient Query Processing in Arbitrary Subspaces Using Vector Approximations. In Proceedings of the 18th International Conference on Scientific and Statistical Database Management (SSDBM′06), Vienna, Austria, 3–5 July 2006; pp. 184–190. [Google Scholar] [CrossRef] [Scilit]
- Jégou, H.; Douze, M.; Schmid, C. Product Quantization for Nearest Neighbor Search. IEEE Trans. Pattern Anal. Mach. Intell. 2011, 33, 117–128. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Ge, T.; He, K.; Ke, Q.; Sun, J. Optimized Product Quantization for Approximate Nearest Neighbor Search. In Proceedings of the 2013 IEEE Conference on Computer Vision and Pattern Recognition, Portland, OR, USA, 23–28 June 2013; pp. 2946–2953. [Google Scholar] [CrossRef] [Scilit]
- Geist, M.; Pietquin, O.; Fricout, G. Kernelizing Vector Quantization Algorithms. In Proceedings of the European Symposium on Artificial Neural Networks (ESANN), Bruges, Belgium, 22–24 April 2009; pp. 541–546. [Google Scholar]
- Ai, L.; Cheng, H.; Wang, X.; Chen, C.; Liu, D.; Zheng, X.; Wang, Y. Approximate nearest neighbor search using enhanced accumulative quantization. Electronics 2022, 11, 2236. [Google Scholar] [CrossRef] [Scilit]
- Kalantidis, Y.; Avrithis, Y. Locally Optimized Product Quantization for Approximate Nearest Neighbor Search. In Proceedings of the IEEE Computer Society Conference on Computer Vision and Pattern Recognition (CVPR), Columbus, OH, USA, 23–28 June 2014; pp. 2321–2328. [Google Scholar] [CrossRef] [Scilit]
- Yu, T.; Meng, J.; Fang, C.; Jin, H.; Yuan, J. Product Quantization Network for Fast Visual Search. Int. J. Comput. Vis. 2020, 128, 2325–2343. [Google Scholar] [CrossRef] [Scilit]
- Zhang, M.; Zhe, X.; Yan, H. Orthonormal Product Quantization Network for Scalable Face Image Retrieval. Pattern Recognit. 2023, 141, 109671. [Google Scholar] [CrossRef] [Scilit]
- Gu, L.; Liu, J.; Liu, X.; Wan, W.; Sun, J. Entropy-Optimized Deep Weighted Product Quantization for Image Retrieval. IEEE Trans. Image Process. 2024, 33, 1162–1174. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, H.; Wang, W.; Xu, B.; Zhou, J.; Du, M.; Yang, K.; Xiao, Y. Tao: A Learning Framework for Adaptive Nearest Neighbor Search using Static Features Only. arXiv 2021, arXiv:2110.00696. [Google Scholar] [CrossRef] [Scilit]
- Babenko, A.; Lempitsky, V. The Inverted Multi-Index. IEEE Trans. Pattern Anal. Mach. Intell. 2014, 37, 1247–1260. [Google Scholar] [CrossRef] [Scilit]
- Malkov, Y.A.; Yashunin, D.A. Efficient and Robust Approximate Nearest Neighbor Search Using Hierarchical Navigable Small World Graphs. IEEE Trans. Pattern Anal. Mach. Intell. 2020, 42, 824–836. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X.; Tao, B.; Jiang, D.; Chen, B.; Tang, D.; Liu, X. Novel probabilistic collision detection for manipulator motion planning using HNSW. Machines 2024, 12, 321. [Google Scholar] [CrossRef] [Scilit]
- pgvector. Open-Source Vector Similarity Search for Postgres. Available online: https://github.com/pgvector/pgvector (accessed on 5 September 2025).
- Wang, J.; Yi, X.; Guo, R.; Jin, H.; Xu, P.; Li, S.; Wang, X.; Guo, X.; Li, C.; Xu, X.; et al. Milvus: A Purpose-Built Vector Data Management System. In Proceedings of the 2021 International Conference on Management of Data (SIGMOD ’21), Online, 20–25 June 2021; ACM: New York, NY, USA, 2021; pp. 2614–2627. [Google Scholar] [CrossRef] [Scilit]
- Jin, Y.; Wu, Y.; Hu, W.; Maggs, B.M.; Zhang, X.; Zhuo, D. Curator: Efficient Indexing for Multi-Tenant Vector Databases. arXiv 2024, arXiv:2401.07119. [Google Scholar] [CrossRef] [Scilit]
- Bruch, S.; Nardini, F.M.; Rulli, C.; Venturini, R. Efficient Inverted Indexes for Approximate Retrieval over Learned Sparse Representations. In Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR ’24), Washington, DC, USA, 14–18 July 2024; ACM: New York, NY, USA, 2024; pp. 152–162. [Google Scholar] [CrossRef] [Scilit]
- ANN-Benchmarks. Benchmarking Environment for Approximate Nearest Neighbor Algorithms. Available online: https://ann-benchmarks.com/index.html (accessed on 5 September 2025).
- Andoni, A.; Indyk, P. Near-Optimal Hashing Algorithms for Approximate Nearest Neighbor in High Dimensions. In 2006 47th Annual IEEE Symposium on Foundations of Computer Science (FOCS’06), Berkeley, CA, USA, 21–24 October 2006; IEEE: Washington, DC, USA, 2006; pp. 459–468. [Google Scholar] [CrossRef] [Scilit]
- Dai, H.; Zhu, M.; Gui, X. LSH Models in Federated Recommendation. Appl. Sci. 2024, 14, 4423. [Google Scholar] [CrossRef] [Scilit]
- Andoni, A.; Indyk, P.; Laarhoven, T.; Razenshteyn, I.; Schmidt, L. Practical and Optimal LSH for Angular Distance. In Advances in Neural Information Processing Systems 28 (NIPS 2015), Proceedings of the 29th Annual Conference on Neural Information Processing Systems 2015, Montreal, QC, Canada, 7–12 December 2015; Cortes, C., Lawrence, N., Lee, D., Sugiyama, M., Garnett, R., Eds.; MIT Press: Cambridge, MA, USA, 2015; pp. 1225–1233. Available online: https://proceedings.neurips.cc/paper/2015/file/2823f4797102ce1a1aec05359cc16dd9-Paper.pdf (accessed on 5 September 2025).
- Romild, C.J.; Schauser, T.H.; Borup, J.A. Enhancing Approximate Nearest Neighbor Search: Binary-Indexed LSH-Tries, Trie Rebuilding, and Batch Extraction. In International Conference on Similarity Search and Applications; Springer Nature: Cham, Switzerland, 2023; pp. 265–272. [Google Scholar]
- Datar, M.; Immorlica, N.; Indyk, P.; Mirrokni, V.S. Locality-Sensitive Hashing Scheme Based on p-Stable Distributions. In Proceedings of the Twentieth Annual Symposium on Computational Geometry (SCG ’04), Brooklyn, NY, USA, 8–11 June 2004; Association for Computing Machinery: New York, NY, USA, 2004; pp. 253–262. [Google Scholar] [CrossRef] [Scilit]
- Indyk, P.; Motwani, R. Approximate Nearest Neighbors: Towards Removing the Curse of Dimensionality. In Proceedings of the Thirtieth Annual ACM Symposium on Theory of Computing (STOC ’98), Dallas, TX, USA, 23–26 May 1998; Association for Computing Machinery: New York, NY, USA, 1998; pp. 604–613. [Google Scholar] [CrossRef] [Scilit]
- Jegou, H.; Douze, M.; Schmid, C. Hamming Embedding and Weak Geometric Consistency for Large Scale Image Search. In Proceedings of the European Conference on Computer Vision (ECCV 2008), Marseille, France, 12–18 October 2008; Springer: Berlin/Heidelberg, Germany, 2008; pp. 304–317. [Google Scholar]
- Wang, R.; Deng, D. DeltaPQ: Lossless Product Quantization Code Compression for High Dimensional Similarity Search. Proc. VLDB Endow. 2020, 13, 3603–3616. [Google Scholar] [CrossRef] [Scilit]
- Wei, C.; Wu, B.; Wang, S.; Lou, R.; Zhan, C.; Li, F.; Cai, Y. AnalyticDB-V: A Hybrid Analytical Engine Towards Query Fusion for Structured and Unstructured Data. Proc. VLDB Endow. 2020, 12, 3152–3165. [Google Scholar] [CrossRef] [Scilit]
- Wu, X.; Guo, R.; Suresh, A.T.; Kumar, S.; Holtmann-Rice, D.N.; Simcha, D.; Yu, F. Multiscale Quantization for Fast Similarity Search. Adv. Neural Inf. Process. Syst. 2017, 30, 5745–5755. [Google Scholar]
- Johnson, J.; Douze, M.; Jegou, H. Billion-scale similarity search with GPUs. arXiv 2017, arXiv:1702.08734. [Google Scholar] [CrossRef] [Scilit]
- Silpa-Anan, C.; Hartley, R. Optimised KD-Trees for Fast Image Descriptor Matching. In Proceedings of the2008 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Anchorage, AK, USA, 23–28 June 2008; IEEE: New York, NY, USA, 2008; pp. 1–8. [Google Scholar]
- Beckmann, N.; Kriegel, H.-P.; Schneider, R.; Seeger, B. The R*-Tree: An Efficient and Robust Access Method for Points and Rectangles. In Proceedings of the 1990 ACM SIGMOD International Conference on Management of Data, Atlantic City, NJ, USA, 23–25 May 1990; pp. 322–331. [Google Scholar]
- Muja, M.; Lowe, D.G. Fast Approximate Nearest Neighbors With Automatic Algorithm Configuration. In Proceedings of the Fourth International Conference on Computer Vision Theory and Applications (VISAPP), Lisbon, Portugal, 5–8 February 2009; SciTePress—Science and Technology Publications: Lisboa, Portugal, 2009; Volume 2, pp. 331–340. [Google Scholar] [CrossRef] [Scilit]
- Aumüller, M.; Bernhardsson, E.; Faithfull, A. ANN-Benchmarks: A Benchmarking Tool for Approximate Nearest Neighbor Algorithms. In International Conference on Similarity Search and Applications (SISAP); Springer: Cham, Switzerland, 2017; pp. 34–49. [Google Scholar]
- Echihabi, K.; Zoumpatianos, K.; Palpanas, T.; Benbrahim, H. Return of the Lernaean Hydra: Experimental Evaluation of Data Series Approximate Similarity Search. Proc. VLDB Endow. 2019, 13, 403–420. [Google Scholar] [CrossRef] [Scilit]
- Fu, C.; Xiang, C.; Wang, C.; Cai, D. Fast Approximate Nearest Neighbor Search with the Navigating Spreading-out Graph. Proc. VLDB Endow. 2019, 12, 461–474. [Google Scholar] [CrossRef] [Scilit]
- Li, W.; Zhang, Y.; Sun, Y.; Wang, W.; Li, M.; Zhang, W.; Lin, X. Approximate Nearest Neighbor Search on High Dimensional Data—Experiments, Analyses, and Improvement. IEEE Trans. Knowl. Data Eng. 2020, 32, 1475–1488. [Google Scholar] [CrossRef] [Scilit]
- Zhang, J.; Khoram, S.; Li, J. Efficient Large-Scale Approximate Nearest Neighbor Search on OpenCL FPGA. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Salt Lake City, UT, USA, 18–22 June 2018; IEEE Computer Society: Los Alamitos, CA, USA, 2018; pp. 4924–4932. [Google Scholar]
- Yu, C.; Wang, M.; Chen, S.; Wang, W.; Fang, W.; Chen, Y.; Xiong, N. Efficient NPU–GPU Scheduling for Real-Time Deep Learning Inference on Mobile Devices. J. Real Time Image Proc. 2025, 22, 1–13. [Google Scholar] [CrossRef] [Scilit]
- Harwood, B.; Drummond, T. FANNG: Fast Approximate Nearest Neighbour Graphs. In Proceedings of the 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Las Vegas, NV, USA, 27–30 June 2016; IEEE: New York, NY, USA, 2016; pp. 5713–5722. [Google Scholar] [CrossRef] [Scilit]
- Li, C.; Zhang, M.; Andersen, D.G.; He, Y. Improving Approximate Nearest Neighbor Search through Learned Adaptive Early Termination. In Proceedings of the 2020 ACM SIGMOD International Conference on Management of Data (SIGMOD ‘20), Portland, OR, USA, 14–19 June 2020; ACM: New York, NY, USA, 2020; pp. 2539–2554. [Google Scholar] [CrossRef] [Scilit]
- Baranchuk, D.; Persiyanov, D.; Sinitsin, A.; Babenko, A. Learning to Route in Similarity Graphs. In Proceedings of the 36th International Conference on Machine Learning (ICML 2019), Long Beach, CA, USA, 9–15 June 2019; Chaudhuri, K., Salakhutdinov, R., Eds.; PMLR: Long Beach, CA, USA, 2019; Volume 97, pp. 475–484. [Google Scholar]
- Bashyam, K.R.; Vadhiyar, S. Fast Scalable Approximate Nearest Neighbor Search for High-Dimensional Data. In Proceedings of the 2020 IEEE International Conference on Cluster Computing (CLUSTER), Kobe, Japan, 14–17 September 2020; IEEE: New York, NY, USA, 2020; pp. 294–302. [Google Scholar] [CrossRef] [Scilit]
- Deng, S.; Yan, X.; Kelvin, K.W.N.; Jiang, C.; Cheng, J. Pyramid: A General Framework for Distributed Similarity Search on Large-Scale Datasets. In Proceedings of the 2019 IEEE International Conference on Big Data (Big Data), Los Angeles, CA, USA, 9–12 December 2019; IEEE: New York, NY, USA, 2019; pp. 1066–1071. [Google Scholar] [CrossRef] [Scilit]
- Subramanya, S.J.; Devvrit, F.; Simhadri, H.V.; Krishnawamy, R.; Kadekodi, R. DiskANN: Fast Accurate Billion-point Nearest Neighbor Search on a Single Node. In Advances in Neural Information Processing Systems 32; Wallach, H., Larochelle, H., Beygelzimer, A., d’Alche-Buc, F., Fox, E., Garnett, R., Eds.; Curran Associates, Inc.: Red Hook, NY, USA, 2019; pp. 13771–13781. Available online: https://proceedings.neurips.cc/paper/2019/file/09853c7fb1d3f8ee67a61b6bf4a7f8e6-Paper.pdf (accessed on 1 July 2025).
- Lin, P.-C.; Zhao, W.-L. Graph based Nearest Neighbor Search: Promises and Failures. arXiv 2019, arXiv:1904.02077. [Google Scholar] [CrossRef] [Scilit]
- Muñoz, J.V.; Gonçalves, M.A.; Dias, Z.; Torres, R.D.S. Hierarchical clustering-based graphs for large scale approximate nearest neighbor search. Pattern Recognit. 2019, 96, 106970. [Google Scholar] [CrossRef] [Scilit]
- PyNNDescent. GitHub—lmcinnes/pynndescent: A Python Nearest Neighbor Descent for Approximate Nearest Neighbors. Available online: https://github.com/lmcinnes/pynndescent (accessed on 16 September 2025).
- Nguyen, D.; Lenharth, A.; Pingali, K. A Lightweight Infrastructure for Graph Analytics. In Proceedings of the Twenty-Fourth ACM Symposium on Operating Systems Principles, Farmington, PA, USA, 3–6 November 2013; ACM: New York, NY, USA, 2013; pp. 456–471. [Google Scholar] [CrossRef] [Scilit]
- Shun, J.; Blelloch, G.E. Ligra: A Lightweight Graph Processing Framework for Shared Memory. In Proceedings of the 18th ACM SIGPLAN Symposium on Principles and Practice of Parallel Programming (PPoPP ‘13), Shenzhen, China, 23–27 February 2013; ACM: New York, NY, USA, 2013; pp. 135–146. [Google Scholar] [CrossRef] [Scilit]
- Pandit, G.; Röder, M.; Ngonga Ngomo, A.C. Evaluating Approximate Nearest Neighbour Search Systems on Knowledge Graph Embeddings. In European Semantic Web Conference; Springer Nature: Cham, Switzerland, 2025; pp. 59–76. [Google Scholar]
- Zhang, K.; Chen, R.; Chen, H. NUMA-Aware Graph-Structured Analytics. In Proceedings of the 20th ACM SIGPLAN Symposium on Principles and Practice of Parallel Programming, San Francisco, CA, USA, 7–11 February 2015; ACM: New York, NY, USA, 2015; pp. 183–193. [Google Scholar] [CrossRef] [Scilit]
- Sun, J.; Vandierendonck, H.; Nikolopoulos, D.S. GraphGrind: Addressing Load Imbalance of Graph Partitioning. In Proceedings of the International Conference on Supercomputing, Chicago, IL, USA, 14 June 2017; ACM: New York, NY, USA, 2017; pp. 1–10. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Brahmakshatriya, A.; Chen, X.; Dhulipala, L.; Kamil, S.; Amarasinghe, S.; Shun, J. Optimizing Ordered Graph Algorithms with GraphIt. In Proceedings of the 18th ACM/IEEE International Symposium on Code Generation and Optimization, San Diego, CA, USA, 22–26 February 2020; ACM: New York, NY, USA, 2020; pp. 158–170. [Google Scholar] [CrossRef] [Scilit]
- Vandierendonck, H. Graptor: Efficient Pull and Push Style Vectorized Graph Processing. In Proceedings of the 34th ACM International Conference on Supercomputing, Barcelona, Spain, 29 June–2 July 2020; ACM: New York, NY, USA, 2020; pp. 1–13. [Google Scholar] [CrossRef] [Scilit]
- Malewicz, G.; Austern, M.H.; Bik, A.J.C.; Dehnert, J.C.; Horn, I.; Leiser, N.; Czajkowski, G. Pregel: A System for Large-Scale Graph Processing. In Proceedings of the 2010 ACM SIGMOD International Conference on Management of Data, Indianapolis, IN, USA, 6–10 June 2010; ACM: New York, NY, USA, 2010; pp. 135–146. [Google Scholar] [CrossRef] [Scilit]
- Kim, J.-H.; Park, Y.-R.; Do, J.; Ji, S.-Y.; Kim, J.-Y. Accelerating large-scale graph-based nearest neighbor search on a computational storage platform. IEEE Trans. Comput. 2022, 72, 278–290. [Google Scholar] [CrossRef] [Scilit]
- Low, Y.; Gonzalez, J.E.; Kyrola, A.; Bickson, D.; Guestrin, C.; Hellerstein, J.M. GraphLab: A New Framework for Parallel Machine Learning. arXiv 2014, arXiv:1408.2041. [Google Scholar] [CrossRef] [Scilit]
- Gonzalez, J.E.; Low, Y.; Gu, H.; Bickson, D.; Guestrin, C. PowerGraph: Distributed Graph-Parallel Computation on Natural Graphs. In Proceedings of the 10th USENIX Symposium on Operating Systems Design and Implementation (OSDI 12), Hollywood, CA, USA, 8–10 October 2012; USENIX Association: Berkeley, CA, USA, 2012; pp. 17–30. Available online: https://www.usenix.org/conference/osdi12/technical-sessions/presentation/gonzalez (accessed on 1 July 2025).
- Kyrola, A.; Blelloch, G.; Guestrin, C. GraphChi: Large-Scale Graph Computation on Just a PC. In Proceedings of the 10th USENIX Symposium on Operating Systems Design and Implementation (OSDI ′12), Hollywood, CA, USA, 8–10 October 2012; Thekkath, C., Ed.; USENIX Association: Berkeley, CA, USA, 2012; pp. 31–46, ISBN 978-1-931971-96-6. Available online: https://www.usenix.org/conference/osdi12/technical-sessions/presentation/kyrola (accessed on 1 July 2025).
- Roy, A.; Mihailovic, I.; Zwaenepoel, W. X-Stream: Edge-Centric Graph Processing Using Streaming Partitions. In Proceedings of the Twenty-Fourth ACM Symposium on Operating Systems Principles, Farmington, PA, USA, 3–6 November 2013; ACM: New York, NY, USA, 2013; pp. 472–488. [Google Scholar] [CrossRef] [Scilit]
- Khorasani, F.; Vora, K.; Gupta, R.; Bhuyan, L.N. CuSha: Vertex-Centric Graph Processing on GPUs. In Proceedings of the 23rd International Symposium on High-Performance Parallel and Distributed Computing, Vancouver, BC, Canada, 23–27 June 2014; ACM: New York, NY, USA, 2014; pp. 239–252. [Google Scholar] [CrossRef] [Scilit]
- Wang, Y.; Davidson, A.; Pan, Y.; Wu, Y.; Riffel, A.; Owens, J.D. Gunrock: A High-Performance Graph Processing Library on the GPU. In Proceedings of the 21st ACM SIGPLAN Symposium on Principles and Practice of Parallel Programming (PPoPP ’16), Barcelona, Spain, 12–16 March 2016; ACM: New York, NY, USA, 2016. Article 11. pp. 1–12. [Google Scholar] [CrossRef] [Scilit]
- Sengupta, D.; Song, S.L.; Agarwal, K.; Schwan, K. GraphReduce: Processing Large-Scale Graphs on Accelerator-Based Systems. In Proceedings of the International Conference for High Performance Computing, Networking, Storage and Analysis, Austin, TX, USA, 15–20 November 2015; ACM: New York, NY, USA, 2015; pp. 1–12. [Google Scholar] [CrossRef] [Scilit]
- Han, W.; Mawhirter, D.; Wu, B.; Buland, M. Graphie: Large- Scale Asynchronous Graph Traversals on Just a GPU. In Proceedings of the 2017 26th International Conference on Parallel Architectures and Compilation Techniques (PACT), Portland, OR, USA, 9–10 September 2017; IEEE: New York, NY, USA, 2017; pp. 233–245. [Google Scholar]
- Valiant, L.G. A Bridging Model for Parallel Computation. Commun. ACM 1990, 33, 103–111. [Google Scholar] [CrossRef] [Scilit]
- Peng, J.; Zhang, X.; Yuan, K.; Peng, X.; Yang, G. GDVI-Fusion: Enhancing Accuracy with Optimal Geometry Matching and Deep Nearest Neighbor Optimization. Appl. Sci. 2025, 15, 8875. [Google Scholar] [CrossRef] [Scilit]
- Naumov, M.; Vrielink, A.; Garland, M. Parallel Depth-First Search for Directed Acyclic Graphs. In Proceedings of the Seventh Workshop on Irregular Applications: Architectures and Algorithms, Denver, CO, USA, 13 November 2017; ACM: New York, NY, USA, 2017; pp. 1–8. [Google Scholar] [CrossRef] [Scilit]
- Meister, C.; Vieira, T.; Cotterell, R. Best-First Beam Search. Trans. Assoc. Comput. Linguist. 2020, 8, 795–809. [Google Scholar] [CrossRef] [Scilit]
- Peng, Z.; Zhang, M.; Li, K.; Jin, R.; Ren, B. Speed-ANN: Low-Latency and High-Accuracy Nearest Neighbor Search via Intra-Query Parallelism. arXiv, 2022; arXiv:2201.13007.
- Linde, Y.; Buzo, A.; Gray, R. An Algorithm for Vector Quantizer Design. IEEE Trans. Commun. 1980, 28, 84–95. [Google Scholar] [CrossRef] [Scilit]
- Rahebi, J. Vector quantization using whale optimization algorithm for digital image compression. Multimed. Tools Appl. 2022, 81, 20077–20103. [Google Scholar] [CrossRef] [Scilit]
- Zhang, X.; Wu, X. Lvqac: Lattice vector quantization coupled with spatially adaptive companding for efficient learned image compression. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Vancouver, BC, Canada, 18–22 June 2023; pp. 10239–10248. [Google Scholar]
- Li, P.; Shlezinger, N.; Zhang, H.; Wang, B.; Eldar, Y.C. Graph signal compression by joint quantization and sampling. IEEE Trans. Signal Process. 2022, 70, 4512–4527. [Google Scholar] [CrossRef] [Scilit]
- Amato, G.; Carrara, F.; Falchi, F.; Gennaro, C.; Rabitti, F.; Vadicamo, L. Scalar Quantization-Based Text Encoding for Large Scale Image Retrieval. In Proceedings of the 2020 Italian Symposium on Advanced Database Systems (SEBD 2020), Online, 21–24 June 2020; Volume 2646, pp. 258–265. Available online: https://ceur-ws.org/Vol-2646/10-paper.pdf (accessed on 1 July 2025).
- Veasey, T.; Trent, B. Scalar Quantization Optimized for Vector Databases. 2025. Available online: https://www.elastic.co/search-labs/blog/vector-db-optimized-scalar-quantization (accessed on 1 July 2025).
- Matsui, Y.; Uchida, Y.; Jégou, H.; Satoh, S. A Survey of Product Quantization. ITE Trans. Media Technol. Appl. 2018, 6, 2–10. [Google Scholar] [CrossRef] [Scilit]
- Babenko, A.; Lempitsky, V. The inverted multi-index. In Proceedings of the 2012 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Providence, RI, USA; 2012; pp. 3069–3076. [Google Scholar] [CrossRef] [Scilit]
- Xu, D.; Tsang, I.; Zhang, Y. Online Product Quantization. IEEE Trans. Knowl. Data Eng. 2018, 30, 2185–2198. [Google Scholar] [CrossRef] [Scilit]
- PINECONE. Faiss: The Missing Manual. Available online: https://www.pinecone.io/learn/series/faiss/vector-indexes/ (accessed on 1 July 2025).
- Liu, Y.; Pan, Z.; Wang, L.; Wang, Y. A new fast inverted file-based algorithm for approximate nearest neighbor search without accuracy reduction. Inf. Sci. 2022, 608, 613–629. [Google Scholar] [CrossRef] [Scilit]
- Liu, J.; Ouzzani, I.; Li, W.; Zhang, L.; Ou, T.; Bouamor, H.; Jin, Z.; Diab, M.T. Towards Global AI Inclusivity: A Large-Scale Multilingual Terminology Dataset (GIST). arXiv 2024, arXiv:2412.18367. [Google Scholar]
- Kazakovtsev, V.; Markushin, E. Data Segmentation Through Two-Level Clustering with Greedy Approach. In ITM Web of Conferences; EDP Sciences: Les Ulis Cedex A, France, 2025; Volume 72. [Google Scholar] [CrossRef] [Scilit]
- Muravyov, S.; Kazakovtsev, V.; Usov, I.; Shpineva, P.; Muravyova, O.; Shalyto, A. An opensource library for AutoML multimodal clustering on Apache Spark. Zap. Nauchnykh Semin. POMI 2024, 540, 178–193. [Google Scholar]
- Ahmatshin, F.; Kazakovtsev, L. Mini-Batch K-Means++ Clustering Initialization. In International Conference on Mathematical Optimization Theory and Operations Research; Springer Nature: Cham, Switzerland, 2024. [Google Scholar] [CrossRef] [Scilit]
- Kazakovtsev, L.; Rozhnov, I.; Kazakovtsev, V. A (1+ λ) evolutionary algorithm with the greedy agglomerative mutation for p-median problems. In AIP Conference Proceedings; AIP Publishing LLC: Melville, NY, USA, 2023; Volume 2700, Number 1; p. 040003. [Google Scholar] [CrossRef] [Scilit]
- Kazakovtsev, L.; Shkaberina, G.; Rozhnov, I.; Li, R.; Kazakovtsev, V. Genetic Algorithms with the Crossover-Like Mutation Operator for the K-Means Problem. In International Conference on Mathematical Optimization Theory and Operations Research; Springer International Publishing: Cham, Switzerland, 2020. [Google Scholar] [CrossRef] [Scilit]
- Elkan, C. Using the triangle inequality to accelerate k-means. In Proceedings of the 20th International Conference on Machine Learning (ICML-03), Washington, DC, USA, 21–24 August 2003. [Google Scholar]

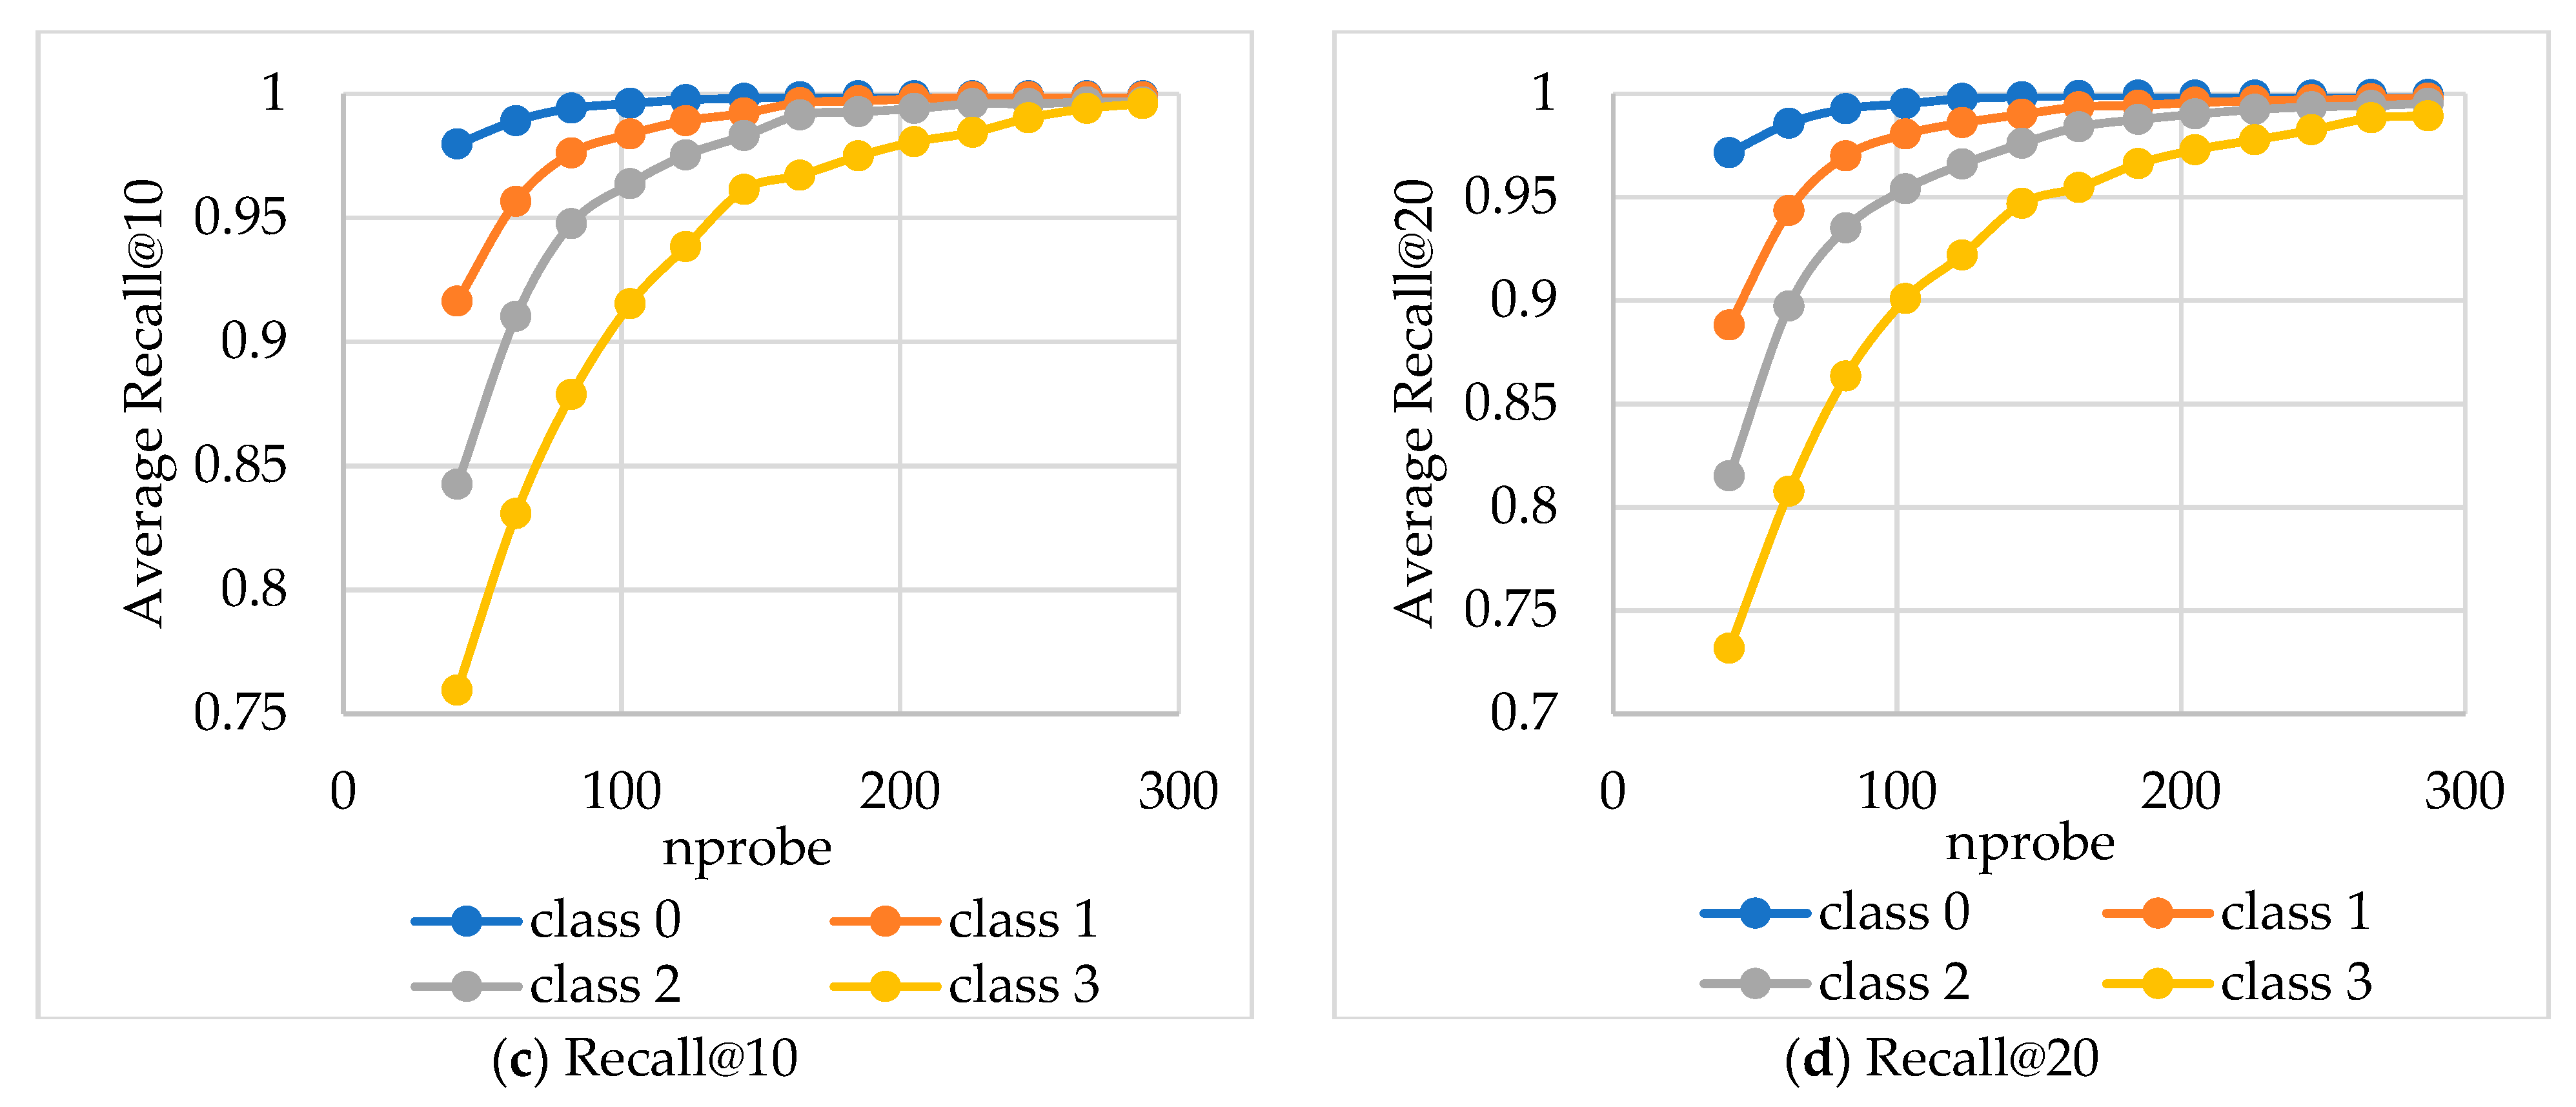
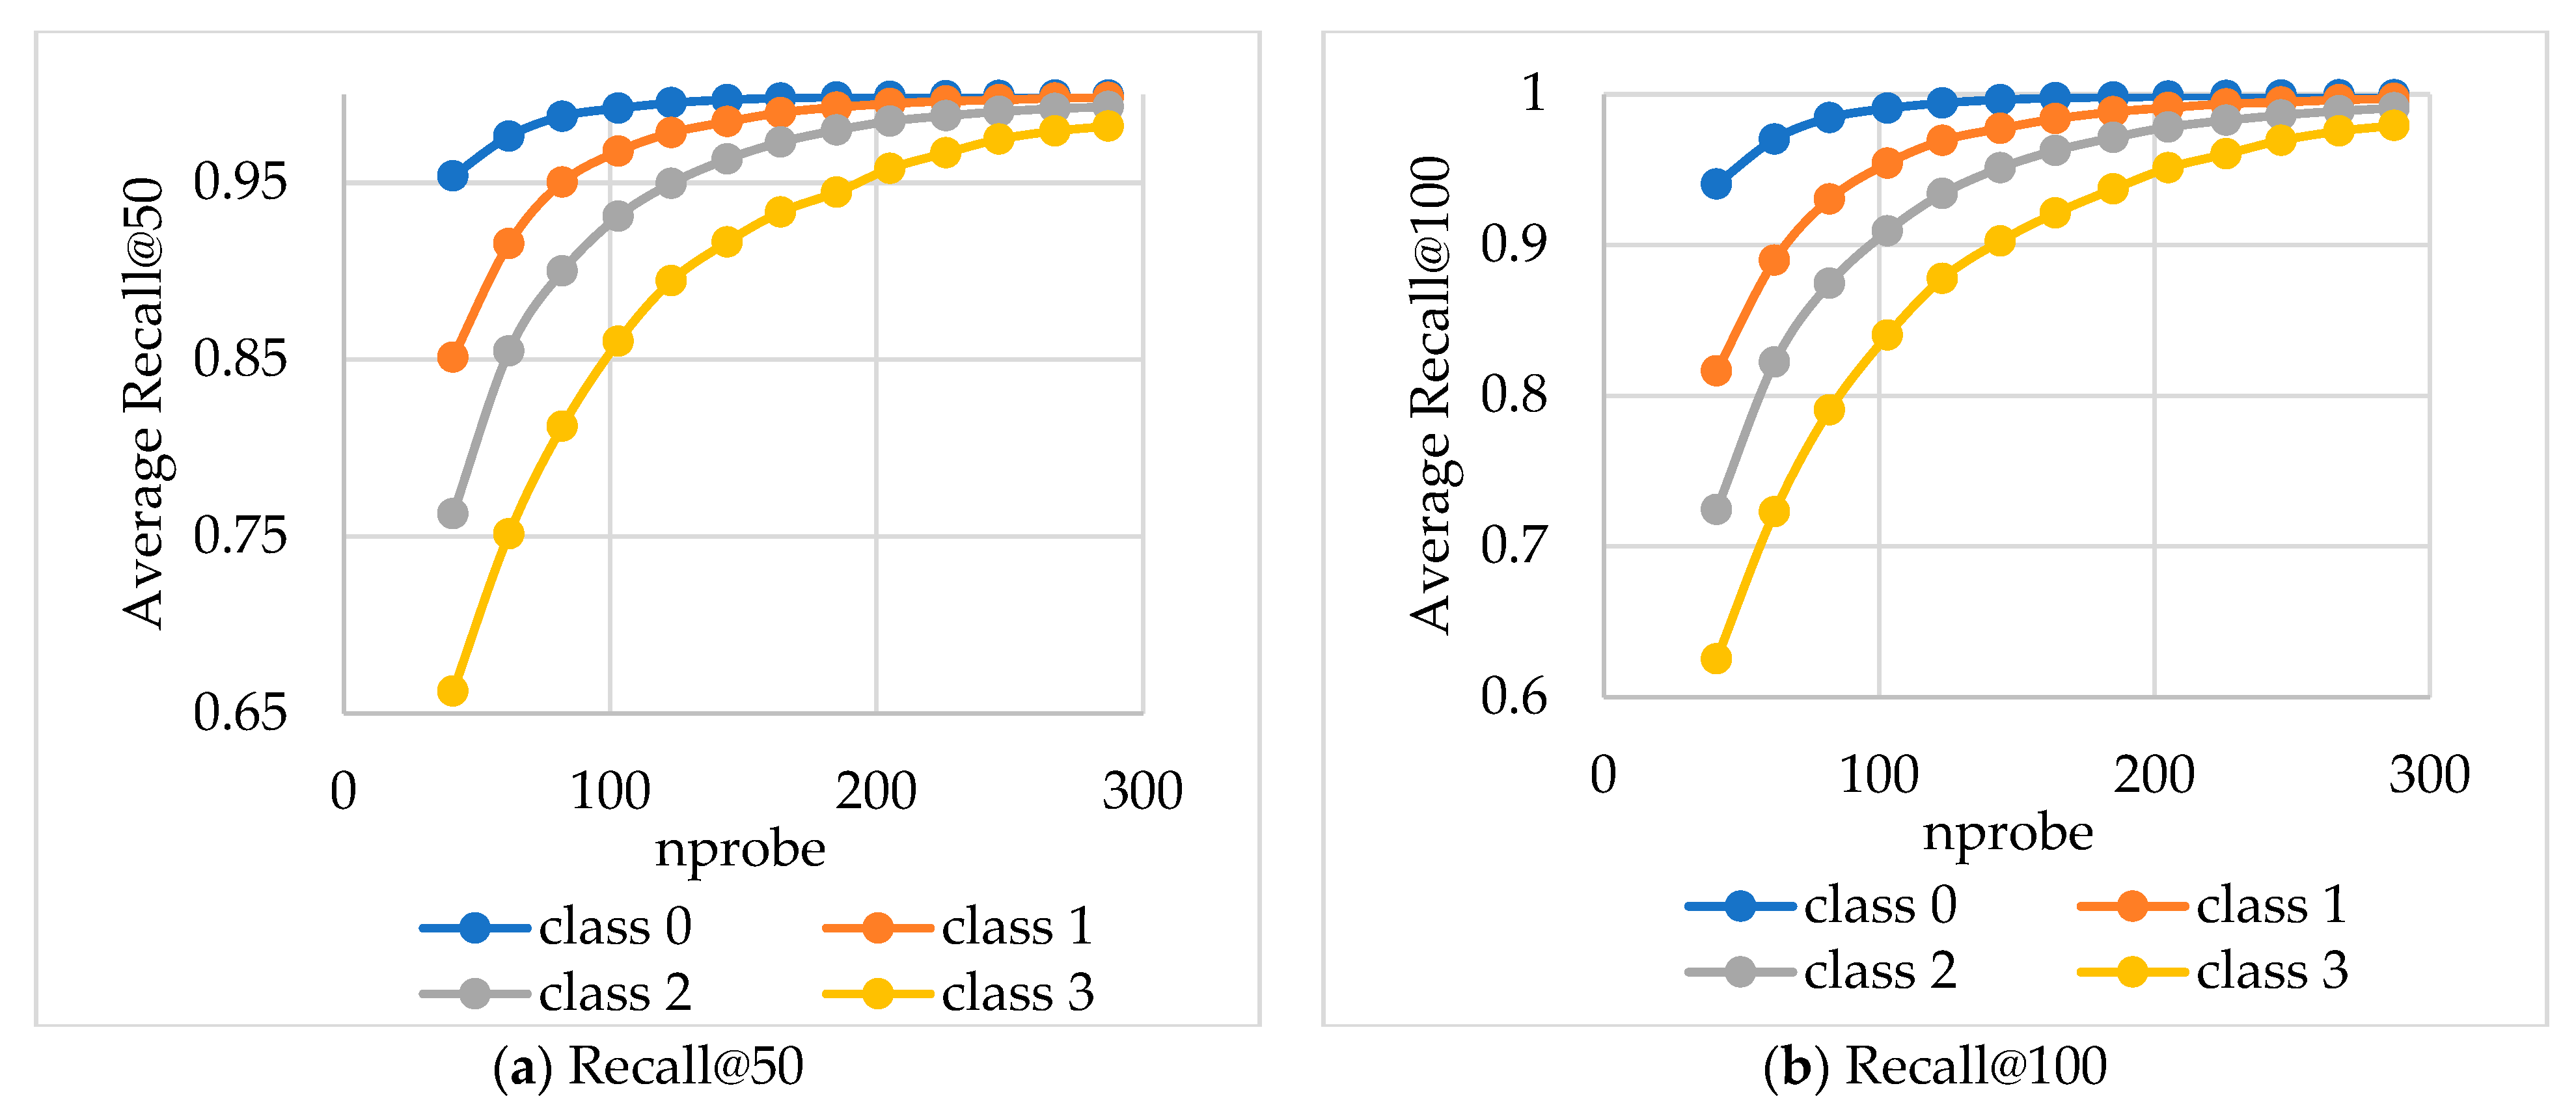
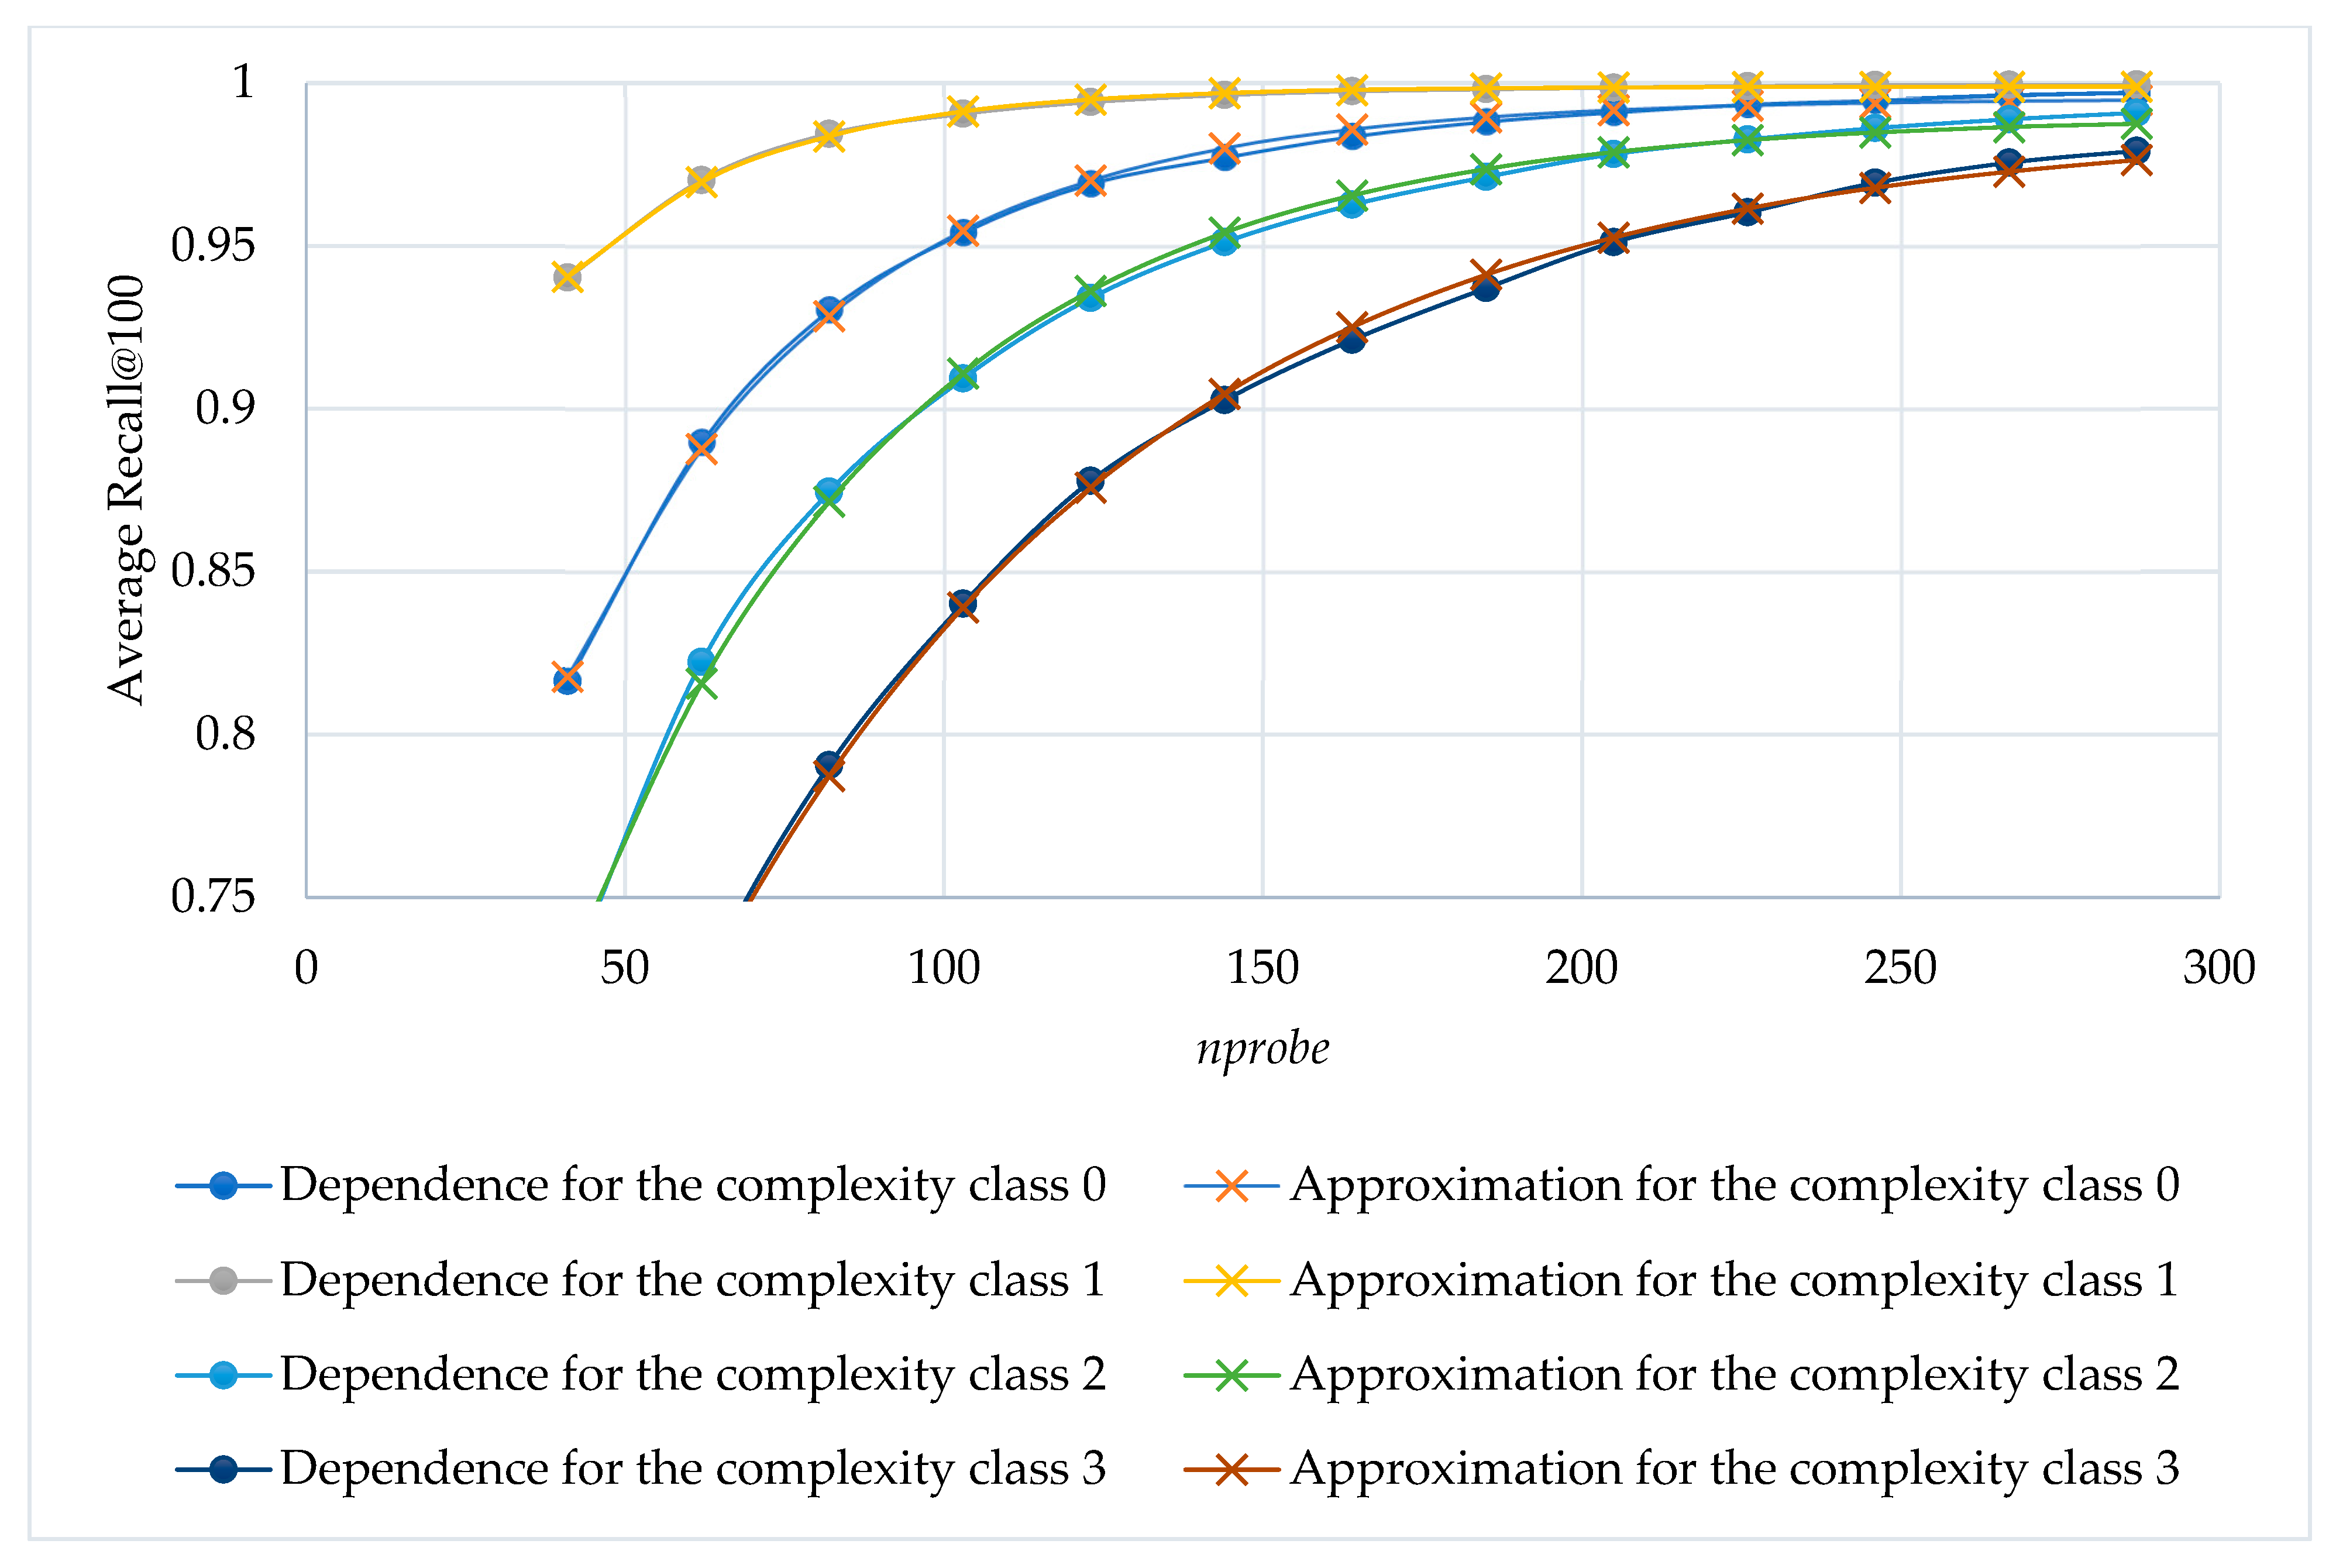

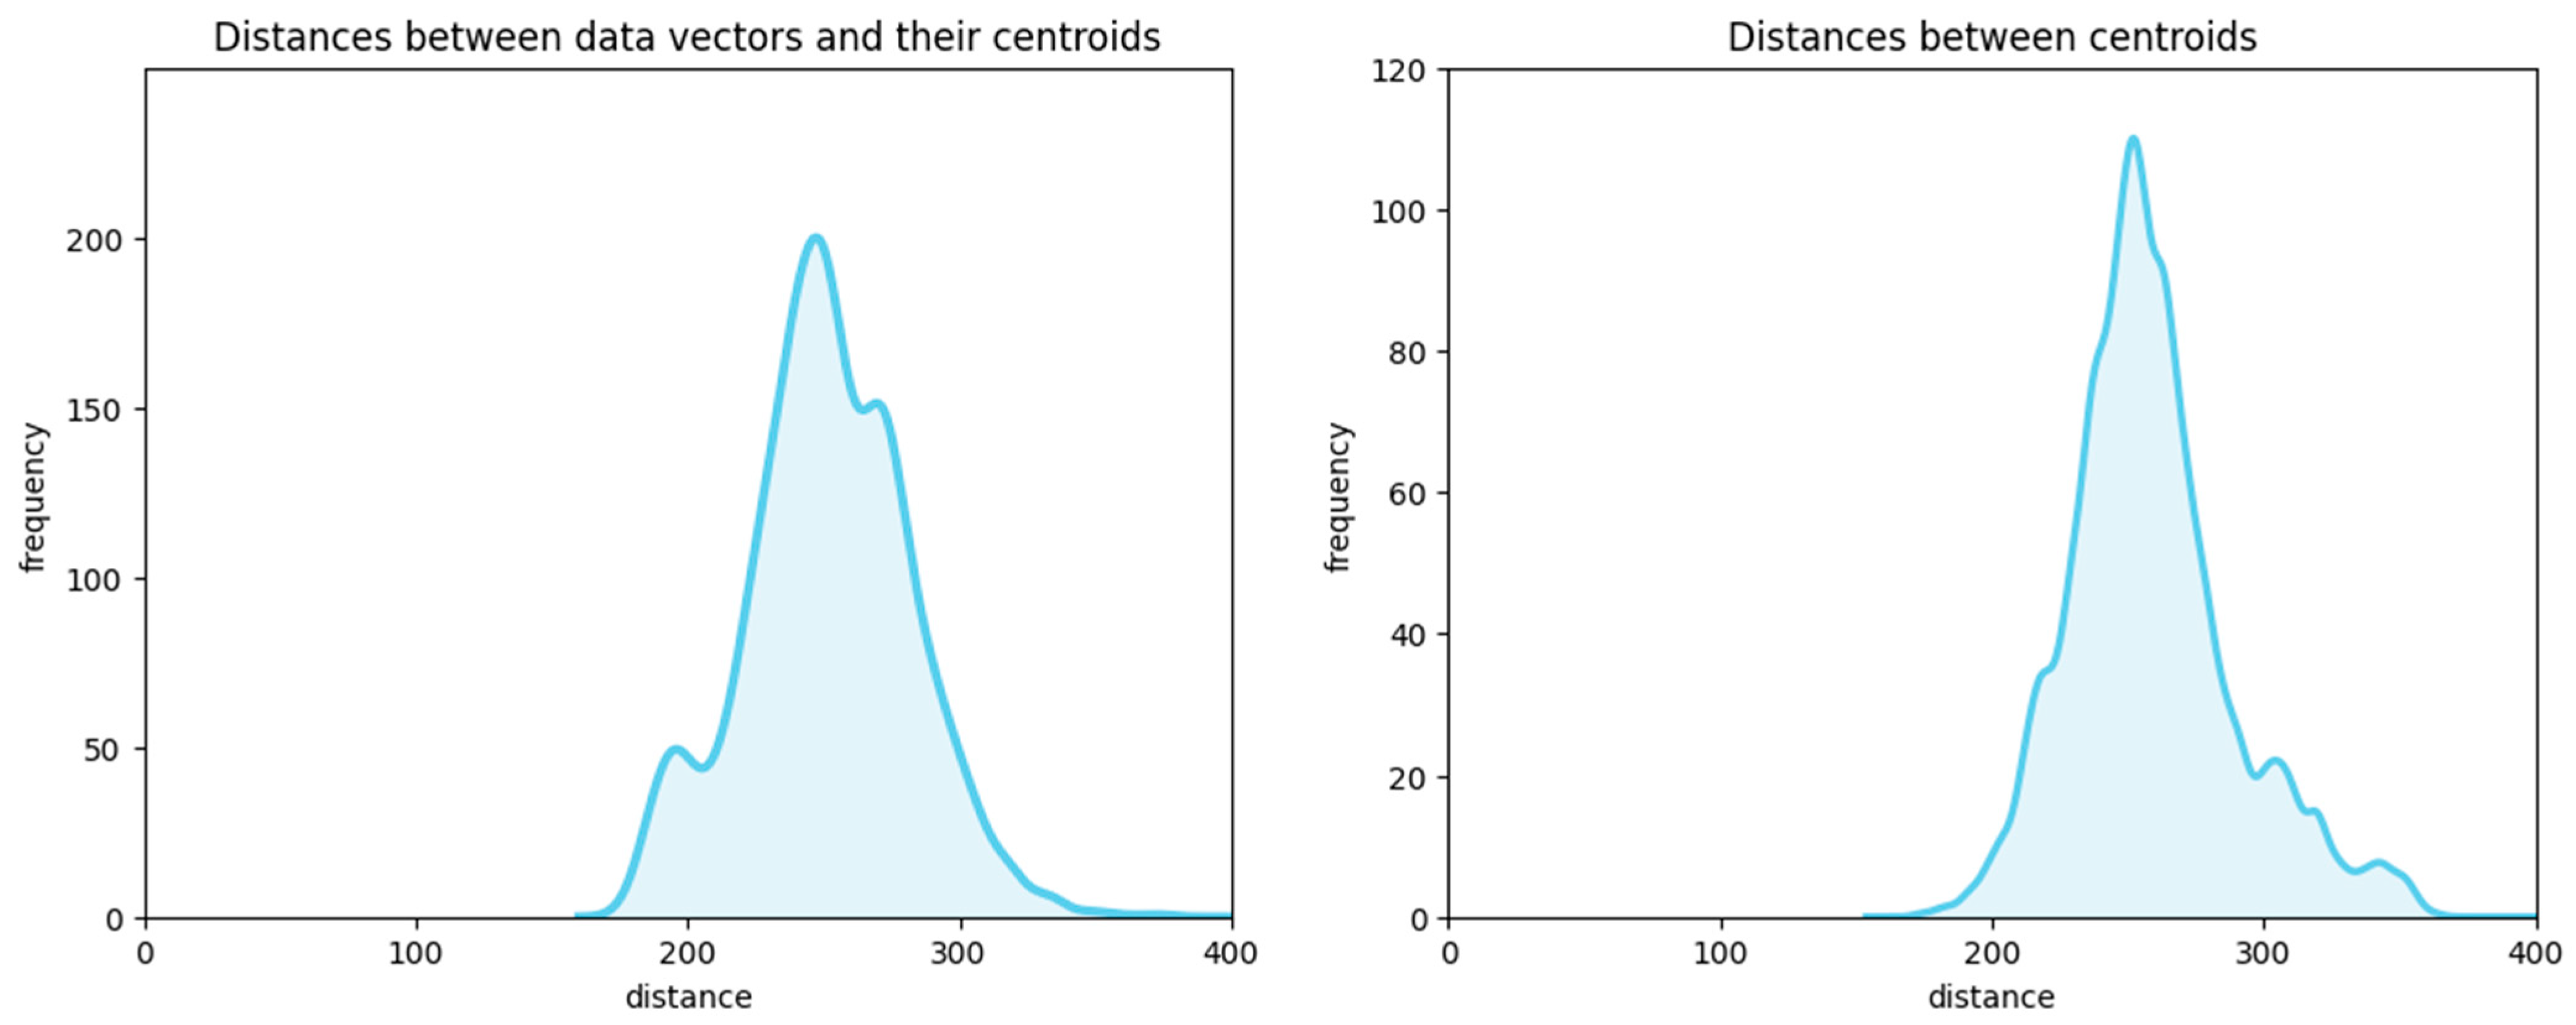

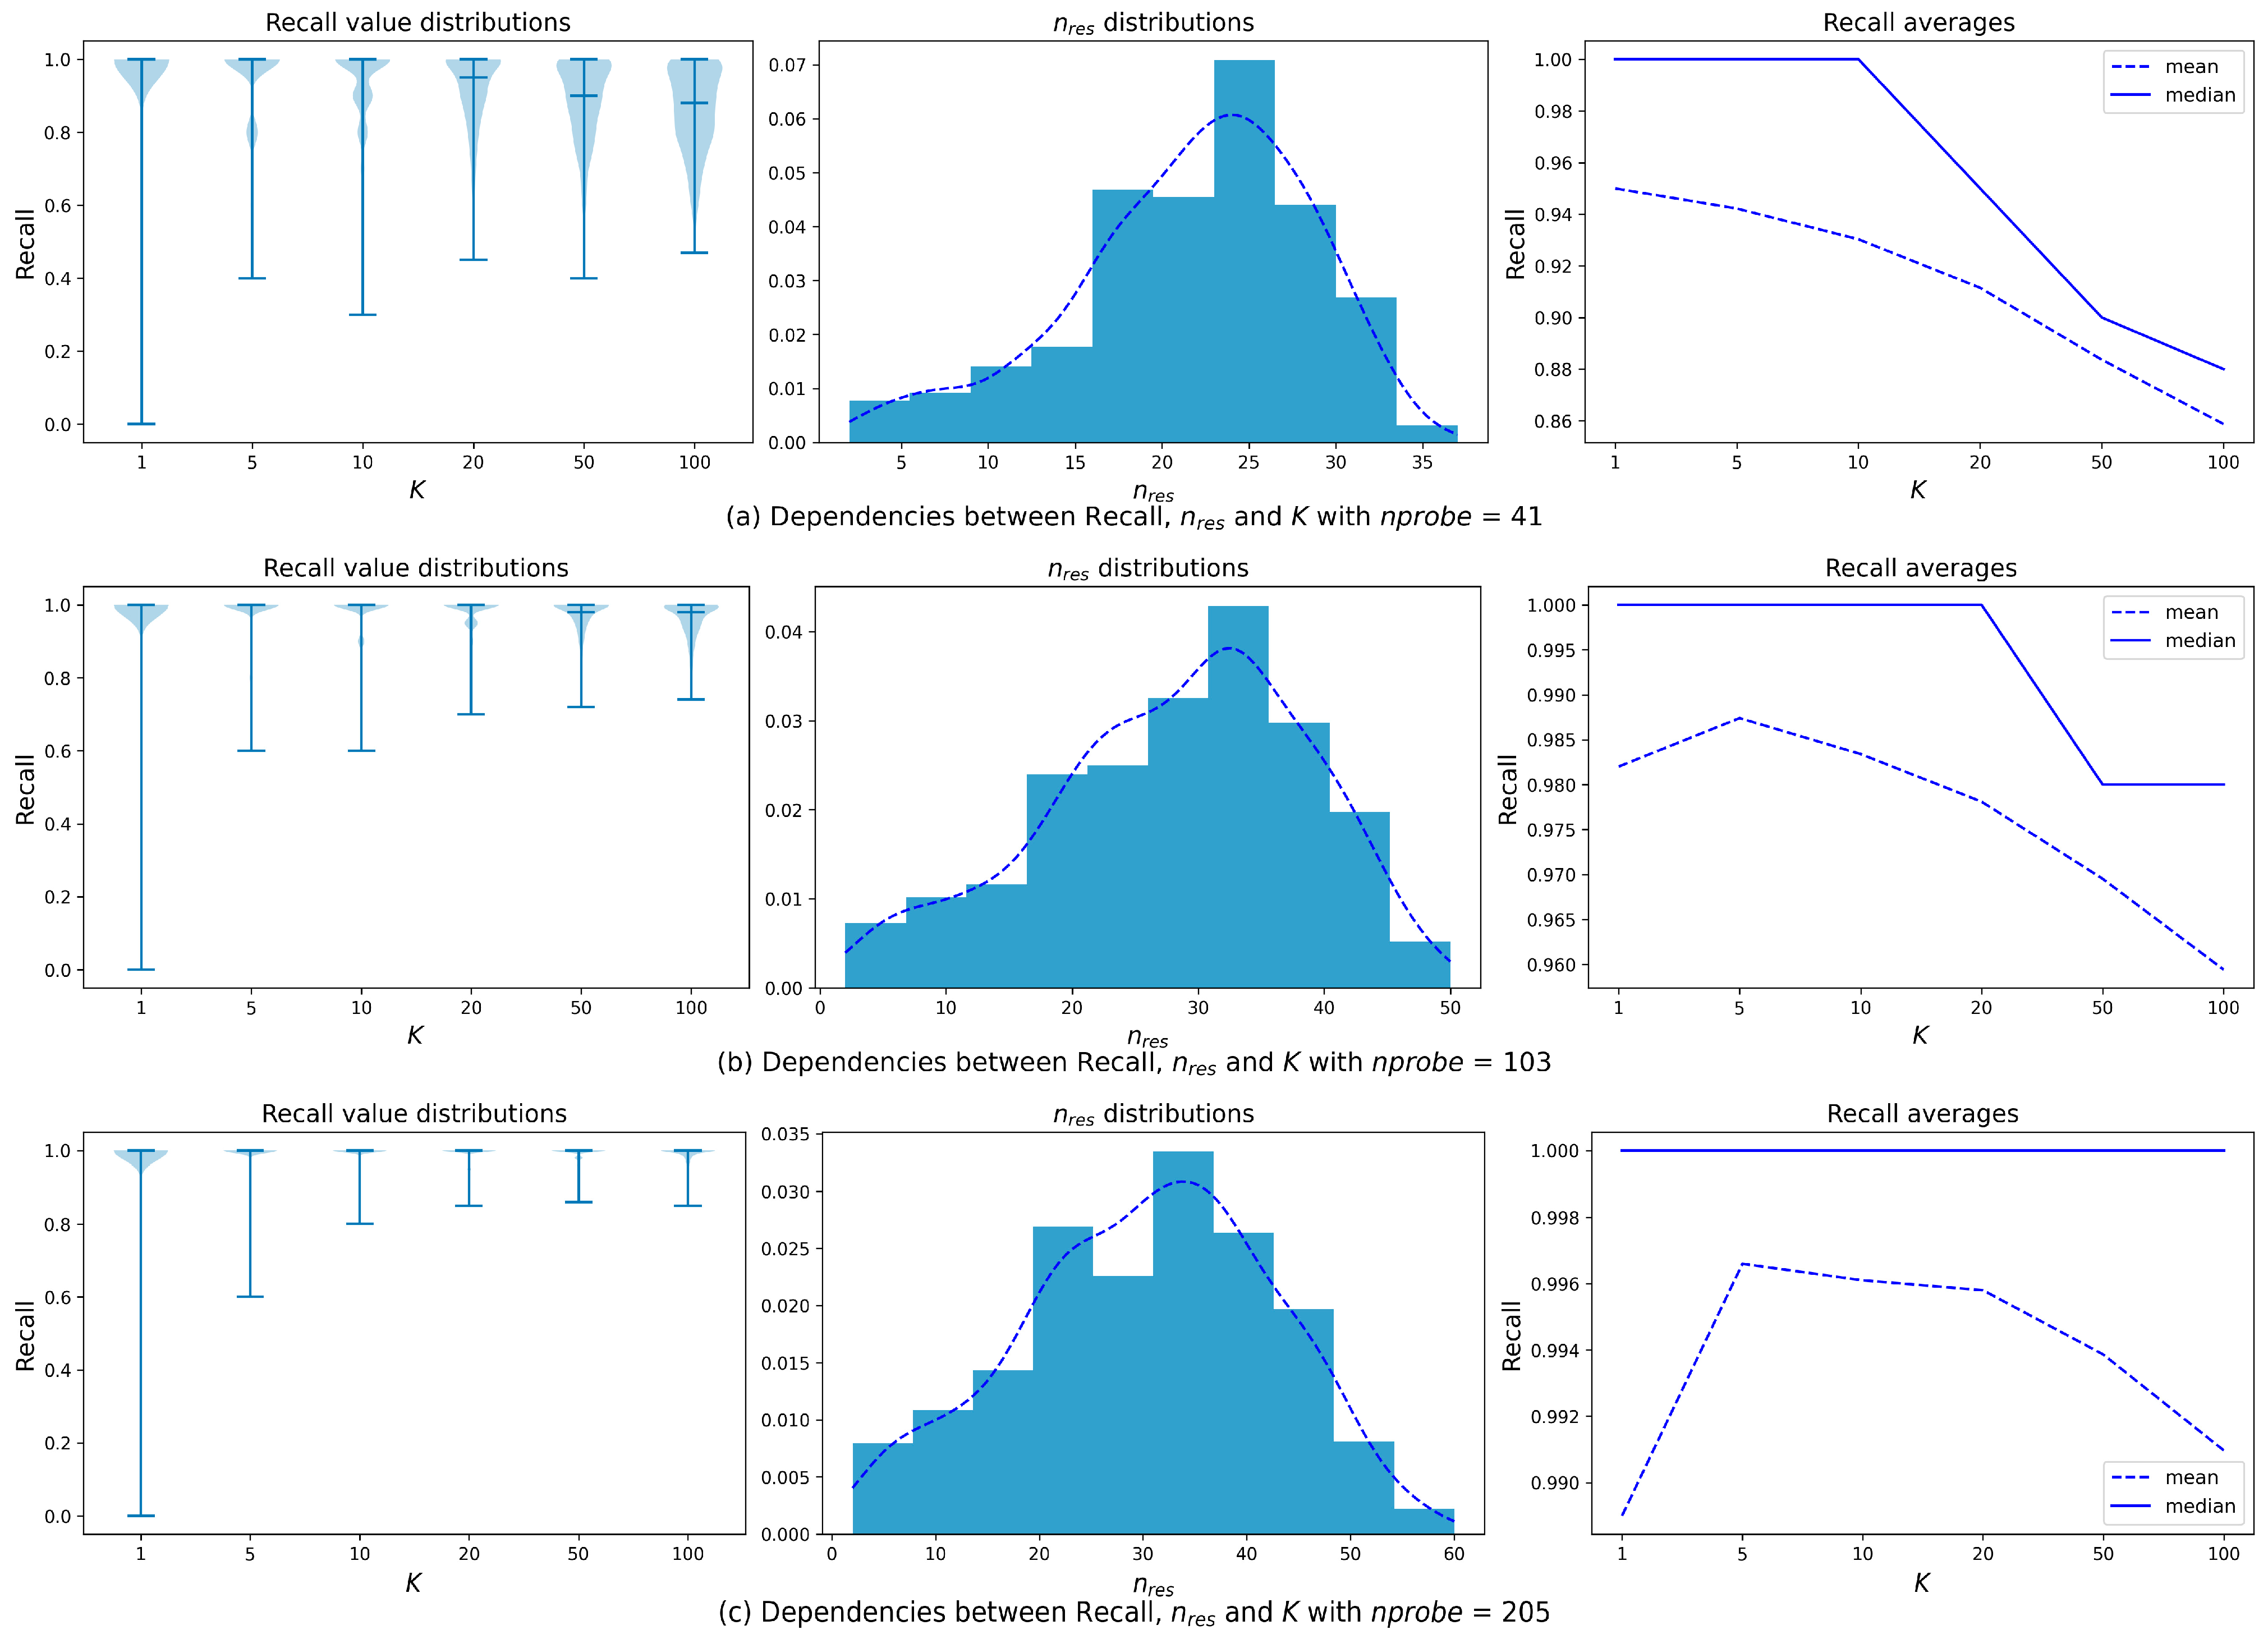
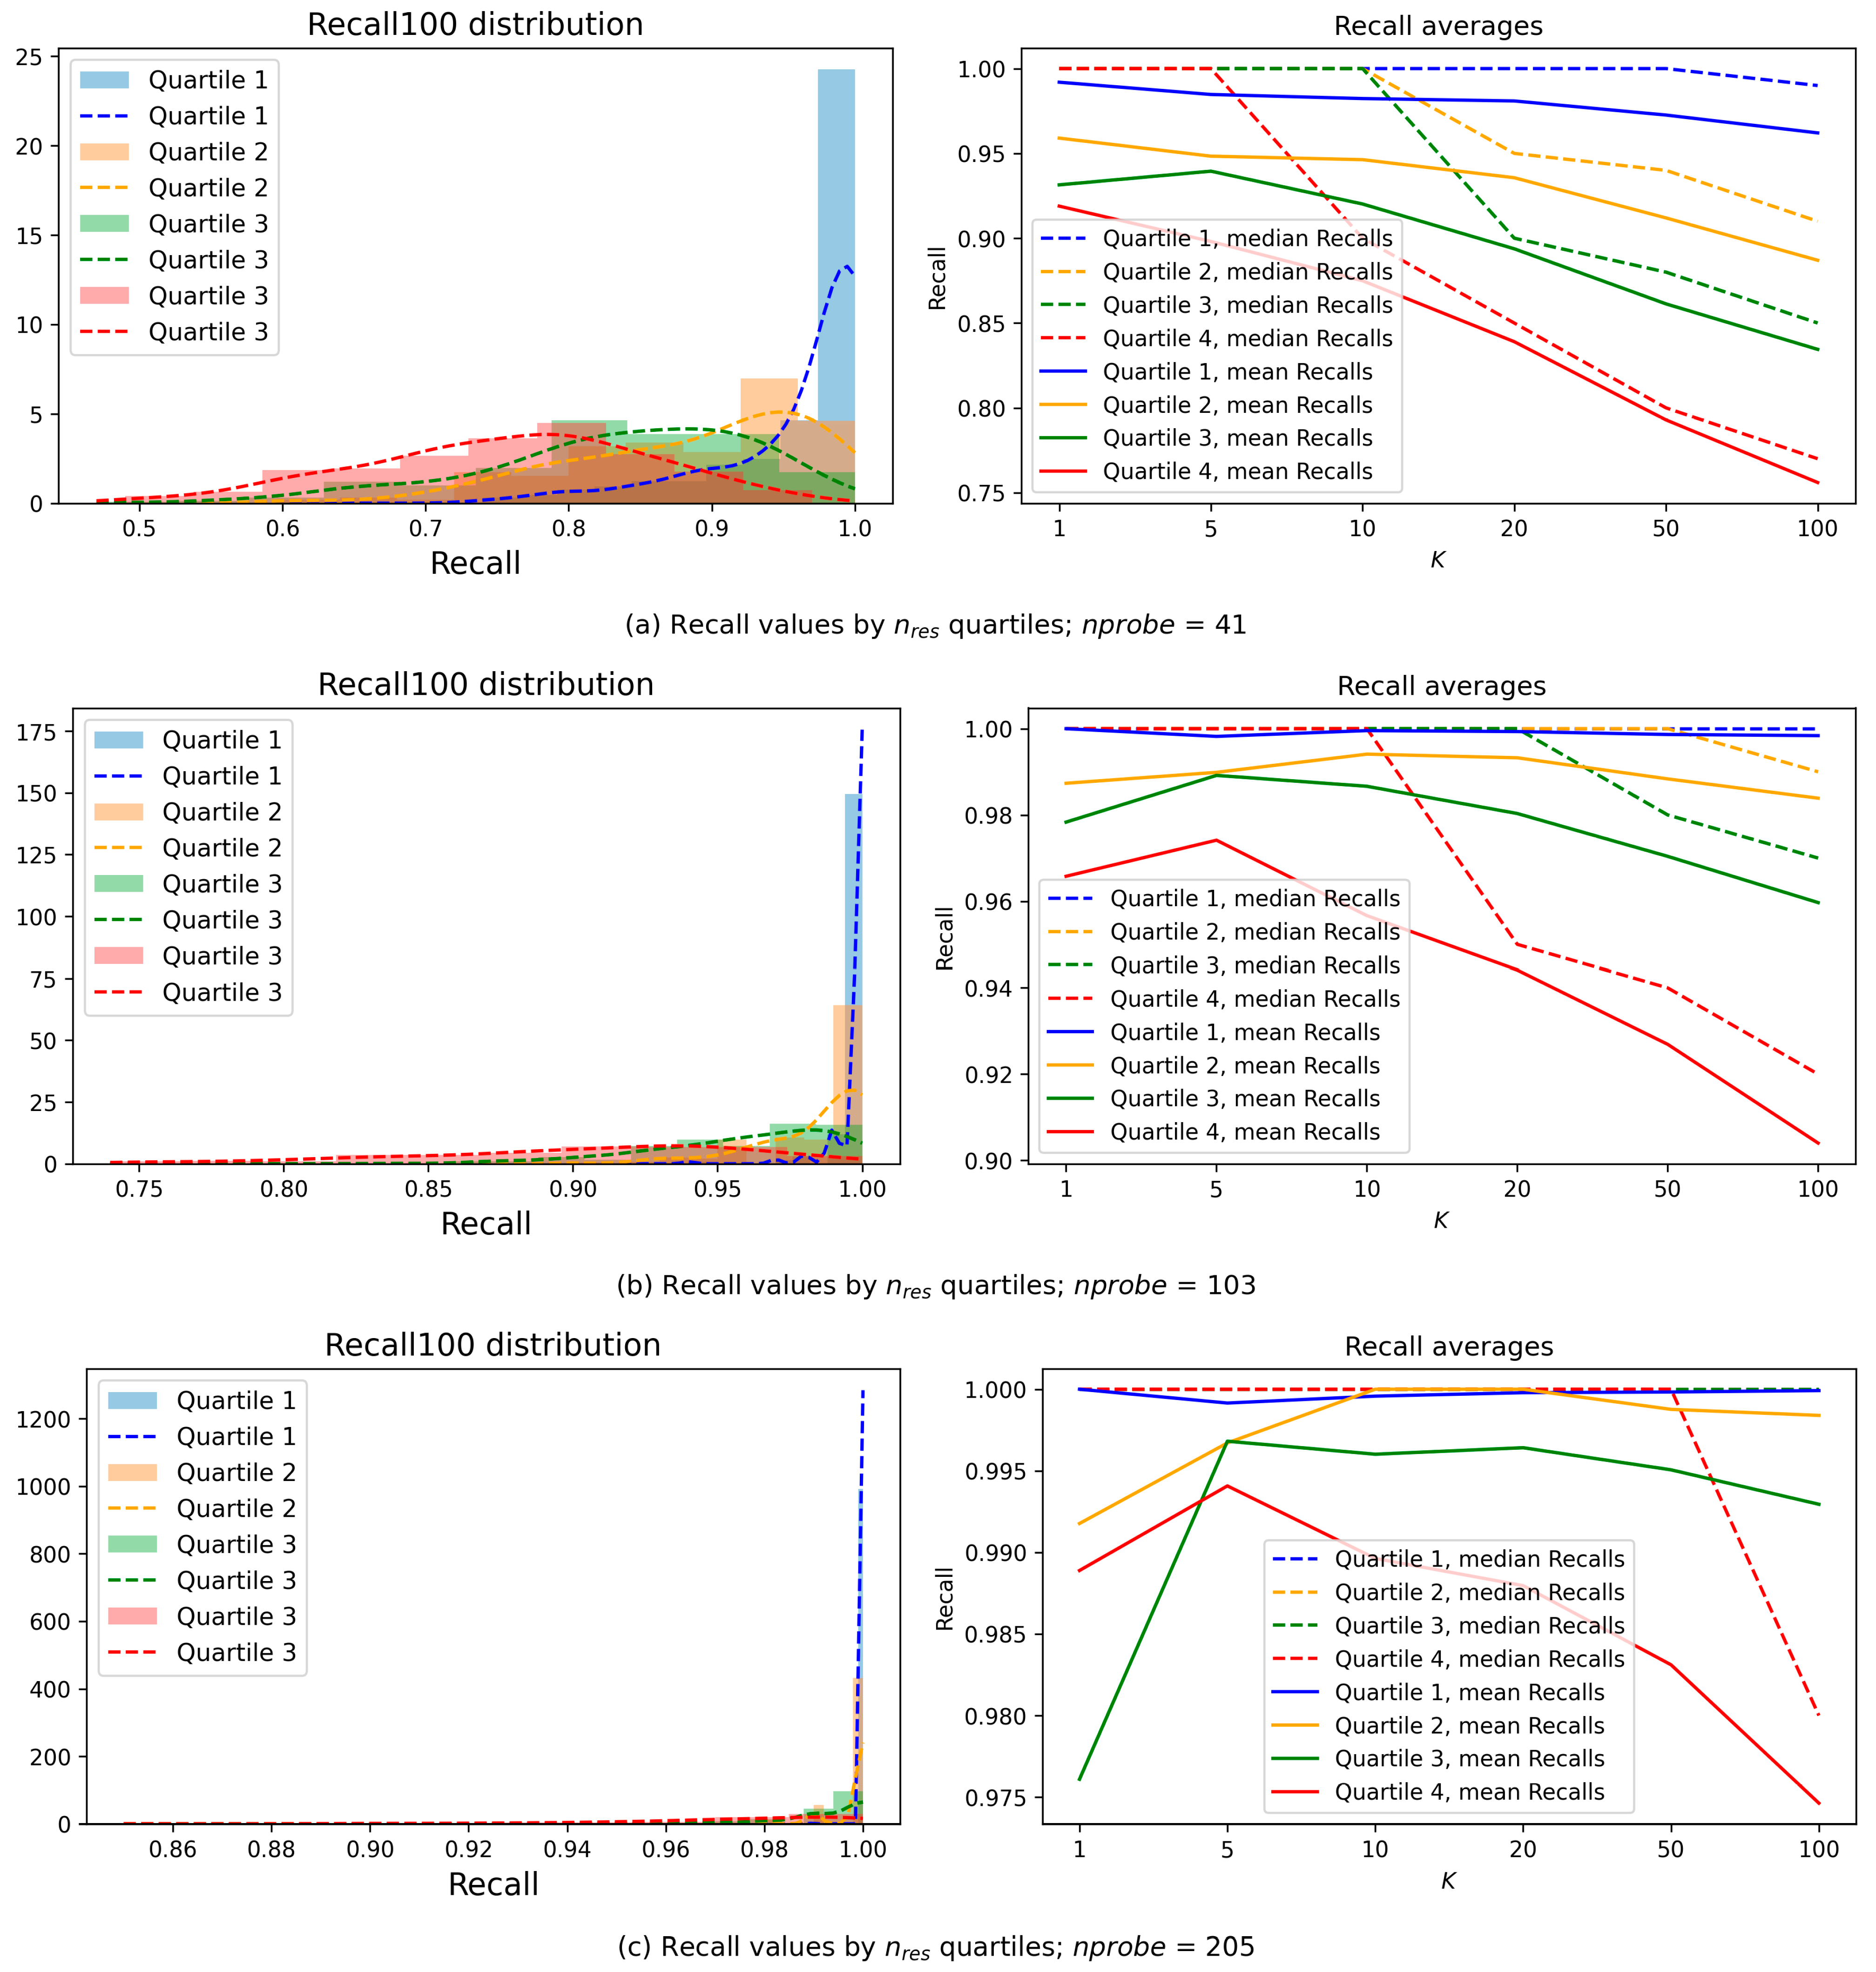
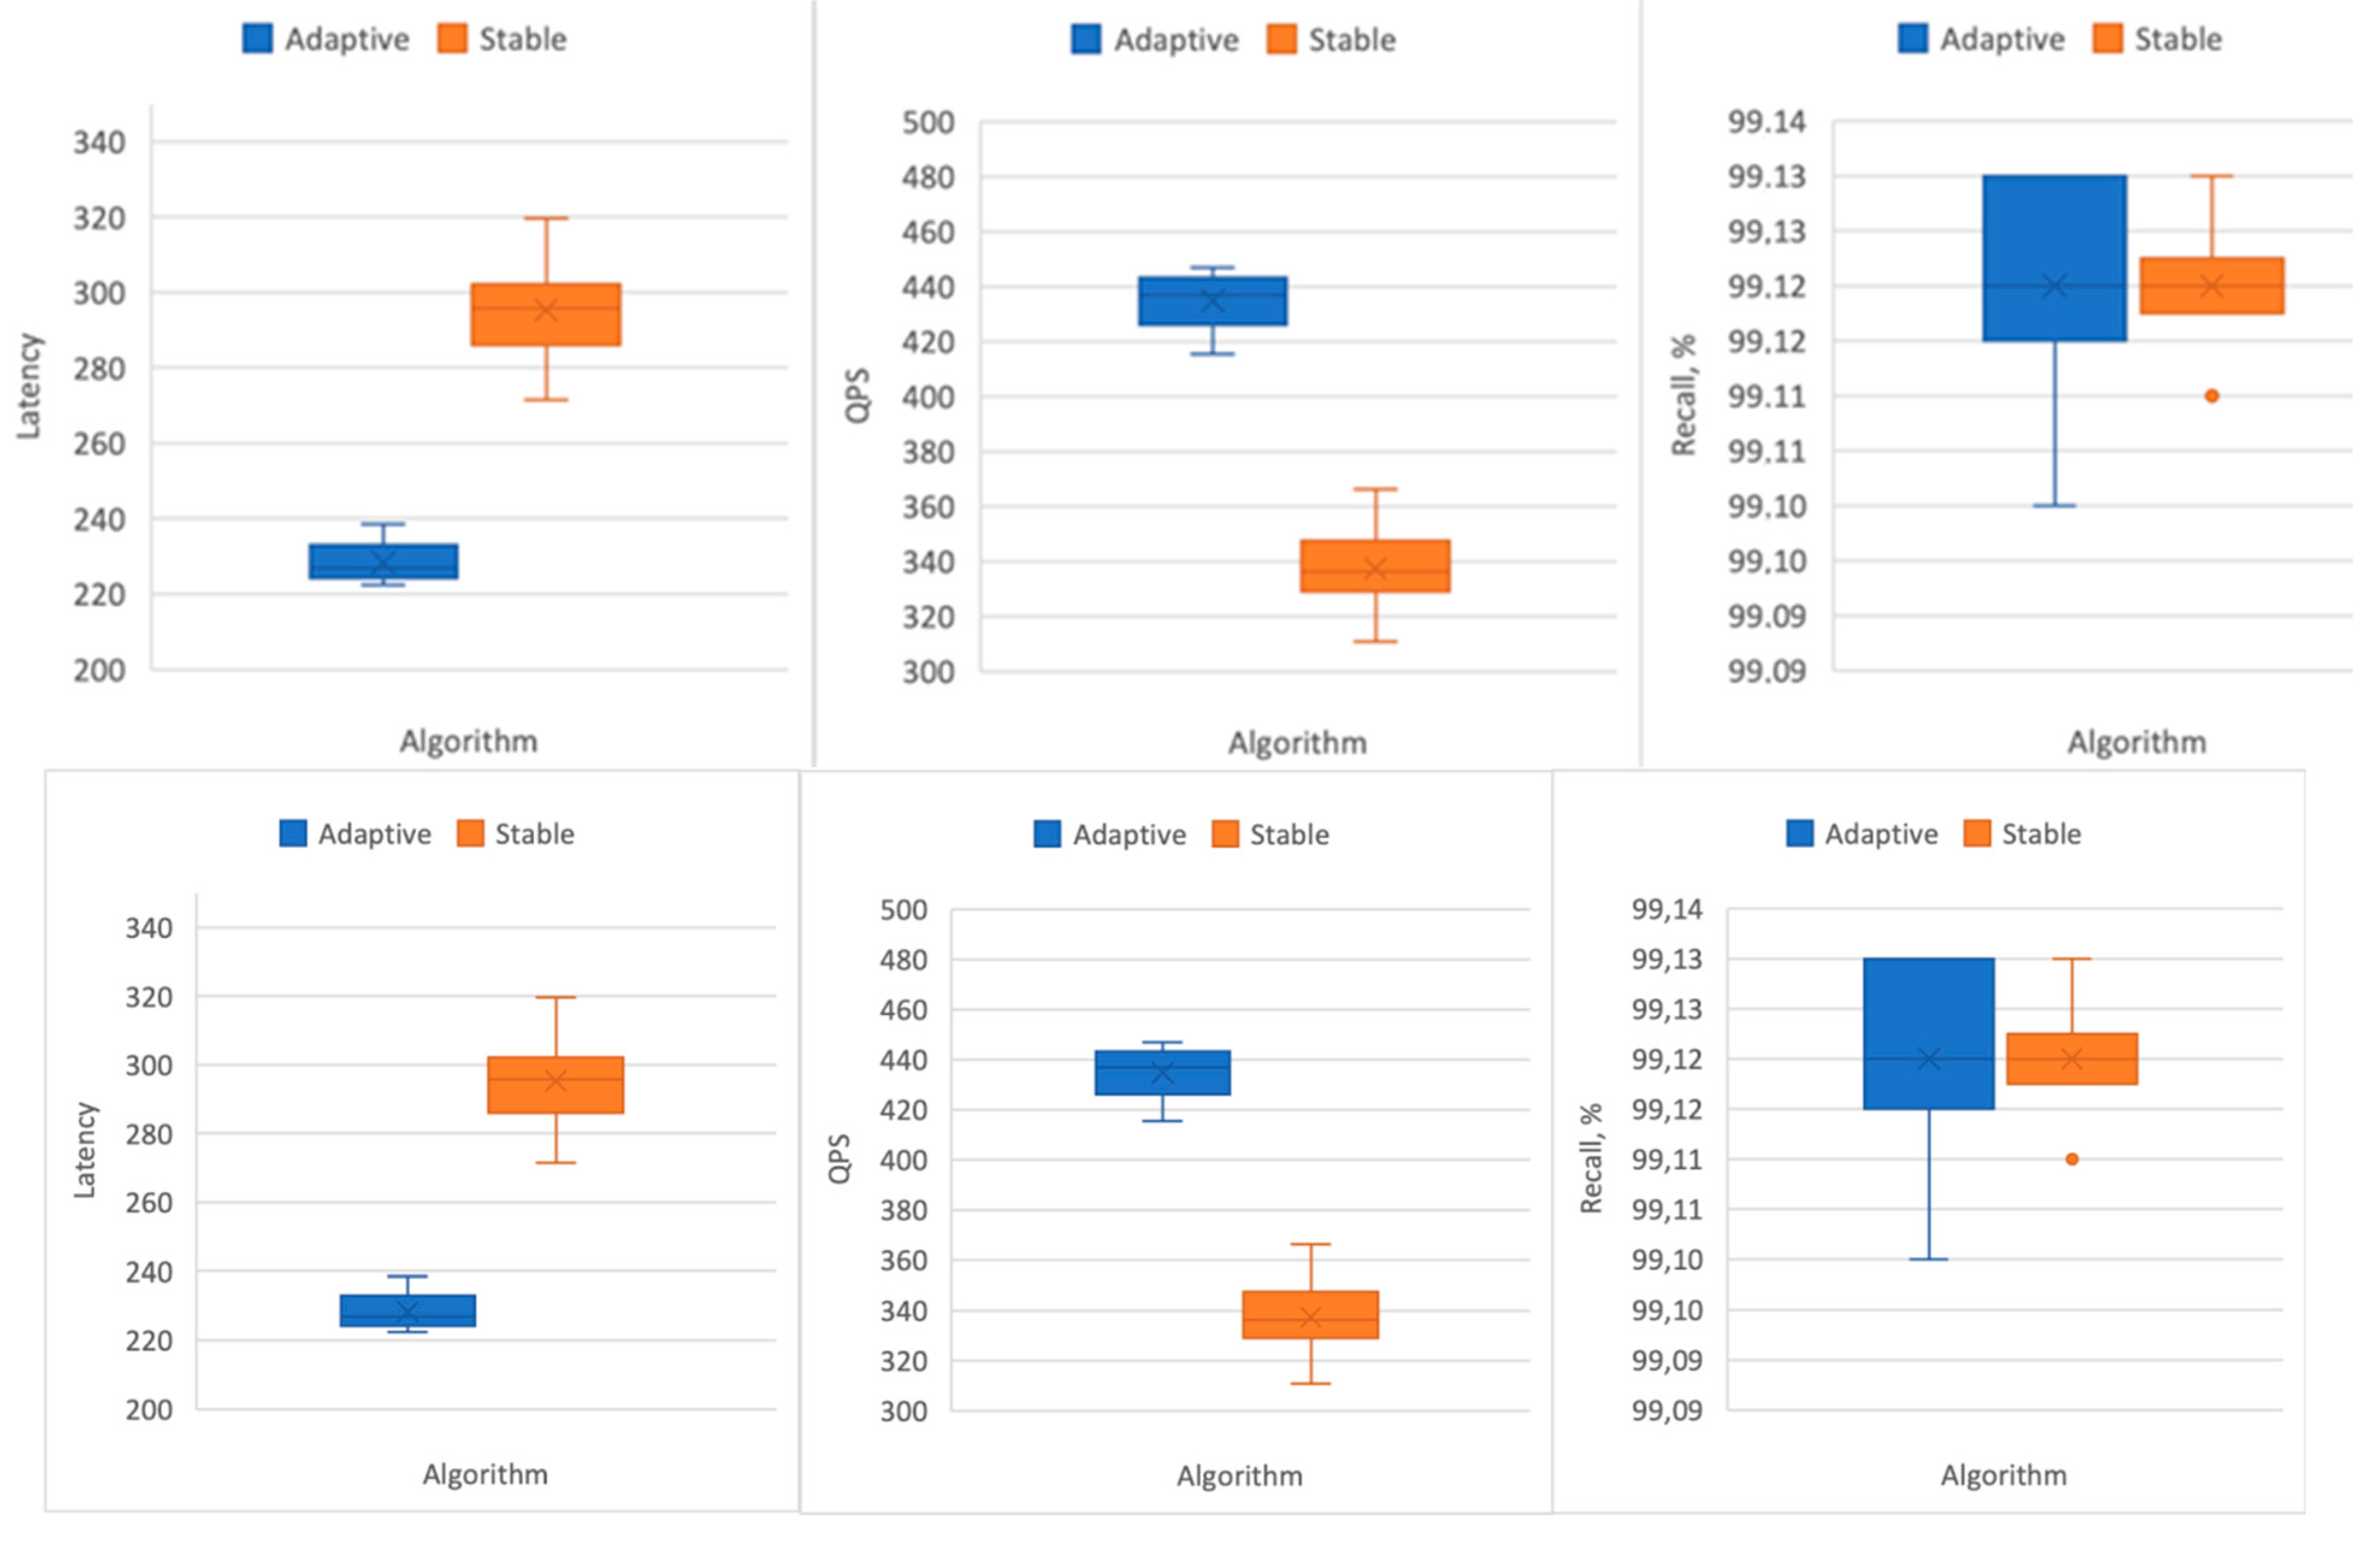
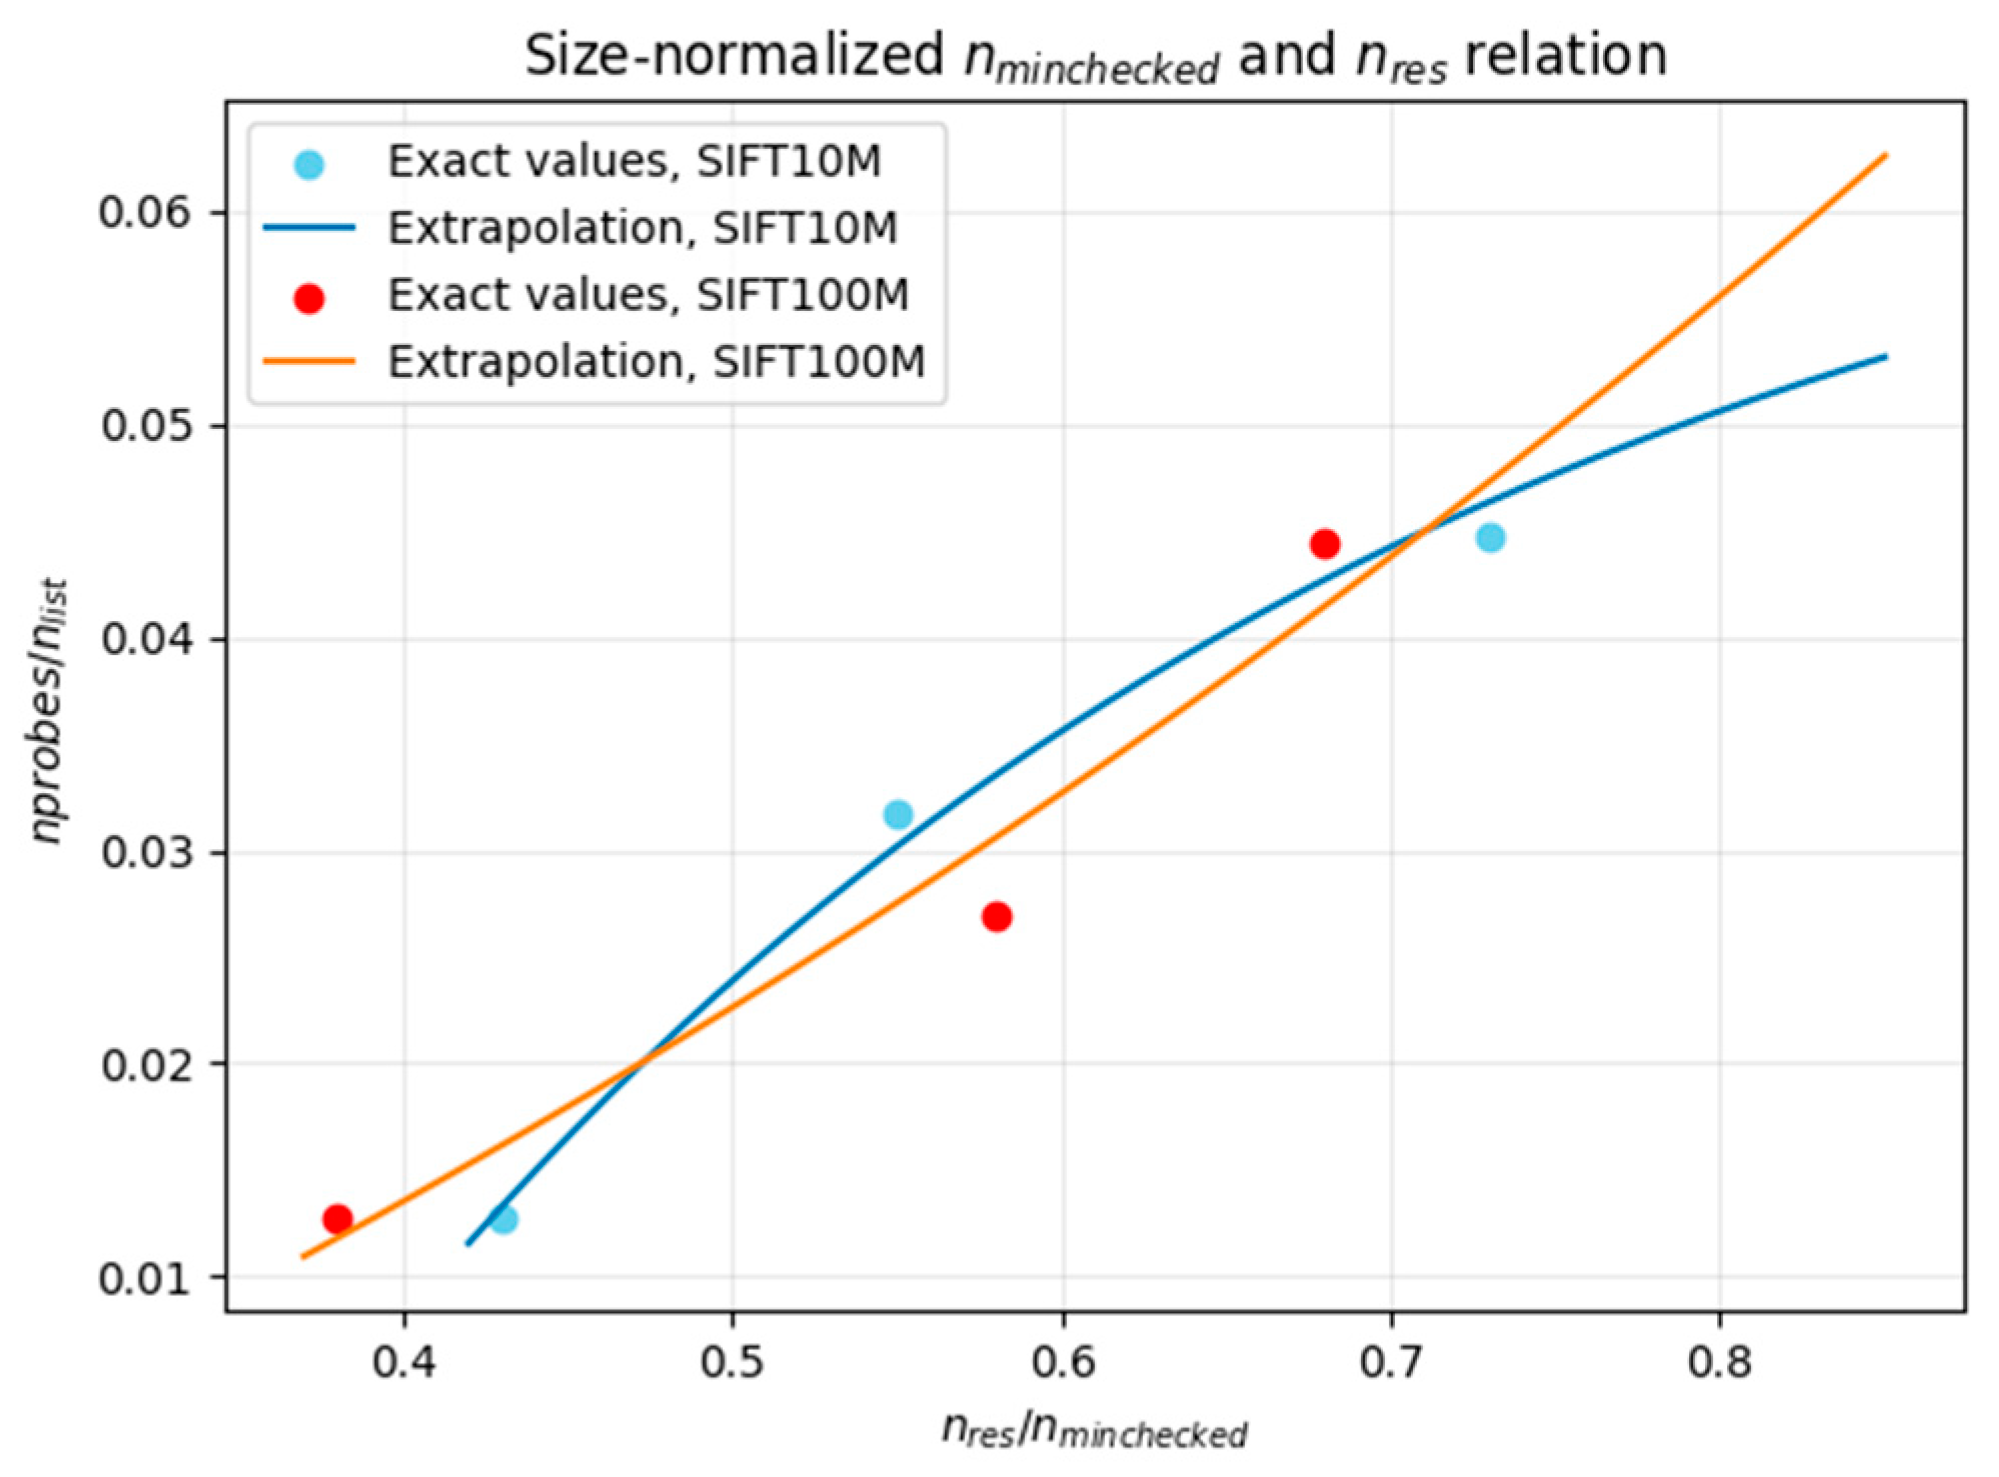


| Algorithm | Source | Recall at K = 100 | Dataset | Note |
|---|---|---|---|---|
| Symmetric Distance Computation | Herve Jegou, Matthijs Douze, and Cordelia Schmid [35] | 0.45 | GIST [115] | |
| Asymmetric Distance Computation | 0.65 | GIST | ||
| PQ+IVFADC (k’ = 1024, w = 64) | 0.74 | GIST | This approach requires setting the codebook size k’ and the number of neighboring cells w. Recall@100 depends on these parameters, and increasing the code length is ineffective when w is small. | |
| PQ+IVFADC (k′ = 8192, w = 64) | 0.61 | GIST | ||
| PQ+IVFADC (k′ = 1024, w = 8) | 0.68 | GIST | ||
| PQ+IVFADC (k′ = 8192, w = 8) | 0.52 | GIST | ||
| Faiss-GPU w/IVFFlat | Peng, Zhen et al. [103] | 0.52 | SIFT | The results presented are taken from a table comparing latency. |
| Speed-ANN-32T on KNL | 0.91 | SIFT | ||
| LSH | FAISS: The missing manual [113] | 0.4 to 0.85 | SIFT | Suitable for small or low dimensional datasets. |
| HNSW | 0.5 to 0.95 | SIFT | High speed and quality usage, uses a lot of memory. | |
| IVF | 0.7 to 0.95 | SIFT | High quality, high speed, easily scalable. |
| Number of Query | <l2> | σ(l2) | max(l2) | <lc> | σ(lc) | max(lc) | nres | Recall |
|---|---|---|---|---|---|---|---|---|
| 0 | 78,725.8 | 5723.66 | 83,582 | 82,588.8 | 10,322.3 | 103,515 | 41 | 0.97 |
| 1 | 62,840.1 | 3453.5 | 66,853 | 54,277.1 | 10,035.0 | 75,566.6 | 28 | 0.96 |
| 2 | 41,863.3 | 3374.59 | 45,862 | 43,334.7 | 8653.09 | 62,068.9 | 23 | 0.99 |
| 3 | 41,260.5 | 3038.36 | 44,852 | 43,877.7 | 4615.84 | 70,784.3 | 14 | 1.00 |
| 4 | 62,709.1 | 4470.44 | 67,477 | 63,630.6 | 19,619.1 | 93,600.6 | 29 | 0.97 |
| 5 | 81,312.2 | 5371.47 | 87,644 | 86,521.2 | 12,956.8 | 108,471 | 42 | 0.88 |
| 6 | 61,879.8 | 3354.74 | 66,123 | 61,033.3 | 9810.32 | 78,267.6 | 43 | 0.94 |
| 7 | 36,848.8 | 4143.73 | 41,901 | 33,443.5 | 12,430.3 | 73,763.8 | 16 | 1.00 |
| 8 | 60,241.2 | 3521.91 | 64,914 | 57,454.6 | 12,061.0 | 81,352.5 | 30 | 0.94 |
| 9 | 58,733.8 | 3965.1 | 63,567 | 61,073.5 | 11,142.1 | 84,609.7 | 32 | 1.00 |
| 10 | 79,190.0 | 6635.88 | 86,494 | 85,952.2 | 8779.93 | 106,106.0 | 44 | 0.93 |
| 11 | 44,841.0 | 3336.09 | 48,074 | 44,711.4 | 6757.47 | 58,723.0 | 26 | 0.97 |
| 12 | 53,708.8 | 3670.09 | 57,272 | 56,956.6 | 7524.57 | 70,652.4 | 32 | 0.98 |
| 13 | 57,174.1 | 3635.02 | 61,995 | 54,672.5 | 13,568.5 | 83,061.7 | 30 | 0.95 |
| 14 | 69,782.6 | 4423.02 | 74,929 | 65,107.2 | 15,021.9 | 90,432.0 | 36 | 0.94 |
| 15 | 55,450.7 | 3565.02 | 59,554 | 58,087.5 | 7800.52 | 74,834.5 | 30 | 1.00 |
| 16 | 51,708.7 | 3701.75 | 55,406 | 49,710.7 | 7565.09 | 69,743.6 | 38 | 0.99 |
| 17 | 57,093.6 | 3028.29 | 60,511 | 56,592.3 | 6949.12 | 72,847.6 | 36 | 0.94 |
| 18 | 62,165.1 | 3509.82 | 66,257 | 65,344.1 | 9005.28 | 84,700.5 | 44 | 0.98 |
| 19 | 46,533.5 | 2720.02 | 49,592 | 44,272.4 | 6638.65 | 58,191.4 | 32 | 0.97 |
| Complexity Class Number | A | b | c | RMSD |
|---|---|---|---|---|
| class 0 | 0.216248 | 30.53076 | 0.998972 | 3.68 × 10⁻⁶ |
| class 1 | 0.460257 | 41.96785 | 0.995304 | 3.48 × 10⁻⁵ |
| class 2 | 0.565668 | 51.76675 | 0.989846 | 1.19 × 10⁻⁴ |
| class 3 | 0.635409 | 70.00414 | 0.987077 | 8.45 × 10⁻⁵ |
| Feature | Importance |
|---|---|
| nres | 0.68 |
| σ(l2) | 0.12 |
| <lc> | 0.09 |
| Big5 | 0.05 |
| <l2> | 0.04 |
| max(l2) | 0.02 |
| Classifier | Accuracy |
|---|---|
| Example Classifier 1, 6 logical rules | 0.91 |
| Example Classifier 2, 3 logical rules | 0.83 |
| Example Classifier 3, 1 logical rule | 0.85 |
| Method | Number of Clusters Processed for Each Query (avg.) | Number of Data Vectors Processed for Each Query (avg.) | Recall@100 (avg., 10,000 Queries) |
|---|---|---|---|
| Processing 4.5% of clusters (classical IVF search) | 184 | 45,519.1015625 | 98.842% |
| Processing 3% of clusters, then recognition, then processing additional 3% of clusters (Algorithm 1) | 182.96 | 45,498.7109375 | 99.149% |
| Index 1 | Index 2 | Index 3 | Index 4 | Index 5 | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Run number | 1 | 2 | 1 | 2 | 1 | 2 | 1 | 2 | 1 | 2 |
| Top K | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 |
| Parallel processes | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 |
| M1 | 17 | 17 | 17 | 17 | 17 | 17 | 17 | 17 | 17 | 17 |
| M2 | 22 | 22 | 22 | 22 | 22 | 22 | 22 | 22 | 22 | 22 |
| M3 | 29 | 29 | 29 | 29 | 29 | 29 | 29 | 29 | 29 | 29 |
| M1/nminchecked | 0.43 | 0.43 | 0.43 | 0.43 | 0.43 | 0.43 | 0.43 | 0.43 | 0.43 | 0.43 |
| M2/nminchecked | 0.55 | 0.55 | 0.55 | 0.55 | 0.55 | 0.55 | 0.55 | 0.55 | 0.55 | 0.55 |
| M3/nminchecked | 0.73 | 0.73 | 0.73 | 0.73 | 0.73 | 0.73 | 0.73 | 0.73 | 0.73 | 0.73 |
| S1 | 40 | 40 | 40 | 40 | 40 | 40 | 40 | 40 | 40 | 40 |
| S2 | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 |
| S3 | 141 | 141 | 141 | 141 | 141 | 141 | 141 | 141 | 141 | 141 |
| S4 | 185 | 185 | 185 | 185 | 185 | 185 | 185 | 185 | 185 | 185 |
| Recall@100 | 0.9913 | 0.9913 | 0.9912 | 0.9912 | 0.9913 | 0.9913 | 0.9910 | 0.9910 | 0.9912 | 0.9912 |
| Latency | 227.77 | 222.5 | 235.17 | 232.34 | 224.73 | 222.63 | 225.52 | 226 | 238.61 | 227.7 |
| QPS | 436.59 | 446.87 | 422.13 | 427.46 | 442.22 | 446.85 | 437.02 | 440.29 | 415.28 | 433.66 |
| nlist | 3150 | 3150 | 3150 | 3150 | 3150 | 3150 | 3150 | 3150 | 3150 | 3150 |
| Index 1 | Index 2 | Index 3 | Index 4 | Index 5 | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Run number | 1 | 2 | 1 | 2 | 1 | 2 | 1 | 2 | 1 | 2 |
| nprobe | 125 | 125 | 125 | 125 | 125 | 125 | 125 | 125 | 125 | 125 |
| Top K | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 |
| Parallel processes | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 |
| Recall@100 | 0.9912 | 0.9912 | 0.9911 | 0.9911 | 0.9913 | 0.9913 | 0.9912 | 0.9912 | 0.9912 | 0.9912 |
| Latency | 296.53 | 288.4 | 294.87 | 315.64 | 319.58 | 271.42 | 297.33 | 286.06 | 297.8 | 286.17 |
| QPS | 335.61 | 344.78 | 337.15 | 314.85 | 310.92 | 366.25 | 334.37 | 347.47 | 333.79 | 347.36 |
| nlist | 3150 | 3150 | 3150 | 3150 | 3150 | 3150 | 3150 | 3150 | 3150 | 3150 |
| Series | ||
|---|---|---|
| 1 | 2 | |
| Top K | 100 | 100 |
| Parallel processes | 100 | 100 |
| M1 | 10 | 10 |
| M2 | 18 | 17 |
| M3 | 23 | 23 |
| S1 | 12 | 9 |
| S2 | 47 | 37 |
| S3 | 82 | 88 |
| S4 | 158 | 163 |
| Recall@100 | 0.99004 (avg.), std.dev. = 0.0002 | 0.99072 (avg.), std.dev. = 0.0002 |
| Latency | 227.428 (avg.), std.dev. = 14.135 | 246.847 (avg.), std.dev. = 14.623 |
| QPS (avg.) | 437.622 | 404.823 |
| Nlist | 3150 | 3150 |
| Algorithm, Index | Brute Force | Standard IVF, Averaged for Six Runs with Four Indexes | Adaptive IVF, Index 1 (Two Runs) | Adaptive IVF, Index 2 (Two Runs) | Adaptive IVF, Index 3 | Adaptive IVF, Index 4 | ||
|---|---|---|---|---|---|---|---|---|
| Top K | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 |
| Parallel processes | 100 | 100 | 100 | 100 | 100 | 100 | 100 | 100 |
| M1 | - | - | 15 | 15 | 15 | 15 | 15 | 15 |
| M2 | - | - | 23 | 23 | 23 | 23 | 23 | 23 |
| M3 | - | - | 27 | 27 | 27 | 27 | 27 | 27 |
| M1/nminchecked | - | - | 0.38 | 0.38 | 0.38 | 0.38 | 0.38 | 0.38 |
| M2/nminchecked | - | - | 0.58 | 0.58 | 0.58 | 0.58 | 0.58 | 0.58 |
| M3/nminchecked | - | - | 0.68 | 0.68 | 0.68 | 0.68 | 0.68 | 0.68 |
| S1 | - | - | 40 | 40 | 40 | 40 | 40 | 40 |
| S2 | - | - | 85 | 85 | 85 | 85 | 85 | 85 |
| S3 | - | - | 140 | 140 | 140 | 140 | 140 | 140 |
| S4 | - | - | 255 | 255 | 255 | 255 | 255 | 255 |
| Recall@100 | 1.00 | 0.9863 | 0.9904 | 0.9902 | 0.9902 | 0.9901 | 0.9901 | 0.9906 |
| Latency | - | 719.8 | 660.54 | 602.82 | 572.32 | 670.82 | 673.5 | 679.2 |
| QPS | 19.61 | 136.21 | 147.14 | 158.3 | 167.32 | 145.21 | 145.02 | 144.88 |
| nlist | - | 10,000 | 10,000 | 10,000 | 10,000 | 10,000 | 10,000 | 10,000 |
| nprobe | - | 120 | Adaptive (avg. 106.4) | Adaptive (avg. 106.4) | Adaptive (avg. 106.4) | Adaptive (avg. 106.3) | Adaptive (avg. 106.4) | Adaptive (avg. 106.4) |
| Recall100@100 | Latency, ms | QPS | |
|---|---|---|---|
| Standard IVF | 0.9904 (avg.), std.dev. = 0.0002 | 7959 (avg.), std.dev. = 356 | 6.08 (avg.) |
| Adaptive IVF (Algorithm 3) | 99.05 (avg.), std.dev. = 0.0002 | 5607 (avg.), std.dev. = 380 | 8.47 (avg.) |
| Avg. improvement, % | 29.6% | 39.3% |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2025 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license (https://creativecommons.org/licenses/by/4.0/).
Share and Cite
Kazakovtsev, V.; Plekhanov, M.; Naumchev, A.; Shkaberina, G.; Masich, I.; Egorova, L.; Stupina, A.; Popov, A.; Kazakovtsev, L. Fast Adaptive Approximate Nearest Neighbor Search with Cluster-Shaped Indices. Big Data Cogn. Comput. 2025, 9, 254. https://doi.org/10.3390/bdcc9100254
Kazakovtsev V, Plekhanov M, Naumchev A, Shkaberina G, Masich I, Egorova L, Stupina A, Popov A, Kazakovtsev L. Fast Adaptive Approximate Nearest Neighbor Search with Cluster-Shaped Indices. Big Data and Cognitive Computing. 2025; 9(10):254. https://doi.org/10.3390/bdcc9100254
Chicago/Turabian StyleKazakovtsev, Vladimir, Mikhail Plekhanov, Alexandr Naumchev, Guzel Shkaberina, Igor Masich, Lyudmila Egorova, Alena Stupina, Aleksey Popov, and Lev Kazakovtsev. 2025. "Fast Adaptive Approximate Nearest Neighbor Search with Cluster-Shaped Indices" Big Data and Cognitive Computing 9, no. 10: 254. https://doi.org/10.3390/bdcc9100254
APA StyleKazakovtsev, V., Plekhanov, M., Naumchev, A., Shkaberina, G., Masich, I., Egorova, L., Stupina, A., Popov, A., & Kazakovtsev, L. (2025). Fast Adaptive Approximate Nearest Neighbor Search with Cluster-Shaped Indices. Big Data and Cognitive Computing, 9(10), 254. https://doi.org/10.3390/bdcc9100254



