
An Object Detection Method Based on Frequency-Band Enhancement and Multi-Scale Fusion

Abstract
1. Introduction
- 1.
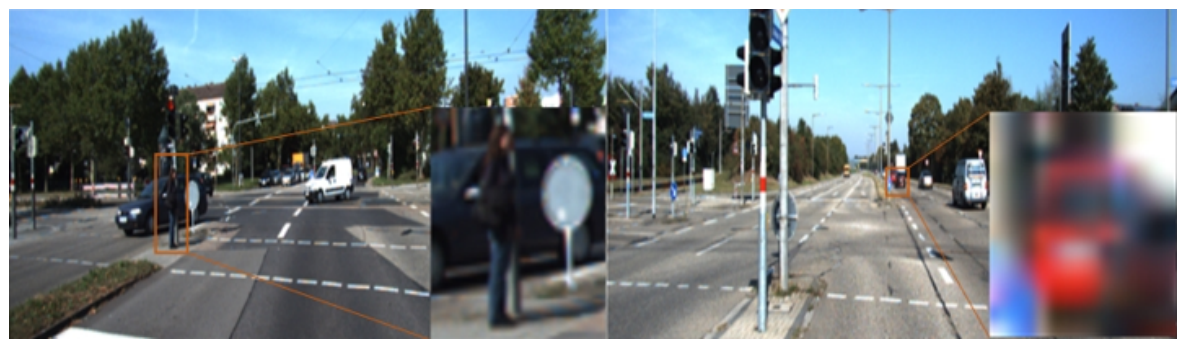
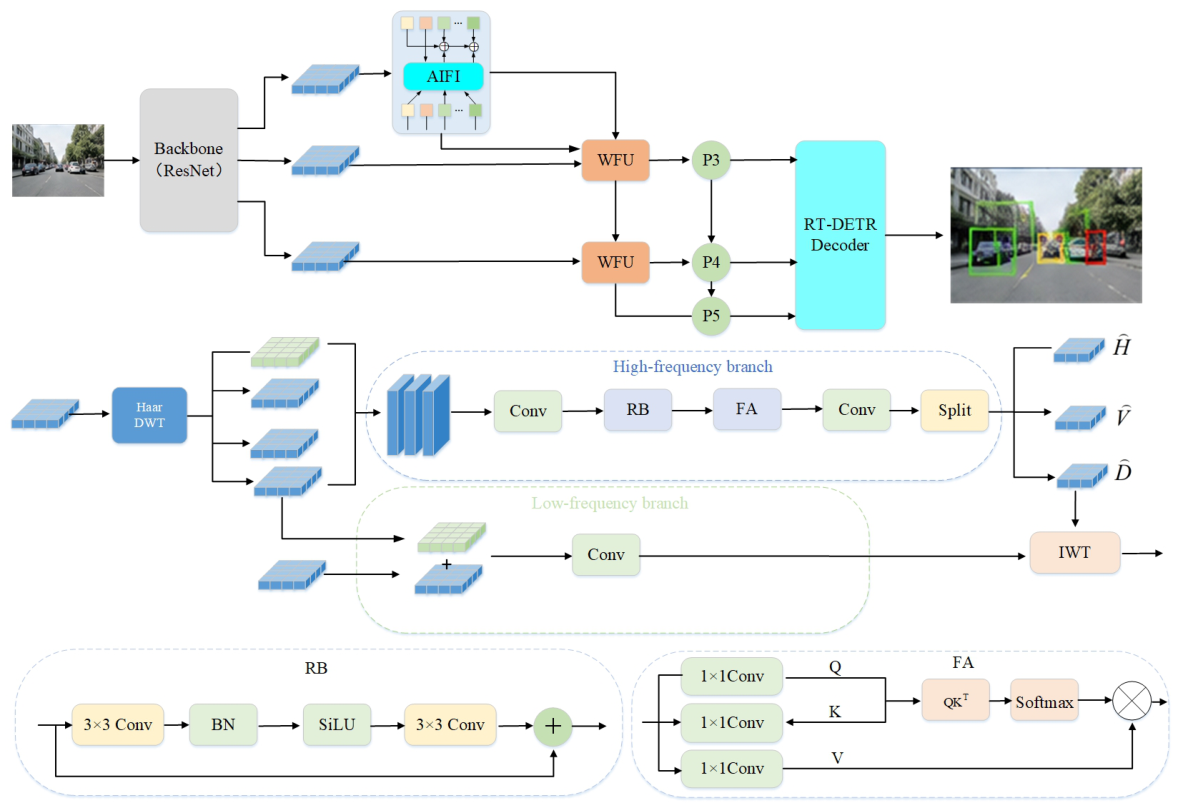
- A frequency-band enhancement and multi-scale fusion framework based on RT-DETR is introduced for object detection. To overcome the insufficient representation capability of small objects caused by limited pixel information, weak edges, and texture loss in autonomous driving scenarios, a frequency-aware feature enhancement strategy is integrated into the RT-DETR neck to improve small-object feature representation.
- 2.
- A Wavelet Frequency Unit (WFU) is developed to decompose high-resolution feature maps into low-frequency structural components and high-frequency detail components through Haar wavelet transformation. This decomposition enables the separation of semantic structures and fine-grained details, reducing the loss of small-object information during conventional spatial-domain feature fusion.
- 3.
- A dual-path enhancement strategy combining high-frequency detail refinement and low-frequency cross-scale fusion is proposed. In the high-frequency branch, residual enhancement and frequency attention mechanisms are employed to strengthen edge and texture representations of small objects. In the low-frequency branch, deeper semantic features are fused to improve the joint representation of object structures and contextual information.
- 4.
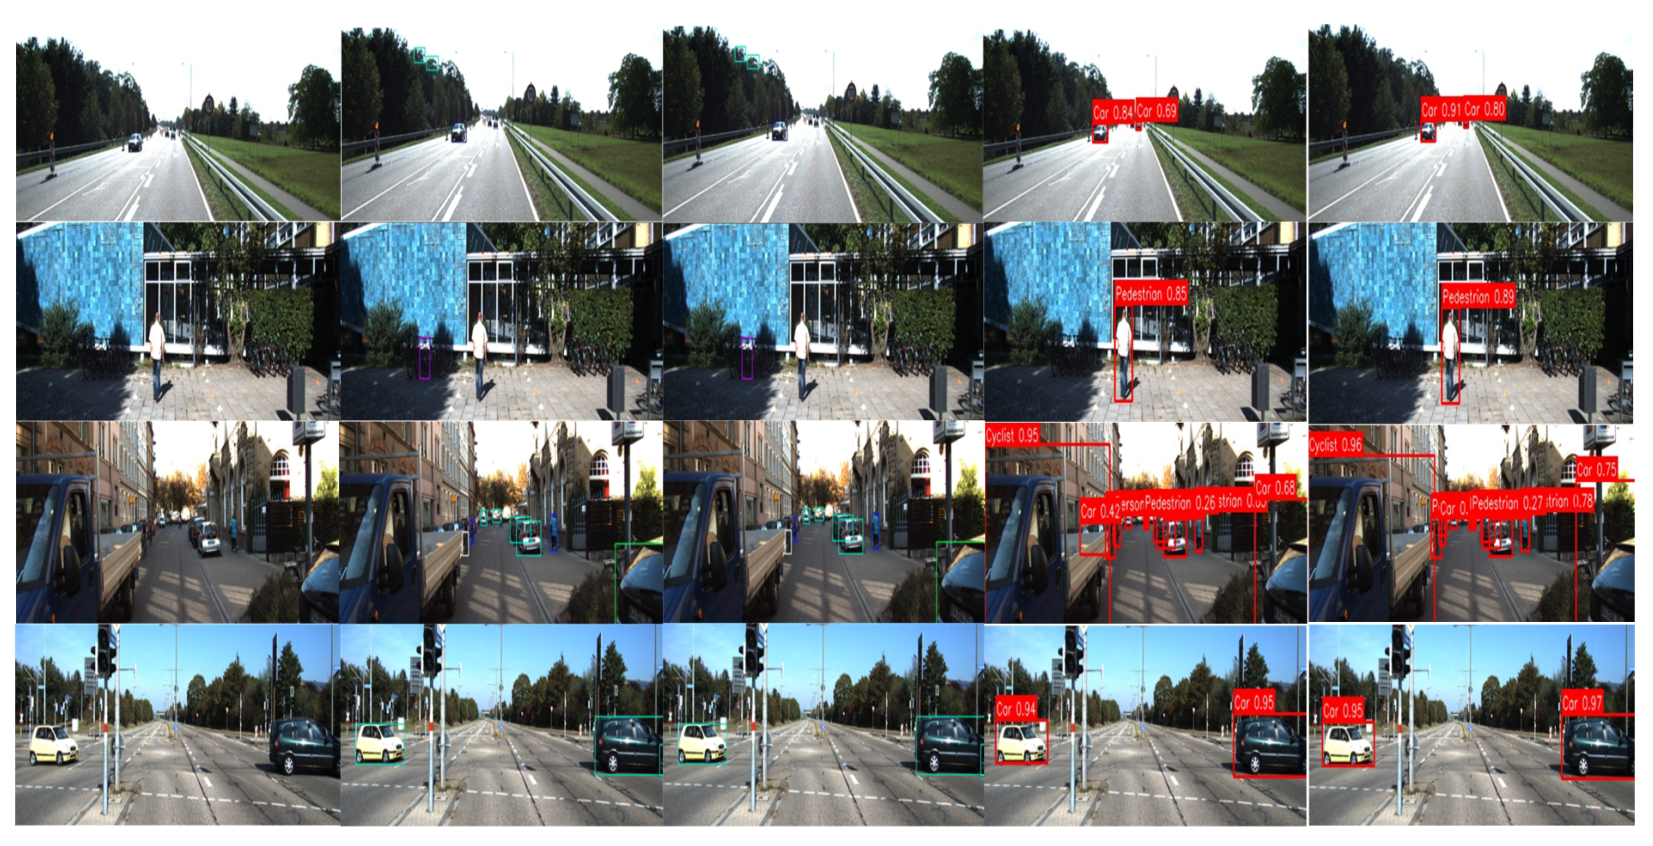
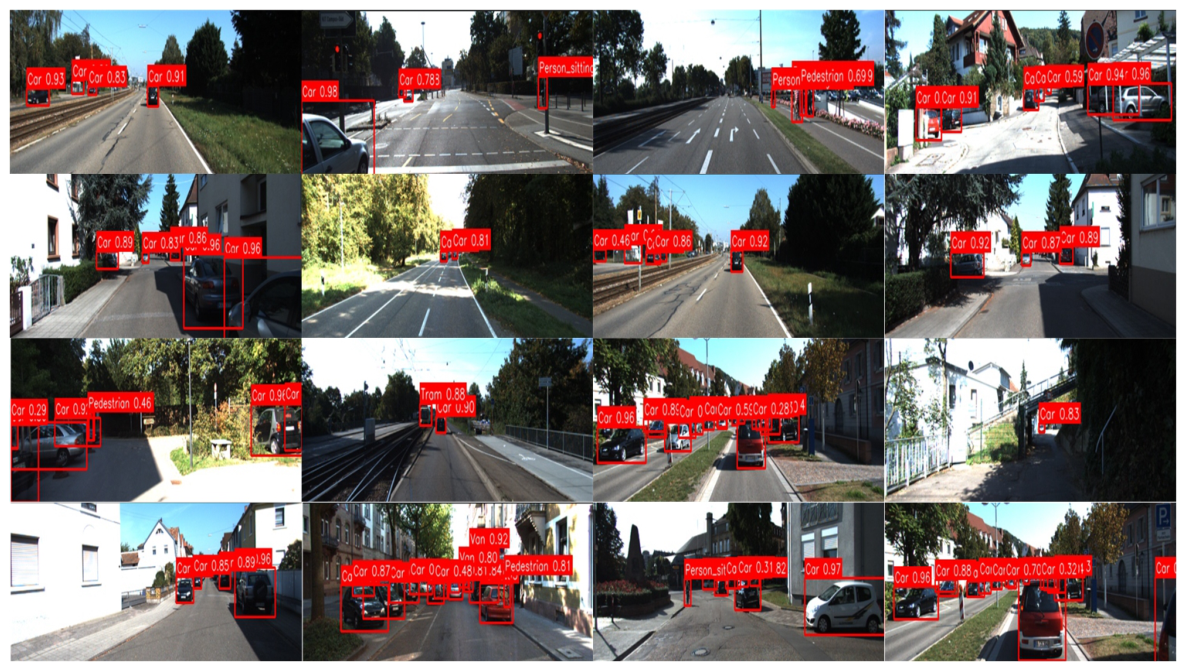
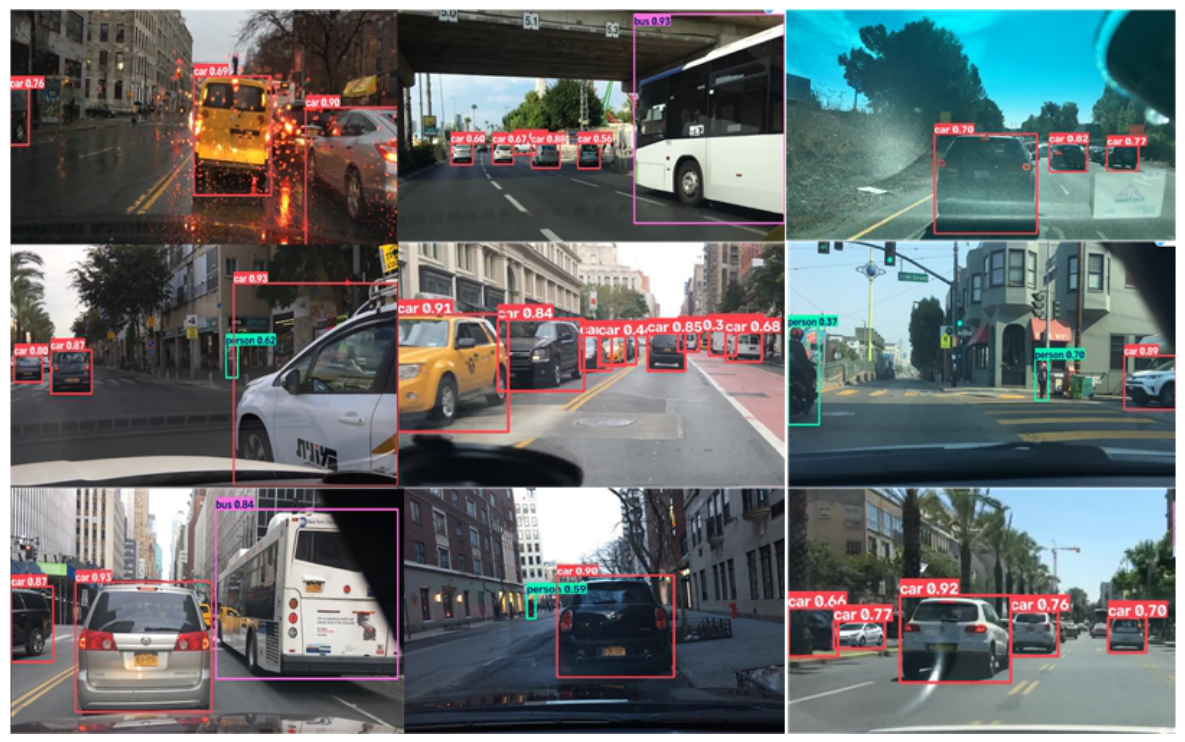
- Extensive experiments are conducted on the KITTI and BDD100K datasets. Comparative experiments, ablation studies, and repeated evaluations are performed on the KITTI dataset, while small-object detection assessments and visualization analyses are conducted on both datasets to comprehensively validate the effectiveness and robustness of the proposed approach.
2. Related Work
2.1. Transformer-Based Object Detection Methods
2.2. Applications of Wavelet Transforms in Object Detection
3. Method
3.1. Overall Network Architecture
3.2. High-Frequency Detail Enhancement
3.2.1. Residual Enhancement Block
3.2.2. High-Frequency Subband Spatial Attention
3.3. Multiscale Fusion and Feature Reconstruction
4. Experiments
4.1. Datasets and Data Splits
4.2. Evaluation Metrics
4.3. Experimental Settings
4.4. Comparative Experiments
4.5. Ablation Experiments
4.6. Visualization Analysis
5. Conclusions
Author Contributions
Funding
Institutional Review Board Statement
Informed Consent Statement
Data Availability Statement
Conflicts of Interest
References
- Liu, F.; Lu, Z.; Lin, X. Vision-based environmental perception for autonomous driving. Proc. Inst. Mech. Eng. Part D J. Automob. Eng. 2025, 239, 39–69. [Google Scholar] [CrossRef] [Scilit]
- Alaba, S.Y.; Ball, J.E. Deep learning-based image 3-D object detection for autonomous driving. IEEE Sens. J. 2023, 23, 3378–3394. [Google Scholar] [CrossRef] [Scilit]
- Pravallika, A.; Hashmi, M.F.; Gupta, A. Deep learning frontiers in 3D object detection: A comprehensive review for autonomous driving. IEEE Access 2024, 12, 173936–173980. [Google Scholar] [CrossRef] [Scilit]
- Khan, S.; Naseer, M.; Hayat, M.; Zamir, S.W.; Khan, F.S.; Shah, M. Transformers in vision: A survey. ACM Comput. Surv. 2022, 54, 1–41. [Google Scholar] [CrossRef] [Scilit]
- Hassija, V.; Palanisamy, B.; Chatterjee, A.; Mandal, A.; Chakraborty, D.; Pandey, A.; Chalapathi, G.S.S.; Kumar, D. Transformers for vision: A survey on innovative methods for computer vision. IEEE Access 2025, 13, 95496–95523. [Google Scholar] [CrossRef] [Scilit]
- Jamil, S.; Piran, M.J.; Kwon, O.-J. A comprehensive survey of transformers for computer vision. Drones 2023, 7, 287. [Google Scholar] [CrossRef] [Scilit]
- Thisanke, H.; Deshan, C.; Chamith, K.; Seneviratne, S.; Vidanaarachchi, R.; Herath, D. Semantic segmentation using vision transformers: A survey. Eng. Appl. Artif. Intell. 2023, 126, 106669. [Google Scholar] [CrossRef] [Scilit]
- Carion, N.; Massa, F.; Synnaeve, G.; Usunier, N.; Kirillov, A.; Zagoruyko, S. End-to-end object detection with transformers. In Proceedings of the European Conference on Computer Vision; Springer: Cham, Switzerland, 2020; pp. 213–229. [Google Scholar]
- Zhao, Y.; Lv, W.; Xu, S.; Wei, J.; Wang, G.; Dang, Q.; Liu, Y.; Chen, J. DETRs beat YOLOs on real-time object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition; IEEE: Piscataway, NJ, USA, 2024; pp. 16965–16974. [Google Scholar]
- Kong, Y.; Shang, X.; Jia, S. Drone-DETR: Efficient small object detection for remote sensing image using enhanced RT-DETR model. Sensors 2024, 24, 5496. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Madan, M.; Reich, C. Strengthening small object detection in adapted RT-DETR through robust enhancements. Electronics 2025, 14, 3830. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Zhang, T.; Wu, C.; Tao, R. Multi-scale spatiotemporal feature fusion network for video saliency prediction. IEEE Trans. Multimed. 2023, 26, 4183–4193. [Google Scholar] [CrossRef] [Scilit]
- Cheng, J.; Liu, H.; Liu, T.; Wang, F.; Li, H. Remote sensing image fusion via wavelet transform and sparse representation. ISPRS J. Photogramm. Remote Sens. 2015, 104, 158–173. [Google Scholar] [CrossRef] [Scilit]
- Zhu, X.; Su, W.; Lu, L.; Li, B.; Wang, X.; Dai, J. Deformable DETR: Deformable transformers for end-to-end object detection. arXiv 2020, arXiv:2010.04159. [Google Scholar]
- Liu, S.; Li, F.; Zhang, H.; Yang, X.; Qi, X.; Su, H.; Zhu, J.; Zhang, L. DAB-DETR: Dynamic anchor boxes are better queries for DETR. arXiv 2022, arXiv:2201.12329. [Google Scholar]
- Zhang, H.; Li, F.; Liu, S.; Zhang, L.; Su, H.; Zhu, J.; Ni, L.M.; Shum, H.-Y. DINO: DETR with improved denoising anchor boxes for end-to-end object detection. arXiv 2022, arXiv:2203.03605. [Google Scholar]
- Zong, Z.; Song, G.; Liu, Y. DETRs with collaborative hybrid assignments training. In Proceedings of the IEEE/CVF International Conference on Computer Vision; IEEE: Piscataway, NJ, USA, 2023; pp. 6748–6758. [Google Scholar]
- Lv, W.; Zhao, Y.; Chang, Q.; Huang, K.; Wang, G.; Liu, Y. RT-DETRv2: Improved baseline with bag-of-freebies for real-time detection transformer. arXiv 2024, arXiv:2407.17140. [Google Scholar]
- Chen, Q.; Su, X.; Zhang, X.; Wang, J.; Chen, J.; Shen, Y.; Han, C.; Chen, Z.; Xu, W.; Li, F.; et al. LW-DETR: A transformer replacement to YOLO for real-time detection. arXiv 2024, arXiv:2406.03459. [Google Scholar]
- Zhang, J.; Huang, X. FFC-YOLO: A SAR ship detection network with enhanced feature representation and dynamic cross-scale fusion. Eng. Res. Express 2025, 7, 025233. [Google Scholar] [CrossRef] [Scilit]
- Zhao, Y. Research on adaptive weight and frequency domain enhancement fusion method for small target detection. In Proceedings of the 2024 IEEE 2nd International Conference on Electrical, Automation and Computer Engineering (ICEACE); IEEE: Piscataway, NJ, USA, 2024; pp. 186–190. [Google Scholar]
- Chen, J.; Liu, N.; Sun, H.; Wang, Y. Freq-DETR: Frequency-aware transformer for real-time small object detection in unmanned aerial vehicle imagery. Expert Syst. Appl. 2025, 298, 129710. [Google Scholar] [CrossRef] [Scilit]
- Ge, X.; Qi, L.; Yan, Q.; Sun, J.; Zhu, Y.; Zhang, Y. Enhancing real-time aerial image object detection with high-frequency feature learning and context-aware fusion. Remote Sens. 2025, 17, 1994. [Google Scholar] [CrossRef] [Scilit]
- Yang, J.; Zhou, L.; Ju, Y. WDARFNet: A wavelet-domain adaptive receptive field network for improved oriented object detection in remote sensing. Appl. Sci. 2025, 15, 7035. [Google Scholar] [CrossRef] [Scilit]
- He, K.; Zhang, X.; Ren, S.; Sun, J. Deep residual learning for image recognition. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2016; pp. 770–778. [Google Scholar]
- Mallat, S.G. A theory for multiresolution signal decomposition: The wavelet representation. IEEE Trans. Pattern Anal. Mach. Intell. 1989, 11, 674–693. [Google Scholar] [CrossRef] [Scilit]
- Geiger, A.; Lenz, P.; Stiller, C.; Urtasun, R. Vision meets robotics: The KITTI dataset. Int. J. Robot. Res. 2013, 32, 1231–1237. [Google Scholar] [CrossRef] [Scilit]
- Wang, S.; Zhang, E.-L.; Hong, R.-L.; Kim, J. An enhanced YOLOv10 framework for small-object safety helmet detection on construction sites. Sci. Rep. 2026. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Wang, S.; Kim, H.; Yeo, J.; Kim, J. YOLOv10-based multi-scale variant object detection for multi-category PPE non-compliance monitoring on construction sites. Sci. Rep. 2026, 16, 24591. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Yu, F.; Chen, H.; Wang, X.; Xian, W.; Chen, Y.; Liu, F.; Madhavan, V.; Darrell, T. BDD100K: A diverse driving dataset for heterogeneous multitask learning. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2020; pp. 2633–2642. [Google Scholar]
- Lin, T.-Y.; Maire, M.; Belongie, S.; Hays, J.; Perona, P.; Ramanan, D.; Dollár, P.; Zitnick, C.L. Microsoft COCO: Common objects in context. In European Conference on Computer Vision (ECCV); Springer International Publishing: Cham, Switzerland, 2014; pp. 740–755. [Google Scholar]
- Loshchilov, I.; Hutter, F. Decoupled weight decay regularization. arXiv 2017, arXiv:1711.05101. [Google Scholar]
- Ren, S.; He, K.; Girshick, R.; Sun, J. Faster R-CNN: Towards real-time object detection with region proposal networks. IEEE Trans. Pattern Anal. Mach. Intell. 2016, 39, 1137–1149. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Redmon, J.; Farhadi, A. YOLOv3: An incremental improvement. arXiv 2018, arXiv:1804.02767. [Google Scholar]
- Jocher, G.; Stoken, A.; Borovec, J.; Liu, C.; Hogan, A.; Diaconu, L.; Poznanski, J.; Yu, L.; Rai, P.; Ferriday, R.; et al. Ultralytics/yolov5: v2.0. Zenodo. 2020. Available online: https://ui.adsabs.harvard.edu/abs/2020zndo...3958273J/abstract (accessed on 19 August 2026).
- Wang, C.-Y.; Bochkovskiy, A.; Liao, H.-Y.M. YOLOv7: Trainable bag-of-freebies sets new state-of-the-art for real-time object detectors. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR); IEEE: Piscataway, NJ, USA, 2023; pp. 7464–7475. [Google Scholar]
- Sapkota, R.; Karkee, M. Ultralytics YOLO evolution: An overview of YOLO26, YOLO11, YOLOv8 and YOLOv5 object detectors for computer vision and pattern recognition. arXiv 2025, arXiv:2510.09653. [Google Scholar]
- Wang, C.; He, W.; Nie, Y.; Guo, J.; Liu, C.; Wang, Y.; Han, K. Gold-YOLO: Efficient object detector via gather-and-distribute mechanism. In Advances in Neural Information Processing Systems (NeurIPS); Neural Information Processing Systems Foundation, Inc.: San Diego, CA, USA, 2023; Volume 36, pp. 51094–51112. [Google Scholar]
- Wang, A.; Chen, H.; Liu, L.; Chen, K.; Lin, Z.; Han, J.; Ding, G. YOLOv10: Real-time end-to-end object detection. In Advances in Neural Information Processing Systems (NeurIPS); Neural Information Processing Systems Foundation, Inc.: San Diego, CA, USA, 2024; Volume 37, pp. 107984–108011. [Google Scholar]



| Model | P (%) | R (%) | mAP@0.5 (%) | mAP@0.5:0.95 (%) | Parameters (M) | FPS |
|---|---|---|---|---|---|---|
| Faster-RCNN | 82.6 | 73.4 | 72.8 | 43.0 | 41.3 | 18.7 |
| YOLOv3-tiny | 85.1 | 72.2 | 75.7 | 53.0 | 8.5 | 154.7 |
| YOLOv5n | 87.0 | 77.5 | 84.0 | 53.2 | 1.9 | 125.4 |
| YOLOv7-tiny | 88.9 | 79.0 | 86.8 | 45.1 | 6.2 | 104.7 |
| YOLOv8n | 89.2 | 80.7 | 87.5 | 57.3 | 3.1 | 135.0 |
| GOLD-YOLO | 90.8 | 81.6 | 88.6 | 59.8 | 35.6 | 118.4 |
| DINO | 89.5 | 81.2 | 88.7 | 59.4 | 23.0 | 87.2 |
| YOLOv10n | 90.4 | 81.6 | 88.5 | 60.8 | 2.3 | 126.3 |
| YOLOv11n | 91.8 | 82.0 | 89.5 | 61.5 | 2.6 | 134.5 |
| RT-DETR | 89.8 ± 0.3 | 92.2 ± 0.2 | 93.7 ± 0.2 | 68.6 ± 0.2 | 30.9 | 95.6 |
| Ours | 93.5 ± 0.2 | 91.1 ± 0.3 | 95.5 ± 0.2 | 69.7 ± 0.2 | 31.8 | 92.8 |
| Model | Car | Van | Truck | Pedestrian | Cyclist | Tram |
|---|---|---|---|---|---|---|
| Faster-RCNN | 81.3 | 72.0 | 68.5 | 70.5 | 73.8 | 70.7 |
| YOLOv3-tiny | 82.8 | 76.0 | 72.5 | 72.5 | 75.4 | 75.0 |
| YOLOv5n | 91.5 | 81.8 | 79.2 | 85.3 | 86.6 | 79.6 |
| YOLOv7-tiny | 94.2 | 84.7 | 81.3 | 88.8 | 88.1 | 83.7 |
| YOLOv8n | 95.1 | 85.3 | 82.4 | 90.2 | 89.4 | 82.6 |
| GOLD-YOLO | 96.2 | 86.8 | 83.5 | 91.2 | 90.4 | 83.5 |
| DINO | 96.8 | 86.1 | 82.9 | 91.8 | 90.7 | 83.9 |
| YOLOv10n | 97.1 | 85.6 | 82.1 | 91.6 | 90.8 | 83.3 |
| YOLOv11n | 97.4 | 87.0 | 83.8 | 92.2 | 91.1 | 85.5 |
| RT-DETR | 97.0 | 95.2 | 94.3 | 92.1 | 90.1 | 93.5 |
| Ours | 98.1 | 94.8 | 95.4 | 94.2 | 92.0 | 98.5 |
| Metric | RT-DETR (Mean ± SD) | Ours (Mean ± SD) | 95% CI of RT-DETR | 95% CI of Ours |
|---|---|---|---|---|
| P (%) | 89.8 ± 0.3 | 93.5 ± 0.2 | [89.05, 90.55] | [93.00, 94.00] |
| R (%) | 92.2 ± 0.2 | 91.1 ± 0.3 | [91.70, 92.70] | [90.35, 91.85] |
| mAP@0.5 (%) | 93.7 ± 0.2 | 95.5 ± 0.2 | [93.20, 94.20] | [95.00, 96.00] |
| mAP@0.5:0.95 (%) | 68.6 ± 0.2 | 69.7 ± 0.2 | [68.10, 69.10] | [69.20, 70.20] |
| APs (%) | 46.8 ± 0.4 | 49.5 ± 0.3 | [45.81, 47.79] | [48.76, 50.24] |
| ARs (%) | 58.1 ± 0.3 | 60.4 ± 0.2 | [57.36, 58.84] | [59.90, 60.90] |
| Model | Parameters (M) | FPS | mAP@0.5 (%) | mAP@0.5:0.95 (%) |
|---|---|---|---|---|
| Faster-RCNN | 41.3 | 18.7 | 47.9 | 26.5 |
| YOLOv3-tiny | 8.5 | 154.0 | 46.7 | 25.9 |
| YOLOv5n | 1.9 | 125.4 | 49.5 | 26.2 |
| YOLOv7-tiny | 6.2 | 104.7 | 50.7 | 29.1 |
| YOLOv8n | 3.1 | 135.0 | 51.2 | 28.7 |
| RT-DETR | 30.9 | 95.6 | 50.0 | 28.6 |
| Ours | 31.8 | 92.8 | 51.7 | 29.7 |
| Metric | RT-DETR (Mean ± SD) | Ours (Mean ± SD) | 95% CI of RT-DETR | 95% CI of Ours |
|---|---|---|---|---|
| 50.0 ± 0.3 | 51.7 ± 0.2 | [49.25, 50.75] | [51.20, 52.20] | |
| 28.6 ± 0.2 | 29.7 ± 0.2 | [28.10, 29.10] | [29.20, 30.20] | |
| 14.8 ± 0.3 | 16.4 ± 0.3 | [14.05, 15.55] | [15.65, 17.15] | |
| 27.9 ± 0.4 | 29.6 ± 0.3 | [26.91, 28.89] | [28.85, 30.35] |
| Model | P (%) | R (%) | mAP@0.5 (%) | mAP@0.5:0.95 (%) |
|---|---|---|---|---|
| RT-DETR | 89.8 | 92.2 | 93.7 | 68.6 |
| RT-DETR+A | 91.3 | 91.8 | 94.5 | 68.4 |
| RT-DETR+B | 92.1 | 91.6 | 94.8 | 69.2 |
| RT-DETR+C | 92.8 | 91.4 | 95.1 | 69.0 |
| RT-DETR+A+B | 92.5 | 91.6 | 95.0 | 68.8 |
| RT-DETR+A+C | 93.1 | 92.1 | 95.1 | 69.3 |
| RT-DETR+B+C | 92.9 | 92.2 | 95.3 | 69.5 |
| Ours | 93.5 | 91.1 | 95.5 | 69.7 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Dai, Z.; Qiu, Y.; Lu, Y. An Object Detection Method Based on Frequency-Band Enhancement and Multi-Scale Fusion. J. Imaging 2026, 12, 447. https://doi.org/10.3390/jimaging12090447
Dai Z, Qiu Y, Lu Y. An Object Detection Method Based on Frequency-Band Enhancement and Multi-Scale Fusion. Journal of Imaging. 2026; 12(9):447. https://doi.org/10.3390/jimaging12090447
Chicago/Turabian StyleDai, Zhenzhao, Yongsheng Qiu, and Yuanyao Lu. 2026. "An Object Detection Method Based on Frequency-Band Enhancement and Multi-Scale Fusion" Journal of Imaging 12, no. 9: 447. https://doi.org/10.3390/jimaging12090447
APA StyleDai, Z., Qiu, Y., & Lu, Y. (2026). An Object Detection Method Based on Frequency-Band Enhancement and Multi-Scale Fusion. Journal of Imaging, 12(9), 447. https://doi.org/10.3390/jimaging12090447