


Abstract
Municipal Solid Waste (MSW) is a common problem in all cities worldwide; it is expected to increase to 3400 billion tons by 2050. In Mexico, an average of 108,146 tons of MSW are generated daily. Artificial Intelligence (AI) is a computer tool that allows the development of systems that facilitate the recycling process. However, most AI programs focus on classifying paper, plastic, glass and metal; therefore, wood and textile waste have received little attention. Using texture techniques such as Local Binary Pattern (LBP), Gray-Level Co-occurrence Matrix (GLCM), Histogram of Oriented Gradients (HOG), Canny/Sobel edge detection, Fractal Dimension (FD), feature values were extracted and integrated from 4396 images belonging to wood and textile categories. Using the Random Forest Importance method, the most significant features were selected to train three Machine Learning (ML) algorithms. Multilayer Perceptron (MLP) achieved the best performance in accuracy with 96.70%, followed by Random Forest (RF) at 95.45% and Support Vector Machine (SVM) with 95.22%. The implementation of these comparisons will serve as a basis for the development of new technological tools with low computational cost that carry out a proper waste separation.
1. Introduction
Municipal Solid Waste (MSW) is a common problem in cities all worldwide. The challenge for government administrations is to achieve a proper management that reduces the consequences of MSW such as water, air, soil pollution, to mitigate its effects on the fauna and flora of the surrounding environment and it is expected global waste to increase to 3400 billion tons by 2050. Food and plant waste represent 44% and dry recyclable material such as plastic, paper, cardboard, metal and glass represent another 38% [1]. In this respect, the efficient use of landfills and the challenges linked to recycling, energy recovery and end-of-life waste treatment technologies have acquired great importance [2]. In Mexico in 2022, the average daily amount of MSW collected was 108,146 tons, of which 66.7% was collected through the door-to-door collection system; 24.9% at a designated collection point and 8.4% through container system [3]. Mexico has maintained its active participation in the implementation of the 2030 Agenda by presenting progress on the Sustainable Development Goals (SDGs) to the High-Level Political Forum on Sustainable Development [4].
The Ministry of Environment and Natural Resources (SEMARNAT) establishes a separation system to promote recycling. This system organizes it into a primary classification which includes organic and inorganic waste; and a secondary classification which includes the fractions with the greatest potential for reuse paper, plastic, metal, glass, wood and fabric [5]. The fundamental principles of a circular economy are to avoid the generation of waste, improve resource recovery, increase the use of recycled elements, better manage of the flow of materials for the benefit of the environment, economy and society. Wood is used abundantly worldwide, its potential to be part of the circular economy have received less attention [6]. Regarding textiles, circular management requires the creation of safe production cycles that generate less waste by promoting reuse and recycling, and avoiding incineration and landfilling [7]. SEMARNAT through its Basic Diagnosis for Comprehensive Waste Management estimates that the percentage of wood is 0.79% and textiles (rags) 2.82% at the national level [8].
With rapid advances in Artificial Intelligence (AI), through computer vision, the automatic detection and recognition of waste from images to replace manual classification is becoming more and more possible [9]. AI has enabled the development of tools to help sort MSW and thus increase recycling [10]. Convolutional Neural Networks (CNNs) are deep learning models, efficient and robust for working with large amounts of images automatically and are being used for MSW classification, among their disadvantages are that they need significant computational resources, a lot of training time, in addition to large amounts of labeled data, otherwise the model may malfunction due to overadjustment [11].
Various methods have been used in MSW management to collect and classify data into different categories. High-quality datasets are the foundation of a good AI model, allowing algorithms to be tailored to specific waste characteristics. Large datasets offer broad coverage; medium-sized ones typically balance comprehensive coverage with specific areas of focus, while small ones tend to excel in specialized applications or serve as well-documented references, providing options for training and evaluating waste classification. One of the limitations of datasets is scalability and maintainability, due to the dynamic nature of waste production and the evolution of material types, which requires the periodic updating and expansion of datasets. Addressing these challenges not only improves the accuracy and generalizability of classification algorithms but also strengthens the foundation for AI-powered modeling techniques [12].
To manage this situation, approaches are proposed to select the best combination of descriptors that, together, provide a better classification. Even if more than one descriptor needs to be calculated, this method remains fast enough for real-time applications. The resulting set of descriptors always improves the quality of the classification compared to the best descriptor alone; these selection techniques can be used in different datasets and contexts [13]. Machine Learning (ML) algorithms are designed to extract information that is used for tasks such as regression or classification. The workflow of ML methods consists of data processing, feature extraction and selection [14]. ML can be more effective than traditional statistical tools at handling several data formats, such as text, images and graphs. Using a combination of unknown feature to determine the result, they are adequate to solve complex environmental problems with large set of input feature [15]. There are studies that used Artificial Neural Networks (ANN) for automatic separation of waste materials [16]. Although there are smart trash cans that include an automatic classification system, most classify limited amounts and focus mainly on paper, plastic, glass, metal and others [17]; leaving aside wood and textile MSW.
Literature Review
There are MSW classification studies using AI algorithms. R3sNet neural network uses a combination of processing techniques and an optimized architecture with an accuracy of 87% for organic waste and 94% for inorganic waste. R3sNet outperforms the pre-trained ResNet50 model by up to 6% in MSW classification [18]. Comparing accuracy in four CNN models of YOLO (You Only Look Once) family through their performance in terms of inference speed and resource usage in an embedded system installed on a Raspberry Pi for organic and inorganic waste classification. The results obtained were: YOLOv4-tiny, 91.71%; YOLOv7-tiny, 91.34%; YOLOv8-nano, 93%; and YOLOv9-tiny, 92% [19].
The complexity of managing organic and recyclable waste was addressed using the CNN model architecture called VGG16. This model achieved an accuracy of 96% for organic waste and 88% recyclable waste; with the capabilities of the VGG16 framework, the model version achieved a recognition rate of 97% for labeled images [20]. By combining DL through MobileNetV3 model for feature extraction; with support of the optimization algorithm Harris Hawk Optimization to eliminate irrelevant feature and ML for classification, RF, SVM and Logistic Regression performance was compared. SVM reached the best accuracy of 96.74% [14].
With the help of simulation to forecast MSW generation and with historical data of variables such as population, formal employment, unemployment, number of family units and some others were trained, an ANN with five different neurons (5, 10, 20, 30 and 40) and six SVM algorithms (linear, quadratic, cubic, fine Gaussian, medium Gaussian and coarse Gaussian); RNS results with 10 neurons got the accuracy of 99.9% different from the SVM model linear result of 98.5% [21].
Through a data set of wood chip images with range of moisture levels in three categories: dry, medium and wet, five types of texture feature were extracted: Haralick, First-Order Statistics, Fast Fourier Power Spectrum, Gray Level Run Length Matrix and LBP. The developed AdaptMoist model generalizes data without label, and obtained an average accuracy of 80% [22]. For the prediction of texture parameters in textile industry, several texture extraction methods such as GLCM, Gabor Filter Bank, LBP and Interwined Frame Vector were applied to 130 texture images captured with a portable digital microscope with a resolution of 640 × 480 pixels, with ML algorithms such as RF, XGBoost and MLP. Best accuracy was achieved by XGBoost with 98.7% [23].
In Japan [24], an automatic sorting robot for beverage container recycling (plastic, cans, and clear and colored glass) was developed using AI for image recognition and high-speed suction grippers. Object detection was performed using YOLOv7, achieving a mean Average Precision (mAP) of 0.9967. Segment Anything Meta AI (SAM) was used to generate segmentation masks to calculate the robot’s exact grip point and to assist the neural network in correctly identifying glass colors. To validate its performance, 495 containers were placed on the conveyor belt; the robot reached a maximum speed of 45 picks per minute () with a 93% correct classification rate for the items it successfully gripped.
In China [25], a new garbage classification approach was presented, employing a dynamic Graph Neural Network based on multimodal feature fusion. This method aims to integrate deep visual information extracted by neural networks with global statistical data on image color. The improved model extracts deep semantic features through a Residual Network Attention Module (RNAM) and utilizes the CIELAB (LAB) color histogram to capture the global color distribution of the image. A k-nearest neighbor adaptive algorithm is used to construct the dynamic graph structure. The model achieved a classification accuracy of 99.33% in classifying kitchen waste, recyclable waste, hazardous waste, and other waste.
In Spain [26], a smart container prototype was designed and implemented to automatically classify waste using a multi-agent system and blockchain integration. The system features sensors that identify organic waste, plastics, paper, and other materials; through the PANGEA platform, it divides the recycling process into intelligent, autonomous modules that collaborate in real time to make instantaneous classification decisions. Blockchain technology was implemented to manage waste records, enhancing traceability throughout the sorting process. Its detection and classification performance was evaluated using three versions of YOLO (YOLOv8, YOLOv11, and YOLOv12). YOLOv12 achieved an mAP@50 of 86.2%, an overall precision of 84.6%, and an average F1-score of 80.1%.
This study proposes a sequential structure in stages that include from the integration of a dataset to the evaluation of the model, with a dataset of 4396 MSW images corresponding to wood and textile categories. Through feature extraction with texture techniques such as LBP, GLCM, HOG, Canny/Sobel edge detection and FD. Relevant feature were selected with Random Forest Importance and ML algorithms were trained such as SVM, RF and MLP, this last one considered an ANN. MLP obtained the best performance in accuracy with 96.70%, followed by RF with 95.45% and by SVM with 95.22%. In this regard, this work proposes a systematic comparative analysis under controlled conditions using ML models, which evaluates the discriminative capacity of classic texture descriptors applied to wood and textile MSW categories. The next step is to extend the validation to uncontrolled scenarios, where materials may appear mixed with other waste, aiming to advance toward the development of technological tools applicable to real-world MSW management contexts.
2. Results
The results of the three models are promising, although they exhibit certain differences. In terms of accuracy, all models achieved high metrics. The MLP model obtained the best accuracy at 96.70%, along with an AUC of 99.56%, indicating high discriminative power. This value corresponds to the use of an optimal threshold based on the F1-score, whereas the model reaches an accuracy of 96.25% using the standard 0.5 threshold.
On the other hand, SVM achieved an accuracy of 95.22% with an AUC of 99.20%, while RF yielded an accuracy of 95.45% and an AUC of 99.07%. Regarding computational cost, SVM is the most efficient model, followed by RF, and finally MLP, which is consistent with the complexity of each approach. MLP requires the longest training time, as shown in Table 1. However, it offers additional advantages, such as the ability to model complex non-linear relationships through deep architectures and adaptive learning adjustment [27], combined with the feature extraction techniques employed, this significantly strengthens the texture classification of wood and textile waste.
Table 1.
Comparison of metrics between SVM, RF and MLP.
3. Discussion
MSW classification is a complex issue in any social context. Multiple AI and computer vision methods have been proposed in the literature, specifically in DL and ML. These methods employ images, statistical texture tools, or a combination of both techniques to achieve better results. Accuracy varies depending on the classes, the context employed, and the complexity of the AI model used. For instance, R3sNet has outperformed ResNet50 by up to 6% in organic and inorganic waste classification [18], while the YOLOv8-nano model has reached accuracies near 93% on embedded systems [19]. Furthermore, hybrid approaches based on DL feature extraction, the Harris Hawk Optimization algorithm to eliminate irrelevant features, and ML for classification, have reported accuracies of up to 96.74% [14]. In the textile industry, combinations of texture descriptors—such as GLCM, GFB, LBP, and IFV—have been used alongside ML algorithms like XGBoost, achieving accuracies of up to 98.7% [23]. Similarly, using a dataset for moisture level prediction in wood chips, the AdaptMoist model achieved an average accuracy of 80% through the extraction of texture descriptors [22].
The results obtained demonstrate that texture feature extraction, combined with classic ML models, constitutes a viable approach for the classification of wood and textile MSW. In particular, the MLP model presented the best performance in terms of accuracy, AUC, and log-loss. From a structural standpoint, the performance of the texture descriptors can be interpreted based on the physical properties of the materials. FD captures the multiscale complexity and irregularity of surfaces, aligning with the intrinsic nature of wood, which is characterized by non-uniform patterns. In contrast, GLCM and LBP-based descriptors are more suitable for modeling homogeneous or periodic textures, such as those found in textile materials, while Canny and Sobel operators detect both coarse and fine edges. This complementarity among descriptors allows for the construction of a highly discriminative feature space.
It is important to note that the dataset used was constructed under controlled conditions, where textures are clearly distinguishable and background interference is minimal. While this configuration facilitates the extraction of discriminative features, it does not fully represent the complexity of real-world waste classification scenarios. In industrial or municipal environments, additional challenges must be considered, such as complex and cluttered backgrounds, lighting variations, the presence of contaminants, deformation of textile materials, and varying sizes of wood, as well as the coexistence of multiple materials within the same scene.
These factors can affect the generalization capability of the models, particularly those based exclusively on texture information. In scenarios with mixed materials or partial occlusions, descriptors may capture ambiguous information, which could degrade system performance. Therefore, while the results are promising, they should be interpreted with caution.
From a practical perspective, the results suggest that approaches based on texture descriptors combined with classical ML models can be useful in controlled or semi-controlled environments where image acquisition conditions are stable. Furthermore, these models offer advantages in terms of computational cost, making them suitable for applications in resource-constrained systems.
The experimental results confirm texture analysis as an effective tool for waste texture classification, yet they highlight the need to extend validation to more realistic scenarios, as well as to integrate additional information such as color and object segmentation to improve system capability.
4. Materials and Methods
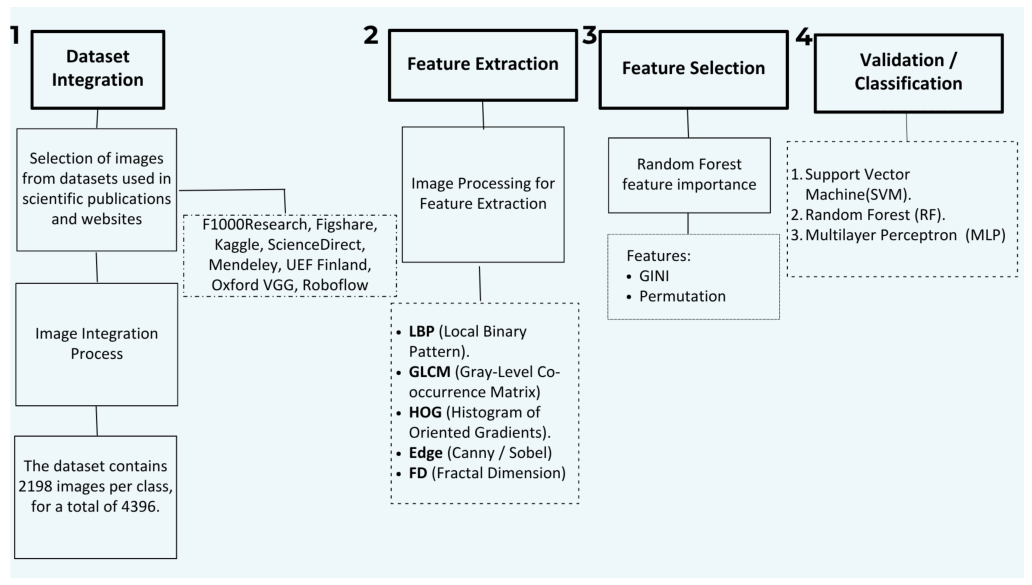
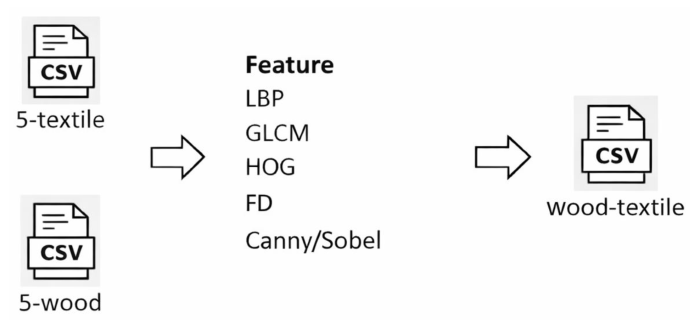
The experiment was conducted using a desk computer assembled with a 64 bits Windows operating system, Intel® Core (TM) i7-7700 processor CPU @3.60 GHz, 32 GB in RAM, NVIDIA graphics card Quadro M6000 24 GB and Python version 3.10.11 programming language. To evaluate and compare effectiveness of ML algorithms, a methodology that begins with the integration of a set of images of wood and textile waste was developed; to process them through extraction, integration and selection of feature, as shown in Figure 1.
Figure 1.
Methodological diagram.
4.1. Dataset Integration
To construct a diverse dataset for the wood and textile MSW categories, images were collected from various public sources and scientific repositories, where each dataset was originally developed in different scenarios and for specific purposes (Table 2). A visual inspection was performed to identify and remove duplicate images, selecting samples that best represented the textural characteristics of each material. For textiles, this included patterns such as weaves, embroidery, denim, and weathered surfaces; for wood, features like grains, knots, and cracks were prioritized. This selection process aimed to approximate real-world operating conditions.
Table 2.
Collected Dataset.
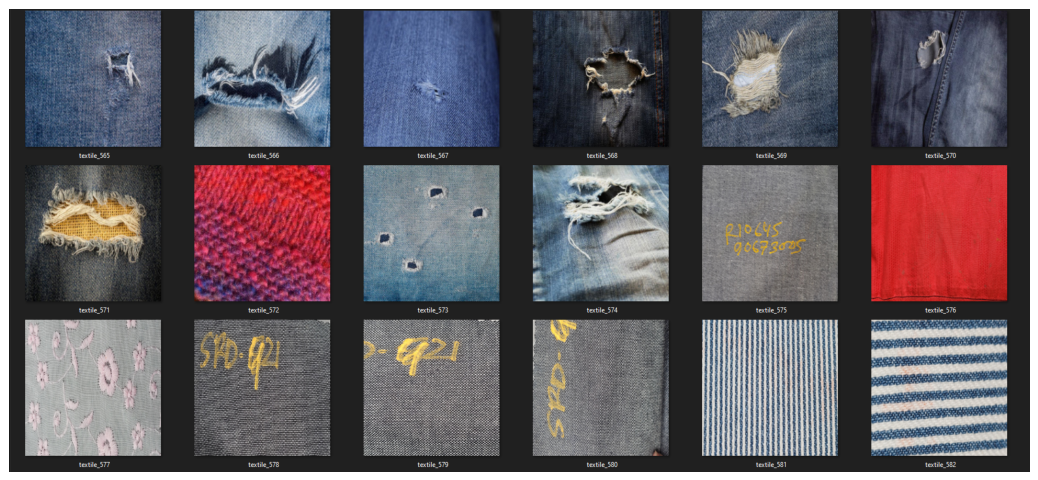
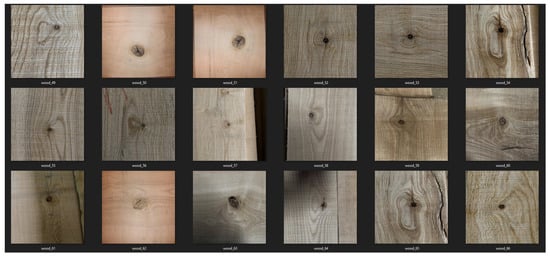
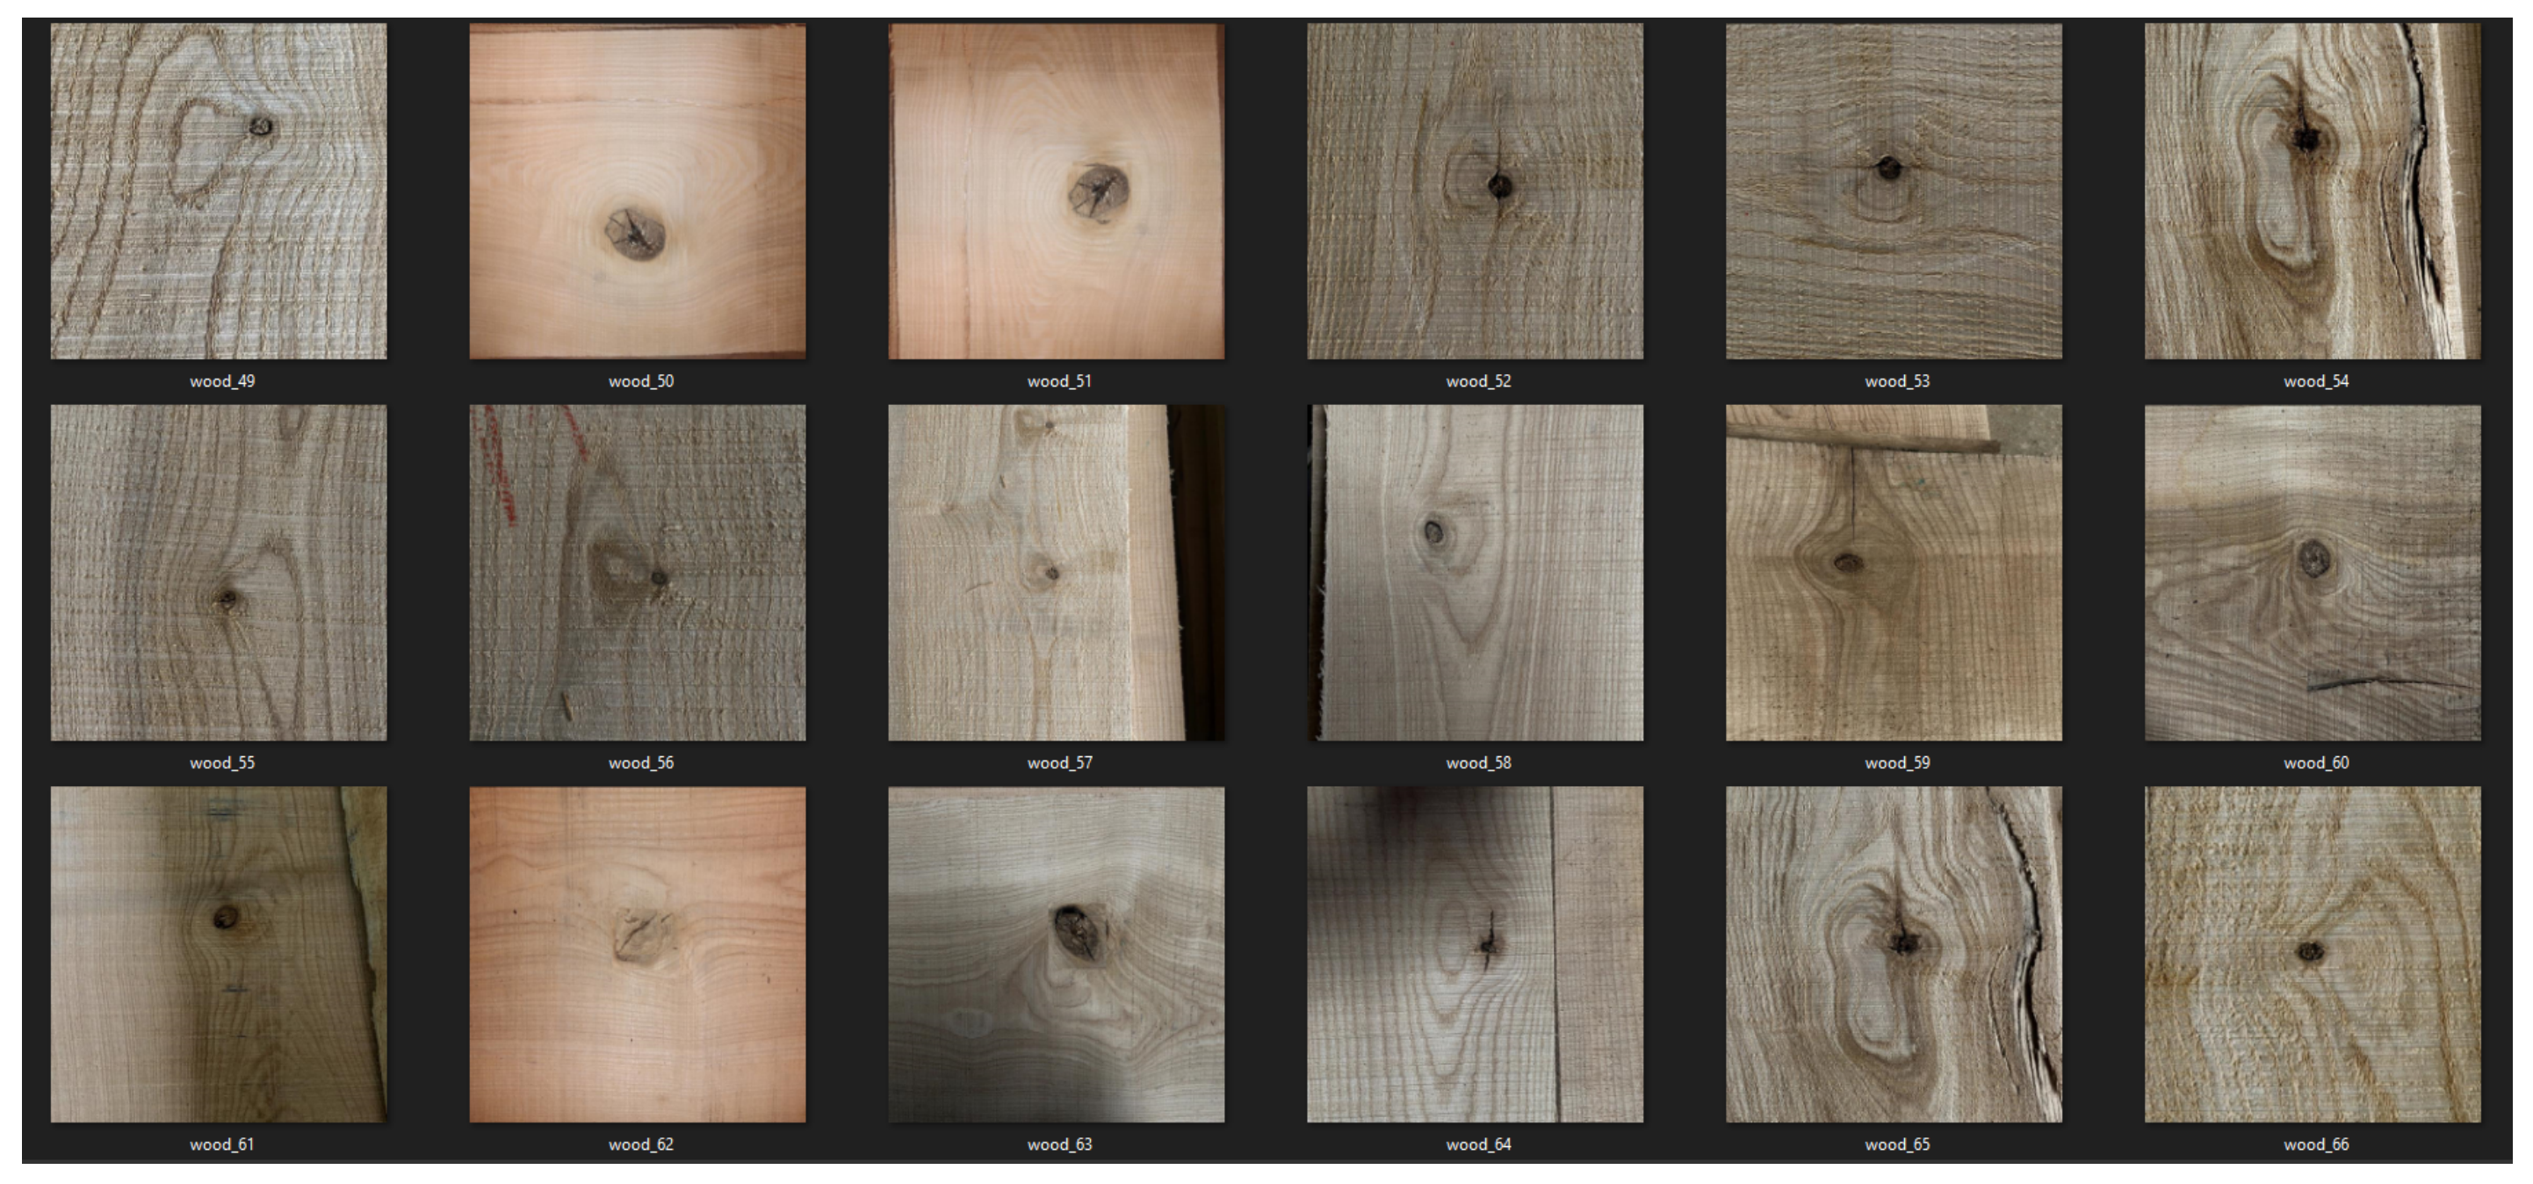
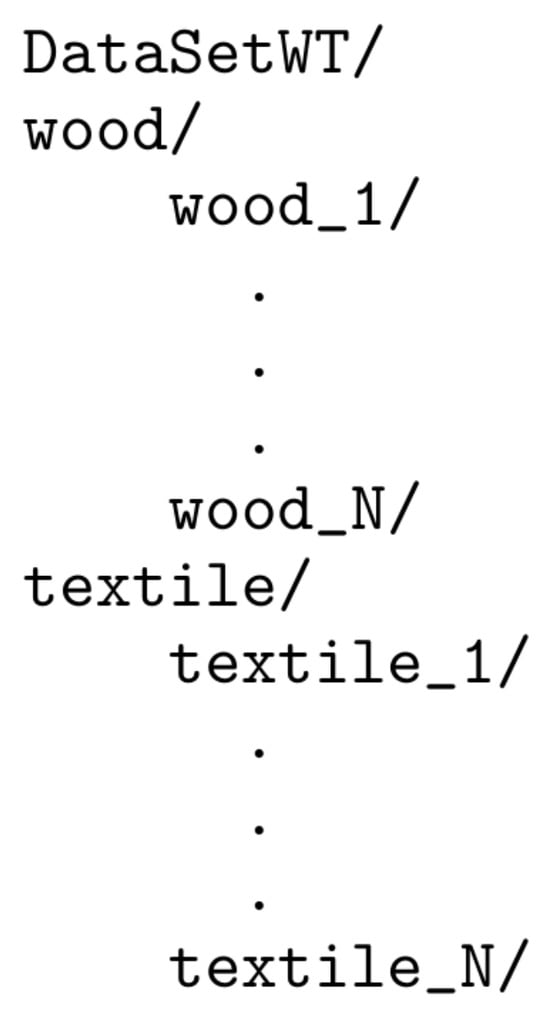
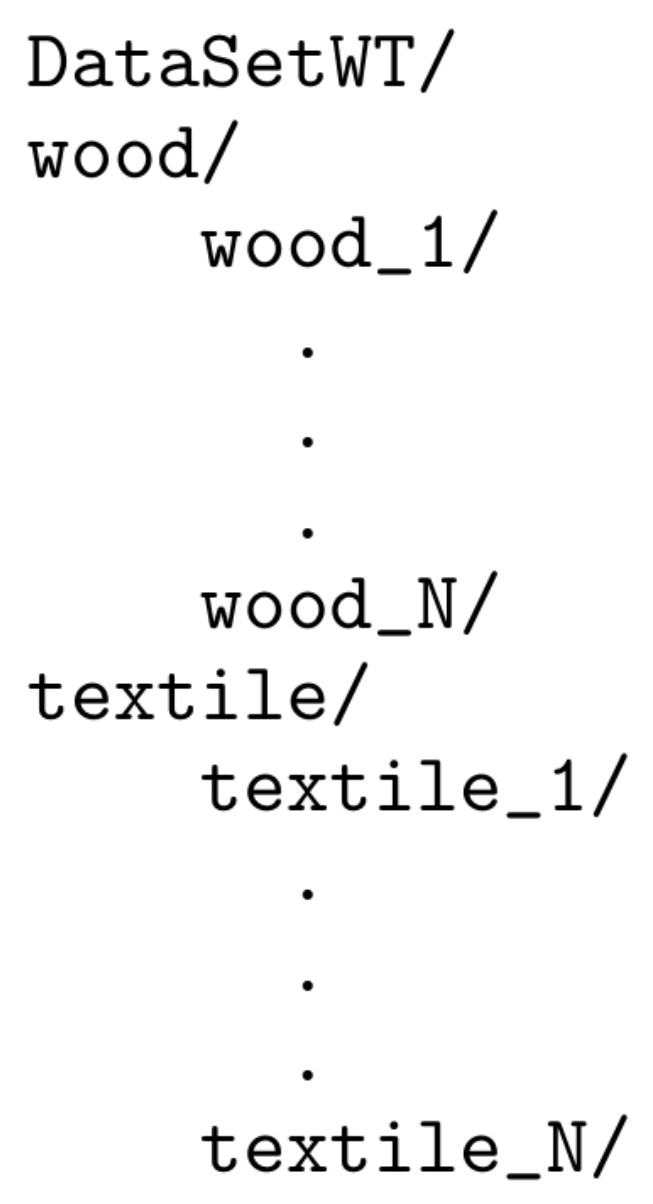
The final dataset consists of 4396 images, balanced with 2198 samples per class (Figure 2 and Figure 3). All images were normalized to a resolution of 640 × 640 pixels and organized into a folder structure for each class (Figure 4). This structure is required for the classical feature extraction algorithms to iterate through the source folders, extract texture descriptors from each image, and calculate and save their values.
Figure 2.
Representative samples of the textile class.
Figure 3.
Representative samples of the wood class.
Figure 4.
Dataset structure for feature extraction.
4.2. Feature Extraction
Using classic techniques such as: LBP, GLCM, HOG, Canny/Sobel edge detection and FD, the texture feature values of each image were calculated.
4.2.1. Gray-Level Co-Occurrence Matrix (GLCM)
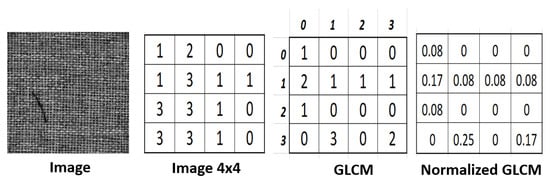
GLCM technique counts how many times two gray intensities appear together in a specific direction and distance as shown in Figure 5 [38]. A scan was performed in each wood and textile folders; from each image information on contrast, correlation, energy, homogeneity, dissimilarity, angular momentum was obtained in four directions . The equations for each feature is set below [39]:
Figure 5.
GLCM creation from an image.
Correlation (1): It is a measure of the linear dependence of the gray level between pixels in their respective locations, its value is 1 or −1 for an image with a completely positive or negative correlation [38].
Contrast (2): It is the difference in color that distinguishes an object.
Dissimilarity (3): Measures the difference between the gray levels of neighboring pixels in an image.
Homogeneity (4): Measures the distance between elements of GLCM and its diagonal.
Energy (5) and its Angular Second Momentum (ASM) (6): Energy is a measure of the uniformity in an image’s texture. Meanwhile, ASM is obtained from the squared root of the Energy.
Information:
- p: probability.
- i: gray level of the pixels at location .
- j: gray level of the pixels at distance d y and orientation .
- d: distance of pixels at orientation angle .
- : orientation angle of the main pixel (, , , ).
- : average of the probabilities in the x and y directions.
4.2.2. Local Binary Pattern (LBP)
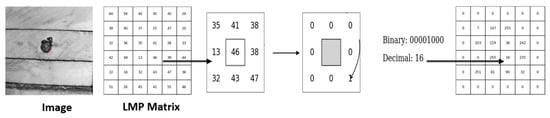
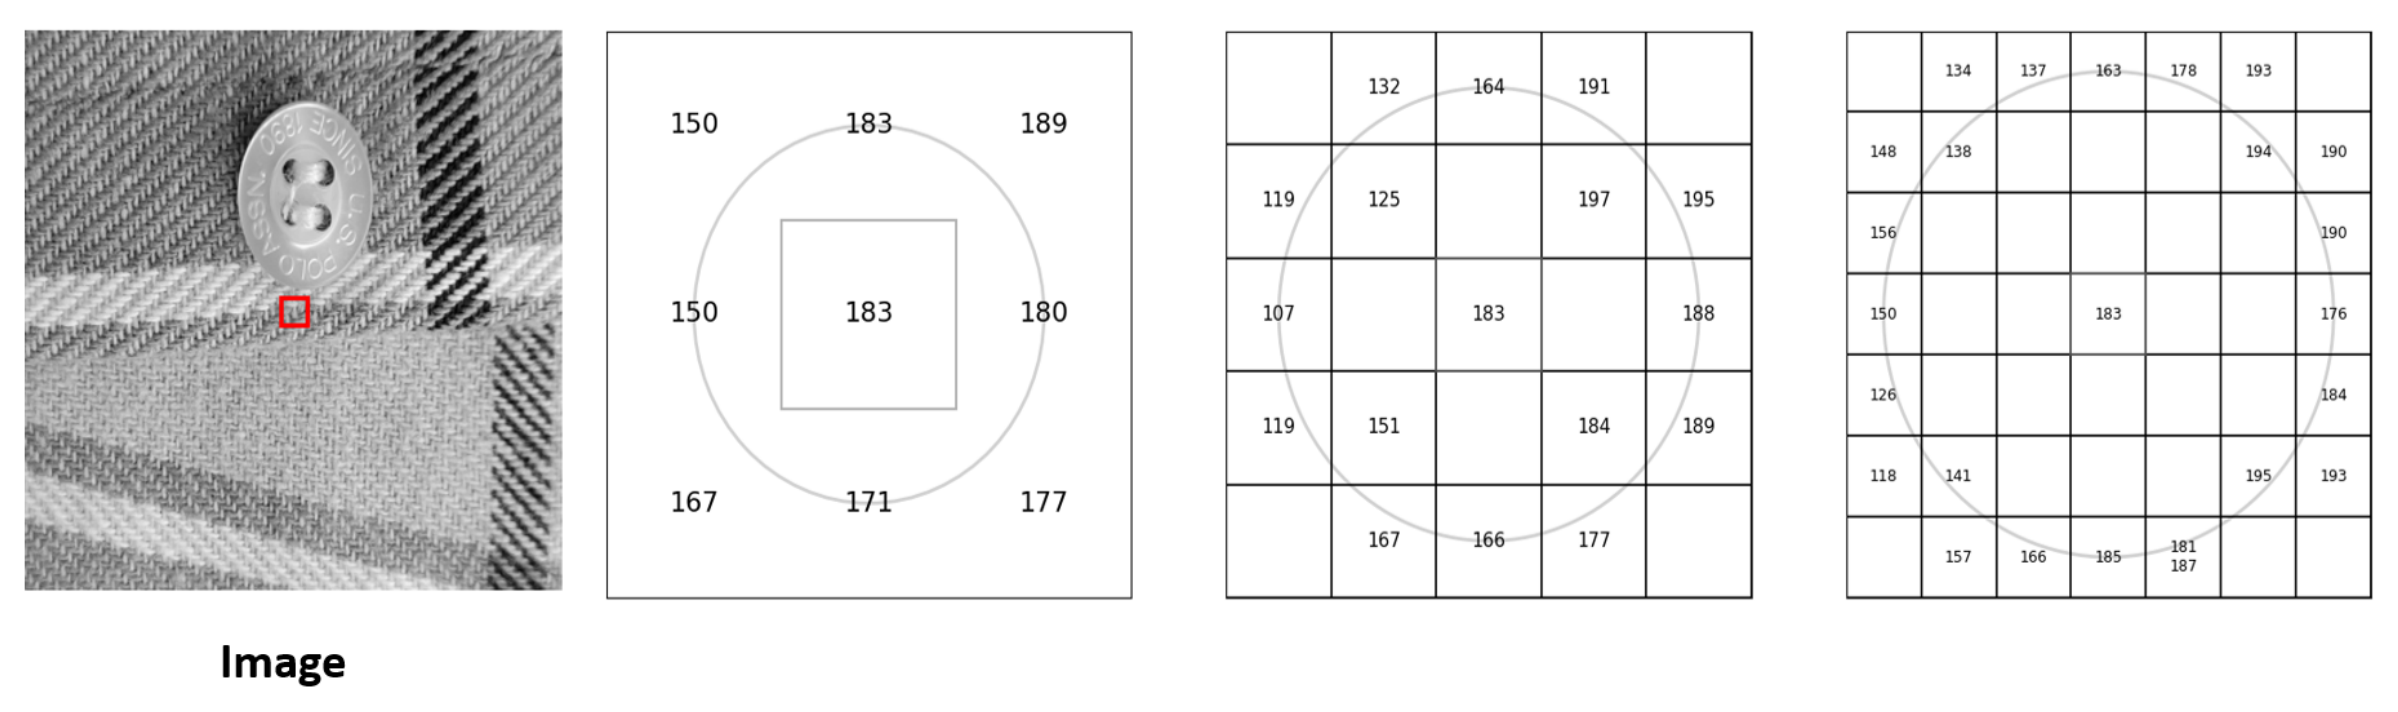
LBP labels the pixels of an image with decimal numbers which encode the local structure around each pixel, each one is compared with its eight neighbors in 3 × 3 circle by subtracting the value of the central pixel; the resulting strictly negative values are encoded with 0 and the rest with 1. By traversing the circle, a binary number is obtained concatenating all these values clockwise, starting by the upper left neighbor. The decimal value corresponding to the generated binary number is used to label the pixel, as shown in Figure 6. A local circumference is defined as a set of sampling points. Figure 7 shows LBP extended at 8, 16 and 24 [40].
Figure 6.
LBP operator, the red square indicates the reference pixel used for analysis.
Figure 7.
Circular neighborhoods (8, 1), (16, 2) and (24, 3), the red square indicates the reference pixel used for analysis.
LBP is used as a feature extraction technique for wood and textile waste images, then the mean, variance, skewness, kurtosis, entropy [41], standard deviation and energy [42] are calculated.
4.2.3. Histogram of Oriented Gradients (HOG)
HOG is a feature extraction technique that analyzes the orientation of local gradients. In a 640 × 640 pixel image, it is divided into 80 × 80 cells of 8 × 8 pixels. The image gradients are calculated using filters such as [−1, 0, 1] in X and Y, obtaining the magnitude and direction of the edge in each pixel. In each cell, a histogram is generated that counts how many gradients point in each direction; then, cells are groups into overlapping 2 × 2 blocks and histograms are normalized to reduce effects of lightning and improve robustness. All normalized histograms are concatenated to form a final HOG descriptor [43]. Then, the mean, entropy, energy and standard deviation are calculated.
4.2.4. Canny/Sobel Edge Detection
Canny: The edge detection algorithm introduced by John Canny, proposes a mathematical formula for a good performance detection, location and a single response to a single edge. Canny demonstrates that detecting an edge affected by noise can be approximated by the first derivative of Equation (7) of the Gaussian [44].
And theoretical performance of a first derivative of a Gaussian filter with the operator optimal (8).
Sobel: It is a discrete differentiation operator that calculates an approximation of the gradient of the image intensity function and allows to identify significant edges. The calculation of the probability of an edge is more reliable. Mathematically two bidimensional vectors of 3 × 3 are used whose components are given by the derivatives in the horizontal and vertical directions to detect edges in both directions [45]. The magnitude of the gradient at each pixel is estimated, Equation (9).
4.2.5. Fractal Dimension (FD)
FD have been widely used as feature in computer vision applications to characterize the roughness and self-similarity of the objects in an image. These features have been successfully adopted mainly in texture segmentation and classification. FD is a quantitative measure that shows how much space a fractal set occupies [46]. Several techniques are found in literature to estimate FD, one of them is Differential Box Counting. Its performance is influenced by numerous parameters. Particularly, the height of the box is directly related to the variations in the gray level on the image grid [47]. The standard formula to calculate FD of an ideal bounded fractal set is expressed by the Equation (10).
where, is the number of distinct cells of scale r required to cover B. If B is not an ideal fractal set, the equation will give different values of FD for different values of r. In that case, the slope of the line obtained by fitting the points is known as the FD of the non-ideal fractal set. Canny’s method in combination with FD was used for an efficient system of pathological brains detection based on AI; demonstrating that edges can be extracted more efficiently without removing significant textures [48].
4.3. Feature Integration
Prior to feature extraction, all images were resized to a resolution of 640 × 640 pixels. Subsequently, each extraction method performed a grayscale conversion to ensure consistency in intensity-based descriptors and to reduce computational complexity.
The parameters used for each technique were as follows: LBP was configured with uniform patterns, a radius (), and () neighbors. GLCM was calculated using distances of 1, 2, and 3 pixels, with orientations of , , , and . HOG was set with 9 orientations, a cell size of pixels, and blocks, with each image scaled to the range.
The FD was estimated using the Differential Box Counting (DBC) method, with multi-resolution scales automatically defined as powers of two based on the image size. Additionally, a second fractal measure was calculated on edge maps obtained with the Canny detector (50, 150) to capture the structural complexity of the contours. For the Canny detector, a prior Gaussian blur with a kernel was used, along with thresholds of 50 and 150. For Sobel, a kernel size of 3 was employed to capture relevant gradients and contours.
Regarding normalization, some descriptors incorporate implicit mechanisms inherent to their formulation. Specifically, LBP is based on relative frequency histograms; GLCM utilizes normalized co-occurrence matrices in probabilistic terms; and HOG incorporates an internal L2-Hys normalization [43], which enhances robustness against contrast variations. In the case of Canny/Sobel edge detection and FD, although there is no explicit internal normalization in their formulation, indirect normalization mechanisms are incorporated, such as normalization by pixel count, the use of weighted histograms, or intensity quantization.
Subsequently, the generated files were integrated into a single dataset through an alignment process based on the image name. This allowed for the correct association of features from each technique into a single CSV file with 25 features per image (Figure 8). The final set is the result of concatenating the individual descriptors. Each classical technique incorporates its own properties, allowing for a more comprehensive and discriminative representation of the visual content (Table 3).
Figure 8.
Feature integration.
Table 3.
Description of the features extracted for texture analysis.
4.4. Feature Selection
RF is a combination of tree features, so that each tree depends on the values of a randomly selected vector in an independent way and with the same distribution for all trees in the forest. Generalization error of forests converges to a limit as the number of trees in the forest increases. Internal estimates monitor the error, strength, correlation and are used to show the response to increasing the number of features used in the division. Internal estimates are also used to measure the importance of the variables [49].
To assess the influence of the variables included in the dataset, methods such as Gini index, crossed entropy or exchange are used [50]. For the importance of features, exchange of a feature is calculated as the average decrease in model accuracy in out-of-bag data samples when values of the respective feature are randomly exchanged and Gini uses decrease in Gini index (impurity) after a node division as a measure of the relevance of the feature [51].
An analysis was implemented to experimentally validate the final feature subset selected through Random Forest Importance. To this end, the integrated feature file was automatically cleaned, and a stratified split was performed with 80% for training and 20% for testing. The RF model was trained with 300 trees to estimate both Gini and permutation importance solely on the training set. Several feature subsets were constructed, and their performance was compared using cross-validation (Table 4).
Table 4.
Different feature subsets.
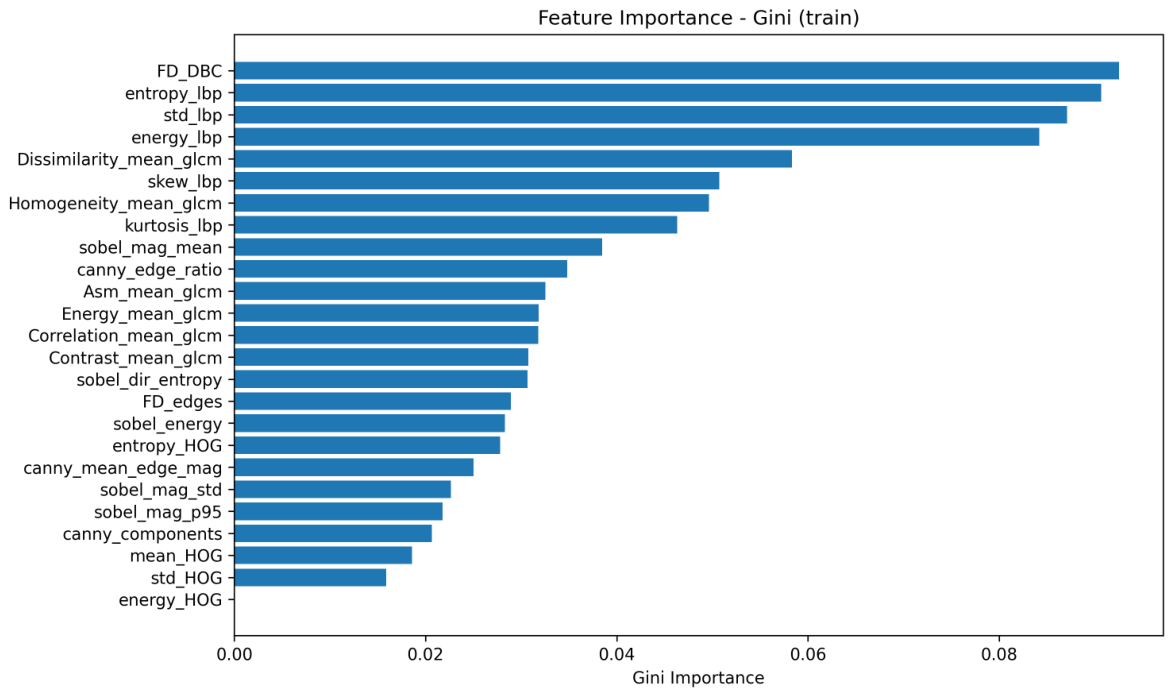
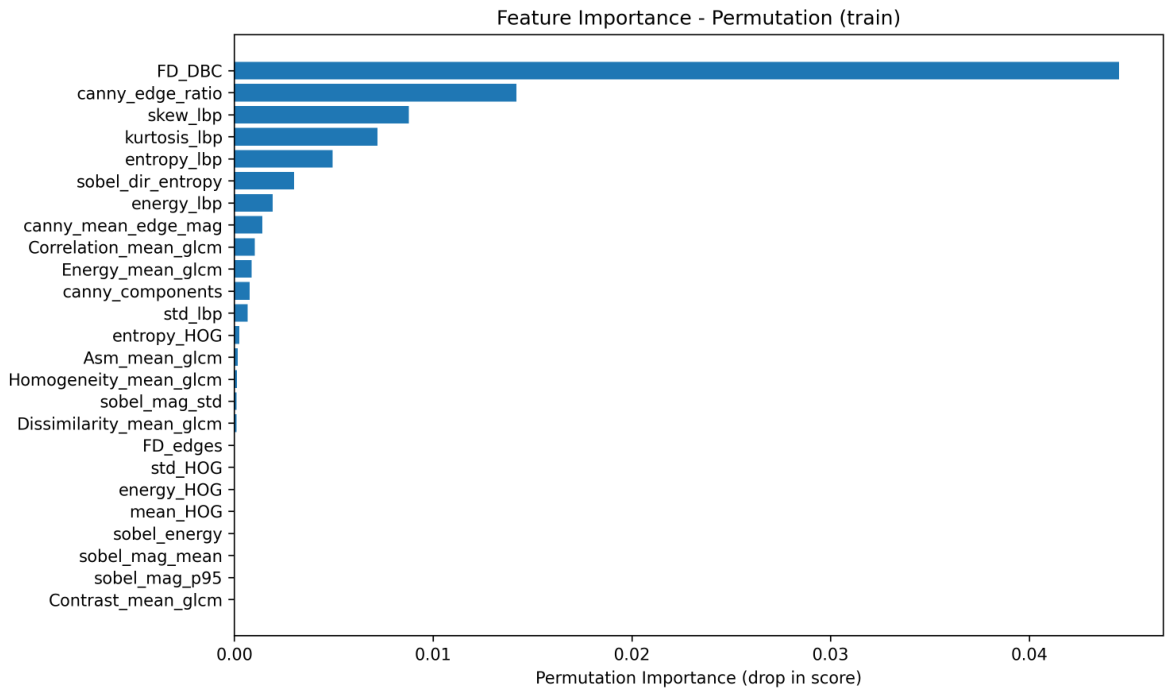
Gini importance indicates that the features with the highest relevance are FD_DBC, entropy_lbp, std_lbp, energy_lbp, and Dissimilarity_mean_glcm, with the top five ranked in ascending order as shown in Figure 9. Permutation importance indicates that the most representative variables are FD_DBC, canny_edge_ratio, skew_lbp, kurtosis_lbp, and entropy_lbp, as illustrated in Figure 10.
Figure 9.
Importance of characteristics using the Gini index.
Figure 10.
Importance of features through permutation.
The Selected_16 subset achieved the best performance, with a precision of 96.59% and a mean cross-validation accuracy of 96.73%, slightly outperforming the full set of 25 variables (96.14% accuracy and 96.67% cross-validation). This result indicates that removing redundant or uninformative variables reduces dimensionality and, by excluding them, enhances the model’s generalization capability. Furthermore, the Top_16_rank subset, obtained through automatic ranking, showed slightly lower performance compared to the Selected_16 subset. On the other hand, excluding the LBP-derived variables led to a significant drop in performance (94.55%), confirming that these features constitute the system’s most discriminative component. In contrast, the exclusion of fractal dimension variables resulted in a smaller decrease (96.25%), indicating that FD provides complementary structural information, although it does not act effectively in isolation.
Similarly, the reduced LBP+FD and Top-5 subsets showed notable performance losses, confirming their limited discriminative capacity when used independently. Taken together, these results demonstrate that the final subset of 16 features represents an optimal balance between relevance, complementarity, and dimensionality reduction, as shown in Table 5.
Table 5.
Comparison of the performance of feature subsets.
Experimental analysis validates that the Selected_16 feature subset constitutes an optimal representation, maximizing performance with lower dimensionality. This behavior provides evidence that variables with lower importance can provide complementary information that enhances the model’s overall performance. Consequently, the Selected_16 subset represents a proper balance between relevance, descriptive diversity, and generalization capability, validating its selection from both a statistical and structural standpoint.
4.5. Validation Metrics
For the evaluation of AI models, there are different key metrics to assess performance such as: Accuracy, Precision, Recall and F1-Score. These metrics have capability to capture different dimensions of performance [52]:
Accuracy (11): This is a control or baseline metric to highlight limitations of naive evaluation in presence of Imbalance.
Precision (12): Precision quantifies the proportion of positive predictions that are correct.
Recall (13): It is the percentage of real positive cases that the specific model correctly Identifies.
F1-Score (14): It is the harmonic mean of accuracy and recovery, balancing the balance between both.
4.6. Model Training
The training of the ML models was conducted through the stages of feature selection, hyperparameter tuning, and evaluation. First, the dataset was divided using a stratified split into 80% for training and 20% for testing, ensuring that the class distribution was maintained. Using the subset of 16 features obtained via Random Forest Importance, the SVM, RF, and MLP models were trained.
Hyperparameter tuning for each model was performed using a grid search (GridSearchCV) [53], combined with a seven-fold stratified cross-validation applied exclusively to the training set. This procedure allowed for the selection of the optimal parameter configuration without involving the test set. Once the best hyperparameters were identified, the final models were fitted using the complete training set. The test set was strictly reserved for final performance evaluation, including metrics such as accuracy, confusion matrix, and log-loss. Additionally, learning curves were generated using only the training set to analyze the models’ stability and generalization capability without introducing bias.
This experimental framework aims to eliminate data leakage across the different process phases, providing an unbiased estimation of model performance and strengthening the validity of the results, as shown in the following section.
4.6.1. Support Vector Machine (SVM)
SVMs are an algorithm that maximizes the margin between training patterns, the decision boundary [54]. They can handle both simple and linear classification tasks as well as complex ones, that is, they handle both separable and non-separable problems. The idea of SVMs is to map the original data points of the input space to a high-dimensional or even infinite-dimensional, feature space, so that classification problem will be simpler in that space [55].
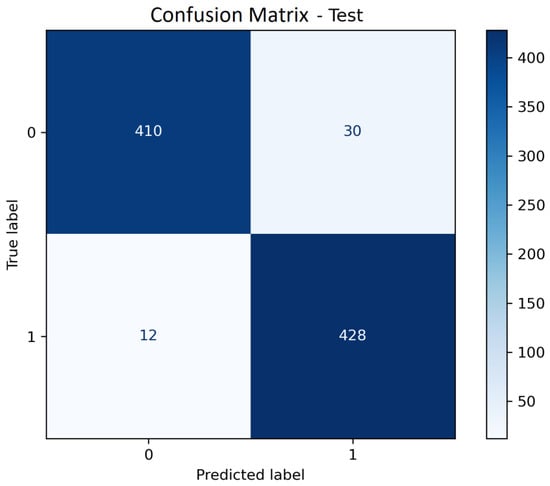
Confusion matrix generated with sample data shows that 410 textile pictures (class: 0) are correctly separated and confusion exists in only 30. Wood class (class: 1) shows confusion in 12 and 428 are correctly separated, as shown in Figure 11.
Figure 11.
Confusion matrix of the SVM model.
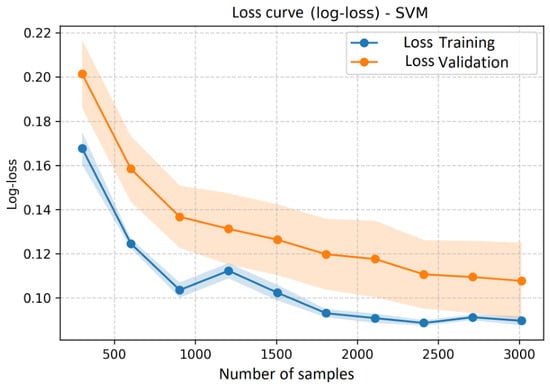
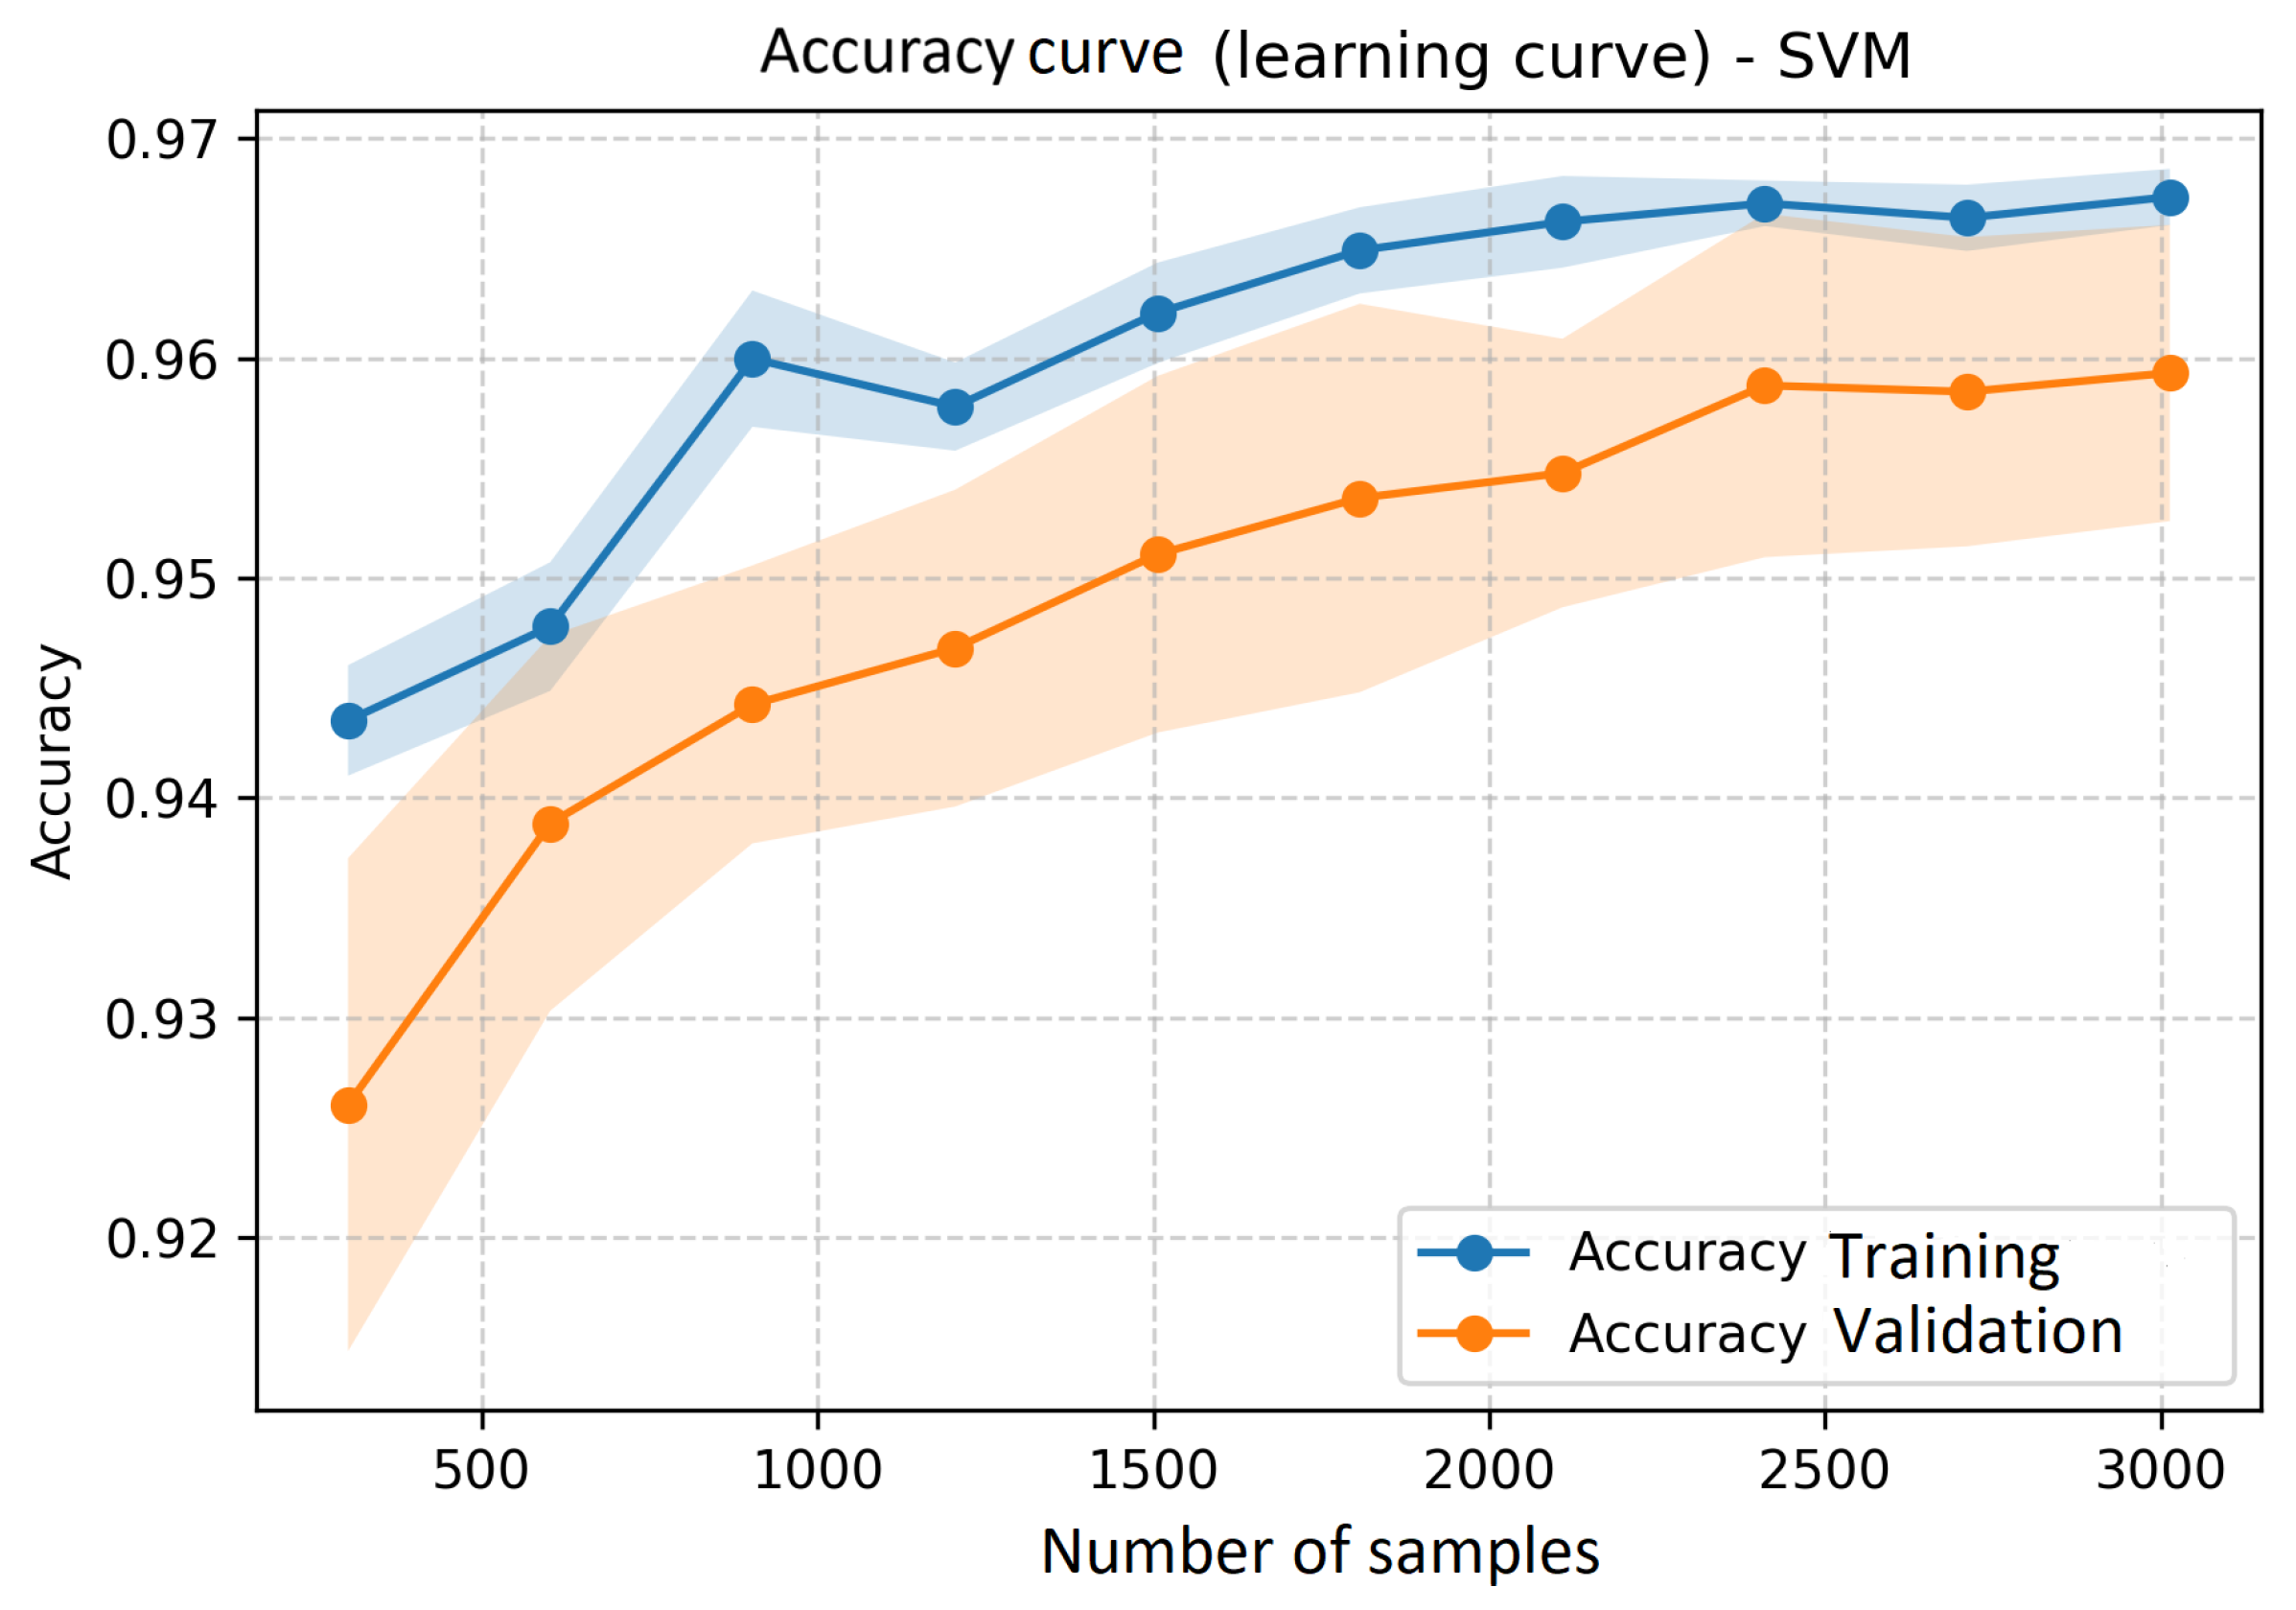
Regarding the behavior of the loss and precision curves, in the first one, both lines fall as the number of samples increases; which is interpreted as the model generalizes well (Figure 12). Precision line grows as data increases, difference between both is small, which shows stability (Figure 13).
Figure 12.
Analysis of the loss function for the SVM model during training: loss graph.
Figure 13.
Analysis of the accuracy function for the SVM model during training: accuracy graph.
Table 6 contains numerical values of the trained model metrics.
Table 6.
SVM model results (kernel RBF).
4.6.2. Random Forests (RF)
RF is an ML technique that is also used to predict generation of waste. This algorithm combines multiple decision trees to create a powerful predictive model. By training RF model with CSV file that contains patterns of waste and significant features, complex relationships are obtained and forecasts are provide [56].
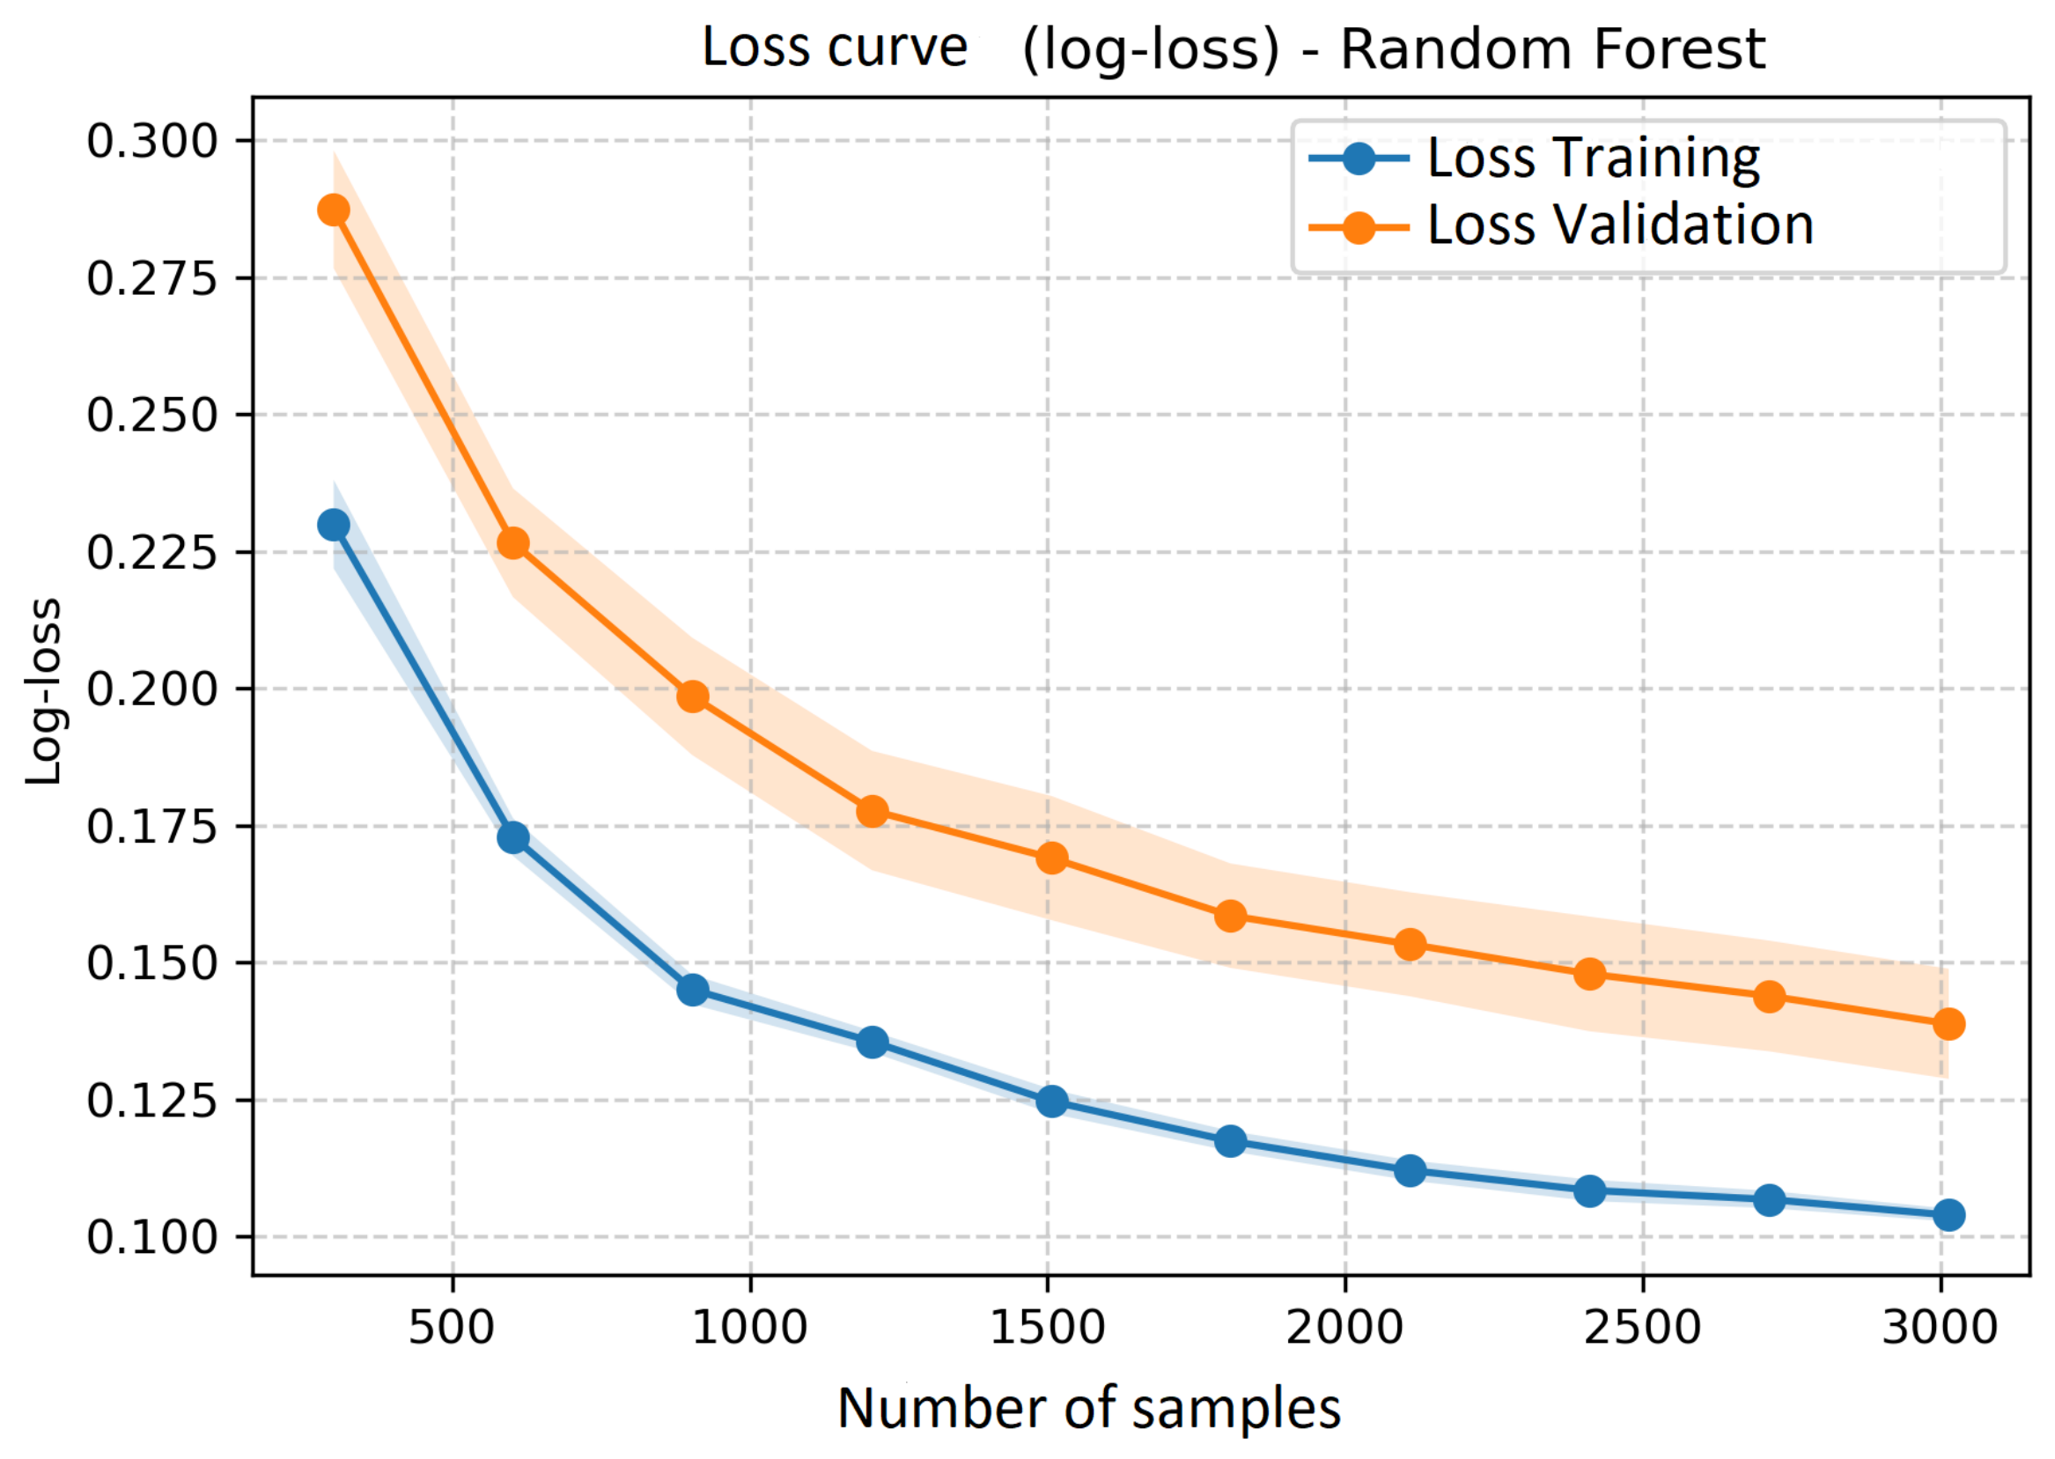
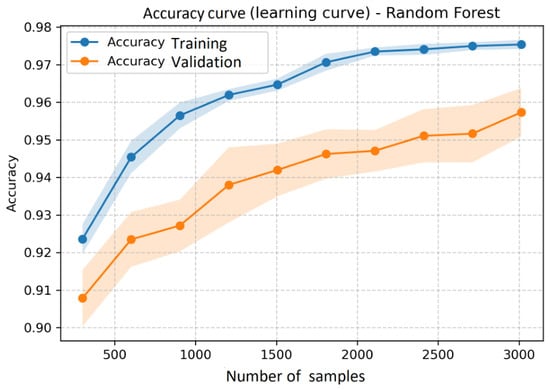
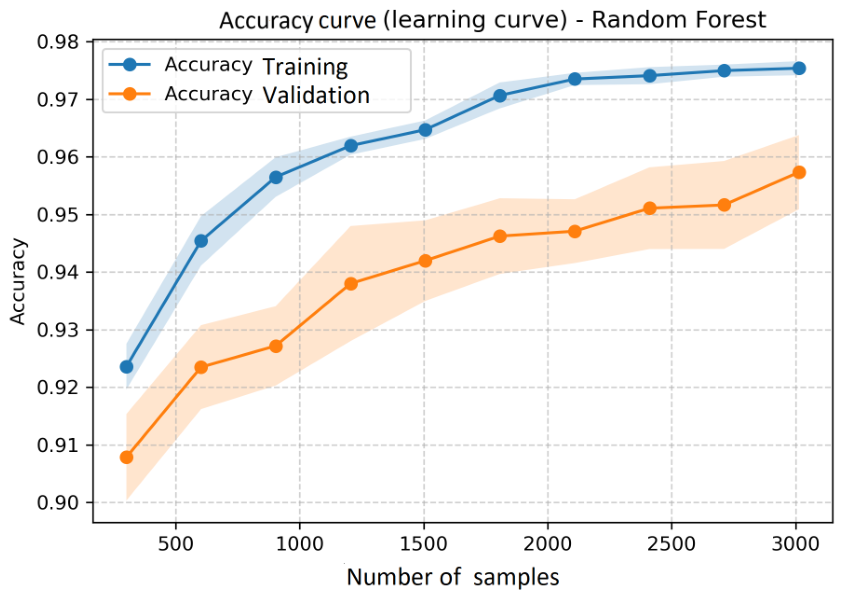
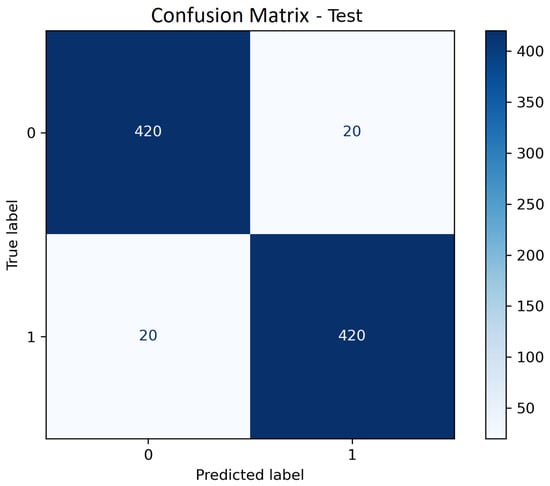
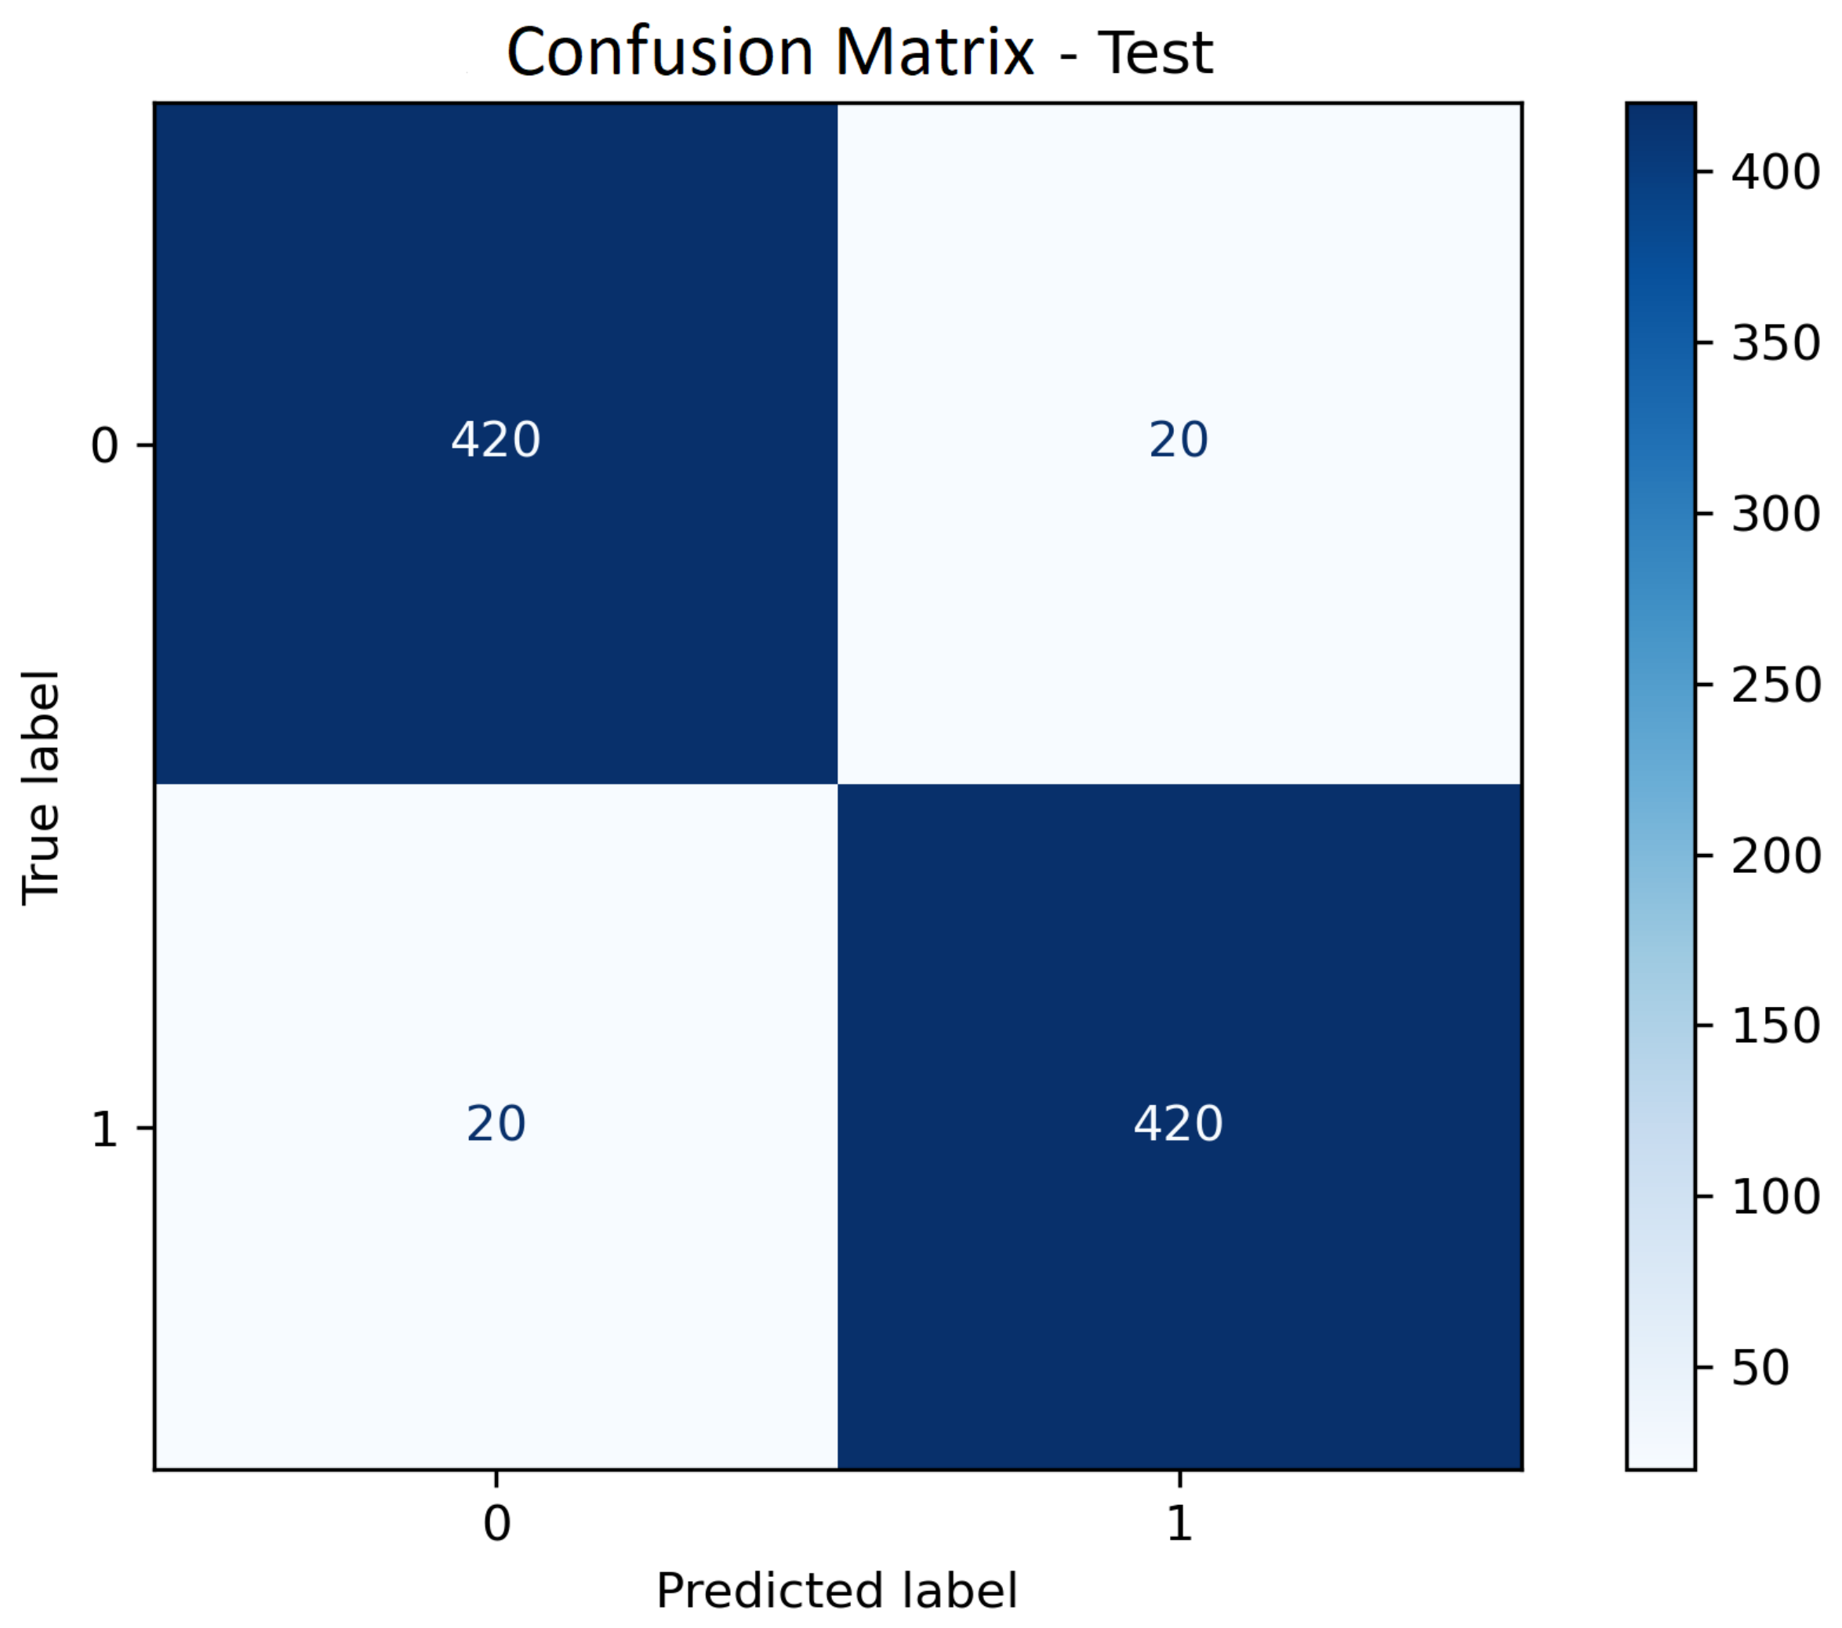
The training behavior shows that the loss curve is constant, with only some differences from the test line (Figure 14). In terms of accuracy, both lines show a constant increase, difference in behavior is small, which implies that there is no overfitting (Figure 15). Furthermore, confusion matrix shows that test values of both classes, have 20 errors equally (Figure 16).
Figure 14.
Analysis of the loss function for the RF model during training: loss graph.
Figure 15.
Analysis of the accuracy function for the RF model during training: accuracy graph.
Figure 16.
Confusion matrix of the RF model.
Table 7 contains numerical values of the trained model metrics.
Table 7.
Random Forest model results.
4.6.3. Multilayer Perceptron (MLP)
MLP is an ANN inspired by the behavior of the nervous system of higher organisms, based on the processing of artificial neurons with the purpose of solving problems such as pattern classification, data mining, regression/approximation of functions and information processing [57]. This algorithm is used to automatically classify waste [58].
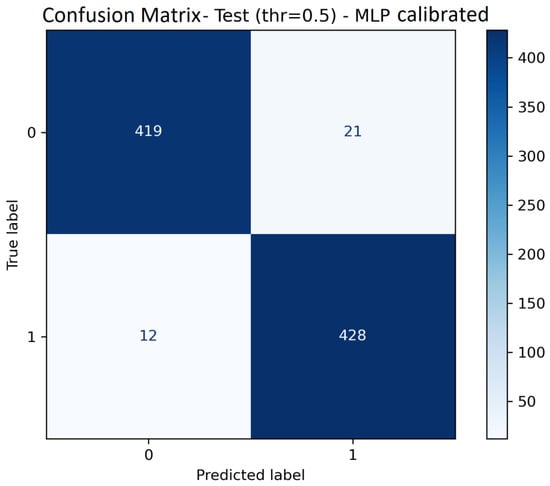
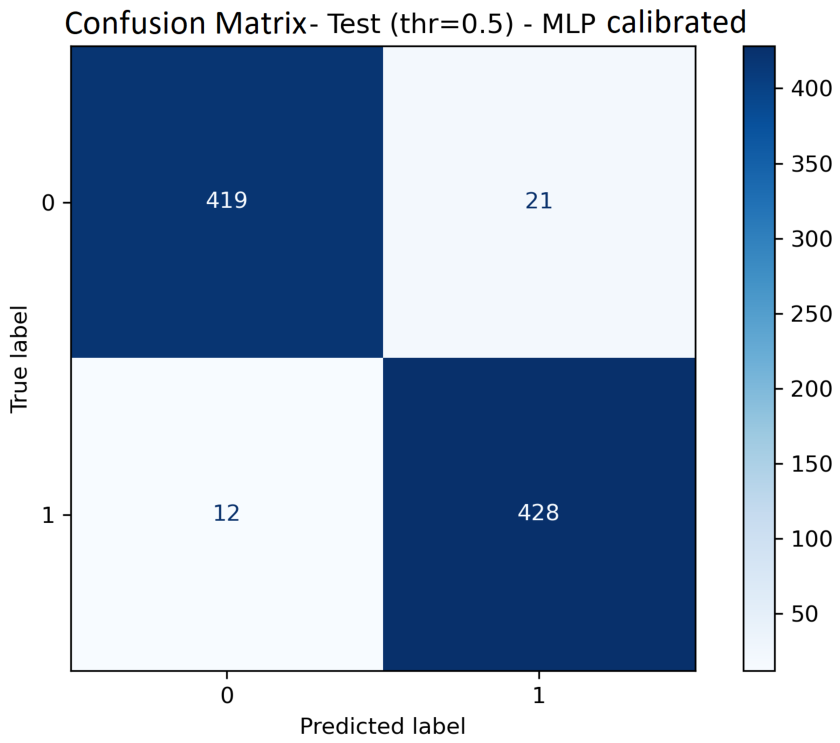
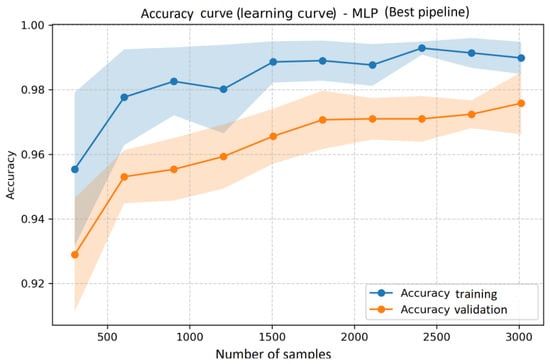
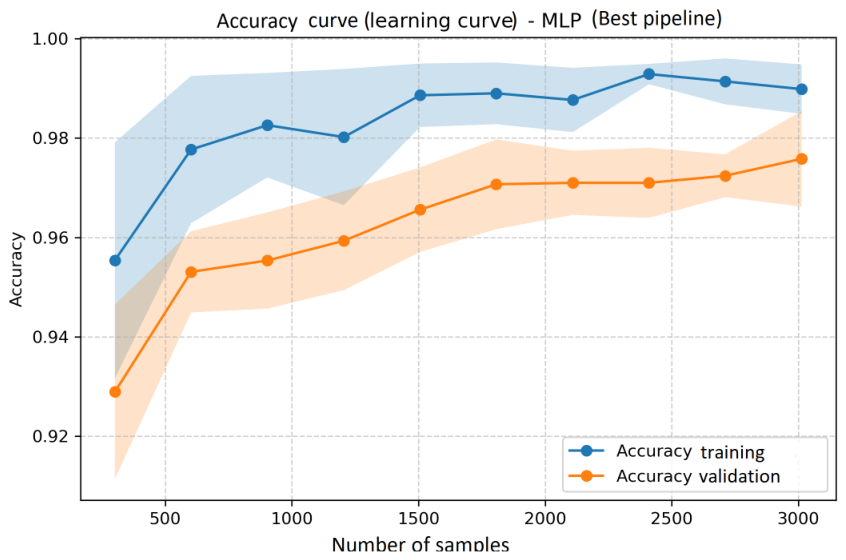
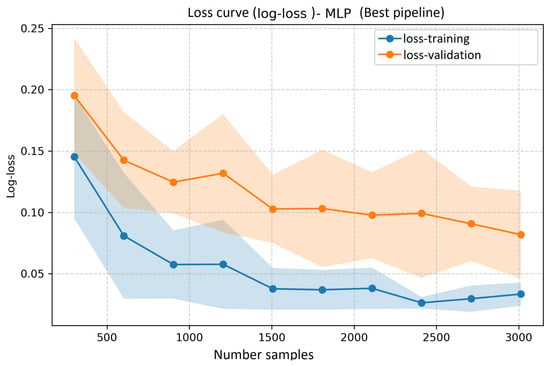
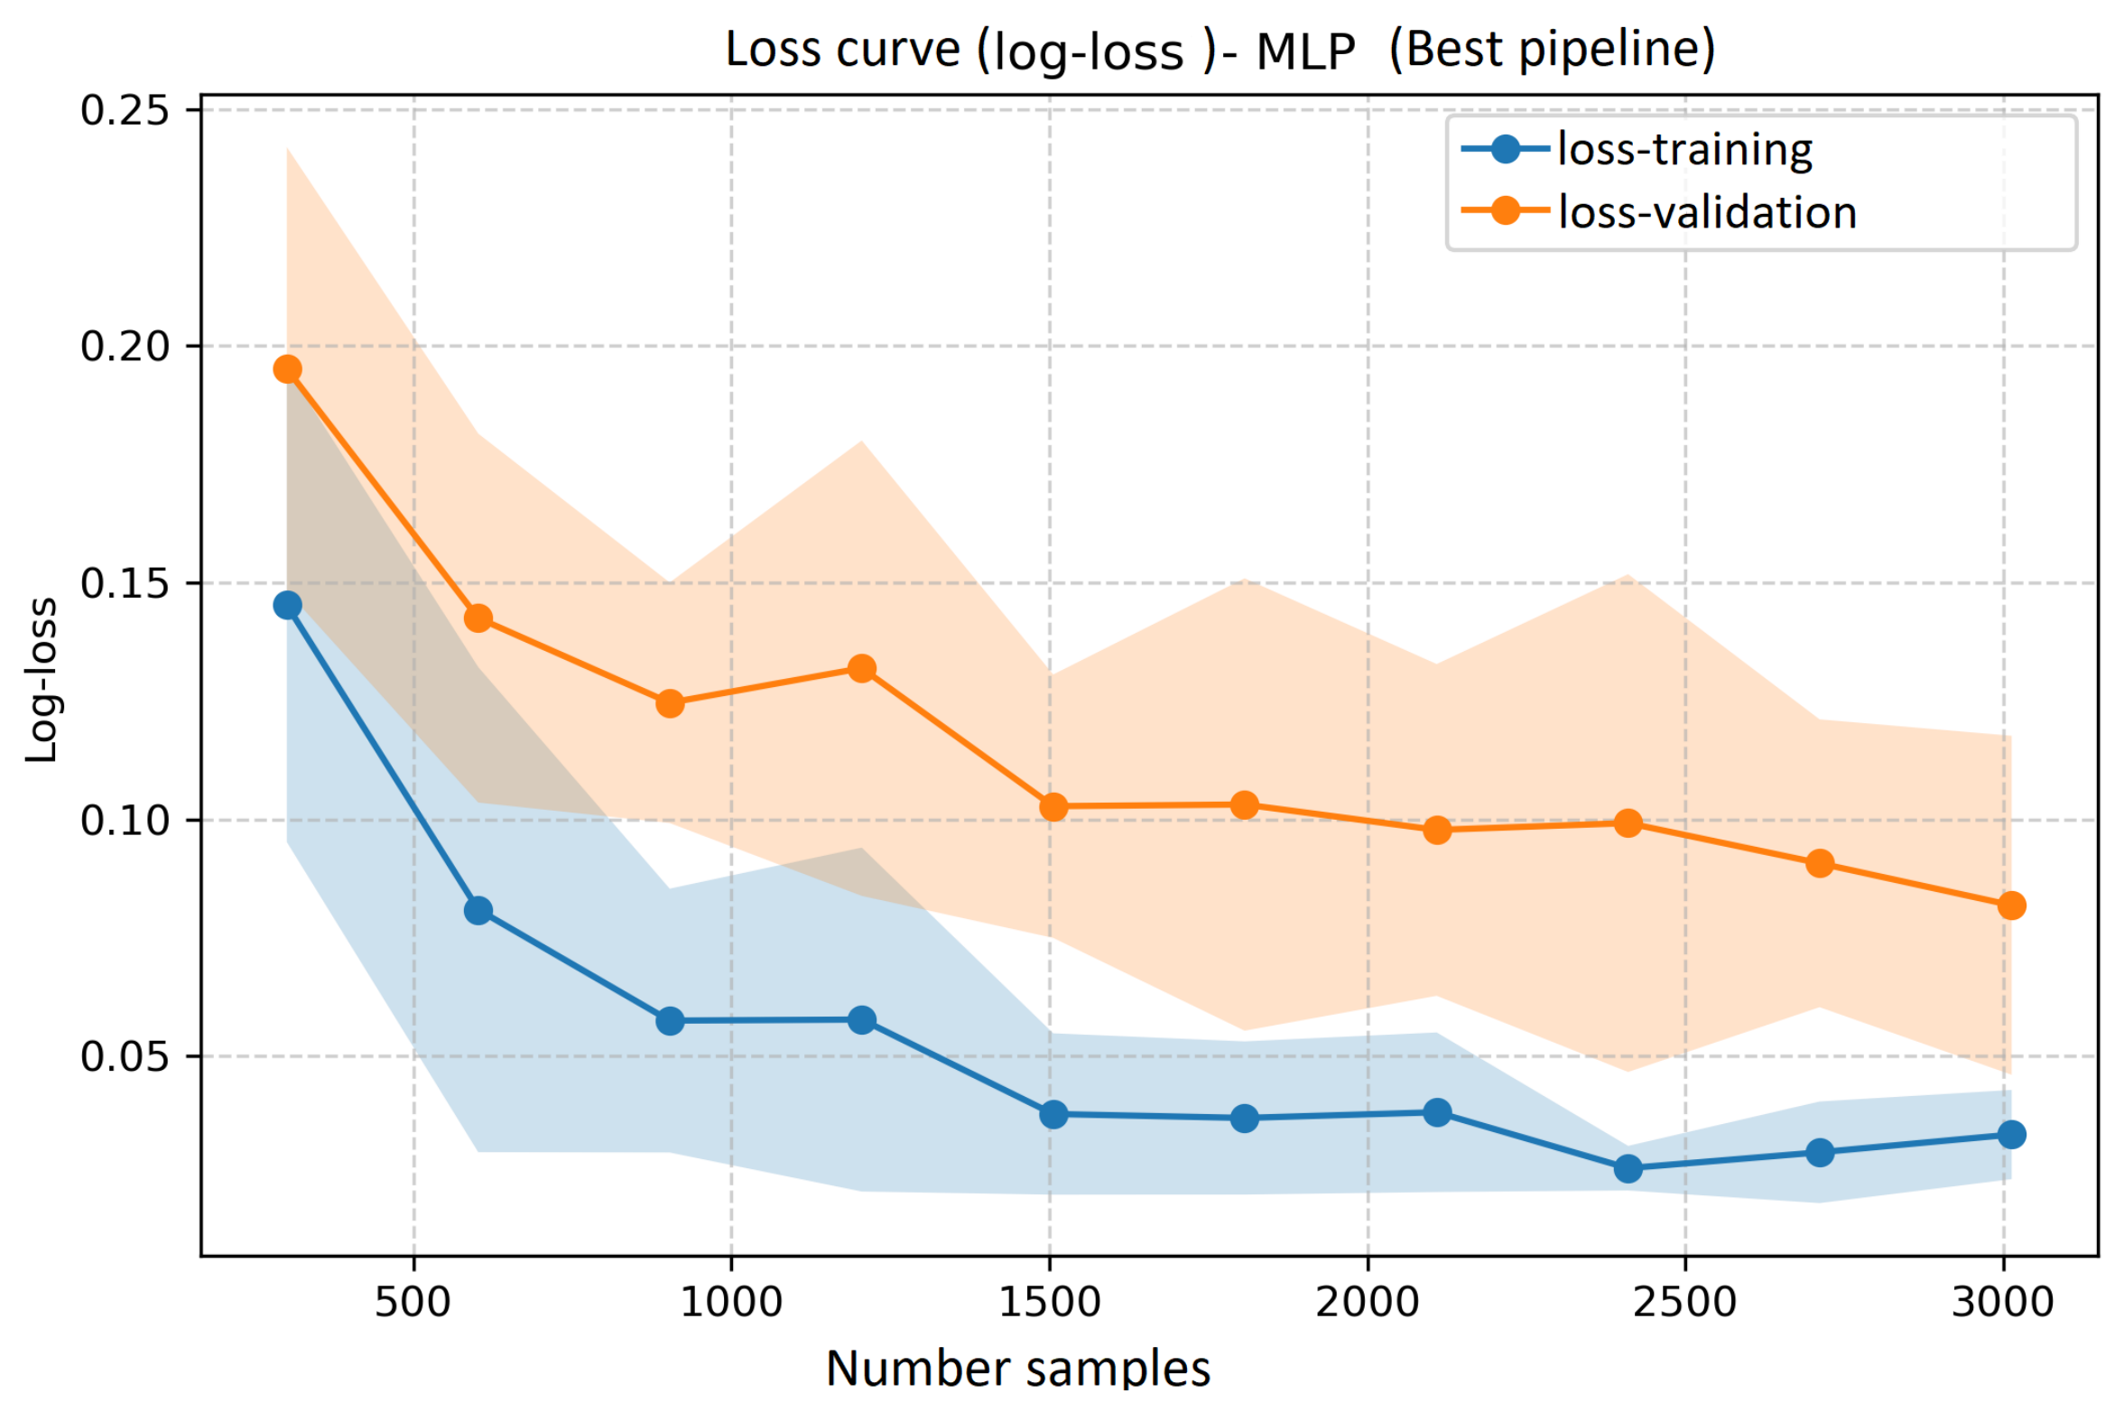
Confusion matrix shows that out of 440 images, only 419 from textile class (class: 0) were correctly classified, while for wood (class: 1) only 21 were not correctly classified, this indicates a balance in the classification of classes (Figure 17). With a training of up to 3000 samples, the behavior of the accuracy curve with the training and sample values shows balanced training (Figure 18). Similarly, the loss lines decrease progressively, which corroborates that class classification is reliable (Figure 19).
Figure 17.
Confusion matrix of the MLP model.
Figure 18.
Analysis of the accuracy function for the MLP model during training: accuracy graph.
Figure 19.
Analysis of the loss function for the MLP model during training: loss graph.
In addition to the evaluation using the default threshold (0.5), a complementary analysis was performed by selecting an optimal decision threshold based on the F1-score via the precision-recall curve. This resulted in an optimal threshold of 0.6095, as shown in Table 8. It is important to emphasize that this threshold was obtained using the predicted probabilities on the test set as a post hoc analysis; it was not used during model training, hyperparameter tuning, or probability calibration. Therefore, the results corresponding to the default threshold (0.5) represent the primary evaluation of the model, while the optimized threshold provides additional insights into the classifier’s behavior under alternative decision criteria.
Table 8.
Results of the calibrated MLP model.
5. Conclusions
The experimentation conducted, which compared ML models (SVM, RF, and MLP) using the dataset of statistical values derived from texture feature extraction techniques (GLCM, LBP, HOG, FD, and Canny/Sobel edges) demonstrated that the MLP algorithm achieved the best performance. The values assigned to the hyperparameters allowed for the effective modeling of non-linear relationships between the texture features, reaching an accuracy of 96.70% and an AUC of 99.56%.
This study demonstrates that combining classical texture techniques with ML models achieves high performance in the binary classification of MSW into wood and textile classes under controlled conditions. However, the findings must be interpreted within the experimental scope of the study; thus, the proposed methodology is presented as a baseline for future research rather than a directly applicable solution for real-world environments.
As future work, it is proposed to expand the dataset by incorporating more realistic conditions, including background variability and scenes with mixed materials. Additionally, incorporating detection or segmentation stages using CNN-based approaches prior to classification could improve system capability by isolating relevant regions of interest.
This hybrid approach could contribute to narrowing the gap between controlled experimental environments and real-world scenarios. The results confirm that texture analysis remains as a powerful tool for material classification; however, its effectiveness in real applications depends on its adaptability to variable environmental conditions and complex scenarios, aiming to advance toward the development of technological tools applicable in real contexts for MSW management.
Author Contributions
Conceptualization, J.V.T., W.C.F., J.J.C.V. and A.B.O.; Methodology, J.V.T. and J.J.C.V.; Software, J.V.T., W.C.F. and J.J.C.V.; Validation, B.D.V.R., E.R.T. and A.B.O.; Formal analysis, B.D.V.R., E.R.T. and A.B.O.; Investigation, J.V.T. and J.J.C.V.; Data curation, J.J.C.V.; Writing—original draft, J.V.T., W.C.F. and J.J.C.V.; Writing—review & editing, J.V.T., W.C.F. and J.J.C.V.; Visualization, B.D.V.R.; Supervision, E.R.T., B.D.V.R. and A.B.O.; Project administration, E.R.T. All authors have read and agreed to the published version of the manuscript.
Funding
This research received no external funding.
Institutional Review Board Statement
Not applicable.
Informed Consent Statement
Not applicable.
Data Availability Statement
Dataset available on request from the authors.
Conflicts of Interest
The authors declare no conflicts of interest.
References
- Kaza, S.; Yao, L.; Bhada-Tata, P.; Van Woerden, F. What a Waste 2.0: A Global Snapshot of Solid Waste Management to 2050; World Bank Publications: Washington, DC, USA, 2018. [Google Scholar]
- Salem, K.S.; Clayson, K.; Salas, M.; Haque, N.; Rao, R.; Agate, S.; Singh, A.; Levis, J.W.; Mittal, A.; Yarbrough, J.M.; et al. A critical review of existing and emerging technologies and systems to optimize solid waste management for feedstocks and energy conversion. Matter 2023, 6, 3348–3377. [Google Scholar] [CrossRef] [Scilit]
- INEGI. Estadísticas a Propósito del Día Mundial del Medio Ambiente (5 de Junio): Datos Nacionales; Technical Report; Instituto Nacional de Estadística y Geografía: Aguascalientes, México, 2025.
- ONU México. Objetivos de Desarrollo Sostenible. 2025. Available online: https://mexico.un.org/es/sdgs (accessed on 22 November 2025).
- SEMARNAT. Secretaría de Medio Ambiente y Recursos Naturales, Residuos Sólidos Urbanos (RSU). 2017. Available online: https://www.gob.mx/semarnat/acciones-y-programas/residuos-solidos-urbanos-rsu (accessed on 22 November 2025).
- Jahan, I.; Zhang, G.; Bhuiyan, M.; Navaratnam, S. Circular Economy of Construction and Demolition Wood Waste—A Theoretical Framework Approach. Sustainability 2022, 14, 10478. [Google Scholar] [CrossRef] [Scilit]
- Vercalsteren, A.; Nicolau, M.; Lafond, E. Textiles and the Environment in a Circular Economy; ETC/WMGE: Copenhagen, Denmark, 2019. [Google Scholar]
- Secretaría de Medio Ambiente y Recursos Naturales (SEMARNAT). Diagnóstico Básico para la Gestión Integral de los Residuos. 2020. Available online: https://www.gob.mx/cms/uploads/attachment/file/554385/DBGIR-15-mayo-2020.pdf (accessed on 22 November 2025).
- Liang, S.; Gu, Y. A deep convolutional neural network to simultaneously localize and recognize waste types in images. Waste Manag. 2021, 126, 247–257. [Google Scholar] [CrossRef] [Scilit]
- Ramos, E.; Lopes, A.G.; Mendonça, F. Application of Machine Learning in Plastic Waste Detection and Classification: A Systematic Review. Processes 2024, 12, 1632. [Google Scholar] [CrossRef] [Scilit]
- Zhou, Y.; Wang, Z.; Zheng, S.; Zhou, L.; Dai, L.; Luo, H.; Zhang, Z.; Sui, M. Optimization of automated garbage recognition model based on ResNet-50 and weakly supervised CNN for sustainable urban development. Alex. Eng. J. 2024, 108, 415–427. [Google Scholar] [CrossRef] [Scilit]
- Fotovvatikhah, F.; Ahmedy, I.; Noor, R.M.; Munir, M.U. A Systematic Review of AI-Based Techniques for Automated Waste Classification. Sensors 2025, 25, 3181. [Google Scholar] [CrossRef] [Scilit]
- Merino, I.; Azpiazu, J.; Remazeilles, A.; Sierra, B. Histogram-Based Descriptor Subset Selection for Visual Recognition of Industrial Parts. Appl. Sci. 2020, 10, 3701. [Google Scholar] [CrossRef] [Scilit]
- Dao, S.V.; Le, T.M.; Tran, H.M.; Pham, H.V.; Vu, M.T.; Chu, T. Integrating artificial intelligence for sustainable waste management: Insights from machine learning and deep learning. Watershed Ecol. Environ. 2025, 7, 353–382. [Google Scholar] [CrossRef] [Scilit]
- Zhong, S.; Zhang, K.; Bagheri, M.; Burken, J.G.; Gu, A.; Li, B.; Ma, X.; Marrone, B.L.; Ren, Z.J.; Schrier, J.; et al. Machine Learning: New Ideas and Tools in Environmental Science and Engineering. Environ. Sci. Technol. 2021, 55, 12741–12754. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Abdallah, M.; Abu Talib, M.; Feroz, S.; Nasir, Q.; Abdalla, H.; Mahfood, B. Artificial intelligence applications in solid waste management: A systematic research review. Waste Manag. 2020, 109, 231–246. [Google Scholar] [CrossRef] [Scilit]
- Zoumpoulis, P.; Konstantinidis, F.K.; Tsimiklis, G.; Amditis, A. Smart bins for enhanced resource recovery and sustainable urban waste practices in smart cities: A systematic literature review. Cities 2024, 152, 105150. [Google Scholar] [CrossRef] [Scilit]
- Castro-Bello, M.; Romero-Juárez, V.M.; Fuentes-Pacheco, J.; Morales-Morales, C.; Marmolejo-Vega, C.V.; Zagal-Barrera, S.R.; Gutiérrez-Valencia, D.E.; Marmolejo-Duarte, C. R3sNet: Optimized Residual Neural Network Architecture for the Classification of Urban Solid Waste via Images. Sustainability 2025, 17, 3502. [Google Scholar] [CrossRef] [Scilit]
- Castro-Bello, M.; Roman-Padilla, D.B.; Morales-Morales, C.; Campos-Francisco, W.; Marmolejo-Vega, C.V.; Marmolejo-Duarte, C.; Evangelista-Alcocer, Y.; Gutiérrez-Valencia, D.E. Convolutional Neural Network Models in Municipal Solid Waste Classification: Towards Sustainable Management. Sustainability 2025, 17, 3523. [Google Scholar] [CrossRef] [Scilit]
- Shafek, D.; Hilow, H.W.; Ahmed, M. Clasificación de imágenes de residuos mediante aprendizaje profundo. J. Appl. Res. Technol. 2025, 23, 381–391. [Google Scholar] [CrossRef] [Scilit]
- Ayeleru, O.; Fajimi, L.; Oboirien, B.; Olubambi, P. Forecasting municipal solid waste quantity using artificial neural network and supported vector machine techniques: A case study of Johannesburg, South Africa. J. Clean. Prod. 2021, 289, 125671. [Google Scholar] [CrossRef] [Scilit]
- Rahman, A.; Marufuzzaman, M.; Street, J.; Wang, H.; Gude, V.G.; Buchanan, R. Robust Cross-Domain Adaptation in Texture Features Transferring for Wood Chip Moisture Content Prediction. arXiv 2025, arXiv:2510.16832. [Google Scholar] [CrossRef] [Scilit]
- Seckin, M.; Seckin, A.C.; Demircioglu, P.; Bogrekci, I. FabricNET: A Microscopic Image Dataset of Woven Fabrics for Predicting Texture and Weaving Parameters through Machine Learning. Sustainability 2023, 15, 15197. [Google Scholar] [CrossRef] [Scilit]
- Cheng, T.; Kojima, D.; Hu, H.; Onoda, H.; Pandyaswargo, A.H. Optimizing Waste Sorting for Sustainability: An AI-Powered Robotic Solution for Beverage Container Recycling. Sustainability 2024, 16, 10155. [Google Scholar] [CrossRef] [Scilit]
- Yang, Y.; Luo, Y.; Yang, Y.; Kang, S. Dynamic Graph Neural Network for Garbage Classification Based on Multimodal Feature Fusion. Appl. Sci. 2025, 15, 7688. [Google Scholar] [CrossRef] [Scilit]
- González, S.G.; García, D.C.; Pérez, R.H.; Sanchez, A.A.; González, G.V. Autonomous Waste Classification Using Multi-Agent Systems and Blockchain: A Low-Cost Intelligent Approach. Sensors 2025, 25, 44364. [Google Scholar] [CrossRef] [Scilit]
- Sumsion, G.R.; Bradshaw, M.S.; Hill, K.T.; Pinto, L.D.G.; Piccolo, S.R. Remote sensing tree classification with a multilayer perceptron. PeerJ 2019, 7, e6101. [Google Scholar] [CrossRef] [Scilit]
- Kodytek, P.; Bodzas, A.; Bilik, P. A large-scale image dataset of wood surface defects for automated vision-based quality control processes [version 2; peer review: 2 approved]. F1000Research 2022, 10, 581. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Neamah, O.N. Fabric Defects Object Detection Dataset. Dataset, Versión 2. 2024. Available online: https://figshare.com/articles/dataset/FD_Dataset_7z/25546465/2 (accessed on 2 October 2025).
- Shakir, S.; Topal, C. Ten Fabrics Dataset (TFD). 2022. Available online: https://www.kaggle.com/datasets/saharshakir/ten-fabrics-dataset-tfd (accessed on 7 October 2025).
- Gil-Arroyo, B.; Sanz, J.M.; Arroyo, Á.; Urda, D.; Basurto, N.; Herrero, Á. Dataset for defect detection in textile manufacturing. Data Brief 2025, 59, 111451. [Google Scholar] [CrossRef] [Scilit] [PubMed]
- Sumaya; Islam, F.; Monir, M.F.; Islam, A. FabricSpotDefect: An Annotated Dataset for Identifying Spot Defects in Different Fabric Types. 2024. Available online: https://data.mendeley.com/datasets/6574nhzm8x/1 (accessed on 17 October 2025).
- Mirhashemi, A. Introducing spectral moment features in analyzing the SpecTex hyperspectral texture database. Mach. Vis. Appl. 2018, 29, 415–432. [Google Scholar] [CrossRef] [Scilit]
- Cimpoi, M.; Maji, S.; Kokkinos, I.; Mohamed, S.; Vedaldi, A. Describing Textures in the Wild. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), Columbus, OH, USA, 24–27 June 2014. [Google Scholar]
- Sinems Workplace. DefectDetectionwk2 Classification Dataset. 2025. Available online: https://universe.roboflow.com/sinems-workplace-gzxdr/defectdetectionwk2 (accessed on 23 November 2025).
- Usuario defect-8n3b5. Dataset de Segmentación: Proyecto segment-vx0be. Dataset de Segmentación. 2025. Available online: https://universe.roboflow.com/defect-8n3b5/segment-vx0be (accessed on 23 November 2025).
- meraldanma. Textile 2 Dataset. Conjunto de Datos. 2024. Available online: https://universe.roboflow.com/meraldanma/textile-2 (accessed on 23 November 2025).
- Chaki, J.; Dey, N. Texture Feature Extraction Techniques for Image Recognition; SpringerBriefs in Computational Intelligence; Springer: Singapore, 2020. [Google Scholar] [CrossRef] [Scilit]
- Utaminingrum, F.; Alqadri, A.M.; Somawirata, I.K.; Karim, C.; Septiarini, A.; Lin, C.Y.; Shih, T.K. Feature selection of gray-level Cooccurrence matrix using genetic algorithm with Extreme learning machine classification for early detection of Pole roads. Results Eng. 2023, 20, 101437. [Google Scholar] [CrossRef] [Scilit]
- Huang, D.; Shan, C.; Ardabilian, M.; Wang, Y.; Chen, L. Local Binary Patterns and Its Application to Facial Image Analysis: A Survey. IEEE Trans. Syst. Man Cybern. Part C (Appl. Rev.) 2011, 41, 765–781. [Google Scholar] [CrossRef] [Scilit]
- Sanjaya, S.; Adzkia, U.; Handayani, L.; Yanto, F. Local Binary Pattern and Learning Vector Quantization for Classification of Principal Line of Palm-Hand. Indones. J. Artif. Intell. Data Min. 2020, 3, 71–77. [Google Scholar] [CrossRef]
- Khan, A.R.; Saba, T.; Sadad, T.; Nobanee, H.; Bahaj, S.A. Identification of Anomalies in Mammograms through Internet of Medical Things (IoMT) Diagnosis System. Comput. Intell. Neurosci. 2022, 2022, 1100775. [Google Scholar] [CrossRef] [Scilit]
- Dalal, N.; Triggs, B. Histograms of oriented gradients for human detection. In Proceedings of the 2005 IEEE Computer Society Conference on Computer Vision and Pattern Recognition (CVPR’05); IEEE: Piscataway, NJ, USA, 2005; Volume 1, pp. 886–893. [Google Scholar] [CrossRef] [Scilit]
- Canny, J. A Computational Approach to Edge Detection. IEEE Trans. Pattern Anal. Mach. Intell. 1986, PAMI-8, 679–698. [Google Scholar] [CrossRef] [Scilit]
- Vincent, O.; Folorunso, O. A Descriptive Algorithm for Sobel Image Edge Detection. In Proceedings of the Informing Science & IT Education Conference (InSITE), Macon, GA, USA, 12–15 June 2009. [Google Scholar] [CrossRef] [Scilit]
- Panigrahy, C.; Seal, A.; Mahato, N.K.; Bhattacharjee, D. Differential box counting methods for estimating fractal dimension of gray-scale images: A survey. Chaos Solitons Fractals 2019, 126, 178–202. [Google Scholar] [CrossRef] [Scilit]
- Panigrahy, C.; Garcia-Pedrero, A.; Seal, A.; Rodríguez-Esparragón, D.; Mahato, N.K.; Gonzalo-Martín, C. An Approximated Box Height for Differential-Box-Counting Method to Estimate Fractal Dimensions of Gray-Scale Images. Entropy 2017, 19, 534. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.D.; Chen, X.Q.; Zhan, T.M.; Jiao, Z.Q.; Sun, Y.; Chen, Z.M.; Yao, Y.; Fang, L.T.; Lv, Y.D.; Wang, S.H. Fractal Dimension Estimation for Developing Pathological Brain Detection System Based on Minkowski-Bouligand Method. IEEE Access 2016, 4, 5937–5947. [Google Scholar] [CrossRef] [Scilit]
- Breiman, L. Random Forests. Mach. Learn. 2001, 45, 5–32. [Google Scholar] [CrossRef] [Scilit]
- Nikitin, N.Y.; Stepashkin, A. Classification of tensile test results of unidirectional carbon fiber-polysulfone composite material based on random forest, KNN and CNN methods. Results Mater. 2025, 28, 100788. [Google Scholar] [CrossRef] [Scilit]
- Altmann, A.; Toloşi, L.; Sander, O.; Lengauer, T. Permutation importance: A corrected feature importance measure. Bioinformatics 2010, 26, 1340–1347. [Google Scholar] [CrossRef] [Scilit]
- Sujon, K.M.; Hassan, R.; Choi, K.; Samad, M.A. Accuracy, precision, recall, f1-score, or MCC? Empirical evidence from advanced statistics, machine learning, and XAI for evaluating business predictive models. J. Big Data 2025, 12, 268. [Google Scholar] [CrossRef] [Scilit]
- Sun, Y.; Wang, J.; Wang, T.; Li, J.; Wei, Z.; Fan, A.; Liu, H.; Chen, S.; Zhang, Z.; Chen, Y.; et al. Post-Fracture Production Prediction with Production Segmentation and Well Logging: Harnessing Pipelines and Hyperparameter Tuning with GridSearchCV. Appl. Sci. 2024, 14, 3954. [Google Scholar] [CrossRef] [Scilit]
- Boser, B.; Guyon, I.; Vapnik, V. A Training Algorithm for Optimal Margin Classifier. In Proceedings of the Fifth Annual Workshop on Computational Learning Theory; Association for Computing Machinery: New York, NY, USA, 1996; Volume 5. [Google Scholar] [CrossRef] [Scilit]
- Luts, J.; Ojeda, F.; Van de Plas, R.; De Moor, B.; Van Huffel, S.; Suykens, J.A. A tutorial on support vector machine-based methods for classification problems in chemometrics. Anal. Chim. Acta 2010, 665, 129–145. [Google Scholar] [CrossRef] [Scilit]
- Pillai, K.S.; ML, S.; Aiswarya, S.; Anand, A.B.; Prasad, G. Municipal Solid Waste Management: A Review of Machine Learning Applications. E3S Web Conf. 2023, 455, 02018. [Google Scholar] [CrossRef] [Scilit]
- Piccioni Costa, L.; Guerreiro, M.; Puchta, E.; Tadano, Y.; Antonini Alves, T.; Kaster, M.; Siqueira, H. Multilayer Perceptron. 2023, p. 105. Available online: https://zenodo.org/records/7562924 (accessed on 23 November 2025).
- Chu, Y.; Huang, C.; Xie, X.; Tan, B.; Kamal, S.; Xiong, X. Multilayer Hybrid Deep-Learning Method for Waste Classification and Recycling. Comput. Intell. Neurosci. 2018, 2018, 5060857. [Google Scholar] [CrossRef] [Scilit]

Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.