
Article

A Benchmark Dataset for Evaluating Practical Performance of Model Quality Assessment of Homology Models

1
Department of Computer Science, School of Computing, Tokyo Institute of Technology, Ookayama, Meguro-ku, Tokyo 152-8550, Japan
2
AIST-Tokyo Tech Real World Big-Data Computation Open Innovation Laboratory (RWBC-OIL), National Institute of Advanced Industrial Science and Technology (AIST), Aomi, Koto-ku, Tokyo 135-0064, Japan
*
Author to whom correspondence should be addressed.
Bioengineering 2022, 9(3), 118; https://doi.org/10.3390/bioengineering9030118

Submission received: 9 February 2022 / Revised: 8 March 2022 / Accepted: 11 March 2022 / Published: 15 March 2022

Abstract

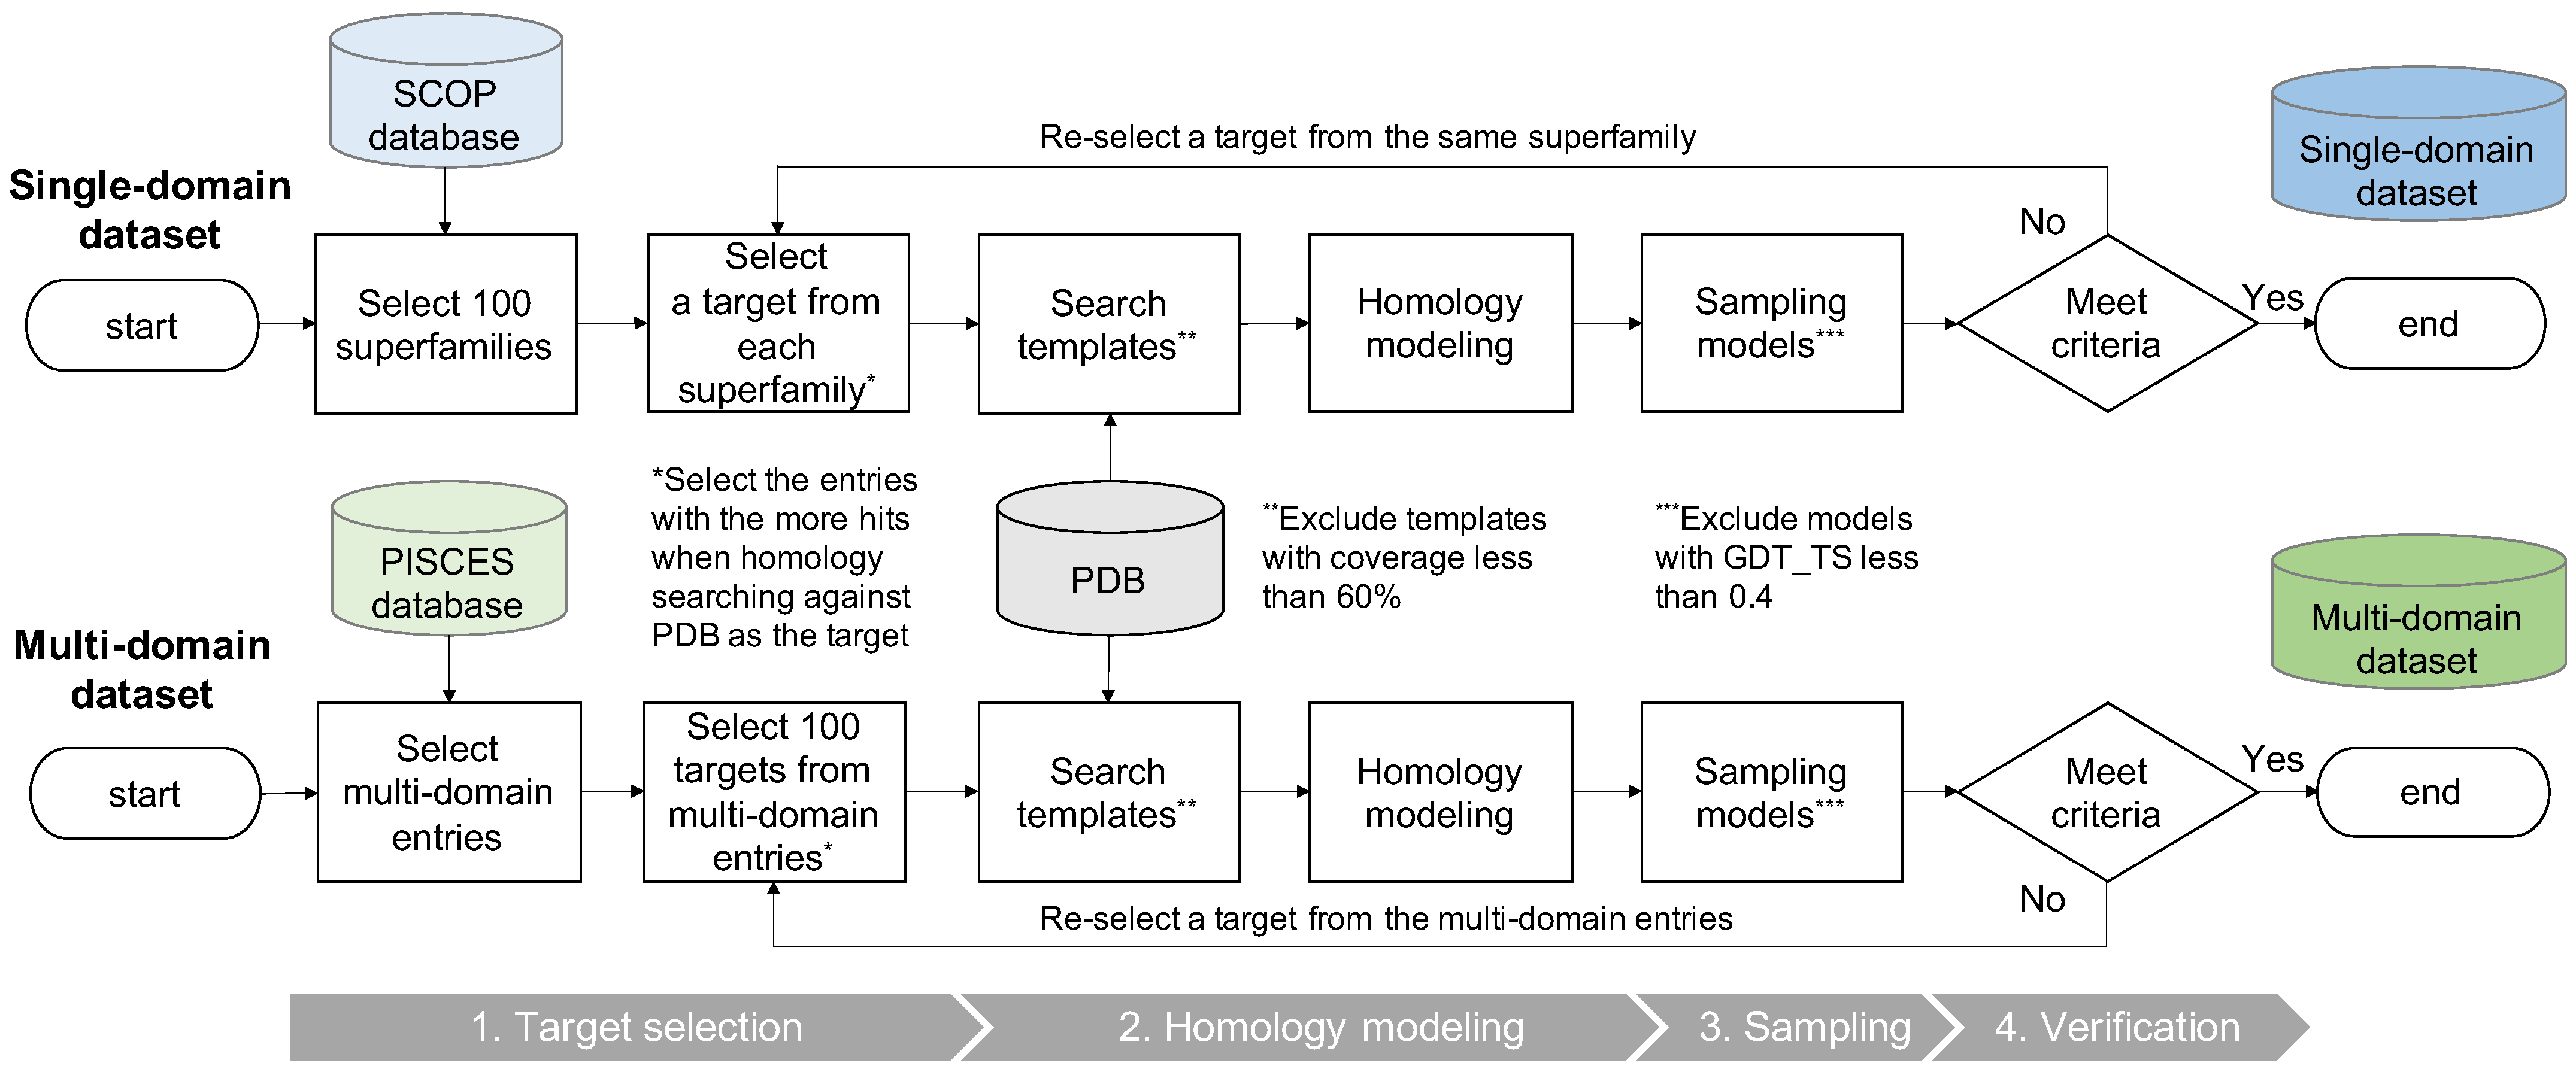
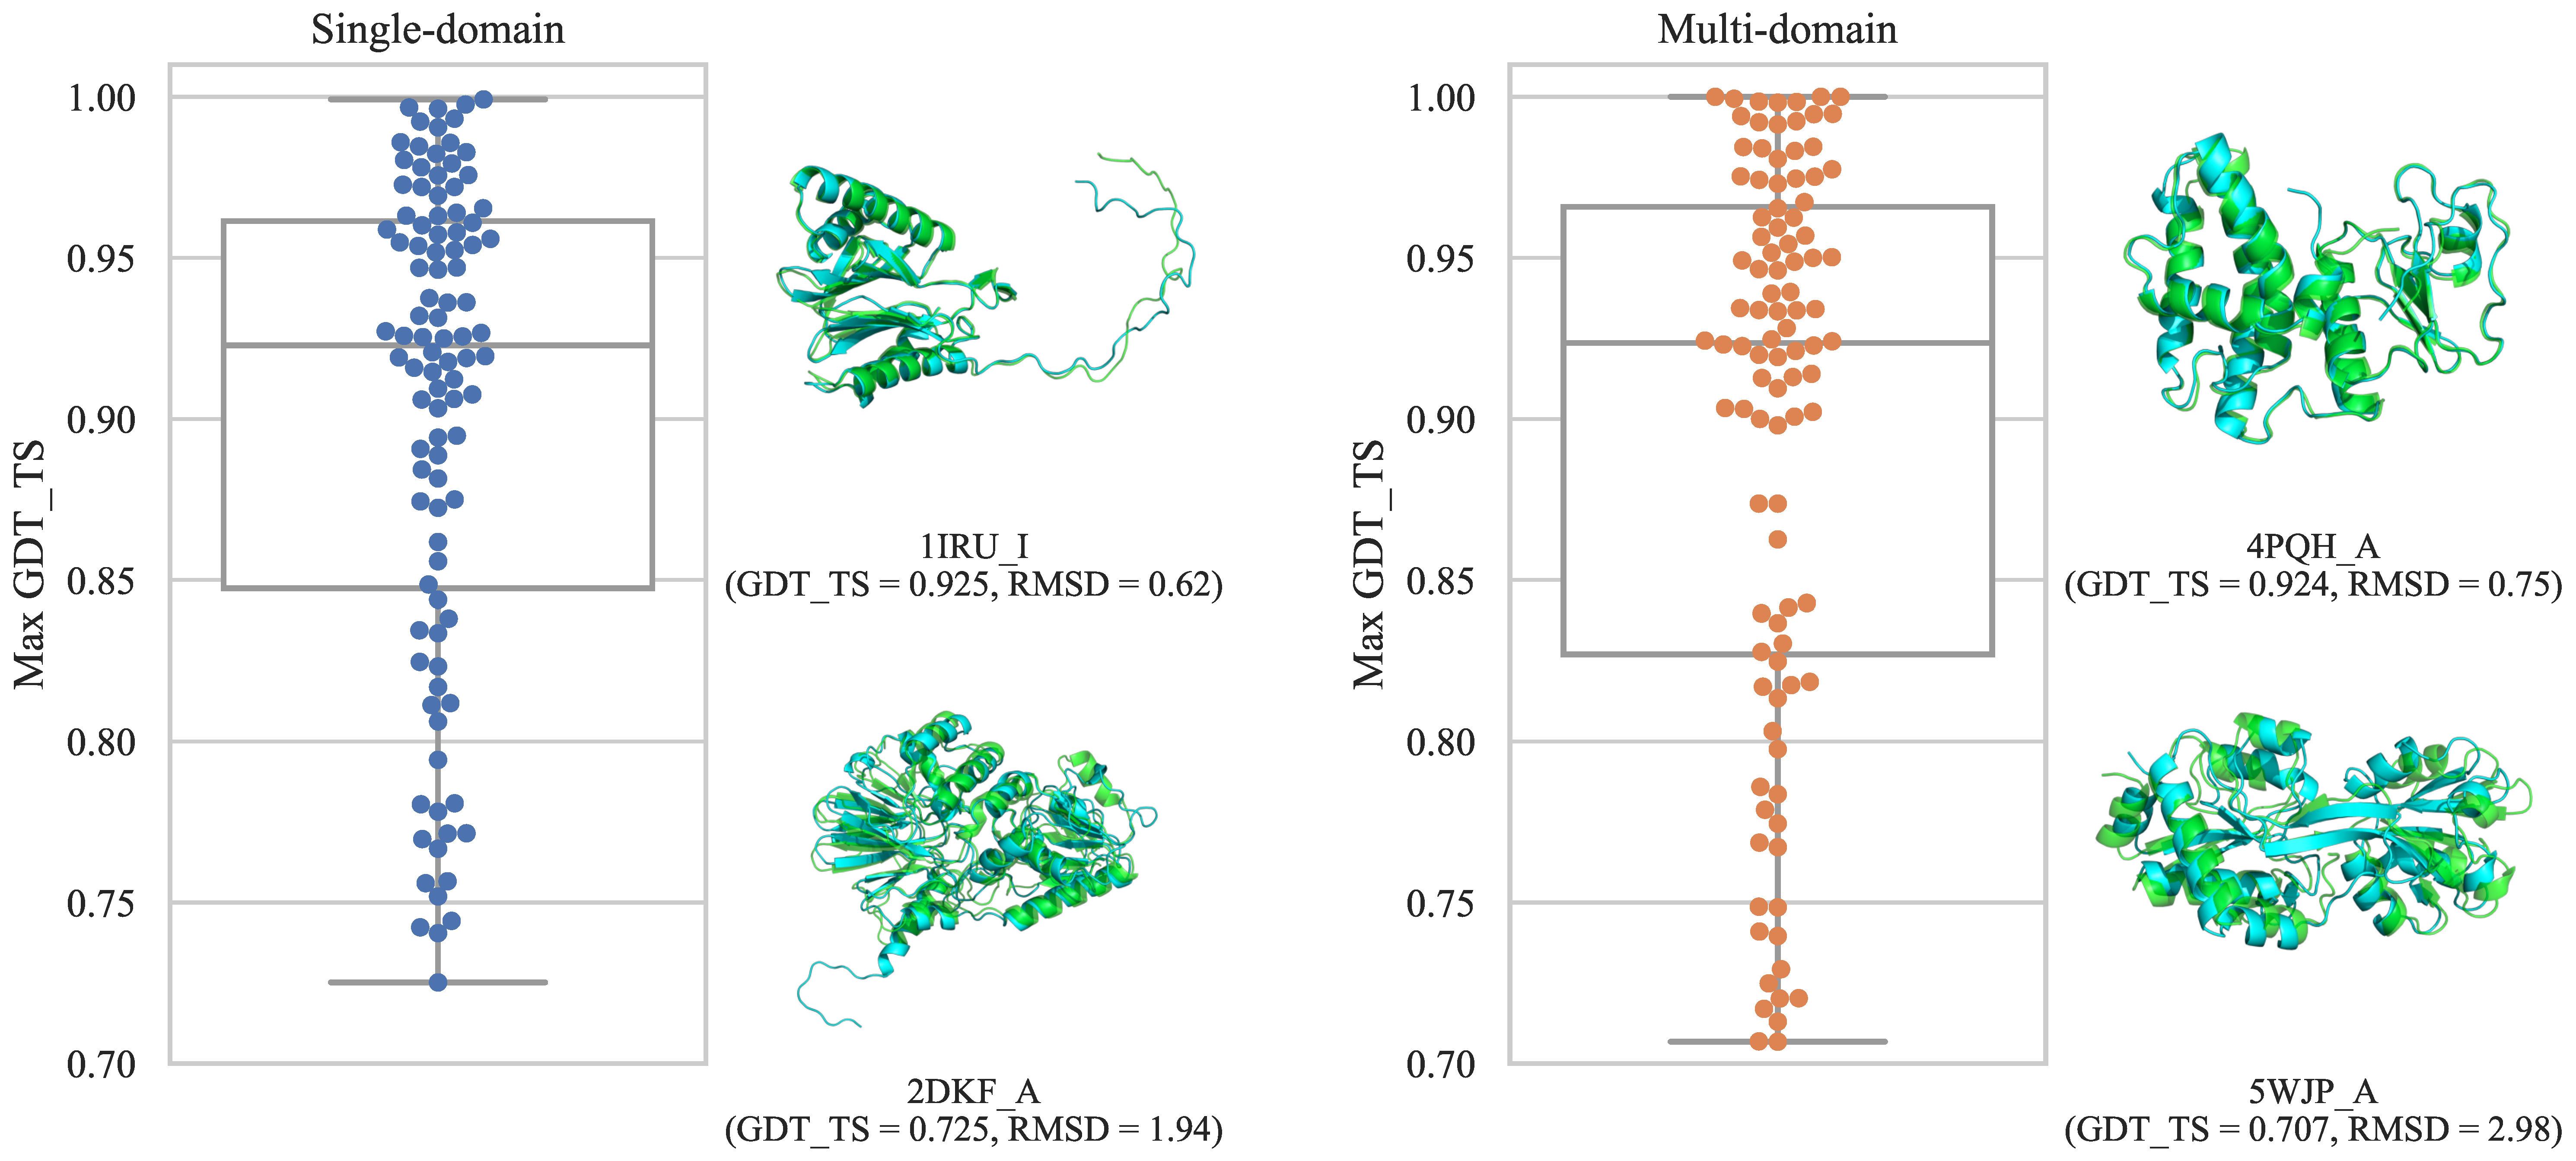
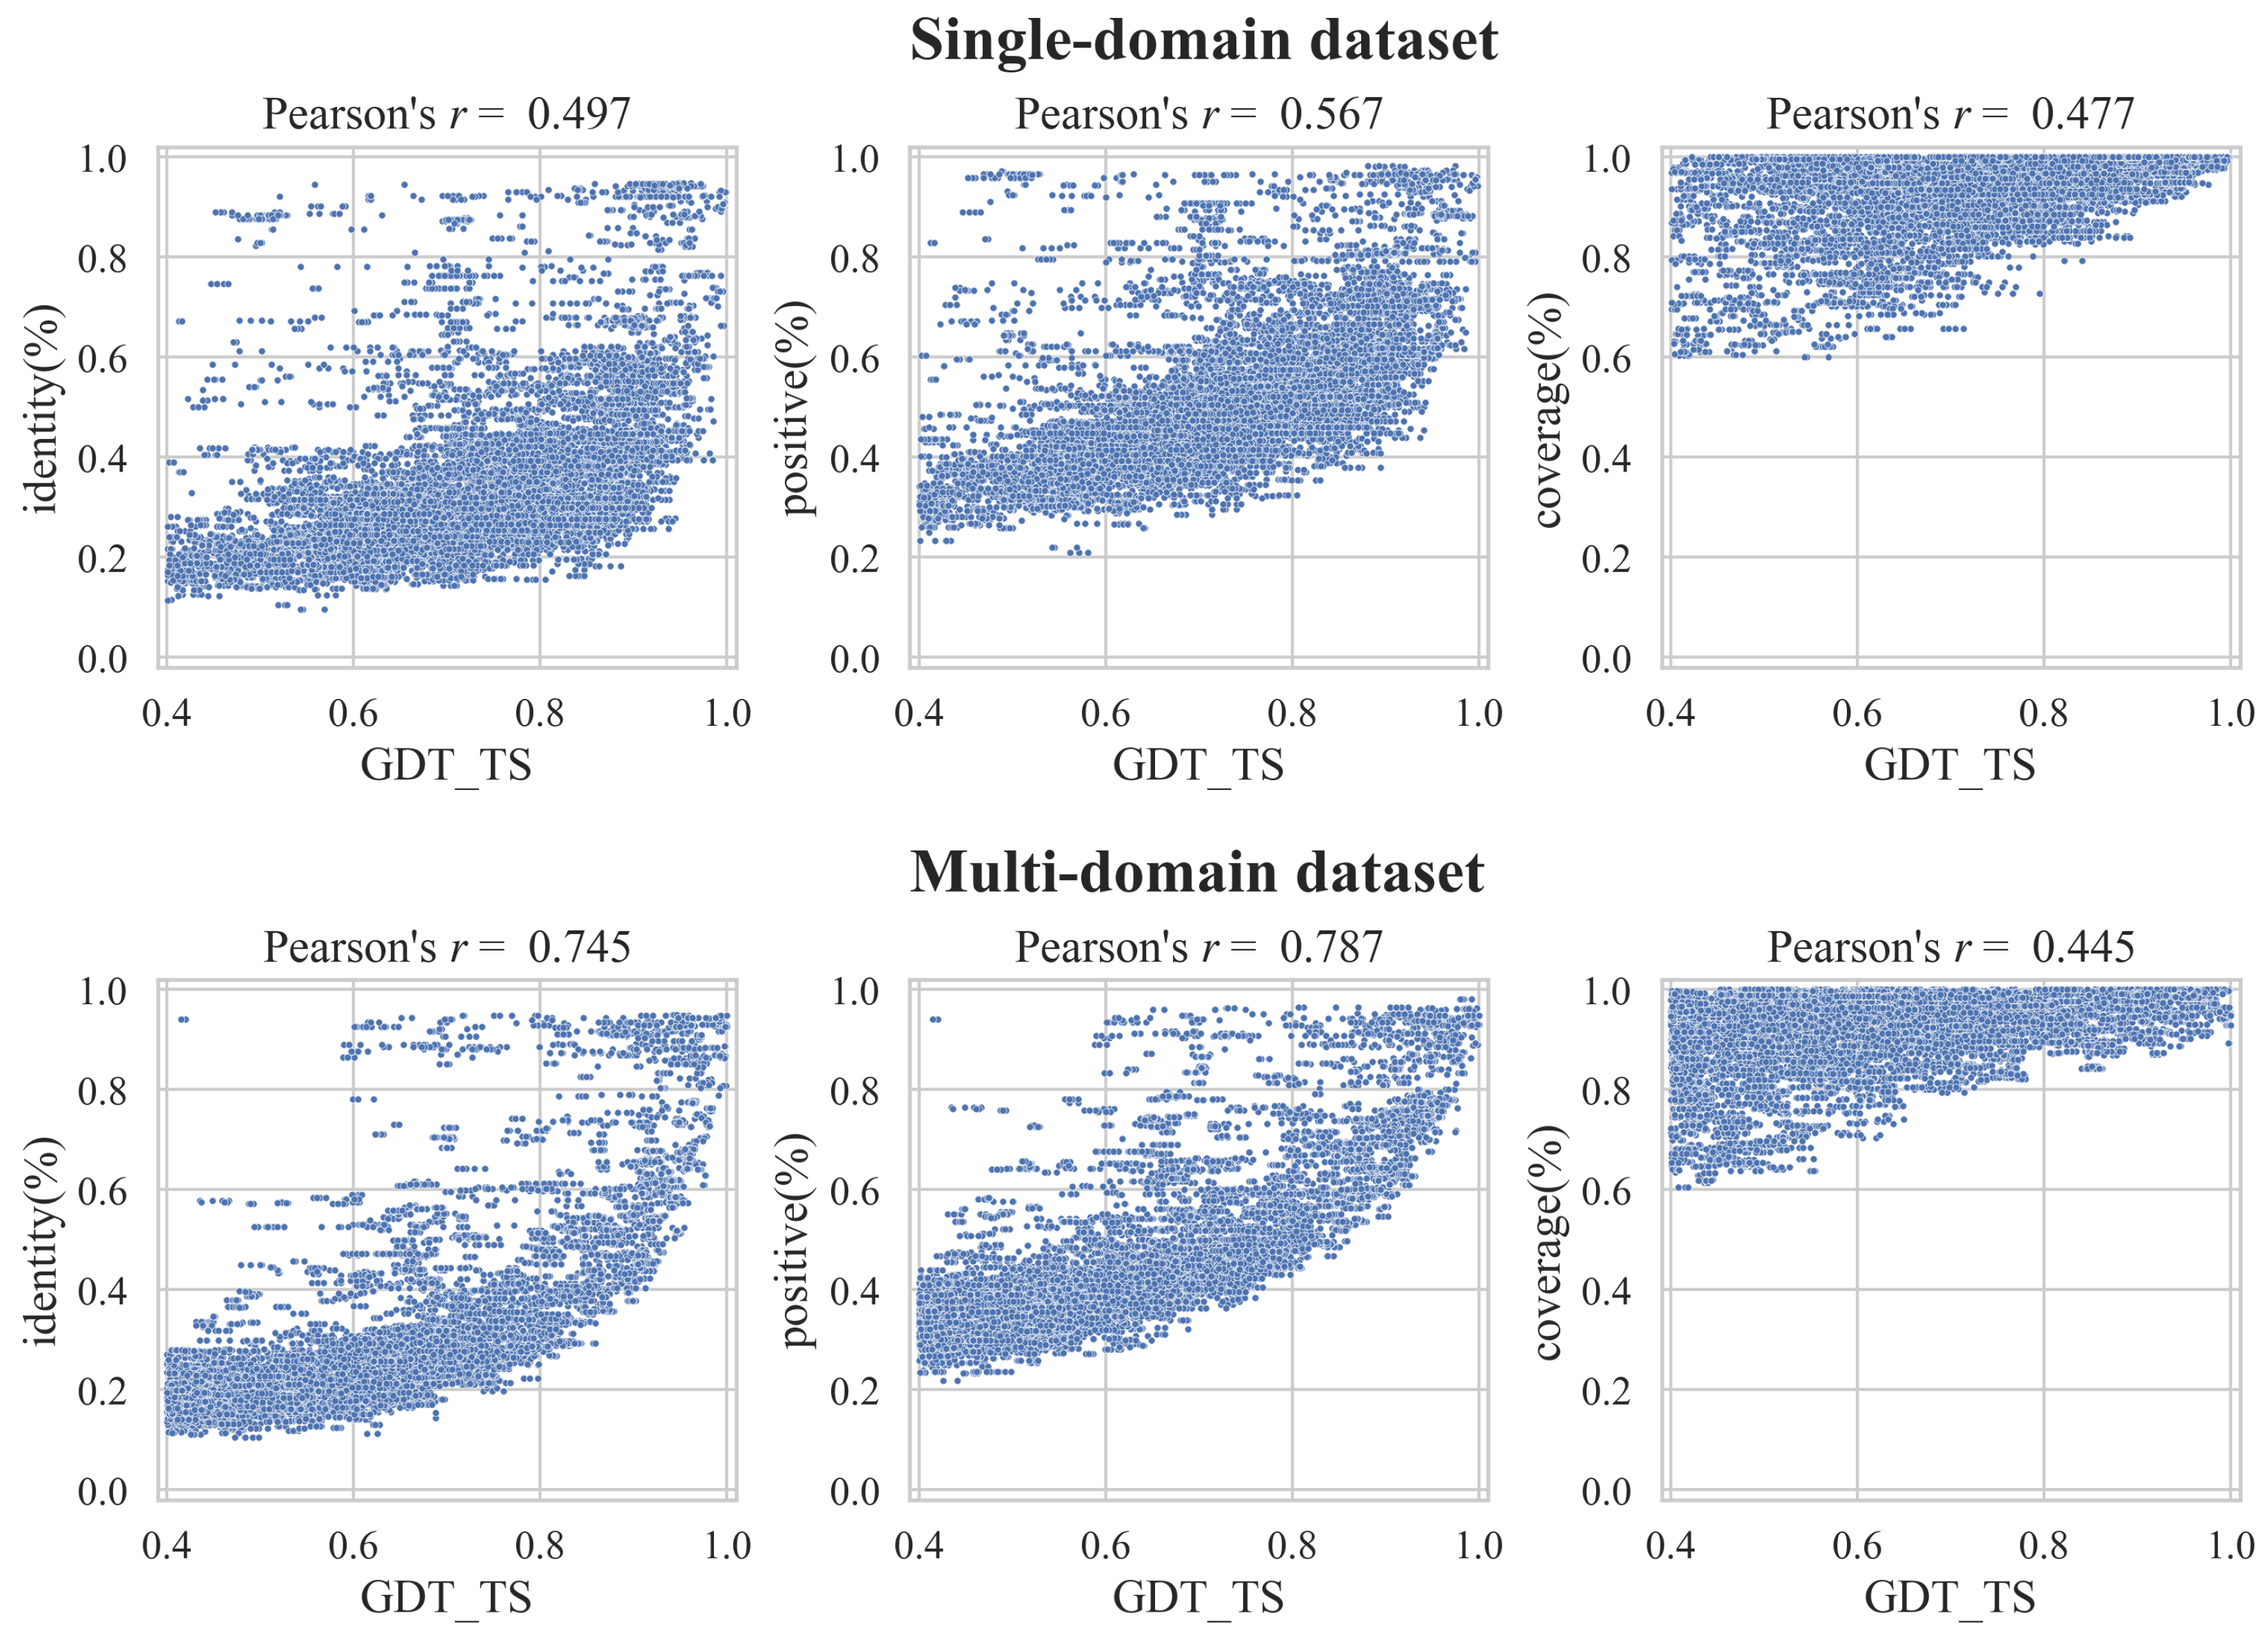
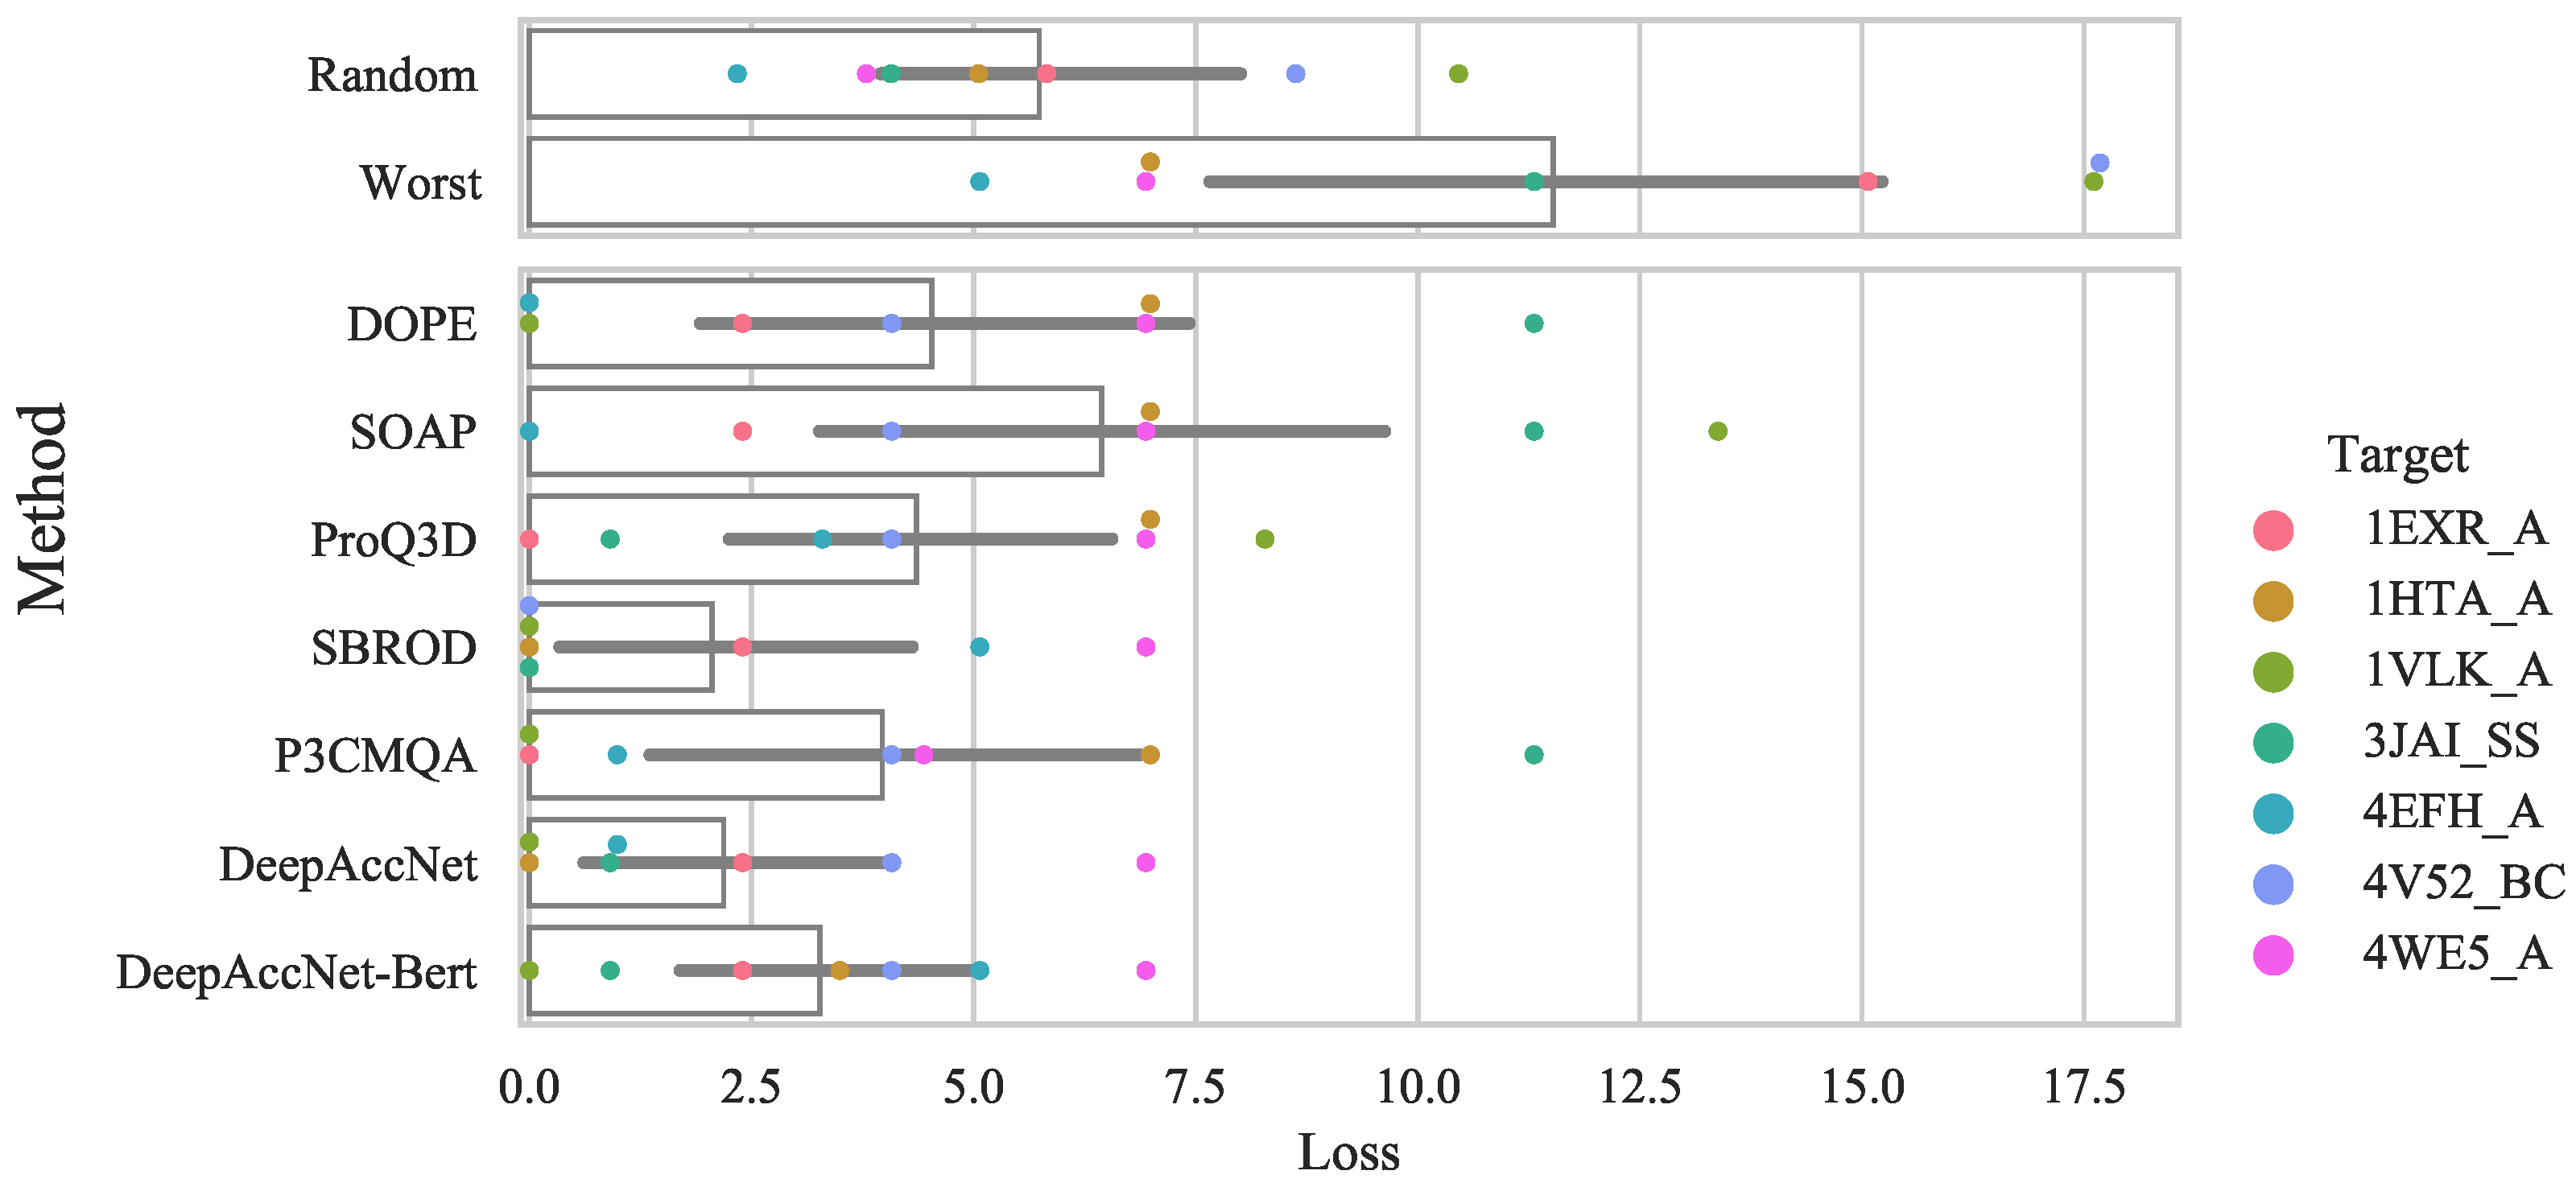
Protein structure prediction is an important issue in structural bioinformatics. In this process, model quality assessment (MQA), which estimates the accuracy of the predicted structure, is also practically important. Currently, the most commonly used dataset to evaluate the performance of MQA is the critical assessment of the protein structure prediction (CASP) dataset. However, the CASP dataset does not contain enough targets with high-quality models, and thus cannot sufficiently evaluate the MQA performance in practical use. Additionally, most application studies employ homology modeling because of its reliability. However, the CASP dataset includes models generated by de novo methods, which may lead to the mis-estimation of MQA performance. In this study, we created new benchmark datasets, named a homology models dataset for model quality assessment (HMDM), that contain targets with high-quality models derived using homology modeling. We then benchmarked the performance of the MQA methods using the new datasets and compared their performance to that of the classical selection based on the sequence identity of the template proteins. The results showed that model selection by the latest MQA methods using deep learning is better than selection by template sequence identity and classical statistical potentials. Using HMDM, it is possible to verify the MQA performance for high-accuracy homology models.
Keywords: model quality assessment; evaluation of model accuracy; protein structure prediction; machine learning; deep learning; MQA; EMA model quality assessment; evaluation of model accuracy; protein structure prediction; machine learning; deep learning; MQA; EMA