Virtual-Document-Augmented Retrieval-Augmented Generation for Power-Domain Knowledge-Base Question Answering with Noise-Enhanced Robustness


 , ,
Abstract
1. Introduction
2. Related Works
3. Methodology
- (1)
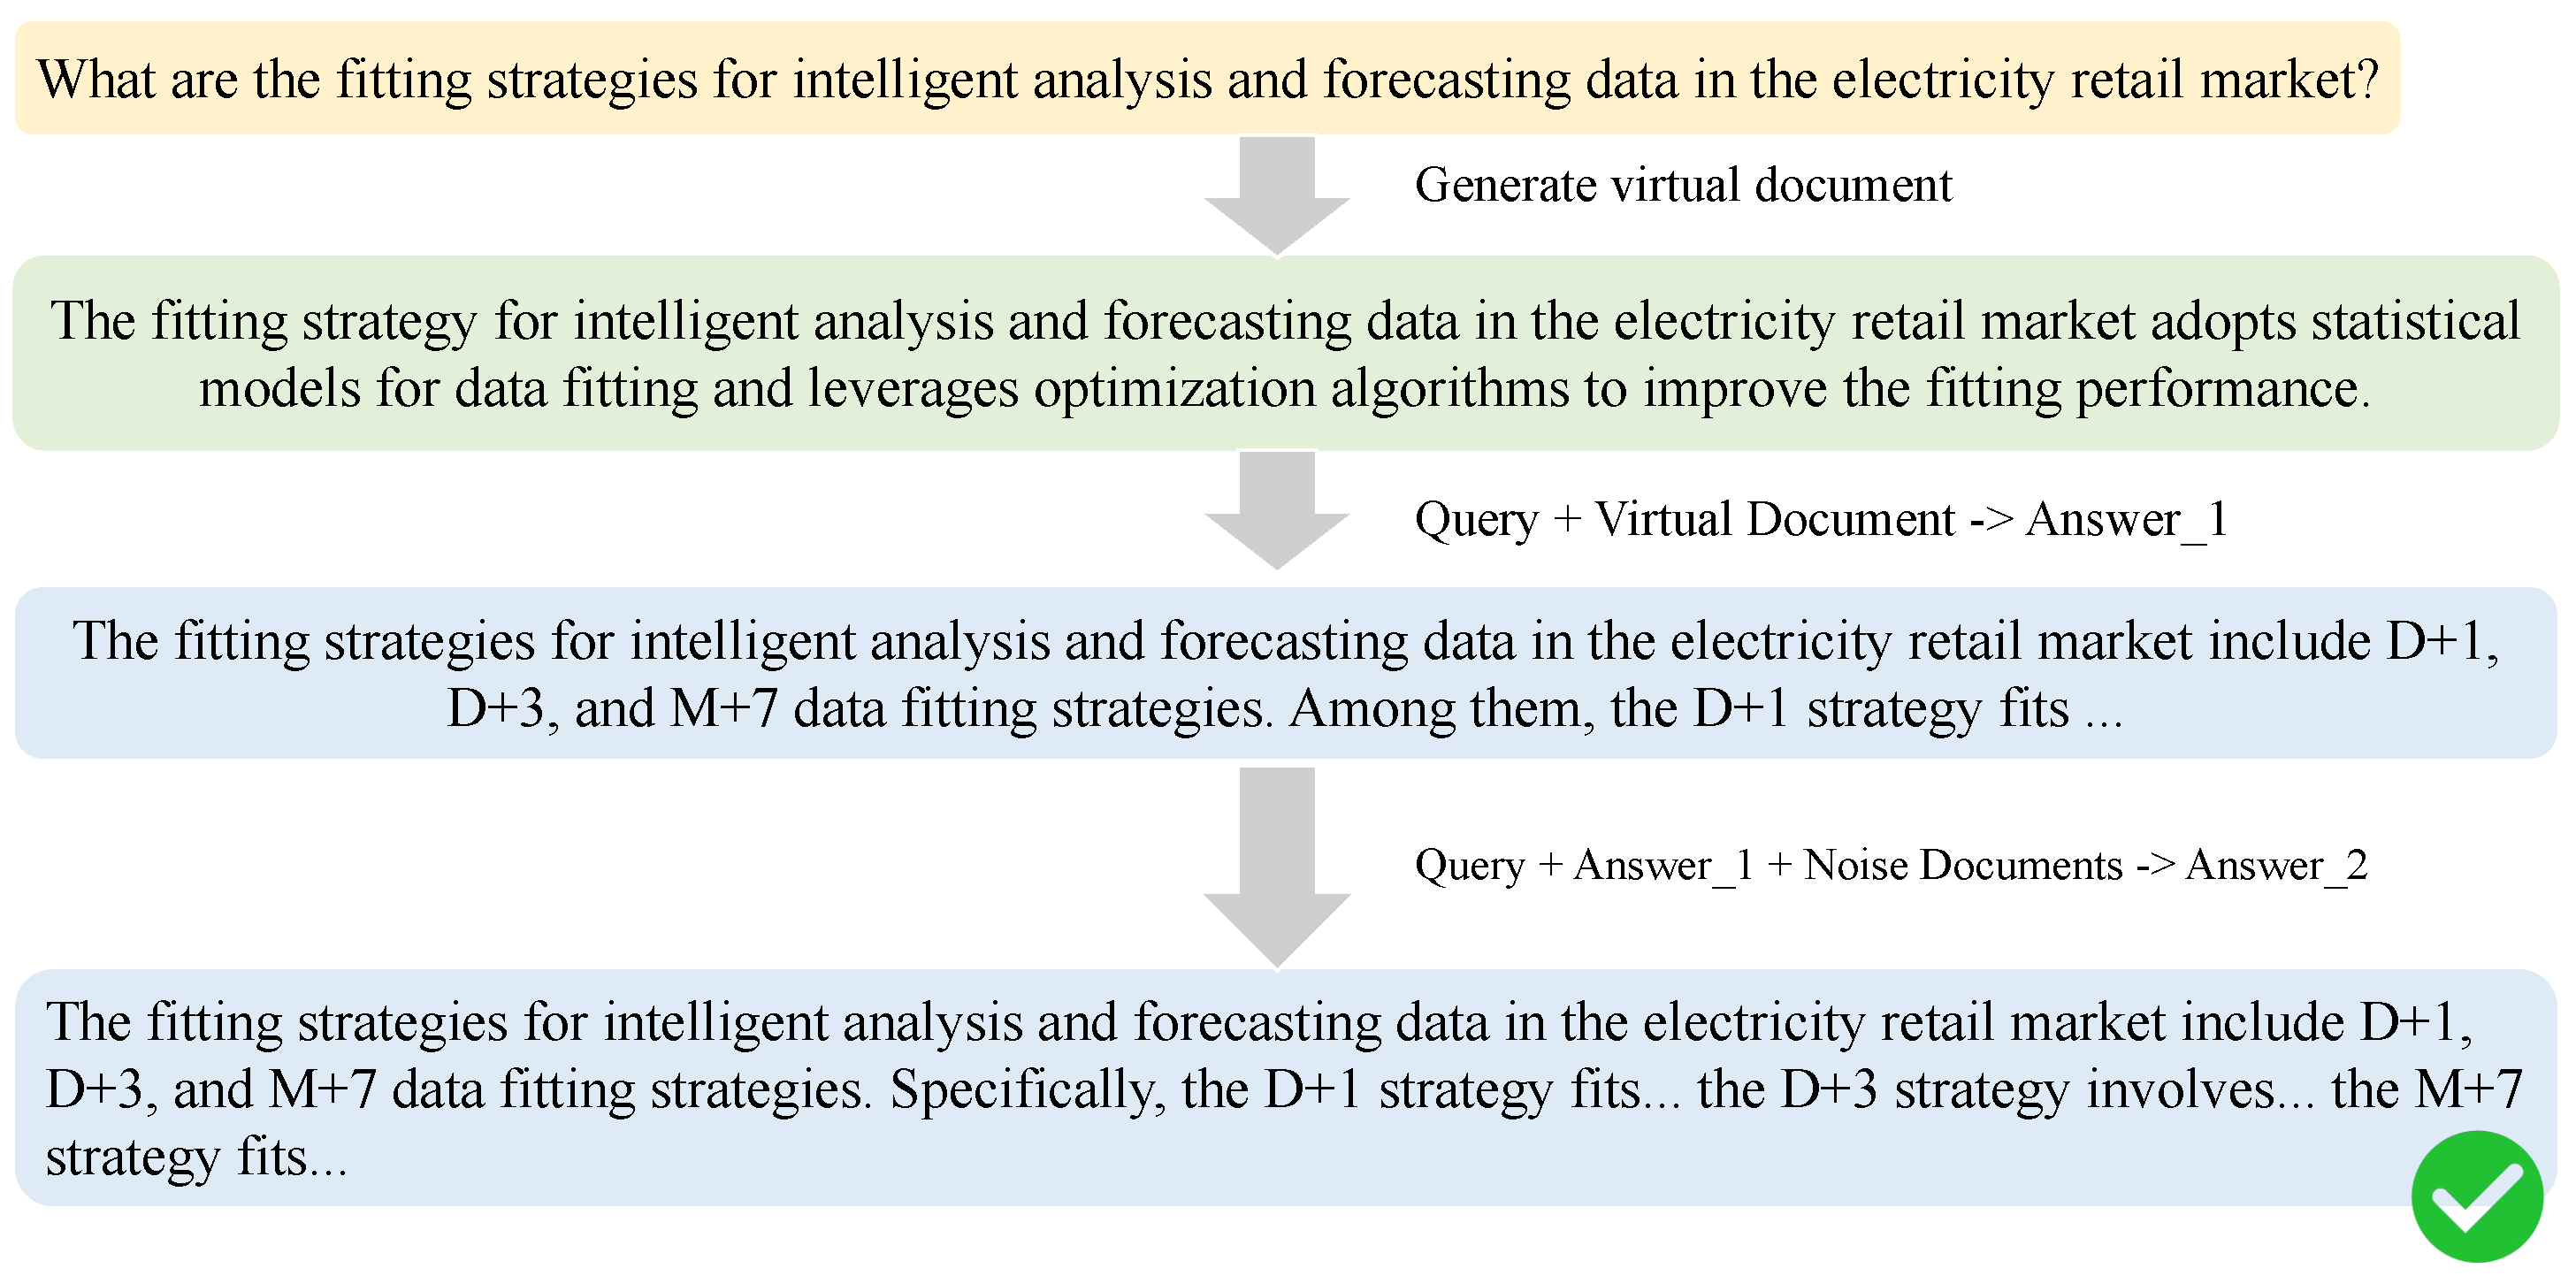
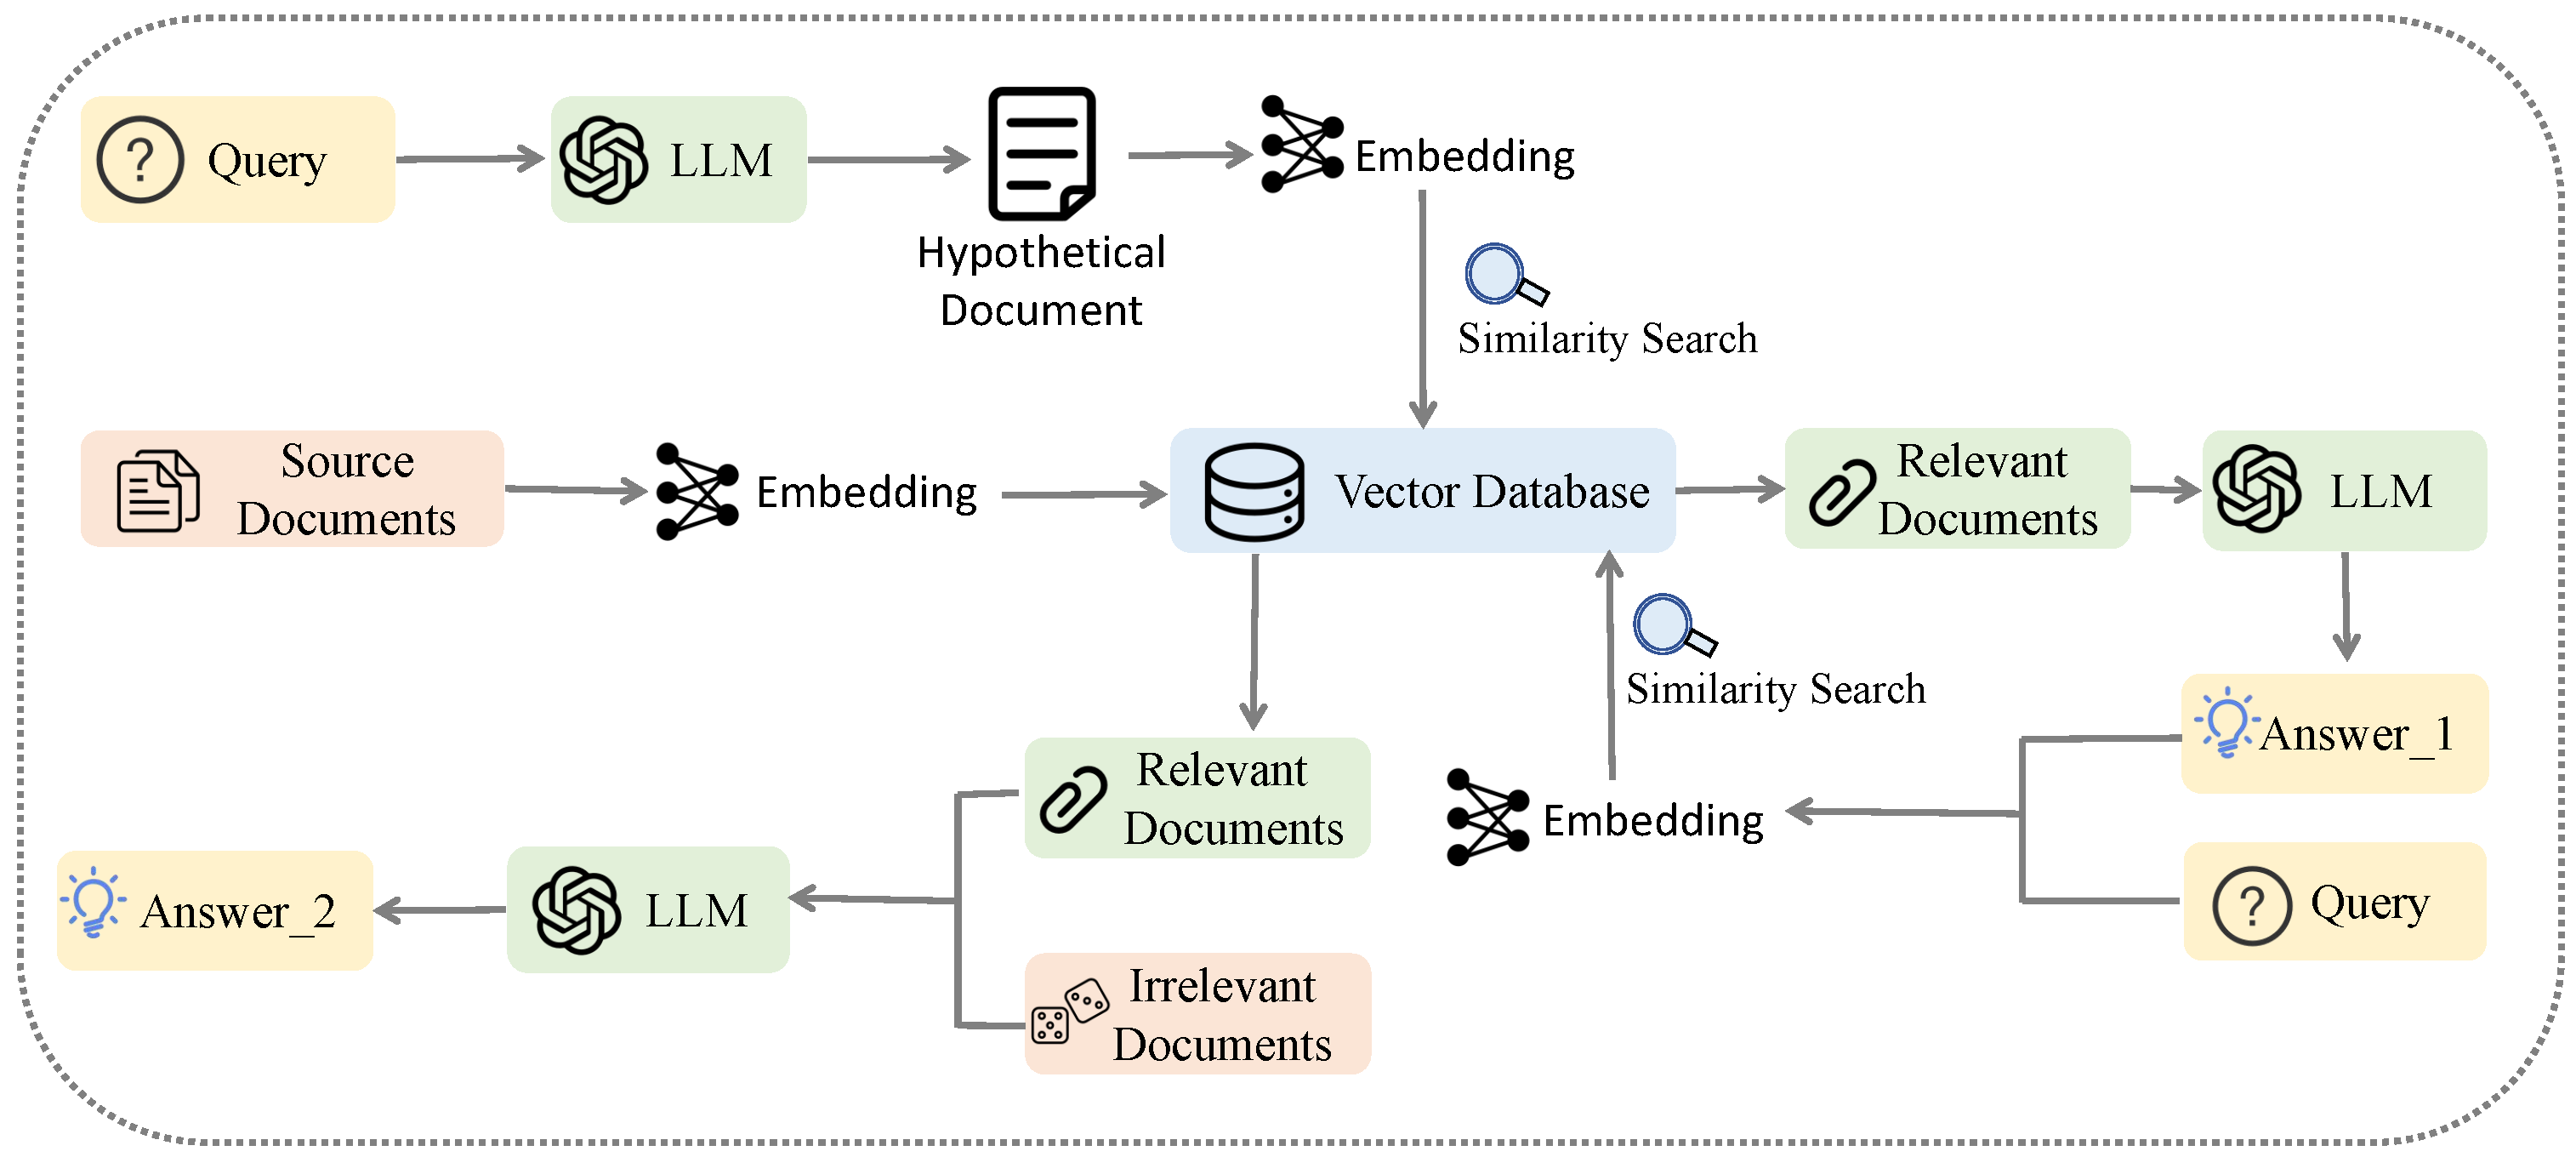
- Virtual Document Substitution: Using a pre-trained LLM, we generate context-rich pseudo-documents to semantically expand the original query. This mechanism closes the representational mismatch between concise queries and lengthy corpus documents by simulating the semantic distribution of complete documents, which in turn improves retrieval accuracy.
- (2)
- Iterative Query-Answer Retrieval: We first integrate the retrieved documents into a prompt template to generate an initial answer. We then concatenate this intermediate answer with the original query and embed them as a refined retrieval vector; this allows for a second-stage retrieval that focuses on more relevant documents.
- (3)
- Noise-Enhanced Robustness: Before inputting documents into the LLM, we introduce irrelevant “noise” documents alongside the retrieved content. This training strategy forces the model to discern signal from noise, which enhances its ability to focus on informative content and improves output robustness.
3.1. Text Chunk Indexing
3.2. Virtual Document Retrieval
3.3. The Introduction of Irrelevant Documents
4. Experiments
4.1. Setup
4.1.1. Implementation
4.1.2. Datasets
4.1.3. Metrics
4.1.4. Failure Cases Analysis
4.2. Main Result
4.3. Ablation Study
4.4. Impact of Irrelevant Documents
4.5. Impact of Relevant Documents Positioning
4.6. Efficiency Analysis
5. Conclusions
Author Contributions
Funding
Data Availability Statement
Acknowledgments
Conflicts of Interest
Appendix A. Failure Cases Analysis
- Case1
- Question: What are the future work plans of Hebei Electric Power for 2023?
- Gold answer: (1) Refine hierarchical responsibilities for power supply assurance; (2) Promote the construction of a new-type load management system; (3) Establish a market analysis and forecasting framework.
- Top-5 documents:
- Challenges faced by Hebei Electric Power regarding high-voltage transmission.
- Electricity consumption in the Beijing-Tianjin-Hebei region during Winter 2023 and subsequent planning: (1) Refine hierarchical responsibilities for power supply assurance; (2) Promote the construction of a new-type load management system.
- Power supply and demand conditions in Hebei during Summer 2023.
- Electricity consumption patterns of Hebei’s manufacturing sector in 2023.
- Analysis of total social installed capacity in Hebei for 2023.
- LLM output: Based on the provided documents, the future work plans of Hebei Electric Power for 2023 cannot be determined.
- Diagnosis: The complete answer is distributed across two separate text chunks; however, the retriever only recalled one of them. Furthermore, the relevant answer segment constitutes only a minor fraction of the retrieved chunk, which the generator consequently failed to exploit effectively. The root cause of this failure lies in semantic fragmentation during the document preprocessing stage: critical information required for a comprehensive response was inadvertently segmented into multiple disparate chunks. This incomplete retrieval prevented the LLM from accessing coherent and comprehensive context, resulting in semantic discontinuity and comprehension bias. Ultimately, the system generated an “unanswerable” response.
- Case2
- Question: What were the objectives of State Grid Corporation of China regarding market forecasting for the second half of 2022?
- Gold answer: Forecast peak load, anticipate power supply gaps, and complete electricity market analysis and forecasting reports.
- Top-5 documents:
- Promoting the establishment of a market-oriented system for market forecasting and analysis.
- Work schedule for market analysis and forecasting, emphasizing inter-departmental coordination.
- Standardizing and optimizing business processes, with specific work requirements and procedures aimed at compliant operations and excellent service.
- New requirements for the market work system, refining job standards and work standards.
- Focusing on establishing and improving business systems for market business analysis, and coordinating business platforms.
- LLM output: The market professional management system has been fully established, refining load management organization and implementation, as well as market analysis and forecasting business processes.
- Diagnosis: This represents a case of semantic retrieval failure. The embedding model was unable to effectively distinguish between “objectives of market forecasting by the grid corporation” and “market analysis and forecasting” as routine activities. Due to the high degree of semantic overlap between these keywords, the retriever recalled generic documents concerning routine market forecasting tasks, which subsequently led the generator to produce an incorrect response.
References
- Brown, T.B.; Mann, B.; Ryder, N.; Subbiah, M.; Kaplan, J.; Dhariwal, P.; Neelakantan, A.; Shyam, P.; Sastry, G.; Askell, A.; et al. Language models are few-shot learners. In Proceedings of the 33th International Conference on Neural Information Processing Systems; Curran Associates Inc.: Red Hook, NY, USA, 2020; pp. 1877–1901. [Google Scholar] [CrossRef] [Scilit]
- Touvron, H.; Martin, L.; Stone, K.; Albert, P.; Almahairi, A.; Babaei, Y.; Bashlykov, N.; Batra, S.; Bhargava, P.; Bhosale, S.; et al. Llama 2: Open foundation and fine-tuned chat models. arXiv 2023, arXiv:2307.09288. [Google Scholar] [CrossRef] [Scilit]
- Zhang, Y.; Li, Y.; Cui, L.; Cai, D.; Liu, L.; Fu, T.; Huang, X.; Zhao, E.; Zhang, Y.; Chen, Y.; et al. Siren’s Song in the AI Ocean: A Survey on Hallucination in Large Language Models. arXiv 2023, arXiv:2309.01219. [Google Scholar] [CrossRef] [Scilit]
- Kandpal, N.; Deng, H.; Roberts, A.; Wallace, E.; Raffel, C. Large Language Models Struggle to Learn Long-Tail Knowledge. In Proceedings of the 40th International Conference on Machine Learning, Honolulu, HI, USA, 23–29 July; PMLR: Cambridge, MA, USA, 2023; pp. 15696–15707. Available online: https://dl.acm.org/doi/abs/10.5555/3618408.3619049 (accessed on 11 February 2026).
- Majumder, S.; Dong, L.; Doudi, F.; Cai, Y.; Tian, C.; Kalathil, D.; Ding, K.; Thatte, A.A.; Li, N.; Xie, L. Exploring the capabilities and limitations of large language models in the electric energy sector. Joule 2024, 8, 1544–1549. [Google Scholar] [CrossRef] [Scilit]
- Lewis, P.; Perez, E.; Piktus, A.; Petroni, F.; Karpukhin, V.; Goyal, N.; Küttler, H.; Lewis, M.; Yih, W.t.; Rocktäschel, T.; et al. Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. In Proceedings of the 33th International Conference on Neural Information Processing Systems; Curran Associates, Inc.: Red Hook, NY, USA, 2020; pp. 9459–9474. [Google Scholar] [CrossRef] [Scilit]
- Pandia, L.; Ettinger, A. Sorting through the noise: Testing robustness of information processing in pre-trained language models. In Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing, Online and Punta Cana, Dominican Republic, 7–11 November 2021; Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 1583–1596. [Google Scholar] [CrossRef] [Scilit]
- Cuconasu, F.; Trappolini, G.; Siciliano, F.; Filice, S.; Campagnano, C.; Maarek, Y.; Tonellotto, N.; Silvestri, F. The Power of Noise: Redefining Retrieval for RAG Systems. In Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval; Association for Computing Machinery: New York, NY, USA, 2024; pp. 719–729. [Google Scholar] [CrossRef] [Scilit]
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A.N.; Kaiser, L.u.; Polosukhin, I. Attention is All you Need. In Proceedings of the 30th International Conference on Neural Information Processing Systems, Long Beach, CA, USA, 4–9 December 2017; Curran Associates, Inc.: Red Hook, NY, USA, 2017. [Google Scholar] [CrossRef] [Scilit]
- Devlin, J.; Chang, M.W.; Lee, K.; Toutanova, K. BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers), Minneapolis, MN, USA, 2–7 June 2019; Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 4171–4186. [Google Scholar] [CrossRef] [Scilit]
- Gao, Y.; Xiong, Y.; Gao, X.; Jia, K.; Pan, J.; Bi, Y.; Dai, Y.; Sun, J.; Guo, Q.; Wang, M.; et al. Retrieval-Augmented Generation for Large Language Models: A Survey. arXiv 2023, arXiv:2312.10997. [Google Scholar] [CrossRef] [Scilit]
- Sparck Jones, K. A statistical interpretation of term specificity and its application in retrieval. J. Doc. 1972, 28, 11–21. [Google Scholar] [CrossRef] [Scilit]
- Karpukhin, V.; Oğuz, B.; Min, S.; Lewis, P.; Wu, L.; Edunov, S.; Chen, D.; Yih, W. Dense passage retrieval for open-domain question answering. In Proceedings of the EMNLP 2020—2020 Conference on Empirical Methods in Natural Language Processing, Proceedings of the Conference, Online, 16–20 November 2020; Association for Computational Linguistics: Stroudsburg, PA, USA, 2020; pp. 6769–6781. [Google Scholar] [CrossRef] [Scilit]
- Mao, Y.; He, P.; Liu, X.; Shen, Y.; Gao, J.; Han, J.; Chen, W. Generation-Augmented Retrieval for Open-Domain Question Answering. In Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers); Association for Computational Linguistics: Stroudsburg, PA, USA, 2021; pp. 4089–4100. [Google Scholar] [CrossRef] [Scilit]
- Gao, L.; Ma, X.; Lin, J.; Callan, J. Precise Zero-Shot Dense Retrieval without Relevance Labels. In Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics, Toronto, ON, Canada, 9–14 July 2023; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 1762–1777. [Google Scholar] [CrossRef] [Scilit]
- Ma, X.; Gong, Y.; He, P.; Zhao, H.; Duan, N. Query Rewriting in Retrieval-Augmented Large Language Models. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, Singapore, 6–10 December 2023; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 5303–5315. [Google Scholar] [CrossRef] [Scilit]
- Cooper Stickland, A.; Sengupta, S.; Krone, J.; Mansour, S.; He, H. Robustification of Multilingual Language Models to Real-world Noise in Crosslingual Zero-shot Settings with Robust Contrastive Pretraining. In Proceedings of the 17th Conference of the European Chapter of the Association for Computational Linguistics, Dubrovnik, Croatia, 2–6 May 2023; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 1375–1391. [Google Scholar] [CrossRef] [Scilit]
- Ye, J.; Xu, N.; Wang, Y.; Zhou, J.; Zhang, Q.; Gui, T.; Huang, X. LLM-DA: Data Augmentation via Large Language Models for Few-Shot Named Entity Recognition. arXiv 2024, arXiv:2402.14568. [Google Scholar] [CrossRef] [Scilit]
- Chen, J.; Lin, H.; Han, X.; Sun, L. Benchmarking large language models in retrieval-augmented generation. In Proceedings of the AAAI Conference on Artificial Intelligence; AAAI Press: Cambridge, MA, USA, 2024; Volume 38, pp. 17754–17762. [Google Scholar] [CrossRef] [Scilit]
- Al Sharou, K.; Li, Z.; Specia, L. Towards a Better Understanding of Noise in Natural Language Processing. In Proceedings of the International Conference on Recent Advances in Natural Language Processing, Online, 1–3 September 2021; INCOMA Ltd.: Shoumen, Bulgaria, 2021; pp. 53–62. Available online: https://aclanthology.org/2021.ranlp-1.7 (accessed on 11 February 2026).
- Wu, J.; Zhang, S.; Che, F.; Feng, M.; Shao, P.; Tao, J. Pandora’s box or aladdin’s lamp: A comprehensive analysis revealing the role of rag noise in large language models. In Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), Vienna, Austria, 27 July–1 August 2025; Association for Computational Linguistics: Stroudsburg, PA, USA, 2025; pp. 5019–5039. [Google Scholar] [CrossRef] [Scilit]
- Cui, Y.; Liu, T.; Che, W.; Xiao, L.; Chen, Z.; Ma, W.; Wang, S.; Hu, G. A Span-Extraction Dataset for Chinese Machine Reading Comprehension. In Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP), Hong Kong, China, 3–7 November 2019; Association for Computational Linguistics: Stroudsburg, PA, USA, 2019; pp. 5883–5889. [Google Scholar] [CrossRef] [Scilit]
- Xiao, S.; Liu, Z.; Zhang, P.; Muennighoff, N.; Lian, D.; Nie, J.Y. C-Pack: Packed Resources For General Chinese Embeddings. In Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval, Washington, DC, USA, 14–18 July 2024; Association for Computing Machinery: New York, NY, USA, 2024; pp. 641–649. [Google Scholar] [CrossRef] [Scilit]
- Jin, J.; Zhu, Y.; Dou, Z.; Dong, G.; Yang, X.; Zhang, C.; Zhao, T.; Yang, Z.; Wen, J.R. FlashRAG: A Modular Toolkit for Efficient Retrieval-Augmented Generation Research. In Proceedings of the Companion Proceedings of the ACM on Web Conference 2025; Association for Computing Machinery: New York, NY, USA, 2025; pp. 737–740. [Google Scholar] [CrossRef] [Scilit]
- Lin, C.Y. Rouge: A package for automatic evaluation of summaries. In Proceedings of the ACL Workshop: Text Summarization Branches Out 2004, Barcelona, Spain, 25–26 July 2004; Association for Computational Linguistics: Stroudsburg, PA, USA, 2004; pp. 74–81. [Google Scholar]
- Papineni, K.; Roukos, S.; Ward, T.; Zhu, W.J. BLEU: A method for automatic evaluation of machine translation. In Proceedings of the 40th Annual Meeting on Association for Computational Linguistics, Philadelphia, PA, USA, 6–12 July 2002; Association for Computational Linguistics: Stroudsburg, PA, USA, 2002; pp. 311–318. [Google Scholar] [CrossRef] [Scilit]
- Es, S.; James, J.; Anke, L.E.; Schockaert, S. Ragas: Automated evaluation of retrieval augmented generation. In Proceedings of the 18th Conference of the European Chapter of the Association for Computational Linguistics: System Demonstrations, St. Julians, Malta, 17–22 March 2024; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 150–158. [Google Scholar] [CrossRef] [Scilit]
- Shao, Z.; Gong, Y.; Shen, Y.; Huang, M.; Duan, N.; Chen, W. Enhancing Retrieval-Augmented Large Language Models with Iterative Retrieval-Generation Synergy. In Proceedings of the Findings of the Association for Computational Linguistics: EMNLP 2023, Singapore, 6–10 December 2023; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 9248–9274. [Google Scholar] [CrossRef] [Scilit]
- Kim, J.; Nam, J.; Mo, S.; Park, J.; Lee, S.W.; Seo, M.; Ha, J.W.; Shin, J. SuRe: Summarizing Retrievals using Answer Candidates for Open-domain QA of LLMs. In Proceedings of the International Conference on Learning Representations; International Conference on Learning Representations: Appleton, WI, USA, 2024; pp. 15213–15245. [Google Scholar] [CrossRef] [Scilit]
- Jiang, Z.; Xu, F.; Gao, L.; Sun, Z.; Liu, Q.; Dwivedi-Yu, J.; Yang, Y.; Callan, J.; Neubig, G. Active Retrieval Augmented Generation. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, Singapore, 6–10 December 2023; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 7969–7992. [Google Scholar] [CrossRef] [Scilit]
- Trivedi, H.; Balasubramanian, N.; Khot, T.; Sabharwal, A. Interleaving Retrieval with Chain-of-Thought Reasoning for Knowledge-Intensive Multi-Step Questions. In Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics, Toronto, ON, Canada, 9–14 July 2023; Association for Computational Linguistics: Stroudsburg, PA, USA, 2023; pp. 10014–10037. [Google Scholar] [CrossRef] [Scilit]
- Shi, W.; Min, S.; Yasunaga, M.; Seo, M.; James, R.; Lewis, M.; Zettlemoyer, L.; Yih, W.t. REPLUG: Retrieval-Augmented Black-Box Language Models. In Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers), Mexico City, Mexico, 16–21 June 2024; Association for Computational Linguistics: Stroudsburg, PA, USA, 2024; pp. 8371–8384. [Google Scholar] [CrossRef] [Scilit]
- Li, Y. Unlocking Context Constraints of LLMs: Enhancing Context Efficiency of LLMs with Self-Information-Based Content Filtering. arXiv 2023, arXiv:2304.12102. [Google Scholar] [CrossRef] [Scilit]





| Method | ROUGE-1 | ROUGE-2 | ROUGE-L | BLEU-4 |
|---|---|---|---|---|
| Naive RAG | 53.67 | 37.30 | 44.94 | 25.08 |
| ITER-RETGEN [28] | 54.31 | 38.05 | 45.94 | 25.76 |
| Sure [29] | 48.45 | 30.09 | 39.89 | 19.39 |
| Flare [30] | 45.73 | 29.93 | 37.46 | 17.76 |
| Ircot [31] | 50.88 | 33.45 | 42.58 | 22.39 |
| Replug [32] | 40.49 | 20.61 | 31.58 | 10.52 |
| Selective-context [33] | 43.26 | 22.16 | 33.56 | 11.61 |
| Ours | 55.34 | 39.16 | 47.02 | 27.92 |
| Method | ROUGE-1 | ROUGE-2 | ROUGE-L | BLEU-4 |
|---|---|---|---|---|
| Naive RAG | 45.35 | 35.57 | 43.59 | 25.27 |
| ITER-RETGEN [28] | 43.88 | 34.13 | 41.97 | 23.94 |
| Sure [29] | 33.62 | 25.52 | 32.03 | 17.69 |
| Flare [30] | 29.01 | 20.08 | 26.88 | 13.45 |
| Ircot [31] | 42.62 | 32.83 | 40.53 | 22.62 |
| Replug [32] | 28.15 | 14.75 | 25.21 | 8.57 |
| Selective-context [33] | 27.20 | 13.09 | 24.41 | 7.42 |
| Ours | 47.13 | 36.96 | 45.32 | 26.56 |
| Method | Context Relevance | Answer Relevancy | Faithfulness | Response Groundedness |
|---|---|---|---|---|
| Naive RAG | 77.00 | 41.40 | 75.55 | 78.50 |
| ITER-RETGEN [28] | 81.50 | 47.42 | 77.00 | 86.00 |
| Sure [29] | 77.50 | 37.39 | 71.95 | 68.00 |
| Flare [30] | 41.00 | 28.75 | 53.00 | 47.00 |
| Ircot [31] | 77.50 | 52.33 | 73.40 | 85.50 |
| Replug [32] | 77.50 | 42.37 | 56.33 | 70.00 |
| Selective-context [33] | 77.50 | 37.98 | 42.95 | 39.00 |
| Ours | 78.50 | 42.49 | 76.05 | 83.00 |
| Module | ROUGE-1 | ROUGE-2 | ROUGE-L | BLEU-4 |
|---|---|---|---|---|
| electricity power dataset | ||||
| HyDE + irrelevant documents | 55.34 | 39.16 | 47.02 | 27.92 |
| w/o irrelevant documents | 54.50 | 38.11 | 45.99 | 26.62 |
| w/o HyDE | 54.59 | 38.01 | 46.12 | 26.24 |
| w/o HyDE+irrelevant documents | 53.67 | 37.30 | 44.94 | 25.08 |
| CMRC dataset | ||||
| HyDE + irrelevant documents | 45.35 | 36.96 | 45.32 | 26.56 |
| w/o irrelevant documents | 46.51 | 36.12 | 44.65 | 26.16 |
| w/o HyDE | 45.94 | 36.24 | 44.23 | 25.98 |
| w/o HyDE+irrelevant documents | 45.35 | 35.57 | 43.59 | 25.27 |
| N | Naive | HyDE | ||||||
|---|---|---|---|---|---|---|---|---|
| ROUGE-1 | ROUGE-2 | ROUGE-L | BLEU-4 | ROUGE-1 | ROUGE-2 | ROUGE-L | BLEU-4 | |
| 0 | 53.67 | 37.30 | 44.94 | 25.08 | 54.50 | 38.11 | 45.99 | 26.62 |
| 1 | 53.70 | 37.15 | 45.04 | 25.08 | 54.49 | 37.96 | 45.99 | 26.63 |
| 2 | 54.11 | 37.83 | 45.72 | 25.91 | 54.98 | 38.82 | 46.78 | 27.58 |
| 3 | 54.18 | 37.44 | 45.57 | 25.55 | 54.94 | 38.46 | 46.71 | 27.34 |
| 4 | 54.59 | 38.01 | 46.12 | 26.24 | 54.66 | 38.17 | 46.34 | 27.03 |
| 5 | 54.54 | 37.97 | 46.12 | 26.31 | 54.53 | 38.17 | 46.27 | 27.02 |
| 6 | 54.13 | 37.55 | 45.73 | 26.08 | 55.06 | 38.65 | 46.75 | 27.63 |
| 7 | 54.07 | 37.52 | 45.68 | 25.74 | 54.53 | 38.32 | 46.32 | 27.24 |
| 8 | 54.33 | 37.80 | 45.96 | 26.35 | 55.34 | 39.16 | 47.02 | 27.92 |
| 9 | 54.03 | 37.54 | 45.69 | 26.19 | 54.73 | 38.40 | 46.42 | 27.26 |
| 10 | 54.08 | 37.59 | 45.87 | 26.08 | 54.86 | 38.51 | 46.45 | 27.39 |
| Model Condition | ROUGE-1 | ROUGE-2 | ROUGE-L | BLEU-4 |
|---|---|---|---|---|
| Naive RAG | 53.67 | 37.30 | 44.94 | 25.08 |
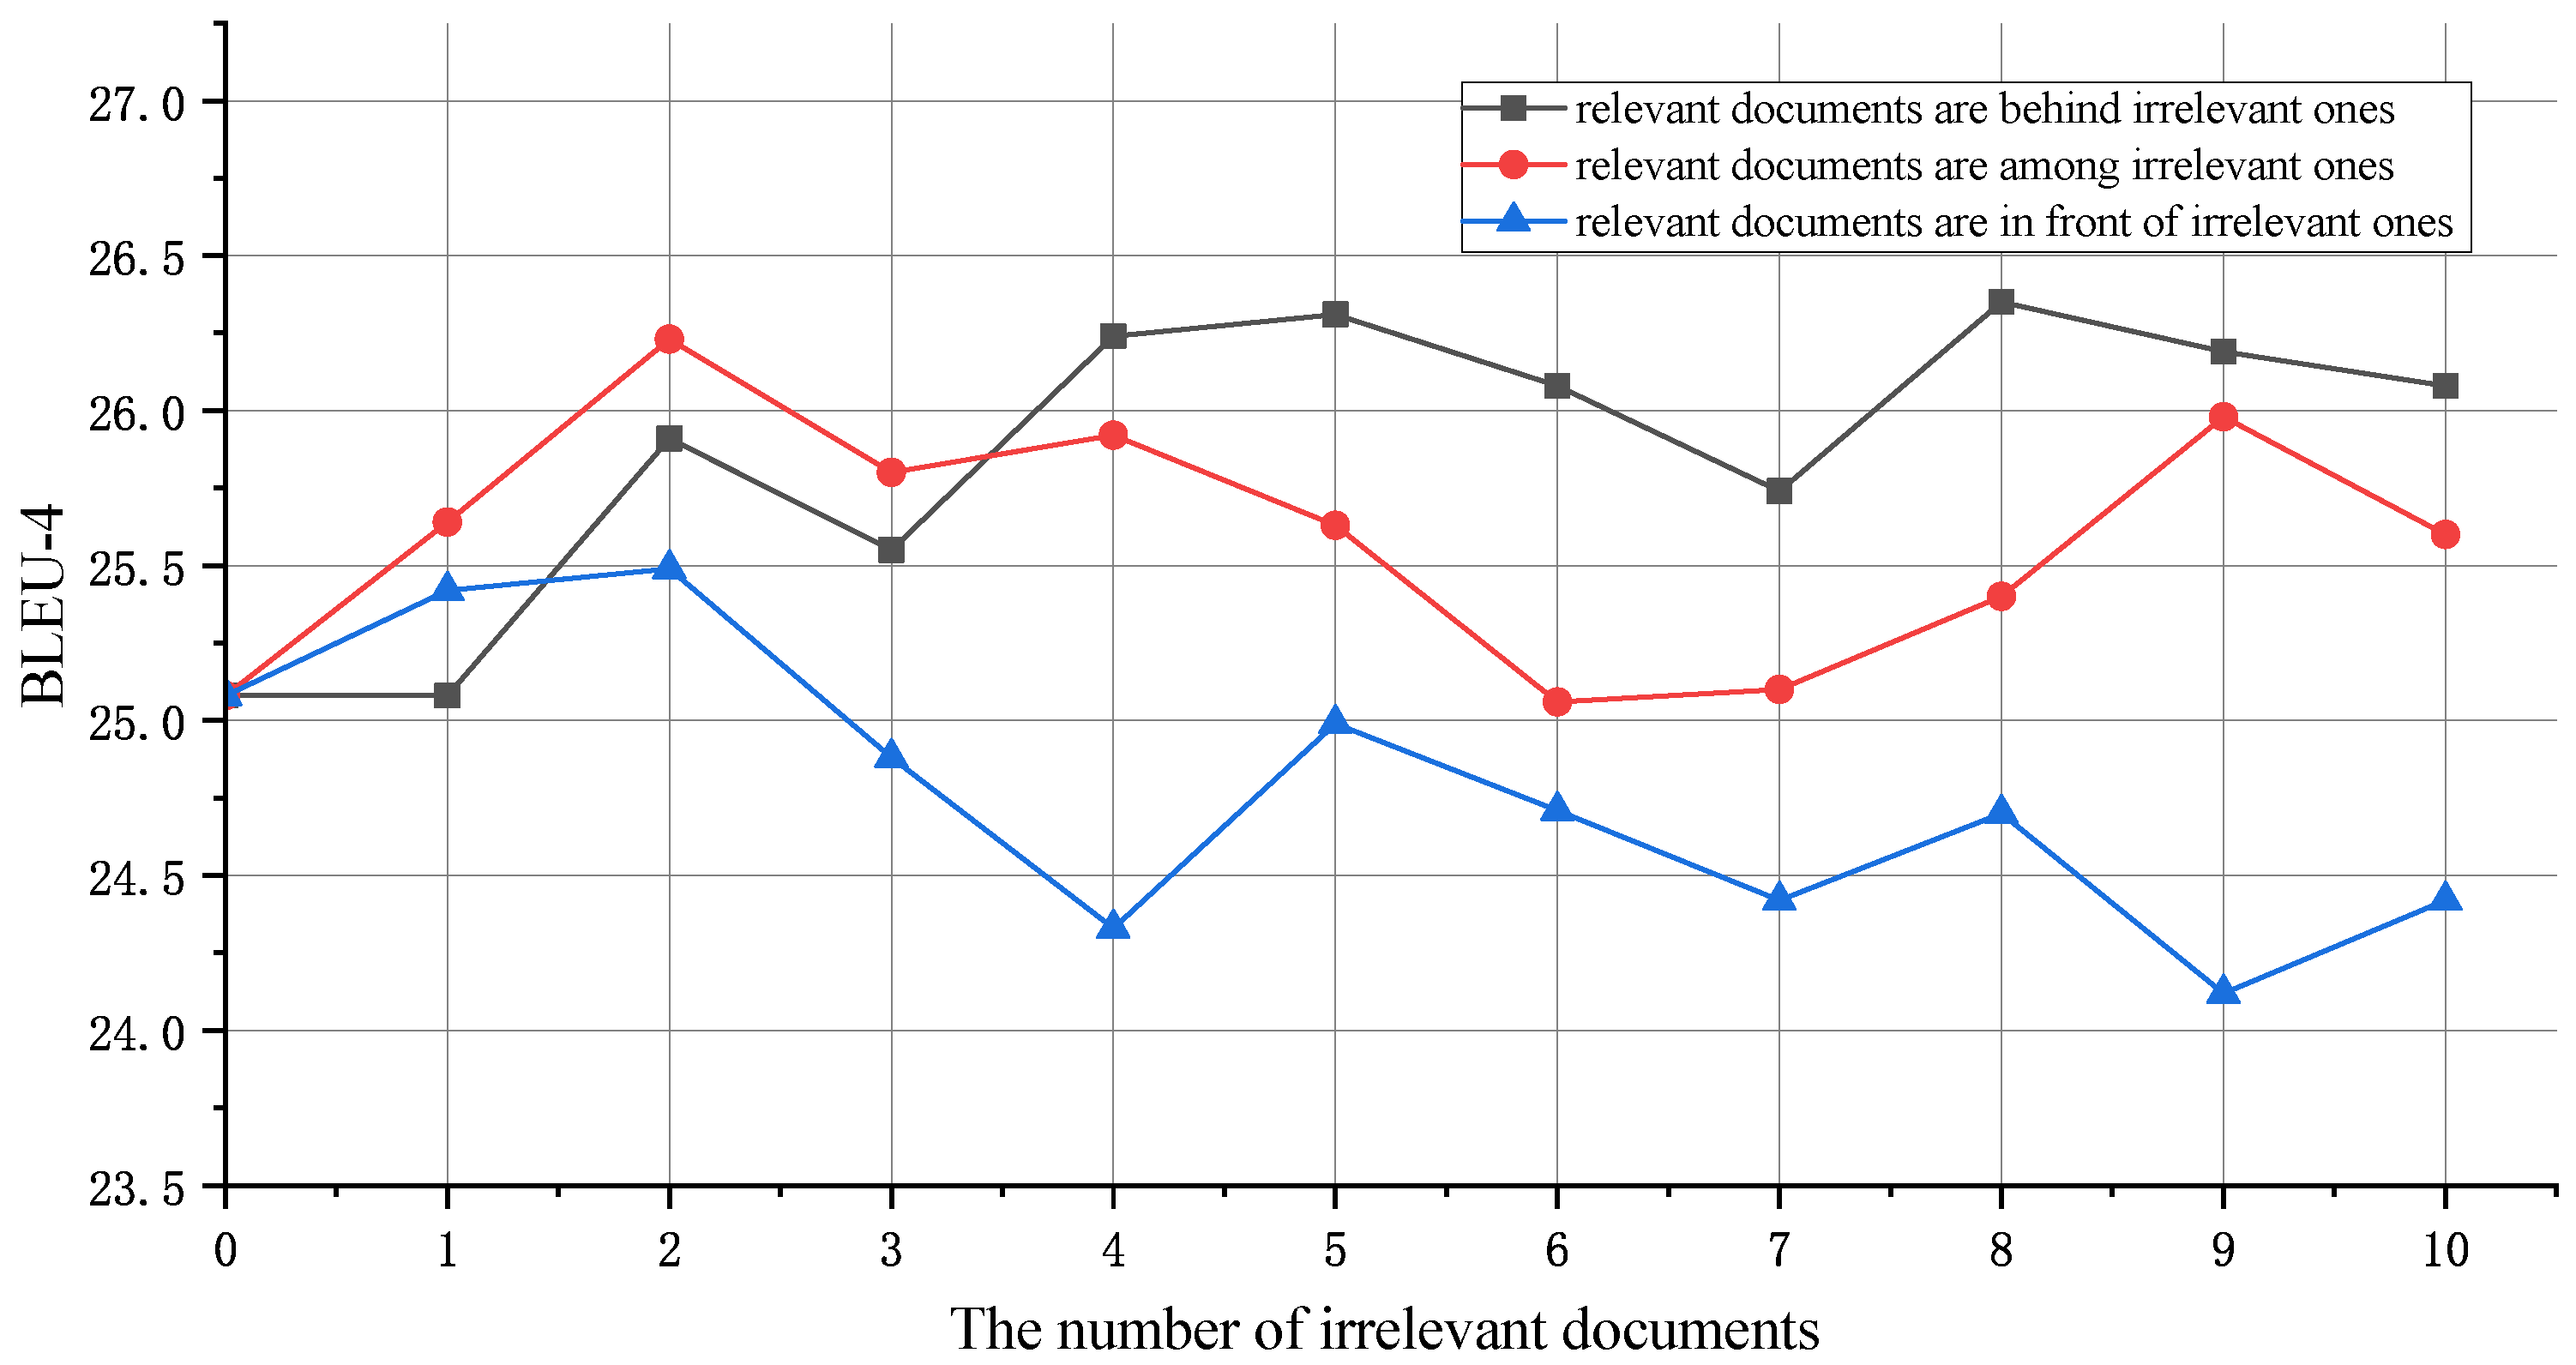
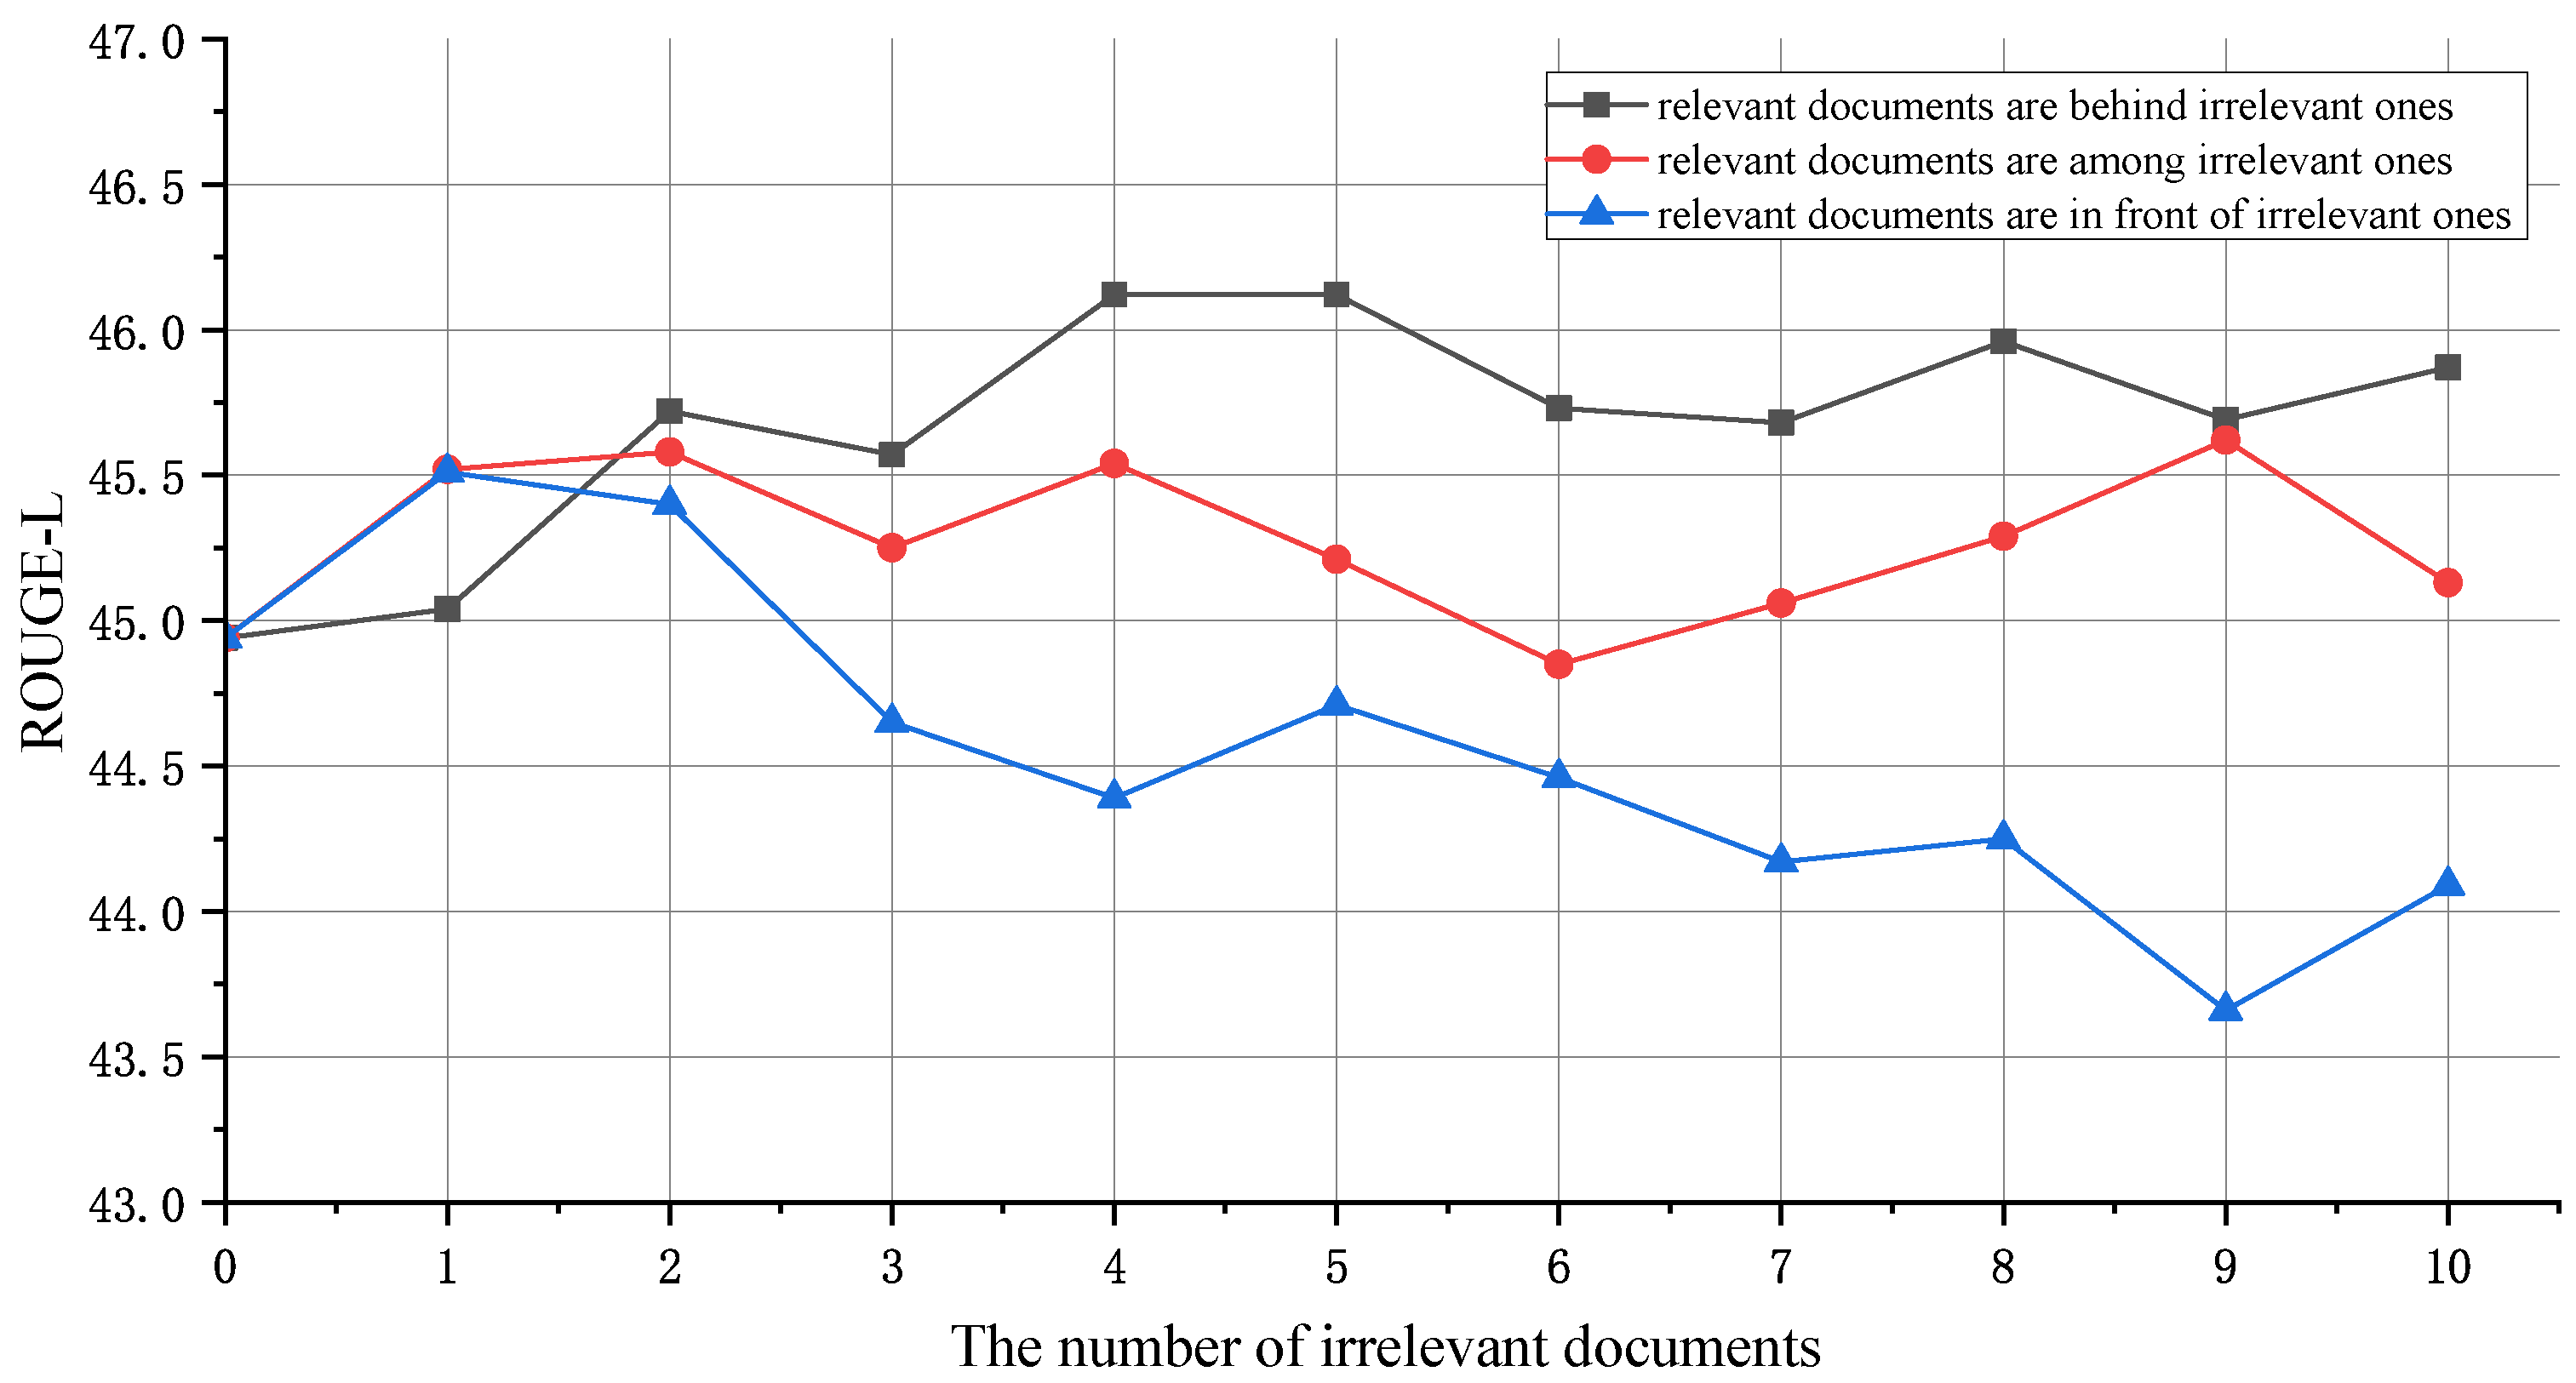
| R are behind irrelevant ones | 54.59 | 38.01 | 46.12 | 26.24 |
| HyDE + R are behind irrelevant ones | 55.34 | 39.16 | 47.02 | 27.92 |
| R are among irrelevant ones | 54.11 | 37.68 | 45.54 | 25.92 |
| HyDE + R are among irrelevant ones | 54.78 | 38.64 | 46.58 | 27.09 |
| R are in front of irrelevant ones | 54.04 | 37.66 | 45.51 | 25.42 |
| HyDE + R are in front of irrelevant ones | 54.72 | 38.77 | 46.43 | 27.46 |
Disclaimer/Publisher’s Note: The statements, opinions and data contained in all publications are solely those of the individual author(s) and contributor(s) and not of MDPI and/or the editor(s). MDPI and/or the editor(s) disclaim responsibility for any injury to people or property resulting from any ideas, methods, instructions or products referred to in the content. |
© 2026 by the authors. Licensee MDPI, Basel, Switzerland. This article is an open access article distributed under the terms and conditions of the Creative Commons Attribution (CC BY) license.
Share and Cite
Chen, Y.; Luo, X.; Zhou, Y.; Peng, Q.; Yuan, Y.; Chen, K.; Liu, Y. Virtual-Document-Augmented Retrieval-Augmented Generation for Power-Domain Knowledge-Base Question Answering with Noise-Enhanced Robustness. Processes 2026, 14, 670. https://doi.org/10.3390/pr14040670
Chen Y, Luo X, Zhou Y, Peng Q, Yuan Y, Chen K, Liu Y. Virtual-Document-Augmented Retrieval-Augmented Generation for Power-Domain Knowledge-Base Question Answering with Noise-Enhanced Robustness. Processes. 2026; 14(4):670. https://doi.org/10.3390/pr14040670
Chicago/Turabian StyleChen, Yanwen, Xiong Luo, Ying Zhou, Qiaojuan Peng, Yuqi Yuan, Ke Chen, and Yinghui Liu. 2026. "Virtual-Document-Augmented Retrieval-Augmented Generation for Power-Domain Knowledge-Base Question Answering with Noise-Enhanced Robustness" Processes 14, no. 4: 670. https://doi.org/10.3390/pr14040670
APA StyleChen, Y., Luo, X., Zhou, Y., Peng, Q., Yuan, Y., Chen, K., & Liu, Y. (2026). Virtual-Document-Augmented Retrieval-Augmented Generation for Power-Domain Knowledge-Base Question Answering with Noise-Enhanced Robustness. Processes, 14(4), 670. https://doi.org/10.3390/pr14040670